Run a <400ms latency Voice Agent on just 4GB VRAM. Fully offline, no API keys required. Optimized for GTX 1650 and edge robotics with zero-copy inference. (Apache 2.0)
Python
146
51 commits
updated May 24, 2026




AXIOM is a voice agent built for robotics / edge environments. It combines modern ML techniques with an efficient inference pipeline to deliver:
.safetensors (no pickle-based model head)5m → 5 meters)# Clone repository
git clone https://github.com/pheonix-delta/axiom-voice-agent.git
cd axiom-voice-agent
# Create virtual environment (recommended name: axiomvenv)
python3 -m venv axiomvenv
source axiomvenv/bin/activate # Linux/Mac
# or
axiomvenv\Scripts\activate # Windows
# Install dependencies (avoid --break-system-packages; use the venv)
pip install -r requirements.txt
Models are symlinked from your system. Verify they're accessible:
# Check symlinks
ls -la models/
# Output should show:
# kokoro-en-v0_19 -> ../../kokoro-en-v0_19
# sherpa-onnx-... -> ../../sherpa-onnx-...

# If symlinks are broken, set environment variables:
export KOKORO_PATH=/path/to/kokoro-en-v0_19
export SHERPA_PATH=/path/to/sherpa-onnx-...
📖 See MODEL_PATH_RESOLUTION.md for complete setup options:
cd backend
python main_agent_web.py

# Output:
# INFO:     Application startup complete
# INFO:     Uvicorn running on http://0.0.0.0:8000
Navigate to:
http://localhost:8000
🎙️ Click the microphone icon and start speaking!
⚠️ Important: Use localhost or 127.0.0.1 (not IP addresses) for browser microphone permissions.
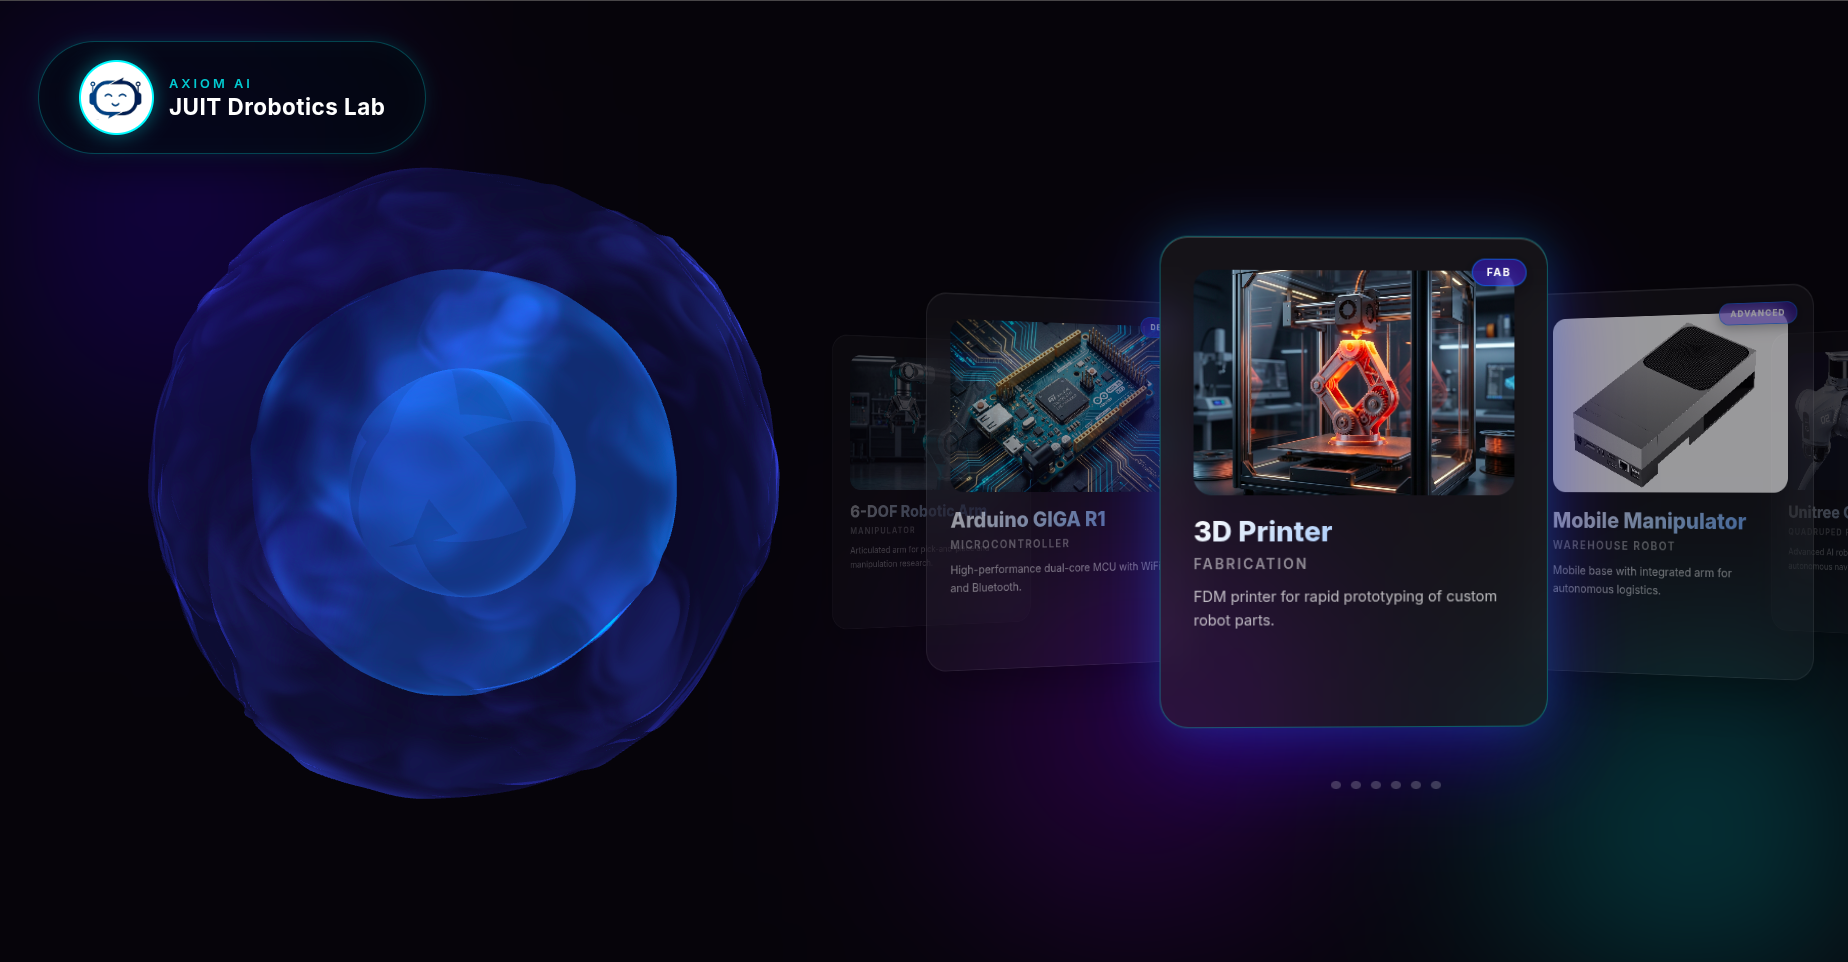
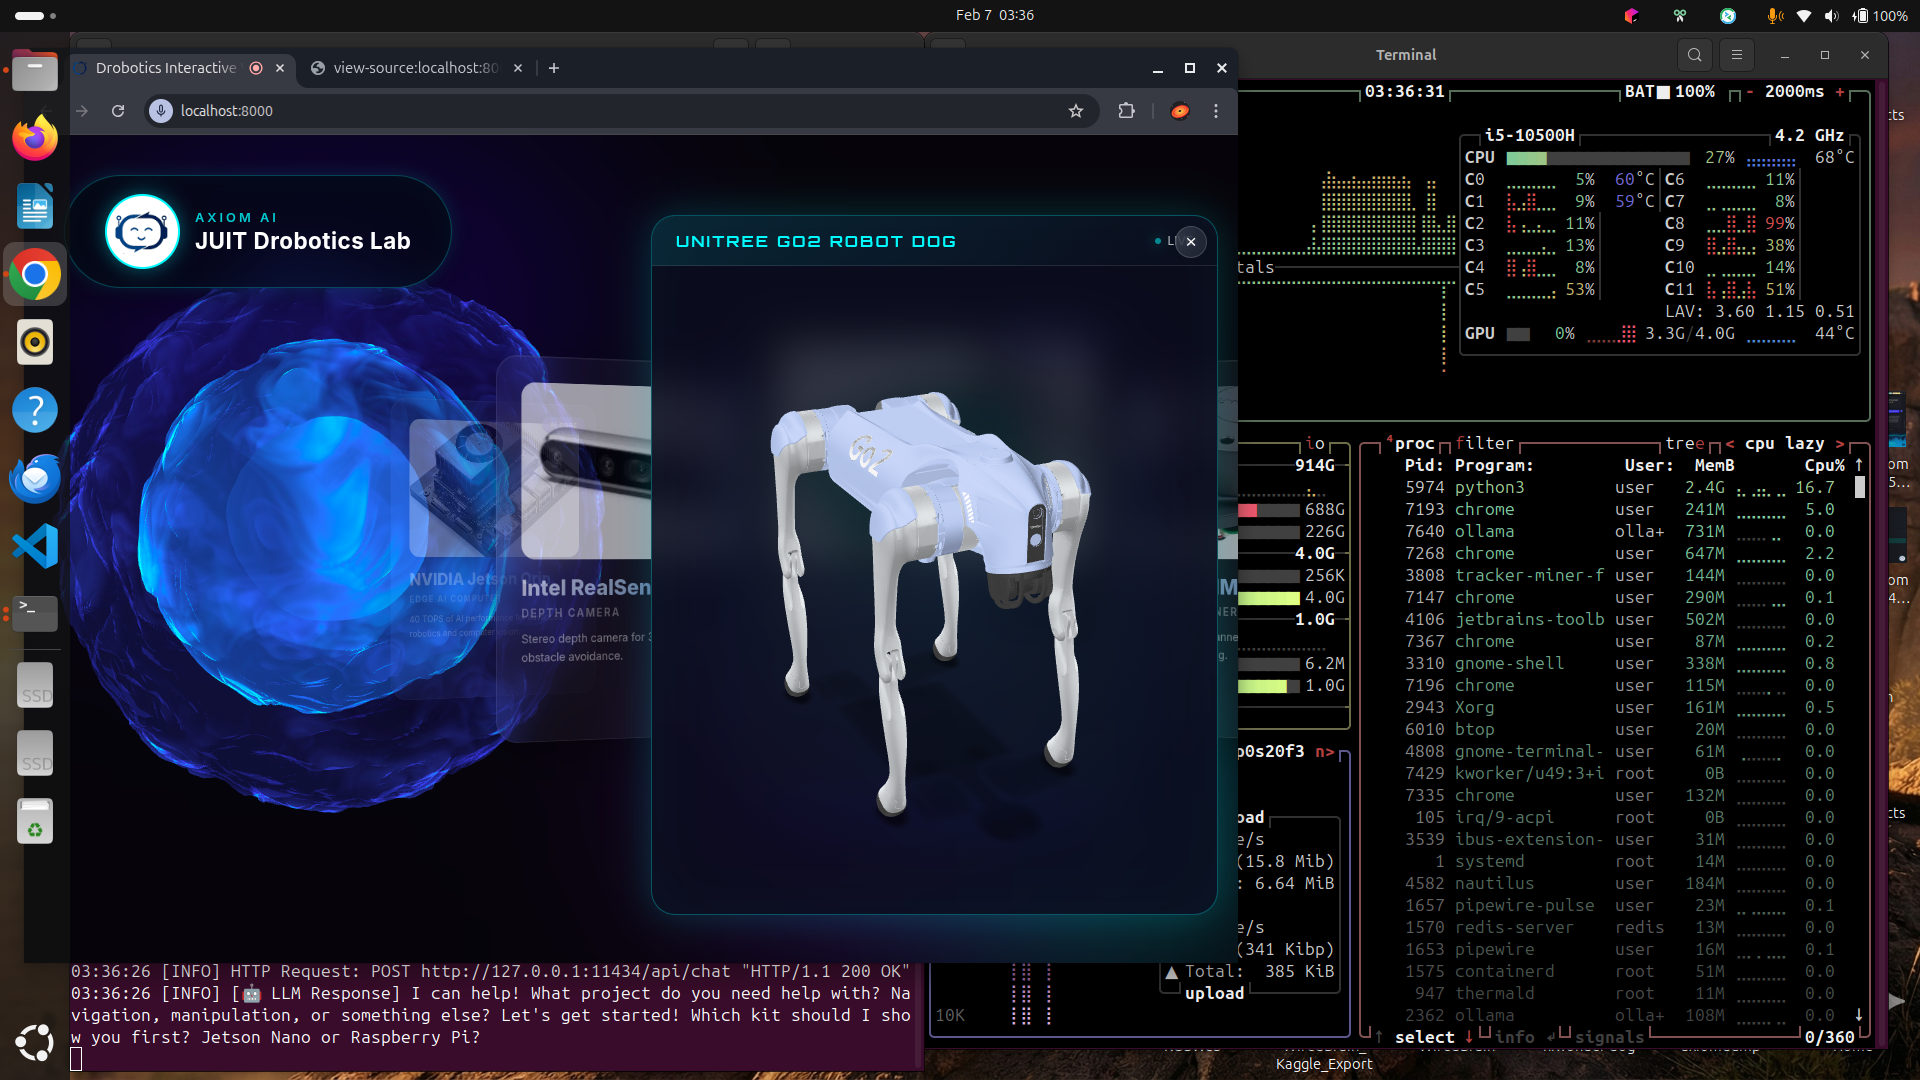
Interactive carousel with equipment cards and voice agent
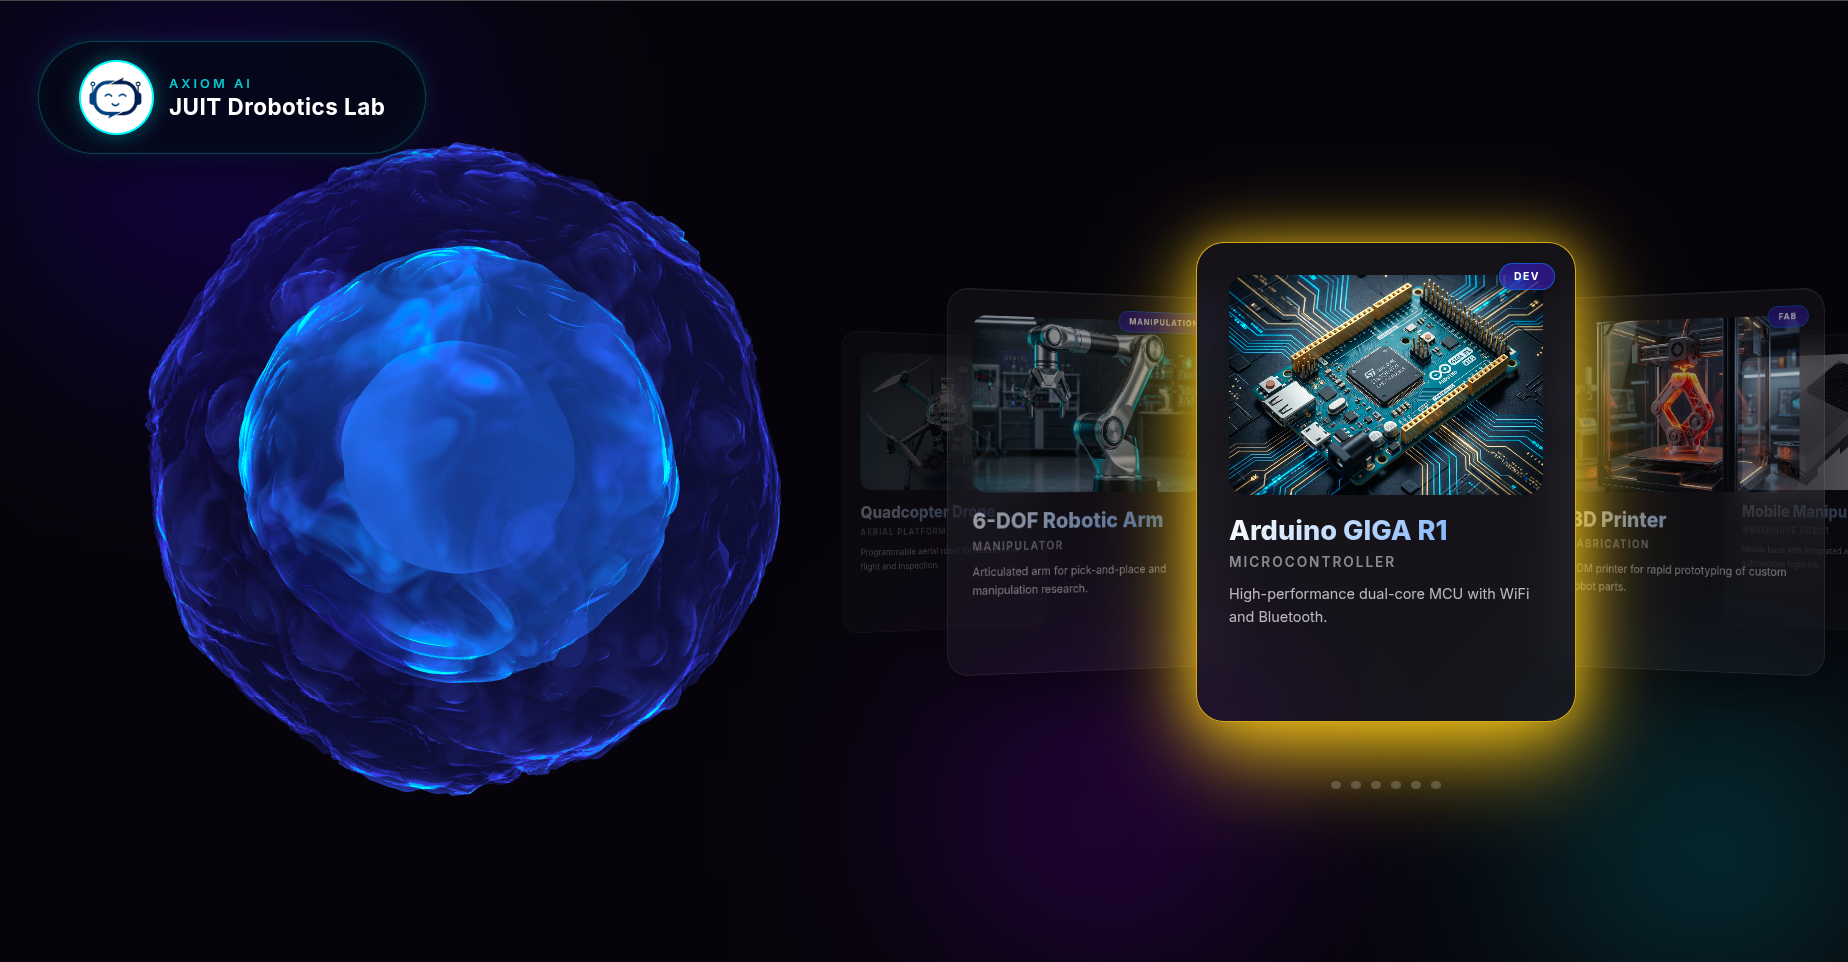
Detailed equipment specifications and 3D models
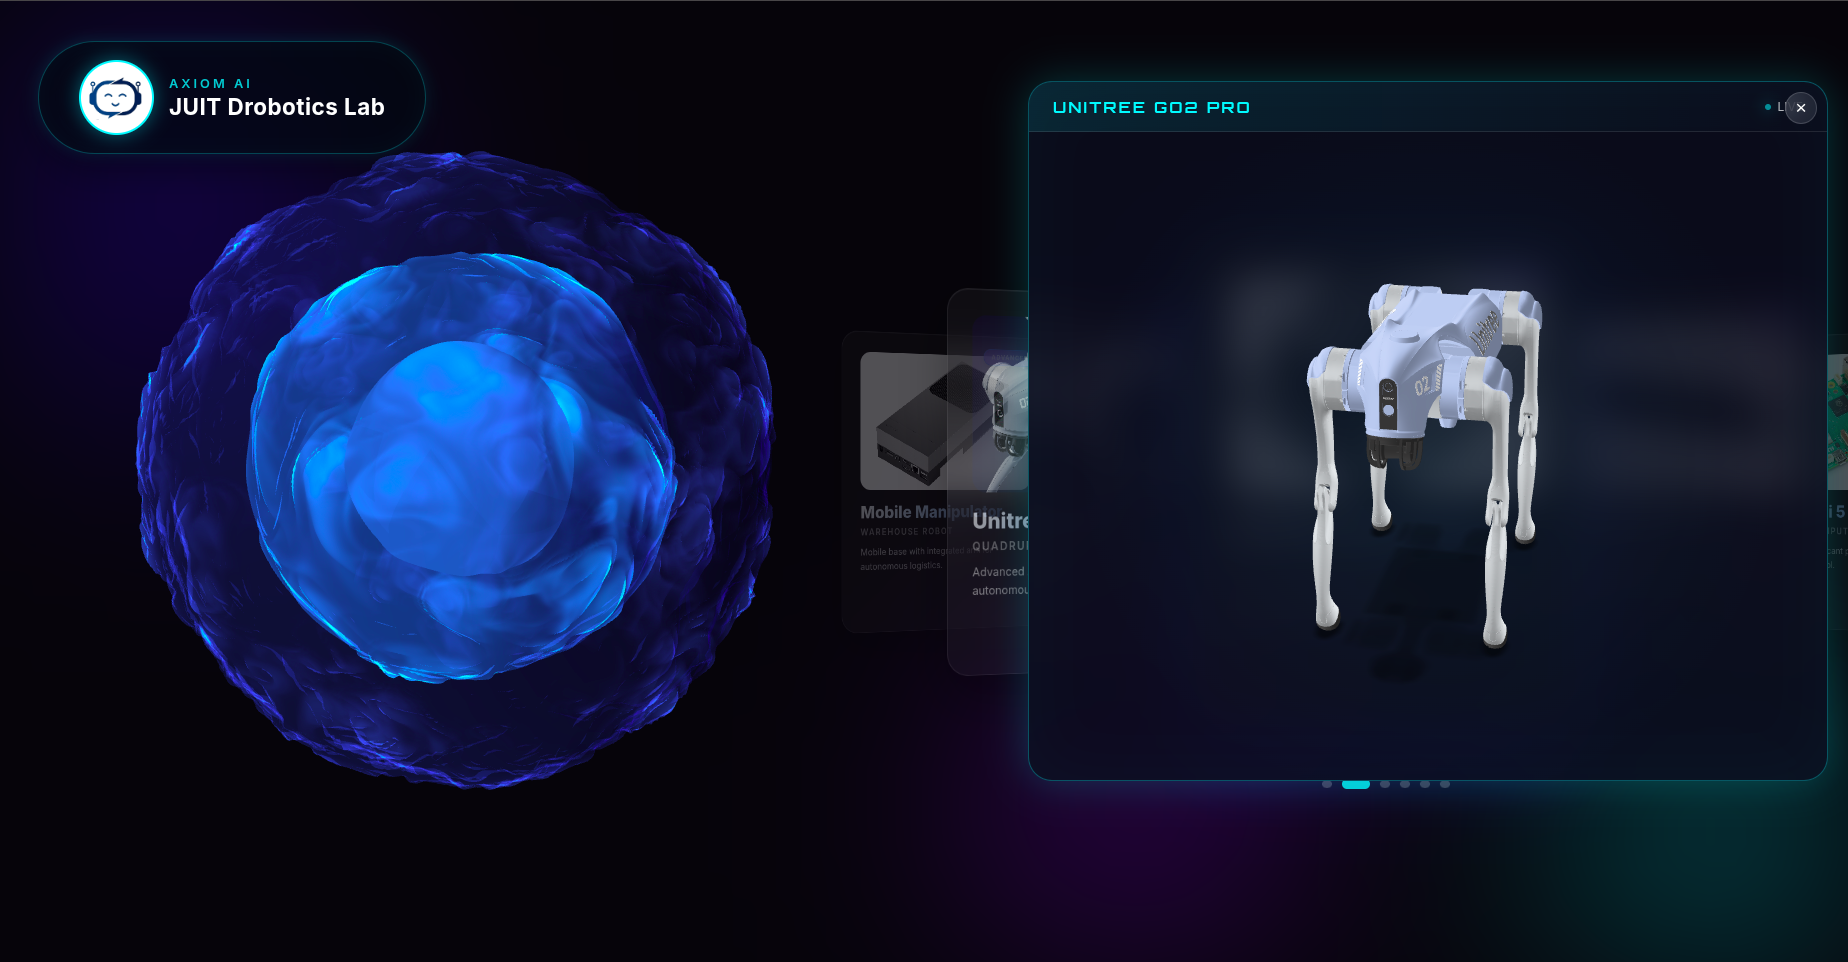
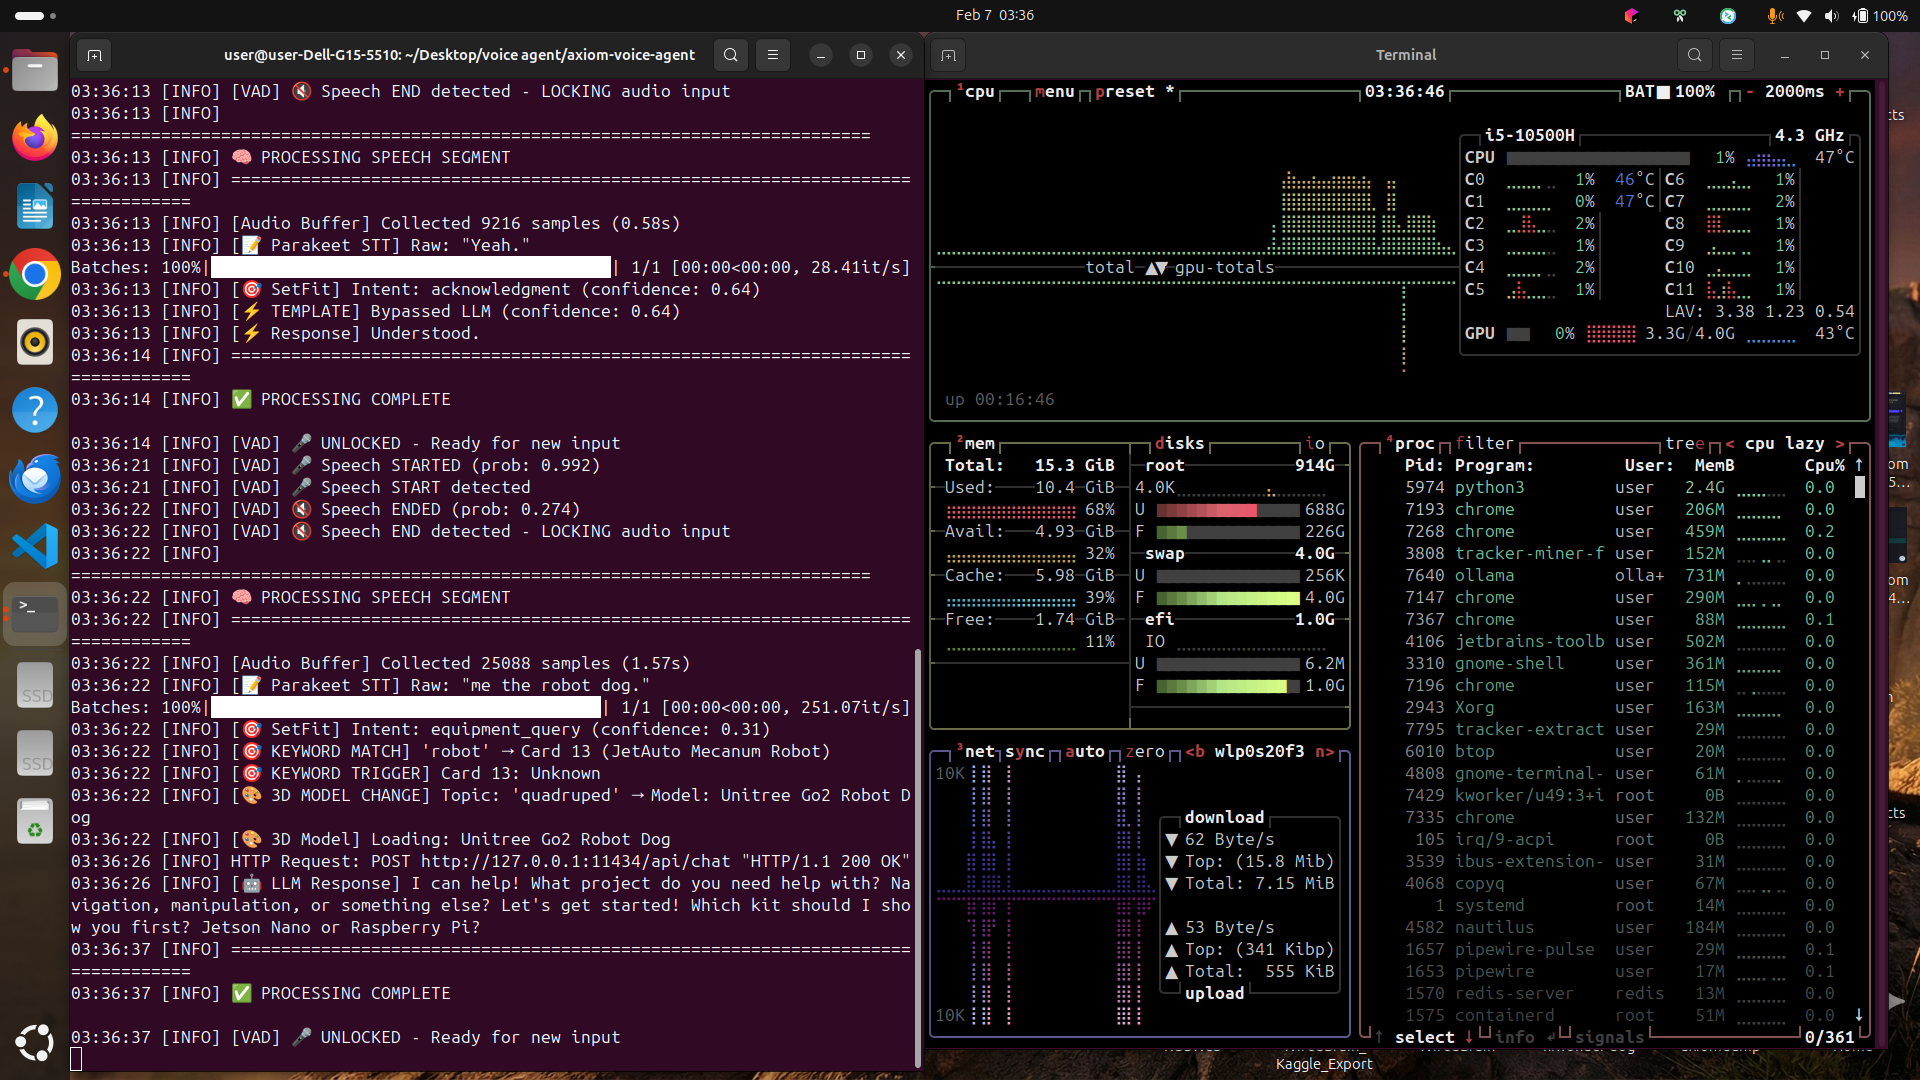
Real-time voice interaction with visual feedback
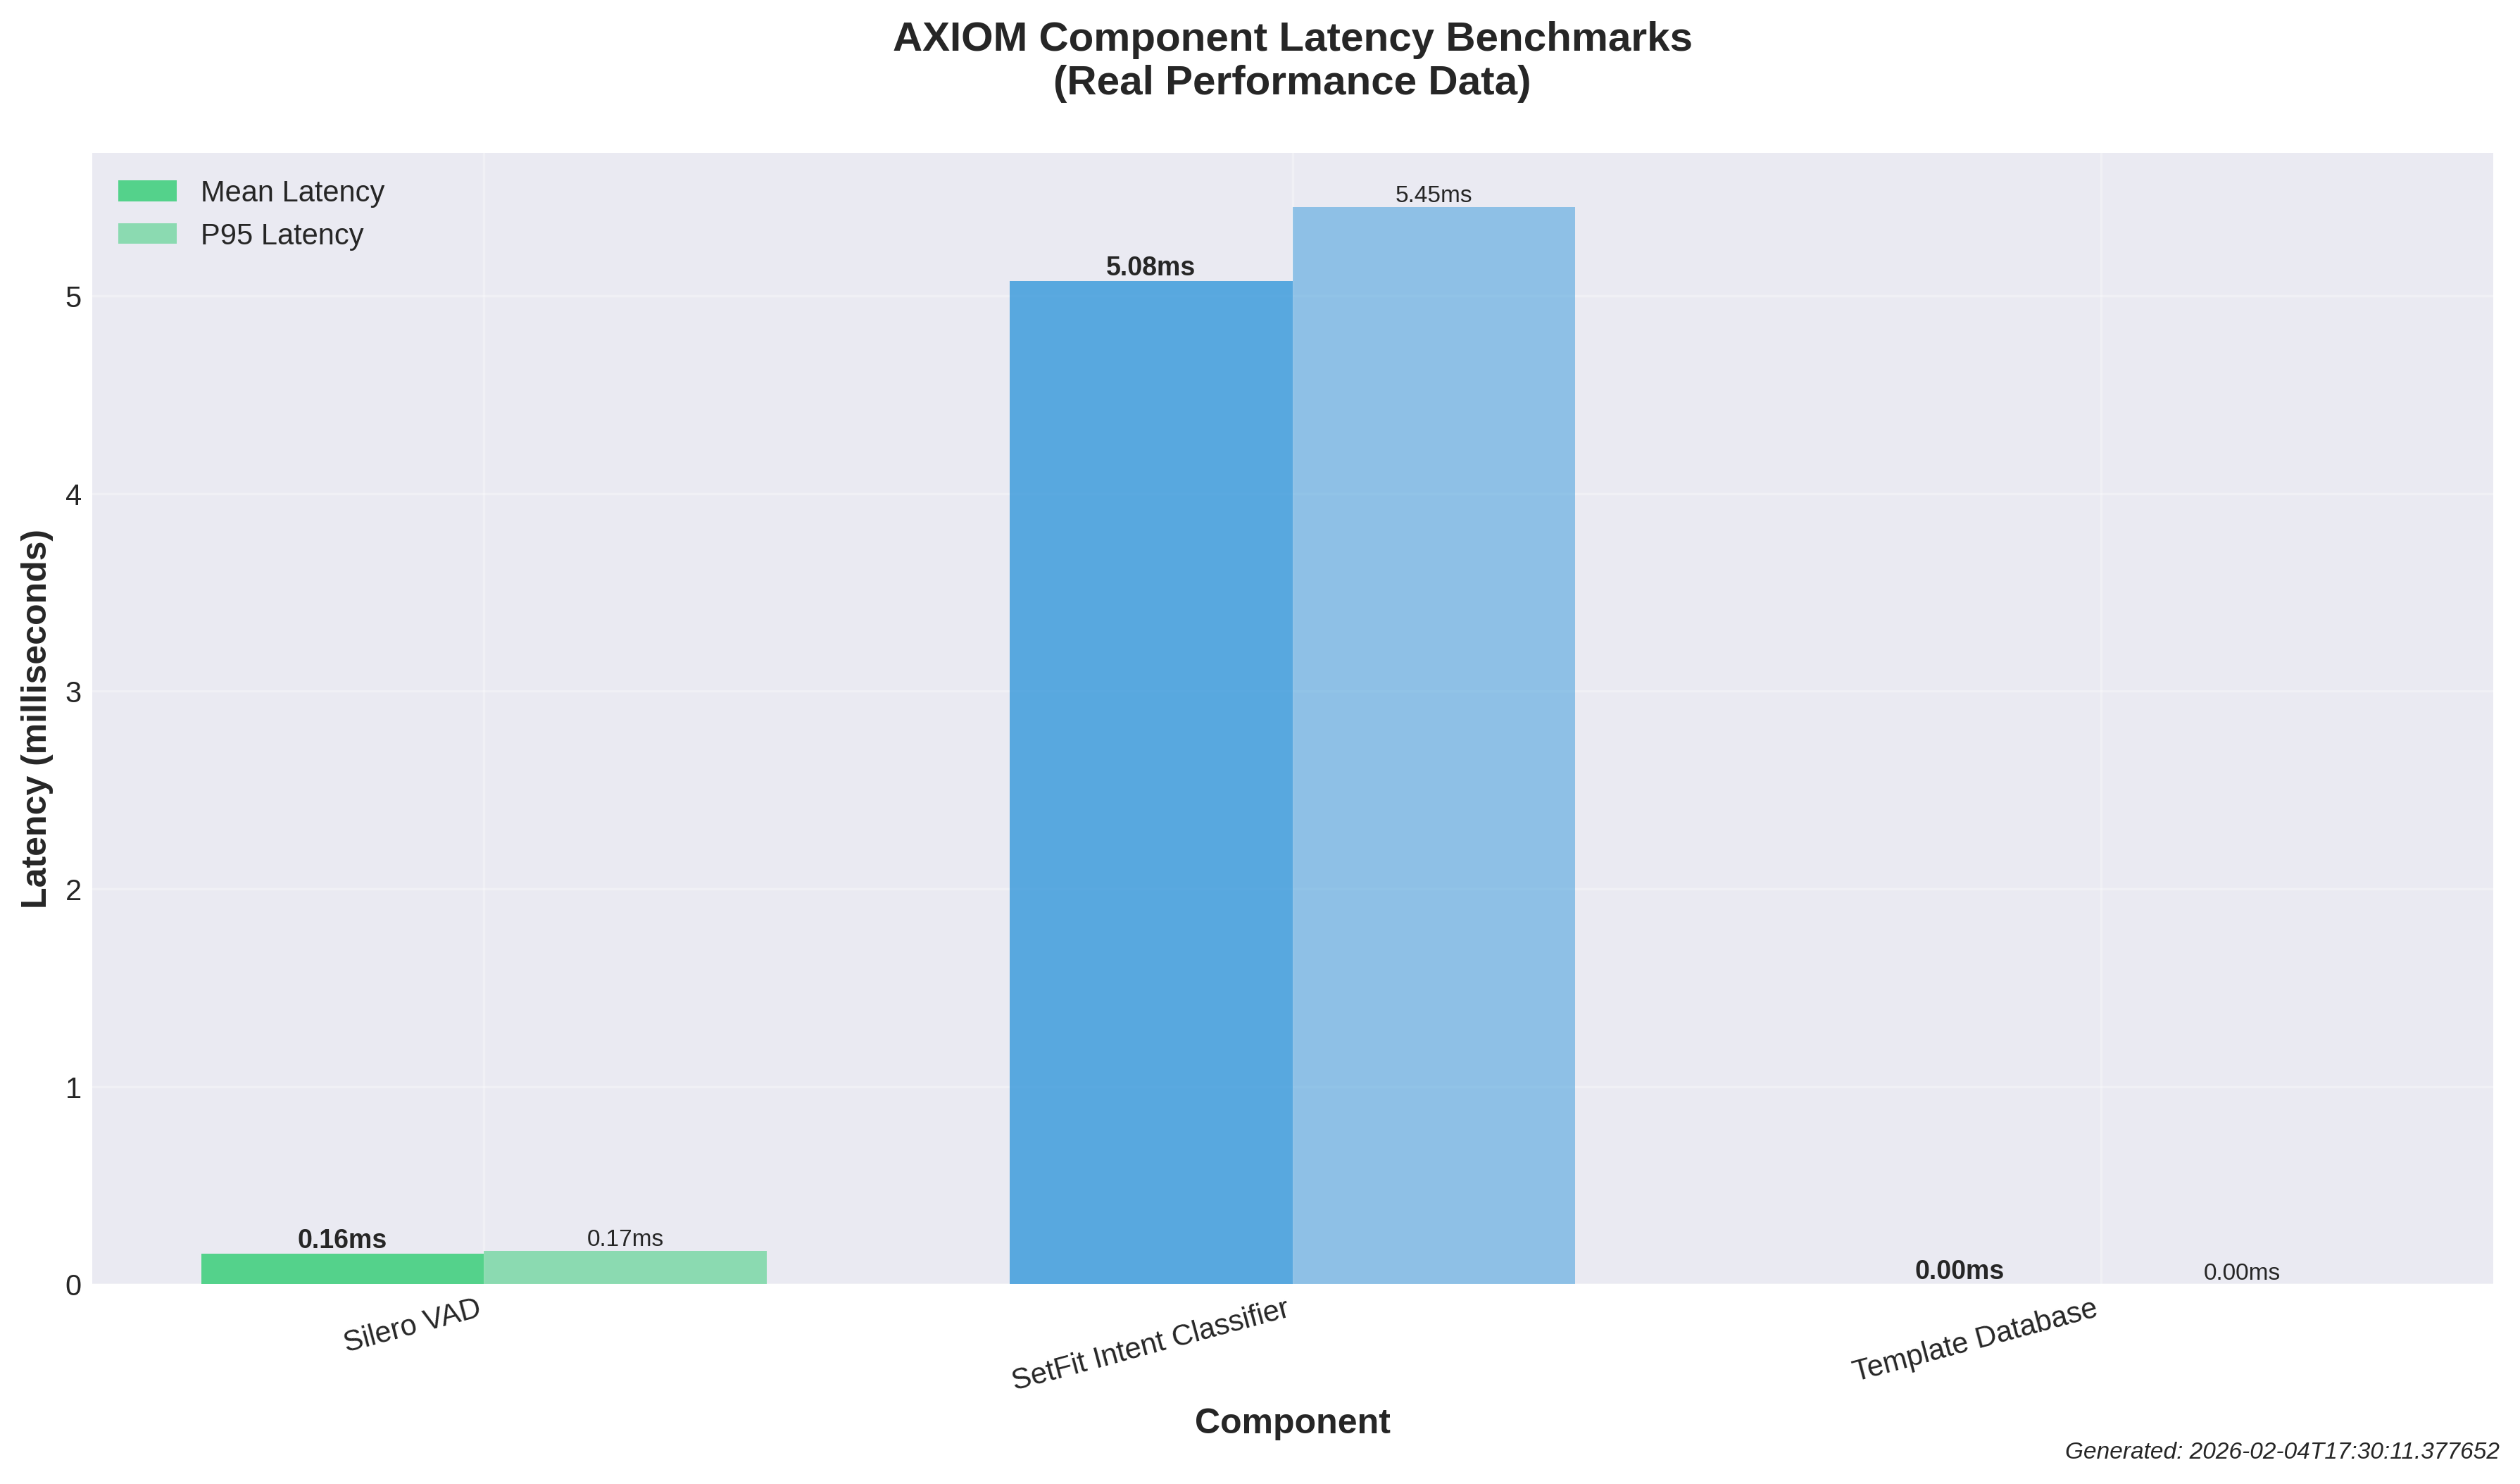
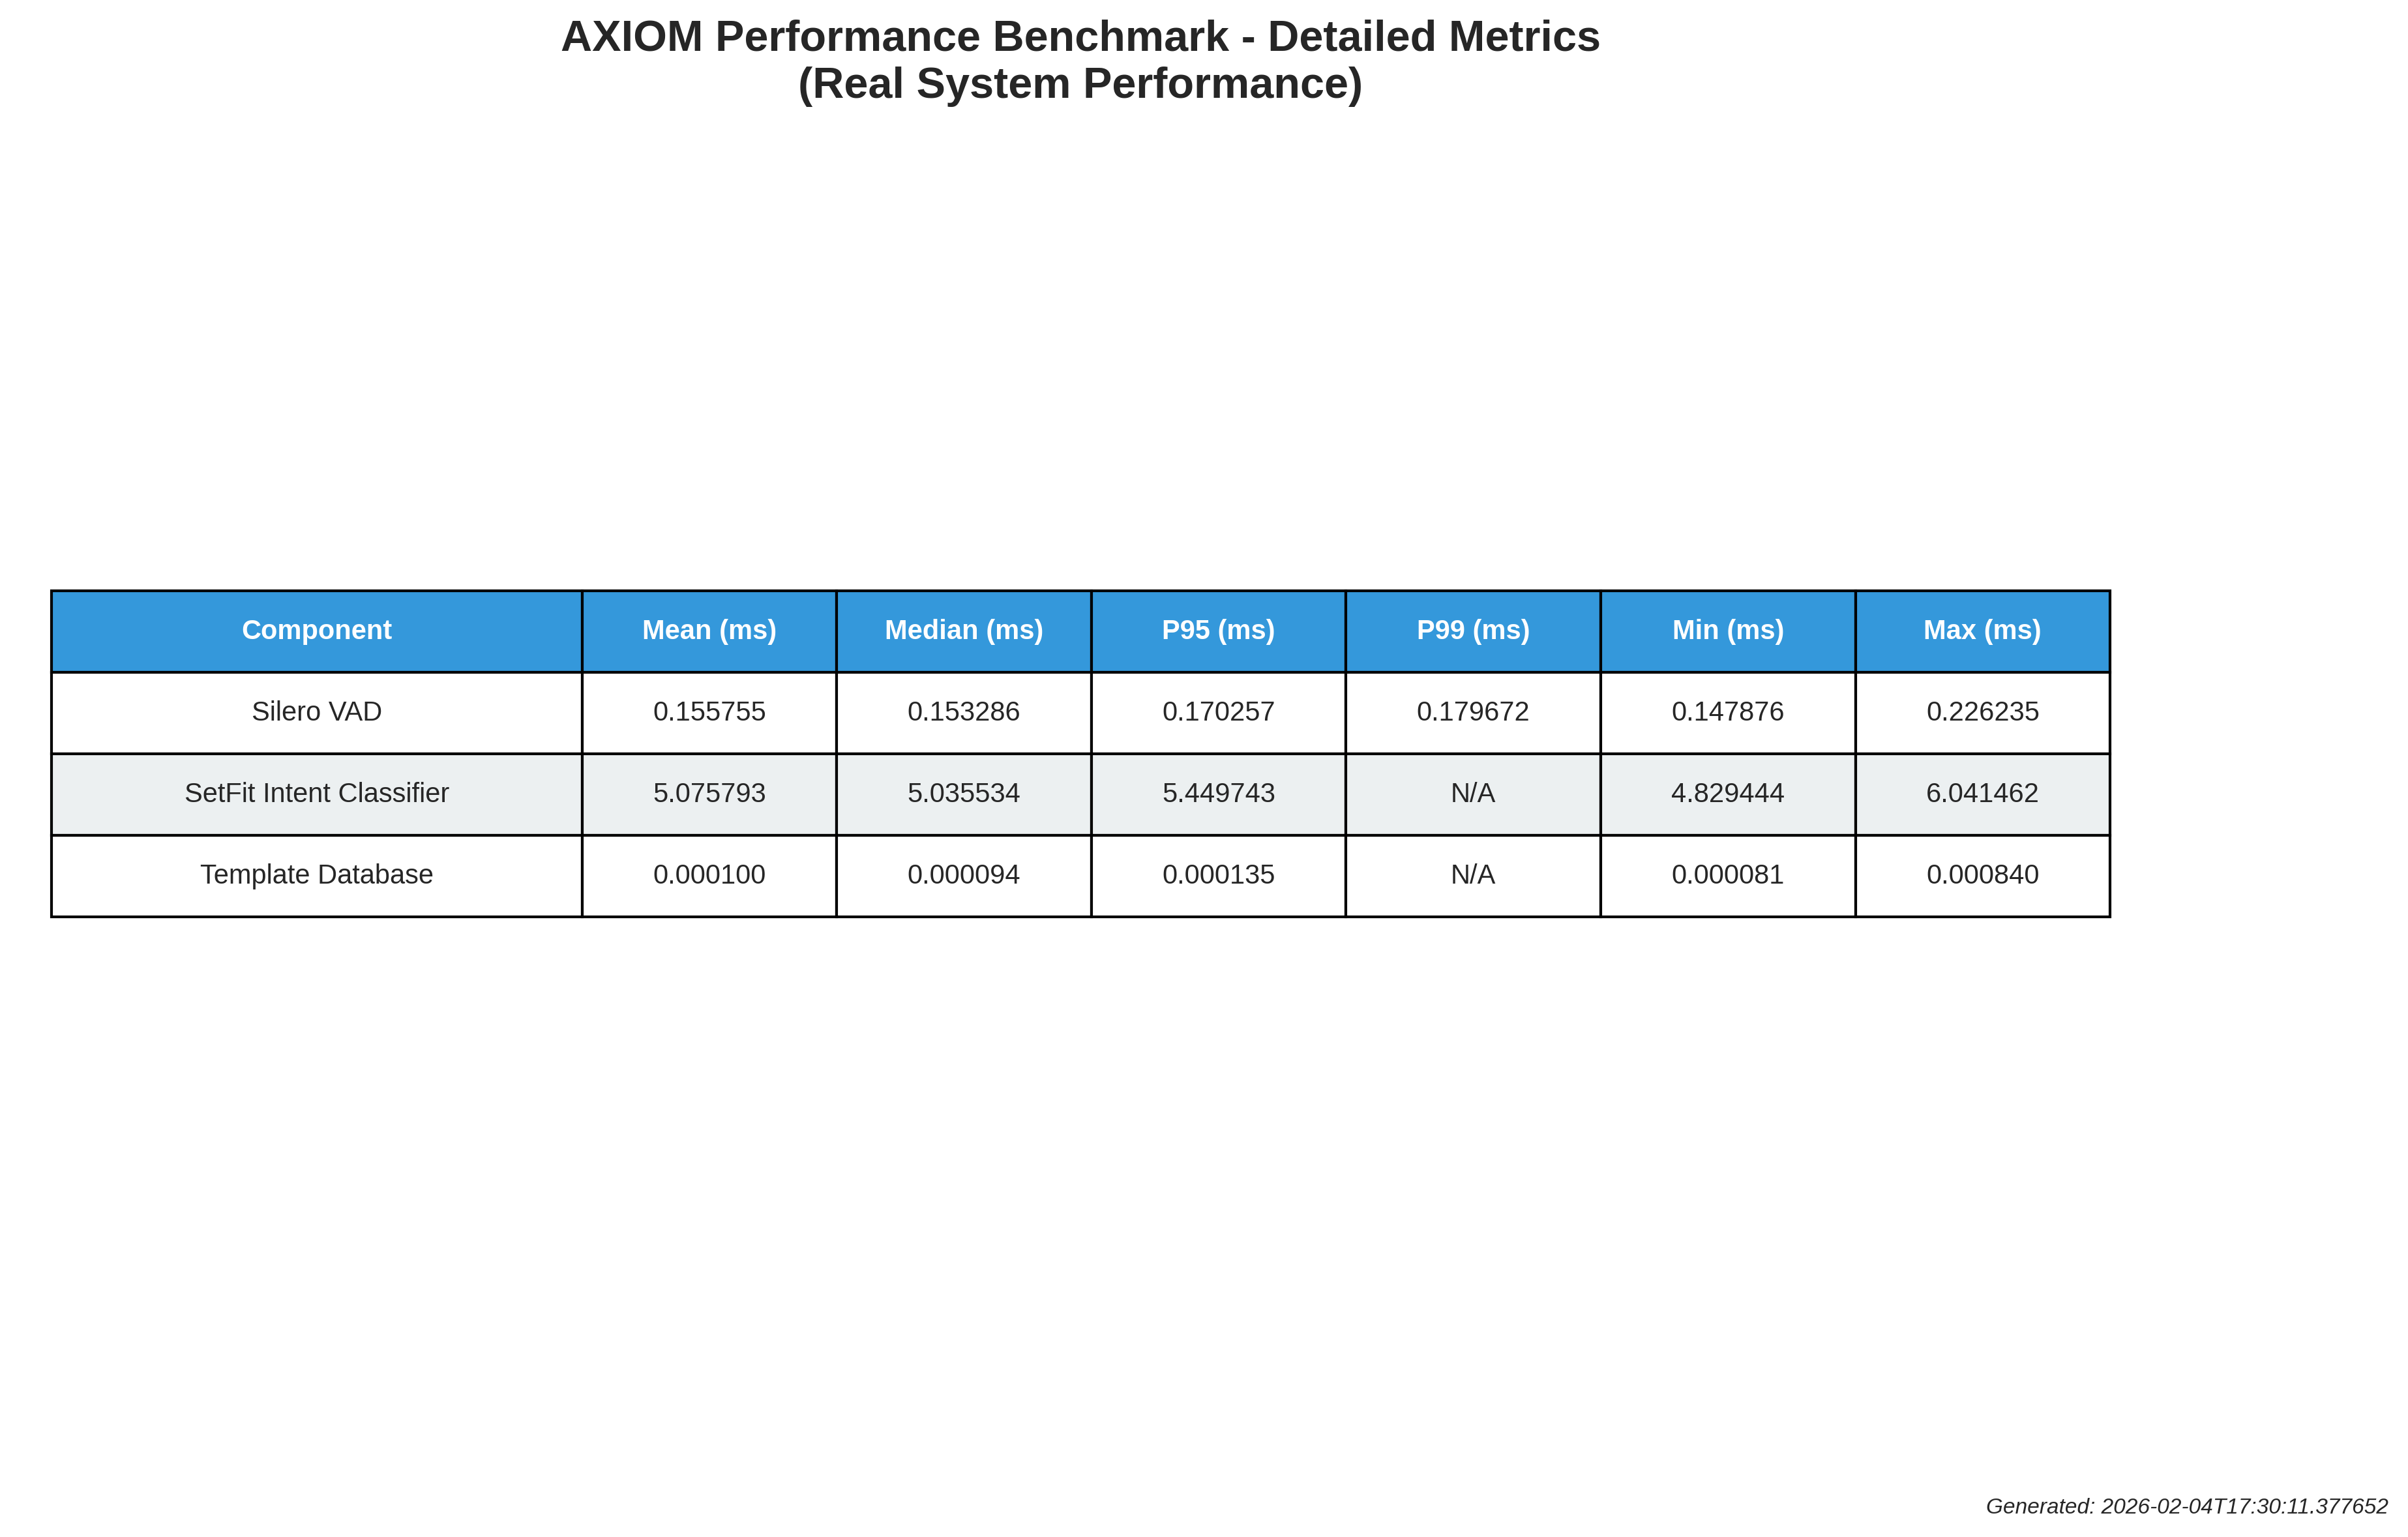
Benchmark scripts and analysis live in benchmarks/.
Component-level latency breakdown and system throughput metrics
End-to-end response time analysis across intent categories
┌─────────────────────┐
│  Browser (Web UI)   │
│  - Voice Capture    │
│  - 3D Visualization │
└──────────┬──────────┘
           │ WebSocket
           ↓
┌──────────────────────────────────────────┐
│         FastAPI Backend Server           │
├──────────────────────────────────────────┤
│ ┌─ STT Pipeline ─────────────────────┐  │
│ │ • Sherpa-ONNX Parakeet             │  │
│ │ • Silero VAD (Voice Detection)     │  │
│ │ • Phonetic + Minimal Safe Corrector│  │
│ └────────────────────────────────────┘  │
│ ┌─ Intent Classification ────────────┐  │
│ │ • SetFit Model (Local inference)   │  │
│ │ • Intent classes                   │  │
│ └────────────────────────────────────┘  │
│ ┌─ Response Pipeline ────────────────┐  │
│ │ • Template-based bypass            │  │
│ │ • Semantic RAG handler             │  │
│ │ • Ollama LLM fallback              │  │
│ └────────────────────────────────────┘  │
│ ┌─ TTS Engine ───────────────────────┐  │
│ │ • Kokoro TTS (Sherpa-ONNX)         │  │
│ │ • Sequential queue (no echo)       │  │
│ │ • TTS-safe text normalization      │  │
│ └────────────────────────────────────┘  │
└──────────────────────────────────────────┘
        ↓ (Data Persistence)
   SQLite Database
   (Conversation History)
┌──────────────────────────────────────────────────────────────────────────────┐
│ Browser (frontend/)                                                          │
│  - voice-carousel-integrated.html                                            │
│  - audio-capture-processor.js                                                │
└──────────────────────────────────┬───────────────────────────────────────────┘
                                   │ WebSocket (binary audio + JSON messages)
                                   ▼
┌──────────────────────────────────────────────────────────────────────────────┐
│ FastAPI Backend (backend/main_agent_web.py)                                  │
│                                                                              │
│  audio bytes                                                                 │
│     ▼                                                                        │
│  [VAD] backend/vad_handler.py                                                │
│     ▼                                                                        │
│  [STT] backend/stt_handler.py  → transcription                               │
│     ▼                                                                        │
│  [Intent] backend/intent_classifier.py → intent + confidence                 │
│     ▼                                                                        │
│  [Context] backend/conversation_manager.py (SQLite + FIFO)                   │
│     ▼                                                                        │
│  [Response]                                                                  │
│     - Fast path: backend/template_responses.py (2,116 templates)             │
│     - Smart path: backend/semantic_rag_handler.py (RAG) + backend/axiom_brain.py (LLM)
│     ▼                                                                        │
│  [TTS] backend/sequential_tts_handler.py + text normalizers                  │
│     ▼                                                                        │
│  audio out → WebSocket → browser playback                                    │
└──────────────────────────────────────────────────────────────────────────────┘
| Component | Purpose | Tech Stack |
|---|---|---|
| VAD Handler | Detect speech segments | Silero VAD |
| STT Handler | Convert audio → text | Sherpa-ONNX |
| Intent Classifier | Detect user intent | SetFit (sentence-transformers) |
| Conversation Manager | Maintain context | SQLite + FIFO |
| Template Responses | Fast replies | 2,116 JSON templates |
| RAG Handler | Search knowledge bases | Sentence-Transformers embeddings |
| LLM Interface | Complex queries | Ollama + local model |
| TTS Handler | Generate speech | Kokoro-EN (Sherpa-ONNX) |
| 3D Mapper | Map keywords → GLB models | Keyword extraction |
| WebSocket Server | Real-time communication | FastAPI + uvicorn |
5m → 5 meters, jetson nano → Jetson Nano**bold**, *italic*, `code` → plain textaxiom-voice-agent/
├── backend/ # FastAPI server + core voice pipeline
│ ├── main_agent_web.py # App entrypoint (WebSocket server)
│ ├── vad_handler.py # Voice activity detection
│ ├── stt_handler.py # Speech-to-text
│ ├── intent_classifier.py # Intent routing
│ ├── semantic_rag_handler.py # RAG + fallback path
│ ├── template_responses.py # 2,116 template responses
│ ├── sequential_tts_handler.py # TTS queue + generation
│ └── ...
├── frontend/ # Web UI
│ ├── voice-carousel-integrated.html
│ └── audio-capture-processor.js
├── data/ # Knowledge bases + templates
│ ├── template_database.json
│ ├── rag_knowledge_base.json
│ ├── project_ideas_rag.json
│ ├── inventory.json
│ └── carousel_mapping.json
├── assets/ # Images, 3D models, benchmarks
│ ├── screenshots/
│ ├── branding/
│ ├── benchmarks/
│ └── 3d v2/
├── benchmarks/ # Benchmark scripts + reports
├── demos/ # Demo logs + recordings
├── docs/ # Architecture + installation docs
├── models/ # Symlink-based model directory
├── scripts/ # Utilities (charts, safetensors tools, etc.)
├── requirements.txt
├── start.sh
└── README.md
If you use AXIOM in research, please cite:
If this project helps you, please star the repo — it helps others find an offline, low-latency voice agent.
Run a <400ms latency Voice Agent on just 4GB VRAM. Fully offline, no API keys required. Optimized for GTX 1650 and edge robotics with zero-copy inference. (Apache 2.0)
Python
146
51 commits
updated May 24, 2026
AXIOM is a voice agent built for robotics / edge environments. It combines modern ML techniques with an efficient inference pipeline to deliver:
.safetensors (no pickle-based model head)5m → 5 meters)# Clone repository
git clone https://github.com/pheonix-delta/axiom-voice-agent.git
cd axiom-voice-agent
# Create virtual environment (recommended name: axiomvenv)
python3 -m venv axiomvenv
source axiomvenv/bin/activate # Linux/Mac
# or
axiomvenv\Scripts\activate # Windows
# Install dependencies (avoid --break-system-packages; use the venv)
pip install -r requirements.txt
Models are symlinked from your system. Verify they're accessible:
# Check symlinks
ls -la models/
# Output should show:
# kokoro-en-v0_19 -> ../../kokoro-en-v0_19
# sherpa-onnx-... -> ../../sherpa-onnx-...

# If symlinks are broken, set environment variables:
export KOKORO_PATH=/path/to/kokoro-en-v0_19
export SHERPA_PATH=/path/to/sherpa-onnx-...
📖 See MODEL_PATH_RESOLUTION.md for complete setup options:
cd backend
python main_agent_web.py

# Output:
# INFO:     Application startup complete
# INFO:     Uvicorn running on http://0.0.0.0:8000
Navigate to:
http://localhost:8000
🎙️ Click the microphone icon and start speaking!
⚠️ Important: Use localhost or 127.0.0.1 (not IP addresses) for browser microphone permissions.
Interactive carousel with equipment cards and voice agent
Detailed equipment specifications and 3D models
Real-time voice interaction with visual feedback
Benchmark scripts and analysis live in benchmarks/.
Component-level latency breakdown and system throughput metrics
End-to-end response time analysis across intent categories
┌─────────────────────┐
│  Browser (Web UI)   │
│  - Voice Capture    │
│  - 3D Visualization │
└──────────┬──────────┘
           │ WebSocket
           ↓
┌──────────────────────────────────────────┐
│         FastAPI Backend Server           │
├──────────────────────────────────────────┤
│ ┌─ STT Pipeline ─────────────────────┐  │
│ │ • Sherpa-ONNX Parakeet             │  │
│ │ • Silero VAD (Voice Detection)     │  │
│ │ • Phonetic + Minimal Safe Corrector│  │
│ └────────────────────────────────────┘  │
│ ┌─ Intent Classification ────────────┐  │
│ │ • SetFit Model (Local inference)   │  │
│ │ • Intent classes                   │  │
│ └────────────────────────────────────┘  │
│ ┌─ Response Pipeline ────────────────┐  │
│ │ • Template-based bypass            │  │
│ │ • Semantic RAG handler             │  │
│ │ • Ollama LLM fallback              │  │
│ └────────────────────────────────────┘  │
│ ┌─ TTS Engine ───────────────────────┐  │
│ │ • Kokoro TTS (Sherpa-ONNX)         │  │
│ │ • Sequential queue (no echo)       │  │
│ │ • TTS-safe text normalization      │  │
│ └────────────────────────────────────┘  │
└──────────────────────────────────────────┘
        ↓ (Data Persistence)
   SQLite Database
   (Conversation History)
┌──────────────────────────────────────────────────────────────────────────────┐
│ Browser (frontend/)                                                          │
│  - voice-carousel-integrated.html                                            │
│  - audio-capture-processor.js                                                │
└──────────────────────────────────┬───────────────────────────────────────────┘
                                   │ WebSocket (binary audio + JSON messages)
                                   ▼
┌──────────────────────────────────────────────────────────────────────────────┐
│ FastAPI Backend (backend/main_agent_web.py)                                  │
│                                                                              │
│  audio bytes                                                                 │
│     ▼                                                                        │
│  [VAD] backend/vad_handler.py                                                │
│     ▼                                                                        │
│  [STT] backend/stt_handler.py  → transcription                               │
│     ▼                                                                        │
│  [Intent] backend/intent_classifier.py → intent + confidence                 │
│     ▼                                                                        │
│  [Context] backend/conversation_manager.py (SQLite + FIFO)                   │
│     ▼                                                                        │
│  [Response]                                                                  │
│     - Fast path: backend/template_responses.py (2,116 templates)             │
│     - Smart path: backend/semantic_rag_handler.py (RAG) + backend/axiom_brain.py (LLM)
│     ▼                                                                        │
│  [TTS] backend/sequential_tts_handler.py + text normalizers                  │
│     ▼                                                                        │
│  audio out → WebSocket → browser playback                                    │
└──────────────────────────────────────────────────────────────────────────────┘
| Component | Purpose | Tech Stack |
|---|---|---|
| VAD Handler | Detect speech segments | Silero VAD |
| STT Handler | Convert audio → text | Sherpa-ONNX |
| Intent Classifier | Detect user intent | SetFit (sentence-transformers) |
| Conversation Manager | Maintain context | SQLite + FIFO |
| Template Responses | Fast replies | 2,116 JSON templates |
| RAG Handler | Search knowledge bases | Sentence-Transformers embeddings |
| LLM Interface | Complex queries | Ollama + local model |
| TTS Handler | Generate speech | Kokoro-EN (Sherpa-ONNX) |
| 3D Mapper | Map keywords → GLB models | Keyword extraction |
| WebSocket Server | Real-time communication | FastAPI + uvicorn |
5m → 5 meters, jetson nano → Jetson Nano**bold**, *italic*, `code` → plain textaxiom-voice-agent/
├── backend/ # FastAPI server + core voice pipeline
│ ├── main_agent_web.py # App entrypoint (WebSocket server)
│ ├── vad_handler.py # Voice activity detection
│ ├── stt_handler.py # Speech-to-text
│ ├── intent_classifier.py # Intent routing
│ ├── semantic_rag_handler.py # RAG + fallback path
│ ├── template_responses.py # 2,116 template responses
│ ├── sequential_tts_handler.py # TTS queue + generation
│ └── ...
├── frontend/ # Web UI
│ ├── voice-carousel-integrated.html
│ └── audio-capture-processor.js
├── data/ # Knowledge bases + templates
│ ├── template_database.json
│ ├── rag_knowledge_base.json
│ ├── project_ideas_rag.json
│ ├── inventory.json
│ └── carousel_mapping.json
├── assets/ # Images, 3D models, benchmarks
│ ├── screenshots/
│ ├── branding/
│ ├── benchmarks/
│ └── 3d v2/
├── benchmarks/ # Benchmark scripts + reports
├── demos/ # Demo logs + recordings
├── docs/ # Architecture + installation docs
├── models/ # Symlink-based model directory
├── scripts/ # Utilities (charts, safetensors tools, etc.)
├── requirements.txt
├── start.sh
└── README.md
If you use AXIOM in research, please cite:
If this project helps you, please star the repo — it helps others find an offline, low-latency voice agent.



