Speech-to-speech AI assistant with natural conversation flow, mid-speech interruption, vision capabilities and AI-initiated follow-ups. Features low-latency audio streaming, dynamic visual feedback, and works with local LLM/TTS services via OpenAI-compatible endpoints.
TypeScript
315
34 commits
updated Apr 14, 2025


A sophisticated AI assistant with speech-to-speech capabilities built on a modern React frontend with a FastAPI backend. Vocalis provides a responsive, low-latency conversational experience with advanced visual feedback.
v1.5.0 (Vision Update) - April 12, 2025
v1.0.0 (Initial Release) - March 31, 2025
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
brew install node
pip install torch
setup.bat to initialise the project (one-time setup)
run.bat to start both frontend and backend serversinstall-deps.batchmod +x *.sh./setup.sh to initialise the project (one-time setup)
./run.sh to start both frontend and backend servers./install-deps.shIf you prefer to set up the project manually, follow these steps:
Create a Python virtual environment:
cd backend
python -m venv env
# Windows:
.\env\Scripts\activate
# macOS/Linux:
source env/bin/activate
Install the Python dependencies:
pip install -r requirements.txt
If you need CUDA support, install PyTorch with CUDA:
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124
Start the backend server:
python -m backend.main
Install Node.js dependencies:
cd frontend
npm install
Start the development server:
npm run dev
After launching Vocalis, you can customise your experience through the sidebar:
The preferences modal offers several ways to tailor Vocalis to your needs:
These settings are saved automatically and persist between sessions, ensuring a consistent experience tailored to your preferences.
Vocalis is designed to work with OpenAI-compatible API endpoints for both LLM and TTS services:
LLM (Language Model): By default, the backend is configured to use LM Studio running locally. This provides a convenient way to run local language models compatible with OpenAI's API format.
Custom Vocalis Model: For optimal performance, Vocalis includes a purpose-built fine-tuned model: lex-au/Vocalis-Q4_K_M.gguf. This model is based on Meta's LLaMA 3 8B Instruct and specifically optimised for immersive conversational experiences with:
Text-to-Speech (TTS): For voice generation, the system works out of the box with:
You can adjust the endpoint in .env to any opensource TTS project. For a lightning-fast alternative:
Both services can be configured in the backend/.env file. The system requires these external services to function properly, as Vocalis acts as an orchestration layer combining speech recognition, language model inference, and speech synthesis.
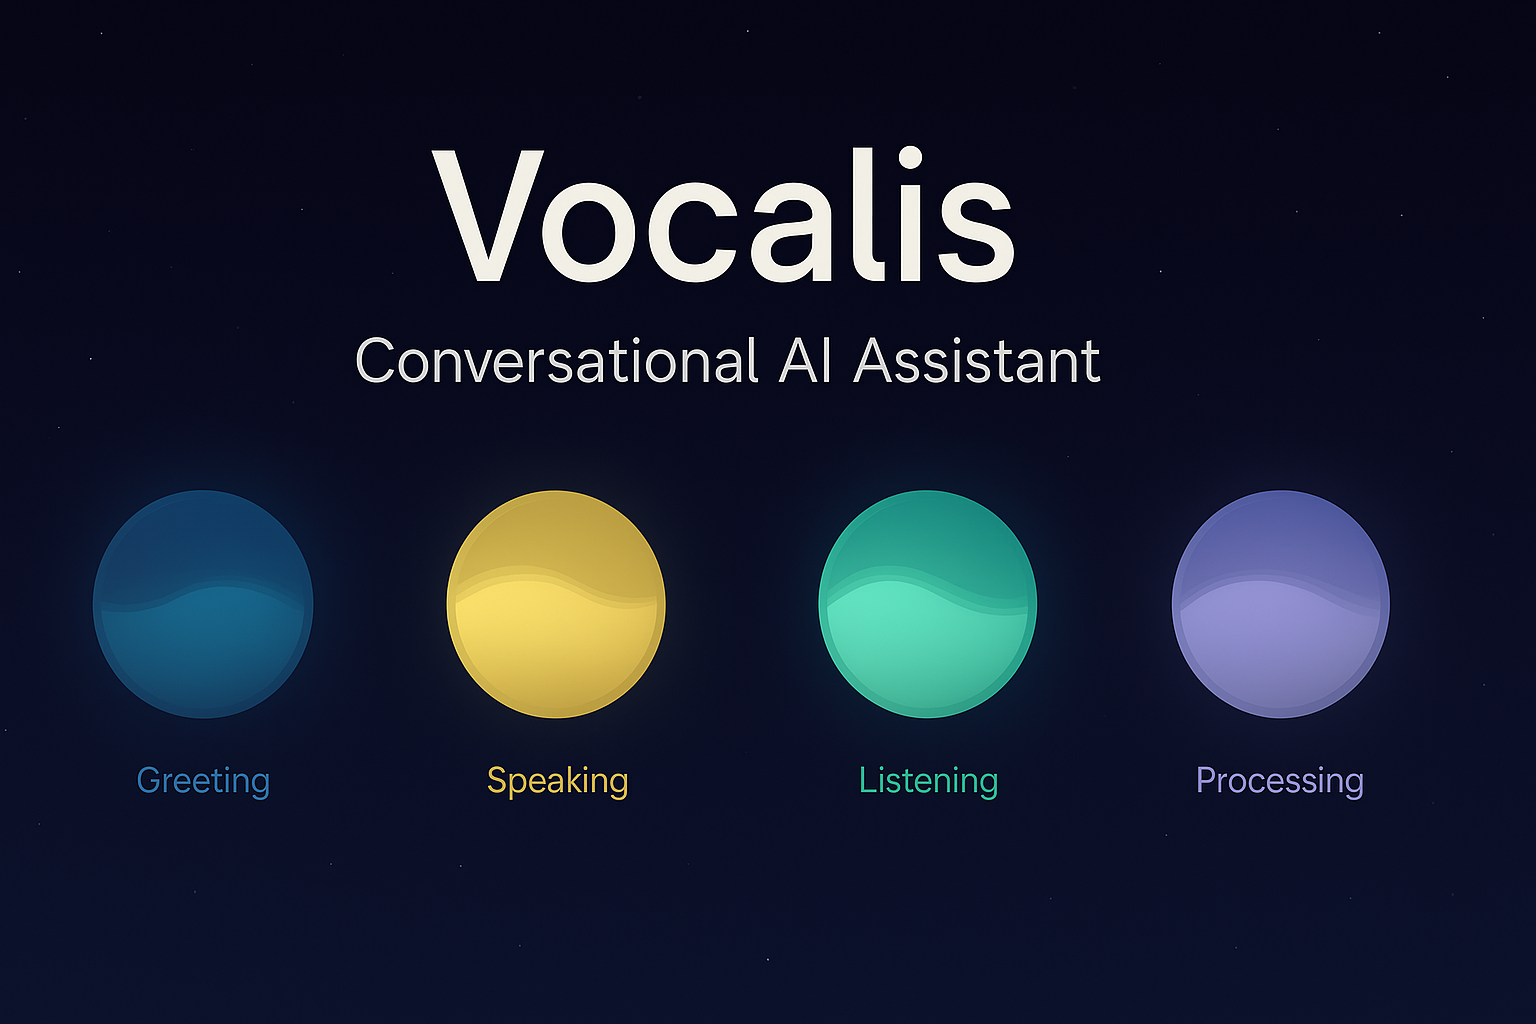
Vocalis includes a robust session management system that allows users to save, load, and organise their conversations:
The session system uses a two-part architecture:
Backend Storage:
Frontend Interface:
This persistent storage system ensures you never lose valuable conversations and can maintain separate contexts for different topics or projects.
graph TB
    subgraph "Frontend (React)"
        AudioCapture[Audio Capture]
        AudioVisualizer[Audio Visualizer]
        WebSocket[WebSocket Client]
        AudioOutput[Audio Output]
        UIState[UI State Management]
        ImageUpload[Image Upload]
        SessionManager[Session Manager]
    end

    subgraph "Backend (FastAPI)"
        WSServer[WebSocket Server]
        VAD[Custom Voice Activity Detection]
        WhisperSTT[Faster Whisper]
        LLMClient[LLM Client]
        TTSClient[TTS Client]
        AudioProcessing[Audio Processing]
        VisionService[SmolVLM Vision Service]
        StorageService[Conversation Storage]
        EnvConfig[Environment Config]
    end

    subgraph "Local API Services"
        LLMEndpoint["LLM API (127.0.0.1:1234)"]
        TTSEndpoint["TTS API (localhost:5005)"]
    end

    subgraph "Storage"
        SessionFiles["Session JSON Files"]
    end

    AudioCapture -->|Audio Stream| WebSocket
    ImageUpload -->|Image Data| WebSocket
    SessionManager -->|Session Commands| WebSocket
    WebSocket <-->|WebSocket Protocol| WSServer
    WSServer --> VAD
    VAD -->|Audio with Speech| WhisperSTT
    WhisperSTT -->|Transcribed Text| LLMClient

    WebSocket -->|Image Data| WSServer
    WSServer -->|Process Image| VisionService
    VisionService -->|Image Description| LLMClient

    WebSocket -->|Session Operations| WSServer
    WSServer -->|Store/Load/List/Delete| StorageService
    StorageService <-->|Read/Write JSON| SessionFiles

    LLMClient -->|API Request| LLMEndpoint
    LLMEndpoint -->|Response Text| LLMClient
    LLMClient -->|Response Text| TTSClient
    TTSClient -->|API Request| TTSEndpoint
    TTSEndpoint -->|Audio Data| TTSClient
    TTSClient --> WSServer
    WSServer -->|Audio Response| WebSocket
    WebSocket --> AudioOutput
    EnvConfig -->|Configuration| WhisperSTT
    EnvConfig -->|Configuration| LLMClient
    EnvConfig -->|Configuration| TTSClient
    EnvConfig -->|Configuration| VisionService
    EnvConfig -->|Configuration| StorageService
    UIState <--> WebSocket
The following diagram provides a comprehensive view of Vocalis's architecture, highlighting the advanced conversation features and interrupt handling systems that enable its natural conversational capabilities:
graph TD
    %% Client Side
    subgraph "Frontend (React + TypeScript + Vite)"
        FE_Audio[Audio Capture/Playback]
        FE_WebSocket[WebSocket Client]
        FE_UI[UI Components]
        FE_State[State Management]
        FE_InterruptDetector[Interrupt Detector]
        FE_SilenceDetector[Silence Detector]
        FE_ImageUpload[Image Upload Handler]
        FE_SessionUI[Session Manager UI]

        subgraph "UI Components"
            UI_Orb[AssistantOrb]
            UI_Stars[BackgroundStars]
            UI_Chat[ChatInterface]
            UI_Prefs[PreferencesModal]
            UI_Sidebar[Sidebar]
            UI_Sessions[SessionManager]
        end

        subgraph "Services"
            FE_AudioService[Audio Service]
            FE_WebSocketService[WebSocket Service]
        end
    end

    %% Server Side
    subgraph "Backend (FastAPI + Python)"
        BE_Main[Main App]
        BE_Config[Configuration]
        BE_WebSocket[WebSocket Handler]
        BE_InterruptHandler[Interrupt Handler]
        BE_ConversationManager[Conversation Manager]

        subgraph "Services"
            BE_Transcription[Speech Transcription & VAD]
            BE_LLM[LLM Client]
            BE_TTS[TTS Client]
            BE_Vision[SmolVLM Vision Service]
            BE_Storage[Conversation Storage]
        end

        subgraph "Conversation Features"
            BE_GreetingSystem[AI Greeting System]
            BE_FollowUpSystem[Follow-Up Generator]
            BE_ContextMemory[Context Memory]
            BE_VisionContext[Image Context Manager]
            BE_SessionMgmt[Session Management]
        end
    end

    %% External Services & Storage
    subgraph "External Services"
        LLM_API[LM Studio OpenAI-compatible API]
        TTS_API[Orpheus-FASTAPI TTS]
    end

    subgraph "Persistent Storage"
        JSON_Files[Session JSON Files]
    end

    %% Data Flow - Main Path
    FE_Audio -->|Audio Stream| FE_AudioService
    FE_AudioService -->|Process Audio| FE_WebSocketService
    FE_WebSocketService -->|Binary Audio Data| FE_WebSocket
    FE_WebSocket <-->|WebSocket Protocol| BE_WebSocket

    BE_WebSocket -->|Audio Chunks| BE_Transcription
    BE_Transcription -->|Voice Activity Detection| BE_Transcription
    BE_Transcription -->|Transcribed Text| BE_ConversationManager
    BE_ConversationManager -->|Format Prompt| BE_LLM
    BE_LLM -->|API Request| LLM_API
    LLM_API -->|Response Text| BE_LLM
    BE_LLM -->|Response Text| BE_TTS
    BE_TTS -->|API Request| TTS_API
    TTS_API -->|Audio Data| BE_TTS
    BE_TTS -->|Processed Audio| BE_WebSocket

    BE_WebSocket -->|Audio Response| FE_WebSocket
    FE_WebSocket -->|Audio Data| FE_AudioService
    FE_AudioService -->|Playback| FE_Audio

    %% Session Management Flow
    FE_SessionUI -->|Save/Load/List/Delete| FE_WebSocketService
    FE_WebSocketService -->|Session Commands| FE_WebSocket
    FE_WebSocket -->|Session Operations| BE_WebSocket
    BE_WebSocket -->|Session Management| BE_SessionMgmt
    BE_SessionMgmt -->|Store/Retrieve| BE_Storage
    BE_Storage <-->|Persist Data| JSON_Files
    BE_Storage -->|Session Response| BE_WebSocket
    BE_WebSocket -->|Session Status| FE_WebSocket
    FE_WebSocket -->|Update UI| FE_SessionUI

    %% Vision Flow
    FE_ImageUpload -->|Image Data| FE_WebSocketService
    FE_WebSocketService -->|Image Base64| FE_WebSocket
    FE_WebSocket -->|Image Data| BE_WebSocket
    BE_WebSocket -->|Process Image| BE_Vision
    BE_Vision -->|Image Description| BE_VisionContext
    BE_VisionContext -->|Augmented Context| BE_ConversationManager

    %% Advanced Feature Paths

    %% 1. Interrupt System
    FE_Audio -->|Voice Activity| FE_InterruptDetector
    FE_InterruptDetector -->|Interrupt Signal| FE_WebSocket
    FE_WebSocket -->|Interrupt Command| BE_WebSocket
    BE_WebSocket -->|Cancel Processing| BE_InterruptHandler
    BE_InterruptHandler -.->|Stop Generation| BE_LLM
    BE_InterruptHandler -.->|Clear Buffer| BE_TTS
    BE_InterruptHandler -.->|Reset State| BE_ConversationManager

    %% 2. AI-Initiated Greetings
    BE_GreetingSystem -->|Initial Greeting| BE_ConversationManager
    BE_ConversationManager -->|Greeting Text| BE_LLM

    %% 3. Silence-based Follow-ups
    FE_SilenceDetector -->|Silence Detected| FE_WebSocket
    FE_WebSocket -->|Silence Notification| BE_WebSocket
    BE_WebSocket -->|Trigger Follow-up| BE_FollowUpSystem
    BE_FollowUpSystem -->|Generate Follow-up| BE_ConversationManager

    %% 4. Context Management
    BE_ConversationManager <-->|Store/Retrieve Context| BE_ContextMemory
    BE_SessionMgmt <-->|Save/Load Messages| BE_ContextMemory

    %% UI Interactions
    FE_State <-->|State Updates| FE_UI
    FE_WebSocketService -->|Connection Status| FE_State
    FE_AudioService -->|Audio Status| FE_State
    FE_InterruptDetector -->|Interrupt Status| FE_State
    FE_ImageUpload -->|Upload Status| FE_State

    %% Configuration
    BE_Config -->|Environment Settings| BE_Main
    BE_Config -->|API Settings| BE_LLM
    BE_Config -->|API Settings| BE_TTS
    BE_Config -->|Model Config| BE_Transcription
    BE_Config -->|Vision Settings| BE_Vision
    BE_Config -->|Storage Settings| BE_Storage
    BE_Config -->|Conversation Settings| BE_GreetingSystem
    BE_Config -->|Follow-up Settings| BE_FollowUpSystem

    %% UI Component Links
    FE_UI -->|Renders| UI_Orb
UI_Orb -->|Visualises States| FE_State
    FE_UI -->|Renders| UI_Stars
    FE_UI -->|Renders| UI_Chat
    UI_Chat -->|Displays Transcript| FE_State
    FE_UI -->|Renders| UI_Prefs
    FE_UI -->|Renders| UI_Sidebar
    FE_UI -->|Renders| UI_Sessions
    UI_Sessions -->|Manages Sessions| FE_SessionUI

    %% Technology Labels
    classDef frontend fill:#61DAFB,color:#000,stroke:#61DAFB
    classDef backend fill:#009688,color:#fff,stroke:#009688
    classDef external fill:#FF9800,color:#000,stroke:#FF9800
    classDef feature fill:#E91E63,color:#fff,stroke:#E91E63
    classDef storage fill:#9C27B0,color:#fff,stroke:#9C27B0

    class FE_Audio,FE_WebSocket,FE_UI,FE_State,FE_AudioService,FE_WebSocketService,UI_Orb,UI_Stars,UI_Chat,UI_Prefs,UI_Sidebar,FE_ImageUpload,FE_SessionUI,UI_Sessions frontend
    class BE_Main,BE_Config,BE_WebSocket,BE_Transcription,BE_LLM,BE_TTS,BE_Vision,BE_Storage backend
    class LLM_API,TTS_API external
    class FE_InterruptDetector,FE_SilenceDetector,BE_InterruptHandler,BE_GreetingSystem,BE_FollowUpSystem,BE_ConversationManager,BE_ContextMemory,BE_VisionContext,BE_SessionMgmt feature
    class JSON_Files storage
For achieving true low-latency in the speech system, we implement streaming TTS with chunked delivery and barge-in capability:
sequenceDiagram
    participant Frontend
    participant AudioBuffer as Frontend Audio Buffer
    participant SilenceDetector as Frontend Silence Detector
    participant InterruptDetector as Frontend Interrupt Detector
    participant SessionMgr as Session Manager
    participant Backend as FastAPI Backend
    participant IntHandler as Backend Interrupt Handler
    participant Transcription as Speech Transcription & VAD
    participant VisionService as Vision Service (SmolVLM)
    participant StorageService as Conversation Storage
    participant LLM as LLM API (LM Studio)
    participant TTS as TTS API (Orpheus-FASTAPI)

    Note over Frontend,TTS: Normal Speech Flow

    Frontend->>Backend: Audio stream (chunks)
    Backend->>Transcription: Process audio
    Transcription->>Transcription: Voice activity detection
    Transcription->>Transcription: Speech-to-text
    Transcription->>Backend: Transcribed text
    Backend->>LLM: Text request with context
    activate LLM
    LLM-->>Backend: Text response (streaming)
    deactivate LLM
    Note over Backend: Begin TTS processing
    Backend->>TTS: Request TTS
    activate TTS

    %% Show parallel processing
    par Streaming audio playback
        TTS-->>Backend: Audio chunk 1
        Backend-->>Frontend: Audio chunk 1
        Frontend->>AudioBuffer: Queue chunk
        AudioBuffer->>Frontend: Begin playback

        TTS-->>Backend: Audio chunk 2
        Backend-->>Frontend: Audio chunk 2
        Frontend->>AudioBuffer: Queue chunk
        AudioBuffer->>Frontend: Continue playback

        TTS-->>Backend: Audio chunk n
        Backend-->>Frontend: Audio chunk n
        Frontend->>AudioBuffer: Queue chunk
        AudioBuffer->>Frontend: Continue playback
    end
    deactivate TTS

    Note over Frontend,TTS: Session Management Flow

    SessionMgr->>Backend: Save current session
    Backend->>StorageService: Store conversation
    StorageService-->>Backend: Session ID
    Backend-->>SessionMgr: Session saved confirmation

    SessionMgr->>Backend: Load specific session
    Backend->>StorageService: Retrieve session data
    StorageService-->>Backend: Conversation history
    Backend->>Backend: Restore conversation context
    Backend-->>SessionMgr: Session loaded confirmation

    Note over Frontend,TTS: Vision Processing Flow

    Frontend->>Backend: Upload image
    Backend->>VisionService: Process image
    activate VisionService
    VisionService-->>Backend: Image description
    deactivate VisionService
    Backend->>Backend: Add to conversation context
    Frontend->>Backend: Audio question about image
    Backend->>Transcription: Process audio
    Transcription->>Backend: Transcribed text
    Backend->>LLM: Text request with image context
    activate LLM
    LLM-->>Backend: Image-informed response
    deactivate LLM
    Backend->>TTS: Request TTS
    activate TTS
    TTS-->>Backend: Audio response
    Backend-->>Frontend: Stream audio response
    deactivate TTS

    Note over Frontend,TTS: Interrupt Flow (Barge-in)

    par Interrupt handling during speech
        Frontend->>InterruptDetector: User begins speaking
        InterruptDetector->>Frontend: Detect interrupt
        Frontend->>Backend: Send interrupt signal
        Backend->>IntHandler: Process interrupt

        IntHandler->>LLM: Cancel generation
        IntHandler->>TTS: Stop audio generation
        IntHandler->>Backend: Clear processing pipeline

        Backend->>Frontend: Stop audio signal
        Frontend->>AudioBuffer: Clear buffer
        AudioBuffer->>Frontend: Stop playback immediately
    end

    Note over Frontend,TTS: Silence Handling (AI Follow-ups)

    par AI-initiated follow-ups
        Frontend->>SilenceDetector: No user speech detected
        SilenceDetector->>Frontend: Silence timeout (3-5s)
        Frontend->>Backend: Silence notification
        Backend->>Backend: Generate follow-up
        Backend->>LLM: Request contextual follow-up
        activate LLM
        LLM-->>Backend: Follow-up response
        deactivate LLM
        Backend->>TTS: Convert to speech
        activate TTS
        TTS-->>Backend: Follow-up audio
        Backend-->>Frontend: Stream follow-up audio
        deactivate TTS
        Frontend->>AudioBuffer: Play follow-up
    end
Vocalis now includes visual understanding capabilities through the SmolVLM-256M-Instruct model:
Image Upload:
Vision Processing:
Contextual Continuation:
Multi-Modal Integration:
Parallel Processing:
Barge-in Capability:
Audio Buffer Management:
Silence Response System:
Backend TTS Integration:
Custom Streaming Implementation:
WebSocket Protocol Enhancement:
audio_chunk: A piece of TTS audio to play immediatelyaudio_start: Signal to prepare audio contextaudio_end: Signal that the complete utterance is finishedFrontend Audio Handling:
Chunk Size Tuning:
Buffer Management:
Format Efficiency:
Abort Capability:
Vocalis achieves exceptional low-latency performance through carefully optimised components:
The system uses Faster-Whisper with the base.en model and a beam size of 2, striking an optimal balance between accuracy and speed. This configuration achieves:
Real-world example from system logs:
INFO:faster_whisper:Processing audio with duration 00:02.229
INFO:backend.services.transcription:Transcription completed in 0.51s: Hi, how are you doing today?...
INFO:backend.services.tts:Sending TTS request with 147 characters of text
INFO:backend.services.tts:Received TTS response after 0.16s, size: 390102 bytes
You can adjust these settings to optimise for your specific needs:
Model Size: In .env, modify WHISPER_MODEL=base.en
Beam Size: In backend/services/transcription.py, modify the beam_size parameter
__init__ method of the WhisperTranscriber class| Model | Beam Size | Approximate ASR Time | Accuracy |
|---|---|---|---|
| tiny.en | 1 | ~0.01s | Lower |
| base.en | 2 | ~0.03s | Good |
| small.en | 3 | ~0.10s | Better |
| medium.en | 4 | ~0.25s | Very Good |
| large | 5 | ~0.50s | Best |
With optimisations in place, Vocalis can achieve total processing latencies well under 250ms when using smaller models, which is typically perceived as "immediate" by users.
Vocalis/
├── README.md
├── setup.bat            # Windows one-time setup script
├── run.bat              # Windows run script
├── install-deps.bat     # Windows dependency update script
├── setup.sh             # Unix one-time setup script
├── run.sh               # Unix run script
├── install-deps.sh      # Unix dependency update script
├── conversations/       # Directory for saved session files
├── backend/
│   ├── .env
│   ├── main.py
│   ├── config.py
│   ├── requirements.txt
│   ├── services/
│   │   ├── __init__.py
│   │   ├── conversation_storage.py
│   │   ├── llm.py
│   │   ├── transcription.py  # Includes VAD functionality
│   │   ├── tts.py
│   │   ├── vision.py
│   ├── routes/
│   │   ├── __init__.py
│   │   ├── websocket.py
├── frontend/
│   ├── public/
│   ├── src/
│   │   ├── components/
│   │   │   ├── AssistantOrb.tsx
│   │   │   ├── BackgroundStars.tsx
│   │   │   ├── ChatInterface.tsx
│   │   │   ├── PreferencesModal.tsx
│   │   │   ├── SessionManager.tsx
│   │   │   ├── Sidebar.tsx
│   │   ├── services/
│   │   │   ├── audio.ts
│   │   │   ├── websocket.ts
│   │   ├── utils/
│   │   │   ├── hooks.ts
│   │   ├── App.tsx
│   │   ├── main.tsx
│   │   ├── index.css
│   │   ├── vite-env.d.ts
│   ├── package.json
│   ├── tsconfig.json
│   ├── tsconfig.node.json
│   ├── vite.config.ts
│   ├── tailwind.config.js
│   ├── postcss.config.js
fastapi==0.109.2
uvicorn==0.27.1
python-dotenv==1.0.1
websockets==12.0
numpy==1.26.4
transformers
faster-whisper==1.1.1
requests==2.31.0
python-multipart==0.0.9
torch==2.0.1
ctranslate2==3.10.0
ffmpeg-python==0.2.0
react
typescript
tailwindcss
lucide-react
websocket
web-audio-api
This project is licensed under the Apache License 2.0 - see the LICENSE file for details.
129 followers · starred Aug 2025
70 followers · starred Aug 2025
35 followers · starred Aug 2025
Speech-to-speech AI assistant with natural conversation flow, mid-speech interruption, vision capabilities and AI-initiated follow-ups. Features low-latency audio streaming, dynamic visual feedback, and works with local LLM/TTS services via OpenAI-compatible endpoints.
TypeScript
315
34 commits
updated Apr 14, 2025
A sophisticated AI assistant with speech-to-speech capabilities built on a modern React frontend with a FastAPI backend. Vocalis provides a responsive, low-latency conversational experience with advanced visual feedback.
v1.5.0 (Vision Update) - April 12, 2025
v1.0.0 (Initial Release) - March 31, 2025
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
brew install node
pip install torch
setup.bat to initialise the project (one-time setup)
run.bat to start both frontend and backend serversinstall-deps.batchmod +x *.sh./setup.sh to initialise the project (one-time setup)
./run.sh to start both frontend and backend servers./install-deps.shIf you prefer to set up the project manually, follow these steps:
Create a Python virtual environment:
cd backend
python -m venv env
# Windows:
.\env\Scripts\activate
# macOS/Linux:
source env/bin/activate
Install the Python dependencies:
pip install -r requirements.txt
If you need CUDA support, install PyTorch with CUDA:
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124
Start the backend server:
python -m backend.main
Install Node.js dependencies:
cd frontend
npm install
Start the development server:
npm run dev
After launching Vocalis, you can customise your experience through the sidebar:
The preferences modal offers several ways to tailor Vocalis to your needs:
These settings are saved automatically and persist between sessions, ensuring a consistent experience tailored to your preferences.
Vocalis is designed to work with OpenAI-compatible API endpoints for both LLM and TTS services:
LLM (Language Model): By default, the backend is configured to use LM Studio running locally. This provides a convenient way to run local language models compatible with OpenAI's API format.
Custom Vocalis Model: For optimal performance, Vocalis includes a purpose-built fine-tuned model: lex-au/Vocalis-Q4_K_M.gguf. This model is based on Meta's LLaMA 3 8B Instruct and specifically optimised for immersive conversational experiences with:
Text-to-Speech (TTS): For voice generation, the system works out of the box with:
You can adjust the endpoint in .env to any opensource TTS project. For a lightning-fast alternative:
Both services can be configured in the backend/.env file. The system requires these external services to function properly, as Vocalis acts as an orchestration layer combining speech recognition, language model inference, and speech synthesis.
Vocalis includes a robust session management system that allows users to save, load, and organise their conversations:
The session system uses a two-part architecture:
Backend Storage:
Frontend Interface:
This persistent storage system ensures you never lose valuable conversations and can maintain separate contexts for different topics or projects.
graph TB
    subgraph "Frontend (React)"
        AudioCapture[Audio Capture]
        AudioVisualizer[Audio Visualizer]
        WebSocket[WebSocket Client]
        AudioOutput[Audio Output]
        UIState[UI State Management]
        ImageUpload[Image Upload]
        SessionManager[Session Manager]
    end

    subgraph "Backend (FastAPI)"
        WSServer[WebSocket Server]
        VAD[Custom Voice Activity Detection]
        WhisperSTT[Faster Whisper]
        LLMClient[LLM Client]
        TTSClient[TTS Client]
        AudioProcessing[Audio Processing]
        VisionService[SmolVLM Vision Service]
        StorageService[Conversation Storage]
        EnvConfig[Environment Config]
    end

    subgraph "Local API Services"
        LLMEndpoint["LLM API (127.0.0.1:1234)"]
        TTSEndpoint["TTS API (localhost:5005)"]
    end

    subgraph "Storage"
        SessionFiles["Session JSON Files"]
    end

    AudioCapture -->|Audio Stream| WebSocket
    ImageUpload -->|Image Data| WebSocket
    SessionManager -->|Session Commands| WebSocket
    WebSocket <-->|WebSocket Protocol| WSServer
    WSServer --> VAD
    VAD -->|Audio with Speech| WhisperSTT
    WhisperSTT -->|Transcribed Text| LLMClient

    WebSocket -->|Image Data| WSServer
    WSServer -->|Process Image| VisionService
    VisionService -->|Image Description| LLMClient

    WebSocket -->|Session Operations| WSServer
    WSServer -->|Store/Load/List/Delete| StorageService
    StorageService <-->|Read/Write JSON| SessionFiles

    LLMClient -->|API Request| LLMEndpoint
    LLMEndpoint -->|Response Text| LLMClient
    LLMClient -->|Response Text| TTSClient
    TTSClient -->|API Request| TTSEndpoint
    TTSEndpoint -->|Audio Data| TTSClient
    TTSClient --> WSServer
    WSServer -->|Audio Response| WebSocket
    WebSocket --> AudioOutput
    EnvConfig -->|Configuration| WhisperSTT
    EnvConfig -->|Configuration| LLMClient
    EnvConfig -->|Configuration| TTSClient
    EnvConfig -->|Configuration| VisionService
    EnvConfig -->|Configuration| StorageService
    UIState <--> WebSocket
The following diagram provides a comprehensive view of Vocalis's architecture, highlighting the advanced conversation features and interrupt handling systems that enable its natural conversational capabilities:
graph TD
    %% Client Side
    subgraph "Frontend (React + TypeScript + Vite)"
        FE_Audio[Audio Capture/Playback]
        FE_WebSocket[WebSocket Client]
        FE_UI[UI Components]
        FE_State[State Management]
        FE_InterruptDetector[Interrupt Detector]
        FE_SilenceDetector[Silence Detector]
        FE_ImageUpload[Image Upload Handler]
        FE_SessionUI[Session Manager UI]

        subgraph "UI Components"
            UI_Orb[AssistantOrb]
            UI_Stars[BackgroundStars]
            UI_Chat[ChatInterface]
            UI_Prefs[PreferencesModal]
            UI_Sidebar[Sidebar]
            UI_Sessions[SessionManager]
        end

        subgraph "Services"
            FE_AudioService[Audio Service]
            FE_WebSocketService[WebSocket Service]
        end
    end

    %% Server Side
    subgraph "Backend (FastAPI + Python)"
        BE_Main[Main App]
        BE_Config[Configuration]
        BE_WebSocket[WebSocket Handler]
        BE_InterruptHandler[Interrupt Handler]
        BE_ConversationManager[Conversation Manager]

        subgraph "Services"
            BE_Transcription[Speech Transcription & VAD]
            BE_LLM[LLM Client]
            BE_TTS[TTS Client]
            BE_Vision[SmolVLM Vision Service]
            BE_Storage[Conversation Storage]
        end

        subgraph "Conversation Features"
            BE_GreetingSystem[AI Greeting System]
            BE_FollowUpSystem[Follow-Up Generator]
            BE_ContextMemory[Context Memory]
            BE_VisionContext[Image Context Manager]
            BE_SessionMgmt[Session Management]
        end
    end

    %% External Services & Storage
    subgraph "External Services"
        LLM_API[LM Studio OpenAI-compatible API]
        TTS_API[Orpheus-FASTAPI TTS]
    end

    subgraph "Persistent Storage"
        JSON_Files[Session JSON Files]
    end

    %% Data Flow - Main Path
    FE_Audio -->|Audio Stream| FE_AudioService
    FE_AudioService -->|Process Audio| FE_WebSocketService
    FE_WebSocketService -->|Binary Audio Data| FE_WebSocket
    FE_WebSocket <-->|WebSocket Protocol| BE_WebSocket

    BE_WebSocket -->|Audio Chunks| BE_Transcription
    BE_Transcription -->|Voice Activity Detection| BE_Transcription
    BE_Transcription -->|Transcribed Text| BE_ConversationManager
    BE_ConversationManager -->|Format Prompt| BE_LLM
    BE_LLM -->|API Request| LLM_API
    LLM_API -->|Response Text| BE_LLM
    BE_LLM -->|Response Text| BE_TTS
    BE_TTS -->|API Request| TTS_API
    TTS_API -->|Audio Data| BE_TTS
    BE_TTS -->|Processed Audio| BE_WebSocket

    BE_WebSocket -->|Audio Response| FE_WebSocket
    FE_WebSocket -->|Audio Data| FE_AudioService
    FE_AudioService -->|Playback| FE_Audio

    %% Session Management Flow
    FE_SessionUI -->|Save/Load/List/Delete| FE_WebSocketService
    FE_WebSocketService -->|Session Commands| FE_WebSocket
    FE_WebSocket -->|Session Operations| BE_WebSocket
    BE_WebSocket -->|Session Management| BE_SessionMgmt
    BE_SessionMgmt -->|Store/Retrieve| BE_Storage
    BE_Storage <-->|Persist Data| JSON_Files
    BE_Storage -->|Session Response| BE_WebSocket
    BE_WebSocket -->|Session Status| FE_WebSocket
    FE_WebSocket -->|Update UI| FE_SessionUI

    %% Vision Flow
    FE_ImageUpload -->|Image Data| FE_WebSocketService
    FE_WebSocketService -->|Image Base64| FE_WebSocket
    FE_WebSocket -->|Image Data| BE_WebSocket
    BE_WebSocket -->|Process Image| BE_Vision
    BE_Vision -->|Image Description| BE_VisionContext
    BE_VisionContext -->|Augmented Context| BE_ConversationManager

    %% Advanced Feature Paths

    %% 1. Interrupt System
    FE_Audio -->|Voice Activity| FE_InterruptDetector
    FE_InterruptDetector -->|Interrupt Signal| FE_WebSocket
    FE_WebSocket -->|Interrupt Command| BE_WebSocket
    BE_WebSocket -->|Cancel Processing| BE_InterruptHandler
    BE_InterruptHandler -.->|Stop Generation| BE_LLM
    BE_InterruptHandler -.->|Clear Buffer| BE_TTS
    BE_InterruptHandler -.->|Reset State| BE_ConversationManager

    %% 2. AI-Initiated Greetings
    BE_GreetingSystem -->|Initial Greeting| BE_ConversationManager
    BE_ConversationManager -->|Greeting Text| BE_LLM

    %% 3. Silence-based Follow-ups
    FE_SilenceDetector -->|Silence Detected| FE_WebSocket
    FE_WebSocket -->|Silence Notification| BE_WebSocket
    BE_WebSocket -->|Trigger Follow-up| BE_FollowUpSystem
    BE_FollowUpSystem -->|Generate Follow-up| BE_ConversationManager

    %% 4. Context Management
    BE_ConversationManager <-->|Store/Retrieve Context| BE_ContextMemory
    BE_SessionMgmt <-->|Save/Load Messages| BE_ContextMemory

    %% UI Interactions
    FE_State <-->|State Updates| FE_UI
    FE_WebSocketService -->|Connection Status| FE_State
    FE_AudioService -->|Audio Status| FE_State
    FE_InterruptDetector -->|Interrupt Status| FE_State
    FE_ImageUpload -->|Upload Status| FE_State

    %% Configuration
    BE_Config -->|Environment Settings| BE_Main
    BE_Config -->|API Settings| BE_LLM
    BE_Config -->|API Settings| BE_TTS
    BE_Config -->|Model Config| BE_Transcription
    BE_Config -->|Vision Settings| BE_Vision
    BE_Config -->|Storage Settings| BE_Storage
    BE_Config -->|Conversation Settings| BE_GreetingSystem
    BE_Config -->|Follow-up Settings| BE_FollowUpSystem

    %% UI Component Links
    FE_UI -->|Renders| UI_Orb
UI_Orb -->|Visualises States| FE_State
    FE_UI -->|Renders| UI_Stars
    FE_UI -->|Renders| UI_Chat
    UI_Chat -->|Displays Transcript| FE_State
    FE_UI -->|Renders| UI_Prefs
    FE_UI -->|Renders| UI_Sidebar
    FE_UI -->|Renders| UI_Sessions
    UI_Sessions -->|Manages Sessions| FE_SessionUI

    %% Technology Labels
    classDef frontend fill:#61DAFB,color:#000,stroke:#61DAFB
    classDef backend fill:#009688,color:#fff,stroke:#009688
    classDef external fill:#FF9800,color:#000,stroke:#FF9800
    classDef feature fill:#E91E63,color:#fff,stroke:#E91E63
    classDef storage fill:#9C27B0,color:#fff,stroke:#9C27B0

    class FE_Audio,FE_WebSocket,FE_UI,FE_State,FE_AudioService,FE_WebSocketService,UI_Orb,UI_Stars,UI_Chat,UI_Prefs,UI_Sidebar,FE_ImageUpload,FE_SessionUI,UI_Sessions frontend
    class BE_Main,BE_Config,BE_WebSocket,BE_Transcription,BE_LLM,BE_TTS,BE_Vision,BE_Storage backend
    class LLM_API,TTS_API external
    class FE_InterruptDetector,FE_SilenceDetector,BE_InterruptHandler,BE_GreetingSystem,BE_FollowUpSystem,BE_ConversationManager,BE_ContextMemory,BE_VisionContext,BE_SessionMgmt feature
    class JSON_Files storage
For achieving true low-latency in the speech system, we implement streaming TTS with chunked delivery and barge-in capability:
sequenceDiagram
    participant Frontend
    participant AudioBuffer as Frontend Audio Buffer
    participant SilenceDetector as Frontend Silence Detector
    participant InterruptDetector as Frontend Interrupt Detector
    participant SessionMgr as Session Manager
    participant Backend as FastAPI Backend
    participant IntHandler as Backend Interrupt Handler
    participant Transcription as Speech Transcription & VAD
    participant VisionService as Vision Service (SmolVLM)
    participant StorageService as Conversation Storage
    participant LLM as LLM API (LM Studio)
    participant TTS as TTS API (Orpheus-FASTAPI)

    Note over Frontend,TTS: Normal Speech Flow

    Frontend->>Backend: Audio stream (chunks)
    Backend->>Transcription: Process audio
    Transcription->>Transcription: Voice activity detection
    Transcription->>Transcription: Speech-to-text
    Transcription->>Backend: Transcribed text
    Backend->>LLM: Text request with context
    activate LLM
    LLM-->>Backend: Text response (streaming)
    deactivate LLM
    Note over Backend: Begin TTS processing
    Backend->>TTS: Request TTS
    activate TTS

    %% Show parallel processing
    par Streaming audio playback
        TTS-->>Backend: Audio chunk 1
        Backend-->>Frontend: Audio chunk 1
        Frontend->>AudioBuffer: Queue chunk
        AudioBuffer->>Frontend: Begin playback

        TTS-->>Backend: Audio chunk 2
        Backend-->>Frontend: Audio chunk 2
        Frontend->>AudioBuffer: Queue chunk
        AudioBuffer->>Frontend: Continue playback

        TTS-->>Backend: Audio chunk n
        Backend-->>Frontend: Audio chunk n
        Frontend->>AudioBuffer: Queue chunk
        AudioBuffer->>Frontend: Continue playback
    end
    deactivate TTS

    Note over Frontend,TTS: Session Management Flow

    SessionMgr->>Backend: Save current session
    Backend->>StorageService: Store conversation
    StorageService-->>Backend: Session ID
    Backend-->>SessionMgr: Session saved confirmation

    SessionMgr->>Backend: Load specific session
    Backend->>StorageService: Retrieve session data
    StorageService-->>Backend: Conversation history
    Backend->>Backend: Restore conversation context
    Backend-->>SessionMgr: Session loaded confirmation

    Note over Frontend,TTS: Vision Processing Flow

    Frontend->>Backend: Upload image
    Backend->>VisionService: Process image
    activate VisionService
    VisionService-->>Backend: Image description
    deactivate VisionService
    Backend->>Backend: Add to conversation context
    Frontend->>Backend: Audio question about image
    Backend->>Transcription: Process audio
    Transcription->>Backend: Transcribed text
    Backend->>LLM: Text request with image context
    activate LLM
    LLM-->>Backend: Image-informed response
    deactivate LLM
    Backend->>TTS: Request TTS
    activate TTS
    TTS-->>Backend: Audio response
    Backend-->>Frontend: Stream audio response
    deactivate TTS

    Note over Frontend,TTS: Interrupt Flow (Barge-in)

    par Interrupt handling during speech
        Frontend->>InterruptDetector: User begins speaking
        InterruptDetector->>Frontend: Detect interrupt
        Frontend->>Backend: Send interrupt signal
        Backend->>IntHandler: Process interrupt

        IntHandler->>LLM: Cancel generation
        IntHandler->>TTS: Stop audio generation
        IntHandler->>Backend: Clear processing pipeline

        Backend->>Frontend: Stop audio signal
        Frontend->>AudioBuffer: Clear buffer
        AudioBuffer->>Frontend: Stop playback immediately
    end

    Note over Frontend,TTS: Silence Handling (AI Follow-ups)

    par AI-initiated follow-ups
        Frontend->>SilenceDetector: No user speech detected
        SilenceDetector->>Frontend: Silence timeout (3-5s)
        Frontend->>Backend: Silence notification
        Backend->>Backend: Generate follow-up
        Backend->>LLM: Request contextual follow-up
        activate LLM
        LLM-->>Backend: Follow-up response
        deactivate LLM
        Backend->>TTS: Convert to speech
        activate TTS
        TTS-->>Backend: Follow-up audio
        Backend-->>Frontend: Stream follow-up audio
        deactivate TTS
        Frontend->>AudioBuffer: Play follow-up
    end
Vocalis now includes visual understanding capabilities through the SmolVLM-256M-Instruct model:
Image Upload:
Vision Processing:
Contextual Continuation:
Multi-Modal Integration:
Parallel Processing:
Barge-in Capability:
Audio Buffer Management:
Silence Response System:
Backend TTS Integration:
Custom Streaming Implementation:
WebSocket Protocol Enhancement:
audio_chunk: A piece of TTS audio to play immediatelyaudio_start: Signal to prepare audio contextaudio_end: Signal that the complete utterance is finishedFrontend Audio Handling:
Chunk Size Tuning:
Buffer Management:
Format Efficiency:
Abort Capability:
Vocalis achieves exceptional low-latency performance through carefully optimised components:
The system uses Faster-Whisper with the base.en model and a beam size of 2, striking an optimal balance between accuracy and speed. This configuration achieves:
Real-world example from system logs:
INFO:faster_whisper:Processing audio with duration 00:02.229
INFO:backend.services.transcription:Transcription completed in 0.51s: Hi, how are you doing today?...
INFO:backend.services.tts:Sending TTS request with 147 characters of text
INFO:backend.services.tts:Received TTS response after 0.16s, size: 390102 bytes
You can adjust these settings to optimise for your specific needs:
Model Size: In .env, modify WHISPER_MODEL=base.en
Beam Size: In backend/services/transcription.py, modify the beam_size parameter
__init__ method of the WhisperTranscriber class| Model | Beam Size | Approximate ASR Time | Accuracy |
|---|---|---|---|
| tiny.en | 1 | ~0.01s | Lower |
| base.en | 2 | ~0.03s | Good |
| small.en | 3 | ~0.10s | Better |
| medium.en | 4 | ~0.25s | Very Good |
| large | 5 | ~0.50s | Best |
With optimisations in place, Vocalis can achieve total processing latencies well under 250ms when using smaller models, which is typically perceived as "immediate" by users.
Vocalis/
├── README.md
├── setup.bat            # Windows one-time setup script
├── run.bat              # Windows run script
├── install-deps.bat     # Windows dependency update script
├── setup.sh             # Unix one-time setup script
├── run.sh               # Unix run script
├── install-deps.sh      # Unix dependency update script
├── conversations/       # Directory for saved session files
├── backend/
│   ├── .env
│   ├── main.py
│   ├── config.py
│   ├── requirements.txt
│   ├── services/
│   │   ├── __init__.py
│   │   ├── conversation_storage.py
│   │   ├── llm.py
│   │   ├── transcription.py  # Includes VAD functionality
│   │   ├── tts.py
│   │   ├── vision.py
│   ├── routes/
│   │   ├── __init__.py
│   │   ├── websocket.py
├── frontend/
│   ├── public/
│   ├── src/
│   │   ├── components/
│   │   │   ├── AssistantOrb.tsx
│   │   │   ├── BackgroundStars.tsx
│   │   │   ├── ChatInterface.tsx
│   │   │   ├── PreferencesModal.tsx
│   │   │   ├── SessionManager.tsx
│   │   │   ├── Sidebar.tsx
│   │   ├── services/
│   │   │   ├── audio.ts
│   │   │   ├── websocket.ts
│   │   ├── utils/
│   │   │   ├── hooks.ts
│   │   ├── App.tsx
│   │   ├── main.tsx
│   │   ├── index.css
│   │   ├── vite-env.d.ts
│   ├── package.json
│   ├── tsconfig.json
│   ├── tsconfig.node.json
│   ├── vite.config.ts
│   ├── tailwind.config.js
│   ├── postcss.config.js
fastapi==0.109.2
uvicorn==0.27.1
python-dotenv==1.0.1
websockets==12.0
numpy==1.26.4
transformers
faster-whisper==1.1.1
requests==2.31.0
python-multipart==0.0.9
torch==2.0.1
ctranslate2==3.10.0
ffmpeg-python==0.2.0
react
typescript
tailwindcss
lucide-react
websocket
web-audio-api
This project is licensed under the Apache License 2.0 - see the LICENSE file for details.
129 followers · starred Aug 2025
70 followers · starred Aug 2025
35 followers · starred Aug 2025