
Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures
35
13 commits
updated Jan 29, 2026
README
Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures


🚀 News
- [2026.1.29] Our survey is now available at: https://arxiv.org/abs/2601.19928
- [2026.1.11] 🔥 We are excited to release our survey on LRM mechanistic studies in this repo.
📌 Overview
Our paper provides a comprehensive survey of the mechanistic understanding of LRMs.
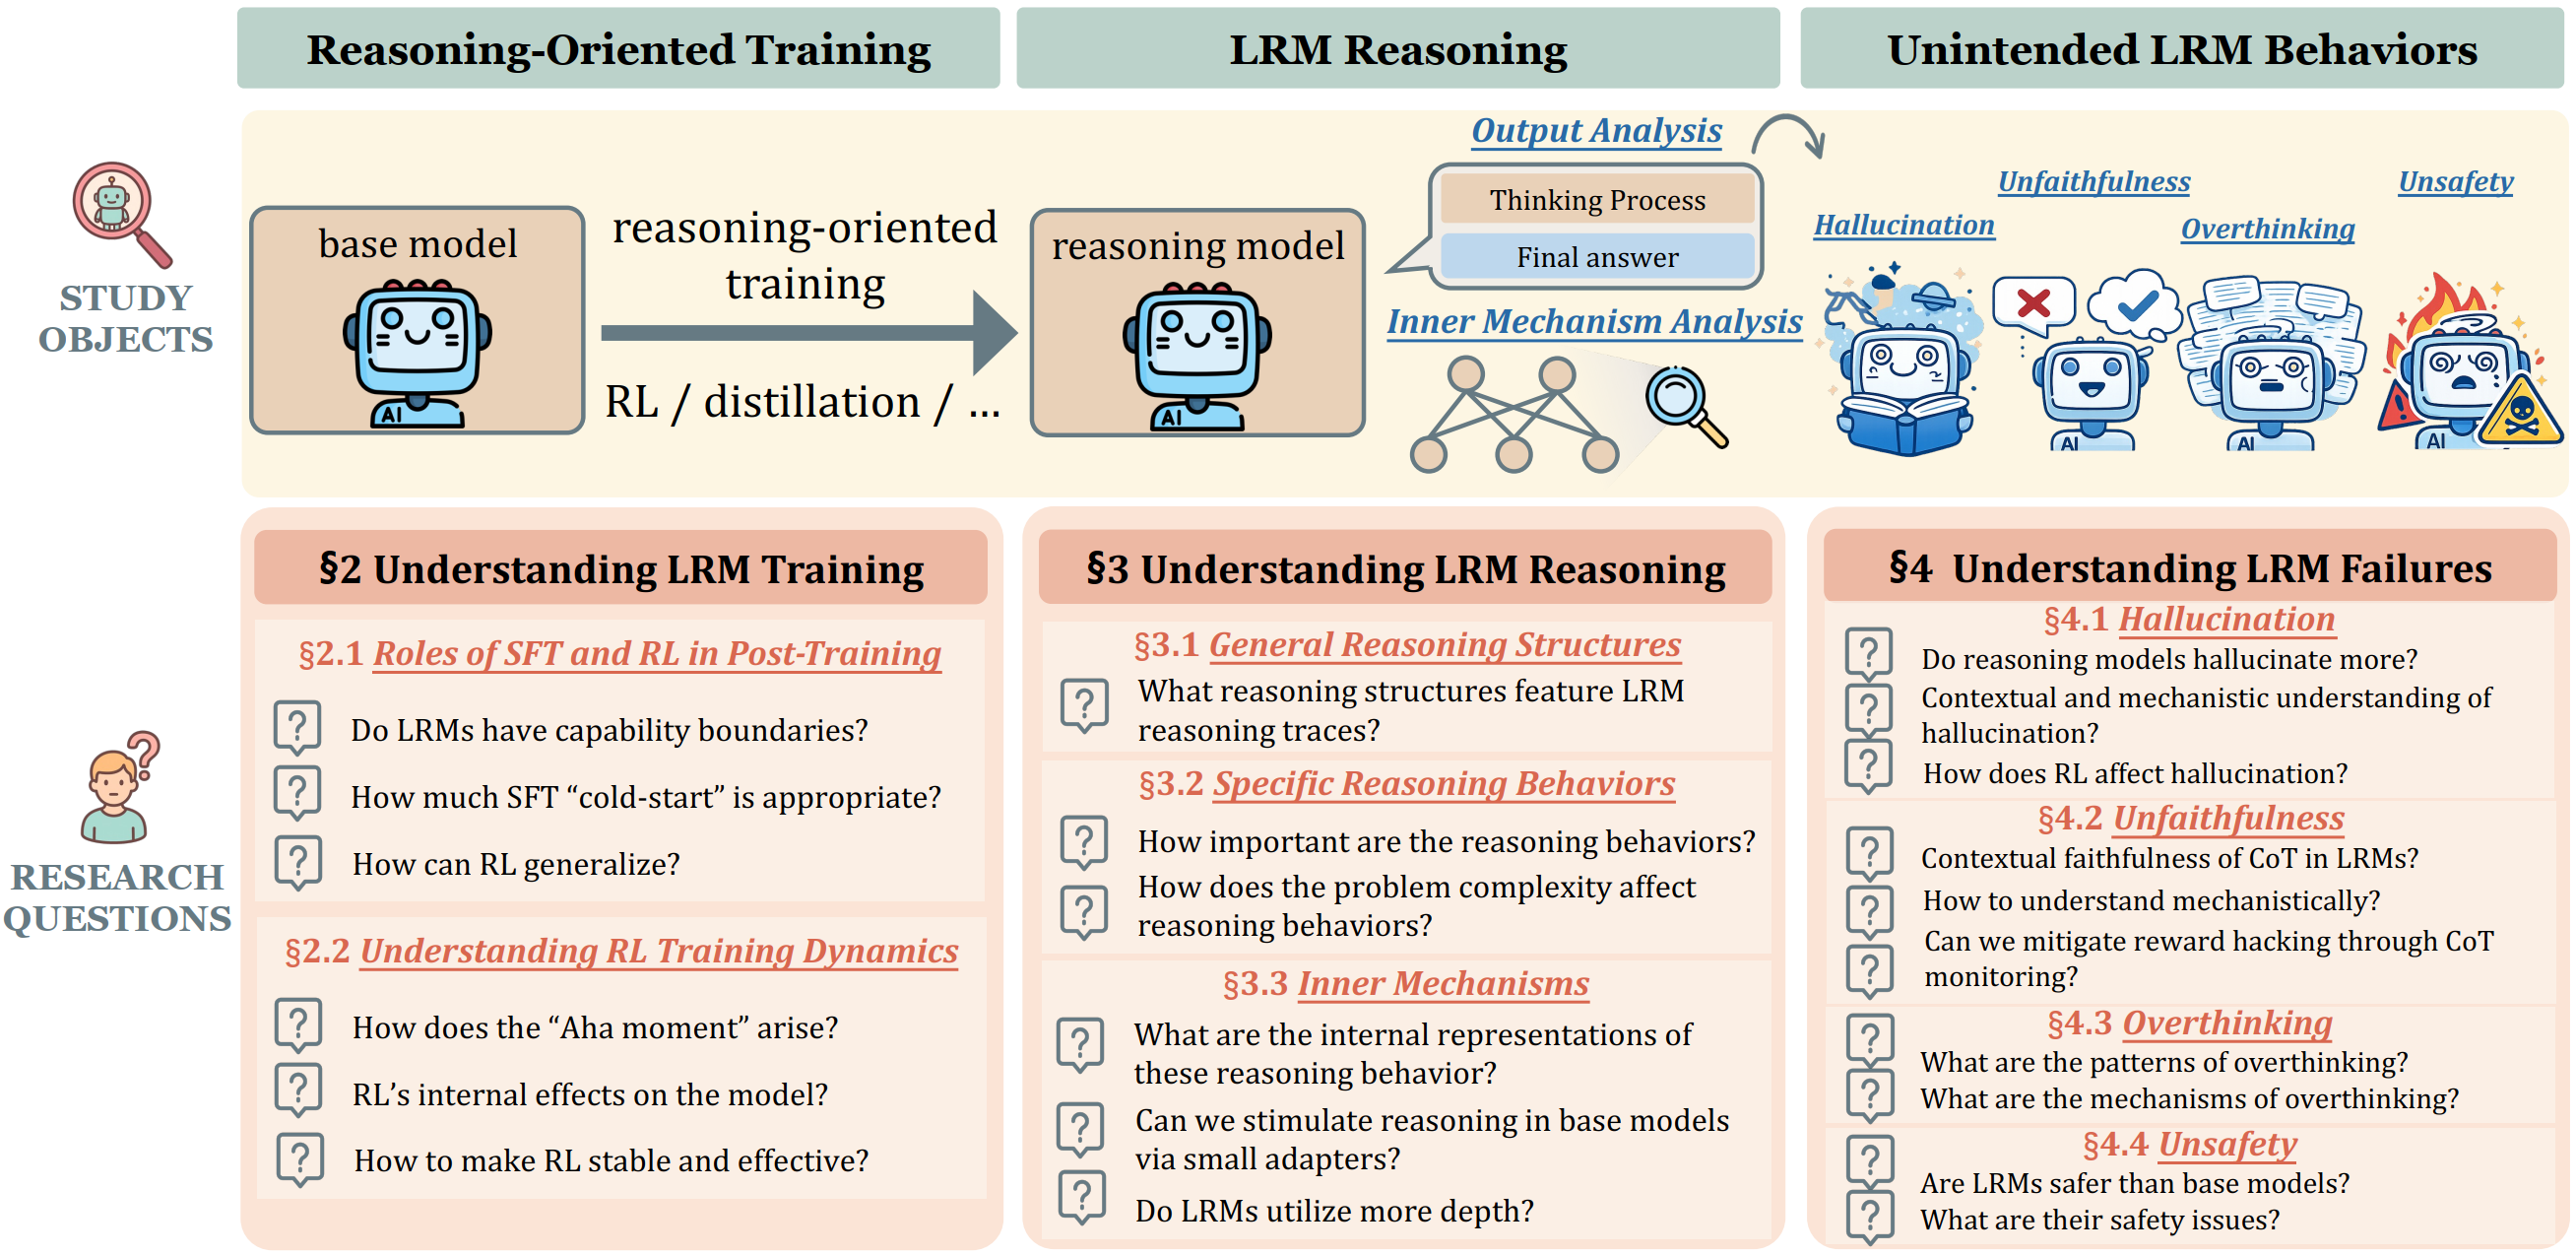
We organize recent findings into three core dimensions:
- Training Dynamics:
- Roles of SFT and RL in Post-Training
- Understanding RL Training Dynamics
- Reasoning Mechanisms:
- General Reasoning Structures
- Specific Reasoning Behaviors
- Internal Mechanisms
- Unintended Behaviors:
- Hallucination
- Unfaithfulness
- Overthinking
- Unsafety
🔗 Citation
If you find our survey helpful, please consider citing our paper:
@misc{hu2026mechanisticunderstandinglargereasoning,
      title={Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures},
      author={Yi Hu and Jiaqi Gu and Ruxin Wang and Zijun Yao and Hao Peng and Xiaobao Wu and Jianhui Chen and Muhan Zhang and Liangming Pan},
      year={2026},
      eprint={2601.19928},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.19928},
}
🗂️ Contents
- Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures
📄 Paper List
Training Dynamics
Roles of SFT and RL in Post-Training
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-01 | Deepseek-R1 | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning |  |  |
| 2025-04 | limit of RLVR | Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model? | |  |
| 2025-09 | RL Squeezes, SFT Expands | RL Squeezes, SFT Expands: A Comparative Study of Reasoning LLMs | | - |
| 2025-07 | Invisible Leash | The Invisible Leash: Why RLVR May or May Not Escape Its Origin | | - |
| 2025-09 | Representation Geometry of LLM | Tracing the Representation Geometry of Language Models from Pretraining to Post-training | | - |
| 2025-05 | Entropy Mechanism of RL | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | |  |
| 2025-09 | Emergent Attention Heads | Thinking Sparks!: Emergent Attention Heads in Reasoning Models During Post Training | | - |
| 2025-01 | SFT Memorizes, RL Generalizes | SFT Memorizes, RL Generalizes: A Comparative Study of Foundation Model Post-training | |  |
| 2025-09 | CoNet | How LLMs Learn to Reason: A Complex Network Perspective | | - |
| 2025-08 | RL Is Neither a Panacea Nor a Mirage | RL Is Neither a Panacea Nor a Mirage: Understanding Supervised vs. Reinforcement Learning Fine-Tuning for LLMs | | - |
| 2025-09 | RL Heals OOD Forgetting | RL Fine-Tuning Heals OOD Forgetting in SFT | |  |
| 2025-05 | ProRL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | |  |
| 2025-09 | From f(x) and g(x) to f(g(x)) | From f(x) and g(x) to f(g(x)): LLMs Learn New Skills in RL by Composing Old Ones | | - |
| 2025-12 | From Atomic to Composite | From Atomic to Composite: Reinforcement Learning Enables Generalization in Complementary Reasoning | |  |
| 2025-06 | OctoThinker | OctoThinker: Mid-training Incentivizes Reinforcement Learning Scaling | |  |
| 2025-12 | Interplay LM Reasoning | On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models | |  |
Understanding RL Training Dynamics
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | HICRA | Emergent Hierarchical Reasoning in LLMs through Reinforcement Learning | |  |
| 2025-09 | CoNet | How LLMs Learn to Reason: A Complex Network Perspective | | - |
| 2025-10 | Two-Stage Dynamic | The Debate on RLVR Reasoning Capability Boundary: Shrinkage, Expansion, or Both? A Two-Stage Dynamic View | | - |
| 2025-09 | RL Enhances Activation | Reinforcement Learning Fine-Tuning Enhances Activation Intensity and Diversity in the Internal Circuitry of LLMs | |  |
| 2025-09 | Post-Training Structural Changes | Understanding Post-Training Structural Changes in Large Language Models | | - |
| 2025-10 | AlphaRL | On Predictability of Reinforcement Learning Dynamics for Large Language Models | |  |
| 2025-05 | Entropy Mechanism of RL | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-10 | Reasoning Boundary Paradox | The Reasoning Boundary Paradox: How Reinforcement Learning Constrains Language Models | |  |
| 2025-09 | VERL | Beyond the Exploration-Exploitation Trade-off: A Hidden State Approach for LLM Reasoning in RLVR | |  |
Reasoning Mechanisms
General Reasoning Structures
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-04 | DeepSeek-R1 Thoughtology | DeepSeek-R1 Thoughtology: Let's think about LLM Reasoning | | - |
| 2025-06 | Functional Blocks | Beyond Accuracy: Dissecting Mathematical Reasoning for LLMs Under Reinforcement Learning | |  |
| 2025-06 | Thought Anchors | Thought Anchors: Which LLM Reasoning Steps Matter? | |  |
| 2025-09 | Schoenfeld's Episode Theory | Understanding the Thinking Process of Reasoning Models: A Perspective from Schoenfeld's Episode Theory | |  |
| 2025-11 | ReJump | ReJump: A Tree-Jump Representation for Analyzing and Improving LLM Reasoning | |  |
| 2025-05 | Structural Patterns | What Makes a Good Reasoning Chain? Uncovering Structural Patterns in Long Chain-of-Thought Reasoning | | - |
| 2025-06 | Topology of Reasoning | Topology of Reasoning: Understanding Large Reasoning Models through Reasoning Graph Properties | |  |
| 2025-05 | Mapping the Minds of LLMs | Mapping the Minds of LLMs: A Graph-Based Analysis of Reasoning LLM | |  |
Specific Reasoning Behaviors
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | Thought Anchors | Thought Anchors: Which LLM Reasoning Steps Matter? | | |
| 2025-05 | Thought Anchors | Cognitive Behaviors that Enable Self-Improving Reasoners, or, Four Habits of Highly Effective STaRs | |  |
| 2025-04 | Understanding Aha Moments | Understanding Aha Moments: from External Observations to Internal Mechanisms | | - |
| 2025-02 | May Not Aha Moment | There may not be aha moment in r1-zero-like training - a pilot study | |  |
| 2025-10 | First Try Matters | First Try Matters: Revisiting the Role of Reflection in Reasoning Models | |  |
| 2025-06 | The Illusion of Thinking | The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity | | - |
| 2025-9 | Performative Thinking | Performative Thinking? The Brittle Correlation Between CoT Length and Problem Complexity | | - |
Internal Mechanisms
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | Towards Understanding Distilled Reasoning Models | Towards Understanding Distilled Reasoning Models: A Representational Approach | |  |
| 2025-05 | Sparse Autoencoders | I Have Covered All the Bases Here: Interpreting Reasoning Features in Large Language Models via Sparse Autoencoders | |  |
| 2025-04 | Hood of a Reasoning Model | Under the Hood of a Reasoning Model | | - |
| 2025-06 | Steering Vectors | Understanding Reasoning in Thinking Language Models via Steering Vectors | |  |
| 2025-10 | Thinking Models Learn When To Reason | Base Models Know How to Reason, Thinking Models Learn When | |  |
| 2025-06 | Thought Anchors | Thought Anchors: Which LLM Reasoning Steps Matter? | | |
| 2025-09 | From Reasoning to Answer | From Reasoning to Answer: Empirical, Attention-Based and Mechanistic Insights into Distilled DeepSeek R1 Models | |  |
| 2025-04 | Understanding Aha Moments | Understanding Aha Moments: from External Observations to Internal Mechanisms | | - |
| 2025-12 | ReflCtrl | ReflCtrl: Controlling LLM Reflection via Representation Engineering | |  |
| 2025-08 | Latent Directions of Reflection | Unveiling the Latent Directions of Reflection in Large Language Models | |  |
| 2025-07 | Reasoning-Finetuning Repurposes Latent Representations | Reasoning-Finetuning Repurposes Latent Representations in Base Models | |  |
| 2025-05 | Bias-Only Adaptation | Steering LLM Reasoning Through Bias-Only Adaptation | |  |
| 2025-11 | Rank-1 LoRAs | Rank-1 LoRAs Encode Interpretable Reasoning Signals | |  |
| 2025-06 | Layer Importance | Layer Importance for Mathematical Reasoning is Forged in Pre-Training and Invariant after Post-Training | |  |
| 2025-12 | Effective Depth | What Affects the Effective Depth of Large Language Models? | |  |
| 2025-12 | Internal Policy | Bottom-up Policy Optimization: Your Language Model Policy Secretly Contains Internal Policies | |  |
| 2025-06 | The Emergence of Mutual Information (MI) Peaks | Demystifying Reasoning Dynamics with Mutual Information: Thinking Tokens are Information Peaks in LLM Reasoning | |  |
Unintended Behaviors
Hallucination
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | FactEval | Are Reasoning Models More Prone to Hallucination? | |  |
| 2025-05 | FSPO | Reasoning Models Hallucinate More: Factuality-Aware Reinforcement Learning for Large Reasoning Models | |  |
| 2025-05 | RDH | Detection and Mitigation of Hallucination in Large Reasoning Models: A Mechanistic Perspective | |  |
| 2025-05 | Hallucination Tax | The Hallucination Tax of Reinforcement Finetuning | |  |
| 2025-09 | TTS_knowledge | Test-Time Scaling in Reasoning Models Is Not Effective for Knowledge-Intensive Tasks Yet | |  |
| 2025-05 | Meta-Cognitive | Auditing Meta-Cognitive Hallucinations in Reasoning Large Language Models | |  |
| 2025-06 | RACE | Joint Evaluation of Answer and Reasoning Consistency for Hallucination Detection in Large Reasoning Models | |  |
Unfaithfulness
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | FactEval | Are Reasoning Models More Prone to Hallucination? | | |
| 2025-01 | Cue Insertion | Are DeepSeek R1 And Other Reasoning Models More Faithful? | | - |
| 2025-05 | Don't Say What They Think | Reasoning Models Don't Always Say What They Think | | - |
| 2025-03 | Unfaithful CoT | Chain-of-Thought Reasoning In The Wild Is Not Always Faithful | |  |
| 2025-06 | Strategic Deception | When Thinking LLMs Lie: Unveiling the Strategic Deception in Representations of Reasoning Models | |  |
| 2025-05 | Reasoning Intermediate Token | Beyond Semantics: The Unreasonable Effectiveness of Reasonless Intermediate Tokens | | - |
| 2025-07 | Alignment Prediction | Can We Predict Alignment Before Models Finish Thinking? Towards Monitoring Misaligned Reasoning Models | |  |
| 2025-10 | Refusal Cliff | Refusal Falls off a Cliff: How Safety Alignment Fails in Reasoning? | | - |
| 2025-03 | CoT Monitor | Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation | | - |
| 2025-06 | VFT | Teaching Models to Verbalize Reward Hacking in Chain-of-Thought Reasoning | | - |
Overthinking
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | R1 Thoughtology | DeepSeek-R1 Thoughtology: Let’s think about LLM reasoning | |  |
| 2025-05 | Between Underthinking and Overthinking | Between Underthinking and Overthinking: An Empirical Study of Reasoning Length and correctness in LLMs | | - |
| 2025-06 | Does Thinking More Always Help? | Does Thinking More always Help? Mirage of Test-Time Scaling in Reasoning Models | | - |
| 2025-05 | Short-m@k | Don't Overthink it. Preferring Shorter Thinking Chains for Improved LLM Reasoning | | - |
| 2025-02 | Thinking-Optimal Scaling | Towards Thinking-Optimal Scaling of Test-Time Compute for LLM Reasoning | |  |
| 2024-12 | Do NOT Think That Much | Do NOT Think That Much for 2+3=? On the Overthinking of o1-Like LLMs | |  |
| 2025-07 | Inverse Scaling | Inverse Scaling in Test-Time Compute | |  |
| 2025-01 | Underthinking | Thoughts Are All Over the Place: On the Underthinking of o1-Like LLMs | | - |
| 2025-02 | ReasoningAction Dilemma | The Danger of Overthinking: Examining the Reasoning-Action Dilemma in Agentic Tasks | | - |
| 2025-10 | REFRAIN | Stop When Enough: Adaptive Early-Stopping for Chain-of-Thought Reasoning | | - |
| 2025-05 | AdaptThink | Stop When Enough: Adaptive Early-Stopping for Chain-of-Thought Reasoning | |  |
| 2025-05 | Self-Braking Tuning | Let LRMs Break Free from Overthinking via Self-Braking Tuning | |  |
| 2025-04 | MiP | Let LRMs Break Free from Overthinking via Self-Braking Tuning | |  |
| 2025-05 | Behavioral Divergence | When Can Large Reasoning Models Save Thinking? Mechanistic Analysis of Behavioral Divergence in Reasoning | | - |
| 2025-04 | Thought Manipulation | Thought Manipulation: External Thought Can Be Efficient for Large Reasoning Models | | - |
| 2025-07 | Disregard Correct Solutions | Large Reasoning Models are not thinking straight: on the unreliability of thinking trajectories | | - |
| 2025-05 | Manifold Steering | Mitigating Overthinking in Large Reasoning Models via Manifold Steering | |  |
| 2025-03 | Representation | Towards Understanding Distilled Reasoning Models: A Representational Approach | | |
| 2025-04 | SEAL | SEAL: Steerable Reasoning Calibration of Large Language Models for Free | |  |
| 2025-05 | Internal Bias | The First Impression Problem: Internal Bias Triggers Overthinking in Reasoning Models | |  |
| 2025-04 | Self-Verification Probing | Reasoning Models Know When They're Right: Probing Hidden States for Self-Verification | |  |
| 2025-10 | Zero-Step Thinking | The Zero-Step Thinking: An Empirical Study of Mode Selection as Harder Early Exit in Reasoning Models | |  |
Unsafety
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-02 | SafeChain | SafeChain: Safety of Language Models with Long Chain-of-Thought Reasoning Capabilities | |  |
| 2025-02 | Hidden Risks | The Hidden Risks of Large Reasoning Models: A Safety Assessment of R1 | | - |
| 2025-03 | DeepSeek-R1-Safe | Safety Evaluation and Enhancement of DeepSeek Models in Chinese Contexts | |  |
| 2025-03 | FreeEvalLM | Trade-offs in Large Reasoning Models: An Empirical Analysis of Deliberative and Adaptive Reasoning over Foundational Capabilities | |  |
| 2025-02 | Mousetrap | A Mousetrap: Fooling Large Reasoning Models for Jailbreak with Chain of Iterative Chaos | |  |
| 2025-02 | H-CoT | H-CoT: Hijacking the Chain-of-Thought Safety Reasoning Mechanism to Jailbreak Large Reasoning Models, Including OpenAI o1/o3, DeepSeek-R1, and Gemini 2.0 Flash Thinking | |  |
| 2025-08 | R1-ACT | R1-ACT: Efficient Reasoning Model Safety Alignment by Activating Safety Knowledge | |  |
| 2025-10 | COG | When Models Outthink Their Safety: Unveiling and Mitigating Self-Jailbreak in Large Reasoning Models | |  |
Training Methods
Combine SFT with RL
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Annealed-RLVR | How LLMs Learn to Reason: A Complex Network Perspective | | - |
| 2025-06 | ReLIFT | Learning What Reinforcement Learning Can't: Interleaved Online Fine-Tuning for Hardest Questions | | - |
| 2025-12 | TRAPO | Trust-Region Adaptive Policy Optimization | |  |
| 2025-05 | UFT | UFT: Unifying Supervised and Reinforcement Fine-Tuning | |  |
| 2025-09 | HPT | Towards a Unified View of Large Language Model Post-Training | |  |
| 2025-08 | CHORD | On-Policy RL Meets Off-Policy Experts: Harmonizing Supervised Fine-Tuning and Reinforcement Learning via Dynamic Weighting | |  |
| 2025-06 | SRFT | SRFT: A Single-Stage Method with Supervised and Reinforcement Fine-Tuning for Reasoning | |  |
| 2025-09 | BRIDGE | Beyond Two-Stage Training: Cooperative SFT and RL for LLM Reasoning | | - |
RL balancing exploration and exploitation
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | |  |
| 2025-05 | Entropy Mechanism of RL | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-05 | ProRL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | |
| 2025-08 | CURE | CURE: Critical-Token-Guided Re-Concatenation for Entropy-Collapse Prevention | |  |
| 2025-10 | Reasoning Boundary Paradox | The Reasoning Boundary Paradox: How Reinforcement Learning Constrains Language Models | | |
| 2025-09 | outcome-based exploration | Outcome-based Exploration for LLM Reasoning | | - |
| 2025-06 | entropy-based advantage | Reasoning with Exploration: An Entropy Perspective | | - |
| 2025-10 | AEPO | Arbitrary Entropy Policy Optimization Breaks The Exploration Bottleneck of Reinforcement Learning | |  |
| 2025-09 | AEnt | On Entropy Control in LLM-RL Algorithms | | - |
| 2025-09 | SIREN | Rethinking Entropy Regularization in Large Reasoning Models | |  |
Contributors


Similar repos


Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures
35
13 commits
updated Jan 29, 2026
README
Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures
🚀 News
- [2026.1.29] Our survey is now available at: https://arxiv.org/abs/2601.19928
- [2026.1.11] 🔥 We are excited to release our survey on LRM mechanistic studies in this repo.
📌 Overview
Our paper provides a comprehensive survey of the mechanistic understanding of LRMs.
We organize recent findings into three core dimensions:
- Training Dynamics:
- Roles of SFT and RL in Post-Training
- Understanding RL Training Dynamics
- Reasoning Mechanisms:
- General Reasoning Structures
- Specific Reasoning Behaviors
- Internal Mechanisms
- Unintended Behaviors:
- Hallucination
- Unfaithfulness
- Overthinking
- Unsafety
🔗 Citation
If you find our survey helpful, please consider citing our paper:
@misc{hu2026mechanisticunderstandinglargereasoning,
      title={Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures},
      author={Yi Hu and Jiaqi Gu and Ruxin Wang and Zijun Yao and Hao Peng and Xiaobao Wu and Jianhui Chen and Muhan Zhang and Liangming Pan},
      year={2026},
      eprint={2601.19928},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.19928},
}
🗂️ Contents
- Towards a Mechanistic Understanding of Large Reasoning Models: A Survey of Training, Inference, and Failures
📄 Paper List
Training Dynamics
Roles of SFT and RL in Post-Training
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-01 | Deepseek-R1 | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning | | |
| 2025-04 | limit of RLVR | Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model? | | |
| 2025-09 | RL Squeezes, SFT Expands | RL Squeezes, SFT Expands: A Comparative Study of Reasoning LLMs | | - |
| 2025-07 | Invisible Leash | The Invisible Leash: Why RLVR May or May Not Escape Its Origin | | - |
| 2025-09 | Representation Geometry of LLM | Tracing the Representation Geometry of Language Models from Pretraining to Post-training | | - |
| 2025-05 | Entropy Mechanism of RL | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-09 | Emergent Attention Heads | Thinking Sparks!: Emergent Attention Heads in Reasoning Models During Post Training | | - |
| 2025-01 | SFT Memorizes, RL Generalizes | SFT Memorizes, RL Generalizes: A Comparative Study of Foundation Model Post-training | | |
| 2025-09 | CoNet | How LLMs Learn to Reason: A Complex Network Perspective | | - |
| 2025-08 | RL Is Neither a Panacea Nor a Mirage | RL Is Neither a Panacea Nor a Mirage: Understanding Supervised vs. Reinforcement Learning Fine-Tuning for LLMs | | - |
| 2025-09 | RL Heals OOD Forgetting | RL Fine-Tuning Heals OOD Forgetting in SFT | | |
| 2025-05 | ProRL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | |
| 2025-09 | From f(x) and g(x) to f(g(x)) | From f(x) and g(x) to f(g(x)): LLMs Learn New Skills in RL by Composing Old Ones | | - |
| 2025-12 | From Atomic to Composite | From Atomic to Composite: Reinforcement Learning Enables Generalization in Complementary Reasoning | | |
| 2025-06 | OctoThinker | OctoThinker: Mid-training Incentivizes Reinforcement Learning Scaling | | |
| 2025-12 | Interplay LM Reasoning | On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models | | |
Understanding RL Training Dynamics
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | HICRA | Emergent Hierarchical Reasoning in LLMs through Reinforcement Learning | | |
| 2025-09 | CoNet | How LLMs Learn to Reason: A Complex Network Perspective | | - |
| 2025-10 | Two-Stage Dynamic | The Debate on RLVR Reasoning Capability Boundary: Shrinkage, Expansion, or Both? A Two-Stage Dynamic View | | - |
| 2025-09 | RL Enhances Activation | Reinforcement Learning Fine-Tuning Enhances Activation Intensity and Diversity in the Internal Circuitry of LLMs | | |
| 2025-09 | Post-Training Structural Changes | Understanding Post-Training Structural Changes in Large Language Models | | - |
| 2025-10 | AlphaRL | On Predictability of Reinforcement Learning Dynamics for Large Language Models | | |
| 2025-05 | Entropy Mechanism of RL | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-10 | Reasoning Boundary Paradox | The Reasoning Boundary Paradox: How Reinforcement Learning Constrains Language Models | | |
| 2025-09 | VERL | Beyond the Exploration-Exploitation Trade-off: A Hidden State Approach for LLM Reasoning in RLVR | | |
Reasoning Mechanisms
General Reasoning Structures
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-04 | DeepSeek-R1 Thoughtology | DeepSeek-R1 Thoughtology: Let's think about LLM Reasoning | | - |
| 2025-06 | Functional Blocks | Beyond Accuracy: Dissecting Mathematical Reasoning for LLMs Under Reinforcement Learning | | |
| 2025-06 | Thought Anchors | Thought Anchors: Which LLM Reasoning Steps Matter? | | |
| 2025-09 | Schoenfeld's Episode Theory | Understanding the Thinking Process of Reasoning Models: A Perspective from Schoenfeld's Episode Theory | | |
| 2025-11 | ReJump | ReJump: A Tree-Jump Representation for Analyzing and Improving LLM Reasoning | | |
| 2025-05 | Structural Patterns | What Makes a Good Reasoning Chain? Uncovering Structural Patterns in Long Chain-of-Thought Reasoning | | - |
| 2025-06 | Topology of Reasoning | Topology of Reasoning: Understanding Large Reasoning Models through Reasoning Graph Properties | | |
| 2025-05 | Mapping the Minds of LLMs | Mapping the Minds of LLMs: A Graph-Based Analysis of Reasoning LLM | | |
Specific Reasoning Behaviors
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | Thought Anchors | Thought Anchors: Which LLM Reasoning Steps Matter? | | |
| 2025-05 | Thought Anchors | Cognitive Behaviors that Enable Self-Improving Reasoners, or, Four Habits of Highly Effective STaRs | | |
| 2025-04 | Understanding Aha Moments | Understanding Aha Moments: from External Observations to Internal Mechanisms | | - |
| 2025-02 | May Not Aha Moment | There may not be aha moment in r1-zero-like training - a pilot study | | |
| 2025-10 | First Try Matters | First Try Matters: Revisiting the Role of Reflection in Reasoning Models | | |
| 2025-06 | The Illusion of Thinking | The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity | | - |
| 2025-9 | Performative Thinking | Performative Thinking? The Brittle Correlation Between CoT Length and Problem Complexity | | - |
Internal Mechanisms
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | Towards Understanding Distilled Reasoning Models | Towards Understanding Distilled Reasoning Models: A Representational Approach | | |
| 2025-05 | Sparse Autoencoders | I Have Covered All the Bases Here: Interpreting Reasoning Features in Large Language Models via Sparse Autoencoders | | |
| 2025-04 | Hood of a Reasoning Model | Under the Hood of a Reasoning Model | | - |
| 2025-06 | Steering Vectors | Understanding Reasoning in Thinking Language Models via Steering Vectors | | |
| 2025-10 | Thinking Models Learn When To Reason | Base Models Know How to Reason, Thinking Models Learn When | | |
| 2025-06 | Thought Anchors | Thought Anchors: Which LLM Reasoning Steps Matter? | | |
| 2025-09 | From Reasoning to Answer | From Reasoning to Answer: Empirical, Attention-Based and Mechanistic Insights into Distilled DeepSeek R1 Models | | |
| 2025-04 | Understanding Aha Moments | Understanding Aha Moments: from External Observations to Internal Mechanisms | | - |
| 2025-12 | ReflCtrl | ReflCtrl: Controlling LLM Reflection via Representation Engineering | | |
| 2025-08 | Latent Directions of Reflection | Unveiling the Latent Directions of Reflection in Large Language Models | | |
| 2025-07 | Reasoning-Finetuning Repurposes Latent Representations | Reasoning-Finetuning Repurposes Latent Representations in Base Models | | |
| 2025-05 | Bias-Only Adaptation | Steering LLM Reasoning Through Bias-Only Adaptation | | |
| 2025-11 | Rank-1 LoRAs | Rank-1 LoRAs Encode Interpretable Reasoning Signals | | |
| 2025-06 | Layer Importance | Layer Importance for Mathematical Reasoning is Forged in Pre-Training and Invariant after Post-Training | | |
| 2025-12 | Effective Depth | What Affects the Effective Depth of Large Language Models? | | |
| 2025-12 | Internal Policy | Bottom-up Policy Optimization: Your Language Model Policy Secretly Contains Internal Policies | | |
| 2025-06 | The Emergence of Mutual Information (MI) Peaks | Demystifying Reasoning Dynamics with Mutual Information: Thinking Tokens are Information Peaks in LLM Reasoning | | |
Unintended Behaviors
Hallucination
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | FactEval | Are Reasoning Models More Prone to Hallucination? | | |
| 2025-05 | FSPO | Reasoning Models Hallucinate More: Factuality-Aware Reinforcement Learning for Large Reasoning Models | | |
| 2025-05 | RDH | Detection and Mitigation of Hallucination in Large Reasoning Models: A Mechanistic Perspective | | |
| 2025-05 | Hallucination Tax | The Hallucination Tax of Reinforcement Finetuning | | |
| 2025-09 | TTS_knowledge | Test-Time Scaling in Reasoning Models Is Not Effective for Knowledge-Intensive Tasks Yet | | |
| 2025-05 | Meta-Cognitive | Auditing Meta-Cognitive Hallucinations in Reasoning Large Language Models | | |
| 2025-06 | RACE | Joint Evaluation of Answer and Reasoning Consistency for Hallucination Detection in Large Reasoning Models | | |
Unfaithfulness
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | FactEval | Are Reasoning Models More Prone to Hallucination? | | |
| 2025-01 | Cue Insertion | Are DeepSeek R1 And Other Reasoning Models More Faithful? | | - |
| 2025-05 | Don't Say What They Think | Reasoning Models Don't Always Say What They Think | | - |
| 2025-03 | Unfaithful CoT | Chain-of-Thought Reasoning In The Wild Is Not Always Faithful | | |
| 2025-06 | Strategic Deception | When Thinking LLMs Lie: Unveiling the Strategic Deception in Representations of Reasoning Models | | |
| 2025-05 | Reasoning Intermediate Token | Beyond Semantics: The Unreasonable Effectiveness of Reasonless Intermediate Tokens | | - |
| 2025-07 | Alignment Prediction | Can We Predict Alignment Before Models Finish Thinking? Towards Monitoring Misaligned Reasoning Models | | |
| 2025-10 | Refusal Cliff | Refusal Falls off a Cliff: How Safety Alignment Fails in Reasoning? | | - |
| 2025-03 | CoT Monitor | Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation | | - |
| 2025-06 | VFT | Teaching Models to Verbalize Reward Hacking in Chain-of-Thought Reasoning | | - |
Overthinking
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | R1 Thoughtology | DeepSeek-R1 Thoughtology: Let’s think about LLM reasoning | | |
| 2025-05 | Between Underthinking and Overthinking | Between Underthinking and Overthinking: An Empirical Study of Reasoning Length and correctness in LLMs | | - |
| 2025-06 | Does Thinking More Always Help? | Does Thinking More always Help? Mirage of Test-Time Scaling in Reasoning Models | | - |
| 2025-05 | Short-m@k | Don't Overthink it. Preferring Shorter Thinking Chains for Improved LLM Reasoning | | - |
| 2025-02 | Thinking-Optimal Scaling | Towards Thinking-Optimal Scaling of Test-Time Compute for LLM Reasoning | | |
| 2024-12 | Do NOT Think That Much | Do NOT Think That Much for 2+3=? On the Overthinking of o1-Like LLMs | | |
| 2025-07 | Inverse Scaling | Inverse Scaling in Test-Time Compute | | |
| 2025-01 | Underthinking | Thoughts Are All Over the Place: On the Underthinking of o1-Like LLMs | | - |
| 2025-02 | ReasoningAction Dilemma | The Danger of Overthinking: Examining the Reasoning-Action Dilemma in Agentic Tasks | | - |
| 2025-10 | REFRAIN | Stop When Enough: Adaptive Early-Stopping for Chain-of-Thought Reasoning | | - |
| 2025-05 | AdaptThink | Stop When Enough: Adaptive Early-Stopping for Chain-of-Thought Reasoning | | |
| 2025-05 | Self-Braking Tuning | Let LRMs Break Free from Overthinking via Self-Braking Tuning | | |
| 2025-04 | MiP | Let LRMs Break Free from Overthinking via Self-Braking Tuning | | |
| 2025-05 | Behavioral Divergence | When Can Large Reasoning Models Save Thinking? Mechanistic Analysis of Behavioral Divergence in Reasoning | | - |
| 2025-04 | Thought Manipulation | Thought Manipulation: External Thought Can Be Efficient for Large Reasoning Models | | - |
| 2025-07 | Disregard Correct Solutions | Large Reasoning Models are not thinking straight: on the unreliability of thinking trajectories | | - |
| 2025-05 | Manifold Steering | Mitigating Overthinking in Large Reasoning Models via Manifold Steering | | |
| 2025-03 | Representation | Towards Understanding Distilled Reasoning Models: A Representational Approach | | |
| 2025-04 | SEAL | SEAL: Steerable Reasoning Calibration of Large Language Models for Free | | |
| 2025-05 | Internal Bias | The First Impression Problem: Internal Bias Triggers Overthinking in Reasoning Models | | |
| 2025-04 | Self-Verification Probing | Reasoning Models Know When They're Right: Probing Hidden States for Self-Verification | | |
| 2025-10 | Zero-Step Thinking | The Zero-Step Thinking: An Empirical Study of Mode Selection as Harder Early Exit in Reasoning Models | | |
Unsafety
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-02 | SafeChain | SafeChain: Safety of Language Models with Long Chain-of-Thought Reasoning Capabilities | | |
| 2025-02 | Hidden Risks | The Hidden Risks of Large Reasoning Models: A Safety Assessment of R1 | | - |
| 2025-03 | DeepSeek-R1-Safe | Safety Evaluation and Enhancement of DeepSeek Models in Chinese Contexts | | |
| 2025-03 | FreeEvalLM | Trade-offs in Large Reasoning Models: An Empirical Analysis of Deliberative and Adaptive Reasoning over Foundational Capabilities | | |
| 2025-02 | Mousetrap | A Mousetrap: Fooling Large Reasoning Models for Jailbreak with Chain of Iterative Chaos | | |
| 2025-02 | H-CoT | H-CoT: Hijacking the Chain-of-Thought Safety Reasoning Mechanism to Jailbreak Large Reasoning Models, Including OpenAI o1/o3, DeepSeek-R1, and Gemini 2.0 Flash Thinking | | |
| 2025-08 | R1-ACT | R1-ACT: Efficient Reasoning Model Safety Alignment by Activating Safety Knowledge | | |
| 2025-10 | COG | When Models Outthink Their Safety: Unveiling and Mitigating Self-Jailbreak in Large Reasoning Models | | |
Training Methods
Combine SFT with RL
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Annealed-RLVR | How LLMs Learn to Reason: A Complex Network Perspective | | - |
| 2025-06 | ReLIFT | Learning What Reinforcement Learning Can't: Interleaved Online Fine-Tuning for Hardest Questions | | - |
| 2025-12 | TRAPO | Trust-Region Adaptive Policy Optimization | | |
| 2025-05 | UFT | UFT: Unifying Supervised and Reinforcement Fine-Tuning | | |
| 2025-09 | HPT | Towards a Unified View of Large Language Model Post-Training | | |
| 2025-08 | CHORD | On-Policy RL Meets Off-Policy Experts: Harmonizing Supervised Fine-Tuning and Reinforcement Learning via Dynamic Weighting | | |
| 2025-06 | SRFT | SRFT: A Single-Stage Method with Supervised and Reinforcement Fine-Tuning for Reasoning | | |
| 2025-09 | BRIDGE | Beyond Two-Stage Training: Cooperative SFT and RL for LLM Reasoning | | - |
RL balancing exploration and exploitation
Click to hide/show the paper list
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-05 | Entropy Mechanism of RL | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-05 | ProRL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | |
| 2025-08 | CURE | CURE: Critical-Token-Guided Re-Concatenation for Entropy-Collapse Prevention | | |
| 2025-10 | Reasoning Boundary Paradox | The Reasoning Boundary Paradox: How Reinforcement Learning Constrains Language Models | | |
| 2025-09 | outcome-based exploration | Outcome-based Exploration for LLM Reasoning | | - |
| 2025-06 | entropy-based advantage | Reasoning with Exploration: An Entropy Perspective | | - |
| 2025-10 | AEPO | Arbitrary Entropy Policy Optimization Breaks The Exploration Bottleneck of Reinforcement Learning | | |
| 2025-09 | AEnt | On Entropy Control in LLM-RL Algorithms | | - |
| 2025-09 | SIREN | Rethinking Entropy Regularization in Large Reasoning Models | | |