
A Survey of Reinforcement Learning for Large Reasoning Models
See the codeREADME

A Survey of Reinforcement Learning for Large Reasoning Models


We welcome everyone to open an issue for any related work we haven’t discussed, and we’ll try to address it in the next release!
🎉 News
- [2026-07-31] 🎉 First OpenRSI release: Frontis-MA1 (35B / 30B, with GGUF derivatives), the OpenMLE stack (Gym / RL / Evo), and the OpenMLE Tasks and OpenMLE SFT Traces datasets. Check it out: GitHub.
- [2026-06-25] 🎉 Our survey Self-Improving Agents in the Era of Experience: A Survey of Self- to Meta-Evolution is now available on OpenReview. Check it out: GitHub and OpenReview.
- [2025-11-05] 🔥 Excited to release our paper list about Memory for Agents, covering breakthroughs in Context Management and Learning from Experience powering self-improving AI agents. Check it out: GitHub
- [2025-10] 🎉 Honored to give talks at BAAI, Qingke Talk and Tencent Wiztalk! Here are the slides.
- [2025-09-18] 🎉 We update the full list of papers in the category structure of the survey!
- [2025-09-12] 🎉 Our survey was ranked #1 Paper of the Day on 🤗 Hugging Face Daily Papers!
- [2025-09-11] 🔥 Excited to release our RL for LRMs Survey! We’ll be updating the full list of papers in with a new category structure soon. Check it out: Paper.
- [2025-08-15] 🔥 Introducing SSRL: an investigation for Agentic Search RL without reliance on external search engine. Check it out: GitHub and Paper.
- [2025-05-27] 🔥 Introducing MARTI: A Framework for LLM-based Multi-Agent Reinforced Training and Inference. Check it out: Github.
- [2025-04-23] 🔥 Introducing TTRL: an open-source solution for online RL on data without ground-truth labels, especially test data. Check it out: Github and Paper.
- [2025-03-20] 🔥 We are excited to introduce collection of papers and projects on RL for reasoning models!
🎈 Citation
If you find this survey helpful, please cite our work:
@article{zhang2025survey,
  title={A survey of reinforcement learning for large reasoning models},
  author={Zhang, Kaiyan and Zuo, Yuxin and He, Bingxiang and Sun, Youbang and Liu, Runze and Jiang, Che and Fan, Yuchen and Tian, Kai and Jia, Guoli and Li, Pengfei and others},
  journal={arXiv preprint arXiv:2509.08827},
  year={2025}
}
📖 Contents
- A Survey of Reinforcement Learning for Large Reasoning Models
- 🎉 News
- 🎈 Citation
- 📖 Contents
- 🗺️ Overview
- 📄 Paper List
- Frontier Models
- Reward Design
- Policy Optimization
- Sampling Strategy
- Training Resource
- Static Corpus (Code)
- Static Corpus (STEM)
- Static Corpus (Math)
- Static Corpus (Agent)
- Static Corpus (Mix)
- Dynamic Environment (Rule-based)
- Dynamic Environment (Code-based)
- Dynamic Environment (Game-based)
- Dynamic Environment (Model-based)
- Dynamic Environment (Ensemble-based)
- RL Infrastructure (Primary)
- RL Infrastructure (Secondary)
- Applications
- 🌟 Acknowledgment
- ✨ Star History
🗺️ Overview
Our survey provides a comprehensive examination of Reinforcement Learning for Large Reasoning Models.
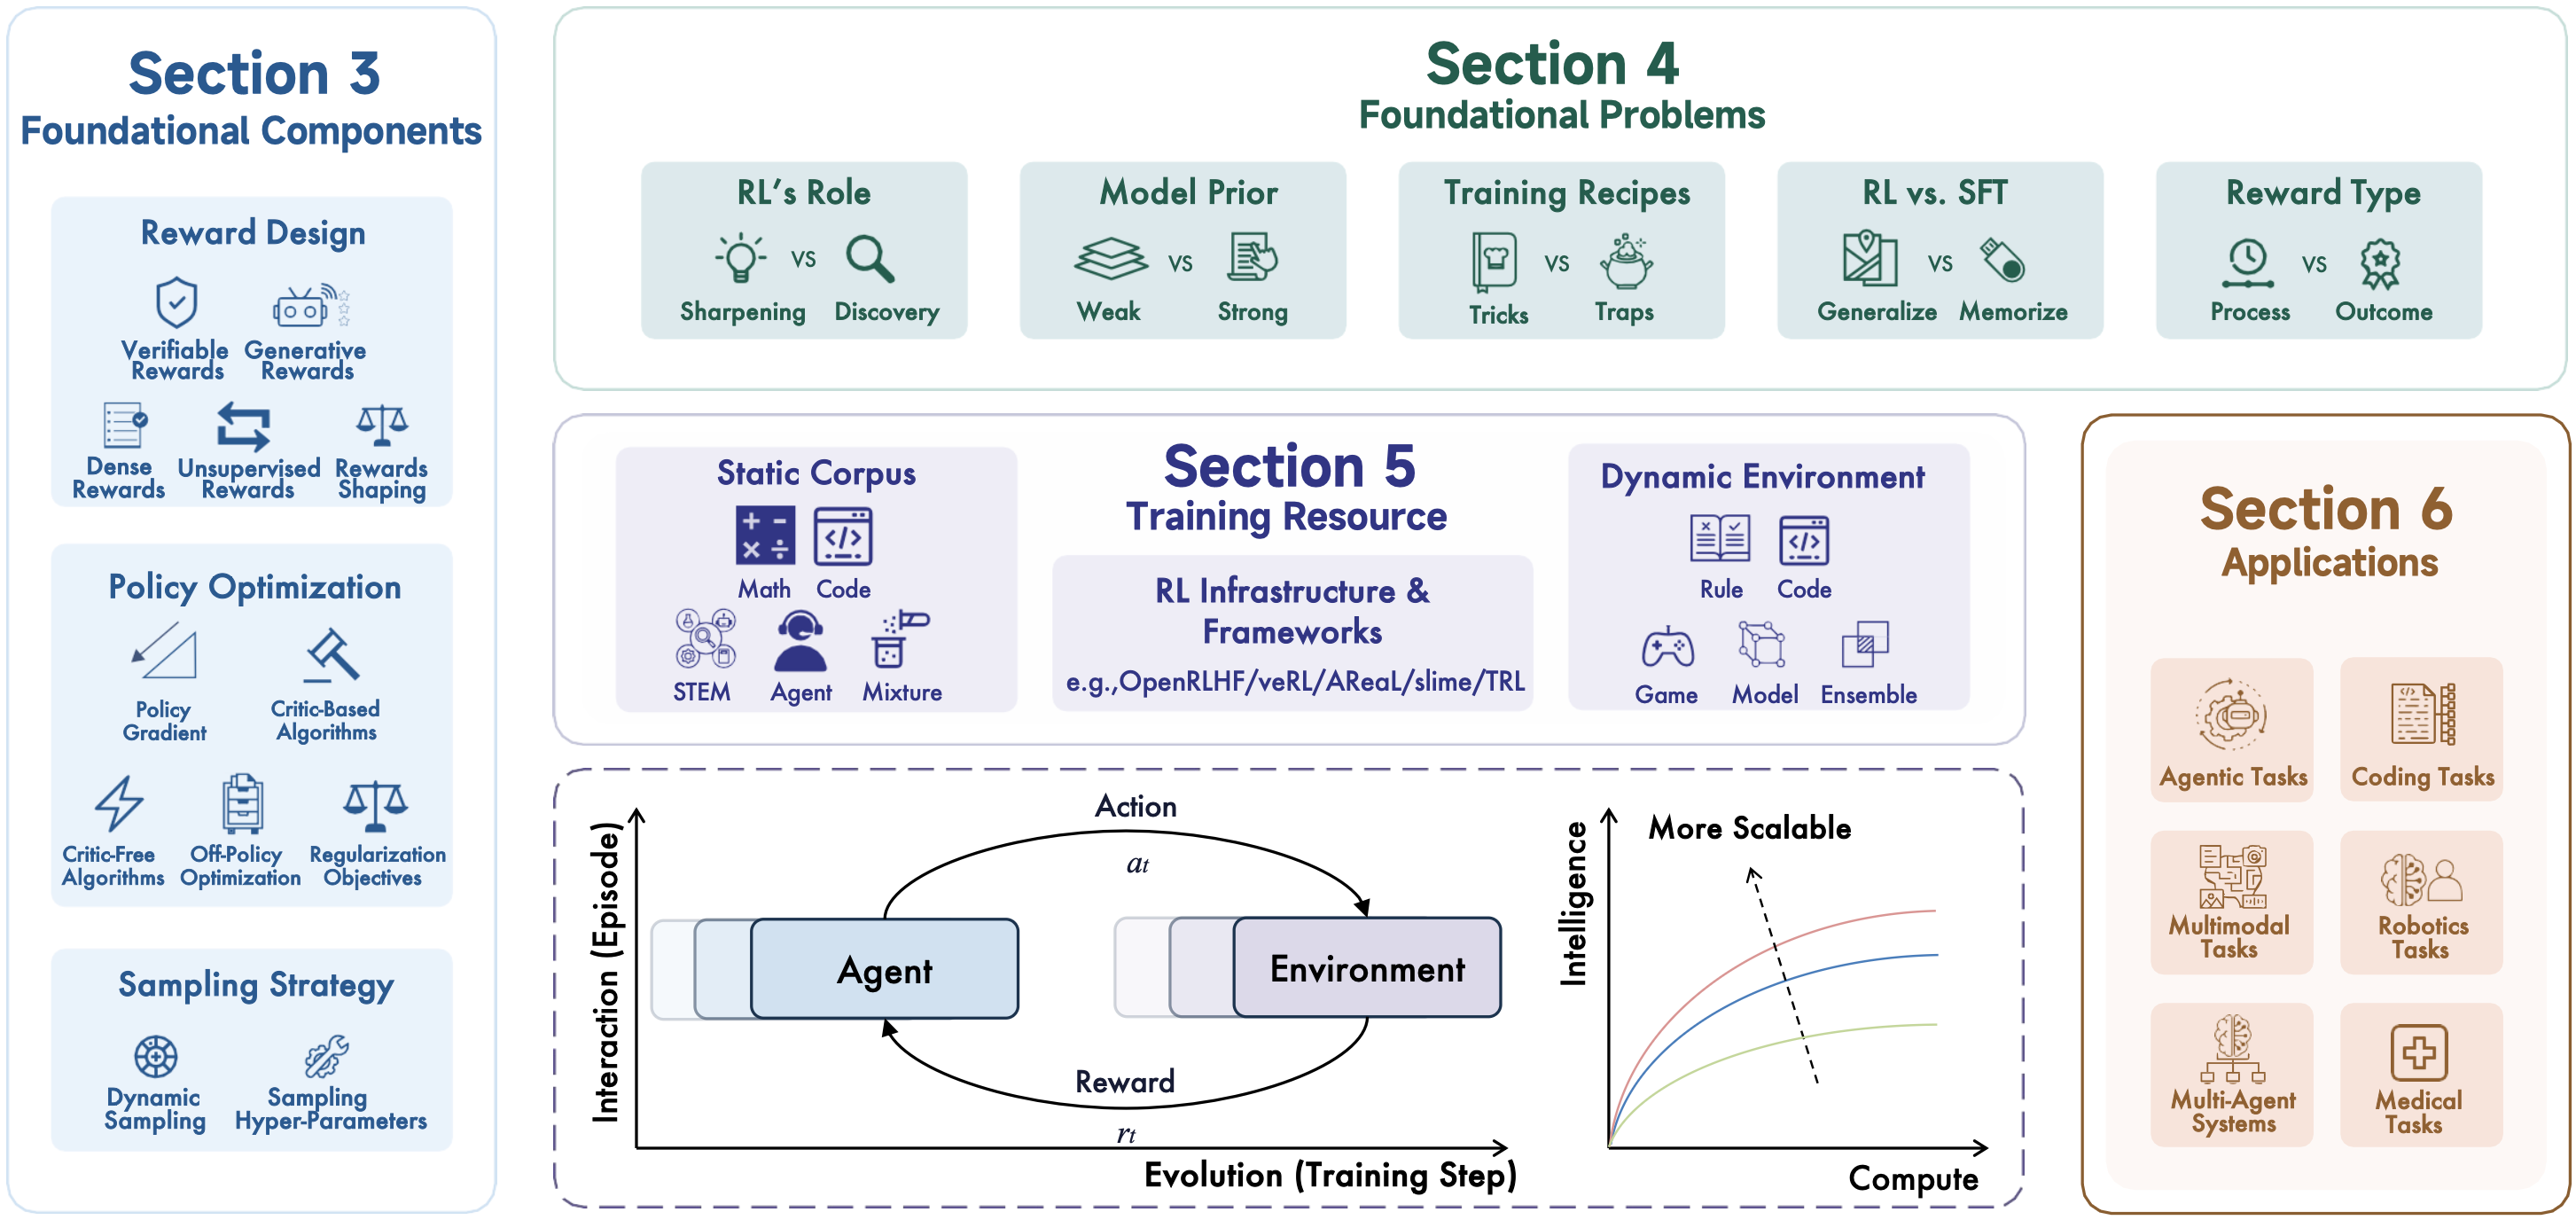
We organize the survey into five main sections:
- Foundational Components: Reward design, policy optimization, and sampling strategies
- Foundational Problems: Key debates and challenges in RL for LRMs
- Training Resources: Static corpora, dynamic environments, and infrastructure
- Applications: Real-world implementations across diverse domains
- Future Directions: Emerging research opportunities and challenges
📄 Paper List
Frontier Models
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | Intern-S1 | Intern-S1: A Scientific Multimodal Foundation Model |  |  |
| 2025-08 | GLM-4.5 | GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models | |  |
| 2025-08 | gpt-oss | gpt-oss-120b & gpt-oss-20b Model Card | |  |
| 2025-08 | InternVL3.5 | InternVL3.5: Advancing Open-Source Multimodal Models in Versatility, Reasoning, and Efficiency | |  |
| 2025-07 | Kimi K2 | Kimi K2: Open Agentic Intelligence | |  |
| 2025-07 | Step 3 | Step-3 is Large yet Affordable: Model-system Co-design for Cost-effective Decoding | |  |
| 2025-07 | GLM-4.1V-Thinking | GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning | |  |
| 2025-07 | Skywork-R1V3 | Skywork-R1V3 Technical Report | |  |
| 2025-07 | GLM-4.5V | GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning | | |
| 2025-06 | Magistral | Magistral | | - |
| 2025-06 | Minimax-M1 | MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning Attention | |  |
| 2025-05 | MiMo | MiMo: Unlocking the Reasoning Potential of Language Model -- From Pretraining to Posttraining | |  |
| 2025-05 | Qwen3 | Qwen3 Technical Report | |  |
| 2025-05 | Llama-Nemotron-Ultra | Llama-Nemotron: Efficient Reasoning Models | |  |
| 2025-05 | INTELLECT-2 | INTELLECT-2: A Reasoning Model Trained Through Globally Decentralized Reinforcement Learning | | - |
| 2025-05 | Hunyuan-TurboS | Hunyuan-TurboS: Advancing Large Language Models through Mamba-Transformer Synergy and Adaptive Chain-of-Thought | |  |
| 2025-05 | Skywork OR-1 | Skywork Open Reasoner 1 Technical Report | |  |
| 2025-04 | Phi-4 Reasoning | Phi-4-reasoning Technical Report | | - |
| 2025-04 | Skywork-R1V2 | Skywork R1V2: Multimodal Hybrid Reinforcement Learning for Reasoning | | |
| 2025-04 | InternVL3 | InternVL3: Exploring Advanced Training and Test-Time Recipes for Open-Source Multimodal Models | | |
| 2025-03 | ORZ | Open-Reasoner-Zero: An Open Source Approach to Scaling Up Reinforcement Learning on the Base Model | |  |
| 2025-01 | DeepSeek-R1 | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning | |  |
| - | QwQ | QwQ-32B: Embracing the Power of Reinforcement Learning |  |  |
| - | Seed-OSS | Seed-OSS Open-Source Models |  |  |
| - | ERNIE-4.5-Thinking | ERNIE 4.5 Technical Report | | - |
Reward Design
Generative Rewards
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2026-06 | - | Steer, Don't Solve: Training Small Critic Models for Large Code Agents | |  |
| 2025-08 | CAPO | CAPO: Towards Enhancing LLM Reasoning through Verifiable Generative Credit Assignment | |  |
| 2025-08 | CompassVerifier | CompassVerifier: A Unified and Robust Verifier for LLMs Evaluation and Outcome Reward | |  |
| 2025-08 | Cooper | Cooper: Co-Optimizing Policy and Reward Models in Reinforcement Learning for Large Language Models | |  |
| 2025-08 | ReviewRL | ReviewRL: Towards Automated Scientific Review with RL | |  |
| 2025-08 | Rubicon | Reinforcement Learning with Rubric Anchors | | - |
| 2025-08 | RuscaRL | Breaking the Exploration Bottleneck: Rubric-Scaffolded Reinforcement Learning for General LLM Reasoning | | - |
| 2025-07 | OMNI-THINKER | OMNI-THINKER: Scaling Cross-Domain Generalization in LLMs via Multi-Task RL with Hybrid Rewards | | - |
| 2025-07 | URPO | URPO: A Unified Reward & Policy Optimization Framework for Large Language Models | | - |
| 2025-07 | RaR | Rubrics as Rewards: Reinforcement Learning Beyond Verifiable Domains | | - |
| 2025-07 | RLCF | Checklists Are Better Than Reward Models For Aligning Language Models | | - |
| 2025-07 | PCL | Post-Completion Learning for Language Models | | - |
| 2025-07 | K2 | KIMI K2: OPEN AGENTIC INTELLIGENCE | | - |
| 2025-07 | LIBRA | LIBRA: ASSESSING AND IMPROVING REWARD MODEL BY LEARNING TO THINK | | - |
| 2025-07 | TP-GRPO | Good Learners Think Their Thinking: Generative PRM Makes Large Reasoning Model More Efficient Math Learner | |  |
| 2025-06 | RewardAnything | RewardAnything: Generalizable Principle-Following Reward Models | | |
| 2025-06 | Writing-Zero | Writing-Zero: Bridge the Gap Between Non-verifiable Tasks and Verifiable Rewards | | - |
| 2025-06 | Critique-GRPO | Critique-GRPO: Advancing LLM Reasoning with Natural Language and Numerical Feedback | |  |
| 2025-06 | PAG | PAG: Multi-Turn Reinforced LLM Self-Correction with Policy as Generative Verifier | | - |
| 2025-06 | GRAM | GRAM: A Generative Foundation Reward Model for Reward Generalization | |  |
| 2025-06 | ProxyReward | From General to Targeted Rewards: Surpassing GPT-4 in Open-Ended Long-Context Generation | | - |
| 2025-06 | QA-LIGN | QA-LIGN: Aligning LLMs through Constitutionally Decomposed QA | | - |
| 2025-05 | RM-R1 | RM-R1: Reward Modeling as Reasoning | |  |
| 2025-05 | J1 | J1: Incentivizing Thinking in LLM-as-a-Judge via RL | | - |
| 2025-05 | TinyV | TinyV: Reducing False Negatives in Verification Improves RL for LLM Reasoning | |  |
| 2025-05 | General-Reasoner | General-reasoner: Advancing llm reasoning across all domains | | - |
| 2025-05 | RRM | Reward Reasoning Model | | - |
| 2025-05 | RL Tango | RL Tango: Reinforcing Generator and Verifier Together for Language Reasoning | |  |
| 2025-05 | Think-RM | Think-RM: Enabling Long-Horizon Reasoning in Generative Reward Models | |  |
| 2025-04 | JudgeLRM | JudgeLRM: Large Reasoning Models as a Judge | |  |
| 2025-04 | GenPRM | GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning | |  |
| 2025-04 | DeepSeek-GRM | Inference-Time Scaling for Generalist Reward Modeling | | - |
| 2025-04 | AIR | AIR: A Systematic Analysis of Annotations, Instructions, and Response Pairs in Preference Dataset | | - |
| 2025-04 | Pairwise-RL | A Unified Pairwise Framework for RLHF: Bridging Generative Reward Modeling and Policy Optimization | | - |
| 2025-04 | xVerify | xVerify: Efficient Answer Verifier for Reasoning Model Evaluations | |  |
| 2025-04 | Seed-Thinking-v1.5 | Seed1.5-Thinking: Advancing Superb Reasoning Models with Reinforcement Learning | | - |
| 2025-04 | ThinkPRM | Process Reward Models That Think | |  |
| 2025-03 | - | Crossing the Reward Bridge: Expanding RL with Verifiable Rewards Across Diverse Domains | | - |
| 2025-02 | - | Self-rewarding correction for mathematical reasoning | |  |
| 2024-10 | GenRM | Generative Reward Models | | - |
| 2024-08 | CLoud | Critique-out-Loud Reward Models | |  |
| 2024-08 | Generative Verifier | Generative Verifiers: Reward Modeling as Next-Token Prediction | | - |
| 2024-01 | Self-Rewarding LM | Self-Rewarding Language Models | | - |
| 2023-10 | Auto-J | Generative Judge for Evaluating Alignment | |  |
| 2023-06 | Judge LLM-as-a-Judge | Judging llm-as-a-judge with mt-bench and chatbot arena | |  |
Dense Rewards
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2026-09 | DRACO | DRACO: Fine-Grained Credit Assignment with Dynamic Rubrics for Long-Horizon Agent Training | |  |
| 2025-09 | Tree-GRPO | Tree Search for LLM Agent Reinforcement Learning | |  |
| 2025-09 | AttnRL | Attention as a Compass: Efficient Exploration for Process-Supervised RL in Reasoning Models | |  |
| 2025-09 | TARL | Process-Supervised Reinforcement Learning for Interactive Multimodal Tool-Use Agents | | - |
| 2025-09 | PROF | Beyond Correctness: Harmonizing Process and Outcome Rewards through RL Training | |  |
| 2025-09 | HICRA | Emergent Hierarchical Reasoning in LLMs through Reinforcement Learning | | - |
| 2025-08 | KlearReasoner | Klear-Reasoner: Advancing Reasoning Capability via Gradient-Preserving Clipping Policy Optimization | |  |
| 2025-08 | CAPO | CAPO: Towards Enhancing LLM Reasoning through Verifiable Generative Credit Assignment | | |
| 2025-08 | GTPO & GRPO-S | GTPO and GRPO-S: Token and Sequence-Level Reward Shaping with Policy Entropy | | - |
| 2025-08 | VSRM | Promoting Efficient Reasoning with Verifiable Stepwise Reward | | - |
| 2025-08 | G-RA | Stabilizing Long-term Multi-turn Reinforcement Learning with Gated Rewards | | - |
| 2025-08 | SSPO | SSPO: Self-traced Step-wise Preference Optimization for Process Supervision and Reasoning Compression | | - |
| 2025-08 | AIRL-S | Your Reward Function for RL is Your Best PRM for Search: Unifying RL and Search-Based TTS | | - |
| 2025-08 | TreePO | TreePO: Bridging the Gap of Policy Optimization and Efficacy and Inference Efficiency with Heuristic Tree-based Modeling | |  |
| 2025-08 | MUA-RL | MUA-RL: Multi-turn User-interacting Agent Reinforcement Learning for agentic tool use | | - |
| 2025-07 | SPRO | Self-Guided Process Reward Optimization with Redefined Step-wise Advantage for Process Reinforcement | | - |
| 2025-07 | FR3E | First Return, Entropy-Eliciting Explore | | - |
| 2025-07 | ARPO | Agentic Reinforced Policy Optimization | |  |
| 2025-07 | TP-GRPO | Good Learners Think Their Thinking: Generative PRM Makes Large Reasoning Model More Efficient Math Learner | | |
| 2025-06 | TreeRPO | TreeRPO: Tree Relative Policy Optimization | |  |
| 2025-06 | TreeRL | TreeRL: LLM Reinforcement Learning with On-Policy Tree Search | |  |
| 2025-06 | Entropy Advantage | Reasoning with Exploration: An Entropy Perspective on Reinforcement Learning for LLMs | | - |
| 2025-06 | ReasonFlux-PRM | ReasonFlux-PRM: Trajectory-Aware PRMs for Long Chain-of-Thought Reasoning in LLMs | |  |
| 2025-05 | S-GRPO | S-GRPO: Early Exit via Reinforcement Learning in Reasoning Models | | - |
| 2025-05 | GiGPO | Group-in-Group Policy Optimization for LLM Agent Training | |  |
| 2025-05 | - | Reinforcing Multi-Turn Reasoning in LLM Agents via Turn-Level Credit Assignment | | - |
| 2025-05 | Tango | RL Tango: Reinforcing Generator and Verifier Together for Language Reasoning | | |
| 2025-05 | StepSearch | StepSearch: Igniting LLMs Search Ability via Step-Wise Proximal Policy Optimization | |  |
| 2025-05 | - | Aligning Dialogue Agents with Global Feedback via Large Language Model Reward Decomposition | | - |
| 2025-05 | Tool-Star | Tool-Star: Empowering LLM-Brained Multi-Tool Reasoner via Reinforcement Learning | |  |
| 2025-05 | SPA-RL | SPA-RL: Reinforcing LLM Agents via Stepwise Progress Attribution | |  |
| 2025-05 | SPO | Segment Policy Optimization: Effective Segment-Level Credit Assignment in RL for Large Language Mode | |  |
| 2025-04 | GenPRM | GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning | | |
| 2025-04 | PURE | Stop Summation: Min-Form Credit Assignment Is All Process Reward Model Needs for Reasoning | |  |
| 2025-03 | MRT | Optimizing Test-Time Compute via Meta Reinforcement Fine-Tuning | |  |
| 2025-03 | SWEET-RL | SWEET-RL: Training Multi-Turn LLM Agents on Collaborative Reasoning Tasks | |  |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | |  |
| 2024-12 | Implicit PRM | Free Process Rewards without Process Labels | |  |
| 2024-10 | VinePPO | VinePPO: Refining Credit Assignment in RL Training of LLMs | |  |
| 2024-10 | PAV | Rewarding Progress: Scaling Automated Process Verifiers for LLM Reasoning | | - |
| 2024-04 | - | From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function | | - |
| 2024-03 | GELI | Improving Dialogue Agents by Decomposing One Global Explicit Annotation with Local Implicit Multimodal Feedback | | - |
| 2023-12 | Math-Shepherd | Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations | | - |
| 2023-05 | PRM800K | Let's Verify Step by Step | |  |
| 2022-11 | - | Solving math word problems with process- and outcome-based feedback | | - |
Unsupervised Rewards
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Vision-Zero | Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | |  |
| 2025-08 | Co-Reward | Co-Reward: Self-supervised Reinforcement Learning for Large Language Model Reasoning via Contrastive Agreement | |  |
| 2025-08 | SQLM | Self-Questioning Language Models | |  |
| 2025-08 | R-zero | R-Zero: Self-Evolving Reasoning LLM from Zero Data | |  |
| 2025-08 | ETTRL | ETTRL: Balancing Exploration and Exploitation in LLM Test-Time Reinforcement Learning Via Entropy Mechanism | | - |
| 2025-07 | RLSF | Post-Training Large Language Models via Reinforcement Learning from Self-Feedback | | - |
| 2025-06 | RLSC | Confidence Is All You Need: Few-Shot RL Fine-Tuning of Language Models | | - |
| 2025-06 | RPT | Reinforcement Pre-Training | | - |
| 2025-06 | CoVo | Consistent Paths Lead to Truth: Self-Rewarding Reinforcement Learning for LLM Reasoning | |  |
| 2025-06 | SEAL | Self-Adapting Language Models | | - |
| 2025-06 | Spurious Rewards | Spurious Rewards: Rethinking Training Signals in RLVR | |  |
| 2025-06 | No Free Lunch | No Free Lunch: Rethinking Internal Feedback for LLM Reasoning | | - |
| 2025-05 | Absolute Zero | Absolute Zero: Reinforced Self-play Reasoning with Zero Data | |  |
| 2025-05 | EM-RL | The Unreasonable Effectiveness of Entropy Minimization in LLM Reasoning | |  |
| 2025-05 | SSR-Zero | SSR-Zero: Simple Self-Rewarding Reinforcement Learning for Machine Translation | |  |
| 2025-05 | - | Surrogate Signals from Format and Length: Reinforcement Learning for Solving Mathematical Problems without Ground Truth Answers | |  |
| 2025-05 | RLIF | Learning to Reason without External Rewards | |  |
| 2025-05 | SeRL | SeRL: Self-Play Reinforcement Learning for Large Language Models with Limited Data | |  |
| 2025-05 | SRT | Can Large Reasoning Models Self-Train? | |  |
| 2025-05 | RENT-RL | Maximizing Confidence Alone Improves Reasoning | |  |
| 2025-04 | EMPO | Right Question is Already Half the Answer: Fully Unsupervised LLM Reasoning Incentivization | |  |
| 2025-04 | TRANS-ZERO | TRANS-ZERO: Self-Play Incentivizes Large Language Models for Multilingual Translation Without Parallel Data | |  |
| 2025-04 | TTRL | TTRL: Test-Time Reinforcement Learning | |  |
| 2025-04 | One-Shot-RLVR | Reinforcement Learning for Reasoning in Large Language Models with One Training Example | |  |
| 2025-02 | CAGSR | A Self-Supervised Reinforcement Learning Approach for Fine-Tuning Large Language Models Using Cross-Attention Signals | | - |
| 2024-07 | MINIMO | Learning Formal Mathematics From Intrinsic Motivation | |  |
Rewards Shaping
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | CDE | CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models | | - |
| 2025-09 | DARLING | Jointly Reinforcing Diversity and Quality in Language Model Generations | |  |
| 2025-09 | DRER | Rethinking Reasoning Quality in Large Language Models through Enhanced Chain-of-Thought via RL | | - |
| 2025-09 | OBE | Outcome-based Exploration for LLM Reasoning | | - |
| 2025-08 | Pass@kTraining | Pass@k Training for Adaptively Balancing Exploration and Exploitation of Large Reasoning Models | |  |
| 2025-05 | PKPO | Pass@K Policy Optimization: Solving Harder Reinforcement Learning Problems | | - |
| 2025-05 | rl-without-gt | Surrogate Signals from Format and Length: Reinforcement Learning for Solving Mathematical Problems without Ground Truth Answers | | |
| 2025-03 | CrossDomain-RLVR | Crossing the Reward Bridge: Expanding RL with Verifiable Rewards Across Diverse Domains | | - |
| 2025-01 | DeepSeek-R1 | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning | | |
| 2024-09 | Qwen2.5-Math | Qwen2. 5-math technical report: Toward mathematical expert model via self-improvement | |  |
Policy Optimization
Policy Gradient Objective
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2017-07 | PPO | Proximal policy optimization algorithms | | - |
| - | PG | Policy gradient methods for reinforcement learning with function approximation. | | - |
| - | REINFORCE | Simple statistical gradient-following algorithms for connectionist reinforcement learning | | - |
| - | TRPO | Trust region policy optimization | | - |
Critic-based Algorithms
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | VL-DAC | Enhancing Vision-Language Model Training with Reinforcement Learning in Synthetic Worlds for Real-World Success | |  |
| 2025-08 | VRPO | VRPO:Rethinking Value Modeling for Robust RL Training under Noisy Supervision | | - |
| 2025-05 | VerIPO | VerIPO: Long Reasoning Video-R1 Model with Iterative Policy Optimization | |  |
| 2025-04 | VAPO | Vapo: Efficient and reliable reinforcement learning for advanced reasoning tasks | | - |
| 2025-03 | VCPPO | What’s Behind PPO’s Collapse in Long-CoT? Value Optimization Holds the Secret | | - |
| 2025-03 | Open reasoner-zero | open reasoner-zero: An open source approach to scaling up reinforcement learning on the base model | | |
| 2025-02 | PRIME | PROCESS REINFORCEMENT THROUGH IMPLICIT REWARDS | | |
| 2024-12 | Implicit PRM | FREE PROCESS REWARDS WITHOUT PROCESS LABELS | |  |
| 2023-12 | Math-shepherd | Math-shepherd: Verify and reinforce LLMs step-by-step without human annotations | | - |
| 2015-06 | GAE | High-dimensional continuous control using generalized advantage estimation | | - |
| - | Autopsv | Autopsv: Automated process-supervised verifier. | |  |
Critic-Free Algorithms
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | UPGE | Towards a Unified View o fLarge Language Model Post-Training | |  |
| 2025-09 | SPO | Single-stream Policy Optimization | | - |
| 2025-08 | LitePPO | Part I: Tricks or Traps? A Deep Dive into RLfor LLM Reasoning | | - |
| 2025-07 | R1-RE | R1-RE: Cross-Domain Relation Extraction with RLVR | | - |
| 2025-07 | GSPO | Group Sequence Policy Optimization | | - |
| 2025-06 | CISPO | MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning Attention | | |
| 2025-05 | KRPO | Kalman Filter Enhanced Group Relative Policy Optimization for Language Model Reasoning | |  |
| 2025-05 | CPGD | CPGD:Toward Stable Rule-based Reinforcement Learning for Language Models | |  |
| 2025-05 | NFT | Bridging Supervised Learning and Reinforcement Learning in Math Reasoning | | - |
| 2025-05 | Clip-Cov/KL-Cov | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | |  |
| 2025-03 | OpenVLThinker | OpenVLThinker: Complex Vision-Language Reasoning via Iterative SFT-RL Cycles | |  |
| 2025-03 | DAPO | DAPO: an Open-Source LLM Reinforcement Learning System at Scale | |  |
| 2025-03 | Dr. GRPO | Understanding R1-Zero-Like Training: A Critical Perspectiv | |  |
| 2025-01 | Kimi k1.5 | Kimi k1.5: Scaling Reinforcement Learning with LLMs | | - |
| 2024-02 | RLOO | Back to basics: Revisiting reinforce style optimization for learning from human feedback in llms | | - |
| 2024-02 | GRPO | DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models | |  |
| 2023-10 | ReMax | ReMax: A Simple, Effective, and Efficient Method for Aligning Large Language Models | |  |
| - | REINFORCE | Simple statistical gradient-following algorithms for connectionist reinforcement learning | | - |
| - | REINFORCE++ | REINFORCE++: An Efficient RLHF Algorithm with Robustnessto Both Prompt and Reward Models | |  |
| - | VinePPO | VINEPPO: UNLOCKING RL POTENTIAL FOR LLM REASONING THROUGH REFINED CREDIT ASSIGNMENT | | |
| - | FlashRL | Fast RL training with Quantized Rollouts | |  |
Off-policy Optimization
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | BRIDGE | Beyond Two-Stage Training: Cooperative SFT and RL for LLM Reasoning | |  |
| 2025-09 | HPT | Towards a Unified View of Large Language Model Post-Training | | |
| 2025-08 | DFT | On the Generalization of SFT: A Reinforcement Learning Perspective with Reward Rectification | |  |
| 2025-08 | RED | Recall-Extend Dynamics: Enhancing Small Language Models through Controlled Exploration and Refined Offline Integration | |  |
| 2025-07 | Prefix‑RFT | Blending Supervised and Reinforcement Fine-Tuning with Prefix Sampling | | - |
| 2025-07 | ReMix | Squeeze the Soaked Sponge: Efficient Off-policy Reinforcement Finetuning for Large Language Model | |  |
| 2025-06 | ReLIFT | Learning What Reinforcement Learning Can't: Interleaved Online Fine-Tuning for Hardest Questions | |  |
| 2025-06 | BREAD | BREAD: Branched Rollouts from Expert Anchors Bridge SFT & RL for Reasoning | | - |
| 2025-06 | SRFT | SRFT: A Single-Stage Method with Supervised and Reinforcement Fine-Tuning for Reasoning | | - |
| 2025-05 | AMPO | Adaptive Thinking via Mode Policy Optimization for Social Language Agents | |  |
| 2025-05 | UFT | UFT: Unifying Supervised and Reinforcement Fine-Tuning | |  |
| 2025-04 | LUFFY | Learning to Reason under Off-Policy Guidance | |  |
| 2025-03 | SPO | Soft Policy Optimization: Online Off-Policy RL for Sequence Models | | |
| 2025-03 | TOPR | TAPERED OFF-POLICY REINFORCE Stable and efficient reinforcement learning for LLMs | | - |
| 2024-05 | IFT | Intuitive Fine-Tuning: Towards Simplifying Alignment into a Single Process | |  |
| 2023-05 | DPO | Direct Preference Optimization: Your Language Model is Secretly a Reward Model | | - |
| 2015-11 | - | Fixed point quantization of deep convolutional networks | | - |
| - | - | Your Efficient RL Framework Secretly Brings You Off-Policy RL Training | |  |
Off-policy Optimization (Exp replay)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SAPO | Sharing is Caring: Efficient LM Post-Training with Collective RL Experience Sharing | | - |
| 2025-09 | SEELE | Staying in the Sweet Spot: Responsive Reasoning Evolution via Capability-Adaptive Hint Scaffolding | |  |
| 2025-08 | Memory-R1 | Memory-R1: Enhancing Large Language Model Agents to Manage and Utilize Memories via Reinforcement Learning | | - |
| 2025-07 | RLEP | RLEP: Reinforcement Learning with Experience Replay for LLM Reasoning | |  |
| 2025-06 | EFRame | EFRame: Deeper Reasoning via Exploration-Filter-Replay Reinforcement Learning Framework | |  |
| 2025-05 | ARPO | ARPO:End-to-End Policy Optimization for GUI Agents with Experience Replay | |  |
| 2025-04 | - | Improving RL Exploration for LLM Reasoning through Retrospective Replay | | - |
Regularization Objectives
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-10 | ASPO | ASPO: Asymmetric Importance Sampling Policy Optimization | |  |
| 2025-09 | CE-GPPO | CE-GPPO: Coordinating Entropy via Gradient-Preserving Clipping Policy Optimization in Reinforcement Learning | |  |
| 2025-09 | CDE | CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models | | - |
| 2025-09 | DPH RL | The Choice of Divergence: A Neglected Key to Mitigating Diversity Collapse in Reinforcement Learning with Verifiable Reward | |  |
| 2025-09 | empgseed-seed | Harnessing Uncertainty: Entropy-Modulated Policy Gradients for Long-Horizon LLM Agents | | - |
| 2025-07 | Archer | Stabilizing Knowledge, Promoting Reasoning: Dual-Token Constraints for RLVR | |  |
| 2025-06 | Bingo | Bingo: Boosting Efficient Reasoning of LLMs via Dynamic and Significance-based Reinforcement Learning | |  |
| 2025-06 | HighEntropy RL | Beyond the 80/20 Rule: High-Entropy Minority Tokens Drive Effective Reinforcement Learning for LLM Reasoning | | - |
| 2025-06 | Entropy RL | Reasoning with Exploration: An Entropy Perspective on Reinforcement Learning for LLMs | | - |
| 2025-06 | ALP RL | Just Enough Thinking: Efficient Reasoning with Adaptive Length Penalties Reinforcement Learning | | - |
| 2025-05 | DisCO | DisCO: Reinforcing Large Reasoning Models with Discriminative Constrained Optimization | |  |
| 2025-05 | Skywork OR1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-05 | Entropy Mechanism | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-05 | ProRL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | - |
| 2025-05 | Short RL | Efficient RL Training for Reasoning Models via Length-Aware Optimization | |  |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | - |
| 2025-03 | L1 | L1: Controlling how long a reasoning model thinks with reinforcement learning | |  |
Sampling Strategy
Dynamic and Structured Sampling
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-10 | EEPO | EEPO: Exploration-Enhanced Policy Optimization via Sample-Then-Forget | |  |
| 2025-09 | AttnRL | Attention as a Compass: Efficient Exploration for Process-Supervised RL in Reasoning Models | | - |
| 2025-09 | DACE | Know When to Explore: Difficulty-Aware Certainty as a Guide for LLM Reinforcement Learning | | - |
| 2025-09 | Parallel-R1 | Parallel-R1: Towards Parallel Thinking via Reinforcement Learning | |  |
| 2025-08 | G^2RPO-A | G^2RPO-A: Guided Group Relative Policy Optimization with Adaptive Guidanc | |  |
| 2025-08 | RuscaRL | Breaking the Exploration Bottleneck: Rubric-Scaffolded Reinforcement Learning for General LLM Reasoning | | - |
| 2025-08 | TreePO | TreePO: Bridging the Gap of Policy Optimization and Efficacy and Inference Efficiency with Heuristic Tree-based Modeling | | |
| 2025-07 | ARPO | Agentic Reinforced Policy Optimization | | |
| 2025-06 | TreeRPO | TreeRPO: Tree Relative Policy Optimization | | |
| 2025-06 | E2H | Curriculum Reinforcement Learning from Easy to Hard Tasks Improves LLM Reasoning | | - |
| 2025-06 | TreeRL | TreeRL: LLM Reinforcement Learning with On-Policy Tree Search | | |
| 2025-05 | ToTRL | ToTRL: Unlock LLM Tree-of-Thoughts Reasoning Potential through Puzzles Solving | | - |
| 2025-03 | DARS | DARS: Dynamic Action Re-Sampling to Enhance Coding Agent Performance by Adaptive Tree Traversal | |  |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| - | POLARIS | POLARIS: A POst-training recipe for scaling reinforcement Learning on Advanced ReasonIng modelS | |  |
Sampling Hyper-Parameters
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | GFPO | Sample More to Think Less: Group Filtered Policy Optimization for Concise Reasoning | | - |
| 2025-06 | AceReason-Nemotron 1.1 | AceReason-Nemotron 1.1: Advancing Math and Code Reasoning through SFT and RL Synergy | | - |
| 2025-06 | T-PPO | Truncated Proximal Policy Optimization | | - |
| 2025-06 | Confucius3-Math | Confucius3-Math: A Lightweight High-Performance Reasoning LLM for Chinese K-12 Mathematics Learning | |  |
| 2025-05 | E3-RL4LLMs | Enhancing Efficiency and Exploration in Reinforcement Learning for LLMs | |  |
| 2025-05 | AceReason-Nemotron | AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning | | - |
| 2025-05 | Pro-RL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | - |
| 2025-03 | - | Output Length Effect on DeepSeek-R1's Safety in Forced Thinking | | - |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| 2025-02 | - | Training Language Models to Reason Efficiently | | - |
| - | DeepScaleR | DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL | |  |
| - | POLARIS | POLARIS: A POst-training recipe for scaling reinforcement Learning on Advanced ReasonIng modelS | | |
Training Resource
Static Corpus (Code)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | rStar-Coder | rStar-Coder: Scaling Competitive Code Reasoning with a Large-Scale Verified Dataset | |  |
| 2025-04 | Z1 | Z1: Efficient Test-time Scaling with Code | |  |
| 2025-04 | OpenCodeReasoning | OpenCodeReasoning: Advancing Data Distillation for Competitive Coding | | - |
| 2025-04 | LeetCodeDataset | LeetCodeDataset: A Temporal Dataset for Robust Evaluation and Efficient Training of Code LLMs | |  |
| 2025-03 | KodCode | KodCode: A Diverse, Challenging, and Verifiable Synthetic Dataset for Coding | | - |
| 2025-01 | SWE-Fixer | SWE-Fixer: Training Open-Source LLMs for Effective and Efficient GitHub Issue Resolution | |  |
| 2024-12 | SWE-Gym | Training Software Engineering Agents and Verifiers with SWE-Gym | |  |
| - | Code-R1 | Code-R1: Reproducing R1 for Code with Reliable Rewards | |  |
| - | codeforces-cots | CodeForces CoTs | | - |
| - | DeepCoder | DeepCoder: A Fully Open-Source 14B Coder at O3-mini Level | |  |
Static Corpus (STEM)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SSMR-Bench | Synthesizing Sheet Music Problems for Evaluation and Reinforcement Learning | |  |
| 2025-09 | Loong | Loong: Synthesize Long Chain-of-Thoughts at Scale through Verifiers | |  |
| 2025-07 | MegaScience | MegaScience: Pushing the Frontiers of Post-Training Datasets for Science Reasoning | | - |
| 2025-06 | ReasonMed | ReasonMed: A 370K Multi-Agent Generated Dataset for Advancing Medical Reasoning | |  |
| 2025-05 | ChemCoTDataset | Beyond Chemical QA: Evaluating LLM's Chemical Reasoning with Modular Chemical Operations | | - |
| 2025-02 | NaturalReasoning | NaturalReasoning: Reasoning in the Wild with 2.8M Challenging Questions | | - |
| 2025-01 | SCP-116K | SCP-116K: A High-Quality Problem-Solution Dataset and a Generalized Pipeline for Automated Extraction in the Higher Education Science Domain | | - |
Static Corpus (Math)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-07 | MiroMind-M1-RL-62K | MiroMind-M1: An Open-Source Advancement in Mathematical Reasoning via Context-Aware Multi-Stage Policy Optimization | |  |
| 2025-04 | DeepMath | DeepMath-103K: A Large-Scale, Challenging, Decontaminated, and Verifiable Mathematical Dataset for Advancing Reasoning | |  |
| 2025-04 | OpenMathReasoning | AIMO-2 Winning Solution: Building State-of-the-Art Mathematical Reasoning Models with OpenMathReasoning dataset | |  |
| 2025-03 | STILL-3-RL | An Empirical Study on Eliciting and Improving R1-like Reasoning Models | |  |
| 2025-03 | Light-R1 | Light-R1: Curriculum SFT, DPO and RL for Long COT from Scratch and Beyond | | - |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-03 | OpenReasoningZero | Open-Reasoner-Zero: An Open Source Approach to Scaling Up Reinforcement Learning on the Base Model | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| 2025-02 | LIMO | Limo: Less is more for reasoning | |  |
| 2025-02 | LIMR | Limr: Less is more for rl scaling | |  |
| 2025-02 | Big-MATH | Big-Math: A Large-Scale, High-Quality Math Dataset for Reinforcement Learning in Language Models | | - |
| - | NuminaMath 1.5 | Numinamath: The largest public dataset in ai4maths with 860k pairs of competition math problems and solutions | |  |
| - | OpenR1-Math | Open R1: A fully open reproduction of DeepSeek-R1 | |  |
| - | DeepScaleR | DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL | | - |
Static Corpus (Agent)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | ASearcher | Beyond Ten Turns: Unlocking Long-Horizon Agentic Search with Large-Scale Asynchronous RL | | - |
| 2025-07 | WebShaper | WebShaper: Agentically Data Synthesizing via Information-Seeking Formalization | | - |
| 2025-05 | ZeroSearch | ZeroSearch: Incentivize the Search Capability of LLMs without Searching | |  |
| 2025-04 | ToolRL | ToolRL: Reward is All Tool Learning Needs | |  |
| 2025-03 | Search-R1 | Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning | |  |
| 2025-03 | ToRL | ToRL: Scaling Tool-Integrated RL | |  |
| - | MicroThinker | MiroVerse V0.1: A Reproducible, Full-Trajectory, Ever-Growing Deep Research Dataset | | - |
| 2025-03 | DeepRetrieval | DeepRetrieval: Hacking Real Search Engines and Retrievers with Large Language Models via Reinforcement Learning | |  |
Static Corpus (Mix)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | Graph-R1 | Graph-R1: Unleashing LLM Reasoning with NP-Hard Graph Problem | | - |
| 2025-06 | RewardAnything | RewardAnything: Generalizable Principle-Following Reward Models | | |
| 2025-06 | guru-RL-92k | Revisiting Reinforcement Learning for LLM Reasoning from A Cross-Domain Perspective | | - |
| 2025-05 | Llama-Nemotron-PT | Llama-Nemotron: Efficient Reasoning Models | | - |
| 2025-05 | SkyWork OR1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-03 | OpenVLThinker | OpenVLThinker: Complex Vision-Language Reasoning via Iterative SFT-RL Cycles | | |
| - | AM-DS-R1-0528-Distilled | AM-DeepSeek-R1-0528-Distilled | |  |
| - | dolphin-r1 | Dolphin R1 Dataset | | - |
| - | SYNTHETIC-1/2 | SYNTHETIC-1 Release: Two Million Collaboratively Generated Reasoning Traces from Deepseek-R1 | | - |
Dynamic Environment (Rule-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | ProtoReasoning | ProtoReasoning: Prototypes as the Foundation for Generalizable Reasoning in LLMs | | - |
| 2025-05 | SynLogic | SynLogic: Synthesizing Verifiable Reasoning Data at Scale for Learning Logical Reasoning and Beyond | |  |
| 2025-05 | Reasoning Gym | REASONING GYM: Reasoning Environments for Reinforcement Learning with Verifiable Rewards | |  |
| 2025-05 | Enigmata | Enigmata: Scaling Logical Reasoning in Large Language Models with Synthetic Verifiable Puzzles | |  |
| 2025-02 | AutoLogi | AutoLogi: Automated Generation of Logic Puzzles for Evaluating Reasoning Abilities of Large Language Models | |  |
| 2025-02 | Logic-RL | Logic-RL: Unleashing LLM Reasoning with Rule-Based Reinforcement Learning | |  |
Dynamic Environment (Code-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | AgentCPM-GUI | AgentCPM-GUI: Building Mobile-Use Agents with Reinforcement Fine-Tuning | |  |
| 2025-06 | MedAgentGym | MedAgentGym: Training LLM Agents for Code-Based Medical Reasoning at Scale | |  |
| 2025-05 | MLE-Dojo | MLE-Dojo: Interactive Environments for Empowering LLM Agents in Machine Learning Engineering | |  |
| 2025-05 | SWE-rebench | SWE-rebench: An Automated Pipeline for Task Collection and Decontaminated Evaluation of Software Engineering Agents | | - |
| 2025-05 | ZeroGUI | ZeroGUI: Automating Online GUI Learning at Zero Human Cost | |  |
| 2025-04 | R2E-Gym | R2E-Gym: Procedural Environment Generation and Hybrid Verifiers for Scaling Open-Weights SWE Agents | |  |
| 2025-03 | ReSearch | ReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning | |  |
| 2025-02 | MLGym | MLGym: A New Framework and Benchmark for Advancing AI Research Agents | |  |
| 2024-07 | AppWorld | AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents | |  |
Dynamic Environment (Game-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | PuzzleJAX | PuzzleJAX: A Benchmark for Reasoning and Learning | |  |
| 2025-06 | Play to Generalize | Play to Generalize: Learning to Reason Through Game Play | |  |
| 2025-06 | Optimus-3 | Optimus-3: Towards Generalist Multimodal Minecraft Agents with Scalable Task Experts | |  |
| 2025-05 | lmgame-Bench | lmgame-Bench: How Good are LLMs at Playing Games? | |  |
| 2025-05 | G1 | G1: Bootstrapping Perception and Reasoning Abilities of Vision-Language Model via Reinforcement Learning | |  |
| 2025-05 | Code2Logic | Code2Logic: Game-Code-Driven Data Synthesis for Enhancing VLMs General Reasoning | |  |
| 2025-05 | KORGym | KORGym: A Dynamic Game Platform for LLM Reasoning Evaluation | |  |
| 2025-04 | Cross-env-coop | Cross-environment Cooperation Enables Zero-shot Multi-agent Coordination | |  |
| 2022-03 | ScienceWorld | ScienceWorld: Is your Agent Smarter than a 5th Grader? | |  |
| 2020-10 | ALFWorld | ALFWorld: Aligning Text and Embodied Environments for Interactive Learning | |  |
Dynamic Environment (Model-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | SwS | SwS: Self-aware Weakness-driven Problem Synthesis in Reinforcement Learning for LLM Reasoning | |  |
| 2025-06 | SPIRAL | SPIRAL: Self-Play on Zero-Sum Games Incentivizes Reasoning via Multi-Agent Multi-Turn Reinforcement Learning | |  |
| 2025-05 | Absolute Zero | Absolute Zero: Reinforced Self-play Reasoning with Zero Data | | |
| 2025-04 | TextArena | TextArena | |  |
| 2025-03 | SWEET-RL | SWEET-RL: Training Multi-Turn LLM Agents on Collaborative Reasoning Tasks | | |
| - | Genie 3 | Genie 3: A new frontier for world models | | - |
Dynamic Environment (Ensemble-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | InternBootcamp | InternBootcamp Technical Report: Boosting LLM Reasoning with Verifiable Task Scaling | |  |
| - | SYNTHETIC-2 | SYNTHETIC-2 Release: Four Million Collaboratively Generated Reasoning Traces | | - |
RL Infrastructure (Primary)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | ROLL | Reinforcement Learning Optimization for Large-Scale Learning: An Efficient and User-Friendly Scaling Library | |  |
| 2025-05 | AReaL | AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning | |  |
| 2024-09 | veRL | HybridFlow: A Flexible and Efficient RLHF Framework | |  |
| 2024-05 | OpenRLHF | OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework | | |
| - | TRL | Transformer Reinforcement Learning | - |  |
| - | NeMo-RL | Nemo RL: A Scalable and Efficient Post-Training Library | - |  |
| - | slime | slime: An SGLang-Native Post-Training Framework for RL Scaling | - |  |
| - | RLinf | RLinf: Reinforcement Learning Infrastructure for Agentic AI | - |  |
RL Infrastructure (Secondary)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | RL-Factory | RLFactory: A Plug-and-Play Reinforcement Learning Post-Training Framework for LLM Multi-Turn Tool-Use | |  |
| 2025-09 | verl-tool | VerlTool: Towards Holistic Agentic Reinforcement Learning with Tool Use | |  |
| 2025-09 | dLLM-RL | Revolutionizing Reinforcement Learning Framework for Diffusion Large Language Models | |  |
| 2025-08 | agent-lightning | Agent Lightning: Train ANY AI Agents with Reinforcement Learning | |  |
| 2025-05 | verl-agent | Group-in-Group Policy Optimization for LLM Agent Training | | |
| 2025-04 | VLM-R1 | VLM-R1: A stable and generalizable R1-style Large Vision-Language Model | |  |
| - | rllm | rLLM: A Framework for Post-Training Language Agents | - | |
| - | EasyR1 | EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework | - |  |
| - | verifiers | Verifiers: Reinforcement Learning with LLMs in Verifiable Environments | - |  |
| - | prime-rl | PRIME-RL: Decentralized RL Training at Scale | - |  |
| - | MARTI | A Framework for LLM-based Multi-Agent Reinforced Training and Inference | - | |
Applications
Coding Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | - | Reinforcement Learning for Machine Learning Engineering Agents | | - |
| 2025-09 | - | Advancing SLM Tool-Use Capability using Reinforcement Learning | | - |
| 2025-09 | SimpleTIR | SimpleTIR: End-to-End Reinforcement Learning for Multi-Turn Tool-Integrated Reasoning | |  |
| 2025-09 | - | The Illusion of Diminishing Returns: Measuring Long Horizon Execution in LLMs | |  |
| 2025-08 | GLM-4.5 | GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models | | |
| 2025-08 | FormaRL | FormaRL: Enhancing Autoformalization with no Labeled Data | |  |
| 2025-08 | RLTR | Encouraging Good Processes Without the Need for Good Answers: Reinforcement Learning for LLM Agent Planning | | - |
| 2025-07 | ARPO | Agentic Reinforced Policy Optimization | |  |
| 2025-07 | Kimi K2 | Kimi K2: Open Agentic Intelligence | | - |
| 2025-07 | AutoTIR | AutoTIR: Autonomous Tools Integrated Reasoning via Reinforcement Learning | |  |
| 2025-06 | CoRT | CoRT: Code-integrated Reasoning within Thinking | |  |
| 2025-05 | EvoScale | Satori-SWE: Evolutionary Test-Time Scaling for Sample-Efficient Software Engineering | |  |
| 2025-03 | ToRL | ToRL: Scaling Tool-Integrated RL | | |
| 2025-02 | SWE-RL | SWE-RL: Advancing LLM Reasoning via Reinforcement Learning on Open Software Evolution | |  |
| - | Qwen3-Coder | Qwen3-Coder: Agentic Coding in the World. | - |  |
Search Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | SSRL | SSRL: Self-Search Reinforcement Learning | |  |
| 2025-07 | WebSailor | WebSailor: Navigating Super-human Reasoning for Web Agent | |  |
| 2025-07 | WebShaper | WebShaper: Agentically Data Synthesizing via Information-Seeking Formalization | | |
| 2025-05 | ZeroSearch | ZeroSearch: Incentivize the Search Capability of LLMs without Searching | | |
| 2025-05 | SEM | SEM: Reinforcement Learning for Search-Efficient Large Language Models | | - |
| 2025-05 | S3 | s3: You Don't Need That Much Data to Train a Search Agent via RL | |  |
| 2025-05 | StepSearch | StepSearch: Igniting LLMs Search Ability via Step-Wise Proximal Policy Optimization | | |
| 2025-05 | R1-Searcher++ | R1-Searcher++: Incentivizing the Dynamic Knowledge Acquisition of LLMs via Reinforcement Learning | |  |
| 2025-04 | ReZero | ReZero: Enhancing LLM search ability by trying one-more-time | | - |
| 2025-03 | DeepRetrieval | DeepRetrieval: Hacking Real Search Engines and Retrievers with Large Language Models via Reinforcement Learning | | |
| 2025-03 | Search-R1 | Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning | | |
| 2025-03 | R1-Searcher | R1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning | |  |
Browser-Use Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | WebAgent-R1 | WebAgent-R1: Training Web Agents via End-to-End Multi-Turn Reinforcement Learning | |  |
| 2025-05 | WebDancer | WebDancer: Towards Autonomous Information Seeking Agency | | |
| 2025-04 | DeepResearcher | DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments | |  |
| 2024-11 | Web-RL | WebRL: Training LLM Web Agents via Self-Evolving Online Curriculum Reinforcement Learning | |  |
| 2021-12 | WebGPT | WebGPT: Browser-assisted question-answering with human feedback | | - |
DeepResearch Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SFR-DeepResearch | SFR-DeepResearch: Towards Effective Reinforcement Learning for Autonomously Reasoning Single Agents | | - |
| 2025-09 | DeepDive | DeepDive: Advancing Deep Search Agents with Knowledge Graphs and Multi-Turn RL | |  |
| 2025-08 | Webwatcher | Webwatcher: Breaking new frontiers of vision-language deep research agent | | |
| 2025-08 | ASearcher | Beyond ten turns: Unlocking long-horizon agentic search with large-scale asynchronous rl | |  |
| 2025-08 | Atom-searcher | Atom-searcher: Enhancing agentic deep research via fine-grained atomic thought reward | |  |
| 2025-08 | MedResearcher-R1 | Medreseacher-r1: Expert-level medical deep researcher via a knowledge-informed trajectory synthesis framework | |  |
| 2025-06 | Jan-nano | Jan-nano Technical Report | | - |
| 2025-04 | WebThinker | WebThinker: Empowering Large Reasoning Models with Deep Research Capability | |  |
| - | Kimi-Researcher | Kimi-Researcher-End-to-End RL Training for Emerging Agentic Capabilities | | - |
| - | Mirothinker | Mirothinker: An open-source agentic model series trained for deep research and complex, long-horizon problem solving | |  |
GUI&Computer Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | UI-TARS 2 | UI-TARS-2 Technical Report: Advancing GUI Agent with Multi-Turn Reinforcement Learning | |  |
| 2025-08 | GUI-RC | Test-Time Reinforcement Learning for GUI Grounding via Region Consistency | |  |
| 2025-08 | Os-r1 | OS-R1: Agentic Operating System Kernel Tuning with Reinforcement Learning | |  |
| 2025-08 | ComputerRL | ComputerRL: Scaling End-to-End Online Reinforcement Learning for Computer Use Agents | | - |
| 2025-08 | Mobile-Agent-v3 | Mobile-Agent-v3: Fundamental Agents for GUI Automation | |  |
| 2025-08 | SWIRL | SWIRL: A Staged Workflow for Interleaved Reinforcement Learning in Mobile GUI Control | |  |
| 2025-08 | InquireMobile | InquireMobile: Teaching VLM-based Mobile Agent to Request Human Assistance via Reinforcement Fine-Tuning | | - |
| 2025-07 | MobileGUI-RL | MobileGUI-RL: Advancing Mobile GUI Agent through Reinforcement Learning in Online Environment | | - |
| 2025-06 | GUI-Critic-R1 | Look Before You Leap: A GUI-Critic-R1 Model for Pre-Operative Error Diagnosis in GUI Automation | | |
| 2025-06 | GUI-Reflection | GUI-Reflection: Empowering Multimodal GUI Models with Self-Reflection Behavior | | - |
| 2025-06 | Mobile-R1 | Mobile-R1: Towards Interactive Reinforcement Learning for VLM-Based Mobile Agent via Task-Level Rewards | | - |
| 2025-05 | UIShift | UIShift: Enhancing VLM-based GUI Agents through Self-supervised Reinforcement Learning | |  |
| 2025-05 | GUI-G1 | GUI-G1: Understanding R1-Zero-Like Training for Visual Grounding in GUI Agents | |  |
| 2025-05 | ARPO | ARPO:End-to-End Policy Optimization for GUI Agents with Experience Replay | | |
| 2025-05 | ZeroGUI | ZeroGUI: Automating Online GUI Learning at Zero Human Cost | | |
| 2025-04 | GUI-R1 | GUI-R1 : A Generalist R1-Style Vision-Language Action Model For GUI Agents | |  |
| 2025-03 | UI-R1 | UI-R1: Enhancing Efficient Action Prediction of GUI Agents by Reinforcement Learning | |  |
| 2025-01 | UI-TARS | UI-TARS: Pioneering Automated GUI Interaction with Native Agents | |  |
Recommendation Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-07 | Shop-R1 | Shop-R1: Rewarding LLMs to Simulate Human Behavior in Online Shopping via Reinforcement Learning | | - |
| 2025-03 | Rec-R1 | Rec-R1: Bridging LLMs and Recommendation Systems via Reinforcement Learning | |  |
Agent (Others)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-07 | OpenTable-R1 | OpenTable-R1: A Reinforcement Learning Augmented Tool Agent for Open-Domain Table Question Answering | |  |
| 2025-07 | LaViPlan | LaViPlan : Language-Guided Visual Path Planning with RLVR | | - |
| 2025-06 | Drive-R1 | Drive-R1: Bridging Reasoning and Planning in VLMs for Autonomous Driving with Reinforcement Learning | | - |
| - | EPO | EPO: Entropy-regularized Policy Optimization for LLM Agents Reinforcement Learning | |  |
Code Generation
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Proof2Silicon | Proof2Silicon: Prompt Repair for Verified Code and Hardware Generation via Reinforcement Learning | | - |
| 2025-09 | AR$^2$ | AR$^2$: Adversarial Reinforcement Learning for Abstract Reasoning in Large Language Models | |  |
| 2025-09 | Dream-Coder | Dream-Coder 7B: An Open Diffusion Language Model for Code | |  |
| 2025-08 | MSRL | Breaking the SFT Plateau: Multimodal Structured Reinforcement Learning for Chart-to-Code Generation | | - |
| 2025-07 | CogniSQL-R1-Zero | CogniSQL-R1-Zero: Lightweight Reinforced Reasoning for Efficient SQL Generation | | - |
| 2025-07 | Leanabell-Prover-V2 | Leanabell-Prover-V2: Verifier-integrated Reasoning for Formal Theorem Proving via Reinforcement Learning | |  |
| 2025-07 | StepFun-Prover | StepFun-Prover Preview: Let's Think and Verify Step by Step | |  |
| 2025-06 | MedAgentGym | MedAgentGym: Training LLM Agents for Code-Based Medical Reasoning at Scale | | |
| 2025-05 | Fortune | Fortune: Formula-Driven Reinforcement Learning for Symbolic Table Reasoning in Language Models | |  |
| 2025-05 | VeriReason | VeriReason: Reinforcement Learning with Testbench Feedback for Reasoning-Enhanced Verilog Generation | |  |
| 2025-05 | ReEX-SQL | ReEx-SQL: Reasoning with Execution-Aware Reinforcement Learning for Text-to-SQL | | - |
| 2025-05 | AceReason-Nemotron | AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning | | - |
| 2025-05 | SkyWork OR1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-05 | CodeV-R1 | CodeV-R1: Reasoning-Enhanced Verilog Generation | |  |
| 2025-05 | AReaL | AREAL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning | | |
| 2025-04 | SQL-R1 | SQL-R1: Training Natural Language to SQL Reasoning Model By Reinforcement Learning | |  |
| 2025-04 | Kimina-Prover | Kimina-Prover Preview: Towards Large Formal Reasoning Models with Reinforcement Learning | | - |
| 2025-04 | DeepSeek-Prover-V2 | DeepSeek-Prover-V2: Advancing Formal Mathematical Reasoning via Reinforcement Learning for Subgoal Decomposition | |  |
| 2025-03 | Reasoning-SQL | Reasoning-SQL: Reinforcement Learning with SQL Tailored Partial Rewards for Reasoning-Enhanced Text-to-SQL | | - |
| - | code-r1 | Code-R1: Reproducing R1 for Code with Reliable Rewards | - | |
| - | Open-R1 | Open-R1: a fully open reproduction of DeepSeek-R1 | | |
| - | DeepCoder | Deepcoder: A fully open-source 14b coder at o3-mini level | | |
Software Engineering
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | UTRL | Learning to Generate Unit Test via Adversarial Reinforcement Learning | | - |
| 2025-07 | RePaCA | RePaCA: Leveraging Reasoning Large Language Models for Static Automated Patch Correctness Assessment | | - |
| 2025-07 | Repair-R1 | Repair-R1: Better Test Before Repair | |  |
| 2025-06 | CURE | Co-Evolving LLM Coder and Unit Tester via Reinforcement Learning | |  |
| 2025-05 | REAL | Training Language Models to Generate Quality Code with Program Analysis Feedback | | - |
| 2025-05 | Afterburner | Afterburner: Reinforcement Learning Facilitates Self-Improving Code Efficiency Optimization | |  |
| 2024-09 | RepoGenReflex | RepoGenReflex: Enhancing Repository-Level Code Completion with Verbal Reinforcement and Retrieval-Augmented Generation | | - |
| 2024-07 | RLCoder | RLCoder: Reinforcement Learning for Repository-Level Code Completion | |  |
Multimodal Understanding
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2026-03 | 3D-RFT | 3D-RFT: Reinforcement Fine-Tuning for Video-based 3D Scene Understanding | | |
| 2025-09 | Vision-Zero | Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | | |
| 2025-09 | ReAd-R | AdsQA: Towards Advertisement Video Understanding | |  |
| 2025-09 | Keye | Kwai Keye-VL 1.5 Technical Report | |  |
| 2025-08 | Sifthinker | Sifthinker: Spatially-aware image focus for visual reasoning | |  |
| 2025-07 | Long-RL | Scaling rl to long videos | |  |
| 2025-06 | RefSpatial | Roborefer: Towards spatial referring with reasoning in vision-language models for robotics | |  |
| 2025-06 | Ego-R1 | Ego-R1: Chain-of-tool-thought for ultra-long egocentric video reasoning | |  |
| 2025-05 | VerIPO | VerIPO: Long Reasoning Video-R1 Model with Iterative Policy Optimization | | |
| 2025-05 | Openthinkimg | Openthinkimg: Learning to think with images via visual tool reinforcement learning | |  |
| 2025-05 | Visual Planning | Visual Planning: Let's think only with images | |  |
| 2025-05 | VideoRFT | Videorft: Incentivizing video reasoning capability in mllms via reinforced fine-tuning | |  |
| 2025-05 | Deepeyes | Deepeyes: Incentivizing" thinking with images" via reinforcement learning | |  |
| 2025-05 | Visionary-R1 | Visionary-R1: Mitigating shortcuts in visual reasoning with reinforcement learning | |  |
| 2025-05 | CoF | Chain-of-focus: Adaptive visual search and zooming for multimodal reasoning via rl | |  |
| 2025-05 | GRIT | GRIT: Teaching mllms to think with images | |  |
| 2025-05 | Pixel Reasoner | Pixel Reasoner: Incentivizing pixel-space reasoning with curiosity-driven reinforcement learning | |  |
| 2025-05 | - | Don’t look only once: Towards multimodal interactive reasoning with selective visual revisitation | |  |
| 2025-05 | Ground-R1 | Ground-R1: Incentivizing grounded visual reasoning via reinforcement learning | |  |
| 2025-05 | TACO | TACO: Think-answer consistency for optimized long-chain reasoning and efficient data learning via reinforcement learning in lvlms | | - |
| 2025-05 | Qwen-LA | Qwen look again: Guiding vision-language reasoning models to re-attention visual information | |  |
| 2025-05 | TW-GRPO | Reinforcing video reasoning with focused thinking | |  |
| 2025-05 | Spatial-MLLM | Spatial-MLLM: Boosting mllm capabilities in visual-based spatial intelligence | |  |
| 2025-04 | R1-Zero-VSI | Improved visual-spatial reasoning via r1-zero-like training | |  |
| 2025-04 | Spacer | Spacer: Reinforcing mllms in video spatial reasoning | |  |
| 2025-04 | Videochat-R1 | Videochat-R1: Enhancing spatio-temporal perception via reinforcement fine-tuning | |  |
| 2025-04 | VLM-R1 | VLM-R1: A stable and generalizable r1-style large vision-language model | | |
| 2025-03 | OpenVLThinker | OpenVLThinker: Complex Vision-Language Reasoning via Iterative SFT-RL Cycles | | |
| 2025-03 | Visual-RFT | Visual-RFT: Visual reinforcement fine-tuning | |  |
| 2025-03 | Vision-R1 | Vision-R1: Incentivizing reasoning capability in multimodal large language models | |  |
| 2025-03 | VisRL | VisRL: Intention-Driven Visual Perception via Reinforced Reasoning | |  |
| 2025-03 | Metaspatial | Metaspatial: Reinforcing 3d spatial reasoning in vlms for the metaverse | |  |
| 2025-03 | Video-R1 | Video-R1: Reinforcing video reasoning in mllms | |  |
| 2025-09 | Vision-Zero | Vision-Zero: Scalable VLM Self-Improvement via strategic Gamified Self-Play | | |
Multimodal Generation
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | IGPO | Inpainting-Guided Policy Optimization for Diffusion Large Language Models | | - |
| 2025-08 | Qwen-Image | Qwen-Image Technical Report | |  |
| 2025-08 | TempFlow-GRPO | TempFlow-GRPO: When timing matters for grpo in flow models | |  |
| 2025-07 | MixGRPO | MixGRPO: Unlocking flow-based grpo efficiency with mixed ode-sde | |  |
| 2025-06 | FocusDiff | Focusdiff: Advancing fine-grained text-image alignment for autoregressive visual generation through rl | |  |
| 2025-06 | SUDER | Reinforcing multimodal understanding and generation with dual self-rewards | | - |
| 2025-05 | T2I-R1 | T2I-R1: Reinforcing image generation with collaborative semantic-level and token-level cot | |  |
| 2025-05 | Flow-GRPO | Flow-GRPO: Training flow matching models via online rl | |  |
| 2025-05 | DanceGRPO | DanceGRPO: Unleashing grpo on visual generation | |  |
| 2025-05 | GoT-R1 | GoT-R1: Unleashing reasoning capability of mllm for visual generation with reinforcement learning | |  |
| 2025-05 | ULM-R1 | Co-Reinforcement learning for unified multimodal understanding and generation | |  |
| 2025-05 | RePrompt | Reprompt: Reasoning-augmented reprompting for text-to-image generation via reinforcement learning | |  |
| 2025-05 | InfLVG | InfLVG: Reinforce inference-time consistent long video generation with grpo | |  |
| 2025-05 | Reasongen-R1 | Reasongen-R1: Cot for autoregressive image generation models through sft and rl | |  |
| 2025-04 | PhysAR | Reasoning physical video generation with diffusion timestep tokens via reinforcement learning | | - |
Robotics Tasks
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SimpleVLA-RL | SimpleVLA-RL: Scaling VLA Training via Reinforcement Learning | |  |
| 2025-06 | TGRPO | TGRPO :Fine-tuning Vision-Language-Action Model via Trajectory-wise Group Relative Policy Optimization | | - |
| 2025-05 | ReinboT | ReinboT: Amplifying Robot Visual-Language Manipulation with Reinforcement Learning | |  |
| 2025-05 | RIPT-VLA | InteractivePost-Trainingfor Vision-Language-ActionModels | |  |
| 2025-05 | VLA-RL | VLA-RL: Towards Masterful and General Robotic Manipulation with Scalable Reinforcement Learning | |  |
| 2025-05 | RFTF | RFTF: Reinforcement Fine-tuning for Embodied Agents with Temporal Feedback | | - |
| 2025-05 | VLA Generalization | What can rl bring to vla generalization? an empirical study | |  |
| 2025-02 | ConRFT | ConRFT: A Reinforced Fine-tuning Method for VLA Models via Consistency Policy | |  |
| 2024-11 | GRAPE | GRAPE: Generalizing Robot Policy via Preference Alignment | | |
| - | RLinf | RLinf: Reinforcement Learning Infrastructure for Agentic AI | | - |
| - | EPO | EPO: Entropy-regularized Policy Optimization for LLM Agents Reinforcement Learning | | |
Multi-Agent Systems
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-10 | AgentFlow | In-the-Flow Agentic System Optimization for Effective Planning and Tool Use | |  |
| 2025-09 | SoftRankPO, | Learning to Deliberate: Meta-policy Collaboration for Agentic LLMs with Multi-agent Reinforcement Learning | | - |
| 2025-09 | BFS-Prover-V2 | Scaling up Multi-Turn Off-Policy RL and Multi-Agent Tree Search for LLM Step-Provers | | - |
| 2025-08 | MAGRPO | LLM Collaboration With Multi-Agent Reinforcement Learning | | - |
| 2025-06 | AlphaEvolve | AlphaEvolve: A coding agent for scientific and algorithmic discovery | | - |
| 2025-06 | JoyAgents-R1 | JoyAgents-R1: Joint Evolution Dynamics for Versatile Multi-LLM Agents with Reinforcement Learning | | - |
| 2025-03 | ReMA | ReMA: Learning to Meta-think for LLMs with Multi-agent Reinforcement Learning | |  |
| 2025-02 | CTRL | Teaching Language Models to Critique via Reinforcement Learning | |  |
| 2025-02 | Maporl | MAPoRL2: Multi-Agent Post-Co-Training for Collaborative Large Language Models with Reinforcement Learning | |  |
| 2023-11 | LLaMAC | Controlling large language model-based agents for large-scale decision-making: An actor-critic approach | | - |
Scientific Tasks
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Baichuan-M2 | Baichuan-M2: Scaling Medical Capability with Large Verifier System | | - |
| 2025-08 | CX-Mind | CX-Mind: A Pioneering Multimodal Large Language Model for Interleaved Reasoning in Chest X-ray via Curriculum-Guided Reinforcement Learning | |  |
| 2025-08 | MORE-CLEAR | MORE-CLEAR: Multimodal Offline Reinforcement learning for Clinical notes Leveraged Enhanced State Representation | | - |
| 2025-08 | ARMed | Breaking Reward Collapse: Adaptive Reinforcement for Open-ended Medical Reasoning with Enhanced Semantic Discrimination | | - |
| 2025-08 | ProMed | ProMed: Shapley Information Gain Guided Reinforcement Learning for Proactive Medical LLMs | |  |
| 2025-08 | OwkinZero | OwkinZero: Accelerating Biological Discovery with AI | | - |
| 2025-08 | MolReasoner | MolReasoner: Toward Effective and Interpretable Reasoning for Molecular LLMs | |  |
| 2025-08 | MedGR$^2$ | MedGR$^2$: Breaking the Data Barrier for Medical Reasoning via Generative Reward Learning | | - |
| 2025-07 | MedGround-R1 | MedGround-R1: Advancing Medical Image Grounding via Spatial-Semantic Rewarded Group Relative Policy Optimization | |  |
| 2025-07 | MedGemma | MedGemma Technical Report | [


Similar repos


Languages
TeX
100.0%
A Survey of Reinforcement Learning for Large Reasoning Models
See the codeREADME
A Survey of Reinforcement Learning for Large Reasoning Models
We welcome everyone to open an issue for any related work we haven’t discussed, and we’ll try to address it in the next release!
🎉 News
- [2026-07-31] 🎉 First OpenRSI release: Frontis-MA1 (35B / 30B, with GGUF derivatives), the OpenMLE stack (Gym / RL / Evo), and the OpenMLE Tasks and OpenMLE SFT Traces datasets. Check it out: GitHub.
- [2026-06-25] 🎉 Our survey Self-Improving Agents in the Era of Experience: A Survey of Self- to Meta-Evolution is now available on OpenReview. Check it out: GitHub and OpenReview.
- [2025-11-05] 🔥 Excited to release our paper list about Memory for Agents, covering breakthroughs in Context Management and Learning from Experience powering self-improving AI agents. Check it out: GitHub
- [2025-10] 🎉 Honored to give talks at BAAI, Qingke Talk and Tencent Wiztalk! Here are the slides.
- [2025-09-18] 🎉 We update the full list of papers in the category structure of the survey!
- [2025-09-12] 🎉 Our survey was ranked #1 Paper of the Day on 🤗 Hugging Face Daily Papers!
- [2025-09-11] 🔥 Excited to release our RL for LRMs Survey! We’ll be updating the full list of papers in with a new category structure soon. Check it out: Paper.
- [2025-08-15] 🔥 Introducing SSRL: an investigation for Agentic Search RL without reliance on external search engine. Check it out: GitHub and Paper.
- [2025-05-27] 🔥 Introducing MARTI: A Framework for LLM-based Multi-Agent Reinforced Training and Inference. Check it out: Github.
- [2025-04-23] 🔥 Introducing TTRL: an open-source solution for online RL on data without ground-truth labels, especially test data. Check it out: Github and Paper.
- [2025-03-20] 🔥 We are excited to introduce collection of papers and projects on RL for reasoning models!
🎈 Citation
If you find this survey helpful, please cite our work:
@article{zhang2025survey,
  title={A survey of reinforcement learning for large reasoning models},
  author={Zhang, Kaiyan and Zuo, Yuxin and He, Bingxiang and Sun, Youbang and Liu, Runze and Jiang, Che and Fan, Yuchen and Tian, Kai and Jia, Guoli and Li, Pengfei and others},
  journal={arXiv preprint arXiv:2509.08827},
  year={2025}
}
📖 Contents
- A Survey of Reinforcement Learning for Large Reasoning Models
- 🎉 News
- 🎈 Citation
- 📖 Contents
- 🗺️ Overview
- 📄 Paper List
- Frontier Models
- Reward Design
- Policy Optimization
- Sampling Strategy
- Training Resource
- Static Corpus (Code)
- Static Corpus (STEM)
- Static Corpus (Math)
- Static Corpus (Agent)
- Static Corpus (Mix)
- Dynamic Environment (Rule-based)
- Dynamic Environment (Code-based)
- Dynamic Environment (Game-based)
- Dynamic Environment (Model-based)
- Dynamic Environment (Ensemble-based)
- RL Infrastructure (Primary)
- RL Infrastructure (Secondary)
- Applications
- 🌟 Acknowledgment
- ✨ Star History
🗺️ Overview
Our survey provides a comprehensive examination of Reinforcement Learning for Large Reasoning Models.
We organize the survey into five main sections:
- Foundational Components: Reward design, policy optimization, and sampling strategies
- Foundational Problems: Key debates and challenges in RL for LRMs
- Training Resources: Static corpora, dynamic environments, and infrastructure
- Applications: Real-world implementations across diverse domains
- Future Directions: Emerging research opportunities and challenges
📄 Paper List
Frontier Models
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | Intern-S1 | Intern-S1: A Scientific Multimodal Foundation Model | | |
| 2025-08 | GLM-4.5 | GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models | | |
| 2025-08 | gpt-oss | gpt-oss-120b & gpt-oss-20b Model Card | | |
| 2025-08 | InternVL3.5 | InternVL3.5: Advancing Open-Source Multimodal Models in Versatility, Reasoning, and Efficiency | | |
| 2025-07 | Kimi K2 | Kimi K2: Open Agentic Intelligence | | |
| 2025-07 | Step 3 | Step-3 is Large yet Affordable: Model-system Co-design for Cost-effective Decoding | | |
| 2025-07 | GLM-4.1V-Thinking | GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning | | |
| 2025-07 | Skywork-R1V3 | Skywork-R1V3 Technical Report | | |
| 2025-07 | GLM-4.5V | GLM-4.5V and GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning | | |
| 2025-06 | Magistral | Magistral | | - |
| 2025-06 | Minimax-M1 | MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning Attention | | |
| 2025-05 | MiMo | MiMo: Unlocking the Reasoning Potential of Language Model -- From Pretraining to Posttraining | | |
| 2025-05 | Qwen3 | Qwen3 Technical Report | | |
| 2025-05 | Llama-Nemotron-Ultra | Llama-Nemotron: Efficient Reasoning Models | | |
| 2025-05 | INTELLECT-2 | INTELLECT-2: A Reasoning Model Trained Through Globally Decentralized Reinforcement Learning | | - |
| 2025-05 | Hunyuan-TurboS | Hunyuan-TurboS: Advancing Large Language Models through Mamba-Transformer Synergy and Adaptive Chain-of-Thought | | |
| 2025-05 | Skywork OR-1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-04 | Phi-4 Reasoning | Phi-4-reasoning Technical Report | | - |
| 2025-04 | Skywork-R1V2 | Skywork R1V2: Multimodal Hybrid Reinforcement Learning for Reasoning | | |
| 2025-04 | InternVL3 | InternVL3: Exploring Advanced Training and Test-Time Recipes for Open-Source Multimodal Models | | |
| 2025-03 | ORZ | Open-Reasoner-Zero: An Open Source Approach to Scaling Up Reinforcement Learning on the Base Model | | |
| 2025-01 | DeepSeek-R1 | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning | | |
| - | QwQ | QwQ-32B: Embracing the Power of Reinforcement Learning | | |
| - | Seed-OSS | Seed-OSS Open-Source Models | | |
| - | ERNIE-4.5-Thinking | ERNIE 4.5 Technical Report | | - |
Reward Design
Generative Rewards
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2026-06 | - | Steer, Don't Solve: Training Small Critic Models for Large Code Agents | | |
| 2025-08 | CAPO | CAPO: Towards Enhancing LLM Reasoning through Verifiable Generative Credit Assignment | | |
| 2025-08 | CompassVerifier | CompassVerifier: A Unified and Robust Verifier for LLMs Evaluation and Outcome Reward | | |
| 2025-08 | Cooper | Cooper: Co-Optimizing Policy and Reward Models in Reinforcement Learning for Large Language Models | | |
| 2025-08 | ReviewRL | ReviewRL: Towards Automated Scientific Review with RL | | |
| 2025-08 | Rubicon | Reinforcement Learning with Rubric Anchors | | - |
| 2025-08 | RuscaRL | Breaking the Exploration Bottleneck: Rubric-Scaffolded Reinforcement Learning for General LLM Reasoning | | - |
| 2025-07 | OMNI-THINKER | OMNI-THINKER: Scaling Cross-Domain Generalization in LLMs via Multi-Task RL with Hybrid Rewards | | - |
| 2025-07 | URPO | URPO: A Unified Reward & Policy Optimization Framework for Large Language Models | | - |
| 2025-07 | RaR | Rubrics as Rewards: Reinforcement Learning Beyond Verifiable Domains | | - |
| 2025-07 | RLCF | Checklists Are Better Than Reward Models For Aligning Language Models | | - |
| 2025-07 | PCL | Post-Completion Learning for Language Models | | - |
| 2025-07 | K2 | KIMI K2: OPEN AGENTIC INTELLIGENCE | | - |
| 2025-07 | LIBRA | LIBRA: ASSESSING AND IMPROVING REWARD MODEL BY LEARNING TO THINK | | - |
| 2025-07 | TP-GRPO | Good Learners Think Their Thinking: Generative PRM Makes Large Reasoning Model More Efficient Math Learner | | |
| 2025-06 | RewardAnything | RewardAnything: Generalizable Principle-Following Reward Models | | |
| 2025-06 | Writing-Zero | Writing-Zero: Bridge the Gap Between Non-verifiable Tasks and Verifiable Rewards | | - |
| 2025-06 | Critique-GRPO | Critique-GRPO: Advancing LLM Reasoning with Natural Language and Numerical Feedback | | |
| 2025-06 | PAG | PAG: Multi-Turn Reinforced LLM Self-Correction with Policy as Generative Verifier | | - |
| 2025-06 | GRAM | GRAM: A Generative Foundation Reward Model for Reward Generalization | | |
| 2025-06 | ProxyReward | From General to Targeted Rewards: Surpassing GPT-4 in Open-Ended Long-Context Generation | | - |
| 2025-06 | QA-LIGN | QA-LIGN: Aligning LLMs through Constitutionally Decomposed QA | | - |
| 2025-05 | RM-R1 | RM-R1: Reward Modeling as Reasoning | | |
| 2025-05 | J1 | J1: Incentivizing Thinking in LLM-as-a-Judge via RL | | - |
| 2025-05 | TinyV | TinyV: Reducing False Negatives in Verification Improves RL for LLM Reasoning | | |
| 2025-05 | General-Reasoner | General-reasoner: Advancing llm reasoning across all domains | | - |
| 2025-05 | RRM | Reward Reasoning Model | | - |
| 2025-05 | RL Tango | RL Tango: Reinforcing Generator and Verifier Together for Language Reasoning | | |
| 2025-05 | Think-RM | Think-RM: Enabling Long-Horizon Reasoning in Generative Reward Models | | |
| 2025-04 | JudgeLRM | JudgeLRM: Large Reasoning Models as a Judge | | |
| 2025-04 | GenPRM | GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning | | |
| 2025-04 | DeepSeek-GRM | Inference-Time Scaling for Generalist Reward Modeling | | - |
| 2025-04 | AIR | AIR: A Systematic Analysis of Annotations, Instructions, and Response Pairs in Preference Dataset | | - |
| 2025-04 | Pairwise-RL | A Unified Pairwise Framework for RLHF: Bridging Generative Reward Modeling and Policy Optimization | | - |
| 2025-04 | xVerify | xVerify: Efficient Answer Verifier for Reasoning Model Evaluations | | |
| 2025-04 | Seed-Thinking-v1.5 | Seed1.5-Thinking: Advancing Superb Reasoning Models with Reinforcement Learning | | - |
| 2025-04 | ThinkPRM | Process Reward Models That Think | | |
| 2025-03 | - | Crossing the Reward Bridge: Expanding RL with Verifiable Rewards Across Diverse Domains | | - |
| 2025-02 | - | Self-rewarding correction for mathematical reasoning | | |
| 2024-10 | GenRM | Generative Reward Models | | - |
| 2024-08 | CLoud | Critique-out-Loud Reward Models | | |
| 2024-08 | Generative Verifier | Generative Verifiers: Reward Modeling as Next-Token Prediction | | - |
| 2024-01 | Self-Rewarding LM | Self-Rewarding Language Models | | - |
| 2023-10 | Auto-J | Generative Judge for Evaluating Alignment | | |
| 2023-06 | Judge LLM-as-a-Judge | Judging llm-as-a-judge with mt-bench and chatbot arena | | |
Dense Rewards
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2026-09 | DRACO | DRACO: Fine-Grained Credit Assignment with Dynamic Rubrics for Long-Horizon Agent Training | | |
| 2025-09 | Tree-GRPO | Tree Search for LLM Agent Reinforcement Learning | | |
| 2025-09 | AttnRL | Attention as a Compass: Efficient Exploration for Process-Supervised RL in Reasoning Models | | |
| 2025-09 | TARL | Process-Supervised Reinforcement Learning for Interactive Multimodal Tool-Use Agents | | - |
| 2025-09 | PROF | Beyond Correctness: Harmonizing Process and Outcome Rewards through RL Training | | |
| 2025-09 | HICRA | Emergent Hierarchical Reasoning in LLMs through Reinforcement Learning | | - |
| 2025-08 | KlearReasoner | Klear-Reasoner: Advancing Reasoning Capability via Gradient-Preserving Clipping Policy Optimization | | |
| 2025-08 | CAPO | CAPO: Towards Enhancing LLM Reasoning through Verifiable Generative Credit Assignment | | |
| 2025-08 | GTPO & GRPO-S | GTPO and GRPO-S: Token and Sequence-Level Reward Shaping with Policy Entropy | | - |
| 2025-08 | VSRM | Promoting Efficient Reasoning with Verifiable Stepwise Reward | | - |
| 2025-08 | G-RA | Stabilizing Long-term Multi-turn Reinforcement Learning with Gated Rewards | | - |
| 2025-08 | SSPO | SSPO: Self-traced Step-wise Preference Optimization for Process Supervision and Reasoning Compression | | - |
| 2025-08 | AIRL-S | Your Reward Function for RL is Your Best PRM for Search: Unifying RL and Search-Based TTS | | - |
| 2025-08 | TreePO | TreePO: Bridging the Gap of Policy Optimization and Efficacy and Inference Efficiency with Heuristic Tree-based Modeling | | |
| 2025-08 | MUA-RL | MUA-RL: Multi-turn User-interacting Agent Reinforcement Learning for agentic tool use | | - |
| 2025-07 | SPRO | Self-Guided Process Reward Optimization with Redefined Step-wise Advantage for Process Reinforcement | | - |
| 2025-07 | FR3E | First Return, Entropy-Eliciting Explore | | - |
| 2025-07 | ARPO | Agentic Reinforced Policy Optimization | | |
| 2025-07 | TP-GRPO | Good Learners Think Their Thinking: Generative PRM Makes Large Reasoning Model More Efficient Math Learner | | |
| 2025-06 | TreeRPO | TreeRPO: Tree Relative Policy Optimization | | |
| 2025-06 | TreeRL | TreeRL: LLM Reinforcement Learning with On-Policy Tree Search | | |
| 2025-06 | Entropy Advantage | Reasoning with Exploration: An Entropy Perspective on Reinforcement Learning for LLMs | | - |
| 2025-06 | ReasonFlux-PRM | ReasonFlux-PRM: Trajectory-Aware PRMs for Long Chain-of-Thought Reasoning in LLMs | | |
| 2025-05 | S-GRPO | S-GRPO: Early Exit via Reinforcement Learning in Reasoning Models | | - |
| 2025-05 | GiGPO | Group-in-Group Policy Optimization for LLM Agent Training | | |
| 2025-05 | - | Reinforcing Multi-Turn Reasoning in LLM Agents via Turn-Level Credit Assignment | | - |
| 2025-05 | Tango | RL Tango: Reinforcing Generator and Verifier Together for Language Reasoning | | |
| 2025-05 | StepSearch | StepSearch: Igniting LLMs Search Ability via Step-Wise Proximal Policy Optimization | | |
| 2025-05 | - | Aligning Dialogue Agents with Global Feedback via Large Language Model Reward Decomposition | | - |
| 2025-05 | Tool-Star | Tool-Star: Empowering LLM-Brained Multi-Tool Reasoner via Reinforcement Learning | | |
| 2025-05 | SPA-RL | SPA-RL: Reinforcing LLM Agents via Stepwise Progress Attribution | | |
| 2025-05 | SPO | Segment Policy Optimization: Effective Segment-Level Credit Assignment in RL for Large Language Mode | | |
| 2025-04 | GenPRM | GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning | | |
| 2025-04 | PURE | Stop Summation: Min-Form Credit Assignment Is All Process Reward Model Needs for Reasoning | | |
| 2025-03 | MRT | Optimizing Test-Time Compute via Meta Reinforcement Fine-Tuning | | |
| 2025-03 | SWEET-RL | SWEET-RL: Training Multi-Turn LLM Agents on Collaborative Reasoning Tasks | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| 2024-12 | Implicit PRM | Free Process Rewards without Process Labels | | |
| 2024-10 | VinePPO | VinePPO: Refining Credit Assignment in RL Training of LLMs | | |
| 2024-10 | PAV | Rewarding Progress: Scaling Automated Process Verifiers for LLM Reasoning | | - |
| 2024-04 | - | From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function | | - |
| 2024-03 | GELI | Improving Dialogue Agents by Decomposing One Global Explicit Annotation with Local Implicit Multimodal Feedback | | - |
| 2023-12 | Math-Shepherd | Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations | | - |
| 2023-05 | PRM800K | Let's Verify Step by Step | | |
| 2022-11 | - | Solving math word problems with process- and outcome-based feedback | | - |
Unsupervised Rewards
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Vision-Zero | Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | | |
| 2025-08 | Co-Reward | Co-Reward: Self-supervised Reinforcement Learning for Large Language Model Reasoning via Contrastive Agreement | | |
| 2025-08 | SQLM | Self-Questioning Language Models | | |
| 2025-08 | R-zero | R-Zero: Self-Evolving Reasoning LLM from Zero Data | | |
| 2025-08 | ETTRL | ETTRL: Balancing Exploration and Exploitation in LLM Test-Time Reinforcement Learning Via Entropy Mechanism | | - |
| 2025-07 | RLSF | Post-Training Large Language Models via Reinforcement Learning from Self-Feedback | | - |
| 2025-06 | RLSC | Confidence Is All You Need: Few-Shot RL Fine-Tuning of Language Models | | - |
| 2025-06 | RPT | Reinforcement Pre-Training | | - |
| 2025-06 | CoVo | Consistent Paths Lead to Truth: Self-Rewarding Reinforcement Learning for LLM Reasoning | | |
| 2025-06 | SEAL | Self-Adapting Language Models | | - |
| 2025-06 | Spurious Rewards | Spurious Rewards: Rethinking Training Signals in RLVR | | |
| 2025-06 | No Free Lunch | No Free Lunch: Rethinking Internal Feedback for LLM Reasoning | | - |
| 2025-05 | Absolute Zero | Absolute Zero: Reinforced Self-play Reasoning with Zero Data | | |
| 2025-05 | EM-RL | The Unreasonable Effectiveness of Entropy Minimization in LLM Reasoning | | |
| 2025-05 | SSR-Zero | SSR-Zero: Simple Self-Rewarding Reinforcement Learning for Machine Translation | | |
| 2025-05 | - | Surrogate Signals from Format and Length: Reinforcement Learning for Solving Mathematical Problems without Ground Truth Answers | | |
| 2025-05 | RLIF | Learning to Reason without External Rewards | | |
| 2025-05 | SeRL | SeRL: Self-Play Reinforcement Learning for Large Language Models with Limited Data | | |
| 2025-05 | SRT | Can Large Reasoning Models Self-Train? | | |
| 2025-05 | RENT-RL | Maximizing Confidence Alone Improves Reasoning | | |
| 2025-04 | EMPO | Right Question is Already Half the Answer: Fully Unsupervised LLM Reasoning Incentivization | | |
| 2025-04 | TRANS-ZERO | TRANS-ZERO: Self-Play Incentivizes Large Language Models for Multilingual Translation Without Parallel Data | | |
| 2025-04 | TTRL | TTRL: Test-Time Reinforcement Learning | | |
| 2025-04 | One-Shot-RLVR | Reinforcement Learning for Reasoning in Large Language Models with One Training Example | | |
| 2025-02 | CAGSR | A Self-Supervised Reinforcement Learning Approach for Fine-Tuning Large Language Models Using Cross-Attention Signals | | - |
| 2024-07 | MINIMO | Learning Formal Mathematics From Intrinsic Motivation | | |
Rewards Shaping
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | CDE | CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models | | - |
| 2025-09 | DARLING | Jointly Reinforcing Diversity and Quality in Language Model Generations | | |
| 2025-09 | DRER | Rethinking Reasoning Quality in Large Language Models through Enhanced Chain-of-Thought via RL | | - |
| 2025-09 | OBE | Outcome-based Exploration for LLM Reasoning | | - |
| 2025-08 | Pass@kTraining | Pass@k Training for Adaptively Balancing Exploration and Exploitation of Large Reasoning Models | | |
| 2025-05 | PKPO | Pass@K Policy Optimization: Solving Harder Reinforcement Learning Problems | | - |
| 2025-05 | rl-without-gt | Surrogate Signals from Format and Length: Reinforcement Learning for Solving Mathematical Problems without Ground Truth Answers | | |
| 2025-03 | CrossDomain-RLVR | Crossing the Reward Bridge: Expanding RL with Verifiable Rewards Across Diverse Domains | | - |
| 2025-01 | DeepSeek-R1 | DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning | | |
| 2024-09 | Qwen2.5-Math | Qwen2. 5-math technical report: Toward mathematical expert model via self-improvement | | |
Policy Optimization
Policy Gradient Objective
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2017-07 | PPO | Proximal policy optimization algorithms | | - |
| - | PG | Policy gradient methods for reinforcement learning with function approximation. | | - |
| - | REINFORCE | Simple statistical gradient-following algorithms for connectionist reinforcement learning | | - |
| - | TRPO | Trust region policy optimization | | - |
Critic-based Algorithms
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | VL-DAC | Enhancing Vision-Language Model Training with Reinforcement Learning in Synthetic Worlds for Real-World Success | | |
| 2025-08 | VRPO | VRPO:Rethinking Value Modeling for Robust RL Training under Noisy Supervision | | - |
| 2025-05 | VerIPO | VerIPO: Long Reasoning Video-R1 Model with Iterative Policy Optimization | | |
| 2025-04 | VAPO | Vapo: Efficient and reliable reinforcement learning for advanced reasoning tasks | | - |
| 2025-03 | VCPPO | What’s Behind PPO’s Collapse in Long-CoT? Value Optimization Holds the Secret | | - |
| 2025-03 | Open reasoner-zero | open reasoner-zero: An open source approach to scaling up reinforcement learning on the base model | | |
| 2025-02 | PRIME | PROCESS REINFORCEMENT THROUGH IMPLICIT REWARDS | | |
| 2024-12 | Implicit PRM | FREE PROCESS REWARDS WITHOUT PROCESS LABELS | | |
| 2023-12 | Math-shepherd | Math-shepherd: Verify and reinforce LLMs step-by-step without human annotations | | - |
| 2015-06 | GAE | High-dimensional continuous control using generalized advantage estimation | | - |
| - | Autopsv | Autopsv: Automated process-supervised verifier. | | |
Critic-Free Algorithms
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | UPGE | Towards a Unified View o fLarge Language Model Post-Training | | |
| 2025-09 | SPO | Single-stream Policy Optimization | | - |
| 2025-08 | LitePPO | Part I: Tricks or Traps? A Deep Dive into RLfor LLM Reasoning | | - |
| 2025-07 | R1-RE | R1-RE: Cross-Domain Relation Extraction with RLVR | | - |
| 2025-07 | GSPO | Group Sequence Policy Optimization | | - |
| 2025-06 | CISPO | MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning Attention | | |
| 2025-05 | KRPO | Kalman Filter Enhanced Group Relative Policy Optimization for Language Model Reasoning | | |
| 2025-05 | CPGD | CPGD:Toward Stable Rule-based Reinforcement Learning for Language Models | | |
| 2025-05 | NFT | Bridging Supervised Learning and Reinforcement Learning in Math Reasoning | | - |
| 2025-05 | Clip-Cov/KL-Cov | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-03 | OpenVLThinker | OpenVLThinker: Complex Vision-Language Reasoning via Iterative SFT-RL Cycles | | |
| 2025-03 | DAPO | DAPO: an Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-03 | Dr. GRPO | Understanding R1-Zero-Like Training: A Critical Perspectiv | | |
| 2025-01 | Kimi k1.5 | Kimi k1.5: Scaling Reinforcement Learning with LLMs | | - |
| 2024-02 | RLOO | Back to basics: Revisiting reinforce style optimization for learning from human feedback in llms | | - |
| 2024-02 | GRPO | DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models | | |
| 2023-10 | ReMax | ReMax: A Simple, Effective, and Efficient Method for Aligning Large Language Models | | |
| - | REINFORCE | Simple statistical gradient-following algorithms for connectionist reinforcement learning | | - |
| - | REINFORCE++ | REINFORCE++: An Efficient RLHF Algorithm with Robustnessto Both Prompt and Reward Models | | |
| - | VinePPO | VINEPPO: UNLOCKING RL POTENTIAL FOR LLM REASONING THROUGH REFINED CREDIT ASSIGNMENT | | |
| - | FlashRL | Fast RL training with Quantized Rollouts | | |
Off-policy Optimization
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | BRIDGE | Beyond Two-Stage Training: Cooperative SFT and RL for LLM Reasoning | | |
| 2025-09 | HPT | Towards a Unified View of Large Language Model Post-Training | | |
| 2025-08 | DFT | On the Generalization of SFT: A Reinforcement Learning Perspective with Reward Rectification | | |
| 2025-08 | RED | Recall-Extend Dynamics: Enhancing Small Language Models through Controlled Exploration and Refined Offline Integration | | |
| 2025-07 | Prefix‑RFT | Blending Supervised and Reinforcement Fine-Tuning with Prefix Sampling | | - |
| 2025-07 | ReMix | Squeeze the Soaked Sponge: Efficient Off-policy Reinforcement Finetuning for Large Language Model | | |
| 2025-06 | ReLIFT | Learning What Reinforcement Learning Can't: Interleaved Online Fine-Tuning for Hardest Questions | | |
| 2025-06 | BREAD | BREAD: Branched Rollouts from Expert Anchors Bridge SFT & RL for Reasoning | | - |
| 2025-06 | SRFT | SRFT: A Single-Stage Method with Supervised and Reinforcement Fine-Tuning for Reasoning | | - |
| 2025-05 | AMPO | Adaptive Thinking via Mode Policy Optimization for Social Language Agents | | |
| 2025-05 | UFT | UFT: Unifying Supervised and Reinforcement Fine-Tuning | | |
| 2025-04 | LUFFY | Learning to Reason under Off-Policy Guidance | | |
| 2025-03 | SPO | Soft Policy Optimization: Online Off-Policy RL for Sequence Models | | |
| 2025-03 | TOPR | TAPERED OFF-POLICY REINFORCE Stable and efficient reinforcement learning for LLMs | | - |
| 2024-05 | IFT | Intuitive Fine-Tuning: Towards Simplifying Alignment into a Single Process | | |
| 2023-05 | DPO | Direct Preference Optimization: Your Language Model is Secretly a Reward Model | | - |
| 2015-11 | - | Fixed point quantization of deep convolutional networks | | - |
| - | - | Your Efficient RL Framework Secretly Brings You Off-Policy RL Training | | |
Off-policy Optimization (Exp replay)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SAPO | Sharing is Caring: Efficient LM Post-Training with Collective RL Experience Sharing | | - |
| 2025-09 | SEELE | Staying in the Sweet Spot: Responsive Reasoning Evolution via Capability-Adaptive Hint Scaffolding | | |
| 2025-08 | Memory-R1 | Memory-R1: Enhancing Large Language Model Agents to Manage and Utilize Memories via Reinforcement Learning | | - |
| 2025-07 | RLEP | RLEP: Reinforcement Learning with Experience Replay for LLM Reasoning | | |
| 2025-06 | EFRame | EFRame: Deeper Reasoning via Exploration-Filter-Replay Reinforcement Learning Framework | | |
| 2025-05 | ARPO | ARPO:End-to-End Policy Optimization for GUI Agents with Experience Replay | | |
| 2025-04 | - | Improving RL Exploration for LLM Reasoning through Retrospective Replay | | - |
Regularization Objectives
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-10 | ASPO | ASPO: Asymmetric Importance Sampling Policy Optimization | | |
| 2025-09 | CE-GPPO | CE-GPPO: Coordinating Entropy via Gradient-Preserving Clipping Policy Optimization in Reinforcement Learning | | |
| 2025-09 | CDE | CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models | | - |
| 2025-09 | DPH RL | The Choice of Divergence: A Neglected Key to Mitigating Diversity Collapse in Reinforcement Learning with Verifiable Reward | | |
| 2025-09 | empgseed-seed | Harnessing Uncertainty: Entropy-Modulated Policy Gradients for Long-Horizon LLM Agents | | - |
| 2025-07 | Archer | Stabilizing Knowledge, Promoting Reasoning: Dual-Token Constraints for RLVR | | |
| 2025-06 | Bingo | Bingo: Boosting Efficient Reasoning of LLMs via Dynamic and Significance-based Reinforcement Learning | | |
| 2025-06 | HighEntropy RL | Beyond the 80/20 Rule: High-Entropy Minority Tokens Drive Effective Reinforcement Learning for LLM Reasoning | | - |
| 2025-06 | Entropy RL | Reasoning with Exploration: An Entropy Perspective on Reinforcement Learning for LLMs | | - |
| 2025-06 | ALP RL | Just Enough Thinking: Efficient Reasoning with Adaptive Length Penalties Reinforcement Learning | | - |
| 2025-05 | DisCO | DisCO: Reinforcing Large Reasoning Models with Discriminative Constrained Optimization | | |
| 2025-05 | Skywork OR1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-05 | Entropy Mechanism | The Entropy Mechanism of Reinforcement Learning for Reasoning Language Models | | |
| 2025-05 | ProRL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | - |
| 2025-05 | Short RL | Efficient RL Training for Reasoning Models via Length-Aware Optimization | | |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | - |
| 2025-03 | L1 | L1: Controlling how long a reasoning model thinks with reinforcement learning | | |
Sampling Strategy
Dynamic and Structured Sampling
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-10 | EEPO | EEPO: Exploration-Enhanced Policy Optimization via Sample-Then-Forget | | |
| 2025-09 | AttnRL | Attention as a Compass: Efficient Exploration for Process-Supervised RL in Reasoning Models | | - |
| 2025-09 | DACE | Know When to Explore: Difficulty-Aware Certainty as a Guide for LLM Reinforcement Learning | | - |
| 2025-09 | Parallel-R1 | Parallel-R1: Towards Parallel Thinking via Reinforcement Learning | | |
| 2025-08 | G^2RPO-A | G^2RPO-A: Guided Group Relative Policy Optimization with Adaptive Guidanc | | |
| 2025-08 | RuscaRL | Breaking the Exploration Bottleneck: Rubric-Scaffolded Reinforcement Learning for General LLM Reasoning | | - |
| 2025-08 | TreePO | TreePO: Bridging the Gap of Policy Optimization and Efficacy and Inference Efficiency with Heuristic Tree-based Modeling | | |
| 2025-07 | ARPO | Agentic Reinforced Policy Optimization | | |
| 2025-06 | TreeRPO | TreeRPO: Tree Relative Policy Optimization | | |
| 2025-06 | E2H | Curriculum Reinforcement Learning from Easy to Hard Tasks Improves LLM Reasoning | | - |
| 2025-06 | TreeRL | TreeRL: LLM Reinforcement Learning with On-Policy Tree Search | | |
| 2025-05 | ToTRL | ToTRL: Unlock LLM Tree-of-Thoughts Reasoning Potential through Puzzles Solving | | - |
| 2025-03 | DARS | DARS: Dynamic Action Re-Sampling to Enhance Coding Agent Performance by Adaptive Tree Traversal | | |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| - | POLARIS | POLARIS: A POst-training recipe for scaling reinforcement Learning on Advanced ReasonIng modelS | | |
Sampling Hyper-Parameters
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | GFPO | Sample More to Think Less: Group Filtered Policy Optimization for Concise Reasoning | | - |
| 2025-06 | AceReason-Nemotron 1.1 | AceReason-Nemotron 1.1: Advancing Math and Code Reasoning through SFT and RL Synergy | | - |
| 2025-06 | T-PPO | Truncated Proximal Policy Optimization | | - |
| 2025-06 | Confucius3-Math | Confucius3-Math: A Lightweight High-Performance Reasoning LLM for Chinese K-12 Mathematics Learning | | |
| 2025-05 | E3-RL4LLMs | Enhancing Efficiency and Exploration in Reinforcement Learning for LLMs | | |
| 2025-05 | AceReason-Nemotron | AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning | | - |
| 2025-05 | Pro-RL | ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models | | - |
| 2025-03 | - | Output Length Effect on DeepSeek-R1's Safety in Forced Thinking | | - |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| 2025-02 | - | Training Language Models to Reason Efficiently | | - |
| - | DeepScaleR | DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL | | |
| - | POLARIS | POLARIS: A POst-training recipe for scaling reinforcement Learning on Advanced ReasonIng modelS | | |
Training Resource
Static Corpus (Code)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | rStar-Coder | rStar-Coder: Scaling Competitive Code Reasoning with a Large-Scale Verified Dataset | | |
| 2025-04 | Z1 | Z1: Efficient Test-time Scaling with Code | | |
| 2025-04 | OpenCodeReasoning | OpenCodeReasoning: Advancing Data Distillation for Competitive Coding | | - |
| 2025-04 | LeetCodeDataset | LeetCodeDataset: A Temporal Dataset for Robust Evaluation and Efficient Training of Code LLMs | | |
| 2025-03 | KodCode | KodCode: A Diverse, Challenging, and Verifiable Synthetic Dataset for Coding | | - |
| 2025-01 | SWE-Fixer | SWE-Fixer: Training Open-Source LLMs for Effective and Efficient GitHub Issue Resolution | | |
| 2024-12 | SWE-Gym | Training Software Engineering Agents and Verifiers with SWE-Gym | | |
| - | Code-R1 | Code-R1: Reproducing R1 for Code with Reliable Rewards | | |
| - | codeforces-cots | CodeForces CoTs | | - |
| - | DeepCoder | DeepCoder: A Fully Open-Source 14B Coder at O3-mini Level | | |
Static Corpus (STEM)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SSMR-Bench | Synthesizing Sheet Music Problems for Evaluation and Reinforcement Learning | | |
| 2025-09 | Loong | Loong: Synthesize Long Chain-of-Thoughts at Scale through Verifiers | | |
| 2025-07 | MegaScience | MegaScience: Pushing the Frontiers of Post-Training Datasets for Science Reasoning | | - |
| 2025-06 | ReasonMed | ReasonMed: A 370K Multi-Agent Generated Dataset for Advancing Medical Reasoning | | |
| 2025-05 | ChemCoTDataset | Beyond Chemical QA: Evaluating LLM's Chemical Reasoning with Modular Chemical Operations | | - |
| 2025-02 | NaturalReasoning | NaturalReasoning: Reasoning in the Wild with 2.8M Challenging Questions | | - |
| 2025-01 | SCP-116K | SCP-116K: A High-Quality Problem-Solution Dataset and a Generalized Pipeline for Automated Extraction in the Higher Education Science Domain | | - |
Static Corpus (Math)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-07 | MiroMind-M1-RL-62K | MiroMind-M1: An Open-Source Advancement in Mathematical Reasoning via Context-Aware Multi-Stage Policy Optimization | | |
| 2025-04 | DeepMath | DeepMath-103K: A Large-Scale, Challenging, Decontaminated, and Verifiable Mathematical Dataset for Advancing Reasoning | | |
| 2025-04 | OpenMathReasoning | AIMO-2 Winning Solution: Building State-of-the-Art Mathematical Reasoning Models with OpenMathReasoning dataset | | |
| 2025-03 | STILL-3-RL | An Empirical Study on Eliciting and Improving R1-like Reasoning Models | | |
| 2025-03 | Light-R1 | Light-R1: Curriculum SFT, DPO and RL for Long COT from Scratch and Beyond | | - |
| 2025-03 | DAPO | DAPO: An Open-Source LLM Reinforcement Learning System at Scale | | |
| 2025-03 | OpenReasoningZero | Open-Reasoner-Zero: An Open Source Approach to Scaling Up Reinforcement Learning on the Base Model | | |
| 2025-02 | PRIME | Process Reinforcement through Implicit Rewards | | |
| 2025-02 | LIMO | Limo: Less is more for reasoning | | |
| 2025-02 | LIMR | Limr: Less is more for rl scaling | | |
| 2025-02 | Big-MATH | Big-Math: A Large-Scale, High-Quality Math Dataset for Reinforcement Learning in Language Models | | - |
| - | NuminaMath 1.5 | Numinamath: The largest public dataset in ai4maths with 860k pairs of competition math problems and solutions | | |
| - | OpenR1-Math | Open R1: A fully open reproduction of DeepSeek-R1 | | |
| - | DeepScaleR | DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL | | - |
Static Corpus (Agent)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | ASearcher | Beyond Ten Turns: Unlocking Long-Horizon Agentic Search with Large-Scale Asynchronous RL | | - |
| 2025-07 | WebShaper | WebShaper: Agentically Data Synthesizing via Information-Seeking Formalization | | - |
| 2025-05 | ZeroSearch | ZeroSearch: Incentivize the Search Capability of LLMs without Searching | | |
| 2025-04 | ToolRL | ToolRL: Reward is All Tool Learning Needs | | |
| 2025-03 | Search-R1 | Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning | | |
| 2025-03 | ToRL | ToRL: Scaling Tool-Integrated RL | | |
| - | MicroThinker | MiroVerse V0.1: A Reproducible, Full-Trajectory, Ever-Growing Deep Research Dataset | | - |
| 2025-03 | DeepRetrieval | DeepRetrieval: Hacking Real Search Engines and Retrievers with Large Language Models via Reinforcement Learning | | |
Static Corpus (Mix)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | Graph-R1 | Graph-R1: Unleashing LLM Reasoning with NP-Hard Graph Problem | | - |
| 2025-06 | RewardAnything | RewardAnything: Generalizable Principle-Following Reward Models | | |
| 2025-06 | guru-RL-92k | Revisiting Reinforcement Learning for LLM Reasoning from A Cross-Domain Perspective | | - |
| 2025-05 | Llama-Nemotron-PT | Llama-Nemotron: Efficient Reasoning Models | | - |
| 2025-05 | SkyWork OR1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-03 | OpenVLThinker | OpenVLThinker: Complex Vision-Language Reasoning via Iterative SFT-RL Cycles | | |
| - | AM-DS-R1-0528-Distilled | AM-DeepSeek-R1-0528-Distilled | | |
| - | dolphin-r1 | Dolphin R1 Dataset | | - |
| - | SYNTHETIC-1/2 | SYNTHETIC-1 Release: Two Million Collaboratively Generated Reasoning Traces from Deepseek-R1 | | - |
Dynamic Environment (Rule-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | ProtoReasoning | ProtoReasoning: Prototypes as the Foundation for Generalizable Reasoning in LLMs | | - |
| 2025-05 | SynLogic | SynLogic: Synthesizing Verifiable Reasoning Data at Scale for Learning Logical Reasoning and Beyond | | |
| 2025-05 | Reasoning Gym | REASONING GYM: Reasoning Environments for Reinforcement Learning with Verifiable Rewards | | |
| 2025-05 | Enigmata | Enigmata: Scaling Logical Reasoning in Large Language Models with Synthetic Verifiable Puzzles | | |
| 2025-02 | AutoLogi | AutoLogi: Automated Generation of Logic Puzzles for Evaluating Reasoning Abilities of Large Language Models | | |
| 2025-02 | Logic-RL | Logic-RL: Unleashing LLM Reasoning with Rule-Based Reinforcement Learning | | |
Dynamic Environment (Code-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | AgentCPM-GUI | AgentCPM-GUI: Building Mobile-Use Agents with Reinforcement Fine-Tuning | | |
| 2025-06 | MedAgentGym | MedAgentGym: Training LLM Agents for Code-Based Medical Reasoning at Scale | | |
| 2025-05 | MLE-Dojo | MLE-Dojo: Interactive Environments for Empowering LLM Agents in Machine Learning Engineering | | |
| 2025-05 | SWE-rebench | SWE-rebench: An Automated Pipeline for Task Collection and Decontaminated Evaluation of Software Engineering Agents | | - |
| 2025-05 | ZeroGUI | ZeroGUI: Automating Online GUI Learning at Zero Human Cost | | |
| 2025-04 | R2E-Gym | R2E-Gym: Procedural Environment Generation and Hybrid Verifiers for Scaling Open-Weights SWE Agents | | |
| 2025-03 | ReSearch | ReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning | | |
| 2025-02 | MLGym | MLGym: A New Framework and Benchmark for Advancing AI Research Agents | | |
| 2024-07 | AppWorld | AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents | | |
Dynamic Environment (Game-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | PuzzleJAX | PuzzleJAX: A Benchmark for Reasoning and Learning | | |
| 2025-06 | Play to Generalize | Play to Generalize: Learning to Reason Through Game Play | | |
| 2025-06 | Optimus-3 | Optimus-3: Towards Generalist Multimodal Minecraft Agents with Scalable Task Experts | | |
| 2025-05 | lmgame-Bench | lmgame-Bench: How Good are LLMs at Playing Games? | | |
| 2025-05 | G1 | G1: Bootstrapping Perception and Reasoning Abilities of Vision-Language Model via Reinforcement Learning | | |
| 2025-05 | Code2Logic | Code2Logic: Game-Code-Driven Data Synthesis for Enhancing VLMs General Reasoning | | |
| 2025-05 | KORGym | KORGym: A Dynamic Game Platform for LLM Reasoning Evaluation | | |
| 2025-04 | Cross-env-coop | Cross-environment Cooperation Enables Zero-shot Multi-agent Coordination | | |
| 2022-03 | ScienceWorld | ScienceWorld: Is your Agent Smarter than a 5th Grader? | | |
| 2020-10 | ALFWorld | ALFWorld: Aligning Text and Embodied Environments for Interactive Learning | | |
Dynamic Environment (Model-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | SwS | SwS: Self-aware Weakness-driven Problem Synthesis in Reinforcement Learning for LLM Reasoning | | |
| 2025-06 | SPIRAL | SPIRAL: Self-Play on Zero-Sum Games Incentivizes Reasoning via Multi-Agent Multi-Turn Reinforcement Learning | | |
| 2025-05 | Absolute Zero | Absolute Zero: Reinforced Self-play Reasoning with Zero Data | | |
| 2025-04 | TextArena | TextArena | | |
| 2025-03 | SWEET-RL | SWEET-RL: Training Multi-Turn LLM Agents on Collaborative Reasoning Tasks | | |
| - | Genie 3 | Genie 3: A new frontier for world models | | - |
Dynamic Environment (Ensemble-based)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | InternBootcamp | InternBootcamp Technical Report: Boosting LLM Reasoning with Verifiable Task Scaling | | |
| - | SYNTHETIC-2 | SYNTHETIC-2 Release: Four Million Collaboratively Generated Reasoning Traces | | - |
RL Infrastructure (Primary)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-06 | ROLL | Reinforcement Learning Optimization for Large-Scale Learning: An Efficient and User-Friendly Scaling Library | | |
| 2025-05 | AReaL | AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning | | |
| 2024-09 | veRL | HybridFlow: A Flexible and Efficient RLHF Framework | | |
| 2024-05 | OpenRLHF | OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework | | |
| - | TRL | Transformer Reinforcement Learning | - | |
| - | NeMo-RL | Nemo RL: A Scalable and Efficient Post-Training Library | - | |
| - | slime | slime: An SGLang-Native Post-Training Framework for RL Scaling | - | |
| - | RLinf | RLinf: Reinforcement Learning Infrastructure for Agentic AI | - | |
RL Infrastructure (Secondary)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | RL-Factory | RLFactory: A Plug-and-Play Reinforcement Learning Post-Training Framework for LLM Multi-Turn Tool-Use | | |
| 2025-09 | verl-tool | VerlTool: Towards Holistic Agentic Reinforcement Learning with Tool Use | | |
| 2025-09 | dLLM-RL | Revolutionizing Reinforcement Learning Framework for Diffusion Large Language Models | | |
| 2025-08 | agent-lightning | Agent Lightning: Train ANY AI Agents with Reinforcement Learning | | |
| 2025-05 | verl-agent | Group-in-Group Policy Optimization for LLM Agent Training | | |
| 2025-04 | VLM-R1 | VLM-R1: A stable and generalizable R1-style Large Vision-Language Model | | |
| - | rllm | rLLM: A Framework for Post-Training Language Agents | - | |
| - | EasyR1 | EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework | - | |
| - | verifiers | Verifiers: Reinforcement Learning with LLMs in Verifiable Environments | - | |
| - | prime-rl | PRIME-RL: Decentralized RL Training at Scale | - | |
| - | MARTI | A Framework for LLM-based Multi-Agent Reinforced Training and Inference | - | |
Applications
Coding Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | - | Reinforcement Learning for Machine Learning Engineering Agents | | - |
| 2025-09 | - | Advancing SLM Tool-Use Capability using Reinforcement Learning | | - |
| 2025-09 | SimpleTIR | SimpleTIR: End-to-End Reinforcement Learning for Multi-Turn Tool-Integrated Reasoning | | |
| 2025-09 | - | The Illusion of Diminishing Returns: Measuring Long Horizon Execution in LLMs | | |
| 2025-08 | GLM-4.5 | GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models | | |
| 2025-08 | FormaRL | FormaRL: Enhancing Autoformalization with no Labeled Data | | |
| 2025-08 | RLTR | Encouraging Good Processes Without the Need for Good Answers: Reinforcement Learning for LLM Agent Planning | | - |
| 2025-07 | ARPO | Agentic Reinforced Policy Optimization | | |
| 2025-07 | Kimi K2 | Kimi K2: Open Agentic Intelligence | | - |
| 2025-07 | AutoTIR | AutoTIR: Autonomous Tools Integrated Reasoning via Reinforcement Learning | | |
| 2025-06 | CoRT | CoRT: Code-integrated Reasoning within Thinking | | |
| 2025-05 | EvoScale | Satori-SWE: Evolutionary Test-Time Scaling for Sample-Efficient Software Engineering | | |
| 2025-03 | ToRL | ToRL: Scaling Tool-Integrated RL | | |
| 2025-02 | SWE-RL | SWE-RL: Advancing LLM Reasoning via Reinforcement Learning on Open Software Evolution | | |
| - | Qwen3-Coder | Qwen3-Coder: Agentic Coding in the World. | - | |
Search Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | SSRL | SSRL: Self-Search Reinforcement Learning | | |
| 2025-07 | WebSailor | WebSailor: Navigating Super-human Reasoning for Web Agent | | |
| 2025-07 | WebShaper | WebShaper: Agentically Data Synthesizing via Information-Seeking Formalization | | |
| 2025-05 | ZeroSearch | ZeroSearch: Incentivize the Search Capability of LLMs without Searching | | |
| 2025-05 | SEM | SEM: Reinforcement Learning for Search-Efficient Large Language Models | | - |
| 2025-05 | S3 | s3: You Don't Need That Much Data to Train a Search Agent via RL | | |
| 2025-05 | StepSearch | StepSearch: Igniting LLMs Search Ability via Step-Wise Proximal Policy Optimization | | |
| 2025-05 | R1-Searcher++ | R1-Searcher++: Incentivizing the Dynamic Knowledge Acquisition of LLMs via Reinforcement Learning | | |
| 2025-04 | ReZero | ReZero: Enhancing LLM search ability by trying one-more-time | | - |
| 2025-03 | DeepRetrieval | DeepRetrieval: Hacking Real Search Engines and Retrievers with Large Language Models via Reinforcement Learning | | |
| 2025-03 | Search-R1 | Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning | | |
| 2025-03 | R1-Searcher | R1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning | | |
Browser-Use Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-05 | WebAgent-R1 | WebAgent-R1: Training Web Agents via End-to-End Multi-Turn Reinforcement Learning | | |
| 2025-05 | WebDancer | WebDancer: Towards Autonomous Information Seeking Agency | | |
| 2025-04 | DeepResearcher | DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments | | |
| 2024-11 | Web-RL | WebRL: Training LLM Web Agents via Self-Evolving Online Curriculum Reinforcement Learning | | |
| 2021-12 | WebGPT | WebGPT: Browser-assisted question-answering with human feedback | | - |
DeepResearch Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SFR-DeepResearch | SFR-DeepResearch: Towards Effective Reinforcement Learning for Autonomously Reasoning Single Agents | | - |
| 2025-09 | DeepDive | DeepDive: Advancing Deep Search Agents with Knowledge Graphs and Multi-Turn RL | | |
| 2025-08 | Webwatcher | Webwatcher: Breaking new frontiers of vision-language deep research agent | | |
| 2025-08 | ASearcher | Beyond ten turns: Unlocking long-horizon agentic search with large-scale asynchronous rl | | |
| 2025-08 | Atom-searcher | Atom-searcher: Enhancing agentic deep research via fine-grained atomic thought reward | | |
| 2025-08 | MedResearcher-R1 | Medreseacher-r1: Expert-level medical deep researcher via a knowledge-informed trajectory synthesis framework | | |
| 2025-06 | Jan-nano | Jan-nano Technical Report | | - |
| 2025-04 | WebThinker | WebThinker: Empowering Large Reasoning Models with Deep Research Capability | | |
| - | Kimi-Researcher | Kimi-Researcher-End-to-End RL Training for Emerging Agentic Capabilities | | - |
| - | Mirothinker | Mirothinker: An open-source agentic model series trained for deep research and complex, long-horizon problem solving | | |
GUI&Computer Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | UI-TARS 2 | UI-TARS-2 Technical Report: Advancing GUI Agent with Multi-Turn Reinforcement Learning | | |
| 2025-08 | GUI-RC | Test-Time Reinforcement Learning for GUI Grounding via Region Consistency | | |
| 2025-08 | Os-r1 | OS-R1: Agentic Operating System Kernel Tuning with Reinforcement Learning | | |
| 2025-08 | ComputerRL | ComputerRL: Scaling End-to-End Online Reinforcement Learning for Computer Use Agents | | - |
| 2025-08 | Mobile-Agent-v3 | Mobile-Agent-v3: Fundamental Agents for GUI Automation | | |
| 2025-08 | SWIRL | SWIRL: A Staged Workflow for Interleaved Reinforcement Learning in Mobile GUI Control | | |
| 2025-08 | InquireMobile | InquireMobile: Teaching VLM-based Mobile Agent to Request Human Assistance via Reinforcement Fine-Tuning | | - |
| 2025-07 | MobileGUI-RL | MobileGUI-RL: Advancing Mobile GUI Agent through Reinforcement Learning in Online Environment | | - |
| 2025-06 | GUI-Critic-R1 | Look Before You Leap: A GUI-Critic-R1 Model for Pre-Operative Error Diagnosis in GUI Automation | | |
| 2025-06 | GUI-Reflection | GUI-Reflection: Empowering Multimodal GUI Models with Self-Reflection Behavior | | - |
| 2025-06 | Mobile-R1 | Mobile-R1: Towards Interactive Reinforcement Learning for VLM-Based Mobile Agent via Task-Level Rewards | | - |
| 2025-05 | UIShift | UIShift: Enhancing VLM-based GUI Agents through Self-supervised Reinforcement Learning | | |
| 2025-05 | GUI-G1 | GUI-G1: Understanding R1-Zero-Like Training for Visual Grounding in GUI Agents | | |
| 2025-05 | ARPO | ARPO:End-to-End Policy Optimization for GUI Agents with Experience Replay | | |
| 2025-05 | ZeroGUI | ZeroGUI: Automating Online GUI Learning at Zero Human Cost | | |
| 2025-04 | GUI-R1 | GUI-R1 : A Generalist R1-Style Vision-Language Action Model For GUI Agents | | |
| 2025-03 | UI-R1 | UI-R1: Enhancing Efficient Action Prediction of GUI Agents by Reinforcement Learning | | |
| 2025-01 | UI-TARS | UI-TARS: Pioneering Automated GUI Interaction with Native Agents | | |
Recommendation Agent
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-07 | Shop-R1 | Shop-R1: Rewarding LLMs to Simulate Human Behavior in Online Shopping via Reinforcement Learning | | - |
| 2025-03 | Rec-R1 | Rec-R1: Bridging LLMs and Recommendation Systems via Reinforcement Learning | | |
Agent (Others)
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-07 | OpenTable-R1 | OpenTable-R1: A Reinforcement Learning Augmented Tool Agent for Open-Domain Table Question Answering | | |
| 2025-07 | LaViPlan | LaViPlan : Language-Guided Visual Path Planning with RLVR | | - |
| 2025-06 | Drive-R1 | Drive-R1: Bridging Reasoning and Planning in VLMs for Autonomous Driving with Reinforcement Learning | | - |
| - | EPO | EPO: Entropy-regularized Policy Optimization for LLM Agents Reinforcement Learning | | |
Code Generation
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Proof2Silicon | Proof2Silicon: Prompt Repair for Verified Code and Hardware Generation via Reinforcement Learning | | - |
| 2025-09 | AR$^2$ | AR$^2$: Adversarial Reinforcement Learning for Abstract Reasoning in Large Language Models | | |
| 2025-09 | Dream-Coder | Dream-Coder 7B: An Open Diffusion Language Model for Code | | |
| 2025-08 | MSRL | Breaking the SFT Plateau: Multimodal Structured Reinforcement Learning for Chart-to-Code Generation | | - |
| 2025-07 | CogniSQL-R1-Zero | CogniSQL-R1-Zero: Lightweight Reinforced Reasoning for Efficient SQL Generation | | - |
| 2025-07 | Leanabell-Prover-V2 | Leanabell-Prover-V2: Verifier-integrated Reasoning for Formal Theorem Proving via Reinforcement Learning | | |
| 2025-07 | StepFun-Prover | StepFun-Prover Preview: Let's Think and Verify Step by Step | | |
| 2025-06 | MedAgentGym | MedAgentGym: Training LLM Agents for Code-Based Medical Reasoning at Scale | | |
| 2025-05 | Fortune | Fortune: Formula-Driven Reinforcement Learning for Symbolic Table Reasoning in Language Models | | |
| 2025-05 | VeriReason | VeriReason: Reinforcement Learning with Testbench Feedback for Reasoning-Enhanced Verilog Generation | | |
| 2025-05 | ReEX-SQL | ReEx-SQL: Reasoning with Execution-Aware Reinforcement Learning for Text-to-SQL | | - |
| 2025-05 | AceReason-Nemotron | AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning | | - |
| 2025-05 | SkyWork OR1 | Skywork Open Reasoner 1 Technical Report | | |
| 2025-05 | CodeV-R1 | CodeV-R1: Reasoning-Enhanced Verilog Generation | | |
| 2025-05 | AReaL | AREAL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning | | |
| 2025-04 | SQL-R1 | SQL-R1: Training Natural Language to SQL Reasoning Model By Reinforcement Learning | | |
| 2025-04 | Kimina-Prover | Kimina-Prover Preview: Towards Large Formal Reasoning Models with Reinforcement Learning | | - |
| 2025-04 | DeepSeek-Prover-V2 | DeepSeek-Prover-V2: Advancing Formal Mathematical Reasoning via Reinforcement Learning for Subgoal Decomposition | | |
| 2025-03 | Reasoning-SQL | Reasoning-SQL: Reinforcement Learning with SQL Tailored Partial Rewards for Reasoning-Enhanced Text-to-SQL | | - |
| - | code-r1 | Code-R1: Reproducing R1 for Code with Reliable Rewards | - | |
| - | Open-R1 | Open-R1: a fully open reproduction of DeepSeek-R1 | | |
| - | DeepCoder | Deepcoder: A fully open-source 14b coder at o3-mini level | | |
Software Engineering
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-08 | UTRL | Learning to Generate Unit Test via Adversarial Reinforcement Learning | | - |
| 2025-07 | RePaCA | RePaCA: Leveraging Reasoning Large Language Models for Static Automated Patch Correctness Assessment | | - |
| 2025-07 | Repair-R1 | Repair-R1: Better Test Before Repair | | |
| 2025-06 | CURE | Co-Evolving LLM Coder and Unit Tester via Reinforcement Learning | | |
| 2025-05 | REAL | Training Language Models to Generate Quality Code with Program Analysis Feedback | | - |
| 2025-05 | Afterburner | Afterburner: Reinforcement Learning Facilitates Self-Improving Code Efficiency Optimization | | |
| 2024-09 | RepoGenReflex | RepoGenReflex: Enhancing Repository-Level Code Completion with Verbal Reinforcement and Retrieval-Augmented Generation | | - |
| 2024-07 | RLCoder | RLCoder: Reinforcement Learning for Repository-Level Code Completion | | |
Multimodal Understanding
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2026-03 | 3D-RFT | 3D-RFT: Reinforcement Fine-Tuning for Video-based 3D Scene Understanding | | |
| 2025-09 | Vision-Zero | Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | | |
| 2025-09 | ReAd-R | AdsQA: Towards Advertisement Video Understanding | | |
| 2025-09 | Keye | Kwai Keye-VL 1.5 Technical Report | | |
| 2025-08 | Sifthinker | Sifthinker: Spatially-aware image focus for visual reasoning | | |
| 2025-07 | Long-RL | Scaling rl to long videos | | |
| 2025-06 | RefSpatial | Roborefer: Towards spatial referring with reasoning in vision-language models for robotics | | |
| 2025-06 | Ego-R1 | Ego-R1: Chain-of-tool-thought for ultra-long egocentric video reasoning | | |
| 2025-05 | VerIPO | VerIPO: Long Reasoning Video-R1 Model with Iterative Policy Optimization | | |
| 2025-05 | Openthinkimg | Openthinkimg: Learning to think with images via visual tool reinforcement learning | | |
| 2025-05 | Visual Planning | Visual Planning: Let's think only with images | | |
| 2025-05 | VideoRFT | Videorft: Incentivizing video reasoning capability in mllms via reinforced fine-tuning | | |
| 2025-05 | Deepeyes | Deepeyes: Incentivizing" thinking with images" via reinforcement learning | | |
| 2025-05 | Visionary-R1 | Visionary-R1: Mitigating shortcuts in visual reasoning with reinforcement learning | | |
| 2025-05 | CoF | Chain-of-focus: Adaptive visual search and zooming for multimodal reasoning via rl | | |
| 2025-05 | GRIT | GRIT: Teaching mllms to think with images | | |
| 2025-05 | Pixel Reasoner | Pixel Reasoner: Incentivizing pixel-space reasoning with curiosity-driven reinforcement learning | | |
| 2025-05 | - | Don’t look only once: Towards multimodal interactive reasoning with selective visual revisitation | | |
| 2025-05 | Ground-R1 | Ground-R1: Incentivizing grounded visual reasoning via reinforcement learning | | |
| 2025-05 | TACO | TACO: Think-answer consistency for optimized long-chain reasoning and efficient data learning via reinforcement learning in lvlms | | - |
| 2025-05 | Qwen-LA | Qwen look again: Guiding vision-language reasoning models to re-attention visual information | | |
| 2025-05 | TW-GRPO | Reinforcing video reasoning with focused thinking | | |
| 2025-05 | Spatial-MLLM | Spatial-MLLM: Boosting mllm capabilities in visual-based spatial intelligence | | |
| 2025-04 | R1-Zero-VSI | Improved visual-spatial reasoning via r1-zero-like training | | |
| 2025-04 | Spacer | Spacer: Reinforcing mllms in video spatial reasoning | | |
| 2025-04 | Videochat-R1 | Videochat-R1: Enhancing spatio-temporal perception via reinforcement fine-tuning | | |
| 2025-04 | VLM-R1 | VLM-R1: A stable and generalizable r1-style large vision-language model | | |
| 2025-03 | OpenVLThinker | OpenVLThinker: Complex Vision-Language Reasoning via Iterative SFT-RL Cycles | | |
| 2025-03 | Visual-RFT | Visual-RFT: Visual reinforcement fine-tuning | | |
| 2025-03 | Vision-R1 | Vision-R1: Incentivizing reasoning capability in multimodal large language models | | |
| 2025-03 | VisRL | VisRL: Intention-Driven Visual Perception via Reinforced Reasoning | | |
| 2025-03 | Metaspatial | Metaspatial: Reinforcing 3d spatial reasoning in vlms for the metaverse | | |
| 2025-03 | Video-R1 | Video-R1: Reinforcing video reasoning in mllms | | |
| 2025-09 | Vision-Zero | Vision-Zero: Scalable VLM Self-Improvement via strategic Gamified Self-Play | | |
Multimodal Generation
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | IGPO | Inpainting-Guided Policy Optimization for Diffusion Large Language Models | | - |
| 2025-08 | Qwen-Image | Qwen-Image Technical Report | | |
| 2025-08 | TempFlow-GRPO | TempFlow-GRPO: When timing matters for grpo in flow models | | |
| 2025-07 | MixGRPO | MixGRPO: Unlocking flow-based grpo efficiency with mixed ode-sde | | |
| 2025-06 | FocusDiff | Focusdiff: Advancing fine-grained text-image alignment for autoregressive visual generation through rl | | |
| 2025-06 | SUDER | Reinforcing multimodal understanding and generation with dual self-rewards | | - |
| 2025-05 | T2I-R1 | T2I-R1: Reinforcing image generation with collaborative semantic-level and token-level cot | | |
| 2025-05 | Flow-GRPO | Flow-GRPO: Training flow matching models via online rl | | |
| 2025-05 | DanceGRPO | DanceGRPO: Unleashing grpo on visual generation | | |
| 2025-05 | GoT-R1 | GoT-R1: Unleashing reasoning capability of mllm for visual generation with reinforcement learning | | |
| 2025-05 | ULM-R1 | Co-Reinforcement learning for unified multimodal understanding and generation | | |
| 2025-05 | RePrompt | Reprompt: Reasoning-augmented reprompting for text-to-image generation via reinforcement learning | | |
| 2025-05 | InfLVG | InfLVG: Reinforce inference-time consistent long video generation with grpo | | |
| 2025-05 | Reasongen-R1 | Reasongen-R1: Cot for autoregressive image generation models through sft and rl | | |
| 2025-04 | PhysAR | Reasoning physical video generation with diffusion timestep tokens via reinforcement learning | | - |
Robotics Tasks
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | SimpleVLA-RL | SimpleVLA-RL: Scaling VLA Training via Reinforcement Learning | | |
| 2025-06 | TGRPO | TGRPO :Fine-tuning Vision-Language-Action Model via Trajectory-wise Group Relative Policy Optimization | | - |
| 2025-05 | ReinboT | ReinboT: Amplifying Robot Visual-Language Manipulation with Reinforcement Learning | | |
| 2025-05 | RIPT-VLA | InteractivePost-Trainingfor Vision-Language-ActionModels | | |
| 2025-05 | VLA-RL | VLA-RL: Towards Masterful and General Robotic Manipulation with Scalable Reinforcement Learning | | |
| 2025-05 | RFTF | RFTF: Reinforcement Fine-tuning for Embodied Agents with Temporal Feedback | | - |
| 2025-05 | VLA Generalization | What can rl bring to vla generalization? an empirical study | | |
| 2025-02 | ConRFT | ConRFT: A Reinforced Fine-tuning Method for VLA Models via Consistency Policy | | |
| 2024-11 | GRAPE | GRAPE: Generalizing Robot Policy via Preference Alignment | | |
| - | RLinf | RLinf: Reinforcement Learning Infrastructure for Agentic AI | | - |
| - | EPO | EPO: Entropy-regularized Policy Optimization for LLM Agents Reinforcement Learning | | |
Multi-Agent Systems
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-10 | AgentFlow | In-the-Flow Agentic System Optimization for Effective Planning and Tool Use | | |
| 2025-09 | SoftRankPO, | Learning to Deliberate: Meta-policy Collaboration for Agentic LLMs with Multi-agent Reinforcement Learning | | - |
| 2025-09 | BFS-Prover-V2 | Scaling up Multi-Turn Off-Policy RL and Multi-Agent Tree Search for LLM Step-Provers | | - |
| 2025-08 | MAGRPO | LLM Collaboration With Multi-Agent Reinforcement Learning | | - |
| 2025-06 | AlphaEvolve | AlphaEvolve: A coding agent for scientific and algorithmic discovery | | - |
| 2025-06 | JoyAgents-R1 | JoyAgents-R1: Joint Evolution Dynamics for Versatile Multi-LLM Agents with Reinforcement Learning | | - |
| 2025-03 | ReMA | ReMA: Learning to Meta-think for LLMs with Multi-agent Reinforcement Learning | | |
| 2025-02 | CTRL | Teaching Language Models to Critique via Reinforcement Learning | | |
| 2025-02 | Maporl | MAPoRL2: Multi-Agent Post-Co-Training for Collaborative Large Language Models with Reinforcement Learning | | |
| 2023-11 | LLaMAC | Controlling large language model-based agents for large-scale decision-making: An actor-critic approach | | - |
Scientific Tasks
| Date | Name | Title | Paper | Github |
|---|---|---|---|---|
| 2025-09 | Baichuan-M2 | Baichuan-M2: Scaling Medical Capability with Large Verifier System | | - |
| 2025-08 | CX-Mind | CX-Mind: A Pioneering Multimodal Large Language Model for Interleaved Reasoning in Chest X-ray via Curriculum-Guided Reinforcement Learning | | |
| 2025-08 | MORE-CLEAR | MORE-CLEAR: Multimodal Offline Reinforcement learning for Clinical notes Leveraged Enhanced State Representation | | - |
| 2025-08 | ARMed | Breaking Reward Collapse: Adaptive Reinforcement for Open-ended Medical Reasoning with Enhanced Semantic Discrimination | | - |
| 2025-08 | ProMed | ProMed: Shapley Information Gain Guided Reinforcement Learning for Proactive Medical LLMs | | |
| 2025-08 | OwkinZero | OwkinZero: Accelerating Biological Discovery with AI | | - |
| 2025-08 | MolReasoner | MolReasoner: Toward Effective and Interpretable Reasoning for Molecular LLMs | | |
| 2025-08 | MedGR$^2$ | MedGR$^2$: Breaking the Data Barrier for Medical Reasoning via Generative Reward Learning | | - |
| 2025-07 | MedGround-R1 | MedGround-R1: Advancing Medical Image Grounding via Spatial-Semantic Rewarded Group Relative Policy Optimization | | |
| 2025-07 | MedGemma | MedGemma Technical Report | [![Paper](https://img.shields.io/badge/paper-A42C |
Truncated — view the full README on GitHub.
Similar repos
Contributors
Languages
TeX
100.0%