
README
LLM Post-Training: A Deep Dive into Reasoning Large Language Models



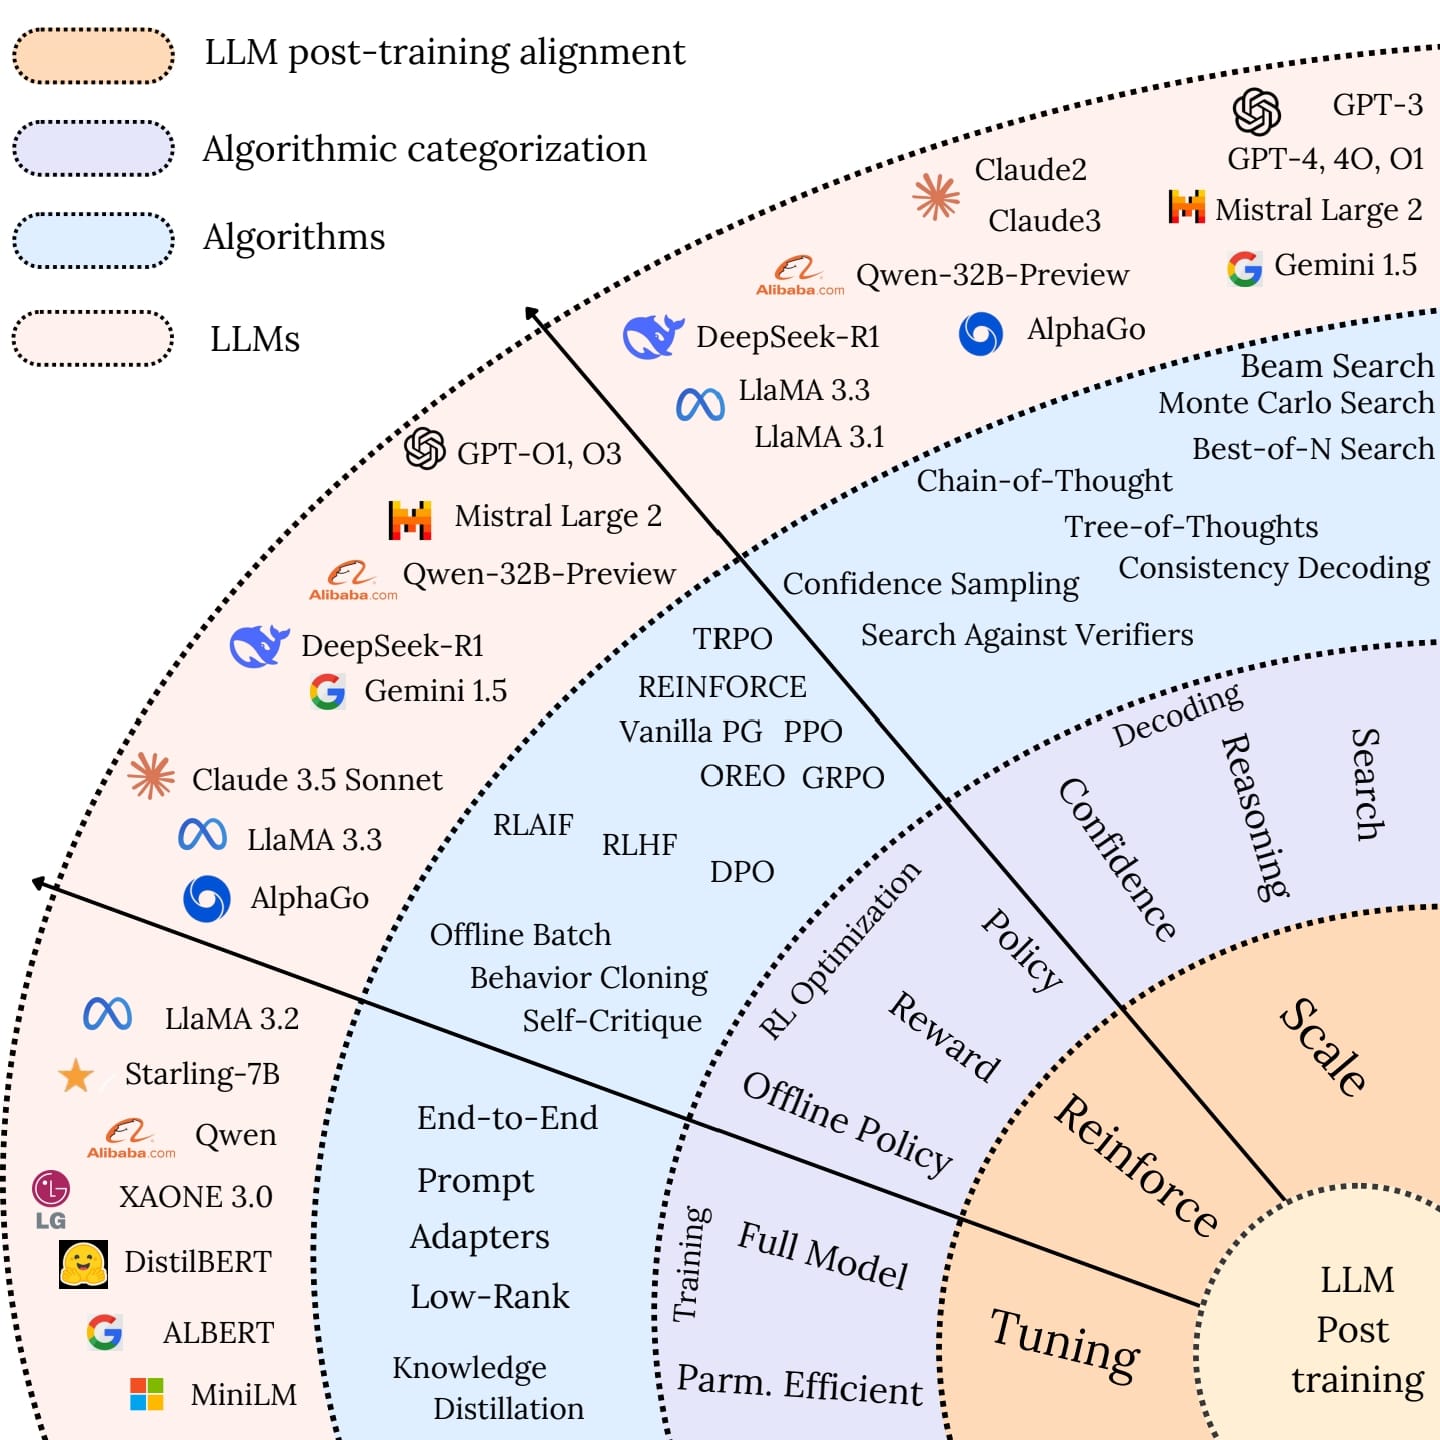
Welcome to the Awesome-LLM-Post-training repository! This repository is a curated collection of the most influential papers, code implementations, benchmarks, and resources related to Large Language Models (LLMs) Post-Training Methodologies.
🎉 News
- Our survey paper, “LLM Post-Training: A Deep Dive into Reasoning Large Language Models,” has been accepted for publication in IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI).
Our work is based on the following paper:
📄 LLM Post-Training: A Deep Dive into Reasoning Large Language Models – Available on
Komal Kumar* , Tajamul Ashraf* , Omkar Thawakar , Rao Muhammad Anwer , Hisham Cholakkal , Mubarak Shah , Ming-Hsuan Yang , Philip H.S. Torr , Fahad Shahbaz Khan , and Salman Khan
* Equally contributing first authors
- Corresponding authors: Komal Kumar, Tajamul Ashraf.
Feel free to ⭐ star and fork this repository to keep up with the latest advancements and contribute to the community.
📌 Contents
| Section | Subsection |
|---|---|
| 📖 Papers | Survey, Theory, Explainability |
| 🤖 LLMs in RL | LLM-Augmented Reinforcement Learning |
| 🏆 Reward Learning | Human Feedback, Preference-Based RL, Intrinsic Motivation |
| 🚀 Policy Optimization | Offline RL, Imitation Learning, Hierarchical RL |
| 🧠 LLMs for Reasoning & Decision-Making | Causal Reasoning, Planning, Commonsense RL |
| 🌀 Exploration & Generalization | Zero-Shot RL, Generalization in RL, Self-Supervised RL |
| 🤝 Multi-Agent RL (MARL) | Emergent Communication, Coordination, Social RL |
| ⚡ Applications & Benchmarks | Autonomous Agents, Simulations, LLM-RL Benchmarks |
| 📚 Tutorials & Courses | Lectures, Workshops |
| 🛠️ Libraries & Implementations | Open-Source RL-LLM Frameworks |
| 🔗 Other Resources | Additional Research & Readings |
📖 Papers
🔍 Survey
| Title | Publication Date | Link |
|---|---|---|
| A Survey on Bridging VLMs and Synthetic Data | 16 May 2025 | OpenReview |
| A Survey on Post-training of Large Language Models | 8 Mar 2025 | Arxiv |
| LLM Post-Training: A Deep Dive into Reasoning Large Language Models | 28 Feb 2025 | Arxiv |
| From System 1 to System 2: A Survey of Reasoning Large Language Models | 25 Feb 2025 | Arxiv |
| Empowering LLMs with Logical Reasoning: A Comprehensive Survey | 24 Feb 2025 | Arxiv |
| Towards Large Reasoning Models: A Survey of Reinforced Reasoning with Large Language Models | 16 Jan 2025 | Arxiv |
| Harmful Fine-tuning Attacks and Defenses for Large Language Models: A Survey | 26 Sep 2024 | Arxiv |
| Reasoning with Large Language Models, a Survey | 16 July 2024 | Arxiv |
| Survey on Large Language Model-Enhanced Reinforcement Learning: Concept, Taxonomy, and Methods | 30 Mar 2024 | Arxiv |
| Reinforcement Learning Enhanced LLMs: A Survey | 5 Dec 2024 | Arxiv |
| Enhancing Code LLMs with Reinforcement Learning in Code Generation: A Survey | 29 Dec 2024 | Arxiv |
| Large Language Models: A Survey of Their Development, Capabilities, and Applications | 15 Jan 2025 | Springer |
| A Survey on Multimodal Large Language Models | 10 Feb 2025 | Oxford Academic |
| Large Language Models (LLMs): Survey, Technical Frameworks, and Future Directions | 20 Jul 2024 | Springer |
| Using Large Language Models to Automate and Expedite Reinforcement Learning with Reward Machines | 11 Feb 2024 | Arxiv |
| ExploRLLM: Guiding Exploration in Reinforcement Learning with Large Language Models | 14 Mar 2024 | Arxiv |
| Reinforcement Learning Problem Solving with Large Language Models | 29 Apr 2024 | Arxiv |
| A Survey on Large Language Models for Reinforcement Learning | 10 Dec 2023 | Arxiv |
| Large Language Models as Decision-Makers: A Survey | 23 Aug 2023 | Arxiv |
| A Survey on Large Language Model Alignment Techniques | 6 May 2023 | Arxiv |
| Reinforcement Learning with Human Feedback: A Survey | 12 April 2023 | Arxiv |
| Reasoning with Large Language Models: A Survey | 14 Feb 2023 | Arxiv |
| A Survey on Foundation Models for Decision Making | 9 Jan 2023 | Arxiv |
| Large Language Models in Reinforcement Learning: Opportunities and Challenges | 5 Dec 2022 | Arxiv |
| Training language models to follow instructions with human feedback | 4 Mar 2022 | Arxiv |
🤖 LLMs-in-RL
- Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play [Paper]
- Satori: Reinforcement Learning with Chain-of-Action-Thought Enhances LLM Reasoning via Autoregressive Search [Paper]
- DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL [Paper]
- QLASS: Boosting Language Agent Inference via Q-Guided Stepwise Search [Paper]
- Process Reinforcement through Implicit Rewards [Paper]
- Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling [Paper]
- Challenges in Ensuring AI Safety in DeepSeek-R1 Models: The Shortcomings of Reinforcement Learning Strategies [Paper]
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning [Paper]
- Kimi k1.5: Scaling Reinforcement Learning with LLMs [Paper]
- Does RLHF Scale? Exploring the Impacts From Data, Model, and Method [Paper]
- Offline Reinforcement Learning for LLM Multi-Step Reasoning [Paper]
- ReFT: Representation Finetuning for Language Models [Paper]
- Deepseekmath: Pushing the limits of mathematical reasoning in open language models [Paper]
- Reasoning with Reinforced Functional Token Tuning [Paper]
- Value-Based Deep RL Scales Predictably [Paper]
- InfAlign: Inference-aware language model alignment [Paper]
- LIMR: Less is More for RL Scaling [Paper]
- A Survey on Feedback-based Multi-step Reasoning for Large Language Models on Mathematics [Paper]


🏆 Reward Learning (Process Reward Models)
- PRMBench: A Fine-grained and Challenging Benchmark for Process-Level Reward Models. [Paper]
- ReARTeR: Retrieval-Augmented Reasoning with Trustworthy Process Rewarding [Paper]
- The Lessons of Developing Process Reward Models in Mathematical Reasoning. [Paper]
- ToolComp: A Multi-Tool Reasoning & Process Supervision Benchmark. [Paper]
- AutoPSV: Automated Process-Supervised Verifier [Paper]
- ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search [Paper]
- Free Process Rewards without Process Labels. [Paper]
- Outcome-Refining Process Supervision for Code Generation [Paper]
- Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations [Paper]
- OVM: Outcome-supervised Value Models for Planning in Mathematical Reasoning [Paper]
- Step-DPO: Step-wise Preference Optimization for Long-chain Reasoning of LLMs [Paper]
- Let's Verify Step by Step. [Paper]
- Improve Mathematical Reasoning in Language Models by Automated Process Supervision [Paper]
- Making Large Language Models Better Reasoners with Step-Aware Verifier [Paper]
- Solving Math Word Problems with Process and Outcome-Based Feedback [Paper]
- Uncertainty-Aware Step-wise Verification with Generative Reward Models [Paper]
- AdaptiveStep: Automatically Dividing Reasoning Step through Model Confidence [Paper]
- Self-Consistency of the Internal Reward Models Improves Self-Rewarding Language Models [Paper]
- Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling [Paper]
- Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals for Reliable Reward Systems [Paper]
- Guided by Gut: Efficient Test-Time Scaling with Reinforced Intrinsic Confidence [Paper]
- LLMs Meet Finance: Fine-Tuning Foundation Models for the Open FinLLM Leaderboard [Paper]


Policy Optimization
- Squeeze the Soaked Sponge: Efficient Off-policy Reinforcement Finetuning for Large Language Model [Paper]

MCTS/Tree Search
- On the Convergence Rate of MCTS for the Optimal Value Estimation in Markov Decision Processes [Paper]
- Search-o1: Agentic Search-Enhanced Large Reasoning Models [Paper]
- rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking [Paper]
- ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search [Paper]
- Forest-of-Thought: Scaling Test-Time Compute for Enhancing LLM Reasoning [Paper]
- HuatuoGPT-o1, Towards Medical Complex Reasoning with LLMs [Paper]
- Mulberry: Empowering MLLM with o1-like Reasoning and Reflection via Collective Monte Carlo Tree Search [Paper]
- Proposing and solving olympiad geometry with guided tree search [Paper]
- SPaR: Self-Play with Tree-Search Refinement to Improve Instruction-Following in Large Language Models [Paper]
- Towards Intrinsic Self-Correction Enhancement in Monte Carlo Tree Search Boosted Reasoning via Iterative Preference Learning [Paper]
- CodeTree: Agent-guided Tree Search for Code Generation with Large Language Models [Paper]
- GPT-Guided Monte Carlo Tree Search for Symbolic Regression in Financial Fraud Detection [Paper]
- MC-NEST -- Enhancing Mathematical Reasoning in Large Language Models with a Monte Carlo Nash Equilibrium Self-Refine Tree [Paper]
- Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions [Paper]
- SRA-MCTS: Self-driven Reasoning Augmentation with Monte Carlo Tree Search for Code Generation [Paper]
- Don’t throw away your value model! Generating more preferable text with Value-Guided Monte-Carlo Tree Search decoding [Paper]
- AFlow: Automating Agentic Workflow Generation [Paper]
- Interpretable Contrastive Monte Carlo Tree Search Reasoning [Paper]
- LLaMA-Berry: Pairwise Optimization for O1-like Olympiad-Level Mathematical Reasoning [Paper]
- Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning [Paper]
- TreeBoN: Enhancing Inference-Time Alignment with Speculative Tree-Search and Best-of-N Sampling [Paper]
- Understanding When Tree of Thoughts Succeeds: Larger Models Excel in Generation, Not Discrimination [Paper]
- RethinkMCTS: Refining Erroneous Thoughts in Monte Carlo Tree Search for Code Generation [Paper]
- Strategist: Learning Strategic Skills by LLMs via Bi-Level Tree Search [Paper]
- LiteSearch: Efficacious Tree Search for LLM [Paper]
- Tree Search for Language Model Agents [Paper]
- Uncertainty-Guided Optimization on Large Language Model Search Trees [Paper]
-
- Accessing GPT-4 level Mathematical Olympiad Solutions via Monte Carlo Tree Self-refine with LLaMa-3 8B [Paper]
- Accessing GPT-4 level Mathematical Olympiad Solutions via Monte Carlo Tree Self-refine with LLaMa-3 8B [Paper]
- Beyond A*: Better Planning with Transformers via Search Dynamics Bootstrapping [Paper]
- LLM Reasoners: New Evaluation, Library, and Analysis of Step-by-Step Reasoning with Large Language Models [Paper]
- AlphaMath Almost Zero: process Supervision without process [Paper]
- Generating Code World Models with Large Language Models Guided by Monte Carlo Tree Search [Paper]
- MindStar: Enhancing Math Reasoning in Pre-trained LLMs at Inference Time [Paper]
- Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning [Paper]
- Stream of Search (SoS): Learning to Search in Language [Paper]
- Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing [Paper]
- Uncertainty of Thoughts: Uncertainty-Aware Planning Enhances Information Seeking in Large Language Models [Paper]
- Reasoning with Language Model is Planning with World Model [Paper]
- Large Language Models as Commonsense Knowledge for Large-Scale Task Planning [Paper]
- ALPHAZERO-LIKE TREE-SEARCH CAN GUIDE LARGE LANGUAGE MODEL DECODING AND TRAINING [Paper]
- Alphazero-like Tree-Search can Guide Large Language Model Decoding and Training [Paper]
- MAKING PPO EVEN BETTER: VALUE-GUIDED MONTE-CARLO TREE SEARCH DECODING [Paper]
- Leveraging Constrained Monte Carlo Tree Search to Generate Reliable Long Chain-of-Thought for Mathematical Reasoning [Paper]
- Hypothesis-Driven Theory-of-Mind Reasoning for Large Language Models [Paper]
- Fine-grained Conversational Decoding via Isotropic and Proximal Search [Paper]
- Control-DAG: Constrained Decoding for Non-Autoregressive Directed Acyclic T5 using Weighted Finite State Automata [Paper]
- Look-back Decoding for Open-Ended Text Generation [Paper]
- LeanProgress: Guiding Search for Neural Theorem Proving via Proof Progress Prediction [Paper]


Explainability
- Agents Thinking Fast and Slow: A Talker-Reasoner Architecture [Paper]
- What Happened in LLMs Layers when Trained for Fast vs. Slow Thinking: A Gradient Perspective [Paper]
- When a Language Model is Optimized for Reasoning, Does It Still Show Embers of Autoregression? An Analysis of OpenAI o1 [Paper]
- The Impact of Reasoning Step Length on Large Language Models [Paper]
- Distilling System 2 into System 1 [Paper]
- System 2 Attention (is something you might need too) [Paper]
- Towards System 2 Reasoning in LLMs: Learning How to Think With Meta Chain-of-Thought [Paper]
- LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLMs [Paper]
- Two Heads Are Better Than One: Dual-Model Verbal Reflection at Inference-Time [Paper]
- Exploring Iterative Enhancement for Improving Learnersourced Multiple-Choice Question Explanations with Large Language Models [Paper]
- AbductionRules: Training Transformers to Explain Unexpected Inputs [Paper]


Multimodal Agent related Slow-Fast System
- Diving into Self-Evolving Training for Multimodal Reasoning [Paper]
- Visual Agents as Fast and Slow Thinkers [Paper]
- Virgo: A Preliminary Exploration on Reproducing o1-like MLLM [Paper]
- Scaling Inference-Time Search With Vision Value Model for Improved Visual Comprehension [Paper]
- Slow Perception: Let's Perceive Geometric Figures Step-by-Step [Paper]
- AtomThink: A Slow Thinking Framework for Multimodal Mathematical Reasoning [Paper]
- LLaVA-o1: Let Vision Language Models Reason Step-by-Step [Paper]
- Vision-Language Models Can Self-Improve Reasoning via Reflection [Paper]
- I Think, Therefore I Diffuse: Enabling Multimodal In-Context Reasoning in Diffusion Models [Paper]
- RAG-Gym: Optimizing Reasoning and Search Agents with Process Supervision [Paper]

Benchmark and Datasets
- PhyX: Does Your Model Have the "Wits" for Physical Reasoning? [Paper]
- Big-Math: A Large-Scale, High-Quality Math Dataset for Reinforcement Learning in Language Models [Paper]
- PRMBench: A Fine-grained and Challenging Benchmark for Process-Level Reward Models [Paper]
- MR-Ben: A Meta-Reasoning Benchmark for Evaluating System-2 Thinking in LLMs [Paper]
- Do NOT Think That Much for 2+3=? On the Overthinking of o1-like LLMs [Paper]
- A Preliminary Study of o1 in Medicine: Are We Closer to an AI Doctor? [Paper]
- EquiBench: Benchmarking Code Reasoning Capabilities of Large Language Models via Equivalence Checking [Paper]
- SuperGPQA: Scaling LLM Evaluation across 285 Graduate Disciplines [Paper]
- Multimodal RewardBench: Holistic Evaluation of Reward Models for Vision Language Models [Paper]
- FrontierMath: A Benchmark for Evaluating Advanced Mathematical Reasoning in AI [Paper]
- Evaluation of OpenAI o1: Opportunities and Challenges of AGI [Paper]
- MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations [Paper]
- LongReason: A Synthetic Long-Context Reasoning Benchmark via Context Expansion [Paper]
- Humanity's Last Exam [Paper]
- LR2Bench: Evaluating Long-chain Reflective Reasoning Capabilities of Large Language Models via Constraint Satisfaction Problems [Paper]
- BIG-Bench Extra Hard [Paper]
- Assessing and Enhancing the Robustness of Large Language Models with Task Structure Variations for Logical Reasoning [Paper]
- Multi-Step Deductive Reasoning Over Natural Language: An Empirical Study on Out-of-Distribution Generalisation [Paper]
- Large Language Models Are Not Strong Abstract Reasoners [Paper]


Reasoning and Safety
- Safety Tax: Safety Alignment Makes Your Large Reasoning Models Less Reasonable [Paper]
- OverThink: Slowdown Attacks on Reasoning LLMs [Paper]
- GuardReasoner: Towards Reasoning-based LLM Safeguards [Paper]
- SafeChain: Safety of Language Models with Long Chain-of-Thought Reasoning Capabilities [Paper]
- ThinkGuard: Deliberative Slow Thinking Leads to Cautious Guardrails [Paper]
- SafeChain: Safety of Language Models with Long Chain-of-Thought Reasoning Capabilities [Paper]
- H-CoT: Hijacking the Chain-of-Thought Safety Reasoning Mechanism to Jailbreak Large Reasoning Models, Including OpenAI o1/o3, DeepSeek-R1, and Gemini 2.0 Flash Thinking [Paper]
- BoT: Breaking Long Thought Processes of o1-like Large Language Models through Backdoor Attack [Paper]
- Abstract Meaning Representation-Based Logic-Driven Data Augmentation for Logical Reasoning [Paper]
- ChatLogic: Integrating Logic Programming with Large Language Models for Multi-step Reasoning [Paper]


🚀 RL & LLM Fine-Tuning Repositories
| # | Repository & Link | Description |
|---|---|---|
| 1 | RL4VLM Archived & Read-Only as of December 15, 2024 | Offers code for fine-tuning large vision-language models as decision-making agents via RL. Includes implementations for training models with task-specific rewards and evaluating them in various environments. |
| 2 | LlamaGym | Simplifies fine-tuning large language model (LLM) agents with online RL. Provides an abstract Agent class to handle various aspects of RL training, allowing for quick iteration and experimentation across different environments. |
| 3 | RL-Based Fine-Tuning of Diffusion Models for Biological Sequences | Accompanies a tutorial and review paper on RL-based fine-tuning, focusing on the design of biological sequences (DNA/RNA). Provides comprehensive tutorials and code implementations for training and fine-tuning diffusion models using RL. |
| 4 | LM-RL-Finetune | Aims to improve KL penalty optimization in RL fine-tuning of language models by computing the KL penalty term analytically. Includes configurations for training with Proximal Policy Optimization (PPO). |
| 5 | InstructLLaMA | Implements pre-training, supervised fine-tuning (SFT), and reinforcement learning from human feedback (RLHF) to train and fine-tune the LLaMA2 model to follow human instructions, similar to InstructGPT or ChatGPT. |
| 6 | SEIKO | Introduces a novel RL method to efficiently fine-tune diffusion models in an online setting. Its techniques outperform baselines such as PPO, classifier-based guidance, and direct reward backpropagation for fine-tuning Stable Diffusion. |
| 7 | TRL (Train Transformer Language Models with RL) | A state-of-the-art library for post-training foundation models using methods like Supervised Fine-Tuning (SFT), Proximal Policy Optimization (PPO), GRPO, and Direct Preference Optimization (DPO). Built on the 🤗 Transformers ecosystem, it supports multiple model architectures and scales efficiently across hardware setups. |
| 8 | Fine-Tuning Reinforcement Learning Models as Continual Learning | Explores fine-tuning RL models as a forgetting mitigation problem (continual learning). Provides insights and code implementations to address forgetting in RL models. |
| 9 | RL4LMs | A modular RL library to fine-tune language models to human preferences. Rigorously evaluated through 2000+ experiments using the GRUE benchmark, ensuring robustness across various NLP tasks. |
| 10 | Lamorel | A high-throughput, distributed architecture for seamless LLM integration in interactive environments. While not specialized in RL or RLHF by default, it supports custom implementations and is ideal for users needing maximum flexibility. |
| 11 | LLM-Reverse-Curriculum-RL | Implements the ICML 2024 paper "Training Large Language Models for Reasoning through Reverse Curriculum Reinforcement Learning". Focuses on enhancing LLM reasoning capabilities using a reverse curriculum RL approach. |
| 12 | veRL | A flexible, efficient, and production-ready RL training library for large language models (LLMs). Serves as the open-source implementation of the HybridFlow framework and supports various RL algorithms (PPO, GRPO), advanced resource utilization, and scalability up to 70B models on hundreds of GPUs. Integrates with Hugging Face models, supervised fine-tuning, and RLHF with multiple reward types. |
| 13 | trlX | A distributed training framework for fine-tuning large language models (LLMs) with reinforcement learning. Supports both Accelerate and NVIDIA NeMo backends, allowing training of models up to 20B+ parameters. Implements PPO and ILQL, and integrates with CHEESE for human-in-the-loop data collection. |
| 14 | Okapi | A framework for instruction tuning in LLMs with RLHF, supporting 26 languages. Provides multilingual resources such as ChatGPT prompts, instruction datasets, and response ranking data, along with both BLOOM-based and LLaMa-based models and evaluation benchmarks. |
| 15 | LLaMA-Factory | Unified Efficient Fine-Tuning of 100+ LLMs & VLMs (ACL 2024). Supports a wide array of models (e.g., LLaMA, LLaVA, Qwen, Mistral) with methods including pre-training, multimodal fine-tuning, reward modeling, PPO, DPO, and ORPO. Offers scalable tuning (16-bit, LoRA, QLoRA) with advanced optimizations and logging integrations, and provides fast inference via API, Gradio UI, and CLI with vLLM workers. |
⚡ Applications & Benchmarks
- "AutoGPT: LLMs for Autonomous RL Agents" - OpenAI (2023) [Paper]
- "Barkour: Benchmarking LLM-Augmented RL" - Wu et al. (2023) [Paper]
- Colon-X: Advancing Intelligent Colonoscopy from Multimodal Understanding to Clinical Reasoning (Medical Understanding & Reasoning) [Paper]
[Code]
- Big-Math: A Large-Scale, High-Quality Math Dataset for Reinforcement Learning in Language Models [Paper]
- PRMBench: A Fine-grained and Challenging Benchmark for Process-Level Reward Models [Paper]
- MR-Ben: A Meta-Reasoning Benchmark for Evaluating System-2 Thinking in LLMs [Paper]
- Do NOT Think That Much for 2+3=? On the Overthinking of o1-like LLMs [Paper]
- A Preliminary Study of o1 in Medicine: Are We Closer to an AI Doctor? [Paper]
- EquiBench: Benchmarking Code Reasoning Capabilities of Large Language Models via Equivalence Checking [Paper]
- SuperGPQA: Scaling LLM Evaluation across 285 Graduate Disciplines [Paper]
- Multimodal RewardBench: Holistic Evaluation of Reward Models for Vision Language Models [Paper]
- FrontierMath: A Benchmark for Evaluating Advanced Mathematical Reasoning in AI [Paper]
- Evaluation of OpenAI o1: Opportunities and Challenges of AGI [Paper]
- MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations [Paper]
- LongReason: A Synthetic Long-Context Reasoning Benchmark via Context Expansion [Paper]
- Humanity's Last Exam [Paper]
- LR2Bench: Evaluating Long-chain Reflective Reasoning Capabilities of Large Language Models via Constraint Satisfaction Problems [Paper]
- BIG-Bench Extra Hard [Paper]
📚 Tutorials & Courses
🛠️ Libraries & Implementations
🔗 Other Resources
📌 Contributing
Contributions are welcome! If you have relevant papers, code, or insights, feel free to submit a pull request.
Citation
If you find our work useful or use it in your research, please consider citing:
@misc{kumar2025llmposttrainingdeepdive,
      title={LLM Post-Training: A Deep Dive into Reasoning Large Language Models},
      author={Komal Kumar and Tajamul Ashraf and Omkar Thawakar and Rao Muhammad Anwer and Hisham Cholakkal and Mubarak Shah and Ming-Hsuan Yang and Phillip H. S. Torr and Fahad Shahbaz Khan and Salman Khan},
      year={2025},
      eprint={2502.21321},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2502.21321},
}
License :scroll:

This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License.
Star History Chart
Looking forward to your feedback, contributions, and stars! :star2: Please raise any issues or questions here.
Contributors


Similar repos


Languages
Python
100.0%
README
LLM Post-Training: A Deep Dive into Reasoning Large Language Models
Welcome to the Awesome-LLM-Post-training repository! This repository is a curated collection of the most influential papers, code implementations, benchmarks, and resources related to Large Language Models (LLMs) Post-Training Methodologies.
🎉 News
- Our survey paper, “LLM Post-Training: A Deep Dive into Reasoning Large Language Models,” has been accepted for publication in IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI).
Our work is based on the following paper:
📄 LLM Post-Training: A Deep Dive into Reasoning Large Language Models – Available on
Komal Kumar* , Tajamul Ashraf* , Omkar Thawakar , Rao Muhammad Anwer , Hisham Cholakkal , Mubarak Shah , Ming-Hsuan Yang , Philip H.S. Torr , Fahad Shahbaz Khan , and Salman Khan
* Equally contributing first authors
- Corresponding authors: Komal Kumar, Tajamul Ashraf.
Feel free to ⭐ star and fork this repository to keep up with the latest advancements and contribute to the community.
📌 Contents
| Section | Subsection |
|---|---|
| 📖 Papers | Survey, Theory, Explainability |
| 🤖 LLMs in RL | LLM-Augmented Reinforcement Learning |
| 🏆 Reward Learning | Human Feedback, Preference-Based RL, Intrinsic Motivation |
| 🚀 Policy Optimization | Offline RL, Imitation Learning, Hierarchical RL |
| 🧠 LLMs for Reasoning & Decision-Making | Causal Reasoning, Planning, Commonsense RL |
| 🌀 Exploration & Generalization | Zero-Shot RL, Generalization in RL, Self-Supervised RL |
| 🤝 Multi-Agent RL (MARL) | Emergent Communication, Coordination, Social RL |
| ⚡ Applications & Benchmarks | Autonomous Agents, Simulations, LLM-RL Benchmarks |
| 📚 Tutorials & Courses | Lectures, Workshops |
| 🛠️ Libraries & Implementations | Open-Source RL-LLM Frameworks |
| 🔗 Other Resources | Additional Research & Readings |
📖 Papers
🔍 Survey
| Title | Publication Date | Link |
|---|---|---|
| A Survey on Bridging VLMs and Synthetic Data | 16 May 2025 | OpenReview |
| A Survey on Post-training of Large Language Models | 8 Mar 2025 | Arxiv |
| LLM Post-Training: A Deep Dive into Reasoning Large Language Models | 28 Feb 2025 | Arxiv |
| From System 1 to System 2: A Survey of Reasoning Large Language Models | 25 Feb 2025 | Arxiv |
| Empowering LLMs with Logical Reasoning: A Comprehensive Survey | 24 Feb 2025 | Arxiv |
| Towards Large Reasoning Models: A Survey of Reinforced Reasoning with Large Language Models | 16 Jan 2025 | Arxiv |
| Harmful Fine-tuning Attacks and Defenses for Large Language Models: A Survey | 26 Sep 2024 | Arxiv |
| Reasoning with Large Language Models, a Survey | 16 July 2024 | Arxiv |
| Survey on Large Language Model-Enhanced Reinforcement Learning: Concept, Taxonomy, and Methods | 30 Mar 2024 | Arxiv |
| Reinforcement Learning Enhanced LLMs: A Survey | 5 Dec 2024 | Arxiv |
| Enhancing Code LLMs with Reinforcement Learning in Code Generation: A Survey | 29 Dec 2024 | Arxiv |
| Large Language Models: A Survey of Their Development, Capabilities, and Applications | 15 Jan 2025 | Springer |
| A Survey on Multimodal Large Language Models | 10 Feb 2025 | Oxford Academic |
| Large Language Models (LLMs): Survey, Technical Frameworks, and Future Directions | 20 Jul 2024 | Springer |
| Using Large Language Models to Automate and Expedite Reinforcement Learning with Reward Machines | 11 Feb 2024 | Arxiv |
| ExploRLLM: Guiding Exploration in Reinforcement Learning with Large Language Models | 14 Mar 2024 | Arxiv |
| Reinforcement Learning Problem Solving with Large Language Models | 29 Apr 2024 | Arxiv |
| A Survey on Large Language Models for Reinforcement Learning | 10 Dec 2023 | Arxiv |
| Large Language Models as Decision-Makers: A Survey | 23 Aug 2023 | Arxiv |
| A Survey on Large Language Model Alignment Techniques | 6 May 2023 | Arxiv |
| Reinforcement Learning with Human Feedback: A Survey | 12 April 2023 | Arxiv |
| Reasoning with Large Language Models: A Survey | 14 Feb 2023 | Arxiv |
| A Survey on Foundation Models for Decision Making | 9 Jan 2023 | Arxiv |
| Large Language Models in Reinforcement Learning: Opportunities and Challenges | 5 Dec 2022 | Arxiv |
| Training language models to follow instructions with human feedback | 4 Mar 2022 | Arxiv |
🤖 LLMs-in-RL
- Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play [Paper]
- Satori: Reinforcement Learning with Chain-of-Action-Thought Enhances LLM Reasoning via Autoregressive Search [Paper]
- DeepScaleR: Surpassing O1-Preview with a 1.5B Model by Scaling RL [Paper]
- QLASS: Boosting Language Agent Inference via Q-Guided Stepwise Search [Paper]
- Process Reinforcement through Implicit Rewards [Paper]
- Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling [Paper]
- Challenges in Ensuring AI Safety in DeepSeek-R1 Models: The Shortcomings of Reinforcement Learning Strategies [Paper]
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning [Paper]
- Kimi k1.5: Scaling Reinforcement Learning with LLMs [Paper]
- Does RLHF Scale? Exploring the Impacts From Data, Model, and Method [Paper]
- Offline Reinforcement Learning for LLM Multi-Step Reasoning [Paper]
- ReFT: Representation Finetuning for Language Models [Paper]
- Deepseekmath: Pushing the limits of mathematical reasoning in open language models [Paper]
- Reasoning with Reinforced Functional Token Tuning [Paper]
- Value-Based Deep RL Scales Predictably [Paper]
- InfAlign: Inference-aware language model alignment [Paper]
- LIMR: Less is More for RL Scaling [Paper]
- A Survey on Feedback-based Multi-step Reasoning for Large Language Models on Mathematics [Paper]
🏆 Reward Learning (Process Reward Models)
- PRMBench: A Fine-grained and Challenging Benchmark for Process-Level Reward Models. [Paper]
- ReARTeR: Retrieval-Augmented Reasoning with Trustworthy Process Rewarding [Paper]
- The Lessons of Developing Process Reward Models in Mathematical Reasoning. [Paper]
- ToolComp: A Multi-Tool Reasoning & Process Supervision Benchmark. [Paper]
- AutoPSV: Automated Process-Supervised Verifier [Paper]
- ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search [Paper]
- Free Process Rewards without Process Labels. [Paper]
- Outcome-Refining Process Supervision for Code Generation [Paper]
- Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations [Paper]
- OVM: Outcome-supervised Value Models for Planning in Mathematical Reasoning [Paper]
- Step-DPO: Step-wise Preference Optimization for Long-chain Reasoning of LLMs [Paper]
- Let's Verify Step by Step. [Paper]
- Improve Mathematical Reasoning in Language Models by Automated Process Supervision [Paper]
- Making Large Language Models Better Reasoners with Step-Aware Verifier [Paper]
- Solving Math Word Problems with Process and Outcome-Based Feedback [Paper]
- Uncertainty-Aware Step-wise Verification with Generative Reward Models [Paper]
- AdaptiveStep: Automatically Dividing Reasoning Step through Model Confidence [Paper]
- Self-Consistency of the Internal Reward Models Improves Self-Rewarding Language Models [Paper]
- Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling [Paper]
- Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals for Reliable Reward Systems [Paper]
- Guided by Gut: Efficient Test-Time Scaling with Reinforced Intrinsic Confidence [Paper]
- LLMs Meet Finance: Fine-Tuning Foundation Models for the Open FinLLM Leaderboard [Paper]
Policy Optimization
- Squeeze the Soaked Sponge: Efficient Off-policy Reinforcement Finetuning for Large Language Model [Paper]
MCTS/Tree Search
- On the Convergence Rate of MCTS for the Optimal Value Estimation in Markov Decision Processes [Paper]
- Search-o1: Agentic Search-Enhanced Large Reasoning Models [Paper]
- rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking [Paper]
- ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search [Paper]
- Forest-of-Thought: Scaling Test-Time Compute for Enhancing LLM Reasoning [Paper]
- HuatuoGPT-o1, Towards Medical Complex Reasoning with LLMs [Paper]
- Mulberry: Empowering MLLM with o1-like Reasoning and Reflection via Collective Monte Carlo Tree Search [Paper]
- Proposing and solving olympiad geometry with guided tree search [Paper]
- SPaR: Self-Play with Tree-Search Refinement to Improve Instruction-Following in Large Language Models [Paper]
- Towards Intrinsic Self-Correction Enhancement in Monte Carlo Tree Search Boosted Reasoning via Iterative Preference Learning [Paper]
- CodeTree: Agent-guided Tree Search for Code Generation with Large Language Models [Paper]
- GPT-Guided Monte Carlo Tree Search for Symbolic Regression in Financial Fraud Detection [Paper]
- MC-NEST -- Enhancing Mathematical Reasoning in Large Language Models with a Monte Carlo Nash Equilibrium Self-Refine Tree [Paper]
- Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions [Paper]
- SRA-MCTS: Self-driven Reasoning Augmentation with Monte Carlo Tree Search for Code Generation [Paper]
- Don’t throw away your value model! Generating more preferable text with Value-Guided Monte-Carlo Tree Search decoding [Paper]
- AFlow: Automating Agentic Workflow Generation [Paper]
- Interpretable Contrastive Monte Carlo Tree Search Reasoning [Paper]
- LLaMA-Berry: Pairwise Optimization for O1-like Olympiad-Level Mathematical Reasoning [Paper]
- Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning [Paper]
- TreeBoN: Enhancing Inference-Time Alignment with Speculative Tree-Search and Best-of-N Sampling [Paper]
- Understanding When Tree of Thoughts Succeeds: Larger Models Excel in Generation, Not Discrimination [Paper]
- RethinkMCTS: Refining Erroneous Thoughts in Monte Carlo Tree Search for Code Generation [Paper]
- Strategist: Learning Strategic Skills by LLMs via Bi-Level Tree Search [Paper]
- LiteSearch: Efficacious Tree Search for LLM [Paper]
- Tree Search for Language Model Agents [Paper]
- Uncertainty-Guided Optimization on Large Language Model Search Trees [Paper]
-
- Accessing GPT-4 level Mathematical Olympiad Solutions via Monte Carlo Tree Self-refine with LLaMa-3 8B [Paper]
- Accessing GPT-4 level Mathematical Olympiad Solutions via Monte Carlo Tree Self-refine with LLaMa-3 8B [Paper]
- Beyond A*: Better Planning with Transformers via Search Dynamics Bootstrapping [Paper]
- LLM Reasoners: New Evaluation, Library, and Analysis of Step-by-Step Reasoning with Large Language Models [Paper]
- AlphaMath Almost Zero: process Supervision without process [Paper]
- Generating Code World Models with Large Language Models Guided by Monte Carlo Tree Search [Paper]
- MindStar: Enhancing Math Reasoning in Pre-trained LLMs at Inference Time [Paper]
- Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning [Paper]
- Stream of Search (SoS): Learning to Search in Language [Paper]
- Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing [Paper]
- Uncertainty of Thoughts: Uncertainty-Aware Planning Enhances Information Seeking in Large Language Models [Paper]
- Reasoning with Language Model is Planning with World Model [Paper]
- Large Language Models as Commonsense Knowledge for Large-Scale Task Planning [Paper]
- ALPHAZERO-LIKE TREE-SEARCH CAN GUIDE LARGE LANGUAGE MODEL DECODING AND TRAINING [Paper]
- Alphazero-like Tree-Search can Guide Large Language Model Decoding and Training [Paper]
- MAKING PPO EVEN BETTER: VALUE-GUIDED MONTE-CARLO TREE SEARCH DECODING [Paper]
- Leveraging Constrained Monte Carlo Tree Search to Generate Reliable Long Chain-of-Thought for Mathematical Reasoning [Paper]
- Hypothesis-Driven Theory-of-Mind Reasoning for Large Language Models [Paper]
- Fine-grained Conversational Decoding via Isotropic and Proximal Search [Paper]
- Control-DAG: Constrained Decoding for Non-Autoregressive Directed Acyclic T5 using Weighted Finite State Automata [Paper]
- Look-back Decoding for Open-Ended Text Generation [Paper]
- LeanProgress: Guiding Search for Neural Theorem Proving via Proof Progress Prediction [Paper]
Explainability
- Agents Thinking Fast and Slow: A Talker-Reasoner Architecture [Paper]
- What Happened in LLMs Layers when Trained for Fast vs. Slow Thinking: A Gradient Perspective [Paper]
- When a Language Model is Optimized for Reasoning, Does It Still Show Embers of Autoregression? An Analysis of OpenAI o1 [Paper]
- The Impact of Reasoning Step Length on Large Language Models [Paper]
- Distilling System 2 into System 1 [Paper]
- System 2 Attention (is something you might need too) [Paper]
- Towards System 2 Reasoning in LLMs: Learning How to Think With Meta Chain-of-Thought [Paper]
- LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLMs [Paper]
- Two Heads Are Better Than One: Dual-Model Verbal Reflection at Inference-Time [Paper]
- Exploring Iterative Enhancement for Improving Learnersourced Multiple-Choice Question Explanations with Large Language Models [Paper]
- AbductionRules: Training Transformers to Explain Unexpected Inputs [Paper]
Multimodal Agent related Slow-Fast System
- Diving into Self-Evolving Training for Multimodal Reasoning [Paper]
- Visual Agents as Fast and Slow Thinkers [Paper]
- Virgo: A Preliminary Exploration on Reproducing o1-like MLLM [Paper]
- Scaling Inference-Time Search With Vision Value Model for Improved Visual Comprehension [Paper]
- Slow Perception: Let's Perceive Geometric Figures Step-by-Step [Paper]
- AtomThink: A Slow Thinking Framework for Multimodal Mathematical Reasoning [Paper]
- LLaVA-o1: Let Vision Language Models Reason Step-by-Step [Paper]
- Vision-Language Models Can Self-Improve Reasoning via Reflection [Paper]
- I Think, Therefore I Diffuse: Enabling Multimodal In-Context Reasoning in Diffusion Models [Paper]
- RAG-Gym: Optimizing Reasoning and Search Agents with Process Supervision [Paper]
Benchmark and Datasets
- PhyX: Does Your Model Have the "Wits" for Physical Reasoning? [Paper]
- Big-Math: A Large-Scale, High-Quality Math Dataset for Reinforcement Learning in Language Models [Paper]
- PRMBench: A Fine-grained and Challenging Benchmark for Process-Level Reward Models [Paper]
- MR-Ben: A Meta-Reasoning Benchmark for Evaluating System-2 Thinking in LLMs [Paper]
- Do NOT Think That Much for 2+3=? On the Overthinking of o1-like LLMs [Paper]
- A Preliminary Study of o1 in Medicine: Are We Closer to an AI Doctor? [Paper]
- EquiBench: Benchmarking Code Reasoning Capabilities of Large Language Models via Equivalence Checking [Paper]
- SuperGPQA: Scaling LLM Evaluation across 285 Graduate Disciplines [Paper]
- Multimodal RewardBench: Holistic Evaluation of Reward Models for Vision Language Models [Paper]
- FrontierMath: A Benchmark for Evaluating Advanced Mathematical Reasoning in AI [Paper]
- Evaluation of OpenAI o1: Opportunities and Challenges of AGI [Paper]
- MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations [Paper]
- LongReason: A Synthetic Long-Context Reasoning Benchmark via Context Expansion [Paper]
- Humanity's Last Exam [Paper]
- LR2Bench: Evaluating Long-chain Reflective Reasoning Capabilities of Large Language Models via Constraint Satisfaction Problems [Paper]
- BIG-Bench Extra Hard [Paper]
- Assessing and Enhancing the Robustness of Large Language Models with Task Structure Variations for Logical Reasoning [Paper]
- Multi-Step Deductive Reasoning Over Natural Language: An Empirical Study on Out-of-Distribution Generalisation [Paper]
- Large Language Models Are Not Strong Abstract Reasoners [Paper]
Reasoning and Safety
- Safety Tax: Safety Alignment Makes Your Large Reasoning Models Less Reasonable [Paper]
- OverThink: Slowdown Attacks on Reasoning LLMs [Paper]
- GuardReasoner: Towards Reasoning-based LLM Safeguards [Paper]
- SafeChain: Safety of Language Models with Long Chain-of-Thought Reasoning Capabilities [Paper]
- ThinkGuard: Deliberative Slow Thinking Leads to Cautious Guardrails [Paper]
- SafeChain: Safety of Language Models with Long Chain-of-Thought Reasoning Capabilities [Paper]
- H-CoT: Hijacking the Chain-of-Thought Safety Reasoning Mechanism to Jailbreak Large Reasoning Models, Including OpenAI o1/o3, DeepSeek-R1, and Gemini 2.0 Flash Thinking [Paper]
- BoT: Breaking Long Thought Processes of o1-like Large Language Models through Backdoor Attack [Paper]
- Abstract Meaning Representation-Based Logic-Driven Data Augmentation for Logical Reasoning [Paper]
- ChatLogic: Integrating Logic Programming with Large Language Models for Multi-step Reasoning [Paper]
🚀 RL & LLM Fine-Tuning Repositories
| # | Repository & Link | Description |
|---|---|---|
| 1 | RL4VLM Archived & Read-Only as of December 15, 2024 | Offers code for fine-tuning large vision-language models as decision-making agents via RL. Includes implementations for training models with task-specific rewards and evaluating them in various environments. |
| 2 | LlamaGym | Simplifies fine-tuning large language model (LLM) agents with online RL. Provides an abstract Agent class to handle various aspects of RL training, allowing for quick iteration and experimentation across different environments. |
| 3 | RL-Based Fine-Tuning of Diffusion Models for Biological Sequences | Accompanies a tutorial and review paper on RL-based fine-tuning, focusing on the design of biological sequences (DNA/RNA). Provides comprehensive tutorials and code implementations for training and fine-tuning diffusion models using RL. |
| 4 | LM-RL-Finetune | Aims to improve KL penalty optimization in RL fine-tuning of language models by computing the KL penalty term analytically. Includes configurations for training with Proximal Policy Optimization (PPO). |
| 5 | InstructLLaMA | Implements pre-training, supervised fine-tuning (SFT), and reinforcement learning from human feedback (RLHF) to train and fine-tune the LLaMA2 model to follow human instructions, similar to InstructGPT or ChatGPT. |
| 6 | SEIKO | Introduces a novel RL method to efficiently fine-tune diffusion models in an online setting. Its techniques outperform baselines such as PPO, classifier-based guidance, and direct reward backpropagation for fine-tuning Stable Diffusion. |
| 7 | TRL (Train Transformer Language Models with RL) | A state-of-the-art library for post-training foundation models using methods like Supervised Fine-Tuning (SFT), Proximal Policy Optimization (PPO), GRPO, and Direct Preference Optimization (DPO). Built on the 🤗 Transformers ecosystem, it supports multiple model architectures and scales efficiently across hardware setups. |
| 8 | Fine-Tuning Reinforcement Learning Models as Continual Learning | Explores fine-tuning RL models as a forgetting mitigation problem (continual learning). Provides insights and code implementations to address forgetting in RL models. |
| 9 | RL4LMs | A modular RL library to fine-tune language models to human preferences. Rigorously evaluated through 2000+ experiments using the GRUE benchmark, ensuring robustness across various NLP tasks. |
| 10 | Lamorel | A high-throughput, distributed architecture for seamless LLM integration in interactive environments. While not specialized in RL or RLHF by default, it supports custom implementations and is ideal for users needing maximum flexibility. |
| 11 | LLM-Reverse-Curriculum-RL | Implements the ICML 2024 paper "Training Large Language Models for Reasoning through Reverse Curriculum Reinforcement Learning". Focuses on enhancing LLM reasoning capabilities using a reverse curriculum RL approach. |
| 12 | veRL | A flexible, efficient, and production-ready RL training library for large language models (LLMs). Serves as the open-source implementation of the HybridFlow framework and supports various RL algorithms (PPO, GRPO), advanced resource utilization, and scalability up to 70B models on hundreds of GPUs. Integrates with Hugging Face models, supervised fine-tuning, and RLHF with multiple reward types. |
| 13 | trlX | A distributed training framework for fine-tuning large language models (LLMs) with reinforcement learning. Supports both Accelerate and NVIDIA NeMo backends, allowing training of models up to 20B+ parameters. Implements PPO and ILQL, and integrates with CHEESE for human-in-the-loop data collection. |
| 14 | Okapi | A framework for instruction tuning in LLMs with RLHF, supporting 26 languages. Provides multilingual resources such as ChatGPT prompts, instruction datasets, and response ranking data, along with both BLOOM-based and LLaMa-based models and evaluation benchmarks. |
| 15 | LLaMA-Factory | Unified Efficient Fine-Tuning of 100+ LLMs & VLMs (ACL 2024). Supports a wide array of models (e.g., LLaMA, LLaVA, Qwen, Mistral) with methods including pre-training, multimodal fine-tuning, reward modeling, PPO, DPO, and ORPO. Offers scalable tuning (16-bit, LoRA, QLoRA) with advanced optimizations and logging integrations, and provides fast inference via API, Gradio UI, and CLI with vLLM workers. |
⚡ Applications & Benchmarks
- "AutoGPT: LLMs for Autonomous RL Agents" - OpenAI (2023) [Paper]
- "Barkour: Benchmarking LLM-Augmented RL" - Wu et al. (2023) [Paper]
- Colon-X: Advancing Intelligent Colonoscopy from Multimodal Understanding to Clinical Reasoning (Medical Understanding & Reasoning) [Paper]
- Big-Math: A Large-Scale, High-Quality Math Dataset for Reinforcement Learning in Language Models [Paper]
- PRMBench: A Fine-grained and Challenging Benchmark for Process-Level Reward Models [Paper]
- MR-Ben: A Meta-Reasoning Benchmark for Evaluating System-2 Thinking in LLMs [Paper]
- Do NOT Think That Much for 2+3=? On the Overthinking of o1-like LLMs [Paper]
- A Preliminary Study of o1 in Medicine: Are We Closer to an AI Doctor? [Paper]
- EquiBench: Benchmarking Code Reasoning Capabilities of Large Language Models via Equivalence Checking [Paper]
- SuperGPQA: Scaling LLM Evaluation across 285 Graduate Disciplines [Paper]
- Multimodal RewardBench: Holistic Evaluation of Reward Models for Vision Language Models [Paper]
- FrontierMath: A Benchmark for Evaluating Advanced Mathematical Reasoning in AI [Paper]
- Evaluation of OpenAI o1: Opportunities and Challenges of AGI [Paper]
- MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations [Paper]
- LongReason: A Synthetic Long-Context Reasoning Benchmark via Context Expansion [Paper]
- Humanity's Last Exam [Paper]
- LR2Bench: Evaluating Long-chain Reflective Reasoning Capabilities of Large Language Models via Constraint Satisfaction Problems [Paper]
- BIG-Bench Extra Hard [Paper]
📚 Tutorials & Courses
🛠️ Libraries & Implementations
🔗 Other Resources
📌 Contributing
Contributions are welcome! If you have relevant papers, code, or insights, feel free to submit a pull request.
Citation
If you find our work useful or use it in your research, please consider citing:
@misc{kumar2025llmposttrainingdeepdive,
      title={LLM Post-Training: A Deep Dive into Reasoning Large Language Models},
      author={Komal Kumar and Tajamul Ashraf and Omkar Thawakar and Rao Muhammad Anwer and Hisham Cholakkal and Mubarak Shah and Ming-Hsuan Yang and Phillip H. S. Torr and Fahad Shahbaz Khan and Salman Khan},
      year={2025},
      eprint={2502.21321},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2502.21321},
}
License :scroll:
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License.
Star History Chart
Looking forward to your feedback, contributions, and stars! :star2: Please raise any issues or questions here.
Similar repos
Contributors
Languages
Python
100.0%