
README
Awesome LLM Reasoning Failures


A curated list of papers on discovery, analysis, and mitigation of LLM reasoning failures.
This repository accompanies the paper "Large Language Model Reasoning Failures" (TMLR 2026 Survey Certification).
If you find this work useful, please consider citing:
@article{songllmreasoningfailures,
  title={Large Language Model Reasoning Failures},
  author={Song, Peiyang and Han, Pengrui and Goodman, Noah},
  journal={Transactions on Machine Learning Research}
}
🗂️ Table of Contents
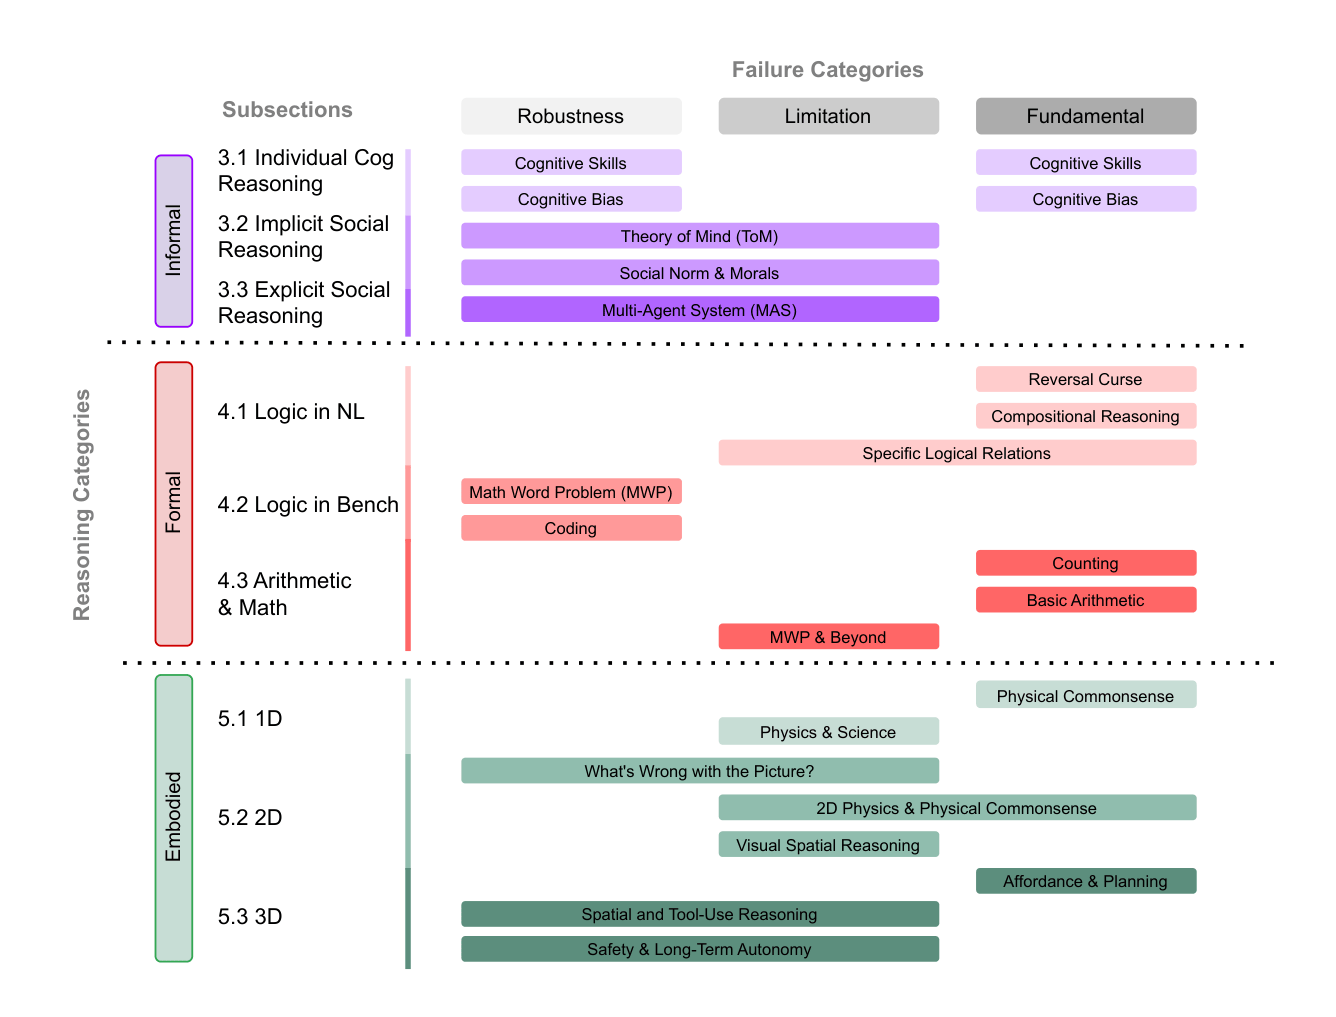
Relevant Surveys & Benchmarks for Reasoning Failures
-
Large Language Model Reasoning Failures
TMLR 2026[paper]Song, Peiyang and Han, Pengrui and Goodman, Noah
-
[Related] Why Do Multi-Agent LLM Systems Fail?
NeurIPS 2025[paper]Cemri, Mert and Pan, Melissa Z. and Yang, Shuyi and Agrawal, Lakshya A. and Chopra, Bhavya and Tiwari, Rishabh and Keutzer, Kurt and Parameswaran, Aditya and Klein, Dan and Ramchandran, Kannan and Zaharia, Matei and Gonzalez, Joseph E. and Stoica, Ion
-
[Related] REFUTE: Apache-2.0 benchmark for scientific critique & epistemic calibration on recent (2025–2026) science summaries. Separates critique skill from calibrated truthfulness (falsification, limitations, overclaims, missing-evidence refusal, confidence calibration, planted-flaw detection). Leaderboard · Technical report · Integrators
Informal Reasoning - Intuitive Cognition and Social Behavior
Individual Cognitive Skills and Biases
-
Working memory capacity of ChatGPT: An empirical study
AAAI 2024[paper]Gong, Dongyu and Wan, Xingchen and Wang, Dingmin
-
Working memory identifies reasoning limits in language models
EMNLP 2024[paper]Zhang, Chunhui and Jian, Yiren and Ouyang, Zhongyu and Vosoughi, Soroush
-
Self-Attention Limits Working Memory Capacity of Transformer-Based Modelss
NeurIPS 2024 Workshop on Behavioral ML[paper]Dongyu Gong and Hantao Zhang
-
Unable to Forget: Proactive lnterference Reveals Working Memory Limits in LLMs Beyond Context Length
ICML 2025 LCFM Workshop[paper]Chupei Wang and Jiaqiu Vince Sun
-
LLMs Do Not Have Human-Like Working Memory
arXiv preprint[paper]Huang, Jen-tse and Sun, Kaiser and Wang, Wenxuan and Dredze, Mark
-
Working memory attack on LLMs
ICLR 2025 Workshop on BuildingTrust[paper]Upadhayay, Bibek and Behzadan, Vahid and Karbasi, Amin
-
In-Context Learning May Not Elicit Trustworthy Reasoning: A-Not-B Errors in Pretrained Language Models
EMNLP 2024[paper]Han, Pengrui and Song, Peiyang and Yu, Haofei and You, Jiaxuan
-
Deficient Executive Control in Transformer Attention
bioRxiv preprint[paper]Patel, Suketu and Wang, Hongbin and Fan, Jin
-
Cognitive flexibility of large language models
ICML 2024 Workshop on LLMs and Cognition[paper]Kennedy, Sean M and Nowak, Robert D
-
LLMs and the Abstraction and Reasoning Corpus: Successes, Failures, and the Importance of Object-based Representations
TMLR 2024[paper]Xu, Yudong and Li, Wenhao and Vaezipoor, Pashootan and Sanner, Scott and Khalil, Elias B
-
Large language models are not strong abstract reasoners
arXiv preprint[paper]Gendron, Ga{"e}l and Bao, Qiming and Witbrock, Michael and Dobbie, Gillian
-
Evidence of Cognitive Deficits and Developmental Advances in Generative AI: A Clock Drawing Test Analysis
arXiv preprint[paper]Galatzer-Levy, Isaac R and McGiffin, Jed and Munday, David and Liu, Xin and Karmon, Danny and Labzovsky, Ilia and Moroshko, Rivka and Zait, Amir and McDuff, Daniel
-
Lost in Time: Clock and Calendar Understanding Challenges in Multimodal LLMs
arXiv preprint[paper]Rohit Saxena and Aryo Pradipta Gema and Pasquale Minervini
-
Language models, like humans, show content effects on reasoning tasks
PNAS Nexus 2024[paper]Lampinen, Andrew K and Dasgupta, Ishita and Chan, Stephanie CY and Sheahan, Hannah R and Creswell, Antonia and Kumaran, Dharshan and McClelland, James L and Hill, Felix
-
Confirmation and Specificity Biases in Large Language Models: An Explorative Study
IEEE Intelligent Systems[paper]O’Leary, Daniel E
-
Unveiling Confirmation Bias in Chain-of-Thought Reasoning
ACL 2025[paper]Yue Wan and Xiaowei Jia and Xiang Lorraine Li
-
Conformity in Large Language Models
ACL 2025[paper]Zhu, Xiaochen and Zhang, Caiqi and Stafford, Tom and Collier, Nigel and Vlachos, Andreas
-
Argumentative Experience: Reducing Confirmation Bias on Controversial Issues through LLM-Generated Multi-Persona Debates
arXiv preprint[paper]Shi, Li and Liu, Houjiang and Wong, Yian and Mujumdar, Utkarsh and Zhang, Dan and Gwizdka, Jacek and Lease, Matthew
-
A Comprehensive Evaluation of Cognitive Biases in LLMs
arXiv preprint[paper]Malberg, Simon and Poletukhin, Roman and Schuster, Carolin M and Groh, Georg
-
Cognitive bias in high-stakes decision-making with llms
EMNLP 2024[paper]Echterhoff, Jessica and Liu, Yao and Alessa, Abeer and McAuley, Julian and He, Zexue
-
Correcting negative bias in large language models through negative attention score alignment
arXiv preprint[paper]Koo, Ryan and Lee, Minhwa and Raheja, Vipul and Park, Jong Inn and Kim, Zae Myung and Kang, Dongyeop
-
Capturing failures of large language models via human cognitive biases
NeurIPS 2022[paper]Jones, Erik and Steinhardt, Jacob
-
Do large language models show decision heuristics similar to humans? A case study using GPT-3.5.
Journal of Experimental Psychology: General 2024[paper]Suri, Gaurav and Slater, Lily R and Ziaee, Ali and Nguyen, Morgan
-
Human bias in AI models? Anchoring effects and mitigation strategies in large language models
Journal of Behavioral and Experimental Finance[paper]Nguyen, Jeremy K
-
An Anchoring Effect in Large Language Models
IEEE Intelligent Systems 2025[paper]O’Leary, Daniel E
-
An Empirical Study of the Anchoring Effect in LLMs: Existence, Mechanism, and Potential Mitigations
arXiv preprint[paper]Huang, Yiming and Bie, Biquan and Na, Zuqiu and Ruan, Weilin and Lei, Songxin and Yue, Yutao and He, Xinlei
-
Assessing Judging Bias in Large Reasoning Models: An Empirical Study
arXiv preprint[paper]Wang, Qian and Lou, Zhanzhi and Tang, Zhenheng and Chen, Nuo and Zhao, Xuandong and Zhang, Wenxuan and Song, Dawn and He, Bingsheng
-
WildFrame: Comparing Framing in Humans and LLMs on Naturally Occurring Texts
arXiv preprint[paper]Lior, Gili and Nacchace, Liron and Stanovsky, Gabriel
-
Framing the Game: How Context Shapes LLM Decision-Making
arXiv preprint[paper]Robinson, Isaac and Burden, John
-
Investigating bias in llm-based bias detection: Disparities between llms and human perception
COLING 2025[paper]Lin, Luyang and Wang, Lingzhi and Guo, Jinsong and Wong, Kam-Fai
-
More or Less Wrong: A Benchmark for Directional Bias in LLM Comparative Reasoning
arXiv preprint[paper]Shafiei, Mohammadamin and Saffari, Hamidreza and Moosavi, Nafise Sadat
-
Verbosity bias in preference labeling by large language models
arXiv preprint[paper]Saito, Keita and Wachi, Akifumi and Wataoka, Koki and Akimoto, Youhei
-
Talent or Luck? Evaluating Attribution Bias in Large Language Models
arXiv preprint[paper]Raj, Chahat and Banerjee, Mahika and Caliskan, Aylin and Anastasopoulos, Antonios and Zhu, Ziwei
-
Large language models as recommender systems: A study of popularity bias
arXiv preprint[paper]Lichtenberg, Jan Malte and Buchholz, Alexander and Schw{"o}bel, Pola
-
Beyond Utility: Evaluating LLM as Recommender
WWW 2025[paper]Jiang, Chumeng and Wang, Jiayin and Ma, Weizhi and Clarke, Charles LA and Wang, Shuai and Wu, Chuhan and Zhang, Min
-
Where to show Demos in Your Prompt: A Positional Bias of In-Context Learning
arXiv preprint[paper]Cobbina, Kwesi and Zhou, Tianyi
-
Large language models sensitivity to the order of options in multiple-choice questions
NAACL 2024[paper]Pezeshkpour, Pouya and Hruschka, Estevam
-
Mitigating order sensitivity in large language models for multiple-choice question tasks
IJAIRD 2024[paper]Jayaram, Vivekananda and Ramineni, Vishnu and Krishnappa, Manjunatha Sughaturu
-
The Order Effect: Investigating Prompt Sensitivity to Input Order in LLMs
KDD 2025 Workshop on Prompt Optimization[paper]Guan, Bryan and Roosta, Tanya and Passban, Peyman and Rezagholizadeh, Mehdi
-
Anchoring Bias in Large Language Models: An Experimental Study
arXiv preprint[paper]Lou, Jiaxu and Sun, Yifan
-
Believing Anthropomorphism: Examining the Role of Anthropomorphic Cues on Trust in Large Language Models
CHI 2024[paper]Cohn, Michelle and Pushkarna, Mahima and Olanubi, Gbolahan O and Moran, Joseph M and Padgett, Daniel and Mengesha, Zion and Heldreth, Courtney
-
Benchmarking cognitive biases in large language models as evaluators
ACL 2024[paper]Koo, Ryan and Lee, Minhwa and Raheja, Vipul and Park, Jong Inn and Kim, Zae Myung and Kang, Dongyeop
-
Large Language Models Can Be Easily Distracted by Irrelevant Context
ICML 2023[paper]Shi, Freda and Chen, Xinyun and Misra, Kanishka and Scales, Nathan and Dohan, David and Chi, Ed and Schärli, Nathanael and Zhou, Denny
-
Instructed to bias: instruction-tuned language models exhibit emergent cognitive bias
TACL 2024[paper]Itzhak, Itay and Stanovsky, Gabriel and Rosenfeld, Nir and Belinkov, Yonatan
-
Machine psychology: Investigating emergent capabilities and behavior in large language models using psychological methods
arXiv preprint[paper]Thilo Hagendorff and Ishita Dasgupta and Marcel Binz and Stephanie C. Y. Chan and Andrew Lampinen and Jane X. Wang and Zeynep Akata and Eric Schulz
-
Cognitive LLMs: Toward Human-Like Artificial Intelligence by Integrating Cognitive Architectures and Large Language Models for Manufacturing Decision-making
Neurosymbolic Artificial Intelligence 2024[paper]Wu, Siyu and Oltramari, Alessandro and Francis, Jonathan and Giles, C Lee and Ritter, Frank E
-
Argumentative Experience: Reducing Confirmation Bias on Controversial Issues through LLM-Generated Multi-Persona Debates
arXiv preprint[paper]Shi, Li and Liu, Houjiang and Wong, Yian and Mujumdar, Utkarsh and Zhang, Dan and Gwizdka, Jacek and Lease, Matthew
Implicit Social Reasoning
-
Theory of mind in large language models: Examining performance of 11 state-of-the-art models vs. children aged 7-10 on advanced tests
CoNLL 2023[paper]van Duijn, Max J and van Dijk, Bram and Kouwenhoven, Tom and de Valk, Werner and Spruit, Marco R and van der Putten, Peter
-
FANToM: A benchmark for stress-testing machine theory of mind in interactions
EMNLP 2023[paper]Kim, Hyunwoo and Sclar, Melanie and Zhou, Xuhui and Bras, Ronan Le and Kim, Gunhee and Choi, Yejin and Sap, Maarten
-
Neural theory-of-mind? on the limits of social intelligence in large lms
EMNLP 2022[paper]Sap, Maarten and LeBras, Ronan and Fried, Daniel and Choi, Yejin
-
Dissecting the Ullman Variations with a SCALPEL: Why do LLMs fail at Trivial Alterations to the False Belief Task?
arXiv preprint[paper]Pi, Zhiqiang and Vadaparty, Annapurna and Bergen, Benjamin K and Jones, Cameron R
-
Large language models fail on trivial alterations to theory-of-mind tasks
arXiv preprint[paper]Ullman, Tomer
-
Evaluating large language models in theory of mind tasks
PNAS 2024[paper]Kosinski, Michal
-
Clever hans or neural theory of mind? stress testing social reasoning in large language models
EACL 2024[paper]Shapira, Natalie and Levy, Mosh and Alavi, Seyed Hossein and Zhou, Xuhui and Choi, Yejin and Goldberg, Yoav and Sap, Maarten and Shwartz, Vered
-
SimpleToM: Exposing the Gap between Explicit ToM Inference and Implicit ToM Application in LLMs
arXiv preprint[paper]Gu, Yuling and Tafjord, Oyvind and Kim, Hyunwoo and Moore, Jared and Bras, Ronan Le and Clark, Peter and Choi, Yejin
-
Hi-tom: A benchmark for evaluating higher-order theory of mind reasoning in large language models
EMNLP 2023[paper]He, Yinghui and Wu, Yufan and Jia, Yilin and Mihalcea, Rada and Chen, Yulong and Deng, Naihao
-
How FaR Are Large Language Models From Agents with Theory-of-Mind?
arXiv preprint[paper]Zhou, Pei and Madaan, Aman and Potharaju, Srividya Pranavi and Gupta, Aditya and McKee, Kevin R and Holtzman, Ari and Pujara, Jay and Ren, Xiang and Mishra, Swaroop and Nematzadeh, Aida and others
-
Testing theory of mind in large language models and humans
Nature Human Behaviour 2024[paper]Strachan, James WA and Albergo, Dalila and Borghini, Giulia and Pansardi, Oriana and Scaliti, Eugenio and Gupta, Saurabh and Saxena, Krati and Rufo, Alessandro and Panzeri, Stefano and Manzi, Guido and others
-
Minding Language Models’ (Lack of) Theory of Mind: A Plug-and-Play Multi-Character Belief Tracker
ACL 2023[paper]Sclar, Melanie and Kumar, Sachin and West, Peter and Suhr, Alane and Choi, Yejin and Tsvetkov, Yulia
-
Artificial Intelligence and the Illusion of Understanding: A Systematic Review of Theory of Mind and Large Language Models
Cyberpsychology, Behavior, and Social Networking 2025[paper]Marchetti, Antonella and Manzi, Federico and Riva, Giuseppe and Gaggioli, Andrea and Massaro, Davide
-
Towards Dynamic Theory of Mind: Evaluating LLM Adaptation to Temporal Evolution of Human States
ACL 2025[paper]Xiao, Yang and Wang, Jiashuo and Xu, Qiancheng and Song, Changhe and Xu, Chunpu and Cheng, Yi and Li, Wenjie and Liu, Pengfei
-
EmoBench: Evaluating the Emotional Intelligence of Large Language Models
ACL 2024[paper]Sabour, Sahand and Liu, Siyang and Zhang, Zheyuan and Liu, June M and Zhou, Jinfeng and Sunaryo, Alvionna S and Li, Juanzi and Lee, Tatia and Mihalcea, Rada and Huang, Minlie
-
EmoBench-M: Benchmarking Emotional Intelligence for Multimodal Large Language Models
arXiv preprint[paper]Hu, He and Zhou, Yucheng and You, Lianzhong and Xu, Hongbo and Wang, Qianning and Lian, Zheng and Yu, Fei Richard and Ma, Fei and Cui, Laizhong
-
Can LLMs Reason Like Humans? Assessing Theory of Mind Reasoning in LLMs for Open-Ended Questions
CIKM 2024[paper]Amirizaniani, Maryam and Martin, Elias and Sivachenko, Maryna and Mashhadi, Afra and Shah, Chirag
-
The Emotional Intelligence of the GPT-4 Large Language Model
Psychol Russ 2024[paper]Vzorinab, Gleb D and Bukinichac, Alexey M and Sedykha, Anna V and Vetrovab, Irina I and Sergienkob, Elena A
-
Multilingual Language Models are not Multicultural: A Case Study in Emotion
ACL 2023[paper]Havaldar, Shreya and Rai, Sunny and Singhal, Bhumika and Liu, Langchen and Guntuku, Sharath Chandra and Ungar, Lyle
-
MoralBench: Moral Evaluation of LLMs
arXiv preprint[paper]Ji, Jianchao and Chen, Yutong and Jin, Mingyu and Xu, Wujiang and Hua, Wenyue and Zhang, Yongfeng
-
As an AI Language Model," Yes I Would Recommend Calling the Police": Norm Inconsistency in LLM Decision-Making
AIES 2024[paper]Jain, Shomik and Calacci, D and Wilson, Ashia
-
Measuring Moral Inconsistencies in Large Language Models
arXiv preprint[paper]Bonagiri, Vamshi Krishna and Vennam, Sreeram and Gaur, Manas and Kumaraguru, Ponnurangam
-
Probing the moral development of large language models through defining issues test
arXiv preprint[paper]Tanmay, Kumar and Khandelwal, Aditi and Agarwal, Utkarsh and Choudhury, Monojit
-
Correcting negative bias in large language models through negative attention score alignment
arXiv preprint[paper]Yu, Sangwon and Song, Jongyoon and Hwang, Bongkyu and Kang, Hoyoung and Cho, Sooah and Choi, Junhwa and Joe, Seongho and Lee, Taehee and Gwon, Youngjune L and Yoon, Sungroh
-
Ethical reasoning and moral value alignment of LLMs depend on the language we prompt them in
ACL 2024[paper]Agarwal, Utkarsh and Tanmay, Kumar and Khandelwal, Aditi and Choudhury, Monojit
-
GreedLlama: Performance of financial value-aligned large language models in moral reasoning
arXiv preprint[paper]Yu, Jeffy and Huber, Maximilian and Tang, Kevin
-
EgoNormia: Benchmarking Physical Social Norm Understanding
arXiv preprint[paper]Rezaei, MohammadHossein and Fu, Yicheng and Cuvin, Phil and Ziems, Caleb and Zhang, Yanzhe and Zhu, Hao and Yang, Diyi
-
The Moral Turing Test: Evaluating Human-LLM Alignment in Moral Decision-Making
arXiv preprint[paper]Garcia, Basile and Qian, Crystal and Palminteri, Stefano
-
The moral machine experiment on large language models
Royal Society[paper]Takemoto, Kazuhiro
-
Investigating machine moral judgement through the Delphi experiment
Nature Machine Intelligence 2025[paper]Jiang, Liwei and Hwang, Jena D and Bhagavatula, Chandra and Bras, Ronan Le and Liang, Jenny T and Levine, Sydney and Dodge, Jesse and Sakaguchi, Keisuke and Forbes, Maxwell and Hessel, Jack and others
Explicit Social Reasoning
-
Theory of mind for multi-agent collaboration via large language models
EMNLP 2023[paper]Li, Huao and Chong, Yu Quan and Stepputtis, Simon and Campbell, Joseph and Hughes, Dana and Lewis, Michael and Sycara, Katia
-
Socialeval: Evaluating social intelligence of large language models
ACL 2025[paper]Zhou, Jinfeng and Chen, Yuxuan and Shi, Yihan and Zhang, Xuanming and Lei, Leqi and Feng, Yi and Xiong, Zexuan and Yan, Miao and Wang, Xunzhi and Cao, Yaru and others
-
Hypothetical minds: Scaffolding theory of mind for multi-agent tasks with large language models
ICLR 2025[paper]Cross, Logan and Xiang, Violet and Bhatia, Agam and Yamins, Daniel LK and Haber, Nick
-
Large language model based multi-agents: A survey of progress and challenges
IJCAI 2024[paper]Guo, Taicheng and Chen, Xiuying and Wang, Yaqi and Chang, Ruidi and Pei, Shichao and Chawla, Nitesh V and Wiest, Olaf and Zhang, Xiangliang
-
LLM multi-agent systems: Challenges and open problems
arXiv preprint[paper]Han, Shanshan and Zhang, Qifan and Yao, Yuhang and Jin, Weizhao and Xu, Zhaozhuo and He, Chaoyang
-
Cooperate or collapse: Emergence of sustainable cooperation in a society of llm agents
NeurIPS 2024[paper]Piatti, Giorgio and Jin, Zhijing and Kleiman-Weiner, Max and Sch{"o}lkopf, Bernhard and Sachan, Mrinmaya and Mihalcea, Rada
-
Building cooperative embodied agents modularly with large language models
ICLR 2024[paper]Zhang, Hongxin and Du, Weihua and Shan, Jiaming and Zhou, Qinhong and Du, Yilun and Tenenbaum, Joshua B and Shu, Tianmin and Gan, Chuang
-
LLM-Coordination: Evaluating and Analyzing Multi-agent Coordination Abilities in Large Language Models
arXiv preprint[paper]Saaket Agashe and Yue Fan and Anthony Reyna and Xin Eric Wang
-
Why Do Multiagent Systems Fail?
ICLR 2025 Workshop[paper]Pan, Melissa Z and Cemri, Mert and Agrawal, Lakshya A and Yang, Shuyi and Chopra, Bhavya and Tiwari, Rishabh and Keutzer, Kurt and Parameswaran, Aditya and Ramchandran, Kannan and Klein, Dan and others
-
On the resilience of multi-agent systems with malicious agents
CoRR 2024[paper]Huang, Jen-tse and Zhou, Jiaxu and Jin, Tailin and Zhou, Xuhui and Chen, Zixi and Wang, Wenxuan and Yuan, Youliang and Sap, Maarten and Lyu, Michael R
-
Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation
arXiv preprint[paper]Baker, Bowen and Huizinga, Joost and Gao, Leo and Dou, Zehao and Guan, Melody Y and Madry, Aleksander and Zaremba, Wojciech and Pachocki, Jakub and Farhi, David
-
Magic: Investigation of large language model powered multi-agent in cognition, adaptability, rationality and collaboration
EMNLP 2024[paper]Xu, Lin and Hu, Zhiyuan and Zhou, Daquan and Ren, Hongyu and Dong, Zhen and Keutzer, Kurt and Ng, See Kiong and Feng, Jiashi
Formal Reasoning -- Logic and Arithmetic
Logic in Natural Languages
-
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
ICLR 2024[paper]Berglund, Lukas and Tong, Meg and Kaufmann, Max and Balesni, Mikita and Stickland, Asa Cooper and Korbak, Tomasz and Evans, Owain
-
Exploring the Reversal Curse and Other Deductive Logical Reasoning in BERT and GPT-Based Large Language Models
Patterns 2024[paper]Wu, Da and Yang, Jingye and Wang, Kai
-
Reverse Training to Nurse the Reversal Curse
COLM 2024[paper]Golovneva, Olga and Allen-Zhu, Zeyuan and Weston, Jason and Sukhbaatar, Sainbayar
-
The Queen of England is not England's Queen: On the Lack of Factual Coherency in PLMs
EACL 2024[paper]Youssef, Paul and Schlötterer, Jörg and Seifert, Christin
-
Exploring Reversal Mathematical Reasoning Ability for Large Language Models
ACL 2024[paper]Guo, Pei and You, WangJie and Li, Juntao and Bowen, Yan and Zhang, Min
-
Mitigating Reversal Curse in Large Language Models via Semantic-aware Permutation Training
ACL 2024[paper]Guo, Qingyan and Wang, Rui and Guo, Junliang and Tan, Xu and Bian, Jiang and Yang, Yujiu
-
An Analysis and Mitigation of the Reversal Curse
EMNLP 2024[paper]Lv, Ang and Zhang, Kaiyi and Xie, Shufang and Tu, Quan and Chen, Yuhan and Wen, Ji-Rong and Yan, Rui
-
Untying the Reversal Curse via Bidirectional Language Model Editing
arXiv preprint[paper]Ma, Jun-Yu and Gu, Jia-Chen and Ling, Zhen-Hua and Liu, Quan and Liu, Cong
-
Rethinking the Reversal Curse of LLMs: a Prescription from Human Knowledge Reversal
EMNLP 2024[paper]Lu, Zhicong and Jin, Li and Li, Peiguang and Tian, Yu and Zhang, Linhao and Wang, Sirui and Xu, Guangluan and Tian, Changyuan and Cai, Xunliang
-
Delving into the Reversal Curse: How Far Can Large Language Models Generalize?
NeurIPS 2024[paper]Lin, Zhengkai and Fu, Zhihang and Liu, Kai and Xie, Liang and Lin, Binbin and Wang, Wenxiao and Cai, Deng and Wu, Yue and Ye, Jieping
-
Towards a Theoretical Understanding of the 'Reversal Curse' via Training Dynamics
NeurIPS 2024[paper]Zhu, Hanlin and Huang, Baihe and Zhang, Shaolun and Jordan, Michael and Jiao, Jiantao and Tian, Yuandong and Russell, Stuart
-
The Two-Hop Curse: LLMs trained on A->B, B->C fail to learn A-->C
arXiv preprint[paper]Balesni, Mikita and Korbak, Tomek and Evans, Owain
-
How Do LLMs Perform Two-Hop Reasoning in Context?
arXiv preprint[paper]Guo, Tianyu and Zhu, Hanlin and Zhang, Ruiqi and Jiao, Jiantao and Mei, Song and Jordan, Michael I. and Russell, Stuart
-
Exploring the Limitations of Large Language Models in Compositional Relation Reasoning
COLM 2024[paper]Zhao, Jinman and Zhang, Xueyan
-
Faith and Fate: Limits of Transformers on Compositionality
NeurIPS 2023[paper]Dziri, Nouha and Lu, Ximing and Sclar, Melanie and Li, Xiang Lorraine and Jiang, Liwei and Lin, Bill Yuchen and West, Peter and Bhagavatula, Chandra and Bras, Ronan Le and Hwang, Jena D. and Sanyal, Soumya and Welleck, Sean and Ren, Xiang and Ettinger, Allyson and Harchaoui, Zaid and Choi, Yejin
-
Exploring the Compositional Deficiency of Large Language Models in Mathematical Reasoning
EMNLP 2024[paper]Zhao, Jun and Tong, Jingqi and Mou, Yurong and Zhang, Ming and Zhang, Qi and Huang, Xuanjing
-
BoolQ: Exploring the Surprising Difficulty of Natural Yes/No Questions
NAACL 2019[paper]Clark, Christopher and Lee, Kenton and Chang, Ming-Wei and Kwiatkowski, Tom and Collins, Michael and Toutanova, Kristina
-
LogicAsker: Evaluating and Improving the Logical Reasoning Ability of Large Language Models
EMNLP 2024[paper]Wan, Yuxuan and Wang, Wenxuan and Yang, Yiliu and Yuan, Youliang and Huang, Jen-tse and He, Pinjia and Jiao, Wenxiang and Lyu, Michael R.
-
Evaluating Large Language Models with NeuBAROCO: Syllogistic Reasoning Ability and Human-like Biases
NALOMA IV[paper]Ando, Risako and Morishita, Takanobu and Abe, Hirohiko and Mineshima, Koji and Okada, Mitsuhiro
-
An Investigation of LLMs' Inefficacy in Understanding Converse Relations
EMNLP 2023[paper]Qi, Chengwen and Li, Bowen and Hui, Binyuan and Wang, Bailin and Li, Jinyang and Wu, Jinwang and Laili, Yuanjun
-
Assessing the Reasoning Abilities of ChatGPT in the Context of Claim Verification
arXiv preprint[paper]Dougrez-Lewis, John and Akhter, Mahmud Elahi and He, Yulan and Liakata, Maria
-
LLMs Are Prone to Fallacies in Causal Inference
EMNLP 2024[paper]Joshi, Nitish and Saparov, Abulhair and Wang, Yixin and He, He
-
Rulebreakers Challenge: Revealing a Blind Spot in Large Language Models' Reasoning with Formal Logic
arXiv preprint[paper]Chan, Jason and Gaizauskas, Robert and Zhao, Zhixue
-
Large Language Models Fall Short: Understanding Complex Relationships in Detective Narratives
ACL 2024[paper]Zhao, Runcong and Zhu, Qinglin and Xu, Hainiu and Li, Jiazheng and Zhou, Yuxiang and He, Yulan and Gui, Lin
-
Not All LLM Reasoners Are Created Equal
arXiv preprint[paper]Hosseini, Arian and Sordoni, Alessandro and Toyama, Daniel and Courville, Aaron and Agarwal, Rishabh
-
Do Large Language Models Have Compositional Ability? An Investigation into Limitations and Scalability
COLM 2024[paper]Xu, Zhuoyan and Shi, Zhenmei and Liang, Yingyu
-
Understanding and Patching Compositional Reasoning in LLMs
ACL 2024[paper]Li, Zhaoyi and Jiang, Gangwei and Xie, Hong and Song, Linqi and Lian, Defu and Wei, Ying
-
Do Large Language Models Perform Latent Multi-Hop Reasoning without Exploiting Shortcuts?
ACL 2024[paper]Yang, Sohee and Kassner, Nora and Gribovskaya, Elena and Riedel, Sebastian and Geva, Mor
-
Enhancing Logical Reasoning in Large Language Models through Graph-based Synthetic Data
arXiv preprint[paper]Zhou, Jiaming and Ghaddar, Abbas and Zhang, Ge and Ma, Liheng and Hu, Yaochen and Pal, Soumyasundar and Coates, Mark and Wang, Bin and Zhang, Yingxue and Hao, Jianye
-
LogicGame: Benchmarking Rule-Based Reasoning Abilities of Large Language Models
ACL 2024[paper]Gui, Jiayi and Liu, Yiming and Cheng, Jiale and Gu, Xiaotao and Liu, Xiao and Wang, Hongning and Dong, Yuxiao and Tang, Jie and Huang, Minlie
-
Can LLMs Reason with Rules? Logic Scaffolding for Stress-Testing and Improving LLMs
ACL 2024[paper]Wang, Siyuan and Wei, Zhongyu and Choi, Yejin and Ren, Xiang
-
See What LLMs Cannot Answer: A Self-Challenge Framework for Uncovering LLM Weaknesses
COLM 2024[paper]Chen, Yulong and Liu, Yang and Yan, Jianhao and Bai, Xuefeng and Zhong, Ming and Yang, Yinghao and Yang, Ziyi and Zhu, Chenguang and Zhang, Yue
Logic in Benchmarks
-
Large Language Models Are Not Robust Multiple Choice Selectors
ICLR 2024[paper]Zheng, Chujie and Zhou, Hao and Meng, Fandong and Zhou, Jie and Huang, Minlie
-
Large language models sensitivity to the order of options in multiple-choice questions
NAACL 2024[paper]Pezeshkpour, Pouya and Hruschka, Estevam
-
When benchmarks are targets: Revealing the sensitivity of large language model leaderboards
ACL 2024[paper]Alzahrani, Norah and Alyahya, Hisham Abdullah and Alnumay, Yazeed and Alrashed, Sultan and Alsubaie, Shaykhah and Almushaykeh, Yusef and Mirza, Faisal and Alotaibi, Nouf and Altwairesh, Nora and Alowisheq, Areeb and Bari, M Saiful and Khan, Haidar
-
In-Context Learning May Not Elicit Trustworthy Reasoning: A-Not-B Errors in Pretrained Language Models"
EMNLP 2024[paper]Han, Pengrui and Song, Peiyang and Yu, Haofei and You, Jiaxuan
-
Changing Answer Order Can Decrease MMLU Accuracy
arXiv preprint[paper]Gupta, Vipul and Pantoja, David and Ross, Candace and Williams, Adina and Ung, Megan
-
Premise Order Matters in Reasoning with Large Language Models
ICML 2024[paper]Chen, Xinyun and Chi, Ryan A. and Wang, Xuezhi and Zhou, Denny
-
Failure Modes of LLMs for Causal Reasoning on Narratives
arXiv preprint[paper]Yamin, Khurram and Gupta, Shantanu and Gaurav R. Ghosal, Gaurav R. and Lipton, Zachary C. and Wilder, Bryan
-
A Peek into Token Bias: Large Language Models Are Not Yet Genuine Reasoners
EMNLP 2024[paper]Jiang, Bowen and Xie, Yangxinyu and Hao, Zhuoqun and Wang, Xiaomeng and Mallick, Tanwi and Su, Weijie J. and Taylor, Camillo J. and Roth, Dan
-
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
arXiv preprint[paper]Mirzadeh, Iman and Alizadeh, Keivan and Shahrokhim, Hooman and Tuzel, Oncel and Bengio, Samy and Farajtabar, Mehrdad
-
Reasoning or Reciting? Exploring the Capabilities and Limitations of Language Models Through Counterfactual Tasks
NAACL 2024[paper]Wu, Zhaofeng and Qiu, Linlu and Ross, Alexis and Akyürek, Ekin and Chen, Boyuan and Wang, Bailin and Kim, Najoung and Andreas, Jacob and Kim, Yoon
-
GSM-Plus: A Comprehensive Benchmark for Evaluating the Robustness of LLMs as Mathematical Problem Solvers
ACL 2024[paper]Li, Qintong and Cui, Leyang and Zhao, Xueliang and Kong, Lingpeng and Bi, Wei
-
Are NLP Models really able to Solve Simple Math Word Problems?
NAACL 2021[paper]Patel, Arkil and Bhattamishra, Satwik and Goyal, Navin
-
Large Language Models Can Be Easily Distracted by Irrelevant Context
ICML 2023[paper]Shi, Freda and Chen, Xinyun and Misra, Kanishka and Scales, Nathan and Dohan, David and Chi, Ed and Schärli, Nathanael and Zhou, Denny
-
ReCode: Robustness Evaluation of Code Generation Models
ACL 2023[[paper]Wang, Shiqi and Li, Zheng and Qian, Haifeng and Yang, Chenghao and Wang, Zijian and Shang, Mingyue and Kumar, Varun and Tan, Samson and Ray, Baishakhi and Bhatia, Parminder and Nallapati, Ramesh and Ramanathan, Murali Krishna and Roth, Dan and Xiang, Bing
-
Do Large Code Models Understand Programming Concepts? A Black-box Approach
ICML 2024[paper]Hooda, Ashish and Christodorescu, Mihai and Allamanis, Miltiadis and Wilson, Aaron and Fawaz, Kassem and Jha, Somesh
-
Top Leaderboard Ranking = Top Coding Proficiency, Always? EvoEval: Evolving Coding Benchmarks via LLM
COLM 2024[paper]Xia, Chunqiu Steven and Deng, Yinlin and Zhang, Lingming
-
Large Language Models of Code Fail at Completing Code with Potential Bugs
NeurIPS 2023[paper]Dinh, Tuan and Zhao, Jinman and Tan, Samson and Negrinho, Renato and Lausen, Leonard and Zha, Sheng and Karypis, George
-
The Larger They Are, the Harder They Fail: Language Models do not Recognize Identifier Swaps in Python
ACL 2023[paper]Miceli-Barone, Antonio Valerio and Barez, Fazl and Konstas, Ioannis and Cohen, Shay B.
-
Syntactic Robustness for LLM-based Code Generation
arXiv preprint[paper]Sarker, Laboni and Downing, Mara and Desai, Achintya and Bultan, Tevfik
-
RUPBench: Benchmarking Reasoning Under Perturbations for Robustness Evaluation in Large Language Models
arXiv preprint[paper]Wang, Yuqing and Zhao, Yun
-
Evaluating LLMs' Mathematical and Coding Competency through Ontology-guided Interventions
arXiv preprint[paper]Hong, Pengfei and Majumder, Navonil and Ghosal, Deepanway and Aditya, Somak and Mihalcea, Rada and Poria, Soujanya
-
Fill in the Blank: Exploring and Enhancing LLM Capabilities for Backward Reasoning in Math Word Problems
arXiv preprint[paper]Deb, Aniruddha and Oza, Neeva and Singla, Sarthak and Khandelwal, Dinesh and Garg, Dinesh and Singla, Parag
-
MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations
arXiv preprint[paper]Huang, Kaixuan and Guo, Jiacheng and Li, Zihao and Ji, Xiang and Ge, Jiawei and Li, Wenzhe and Guo, Yingqing and Cai, Tianle and Yuan, Hui and Wang, Runzhe and Wu, Yue and Yin, Ming and Tang, Shange and Huang, Yangsibo and Jin, Chi and Chen, Xinyun and Zhang, Chiyuan and Wang, Mengdi
-
Reasoning LLMs are Wandering Solution Explorers
arXiv preprint[paper]Lu, Jiahao and Xu, Ziwei and Kankanhalli, Mohan
-
The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity
arXiv preprint[paper]Shojaee, Parshin and Mirzadeh, Iman and Alizadeh, Keivan and Horton, Maxwell and Bengio, Samy and Farajtabar, Mehrdad
-
Comment on The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity
arXiv preprint[paper]Lawsen, Alex
-
OMEGA: Can LLMs Reason Outside the Box in Math? Evaluating Exploratory, Compositional, and Transformative Generalization
arXiv preprint[paper]Sun, Yiyou and Hu, Shawn and Zhou, Georgia and Zheng, Ken and Hajishirzi, Hannaneh and Dziri, Nouha and Song, Dawn
-
FormulaOne: Measuring the Depth of Algorithmic Reasoning Beyond Competitive Programming
arXiv preprint[paper]Beniamini, Gal and Dor, Yuval and Vinnikov, Alon and Peled, Shir Granot and Weinstein, Or and Sharir, Or and Wies, Noam and Nussbaum, Tomer and Shaul, Ido Ben and Zekharya, Tomer and Levine, Yoav and Shalev-Shwartz, Shai and Shashua, Amnon
Arithmetic and Mathematics
-
Why Do Large Language Models (LLMs) Struggle to Count Letters?
arXiv preprint[paper]Fu, Tairan and Ferrando, Raquel and Conde, Javier and Arriaga, Carlos and Reviriego, Pedro
-
Frontier LLMs Still Struggle with Simple Reasoning Tasks
arXiv preprint[paper]Malek, Alan and Ge, Jiawei and Lazic, Nevena and Jin, Chi and György, András and Szepesvári, Csaba
-
Counting Ability of Large Language Models and Impact of Tokenization
arXiv preprint[paper]Zhang, Xiang and Cao, Juntai and You, Chenyu
-
Language Models Need Inductive Biases to Count Inductively
ICLR 2025[paper]Chang, Yingshan and Bisk, Yonatan
-
LLM The Genius Paradox: A Linguistic and Math Expert's Struggle with Simple Word-based Counting Problems
arXiv preprint[paper]Xu, Nan and Ma, Xuezhe
-
When Can Transformers Count to n?
arXiv preprint[paper]Yehudai, Gilad and Kaplan, Haim and Ghandeharioun, Asma and Geva, Mor and Globerson, Amir
-
Large Language Models Lack Understanding of Character Composition of Words
arXiv preprint[paper]Shin, Andrew and Kaneko, Kunitake
-
Large Language Models Can Not Perform Well in Understanding and Manipulating Natural Language at Both Character and Word Levels?
EMNLP 2024[paper]Zhang, Yidan and He, Zhenan
-
Can Neural Networks Do Arithmetic? A Survey on the Elementary Numerical Skills of State-of-the-Art Deep Learning Models
Applied Sciences Vol. 14[paper]Testolin, Alberto
-
Large Language Models Are Unconscious of Unreasonability in Math Problems
arXiv preprint[paper]Ma, Jingyuan and Dai, Damai and Sha, Lei and Sui, Zhifang
-
Putnam-AXIOM: A Functional and Static Benchmark for Measuring Higher Level Mathematical Reasoning
arXiv preprint[paper]Gulati, Aryan and Miranda, Brando and Chen, Eric and Xia, Emily and Fronsdal, Kai and Dumont, Bruno de Moraes and Koyejo, Sanmi
-
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
arXiv preprint[paper]Mirzadeh, Iman and Alizadeh, Keivan and Shahrokhim, Hooman and Tuzel, Oncel and Bengio, Samy and Farajtabar, Mehrdad
-
GSM-Plus: A Comprehensive Benchmark for Evaluating the Robustness of LLMs as Mathematical Problem Solvers
ACL 2024[paper]Li, Qintong and Cui, Leyang and Zhao, Xueliang and Kong, Lingpeng and Bi, Wei
-
Large Language Models Can Be Easily Distracted by Irrelevant Context
ICML 2023[paper]Shi, Freda and Chen, Xinyun and Misra, Kanishka and Scales, Nathan and Dohan, David and Chi, Ed and Schärli, Nathanael and Zhou, Denny
-
VarBench: Robust Language Model Benchmarking Through Dynamic Variable Perturbation
EMNLP 2024[paper]Qian, Kun and Wan, Shunji and Tang, Claudia and Wang, Youzhi and Zhang, Xuanming and Chen, Maximillian and Yu, Zhou
-
Alice in Wonderland: Simple Tasks Showing Complete Reasoning Breakdown in State-Of-the-Art Large Language Models
arXiv preprint[paper]Nezhurina, Marianna and Cipolina-Kun, Lucia and Cherti, Mehdi and Jitsev, Jenia
-
Rationales for Answers to Simple Math Word Problems Confuse Large Language Models
ACL 2024[paper]Zhang, Yidan and Xue, Mingfeng and Liu, Dayiheng and He, Zhenan
-
Living in the Moment: Can Large Language Models Grasp Co-Temporal Reasoning?
ACL 2024[paper]Su, Zhaochen and Li, Juntao and Zhang, Jun and Zhu, Tong and Qu, Xiaoye and Zhou, Pan and Bowen, Yan and Cheng, Yu and zhang, Min
-
Randomly Sampled Language Reasoning Problems Reveal Limits of LLMs
arXiv preprint[paper]Gupta, Kavi and Sanders, Kate and Solar-Lezama, Armando
-
From Blind Solvers to Logical Thinkers: Benchmarking LLMs' Logical Integrity on Faulty Mathematical Problems
arXiv preprint[paper]Rahman, A M Muntasir and Ye, Junyi and Yao, Wei and Yin, Wenpeng and Wang, Guiling
-
How well do Large Language Models perform in Arithmetic tasks?
arXiv preprint[paper]Yuan, Zheng and Yuan, Hongyi and Tan, Chuanqi and Wang, Wei and Huang, Songfang
-
How Numerical Precision Affects Mathematical Reasoning Capabilities of LLMs
arXiv preprint[paper]Feng, Guhao and Yang, Kai and Gu, Yuntian and Ai, Xinyue and Luo, Shengjie and Sun, Jiacheng and He, Di and Li, Zhenguo and Wang, Liwei
-
Language Models Do Hard Arithmetic Tasks Easily and Hardly Do Easy Arithmetic Tasks
ACL 2024[paper]Gambardella, Andrew and Iwasawa, Yusuke and Matsuo, Yutaka
-
Language Models are Symbolic Learners in Arithmetic
arXiv preprint[paper]Deng, Chunyuan and Li, Zhiqi and Xie, Roy and Chang, Ruidi and Chen, Hanjie
-
OccamLLM: Fast and Exact Language Model Arithmetic in a Single Step
NeurIPS 2024[paper]Dugan, Owen and Beneto, Donato Manuel Jimenez and Loh, Charlotte and Chen, Zhuo and Dangovski, Rumen and Soljačić, Marin
-
GPT Can Solve Mathematical Problems Without a Calculator
arXiv preprint[paper]Yang, Zhen and Ding, Ming and Lv, Qingsong and Jiang, Zhihuan and He, Zehai and Guo, Yuyi and Bai, Jinfeng and Tang, Jie
-
Fill in the Blank: Exploring and Enhancing LLM Capabilities for Backward Reasoning in Math Word Problems
arXiv preprint[paper]Deb, Aniruddha and Oza, Neeva and Singla, Sarthak and Khandelwal, Dinesh and Garg, Dinesh and Singla, Parag
-
Robustness Assessment of Mathematical Reasoning in the Presence of Missing and Contradictory Conditions
arXiv preprint[paper]Tian, Shi-Yu and Zhou, Zhi and Jia, Lin-Han and Guo, Lan-Zhe and Li, Yu-Feng
-
Reverse That Number! Decoding Order Matters in Arithmetic Learning
arXiv preprint[paper]Zhang-Li, Daniel and Lin, Nianyi and Yu, Jifan and Zhang, Zheyuan and Yao, Zijun and Zhang, Xiaokang and Hou, Lei and Zhang, Jing and Li, Juanzi
-
RevOrder: A Novel Method for Enhanced Arithmetic in Language Models
arXiv preprint[paper]Shen, Si and Shen, Peijun and Zhu, Danhao
-
Arithmetic Without Algorithms: Language Models Solve Math With a Bag of Heuristics
ICLR 2025[paper]Nikankin, Yaniv and Reusch, Anja and Mueller, Aaron and Belinkov, Yonatan
-
CMATH: Can Your Language Model Pass Chinese Elementary School Math Test?
arXiv preprint[paper]Wei, Tianwen and Luan, Jian and Liu, Wei and Dong, Shuang and Wang, Bin
-
Large Language Models and Mathematical Reasoning Failures
arXiv preprint[paper]Boye, Johan and Moell, Birger
-
HARDMath: A Benchmark Dataset for Challenging Problems in Applied Mathematics
arXiv preprint[paper]Fan, Jingxuan and Martinson, Sarah and Wang, Erik Y. and Hausknecht, Kaylie and Brenner, Jonah and Liu, Danxian and Peng, Nianli and Wang, Corey and Brenner, Michael P.
-
MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations
arXiv preprint[paper]Huang, Kaixuan and Guo, Jiacheng and Li, Zihao and Ji, Xiang and Ge, Jiawei and Li, Wenzhe and Guo, Yingqing and Cai, Tianle and Yuan, Hui and Wang, Runzhe and Wu, Yue and Yin, Ming and Tang, Shange and Huang, Yangsibo and Jin, Chi and Chen, Xinyun and Zhang, Chiyuan and Wang, Mengdi
-
Self-Improving Transformers Overcome Easy-to-Hard and Length Generalization Challenges
arXiv preprint[paper]Lee, Nayoung and Cai, Ziyang and Schwarzschild, Avi and Lee, Kangwook and Papailiopoulos, Dimitris
-
OMEGA: Can LLMs Reason Outside the Box in Math? Evaluating Exploratory, Compositional, and Transformative Generalization
arXiv preprint[paper]Sun, Yiyou and Hu, Shawn and Zhou, Georgia and Zheng, Ken and Hajishirzi, Hannaneh and Dziri, Nouha and Song, Dawn
-
Counting and algorithmic generalization with transformers
arXiv preprint[paper]Ouellette, Simon and Pfister, Rolf and Jud, Hansueli
Reasoning in Embodied Environments
1D - Text Based
-
Prost: Physical reasoning about objects through space and time
ACL 2021[paper]Aroca-Ouellette, Stéphane and Paik, Cory and Roncone, Alessandro and Kann, Katharina
-
TEXT2AFFORD: Probing Object Affordance Prediction abilities of Language Models solely from Text
CoNLL 2024[paper]Adak, Sayantan and Agrawal, Daivik and Mukherjee, Animesh and Aditya, Somak
-
A Multi-layered Approach to Physical Commonsense Understanding: Creation and Evaluation of an Italian Dataset
COLING 2024[paper]Pensa, Giulia and Altuna, Bego{~n}a and Gonzalez-Dios, Itziar
-
ChatGPT and the frustrated socrates
Physics Education 2023[paper]Gregorcic, Bor and Pendrill, Ann-Marie
-
Things not written in text: Exploring spatial commonsense from visual signals
ACL 2022[paper]Liu, Xiao and Yin, Da and Feng, Yansong and Zhao, Dongyan
-
POSQA: Probe the World Models of LLMs with Size Comparisons
EMNLP 2023[paper]Shu, Chang and Han, Jiuzhou and Liu, Fangyu and Shareghi, Ehsan and Collier, Nigel
-
Probing physical reasoning with Counter-Commonsense context
ACL 2023[paper]Kondo, Kazushi and Sugawara, Saku and Aizawa, Akiko
-
NEWTON: Are Large Language Models Capable of Physical Reasoning?
EMNLP 2023[paper]Yi Ru Wang and Jiafei Duan and Dieter Fox and Siddhartha Srinivasa
-
PhysReason: A Comprehensive Benchmark towards Physics-Based Reasoning
arXiv preprint[paper]Zhang, Xinyu and Dong, Yuxuan and Wu, Yanrui and Huang, Jiaxing and Jia, Chengyou and Fernando, Basura and Shou, Mike Zheng and Zhang, Lingling and Liu, Jun
-
UGPhysics: A Comprehensive Benchmark for Undergraduate Physics Reasoning with Large Language Models
arXiv preprint[paper]Xu, Xin and Xu, Qiyun and Xiao, Tong and Chen, Tianhao and Yan, Yuchen and Zhang, Jiaxin and Diao, Shizhe and Yang, Can and Wang, Yang
-
Testing LLM performance on the Physics GRE: some observations
arXiv preprint[paper]Gupta, Pranav
-
PHYBench: Holistic Evaluation of Physical Perception and Reasoning in Large Language Models
arXiv preprint[paper]Qiu, Shi and Guo, Shaoyang and Song, Zhuo-Yang and Sun, Yunbo and Cai, Zeyu and Wei, Jiashen and Luo, Tianyu and Yin, Yixuan and Zhang, Haoxu and Hu, Yi and Wang, Chenyang and Tang, Chencheng and Chang, Haoling and Liu, Qi and Zhou, Ziheng and Zhang, Tianyu and Zhang, Jingtian and Liu, Zhangyi and Li, Minghao and Zhang, Yuku and Jing, Boxuan and Yin, Xianqi and Ren, Yutong and Fu, Zizhuo and Ji, Jiaming and Wang, Weike and Tian, Xudong and Lv, Anqi and Man, Laifu and Li, Jianxiang and Tao, Feiyu and Sun, Qihua and Liang, Zhou and Mu, Yushu and Li, Zhongxuan and Zhang, Jing-Jun and Zhang, Shutao and Li, Xiaotian and Xia, Xingqi and Lin, Jiawei and Shen, Zheyu and Chen, Jiahang and Xiong, Qiuhao and Wang, Binran and Wang, Fengyuan and Ni, Ziyang and Zhang, Bohan and Cui, Fan and Shao, Changkun and Cao, Qing-Hong and Luo, Ming-xing and Yang, Yaodong and Zhang, Muhan and Zhu, Hua Xing
-
ABench-Physics: Benchmarking Physical Reasoning in LLMs via High-Difficulty and Dynamic Physics Problems
arXiv preprint[paper]Zhang, Yiming and Ma, Yingfan and Gu, Yanmei and Yang, Zhengkai and Zhuang, Yihong and Wang, Feng and Huang, Zenan and Wang, Yuanyuan and Huang, Chao and Song, Bowen and others
-
Theoretical Physics Benchmark (TPBench)--a Dataset and Study of AI Reasoning Capabilities in Theoretical Physics
arXiv preprint[paper]Chung, Daniel JH and Gao, Zhiqi and Kvasiuk, Yurii and Li, Tianyi and M{"u}nchmeyer, Moritz and Rudolph, Maja and Sala, Frederic and Tadepalli, Sai Chaitanya
-
Improving Physics Reasoning in Large Language Models Using Mixture of Refinement Agents
arXiv preprint[paper]Jaiswal, Raj and Jain, Dhruv and Popat, Harsh Parimal and Anand, Avinash and Dharmadhikari, Abhishek and Marathe, Atharva and Shah, Rajiv Ratn
-
Structured chemistry reasoning with large language models
ICML 2024[paper]Ouyang, Siru and Zhang, Zhuosheng and Yan, Bing and Liu, Xuan and Choi, Yejin and Han, Jiawei and Qin, Lianhui
-
Auto-Bench: An Automated Benchmark for Scientific Discovery in LLMs
arXiv preprint[paper]Chen, Tingting and Anumasa, Srinivas and Lin, Beibei and Shah, Vedant and Goyal, Anirudh and Liu, Dianbo
2D - Perception Based
-
Core knowledge deficits in multi-modal language models
ICML 2025[paper]Li, Yijiang and Gao, Qingying and Zhao, Tianwei and Wang, Bingyang and Sun, Haoran and Lyu, Haiyun and Hawkins, Robert D and Vasconcelos, Nuno and Golan, Tal and Luo, Dezhi and others
-
Breaking common sense: Whoops! a vision-and-language benchmark of synthetic and compositional images
ICCV 2023[paper]Bitton-Guetta, Nitzan and Bitton, Yonatan and Hessel, Jack and Schmidt, Ludwig and Elovici, Yuval and Stanovsky, Gabriel and Schwartz, Roy
-
Rome: Evaluating pre-trained vision-language models on reasoning beyond visual common sense
EMNLP 2023[paper]Zhou, Kankan and Lai, Eason and Yeong, Wei Bin Au and Mouratidis, Kyriakos and Jiang, Jing
-
Vision language models are blind
ACCV 2024[paper]Rahmanzadehgervi, Pooyan and Bolton, Logan and Taesiri, Mohammad Reza and Nguyen, Anh Totti
-
Visual spatial reasoning
TACL 2023[paper]Liu, Fangyu and Emerson, Guy and Collier, Nigel
-
Can Vision Language Models Learn from Visual Demonstrations of Ambiguous Spatial Reasoning?
NeurIPS 2024[paper]Zhao, Bowen and Dirac, Leo Parker and Varshavskaya, Paulina
-
Understanding the limits of vision language models through the lens of the binding problem
NeurIPS 2024[paper]Campbell, Declan and Rane, Sunayana and Giallanza, Tyler and De Sabbata, Camillo Nicol{`o} and Ghods, Kia and Joshi, Amogh and Ku, Alexander and Frankland, Steven and Griffiths, Tom and Cohen, Jonathan D and others
-
Words or Vision: Do Vision-Language Models Have Blind Faith in Text?
arXiv preprint[paper]Deng, Ailin and Cao, Tri and Chen, Zhirui and Hooi, Bryan
-
Large Language Models Are Challenged by Habitat-Centered Reasoning
EMNLP 2024[paper]Ghaffari, Sadaf and Krishnaswamy, Nikhil
-
Visual cognition in multimodal large language models
Nature Machine Intelligence 2025[paper]Schulze Buschoff, Luca M and Akata, Elif and Bethge, Matthias and Schulz, Eric
-
Learning the effects of physical actions in a multi-modal environment
EACL 2023[paper]Dagan, Gautier and Keller, Frank and Lascarides, Alex
-
Synthetic Vision: Training Vision-Language Models to Understand Physics
arXiv preprint[paper]Balazadeh, Vahid and Ataei, Mohammadmehdi and Cheong, Hyunmin and Khasahmadi, Amir Hosein and Krishnan, Rahul G
-
PhysBench: Benchmarking and Enhancing Vision-Language Models for Physical World Understanding
ICLR 2025[paper]Chow, Wei and Mao, Jiageng and Li, Boyi and Seita, Daniel and Guizilini, Vitor and Wang, Yue
-
Physion: Evaluating physical prediction from vision in humans and machines
NeurIPS 2021[paper]Bear, Daniel M and Wang, Elias and Mrowca, Damian and Binder, Felix J and Tung, Hsiao-Yu Fish and Pramod, RT and Holdaway, Cameron and Tao, Sirui and Smith, Kevin and Sun, Fan-Yun and others
-
Craft: A benchmark for causal reasoning about forces and interactions
ACL 2022[paper]Ates, Tayfun and Atesoglu, M Samil and Yigit, Cagatay and Kesen, Ilker and Kobas, Mert and Erdem, Erkut and Erdem, Aykut and Goksun, Tilbe and Yuret, Deniz
-
Mm-phyqa: Multimodal physics question-answering with multi-image cot prompting
PAKDD 2024[paper]Anand, Avinash and Kapuriya, Janak and Singh, Apoorv and Saraf, Jay and Lal, Naman and Verma, Astha and Gupta, Rushali and Shah, Rajiv
-
PhyX: Does Your Model Have the "Wits" for Physical Reasoning?
arXiv preprint[paper]Hui Shen and Taiqiang Wu and Qi Han and Yunta Hsieh and Jizhou Wang and Yuyue Zhang and Yuxin Cheng and Zijian Hao and Yuansheng Ni and Xin Wang and Zhongwei Wan and Kai Zhang and Wendong Xu and Jing Xiong and Ping Luo and Wenhu Chen and Chaofan Tao and Zhuoqing Mao and Ngai Wong
-
Llmphy: Complex physical reasoning using large language models and world models
arXiv preprint[paper]Cherian, Anoop and Corcodel, Radu and Jain, Siddarth and Romeres, Diego
-
Exploring Failure Cases in Multimodal Reasoning About Physical Dynamics
AAAI 2024[paper]Sadaf Ghaffari and Nikhil Krishnaswamy
-
On Inherent 3D Reasoning of VLMs in Indoor Scene Layout Design
preprint[paper]Kar, Amlan and Acuna, David and Fidler, Sanja
-
Can-Do! A Dataset and Neuro-Symbolic Grounded Framework for Embodied Planning with Large Multimodal Models
arXiv preprint[paper]Chia, Yew Ken and Sun, Qi and Bing, Lidong and Poria, Soujanya
-
Balrog: Benchmarking agentic llm and vlm reasoning on games
ICLR 2025[paper]Paglieri, Davide and Cupia{\l}, Bart{\l}omiej and Coward, Samuel and Piterbarg, Ulyana and Wolczyk, Maciej and Khan, Akbir and Pignatelli, Eduardo and Kuci{'n}ski, {\L}ukasz and Pinto, Lerrel and Fergus, Rob and others
-
DeepPHY: Benchmarking Agentic VLMs on Physical Reasoning
arXiv 2025[paper]Xu, Xinrun and Bu, Pi and Wang, Ye and Karlsson, B{"o}rje F and Wang, Ziming and Song, Tengtao and Zhu, Qi and Song, Jun and Ding, Zhiming and Zheng, Bo
-
Out-of-Distribution Generalization in the ARC-AGI Domain: Comparing Execution-Guided Neural Program Synthesis and Test-Time Fine-Tuning
arXiv 2025[paper]Ouellette, Simon
3D - Real-World
-
Do as i can, not as i say: Grounding language in robotic affordances
CoRL 2022[paper]Ahn, Michael and Brohan, Anthony and Brown, Noah and Chebotar, Yevgen and Cortes, Omar and David, Byron and Finn, Chelsea and Fu, Chuyuan and Gopalakrishnan, Keerthana and Hausman, Karol and others
-
Embodied agent interface: Benchmarking llms for embodied decision making
NeurIPS 2024[paper]Li, Manling and Zhao, Shiyu and Wang, Qineng and Wang, Kangrui and Zhou, Yu and Srivastava, Sanjana and Gokmen, Cem and Lee, Tony and Li, Erran Li and Zhang, Ruohan and others
-
Deploying and evaluating llms to program service mobile robots
IEEE 2024[paper]Hu, Zichao and Lucchetti, Francesca and Schlesinger, Claire and Saxena, Yash and Freeman, Anders and Modak, Sadanand and Guha, Arjun and Biswas, Joydeep
-
Language models as zero-shot planners: Extracting actionable knowledge for embodied agents
ICML 2022[paper]Huang, Wenlong and Abbeel, Pieter and Pathak, Deepak and Mordatch, Igor
-
Robotgpt: Robot manipulation learning from chatgpt
IEEE 2024[paper]Jin, Yixiang and Li, Dingzhe and Yong, A and Shi, Jun and Hao, Peng and Sun, Fuchun and Zhang, Jianwei and Fang, Bin
-
AlphaMaze: Enhancing Large Language Models' Spatial Intelligence via GRPO
arXiv preprint[paper]Dao, Alan and Vu, Dinh Bach
-
A little less conversation, a little more action, please: Investigating the physical common-sense of LLMs in a 3D embodied environment
arXiv preprint[paper]Mecattaf, Matteo G and Slater, Ben and Te{\v{s}}i{'c}, Marko and Prunty, Jonathan and Voudouris, Konstantinos and Cheke, Lucy G
-
Creative robot tool use with large language models
arXiv preprint[paper]Xu, Mengdi and Huang, Peide and Yu, Wenhao and Liu, Shiqi and Zhang, Xilun and Niu, Yaru and Zhang, Tingnan and Xia, Fei and Tan, Jie and Zhao, Ding
-
Spatialvlm: Endowing vision-language models with spatial reasoning capabilities
CVPR 2024[paper]Chen, Boyuan and Xu, Zhuo and Kirmani, Sean and Ichter, Brain and Sadigh, Dorsa and Guibas, Leonidas and Xia, Fei
-
Task-oriented robotic manipulation with vision language models
arXiv preprint[paper]Guran, Nurhan Bulus and Ren, Hanchi and Deng, Jingjing and Xie, Xianghua
-
Code as policies: Language model programs for embodied control
ICRA 2023[paper]Liang, Jacky and Huang, Wenlong and Xia, Fei and Xu, Peng and Hausman, Karol and Ichter, Brian and Florence, Pete and Zeng, Andy
-
Badrobot: Manipulating embodied LLMs in the physical world
ICLR 2025[paper]Zhang, Hangtao and Zhu, Chenyu and Wang, Xianlong and Zhou, Ziqi and Yin, Changgan and Li, Minghui and Xue, Lulu and Wang, Yichen and Hu, Shengshan and Liu, Aishan and others
-
EgoNormia: Benchmarking Physical Social Norm Understanding
arXiv preprint[paper]Rezaei, MohammadHossein and Fu, Yicheng and Cuvin, Phil and Ziems, Caleb and Zhang, Yanzhe and Zhu, Hao and Yang, Diyi
General/Case-by-Case Reasoning Failure Studies
-
Easy Problems That LLMs Get Wrong
arXiv preprint[paper]Williams, Sean and Huckle, James
-
When More Thinking Hurts: Overthinking in LLM Test-Time Compute Scaling
arXiv preprint[paper]Zhou, Shu and Ling, Rui and Chen, Junan and Wang, Xin and Fan, Tao and Wang, Hao
-
Reasoning with Transformer-based Models: Deep Learning, but Shallow Reasoning
AKBC 2022[paper]Helwe, Chadi and Clavel, Chloé and Suchanek, Fabian M.
-
A Categorical Archive of ChatGPT Failures
arXiv preprint[paper]Borji, Ali
-
A Taxonomy of Epistemic Failure Modes in Large Language Models
Preprint 2026[paper]Bosch, Rolando
Citation
If you find our work useful, please consider citing our paper:
@article{songllmreasoningfailures,
  title={Large Language Model Reasoning Failures},
  author={Song, Peiyang and Han, Pengrui and Goodman, Noah},
  journal={Transactions on Machine Learning Research}
}
Contributors


Similar repos


README
Awesome LLM Reasoning Failures
A curated list of papers on discovery, analysis, and mitigation of LLM reasoning failures.
This repository accompanies the paper "Large Language Model Reasoning Failures" (TMLR 2026 Survey Certification).
If you find this work useful, please consider citing:
@article{songllmreasoningfailures,
  title={Large Language Model Reasoning Failures},
  author={Song, Peiyang and Han, Pengrui and Goodman, Noah},
  journal={Transactions on Machine Learning Research}
}
🗂️ Table of Contents
Relevant Surveys & Benchmarks for Reasoning Failures
-
Large Language Model Reasoning Failures
TMLR 2026[paper]Song, Peiyang and Han, Pengrui and Goodman, Noah
-
[Related] Why Do Multi-Agent LLM Systems Fail?
NeurIPS 2025[paper]Cemri, Mert and Pan, Melissa Z. and Yang, Shuyi and Agrawal, Lakshya A. and Chopra, Bhavya and Tiwari, Rishabh and Keutzer, Kurt and Parameswaran, Aditya and Klein, Dan and Ramchandran, Kannan and Zaharia, Matei and Gonzalez, Joseph E. and Stoica, Ion
-
[Related] REFUTE: Apache-2.0 benchmark for scientific critique & epistemic calibration on recent (2025–2026) science summaries. Separates critique skill from calibrated truthfulness (falsification, limitations, overclaims, missing-evidence refusal, confidence calibration, planted-flaw detection). Leaderboard · Technical report · Integrators
Informal Reasoning - Intuitive Cognition and Social Behavior
Individual Cognitive Skills and Biases
-
Working memory capacity of ChatGPT: An empirical study
AAAI 2024[paper]Gong, Dongyu and Wan, Xingchen and Wang, Dingmin
-
Working memory identifies reasoning limits in language models
EMNLP 2024[paper]Zhang, Chunhui and Jian, Yiren and Ouyang, Zhongyu and Vosoughi, Soroush
-
Self-Attention Limits Working Memory Capacity of Transformer-Based Modelss
NeurIPS 2024 Workshop on Behavioral ML[paper]Dongyu Gong and Hantao Zhang
-
Unable to Forget: Proactive lnterference Reveals Working Memory Limits in LLMs Beyond Context Length
ICML 2025 LCFM Workshop[paper]Chupei Wang and Jiaqiu Vince Sun
-
LLMs Do Not Have Human-Like Working Memory
arXiv preprint[paper]Huang, Jen-tse and Sun, Kaiser and Wang, Wenxuan and Dredze, Mark
-
Working memory attack on LLMs
ICLR 2025 Workshop on BuildingTrust[paper]Upadhayay, Bibek and Behzadan, Vahid and Karbasi, Amin
-
In-Context Learning May Not Elicit Trustworthy Reasoning: A-Not-B Errors in Pretrained Language Models
EMNLP 2024[paper]Han, Pengrui and Song, Peiyang and Yu, Haofei and You, Jiaxuan
-
Deficient Executive Control in Transformer Attention
bioRxiv preprint[paper]Patel, Suketu and Wang, Hongbin and Fan, Jin
-
Cognitive flexibility of large language models
ICML 2024 Workshop on LLMs and Cognition[paper]Kennedy, Sean M and Nowak, Robert D
-
LLMs and the Abstraction and Reasoning Corpus: Successes, Failures, and the Importance of Object-based Representations
TMLR 2024[paper]Xu, Yudong and Li, Wenhao and Vaezipoor, Pashootan and Sanner, Scott and Khalil, Elias B
-
Large language models are not strong abstract reasoners
arXiv preprint[paper]Gendron, Ga{"e}l and Bao, Qiming and Witbrock, Michael and Dobbie, Gillian
-
Evidence of Cognitive Deficits and Developmental Advances in Generative AI: A Clock Drawing Test Analysis
arXiv preprint[paper]Galatzer-Levy, Isaac R and McGiffin, Jed and Munday, David and Liu, Xin and Karmon, Danny and Labzovsky, Ilia and Moroshko, Rivka and Zait, Amir and McDuff, Daniel
-
Lost in Time: Clock and Calendar Understanding Challenges in Multimodal LLMs
arXiv preprint[paper]Rohit Saxena and Aryo Pradipta Gema and Pasquale Minervini
-
Language models, like humans, show content effects on reasoning tasks
PNAS Nexus 2024[paper]Lampinen, Andrew K and Dasgupta, Ishita and Chan, Stephanie CY and Sheahan, Hannah R and Creswell, Antonia and Kumaran, Dharshan and McClelland, James L and Hill, Felix
-
Confirmation and Specificity Biases in Large Language Models: An Explorative Study
IEEE Intelligent Systems[paper]O’Leary, Daniel E
-
Unveiling Confirmation Bias in Chain-of-Thought Reasoning
ACL 2025[paper]Yue Wan and Xiaowei Jia and Xiang Lorraine Li
-
Conformity in Large Language Models
ACL 2025[paper]Zhu, Xiaochen and Zhang, Caiqi and Stafford, Tom and Collier, Nigel and Vlachos, Andreas
-
Argumentative Experience: Reducing Confirmation Bias on Controversial Issues through LLM-Generated Multi-Persona Debates
arXiv preprint[paper]Shi, Li and Liu, Houjiang and Wong, Yian and Mujumdar, Utkarsh and Zhang, Dan and Gwizdka, Jacek and Lease, Matthew
-
A Comprehensive Evaluation of Cognitive Biases in LLMs
arXiv preprint[paper]Malberg, Simon and Poletukhin, Roman and Schuster, Carolin M and Groh, Georg
-
Cognitive bias in high-stakes decision-making with llms
EMNLP 2024[paper]Echterhoff, Jessica and Liu, Yao and Alessa, Abeer and McAuley, Julian and He, Zexue
-
Correcting negative bias in large language models through negative attention score alignment
arXiv preprint[paper]Koo, Ryan and Lee, Minhwa and Raheja, Vipul and Park, Jong Inn and Kim, Zae Myung and Kang, Dongyeop
-
Capturing failures of large language models via human cognitive biases
NeurIPS 2022[paper]Jones, Erik and Steinhardt, Jacob
-
Do large language models show decision heuristics similar to humans? A case study using GPT-3.5.
Journal of Experimental Psychology: General 2024[paper]Suri, Gaurav and Slater, Lily R and Ziaee, Ali and Nguyen, Morgan
-
Human bias in AI models? Anchoring effects and mitigation strategies in large language models
Journal of Behavioral and Experimental Finance[paper]Nguyen, Jeremy K
-
An Anchoring Effect in Large Language Models
IEEE Intelligent Systems 2025[paper]O’Leary, Daniel E
-
An Empirical Study of the Anchoring Effect in LLMs: Existence, Mechanism, and Potential Mitigations
arXiv preprint[paper]Huang, Yiming and Bie, Biquan and Na, Zuqiu and Ruan, Weilin and Lei, Songxin and Yue, Yutao and He, Xinlei
-
Assessing Judging Bias in Large Reasoning Models: An Empirical Study
arXiv preprint[paper]Wang, Qian and Lou, Zhanzhi and Tang, Zhenheng and Chen, Nuo and Zhao, Xuandong and Zhang, Wenxuan and Song, Dawn and He, Bingsheng
-
WildFrame: Comparing Framing in Humans and LLMs on Naturally Occurring Texts
arXiv preprint[paper]Lior, Gili and Nacchace, Liron and Stanovsky, Gabriel
-
Framing the Game: How Context Shapes LLM Decision-Making
arXiv preprint[paper]Robinson, Isaac and Burden, John
-
Investigating bias in llm-based bias detection: Disparities between llms and human perception
COLING 2025[paper]Lin, Luyang and Wang, Lingzhi and Guo, Jinsong and Wong, Kam-Fai
-
More or Less Wrong: A Benchmark for Directional Bias in LLM Comparative Reasoning
arXiv preprint[paper]Shafiei, Mohammadamin and Saffari, Hamidreza and Moosavi, Nafise Sadat
-
Verbosity bias in preference labeling by large language models
arXiv preprint[paper]Saito, Keita and Wachi, Akifumi and Wataoka, Koki and Akimoto, Youhei
-
Talent or Luck? Evaluating Attribution Bias in Large Language Models
arXiv preprint[paper]Raj, Chahat and Banerjee, Mahika and Caliskan, Aylin and Anastasopoulos, Antonios and Zhu, Ziwei
-
Large language models as recommender systems: A study of popularity bias
arXiv preprint[paper]Lichtenberg, Jan Malte and Buchholz, Alexander and Schw{"o}bel, Pola
-
Beyond Utility: Evaluating LLM as Recommender
WWW 2025[paper]Jiang, Chumeng and Wang, Jiayin and Ma, Weizhi and Clarke, Charles LA and Wang, Shuai and Wu, Chuhan and Zhang, Min
-
Where to show Demos in Your Prompt: A Positional Bias of In-Context Learning
arXiv preprint[paper]Cobbina, Kwesi and Zhou, Tianyi
-
Large language models sensitivity to the order of options in multiple-choice questions
NAACL 2024[paper]Pezeshkpour, Pouya and Hruschka, Estevam
-
Mitigating order sensitivity in large language models for multiple-choice question tasks
IJAIRD 2024[paper]Jayaram, Vivekananda and Ramineni, Vishnu and Krishnappa, Manjunatha Sughaturu
-
The Order Effect: Investigating Prompt Sensitivity to Input Order in LLMs
KDD 2025 Workshop on Prompt Optimization[paper]Guan, Bryan and Roosta, Tanya and Passban, Peyman and Rezagholizadeh, Mehdi
-
Anchoring Bias in Large Language Models: An Experimental Study
arXiv preprint[paper]Lou, Jiaxu and Sun, Yifan
-
Believing Anthropomorphism: Examining the Role of Anthropomorphic Cues on Trust in Large Language Models
CHI 2024[paper]Cohn, Michelle and Pushkarna, Mahima and Olanubi, Gbolahan O and Moran, Joseph M and Padgett, Daniel and Mengesha, Zion and Heldreth, Courtney
-
Benchmarking cognitive biases in large language models as evaluators
ACL 2024[paper]Koo, Ryan and Lee, Minhwa and Raheja, Vipul and Park, Jong Inn and Kim, Zae Myung and Kang, Dongyeop
-
Large Language Models Can Be Easily Distracted by Irrelevant Context
ICML 2023[paper]Shi, Freda and Chen, Xinyun and Misra, Kanishka and Scales, Nathan and Dohan, David and Chi, Ed and Schärli, Nathanael and Zhou, Denny
-
Instructed to bias: instruction-tuned language models exhibit emergent cognitive bias
TACL 2024[paper]Itzhak, Itay and Stanovsky, Gabriel and Rosenfeld, Nir and Belinkov, Yonatan
-
Machine psychology: Investigating emergent capabilities and behavior in large language models using psychological methods
arXiv preprint[paper]Thilo Hagendorff and Ishita Dasgupta and Marcel Binz and Stephanie C. Y. Chan and Andrew Lampinen and Jane X. Wang and Zeynep Akata and Eric Schulz
-
Cognitive LLMs: Toward Human-Like Artificial Intelligence by Integrating Cognitive Architectures and Large Language Models for Manufacturing Decision-making
Neurosymbolic Artificial Intelligence 2024[paper]Wu, Siyu and Oltramari, Alessandro and Francis, Jonathan and Giles, C Lee and Ritter, Frank E
-
Argumentative Experience: Reducing Confirmation Bias on Controversial Issues through LLM-Generated Multi-Persona Debates
arXiv preprint[paper]Shi, Li and Liu, Houjiang and Wong, Yian and Mujumdar, Utkarsh and Zhang, Dan and Gwizdka, Jacek and Lease, Matthew
Implicit Social Reasoning
-
Theory of mind in large language models: Examining performance of 11 state-of-the-art models vs. children aged 7-10 on advanced tests
CoNLL 2023[paper]van Duijn, Max J and van Dijk, Bram and Kouwenhoven, Tom and de Valk, Werner and Spruit, Marco R and van der Putten, Peter
-
FANToM: A benchmark for stress-testing machine theory of mind in interactions
EMNLP 2023[paper]Kim, Hyunwoo and Sclar, Melanie and Zhou, Xuhui and Bras, Ronan Le and Kim, Gunhee and Choi, Yejin and Sap, Maarten
-
Neural theory-of-mind? on the limits of social intelligence in large lms
EMNLP 2022[paper]Sap, Maarten and LeBras, Ronan and Fried, Daniel and Choi, Yejin
-
Dissecting the Ullman Variations with a SCALPEL: Why do LLMs fail at Trivial Alterations to the False Belief Task?
arXiv preprint[paper]Pi, Zhiqiang and Vadaparty, Annapurna and Bergen, Benjamin K and Jones, Cameron R
-
Large language models fail on trivial alterations to theory-of-mind tasks
arXiv preprint[paper]Ullman, Tomer
-
Evaluating large language models in theory of mind tasks
PNAS 2024[paper]Kosinski, Michal
-
Clever hans or neural theory of mind? stress testing social reasoning in large language models
EACL 2024[paper]Shapira, Natalie and Levy, Mosh and Alavi, Seyed Hossein and Zhou, Xuhui and Choi, Yejin and Goldberg, Yoav and Sap, Maarten and Shwartz, Vered
-
SimpleToM: Exposing the Gap between Explicit ToM Inference and Implicit ToM Application in LLMs
arXiv preprint[paper]Gu, Yuling and Tafjord, Oyvind and Kim, Hyunwoo and Moore, Jared and Bras, Ronan Le and Clark, Peter and Choi, Yejin
-
Hi-tom: A benchmark for evaluating higher-order theory of mind reasoning in large language models
EMNLP 2023[paper]He, Yinghui and Wu, Yufan and Jia, Yilin and Mihalcea, Rada and Chen, Yulong and Deng, Naihao
-
How FaR Are Large Language Models From Agents with Theory-of-Mind?
arXiv preprint[paper]Zhou, Pei and Madaan, Aman and Potharaju, Srividya Pranavi and Gupta, Aditya and McKee, Kevin R and Holtzman, Ari and Pujara, Jay and Ren, Xiang and Mishra, Swaroop and Nematzadeh, Aida and others
-
Testing theory of mind in large language models and humans
Nature Human Behaviour 2024[paper]Strachan, James WA and Albergo, Dalila and Borghini, Giulia and Pansardi, Oriana and Scaliti, Eugenio and Gupta, Saurabh and Saxena, Krati and Rufo, Alessandro and Panzeri, Stefano and Manzi, Guido and others
-
Minding Language Models’ (Lack of) Theory of Mind: A Plug-and-Play Multi-Character Belief Tracker
ACL 2023[paper]Sclar, Melanie and Kumar, Sachin and West, Peter and Suhr, Alane and Choi, Yejin and Tsvetkov, Yulia
-
Artificial Intelligence and the Illusion of Understanding: A Systematic Review of Theory of Mind and Large Language Models
Cyberpsychology, Behavior, and Social Networking 2025[paper]Marchetti, Antonella and Manzi, Federico and Riva, Giuseppe and Gaggioli, Andrea and Massaro, Davide
-
Towards Dynamic Theory of Mind: Evaluating LLM Adaptation to Temporal Evolution of Human States
ACL 2025[paper]Xiao, Yang and Wang, Jiashuo and Xu, Qiancheng and Song, Changhe and Xu, Chunpu and Cheng, Yi and Li, Wenjie and Liu, Pengfei
-
EmoBench: Evaluating the Emotional Intelligence of Large Language Models
ACL 2024[paper]Sabour, Sahand and Liu, Siyang and Zhang, Zheyuan and Liu, June M and Zhou, Jinfeng and Sunaryo, Alvionna S and Li, Juanzi and Lee, Tatia and Mihalcea, Rada and Huang, Minlie
-
EmoBench-M: Benchmarking Emotional Intelligence for Multimodal Large Language Models
arXiv preprint[paper]Hu, He and Zhou, Yucheng and You, Lianzhong and Xu, Hongbo and Wang, Qianning and Lian, Zheng and Yu, Fei Richard and Ma, Fei and Cui, Laizhong
-
Can LLMs Reason Like Humans? Assessing Theory of Mind Reasoning in LLMs for Open-Ended Questions
CIKM 2024[paper]Amirizaniani, Maryam and Martin, Elias and Sivachenko, Maryna and Mashhadi, Afra and Shah, Chirag
-
The Emotional Intelligence of the GPT-4 Large Language Model
Psychol Russ 2024[paper]Vzorinab, Gleb D and Bukinichac, Alexey M and Sedykha, Anna V and Vetrovab, Irina I and Sergienkob, Elena A
-
Multilingual Language Models are not Multicultural: A Case Study in Emotion
ACL 2023[paper]Havaldar, Shreya and Rai, Sunny and Singhal, Bhumika and Liu, Langchen and Guntuku, Sharath Chandra and Ungar, Lyle
-
MoralBench: Moral Evaluation of LLMs
arXiv preprint[paper]Ji, Jianchao and Chen, Yutong and Jin, Mingyu and Xu, Wujiang and Hua, Wenyue and Zhang, Yongfeng
-
As an AI Language Model," Yes I Would Recommend Calling the Police": Norm Inconsistency in LLM Decision-Making
AIES 2024[paper]Jain, Shomik and Calacci, D and Wilson, Ashia
-
Measuring Moral Inconsistencies in Large Language Models
arXiv preprint[paper]Bonagiri, Vamshi Krishna and Vennam, Sreeram and Gaur, Manas and Kumaraguru, Ponnurangam
-
Probing the moral development of large language models through defining issues test
arXiv preprint[paper]Tanmay, Kumar and Khandelwal, Aditi and Agarwal, Utkarsh and Choudhury, Monojit
-
Correcting negative bias in large language models through negative attention score alignment
arXiv preprint[paper]Yu, Sangwon and Song, Jongyoon and Hwang, Bongkyu and Kang, Hoyoung and Cho, Sooah and Choi, Junhwa and Joe, Seongho and Lee, Taehee and Gwon, Youngjune L and Yoon, Sungroh
-
Ethical reasoning and moral value alignment of LLMs depend on the language we prompt them in
ACL 2024[paper]Agarwal, Utkarsh and Tanmay, Kumar and Khandelwal, Aditi and Choudhury, Monojit
-
GreedLlama: Performance of financial value-aligned large language models in moral reasoning
arXiv preprint[paper]Yu, Jeffy and Huber, Maximilian and Tang, Kevin
-
EgoNormia: Benchmarking Physical Social Norm Understanding
arXiv preprint[paper]Rezaei, MohammadHossein and Fu, Yicheng and Cuvin, Phil and Ziems, Caleb and Zhang, Yanzhe and Zhu, Hao and Yang, Diyi
-
The Moral Turing Test: Evaluating Human-LLM Alignment in Moral Decision-Making
arXiv preprint[paper]Garcia, Basile and Qian, Crystal and Palminteri, Stefano
-
The moral machine experiment on large language models
Royal Society[paper]Takemoto, Kazuhiro
-
Investigating machine moral judgement through the Delphi experiment
Nature Machine Intelligence 2025[paper]Jiang, Liwei and Hwang, Jena D and Bhagavatula, Chandra and Bras, Ronan Le and Liang, Jenny T and Levine, Sydney and Dodge, Jesse and Sakaguchi, Keisuke and Forbes, Maxwell and Hessel, Jack and others
Explicit Social Reasoning
-
Theory of mind for multi-agent collaboration via large language models
EMNLP 2023[paper]Li, Huao and Chong, Yu Quan and Stepputtis, Simon and Campbell, Joseph and Hughes, Dana and Lewis, Michael and Sycara, Katia
-
Socialeval: Evaluating social intelligence of large language models
ACL 2025[paper]Zhou, Jinfeng and Chen, Yuxuan and Shi, Yihan and Zhang, Xuanming and Lei, Leqi and Feng, Yi and Xiong, Zexuan and Yan, Miao and Wang, Xunzhi and Cao, Yaru and others
-
Hypothetical minds: Scaffolding theory of mind for multi-agent tasks with large language models
ICLR 2025[paper]Cross, Logan and Xiang, Violet and Bhatia, Agam and Yamins, Daniel LK and Haber, Nick
-
Large language model based multi-agents: A survey of progress and challenges
IJCAI 2024[paper]Guo, Taicheng and Chen, Xiuying and Wang, Yaqi and Chang, Ruidi and Pei, Shichao and Chawla, Nitesh V and Wiest, Olaf and Zhang, Xiangliang
-
LLM multi-agent systems: Challenges and open problems
arXiv preprint[paper]Han, Shanshan and Zhang, Qifan and Yao, Yuhang and Jin, Weizhao and Xu, Zhaozhuo and He, Chaoyang
-
Cooperate or collapse: Emergence of sustainable cooperation in a society of llm agents
NeurIPS 2024[paper]Piatti, Giorgio and Jin, Zhijing and Kleiman-Weiner, Max and Sch{"o}lkopf, Bernhard and Sachan, Mrinmaya and Mihalcea, Rada
-
Building cooperative embodied agents modularly with large language models
ICLR 2024[paper]Zhang, Hongxin and Du, Weihua and Shan, Jiaming and Zhou, Qinhong and Du, Yilun and Tenenbaum, Joshua B and Shu, Tianmin and Gan, Chuang
-
LLM-Coordination: Evaluating and Analyzing Multi-agent Coordination Abilities in Large Language Models
arXiv preprint[paper]Saaket Agashe and Yue Fan and Anthony Reyna and Xin Eric Wang
-
Why Do Multiagent Systems Fail?
ICLR 2025 Workshop[paper]Pan, Melissa Z and Cemri, Mert and Agrawal, Lakshya A and Yang, Shuyi and Chopra, Bhavya and Tiwari, Rishabh and Keutzer, Kurt and Parameswaran, Aditya and Ramchandran, Kannan and Klein, Dan and others
-
On the resilience of multi-agent systems with malicious agents
CoRR 2024[paper]Huang, Jen-tse and Zhou, Jiaxu and Jin, Tailin and Zhou, Xuhui and Chen, Zixi and Wang, Wenxuan and Yuan, Youliang and Sap, Maarten and Lyu, Michael R
-
Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation
arXiv preprint[paper]Baker, Bowen and Huizinga, Joost and Gao, Leo and Dou, Zehao and Guan, Melody Y and Madry, Aleksander and Zaremba, Wojciech and Pachocki, Jakub and Farhi, David
-
Magic: Investigation of large language model powered multi-agent in cognition, adaptability, rationality and collaboration
EMNLP 2024[paper]Xu, Lin and Hu, Zhiyuan and Zhou, Daquan and Ren, Hongyu and Dong, Zhen and Keutzer, Kurt and Ng, See Kiong and Feng, Jiashi
Formal Reasoning -- Logic and Arithmetic
Logic in Natural Languages
-
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
ICLR 2024[paper]Berglund, Lukas and Tong, Meg and Kaufmann, Max and Balesni, Mikita and Stickland, Asa Cooper and Korbak, Tomasz and Evans, Owain
-
Exploring the Reversal Curse and Other Deductive Logical Reasoning in BERT and GPT-Based Large Language Models
Patterns 2024[paper]Wu, Da and Yang, Jingye and Wang, Kai
-
Reverse Training to Nurse the Reversal Curse
COLM 2024[paper]Golovneva, Olga and Allen-Zhu, Zeyuan and Weston, Jason and Sukhbaatar, Sainbayar
-
The Queen of England is not England's Queen: On the Lack of Factual Coherency in PLMs
EACL 2024[paper]Youssef, Paul and Schlötterer, Jörg and Seifert, Christin
-
Exploring Reversal Mathematical Reasoning Ability for Large Language Models
ACL 2024[paper]Guo, Pei and You, WangJie and Li, Juntao and Bowen, Yan and Zhang, Min
-
Mitigating Reversal Curse in Large Language Models via Semantic-aware Permutation Training
ACL 2024[paper]Guo, Qingyan and Wang, Rui and Guo, Junliang and Tan, Xu and Bian, Jiang and Yang, Yujiu
-
An Analysis and Mitigation of the Reversal Curse
EMNLP 2024[paper]Lv, Ang and Zhang, Kaiyi and Xie, Shufang and Tu, Quan and Chen, Yuhan and Wen, Ji-Rong and Yan, Rui
-
Untying the Reversal Curse via Bidirectional Language Model Editing
arXiv preprint[paper]Ma, Jun-Yu and Gu, Jia-Chen and Ling, Zhen-Hua and Liu, Quan and Liu, Cong
-
Rethinking the Reversal Curse of LLMs: a Prescription from Human Knowledge Reversal
EMNLP 2024[paper]Lu, Zhicong and Jin, Li and Li, Peiguang and Tian, Yu and Zhang, Linhao and Wang, Sirui and Xu, Guangluan and Tian, Changyuan and Cai, Xunliang
-
Delving into the Reversal Curse: How Far Can Large Language Models Generalize?
NeurIPS 2024[paper]Lin, Zhengkai and Fu, Zhihang and Liu, Kai and Xie, Liang and Lin, Binbin and Wang, Wenxiao and Cai, Deng and Wu, Yue and Ye, Jieping
-
Towards a Theoretical Understanding of the 'Reversal Curse' via Training Dynamics
NeurIPS 2024[paper]Zhu, Hanlin and Huang, Baihe and Zhang, Shaolun and Jordan, Michael and Jiao, Jiantao and Tian, Yuandong and Russell, Stuart
-
The Two-Hop Curse: LLMs trained on A->B, B->C fail to learn A-->C
arXiv preprint[paper]Balesni, Mikita and Korbak, Tomek and Evans, Owain
-
How Do LLMs Perform Two-Hop Reasoning in Context?
arXiv preprint[paper]Guo, Tianyu and Zhu, Hanlin and Zhang, Ruiqi and Jiao, Jiantao and Mei, Song and Jordan, Michael I. and Russell, Stuart
-
Exploring the Limitations of Large Language Models in Compositional Relation Reasoning
COLM 2024[paper]Zhao, Jinman and Zhang, Xueyan
-
Faith and Fate: Limits of Transformers on Compositionality
NeurIPS 2023[paper]Dziri, Nouha and Lu, Ximing and Sclar, Melanie and Li, Xiang Lorraine and Jiang, Liwei and Lin, Bill Yuchen and West, Peter and Bhagavatula, Chandra and Bras, Ronan Le and Hwang, Jena D. and Sanyal, Soumya and Welleck, Sean and Ren, Xiang and Ettinger, Allyson and Harchaoui, Zaid and Choi, Yejin
-
Exploring the Compositional Deficiency of Large Language Models in Mathematical Reasoning
EMNLP 2024[paper]Zhao, Jun and Tong, Jingqi and Mou, Yurong and Zhang, Ming and Zhang, Qi and Huang, Xuanjing
-
BoolQ: Exploring the Surprising Difficulty of Natural Yes/No Questions
NAACL 2019[paper]Clark, Christopher and Lee, Kenton and Chang, Ming-Wei and Kwiatkowski, Tom and Collins, Michael and Toutanova, Kristina
-
LogicAsker: Evaluating and Improving the Logical Reasoning Ability of Large Language Models
EMNLP 2024[paper]Wan, Yuxuan and Wang, Wenxuan and Yang, Yiliu and Yuan, Youliang and Huang, Jen-tse and He, Pinjia and Jiao, Wenxiang and Lyu, Michael R.
-
Evaluating Large Language Models with NeuBAROCO: Syllogistic Reasoning Ability and Human-like Biases
NALOMA IV[paper]Ando, Risako and Morishita, Takanobu and Abe, Hirohiko and Mineshima, Koji and Okada, Mitsuhiro
-
An Investigation of LLMs' Inefficacy in Understanding Converse Relations
EMNLP 2023[paper]Qi, Chengwen and Li, Bowen and Hui, Binyuan and Wang, Bailin and Li, Jinyang and Wu, Jinwang and Laili, Yuanjun
-
Assessing the Reasoning Abilities of ChatGPT in the Context of Claim Verification
arXiv preprint[paper]Dougrez-Lewis, John and Akhter, Mahmud Elahi and He, Yulan and Liakata, Maria
-
LLMs Are Prone to Fallacies in Causal Inference
EMNLP 2024[paper]Joshi, Nitish and Saparov, Abulhair and Wang, Yixin and He, He
-
Rulebreakers Challenge: Revealing a Blind Spot in Large Language Models' Reasoning with Formal Logic
arXiv preprint[paper]Chan, Jason and Gaizauskas, Robert and Zhao, Zhixue
-
Large Language Models Fall Short: Understanding Complex Relationships in Detective Narratives
ACL 2024[paper]Zhao, Runcong and Zhu, Qinglin and Xu, Hainiu and Li, Jiazheng and Zhou, Yuxiang and He, Yulan and Gui, Lin
-
Not All LLM Reasoners Are Created Equal
arXiv preprint[paper]Hosseini, Arian and Sordoni, Alessandro and Toyama, Daniel and Courville, Aaron and Agarwal, Rishabh
-
Do Large Language Models Have Compositional Ability? An Investigation into Limitations and Scalability
COLM 2024[paper]Xu, Zhuoyan and Shi, Zhenmei and Liang, Yingyu
-
Understanding and Patching Compositional Reasoning in LLMs
ACL 2024[paper]Li, Zhaoyi and Jiang, Gangwei and Xie, Hong and Song, Linqi and Lian, Defu and Wei, Ying
-
Do Large Language Models Perform Latent Multi-Hop Reasoning without Exploiting Shortcuts?
ACL 2024[paper]Yang, Sohee and Kassner, Nora and Gribovskaya, Elena and Riedel, Sebastian and Geva, Mor
-
Enhancing Logical Reasoning in Large Language Models through Graph-based Synthetic Data
arXiv preprint[paper]Zhou, Jiaming and Ghaddar, Abbas and Zhang, Ge and Ma, Liheng and Hu, Yaochen and Pal, Soumyasundar and Coates, Mark and Wang, Bin and Zhang, Yingxue and Hao, Jianye
-
LogicGame: Benchmarking Rule-Based Reasoning Abilities of Large Language Models
ACL 2024[paper]Gui, Jiayi and Liu, Yiming and Cheng, Jiale and Gu, Xiaotao and Liu, Xiao and Wang, Hongning and Dong, Yuxiao and Tang, Jie and Huang, Minlie
-
Can LLMs Reason with Rules? Logic Scaffolding for Stress-Testing and Improving LLMs
ACL 2024[paper]Wang, Siyuan and Wei, Zhongyu and Choi, Yejin and Ren, Xiang
-
See What LLMs Cannot Answer: A Self-Challenge Framework for Uncovering LLM Weaknesses
COLM 2024[paper]Chen, Yulong and Liu, Yang and Yan, Jianhao and Bai, Xuefeng and Zhong, Ming and Yang, Yinghao and Yang, Ziyi and Zhu, Chenguang and Zhang, Yue
Logic in Benchmarks
-
Large Language Models Are Not Robust Multiple Choice Selectors
ICLR 2024[paper]Zheng, Chujie and Zhou, Hao and Meng, Fandong and Zhou, Jie and Huang, Minlie
-
Large language models sensitivity to the order of options in multiple-choice questions
NAACL 2024[paper]Pezeshkpour, Pouya and Hruschka, Estevam
-
When benchmarks are targets: Revealing the sensitivity of large language model leaderboards
ACL 2024[paper]Alzahrani, Norah and Alyahya, Hisham Abdullah and Alnumay, Yazeed and Alrashed, Sultan and Alsubaie, Shaykhah and Almushaykeh, Yusef and Mirza, Faisal and Alotaibi, Nouf and Altwairesh, Nora and Alowisheq, Areeb and Bari, M Saiful and Khan, Haidar
-
In-Context Learning May Not Elicit Trustworthy Reasoning: A-Not-B Errors in Pretrained Language Models"
EMNLP 2024[paper]Han, Pengrui and Song, Peiyang and Yu, Haofei and You, Jiaxuan
-
Changing Answer Order Can Decrease MMLU Accuracy
arXiv preprint[paper]Gupta, Vipul and Pantoja, David and Ross, Candace and Williams, Adina and Ung, Megan
-
Premise Order Matters in Reasoning with Large Language Models
ICML 2024[paper]Chen, Xinyun and Chi, Ryan A. and Wang, Xuezhi and Zhou, Denny
-
Failure Modes of LLMs for Causal Reasoning on Narratives
arXiv preprint[paper]Yamin, Khurram and Gupta, Shantanu and Gaurav R. Ghosal, Gaurav R. and Lipton, Zachary C. and Wilder, Bryan
-
A Peek into Token Bias: Large Language Models Are Not Yet Genuine Reasoners
EMNLP 2024[paper]Jiang, Bowen and Xie, Yangxinyu and Hao, Zhuoqun and Wang, Xiaomeng and Mallick, Tanwi and Su, Weijie J. and Taylor, Camillo J. and Roth, Dan
-
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
arXiv preprint[paper]Mirzadeh, Iman and Alizadeh, Keivan and Shahrokhim, Hooman and Tuzel, Oncel and Bengio, Samy and Farajtabar, Mehrdad
-
Reasoning or Reciting? Exploring the Capabilities and Limitations of Language Models Through Counterfactual Tasks
NAACL 2024[paper]Wu, Zhaofeng and Qiu, Linlu and Ross, Alexis and Akyürek, Ekin and Chen, Boyuan and Wang, Bailin and Kim, Najoung and Andreas, Jacob and Kim, Yoon
-
GSM-Plus: A Comprehensive Benchmark for Evaluating the Robustness of LLMs as Mathematical Problem Solvers
ACL 2024[paper]Li, Qintong and Cui, Leyang and Zhao, Xueliang and Kong, Lingpeng and Bi, Wei
-
Are NLP Models really able to Solve Simple Math Word Problems?
NAACL 2021[paper]Patel, Arkil and Bhattamishra, Satwik and Goyal, Navin
-
Large Language Models Can Be Easily Distracted by Irrelevant Context
ICML 2023[paper]Shi, Freda and Chen, Xinyun and Misra, Kanishka and Scales, Nathan and Dohan, David and Chi, Ed and Schärli, Nathanael and Zhou, Denny
-
ReCode: Robustness Evaluation of Code Generation Models
ACL 2023[[paper]Wang, Shiqi and Li, Zheng and Qian, Haifeng and Yang, Chenghao and Wang, Zijian and Shang, Mingyue and Kumar, Varun and Tan, Samson and Ray, Baishakhi and Bhatia, Parminder and Nallapati, Ramesh and Ramanathan, Murali Krishna and Roth, Dan and Xiang, Bing
-
Do Large Code Models Understand Programming Concepts? A Black-box Approach
ICML 2024[paper]Hooda, Ashish and Christodorescu, Mihai and Allamanis, Miltiadis and Wilson, Aaron and Fawaz, Kassem and Jha, Somesh
-
Top Leaderboard Ranking = Top Coding Proficiency, Always? EvoEval: Evolving Coding Benchmarks via LLM
COLM 2024[paper]Xia, Chunqiu Steven and Deng, Yinlin and Zhang, Lingming
-
Large Language Models of Code Fail at Completing Code with Potential Bugs
NeurIPS 2023[paper]Dinh, Tuan and Zhao, Jinman and Tan, Samson and Negrinho, Renato and Lausen, Leonard and Zha, Sheng and Karypis, George
-
The Larger They Are, the Harder They Fail: Language Models do not Recognize Identifier Swaps in Python
ACL 2023[paper]Miceli-Barone, Antonio Valerio and Barez, Fazl and Konstas, Ioannis and Cohen, Shay B.
-
Syntactic Robustness for LLM-based Code Generation
arXiv preprint[paper]Sarker, Laboni and Downing, Mara and Desai, Achintya and Bultan, Tevfik
-
RUPBench: Benchmarking Reasoning Under Perturbations for Robustness Evaluation in Large Language Models
arXiv preprint[paper]Wang, Yuqing and Zhao, Yun
-
Evaluating LLMs' Mathematical and Coding Competency through Ontology-guided Interventions
arXiv preprint[paper]Hong, Pengfei and Majumder, Navonil and Ghosal, Deepanway and Aditya, Somak and Mihalcea, Rada and Poria, Soujanya
-
Fill in the Blank: Exploring and Enhancing LLM Capabilities for Backward Reasoning in Math Word Problems
arXiv preprint[paper]Deb, Aniruddha and Oza, Neeva and Singla, Sarthak and Khandelwal, Dinesh and Garg, Dinesh and Singla, Parag
-
MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations
arXiv preprint[paper]Huang, Kaixuan and Guo, Jiacheng and Li, Zihao and Ji, Xiang and Ge, Jiawei and Li, Wenzhe and Guo, Yingqing and Cai, Tianle and Yuan, Hui and Wang, Runzhe and Wu, Yue and Yin, Ming and Tang, Shange and Huang, Yangsibo and Jin, Chi and Chen, Xinyun and Zhang, Chiyuan and Wang, Mengdi
-
Reasoning LLMs are Wandering Solution Explorers
arXiv preprint[paper]Lu, Jiahao and Xu, Ziwei and Kankanhalli, Mohan
-
The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity
arXiv preprint[paper]Shojaee, Parshin and Mirzadeh, Iman and Alizadeh, Keivan and Horton, Maxwell and Bengio, Samy and Farajtabar, Mehrdad
-
Comment on The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity
arXiv preprint[paper]Lawsen, Alex
-
OMEGA: Can LLMs Reason Outside the Box in Math? Evaluating Exploratory, Compositional, and Transformative Generalization
arXiv preprint[paper]Sun, Yiyou and Hu, Shawn and Zhou, Georgia and Zheng, Ken and Hajishirzi, Hannaneh and Dziri, Nouha and Song, Dawn
-
FormulaOne: Measuring the Depth of Algorithmic Reasoning Beyond Competitive Programming
arXiv preprint[paper]Beniamini, Gal and Dor, Yuval and Vinnikov, Alon and Peled, Shir Granot and Weinstein, Or and Sharir, Or and Wies, Noam and Nussbaum, Tomer and Shaul, Ido Ben and Zekharya, Tomer and Levine, Yoav and Shalev-Shwartz, Shai and Shashua, Amnon
Arithmetic and Mathematics
-
Why Do Large Language Models (LLMs) Struggle to Count Letters?
arXiv preprint[paper]Fu, Tairan and Ferrando, Raquel and Conde, Javier and Arriaga, Carlos and Reviriego, Pedro
-
Frontier LLMs Still Struggle with Simple Reasoning Tasks
arXiv preprint[paper]Malek, Alan and Ge, Jiawei and Lazic, Nevena and Jin, Chi and György, András and Szepesvári, Csaba
-
Counting Ability of Large Language Models and Impact of Tokenization
arXiv preprint[paper]Zhang, Xiang and Cao, Juntai and You, Chenyu
-
Language Models Need Inductive Biases to Count Inductively
ICLR 2025[paper]Chang, Yingshan and Bisk, Yonatan
-
LLM The Genius Paradox: A Linguistic and Math Expert's Struggle with Simple Word-based Counting Problems
arXiv preprint[paper]Xu, Nan and Ma, Xuezhe
-
When Can Transformers Count to n?
arXiv preprint[paper]Yehudai, Gilad and Kaplan, Haim and Ghandeharioun, Asma and Geva, Mor and Globerson, Amir
-
Large Language Models Lack Understanding of Character Composition of Words
arXiv preprint[paper]Shin, Andrew and Kaneko, Kunitake
-
Large Language Models Can Not Perform Well in Understanding and Manipulating Natural Language at Both Character and Word Levels?
EMNLP 2024[paper]Zhang, Yidan and He, Zhenan
-
Can Neural Networks Do Arithmetic? A Survey on the Elementary Numerical Skills of State-of-the-Art Deep Learning Models
Applied Sciences Vol. 14[paper]Testolin, Alberto
-
Large Language Models Are Unconscious of Unreasonability in Math Problems
arXiv preprint[paper]Ma, Jingyuan and Dai, Damai and Sha, Lei and Sui, Zhifang
-
Putnam-AXIOM: A Functional and Static Benchmark for Measuring Higher Level Mathematical Reasoning
arXiv preprint[paper]Gulati, Aryan and Miranda, Brando and Chen, Eric and Xia, Emily and Fronsdal, Kai and Dumont, Bruno de Moraes and Koyejo, Sanmi
-
GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models
arXiv preprint[paper]Mirzadeh, Iman and Alizadeh, Keivan and Shahrokhim, Hooman and Tuzel, Oncel and Bengio, Samy and Farajtabar, Mehrdad
-
GSM-Plus: A Comprehensive Benchmark for Evaluating the Robustness of LLMs as Mathematical Problem Solvers
ACL 2024[paper]Li, Qintong and Cui, Leyang and Zhao, Xueliang and Kong, Lingpeng and Bi, Wei
-
Large Language Models Can Be Easily Distracted by Irrelevant Context
ICML 2023[paper]Shi, Freda and Chen, Xinyun and Misra, Kanishka and Scales, Nathan and Dohan, David and Chi, Ed and Schärli, Nathanael and Zhou, Denny
-
VarBench: Robust Language Model Benchmarking Through Dynamic Variable Perturbation
EMNLP 2024[paper]Qian, Kun and Wan, Shunji and Tang, Claudia and Wang, Youzhi and Zhang, Xuanming and Chen, Maximillian and Yu, Zhou
-
Alice in Wonderland: Simple Tasks Showing Complete Reasoning Breakdown in State-Of-the-Art Large Language Models
arXiv preprint[paper]Nezhurina, Marianna and Cipolina-Kun, Lucia and Cherti, Mehdi and Jitsev, Jenia
-
Rationales for Answers to Simple Math Word Problems Confuse Large Language Models
ACL 2024[paper]Zhang, Yidan and Xue, Mingfeng and Liu, Dayiheng and He, Zhenan
-
Living in the Moment: Can Large Language Models Grasp Co-Temporal Reasoning?
ACL 2024[paper]Su, Zhaochen and Li, Juntao and Zhang, Jun and Zhu, Tong and Qu, Xiaoye and Zhou, Pan and Bowen, Yan and Cheng, Yu and zhang, Min
-
Randomly Sampled Language Reasoning Problems Reveal Limits of LLMs
arXiv preprint[paper]Gupta, Kavi and Sanders, Kate and Solar-Lezama, Armando
-
From Blind Solvers to Logical Thinkers: Benchmarking LLMs' Logical Integrity on Faulty Mathematical Problems
arXiv preprint[paper]Rahman, A M Muntasir and Ye, Junyi and Yao, Wei and Yin, Wenpeng and Wang, Guiling
-
How well do Large Language Models perform in Arithmetic tasks?
arXiv preprint[paper]Yuan, Zheng and Yuan, Hongyi and Tan, Chuanqi and Wang, Wei and Huang, Songfang
-
How Numerical Precision Affects Mathematical Reasoning Capabilities of LLMs
arXiv preprint[paper]Feng, Guhao and Yang, Kai and Gu, Yuntian and Ai, Xinyue and Luo, Shengjie and Sun, Jiacheng and He, Di and Li, Zhenguo and Wang, Liwei
-
Language Models Do Hard Arithmetic Tasks Easily and Hardly Do Easy Arithmetic Tasks
ACL 2024[paper]Gambardella, Andrew and Iwasawa, Yusuke and Matsuo, Yutaka
-
Language Models are Symbolic Learners in Arithmetic
arXiv preprint[paper]Deng, Chunyuan and Li, Zhiqi and Xie, Roy and Chang, Ruidi and Chen, Hanjie
-
OccamLLM: Fast and Exact Language Model Arithmetic in a Single Step
NeurIPS 2024[paper]Dugan, Owen and Beneto, Donato Manuel Jimenez and Loh, Charlotte and Chen, Zhuo and Dangovski, Rumen and Soljačić, Marin
-
GPT Can Solve Mathematical Problems Without a Calculator
arXiv preprint[paper]Yang, Zhen and Ding, Ming and Lv, Qingsong and Jiang, Zhihuan and He, Zehai and Guo, Yuyi and Bai, Jinfeng and Tang, Jie
-
Fill in the Blank: Exploring and Enhancing LLM Capabilities for Backward Reasoning in Math Word Problems
arXiv preprint[paper]Deb, Aniruddha and Oza, Neeva and Singla, Sarthak and Khandelwal, Dinesh and Garg, Dinesh and Singla, Parag
-
Robustness Assessment of Mathematical Reasoning in the Presence of Missing and Contradictory Conditions
arXiv preprint[paper]Tian, Shi-Yu and Zhou, Zhi and Jia, Lin-Han and Guo, Lan-Zhe and Li, Yu-Feng
-
Reverse That Number! Decoding Order Matters in Arithmetic Learning
arXiv preprint[paper]Zhang-Li, Daniel and Lin, Nianyi and Yu, Jifan and Zhang, Zheyuan and Yao, Zijun and Zhang, Xiaokang and Hou, Lei and Zhang, Jing and Li, Juanzi
-
RevOrder: A Novel Method for Enhanced Arithmetic in Language Models
arXiv preprint[paper]Shen, Si and Shen, Peijun and Zhu, Danhao
-
Arithmetic Without Algorithms: Language Models Solve Math With a Bag of Heuristics
ICLR 2025[paper]Nikankin, Yaniv and Reusch, Anja and Mueller, Aaron and Belinkov, Yonatan
-
CMATH: Can Your Language Model Pass Chinese Elementary School Math Test?
arXiv preprint[paper]Wei, Tianwen and Luan, Jian and Liu, Wei and Dong, Shuang and Wang, Bin
-
Large Language Models and Mathematical Reasoning Failures
arXiv preprint[paper]Boye, Johan and Moell, Birger
-
HARDMath: A Benchmark Dataset for Challenging Problems in Applied Mathematics
arXiv preprint[paper]Fan, Jingxuan and Martinson, Sarah and Wang, Erik Y. and Hausknecht, Kaylie and Brenner, Jonah and Liu, Danxian and Peng, Nianli and Wang, Corey and Brenner, Michael P.
-
MATH-Perturb: Benchmarking LLMs' Math Reasoning Abilities against Hard Perturbations
arXiv preprint[paper]Huang, Kaixuan and Guo, Jiacheng and Li, Zihao and Ji, Xiang and Ge, Jiawei and Li, Wenzhe and Guo, Yingqing and Cai, Tianle and Yuan, Hui and Wang, Runzhe and Wu, Yue and Yin, Ming and Tang, Shange and Huang, Yangsibo and Jin, Chi and Chen, Xinyun and Zhang, Chiyuan and Wang, Mengdi
-
Self-Improving Transformers Overcome Easy-to-Hard and Length Generalization Challenges
arXiv preprint[paper]Lee, Nayoung and Cai, Ziyang and Schwarzschild, Avi and Lee, Kangwook and Papailiopoulos, Dimitris
-
OMEGA: Can LLMs Reason Outside the Box in Math? Evaluating Exploratory, Compositional, and Transformative Generalization
arXiv preprint[paper]Sun, Yiyou and Hu, Shawn and Zhou, Georgia and Zheng, Ken and Hajishirzi, Hannaneh and Dziri, Nouha and Song, Dawn
-
Counting and algorithmic generalization with transformers
arXiv preprint[paper]Ouellette, Simon and Pfister, Rolf and Jud, Hansueli
Reasoning in Embodied Environments
1D - Text Based
-
Prost: Physical reasoning about objects through space and time
ACL 2021[paper]Aroca-Ouellette, Stéphane and Paik, Cory and Roncone, Alessandro and Kann, Katharina
-
TEXT2AFFORD: Probing Object Affordance Prediction abilities of Language Models solely from Text
CoNLL 2024[paper]Adak, Sayantan and Agrawal, Daivik and Mukherjee, Animesh and Aditya, Somak
-
A Multi-layered Approach to Physical Commonsense Understanding: Creation and Evaluation of an Italian Dataset
COLING 2024[paper]Pensa, Giulia and Altuna, Bego{~n}a and Gonzalez-Dios, Itziar
-
ChatGPT and the frustrated socrates
Physics Education 2023[paper]Gregorcic, Bor and Pendrill, Ann-Marie
-
Things not written in text: Exploring spatial commonsense from visual signals
ACL 2022[paper]Liu, Xiao and Yin, Da and Feng, Yansong and Zhao, Dongyan
-
POSQA: Probe the World Models of LLMs with Size Comparisons
EMNLP 2023[paper]Shu, Chang and Han, Jiuzhou and Liu, Fangyu and Shareghi, Ehsan and Collier, Nigel
-
Probing physical reasoning with Counter-Commonsense context
ACL 2023[paper]Kondo, Kazushi and Sugawara, Saku and Aizawa, Akiko
-
NEWTON: Are Large Language Models Capable of Physical Reasoning?
EMNLP 2023[paper]Yi Ru Wang and Jiafei Duan and Dieter Fox and Siddhartha Srinivasa
-
PhysReason: A Comprehensive Benchmark towards Physics-Based Reasoning
arXiv preprint[paper]Zhang, Xinyu and Dong, Yuxuan and Wu, Yanrui and Huang, Jiaxing and Jia, Chengyou and Fernando, Basura and Shou, Mike Zheng and Zhang, Lingling and Liu, Jun
-
UGPhysics: A Comprehensive Benchmark for Undergraduate Physics Reasoning with Large Language Models
arXiv preprint[paper]Xu, Xin and Xu, Qiyun and Xiao, Tong and Chen, Tianhao and Yan, Yuchen and Zhang, Jiaxin and Diao, Shizhe and Yang, Can and Wang, Yang
-
Testing LLM performance on the Physics GRE: some observations
arXiv preprint[paper]Gupta, Pranav
-
PHYBench: Holistic Evaluation of Physical Perception and Reasoning in Large Language Models
arXiv preprint[paper]Qiu, Shi and Guo, Shaoyang and Song, Zhuo-Yang and Sun, Yunbo and Cai, Zeyu and Wei, Jiashen and Luo, Tianyu and Yin, Yixuan and Zhang, Haoxu and Hu, Yi and Wang, Chenyang and Tang, Chencheng and Chang, Haoling and Liu, Qi and Zhou, Ziheng and Zhang, Tianyu and Zhang, Jingtian and Liu, Zhangyi and Li, Minghao and Zhang, Yuku and Jing, Boxuan and Yin, Xianqi and Ren, Yutong and Fu, Zizhuo and Ji, Jiaming and Wang, Weike and Tian, Xudong and Lv, Anqi and Man, Laifu and Li, Jianxiang and Tao, Feiyu and Sun, Qihua and Liang, Zhou and Mu, Yushu and Li, Zhongxuan and Zhang, Jing-Jun and Zhang, Shutao and Li, Xiaotian and Xia, Xingqi and Lin, Jiawei and Shen, Zheyu and Chen, Jiahang and Xiong, Qiuhao and Wang, Binran and Wang, Fengyuan and Ni, Ziyang and Zhang, Bohan and Cui, Fan and Shao, Changkun and Cao, Qing-Hong and Luo, Ming-xing and Yang, Yaodong and Zhang, Muhan and Zhu, Hua Xing
-
ABench-Physics: Benchmarking Physical Reasoning in LLMs via High-Difficulty and Dynamic Physics Problems
arXiv preprint[paper]Zhang, Yiming and Ma, Yingfan and Gu, Yanmei and Yang, Zhengkai and Zhuang, Yihong and Wang, Feng and Huang, Zenan and Wang, Yuanyuan and Huang, Chao and Song, Bowen and others
-
Theoretical Physics Benchmark (TPBench)--a Dataset and Study of AI Reasoning Capabilities in Theoretical Physics
arXiv preprint[paper]Chung, Daniel JH and Gao, Zhiqi and Kvasiuk, Yurii and Li, Tianyi and M{"u}nchmeyer, Moritz and Rudolph, Maja and Sala, Frederic and Tadepalli, Sai Chaitanya
-
Improving Physics Reasoning in Large Language Models Using Mixture of Refinement Agents
arXiv preprint[paper]Jaiswal, Raj and Jain, Dhruv and Popat, Harsh Parimal and Anand, Avinash and Dharmadhikari, Abhishek and Marathe, Atharva and Shah, Rajiv Ratn
-
Structured chemistry reasoning with large language models
ICML 2024[paper]Ouyang, Siru and Zhang, Zhuosheng and Yan, Bing and Liu, Xuan and Choi, Yejin and Han, Jiawei and Qin, Lianhui
-
Auto-Bench: An Automated Benchmark for Scientific Discovery in LLMs
arXiv preprint[paper]Chen, Tingting and Anumasa, Srinivas and Lin, Beibei and Shah, Vedant and Goyal, Anirudh and Liu, Dianbo
2D - Perception Based
-
Core knowledge deficits in multi-modal language models
ICML 2025[paper]Li, Yijiang and Gao, Qingying and Zhao, Tianwei and Wang, Bingyang and Sun, Haoran and Lyu, Haiyun and Hawkins, Robert D and Vasconcelos, Nuno and Golan, Tal and Luo, Dezhi and others
-
Breaking common sense: Whoops! a vision-and-language benchmark of synthetic and compositional images
ICCV 2023[paper]Bitton-Guetta, Nitzan and Bitton, Yonatan and Hessel, Jack and Schmidt, Ludwig and Elovici, Yuval and Stanovsky, Gabriel and Schwartz, Roy
-
Rome: Evaluating pre-trained vision-language models on reasoning beyond visual common sense
EMNLP 2023[paper]Zhou, Kankan and Lai, Eason and Yeong, Wei Bin Au and Mouratidis, Kyriakos and Jiang, Jing
-
Vision language models are blind
ACCV 2024[paper]Rahmanzadehgervi, Pooyan and Bolton, Logan and Taesiri, Mohammad Reza and Nguyen, Anh Totti
-
Visual spatial reasoning
TACL 2023[paper]Liu, Fangyu and Emerson, Guy and Collier, Nigel
-
Can Vision Language Models Learn from Visual Demonstrations of Ambiguous Spatial Reasoning?
NeurIPS 2024[paper]Zhao, Bowen and Dirac, Leo Parker and Varshavskaya, Paulina
-
Understanding the limits of vision language models through the lens of the binding problem
NeurIPS 2024[paper]Campbell, Declan and Rane, Sunayana and Giallanza, Tyler and De Sabbata, Camillo Nicol{`o} and Ghods, Kia and Joshi, Amogh and Ku, Alexander and Frankland, Steven and Griffiths, Tom and Cohen, Jonathan D and others
-
Words or Vision: Do Vision-Language Models Have Blind Faith in Text?
arXiv preprint[paper]Deng, Ailin and Cao, Tri and Chen, Zhirui and Hooi, Bryan
-
Large Language Models Are Challenged by Habitat-Centered Reasoning
EMNLP 2024[paper]Ghaffari, Sadaf and Krishnaswamy, Nikhil
-
Visual cognition in multimodal large language models
Nature Machine Intelligence 2025[paper]Schulze Buschoff, Luca M and Akata, Elif and Bethge, Matthias and Schulz, Eric
-
Learning the effects of physical actions in a multi-modal environment
EACL 2023[paper]Dagan, Gautier and Keller, Frank and Lascarides, Alex
-
Synthetic Vision: Training Vision-Language Models to Understand Physics
arXiv preprint[paper]Balazadeh, Vahid and Ataei, Mohammadmehdi and Cheong, Hyunmin and Khasahmadi, Amir Hosein and Krishnan, Rahul G
-
PhysBench: Benchmarking and Enhancing Vision-Language Models for Physical World Understanding
ICLR 2025[paper]Chow, Wei and Mao, Jiageng and Li, Boyi and Seita, Daniel and Guizilini, Vitor and Wang, Yue
-
Physion: Evaluating physical prediction from vision in humans and machines
NeurIPS 2021[paper]Bear, Daniel M and Wang, Elias and Mrowca, Damian and Binder, Felix J and Tung, Hsiao-Yu Fish and Pramod, RT and Holdaway, Cameron and Tao, Sirui and Smith, Kevin and Sun, Fan-Yun and others
-
Craft: A benchmark for causal reasoning about forces and interactions
ACL 2022[paper]Ates, Tayfun and Atesoglu, M Samil and Yigit, Cagatay and Kesen, Ilker and Kobas, Mert and Erdem, Erkut and Erdem, Aykut and Goksun, Tilbe and Yuret, Deniz
-
Mm-phyqa: Multimodal physics question-answering with multi-image cot prompting
PAKDD 2024[paper]Anand, Avinash and Kapuriya, Janak and Singh, Apoorv and Saraf, Jay and Lal, Naman and Verma, Astha and Gupta, Rushali and Shah, Rajiv
-
PhyX: Does Your Model Have the "Wits" for Physical Reasoning?
arXiv preprint[paper]Hui Shen and Taiqiang Wu and Qi Han and Yunta Hsieh and Jizhou Wang and Yuyue Zhang and Yuxin Cheng and Zijian Hao and Yuansheng Ni and Xin Wang and Zhongwei Wan and Kai Zhang and Wendong Xu and Jing Xiong and Ping Luo and Wenhu Chen and Chaofan Tao and Zhuoqing Mao and Ngai Wong
-
Llmphy: Complex physical reasoning using large language models and world models
arXiv preprint[paper]Cherian, Anoop and Corcodel, Radu and Jain, Siddarth and Romeres, Diego
-
Exploring Failure Cases in Multimodal Reasoning About Physical Dynamics
AAAI 2024[paper]Sadaf Ghaffari and Nikhil Krishnaswamy
-
On Inherent 3D Reasoning of VLMs in Indoor Scene Layout Design
preprint[paper]Kar, Amlan and Acuna, David and Fidler, Sanja
-
Can-Do! A Dataset and Neuro-Symbolic Grounded Framework for Embodied Planning with Large Multimodal Models
arXiv preprint[paper]Chia, Yew Ken and Sun, Qi and Bing, Lidong and Poria, Soujanya
-
Balrog: Benchmarking agentic llm and vlm reasoning on games
ICLR 2025[paper]Paglieri, Davide and Cupia{\l}, Bart{\l}omiej and Coward, Samuel and Piterbarg, Ulyana and Wolczyk, Maciej and Khan, Akbir and Pignatelli, Eduardo and Kuci{'n}ski, {\L}ukasz and Pinto, Lerrel and Fergus, Rob and others
-
DeepPHY: Benchmarking Agentic VLMs on Physical Reasoning
arXiv 2025[paper]Xu, Xinrun and Bu, Pi and Wang, Ye and Karlsson, B{"o}rje F and Wang, Ziming and Song, Tengtao and Zhu, Qi and Song, Jun and Ding, Zhiming and Zheng, Bo
-
Out-of-Distribution Generalization in the ARC-AGI Domain: Comparing Execution-Guided Neural Program Synthesis and Test-Time Fine-Tuning
arXiv 2025[paper]Ouellette, Simon
3D - Real-World
-
Do as i can, not as i say: Grounding language in robotic affordances
CoRL 2022[paper]Ahn, Michael and Brohan, Anthony and Brown, Noah and Chebotar, Yevgen and Cortes, Omar and David, Byron and Finn, Chelsea and Fu, Chuyuan and Gopalakrishnan, Keerthana and Hausman, Karol and others
-
Embodied agent interface: Benchmarking llms for embodied decision making
NeurIPS 2024[paper]Li, Manling and Zhao, Shiyu and Wang, Qineng and Wang, Kangrui and Zhou, Yu and Srivastava, Sanjana and Gokmen, Cem and Lee, Tony and Li, Erran Li and Zhang, Ruohan and others
-
Deploying and evaluating llms to program service mobile robots
IEEE 2024[paper]Hu, Zichao and Lucchetti, Francesca and Schlesinger, Claire and Saxena, Yash and Freeman, Anders and Modak, Sadanand and Guha, Arjun and Biswas, Joydeep
-
Language models as zero-shot planners: Extracting actionable knowledge for embodied agents
ICML 2022[paper]Huang, Wenlong and Abbeel, Pieter and Pathak, Deepak and Mordatch, Igor
-
Robotgpt: Robot manipulation learning from chatgpt
IEEE 2024[paper]Jin, Yixiang and Li, Dingzhe and Yong, A and Shi, Jun and Hao, Peng and Sun, Fuchun and Zhang, Jianwei and Fang, Bin
-
AlphaMaze: Enhancing Large Language Models' Spatial Intelligence via GRPO
arXiv preprint[paper]Dao, Alan and Vu, Dinh Bach
-
A little less conversation, a little more action, please: Investigating the physical common-sense of LLMs in a 3D embodied environment
arXiv preprint[paper]Mecattaf, Matteo G and Slater, Ben and Te{\v{s}}i{'c}, Marko and Prunty, Jonathan and Voudouris, Konstantinos and Cheke, Lucy G
-
Creative robot tool use with large language models
arXiv preprint[paper]Xu, Mengdi and Huang, Peide and Yu, Wenhao and Liu, Shiqi and Zhang, Xilun and Niu, Yaru and Zhang, Tingnan and Xia, Fei and Tan, Jie and Zhao, Ding
-
Spatialvlm: Endowing vision-language models with spatial reasoning capabilities
CVPR 2024[paper]Chen, Boyuan and Xu, Zhuo and Kirmani, Sean and Ichter, Brain and Sadigh, Dorsa and Guibas, Leonidas and Xia, Fei
-
Task-oriented robotic manipulation with vision language models
arXiv preprint[paper]Guran, Nurhan Bulus and Ren, Hanchi and Deng, Jingjing and Xie, Xianghua
-
Code as policies: Language model programs for embodied control
ICRA 2023[paper]Liang, Jacky and Huang, Wenlong and Xia, Fei and Xu, Peng and Hausman, Karol and Ichter, Brian and Florence, Pete and Zeng, Andy
-
Badrobot: Manipulating embodied LLMs in the physical world
ICLR 2025[paper]Zhang, Hangtao and Zhu, Chenyu and Wang, Xianlong and Zhou, Ziqi and Yin, Changgan and Li, Minghui and Xue, Lulu and Wang, Yichen and Hu, Shengshan and Liu, Aishan and others
-
EgoNormia: Benchmarking Physical Social Norm Understanding
arXiv preprint[paper]Rezaei, MohammadHossein and Fu, Yicheng and Cuvin, Phil and Ziems, Caleb and Zhang, Yanzhe and Zhu, Hao and Yang, Diyi
General/Case-by-Case Reasoning Failure Studies
-
Easy Problems That LLMs Get Wrong
arXiv preprint[paper]Williams, Sean and Huckle, James
-
When More Thinking Hurts: Overthinking in LLM Test-Time Compute Scaling
arXiv preprint[paper]Zhou, Shu and Ling, Rui and Chen, Junan and Wang, Xin and Fan, Tao and Wang, Hao
-
Reasoning with Transformer-based Models: Deep Learning, but Shallow Reasoning
AKBC 2022[paper]Helwe, Chadi and Clavel, Chloé and Suchanek, Fabian M.
-
A Categorical Archive of ChatGPT Failures
arXiv preprint[paper]Borji, Ali
-
A Taxonomy of Epistemic Failure Modes in Large Language Models
Preprint 2026[paper]Bosch, Rolando
Citation
If you find our work useful, please consider citing our paper:
@article{songllmreasoningfailures,
  title={Large Language Model Reasoning Failures},
  author={Song, Peiyang and Han, Pengrui and Goodman, Noah},
  journal={Transactions on Machine Learning Research}
}