
🎥 [Awesome] Egocentric / First-Person Video Datasets 📚 Papers, Benchmarks & Resources for Ego Vision
225
38 commits
updated Sep 21, 2026
README
🎥 Awesome Egocentric Video Datasets
📜 A Curated List of Egocentric (First-Person) Video Datasets, Benchmarks, and Tools


Overview
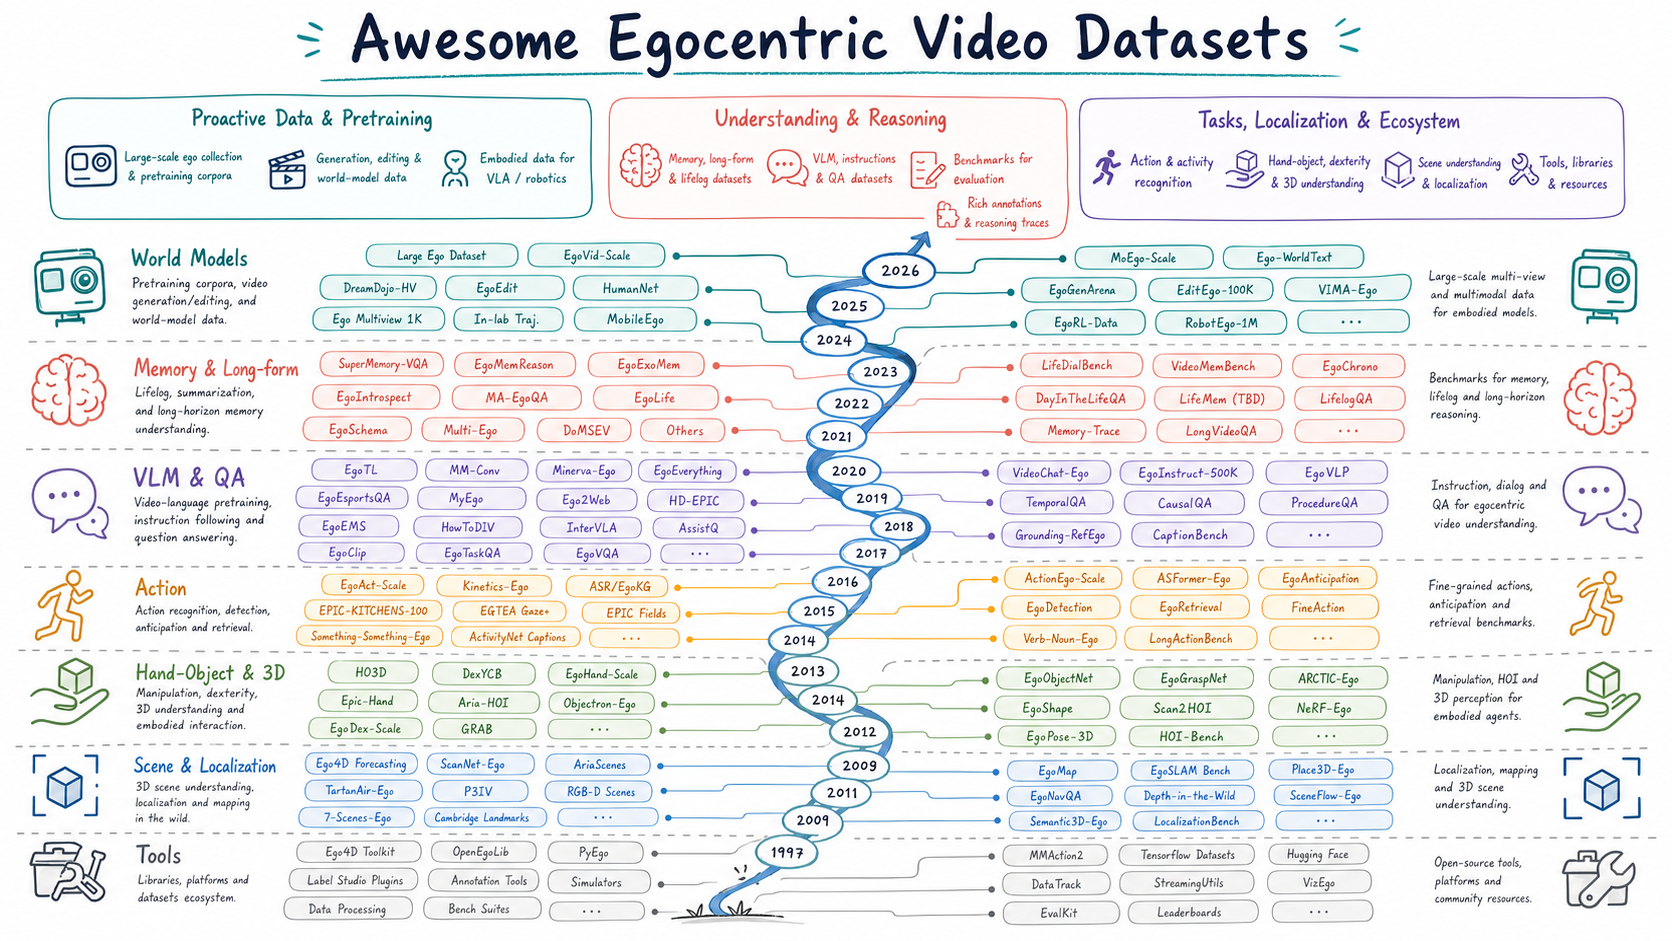
This repository tracks egocentric video datasets through a task-first view: every dataset appears once as a primary entry under one of seven research themes, with cross-links where it also matters. The goal is fast navigation for researchers who need scale, task fit, benchmark context, and official resources without bouncing across multiple index files.
- 📚 Papers & Surveys
- 🎬 Video Generation & World-Model Pretraining
- 🧠 Memory, Summarization & Long-form Understanding
- 💬 VLMs, Instructions & QA
- 🏃 Action & Activity Recognition
- ✋ Hand–Object Interaction, Dexterity & 3D
- 📋 Procedural Activities & Skill Learning
- 🗺️ 3D Scene Understanding & Localization
- 🛠️ Tools & Libraries | 🔗 Related Awesome Lists | 🤝 Contributing | ❤️ Contact | 📄 License
Papers & Surveys
Sorted newest to oldest, with flagship surveys and corpus papers highlighted first.
-
Vision-Language Models for Egocentric Video: From Hand-Object Interaction to Embodied AI (2026) — Survey of egocentric VLMs spanning datasets, hand-object interaction, temporal reasoning, multimodal learning, wearable assistance, and human-to-robot transfer.
-
Position: Life-Logging Video Streams Make the Privacy-Utility Trade-off Inevitable (2026) — Position paper arguing that privacy leakage in always-on wearable video should be evaluated across the full data and model pipeline with standardized metrics and benchmarks.

-
Building Egocentric Procedural AI Assistant: Methods, Benchmarks, and Challenges (2025) — Li et al., 2025 survey and benchmark paper of egocentric procedural activity understanding, focus on building egocentric procedural AI assistant.

-
[⭐️] Challenges and Trends in Egocentric Vision: A Survey (2025) — Li et al., 2025 survey of datasets, tasks, benchmarks, and open challenges in egocentric vision.

-
Bridging Perspectives: A Survey on Cross-view Collaborative Intelligence with Egocentric-Exocentric Vision (2025) — Cross-view survey covering ego-exo collaboration, paired capture, and collaborative perception.

-
HD-EPIC: A Highly-Detailed Egocentric Video Dataset (2025) — Dataset paper introducing fine-grained kitchen understanding with dense multimodal annotations.

-
Ego-Exo4D: Understanding Skilled Human Activity from First- and Third-Person Perspectives (2024) — Large-scale paired ego-exo dataset paper spanning skilled activity and multiview understanding.

-
EgoExoLearn: A Dataset for Bridging Asynchronous Ego- and Exo-centric View of Procedural Activities in Real World (2024) — Procedural ego-exo paper focused on asynchronous activity alignment in real environments.

-
EgoSchema: A Diagnostic Benchmark for Very Long-form Video Language Understanding (2023) — Benchmark paper targeting long-form memory and reasoning over egocentric video.

-
[⭐️] Ego4D: Around the World in 3,000 Hours of Egocentric Video (2022) — Flagship corpus paper introducing the large-scale Ego4D benchmark suite.

-
[⭐️] Rescaling Egocentric Vision: Collection, Pipeline and Challenges for EPIC-KITCHENS-100 (2021) — Canonical kitchen benchmark paper for action recognition, detection, and anticipation.
-
Charades-Ego: A Large-Scale Dataset of Paired Third and First Person Videos (2018) — Early paired ego-exo benchmark for activity transfer and alignment.

🎬 Video Generation & World-Model Pretraining
Datasets here emphasize large-scale first-person pretraining corpora, video generation, editing, or world-model supervision from ego video.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ Ropedia Xperience-10M | 2026 | Large multi-stream experiences | Multimodal ego learning | N/A | Hugging Face |
| WorldRover-10M | 2026 | 6,003 seq. / 21.9M frames / 202.7 h | First-person world models, 3D exploration | Paper | N/A |
| H2R-Bench | 2026 | 6 manipulation families / 2 robot embodiments | Human-to-robot video generation | Paper | N/A |
| Ego-OSCAR-550h | 2026 | ~550 h/camera / 1,462 stereo sessions | Stereo-inertial ego pretraining, capture | Paper | N/A |
| Ego2Robot | 2026 | 18,561 h / 15 robot morphologies | Ego-to-robot data synthesis, VLA pretraining | Paper | Site |
| ACE-Data-0 | 2026 | 150 h / 75K episodes / 200 tasks | Multimodal embodied pretraining | Paper | Site |
| EgoPlay | 2026 | 106K event-triggered clip-prompt pairs | Event-triggered ego video editing | Paper | N/A |
| Open-AoE | 2026 | ~2,000 h / 500+ contributors | Manipulation pretraining, data toolchain | Paper | GitHub |
| EgoVid-Pro | 2026 | 103K clips / ~12M frames | Hand-controlled ego video generation | Paper | N/A |
| RetailSMV | 2026 | 32,105 clips / 16.1K ego + 16.0K exo | Retail world-model adaptation | Paper | Site |
| EgoCS-400K | 2026 | 400K+ videos / 10K h gameplay | Action-conditioned world models | Paper | N/A |
| WM-H (Wh0) | 2026 | 50K generated HOI episodes | Synthetic dexterous VLA data | Paper | Site |
| DreamDojo-HV | 2026 | Very large FP video (see paper) | World models, pretraining | Paper | N/A |
| Ego-1K | 2026 | Multiview clips (~1K takes) | Neural 3D/4D synthesis | Paper | Hugging Face |
| In-lab | 2026 | Lab tabletop trajectories | Skills, world models (w/ DreamDojo) | Paper | N/A |
| HumanNet | 2026 | ~1M h human-centric video (ego + exo) | VLA / embodied pretraining | Paper | N/A |
| MobileEgo Anywhere | 2026 | 200 h smartphone-collected long-horizon ego | Long-horizon ego data infra, VLA | Paper | N/A |
| EgoEdit | 2025 | 100K editing pairs | Egocentric video editing | Paper | Site |
| EgoVid-5M | 2024 | 5M clips | Video generation, motion+text | Paper | Site |
Entries
-
[⭐️] Ropedia Xperience-10M (2026) — 10M multimodal experiences with 6 RGB streams, stereo depth, pose/SLAM, hand-body mocap, audio, and IMU for large-scale ego pretraining.


-
WorldRover-10M (2026) — 6,003 synthetic exploration sequences from 32 environments (21.9M frames / 202.7 h, including 10.8M first-person frames) with first-person, third-person, and 360° views aligned to metric depth, trajectories, geometry, and action signals.
-
H2R-Bench (2026) — Cross-embodiment benchmark for transforming egocentric human demonstrations into robot manipulation videos, evaluated across six manipulation families, two target embodiments, and five dimensions covering execution, contact, embodiment, and visual quality.
-
Ego-OSCAR-550h (2026) — ~550 h per camera (1,462 stereo sessions) of calibrated everyday egocentric video with synchronized IMU, dense open-vocabulary action captions, per-frame 3D hand reconstructions, and an open sub-$200 capture stack.
-
Ego2Robot (2026) — 18,561 h of synthetic robot training data across 15 morphologies, generated from curated and in-the-wild egocentric manipulation video through action retargeting, robot-arm compositing, and multi-level quality curation.
-
ACE-Data-0 (2026) — 150 h and 75K interaction episodes across 200 household task categories, synchronizing ego/exo video, full-body and hand motion, object state, audio, and tactile signals at table and room scale.
-
EgoPlay (2026) — 106K event-triggered egocentric clip-prompt pairs, primarily derived from Ego4D, covering positive, fabricated-negative, and multi-event triggers for temporally restrained video editing and streaming evaluation.
-
Open-AoE (2026) — ~2,000 h of smartphone-collected manipulation video from 500+ contributors with bilingual text, MANO hand pose, camera trajectory, and atomic-action annotations, plus capture-to-training tools for VLA and world-model research.

-
EgoVid-Pro (2026) — 103K in-the-wild egocentric clips (~12M frames) with clean protagonist-only 3D hand trajectories, curated for HandsOnWorld and Plucker Hand Map conditioning in hand-controlled first-person video generation.
-
RetailSMV (2026) — 32,105 captioned retail clips from five supermarkets with synchronized staff-view egocentric and exocentric capture, predefined train/val/test splits, and a held-out protocol for video-world-model adaptation.
-
EgoCS-400K (2026) — 400K+ replay-grounded first-person Counter-Strike videos (10K h) aligned with player states, view directions, movements, keyboard/button inputs, events, and round context for action-conditioned rollout, captioning, and world-model training.
-
WM-H (Wh0) (2026) — 50K world-model-generated egocentric human-object manipulation episodes conditioned on language, objects, and scenes, then converted into robot-trainable supervision for dexterous VLA adaptation.
-
DreamDojo-HV (2026) — Very large FP video (see paper); World models, pretraining.

-
Ego-1K (2026) — Multiview clips (~1K takes); Neural 3D/4D synthesis.

-
In-lab (2026) — Lab tabletop trajectories; Skills, world models (w/ DreamDojo).
-
HumanNet (2026) — ~1M h of human-centric video (mix of ego and exo) with interaction-centric annotations; the authors report 1k h of ego human video outperforms 100 h of real-robot data for VLA training.

-
MobileEgo Anywhere (2026) — 200 h of hour-plus egocentric trajectories collected on commodity smartphones, released with an open-source mobile capture app and a processing pipeline aimed at VLA pretraining.

-
EgoEdit (2025) — 100K editing pairs; Egocentric video editing.

-
EgoVid-5M (2024) — 5M first-person clips curated for text-and-motion-conditioned video generation from wearable footage.

Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| H2R-Bench | Cross-embodiment human-to-robot manipulation video generation | H2R-Bench | Paper | Standalone |
| EgoPlay | Event-triggered editing, pre-trigger preservation, false-trigger robustness | EgoPlay / Ego4D | Paper | Dataset+benchmark |
| ACE-Data-0 | Hierarchical signals-to-scenes-to-interactions evaluation | ACE-Data-0 | Site | Dataset+benchmark |
| Ego2Robot / RoboTwin2.0 extension | OOD visual, spatial, embodiment, and semantic generalization | Ego2Robot | Site | Dataset+benchmark |
| HandsOnWorld / EgoVid-Pro | Camera-disentangled hand-controlled egocentric video generation | EgoVid-Pro | Paper | Dataset+benchmark |
| RetailSMV | Retail video-world-model adaptation and ego/exo viewpoint ablations | RetailSMV | Site | Dataset+benchmark |
| EgoCS-400K | Action-conditioned future prediction, state/event-aware rollout, replay-grounded captioning | EgoCS-400K | Paper | Dataset+benchmark |
| Wh0 / WM-H | Synthetic egocentric dexterous manipulation data for VLA adaptation | WM-H | Site | Dataset+training resource |
| EgoEdit | Egocentric video editing | EgoEdit / EgoEditData | Project | Dataset+benchmark |
🧠 Memory, Summarization & Long-form Understanding
This section collects long-horizon lifelog, summarization, and persistent-memory datasets where temporal continuity matters as much as recognition.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ EgoLife | 2025 | ~266–300 h daily life | Long-form assistants, memory | Paper | Site |
| ⭐ EgoSchema | 2023 | 250+ h / 5K QA | Long-form video QA | Paper | Site |
| EgoMonth | 2026 | 301 h / 738 clips / 1,443 QA | Month-level spatiotemporal memory | Paper | HF |
| MEMORA-Bench | 2026 | 45 h / 18 participants | Embodied action memory, planning | Paper | N/A |
| EgoServe | 2026 | 3K+ service instances / 4 horizons | Proactive continuous-video assistance | Paper | Site |
| SuperMemory-VQA | 2026 | 52.9 h / 4,853 QA | Long-horizon memory VQA | Paper | HF |
| EgoMemReason | 2026 | 500 MCQs over EgoLife | Week-long memory reasoning | Paper | HF |
| EgoExoMem | 2026 | 2.6K MCQs / 390 videos | Cross-view memory reasoning | Paper | GitHub |
| EgoIntrospect | 2026 | 180 h / 60 subjects | Internal-state reasoning, memory | Paper | Site |
| MA-EgoQA | 2026 | 1,741 QA / 6 agents / 7 days | Multi-agent egocentric QA | Paper | Site |
| EgoStream | 2026 | 2,250 Q / 8,528 evals, streams up to 45.3 h | Streaming episodic memory | Paper | Site |
| VidChapters-7M | 2023 | 817K videos / 7M chapters | Chaptering (not ego-only) | Paper | Site |
| Multi-Ego | 2022 | ~12 h / 41 seq. | Multi-wearer, summarization | Paper | GitHub |
| DoMSEV | 2018 | 80 h, 48 seq. | Semantic fast-forward, first-person video | Paper | Site |
| HUJI-EgoSeg | 2014 | 29 long egocentric videos (~1–5 h each), pixel-level temporal segmentation annotations | memory, summarization & long-form understanding | Paper | Site |
| UT Ego | 2012 | ~17 h, 4 long videos | Summarization, long-form ego | Paper | Site |
| VINST / Visual Diaries | 2011 | 31 egocentric videos capturing daily commutes; used for temporal segmentation and video summarization | memory, summarization & long-form understanding | Paper | Site |
Entries
-
[⭐️] EgoLife (2025) — ~266-300 h of daily-life capture in EgoHouse with Meta Aria, third-person cameras, and mmWave sensors for persistent assistant memory.

-
[⭐️] EgoSchema (2023) — 250+ h of long-form Ego4D video with 5K QA pairs designed to probe memory and causal understanding over extended clips.
-
EgoMonth (2026) — 301 h across 738 wearable-camera clips from 20 participants recorded over 20–120 days, paired with 1,443 human-authored questions spanning schema consolidation, episodic indexing, and cascading reasoning.
-
MEMORA-Bench (2026) — 45 h of EPIC-KITCHENS-100 extension video from 18 participants for memory-grounded planning toward seen and unseen goals, plus structured assessment of environment, entity, activity, and inferred-knowledge memory.
-
EgoServe (2026) — 3K+ manually verified proactive-service instances over EgoLife, HoloAssist, and CaptainCook4D, organized into 10 assistance categories and four temporal horizons from instant alerts to multi-day habit coaching.
-
SuperMemory-VQA (2026) — 52.9 h of everyday Meta Aria recordings with RGB, processed gaze, IMU, SLAM trajectories, point clouds, redacted transcripts, and 4,853 human-verified long-horizon memory QA pairs.

-
EgoMemReason (2026) — 500 multiple-choice questions over week-long EgoLife video for entity, event, and behavior memory reasoning, with public questions and leaderboard evaluation.

-
EgoExoMem (2026) — 2.6K human-verified MCQs over 390 synchronized egocentric and exocentric videos from EgoExo4D and LEMMA for cross-view memory reasoning.

-
EgoIntrospect (2026) — 180 h of user-driven egocentric recordings from 60 subjects with synchronized video, audio, gaze, motion, and physiological signals for affective experience, request intent, and cognitive-memory reasoning; the paper states data will be made public.

-
MA-EgoQA (2026) — 1,741 QA pairs over six temporally aligned EgoLife egocentric streams spanning seven days, targeting multi-agent social interaction, task coordination, theory-of-mind, temporal reasoning, and environmental interaction.

-
EgoStream (2026) — 2,250 curated questions expanded to 8,528 recall-conditioned evaluations via Answer Validity Windows over egocentric streams up to 45.3 h (curated from Ego4D, EgoLife, EgoTempo, Multi-Hop EgoQA, and HD-EPIC), spanning seven cognitive memory dimensions for diagnosing streaming episodic memory in video-language models.

-
VidChapters-7M (2023) — 817K videos / 7M chapters; Chaptering (not ego-only).

-
Multi-Ego (2022) — ~12 h / 41 seq; Multi-wearer, summarization.

-
DoMSEV (2018) — 80 h, 48 seq; Semantic fast-forward, first-person video.
-
HUJI-EgoSeg (2014) — 29 long egocentric videos (~1–5 h each), pixel-level temporal segmentation annotations; memory, summarization & long-form understanding.
-
UT Ego (2012) — ~17 h, 4 long videos; Summarization, long-form ego.


-
VINST / Visual Diaries (2011) — 31 egocentric videos capturing daily commutes; used for temporal segmentation and video summarization; memory, summarization & long-form understanding.
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| EgoMonth | Month-level schema, episodic, spatial, and cross-day memory reasoning | EgoMonth | HF | Dataset+benchmark |
| MEMORA-Bench | Embodied action memory formation, consolidation, retrieval, and planning | EPIC-KITCHENS-100 extension | Paper | Standalone |
| EgoServe | Proactive assistance over instant, short-term, episodic, and long-term context | EgoLife / HoloAssist / CaptainCook4D | Site | Standalone |
| SuperMemory-VQA | Long-horizon egocentric memory VQA with answerability checks | SuperMemory-VQA | HF | Dataset+benchmark |
| EgoMemReason | Week-long entity, event, and behavior memory reasoning | EgoLife | HF | Standalone |
| EgoExoMem | Cross-view memory reasoning over synchronized ego-exo videos | EgoExo4D / LEMMA | GitHub | Standalone |
| EgoIntrospect | User internal-state reasoning over multimodal egocentric streams | EgoIntrospect | Site | Dataset+benchmark |
| MA-EgoQA | Multi-agent egocentric video QA over week-long streams | EgoLife | Site | Standalone |
| EgoSchema | Long-form video-language understanding | Ego4D | Site | Standalone |
| EgoStream | Streaming episodic memory diagnosis | Ego4D / EgoLife / EgoTempo / Multi-Hop EgoQA / HD-EPIC | Site | Standalone |
💬 VLMs, Instructions & QA
These datasets target egocentric video-language pretraining, instruction following, dialog, and question answering over first-person streams.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ HD-EPIC | 2025 | ~41 h / dense labels | Fine-grained kitchen, VQA | Paper | Site |
| ⭐ EgoClip | 2022 | 3.8M clip–text pairs | Video-language pretraining | Paper | GitHub |
| CrossView | 2026 | ~6K questions / 4 domains | Multi-camera video QA | Paper | Site |
| EgoCross | 2026 | 798 clips / 957 QA | Cross-domain egocentric VideoQA | Paper | Site |
| HumanCLAW-Bench | 2026 | 1,218 episodes / 41 scenes | Closed-loop embodied action intelligence | Paper | Site |
| EgoSafe-Bench | 2026 | 3K clips / 12K evaluation samples | Visual safety, forensic reasoning | Paper | N/A |
| VIABench | 2026 | 761 videos / 46.9 h / 14.5K annotations | Visual-impairment assistance | Paper | GitHub |
| LongEgoRefer | 2026 | 1,498 refs / avg. 45 min | Long-form video REC, grounding | Paper | GitHub |
| EgoGapBench | 2026 | 1,000 action-selection items | Egocentric action selection | Paper | GitHub |
| EgoSafetyBench | 2026 | 1,200 robot-view scenarios | Streaming safety guards | Paper | N/A |
| EgoSAT | 2026 | 1,997 videos / 165 h / 4.8K QA | Streaming interaction understanding | Paper | Site |
| EgoTL | 2026 | 100+ daily household tasks | Long-horizon reasoning, spatial QA | Paper | Site |
| MM-Conv | 2026 | 6.7 h / 4,211 expressions | Context-aware 3D dialogue grounding | Paper | N/A |
| Minerva-Ego | 2026 | 1,160 QA / 156 videos | Spatiotemporal reasoning traces | Paper | GitHub |
| EgoEverything | 2026 | 100+ h / 5K+ MCQs | Long-context AR VideoQA | Paper | N/A |
| EgoEsportsQA | 2026 | 1,745 QA pairs | Esports VideoQA, reasoning | Paper | N/A |
| GameplayQA | 2026 | ~2.4K QA / 15 task categories | POV-synced multi-video gameplay QA | Paper | Site |
| MyEgo | 2026 | 541 long videos / 5K QA | Personalized VideoQA, ego-grounding | Paper | GitHub |
| LifeDialBench / EgoMem | 2026 | EgoMem + LifeMem (coming soon) | Lifelog memory, online eval | Paper | GitHub |
| Ego2Web | 2026 | 500 video-instruction pairs | Egocentric video-grounded web agents | Paper | HF |
| NoRA | 2026 | 1,420 clips / support graphs | Normative action reasoning | Paper | N/A |
| Causal-Plan-1M | 2026 | 1M QA / 22.2K clips / 770+ h | Physically grounded planning QA | Paper | HF |
| Pause-and-Think | 2026 | 10K QA clips + 300-sample benchmark | Assistive action suggestion | Paper | GitHub |
| EgoCoT-Bench | 2026 | 351 videos / 3,172 QA | Grounded operation-centric CoT QA | Paper | Site |
| EgoEMS | 2025 | 20+ h emergency scenarios | EMS QA, multimodal | Paper | GitHub |
| HowToDIV | 2025 | ~24 h instructional | Dialog, procedural QA | Paper | GitHub |
| InterVLA | 2025 | 11.4 h interactions | Instruction, ego–exo mocap | Paper | Site |
| AssistQ | 2022 | 100 long videos / 529 QA | Instructional QA | Paper | GitHub |
| EgoTaskQA | 2022 | ~2K videos / 40K QA | Causal & task QA | Paper | Site |
| EgoVQA | 2019 | 600+ QAs | Video QA | Paper | N/A |
Entries
-
[⭐️] HD-EPIC (2025) — ~41 h of densely labeled cooking video with recipe steps, audio events, gaze, 3D grounding, and VQA supervision.
-
[⭐️] EgoClip (2022) — 3.8M clip–text pairs; Video-language pretraining.

-
CrossView (2026) — ~6K multi-camera video questions across autonomous driving, surveillance, ego/exo activity, and robotics, including 4–7 synchronized Ego-Exo4D cameras per egocentric question.
-
EgoCross (2026) — 798 clips and 957 human-verified QA pairs across surgery, industrial assembly, extreme sports, and animal perspectives, designed to test cross-domain generalization beyond daily-life egocentric video.
-
HumanCLAW-Bench (2026) — 1,218 long-horizon find–navigate–interact episodes across 41 simulated indoor scenes for evaluating whether VLMs can select and sequence actions from a continuously updated egocentric body view.
-
EgoSafe-Bench (2026) — 12K evaluation samples formed from 3K mobile-captured first-person clips and hierarchical QA chains for feature anchoring, blind-spot deduction, intent inference, and logically consistent visual-safety reasoning.
-
VIABench (2026) — 761 first-person videos (46.9 h) recorded or shared by blind individuals with 14,526 curated annotations for proactive reminders, visual question answering, and vision-guided interaction in online and offline settings.
-
LongEgoRefer (2026) — 1,498 referring expressions over long-form Ego4D videos averaging 45 minutes, requiring temporal and spatial localization of sparse referred objects in untrimmed egocentric recordings.
-
EgoGapBench (2026) — 1,000 egocentric action-selection items from multi-agent scenes without first-person body cues, designed to test whether VLMs choose actions from the correct self/other perspective.
-
EgoSafetyBench (2026) — 1,200 egocentric robot-view scenarios annotated at half-second granularity, split into situational and visual-channel tracks for evaluating runtime VLM safety guards.

-
EgoSAT (2026) — 1,997 Ego4D videos (165 h) with ~4.8K QA pairs for streaming egocentric interaction understanding, covering retrospective, present, and prospective reasoning under partial observability.
-
EgoTL (2026) — 100+ daily household tasks with think-aloud chains, navigation and manipulation annotations, and metric spatial labels for long-horizon egocentric reasoning and QA.

-
MM-Conv (2026) — 6.7 h of egocentric VR interaction with synchronized speech, motion, gaze, 3D scene geometry, and 4,211 verified referring expressions for context-aware conversational grounding; full public release is described as following camera-ready.

-
Minerva-Ego (2026) — 1,160 hand-crafted multiple-choice questions over 156 HD-EPIC egocentric videos, paired with dense spatiotemporal human reasoning traces and object masks for diagnosable video reasoning.

-
EgoEverything (2026) — 100+ h of AR egocentric video with 5K+ multiple-choice questions for human-behavior-inspired long-context video understanding.

-
EgoEsportsQA (2026) — 1,745 expert QA pairs from first-person shooter esports videos for testing fast virtual-scene perception and tactical reasoning.

-
GameplayQA (2026) — ~2.4K QA pairs across 15 task categories and 3 cognitive levels for decision-dense, POV-synced multi-video understanding of multi-agent 3D gameplay, with densely labeled first-person player viewpoints (1.22 labels/sec); egocentric viewpoints are virtual/synthetic. ACL 2026.

-
MyEgo (2026) — 541 long egocentric videos with 5K personalized questions about the camera wearer, their activities, and past context.

-
LifeDialBench / EgoMem (2026) — Lifelog memory benchmark with EgoMem built from real-world egocentric videos and an online evaluation protocol; the project page currently marks the dataset and scripts as coming soon.

-
Ego2Web (2026) — 500 egocentric video-instruction pairs for evaluating web agents that must ground real-world first-person visual context before executing online tasks.

-
NoRA (2026) — 1,420 Ego4D-derived clips (190 human-verified HumanGold + 1,230 LLM-validated LLMSilver) with fact–reason–action support-graph annotations for benchmarking grounded normative action reasoning in VLMs.

-
Causal-Plan-1M (2026) — 1M QA pairs with four-stage causal reasoning-trace annotations over 22,201 egocentric clips (770+ h curated from Ego4D, EPIC-KITCHENS, HoloAssist, MECCANO, and others), plus the 1,200-instance Causal-Plan-Bench for physically grounded embodied planning.

-
Pause-and-Think (2026) — 10,051 reasoning-annotated training QA clips and a 300-sample benchmark curated from EPIC-KITCHENS, Ego4D, and Assembly101 with structured thinking/answer supervision for video-grounded assistive action suggestion and goal planning.

-
EgoCoT-Bench (2026) — 3,172 verifiable QA pairs over 351 first-person videos (sourced from Ego4D, EPIC-KITCHENS, Charades-Ego, MECCANO, and HD-EPIC) with step-by-step rationale annotations for evaluating grounded operation-centric chain-of-thought reasoning in MLLMs.

-
EgoEMS (2025) — 20+ h emergency scenarios; EMS QA, multimodal.

-
HowToDIV (2025) — ~24 h instructional; Dialog, procedural QA.

-
InterVLA (2025) — 11.4 h interactions; Instruction, ego–exo mocap.

-
AssistQ (2022) — 100 long videos / 529 QA; Instructional QA.

-
EgoTaskQA (2022) — ~2K videos / 40K QA; Causal & task QA.

-
EgoVQA (2019) — 600+ QAs; Video QA.

-
EgoSchema — see Memory, Summarization & Long-form Understanding
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| CrossView | Multi-camera evidence integration across four domains | Ego-Exo4D / nuScenes / MEVA / AgiBot | Site | Standalone |
| EgoCross | Cross-domain egocentric VideoQA in surgery, industry, sports, and animal views | EgoCross | Site | Dataset+challenge |
| HumanCLAW-Bench | Closed-loop find–navigate–interact action intelligence | HSSD simulated scenes | Site | Standalone |
| EgoSafe-Bench | Hierarchical visual-safety and forensic reasoning | EgoSafe-Bench | Paper | Dataset+benchmark |
| VIABench | Proactive reminder, VQA, and vision-guided assistance | VIABench | GitHub | Dataset+benchmark |
| LongEgoRefer | Long-form egocentric spatiotemporal referring expression comprehension | Ego4D | GitHub | Standalone |
| EgoGapBench | Egocentric action selection in multi-agent scenes | EgoGapBench | GitHub | Standalone |
| EgoSafetyBench | Runtime safety-guard evaluation over egocentric robot-view video | EgoSafetyBench | Paper | Standalone |
| EgoSAT | Retrospective, present, and prospective streaming VideoQA | Ego4D | Site | Standalone |
| EgoTL-Bench | Long-horizon planning, action reasoning, perceptual-metric understanding | EgoTL | Site | Dataset+benchmark |
| MM-Conv | Context-aware grounding in spontaneous 3D dialogue | MM-Conv | Paper | Dataset+benchmark |
| Minerva-Ego | Egocentric multi-step VideoQA with spatiotemporal reasoning traces | HD-EPIC | GitHub | Standalone |
| EgoEverything | Long-context AR VideoQA | EgoEverything | Paper | Standalone |
| EgoEsportsQA | Esports VideoQA and tactical reasoning | EgoEsportsQA | Paper | Standalone |
| GameplayQA | Decision-dense POV-synced multi-video gameplay QA | GameplayQA | Site | Dataset+benchmark |
| MyEgo | Personalized egocentric VideoQA | MyEgo | GitHub | Dataset+benchmark |
| LifeDialBench / EgoMem | Lifelog memory and online evaluation | EgoMem | GitHub | Dataset+benchmark |
| Ego2Web | Egocentric video-grounded web-agent execution | Ego2Web | Site | Dataset+benchmark |
| EgoExoBench | Cross-perspective video understanding in MLLMs | Ego-Exo4D / LEMMA / EgoExoLearn / TF2023 / EgoMe / CVMHAT | GitHub | Standalone |
| EgoBabyVLM / Machine-DevBench | Cross-modal learning from naturalistic egocentric video | Naturalistic infant/adult ego video corpora | Paper | Standalone |
| EgoEMS | EMS QA, multimodal assessment | EgoEMS | GitHub | Dataset+benchmark |
| HD-EPIC | Fine-grained kitchen understanding, VQA | HD-EPIC | Site | Dataset+benchmark |
| HowToDIV | Multi-turn instructional dialog & QA | HowToDIV | GitHub | Standalone |
| InterVLA | Instruction following, interaction understanding | InterVLA | Site | Dataset+benchmark |
| AssistQ | Instructional affordance-centric QA | AssistQ | GitHub | Standalone |
| EgoTaskQA | Causal, predictive, explanatory, counterfactual QA | EgoTaskQA | Site | Standalone |
| EgoVQA | Egocentric video QA | EgoVQA | Open Access (ICCVW 2019 / EPIC) | Standalone |
| NoRA | Grounded normative action reasoning | Ego4D | Paper | Standalone |
| Causal-Plan-Bench | Physically grounded embodied planning QA | Causal-Plan-1M | HF | Dataset+benchmark |
| Pause-and-Think | Video-grounded assistive action suggestion | EPIC-KITCHENS / Ego4D / Assembly101 | GitHub | Dataset+benchmark |
| EgoCoT-Bench | Grounded operation-centric chain-of-thought QA | Ego4D / EPIC-KITCHENS / Charades-Ego / MECCANO / HD-EPIC | Site | Standalone |
🏃 Action & Activity Recognition
Canonical action-recognition, activity-analysis, affect, and interaction datasets built around first-person human behavior live here.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ Ego4D | 2022 | ~3,670 h | AR, VQA, forecasting, many | Paper | Site |
| ⭐ EPIC-KITCHENS-100 | 2021 | 100 h / 90K segments | Action recognition, many | Paper | Site |
| HUI360 | 2026 | 71 h captured / 11 h filtered / 1M annotations | Human-robot interaction anticipation | Paper | Site |
| EventKitchen | 2026 | 5.5 h / 10.8K action segments | Event-based action recognition, detection | Paper | Site |
| InterPet4D | 2026 | 6.8M frames / 13 dogs / 23 people | Human-pet interaction, motion generation | Paper | Site |
| EgoPolice | 2026 | 180+ h / 9 action classes | Body-camera action recognition, VideoQA | Paper | GitHub |
| ChildLens | 2026 | 108.58 h / 354 videos | Child activity analysis | Paper | Data |
| EgoScale | 2026 | 20k+ h labeled manipulation (paper) | Action, dexterous transfer | Paper | N/A |
| CogDrive (EyeCue) | 2026 | Multi-scenario driving clips | Driver cognitive-distraction detection, gaze + ego | Paper | N/A |
| Ego-METAS | 2026 | 100+ h / 5 modalities | Online action segmentation, sensor routing | Paper | HF |
| Furhat Egocentric Dataset | 2026 | 20 seq. / ~25 min | Robot-ego face/body tracking, re-ID | Paper | N/A |
| World In Your Hands | 2025 | 1000+ h labeled manipulation (paper) | Action, dexterous transfer, VLA training | Paper | GitHub |
| EgoCampus | 2025 | ~32 h / campus paths (paper) | Gaze, pedestrian ego | Paper | GitHub |
| AEA | 2024 | 143 seq. / ~7.3 h | Everyday activities, Aria | Paper | Site |
| EgoSurgery (Phase / Tool / HTS) | 2024 | Open-surgery ego video | Phase, tools, segmentation | Phase / Tool / HTS | GitHub |
| EgoExo-Fitness | 2024 | 32 h / 1,276 seq. | Full-body action, quality assessment | Paper | GitHub |
| E³ (Exploring Embodied Emotion) | 2024 | 50+ h | Emotion, multimodal ego | Paper | GitHub |
| EGOFALLS | 2023 | Fall samples / AV | Fall detection | Paper | Site |
| Epic-Sounding-Object | 2023 | 3.2K short clips | Audio-visual localization | Paper | GitHub |
| HoloAssist | 2023 | 169 h | Interactive assistants | Paper | Site |
| WEAR | 2023 | ~19 h outdoor sports | Activity + IMU | Paper | Site |
| N-EPIC-KITCHENS | 2022 | Event + RGB subset | Action, neuromorphic | Paper | GitHub |
| Ego-Deliver | 2021 | 5,360 videos | Delivery ego analysis | N/A | Site |
| HOMAGE | 2021 | 30 h / compositional | Home activities | Paper | Site |
| MECCANO | 2021 | ~55 h industrial | HOI, ego | Paper | Site |
| EGO-CH | 2020 | 27+ h, cultural sites | Visitor behavior, POI tasks | Paper | N/A |
| EgoCom | 2020 | 38.5 h conversation | Multiperson ego dialog | Paper | GitHub |
| LEMMA | 2020 | Multi-view activities | Multi-agent tasks | Paper | Site |
| Charades-Ego | 2018 | Paired ego / exo | Alignment, actions | Paper | Site |
| EGTEA Gaze+ | 2018 | 28 h cooking | Gaze + action recognition | Paper | Site |
| EgoGesture | 2017 | 2K+ videos / 24K samples | Gesture recognition | Paper | Site |
| Stanford ECM | 2017 | 31 hours, augmented with heart rate and accelerometer, 23–24 daily activity categories | action & activity recognition | Paper | N/A |
| THU-READ | 2017 | 1,920 clips (8 subjects × 40 actions × 3 reps × 2 modalities), RGB-D from helmet-mounted sensor | action & activity recognition | Paper | Site |
| PEV (UTokyo Paired Ego-Video) | 2016 | 1,226 pairs of first-person clips, synchronous dyadic conversations, 8 interaction categories, 6 subjects | action & activity recognition | Paper | N/A |
| FPPA | 2015 | 5 subjects, 5 daily actions, egocentric video with hand and gaze cues | action & activity recognition | Paper | N/A |
| JPL-Interaction | 2013 | 84 videos, 7 activity types (4 positive, 1 neutral, 2 negative interactions), 320×240@30 fps | action & activity recognition | Paper | Site |
| ADL | 2012 | ~10 h, 20 participants | ADL recognition, objects | Paper | Site |
| Social Interactions | 2012 | 8 social events, ~60 hours, head-mounted cameras, multiple participants per event | action & activity recognition | Paper | Site |
| EgoAction | 2011 | First-person sports videos (skateboarding, skiing, cycling, etc | action & activity recognition | Paper | N/A |
Entries
-
[⭐️] Ego4D (2022) — ~3,670 h; AR, VQA, forecasting, many.
-
[⭐️] EPIC-KITCHENS-100 (2021) — 100 h of unscripted kitchen activity with 90K segments; the canonical egocentric action-recognition and anticipation benchmark.
-
HUI360 (2026) — 71 h of in-the-wild 360° robot-egocentric capture (11 h retained for the benchmark) with more than 1M curated pose, face-keypoint, mask, tracking, and interaction annotations for human-robot interaction anticipation.
-
EventKitchen (2026) — 5.5 h of unscripted cooking from 10 participants in 13 kitchens, captured with stereo event cameras plus synchronized RGB, depth, and IMU and annotated with 10,762 action segments and 13,482 object boxes.
-
InterPet4D (2026) — 6.8M synchronized multi-view and egocentric frames from 13 dogs of 11 breeds interacting with 23 people, with audio, segmentation, 2D/3D keypoints, and human, hand, and pet meshes.
-
EgoPolice (2026) — 180+ h of real police body-worn camera footage with second-by-second annotations for nine high-stakes police/civilian action classes, classification folds, and multiple-choice VideoQA.
-
ChildLens (2026) — 108.58 h of child-worn egocentric video and audio from 62 children for activity analysis in everyday home behavior.

-
EgoScale (2026) — 20k+ h labeled manipulation (paper); Action, dexterous transfer.

-
CogDrive (EyeCue) (2026) — Augmented multi-scenario driving dataset paired with the EyeCue gaze-empowered ego-video framework for driver cognitive-distraction detection (reported 74.38% accuracy).

-
Ego-METAS (2026) — 100+ h of untrimmed multimodal egocentric video (RGB, audio, gaze, IMU, monochrome) curated from Ego-Exo4D, CMU-MMAC, and CaptainCook4D with unified splits, pre-extracted features, and baseline sensor-routing policies for online energy-efficient temporal action segmentation.

-
Furhat Egocentric Dataset (2026) — 20 sequences (~25 min) of close-range multi-party interactions captured from a Furhat social robot's egocentric camera with amodal face/body boxes and consistent identities for multi-person tracking and re-identification in HRI; available on request under a Data Usage Agreement.

-
World In Your Hands (2025) — 1000+ h of labeled human manipulation data with video-language annotations for action understanding, dexterous transfer, and VLA training.

-
EgoCampus (2025) — ~32 h / campus paths (paper); Gaze, pedestrian ego.

-
AEA (2024) — 143 seq. / ~7.3 h; Everyday activities, Aria.

-
EgoSurgery (Phase / Tool / HTS) (2024) — Open-surgery ego video with companion phase, tool, and hand-tool segmentation releases for phase recognition, instrument analysis, and dense surgical interaction understanding.


-
EgoExo-Fitness (2024) — 32 h of synchronized egocentric and exocentric fitness video with temporal boundaries, sub-step annotations, action comments, and quality scores for full-body action understanding.

-
E³ (Exploring Embodied Emotion) (2024) — 50+ h; Emotion, multimodal ego.

-
EGOFALLS (2023) — Fall samples / AV; Fall detection.

-
Epic-Sounding-Object (2023) — 3.2K short clips; Audio-visual localization.
-
HoloAssist (2023) — 169 h; Interactive assistants.
-
WEAR (2023) — ~19 h outdoor sports; Activity + IMU.

-
N-EPIC-KITCHENS (2022) — Event + RGB subset; Action, neuromorphic.
-
Ego-Deliver (2021) — 5,360 videos; Delivery ego analysis.
-
HOMAGE (2021) — 30 h / compositional; Home activities.
-
MECCANO (2021) — ~55 h industrial; HOI, ego.
-
EGO-CH (2020) — 27+ h, cultural sites; Visitor behavior, POI tasks.

-
EgoCom (2020) — 38.5 h conversation; Multiperson ego dialog.
-
LEMMA (2020) — Multi-view activities; Multi-agent tasks.

-
Charades-Ego (2018) — Paired ego / exo; Alignment, actions.
-
EGTEA Gaze+ (2018) — 28 h cooking; Gaze + action recognition.
-
EgoGesture (2017) — 2K+ videos / 24K samples; Gesture recognition.
-
Stanford ECM (2017) — 31 hours, augmented with heart rate and accelerometer, 23–24 daily activity categories; action & activity recognition.
-
THU-READ (2017) — 1,920 clips (8 subjects × 40 actions × 3 reps × 2 modalities), RGB-D from helmet-mounted sensor; action & activity recognition.
-
PEV (UTokyo Paired Ego-Video) (2016) — 1,226 pairs of first-person clips, synchronous dyadic conversations, 8 interaction categories, 6 subjects; action & activity recognition.
-
FPPA (2015) — 5 subjects, 5 daily actions, egocentric video with hand and gaze cues; action & activity recognition.
-
JPL-Interaction (2013) — 84 videos, 7 activity types (4 positive, 1 neutral, 2 negative interactions), 320×240@30 fps; action & activity recognition.
-
ADL (2012) — ~10 h, 20 participants; ADL recognition, objects.
-
Social Interactions (2012) — 8 social events, ~60 hours, head-mounted cameras, multiple participants per event; action & activity recognition.
-
EgoAction (2011) — First-person sports videos (skateboarding, skiing, cycling, etc; action & activity recognition.
-
Ego-Exo4D — see 3D Scene Understanding & Localization
-
EgoExoLearn — see Procedural Activities & Skill Learning
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| HUI360 | In-the-wild human-robot interaction anticipation and cross-dataset transfer | HUI360 / SSUP-HRI | Site | Dataset+benchmark |
| EventKitchen | Event-based action recognition, object detection, and stereo depth | EventKitchen | Site | Dataset+benchmark |
| InterPet4D | Multimodal human-pet interaction and pet-motion generation | InterPet4D | Site | Dataset+benchmark |
| EgoPolice | High-stakes action classification and body-camera VideoQA | EgoPolice | GitHub | Dataset+benchmark |
| E³ (Exploring Embodied Emotion) | Emotion recognition, classification, localization, reasoning | E³ | GitHub | Standalone |
| EGOFALLS | Fall detection (visual + audio) | EGOFALLS | Dataverse | Standalone |
| EgoExo-Fitness | Action localization, cross-view verification, skill determination | EgoExo-Fitness | GitHub | Dataset+benchmark |
| Ego4D | Action, forecasting, VQA, narration, … | Ego4D | Site | Suite |
| EPIC-KITCHENS-100 | Action recognition, detection, anticipation, … | EPIC-KITCHENS-100 | Site | Suite |
| EgoGesture | Egocentric hand gesture recognition | EgoGesture | Site | Standalone |
| Ego-METAS | Online energy-efficient temporal action segmentation | Ego-Exo4D / CMU-MMAC / CaptainCook4D | HF | Standalone |
✋ Hand–Object Interaction, Dexterity & 3D
This section focuses on egocentric hands, dexterous manipulation, object interaction, tracking, and dense 3D understanding around the body and manipulated objects.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ HOI4D | 2022 | 2.4M frames / 4K seq. | 4D HOI | Paper | Site |
| ⭐ EgoDex | 2025 | 829 h / 30K trajectories | Dexterous manipulation, pose | Paper | GitHub |
| EgoAffordance | 2026 | 204K episodes / 17.2M affordances | Visual, grasp, trajectory affordances | Paper | Site |
| H-Tac | 2026 | 160 h / 135K episodes | Tactile-action pretraining | Paper | N/A |
| EPIC-Contact | 2026 | 2.3K clips / 62.3K frames | In-the-wild 3D hand-object contact | Paper | Site |
| HT-Bench | 2026 | 10M RGB / 7.8M tactile frames | Full-hand tactile representation | Paper | N/A |
| ForceBand | 2026 | 10 h multimodal force demos | sEMG-to-force, forceful manipulation | Paper | Site |
| EventEgoHands | 2026 | 48 clips / 129.6K frames | RGB+event hand detection | Paper | GitHub |
| EgoTactile | 2026 | ~6 h / 768 clips / 63 objects | Grasp pressure from ego video | Paper | Site |
| EgoDex-R | 2026 | 4.3M RGB-D frames / 5.6K seq. | Dexterous manipulation, hand-object pose | Paper | N/A |
| HA-Ego-1K | 2026 | ~24 h / 484 multi-view clips | Manipulation, 6-cam ego + IMU | N/A | HF |
| DexGloveHOI | 2026 | 3.5 h / 100K+ samples | Vision-IMU 3D hand tracking | Paper | N/A |
| EgoTouch | 2026 | 1,891 episodes / 208 tasks | Tactile HOI, vision-to-touch | Paper | HF |
| EgoEVHands | 2026 | 5,419 annotated seq. | Stereo event 3D hand pose, gesture | Paper | GitHub |
| EgoEMG | 2026 | 41 participants / 10+ h | EMG + vision hand pose | Paper | GitHub |
| HRDexDB | 2026 | 1.4K grasping trials | Dexterous grasping, tactile, ego streams | Paper | HF |
| TouchMoment | 2026 | 4,021 videos / 8,456 touch moments | Contact moment detection | Paper | N/A |
| EgoFun3D | 2026 | 271 egocentric videos | Interactive 3D objects, function templates | Paper | Site |
| SHOW3D | 2026 | In-the-wild ego-exo HOI | 3D hand-object annotations | Paper | N/A |
| FEEL | 2026 | Force-sync kitchen ego video | Physical action understanding | Paper | Site |
| EgoPoints | 2025 | Point tracks + synthetic | Tracking in ego video | Paper | GitHub |
| AssemblyHands | 2023 | 3M images / hands | 3D hand pose, assembly | Paper | Site |
| EgoObjects | 2023 | 9.2K+ videos | Detection, instance seg | Paper | GitHub |
| ENIGMA-51 | 2023 | 22 h industrial | Fine-grained behavior | Paper | Site |
| POV-Surgery | 2023 | ~88K frames, 53 seq. (synth.) | Surgical hand–tool pose, segmentation | Paper | Site |
| VOST | 2023 | 713 videos | VOS, transforming objects | Paper | Site |
| EgoBody | 2022 | 125 seq. / multi-view | Body pose, interaction | Paper | Site |
| EgoHOS | 2022 | 11K+ images | Hand–object segmentation | Paper | GitHub |
| EgoPAT3D | 2022 | 1M+ frames RGB-D | 3D action target prediction | Paper | Site |
| Touch and Go | 2022 | 12K+ vis–tactile frames | Vision + touch | Paper | Site |
| VISOR | 2022 | EPIC + masks / relations | Segmentation, HOI | Paper | Site |
| H2O | 2021 | 100K+ frames | Two-hand interaction | Paper | Site |
| TREK-150 | 2021 | 150 EPIC seq. | Object tracking | Paper | Site |
| You2Me | 2020 | 14 seq., chest-mounted GoPro | Body pose via ego–exo interaction | Paper | GitHub |
| FPHA | 2018 | 1.2K seq. hand action | Hand pose + action | Paper | Site |
| EgoDexter | 2017 | ~3.2K frames, 4 seq. | Hand tracking under occlusion | Paper | Site |
| EgoHands | 2015 | 4.8K labeled frames | Hand detection / boxes | Paper | Site |
| BEOID | 2014 | 58 videos, 6 environments, 34 object interaction classes, ~30 fps | hand–object interaction, dexterity & 3d | Paper | Data |
| EDSH | 2013 | 2 videos (~5 min each), pixel-level hand segmentation, egocentric daily activities | hand–object interaction, dexterity & 3d | Paper | Site |
| Handled Objects | 2009 | 11 object categories, multiple grasp sequences, RGB + depth from wearable camera | hand–object interaction, dexterity & 3d | Paper | N/A |
Entries
-
[⭐️] HOI4D (2022) — 2.4M RGB-D frames with object poses, hand poses, interaction regions, and motion segmentation for category-level 4D HOI.
-
[⭐️] EgoDex (2025) — 829 h / 30K trajectories; Dexterous manipulation, pose.

-
EgoAffordance (2026) — 204K egocentric manipulation episodes with 5.6M visual affordances and 11.6M grasp and trajectory affordances, automatically extracted in a shared 3D actionable representation for VLAff and robot transfer.
-
H-Tac (2026) — 160 h of egocentric human videos with tactile/action data across 300+ tasks and 135K episodes, introduced for human-centric transferable tactile-action pretraining and future tactile prediction.
-
EPIC-Contact (2026) — 2.3K in-the-wild EPIC-KITCHENS stable-grasp clips (62.3K frames) with dense bijective 3D hand-object contact correspondences and posed hand/object meshes for unconstrained 3D HOI pose estimation.
-
HT-Bench (2026) — Large-scale benchmark pairing egocentric vision with full-hand tactile sensing, comprising 10M RGB frames and 7.8M tactile frames across 226 tasks for tactile retrieval, inpainting, vision-to-touch synthesis, and multimodal prediction.
-
ForceBand (2026) — 10 h multimodal dataset with egocentric video, wrist sEMG, IMU, and fingertip force measurements across diverse everyday objects/actions, used to learn EMG-to-force labels for force-augmented robot demonstrations; public dataset release is marked as coming soon.
-
EventEgoHands (2026) — 48 egocentric clips (~1.2 h, 129.6K frames) pairing RGB with synthetic event streams (synthesized from EgoHands via v2e) and 393K hand bounding boxes for RGB-event hand detection under motion blur and low light.

-
EgoTactile (2026) — ~6 h (768 clips, 319K frames) of head- and neck-mounted egocentric video of 12 participants grasping 63 everyday objects with synchronized 162-taxel pressure-glove supervision and a bare-hand transfer subset for full-hand grasp pressure estimation; the dataset currently sits under an anonymous ICML-submission account.

-
EgoDex-R (2026) — 4.3M egocentric RGB-D frames across 5,600 manipulation sequences (1,000+ objects, 200+ daily task categories) with MANO hand poses, 6-DoF object trajectories, reconstructed meshes, and contact annotations, introduced in the EgoAERO paper; distinct from Apple's EgoDex.

-
HA-Ego-1K (2026) — ~24 h of privacy-redacted six-camera + IMU egocentric video (484 multi-view clips across 22 real-world work scenarios such as workshops, construction, and factories) captured with the head-worn Human Archive GSI Cap for dexterous-manipulation and long-horizon task research; gated access (CC BY-NC 4.0), no paper yet.
-
DexGloveHOI (2026) — 3.5 h / 100K+ synchronized egocentric vision-IMU samples with MoCap 3D hand-pose ground truth for dexterous hand-object interaction tracking; no official public data page was found.

-
EgoTouch (2026) — 1,891 bimanual hand-object interaction episodes across 208 manipulation tasks with synchronized egocentric and wrist RGB video, 3D hand pose, and dense tactile pressure maps.

-
EgoEVHands (2026) — 5,419 real-world stereo event-camera egocentric sequences with dense 2D/3D hand keypoints across 38 gesture classes; the official repository currently says code, models, and dataset links are to be uploaded.

-
EgoEMG (2026) — 10+ h of synchronized bilateral EMG, IMU, egocentric RGB, external RGB-D, and mocap-derived hand pose across 41 participants and 60 gesture classes.

-
HRDexDB (2026) — 1.4K dexterous human and robotic hand grasping trials with synchronized multi-view video, egocentric video streams, tactile signals, and 3D motion.

-
TouchMoment (2026) — 4,021 egocentric videos with 8,456 annotated hand-object contact moments for frame-precise touch detection.

-
EgoFun3D (2026) — 271 egocentric interaction videos with paired 3D geometry, 2D/3D segmentation, articulation labels, and function-template annotations.

-
SHOW3D (2026) — In-the-wild ego-exo capture of hands interacting with objects, with 3D hand-object annotations from a marker-less multi-camera system.

-
FEEL (2026) — Force-sync kitchen ego video; Physical action understanding.

-
EgoPoints (2025) — Point tracks + synthetic; Tracking in ego video.

-
AssemblyHands (2023) — 3M egocentric hand images on top of Assembly101 for detailed 3D hand pose estimation during assembly.
-
EgoObjects (2023) — 9.2K+ videos; Detection, instance seg.
-
ENIGMA-51 (2023) — 22 h industrial; Fine-grained behavior.

-
POV-Surgery (2023) — ~88K frames, 53 seq. (synth.); Surgical hand–tool pose, segmentation.

-
VOST (2023) — 713 videos; VOS, transforming objects.

-
EgoBody (2022) — 125 seq. / multi-view; Body pose, interaction.

-
EgoHOS (2022) — 11K+ images; Hand–object segmentation.

-
EgoPAT3D (2022) — 1M+ frames RGB-D; 3D action target prediction.
-
Touch and Go (2022) — 12K+ vis–tactile frames; Vision + touch.

-
VISOR (2022) — EPIC + masks / relations; Segmentation, HOI.

-
H2O (2021) — 100K+ frames; Two-hand interaction.
-
TREK-150 (2021) — 150 EPIC seq; Object tracking.

-
You2Me (2020) — 14 seq., chest-mounted GoPro; Body pose via ego–exo interaction.

-
FPHA (2018) — 1,175 RGB-D sequences with 3D hand pose and action labels; a foundational first-person hand-action benchmark.
-
EgoDexter (2017) — ~3.2K frames, 4 seq; Hand tracking under occlusion.

-
EgoHands (2015) — 4.8K labeled frames; Hand detection / boxes.
-
BEOID (2014) — 58 videos, 6 environments, 34 object interaction classes, ~30 fps; hand–object interaction, dexterity & 3d.

-
EDSH (2013) — 2 videos (~5 min each), pixel-level hand segmentation, egocentric daily activities; hand–object interaction, dexterity & 3d.
-
Handled Objects (2009) — 11 object categories, multiple grasp sequences, RGB + depth from wearable camera; hand–object interaction, dexterity & 3d.
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| EgoAffordance / VLAff | Visual, grasp, and trajectory affordance prediction | EgoAffordance | Site | Dataset+benchmark |
| H-Tac | Human-to-robot tactile-action pretraining and future tactile prediction | H-Tac | Paper | Dataset+pretraining resource |
| EPIC-Contact / HOPformer | In-the-wild egocentric 3D hand-object pose and contact estimation | EPIC-Contact | Site | Dataset+benchmark |
| HT-Bench | Full-hand tactile representation learning with egocentric vision | HT-Bench | Paper | Dataset+benchmark |
| ForceBand / EMG2Force | sEMG-to-fingertip-force prediction and forceful manipulation policy learning | ForceBand | Site | Dataset+benchmark |
| TouchMoment | Frame-precise hand-object contact moment detection | TouchMoment | Paper | Standalone |
| EgoFun3D | Interactive 3D object modeling and function-template inference | EgoFun3D | Site | Dataset+benchmark |
| EgoEMG | EMG-to-pose, vision-to-pose, and EMG+vision fusion | EgoEMG | GitHub | Dataset+benchmark |
| EgoTouch / TouchAnything | Vision-to-touch prediction for bimanual HOI | EgoTouch | HF | Dataset+benchmark |
| DexGloveHOI | Vision-IMU 3D hand tracking under HOI occlusion | DexGloveHOI | Paper | Dataset+benchmark |
| EgoEVHands | Stereo event 3D hand pose and gesture recognition | EgoEVHands | GitHub | Dataset+benchmark |
| AssemblyHands | Egocentric 3D hand pose | Assembly101 | Site | Standalone |
| VISOR | Video object segmentation, hand–object relations | EPIC-KITCHENS | Site | Standalone |
| TREK-150 | Egocentric single-object tracking | EPIC-KITCHENS | Site | Standalone |
| EggHand | Egocentric 3D hand pose forecasting | EgoExo4D | Paper | Method benchmark |
| FPHA | Hand action + 3D hand pose | FPHA | Site | Standalone |
| EgoTactile | Full-hand grasp pressure estimation from ego video | EgoTactile | Site | Dataset+benchmark |
| EventEgoHands | Multimodal RGB-event egocentric hand detection | EventEgoHands (from EgoHands) | GitHub | Dataset+benchmark |
📋 Procedural Activities & Skill Learning
Datasets centered on step structure, instructional execution, assembly, or skill transfer from egocentric experience are grouped here.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ EgoExoLearn | 2024 | 120 h ego+exo | Procedural, async views | Paper | GitHub |
| ⭐ Assembly101 | 2022 | 513 h multiview | Assembly, procedure | Paper | Site |
| EgoProceVQA | 2026 | 3,600 QA / 31 tasks / 4 scenarios | Key-step procedural reasoning | Paper | Site |
| CoMind | 2026 | Dual ego + 2 exo views / 55 environments | Collaborative activity, social reasoning | Paper | Site |
| VLK | 2026 | 48K synthetic paired trajectories | Humanoid loco-manipulation, VLK | Paper | Site |
| EgoVerse | 2026 | 1,362 h / ~80K episodes | Robot learning, manipulation skills | Paper | Site |
| EgoLive | 2026 | Large-scale real-world task routines | Robot manipulation learning | Paper | N/A |
| EgoMAGIC | 2026 | 3,355 videos / 50 medical tasks | Field medicine, action detection | Paper | Zenodo |
| HumanEgo | 2026 | Minutes-per-task Aria demonstrations | Human-to-robot policy learning | Paper | Site |
| EgoSPT | 2026 | 11,515 episodes / 112 task folders | Spatially prompted manipulation trajectories | Paper | HF |
| Ego-EXTRA | 2026 | 50 h / 15K+ VQA | Expert-trainee assistance | Paper | Site |
| GM-100 | 2026 | 100+ tasks / 13K+ trajectories | Robot manipulation, embodied evaluation | Paper | Site |
| SABER | 2026 | 100+ h / 44.8K samples | Retail VLA adaptation | Paper | Site |
| EgoProactive / Pro²Bench | 2026 | 700 recordings (22–55 min) / 42K eval instances | Proactive procedural assistance | Paper | HF |
| EgoYC2 / Exo2EgoDVC | 2025 | ~43 h cooking | Dense captioning, procedural | Paper | GitHub |
| IndustReal | 2024 | ~6 h industrial | Procedure steps, errors | Paper | Site |
| EgoProceL | 2022 | 62 videos / 16 tasks | Procedure learning | Paper | Site |
| EPIC-Tent | 2019 | 7+ h, tent assembly | Procedural, dual HMD + gaze | Paper | Site |
| CMU-MMAC | 2011 | 25 subjects, 5 cooking recipes | procedural activities & skill learning | Paper | Site |
| GTEA Gaze | 2011 | 17 meal preparation sessions, 7 cooking activities, gaze tracking annotations | procedural activities & skill learning | Paper | Site |
Entries
-
[⭐️] EgoExoLearn (2024) — 120 h ego+exo; Procedural, async views.
-
[⭐️] Assembly101 (2022) — 513 h multiview; Assembly, procedure.
-
EgoProceVQA (2026) — 3,600 key-step-centric questions across 31 everyday tasks and four procedural scenarios, covering six question types generated with EgoProceGen and human-checked for procedural reasoning evaluation.
-
CoMind (2026) — Collaborative cooking captured from two synchronized head-mounted cameras and two exocentric views, with audio, gaze, hand/object interactions, social cues, and aligned scans across 55 environments.
-
VLK (2026) — 48K synthetic vision-language-kinematics trajectories rendered as egocentric observations in reconstructed indoor 3DGS scenes, paired with language commands and whole-body humanoid kinematic trajectories for loco-manipulation.
-
EgoVerse (2026) — 1,362 h of egocentric human demonstrations spanning ~80K episodes and 1,965 tasks for robot learning from human manipulation experience.

-
EgoLive (2026) — Large-scale annotated egocentric recordings of real-world human task routines for robot manipulation learning.

-
EgoMAGIC (2026) — 3,355 egocentric field-medicine videos covering 50 medical tasks, with released medical training data and an action-detection challenge.


-
HumanEgo (2026) — Minutes-per-task human egocentric demonstrations collected with Aria glasses for zero-shot human-to-robot manipulation-policy learning via interaction-centric spatial representations.

-
EgoSPT (2026) — 11,515 processed egocentric manipulation episodes for spatially prompted visual trajectory prediction, with RGB video, end-effector poses, gripper widths, and valid-frame masks.

-
Ego-EXTRA (2026) — 50 h of unscripted expert-trainee egocentric procedural assistance across bike workshop, kitchen, bakery, and assembly scenarios, with dialogue transcripts and 15K+ VQA sets.

-
GM-100 (2026) — 100+ detail-oriented robot manipulation tasks with 13K+ teleoperated trajectories and robot first-person camera views for embodied skill evaluation.

-
SABER (2026) — 100+ h of natural in-store retail activity with head-mounted egocentric video, 360-degree exocentric video, and 44.8K action samples for VLA adaptation.

-
EgoProactive / Pro²Bench (2026) — 700 Ray-Ban Meta smart-glasses recordings (22–55 min each) of cooking, crafts, DIY, and tutorial sessions with per-decision-point interrupt/silent labels and Out-of-Plan deviation-recovery annotations for proactive procedural assistance; Pro²Bench unifies five existing egocentric benchmarks into 42K evaluation and 250K training instances.

-
EgoYC2 / Exo2EgoDVC (2025) — ~43 h cooking; Dense captioning, procedural.

-
IndustReal (2024) — ~6 h industrial; Procedure steps, errors.
-
EgoProceL (2022) — 62 videos / 16 tasks; Procedure learning.

-
EPIC-Tent (2019) — 7+ h, tent assembly; Procedural, dual HMD + gaze.
-
CMU-MMAC (2011) — 25 subjects, 5 cooking recipes; procedural activities & skill learning.
-
GTEA Gaze (2011) — 17 meal preparation sessions, 7 cooking activities, gaze tracking annotations; procedural activities & skill learning.
-
Ego-Exo4D — see 3D Scene Understanding & Localization
-
HowToDIV — see VLMs, Instructions & QA
-
ADT (Aria Digital Twin) — see 3D Scene Understanding & Localization
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| EgoProceVQA | Key-step procedural understanding across six QA types | EgoProceVQA | Site | Dataset+benchmark |
| CoMind | Joint attention, socially conditioned interaction anticipation, collaborative handover | CoMind | Site | Dataset+benchmark |
| VLK | Vision-language-kinematics policy learning for humanoid navigation and object transport | Synthetic 3DGS trajectories | Site | Dataset+benchmark |
| HumanEgo | Zero-shot human-to-robot manipulation from egocentric video | HumanEgo | Site | Dataset+benchmark |
| EgoSPT / SP-VTP | Spatially prompted visual trajectory prediction for manipulation | EgoSPT | HF | Dataset+benchmark |
| Ego-EXTRA | Expert-trainee procedural assistance and VQA | Ego-EXTRA | Site | Dataset+benchmark |
| EgoMAGIC | Field-medicine action detection | EgoMAGIC | Zenodo | Dataset+benchmark |
| GM-100 | Detail-oriented robot manipulation evaluation | GM-100 | Site | Dataset+benchmark |
| TAVIS | Active-vision imitation learning on humanoid robots (GR1T2, Reachy2) in IsaacLab; TAVIS-Head + TAVIS-Hands suites with the GALT anticipatory-gaze metric | Simulation-only (no real-data release) | Paper | Standalone benchmark |
| EgoProactive / Pro²Bench | Proactive intervention timing and Out-of-Plan recovery guidance | EgoProactive + Ego4D / EPIC-KITCHENS / Ego-Exo4D / HoloAssist / HowTo100M | HF | Dataset+benchmark |
🗺️ 3D Scene Understanding & Localization
These datasets emphasize geometry, localization, scene graphs, multiview capture, or machine-perception tasks grounded in ego video.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ Ego-Exo4D | 2024 | 1,286+ h ego+exo | Skilled activity, many tasks | Paper | Site |
| ⭐ ADT (Aria Digital Twin) | 2023 | 200 seq., 2 scenes | Egocentric 3D perception | Paper | Site |
| GST-Bench / GST-Train | 2026 | 6,790 min synthetic video | Global spatial awareness from ego video | Paper | N/A |
| FloAff-Kitchen | 2026 | Cross-scene, multi-view kitchen benchmark | Navigation-to-manipulation affordance | Paper | Site |
| EgoHTR | 2026 | 55 seq. / 150K+ frames / 7 scenes | 4D human-terrain reconstruction | Paper | Site |
| SG-Ego | 2026 | 3.8M graphs / 7.3K Ego4D videos | Spatio-temporal scene graphs | Paper | HF |
| PRISM | 2026 | 270K samples / 11.8M frames | Retail embodied VLM, spatial reasoning | Paper | HF |
| EgoTraj | 2026 | 10.7 h / 1.15M frames | Egocentric trajectory prediction | Paper | GitHub |
| AIST-Living | 2026 | Egocentric video + GT motion in scanned env. | Global pose, localization | Paper | Site |
| OVO-S-Bench | 2026 | 348 videos / 1,680 Q / 30 task types | Streaming spatial intelligence QA | Paper | Site |
| PVSG | 2023 | 400 vids, ~150K frames | Panoptic video scene graph (ego + third-person) | Paper | Site |
| DR(eye)VE | 2018 | ~6 h driving, 555K frames | Gaze prediction, driving ego video | Paper | Site |
| EgoCart | 2018 | Retail RGB-D, 9 videos | Indoor / cart localization | Paper | Site |
| IU ShareView | 2018 | 9 paired ego video sets | Person seg / ID across synchronized wearers | Paper | Site |
| OST | 2017 | 57 sequences, 55 subjects, ~15 min/video, egocentric object search tasks, eye-tracking ground truth | 3d scene understanding & localization | Paper | GitHub |
Entries
-
[⭐️] Ego-Exo4D (2024) — 1,286+ h of paired first- and third-person skilled activity with multiview geometry and a broad benchmark suite.
-
[⭐️] ADT (Aria Digital Twin) (2023) — 200 seq., 2 scenes; Egocentric 3D perception.
-
GST-Bench / GST-Train (2026) — Human-verified global-spatial-temporal questions derived from 6,790 minutes of synthetic first-person exploration, requiring novel-view inference and mapping ego observations onto global top-down scenes, plus a companion training set.
-
FloAff-Kitchen (2026) — Cross-scene, multi-view benchmark for predicting where a mobile robot should stand to execute downstream manipulation, spanning varied skills, layouts, furniture styles, and egocentric viewpoints.
-
EgoHTR (2026) — 55 scene-aligned 4D human-terrain traversal sequences (150K+ frames across seven challenging scenes) with ego/exo Aria video, SLAM, IMU, 3D scans, and parametrized human motion for analysis, synthesis, and humanoid locomotion transfer.
-
SG-Ego (2026) — Large-scale spatio-temporal scene-graph annotations extending Ego4D: SG-Ego-Align provides ~3.8M graphs from 7,297 videos, while SG-Ego-Edit adds action-conditioned graph-edit forecasting samples for A-GEF.
-
PRISM (2026) — 270K-sample multi-view retail video SFT corpus with egocentric, exocentric, and 360-degree views for embodied VLM spatial, physical, and action reasoning.

-
EgoTraj (2026) — 10.7 h / 1.15M frames of Meta Quest Pro egocentric urban navigation with synchronized RGB, 6DoF head pose, gaze, and scene annotations for trajectory forecasting; the GitHub README says the dataset and dashboard will be released after publication.

-
AIST-Living (2026) — Dataset introduced with Map-Mono-Ego that pairs monocular egocentric video with ground-truth human motion in a pre-scanned 3D environment for globally consistent pose estimation.

-
OVO-S-Bench (2026) — 1,680 fully human-annotated questions over 348 continuous egocentric streams (indoor walkthroughs, daily activities, outdoor tours, and driving from nine sources) spanning 30 task types across four hierarchical levels, from instantaneous perception to allocentric mapping, for streaming spatial intelligence in multimodal LLMs.

-
PVSG (2023) — 400 vids, ~150K frames; Panoptic video scene graph (ego + third-person).

-
DR(eye)VE (2018) — ~6 h driving, 555K frames; Gaze prediction, driving ego video.

-
EgoCart (2018) — Retail RGB-D, 9 videos; Indoor / cart localization.
-
IU ShareView (2018) — 9 paired ego video sets; Person seg / ID across synchronized wearers.

-
OST (2017) — 57 sequences, 55 subjects, ~15 min/video, egocentric object search tasks, eye-tracking ground truth; 3d scene understanding & localization.
-
Ego-1K — see Video Generation & World-Model Pretraining
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| GST-Bench | Global spatial-temporal VQA and allocentric mapping from ego streams | GST-Bench | Paper | Dataset+benchmark |
| FloAff-Kitchen | Target-conditioned floor-affordance prediction for mobile manipulation | FloAff-Kitchen | Site | Dataset+benchmark |
| EgoHTR | Scene-aligned 4D human motion reconstruction and terrain traversal | EgoHTR | Site | Dataset+benchmark |
| A-GEF / SG-Ego | Action-conditioned scene-graph edit forecasting and graph-text reasoning | SG-Ego | Site | Dataset+benchmark |
| Ego-Exo4D | Ego–exo skill understanding, many tasks | Ego-Exo4D | Site | Suite |
| EgoTraj | Egocentric multimodal trajectory forecasting | EgoTraj | GitHub | Dataset+benchmark |
| EgoProx | Egocentric 3D proximity reasoning VQA | ADT / EgoExo4D | Site | Standalone |
| Map-Mono-Ego | Map-grounded global human pose estimation | AIST-Living | Site | Dataset+benchmark |
| ADT (Aria Digital Twin) | Egocentric 3D machine perception | ADT | Aria | Dataset+benchmark |
| OVO-S-Bench | Streaming spatial intelligence over continuous ego video | Nine egocentric video sources | Site | Standalone |
🛠️ Tools & Libraries
| Name | Description | Link |
|---|---|---|
| Ego4D CLI | Official downloader and tooling for accessing Ego4D releases. | GitHub |
| HOMIE-toolkit | Toolkit released with Ropedia Xperience-10M for large-scale multimodal ego data. | GitHub |
| Open-AoE Toolchain | Smartphone capture, reconstruction, visualization, retargeting, and model-ready conversion for Open-AoE. | GitHub |
| Ego-OSCAR | Open-hardware stereo-inertial capture device and recording stack with a sub-$200 bill of materials. | Paper |
| ego-stereo-cn-v1-tools | Loading + timing verification for the ego-stereo-cn-v1 LeRobot v3 stereo+IMU sample (hardware-synced). | GitHub |
| AssemblyHands Toolkit | Official toolkit for the AssemblyHands benchmark. | GitHub |
| TREK-150 Toolkit | Toolkit for the TREK-150 egocentric tracking benchmark. | GitHub |
🔗 Related Awesome Lists
🤝 Contributing
- Add or update the dataset, benchmark, or survey directly in the matching section of
README.md. - Keep primary entries unique: one full entry under one topic, cross-links everywhere else.
- Preserve newest-to-oldest ordering inside each topic block, with flagship entries kept at the top.
- Follow the detailed checklist in CONTRIBUTING.md before opening a PR.
❤️ Contact
If you have suggestions, dataset updates, or find this project useful, feel free to contact Shen Yujiao at shenyujiao18@gmail.com.
License
CC0 1.0 Universal. See LICENSE.
Contributors


Similar repos


🎥 [Awesome] Egocentric / First-Person Video Datasets 📚 Papers, Benchmarks & Resources for Ego Vision
225
38 commits
updated Sep 21, 2026
README
🎥 Awesome Egocentric Video Datasets
📜 A Curated List of Egocentric (First-Person) Video Datasets, Benchmarks, and Tools
Overview
This repository tracks egocentric video datasets through a task-first view: every dataset appears once as a primary entry under one of seven research themes, with cross-links where it also matters. The goal is fast navigation for researchers who need scale, task fit, benchmark context, and official resources without bouncing across multiple index files.
- 📚 Papers & Surveys
- 🎬 Video Generation & World-Model Pretraining
- 🧠 Memory, Summarization & Long-form Understanding
- 💬 VLMs, Instructions & QA
- 🏃 Action & Activity Recognition
- ✋ Hand–Object Interaction, Dexterity & 3D
- 📋 Procedural Activities & Skill Learning
- 🗺️ 3D Scene Understanding & Localization
- 🛠️ Tools & Libraries | 🔗 Related Awesome Lists | 🤝 Contributing | ❤️ Contact | 📄 License
Papers & Surveys
Sorted newest to oldest, with flagship surveys and corpus papers highlighted first.
-
Vision-Language Models for Egocentric Video: From Hand-Object Interaction to Embodied AI (2026) — Survey of egocentric VLMs spanning datasets, hand-object interaction, temporal reasoning, multimodal learning, wearable assistance, and human-to-robot transfer.
-
Position: Life-Logging Video Streams Make the Privacy-Utility Trade-off Inevitable (2026) — Position paper arguing that privacy leakage in always-on wearable video should be evaluated across the full data and model pipeline with standardized metrics and benchmarks.
-
Building Egocentric Procedural AI Assistant: Methods, Benchmarks, and Challenges (2025) — Li et al., 2025 survey and benchmark paper of egocentric procedural activity understanding, focus on building egocentric procedural AI assistant.
-
[⭐️] Challenges and Trends in Egocentric Vision: A Survey (2025) — Li et al., 2025 survey of datasets, tasks, benchmarks, and open challenges in egocentric vision.
-
Bridging Perspectives: A Survey on Cross-view Collaborative Intelligence with Egocentric-Exocentric Vision (2025) — Cross-view survey covering ego-exo collaboration, paired capture, and collaborative perception.
-
HD-EPIC: A Highly-Detailed Egocentric Video Dataset (2025) — Dataset paper introducing fine-grained kitchen understanding with dense multimodal annotations.
-
Ego-Exo4D: Understanding Skilled Human Activity from First- and Third-Person Perspectives (2024) — Large-scale paired ego-exo dataset paper spanning skilled activity and multiview understanding.
-
EgoExoLearn: A Dataset for Bridging Asynchronous Ego- and Exo-centric View of Procedural Activities in Real World (2024) — Procedural ego-exo paper focused on asynchronous activity alignment in real environments.
-
EgoSchema: A Diagnostic Benchmark for Very Long-form Video Language Understanding (2023) — Benchmark paper targeting long-form memory and reasoning over egocentric video.
-
[⭐️] Ego4D: Around the World in 3,000 Hours of Egocentric Video (2022) — Flagship corpus paper introducing the large-scale Ego4D benchmark suite.
-
[⭐️] Rescaling Egocentric Vision: Collection, Pipeline and Challenges for EPIC-KITCHENS-100 (2021) — Canonical kitchen benchmark paper for action recognition, detection, and anticipation.
-
Charades-Ego: A Large-Scale Dataset of Paired Third and First Person Videos (2018) — Early paired ego-exo benchmark for activity transfer and alignment.
🎬 Video Generation & World-Model Pretraining
Datasets here emphasize large-scale first-person pretraining corpora, video generation, editing, or world-model supervision from ego video.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ Ropedia Xperience-10M | 2026 | Large multi-stream experiences | Multimodal ego learning | N/A | Hugging Face |
| WorldRover-10M | 2026 | 6,003 seq. / 21.9M frames / 202.7 h | First-person world models, 3D exploration | Paper | N/A |
| H2R-Bench | 2026 | 6 manipulation families / 2 robot embodiments | Human-to-robot video generation | Paper | N/A |
| Ego-OSCAR-550h | 2026 | ~550 h/camera / 1,462 stereo sessions | Stereo-inertial ego pretraining, capture | Paper | N/A |
| Ego2Robot | 2026 | 18,561 h / 15 robot morphologies | Ego-to-robot data synthesis, VLA pretraining | Paper | Site |
| ACE-Data-0 | 2026 | 150 h / 75K episodes / 200 tasks | Multimodal embodied pretraining | Paper | Site |
| EgoPlay | 2026 | 106K event-triggered clip-prompt pairs | Event-triggered ego video editing | Paper | N/A |
| Open-AoE | 2026 | ~2,000 h / 500+ contributors | Manipulation pretraining, data toolchain | Paper | GitHub |
| EgoVid-Pro | 2026 | 103K clips / ~12M frames | Hand-controlled ego video generation | Paper | N/A |
| RetailSMV | 2026 | 32,105 clips / 16.1K ego + 16.0K exo | Retail world-model adaptation | Paper | Site |
| EgoCS-400K | 2026 | 400K+ videos / 10K h gameplay | Action-conditioned world models | Paper | N/A |
| WM-H (Wh0) | 2026 | 50K generated HOI episodes | Synthetic dexterous VLA data | Paper | Site |
| DreamDojo-HV | 2026 | Very large FP video (see paper) | World models, pretraining | Paper | N/A |
| Ego-1K | 2026 | Multiview clips (~1K takes) | Neural 3D/4D synthesis | Paper | Hugging Face |
| In-lab | 2026 | Lab tabletop trajectories | Skills, world models (w/ DreamDojo) | Paper | N/A |
| HumanNet | 2026 | ~1M h human-centric video (ego + exo) | VLA / embodied pretraining | Paper | N/A |
| MobileEgo Anywhere | 2026 | 200 h smartphone-collected long-horizon ego | Long-horizon ego data infra, VLA | Paper | N/A |
| EgoEdit | 2025 | 100K editing pairs | Egocentric video editing | Paper | Site |
| EgoVid-5M | 2024 | 5M clips | Video generation, motion+text | Paper | Site |
Entries
-
[⭐️] Ropedia Xperience-10M (2026) — 10M multimodal experiences with 6 RGB streams, stereo depth, pose/SLAM, hand-body mocap, audio, and IMU for large-scale ego pretraining.
-
WorldRover-10M (2026) — 6,003 synthetic exploration sequences from 32 environments (21.9M frames / 202.7 h, including 10.8M first-person frames) with first-person, third-person, and 360° views aligned to metric depth, trajectories, geometry, and action signals.
-
H2R-Bench (2026) — Cross-embodiment benchmark for transforming egocentric human demonstrations into robot manipulation videos, evaluated across six manipulation families, two target embodiments, and five dimensions covering execution, contact, embodiment, and visual quality.
-
Ego-OSCAR-550h (2026) — ~550 h per camera (1,462 stereo sessions) of calibrated everyday egocentric video with synchronized IMU, dense open-vocabulary action captions, per-frame 3D hand reconstructions, and an open sub-$200 capture stack.
-
Ego2Robot (2026) — 18,561 h of synthetic robot training data across 15 morphologies, generated from curated and in-the-wild egocentric manipulation video through action retargeting, robot-arm compositing, and multi-level quality curation.
-
ACE-Data-0 (2026) — 150 h and 75K interaction episodes across 200 household task categories, synchronizing ego/exo video, full-body and hand motion, object state, audio, and tactile signals at table and room scale.
-
EgoPlay (2026) — 106K event-triggered egocentric clip-prompt pairs, primarily derived from Ego4D, covering positive, fabricated-negative, and multi-event triggers for temporally restrained video editing and streaming evaluation.
-
Open-AoE (2026) — ~2,000 h of smartphone-collected manipulation video from 500+ contributors with bilingual text, MANO hand pose, camera trajectory, and atomic-action annotations, plus capture-to-training tools for VLA and world-model research.
-
EgoVid-Pro (2026) — 103K in-the-wild egocentric clips (~12M frames) with clean protagonist-only 3D hand trajectories, curated for HandsOnWorld and Plucker Hand Map conditioning in hand-controlled first-person video generation.
-
RetailSMV (2026) — 32,105 captioned retail clips from five supermarkets with synchronized staff-view egocentric and exocentric capture, predefined train/val/test splits, and a held-out protocol for video-world-model adaptation.
-
EgoCS-400K (2026) — 400K+ replay-grounded first-person Counter-Strike videos (10K h) aligned with player states, view directions, movements, keyboard/button inputs, events, and round context for action-conditioned rollout, captioning, and world-model training.
-
WM-H (Wh0) (2026) — 50K world-model-generated egocentric human-object manipulation episodes conditioned on language, objects, and scenes, then converted into robot-trainable supervision for dexterous VLA adaptation.
-
DreamDojo-HV (2026) — Very large FP video (see paper); World models, pretraining.
-
Ego-1K (2026) — Multiview clips (~1K takes); Neural 3D/4D synthesis.
-
In-lab (2026) — Lab tabletop trajectories; Skills, world models (w/ DreamDojo).
-
HumanNet (2026) — ~1M h of human-centric video (mix of ego and exo) with interaction-centric annotations; the authors report 1k h of ego human video outperforms 100 h of real-robot data for VLA training.
-
MobileEgo Anywhere (2026) — 200 h of hour-plus egocentric trajectories collected on commodity smartphones, released with an open-source mobile capture app and a processing pipeline aimed at VLA pretraining.
-
EgoEdit (2025) — 100K editing pairs; Egocentric video editing.
-
EgoVid-5M (2024) — 5M first-person clips curated for text-and-motion-conditioned video generation from wearable footage.
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| H2R-Bench | Cross-embodiment human-to-robot manipulation video generation | H2R-Bench | Paper | Standalone |
| EgoPlay | Event-triggered editing, pre-trigger preservation, false-trigger robustness | EgoPlay / Ego4D | Paper | Dataset+benchmark |
| ACE-Data-0 | Hierarchical signals-to-scenes-to-interactions evaluation | ACE-Data-0 | Site | Dataset+benchmark |
| Ego2Robot / RoboTwin2.0 extension | OOD visual, spatial, embodiment, and semantic generalization | Ego2Robot | Site | Dataset+benchmark |
| HandsOnWorld / EgoVid-Pro | Camera-disentangled hand-controlled egocentric video generation | EgoVid-Pro | Paper | Dataset+benchmark |
| RetailSMV | Retail video-world-model adaptation and ego/exo viewpoint ablations | RetailSMV | Site | Dataset+benchmark |
| EgoCS-400K | Action-conditioned future prediction, state/event-aware rollout, replay-grounded captioning | EgoCS-400K | Paper | Dataset+benchmark |
| Wh0 / WM-H | Synthetic egocentric dexterous manipulation data for VLA adaptation | WM-H | Site | Dataset+training resource |
| EgoEdit | Egocentric video editing | EgoEdit / EgoEditData | Project | Dataset+benchmark |
🧠 Memory, Summarization & Long-form Understanding
This section collects long-horizon lifelog, summarization, and persistent-memory datasets where temporal continuity matters as much as recognition.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ EgoLife | 2025 | ~266–300 h daily life | Long-form assistants, memory | Paper | Site |
| ⭐ EgoSchema | 2023 | 250+ h / 5K QA | Long-form video QA | Paper | Site |
| EgoMonth | 2026 | 301 h / 738 clips / 1,443 QA | Month-level spatiotemporal memory | Paper | HF |
| MEMORA-Bench | 2026 | 45 h / 18 participants | Embodied action memory, planning | Paper | N/A |
| EgoServe | 2026 | 3K+ service instances / 4 horizons | Proactive continuous-video assistance | Paper | Site |
| SuperMemory-VQA | 2026 | 52.9 h / 4,853 QA | Long-horizon memory VQA | Paper | HF |
| EgoMemReason | 2026 | 500 MCQs over EgoLife | Week-long memory reasoning | Paper | HF |
| EgoExoMem | 2026 | 2.6K MCQs / 390 videos | Cross-view memory reasoning | Paper | GitHub |
| EgoIntrospect | 2026 | 180 h / 60 subjects | Internal-state reasoning, memory | Paper | Site |
| MA-EgoQA | 2026 | 1,741 QA / 6 agents / 7 days | Multi-agent egocentric QA | Paper | Site |
| EgoStream | 2026 | 2,250 Q / 8,528 evals, streams up to 45.3 h | Streaming episodic memory | Paper | Site |
| VidChapters-7M | 2023 | 817K videos / 7M chapters | Chaptering (not ego-only) | Paper | Site |
| Multi-Ego | 2022 | ~12 h / 41 seq. | Multi-wearer, summarization | Paper | GitHub |
| DoMSEV | 2018 | 80 h, 48 seq. | Semantic fast-forward, first-person video | Paper | Site |
| HUJI-EgoSeg | 2014 | 29 long egocentric videos (~1–5 h each), pixel-level temporal segmentation annotations | memory, summarization & long-form understanding | Paper | Site |
| UT Ego | 2012 | ~17 h, 4 long videos | Summarization, long-form ego | Paper | Site |
| VINST / Visual Diaries | 2011 | 31 egocentric videos capturing daily commutes; used for temporal segmentation and video summarization | memory, summarization & long-form understanding | Paper | Site |
Entries
-
[⭐️] EgoLife (2025) — ~266-300 h of daily-life capture in EgoHouse with Meta Aria, third-person cameras, and mmWave sensors for persistent assistant memory.
-
[⭐️] EgoSchema (2023) — 250+ h of long-form Ego4D video with 5K QA pairs designed to probe memory and causal understanding over extended clips.
-
EgoMonth (2026) — 301 h across 738 wearable-camera clips from 20 participants recorded over 20–120 days, paired with 1,443 human-authored questions spanning schema consolidation, episodic indexing, and cascading reasoning.
-
MEMORA-Bench (2026) — 45 h of EPIC-KITCHENS-100 extension video from 18 participants for memory-grounded planning toward seen and unseen goals, plus structured assessment of environment, entity, activity, and inferred-knowledge memory.
-
EgoServe (2026) — 3K+ manually verified proactive-service instances over EgoLife, HoloAssist, and CaptainCook4D, organized into 10 assistance categories and four temporal horizons from instant alerts to multi-day habit coaching.
-
SuperMemory-VQA (2026) — 52.9 h of everyday Meta Aria recordings with RGB, processed gaze, IMU, SLAM trajectories, point clouds, redacted transcripts, and 4,853 human-verified long-horizon memory QA pairs.
-
EgoMemReason (2026) — 500 multiple-choice questions over week-long EgoLife video for entity, event, and behavior memory reasoning, with public questions and leaderboard evaluation.
-
EgoExoMem (2026) — 2.6K human-verified MCQs over 390 synchronized egocentric and exocentric videos from EgoExo4D and LEMMA for cross-view memory reasoning.
-
EgoIntrospect (2026) — 180 h of user-driven egocentric recordings from 60 subjects with synchronized video, audio, gaze, motion, and physiological signals for affective experience, request intent, and cognitive-memory reasoning; the paper states data will be made public.
-
MA-EgoQA (2026) — 1,741 QA pairs over six temporally aligned EgoLife egocentric streams spanning seven days, targeting multi-agent social interaction, task coordination, theory-of-mind, temporal reasoning, and environmental interaction.
-
EgoStream (2026) — 2,250 curated questions expanded to 8,528 recall-conditioned evaluations via Answer Validity Windows over egocentric streams up to 45.3 h (curated from Ego4D, EgoLife, EgoTempo, Multi-Hop EgoQA, and HD-EPIC), spanning seven cognitive memory dimensions for diagnosing streaming episodic memory in video-language models.
-
VidChapters-7M (2023) — 817K videos / 7M chapters; Chaptering (not ego-only).
-
Multi-Ego (2022) — ~12 h / 41 seq; Multi-wearer, summarization.
-
DoMSEV (2018) — 80 h, 48 seq; Semantic fast-forward, first-person video.
-
HUJI-EgoSeg (2014) — 29 long egocentric videos (~1–5 h each), pixel-level temporal segmentation annotations; memory, summarization & long-form understanding.
-
UT Ego (2012) — ~17 h, 4 long videos; Summarization, long-form ego.
-
VINST / Visual Diaries (2011) — 31 egocentric videos capturing daily commutes; used for temporal segmentation and video summarization; memory, summarization & long-form understanding.
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| EgoMonth | Month-level schema, episodic, spatial, and cross-day memory reasoning | EgoMonth | HF | Dataset+benchmark |
| MEMORA-Bench | Embodied action memory formation, consolidation, retrieval, and planning | EPIC-KITCHENS-100 extension | Paper | Standalone |
| EgoServe | Proactive assistance over instant, short-term, episodic, and long-term context | EgoLife / HoloAssist / CaptainCook4D | Site | Standalone |
| SuperMemory-VQA | Long-horizon egocentric memory VQA with answerability checks | SuperMemory-VQA | HF | Dataset+benchmark |
| EgoMemReason | Week-long entity, event, and behavior memory reasoning | EgoLife | HF | Standalone |
| EgoExoMem | Cross-view memory reasoning over synchronized ego-exo videos | EgoExo4D / LEMMA | GitHub | Standalone |
| EgoIntrospect | User internal-state reasoning over multimodal egocentric streams | EgoIntrospect | Site | Dataset+benchmark |
| MA-EgoQA | Multi-agent egocentric video QA over week-long streams | EgoLife | Site | Standalone |
| EgoSchema | Long-form video-language understanding | Ego4D | Site | Standalone |
| EgoStream | Streaming episodic memory diagnosis | Ego4D / EgoLife / EgoTempo / Multi-Hop EgoQA / HD-EPIC | Site | Standalone |
💬 VLMs, Instructions & QA
These datasets target egocentric video-language pretraining, instruction following, dialog, and question answering over first-person streams.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ HD-EPIC | 2025 | ~41 h / dense labels | Fine-grained kitchen, VQA | Paper | Site |
| ⭐ EgoClip | 2022 | 3.8M clip–text pairs | Video-language pretraining | Paper | GitHub |
| CrossView | 2026 | ~6K questions / 4 domains | Multi-camera video QA | Paper | Site |
| EgoCross | 2026 | 798 clips / 957 QA | Cross-domain egocentric VideoQA | Paper | Site |
| HumanCLAW-Bench | 2026 | 1,218 episodes / 41 scenes | Closed-loop embodied action intelligence | Paper | Site |
| EgoSafe-Bench | 2026 | 3K clips / 12K evaluation samples | Visual safety, forensic reasoning | Paper | N/A |
| VIABench | 2026 | 761 videos / 46.9 h / 14.5K annotations | Visual-impairment assistance | Paper | GitHub |
| LongEgoRefer | 2026 | 1,498 refs / avg. 45 min | Long-form video REC, grounding | Paper | GitHub |
| EgoGapBench | 2026 | 1,000 action-selection items | Egocentric action selection | Paper | GitHub |
| EgoSafetyBench | 2026 | 1,200 robot-view scenarios | Streaming safety guards | Paper | N/A |
| EgoSAT | 2026 | 1,997 videos / 165 h / 4.8K QA | Streaming interaction understanding | Paper | Site |
| EgoTL | 2026 | 100+ daily household tasks | Long-horizon reasoning, spatial QA | Paper | Site |
| MM-Conv | 2026 | 6.7 h / 4,211 expressions | Context-aware 3D dialogue grounding | Paper | N/A |
| Minerva-Ego | 2026 | 1,160 QA / 156 videos | Spatiotemporal reasoning traces | Paper | GitHub |
| EgoEverything | 2026 | 100+ h / 5K+ MCQs | Long-context AR VideoQA | Paper | N/A |
| EgoEsportsQA | 2026 | 1,745 QA pairs | Esports VideoQA, reasoning | Paper | N/A |
| GameplayQA | 2026 | ~2.4K QA / 15 task categories | POV-synced multi-video gameplay QA | Paper | Site |
| MyEgo | 2026 | 541 long videos / 5K QA | Personalized VideoQA, ego-grounding | Paper | GitHub |
| LifeDialBench / EgoMem | 2026 | EgoMem + LifeMem (coming soon) | Lifelog memory, online eval | Paper | GitHub |
| Ego2Web | 2026 | 500 video-instruction pairs | Egocentric video-grounded web agents | Paper | HF |
| NoRA | 2026 | 1,420 clips / support graphs | Normative action reasoning | Paper | N/A |
| Causal-Plan-1M | 2026 | 1M QA / 22.2K clips / 770+ h | Physically grounded planning QA | Paper | HF |
| Pause-and-Think | 2026 | 10K QA clips + 300-sample benchmark | Assistive action suggestion | Paper | GitHub |
| EgoCoT-Bench | 2026 | 351 videos / 3,172 QA | Grounded operation-centric CoT QA | Paper | Site |
| EgoEMS | 2025 | 20+ h emergency scenarios | EMS QA, multimodal | Paper | GitHub |
| HowToDIV | 2025 | ~24 h instructional | Dialog, procedural QA | Paper | GitHub |
| InterVLA | 2025 | 11.4 h interactions | Instruction, ego–exo mocap | Paper | Site |
| AssistQ | 2022 | 100 long videos / 529 QA | Instructional QA | Paper | GitHub |
| EgoTaskQA | 2022 | ~2K videos / 40K QA | Causal & task QA | Paper | Site |
| EgoVQA | 2019 | 600+ QAs | Video QA | Paper | N/A |
Entries
-
[⭐️] HD-EPIC (2025) — ~41 h of densely labeled cooking video with recipe steps, audio events, gaze, 3D grounding, and VQA supervision.
-
[⭐️] EgoClip (2022) — 3.8M clip–text pairs; Video-language pretraining.
-
CrossView (2026) — ~6K multi-camera video questions across autonomous driving, surveillance, ego/exo activity, and robotics, including 4–7 synchronized Ego-Exo4D cameras per egocentric question.
-
EgoCross (2026) — 798 clips and 957 human-verified QA pairs across surgery, industrial assembly, extreme sports, and animal perspectives, designed to test cross-domain generalization beyond daily-life egocentric video.
-
HumanCLAW-Bench (2026) — 1,218 long-horizon find–navigate–interact episodes across 41 simulated indoor scenes for evaluating whether VLMs can select and sequence actions from a continuously updated egocentric body view.
-
EgoSafe-Bench (2026) — 12K evaluation samples formed from 3K mobile-captured first-person clips and hierarchical QA chains for feature anchoring, blind-spot deduction, intent inference, and logically consistent visual-safety reasoning.
-
VIABench (2026) — 761 first-person videos (46.9 h) recorded or shared by blind individuals with 14,526 curated annotations for proactive reminders, visual question answering, and vision-guided interaction in online and offline settings.
-
LongEgoRefer (2026) — 1,498 referring expressions over long-form Ego4D videos averaging 45 minutes, requiring temporal and spatial localization of sparse referred objects in untrimmed egocentric recordings.
-
EgoGapBench (2026) — 1,000 egocentric action-selection items from multi-agent scenes without first-person body cues, designed to test whether VLMs choose actions from the correct self/other perspective.
-
EgoSafetyBench (2026) — 1,200 egocentric robot-view scenarios annotated at half-second granularity, split into situational and visual-channel tracks for evaluating runtime VLM safety guards.
-
EgoSAT (2026) — 1,997 Ego4D videos (165 h) with ~4.8K QA pairs for streaming egocentric interaction understanding, covering retrospective, present, and prospective reasoning under partial observability.
-
EgoTL (2026) — 100+ daily household tasks with think-aloud chains, navigation and manipulation annotations, and metric spatial labels for long-horizon egocentric reasoning and QA.
-
MM-Conv (2026) — 6.7 h of egocentric VR interaction with synchronized speech, motion, gaze, 3D scene geometry, and 4,211 verified referring expressions for context-aware conversational grounding; full public release is described as following camera-ready.
-
Minerva-Ego (2026) — 1,160 hand-crafted multiple-choice questions over 156 HD-EPIC egocentric videos, paired with dense spatiotemporal human reasoning traces and object masks for diagnosable video reasoning.
-
EgoEverything (2026) — 100+ h of AR egocentric video with 5K+ multiple-choice questions for human-behavior-inspired long-context video understanding.
-
EgoEsportsQA (2026) — 1,745 expert QA pairs from first-person shooter esports videos for testing fast virtual-scene perception and tactical reasoning.
-
GameplayQA (2026) — ~2.4K QA pairs across 15 task categories and 3 cognitive levels for decision-dense, POV-synced multi-video understanding of multi-agent 3D gameplay, with densely labeled first-person player viewpoints (1.22 labels/sec); egocentric viewpoints are virtual/synthetic. ACL 2026.
-
MyEgo (2026) — 541 long egocentric videos with 5K personalized questions about the camera wearer, their activities, and past context.
-
LifeDialBench / EgoMem (2026) — Lifelog memory benchmark with EgoMem built from real-world egocentric videos and an online evaluation protocol; the project page currently marks the dataset and scripts as coming soon.
-
Ego2Web (2026) — 500 egocentric video-instruction pairs for evaluating web agents that must ground real-world first-person visual context before executing online tasks.
-
NoRA (2026) — 1,420 Ego4D-derived clips (190 human-verified HumanGold + 1,230 LLM-validated LLMSilver) with fact–reason–action support-graph annotations for benchmarking grounded normative action reasoning in VLMs.
-
Causal-Plan-1M (2026) — 1M QA pairs with four-stage causal reasoning-trace annotations over 22,201 egocentric clips (770+ h curated from Ego4D, EPIC-KITCHENS, HoloAssist, MECCANO, and others), plus the 1,200-instance Causal-Plan-Bench for physically grounded embodied planning.
-
Pause-and-Think (2026) — 10,051 reasoning-annotated training QA clips and a 300-sample benchmark curated from EPIC-KITCHENS, Ego4D, and Assembly101 with structured thinking/answer supervision for video-grounded assistive action suggestion and goal planning.
-
EgoCoT-Bench (2026) — 3,172 verifiable QA pairs over 351 first-person videos (sourced from Ego4D, EPIC-KITCHENS, Charades-Ego, MECCANO, and HD-EPIC) with step-by-step rationale annotations for evaluating grounded operation-centric chain-of-thought reasoning in MLLMs.
-
EgoEMS (2025) — 20+ h emergency scenarios; EMS QA, multimodal.
-
HowToDIV (2025) — ~24 h instructional; Dialog, procedural QA.
-
InterVLA (2025) — 11.4 h interactions; Instruction, ego–exo mocap.
-
AssistQ (2022) — 100 long videos / 529 QA; Instructional QA.
-
EgoTaskQA (2022) — ~2K videos / 40K QA; Causal & task QA.
-
EgoVQA (2019) — 600+ QAs; Video QA.
-
EgoSchema — see Memory, Summarization & Long-form Understanding
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| CrossView | Multi-camera evidence integration across four domains | Ego-Exo4D / nuScenes / MEVA / AgiBot | Site | Standalone |
| EgoCross | Cross-domain egocentric VideoQA in surgery, industry, sports, and animal views | EgoCross | Site | Dataset+challenge |
| HumanCLAW-Bench | Closed-loop find–navigate–interact action intelligence | HSSD simulated scenes | Site | Standalone |
| EgoSafe-Bench | Hierarchical visual-safety and forensic reasoning | EgoSafe-Bench | Paper | Dataset+benchmark |
| VIABench | Proactive reminder, VQA, and vision-guided assistance | VIABench | GitHub | Dataset+benchmark |
| LongEgoRefer | Long-form egocentric spatiotemporal referring expression comprehension | Ego4D | GitHub | Standalone |
| EgoGapBench | Egocentric action selection in multi-agent scenes | EgoGapBench | GitHub | Standalone |
| EgoSafetyBench | Runtime safety-guard evaluation over egocentric robot-view video | EgoSafetyBench | Paper | Standalone |
| EgoSAT | Retrospective, present, and prospective streaming VideoQA | Ego4D | Site | Standalone |
| EgoTL-Bench | Long-horizon planning, action reasoning, perceptual-metric understanding | EgoTL | Site | Dataset+benchmark |
| MM-Conv | Context-aware grounding in spontaneous 3D dialogue | MM-Conv | Paper | Dataset+benchmark |
| Minerva-Ego | Egocentric multi-step VideoQA with spatiotemporal reasoning traces | HD-EPIC | GitHub | Standalone |
| EgoEverything | Long-context AR VideoQA | EgoEverything | Paper | Standalone |
| EgoEsportsQA | Esports VideoQA and tactical reasoning | EgoEsportsQA | Paper | Standalone |
| GameplayQA | Decision-dense POV-synced multi-video gameplay QA | GameplayQA | Site | Dataset+benchmark |
| MyEgo | Personalized egocentric VideoQA | MyEgo | GitHub | Dataset+benchmark |
| LifeDialBench / EgoMem | Lifelog memory and online evaluation | EgoMem | GitHub | Dataset+benchmark |
| Ego2Web | Egocentric video-grounded web-agent execution | Ego2Web | Site | Dataset+benchmark |
| EgoExoBench | Cross-perspective video understanding in MLLMs | Ego-Exo4D / LEMMA / EgoExoLearn / TF2023 / EgoMe / CVMHAT | GitHub | Standalone |
| EgoBabyVLM / Machine-DevBench | Cross-modal learning from naturalistic egocentric video | Naturalistic infant/adult ego video corpora | Paper | Standalone |
| EgoEMS | EMS QA, multimodal assessment | EgoEMS | GitHub | Dataset+benchmark |
| HD-EPIC | Fine-grained kitchen understanding, VQA | HD-EPIC | Site | Dataset+benchmark |
| HowToDIV | Multi-turn instructional dialog & QA | HowToDIV | GitHub | Standalone |
| InterVLA | Instruction following, interaction understanding | InterVLA | Site | Dataset+benchmark |
| AssistQ | Instructional affordance-centric QA | AssistQ | GitHub | Standalone |
| EgoTaskQA | Causal, predictive, explanatory, counterfactual QA | EgoTaskQA | Site | Standalone |
| EgoVQA | Egocentric video QA | EgoVQA | Open Access (ICCVW 2019 / EPIC) | Standalone |
| NoRA | Grounded normative action reasoning | Ego4D | Paper | Standalone |
| Causal-Plan-Bench | Physically grounded embodied planning QA | Causal-Plan-1M | HF | Dataset+benchmark |
| Pause-and-Think | Video-grounded assistive action suggestion | EPIC-KITCHENS / Ego4D / Assembly101 | GitHub | Dataset+benchmark |
| EgoCoT-Bench | Grounded operation-centric chain-of-thought QA | Ego4D / EPIC-KITCHENS / Charades-Ego / MECCANO / HD-EPIC | Site | Standalone |
🏃 Action & Activity Recognition
Canonical action-recognition, activity-analysis, affect, and interaction datasets built around first-person human behavior live here.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ Ego4D | 2022 | ~3,670 h | AR, VQA, forecasting, many | Paper | Site |
| ⭐ EPIC-KITCHENS-100 | 2021 | 100 h / 90K segments | Action recognition, many | Paper | Site |
| HUI360 | 2026 | 71 h captured / 11 h filtered / 1M annotations | Human-robot interaction anticipation | Paper | Site |
| EventKitchen | 2026 | 5.5 h / 10.8K action segments | Event-based action recognition, detection | Paper | Site |
| InterPet4D | 2026 | 6.8M frames / 13 dogs / 23 people | Human-pet interaction, motion generation | Paper | Site |
| EgoPolice | 2026 | 180+ h / 9 action classes | Body-camera action recognition, VideoQA | Paper | GitHub |
| ChildLens | 2026 | 108.58 h / 354 videos | Child activity analysis | Paper | Data |
| EgoScale | 2026 | 20k+ h labeled manipulation (paper) | Action, dexterous transfer | Paper | N/A |
| CogDrive (EyeCue) | 2026 | Multi-scenario driving clips | Driver cognitive-distraction detection, gaze + ego | Paper | N/A |
| Ego-METAS | 2026 | 100+ h / 5 modalities | Online action segmentation, sensor routing | Paper | HF |
| Furhat Egocentric Dataset | 2026 | 20 seq. / ~25 min | Robot-ego face/body tracking, re-ID | Paper | N/A |
| World In Your Hands | 2025 | 1000+ h labeled manipulation (paper) | Action, dexterous transfer, VLA training | Paper | GitHub |
| EgoCampus | 2025 | ~32 h / campus paths (paper) | Gaze, pedestrian ego | Paper | GitHub |
| AEA | 2024 | 143 seq. / ~7.3 h | Everyday activities, Aria | Paper | Site |
| EgoSurgery (Phase / Tool / HTS) | 2024 | Open-surgery ego video | Phase, tools, segmentation | Phase / Tool / HTS | GitHub |
| EgoExo-Fitness | 2024 | 32 h / 1,276 seq. | Full-body action, quality assessment | Paper | GitHub |
| E³ (Exploring Embodied Emotion) | 2024 | 50+ h | Emotion, multimodal ego | Paper | GitHub |
| EGOFALLS | 2023 | Fall samples / AV | Fall detection | Paper | Site |
| Epic-Sounding-Object | 2023 | 3.2K short clips | Audio-visual localization | Paper | GitHub |
| HoloAssist | 2023 | 169 h | Interactive assistants | Paper | Site |
| WEAR | 2023 | ~19 h outdoor sports | Activity + IMU | Paper | Site |
| N-EPIC-KITCHENS | 2022 | Event + RGB subset | Action, neuromorphic | Paper | GitHub |
| Ego-Deliver | 2021 | 5,360 videos | Delivery ego analysis | N/A | Site |
| HOMAGE | 2021 | 30 h / compositional | Home activities | Paper | Site |
| MECCANO | 2021 | ~55 h industrial | HOI, ego | Paper | Site |
| EGO-CH | 2020 | 27+ h, cultural sites | Visitor behavior, POI tasks | Paper | N/A |
| EgoCom | 2020 | 38.5 h conversation | Multiperson ego dialog | Paper | GitHub |
| LEMMA | 2020 | Multi-view activities | Multi-agent tasks | Paper | Site |
| Charades-Ego | 2018 | Paired ego / exo | Alignment, actions | Paper | Site |
| EGTEA Gaze+ | 2018 | 28 h cooking | Gaze + action recognition | Paper | Site |
| EgoGesture | 2017 | 2K+ videos / 24K samples | Gesture recognition | Paper | Site |
| Stanford ECM | 2017 | 31 hours, augmented with heart rate and accelerometer, 23–24 daily activity categories | action & activity recognition | Paper | N/A |
| THU-READ | 2017 | 1,920 clips (8 subjects × 40 actions × 3 reps × 2 modalities), RGB-D from helmet-mounted sensor | action & activity recognition | Paper | Site |
| PEV (UTokyo Paired Ego-Video) | 2016 | 1,226 pairs of first-person clips, synchronous dyadic conversations, 8 interaction categories, 6 subjects | action & activity recognition | Paper | N/A |
| FPPA | 2015 | 5 subjects, 5 daily actions, egocentric video with hand and gaze cues | action & activity recognition | Paper | N/A |
| JPL-Interaction | 2013 | 84 videos, 7 activity types (4 positive, 1 neutral, 2 negative interactions), 320×240@30 fps | action & activity recognition | Paper | Site |
| ADL | 2012 | ~10 h, 20 participants | ADL recognition, objects | Paper | Site |
| Social Interactions | 2012 | 8 social events, ~60 hours, head-mounted cameras, multiple participants per event | action & activity recognition | Paper | Site |
| EgoAction | 2011 | First-person sports videos (skateboarding, skiing, cycling, etc | action & activity recognition | Paper | N/A |
Entries
-
[⭐️] Ego4D (2022) — ~3,670 h; AR, VQA, forecasting, many.
-
[⭐️] EPIC-KITCHENS-100 (2021) — 100 h of unscripted kitchen activity with 90K segments; the canonical egocentric action-recognition and anticipation benchmark.
-
HUI360 (2026) — 71 h of in-the-wild 360° robot-egocentric capture (11 h retained for the benchmark) with more than 1M curated pose, face-keypoint, mask, tracking, and interaction annotations for human-robot interaction anticipation.
-
EventKitchen (2026) — 5.5 h of unscripted cooking from 10 participants in 13 kitchens, captured with stereo event cameras plus synchronized RGB, depth, and IMU and annotated with 10,762 action segments and 13,482 object boxes.
-
InterPet4D (2026) — 6.8M synchronized multi-view and egocentric frames from 13 dogs of 11 breeds interacting with 23 people, with audio, segmentation, 2D/3D keypoints, and human, hand, and pet meshes.
-
EgoPolice (2026) — 180+ h of real police body-worn camera footage with second-by-second annotations for nine high-stakes police/civilian action classes, classification folds, and multiple-choice VideoQA.
-
ChildLens (2026) — 108.58 h of child-worn egocentric video and audio from 62 children for activity analysis in everyday home behavior.
-
EgoScale (2026) — 20k+ h labeled manipulation (paper); Action, dexterous transfer.
-
CogDrive (EyeCue) (2026) — Augmented multi-scenario driving dataset paired with the EyeCue gaze-empowered ego-video framework for driver cognitive-distraction detection (reported 74.38% accuracy).
-
Ego-METAS (2026) — 100+ h of untrimmed multimodal egocentric video (RGB, audio, gaze, IMU, monochrome) curated from Ego-Exo4D, CMU-MMAC, and CaptainCook4D with unified splits, pre-extracted features, and baseline sensor-routing policies for online energy-efficient temporal action segmentation.
-
Furhat Egocentric Dataset (2026) — 20 sequences (~25 min) of close-range multi-party interactions captured from a Furhat social robot's egocentric camera with amodal face/body boxes and consistent identities for multi-person tracking and re-identification in HRI; available on request under a Data Usage Agreement.
-
World In Your Hands (2025) — 1000+ h of labeled human manipulation data with video-language annotations for action understanding, dexterous transfer, and VLA training.
-
EgoCampus (2025) — ~32 h / campus paths (paper); Gaze, pedestrian ego.
-
AEA (2024) — 143 seq. / ~7.3 h; Everyday activities, Aria.
-
EgoSurgery (Phase / Tool / HTS) (2024) — Open-surgery ego video with companion phase, tool, and hand-tool segmentation releases for phase recognition, instrument analysis, and dense surgical interaction understanding.
-
EgoExo-Fitness (2024) — 32 h of synchronized egocentric and exocentric fitness video with temporal boundaries, sub-step annotations, action comments, and quality scores for full-body action understanding.
-
E³ (Exploring Embodied Emotion) (2024) — 50+ h; Emotion, multimodal ego.
-
EGOFALLS (2023) — Fall samples / AV; Fall detection.
-
Epic-Sounding-Object (2023) — 3.2K short clips; Audio-visual localization.
-
HoloAssist (2023) — 169 h; Interactive assistants.
-
WEAR (2023) — ~19 h outdoor sports; Activity + IMU.
-
N-EPIC-KITCHENS (2022) — Event + RGB subset; Action, neuromorphic.
-
Ego-Deliver (2021) — 5,360 videos; Delivery ego analysis.
-
HOMAGE (2021) — 30 h / compositional; Home activities.
-
MECCANO (2021) — ~55 h industrial; HOI, ego.
-
EGO-CH (2020) — 27+ h, cultural sites; Visitor behavior, POI tasks.
-
EgoCom (2020) — 38.5 h conversation; Multiperson ego dialog.
-
LEMMA (2020) — Multi-view activities; Multi-agent tasks.
-
Charades-Ego (2018) — Paired ego / exo; Alignment, actions.
-
EGTEA Gaze+ (2018) — 28 h cooking; Gaze + action recognition.
-
EgoGesture (2017) — 2K+ videos / 24K samples; Gesture recognition.
-
Stanford ECM (2017) — 31 hours, augmented with heart rate and accelerometer, 23–24 daily activity categories; action & activity recognition.
-
THU-READ (2017) — 1,920 clips (8 subjects × 40 actions × 3 reps × 2 modalities), RGB-D from helmet-mounted sensor; action & activity recognition.
-
PEV (UTokyo Paired Ego-Video) (2016) — 1,226 pairs of first-person clips, synchronous dyadic conversations, 8 interaction categories, 6 subjects; action & activity recognition.
-
FPPA (2015) — 5 subjects, 5 daily actions, egocentric video with hand and gaze cues; action & activity recognition.
-
JPL-Interaction (2013) — 84 videos, 7 activity types (4 positive, 1 neutral, 2 negative interactions), 320×240@30 fps; action & activity recognition.
-
ADL (2012) — ~10 h, 20 participants; ADL recognition, objects.
-
Social Interactions (2012) — 8 social events, ~60 hours, head-mounted cameras, multiple participants per event; action & activity recognition.
-
EgoAction (2011) — First-person sports videos (skateboarding, skiing, cycling, etc; action & activity recognition.
-
Ego-Exo4D — see 3D Scene Understanding & Localization
-
EgoExoLearn — see Procedural Activities & Skill Learning
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| HUI360 | In-the-wild human-robot interaction anticipation and cross-dataset transfer | HUI360 / SSUP-HRI | Site | Dataset+benchmark |
| EventKitchen | Event-based action recognition, object detection, and stereo depth | EventKitchen | Site | Dataset+benchmark |
| InterPet4D | Multimodal human-pet interaction and pet-motion generation | InterPet4D | Site | Dataset+benchmark |
| EgoPolice | High-stakes action classification and body-camera VideoQA | EgoPolice | GitHub | Dataset+benchmark |
| E³ (Exploring Embodied Emotion) | Emotion recognition, classification, localization, reasoning | E³ | GitHub | Standalone |
| EGOFALLS | Fall detection (visual + audio) | EGOFALLS | Dataverse | Standalone |
| EgoExo-Fitness | Action localization, cross-view verification, skill determination | EgoExo-Fitness | GitHub | Dataset+benchmark |
| Ego4D | Action, forecasting, VQA, narration, … | Ego4D | Site | Suite |
| EPIC-KITCHENS-100 | Action recognition, detection, anticipation, … | EPIC-KITCHENS-100 | Site | Suite |
| EgoGesture | Egocentric hand gesture recognition | EgoGesture | Site | Standalone |
| Ego-METAS | Online energy-efficient temporal action segmentation | Ego-Exo4D / CMU-MMAC / CaptainCook4D | HF | Standalone |
✋ Hand–Object Interaction, Dexterity & 3D
This section focuses on egocentric hands, dexterous manipulation, object interaction, tracking, and dense 3D understanding around the body and manipulated objects.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ HOI4D | 2022 | 2.4M frames / 4K seq. | 4D HOI | Paper | Site |
| ⭐ EgoDex | 2025 | 829 h / 30K trajectories | Dexterous manipulation, pose | Paper | GitHub |
| EgoAffordance | 2026 | 204K episodes / 17.2M affordances | Visual, grasp, trajectory affordances | Paper | Site |
| H-Tac | 2026 | 160 h / 135K episodes | Tactile-action pretraining | Paper | N/A |
| EPIC-Contact | 2026 | 2.3K clips / 62.3K frames | In-the-wild 3D hand-object contact | Paper | Site |
| HT-Bench | 2026 | 10M RGB / 7.8M tactile frames | Full-hand tactile representation | Paper | N/A |
| ForceBand | 2026 | 10 h multimodal force demos | sEMG-to-force, forceful manipulation | Paper | Site |
| EventEgoHands | 2026 | 48 clips / 129.6K frames | RGB+event hand detection | Paper | GitHub |
| EgoTactile | 2026 | ~6 h / 768 clips / 63 objects | Grasp pressure from ego video | Paper | Site |
| EgoDex-R | 2026 | 4.3M RGB-D frames / 5.6K seq. | Dexterous manipulation, hand-object pose | Paper | N/A |
| HA-Ego-1K | 2026 | ~24 h / 484 multi-view clips | Manipulation, 6-cam ego + IMU | N/A | HF |
| DexGloveHOI | 2026 | 3.5 h / 100K+ samples | Vision-IMU 3D hand tracking | Paper | N/A |
| EgoTouch | 2026 | 1,891 episodes / 208 tasks | Tactile HOI, vision-to-touch | Paper | HF |
| EgoEVHands | 2026 | 5,419 annotated seq. | Stereo event 3D hand pose, gesture | Paper | GitHub |
| EgoEMG | 2026 | 41 participants / 10+ h | EMG + vision hand pose | Paper | GitHub |
| HRDexDB | 2026 | 1.4K grasping trials | Dexterous grasping, tactile, ego streams | Paper | HF |
| TouchMoment | 2026 | 4,021 videos / 8,456 touch moments | Contact moment detection | Paper | N/A |
| EgoFun3D | 2026 | 271 egocentric videos | Interactive 3D objects, function templates | Paper | Site |
| SHOW3D | 2026 | In-the-wild ego-exo HOI | 3D hand-object annotations | Paper | N/A |
| FEEL | 2026 | Force-sync kitchen ego video | Physical action understanding | Paper | Site |
| EgoPoints | 2025 | Point tracks + synthetic | Tracking in ego video | Paper | GitHub |
| AssemblyHands | 2023 | 3M images / hands | 3D hand pose, assembly | Paper | Site |
| EgoObjects | 2023 | 9.2K+ videos | Detection, instance seg | Paper | GitHub |
| ENIGMA-51 | 2023 | 22 h industrial | Fine-grained behavior | Paper | Site |
| POV-Surgery | 2023 | ~88K frames, 53 seq. (synth.) | Surgical hand–tool pose, segmentation | Paper | Site |
| VOST | 2023 | 713 videos | VOS, transforming objects | Paper | Site |
| EgoBody | 2022 | 125 seq. / multi-view | Body pose, interaction | Paper | Site |
| EgoHOS | 2022 | 11K+ images | Hand–object segmentation | Paper | GitHub |
| EgoPAT3D | 2022 | 1M+ frames RGB-D | 3D action target prediction | Paper | Site |
| Touch and Go | 2022 | 12K+ vis–tactile frames | Vision + touch | Paper | Site |
| VISOR | 2022 | EPIC + masks / relations | Segmentation, HOI | Paper | Site |
| H2O | 2021 | 100K+ frames | Two-hand interaction | Paper | Site |
| TREK-150 | 2021 | 150 EPIC seq. | Object tracking | Paper | Site |
| You2Me | 2020 | 14 seq., chest-mounted GoPro | Body pose via ego–exo interaction | Paper | GitHub |
| FPHA | 2018 | 1.2K seq. hand action | Hand pose + action | Paper | Site |
| EgoDexter | 2017 | ~3.2K frames, 4 seq. | Hand tracking under occlusion | Paper | Site |
| EgoHands | 2015 | 4.8K labeled frames | Hand detection / boxes | Paper | Site |
| BEOID | 2014 | 58 videos, 6 environments, 34 object interaction classes, ~30 fps | hand–object interaction, dexterity & 3d | Paper | Data |
| EDSH | 2013 | 2 videos (~5 min each), pixel-level hand segmentation, egocentric daily activities | hand–object interaction, dexterity & 3d | Paper | Site |
| Handled Objects | 2009 | 11 object categories, multiple grasp sequences, RGB + depth from wearable camera | hand–object interaction, dexterity & 3d | Paper | N/A |
Entries
-
[⭐️] HOI4D (2022) — 2.4M RGB-D frames with object poses, hand poses, interaction regions, and motion segmentation for category-level 4D HOI.
-
[⭐️] EgoDex (2025) — 829 h / 30K trajectories; Dexterous manipulation, pose.
-
EgoAffordance (2026) — 204K egocentric manipulation episodes with 5.6M visual affordances and 11.6M grasp and trajectory affordances, automatically extracted in a shared 3D actionable representation for VLAff and robot transfer.
-
H-Tac (2026) — 160 h of egocentric human videos with tactile/action data across 300+ tasks and 135K episodes, introduced for human-centric transferable tactile-action pretraining and future tactile prediction.
-
EPIC-Contact (2026) — 2.3K in-the-wild EPIC-KITCHENS stable-grasp clips (62.3K frames) with dense bijective 3D hand-object contact correspondences and posed hand/object meshes for unconstrained 3D HOI pose estimation.
-
HT-Bench (2026) — Large-scale benchmark pairing egocentric vision with full-hand tactile sensing, comprising 10M RGB frames and 7.8M tactile frames across 226 tasks for tactile retrieval, inpainting, vision-to-touch synthesis, and multimodal prediction.
-
ForceBand (2026) — 10 h multimodal dataset with egocentric video, wrist sEMG, IMU, and fingertip force measurements across diverse everyday objects/actions, used to learn EMG-to-force labels for force-augmented robot demonstrations; public dataset release is marked as coming soon.
-
EventEgoHands (2026) — 48 egocentric clips (~1.2 h, 129.6K frames) pairing RGB with synthetic event streams (synthesized from EgoHands via v2e) and 393K hand bounding boxes for RGB-event hand detection under motion blur and low light.
-
EgoTactile (2026) — ~6 h (768 clips, 319K frames) of head- and neck-mounted egocentric video of 12 participants grasping 63 everyday objects with synchronized 162-taxel pressure-glove supervision and a bare-hand transfer subset for full-hand grasp pressure estimation; the dataset currently sits under an anonymous ICML-submission account.
-
EgoDex-R (2026) — 4.3M egocentric RGB-D frames across 5,600 manipulation sequences (1,000+ objects, 200+ daily task categories) with MANO hand poses, 6-DoF object trajectories, reconstructed meshes, and contact annotations, introduced in the EgoAERO paper; distinct from Apple's EgoDex.
-
HA-Ego-1K (2026) — ~24 h of privacy-redacted six-camera + IMU egocentric video (484 multi-view clips across 22 real-world work scenarios such as workshops, construction, and factories) captured with the head-worn Human Archive GSI Cap for dexterous-manipulation and long-horizon task research; gated access (CC BY-NC 4.0), no paper yet.
-
DexGloveHOI (2026) — 3.5 h / 100K+ synchronized egocentric vision-IMU samples with MoCap 3D hand-pose ground truth for dexterous hand-object interaction tracking; no official public data page was found.
-
EgoTouch (2026) — 1,891 bimanual hand-object interaction episodes across 208 manipulation tasks with synchronized egocentric and wrist RGB video, 3D hand pose, and dense tactile pressure maps.
-
EgoEVHands (2026) — 5,419 real-world stereo event-camera egocentric sequences with dense 2D/3D hand keypoints across 38 gesture classes; the official repository currently says code, models, and dataset links are to be uploaded.
-
EgoEMG (2026) — 10+ h of synchronized bilateral EMG, IMU, egocentric RGB, external RGB-D, and mocap-derived hand pose across 41 participants and 60 gesture classes.
-
HRDexDB (2026) — 1.4K dexterous human and robotic hand grasping trials with synchronized multi-view video, egocentric video streams, tactile signals, and 3D motion.
-
TouchMoment (2026) — 4,021 egocentric videos with 8,456 annotated hand-object contact moments for frame-precise touch detection.
-
EgoFun3D (2026) — 271 egocentric interaction videos with paired 3D geometry, 2D/3D segmentation, articulation labels, and function-template annotations.
-
SHOW3D (2026) — In-the-wild ego-exo capture of hands interacting with objects, with 3D hand-object annotations from a marker-less multi-camera system.
-
FEEL (2026) — Force-sync kitchen ego video; Physical action understanding.
-
EgoPoints (2025) — Point tracks + synthetic; Tracking in ego video.
-
AssemblyHands (2023) — 3M egocentric hand images on top of Assembly101 for detailed 3D hand pose estimation during assembly.
-
EgoObjects (2023) — 9.2K+ videos; Detection, instance seg.
-
ENIGMA-51 (2023) — 22 h industrial; Fine-grained behavior.
-
POV-Surgery (2023) — ~88K frames, 53 seq. (synth.); Surgical hand–tool pose, segmentation.
-
VOST (2023) — 713 videos; VOS, transforming objects.
-
EgoBody (2022) — 125 seq. / multi-view; Body pose, interaction.
-
EgoHOS (2022) — 11K+ images; Hand–object segmentation.
-
EgoPAT3D (2022) — 1M+ frames RGB-D; 3D action target prediction.
-
Touch and Go (2022) — 12K+ vis–tactile frames; Vision + touch.
-
VISOR (2022) — EPIC + masks / relations; Segmentation, HOI.
-
H2O (2021) — 100K+ frames; Two-hand interaction.
-
TREK-150 (2021) — 150 EPIC seq; Object tracking.
-
You2Me (2020) — 14 seq., chest-mounted GoPro; Body pose via ego–exo interaction.
-
FPHA (2018) — 1,175 RGB-D sequences with 3D hand pose and action labels; a foundational first-person hand-action benchmark.
-
EgoDexter (2017) — ~3.2K frames, 4 seq; Hand tracking under occlusion.
-
EgoHands (2015) — 4.8K labeled frames; Hand detection / boxes.
-
BEOID (2014) — 58 videos, 6 environments, 34 object interaction classes, ~30 fps; hand–object interaction, dexterity & 3d.
-
EDSH (2013) — 2 videos (~5 min each), pixel-level hand segmentation, egocentric daily activities; hand–object interaction, dexterity & 3d.
-
Handled Objects (2009) — 11 object categories, multiple grasp sequences, RGB + depth from wearable camera; hand–object interaction, dexterity & 3d.
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| EgoAffordance / VLAff | Visual, grasp, and trajectory affordance prediction | EgoAffordance | Site | Dataset+benchmark |
| H-Tac | Human-to-robot tactile-action pretraining and future tactile prediction | H-Tac | Paper | Dataset+pretraining resource |
| EPIC-Contact / HOPformer | In-the-wild egocentric 3D hand-object pose and contact estimation | EPIC-Contact | Site | Dataset+benchmark |
| HT-Bench | Full-hand tactile representation learning with egocentric vision | HT-Bench | Paper | Dataset+benchmark |
| ForceBand / EMG2Force | sEMG-to-fingertip-force prediction and forceful manipulation policy learning | ForceBand | Site | Dataset+benchmark |
| TouchMoment | Frame-precise hand-object contact moment detection | TouchMoment | Paper | Standalone |
| EgoFun3D | Interactive 3D object modeling and function-template inference | EgoFun3D | Site | Dataset+benchmark |
| EgoEMG | EMG-to-pose, vision-to-pose, and EMG+vision fusion | EgoEMG | GitHub | Dataset+benchmark |
| EgoTouch / TouchAnything | Vision-to-touch prediction for bimanual HOI | EgoTouch | HF | Dataset+benchmark |
| DexGloveHOI | Vision-IMU 3D hand tracking under HOI occlusion | DexGloveHOI | Paper | Dataset+benchmark |
| EgoEVHands | Stereo event 3D hand pose and gesture recognition | EgoEVHands | GitHub | Dataset+benchmark |
| AssemblyHands | Egocentric 3D hand pose | Assembly101 | Site | Standalone |
| VISOR | Video object segmentation, hand–object relations | EPIC-KITCHENS | Site | Standalone |
| TREK-150 | Egocentric single-object tracking | EPIC-KITCHENS | Site | Standalone |
| EggHand | Egocentric 3D hand pose forecasting | EgoExo4D | Paper | Method benchmark |
| FPHA | Hand action + 3D hand pose | FPHA | Site | Standalone |
| EgoTactile | Full-hand grasp pressure estimation from ego video | EgoTactile | Site | Dataset+benchmark |
| EventEgoHands | Multimodal RGB-event egocentric hand detection | EventEgoHands (from EgoHands) | GitHub | Dataset+benchmark |
📋 Procedural Activities & Skill Learning
Datasets centered on step structure, instructional execution, assembly, or skill transfer from egocentric experience are grouped here.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ EgoExoLearn | 2024 | 120 h ego+exo | Procedural, async views | Paper | GitHub |
| ⭐ Assembly101 | 2022 | 513 h multiview | Assembly, procedure | Paper | Site |
| EgoProceVQA | 2026 | 3,600 QA / 31 tasks / 4 scenarios | Key-step procedural reasoning | Paper | Site |
| CoMind | 2026 | Dual ego + 2 exo views / 55 environments | Collaborative activity, social reasoning | Paper | Site |
| VLK | 2026 | 48K synthetic paired trajectories | Humanoid loco-manipulation, VLK | Paper | Site |
| EgoVerse | 2026 | 1,362 h / ~80K episodes | Robot learning, manipulation skills | Paper | Site |
| EgoLive | 2026 | Large-scale real-world task routines | Robot manipulation learning | Paper | N/A |
| EgoMAGIC | 2026 | 3,355 videos / 50 medical tasks | Field medicine, action detection | Paper | Zenodo |
| HumanEgo | 2026 | Minutes-per-task Aria demonstrations | Human-to-robot policy learning | Paper | Site |
| EgoSPT | 2026 | 11,515 episodes / 112 task folders | Spatially prompted manipulation trajectories | Paper | HF |
| Ego-EXTRA | 2026 | 50 h / 15K+ VQA | Expert-trainee assistance | Paper | Site |
| GM-100 | 2026 | 100+ tasks / 13K+ trajectories | Robot manipulation, embodied evaluation | Paper | Site |
| SABER | 2026 | 100+ h / 44.8K samples | Retail VLA adaptation | Paper | Site |
| EgoProactive / Pro²Bench | 2026 | 700 recordings (22–55 min) / 42K eval instances | Proactive procedural assistance | Paper | HF |
| EgoYC2 / Exo2EgoDVC | 2025 | ~43 h cooking | Dense captioning, procedural | Paper | GitHub |
| IndustReal | 2024 | ~6 h industrial | Procedure steps, errors | Paper | Site |
| EgoProceL | 2022 | 62 videos / 16 tasks | Procedure learning | Paper | Site |
| EPIC-Tent | 2019 | 7+ h, tent assembly | Procedural, dual HMD + gaze | Paper | Site |
| CMU-MMAC | 2011 | 25 subjects, 5 cooking recipes | procedural activities & skill learning | Paper | Site |
| GTEA Gaze | 2011 | 17 meal preparation sessions, 7 cooking activities, gaze tracking annotations | procedural activities & skill learning | Paper | Site |
Entries
-
[⭐️] EgoExoLearn (2024) — 120 h ego+exo; Procedural, async views.
-
[⭐️] Assembly101 (2022) — 513 h multiview; Assembly, procedure.
-
EgoProceVQA (2026) — 3,600 key-step-centric questions across 31 everyday tasks and four procedural scenarios, covering six question types generated with EgoProceGen and human-checked for procedural reasoning evaluation.
-
CoMind (2026) — Collaborative cooking captured from two synchronized head-mounted cameras and two exocentric views, with audio, gaze, hand/object interactions, social cues, and aligned scans across 55 environments.
-
VLK (2026) — 48K synthetic vision-language-kinematics trajectories rendered as egocentric observations in reconstructed indoor 3DGS scenes, paired with language commands and whole-body humanoid kinematic trajectories for loco-manipulation.
-
EgoVerse (2026) — 1,362 h of egocentric human demonstrations spanning ~80K episodes and 1,965 tasks for robot learning from human manipulation experience.
-
EgoLive (2026) — Large-scale annotated egocentric recordings of real-world human task routines for robot manipulation learning.
-
EgoMAGIC (2026) — 3,355 egocentric field-medicine videos covering 50 medical tasks, with released medical training data and an action-detection challenge.
-
HumanEgo (2026) — Minutes-per-task human egocentric demonstrations collected with Aria glasses for zero-shot human-to-robot manipulation-policy learning via interaction-centric spatial representations.
-
EgoSPT (2026) — 11,515 processed egocentric manipulation episodes for spatially prompted visual trajectory prediction, with RGB video, end-effector poses, gripper widths, and valid-frame masks.
-
Ego-EXTRA (2026) — 50 h of unscripted expert-trainee egocentric procedural assistance across bike workshop, kitchen, bakery, and assembly scenarios, with dialogue transcripts and 15K+ VQA sets.
-
GM-100 (2026) — 100+ detail-oriented robot manipulation tasks with 13K+ teleoperated trajectories and robot first-person camera views for embodied skill evaluation.
-
SABER (2026) — 100+ h of natural in-store retail activity with head-mounted egocentric video, 360-degree exocentric video, and 44.8K action samples for VLA adaptation.
-
EgoProactive / Pro²Bench (2026) — 700 Ray-Ban Meta smart-glasses recordings (22–55 min each) of cooking, crafts, DIY, and tutorial sessions with per-decision-point interrupt/silent labels and Out-of-Plan deviation-recovery annotations for proactive procedural assistance; Pro²Bench unifies five existing egocentric benchmarks into 42K evaluation and 250K training instances.
-
EgoYC2 / Exo2EgoDVC (2025) — ~43 h cooking; Dense captioning, procedural.
-
IndustReal (2024) — ~6 h industrial; Procedure steps, errors.
-
EgoProceL (2022) — 62 videos / 16 tasks; Procedure learning.
-
EPIC-Tent (2019) — 7+ h, tent assembly; Procedural, dual HMD + gaze.
-
CMU-MMAC (2011) — 25 subjects, 5 cooking recipes; procedural activities & skill learning.
-
GTEA Gaze (2011) — 17 meal preparation sessions, 7 cooking activities, gaze tracking annotations; procedural activities & skill learning.
-
Ego-Exo4D — see 3D Scene Understanding & Localization
-
HowToDIV — see VLMs, Instructions & QA
-
ADT (Aria Digital Twin) — see 3D Scene Understanding & Localization
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| EgoProceVQA | Key-step procedural understanding across six QA types | EgoProceVQA | Site | Dataset+benchmark |
| CoMind | Joint attention, socially conditioned interaction anticipation, collaborative handover | CoMind | Site | Dataset+benchmark |
| VLK | Vision-language-kinematics policy learning for humanoid navigation and object transport | Synthetic 3DGS trajectories | Site | Dataset+benchmark |
| HumanEgo | Zero-shot human-to-robot manipulation from egocentric video | HumanEgo | Site | Dataset+benchmark |
| EgoSPT / SP-VTP | Spatially prompted visual trajectory prediction for manipulation | EgoSPT | HF | Dataset+benchmark |
| Ego-EXTRA | Expert-trainee procedural assistance and VQA | Ego-EXTRA | Site | Dataset+benchmark |
| EgoMAGIC | Field-medicine action detection | EgoMAGIC | Zenodo | Dataset+benchmark |
| GM-100 | Detail-oriented robot manipulation evaluation | GM-100 | Site | Dataset+benchmark |
| TAVIS | Active-vision imitation learning on humanoid robots (GR1T2, Reachy2) in IsaacLab; TAVIS-Head + TAVIS-Hands suites with the GALT anticipatory-gaze metric | Simulation-only (no real-data release) | Paper | Standalone benchmark |
| EgoProactive / Pro²Bench | Proactive intervention timing and Out-of-Plan recovery guidance | EgoProactive + Ego4D / EPIC-KITCHENS / Ego-Exo4D / HoloAssist / HowTo100M | HF | Dataset+benchmark |
🗺️ 3D Scene Understanding & Localization
These datasets emphasize geometry, localization, scene graphs, multiview capture, or machine-perception tasks grounded in ego video.
Datasets at a glance
| Name | Year | Scale | Key tasks | Paper | Link |
|---|---|---|---|---|---|
| ⭐ Ego-Exo4D | 2024 | 1,286+ h ego+exo | Skilled activity, many tasks | Paper | Site |
| ⭐ ADT (Aria Digital Twin) | 2023 | 200 seq., 2 scenes | Egocentric 3D perception | Paper | Site |
| GST-Bench / GST-Train | 2026 | 6,790 min synthetic video | Global spatial awareness from ego video | Paper | N/A |
| FloAff-Kitchen | 2026 | Cross-scene, multi-view kitchen benchmark | Navigation-to-manipulation affordance | Paper | Site |
| EgoHTR | 2026 | 55 seq. / 150K+ frames / 7 scenes | 4D human-terrain reconstruction | Paper | Site |
| SG-Ego | 2026 | 3.8M graphs / 7.3K Ego4D videos | Spatio-temporal scene graphs | Paper | HF |
| PRISM | 2026 | 270K samples / 11.8M frames | Retail embodied VLM, spatial reasoning | Paper | HF |
| EgoTraj | 2026 | 10.7 h / 1.15M frames | Egocentric trajectory prediction | Paper | GitHub |
| AIST-Living | 2026 | Egocentric video + GT motion in scanned env. | Global pose, localization | Paper | Site |
| OVO-S-Bench | 2026 | 348 videos / 1,680 Q / 30 task types | Streaming spatial intelligence QA | Paper | Site |
| PVSG | 2023 | 400 vids, ~150K frames | Panoptic video scene graph (ego + third-person) | Paper | Site |
| DR(eye)VE | 2018 | ~6 h driving, 555K frames | Gaze prediction, driving ego video | Paper | Site |
| EgoCart | 2018 | Retail RGB-D, 9 videos | Indoor / cart localization | Paper | Site |
| IU ShareView | 2018 | 9 paired ego video sets | Person seg / ID across synchronized wearers | Paper | Site |
| OST | 2017 | 57 sequences, 55 subjects, ~15 min/video, egocentric object search tasks, eye-tracking ground truth | 3d scene understanding & localization | Paper | GitHub |
Entries
-
[⭐️] Ego-Exo4D (2024) — 1,286+ h of paired first- and third-person skilled activity with multiview geometry and a broad benchmark suite.
-
[⭐️] ADT (Aria Digital Twin) (2023) — 200 seq., 2 scenes; Egocentric 3D perception.
-
GST-Bench / GST-Train (2026) — Human-verified global-spatial-temporal questions derived from 6,790 minutes of synthetic first-person exploration, requiring novel-view inference and mapping ego observations onto global top-down scenes, plus a companion training set.
-
FloAff-Kitchen (2026) — Cross-scene, multi-view benchmark for predicting where a mobile robot should stand to execute downstream manipulation, spanning varied skills, layouts, furniture styles, and egocentric viewpoints.
-
EgoHTR (2026) — 55 scene-aligned 4D human-terrain traversal sequences (150K+ frames across seven challenging scenes) with ego/exo Aria video, SLAM, IMU, 3D scans, and parametrized human motion for analysis, synthesis, and humanoid locomotion transfer.
-
SG-Ego (2026) — Large-scale spatio-temporal scene-graph annotations extending Ego4D: SG-Ego-Align provides ~3.8M graphs from 7,297 videos, while SG-Ego-Edit adds action-conditioned graph-edit forecasting samples for A-GEF.
-
PRISM (2026) — 270K-sample multi-view retail video SFT corpus with egocentric, exocentric, and 360-degree views for embodied VLM spatial, physical, and action reasoning.
-
EgoTraj (2026) — 10.7 h / 1.15M frames of Meta Quest Pro egocentric urban navigation with synchronized RGB, 6DoF head pose, gaze, and scene annotations for trajectory forecasting; the GitHub README says the dataset and dashboard will be released after publication.
-
AIST-Living (2026) — Dataset introduced with Map-Mono-Ego that pairs monocular egocentric video with ground-truth human motion in a pre-scanned 3D environment for globally consistent pose estimation.
-
OVO-S-Bench (2026) — 1,680 fully human-annotated questions over 348 continuous egocentric streams (indoor walkthroughs, daily activities, outdoor tours, and driving from nine sources) spanning 30 task types across four hierarchical levels, from instantaneous perception to allocentric mapping, for streaming spatial intelligence in multimodal LLMs.
-
PVSG (2023) — 400 vids, ~150K frames; Panoptic video scene graph (ego + third-person).
-
DR(eye)VE (2018) — ~6 h driving, 555K frames; Gaze prediction, driving ego video.
-
EgoCart (2018) — Retail RGB-D, 9 videos; Indoor / cart localization.
-
IU ShareView (2018) — 9 paired ego video sets; Person seg / ID across synchronized wearers.
-
OST (2017) — 57 sequences, 55 subjects, ~15 min/video, egocentric object search tasks, eye-tracking ground truth; 3d scene understanding & localization.
-
Ego-1K — see Video Generation & World-Model Pretraining
Benchmarks built on these datasets
| Benchmark | Capability | Primary data | Official link | Notes |
|---|---|---|---|---|
| GST-Bench | Global spatial-temporal VQA and allocentric mapping from ego streams | GST-Bench | Paper | Dataset+benchmark |
| FloAff-Kitchen | Target-conditioned floor-affordance prediction for mobile manipulation | FloAff-Kitchen | Site | Dataset+benchmark |
| EgoHTR | Scene-aligned 4D human motion reconstruction and terrain traversal | EgoHTR | Site | Dataset+benchmark |
| A-GEF / SG-Ego | Action-conditioned scene-graph edit forecasting and graph-text reasoning | SG-Ego | Site | Dataset+benchmark |
| Ego-Exo4D | Ego–exo skill understanding, many tasks | Ego-Exo4D | Site | Suite |
| EgoTraj | Egocentric multimodal trajectory forecasting | EgoTraj | GitHub | Dataset+benchmark |
| EgoProx | Egocentric 3D proximity reasoning VQA | ADT / EgoExo4D | Site | Standalone |
| Map-Mono-Ego | Map-grounded global human pose estimation | AIST-Living | Site | Dataset+benchmark |
| ADT (Aria Digital Twin) | Egocentric 3D machine perception | ADT | Aria | Dataset+benchmark |
| OVO-S-Bench | Streaming spatial intelligence over continuous ego video | Nine egocentric video sources | Site | Standalone |
🛠️ Tools & Libraries
| Name | Description | Link |
|---|---|---|
| Ego4D CLI | Official downloader and tooling for accessing Ego4D releases. | GitHub |
| HOMIE-toolkit | Toolkit released with Ropedia Xperience-10M for large-scale multimodal ego data. | GitHub |
| Open-AoE Toolchain | Smartphone capture, reconstruction, visualization, retargeting, and model-ready conversion for Open-AoE. | GitHub |
| Ego-OSCAR | Open-hardware stereo-inertial capture device and recording stack with a sub-$200 bill of materials. | Paper |
| ego-stereo-cn-v1-tools | Loading + timing verification for the ego-stereo-cn-v1 LeRobot v3 stereo+IMU sample (hardware-synced). | GitHub |
| AssemblyHands Toolkit | Official toolkit for the AssemblyHands benchmark. | GitHub |
| TREK-150 Toolkit | Toolkit for the TREK-150 egocentric tracking benchmark. | GitHub |
🔗 Related Awesome Lists
🤝 Contributing
- Add or update the dataset, benchmark, or survey directly in the matching section of
README.md. - Keep primary entries unique: one full entry under one topic, cross-links everywhere else.
- Preserve newest-to-oldest ordering inside each topic block, with flagship entries kept at the top.
- Follow the detailed checklist in CONTRIBUTING.md before opening a PR.
❤️ Contact
If you have suggestions, dataset updates, or find this project useful, feel free to contact Shen Yujiao at shenyujiao18@gmail.com.
License
CC0 1.0 Universal. See LICENSE.