
[TPAMI 2025] Towards Visual Grounding: A Survey
See the codeREADME


Towards Visual Grounding: A Survey
Accepted by TPAMI, 2025
Linhui Xiao
·
Xiaoshan Yang
·
Xiangyuan Lan
·
Yaowei Wang
·
Changsheng Xu


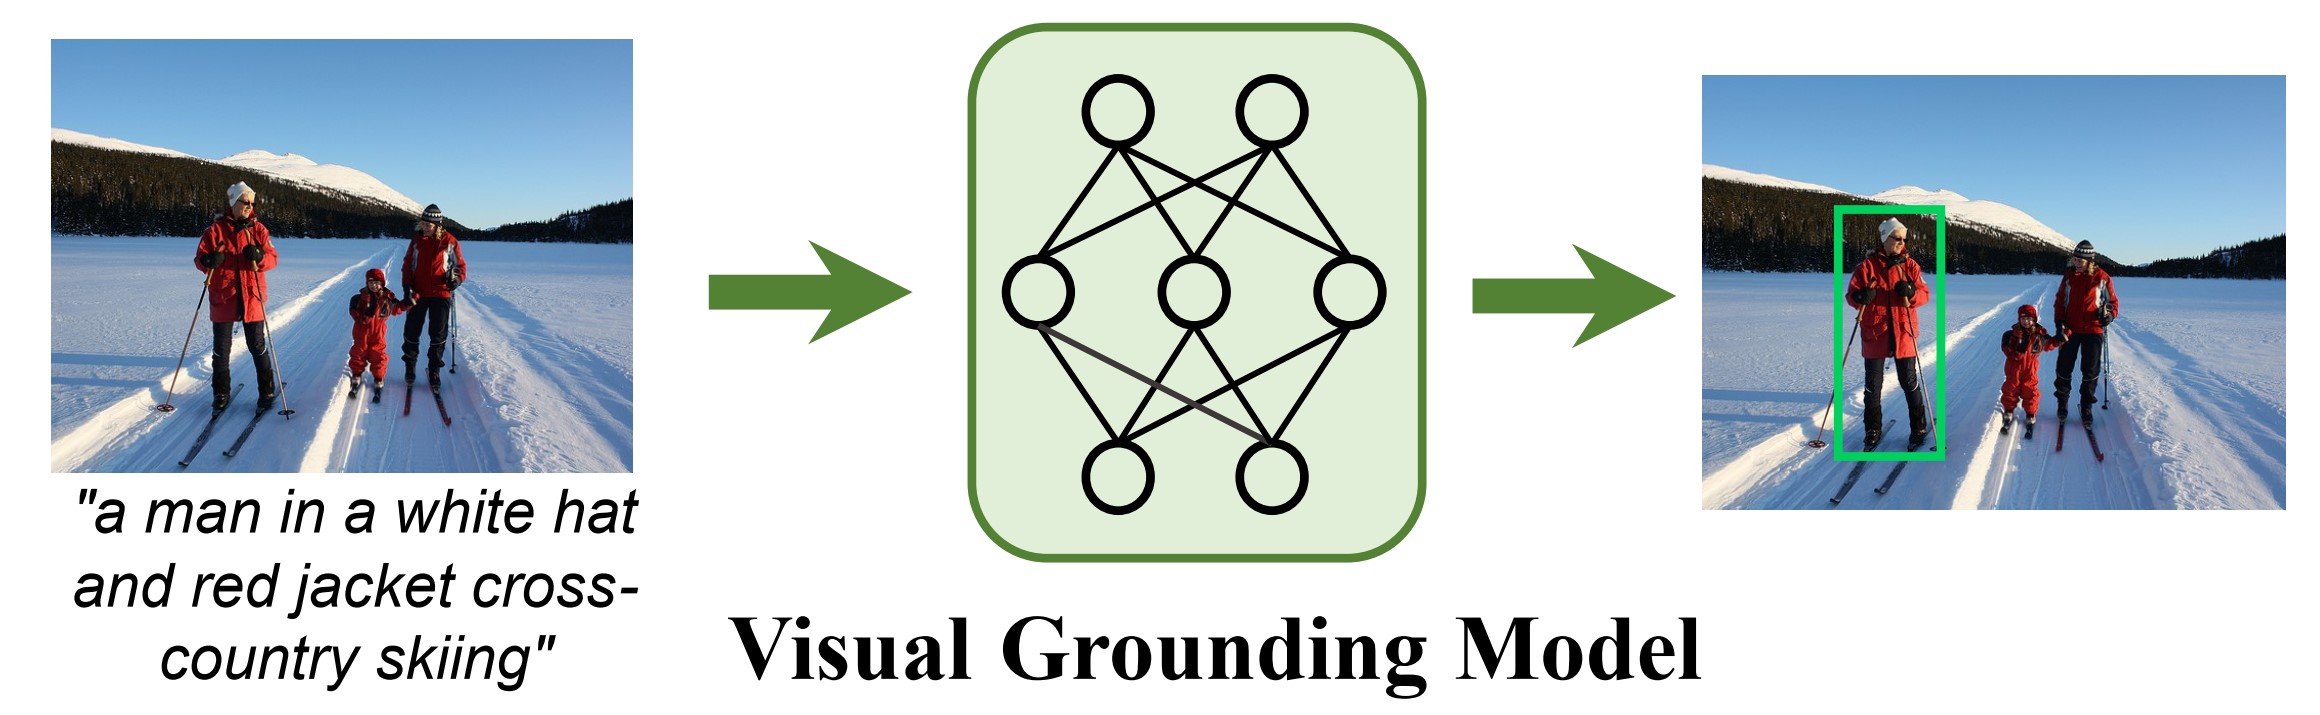
An Illustration of Visual Grounding
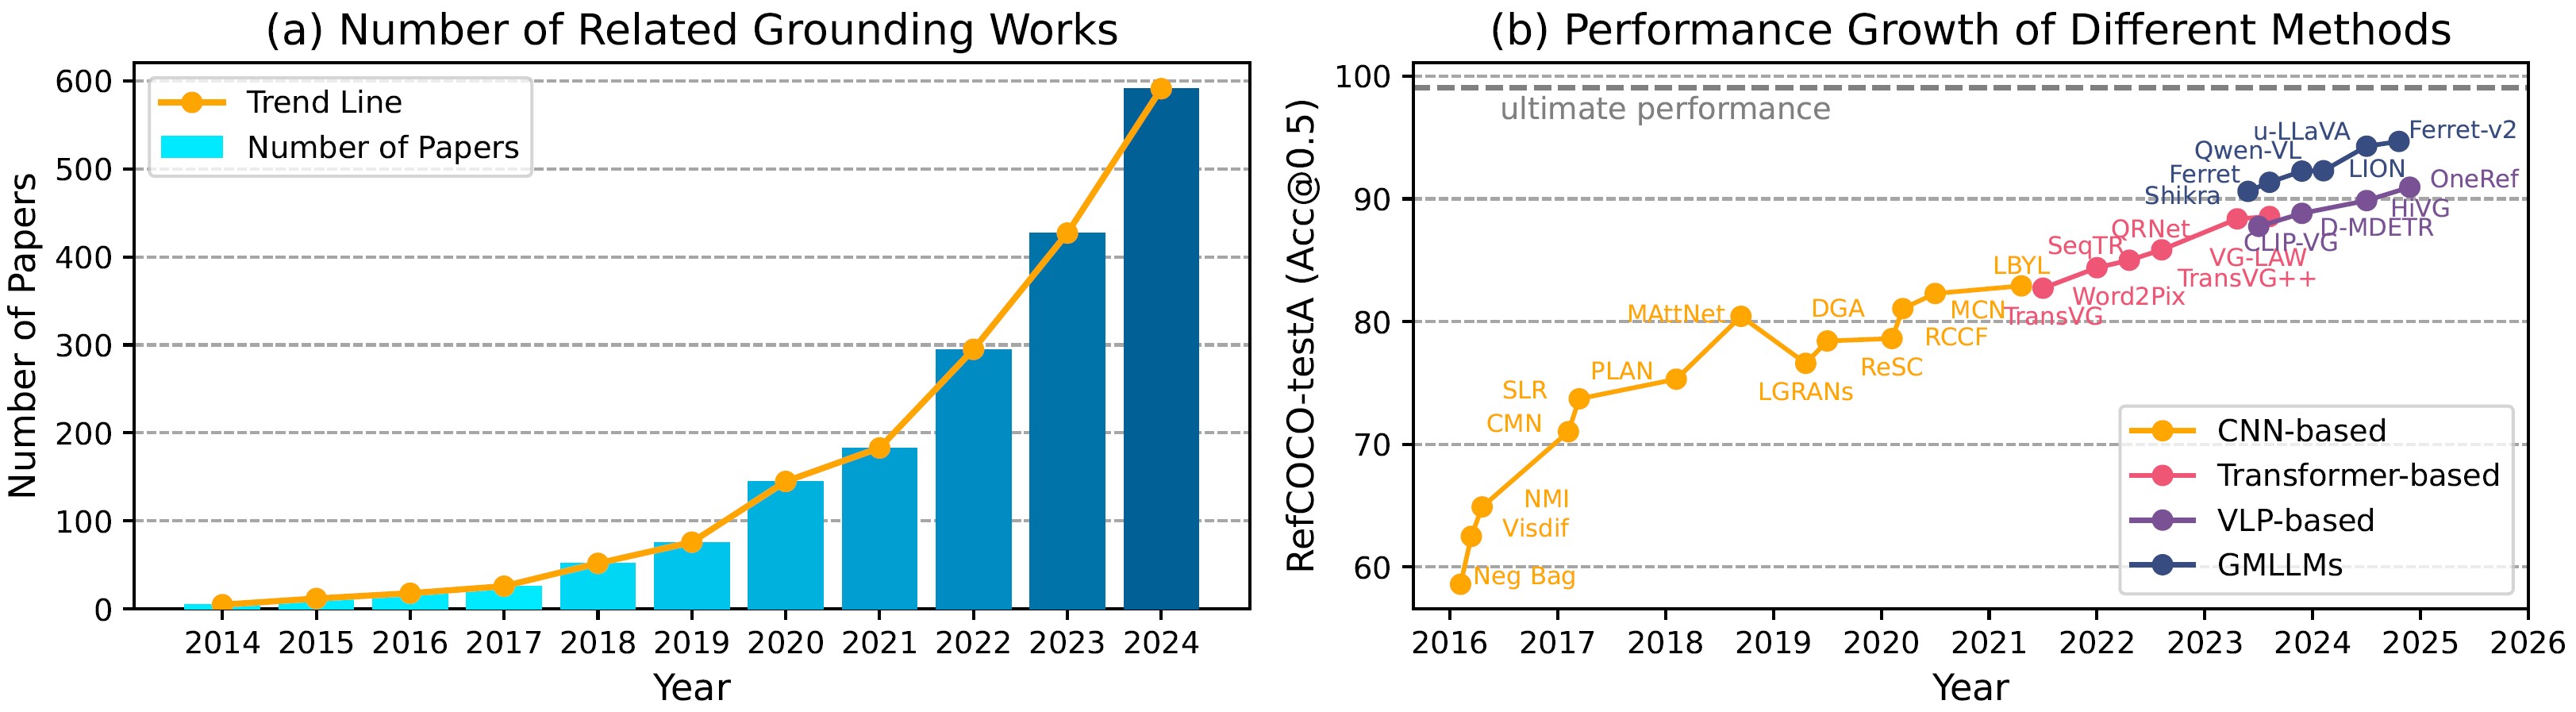
A Decade of Visual Grounding
This repo is used for recording, tracking, and benchmarking several recent visual grounding methods to supplement our Grounding Survey.
Links: TPAMI, ArXiv, 《机器之心》中文解读
Please leave a STAR ⭐ if you like this project!
🔥 Add Your Paper in our Repo and Survey!
-
If you find any work missing or have any suggestions (papers, implementations, and other resources), feel free to pull requests. We will add the missing papers to this repo as soon as possible.
-
You are welcome to give us an issue or PR (pull request) for your visual grounding related works!
-
Note that: Due to the huge paper in Arxiv, we are sorry to cover all in our survey. You can directly present a PR into this repo and we will record it for next version update of our survey.
🔥 New
-
🔥🔥🔥 Our Grounding survey (TPAMI, Arxiv, Project) has been accepted by TPAMI on October 30, 2025 !!!
-
🔥 We made our survey paper public and created this repository on December 28, 2024.
-
Our advanced one-tower grounding work OneRef (Paper, Code) has been accepted by top conference NeurIPS 2024 in October 2024!
-
Our advanced grounding work HiVG (Paper, Code) has been accepted by top conference ACM MM 2024 in July 2024!
-
Our grounding work CLIP-VG (Paper, Code) has been accepted by top journal TMM in September 2023!
🔥 Highlight!!
-
A comprehensive survey for Visual Grounding, including Referring Expression Comprehension and Phrase Grounding.
-
It includes the newly concepts, such as Grounding Multi-modal LLMs, Generalized Visual Grounding, and VLP-based grounding transfer works.
-
We list detailed results for the most representative works and give a fairer and clearer comparison of different approaches.
-
We provide a list of future research insights.
Introduction
We are the first survey in the past five years to systematically track and summarize the development of visual grounding over the last decade. By extracting common technical details, this review encompasses the most representative work in each subtopic.
This survey is also currently the most comprehensive review in the field of visual grounding. We aim for this article to serve as a valuable resource not only for beginners seeking an introduction to grounding but also for researchers with an established foundation, enabling them to navigate and stay up-to-date with the latest advancements.
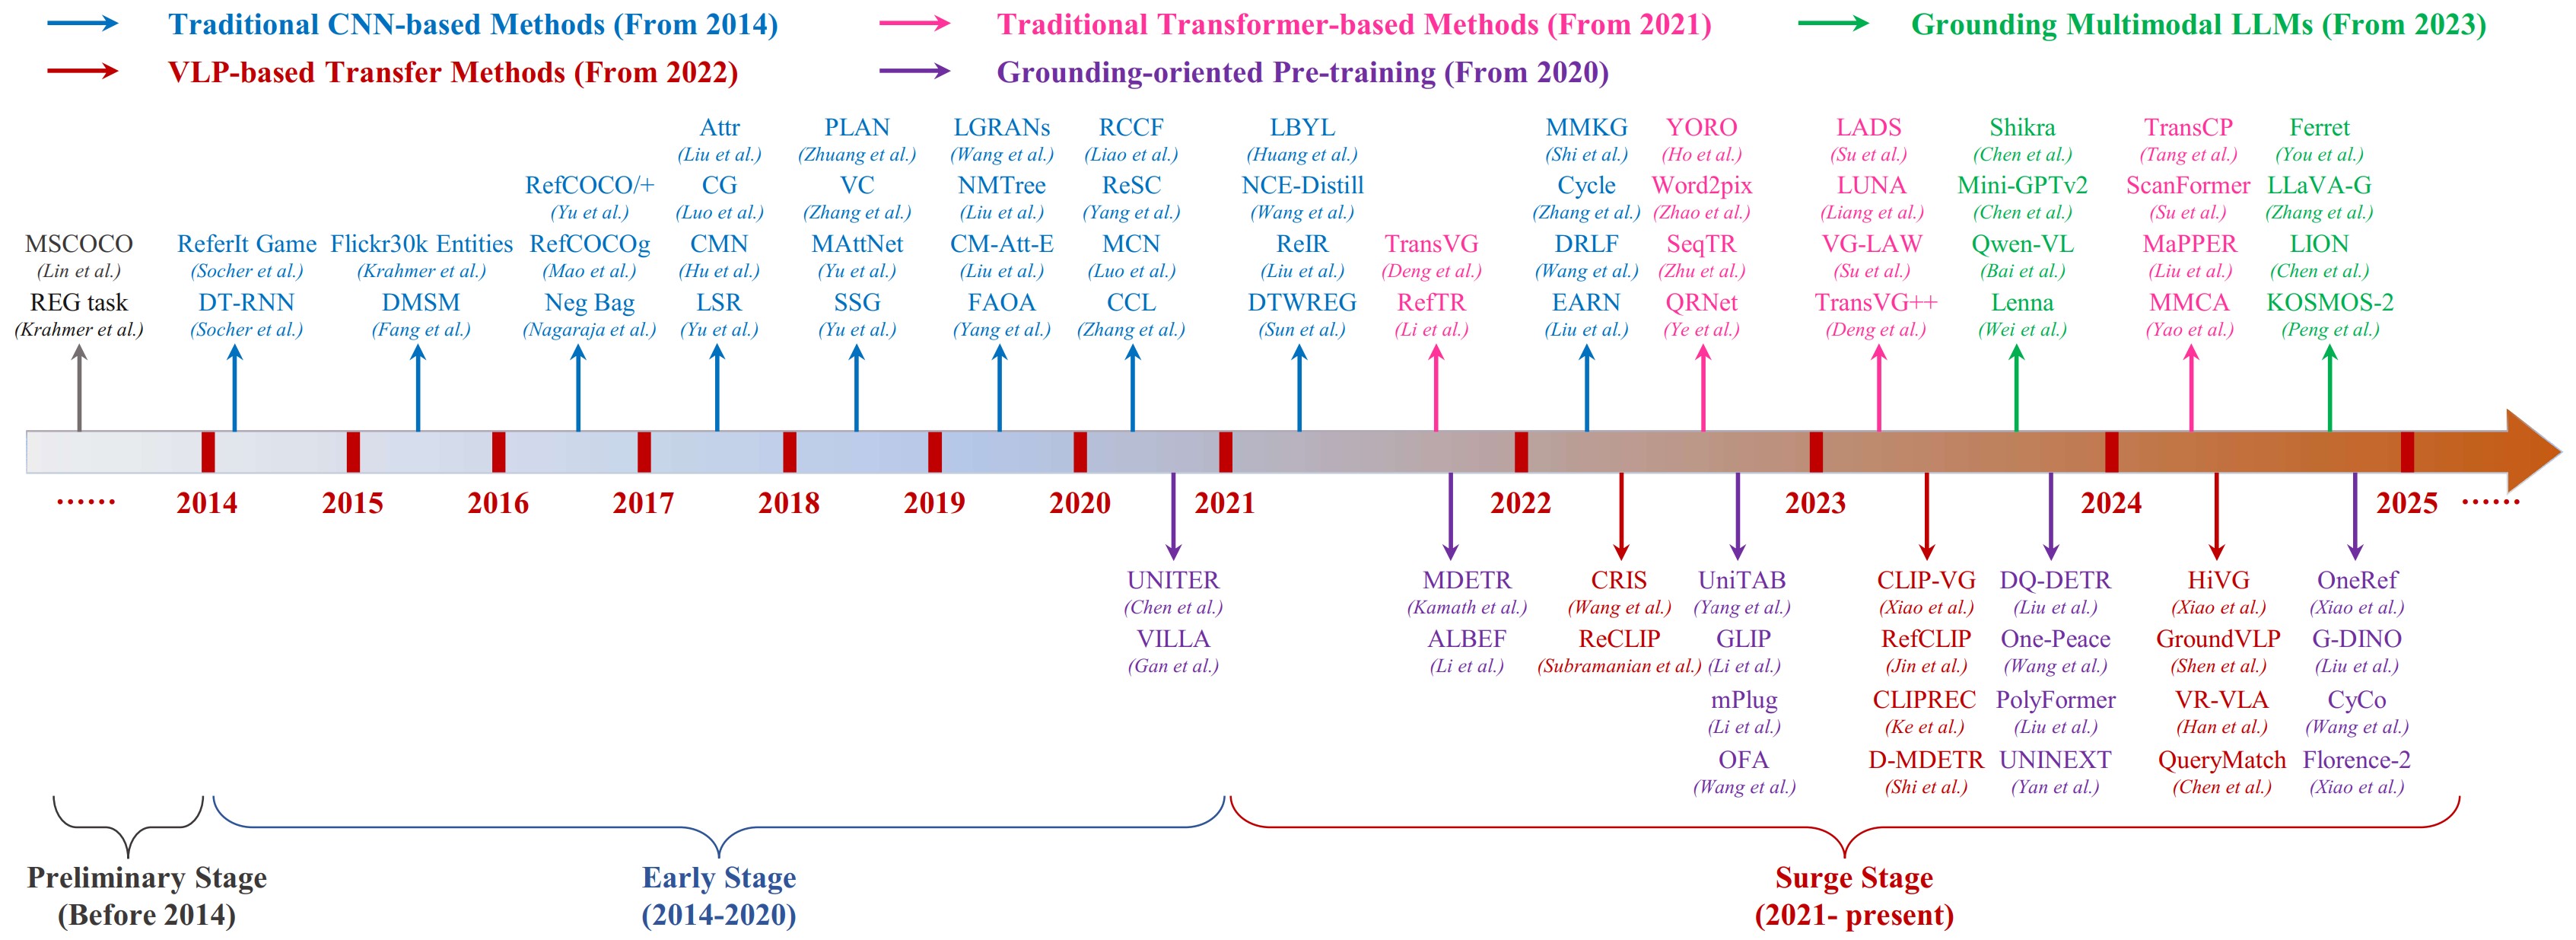
A Decade of Visual Grounding
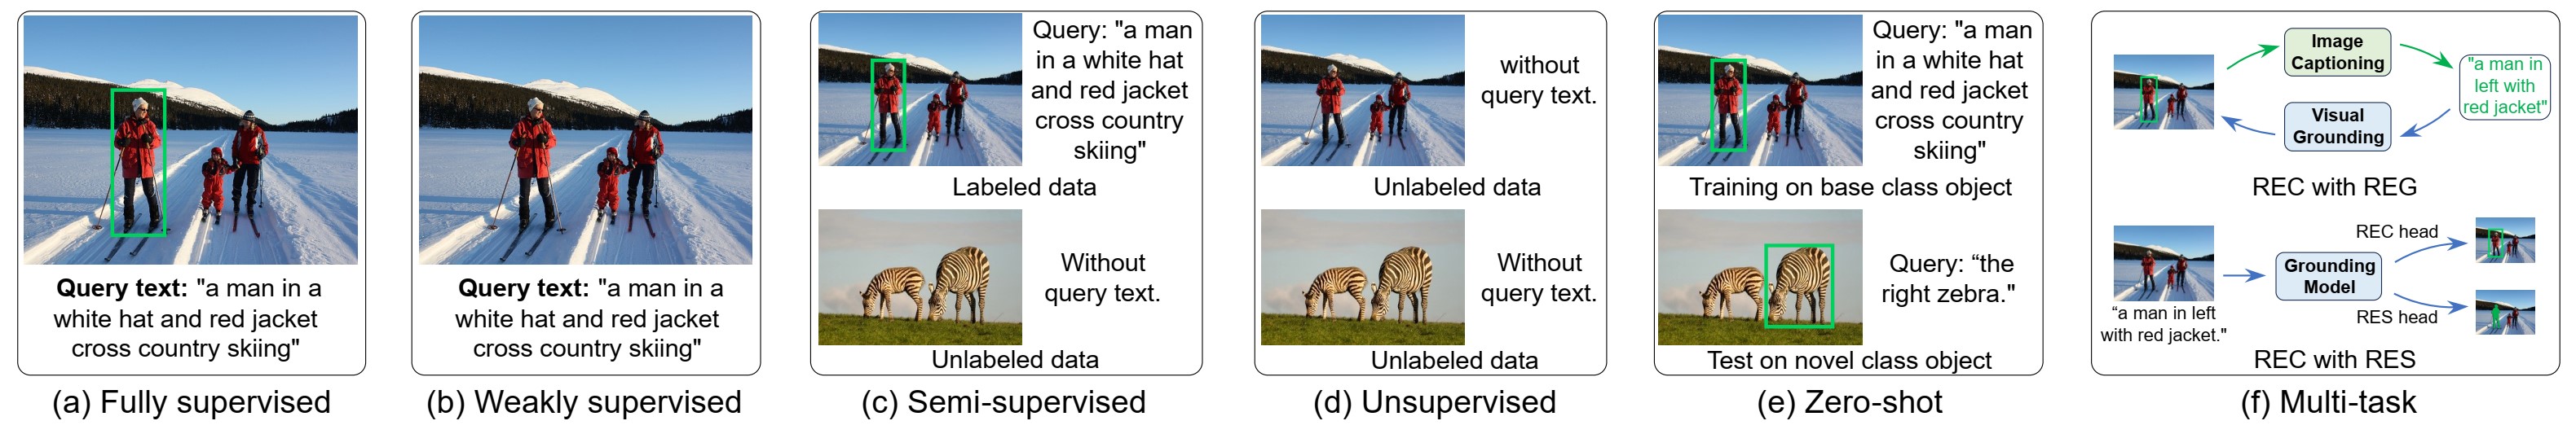
Mainstream Settings in Visual Grounding
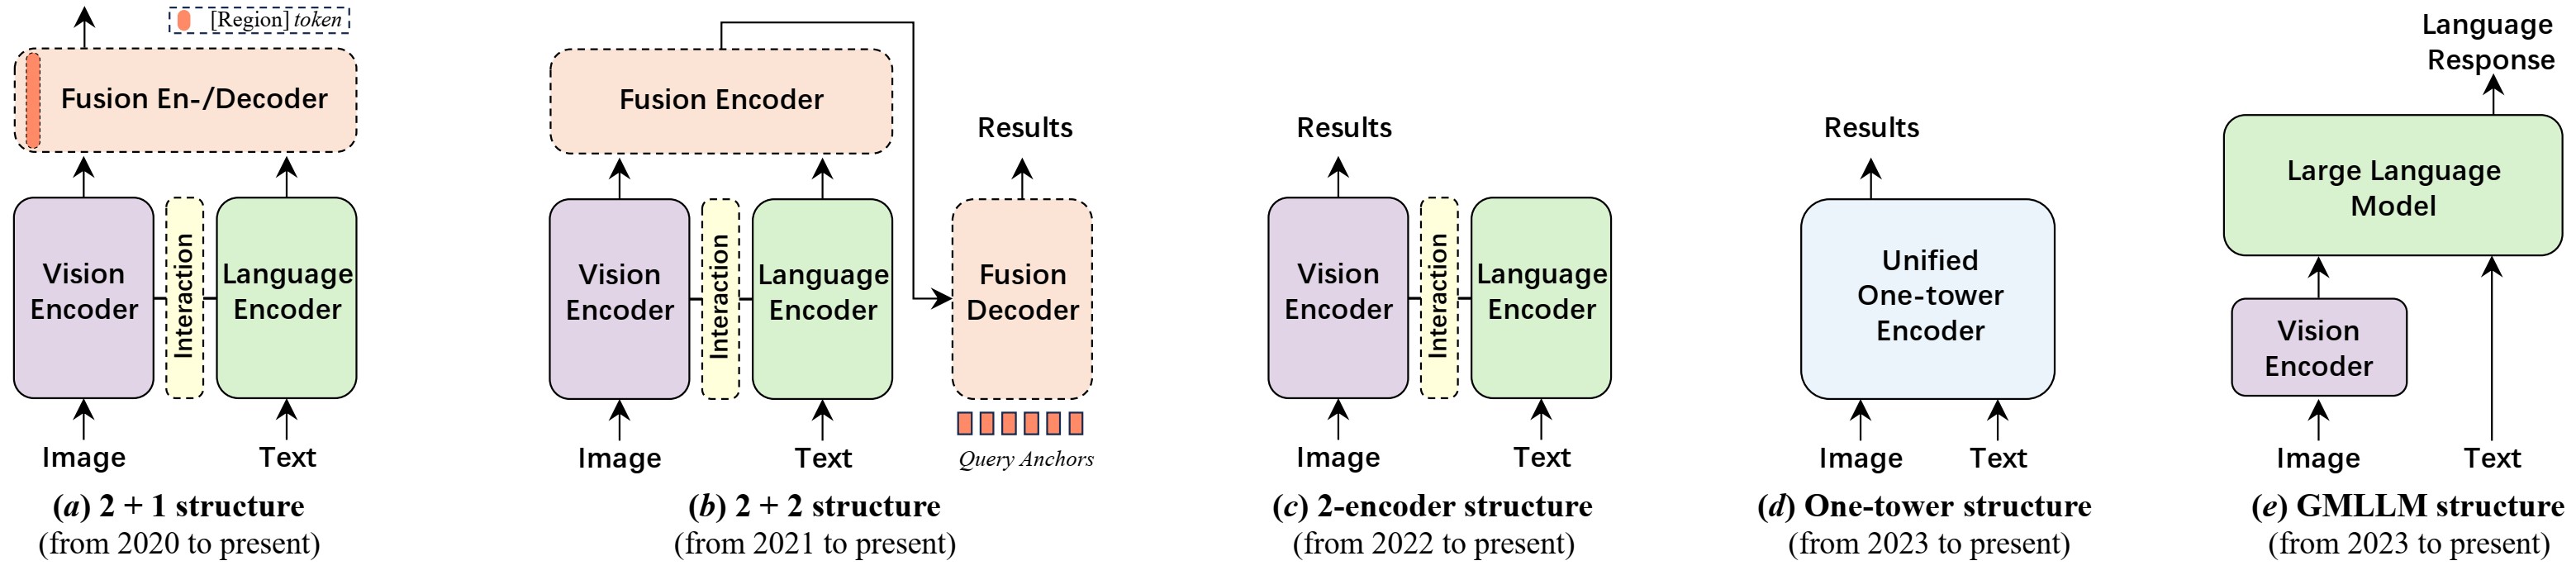
Typical Framework Architectures for Visual Grounding
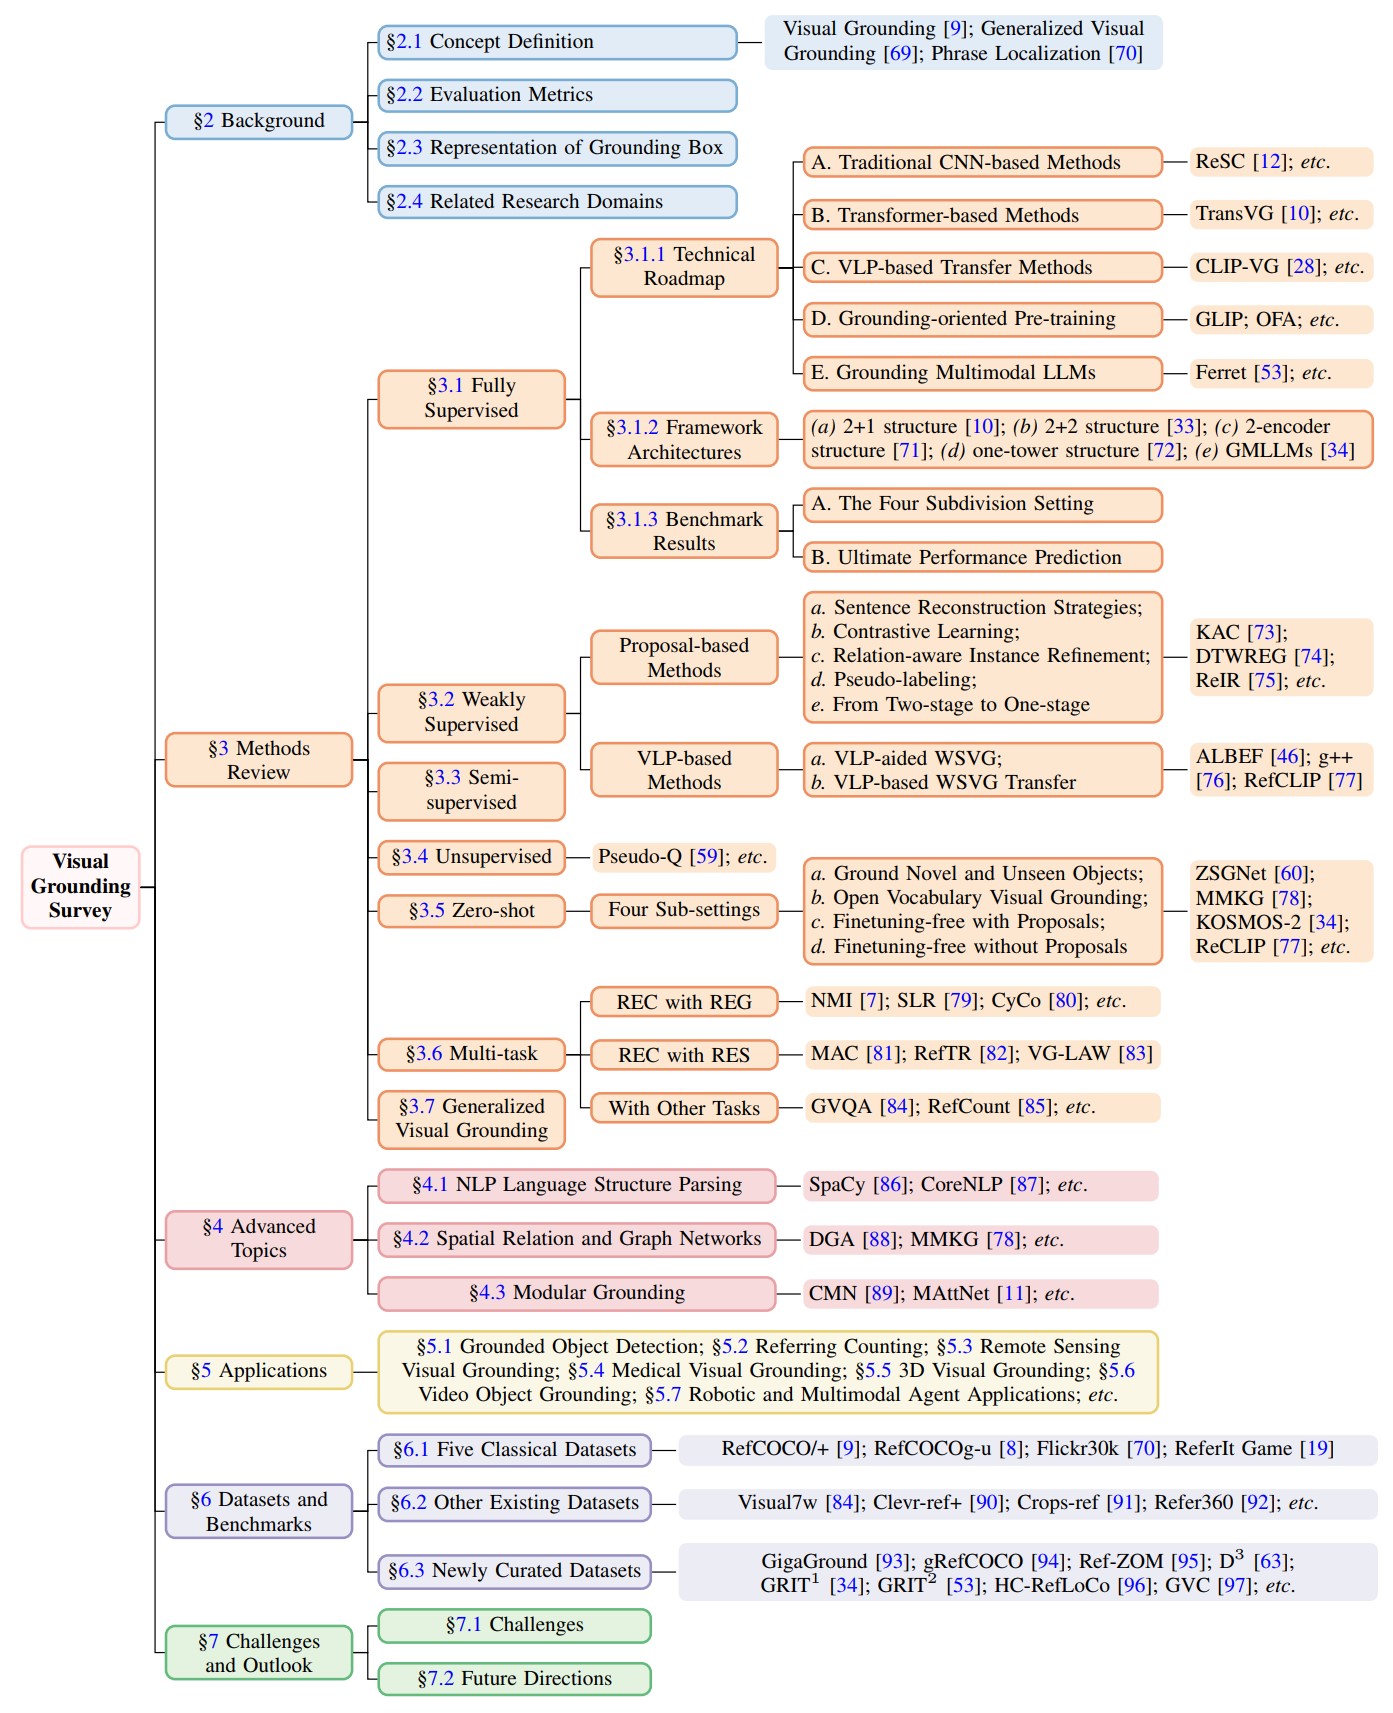
Our Paper Structure
Citation
If you find our work helpful for your research, please consider citing the following BibTeX entry.
@article{xiao2025groundingsurvey,
      title={Towards Visual Grounding: A Survey},
      author={Linhui Xiao and Xiaoshan Yang and Xiangyuan Lan and Yaowei Wang and Changsheng Xu},
      journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
      year={2025},
      volume={1},
      number={1},
      pages={1-20},
      doi={10.1109/TPAMI.2025.3630635}
}
It should be noted that, due to the typesetting restrictions of the journal, there are small differences in the typesetting between the Arxiv version and review version.
The following will be the relevant grounding papers and associated code links in this paper:
Summary of Contents
This content corresponds to the main text.
- Introduction
- Summary of Contents
- 1. Methods: A Survey
- 2. Advanced Topics
- 3. Applications
- 4. Datasets and Benchmarks
- 5. Challenges And Outlook
- 6. Other Valuable Survey and Project
- Acknowledgement
- Contact
1. Methods: A Survey
1.1 Fully Supervised Setting
A. Traditional CNN-based Methods
B. Transformer-based Methods
| Year | Venue | Work Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2021 | ICCV | TransVG | Transvg: End-to-end Visual Grounding with Transformers | Code |
| 2023 | TPAMI | TransVG++ | TransVG++: End-to-End Visual Grounding with Language Conditioned Vision Transformer | N/A |
| 2022 | CVPR | QRNet | Shifting More Attention to Visual Backbone: Query-Modulated Refinement Networks for End-to-End Visual Grounding | Code |
| 2024 | ACM MM | MMCA | Visual grounding with multimodal conditional adaptation | Code |
C. VLP-based Methods
D. Grounding-oriented Pre-training
E. Grounding Multimodal LLMs
1.2 Weakly Supervised Setting
1.3 Semi-supervised Setting
1.4 Unsupervised Setting
1.5 Zero-shot Setting
1.6 Multi-task Setting
A. REC with REG Multi-task Setting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | Arxiv | VLM-VG | Learning visual grounding from generative vision and language model | N/A |
| 2024 | Arxiv | EEVG | An efficient and effective transformer decoder-based framework for multi-task visual grounding | Code |
| 2006 | INLGC | N/A | Building a Semantically Transparent Corpus for the Generation of Referring Expressions | Project |
| 2010 | ACL | N/A | Natural reference to objects in a visual domain | Code |
| 2012 | CL | Survey | Computational generation of referring expressions: A survey | N/A |
| 2013 | NAACL | N/A | Generating expressions that refer to visible object | Code |
| 2016 | CVPR | NMI | Generation and comprehension of unambiguous object descriptions | Code |
| 2017 | ICCV | Attribute | Referring Expression Generation and Comprehension via Attributes | N/A |
| 2017 | CVPR | SLR | A Joint Speaker-Listener-Reinforcer Model for Referring Expressions | N/A |
| 2017 | CVPR | CG | Comprehension-guided referring expressions | N/A |
| 2024 | AAAI | CyCo | A Joint Speaker-Listener-Reinforcer Model for Referring Expressions | N/A |
B. REC with RES Multi-task Setting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2020 | CVPR | MCN | Multi-task Collaborative Network for Joint Referring Expression Comprehension and Segmentation | code |
| 2021 | NeurIPS | RefTR | Referring Transformer: A One-step Approach to Multi-task Visual Grounding | code |
| 2022 | ECCV | SeqTR | SeqTR: A Simple yet Universal Network for Visual Grounding | code |
| 2023 | CVPR | VG-LAW | Language Adaptive Weight Generation for Multi-task Visual Grounding | code |
| 2024 | Neurocomputing | M2IF | Improving visual grounding with multi-modal interaction and auto-regressive vertex generation | Code |
C. Other Multi-task Setting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2016 | EMNLP | MCB | Multimodal compact bilinear pooling for visual question answering and visual groundin | Code |
| 2024 | CVPR | RefCount | Referring expression counting | Code |
| 2022 | CVPR | VizWiz-VQA-Grounding | Grounding Answers for Visual Questions Asked by Visually Impaired People | Project |
| 2022 | ECCV | N/A | Weakly supervised grounding for VQA in vision-language transformers | Code |
| 2020 | ACL | N/A | A Negative Case Analysis of Visual Grounding Methods for VQA | Code |
| 2024 | Arxiv | TrueVG | Uncovering the Full Potential of Visual Grounding Methods in VQA | Code |
| 2020 | IVC | N/A | Explaining VQA predictions using visual grounding and a knowledge base | N/A |
| 2019 | CVPR | N/A | Multi-task Learning of Hierarchical Vision-Language Representation | N/A |
1.7 Generalized Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2021 | CVPR | OVR-CNN | Open-Vocabulary Object Detection Using Captions | Code |
| 2021 | ICCV | VLT | Vision-Language Transformer and Query Generation for Referring Segmentation | Code |
| 2023 | Arxiv | GREC | GREC:Generalized Referring Expression Comprehension | Code |
| 2024 | EMNLP | RECANTFormer | Recantformer: Referring expression comprehension with varying numbers of targets | N/A |
| 2023 | CVPR | gRefCOCO | GRES: Generalized Referring Expression Segmentation | Code |
| 2024 | ICCV | Ref-ZOM | Beyond One-to-One: Rethinking the Referring Image Segmentation | Code |
2. Advanced Topics
2.1 NLP Language Structure Parsing in Visual Grounding
2.2 Spatial Relation and Graph Networks
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2023 | TMM | CLIPREC | CLIPREC: Graph-Based Domain Adaptive Network for Zero-Shot Referring Expression Comprehension | N/A |
| 2024 | ACM MM | ResVG | ResVG: Enhancing Relation and Semantic Understanding in Multiple Instances for Visual Grounding | code |
| 2023 | Arxiv | Shikra | Code | |
| 2023 | ACM MM | TAGRL | Towards adaptable graph representation learning: An adaptive multi-graph contrastive transformer | N/A |
| 2020 | AAAI | CMCC | Learning cross-modal context graph for visual grounding | code |
| 2019 | CVPR | LGRANs | Neighbourhood watch: Referring expression comprehension via language-guided graph attention networks | N/A |
| 2019 | CVPR | CMRIN | Cross-Modal Relationship Inference for Grounding Referring Expressions | N/A |
| 2019 | ICCV | DGA | Dynamic Graph Attention for Referring Expression Comprehension | N/A |
| 2024 | TPAMI | N/A | A Survey on Graph Neural Networks and GraphTransformers in Computer Vision: A Task-Oriented Perspective | N/A |
2.3 Modular Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2018 | CVPR | Mattnet | Mattnet: Modular attention network for referring expression comprehension | Code |
| 2017 | CVPR | CMN | Modeling relationships in referential expressions with compositional modular networks | Code |
| 2016 | CVPR | NMN | Neural Module Networks | code |
| 2019 | CVPR | MTGCR | Modularized Textual Grounding for Counterfactual Resilience | N/A |
3. Applications
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2019 | CVPR | CAGDC | Context and Attribute Grounded Dense Captioning | N/A |
3.1 Grounded Object Detection
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | NeurlPS | MQ-Det | Multi-modal queried object detection in the wild | code |
| 2023 | Arxiv | Shikra | Code | |
| 2022 | CVPR | GLIP | Grounded language-image pretraining | Code |
| 2024 | CVPR | ScanFormer | ScanFormer: Referring Expression Comprehension by Iteratively Scanning | N/A |
| 2024 | Arxiv | Ref-L4 | Revisiting Referring Expression Comprehension Evaluation in the Era of Large Multimodal Models | code |
3.2 Referring Counting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | CVPR | RefCount | Referring expression counting | Code |
3.3 Remote Sensing Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | TGRS | Rrsis | “Rrsis: Referring remote sensing image segmentation | code |
| 2024 | TGRS | LQVG | Language query based transformer with multi-scale cross-modal alignment for visual grounding on remote sensing images | code |
| 2024 | TGRS | RINet | A regionally indicated visual grounding network for remote sensing images | code |
| 2024 | GRSL | MSAM | Multi-stage synergistic aggregation network for remote sensing visual grounding | code |
| 2024 | GRSL | VSMR | Visual selection and multi-stage reasoning for rsvg | N/A |
| 2024 | TGRS | LPVA | Language-guided progressive attention for visual grounding in remote sensing images | code |
| 2024 | Arxiv | GeoGround | GeoGround: A Unified Large Vision-Language Model. for Remote Sensing Visual Grounding | code |
| 2023 | TGRS | RSVG | RSVG: Exploring Data and Models for Visual Grounding on Remote Sensing Data | N/A |
| 2022 | ACM MM | RSVG | Visual grounding in remote sensing images | code |
3.4 Medical Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2023 | MICCAI | MedRPG | Medical Grounding with Region-Phrase Context Contrastive Alignment | N/A |
| 2024 | Arxiv | PFMVG | Parameter-Efficient Fine-Tuning Medical Multimodal Large Language Models for Medical Visual Grounding | unavailable |
| 2022 | ECCV | CXR-BERT | Making the most of text semantics to improve biomedical vision–language processing | code |
| 2017 | CVPR | ChestX-ray8 | Chestx-ray8: Hospital-scale chest x-ray database and benchmarks on weakly-supervised classification and localization of common thorax diseases | N/A |
| 2019 | Arxiv | MIMIC-CXR-JPG | MIMIC-CXR-JPG, a large publicly available database of labeled chest radiographs | Code |
| 2024 | Arxiv | MedRG | MedRG: Medical Report Grounding with Multi-modal Large Language Model | N/A |
| 2024 | Arxiv | VividMed | VividMed: Vision Language Model with Versatile Visual Grounding for Medicine | Code |
| 2023 | Arxiv | ViLaM | ViLaM: A Vision-Language Model with Enhanced Visual Grounding and Generalization Capability | Code |
3.5 3D Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2022 | CVPR | 3D-SPS | 3D-SPS: Single-Stage 3D Visual Grounding via Referred Point Progressive Selection | Code |
| 2021 | ACMMM | TransRefer3D | TransRefer3D: Entity-and-Relation Aware Transformer for Fine-Grained 3D Visual Grounding | Code |
| 2020 | ECCV | Scanrefer | Scanrefer: 3d object localization in rgb-d scans using natural language | Code |
| 2020 | ECCV | ReferIt3D | ReferIt3D: Neural Listeners for Fine-Grained 3D Object Identification in Real-World Scenes | Code |
| 2024 | Arxiv | - | A Survey on Text-guided 3D Visual Grounding: Elements, Recent Advances, and Future Directions | N/A |
3.6 Video Object Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2020 | CVPR | VOGNet | Video object grounding using semantic roles in language description | Code |
| 2024 | Arxiv | - | Described Spatial-Temporal Video Detection | unavailable |
| 2023 | TOMM | - | A survey on temporal sentence grounding in videos | N/A |
| 2023 | TPAMI | - | Temporal sentence grounding in videos: A survey and future directions | N/A |
| 2024 | CVPR | MC-TTA | Modality-Collaborative Test-Time Adaptation for Action Recognition | N/A |
| 2023 | CVPR | TransRMOT | Referring multi-object tracking | code |
3.7 Robotic and Multimodal Agent Applications
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2018 | CVPR | VLN | Vision-and-language navigation: Interpreting visually-grounded navigation instructions in real environments | Data |
| 2019 | RAS | Dynamic-SLAM | Dynamic-SLAM: Semantic monocular visual localization and mapping based on deep learning in dynamic environment | Code |
| 2019 | WCSP | N/A | Integrated Wearable Indoor Positioning System Based On Visible Light Positioning And Inertial Navigation Using Unscented Kalman Filter | N/A |
| 2019 | ICRA | Ground then Navigate | Ground then Navigate: Language-guided Navigation in Dynamic Scenes | Code |
| 2023 | MEAS SCI TECHNOL | FDO-Calibr | FDO-Calibr: visual-aided IMU calibration based on frequency-domain optimization | N/A |
| 2024 | arxiv | HiFi-CS | Towards Open Vocabulary Visual Grounding For Robotic Grasping Using Vision-Language Models | N/A |
| 2025 | ECCV | Ferret-UI | Grounded Mobile UI Understanding with Multimodal LLMs | N/A |
3.8 Multi-image Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2025 | ACL | Migician | Migician: Revealing the Magic of Free-Form Multi-Image Grounding in Multimodal Large Language Models | Code/ Project |
| 2025 | arxiv | UniVG-R1 | UniVG-R1: Reasoning Guided Universal Visual Grounding with Reinforcement Learning | Code/ Project |
4. Datasets and Benchmarks
4.1 The Five Datasets for Classical Visual Grounding
4.2 The Other Datasets for Classical Visual Grounding
4.3 Dataset for the Newly Curated Scenarios
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | NeurIPS | D$^3$ | Described Object Detection: Liberating Object Detection with Flexible Expressions | Code |
A. Dataset for Generalized Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2023 | CVPR | gRefCOCO | GRES: Generalized Referring Expression Segmentation | Code |
| 2024 | ICCV | Ref-ZOM | Beyond One-to-One: Rethinking the Referring Image Segmentation | Code |
B. Datasets and Benchmarks for GMLLMs
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | Arxiv | Inst-IT | Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning | Code / Project |
| 2024 | NeurIPS | HC-RefLoCo | A Large-Scale Human-Centric Benchmark for Referring Expression Comprehension in the LMM Era | Code |
| 2024 | ECCV | GVC | Llava-grounding: Grounded visual chat with large multimodal models | N/A |
| 2024 | ICLR | KOSMOS-2 | GROUNDING MULTIMODAL LARGE LANGUAGE MODELS TO THE WORLD | Code |
C. Dataset for Other Newly Curated Scenarios
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | CVPR | GigaGround | When visual grounding meets gigapixel-level large-scale scenes: Benchmark and approach | Code |
| 2025 | ACL | MGrounding-630k/MIG-Bench | Migician: Revealing the Magic of Free-Form Multi-Image Grounding in Multimodal Large Language Models | Code/ Project |
| 2025 | Arxiv | PixMMVP, PixCV-Bench (Pixel-level VG) | PixFoundation: Are We Heading in the Right Direction with Pixel-level Vision Foundation Models? | Code/ Project |
| 2025 | Arxiv | MoCentric-Bench (Pixel-level VG) | PixFoundation 2.0: Do Video Multi-Modal LLMs Use Motion in Visual Grounding? | Code/ Project |
5. Challenges And Outlook
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | Arxiv | - | AI Models Collapse When Trained on Recursively Generated Data | N/A |
| 2024 | CVPR | RefCount | Referring expression counting | Code |
| 2024 | CVPR | GigaGround | When visual grounding meets gigapixel-level large-scale scenes: Benchmark and approach | Code |
| 2022 | CVPR | GLIP | Grounded language-image pretraining | Code |
| 2025 | ACL | Migician | Migician: Revealing the Magic of Free-Form Multi-Image Grounding in Multimodal Large Language Models | Code/ Project |
6. Other Valuable Survey and Project
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2018 | TPAMI | N/A | Multimodal machine learning: A survey and taxonomy | N/A |
| 2020 | TMM | N/A | Referring expression comprehension: A survey of methods and datasets | N/A |
| 2021 | Github | awesome-grounding | N/A | Project |
| 2023 | TPAMI | Awesome-Open-Vocabulary | Towards Open Vocabulary Learning: A Survey | Project |
| 2023 | TPAMI | N/A | Multimodal learning with transformers: A survey | N/A |
| 2024 | Github | awesome-described-object-detection | N/A | awesome-described-object-detection |
Acknowledgement
This survey took half a year to complete, and the process was laborious and burdensome.
Building up this GitHub repository also required significant effort. We would like to thank the following individuals for their contributions to completing this project: Baochen Xiong, Yifan Xu, Yaguang Song, Menghao Hu, Han Jiang, Hao Liu, Chenlin Zhao, Fang Peng, Xudong Yao, Zibo Shao, Kaichen Li, Jianhao Huang, Xianbing Yang, Shuaitong Li, Jisheng Yin, Yupeng Wu, Shaobo Xie, etc.
Contact
Email: xiaolinhui16@mails.ucas.ac.cn. Any kind discussions are welcomed!
Star History
Contributors


Similar repos


Languages
Shell
100.0%
[TPAMI 2025] Towards Visual Grounding: A Survey
See the codeREADME
Towards Visual Grounding: A Survey
Accepted by TPAMI, 2025
Linhui Xiao
·
Xiaoshan Yang
·
Xiangyuan Lan
·
Yaowei Wang
·
Changsheng Xu
An Illustration of Visual Grounding
A Decade of Visual Grounding
This repo is used for recording, tracking, and benchmarking several recent visual grounding methods to supplement our Grounding Survey.
Links: TPAMI, ArXiv, 《机器之心》中文解读
Please leave a STAR ⭐ if you like this project!
🔥 Add Your Paper in our Repo and Survey!
-
If you find any work missing or have any suggestions (papers, implementations, and other resources), feel free to pull requests. We will add the missing papers to this repo as soon as possible.
-
You are welcome to give us an issue or PR (pull request) for your visual grounding related works!
-
Note that: Due to the huge paper in Arxiv, we are sorry to cover all in our survey. You can directly present a PR into this repo and we will record it for next version update of our survey.
🔥 New
-
🔥🔥🔥 Our Grounding survey (TPAMI, Arxiv, Project) has been accepted by TPAMI on October 30, 2025 !!!
-
🔥 We made our survey paper public and created this repository on December 28, 2024.
-
Our advanced one-tower grounding work OneRef (Paper, Code) has been accepted by top conference NeurIPS 2024 in October 2024!
-
Our advanced grounding work HiVG (Paper, Code) has been accepted by top conference ACM MM 2024 in July 2024!
-
Our grounding work CLIP-VG (Paper, Code) has been accepted by top journal TMM in September 2023!
🔥 Highlight!!
-
A comprehensive survey for Visual Grounding, including Referring Expression Comprehension and Phrase Grounding.
-
It includes the newly concepts, such as Grounding Multi-modal LLMs, Generalized Visual Grounding, and VLP-based grounding transfer works.
-
We list detailed results for the most representative works and give a fairer and clearer comparison of different approaches.
-
We provide a list of future research insights.
Introduction
We are the first survey in the past five years to systematically track and summarize the development of visual grounding over the last decade. By extracting common technical details, this review encompasses the most representative work in each subtopic.
This survey is also currently the most comprehensive review in the field of visual grounding. We aim for this article to serve as a valuable resource not only for beginners seeking an introduction to grounding but also for researchers with an established foundation, enabling them to navigate and stay up-to-date with the latest advancements.
A Decade of Visual Grounding
Mainstream Settings in Visual Grounding
Typical Framework Architectures for Visual Grounding
Our Paper Structure
Citation
If you find our work helpful for your research, please consider citing the following BibTeX entry.
@article{xiao2025groundingsurvey,
      title={Towards Visual Grounding: A Survey},
      author={Linhui Xiao and Xiaoshan Yang and Xiangyuan Lan and Yaowei Wang and Changsheng Xu},
      journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
      year={2025},
      volume={1},
      number={1},
      pages={1-20},
      doi={10.1109/TPAMI.2025.3630635}
}
It should be noted that, due to the typesetting restrictions of the journal, there are small differences in the typesetting between the Arxiv version and review version.
The following will be the relevant grounding papers and associated code links in this paper:
Summary of Contents
This content corresponds to the main text.
- Introduction
- Summary of Contents
- 1. Methods: A Survey
- 2. Advanced Topics
- 3. Applications
- 4. Datasets and Benchmarks
- 5. Challenges And Outlook
- 6. Other Valuable Survey and Project
- Acknowledgement
- Contact
1. Methods: A Survey
1.1 Fully Supervised Setting
A. Traditional CNN-based Methods
B. Transformer-based Methods
| Year | Venue | Work Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2021 | ICCV | TransVG | Transvg: End-to-end Visual Grounding with Transformers | Code |
| 2023 | TPAMI | TransVG++ | TransVG++: End-to-End Visual Grounding with Language Conditioned Vision Transformer | N/A |
| 2022 | CVPR | QRNet | Shifting More Attention to Visual Backbone: Query-Modulated Refinement Networks for End-to-End Visual Grounding | Code |
| 2024 | ACM MM | MMCA | Visual grounding with multimodal conditional adaptation | Code |
C. VLP-based Methods
D. Grounding-oriented Pre-training
E. Grounding Multimodal LLMs
1.2 Weakly Supervised Setting
1.3 Semi-supervised Setting
1.4 Unsupervised Setting
1.5 Zero-shot Setting
1.6 Multi-task Setting
A. REC with REG Multi-task Setting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | Arxiv | VLM-VG | Learning visual grounding from generative vision and language model | N/A |
| 2024 | Arxiv | EEVG | An efficient and effective transformer decoder-based framework for multi-task visual grounding | Code |
| 2006 | INLGC | N/A | Building a Semantically Transparent Corpus for the Generation of Referring Expressions | Project |
| 2010 | ACL | N/A | Natural reference to objects in a visual domain | Code |
| 2012 | CL | Survey | Computational generation of referring expressions: A survey | N/A |
| 2013 | NAACL | N/A | Generating expressions that refer to visible object | Code |
| 2016 | CVPR | NMI | Generation and comprehension of unambiguous object descriptions | Code |
| 2017 | ICCV | Attribute | Referring Expression Generation and Comprehension via Attributes | N/A |
| 2017 | CVPR | SLR | A Joint Speaker-Listener-Reinforcer Model for Referring Expressions | N/A |
| 2017 | CVPR | CG | Comprehension-guided referring expressions | N/A |
| 2024 | AAAI | CyCo | A Joint Speaker-Listener-Reinforcer Model for Referring Expressions | N/A |
B. REC with RES Multi-task Setting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2020 | CVPR | MCN | Multi-task Collaborative Network for Joint Referring Expression Comprehension and Segmentation | code |
| 2021 | NeurIPS | RefTR | Referring Transformer: A One-step Approach to Multi-task Visual Grounding | code |
| 2022 | ECCV | SeqTR | SeqTR: A Simple yet Universal Network for Visual Grounding | code |
| 2023 | CVPR | VG-LAW | Language Adaptive Weight Generation for Multi-task Visual Grounding | code |
| 2024 | Neurocomputing | M2IF | Improving visual grounding with multi-modal interaction and auto-regressive vertex generation | Code |
C. Other Multi-task Setting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2016 | EMNLP | MCB | Multimodal compact bilinear pooling for visual question answering and visual groundin | Code |
| 2024 | CVPR | RefCount | Referring expression counting | Code |
| 2022 | CVPR | VizWiz-VQA-Grounding | Grounding Answers for Visual Questions Asked by Visually Impaired People | Project |
| 2022 | ECCV | N/A | Weakly supervised grounding for VQA in vision-language transformers | Code |
| 2020 | ACL | N/A | A Negative Case Analysis of Visual Grounding Methods for VQA | Code |
| 2024 | Arxiv | TrueVG | Uncovering the Full Potential of Visual Grounding Methods in VQA | Code |
| 2020 | IVC | N/A | Explaining VQA predictions using visual grounding and a knowledge base | N/A |
| 2019 | CVPR | N/A | Multi-task Learning of Hierarchical Vision-Language Representation | N/A |
1.7 Generalized Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2021 | CVPR | OVR-CNN | Open-Vocabulary Object Detection Using Captions | Code |
| 2021 | ICCV | VLT | Vision-Language Transformer and Query Generation for Referring Segmentation | Code |
| 2023 | Arxiv | GREC | GREC:Generalized Referring Expression Comprehension | Code |
| 2024 | EMNLP | RECANTFormer | Recantformer: Referring expression comprehension with varying numbers of targets | N/A |
| 2023 | CVPR | gRefCOCO | GRES: Generalized Referring Expression Segmentation | Code |
| 2024 | ICCV | Ref-ZOM | Beyond One-to-One: Rethinking the Referring Image Segmentation | Code |
2. Advanced Topics
2.1 NLP Language Structure Parsing in Visual Grounding
2.2 Spatial Relation and Graph Networks
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2023 | TMM | CLIPREC | CLIPREC: Graph-Based Domain Adaptive Network for Zero-Shot Referring Expression Comprehension | N/A |
| 2024 | ACM MM | ResVG | ResVG: Enhancing Relation and Semantic Understanding in Multiple Instances for Visual Grounding | code |
| 2023 | Arxiv | Shikra | Code | |
| 2023 | ACM MM | TAGRL | Towards adaptable graph representation learning: An adaptive multi-graph contrastive transformer | N/A |
| 2020 | AAAI | CMCC | Learning cross-modal context graph for visual grounding | code |
| 2019 | CVPR | LGRANs | Neighbourhood watch: Referring expression comprehension via language-guided graph attention networks | N/A |
| 2019 | CVPR | CMRIN | Cross-Modal Relationship Inference for Grounding Referring Expressions | N/A |
| 2019 | ICCV | DGA | Dynamic Graph Attention for Referring Expression Comprehension | N/A |
| 2024 | TPAMI | N/A | A Survey on Graph Neural Networks and GraphTransformers in Computer Vision: A Task-Oriented Perspective | N/A |
2.3 Modular Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2018 | CVPR | Mattnet | Mattnet: Modular attention network for referring expression comprehension | Code |
| 2017 | CVPR | CMN | Modeling relationships in referential expressions with compositional modular networks | Code |
| 2016 | CVPR | NMN | Neural Module Networks | code |
| 2019 | CVPR | MTGCR | Modularized Textual Grounding for Counterfactual Resilience | N/A |
3. Applications
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2019 | CVPR | CAGDC | Context and Attribute Grounded Dense Captioning | N/A |
3.1 Grounded Object Detection
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | NeurlPS | MQ-Det | Multi-modal queried object detection in the wild | code |
| 2023 | Arxiv | Shikra | Code | |
| 2022 | CVPR | GLIP | Grounded language-image pretraining | Code |
| 2024 | CVPR | ScanFormer | ScanFormer: Referring Expression Comprehension by Iteratively Scanning | N/A |
| 2024 | Arxiv | Ref-L4 | Revisiting Referring Expression Comprehension Evaluation in the Era of Large Multimodal Models | code |
3.2 Referring Counting
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | CVPR | RefCount | Referring expression counting | Code |
3.3 Remote Sensing Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | TGRS | Rrsis | “Rrsis: Referring remote sensing image segmentation | code |
| 2024 | TGRS | LQVG | Language query based transformer with multi-scale cross-modal alignment for visual grounding on remote sensing images | code |
| 2024 | TGRS | RINet | A regionally indicated visual grounding network for remote sensing images | code |
| 2024 | GRSL | MSAM | Multi-stage synergistic aggregation network for remote sensing visual grounding | code |
| 2024 | GRSL | VSMR | Visual selection and multi-stage reasoning for rsvg | N/A |
| 2024 | TGRS | LPVA | Language-guided progressive attention for visual grounding in remote sensing images | code |
| 2024 | Arxiv | GeoGround | GeoGround: A Unified Large Vision-Language Model. for Remote Sensing Visual Grounding | code |
| 2023 | TGRS | RSVG | RSVG: Exploring Data and Models for Visual Grounding on Remote Sensing Data | N/A |
| 2022 | ACM MM | RSVG | Visual grounding in remote sensing images | code |
3.4 Medical Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2023 | MICCAI | MedRPG | Medical Grounding with Region-Phrase Context Contrastive Alignment | N/A |
| 2024 | Arxiv | PFMVG | Parameter-Efficient Fine-Tuning Medical Multimodal Large Language Models for Medical Visual Grounding | unavailable |
| 2022 | ECCV | CXR-BERT | Making the most of text semantics to improve biomedical vision–language processing | code |
| 2017 | CVPR | ChestX-ray8 | Chestx-ray8: Hospital-scale chest x-ray database and benchmarks on weakly-supervised classification and localization of common thorax diseases | N/A |
| 2019 | Arxiv | MIMIC-CXR-JPG | MIMIC-CXR-JPG, a large publicly available database of labeled chest radiographs | Code |
| 2024 | Arxiv | MedRG | MedRG: Medical Report Grounding with Multi-modal Large Language Model | N/A |
| 2024 | Arxiv | VividMed | VividMed: Vision Language Model with Versatile Visual Grounding for Medicine | Code |
| 2023 | Arxiv | ViLaM | ViLaM: A Vision-Language Model with Enhanced Visual Grounding and Generalization Capability | Code |
3.5 3D Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2022 | CVPR | 3D-SPS | 3D-SPS: Single-Stage 3D Visual Grounding via Referred Point Progressive Selection | Code |
| 2021 | ACMMM | TransRefer3D | TransRefer3D: Entity-and-Relation Aware Transformer for Fine-Grained 3D Visual Grounding | Code |
| 2020 | ECCV | Scanrefer | Scanrefer: 3d object localization in rgb-d scans using natural language | Code |
| 2020 | ECCV | ReferIt3D | ReferIt3D: Neural Listeners for Fine-Grained 3D Object Identification in Real-World Scenes | Code |
| 2024 | Arxiv | - | A Survey on Text-guided 3D Visual Grounding: Elements, Recent Advances, and Future Directions | N/A |
3.6 Video Object Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2020 | CVPR | VOGNet | Video object grounding using semantic roles in language description | Code |
| 2024 | Arxiv | - | Described Spatial-Temporal Video Detection | unavailable |
| 2023 | TOMM | - | A survey on temporal sentence grounding in videos | N/A |
| 2023 | TPAMI | - | Temporal sentence grounding in videos: A survey and future directions | N/A |
| 2024 | CVPR | MC-TTA | Modality-Collaborative Test-Time Adaptation for Action Recognition | N/A |
| 2023 | CVPR | TransRMOT | Referring multi-object tracking | code |
3.7 Robotic and Multimodal Agent Applications
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2018 | CVPR | VLN | Vision-and-language navigation: Interpreting visually-grounded navigation instructions in real environments | Data |
| 2019 | RAS | Dynamic-SLAM | Dynamic-SLAM: Semantic monocular visual localization and mapping based on deep learning in dynamic environment | Code |
| 2019 | WCSP | N/A | Integrated Wearable Indoor Positioning System Based On Visible Light Positioning And Inertial Navigation Using Unscented Kalman Filter | N/A |
| 2019 | ICRA | Ground then Navigate | Ground then Navigate: Language-guided Navigation in Dynamic Scenes | Code |
| 2023 | MEAS SCI TECHNOL | FDO-Calibr | FDO-Calibr: visual-aided IMU calibration based on frequency-domain optimization | N/A |
| 2024 | arxiv | HiFi-CS | Towards Open Vocabulary Visual Grounding For Robotic Grasping Using Vision-Language Models | N/A |
| 2025 | ECCV | Ferret-UI | Grounded Mobile UI Understanding with Multimodal LLMs | N/A |
3.8 Multi-image Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2025 | ACL | Migician | Migician: Revealing the Magic of Free-Form Multi-Image Grounding in Multimodal Large Language Models | Code/ Project |
| 2025 | arxiv | UniVG-R1 | UniVG-R1: Reasoning Guided Universal Visual Grounding with Reinforcement Learning | Code/ Project |
4. Datasets and Benchmarks
4.1 The Five Datasets for Classical Visual Grounding
4.2 The Other Datasets for Classical Visual Grounding
4.3 Dataset for the Newly Curated Scenarios
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | NeurIPS | D$^3$ | Described Object Detection: Liberating Object Detection with Flexible Expressions | Code |
A. Dataset for Generalized Visual Grounding
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2023 | CVPR | gRefCOCO | GRES: Generalized Referring Expression Segmentation | Code |
| 2024 | ICCV | Ref-ZOM | Beyond One-to-One: Rethinking the Referring Image Segmentation | Code |
B. Datasets and Benchmarks for GMLLMs
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | Arxiv | Inst-IT | Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning | Code / Project |
| 2024 | NeurIPS | HC-RefLoCo | A Large-Scale Human-Centric Benchmark for Referring Expression Comprehension in the LMM Era | Code |
| 2024 | ECCV | GVC | Llava-grounding: Grounded visual chat with large multimodal models | N/A |
| 2024 | ICLR | KOSMOS-2 | GROUNDING MULTIMODAL LARGE LANGUAGE MODELS TO THE WORLD | Code |
C. Dataset for Other Newly Curated Scenarios
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | CVPR | GigaGround | When visual grounding meets gigapixel-level large-scale scenes: Benchmark and approach | Code |
| 2025 | ACL | MGrounding-630k/MIG-Bench | Migician: Revealing the Magic of Free-Form Multi-Image Grounding in Multimodal Large Language Models | Code/ Project |
| 2025 | Arxiv | PixMMVP, PixCV-Bench (Pixel-level VG) | PixFoundation: Are We Heading in the Right Direction with Pixel-level Vision Foundation Models? | Code/ Project |
| 2025 | Arxiv | MoCentric-Bench (Pixel-level VG) | PixFoundation 2.0: Do Video Multi-Modal LLMs Use Motion in Visual Grounding? | Code/ Project |
5. Challenges And Outlook
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2024 | Arxiv | - | AI Models Collapse When Trained on Recursively Generated Data | N/A |
| 2024 | CVPR | RefCount | Referring expression counting | Code |
| 2024 | CVPR | GigaGround | When visual grounding meets gigapixel-level large-scale scenes: Benchmark and approach | Code |
| 2022 | CVPR | GLIP | Grounded language-image pretraining | Code |
| 2025 | ACL | Migician | Migician: Revealing the Magic of Free-Form Multi-Image Grounding in Multimodal Large Language Models | Code/ Project |
6. Other Valuable Survey and Project
| Year | Venue | Name | Paper Title / Paper Link | Code / Project |
|---|---|---|---|---|
| 2018 | TPAMI | N/A | Multimodal machine learning: A survey and taxonomy | N/A |
| 2020 | TMM | N/A | Referring expression comprehension: A survey of methods and datasets | N/A |
| 2021 | Github | awesome-grounding | N/A | Project |
| 2023 | TPAMI | Awesome-Open-Vocabulary | Towards Open Vocabulary Learning: A Survey | Project |
| 2023 | TPAMI | N/A | Multimodal learning with transformers: A survey | N/A |
| 2024 | Github | awesome-described-object-detection | N/A | awesome-described-object-detection |
Acknowledgement
This survey took half a year to complete, and the process was laborious and burdensome.
Building up this GitHub repository also required significant effort. We would like to thank the following individuals for their contributions to completing this project: Baochen Xiong, Yifan Xu, Yaguang Song, Menghao Hu, Han Jiang, Hao Liu, Chenlin Zhao, Fang Peng, Xudong Yao, Zibo Shao, Kaichen Li, Jianhao Huang, Xianbing Yang, Shuaitong Li, Jisheng Yin, Yupeng Wu, Shaobo Xie, etc.
Contact
Email: xiaolinhui16@mails.ucas.ac.cn. Any kind discussions are welcomed!
Star History
Similar repos
Contributors
Languages
Shell
100.0%