
Collection of AWESOME vision-language models for vision tasks
3,126
107 commits
updated Sep 16, 2026
README
Awesome Vision-Language Models 
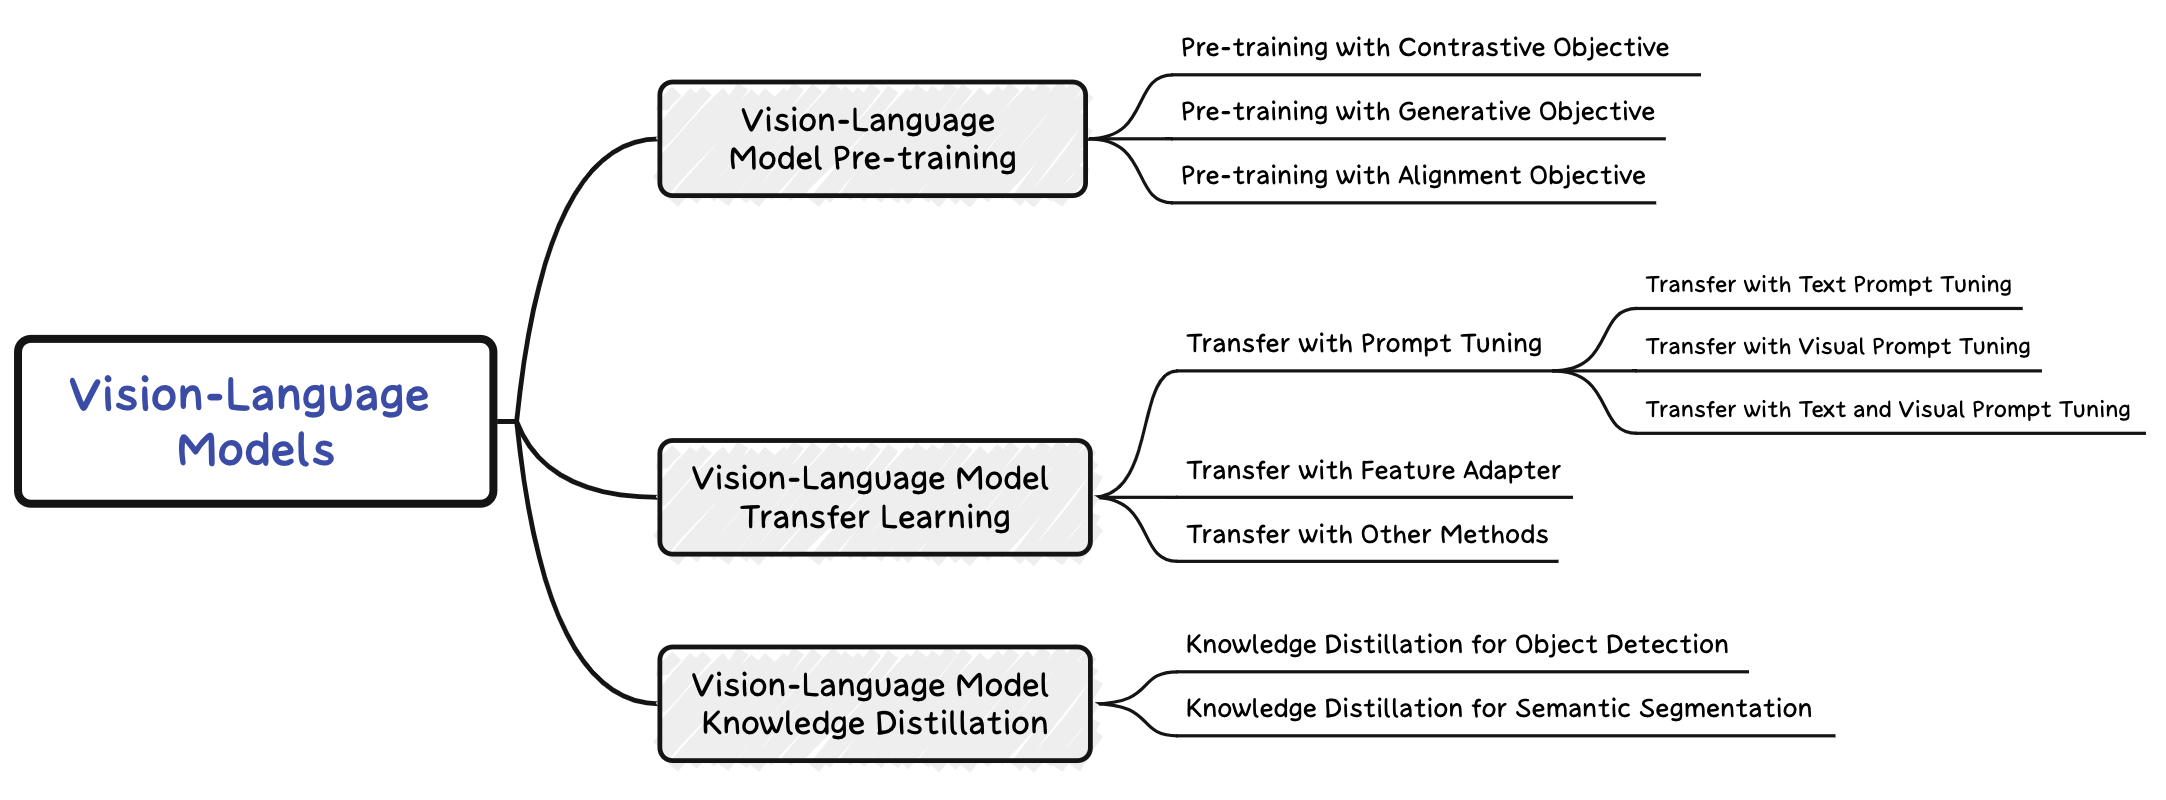
This is the repository of Vision Language Models for Vision Tasks: a Survey, a systematic survey of VLM studies in various visual recognition tasks including image classification, object detection, semantic segmentation, etc. For details, please refer to:
Vision-Language Models for Vision Tasks: A Survey [Paper]
IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), 2024
🤩 Our paper is selected into TPAMI Top 50 Popular Paper List !!


Feel free to pull requests or contact us if you find any related papers that are not included here.
The process to submit a pull request is as follows:
- a. Fork the project into your own repository.
- b. Add the Title, Paper link, Conference, Project/Code link in
README.mdusing the following format:
|[Title](Paper Link)|Conference|[Code/Project](Code/Project link)|
- c. Submit the pull request to this branch.
We plan to update the arXiv version of our survey paper soon. If your paper is missing from this repository, feel free to contact us or open an issue!
🔥 News


📅 Last update on 2025/10/14
VLMs and Synthetic Data
- [CVPR 2025] Synthetic Data is an Elegant GIFT for Continual Vision-Language Models [Paper][Code]
- [CVPR 2025] Enhancing Vision-Language Compositional Understanding with Multimodal Synthetic Data [Paper]
- [OpenReview 2025] A Survey on Bridging VLMs and Synthetic Data [Paper][Code]
VLM Pre-training Methods
- [NeurIPS 2024] PLIP: Language-Image Pre-training for Person Representation Learning [Paper][Code]
- [NeurIPS 2024] LoTLIP: Improving Language-Image Pre-training for Long Text Understanding [Paper][Code]
- [NeurIPS 2024] Accelerating Pre-training of Multimodal LLMs via Chain-of-Sight [Paper][Code]
VLM Transfer Learning Methods
- [ICCV 2025] One Last Attention for Your Vision-Language Model [Paper][Code]
- [ICCV 2025] Hierarchical Cross-modal Prompt Learning for Vision-Language Models [Paper][Code]
- [CVPR 2025] DPC: Dual-Prompt Collaboration for Tuning Vision-Language Models [Paper][Code]
- [CVPR 2025] O-TPT: Orthogonality Constraints for Calibrating Test-time Prompt Tuning in Vision-Language Models [Paper][Code]
- [CVPR 2025] R-TPT: Improving Adversarial Robustness of Vision-Language Models through Test-Time Prompt Tuning [Paper][Code]
- [CVPR 2025] TAPT: Test-Time Adversarial Prompt Tuning for Robust Inference in Vision-Language Models [Paper][Code]
- [CVPR 2025] Skip Tuning: Pre-trained Vision-Language Models are Effective and Efficient Adapters Themselves [Paper][Code]
- [CVPR 2025] Adaptive Parameter Selection for Tuning Vision-Language Models [Paper]
- [CVPR 2025] Task-Aware Clustering for Prompting Vision-Language Models [Paper][Code]
- [CVPR 2025] Bayesian Test-Time Adaptation for Vision-Language Models [Paper]
- [CVPR 2025] NLPrompt: Noise-Label Prompt Learning for Vision-Language Models [Paper][Code]
- [CVPR 2025] Realistic Test-Time Adaptation of Vision-Language Models [Paper][Code]
- [NeurIPS 2024] ControlMLLM: Training-Free Visual Prompt Learning for Multimodal Large Language Models [Paper][Code]
- [NeurIPS 2024] Leveraging Hallucinations to Reduce Manual Prompt Dependency in Promptable Segmentation [Paper][Code]
- [NeurIPS 2024] Visual Fourier Prompt Tuning [Paper][Code]
- [NeurIPS 2024] Improving Visual Prompt Tuning by Gaussian Neighborhood Minimization for Long-Tailed Visual Recognition [Paper][Code]
- [NeurIPS 2024] Few-Shot Adversarial Prompt Learning on Vision-Language Models [Paper][Code]
- [NeurIPS 2024] Visual Prompt Tuning in Null Space for Continual Learning [Paper][Code]
- [NeurIPS 2024] IPO: Interpretable Prompt Optimization for Vision-Language Models [Paper]
- [NeurIPS 2024] LoCoOp: Few-Shot Out-of-Distribution Detection via Prompt Learning [Paper][Code]
VLM Knowledge Distillation for Detection
- [NeurIPS 2024] Scaling Open-Vocabulary Object Detection [Paper][Code]
- [NeurIPS 2024] Bridging the Gap between Object and Image-level Representations for Open-Vocabulary Detection [Paper][Code]
- [NeurIPS 2024] CoDet: Co-Occurrence Guided Region-Word Alignment for Open-Vocabulary Object Detection [Paper][Code]
VLM Knowledge Distillation for Segmentation
- [NeurIPS 2024] Relationship Prompt Learning is Enough for Open-Vocabulary Semantic Segmentation [Paper]
VLM Knowledge Distillation for Other Vision Tasks
Abstract
Most visual recognition studies rely heavily on crowd-labelled data in deep neural networks (DNNs) training, and they usually train a DNN for each single visual recognition task, leading to a laborious and time-consuming visual recognition paradigm. To address the two challenges, Vision Language Models (VLMs) have been intensively investigated recently, which learns rich vision-language correlation from web-scale image-text pairs that are almost infinitely available on the Internet and enables zero-shot predictions on various visual recognition tasks with a single VLM. This paper provides a systematic review of visual language models for various visual recognition tasks, including: (1) the background that introduces the development of visual recognition paradigms; (2) the foundations of VLM that summarize the widely-adopted network architectures, pre-training objectives, and downstream tasks; (3) the widely adopted datasets in VLM pre-training and evaluations; (4) the review and categorization of existing VLM pre-training methods, VLM transfer learning methods, and VLM knowledge distillation methods; (5) the benchmarking, analysis and discussion of the reviewed methods; (6) several research challenges and potential research directions that could be pursued in the future VLM studies for visual recognition.
Citation
If you find our work useful in your research, please consider citing:
@article{zhang2024vision,
  title={Vision-language models for vision tasks: A survey},
  author={Zhang, Jingyi and Huang, Jiaxing and Jin, Sheng and Lu, Shijian},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  year={2024},
  publisher={IEEE}
}
Menu
- Datasets
- Vision-Language Pre-training Methods
- Vision-Language Model Transfer Learning Methods
- Vision-Language Model Knowledge Distillation Methods
Datasets
Datasets for VLM Pre-training
| Dataset | Year | Num of Image-Text Paris | Language | Project |
|---|---|---|---|---|
| SBU Caption | 2011 | 1M | English | Project |
| COCO Caption | 2016 | 1.5M | English | Project |
| Yahoo Flickr Creative Commons 100 Million | 2016 | 100M | English | Project |
| Visual Genome | 2017 | 5.4M | English | Project |
| Conceptual Captions 3M | 2018 | 3.3M | English | Project |
| Localized Narratives | 2020 | 0.87M | English | Project |
| Conceptual 12M | 2021 | 12M | English | Project |
| Wikipedia-based Image Text | 2021 | 37.6M | 108 Languages | Project |
| Red Caps | 2021 | 12M | English | Project |
| LAION400M | 2021 | 400M | English | Project |
| LAION5B | 2022 | 5B | Over 100 Languages | Project |
| WuKong | 2022 | 100M | Chinese | Project |
| CLIP | 2021 | 400M | English | - |
| ALIGN | 2021 | 1.8B | English | - |
| FILIP | 2021 | 300M | English | - |
| WebLI | 2022 | 12B | English | - |
Datasets for VLM Evaluation
Image Classification
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| MNIST | 1998 | 10 | 60,000 | 10,000 | Accuracy | Project |
| Caltech-101 | 2004 | 102 | 3,060 | 6,085 | Mean Per Class | Project |
| PASCAL VOC 2007 | 2007 | 20 | 5,011 | 4,952 | 11-point mAP | Project |
| Oxford 102 Flowers | 2008 | 102 | 2,040 | 6,149 | Mean Per Class | Project |
| CIFAR-10 | 2009 | 10 | 50,000 | 10,000 | Accuracy | Project |
| CIFAR-100 | 2009 | 100 | 50,000 | 10,000 | Accuracy | Project |
| ImageNet-1k | 2009 | 1000 | 1,281,167 | 50,000 | Accuracy | Project |
| SUN397 | 2010 | 397 | 19,850 | 19,850 | Accuracy | Project |
| SVHN | 2011 | 10 | 73,257 | 26,032 | Accuracy | Project |
| STL-10 | 2011 | 10 | 1,000 | 8,000 | Accuracy | Project |
| GTSRB | 2011 | 43 | 26,640 | 12,630 | Accuracy | Project |
| KITTI Distance | 2012 | 4 | 6,770 | 711 | Accuracy | Project |
| IIIT5k | 2012 | 36 | 2,000 | 3,000 | Accuracy | Project |
| Oxford-IIIT PETS | 2012 | 37 | 3,680 | 3,669 | Mean Per Class | Project |
| Stanford Cars | 2013 | 196 | 8,144 | 8,041 | Accuracy | Project |
| FGVC Aircraft | 2013 | 100 | 6,667 | 3,333 | Mean Per Class | Project |
| Facial Emotion | 2013 | 8 | 32,140 | 3,574 | Accuracy | Project |
| Rendered SST2 | 2013 | 2 | 7,792 | 1,821 | Accuracy | Project |
| Describable Textures | 2014 | 47 | 3,760 | 1,880 | Accuracy | Project |
| Food-101 | 2014 | 101 | 75,750 | 25,250 | Accuracy | Project |
| Birdsnap | 2014 | 500 | 42,283 | 2,149 | Accuracy | Project |
| RESISC45 | 2017 | 45 | 3,150 | 25,200 | Accuracy | Project |
| CLEVR Counts | 2017 | 8 | 2,000 | 500 | Accuracy | Project |
| PatchCamelyon | 2018 | 2 | 294,912 | 32,768 | Accuracy | Project |
| EuroSAT | 2019 | 10 | 10,000 | 5,000 | Accuracy | Project |
| Hateful Memes | 2020 | 2 | 8,500 | 500 | ROC AUC | Project |
| Country211 | 2021 | 211 | 43,200 | 21,100 | Accuracy | Project |
Image-Text Retrieval
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| Flickr30k | 2014 | - | 31,783 | - | Recall | Project |
| COCO Caption | 2015 | - | 82,783 | 5,000 | Recall | Project |
Action Recognition
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| UCF101 | 2012 | 101 | 9,537 | 1,794 | Accuracy | Project |
| Kinetics700 | 2019 | 700 | 494,801 | 31,669 | Mean (top1, top5) | Project |
| RareAct | 2020 | 122 | 7,607 | - | mWAP, mSAP | Project |
Object Detection
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| COCO 2014 Detection | 2014 | 80 | 83,000 | 41,000 | Box mAP | Project |
| COCO 2017 Detection | 2017 | 80 | 118,000 | 5,000 | Box mAP | Project |
| LVIS | 2019 | 1203 | 118,000 | 5,000 | Box mAP | Project |
| ODinW | 2022 | 314 | 132,413 | 20,070 | Box mAP | Project |
Semantic Segmentation
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| PASCAL VOC 2012 | 2012 | 20 | 1,464 | 1,449 | mIoU | Project |
| PASCAL Content | 2014 | 459 | 4,998 | 5,105 | mIoU | Project |
| Cityscapes | 2016 | 19 | 2,975 | 500 | mIoU | Project |
| ADE20k | 2017 | 150 | 25,574 | 2,000 | mIoU | Project |
Vision-Language Pre-training Methods
Pre-training with Contrastive Objective
Pre-training with Generative Objective
Pre-training with Alignment Objective
Vision-Language Model Transfer Learning Methods
Transfer with Prompt Tuning
Transfer with Text Prompt Tuning
Transfer with Visual Prompt Tuning
Transfer with Text and Visual Prompt Tuning
Transfer with Feature Adapter
Transfer with Other Methods
Vision-Language Model Knowledge Distillation Methods
Knowledge Distillation for Object Detection
Knowledge Distillation for Semantic Segmentation
Knowledge Distillation for Other Tasks
Contributors


Similar repos


Collection of AWESOME vision-language models for vision tasks
3,126
107 commits
updated Sep 16, 2026
README
Awesome Vision-Language Models
This is the repository of Vision Language Models for Vision Tasks: a Survey, a systematic survey of VLM studies in various visual recognition tasks including image classification, object detection, semantic segmentation, etc. For details, please refer to:
Vision-Language Models for Vision Tasks: A Survey [Paper]
IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), 2024
🤩 Our paper is selected into TPAMI Top 50 Popular Paper List !!
Feel free to pull requests or contact us if you find any related papers that are not included here.
The process to submit a pull request is as follows:
- a. Fork the project into your own repository.
- b. Add the Title, Paper link, Conference, Project/Code link in
README.mdusing the following format:
|[Title](Paper Link)|Conference|[Code/Project](Code/Project link)|
- c. Submit the pull request to this branch.
We plan to update the arXiv version of our survey paper soon. If your paper is missing from this repository, feel free to contact us or open an issue!
🔥 News
📅 Last update on 2025/10/14
VLMs and Synthetic Data
- [CVPR 2025] Synthetic Data is an Elegant GIFT for Continual Vision-Language Models [Paper][Code]
- [CVPR 2025] Enhancing Vision-Language Compositional Understanding with Multimodal Synthetic Data [Paper]
- [OpenReview 2025] A Survey on Bridging VLMs and Synthetic Data [Paper][Code]
VLM Pre-training Methods
- [NeurIPS 2024] PLIP: Language-Image Pre-training for Person Representation Learning [Paper][Code]
- [NeurIPS 2024] LoTLIP: Improving Language-Image Pre-training for Long Text Understanding [Paper][Code]
- [NeurIPS 2024] Accelerating Pre-training of Multimodal LLMs via Chain-of-Sight [Paper][Code]
VLM Transfer Learning Methods
- [ICCV 2025] One Last Attention for Your Vision-Language Model [Paper][Code]
- [ICCV 2025] Hierarchical Cross-modal Prompt Learning for Vision-Language Models [Paper][Code]
- [CVPR 2025] DPC: Dual-Prompt Collaboration for Tuning Vision-Language Models [Paper][Code]
- [CVPR 2025] O-TPT: Orthogonality Constraints for Calibrating Test-time Prompt Tuning in Vision-Language Models [Paper][Code]
- [CVPR 2025] R-TPT: Improving Adversarial Robustness of Vision-Language Models through Test-Time Prompt Tuning [Paper][Code]
- [CVPR 2025] TAPT: Test-Time Adversarial Prompt Tuning for Robust Inference in Vision-Language Models [Paper][Code]
- [CVPR 2025] Skip Tuning: Pre-trained Vision-Language Models are Effective and Efficient Adapters Themselves [Paper][Code]
- [CVPR 2025] Adaptive Parameter Selection for Tuning Vision-Language Models [Paper]
- [CVPR 2025] Task-Aware Clustering for Prompting Vision-Language Models [Paper][Code]
- [CVPR 2025] Bayesian Test-Time Adaptation for Vision-Language Models [Paper]
- [CVPR 2025] NLPrompt: Noise-Label Prompt Learning for Vision-Language Models [Paper][Code]
- [CVPR 2025] Realistic Test-Time Adaptation of Vision-Language Models [Paper][Code]
- [NeurIPS 2024] ControlMLLM: Training-Free Visual Prompt Learning for Multimodal Large Language Models [Paper][Code]
- [NeurIPS 2024] Leveraging Hallucinations to Reduce Manual Prompt Dependency in Promptable Segmentation [Paper][Code]
- [NeurIPS 2024] Visual Fourier Prompt Tuning [Paper][Code]
- [NeurIPS 2024] Improving Visual Prompt Tuning by Gaussian Neighborhood Minimization for Long-Tailed Visual Recognition [Paper][Code]
- [NeurIPS 2024] Few-Shot Adversarial Prompt Learning on Vision-Language Models [Paper][Code]
- [NeurIPS 2024] Visual Prompt Tuning in Null Space for Continual Learning [Paper][Code]
- [NeurIPS 2024] IPO: Interpretable Prompt Optimization for Vision-Language Models [Paper]
- [NeurIPS 2024] LoCoOp: Few-Shot Out-of-Distribution Detection via Prompt Learning [Paper][Code]
VLM Knowledge Distillation for Detection
- [NeurIPS 2024] Scaling Open-Vocabulary Object Detection [Paper][Code]
- [NeurIPS 2024] Bridging the Gap between Object and Image-level Representations for Open-Vocabulary Detection [Paper][Code]
- [NeurIPS 2024] CoDet: Co-Occurrence Guided Region-Word Alignment for Open-Vocabulary Object Detection [Paper][Code]
VLM Knowledge Distillation for Segmentation
- [NeurIPS 2024] Relationship Prompt Learning is Enough for Open-Vocabulary Semantic Segmentation [Paper]
VLM Knowledge Distillation for Other Vision Tasks
Abstract
Most visual recognition studies rely heavily on crowd-labelled data in deep neural networks (DNNs) training, and they usually train a DNN for each single visual recognition task, leading to a laborious and time-consuming visual recognition paradigm. To address the two challenges, Vision Language Models (VLMs) have been intensively investigated recently, which learns rich vision-language correlation from web-scale image-text pairs that are almost infinitely available on the Internet and enables zero-shot predictions on various visual recognition tasks with a single VLM. This paper provides a systematic review of visual language models for various visual recognition tasks, including: (1) the background that introduces the development of visual recognition paradigms; (2) the foundations of VLM that summarize the widely-adopted network architectures, pre-training objectives, and downstream tasks; (3) the widely adopted datasets in VLM pre-training and evaluations; (4) the review and categorization of existing VLM pre-training methods, VLM transfer learning methods, and VLM knowledge distillation methods; (5) the benchmarking, analysis and discussion of the reviewed methods; (6) several research challenges and potential research directions that could be pursued in the future VLM studies for visual recognition.
Citation
If you find our work useful in your research, please consider citing:
@article{zhang2024vision,
  title={Vision-language models for vision tasks: A survey},
  author={Zhang, Jingyi and Huang, Jiaxing and Jin, Sheng and Lu, Shijian},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  year={2024},
  publisher={IEEE}
}
Menu
- Datasets
- Vision-Language Pre-training Methods
- Vision-Language Model Transfer Learning Methods
- Vision-Language Model Knowledge Distillation Methods
Datasets
Datasets for VLM Pre-training
| Dataset | Year | Num of Image-Text Paris | Language | Project |
|---|---|---|---|---|
| SBU Caption | 2011 | 1M | English | Project |
| COCO Caption | 2016 | 1.5M | English | Project |
| Yahoo Flickr Creative Commons 100 Million | 2016 | 100M | English | Project |
| Visual Genome | 2017 | 5.4M | English | Project |
| Conceptual Captions 3M | 2018 | 3.3M | English | Project |
| Localized Narratives | 2020 | 0.87M | English | Project |
| Conceptual 12M | 2021 | 12M | English | Project |
| Wikipedia-based Image Text | 2021 | 37.6M | 108 Languages | Project |
| Red Caps | 2021 | 12M | English | Project |
| LAION400M | 2021 | 400M | English | Project |
| LAION5B | 2022 | 5B | Over 100 Languages | Project |
| WuKong | 2022 | 100M | Chinese | Project |
| CLIP | 2021 | 400M | English | - |
| ALIGN | 2021 | 1.8B | English | - |
| FILIP | 2021 | 300M | English | - |
| WebLI | 2022 | 12B | English | - |
Datasets for VLM Evaluation
Image Classification
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| MNIST | 1998 | 10 | 60,000 | 10,000 | Accuracy | Project |
| Caltech-101 | 2004 | 102 | 3,060 | 6,085 | Mean Per Class | Project |
| PASCAL VOC 2007 | 2007 | 20 | 5,011 | 4,952 | 11-point mAP | Project |
| Oxford 102 Flowers | 2008 | 102 | 2,040 | 6,149 | Mean Per Class | Project |
| CIFAR-10 | 2009 | 10 | 50,000 | 10,000 | Accuracy | Project |
| CIFAR-100 | 2009 | 100 | 50,000 | 10,000 | Accuracy | Project |
| ImageNet-1k | 2009 | 1000 | 1,281,167 | 50,000 | Accuracy | Project |
| SUN397 | 2010 | 397 | 19,850 | 19,850 | Accuracy | Project |
| SVHN | 2011 | 10 | 73,257 | 26,032 | Accuracy | Project |
| STL-10 | 2011 | 10 | 1,000 | 8,000 | Accuracy | Project |
| GTSRB | 2011 | 43 | 26,640 | 12,630 | Accuracy | Project |
| KITTI Distance | 2012 | 4 | 6,770 | 711 | Accuracy | Project |
| IIIT5k | 2012 | 36 | 2,000 | 3,000 | Accuracy | Project |
| Oxford-IIIT PETS | 2012 | 37 | 3,680 | 3,669 | Mean Per Class | Project |
| Stanford Cars | 2013 | 196 | 8,144 | 8,041 | Accuracy | Project |
| FGVC Aircraft | 2013 | 100 | 6,667 | 3,333 | Mean Per Class | Project |
| Facial Emotion | 2013 | 8 | 32,140 | 3,574 | Accuracy | Project |
| Rendered SST2 | 2013 | 2 | 7,792 | 1,821 | Accuracy | Project |
| Describable Textures | 2014 | 47 | 3,760 | 1,880 | Accuracy | Project |
| Food-101 | 2014 | 101 | 75,750 | 25,250 | Accuracy | Project |
| Birdsnap | 2014 | 500 | 42,283 | 2,149 | Accuracy | Project |
| RESISC45 | 2017 | 45 | 3,150 | 25,200 | Accuracy | Project |
| CLEVR Counts | 2017 | 8 | 2,000 | 500 | Accuracy | Project |
| PatchCamelyon | 2018 | 2 | 294,912 | 32,768 | Accuracy | Project |
| EuroSAT | 2019 | 10 | 10,000 | 5,000 | Accuracy | Project |
| Hateful Memes | 2020 | 2 | 8,500 | 500 | ROC AUC | Project |
| Country211 | 2021 | 211 | 43,200 | 21,100 | Accuracy | Project |
Image-Text Retrieval
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| Flickr30k | 2014 | - | 31,783 | - | Recall | Project |
| COCO Caption | 2015 | - | 82,783 | 5,000 | Recall | Project |
Action Recognition
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| UCF101 | 2012 | 101 | 9,537 | 1,794 | Accuracy | Project |
| Kinetics700 | 2019 | 700 | 494,801 | 31,669 | Mean (top1, top5) | Project |
| RareAct | 2020 | 122 | 7,607 | - | mWAP, mSAP | Project |
Object Detection
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| COCO 2014 Detection | 2014 | 80 | 83,000 | 41,000 | Box mAP | Project |
| COCO 2017 Detection | 2017 | 80 | 118,000 | 5,000 | Box mAP | Project |
| LVIS | 2019 | 1203 | 118,000 | 5,000 | Box mAP | Project |
| ODinW | 2022 | 314 | 132,413 | 20,070 | Box mAP | Project |
Semantic Segmentation
| Dataset | Year | Classes | Training | Testing | Evaluation Metric | Project |
|---|---|---|---|---|---|---|
| PASCAL VOC 2012 | 2012 | 20 | 1,464 | 1,449 | mIoU | Project |
| PASCAL Content | 2014 | 459 | 4,998 | 5,105 | mIoU | Project |
| Cityscapes | 2016 | 19 | 2,975 | 500 | mIoU | Project |
| ADE20k | 2017 | 150 | 25,574 | 2,000 | mIoU | Project |