
README
A Survey on Knowledge Distillation of Vision-Language Models

🔔 News
- [10/09/2026] Camera-ready version for EMNLP 2026 is now available [PDF].
- [21/08/2026] 🎉 This survey has been accepted by the Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026!
📝 Introduction
This paper provides the first dedicated survey of knowledge distillation for vision-language models. We propose a unified taxonomy that organizes methods along three orthogonal views: knowledge type, teacher accessibility, and structural compatibility, and use it to organize methods across major VLM distillation settings.
📊 Taxonomy
Below is the taxonomy summarizing the landscape of knowledge distillation research for VLMs:
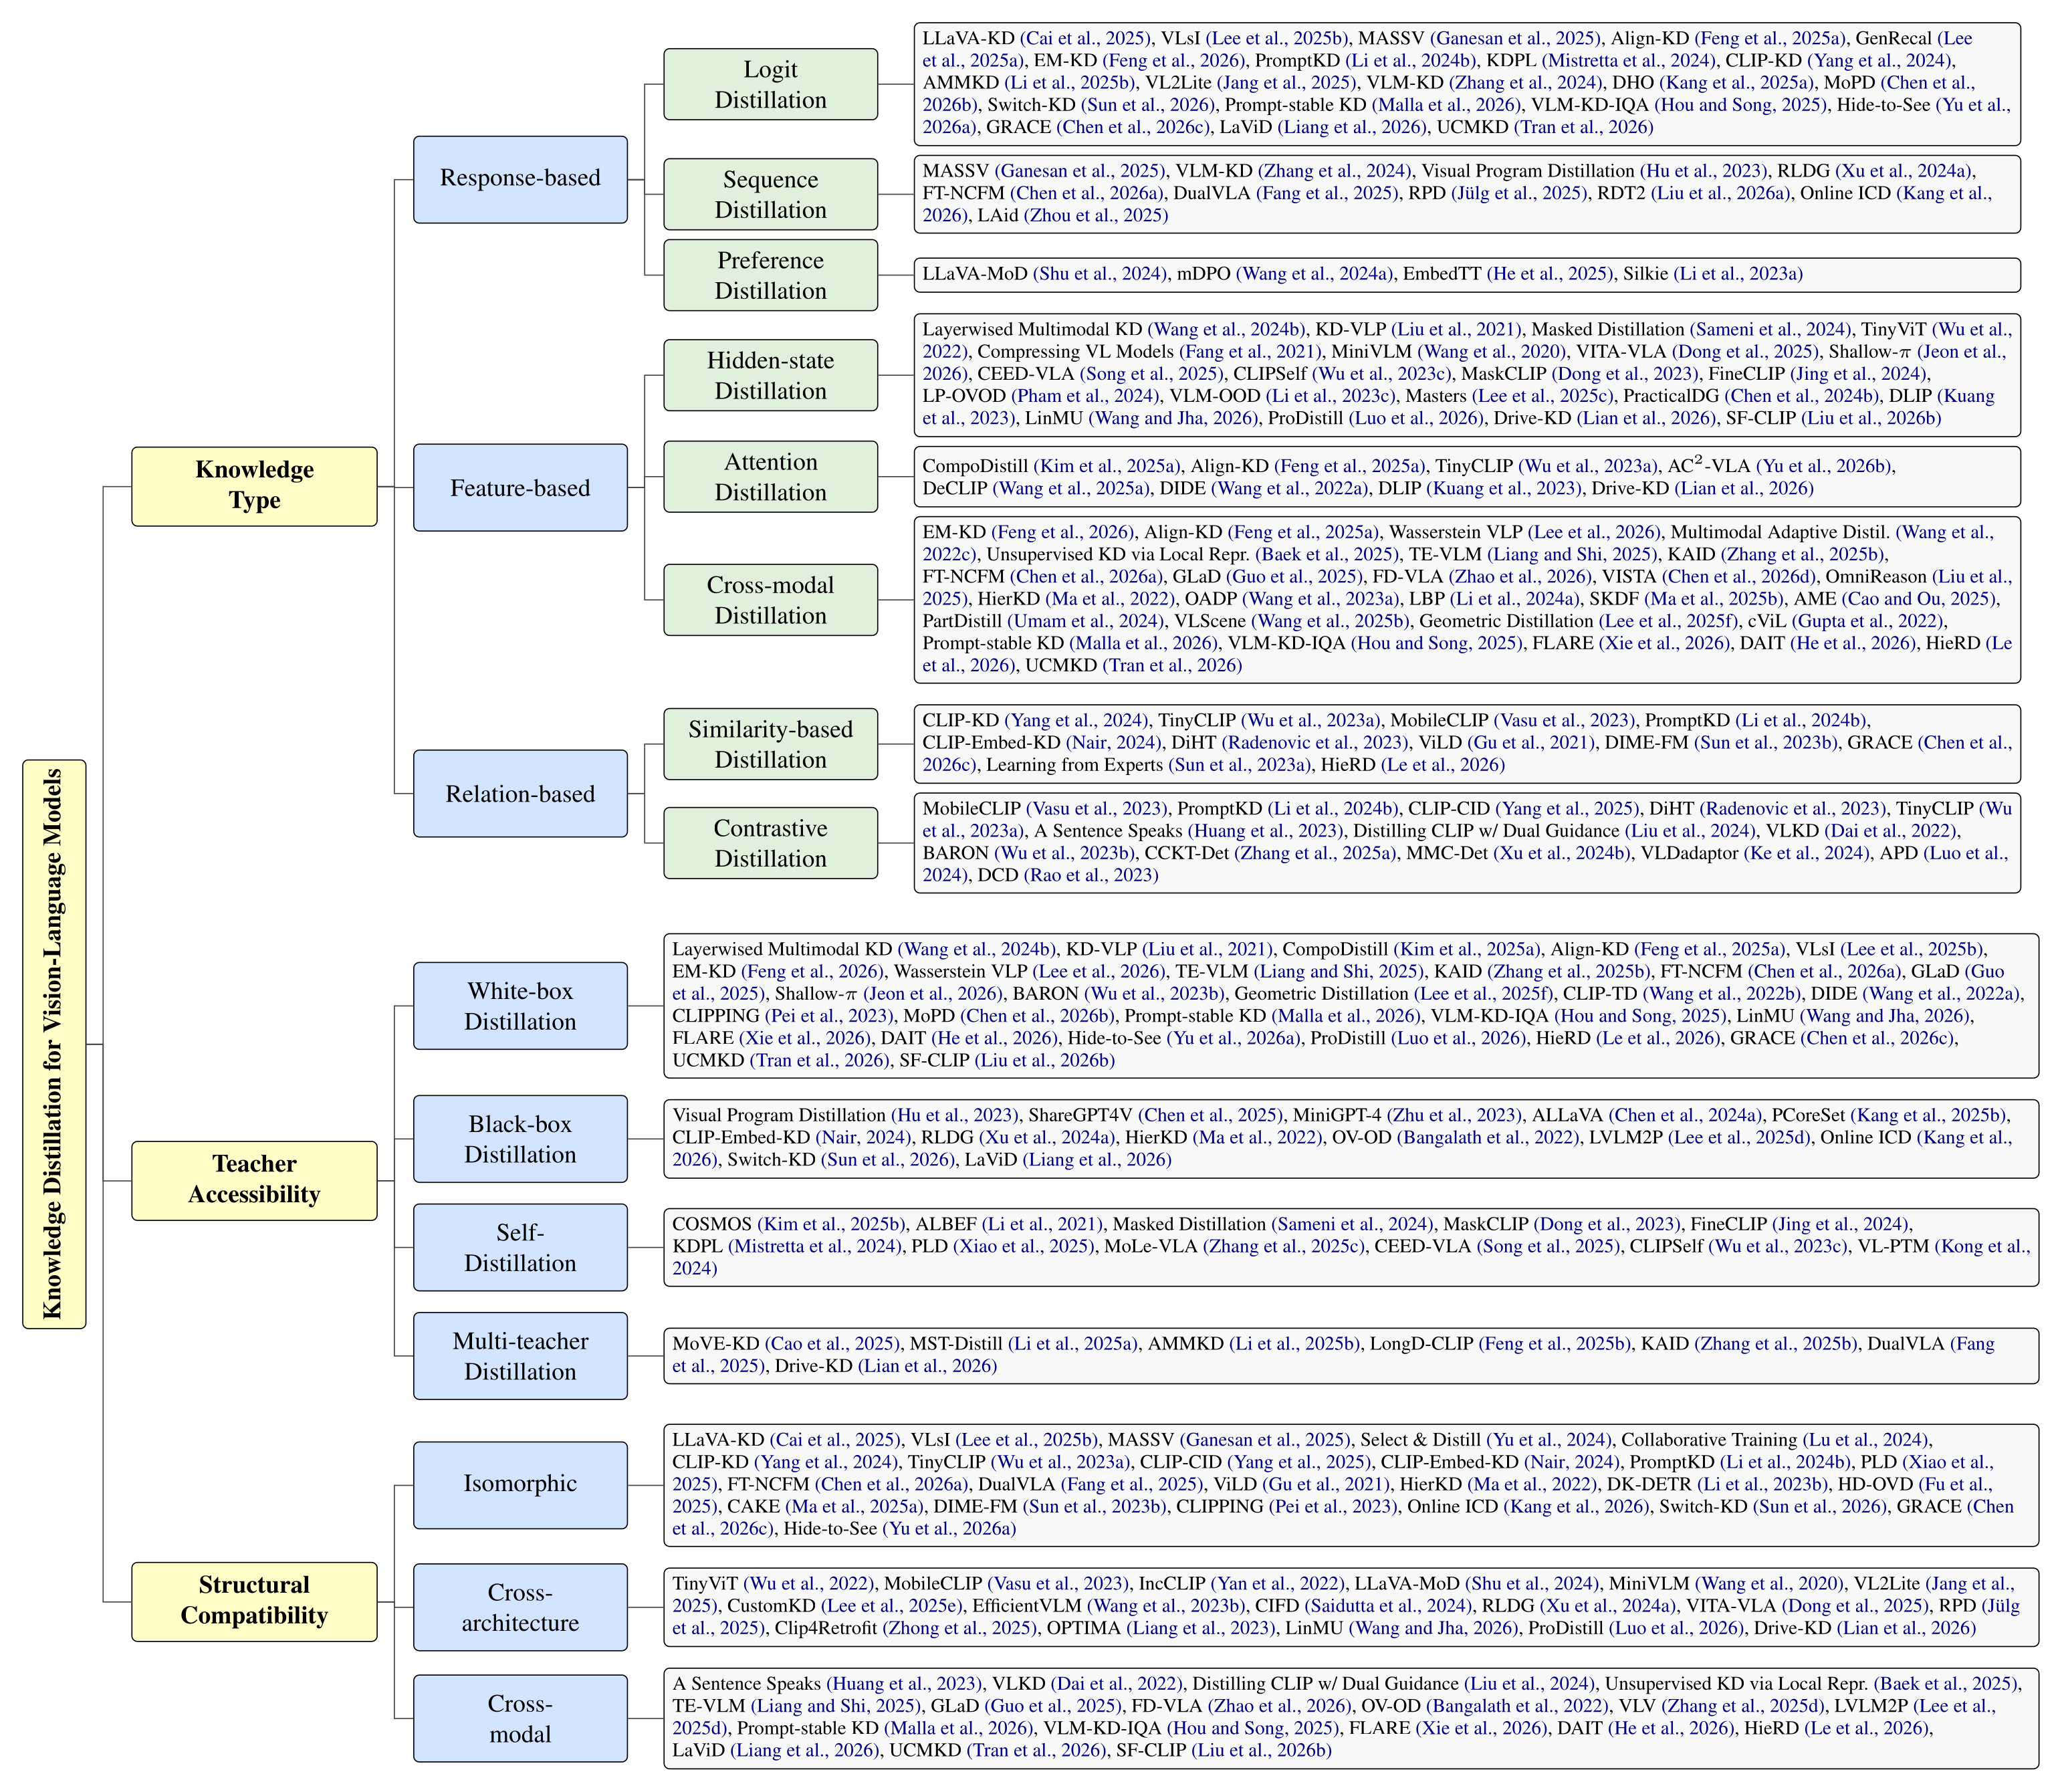
This survey organizes VLM distillation methods along three orthogonal axes. Each axis is illustrated below, immediately before the corresponding paper sections.
| Axis | Question | Sections |
|---|---|---|
| Knowledge Type | What does the student learn from the teacher? | I · II · III |
| Teacher Accessibility | What can the student observe about the teacher? | IV · V · VI · VII |
| Structural Compatibility | What must be bridged before distillation can proceed? | VIII · IX · X |
| Application | Section |
|---|---|
| Vision-Language-Action | VLA |
| Vision-Language Embedding | Embedding |
| Semantic Segmentation | Segmentation |
| Open-Vocabulary Object Detection | OVD |
Knowledge Type
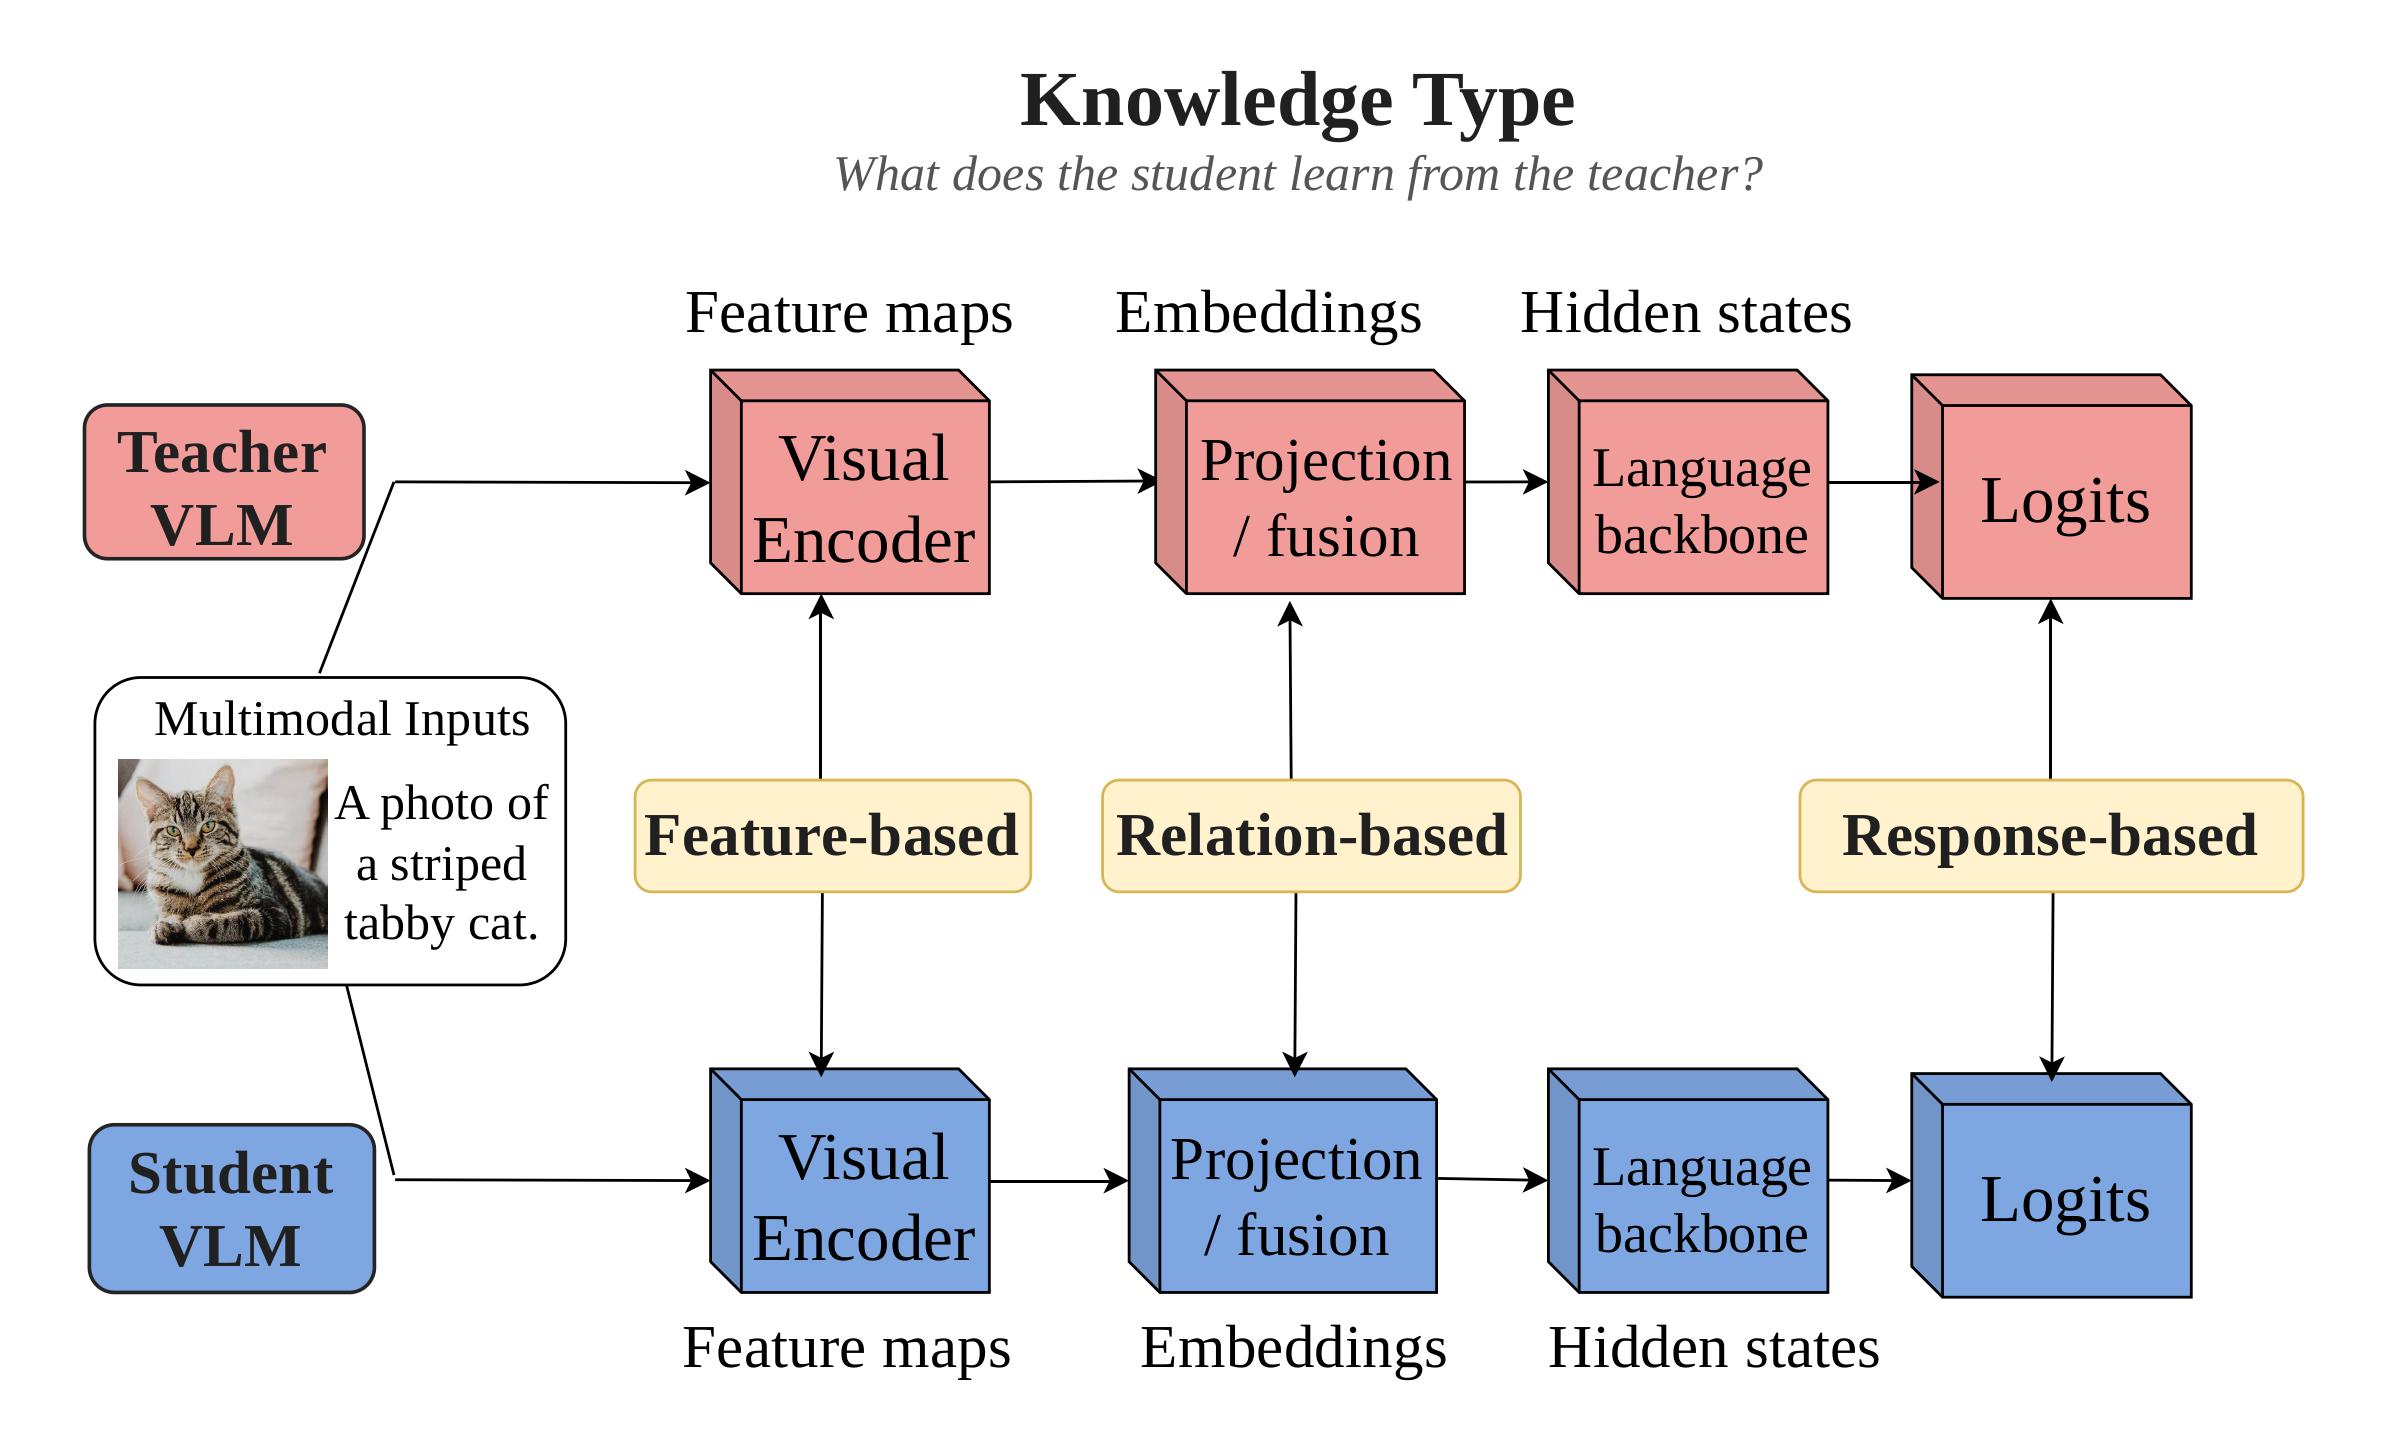
| Branch | Section |
|---|---|
| Response-based Distillation | Section I |
| Feature-based Distillation | Section II |
| Relation-based Distillation | Section III |
Section I: Response-based Distillation
Logit Distillation
- MoPD: Mixture-of-Prompts Distillation for Vision-Language Models [Paper]
- Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- Hide to See: Reasoning-prefix Masking for Visual-anchored Thinking in VLM Distillation [Paper]
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- LLaVA-KD: A Framework of Distilling Multimodal Large Language Models [Paper]
- VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models [Paper]
- MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models [Paper]
- GenRecal: Generation after Recalibration from Large to Small Vision-Language Models [Paper]
- EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens [Paper]
- AMMKD: Adaptive Multimodal Multi-Teacher Distillation for Lightweight Vision-Language Models [Paper]
- VL2Lite: Task-Specific Knowledge Distillation from Large Vision-Language Models to Lightweight Networks [Paper]
- DHO: Simple yet Effective Semi-supervised Knowledge Distillation from Vision-Language Models via Dual-Head Optimization [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- Improving Zero-Shot Generalization of Learned Prompts via Unsupervised Knowledge Distillation [Paper]
- VLM-KD: Knowledge Distillation from VLM for Long-Tail Visual Recognition [Paper]
- CLIP-KD: An Empirical Study of CLIP Model Distillation [Paper]


Sequence Distillation
- RDT2: Exploring the Scaling Limit of UMI Data Towards Zero-Shot Cross-Embodiment Generalization [Paper]
- MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
- Refined Policy Distillation: From VLA Generalists to RL Experts [Paper]
- Online In-Context Distillation for Low-Resource Vision Language Models [Paper]
- Towards Long-window Anchoring in Vision-Language Model Distillation [Paper]
- VLM-KD: Knowledge Distillation from VLM for Long-Tail Visual Recognition [Paper]
- Visual Program Distillation: Distilling Tools and Programmatic Reasoning into Vision-Language Models [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
Preference Distillation
- Embedding the Teacher: Distilling vLLM Preferences for Scalable Image Retrieval [Paper]
- LLaVA-MoD: Making LLaVA Tiny via MoE Knowledge Distillation [Paper]
- mDPO: Conditional Preference Optimization for Multimodal Large Language Models [Paper]
- Silkie: Preference Distillation for Large Visual Language Models [Paper]
Section II: Feature-based Distillation
Hidden-state Distillation
- Shallow-π: Knowledge Distillation for Flow-based VLAs [Paper]
- LinMU: Multimodal Understanding Made Linear [Paper]
- Prodistill: A Progressive Prompting Framework for Fine-Grained VLM Distillation [Paper]
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- SF-CLIP: CLIP-based Arbitrary Style Image Retrieval with Style and Fine-Grained Semantic Enhancement [Paper]
- VITA-VLA: Efficiently Teaching Vision-Language Models to Act via Action Expert Distillation [Paper]
- CEED-VLA: Consistency Vision-Language-Action Model with Early-Exit Decoding [Paper]
- Masking Teacher and Reinforcing Student for Distilling Vision-Language Models [Paper]
- Layerwised Multimodal Knowledge Distillation for Vision-Language Pretrained Model [Paper]
- Building Vision-Language Models on Solid Foundations with Masked Distillation [Paper]
- FineCLIP: Self-distilled Region-based CLIP for Better Fine-grained Understanding [Paper]
- LP-OVOD: Open-Vocabulary Object Detection by Linear Probing [Paper]
- PracticalDG: Perturbation Distillation on Vision-Language Models for Hybrid Domain Generalization [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- MaskCLIP: Masked Self-Distillation Advances Contrastive Language-Image Pretraining [Paper]
- Distilling Large Vision-Language Model with Out-of-Distribution Generalizability [Paper]
- DLIP: Distilling Language-Image Pre-training [Paper]
- KD-VLP: Improving End-to-End Vision-and-Language Pretraining with Object Knowledge Distillation [Paper]
- TinyViT: Fast Pretraining Distillation for Small Vision Transformers [Paper]
- Compressing Visual-Linguistic Model via Knowledge Distillation [Paper]
- MiniVLM: A Smaller and Faster Vision-Language Model [Paper]


Attention Distillation
- AC^2-VLA: Action-Context-Aware Adaptive Computation in Vision-Language-Action Models for Efficient Robotic Manipulation [Paper]
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- CompoDistill: Attention Distillation for Compositional Reasoning in Multimodal LLMs [Paper]
- DeCLIP: Decoupled Learning for Open-Vocabulary Dense Perception [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- DLIP: Distilling Language-Image Pre-training [Paper]
- DIDE: Distilled Dual-Encoder Model for Vision-Language Understanding [Paper]
Cross-modal Feature Distillation
- FD-VLA: Force-Distilled Vision-Language-Action Model for Contact-Rich Manipulation [Paper]
- VISTA: Enhancing Visual Conditioning via Track-Following Preference Optimization in Vision-Language-Action Models [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- FLARE: Learning Future-Aware Latent Representations from Vision-Language Models for Autonomous Driving [Paper]
- DAIT: Distillation from Vision-Language Models to Lightweight Classifiers with Adaptive Intermediate Teacher Transfer [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens [Paper]
- Modality-specific Knowledge Distillation with Wasserstein Distance Minimization for Vision-Language Pretrained Models [Paper]
- Unsupervised Knowledge Distillation via Local Representations for Vision-Language Models [Paper]
- TE-VLM: Transfer Entropy for Vision Language Model Distillation [Paper]
- KAID: Knowledge-Aware Interactive Distillation for Vision-Language Models [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- OmniReason: A Temporal-Guided Vision-Language-Action Framework for Autonomous Driving [Paper]
- AME: Aligned Manifold Entropy for Robust Vision-Language Distillation [Paper]
- VLScene: Vision-language guidance distillation for camera-based 3D semantic scene completion [Paper]
- 3D-aware vision-language models fine-tuning with geometric distillation [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- Learning Background Prompts to Discover Implicit Knowledge for Open Vocabulary Object Detection [Paper]
- SKDF: A Simple Knowledge Distillation Framework for Distilling Open-Vocabulary Knowledge to Open-World Object Detector [Paper]
- PartDistill: 3D Shape Part Segmentation by Vision-Language Model Distillation [Paper]
- Object-Aware Distillation Pyramid for Open-Vocabulary Object Detection [Paper]
- Multimodal Adaptive Distillation for Leveraging Unimodal Encoders for Vision-Language Tasks [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
- cViL: Cross-Lingual Training of Vision-Language Models using Knowledge Distillation [Paper]
Section III: Relation-based Distillation
Similarity-based Distillation
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- CLIP-Embed-KD: Computationally Efficient Knowledge Distillation Using Embeddings as Teachers [Paper]
- CLIP-KD: An Empirical Study of CLIP Model Distillation [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- Filtering, Distillation, and Hard Negatives for Vision-Language Pre-Training [Paper]
- DIME-FM: Distilling Multimodal and Efficient Foundation Models [Paper]
- Learning From Expert: Vision-Language Knowledge Distillation for Unsupervised Cross-Modal Hashing Retrieval [Paper]
- Open-Vocabulary Object Detection via Vision and Language Knowledge Distillation [Paper]
Contrastive Distillation
- CLIP-CID: Efficient CLIP Distillation via Cluster-Instance Discrimination [Paper]
- Cyclic Contrastive Knowledge Transfer for Open-Vocabulary Object Detection [Paper]
- MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- Distilling CLIP with Dual Guidance for Learning Discriminative Human Body Shape Representation [Paper]
- VLDadaptor: Domain Adaptive Object Detection with Vision-Language Model Distillation [Paper]
- Adversarial prompt distillation for vision-language models [Paper]
- Filtering, Distillation, and Hard Negatives for Vision-Language Pre-Training [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- A Sentence Speaks a Thousand Images: Domain Generalization through Distilling CLIP with Language Guidance [Paper]
- Aligning Bag of Regions for Open-Vocabulary Object Detection [Paper]
- Exploring Multi-Modal Contextual Knowledge for Open-Vocabulary Object Detection [Paper]
- Dynamic contrastive distillation for image-text retrieval [Paper]
- Enabling Multimodal Generation on CLIP via Vision-Language Knowledge Distillation [Paper]
Teacher Accessibility
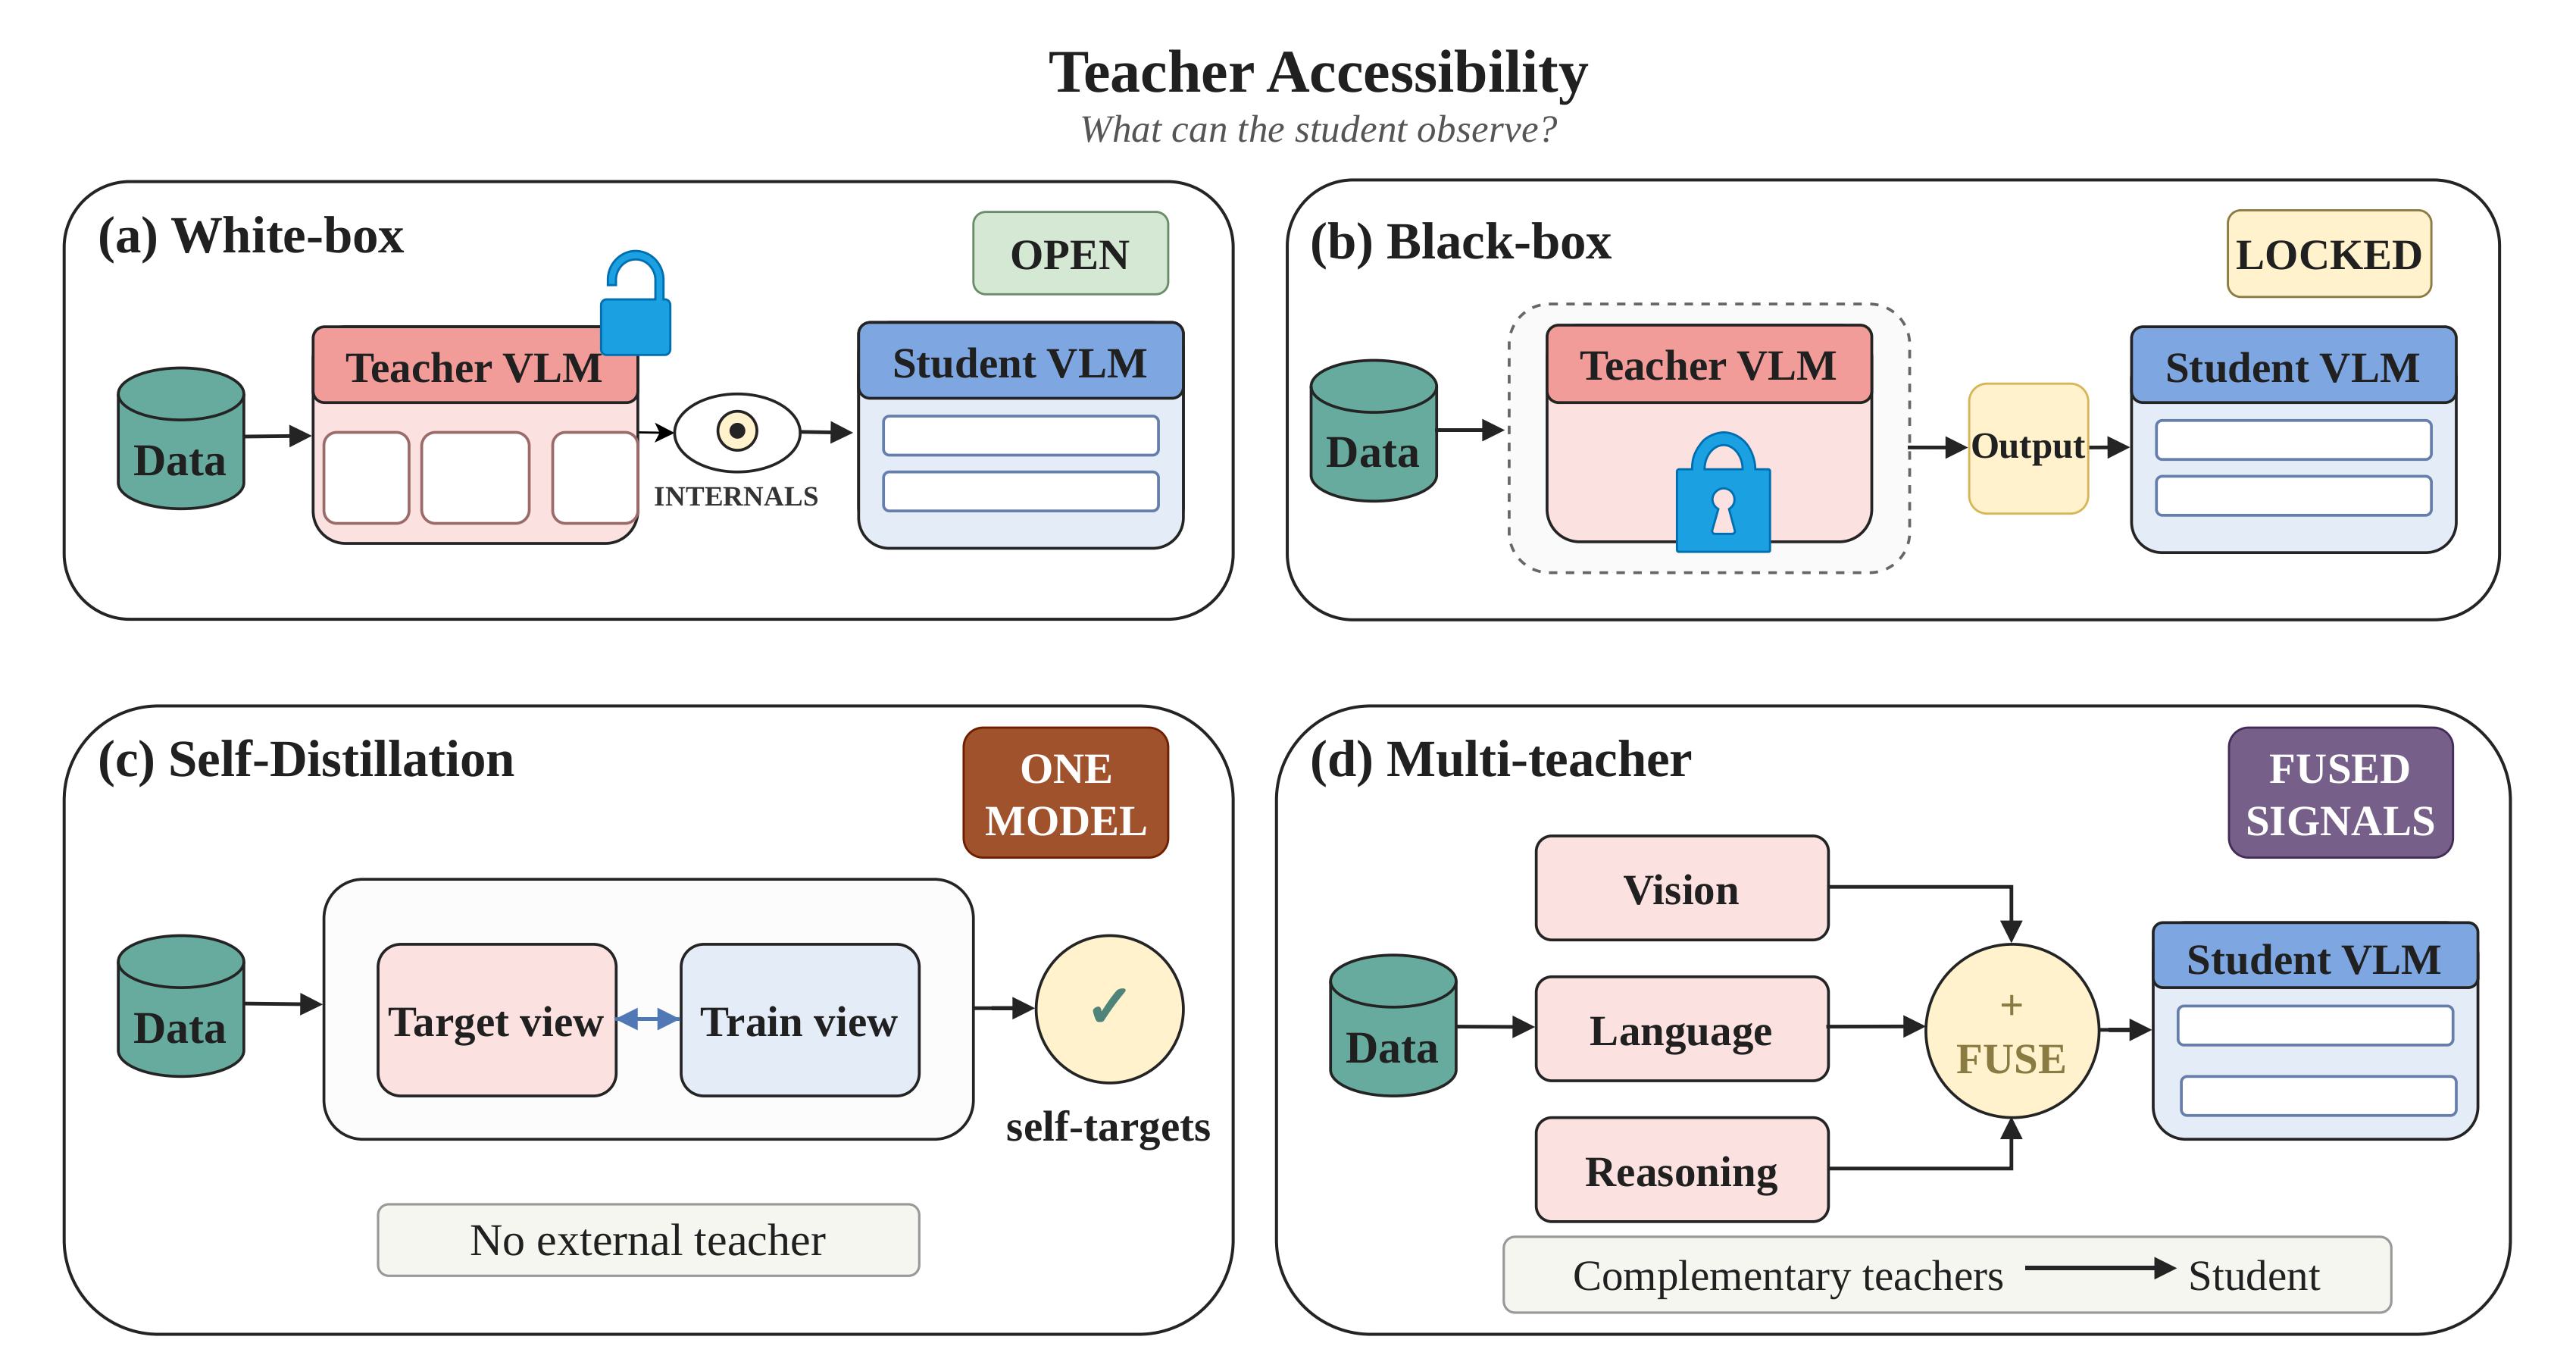
| Regime | Section |
|---|---|
| White-box Distillation | Section IV |
| Black-box Distillation | Section V |
| Self-Distillation | Section VI |
| Multi-teacher Distillation | Section VII |
Section IV: White-box Distillation
- Shallow-π: Knowledge Distillation for Flow-based VLAs [Paper]
- MoPD: Mixture-of-Prompts Distillation for Vision-Language Models [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- LinMU: Multimodal Understanding Made Linear [Paper]
- FLARE: Learning Future-Aware Latent Representations from Vision-Language Models for Autonomous Driving [Paper]
- DAIT: Distillation from Vision-Language Models to Lightweight Classifiers with Adaptive Intermediate Teacher Transfer [Paper]
- Hide to See: Reasoning-prefix Masking for Visual-anchored Thinking in VLM Distillation [Paper]
- Prodistill: A Progressive Prompting Framework for Fine-Grained VLM Distillation [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- SF-CLIP: CLIP-based Arbitrary Style Image Retrieval with Style and Fine-Grained Semantic Enhancement [Paper]
- CompoDistill: Attention Distillation for Compositional Reasoning in Multimodal LLMs [Paper]
- VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models [Paper]
- EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens [Paper]
- Modality-specific Knowledge Distillation with Wasserstein Distance Minimization for Vision-Language Pretrained Models [Paper]
- TE-VLM: Transfer Entropy for Vision Language Model Distillation [Paper]
- KAID: Knowledge-Aware Interactive Distillation for Vision-Language Models [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- 3D-aware vision-language models fine-tuning with geometric distillation [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Layerwised Multimodal Knowledge Distillation for Vision-Language Pretrained Model [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- Aligning Bag of Regions for Open-Vocabulary Object Detection [Paper]
- CLIPPING: Distilling CLIP-Based Models with a Student Base for Video-Language Retrieval [Paper]
- KD-VLP: Improving End-to-End Vision-and-Language Pretraining with Object Knowledge Distillation [Paper]
- CLIP-TD: CLIP targeted distillation for vision-language tasks [Paper]
- DIDE: Distilled Dual-Encoder Model for Vision-Language Understanding [Paper]
Section V: Black-box Distillation
- Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models [Paper]
- Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge [Paper]
- PCoreSet: Effective Active Learning through Knowledge Distillation from Vision-Language Models [Paper]
- LVLM2P: Sample Efficient Reinforcement Learning via Large Vision Language Model Distillation [Paper]
- Online In-Context Distillation for Low-Resource Vision Language Models [Paper]
- Visual Program Distillation: Distilling Tools and Programmatic Reasoning into Vision-Language Models [Paper]
- ALLaVA: Harnessing GPT4V-Synthesized Data for Lite Vision-Language Models [Paper]
- CLIP-Embed-KD: Computationally Efficient Knowledge Distillation Using Embeddings as Teachers [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
- ShareGPT4V: Improving Large Multi-Modal Models with Better Captions [Paper]
- MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language Models [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
- Bridging the Gap between Object and Image-Level Representations for Open-Vocabulary Detection [Paper]
Section VI: Self-Distillation
- COSMOS: Cross-Modality Self-Distillation for Vision Language Pre-training [Paper]
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL [Paper]
- MoLe-VLA: Dynamic Layer-Skipping Vision Language Action Model via Mixture-of-Layers for Efficient Robot Manipulation [Paper]
- CEED-VLA: Consistency Vision-Language-Action Model with Early-Exit Decoding [Paper]
- Building Vision-Language Models on Solid Foundations with Masked Distillation [Paper]
- FineCLIP: Self-distilled Region-based CLIP for Better Fine-grained Understanding [Paper]
- Improving Zero-Shot Generalization of Learned Prompts via Unsupervised Knowledge Distillation [Paper]
- Multimodality Self-distillation for Fast Inference of Vision and Language Pretrained Models [Paper]
- MaskCLIP: Masked Self-Distillation Advances Contrastive Language-Image Pretraining [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- Align before Fuse: Vision and Language Representation Learning with Momentum Distillation [Paper]
Section VII: Multi-teacher Distillation
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- MoVE-KD: Knowledge Distillation for VLMs with Mixture of Visual Encoders [Paper]
- MST-Distill: Mixture of Specialized Teachers for Cross-Modal Knowledge Distillation [Paper]
- AMMKD: Adaptive Multimodal Multi-Teacher Distillation for Lightweight Vision-Language Models [Paper]
- Retaining Knowledge and Enhancing Long-Text Representations in CLIP through Dual-Teacher Distillation [Paper]
- KAID: Knowledge-Aware Interactive Distillation for Vision-Language Models [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
Structural Compatibility
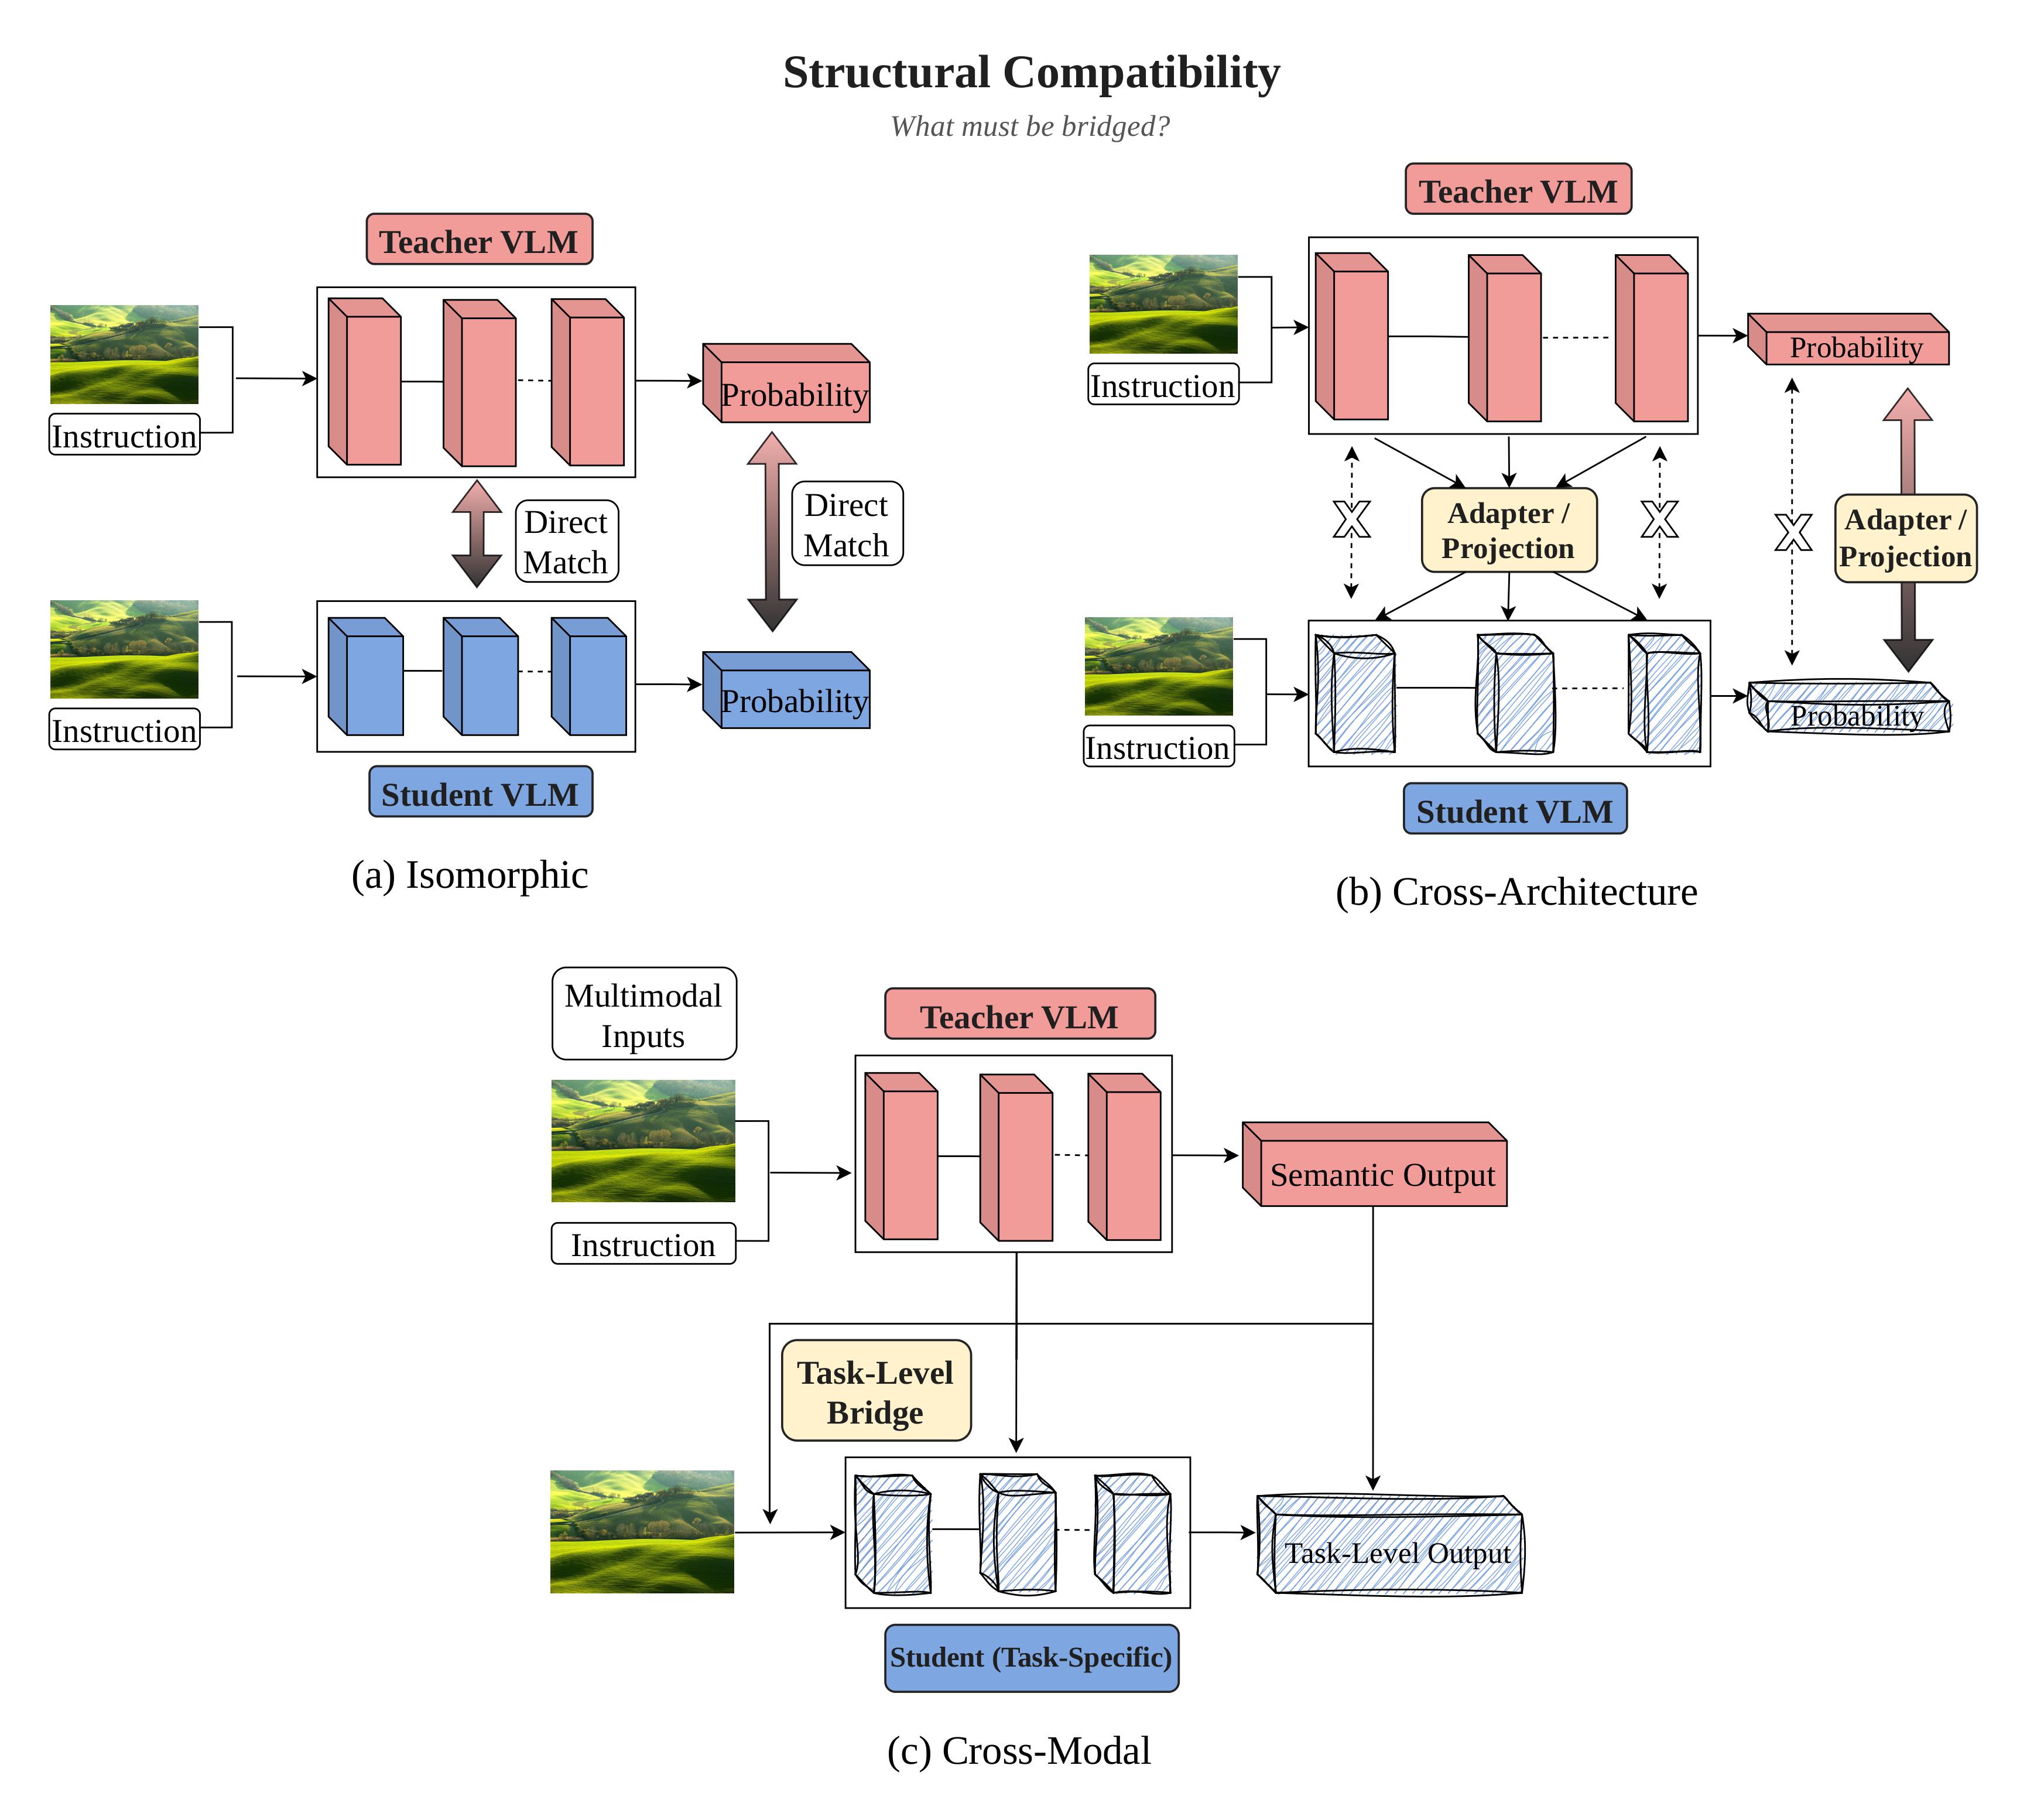
| Type | Section |
|---|---|
| Isomorphic | Section VIII |
| Cross-Architecture | Section IX |
| Cross-Modal | Section X |
Section VIII: Structural Compatibility - Isomorphic
- Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models [Paper]
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- Hide to See: Reasoning-prefix Masking for Visual-anchored Thinking in VLM Distillation [Paper]
- LLaVA-KD: A Framework of Distilling Multimodal Large Language Models [Paper]
- VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models [Paper]
- MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models [Paper]
- CLIP-CID: Efficient CLIP Distillation via Cluster-Instance Discrimination [Paper]
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
- A Hierarchical Semantic Distillation Framework for Open-Vocabulary Object Detection [Paper]
- CAKE: Category Aware Knowledge Extraction for Open-Vocabulary Object Detection [Paper]
- Online In-Context Distillation for Low-Resource Vision Language Models [Paper]
- Select and Distill: Selective Dual-Teacher Knowledge Transfer for Continual Learning on Vision-Language Models [Paper]
- Collaborative Training of Tiny-Large Vision Language Models [Paper]
- CLIP-Embed-KD: Computationally Efficient Knowledge Distillation Using Embeddings as Teachers [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- CLIP-KD: An Empirical Study of CLIP Model Distillation [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- Distilling DETR with Visual-Linguistic Knowledge for Open-Vocabulary Object Detection [Paper]
- DIME-FM: Distilling Multimodal and Efficient Foundation Models [Paper]
- CLIPPING: Distilling CLIP-Based Models with a Student Base for Video-Language Retrieval [Paper]
- Open-Vocabulary Object Detection via Vision and Language Knowledge Distillation [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
Section IX: Structural Compatibility - Cross-Architecture
- LinMU: Multimodal Understanding Made Linear [Paper]
- Prodistill: A Progressive Prompting Framework for Fine-Grained VLM Distillation [Paper]
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- VL2Lite: Task-Specific Knowledge Distillation from Large Vision-Language Models to Lightweight Networks [Paper]
- CustomKD: Customizing Large Vision Foundation for Edge Model Improvement via Knowledge Distillation [Paper]
- VITA-VLA: Efficiently Teaching Vision-Language Models to Act via Action Expert Distillation [Paper]
- Refined Policy Distillation: From VLA Generalists to RL Experts [Paper]
- Clip4Retrofit: Enabling real-time image labeling on edge devices via cross-architecture CLIP distillation [Paper]
- MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training [Paper]
- LLaVA-MoD: Making LLaVA Tiny via MoE Knowledge Distillation [Paper]
- CIFD: Controlled Information Flow to Enhance Knowledge Distillation [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
- EfficientVLM: Fast and Accurate Vision-Language Models via Knowledge Distillation and Modal-Adaptive Pruning [Paper]
- Module-wise Adaptive Distillation for Multimodality Foundation Models [Paper]
- TinyViT: Fast Pretraining Distillation for Small Vision Transformers [Paper]
- Generative Negative Text Replay for Continual Vision-Language Pretraining [Paper]
- MiniVLM: A Smaller and Faster Vision-Language Model [Paper]
Section X: Structural Compatibility - Cross-Modal
- FD-VLA: Force-Distilled Vision-Language-Action Model for Contact-Rich Manipulation [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- FLARE: Learning Future-Aware Latent Representations from Vision-Language Models for Autonomous Driving [Paper]
- DAIT: Distillation from Vision-Language Models to Lightweight Classifiers with Adaptive Intermediate Teacher Transfer [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- SF-CLIP: CLIP-based Arbitrary Style Image Retrieval with Style and Fine-Grained Semantic Enhancement [Paper]
- Unsupervised Knowledge Distillation via Local Representations for Vision-Language Models [Paper]
- TE-VLM: Transfer Entropy for Vision Language Model Distillation [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- Vision-Language-Vision Auto-Encoder: Scalable Knowledge Distillation from Diffusion Models [Paper]
- LVLM2P: Sample Efficient Reinforcement Learning via Large Vision Language Model Distillation [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Distilling CLIP with Dual Guidance for Learning Discriminative Human Body Shape Representation [Paper]
- A Sentence Speaks a Thousand Images: Domain Generalization through Distilling CLIP with Language Guidance [Paper]
- Enabling Multimodal Generation on CLIP via Vision-Language Knowledge Distillation [Paper]
- Bridging the Gap between Object and Image-Level Representations for Open-Vocabulary Detection [Paper]
Knowledge Distillation for Vision-Language-Action Models
- FD-VLA: Force-Distilled Vision-Language-Action Model for Contact-Rich Manipulation [Paper]
- VISTA: Enhancing Visual Conditioning via Track-Following Preference Optimization in Vision-Language-Action Models [Paper]
- Shallow-π: Knowledge Distillation for Flow-based VLAs [Paper]
- AC^2-VLA: Action-Context-Aware Adaptive Computation in Vision-Language-Action Models for Efficient Robotic Manipulation [Paper]
- RDT2: Exploring the Scaling Limit of UMI Data Towards Zero-Shot Cross-Embodiment Generalization [Paper]
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- LatBot: Distilling Universal Latent Actions for Vision-Language-Action Models [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- VITA-VLA: Efficiently Teaching Vision-Language Models to Act via Action Expert Distillation [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
- Refined Policy Distillation: From VLA Generalists to RL Experts [Paper]
- MoLe-VLA: Dynamic Layer-Skipping Vision Language Action Model via Mixture-of-Layers for Efficient Robot Manipulation [Paper]
- CEED-VLA: Consistency Vision-Language-Action Model with Early-Exit Decoding [Paper]
- OmniReason: A Temporal-Guided Vision-Language-Action Framework for Autonomous Driving [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
Knowledge Distillation for Vision-Language Embedding Models
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Qwen3-VL-Embedding and Qwen3-VL-Reranker: A Unified Framework for State-of-the-Art Multimodal Retrieval and Ranking [Paper]
- UniME-V2: MLLM-as-a-Judge for Universal Multimodal Embedding Learning [Paper]
- xVLM2Vec: Adapting LVLM-based Embedding Models to Multilinguality using Self-Knowledge Distillation [Paper]
- Breaking the Modality Barrier: Universal Embedding Learning with Multimodal LLMs [Paper]
VLM Knowledge Distillation for Segmentation
- PartDistill: 3D Shape Part Segmentation by Vision-Language Model Distillation [Paper]
- CLIP is Also an Efficient Segmenter: A Text-Driven Approach for Weakly Supervised Semantic Segmentation [Paper]
- Plug-and-Play, Dense-Label-Free Extraction of Open-Vocabulary Semantic Segmentation from Vision-Language Models [Paper]
- Segment Anything is A Good Pseudo-label Generator for Weakly Supervised Semantic Segmentation [Paper]
- ZegCLIP: Towards Adapting CLIP for Zero-shot Semantic Segmentation [Paper]
- Open-Vocabulary Semantic Segmentation with Mask-adapted CLIP [Paper]
- FreeSeg: Unified, Universal and Open-Vocabulary Image Segmentation [Paper]
- SegPrompt: Boosting Open-world Segmentation via Category-level Prompt Learning [Paper]
- Exploring Open-Vocabulary Semantic Segmentation without Human Labels [Paper]
- Mask-free OVIS: Open-Vocabulary Instance Segmentation without Manual Mask Annotations [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- Extract Free Dense Labels from CLIP [Paper]
- Open-Vocabulary Semantic Segmentation with Frozen Vision-Language Models [Paper]
- A Simple Baseline for Open-Vocabulary Semantic Segmentation with Pre-trained Vision-language Model [Paper]
- Scaling Open-Vocabulary Image Segmentation with Image-Level Labels [Paper]
- Language-driven Semantic Segmentation [Paper]
- Image Segmentation Using Text and Image Prompts [Paper]
- Decoupling Zero-Shot Semantic Segmentation [Paper]
VLM Knowledge Distillation for Open-Vocabulary Object Detection
- DeCLIP: Decoupled Learning for Open-Vocabulary Dense Perception [Paper]
- A Hierarchical Semantic Distillation Framework for Open-Vocabulary Object Detection [Paper]
- CAKE: Category Aware Knowledge Extraction for Open-Vocabulary Object Detection [Paper]
- Cyclic Contrastive Knowledge Transfer for Open-Vocabulary Object Detection [Paper]
- Learning Background Prompts to Discover Implicit Knowledge for Open Vocabulary Object Detection [Paper]
- LP-OVOD: Open-Vocabulary Object Detection by Linear Probing [Paper]
- SKDF: A Simple Knowledge Distillation Framework for Distilling Open-Vocabulary Knowledge to Open-World Object Detector [Paper]
- VLDadaptor: Domain Adaptive Object Detection with Vision-Language Model Distillation [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- Object-Aware Distillation Pyramid for Open-Vocabulary Object Detection [Paper]
- Aligning Bag of Regions for Open-Vocabulary Object Detection [Paper]
- Distilling DETR with Visual-Linguistic Knowledge for Open-Vocabulary Object Detection [Paper]
- Exploring Multi-Modal Contextual Knowledge for Open-Vocabulary Object Detection [Paper]
- Open-Vocabulary Object Detection via Vision and Language Knowledge Distillation [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
- Bridging the Gap between Object and Image-Level Representations for Open-Vocabulary Detection [Paper]
Contributors


Similar repos


README
A Survey on Knowledge Distillation of Vision-Language Models
🔔 News
- [10/09/2026] Camera-ready version for EMNLP 2026 is now available [PDF].
- [21/08/2026] 🎉 This survey has been accepted by the Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026!
📝 Introduction
This paper provides the first dedicated survey of knowledge distillation for vision-language models. We propose a unified taxonomy that organizes methods along three orthogonal views: knowledge type, teacher accessibility, and structural compatibility, and use it to organize methods across major VLM distillation settings.
📊 Taxonomy
Below is the taxonomy summarizing the landscape of knowledge distillation research for VLMs:
This survey organizes VLM distillation methods along three orthogonal axes. Each axis is illustrated below, immediately before the corresponding paper sections.
| Axis | Question | Sections |
|---|---|---|
| Knowledge Type | What does the student learn from the teacher? | I · II · III |
| Teacher Accessibility | What can the student observe about the teacher? | IV · V · VI · VII |
| Structural Compatibility | What must be bridged before distillation can proceed? | VIII · IX · X |
| Application | Section |
|---|---|
| Vision-Language-Action | VLA |
| Vision-Language Embedding | Embedding |
| Semantic Segmentation | Segmentation |
| Open-Vocabulary Object Detection | OVD |
Knowledge Type
| Branch | Section |
|---|---|
| Response-based Distillation | Section I |
| Feature-based Distillation | Section II |
| Relation-based Distillation | Section III |
Section I: Response-based Distillation
Logit Distillation
- MoPD: Mixture-of-Prompts Distillation for Vision-Language Models [Paper]
- Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- Hide to See: Reasoning-prefix Masking for Visual-anchored Thinking in VLM Distillation [Paper]
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- LLaVA-KD: A Framework of Distilling Multimodal Large Language Models [Paper]
- VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models [Paper]
- MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models [Paper]
- GenRecal: Generation after Recalibration from Large to Small Vision-Language Models [Paper]
- EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens [Paper]
- AMMKD: Adaptive Multimodal Multi-Teacher Distillation for Lightweight Vision-Language Models [Paper]
- VL2Lite: Task-Specific Knowledge Distillation from Large Vision-Language Models to Lightweight Networks [Paper]
- DHO: Simple yet Effective Semi-supervised Knowledge Distillation from Vision-Language Models via Dual-Head Optimization [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- Improving Zero-Shot Generalization of Learned Prompts via Unsupervised Knowledge Distillation [Paper]
- VLM-KD: Knowledge Distillation from VLM for Long-Tail Visual Recognition [Paper]
- CLIP-KD: An Empirical Study of CLIP Model Distillation [Paper]
Sequence Distillation
- RDT2: Exploring the Scaling Limit of UMI Data Towards Zero-Shot Cross-Embodiment Generalization [Paper]
- MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
- Refined Policy Distillation: From VLA Generalists to RL Experts [Paper]
- Online In-Context Distillation for Low-Resource Vision Language Models [Paper]
- Towards Long-window Anchoring in Vision-Language Model Distillation [Paper]
- VLM-KD: Knowledge Distillation from VLM for Long-Tail Visual Recognition [Paper]
- Visual Program Distillation: Distilling Tools and Programmatic Reasoning into Vision-Language Models [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
Preference Distillation
- Embedding the Teacher: Distilling vLLM Preferences for Scalable Image Retrieval [Paper]
- LLaVA-MoD: Making LLaVA Tiny via MoE Knowledge Distillation [Paper]
- mDPO: Conditional Preference Optimization for Multimodal Large Language Models [Paper]
- Silkie: Preference Distillation for Large Visual Language Models [Paper]
Section II: Feature-based Distillation
Hidden-state Distillation
- Shallow-π: Knowledge Distillation for Flow-based VLAs [Paper]
- LinMU: Multimodal Understanding Made Linear [Paper]
- Prodistill: A Progressive Prompting Framework for Fine-Grained VLM Distillation [Paper]
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- SF-CLIP: CLIP-based Arbitrary Style Image Retrieval with Style and Fine-Grained Semantic Enhancement [Paper]
- VITA-VLA: Efficiently Teaching Vision-Language Models to Act via Action Expert Distillation [Paper]
- CEED-VLA: Consistency Vision-Language-Action Model with Early-Exit Decoding [Paper]
- Masking Teacher and Reinforcing Student for Distilling Vision-Language Models [Paper]
- Layerwised Multimodal Knowledge Distillation for Vision-Language Pretrained Model [Paper]
- Building Vision-Language Models on Solid Foundations with Masked Distillation [Paper]
- FineCLIP: Self-distilled Region-based CLIP for Better Fine-grained Understanding [Paper]
- LP-OVOD: Open-Vocabulary Object Detection by Linear Probing [Paper]
- PracticalDG: Perturbation Distillation on Vision-Language Models for Hybrid Domain Generalization [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- MaskCLIP: Masked Self-Distillation Advances Contrastive Language-Image Pretraining [Paper]
- Distilling Large Vision-Language Model with Out-of-Distribution Generalizability [Paper]
- DLIP: Distilling Language-Image Pre-training [Paper]
- KD-VLP: Improving End-to-End Vision-and-Language Pretraining with Object Knowledge Distillation [Paper]
- TinyViT: Fast Pretraining Distillation for Small Vision Transformers [Paper]
- Compressing Visual-Linguistic Model via Knowledge Distillation [Paper]
- MiniVLM: A Smaller and Faster Vision-Language Model [Paper]
Attention Distillation
- AC^2-VLA: Action-Context-Aware Adaptive Computation in Vision-Language-Action Models for Efficient Robotic Manipulation [Paper]
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- CompoDistill: Attention Distillation for Compositional Reasoning in Multimodal LLMs [Paper]
- DeCLIP: Decoupled Learning for Open-Vocabulary Dense Perception [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- DLIP: Distilling Language-Image Pre-training [Paper]
- DIDE: Distilled Dual-Encoder Model for Vision-Language Understanding [Paper]
Cross-modal Feature Distillation
- FD-VLA: Force-Distilled Vision-Language-Action Model for Contact-Rich Manipulation [Paper]
- VISTA: Enhancing Visual Conditioning via Track-Following Preference Optimization in Vision-Language-Action Models [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- FLARE: Learning Future-Aware Latent Representations from Vision-Language Models for Autonomous Driving [Paper]
- DAIT: Distillation from Vision-Language Models to Lightweight Classifiers with Adaptive Intermediate Teacher Transfer [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens [Paper]
- Modality-specific Knowledge Distillation with Wasserstein Distance Minimization for Vision-Language Pretrained Models [Paper]
- Unsupervised Knowledge Distillation via Local Representations for Vision-Language Models [Paper]
- TE-VLM: Transfer Entropy for Vision Language Model Distillation [Paper]
- KAID: Knowledge-Aware Interactive Distillation for Vision-Language Models [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- OmniReason: A Temporal-Guided Vision-Language-Action Framework for Autonomous Driving [Paper]
- AME: Aligned Manifold Entropy for Robust Vision-Language Distillation [Paper]
- VLScene: Vision-language guidance distillation for camera-based 3D semantic scene completion [Paper]
- 3D-aware vision-language models fine-tuning with geometric distillation [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- Learning Background Prompts to Discover Implicit Knowledge for Open Vocabulary Object Detection [Paper]
- SKDF: A Simple Knowledge Distillation Framework for Distilling Open-Vocabulary Knowledge to Open-World Object Detector [Paper]
- PartDistill: 3D Shape Part Segmentation by Vision-Language Model Distillation [Paper]
- Object-Aware Distillation Pyramid for Open-Vocabulary Object Detection [Paper]
- Multimodal Adaptive Distillation for Leveraging Unimodal Encoders for Vision-Language Tasks [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
- cViL: Cross-Lingual Training of Vision-Language Models using Knowledge Distillation [Paper]
Section III: Relation-based Distillation
Similarity-based Distillation
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- CLIP-Embed-KD: Computationally Efficient Knowledge Distillation Using Embeddings as Teachers [Paper]
- CLIP-KD: An Empirical Study of CLIP Model Distillation [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- Filtering, Distillation, and Hard Negatives for Vision-Language Pre-Training [Paper]
- DIME-FM: Distilling Multimodal and Efficient Foundation Models [Paper]
- Learning From Expert: Vision-Language Knowledge Distillation for Unsupervised Cross-Modal Hashing Retrieval [Paper]
- Open-Vocabulary Object Detection via Vision and Language Knowledge Distillation [Paper]
Contrastive Distillation
- CLIP-CID: Efficient CLIP Distillation via Cluster-Instance Discrimination [Paper]
- Cyclic Contrastive Knowledge Transfer for Open-Vocabulary Object Detection [Paper]
- MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- Distilling CLIP with Dual Guidance for Learning Discriminative Human Body Shape Representation [Paper]
- VLDadaptor: Domain Adaptive Object Detection with Vision-Language Model Distillation [Paper]
- Adversarial prompt distillation for vision-language models [Paper]
- Filtering, Distillation, and Hard Negatives for Vision-Language Pre-Training [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- A Sentence Speaks a Thousand Images: Domain Generalization through Distilling CLIP with Language Guidance [Paper]
- Aligning Bag of Regions for Open-Vocabulary Object Detection [Paper]
- Exploring Multi-Modal Contextual Knowledge for Open-Vocabulary Object Detection [Paper]
- Dynamic contrastive distillation for image-text retrieval [Paper]
- Enabling Multimodal Generation on CLIP via Vision-Language Knowledge Distillation [Paper]
Teacher Accessibility
| Regime | Section |
|---|---|
| White-box Distillation | Section IV |
| Black-box Distillation | Section V |
| Self-Distillation | Section VI |
| Multi-teacher Distillation | Section VII |
Section IV: White-box Distillation
- Shallow-π: Knowledge Distillation for Flow-based VLAs [Paper]
- MoPD: Mixture-of-Prompts Distillation for Vision-Language Models [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- LinMU: Multimodal Understanding Made Linear [Paper]
- FLARE: Learning Future-Aware Latent Representations from Vision-Language Models for Autonomous Driving [Paper]
- DAIT: Distillation from Vision-Language Models to Lightweight Classifiers with Adaptive Intermediate Teacher Transfer [Paper]
- Hide to See: Reasoning-prefix Masking for Visual-anchored Thinking in VLM Distillation [Paper]
- Prodistill: A Progressive Prompting Framework for Fine-Grained VLM Distillation [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- SF-CLIP: CLIP-based Arbitrary Style Image Retrieval with Style and Fine-Grained Semantic Enhancement [Paper]
- CompoDistill: Attention Distillation for Compositional Reasoning in Multimodal LLMs [Paper]
- VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models [Paper]
- EM-KD: Distilling Efficient Multimodal Large Language Model with Unbalanced Vision Tokens [Paper]
- Modality-specific Knowledge Distillation with Wasserstein Distance Minimization for Vision-Language Pretrained Models [Paper]
- TE-VLM: Transfer Entropy for Vision Language Model Distillation [Paper]
- KAID: Knowledge-Aware Interactive Distillation for Vision-Language Models [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- 3D-aware vision-language models fine-tuning with geometric distillation [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Layerwised Multimodal Knowledge Distillation for Vision-Language Pretrained Model [Paper]
- Align-KD: Distilling Cross-Modal Alignment Knowledge for Mobile Vision-Language Large Model Enhancement [Paper]
- Aligning Bag of Regions for Open-Vocabulary Object Detection [Paper]
- CLIPPING: Distilling CLIP-Based Models with a Student Base for Video-Language Retrieval [Paper]
- KD-VLP: Improving End-to-End Vision-and-Language Pretraining with Object Knowledge Distillation [Paper]
- CLIP-TD: CLIP targeted distillation for vision-language tasks [Paper]
- DIDE: Distilled Dual-Encoder Model for Vision-Language Understanding [Paper]
Section V: Black-box Distillation
- Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models [Paper]
- Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge [Paper]
- PCoreSet: Effective Active Learning through Knowledge Distillation from Vision-Language Models [Paper]
- LVLM2P: Sample Efficient Reinforcement Learning via Large Vision Language Model Distillation [Paper]
- Online In-Context Distillation for Low-Resource Vision Language Models [Paper]
- Visual Program Distillation: Distilling Tools and Programmatic Reasoning into Vision-Language Models [Paper]
- ALLaVA: Harnessing GPT4V-Synthesized Data for Lite Vision-Language Models [Paper]
- CLIP-Embed-KD: Computationally Efficient Knowledge Distillation Using Embeddings as Teachers [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
- ShareGPT4V: Improving Large Multi-Modal Models with Better Captions [Paper]
- MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language Models [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
- Bridging the Gap between Object and Image-Level Representations for Open-Vocabulary Detection [Paper]
Section VI: Self-Distillation
- COSMOS: Cross-Modality Self-Distillation for Vision Language Pre-training [Paper]
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL [Paper]
- MoLe-VLA: Dynamic Layer-Skipping Vision Language Action Model via Mixture-of-Layers for Efficient Robot Manipulation [Paper]
- CEED-VLA: Consistency Vision-Language-Action Model with Early-Exit Decoding [Paper]
- Building Vision-Language Models on Solid Foundations with Masked Distillation [Paper]
- FineCLIP: Self-distilled Region-based CLIP for Better Fine-grained Understanding [Paper]
- Improving Zero-Shot Generalization of Learned Prompts via Unsupervised Knowledge Distillation [Paper]
- Multimodality Self-distillation for Fast Inference of Vision and Language Pretrained Models [Paper]
- MaskCLIP: Masked Self-Distillation Advances Contrastive Language-Image Pretraining [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- Align before Fuse: Vision and Language Representation Learning with Momentum Distillation [Paper]
Section VII: Multi-teacher Distillation
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- MoVE-KD: Knowledge Distillation for VLMs with Mixture of Visual Encoders [Paper]
- MST-Distill: Mixture of Specialized Teachers for Cross-Modal Knowledge Distillation [Paper]
- AMMKD: Adaptive Multimodal Multi-Teacher Distillation for Lightweight Vision-Language Models [Paper]
- Retaining Knowledge and Enhancing Long-Text Representations in CLIP through Dual-Teacher Distillation [Paper]
- KAID: Knowledge-Aware Interactive Distillation for Vision-Language Models [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
Structural Compatibility
| Type | Section |
|---|---|
| Isomorphic | Section VIII |
| Cross-Architecture | Section IX |
| Cross-Modal | Section X |
Section VIII: Structural Compatibility - Isomorphic
- Switch-KD: Visual-Switch Knowledge Distillation for Vision-Language Models [Paper]
- Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs [Paper]
- Hide to See: Reasoning-prefix Masking for Visual-anchored Thinking in VLM Distillation [Paper]
- LLaVA-KD: A Framework of Distilling Multimodal Large Language Models [Paper]
- VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models [Paper]
- MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models [Paper]
- CLIP-CID: Efficient CLIP Distillation via Cluster-Instance Discrimination [Paper]
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
- A Hierarchical Semantic Distillation Framework for Open-Vocabulary Object Detection [Paper]
- CAKE: Category Aware Knowledge Extraction for Open-Vocabulary Object Detection [Paper]
- Online In-Context Distillation for Low-Resource Vision Language Models [Paper]
- Select and Distill: Selective Dual-Teacher Knowledge Transfer for Continual Learning on Vision-Language Models [Paper]
- Collaborative Training of Tiny-Large Vision Language Models [Paper]
- CLIP-Embed-KD: Computationally Efficient Knowledge Distillation Using Embeddings as Teachers [Paper]
- PromptKD: Unsupervised Prompt Distillation for Vision-Language Models [Paper]
- CLIP-KD: An Empirical Study of CLIP Model Distillation [Paper]
- TinyCLIP: CLIP Distillation via Affinity Mimicking and Weight Inheritance [Paper]
- Distilling DETR with Visual-Linguistic Knowledge for Open-Vocabulary Object Detection [Paper]
- DIME-FM: Distilling Multimodal and Efficient Foundation Models [Paper]
- CLIPPING: Distilling CLIP-Based Models with a Student Base for Video-Language Retrieval [Paper]
- Open-Vocabulary Object Detection via Vision and Language Knowledge Distillation [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
Section IX: Structural Compatibility - Cross-Architecture
- LinMU: Multimodal Understanding Made Linear [Paper]
- Prodistill: A Progressive Prompting Framework for Fine-Grained VLM Distillation [Paper]
- Drive-KD: Multi-Teacher Distillation for VLMs in Autonomous Driving [Paper]
- VL2Lite: Task-Specific Knowledge Distillation from Large Vision-Language Models to Lightweight Networks [Paper]
- CustomKD: Customizing Large Vision Foundation for Edge Model Improvement via Knowledge Distillation [Paper]
- VITA-VLA: Efficiently Teaching Vision-Language Models to Act via Action Expert Distillation [Paper]
- Refined Policy Distillation: From VLA Generalists to RL Experts [Paper]
- Clip4Retrofit: Enabling real-time image labeling on edge devices via cross-architecture CLIP distillation [Paper]
- MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training [Paper]
- LLaVA-MoD: Making LLaVA Tiny via MoE Knowledge Distillation [Paper]
- CIFD: Controlled Information Flow to Enhance Knowledge Distillation [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
- EfficientVLM: Fast and Accurate Vision-Language Models via Knowledge Distillation and Modal-Adaptive Pruning [Paper]
- Module-wise Adaptive Distillation for Multimodality Foundation Models [Paper]
- TinyViT: Fast Pretraining Distillation for Small Vision Transformers [Paper]
- Generative Negative Text Replay for Continual Vision-Language Pretraining [Paper]
- MiniVLM: A Smaller and Faster Vision-Language Model [Paper]
Section X: Structural Compatibility - Cross-Modal
- FD-VLA: Force-Distilled Vision-Language-Action Model for Contact-Rich Manipulation [Paper]
- Prompt-stable knowledge distillation of vision-language models for efficient waste classification in material recovery facilities [Paper]
- FLARE: Learning Future-Aware Latent Representations from Vision-Language Models for Autonomous Driving [Paper]
- DAIT: Distillation from Vision-Language Models to Lightweight Classifiers with Adaptive Intermediate Teacher Transfer [Paper]
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge [Paper]
- Cross-Modal Knowledge Distillation without Paired Data: Theoretical Foundation and Algorithm [Paper]
- SF-CLIP: CLIP-based Arbitrary Style Image Retrieval with Style and Fine-Grained Semantic Enhancement [Paper]
- Unsupervised Knowledge Distillation via Local Representations for Vision-Language Models [Paper]
- TE-VLM: Transfer Entropy for Vision Language Model Distillation [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- Vision-Language-Vision Auto-Encoder: Scalable Knowledge Distillation from Diffusion Models [Paper]
- LVLM2P: Sample Efficient Reinforcement Learning via Large Vision Language Model Distillation [Paper]
- Visual-Language Model Knowledge Distillation Method for Image Quality Assessment [Paper]
- Distilling CLIP with Dual Guidance for Learning Discriminative Human Body Shape Representation [Paper]
- A Sentence Speaks a Thousand Images: Domain Generalization through Distilling CLIP with Language Guidance [Paper]
- Enabling Multimodal Generation on CLIP via Vision-Language Knowledge Distillation [Paper]
- Bridging the Gap between Object and Image-Level Representations for Open-Vocabulary Detection [Paper]
Knowledge Distillation for Vision-Language-Action Models
- FD-VLA: Force-Distilled Vision-Language-Action Model for Contact-Rich Manipulation [Paper]
- VISTA: Enhancing Visual Conditioning via Track-Following Preference Optimization in Vision-Language-Action Models [Paper]
- Shallow-π: Knowledge Distillation for Flow-based VLAs [Paper]
- AC^2-VLA: Action-Context-Aware Adaptive Computation in Vision-Language-Action Models for Efficient Robotic Manipulation [Paper]
- RDT2: Exploring the Scaling Limit of UMI Data Towards Zero-Shot Cross-Embodiment Generalization [Paper]
- Self-Improving Vision-Language-Action Models with Data Generation via Residual RL [Paper]
- FT-NCFM: An Influence-Aware Data Distillation Framework for Efficient VLA Models [Paper]
- LatBot: Distilling Universal Latent Actions for Vision-Language-Action Models [Paper]
- GLaD: Geometric Latent Distillation for Vision-Language-Action Models [Paper]
- VITA-VLA: Efficiently Teaching Vision-Language Models to Act via Action Expert Distillation [Paper]
- DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action [Paper]
- Refined Policy Distillation: From VLA Generalists to RL Experts [Paper]
- MoLe-VLA: Dynamic Layer-Skipping Vision Language Action Model via Mixture-of-Layers for Efficient Robot Manipulation [Paper]
- CEED-VLA: Consistency Vision-Language-Action Model with Early-Exit Decoding [Paper]
- OmniReason: A Temporal-Guided Vision-Language-Action Framework for Autonomous Driving [Paper]
- RLDG: Robotic Generalist Policy Distillation via Reinforcement Learning [Paper]
Knowledge Distillation for Vision-Language Embedding Models
- HieRD: Hierarchical Relational Distillation for Vision-Language Embedding Models [Paper]
- Qwen3-VL-Embedding and Qwen3-VL-Reranker: A Unified Framework for State-of-the-Art Multimodal Retrieval and Ranking [Paper]
- UniME-V2: MLLM-as-a-Judge for Universal Multimodal Embedding Learning [Paper]
- xVLM2Vec: Adapting LVLM-based Embedding Models to Multilinguality using Self-Knowledge Distillation [Paper]
- Breaking the Modality Barrier: Universal Embedding Learning with Multimodal LLMs [Paper]
VLM Knowledge Distillation for Segmentation
- PartDistill: 3D Shape Part Segmentation by Vision-Language Model Distillation [Paper]
- CLIP is Also an Efficient Segmenter: A Text-Driven Approach for Weakly Supervised Semantic Segmentation [Paper]
- Plug-and-Play, Dense-Label-Free Extraction of Open-Vocabulary Semantic Segmentation from Vision-Language Models [Paper]
- Segment Anything is A Good Pseudo-label Generator for Weakly Supervised Semantic Segmentation [Paper]
- ZegCLIP: Towards Adapting CLIP for Zero-shot Semantic Segmentation [Paper]
- Open-Vocabulary Semantic Segmentation with Mask-adapted CLIP [Paper]
- FreeSeg: Unified, Universal and Open-Vocabulary Image Segmentation [Paper]
- SegPrompt: Boosting Open-world Segmentation via Category-level Prompt Learning [Paper]
- Exploring Open-Vocabulary Semantic Segmentation without Human Labels [Paper]
- Mask-free OVIS: Open-Vocabulary Instance Segmentation without Manual Mask Annotations [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- Extract Free Dense Labels from CLIP [Paper]
- Open-Vocabulary Semantic Segmentation with Frozen Vision-Language Models [Paper]
- A Simple Baseline for Open-Vocabulary Semantic Segmentation with Pre-trained Vision-language Model [Paper]
- Scaling Open-Vocabulary Image Segmentation with Image-Level Labels [Paper]
- Language-driven Semantic Segmentation [Paper]
- Image Segmentation Using Text and Image Prompts [Paper]
- Decoupling Zero-Shot Semantic Segmentation [Paper]
VLM Knowledge Distillation for Open-Vocabulary Object Detection
- DeCLIP: Decoupled Learning for Open-Vocabulary Dense Perception [Paper]
- A Hierarchical Semantic Distillation Framework for Open-Vocabulary Object Detection [Paper]
- CAKE: Category Aware Knowledge Extraction for Open-Vocabulary Object Detection [Paper]
- Cyclic Contrastive Knowledge Transfer for Open-Vocabulary Object Detection [Paper]
- Learning Background Prompts to Discover Implicit Knowledge for Open Vocabulary Object Detection [Paper]
- LP-OVOD: Open-Vocabulary Object Detection by Linear Probing [Paper]
- SKDF: A Simple Knowledge Distillation Framework for Distilling Open-Vocabulary Knowledge to Open-World Object Detector [Paper]
- VLDadaptor: Domain Adaptive Object Detection with Vision-Language Model Distillation [Paper]
- CLIPSelf: Vision Transformer Distills Itself for Open-Vocabulary Dense Prediction [Paper]
- Object-Aware Distillation Pyramid for Open-Vocabulary Object Detection [Paper]
- Aligning Bag of Regions for Open-Vocabulary Object Detection [Paper]
- Distilling DETR with Visual-Linguistic Knowledge for Open-Vocabulary Object Detection [Paper]
- Exploring Multi-Modal Contextual Knowledge for Open-Vocabulary Object Detection [Paper]
- Open-Vocabulary Object Detection via Vision and Language Knowledge Distillation [Paper]
- Open-Vocabulary One-Stage Detection with Hierarchical Visual-Language Knowledge Distillation [Paper]
- Bridging the Gap between Object and Image-Level Representations for Open-Vocabulary Detection [Paper]