
A most Frontend Collection and survey of vision-language model papers, and models GitHub repository. Continuous updates.
HTML
720
189 commits
updated Sep 14, 2026
README
Frontier Vision-Language Models: Architectural Evolution, Benchmarks, Applications, and Challenges
🌐 Language: English · 简体中文

A most Frontend Collection and survey of vision-language model papers, and models GitHub repository
🧭 The Evolution of VLM Architectures
VLM design has gone through four distinct architectural eras in just six years — and Era 3 has split into two parallel branches. Early models kept frozen vision and language towers, aligned contrastively (CLIP) or bridged by a learnable connector into a frozen LM (BLIP-2, Flamingo). The 2023–2025 generation made a pretrained LLM the trunk and treated vision as a bolt-on adapter (LLaVA, Qwen2.5-VL, GPT-4V). The 2025–2026 generation drops the bridge entirely and early-fuses all modalities into a single transformer — forking along the output axis — and in 2026 the trunk is becoming a world model that predicts and acts:
- Era 3a — Native Multimodal Input → Text Out. Image, video, and (sometimes) audio enter a single early-fused token stream, but generation is still autoregressive text. This is the design used by today's general-purpose flagships: Qwen3.5 / Qwen3.6, Gemma 4, Gemini 3, GPT-5.4, Phi-4-Reasoning-Vision, Claude Opus 4.6, Nemotron 3 Nano Omni.
- Era 3b — Omni-Modal Unified I/O. The same fused trunk plus dedicated image / video decoder (VAE / DiT / flow-matching) and/or audio codec decoder heads, so the model can also generate images, video, and speech — via autoregression or, increasingly, discrete diffusion / AR-Diffusion (LLaDA2.0-Uni, Mamoda2.5) — and the newest 3b models (SenseNova-U1.5, 09/2026) are dropping the VAE too, running understanding + reasoning + generation through one encoder-free and VAE-free mixture-of-transformers trunk. This is the design used by unified models: SenseNova-U1.5, BAGEL, Qwen3.5-Omni, InternVL-U, Emu3 / Emu3.5, Erin 5.0, DeepSeek-Janus-Pro, LLaDA2.0-Uni, Mamoda2.5. Generation-only specialists share the same decoder stack without the understanding half — Sora 2, Veo 3, Kling now generate video with synchronized audio, and they double as the substrate for Era 4 world models (DreamX-World builds on Wan, OmniDreams on Cosmos, SolarWM on Wan2.2 / LTX-2.5 / MiniMax-H3).
- Era 4 — World-Action Models (2026 →). The unified trunk adds action as a first-class modality and closes the loop with the environment: it predicts future observations, maintains persistent state and spatial memory, and emits actions — generator, perceiver, and policy in one network. Founding releases: Cosmos 3, Kairos, DreamX-World 1.0, OmniDreams; the 08–09/2026 wave: DreamX-Phi 1.0 (WorldArena 2.0 winner), SimWAM (91.5 PDMS NAVSIM), ZimaBlue (120k h video pretraining), G0.5 (one AR stream for reasoning+action), Puffin-World (native 3D world states), SolarWM (open 5B–33B, real-time minute-to-hour rollouts) (see §1.1 World Models).
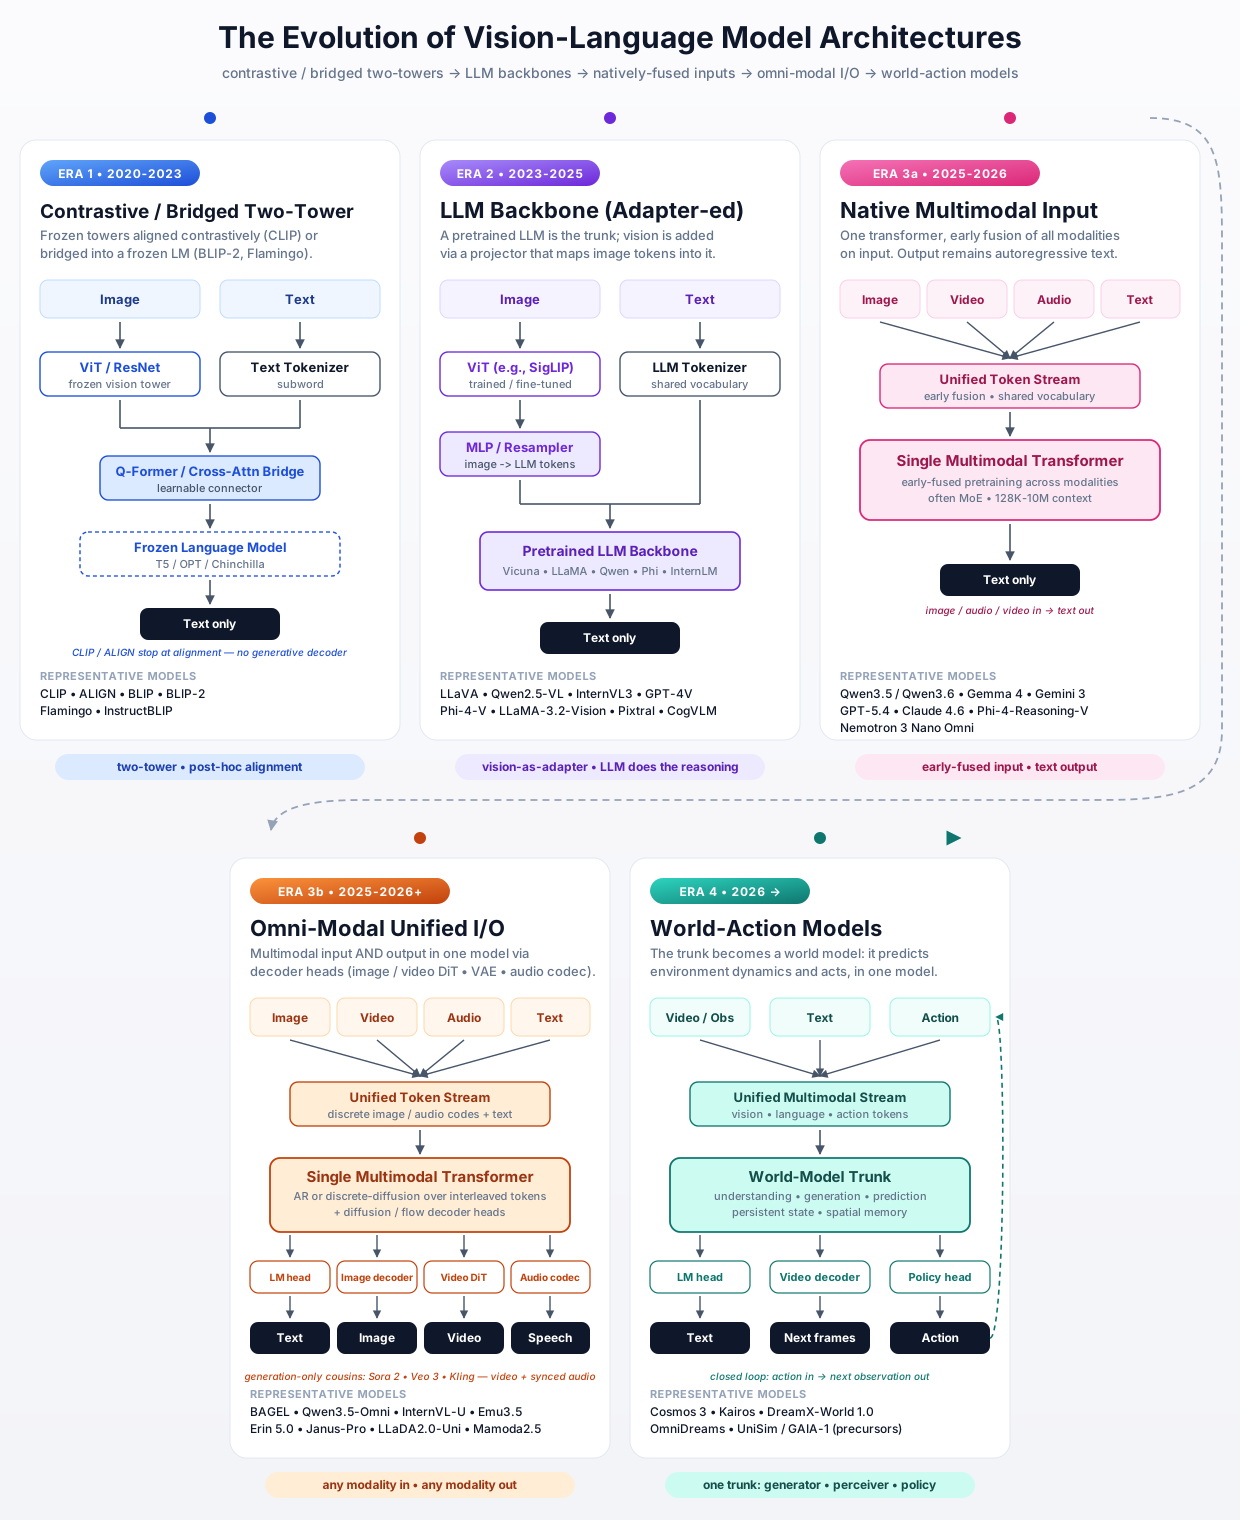
Reading the diagram (left → right). Era 1 uses a two-tower design — aligned contrastively (CLIP: no generative decoder) or with a learnable cross-modal bridge (e.g. Q-Former) into a frozen LM — text-only output. Era 2 puts a pretrained LLM at the center; an MLP/Resampler projects visual tokens into the LLM's vocabulary, and the LLM does all the reasoning — still text-only output. Era 3a drops the bridge: image, video, audio, and text share a single tokenizer/embedding space and flow through one early-fused transformer — but the output is still autoregressive text. Era 3b keeps that fused trunk and adds decoder heads (image/video DiT, VAE, audio codec) so the model can natively output text, image, video, and/or speech — generation-only video models (Sora 2, Veo 3, Kling) reuse this decoder stack, now with synchronized audio. Era 4 adds an action token stream, persistent state, and a policy head, closing the observation → action → next-observation loop: the world-action model is generator, perceiver, and policy at once. Eras 3a, 3b, and 4 coexist; the choice is essentially "how much do you want the model to generate — and to act?"
🆕 What's in this repo
Below we compile awesome papers and model and github repositories that
- State-of-the-Art VLMs Collection of newest to oldest VLMs (we'll keep updating new models and benchmarks).
- Evaluate VLM benchmarks and corresponding link to the works
- Post-training/Alignment Newest related work for VLM alignment including RL, sft.
- Applications applications of VLMs in embodied AI, robotics, etc.
- Contribute surveys, perspectives, and datasets on the above topics.
📡 VLM Trends
VLM Trends is the live companion to this repository. This README records what exists; VLM Trends tracks what changed today — new model releases, papers, benchmarks, and datasets pulled daily from arXiv, Hugging Face, GitHub, and Semantic Scholar, scored on a published rubric, and grouped by topic and model family. It also makes this survey browsable, and charts how each research direction is moving over time.
Progressive research reports
We track new VLMs, benchmarks, and post-training methods that haven't yet been folded into the main tables in dated mini-surveys:
📂 Expand all 10 reports — latest: 2026-09-13, Era 4 fills out and the unified trunk drops the VAE (50 new entries)
-
📰
2026-09-13— latest: Era 4 becomes a paradigm — six world-action systems ship in five weeks: DreamX-Phi 1.0 (WorldArena 2.0 winner), SimWAM (91.5 PDMS NAVSIM), ZimaBlue (120k h video pretraining, 30 Hz on RTX 4090), G0.5 (one AR stream for reasoning+action), Puffin-World (native 3D world states), SolarWM (open 5B–33B). Unified stack keeps shedding components — SenseNova-U1.5 ships 8B mixture-of-transformers encoder-free and VAE-free at native 4K. First VL foundation model for driving: Qwen-Drive-1.0 (Alibaba). Speech unification: AuK (Tencent Hunyuan, 4.5× via 4-step). First open >700B multimodal RL post-training stack: Miles v0.1 (GLM-5.2 744B-A40B, 64 GB300s, 263s/step). Frontier eval reopens on continuous settings — VideoGAIA puts GPT-5.5/Kimi K3 <60%; EgoMonth: 71.8% Gemini vs 94.2% human; StateSight probes latent state; WorldReward and PAWBench add reward/probabilistic-alignment axes for world models — 50 new entries since August 10. -
📰
2026-08-10— Evaluation stops asking whether a model sees — HumanCLAW (can a VLM act through a body?), GST-Bench (global spatial awareness from video), ChronoVision (temporal reasoning via latent state), WorldExam (reactivity over appearance); judging becomes its own research problem via OSReward, ConfBench, TruthLens. On the model side: Qwen3.8-Max (2.4T · 95B active, Vision Arena #2), DiffusionGemma (26B-A4B diffusion Gemma), Hunyuan3D-Buffalo 1.0 (unified 3D); plus N₀-VTLA (tactile VLA), Metis, Ego2Robot, VideoCoCo, OmniPack — 29 new entries since July 22. -
📰
2026-07-22— World models become the evaluators — GigaWorld-1 + WMBench, RoboWorld (r = 0.989 vs real-world), World-Action-Model tutorial; Gemma 4 tech report (encoder-free 12B), PRA-GRPO (93.2% V-Star at 4B), VRRL (trained self-reflection), LingBot-VLA 2.0 (60,000-hour corpus), ROSA (robot-factory serving), ISPA (50% KV-cache cut), OmniFocus, MoHallBench / LongVQUBench / SciVis-literacy benchmarks; plus the July frontier wave: Gemini 3.6 Flash, Kimi K3 (2.8T open MoE), GPT-5.5 / GPT-5.6 Sol, Grok 4.5, Qwen3.7-Plus — 19 new entries since June 27. -
📰
2026-06-27— World-model foundation releases — Cosmos 3 (NVIDIA omnimodal family: best open T2I/I2V + best RoboArena policy), Kairos (4B edge-real-time world-model stack, beats 14B), DreamX-World 1.0 (5B MIT-licensed interactive world model); "Persistent State Core" critique + Echo-Memory; ZPPO (teacher-in-prompts beats GRPO), Qwen-RobotManip (38,100-hour corpus), Supervise What Survives, VisCritic (visual process rewards for GUI), HPP (long video), IMCBench (medical dialogue safety) — 11 new entries since June 23. -
📰
2026-06-23— World Models focus — NVIDIA OmniDreams (real-time closed-loop driving world model), Mirage (latent spatial memory), Reward-as-Agent (GRPO for world models), WorldOlympiad & LongSpace-Bench (world-model benchmarks); plus PP-OCRv6 (34.5M beats 235B VLMs on OCR), Occ-VLM (3D-grounded), discrete-diffusion RL reasoning, VLA layer pruning, Hy-Embodied-0.5-VLA, RT-VLA (44.8× faster driving), VLA language steering — 12 new entries since June 2. -
📰
2026-06-02— Mamoda2.5 (AR-Diffusion DiT-MoE, 95.9× faster editing), VLM3 (native 3D learners), AlphaGRPO (RL for unified-model generation), Stage-wise Preference Optimization, FastOCR / WindowQuant (KV-cache efficiency), Fast-dDrive / CLOVER / CoWorld-VLA (driving VLA), Lost in Fog (reasoning-as-safety-signal), LiteGUI (SFT-free GUI agents), Health-Conditioned VLA, POLAR, TOC-Bench / VGenST-Bench (video), HalluCXR (medical) — 16 new entries since May 16. -
📰
2026-05-16— LensVLM (Apple), Nemotron 3 Nano Omni (NVIDIA), LLaDA2.0-Uni, PLaMo 2.1-VL, S-GRPO / Faithful GRPO / GRPO-TTA / OpenSearch-VL, MindVLA-U1 (surpasses human driving), VLADriver-RAG, Green-VLA, Anticipation-VLA, VLA Foundry, LAMO, ScreenExplorer, VideoZeroBench, Video-Oasis, MedThinkVQA, data curation at 87× less compute — 34 new entries since April 28. -
📰
2026-04-28— Qwen3.6-27B & Qwen3.6-35B-A3B, Claude Mythos (gated), S1-VL, GLM-5V-Turbo, FreshPER / GMPO / ARPO / GRPO-VPS, QUOTA, Fast-dVLM, VLA-World, SpanVLA, VLA-Forget, R-VLM, UILoop, WebForge, WorldMark, Video-MME-v2, CrossMath, BabyVision, SlowBA — 30 new entries since April 13. -
📰
2026-04-13— LFM2.5-VL-450M, EXAONE 4.5, Gemma 4, Granite 4.0 3B Vision, InternVL-U, GLM-4.6V, Vero, MolmoWeb, UniDriveVLA, QAPruner, Firebolt-VL, CoME-VL, and more. -
📰
2026-03-25— GPT-5.4, Phi-4-Reasoning-Vision-15B, Gemini 3.0, Qwen3.5, Claude Opus 4.6, Molmo2, and more.
Welcome to contribute and discuss!
🤩 Papers marked with a ⭐️ are contributed by the maintainers of this repository. If you find them useful, we would greatly appreciate it if you could give the repository a star or cite our paper.
Table of Contents
-
- 1.1. 🌍 World Models
-
- 3.1. RL Alignment for VLM
- 3.2. Regular finetuning (SFT)
- 3.3. VLM Alignment Github
- 3.4. Prompt Engineering
-
- 4.1. Embodied VLM agents
- 4.2. Generative Visual Media Applications
- 4.3. Robotics and Embodied AI
- 4.3.1. Manipulation
- 4.3.2. Navigation
- 4.3.3. Human-robot Interaction
- 4.3.4. Autonomous Driving
- 4.4. Human-Centered AI
- 4.4.1. Web Agent
- 4.4.2. Accessibility
- 4.4.3. Medical and Healthcare
- 4.4.4. Social Goodness
-
- 5.1. Hallucination
- 5.2. Safety
- 5.3. Fairness
- 5.4. Alignment
- 5.4.1. Multi-modality Alignment
- 5.5. Efficient Training and Fine-Tuning
- 5.6. Scarce of High-quality Dataset
0. Citation
@InProceedings{Li_2025_CVPR,
    author    = {Li, Zongxia and Wu, Xiyang and Du, Hongyang and Liu, Fuxiao and Nghiem, Huy and Shi, Guangyao},
    title     = {A Survey of State of the Art Large Vision Language Models: Benchmark Evaluations and Challenges},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops},
    month     = {June},
    year      = {2025},
    pages     = {1587-1606}
}
1. 📚 SoTA VLMs
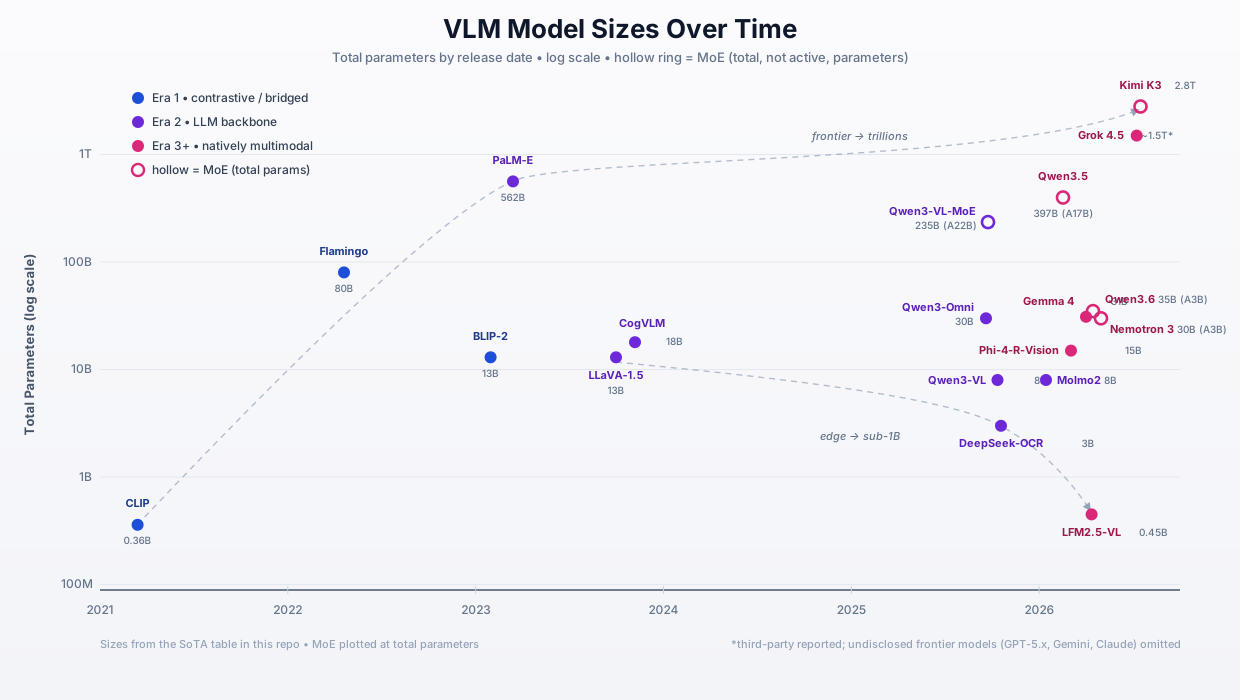
| Model | Year | Architecture | Training Data | Parameters | Vision Encoder/Tokenizer | Pretrained Backbone Model |
|---|---|---|---|---|---|---|
| SenseNova-U1.5 | 09/10/2026 | Encoder-free and VAE-free native unified visual intelligence; mixture-of-transformers; understanding + reasoning + generation in one trunk; native resolutions up to 4K | Undisclosed | 8B MoT | None (encoder-free) | Trained from scratch — HF · Code |
| Qwen3.8-Max (Alibaba) | 08/03/2026 | Sparse MoE + hybrid attention; text + vision in, 1M context; Vision Arena #2 | Undisclosed | 2.4T total · 95B active | Native multimodal | Qwen3.8 |
| DiffusionGemma (Google) | 08/05/2026 | Diffusion (non-autoregressive) language model in the Gemma family | Undisclosed | 26B total · 4B active | Native multimodal | Gemma |
| Hunyuan3D-Buffalo 1.0 (Tencent) | 08/05/2026 | Unified multimodal — 3D generation + understanding + editing | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Gemini 3.6 Flash (Google) | 07/21/2026 | Decoder-only / natively multimodal input (text, image, speech, video → text) | Undisclosed | Undisclosed | Native multimodal | Gemini 3.x |
| Kimi K3 (Moonshot AI) | 07/17/2026 | MoE, natively multimodal reasoning — text + image + video in one trunk (no separate vision module); 1M context; open weights due 07/27/2026 | Undisclosed | ~2.8T total (MoE) | Native (encoder-integrated) | New architecture |
| GPT-5.6 Sol (OpenAI) | 07/09/2026 | Decoder-only; text + image in, 1.05M context / 128K output; max & ultra reasoning modes, sub-agent orchestration (Ultra); family: Luna / Terra / Sol | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Grok 4.5 (xAI) | 07/08/2026 | Decoder-only reasoning (extended thinking); text + image + files in, 500K context | Undisclosed | ~1.5T (reported) | Undisclosed | Undisclosed |
| Qwen3.7-Plus (Alibaba) | 06/01/2026 | Natively multimodal agent — image + video understanding, GUI grounding, tool invocation (note: Qwen3.7-Max is text-only) | Undisclosed | Undisclosed | Native multimodal ViT | Qwen3.7 |
| Mamoda2.5 (InclusionAI) | 05/04/2026 | AR-Diffusion + DiT-MoE (unified understanding + generation; 128 experts, Top-8) | Multimodal und. + image/video generation & editing | 25B total · 3B active | Semantic tokenizer + DiT decoder head | Mamoda2 |
| Nemotron 3 Nano Omni (NVIDIA) | 04/28/2026 | Hybrid MoE (omni-modal: vision + audio + text) | Vision + audio + text joint training | 30B total · 3B active | Dynamic-res ViT + Conv3D temporal | Nemotron 3 |
| GPT-5.5 (OpenAI) | 04/23/2026 | Decoder-only; text + image in (GPT-5 input stack), computer-use screen reading in Codex; topped AA Intelligence Index at release | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Qwen3.6-27B (Alibaba) | 04/22/2026 | Decoder-only / natively multimodal input (thinking + non-thinking) | Multimodal pretraining + agentic mid-training | 27B dense | Native multimodal ViT | Qwen3.6 |
| Qwen3.6-35B-A3B (Alibaba) | 04/15/2026 | MoE / natively multimodal input | Multimodal pretraining + agentic SFT/RL | 35B total · 3B active | Native multimodal ViT | Qwen3.6 |
| LFM2.5-VL-450M (Liquid AI) | 04/11/2026 | Liquid Foundation Model | Undisclosed | 450M | Non-overlapping tile ViT | LFM2.5 |
| EXAONE 4.5 (LG AI Research) | 04/09/2026 | Unified VL | Undisclosed | 33B | Proprietary vision encoder | EXAONE 4.5 |
| Claude Mythos (Anthropic, gated preview) | 04/07/2026 | Decoder-only (frontier; Project Glasswing gated) | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Gemma 4 (Google) | 04/02/2026 | Decoder-only / MoE | Undisclosed (140+ languages) | E2B / E4B / 26B MoE / 31B Dense | Native multimodal | Gemini 3 |
| Granite 4.0 3B Vision (IBM) | 04/01/2026 | Decoder-only | Enterprise document corpora | 3B | Undisclosed | Granite 4.0 |
| GLM-5V-Turbo (Zhipu / Z.AI) | 04/01/2026 | Natively multimodal (vision-coding) with Multi-Token Prediction | 30+ task joint RL | Undisclosed | CogViT | GLM-5 |
| InternVL-U (Shanghai AI Lab) | 03/10/2026 | Unified (MLLM + MMDiT) | Multimodal understanding + generation | 4B | InternViT | InternVL |
| GPT-5.4 / GPT-5.4 Thinking (OpenAI) | 03/06/2026 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Phi-4-Reasoning-Vision-15B (Microsoft) | 03/04/2026 | Decoder-only | Curated synthetic + filtered data | 15B | High-res dynamic-resolution ViT | Phi-4 |
| Gemini 3.0 (Google) | 03/2026 | Unified Model | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Qwen3.5 (Alibaba) | 02/16/2026 | Unified VL (early fusion) | Trillions of multimodal tokens | 0.8B–397B (MoE, 17B active) | ViT (native) | Qwen3.5 |
| Claude Opus 4.6 (Anthropic) | 02/2026 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Erin 5.0 (Baidu) | 02/05/2026 | Unified Model (Visual, Text, Audio) | Unified Modality Dataset | - | CNN–ViT (Understanding)/Next-Frame-and-Scale Prediction (Generation) | Unified Autoregressive Transformer |
| Molmo2 (Allen AI) | 01/15/2026 | Decoder-only | 7 new video + 2 multi-image datasets (9.19M videos) | 4B / 7B / 8B | Bi-directional attention ViT | Qwen 3 / OLMo |
| Gemini 3 | 11/18/2025 | Unified Model | Undisclosed | - | - | - |
| Emu3.5 | 10/30/2025 | Deconder-only | Unified Modality Dataset | - | SigLIP | Qwen3 |
| DeepSeek-OCR | 10/20/2025 | Encoder-Deconder | 70% OCR, 20% general vision, 10% text-only | 3B | DeepEncoder | DeepSeek-3B |
| Qwen3-VL | 10/11/2025 | Decoder-Only | - | 8B/4B | ViT | Qwen3 |
| Qwen3-VL-MoE | 09/25/2025 | Decoder-Only | - | 235B-A22B | ViT | Qwen3 |
| Qwen3-Omni (Visual/Audio/Text) | 09/21/2025 | - | Video/Audio/Image | 30B | ViT | Qwen3-Omni-MoE-Thinker |
| LLaVA-Onevision-1.5 | 09/15/2025 | - | Mid-Training-85M & SFT | 8B | Qwen2VLImageProcessor | Qwen3 |
| InternVL3.5 | 08/25/2025 | Decoder-Only | multimodal & text-only | 30B/38B/241B | InternViT-300M/6B | Qwen3 / GPT-OSS |
| SkyWork-Unipic-1.5B | 07/29/2025 | - | image/video.. | - | - | - |
| Grok 4 | 07/09/2025 | - | image/video.. | 1-2 Trillion | - | - |
| Kwai Keye-VL (Kuaishou) | 07/02/2025 | Decdoer-only | image/video.. | 8B | ViT | QWen-3-8B |
| OmniGen2 | 06/23/2025 | Decdoer-only & VAE | LLaVA-OneVision/ SAM-LLaVA.. | - | ViT | QWen-2.5-VL |
| Gemini-2.5-Pro | 06/17/2025 | - | - | - | - | - |
| GPT-o3/o4-mini | 06/10/2025 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Mimo-VL (Xiaomi) | 06/04/2025 | Decdoer-only | 24 Trillion MLLM tokens | 7B | [Qwen2.5-ViT | Mimo-7B-base |
| BAGEL (Bytedance) | 05/20/2025 | Unified Model | Video/Image/Text | 7B | SigLIP2-so400m/14](https://arxiv.org/abs/2502.14786) | Qwen2.5 |
| BLIP3-o | 05/14/2025 | Decdoer-only | (BLIP3-o 60K) GPT-4o Generated Image Generation Data | 4/8B | ViT | QWen-2.5-VL |
| InternVL-3 | 04/14/2025 | Decdoer-only | 200 Billion Tokens | 1/2/8/9/14/38/78B | ViT-300M/6B | InterLM2.5/QWen2.5 |
| LLaMA4-Scout/Maverick | 04/04/2025 | Decdoer-only | 40/20 Trillion Tokens | 17B | MetaClip | LLaMA4 |
| Qwen2.5-Omni | 03/26/2025 | Decdoer-only | Video/Audio/Image/Text | 7B | Qwen2-Audio/Qwen2.5-VL ViT | End-to-End Mini-Omni |
| QWen2.5-VL | 01/28/2025 | Decdoer-only | Image caption, VQA, grounding agent, long video | 3B/7B/72B | Redesigned ViT | Qwen2.5 |
| GLM-4.6V (Zhipu / Z.AI) | 12/2025 | Decoder-only | Undisclosed | 106B / 9B (Flash) | Undisclosed | GLM-4.6 |
| Ola | 2025 | Decoder-only | Image/Video/Audio/Text | 7B | OryxViT | Qwen-2.5-7B, SigLIP-400M, Whisper-V3-Large, BEATs-AS2M(cpt2) |
| Ocean-OCR | 2025 | Decdoer-only | Pure Text, Caption, Interleaved, OCR | 3B | NaViT | Pretrained from scratch |
| SmolVLM | 2025 | Decoder-only | SmolVLM-Instruct | 250M & 500M | SigLIP | SmolLM |
| DeepSeek-Janus-Pro | 2025 | Decoder-only | Undisclosed | 7B | SigLIP | DeepSeek-Janus-Pro |
| Inst-IT | 2024 | Decoder-only | Inst-IT Dataset, LLaVA-NeXT-Data | 7B | CLIP/Vicuna, SigLIP/Qwen2 | LLaVA-NeXT |
| DeepSeek-VL2 | 2024 | Decoder-only | WiT, WikiHow | 4.5B x 74 | SigLIP/SAMB | DeepSeekMoE |
| xGen-MM (BLIP-3) | 2024 | Decoder-only | MINT-1T, OBELICS, Caption | 4B | ViT + Perceiver Resampler | Phi-3-mini |
| TransFusion | 2024 | Encoder-decoder | Undisclosed | 7B | VAE Encoder | Pretrained from scratch on transformer architecture |
| Baichuan Ocean Mini | 2024 | Decoder-only | Image/Video/Audio/Text | 7B | CLIP ViT-L/14 | Baichuan |
| LLaMA 3.2-vision | 2024 | Decoder-only | Undisclosed | 11B-90B | CLIP | LLaMA-3.1 |
| Pixtral | 2024 | Decoder-only | Undisclosed | 12B | CLIP ViT-L/14 | Mistral Large 2 |
| Qwen2-VL | 2024 | Decoder-only | Undisclosed | 7B-14B | EVA-CLIP ViT-L | Qwen-2 |
| NVLM | 2024 | Encoder-decoder | LAION-115M | 8B-24B | Custom ViT | Qwen-2-Instruct |
| Emu3 | 2024 | Decoder-only | Aquila | 7B | MoVQGAN | LLaMA-2 |
| Claude 3 | 2024 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| InternVL | 2023 | Encoder-decoder | LAION-en, LAION- multi | 7B/20B | Eva CLIP ViT-g | QLLaMA |
| InstructBLIP | 2023 | Encoder-decoder | CoCo, VQAv2 | 13B | ViT | Flan-T5, Vicuna |
| CogVLM | 2023 | Encoder-decoder | LAION-2B ,COYO-700M | 18B | CLIP ViT-L/14 | Vicuna |
| PaLM-E | 2023 | Decoder-only | All robots, WebLI | 562B | ViT | PaLM |
| LLaVA-1.5 | 2023 | Decoder-only | COCO | 13B | CLIP ViT-L/14 | Vicuna |
| Gemini | 2023 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| GPT-4V | 2023 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| BLIP-2 | 2023 | Encoder-decoder | COCO, Visual Genome | 7B-13B | ViT-g | Open Pretrained Transformer (OPT) |
| Flamingo | 2022 | Decoder-only | M3W, ALIGN | 80B | Custom | Chinchilla |
| BLIP | 2022 | Encoder-decoder | COCO, Visual Genome | 223M-400M | ViT-B/L/g | Pretrained from scratch |
| CLIP | 2021 | Encoder-decoder | 400M image-text pairs | 63M-355M | ViT/ResNet | Pretrained from scratch |
1.1. 🌍 World Models
World models moved from research demos to release-grade artifacts in mid-2026: unified trunks that serve as generator, perceiver, and policy at once. Foundation releases first, then memory/state analyses and benchmarks.
| Model | Date | Type | Scale / License | Key Result | Links |
|---|---|---|---|---|---|
| Puffin-World | 09/03/2026 | Unified multimodal model with native 3D world states — jointly models gravity/latitude, depth, and image via Omni-Camera representation | Puffin-16M dataset; open code + weights | Ties physical understanding, spatial simulation, and 3D world generation/reconstruction into one architecture | Paper · Project |
| SolarWM | 09/02/2026 | Open foundation for interactive video world models; reconfigurable multi-source data engine + backbone-native adaptation on Wan2.2 / LTX-2.5 / MiniMax-H3 | 5B, 12B, 20B, 33B; CC BY 4.0 | Real-time minute-to-hour rollouts after training on only 5 s sequences; data + pipeline + weights + framework released | Paper · Project |
| ZimaBlue | 08/31/2026 | Generalizable world-action model via video pre-training on >120k h human + robot egocentric video; asynchronous Slow-Fast | 120k+ h | Zero-shot real-robot success 36.1% → 77.8% as pretraining video scales; 30 Hz on an RTX 4090 | Paper |
| Matrix-Game 3.5 | 08/30/2026 | Real-time streaming interactive world model with parameter-free patch memory + tiled-PRoPE geometry-aware memory + two-stage distillation | — | Minute-long real-time generation; extends v3.0 to answer the persistent-state critique | Paper · Project |
| DreamX-Phi 1.0 | 08/13/2026 | Action-conditioned video world model for robotic manipulation; per-arm SE(3) via PRoPE + depth branch + SAM3/V-JEPA object consistency + DMD few-step distillation | Open weights + code | 1st on Track 1, 2nd on Track 2 of the WorldArena 2.0 Challenge | Paper · Code |
| SimWAM | 08/07/2026 | World-Action Model for end-to-end autonomous driving; video expert + lightweight action expert co-trained via flow matching + RL | Open weights + code (CC BY 4.0) | 91.5 PDMS on NAVSIM with zero-shot nuScenes transfer | Paper · Code |
| G0.5 | 08/12/2026 | One AR stream for robot reasoning and action — single transformer emits reasoning + action tokens under one objective; cross-embodiment action tokenizer + multi-second visual memory | — | 76.7% R1lite/R1pro (vs π0.5 53.3%, GR00T-N1.7 24.4%), 82.5% zero-shot DROID, 98.9% LIBERO, 87.3% SimplerEnv-Bridge | Paper |
| HelloWorld | 08/06/2026 | Video world model with socially interactive characters | — | Pushes world models past physics and navigation into social dynamics: characters that respond to the viewer rather than merely persisting | Paper |
| VideoCoCo | 07/31/2026 | Agentic dual-engine text-to-video with Code-as-CoT | — | Infers temporal evolution symbolically via generated code instead of implicitly, then renders — a hybrid attack on physics violations in T2V | Paper |
| StatePlay | 07/29/2026 | State-aware game world model | — | Enforces mechanics consistency through explicit state, an answer to the persistent-state critique below | Paper |
| Cosmos 3 (NVIDIA) | 06/01/2026 | Omnimodal world-model family (language, image, video, audio, action) — mixture-of-transformers | Family; open code/checkpoints/data (OpenMDW-1.1) | SoTA across VL, video generation, robot policy; best open T2I/I2V + best RoboArena policy | Paper |
| Kairos | 06/15/2026 | Native world-model stack (understanding + generation + prediction) | 4B unified; Hybrid Linear Temporal Attention | Cross-embodiment data curriculum; real-time rollout on edge hardware; beats 14B on embodied benchmarks | Paper |
| DreamX-World 1.0 (Alibaba AMAP) | 06/15/2026 | General-purpose interactive T/I-to-video world model | 5B (Wan2.2-T2V-5B base); MIT open weights | Camera navigation, revisit consistency, promptable events; E-PRoPE encoding; few-step AR via causal forcing + DMD distillation | HF · Code |
| NVIDIA OmniDreams | 06/02/2026 | Real-time generative world model for closed-loop AV simulation | Mid/post-trained from Cosmos on 21k h driving | Action-conditioned sensor video; derived world-action model beats VLA-based Alpamayo 1.5 at 1/5 params | Paper |
| Mirage | 06/08/2026 | Latent spatial memory for video world models | — | 3D scene memory in diffusion latent space via depth-guided back-projection; faster + lighter than explicit-3D baselines | Paper |
| Reward as An Agent | 06/18/2026 | RL post-training for embodied world models | — | DynDiff-GRPO diversifies action-space exploration; agentic reward verification curbs reward hacking | Paper |
Benchmarks & analyses
| Title | Date | What It Shows | Link |
|---|---|---|---|
| WorldReward | 09/03/2026 | First VLM-based pairwise preference reward model for camera-conditioned world models; decomposes paired videos into action-aligned chunks with structured visual evidence; beats GPT-5.5 by 3.42/1.45/3.56 pts on three WorldReward-Bench dimensions and improves HY-WorldPlay 1.5 in RL post-training | Paper |
| PAWBench | 08/27/2026 | Probabilistic alignment: evaluates video generators as stochastic samplers of world dynamics via PAWEval (repeated rollouts → empirical outcome distributions); no model across 50 scenarios / 11 systems consistently matches reference probabilities while covering valid behaviors | Paper |
| GUI-CC | 09/01/2026 | Benchmarks contextual consistency of GUI world models as agent environments — extends the world-model-as-environment critique to computer-use | Paper |
| WorldExam | 08/04/2026 | Separates apparent appearance from inherent reactivity: a world model can look right while reacting wrong, formalising the critique that visual realism has been over-weighted | Paper |
| WorldOlympiad | 06/09/2026 | Physics / geometry / interaction "triathlon": SoTA world models show substantial gaps in physical reasoning, 3D consistency, long-horizon control | Paper |
| Current World Models Lack a Persistent State Core | 06/18/2026 | World models treat the world as a "tracking shot" — off-screen entities freeze instead of evolving; persists across architectures and scales | Paper |
| Echo-Memory | 06/08/2026 | Controlled memory study: raw context beats compressed memory for capacity; state-space recurrence best for revisit consistency | Paper |
| LongSpace / LongSpace-Bench | 06/04/2026 | Video MLLMs fail long-horizon spatial recall without explicit spatial memory (3D cues + layer-aware retrieval) | Paper |
See also the earlier world-model entries in §2.3 (UniSim, GAIA-1, LWM, Genesis, RoboGen) and the
2026-06-23/2026-06-27/2026-09-13progressive reports.
2. 🗂️ Benchmarks and Evaluation
2.1. Datasets for Training VLMs
| Dataset | Task | Size |
|---|---|---|
| 20/20 Vision — Data Curation (DatologyAI)(05/2026) | Data Curation for VLM Training | +11.7pp avg improvement; 17–87× less compute |
| MolmoWebMix (Allen AI)(04/2026) | Web Agent Training Trajectories | 100K+ synthetic + 30K human demos |
| Vero-600K(04/2026) | Broad Visual Reasoning RL Training | 600K samples from 59 datasets, 6 task categories |
| BigEarthNet.txt(03/2026) | Multi-sensor Earth Observation Image-Text | 464K images, 9.6M text annotations |
| OmniScience(02/2026) | Scientific Image Understanding | 1.5M figure-caption-context triplets |
| MaD-Mix(02/2026) | Multi-modal Data Mixture Optimization | Framework (0.5B–7B scale) |
| OVID(2026) | Open Video Pre-training | 10M hours, 300M frame-caption pairs |
| Molmo2 Video Datasets(01/2026) | Video Captions, QA, Tracking, Pointing | 9.19M videos (7 video + 2 multi-image datasets) |
| MMFineReason(/1/30/2026) | REasoning | 1.8M |
| FineVision(09/04/2025) | Mixed Domain | 24.3 M/4.48TB |
2.2. Datasets and Evaluation for VLM
🧮 Visual Math (+ Visual Math Reasoning)
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| MathVision | Visual Math | MC / Answer Match | Human | 3.04 | Repo |
| MathVista | Visual Math | MC / Answer Match | Human | 6 | Repo |
| MathVerse | Visual Math | MC | Human | 4.6 | Repo |
| VisNumBench | Visual Number Reasoning | MC | Python Program generated/Web Collection/Real life photos | 1.91 | Repo |
💬 Benchmark for Unified Models
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| ROVER | Reciprocal Cross-Modal Reasoning | Visual Gen + Verbal Gen Eval | Human | 1.3 (1,876 images) | Paper |
| RealUnify | Math, World knowledge, Image Gen | Direct & StepWise Eval (Sec 3.3) | Script & Humanverification | 1.0 | Repo |
| Uni-MMMU | Science, Code, Image Gen | DreamSim (Image Gen Eval) & String Matching (Understanding Eval) | - | 1.0 | Repo |
🎞️ Video Understanding
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| VideoGAIA | Agentic Video Understanding (tool-augmented multi-turn) | Human/model co-designed, triple-expert-verified | Expert | 0.27 (271 tasks) | Paper |
| OmniAssistBench | Real-Time Omni-LLM Assistants | Multi-turn guided interaction with predefined route priors | Expert (>1000 h) | - | Project |
| EgoMonth | Month-Level Egocentric Video / Long-Term Spatiotemporal Memory | 14-task Schema Consolidation / Episodic Indexing / Cascading Reasoning framework | Human | 1.44 (300+ h from 20 participants) | Paper |
| Video-IFBench | Instruction Following in Video Understanding | - | - | - | Paper |
| GST-Bench | Global Spatial Awareness from Continuous Video | Long-traversal scene integration (vs. single-viewpoint local perception) | - | - | Paper |
| ChronoVision | Multi-step Temporal Reasoning | Latent state reconstruction | - | - | Paper |
| VGenST-Bench | Spatio-temporal Reasoning via Active Video Synthesis | 3×2×2 taxonomy; synthesized controlled scenes decouple perception from reasoning | Multi-agent + Human QC | — | Paper |
| TOC-Bench | Temporal Object Consistency for Video-LLMs | 3-layer temporal-necessity filtering; identity/continuity through occlusion & state change | Human-verified | 2.3 (2,323 QA / 1,951 videos) | Paper |
| VideoZeroBench | Spatio-temporal Evidence Verification for Long-Video QA | 5-level progressive evidence tightening | Human | 0.5 (500 questions, 13 domains) | Paper |
| Video-Oasis | Diagnostic Meta-benchmark for Video Understanding | Measures % solvable without visual/temporal context | Meta-analysis | — | Paper |
| LoVR | Long Video Retrieval in Multimodal Contexts | Retrieval accuracy | — | — | Paper |
| MMOU | Omni-modal Long Video Understanding | MC | Human | 15 (9,038 videos) | Paper |
| Video-MMMU | Knowledge Acquisition from Professional Videos | MC + Knowledge Gain | Expert | 0.9 (300 videos) | Paper |
| MMVU | Expert-Level Multi-Discipline Video Understanding | MC | Expert | 3 (27 subjects) | Paper |
| VideoHallu | Video Understanding | LLM Eval | Human | 3.2 | Repo |
| Video SimpleQA | Video Understanding | LLM Eval | Human | 2.03 | Repo |
| MovieChat | Video Understanding | LLM Eval | Human | 1 | Repo |
| Perception‑Test | Video Understanding | MC | Crowd | 11.6 | Repo |
| VideoMME | Video Understanding | MC | Experts | 2.7 | Site |
| EgoSchem | Video Understanding | MC | Synth / Human | 5 | Site |
| Inst‑IT‑Bench | Fine‑grained Image & Video | MC & LLM | Human / Synth | 2 | Repo |
💬 Multimodal Conversation
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| VisionArena | Multimodal Conversation | Pairwise Pref | Human | 23 | Repo |
🧠 Multimodal General Intelligence
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| StateSight | Latent Spatial-State Reconstruction | Procedural single-image tasks (cube-nets, occluded towers, connected components); companion StateSight-Steps for intermediate visual states | Synth + oracle | 0.9 (300 items × 3 families) + 0.9 with interleaved steps | Paper |
| GUI-Primitives | Spatial Reasoning in GUI Grounding | 7 spatial relations; contrastive pairs; strict point-in-box | Human validated | 0.99 (994 pairs) | Paper |
| MBA | Real-World Business Ideation Agents | Multimodal agentic task quality | - | - | Paper |
| HumanCLAW | Can a VLM Act Through a Body? | Decouples the decision from motor control so failures attribute to perception, planning, or actuation | - | - | Paper |
| PerceptionBench | Atomic Visual Perception | Decomposes perception into primitive operations rather than end-task accuracy | - | - | Paper |
| C$^3$PO | Cross-Modal Composition & Counterfactuals (omni-modal) | Compositional and counterfactual probes for any-to-any models | - | - | Paper |
| OmniEarth | Geospatial / Remote Sensing VLM Eval | MC + Open VQA | Human (verified) | 44.2 (9,275 images, 28 tasks) | Paper |
| MultiHaystack | Multimodal Retrieval & Reasoning | Retrieval + QA | Human | 0.75 (46K+ candidates) | Paper |
| DatBench | Discriminative, Faithful VLM Eval | MC (format-aware) | Synth | - | Paper |
| MMLU | General MM | MC | Human | 15.9 | Repo |
| MMStar | General MM | MC | Human | 1.5 | Site |
| NaturalBench | General MM | Yes/No, MC | Human | 10 | HF |
| PHYSBENCH | Visual Math Reasoning | MC | Grad STEM | 0.10 | Repo |
🔎 Visual Reasoning / VQA (+ Multilingual & OCR)
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| EMMA | Visual Reasoning | MC | Human + Synth | 2.8 | Repo |
| MMTBENCH | Visual Reasoning & QA | MC | AI Experts | 30.1 | Repo |
| MM‑Vet | OCR / Visual Reasoning | LLM Eval | Human | 0.2 | Repo |
| MM‑En/CN | Multilingual MM Understanding | MC | Human | 3.2 | Repo |
| GQA | Visual Reasoning & QA | Answer Match | Seed + Synth | 22 | Site |
| VCR | Visual Reasoning & QA | MC | MTurks | 290 | Site |
| VQAv2 | Visual Reasoning & QA | Yes/No, Ans Match | MTurks | 1100 | Repo |
| MMMU | Visual Reasoning & QA | Ans Match, MC | College | 11.5 | Site |
| MMMU-Pro | Visual Reasoning & QA | Ans Match, MC | College | 5.19 | Site |
| R1‑Onevision | Visual Reasoning & QA | MC | Human | 155 | Repo |
| VLM²‑Bench | Visual Reasoning & QA | Ans Match, MC | Human | 3 | Site |
| VisualWebInstruct | Visual Reasoning & QA | LLM Eval | Web | 0.9 | Site |
📝 Visual Text / Document Understanding (+ Charts)
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| ExtractBench | Schema-Guided Enterprise Document Extraction | Scored against a target schema rather than free-form answers | - | - | Paper |
| ConfBench | Confidence Calibration on Document Extraction | Asks whether the model knows when it is wrong, not only whether it is right | - | - | Paper |
| TableVision | Spatially Grounded Table Reasoning | 3-level Cognitive Eval | Human | 6.8 (13 sub-categories) | Paper |
| TextVQA | Visual Text Understanding | Ans Match | Expert | 28.6 | Repo |
| DocVQA | Document VQA | Ans Match | Crowd | 50 | Site |
| ChartQA | Chart Graphic Understanding | Ans Match | Crowd / Synth | 32.7 | Repo |
🌄 Text‑to‑Image Generation
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| Sci-VBench | Knowledge- & Reasoning-Intensive Video Generation (Science) | Rubric-based (Prompt Grounding, Scientific/Causal Correctness); MLLM-as-Judge validated | Expert | 1.25 (1,253 prompts × 60 subjects) | Paper |
| PAWBench | Probabilistically Aligned World Modeling | PAWEval — repeated rollouts → empirical outcome distributions | Reference distributions | 50 scenarios × 11 systems | Paper |
| VGI-Bench | Visual Intelligence in Video Generation Models | Probes scene understanding inside the generator | - | - | Paper |
| FilmBench | Film-Grade Cinematic Video Generation | Craft criteria — shot grammar, continuity, staging | - | - | Paper |
| MPIE-Bench | Anatomically Plausible Multi-Person Interaction Editing | Anatomical plausibility under multi-subject edits | - | - | Paper |
| MSCOCO‑30K | Text‑to‑Image | BLEU, ROUGE, Sim | MTurks | 30 | Site |
| GenAI‑Bench | Text‑to‑Image | Human Rating | Human | 80 | HF |
🚨 Hallucination Detection / Control
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| HallusionBench | Hallucination | Yes/No | Human | 1.13 | Repo |
| POPE | Hallucination | Yes/No | Human | 9 | Repo |
| CHAIR | Hallucination | Yes/No | Human | 124 | Repo |
| MHalDetect | Hallucination | Ans Match | Human | 4 | Repo |
| Hallu‑Pi | Hallucination | Ans Match | Human | 1.26 | Repo |
| HallE‑Control | Hallucination | Yes/No | Human | 108 | Repo |
| AutoHallusion | Hallucination | Ans Match | Synth | 3.129 | Repo |
| BEAF | Hallucination | Yes/No | Human | 26 | Site |
| GAIVE | Hallucination | Ans Match | Synth | 320 | Repo |
| HalEval | Hallucination | Yes/No | Crowd / Synth | 2 | Repo |
| AMBER | Hallucination | Ans Match | Human | 15.22 | Repo |
| MVI-Bench | Misleading Visual Inputs | Ans Match | Human | 1.25 | Repo |
2.3. Benchmark Datasets, Simulators, and Generative Models for Embodied VLM
| Benchmark | Domain | Type | Project |
|---|---|---|---|
| OSReward | Computer-Use Agents | Cross-platform reward-model evaluation | Paper |
| Drive-Bench | Embodied AI | Autonomous Driving | Website |
| Habitat, Habitat 2.0, Habitat 3.0 | Robotics (Navigation) | Simulator + Dataset | Website |
| Gibson | Robotics (Navigation) | Simulator + Dataset | Website, Github Repo |
| iGibson1.0, iGibson2.0 | Robotics (Navigation) | Simulator + Dataset | Website, Document |
| Isaac Gym | Robotics (Navigation) | Simulator | Website, Github Repo |
| Isaac Lab | Robotics (Navigation) | Simulator | Website, Github Repo |
| AI2THOR | Robotics (Navigation) | Simulator | Website, Github Repo |
| ProcTHOR | Robotics (Navigation) | Simulator + Dataset | Website, Github Repo |
| VirtualHome | Robotics (Navigation) | Simulator | Website, Github Repo |
| ThreeDWorld | Robotics (Navigation) | Simulator | Website, Github Repo |
| VIMA-Bench | Robotics (Manipulation) | Simulator | Website, Github Repo |
| VLMbench | Robotics (Manipulation) | Simulator | Github Repo |
| CALVIN | Robotics (Manipulation) | Simulator | Website, Github Repo |
| GemBench | Robotics (Manipulation) | Simulator | Website, Github Repo |
| WebArena | Web Agent | Simulator | Website, Github Repo |
| UniSim | Robotics (Manipulation) | Generative Model, World Model | Website |
| GAIA-1 | Robotics (Automonous Driving) | Generative Model, World Model | Website |
| LWM | Embodied AI | Generative Model, World Model | Website, Github Repo |
| Genesis | Embodied AI | Generative Model, World Model | Github Repo |
| EMMOE | Embodied AI | Generative Model, World Model | Paper |
| RoboGen | Embodied AI | Generative Model, World Model | Website |
| UnrealZoo | Embodied AI (Tracking, Navigation, Multi Agent) | Simulator | Website |
3. ⚒️ Post-Training
3.1. RL Alignment for VLM
| Title | Year | Paper | RL | Code |
|---|---|---|---|---|
| Miles v0.1: Production-Level Post-Training | 09/08/2026 | Paper | Full-stack open async agentic RL; demonstrated on GLM-5.2 744B-A40B MoE across 64 NVIDIA GB300 GPUs (263 s median step) | Code |
| Reason Through the Latent! (CVRR) | 09/06/2026 | Paper | Causal Visual Recurrent Reasoning — strips visual KV cache before decoding to force latent reasoning; strong retention on V*, MMVP, BLINK, MME-RealWorld-Lite | - |
| Beyond Data Scaling: Representation-Centric Continued Pre-training for VLAs (VLAct) | 08/27/2026 | Paper | VLM-prior preservation + multi-head continuous action co-supervision + partial cross-embodiment unification; 82.6% LIBERO-Plus, 92.5% RoboTwin 2.0 with 20% of trajectories | Project |
| Co-RL: Unsupervised Reasoning Emerges from Diverse Cohort in Multi-Agent RL | 08/18/2026 | Paper | Multi-agent cooperative RL with peer-derived rewards — no ground-truth labels; 3.0–8.6% avg gain on 7 LLM benchmarks, 2.3–7.2% on 4 VLM benchmarks | Code |
| Spatial Memory Agent | 08/13/2026 | Paper | Experience-grounded runtime — self-evolves a frozen VLM's spatial reasoning via verifier-guided reflection distilled into lessons scored by a Transfer Reliability Score | - |
| Evidence-RL: Towards Evidence-intensive Visual Reasoning | 08/08/2026 | Paper | Counterfactual Evidence Disentanglement inside GRPO — rewards evidence-grounded answers without evidence annotations; gains on 9 benchmarks × 4 backbones | - |
| ZPPO: Zone of Proximal Policy Optimization — Teacher in Prompts, Not Gradients | 06/16/2026 | Paper | Teacher guidance via reformulated prompts; beats distillation & GRPO on Qwen3.5 VLMs (0.8B–9B, 31-benchmark suite) | - |
| Efficient Reinforcement for Visual-Textual Thinking with Discrete Diffusion | 06/11/2026 | Paper | GRPO over multimodal discrete diffusion; localized visual editing cuts rollout compute 26.9% vs AR | - |
| AlphaGRPO: Self-Reflective Multimodal Generation in UMMs | 05/12/2026 | Paper | GRPO for unified-model generation; LLM-decomposed verifiable reward (GenEval, TIIF, DPG, WISE) | - |
| OpenSearch-VL: Multi-Turn Fatal-Aware GRPO for Multimodal Search Agents | 05/07/2026 | Paper | Fatal-aware GRPO; handles tool-call failures in agentic multi-turn RL | - |
| GRPO-TTA: Test-Time Visual Tuning via GRPO-Driven RL | 05/05/2026 | Paper | GRPO for test-time visual encoder tuning; no ground-truth labels needed | - |
| S-GRPO: Unified Post-Training for Large VLMs | 04/2026 | Paper | Supervised GRPO; injects ground-truth trajectories to solve cold-start | - |
| Faithful GRPO (FGRPO): Constrained Policy Optimization for Visual Spatial Reasoning | 04/2026 | Paper | Lagrangian-constrained GRPO; inconsistency 24.5% → 1.7% | - |
| Vero: An Open RL Recipe for General Visual Reasoning | 04/2026 | Paper | Task-routed rewards; GRPO-based | Code |
| wDPO: Winsorized Direct Preference Optimization for Robust Alignment | 03/2026 | Paper | wDPO | - |
| f-GRPO and Beyond: Divergence-Based RL for General LLM Alignment | 02/2026 | Paper | f-GRPO / f-HAL | - |
| From Sight to Insight: Improving Visual Reasoning of MLLMs via Reinforcement Learning | 01/2026 | Paper | GRPO (6 reward functions) | - |
| SaFeR-VLM: Safety-Aware Reinforcement Learning for Multimodal Reasoning | 2026 (ICLR) | Paper | GRPO + safety reward | - |
| SAIL-RL: Guiding MLLMs in When and How to Think via Dual-Reward RL Tuning | 11/2025 | Paper | Dual-Reward (Thinking + Judging) | - |
| GIFT: Group-relative Implicit Fine Tuning Integrates GRPO with DPO and UNA | 10/2025 | Paper | GIFT (convex MSE loss) | - |
| Game-RL: Synthesizing Multimodal Verifiable Game Data to Boost VLMs' General Reasoning | 10/12/2025 | Paper | GRPO | - |
| Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | 09/29/2025 | Paper | GRPO | - |
| Vision-SR1: Self-rewarding vision-language model via reasoning decomposition | 08/26/2025 | Paper | GRPO | - |
| Group Sequence Policy Optimization | 06/24/2025 | Paper | GSPO | - |
| Visionary-R1: Mitigating Shortcuts in Visual Reasoning with Reinforcement Learning | 05/20/2025 | Paper | GRPO | - |
| VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning | 2025/04/10 | Paper | GRPO | Code |
| OpenVLThinker: An Early Exploration to Complex Vision-Language Reasoning via Iterative Self-Improvement | 2025/03/21 | Paper | GRPO | Code |
| Boosting the Generalization and Reasoning of Vision Language Models with Curriculum Reinforcement Learning | 2025/03/10 | Paper | GRPO | Code |
| OmniAlign-V: Towards Enhanced Alignment of MLLMs with Human Preference | 2025 | Paper | DPO | Code |
| Multimodal Open R1/R1-Multimodal-Journey | 2025 | - | GRPO | Code |
| R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization | 2025 | Paper | GRPO | Code |
| Agent-R1: Training Powerful LLM Agents with End-to-End Reinforcement Learning | 2025 | - | PPO/REINFORCE++/GRPO | Code |
| MM-Eureka: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning | 2025 | Paper | REINFORCE Leave-One-Out (RLOO) | Code |
| MM-RLHF: The Next Step Forward in Multimodal LLM Alignment | 2025 | Paper | DPO | Code |
| LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL | 2025 | Paper | PPO | Code |
| Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models | 2025 | Paper | GRPO | Code |
| Unified Reward Model for Multimodal Understanding and Generation | 2025 | Paper | DPO | Code |
| Can We Generate Images with CoT? Let's Verify and Reinforce Image Generation Step by Step | 2025 | Paper | DPO | Code |
| All Roads Lead to Likelihood: The Value of Reinforcement Learning in Fine-Tuning | 2025 | Paper | Online RL | - |
| Video-R1: Reinforcing Video Reasoning in MLLMs | 2025 | Paper | GRPO | Code |
3.2. Finetuning for VLM
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes | 08/2026 | Paper | - | - |
| SpatialCLI: Learning to Reason With Spatial Tools, Then Without Them | 07/2026 | Paper | - | - |
| Why Does RL Generalize Better Than SFT? A Data-Centric Perspective (DC-SFT) | 02/2026 | Paper | - | - |
| The Synergy Dilemma of Long-CoT SFT and RL | 2026 (TMLR) | Paper | - | - |
| Layer-wise Analysis of Supervised Fine-Tuning | 04/2026 | Paper | - | - |
| AGFT: Alignment-Guided Fine-Tuning for Zero-Shot Adversarial Robustness of VLMs | 2026/03 | Paper | - | - |
| CoVFT: Context-aware Visual Fine-tuning for Multimodal Large Language Models | 2026/03 | Paper | - | - |
| MERGETUNE: Continued Fine-Tuning of Vision-Language Models | 2026/01 (ICLR 2026) | Paper | - | - |
| Mask Fine-Tuning (MFT): Unlocking Hidden Capabilities in Vision-Language Models | 2025/12 | Paper | - | - |
| Image-LoRA: Towards Minimal Fine-Tuning of VLMs | 2025/12 | Paper | - | - |
| Reassessing the Role of Supervised Fine-Tuning: An Empirical Study in VLM Reasoning | 2025/12 | Paper | - | - |
| Eagle 2.5: Boosting Long-Context Post-Training for Frontier Vision-Language Models | 2025/04/21 | Paper | Website | Code |
| OMNICAPTIONER: One Captioner to Rule Them All | 2025/04/09 | Paper | Website | Code |
| Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning | 2024 | Paper | Website | Code |
| LLaVolta: Efficient Multi-modal Models via Stage-wise Visual Context Compression | 2024 | Paper | Website | Code |
| ViTamin: Designing Scalable Vision Models in the Vision-Language Era | 2024 | Paper | Website | Code |
| Espresso: High Compression For Rich Extraction From Videos for Your Vision-Language Model | 2024 | Paper | - | - |
| Should VLMs be Pre-trained with Image Data? | 2025 | Paper | - | - |
| VisionArena: 230K Real World User-VLM Conversations with Preference Labels | 2024 | Paper | - | Code |
3.3. VLM Alignment github
| Project | Repository Link |
|---|---|
| Verl | 🔗 GitHub |
| EasyR1 | 🔗 GitHub |
| OpenR1 | 🔗 GitHub |
| LLaMAFactory | 🔗 GitHub |
| MM-Eureka-Zero | 🔗 GitHub |
| MM-RLHF | 🔗 GitHub |
| LMM-R1 | 🔗 GitHub |
3.4. Prompt Optimization
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| EvoPrompt: Evolving Prompt Adaptation for Vision-Language Models | 2026/03 | Paper | - | - |
| MMLoP: Multi-Modal Low-Rank Prompting for Efficient Vision-Language Adaptation | 2026/02 | Paper | - | - |
| Multimodal Prompt Optimizer (MPO): Joint Optimization of Multimodal Prompts | 2025/10 | Paper | - | - |
| Evolutionary Prompt Optimization Discovers Emergent Multimodal Reasoning Strategies | 2025/03 | Paper | - | - |
| In-ContextEdit:EnablingInstructionalImageEditingwithIn-Context GenerationinLargeScaleDiffusionTransformer | 2025/04/30 | Paper | Website | Code |
4. ⚒️ Applications
4.1 Embodied VLM Agents
| Title | Year | Paper Link |
|---|---|---|
| Intern-S2-Preview: Scientific Agentic Foundation Model — 397B backbone + 4B memory decoder (Intern-MemDec-4B); Biology-Instructions 56.92 → 60.32 without touching the backbone | 08/13/2026 | Paper |
| G0.5: One Autoregressive Stream for Robot Reasoning and Action | 08/12/2026 | Paper |
| LightNav-0: Eliciting VLM Spatial Intelligence for Generalist Embodied Navigation | 08/31/2026 | Paper |
| Embodied-Navigator (TAMP-Nav): Point, Think, Memorize, Align — 66.2% SR on R2R-CE | 08/18/2026 | Paper |
| SimpleMemVLA: Native-Video Memory for Vision-Language-Action Models | 09/06/2026 | Paper |
| UI-Mate: Open-Weight Foundation GUI Agent (UI-Mate-27B on Qwen3.6-27B; 77.0% OSWorld-Verified, 66.2% WindowsAgentArena) | 08/16/2026 | Paper |
| UI-Venus-2 Technical Report — open-source foundation GUI agent (mobile, web, desktop) | 08/27/2026 | Paper |
| WM-R1: Training GUI Agents to Reason and Leverage World Models with RL | 09/01/2026 | Paper |
| ComBodied Agents: A New Paradigm of Human-Centric Agentic AI | 08/14/2026 | Paper |
| Metis: Memory Foundation Model | 07/2026 | Paper |
| Aligning Cyber Space with Physical World: A Comprehensive Survey on Embodied AI | 2024 | Paper |
| ScreenAI: A Vision-Language Model for UI and Infographics Understanding | 2024 | Paper |
| ChartLlama: A Multimodal LLM for Chart Understanding and Generation | 2023 | Paper |
| SciDoc2Diagrammer-MAF: Towards Generation of Scientific Diagrams from Documents guided by Multi-Aspect Feedback Refinement | 2024 | 📄 Paper |
| Training a Vision Language Model as Smartphone Assistant | 2024 | Paper |
| ScreenAgent: A Vision-Language Model-Driven Computer Control Agent | 2024 | Paper |
| Embodied Vision-Language Programmer from Environmental Feedback | 2024 | Paper |
| VLMs Play StarCraft II: A Benchmark and Multimodal Decision Method | 2025 | 📄 Paper |
| MP-GUI: Modality Perception with MLLMs for GUI Understanding | 2025 | 📄 Paper |
4.2. Generative Visual Media Applications
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| AuK (Tencent Hunyuan): open-source foundation model for speech generation and editing — multimodal LLM + jointly trained VAE + hybrid rectified-flow Transformer (MMDiT → single-stream DiT); AuK-Flash gives 4.5× wall-clock speedup via 4-step inference; trained on ~3.03B instruction-audio instances / 1.95M h | 09/08/2026 | 📄 Paper | - | 💾 Code |
| Chimera: Designing and Chinchilla-Scaling Hybrid Visual Diffusion Transformers | 07/2026 | 📄 Paper | - | - |
| GPT4Motion: Scripting Physical Motions in Text-to-Video Generation via Blender-Oriented GPT Planning | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
| Spurious Correlation in Multimodal LLMs | 2025 | 📄 Paper | - | - |
| WeGen: A Unified Model for Interactive Multimodal Generation as We Chat | 2025 | 📄 Paper | - | 💾 Code |
| VideoMind: A Chain-of-LoRA Agent for Long Video Reasoning | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
4.3. Robotics and Embodied AI
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| AHA: A Vision-Language-Model for Detecting and Reasoning Over Failures in Robotic Manipulation | 2024 | 📄 Paper | 🌍 Website | - |
| SpatialVLM: Endowing Vision-Language Models with Spatial Reasoning Capabilities | 2024 | 📄 Paper | 🌍 Website | - |
| Vision-language model-driven scene understanding and robotic object manipulation | 2024 | 📄 Paper | - | - |
| Guiding Long-Horizon Task and Motion Planning with Vision Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| AutoTAMP: Autoregressive Task and Motion Planning with LLMs as Translators and Checkers | 2023 | 📄 Paper | 🌍 Website | - |
| VLM See, Robot Do: Human Demo Video to Robot Action Plan via Vision Language Model | 2024 | 📄 Paper | - | - |
| Scalable Multi-Robot Collaboration with Large Language Models: Centralized or Decentralized Systems? | 2023 | 📄 Paper | 🌍 Website | - |
| DART-LLM: Dependency-Aware Multi-Robot Task Decomposition and Execution using Large Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| MotionGPT: Human Motion as a Foreign Language | 2023 | 📄 Paper | - | 💾 Code |
| Learning Reward for Robot Skills Using Large Language Models via Self-Alignment | 2024 | 📄 Paper | - | - |
| Language to Rewards for Robotic Skill Synthesis | 2023 | 📄 Paper | 🌍 Website | - |
| Eureka: Human-Level Reward Design via Coding Large Language Models | 2023 | 📄 Paper | 🌍 Website | - |
| Integrated Task and Motion Planning | 2020 | 📄 Paper | - | - |
| Jailbreaking LLM-Controlled Robots | 2024 | 📄 Paper | 🌍 Website | - |
| Robots Enact Malignant Stereotypes | 2022 | 📄 Paper | 🌍 Website | - |
| LLM-Driven Robots Risk Enacting Discrimination, Violence, and Unlawful Actions | 2024 | 📄 Paper | - | - |
| Highlighting the Safety Concerns of Deploying LLMs/VLMs in Robotics | 2024 | 📄 Paper | 🌍 Website | - |
| EmbodiedBench: Comprehensive Benchmarking Multi-modal Large Language Models for Vision-Driven Embodied Agents | 2025 | 📄 Paper | 🌍 Website | 💾 Code & Dataset |
| Gemini Robotics: Bringing AI into the Physical World | 2025 | 📄 Technical Report | 🌍 Website | - |
| GR-2: A Generative Video-Language-Action Model with Web-Scale Knowledge for Robot Manipulation | 2024 | 📄 Paper | 🌍 Website | - |
| Magma: A Foundation Model for Multimodal AI Agents | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| DayDreamer: World Models for Physical Robot Learning | 2022 | 📄 Paper | 🌍 Website | 💾 Code |
| Hi Robot: Open-Ended Instruction Following with Hierarchical Vision-Language-Action Models | 2025 | 📄 Paper | - | - |
| RL-VLM-F: Reinforcement Learning from Vision Language Foundation Model Feedback | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| KALIE: Fine-Tuning Vision-Language Models for Open-World Manipulation without Robot Data | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| Unified Video Action Model | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| HybridVLA: Collaborative Diffusion and Autoregression in a Unified Vision-Language-Action Model | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| Anticipation-VLA: Long-Horizon Embodied Tasks via Anticipation-Based Subgoal Generation | 05/02/2026 | 📄 Paper | - | - |
| Green-VLA: Staged VLA for Generalist Robots | 05/2026 | 📄 Paper | 🌍 Website | - |
| VLA Foundry: Unified Framework for Training VLAs | 04/2026 | 📄 Paper | - | - |
| OmniVLA-RL: Spatial Understanding + Online RL for VLA | 04/2026 | 📄 Paper | - | - |
| DAM-VLA: A Dynamic Action Model-Based Vision-Language-Action Framework for Robot Manipulation | 03/2026 | 📄 Paper | - | - |
| NS-VLA: Towards Neuro-Symbolic Vision-Language-Action Models | 03/2026 | 📄 Paper | - | - |
| Steerable Vision-Language-Action Policies for Embodied Reasoning and Hierarchical Control | 02/2026 | 📄 Paper | - | - |
| ST4VLA: Spatial Guided Training for Vision-Language-Action Models | 02/2026 | 📄 Paper | - | - |
4.3.1. Manipulation
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| G0.5: One Autoregressive Stream for Robot Reasoning and Action — 76.7% R1lite/R1pro, 82.5% zero-shot DROID, 98.9% LIBERO | 08/12/2026 | 📄 Paper | - | - |
| DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation — WorldArena 2.0 Track 1 winner | 08/13/2026 | 📄 Paper | - | 💾 Code |
| ZimaBlue: Evolving Generalizable World-Action Models via >120k h video pre-training — 30 Hz on RTX 4090, 36.1% → 77.8% zero-shot real-robot success | 08/31/2026 | 📄 Paper | - | - |
| Beyond Data Scaling: Representation-Centric Continued Pre-training for VLAs (VLAct) — 82.6% LIBERO-Plus, 92.5% RoboTwin 2.0 with 20% of trajectories | 08/27/2026 | 📄 Paper | 🌍 Project | - |
| SimpleMemVLA: Native-Video Memory for Vision-Language-Action Models | 09/06/2026 | 📄 Paper | - | - |
| Ego2Robot: Scalable Robot Data Synthesis from Egocentric Human Data | 08/03/2026 | 📄 Paper | - | - |
| N₀-VTLA: Scaling Vision-Tactile-Language-Action Model with Latent Tactile Tokens | 07/26/2026 | 📄 Paper | - | - |
| Supervise What Survives: Geometry-Guided VLA Adaptation from Synthetic Robot Videos | 06/23/2026 | 📄 Paper | - | - |
| Qwen-RobotManip: Alignment Unlocks Scale for Robotic Manipulation Foundation Models (38,100-hour corpus) | 06/16/2026 | 📄 Paper | - | - |
| Hy-Embodied-0.5-VLA: From VLA Models to a Real-World Robot Learning Stack (10,000-hour UMI corpus) | 06/12/2026 | 📄 Paper | - | - |
| Learning What to Say to Your VLA: Mostly Harmless VLA Steering | 06/10/2026 | 📄 Paper | - | - |
| Finetuning VLA Models Requires Fewer Layers Than You Think (50% depth pruning) | 06/18/2026 | 📄 Paper | - | - |
| Health-Conditioned VLA for Malfunction-Aware Robot Control | 05/15/2026 | 📄 Paper | - | - |
| VIMA: General Robot Manipulation with Multimodal Prompts | 2022 | 📄 Paper | 🌍 Website | |
| Instruct2Act: Mapping Multi-Modality Instructions to Robotic Actions with Large Language Model | 2023 | 📄 Paper | - | - |
| Creative Robot Tool Use with Large Language Models | 2023 | 📄 Paper | 🌍 Website | - |
| RoboVQA: Multimodal Long-Horizon Reasoning for Robotics | 2024 | 📄 Paper | - | - |
| RT-1: Robotics Transformer for Real-World Control at Scale | 2022 | 📄 Paper | 🌍 Website | - |
| RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control | 2023 | 📄 Paper | 🌍 Website | - |
| Open X-Embodiment: Robotic Learning Datasets and RT-X Models | 2023 | 📄 Paper | 🌍 Website | - |
| ExploRLLM: Guiding Exploration in Reinforcement Learning with Large Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| AnyTouch: Learning Unified Static-Dynamic Representation across Multiple Visuo-tactile Sensors | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| Masked World Models for Visual Control | 2022 | 📄 Paper | 🌍 Website | 💾 Code |
| Multi-View Masked World Models for Visual Robotic Manipulation | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
4.3.2. Navigation
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| LightNav-0: Eliciting VLM Spatial Intelligence for Generalist Embodied Navigation — dual-channel pointing + residual-VQ action tokenizer; SoTA monocular success across 10 navigation sims | 08/31/2026 | 📄 Paper | - | - |
| Embodied-Navigator (TAMP-Nav): Point-Think-Memorize-Align with Space-Time Indicator memory — 66.2% SR on R2R-CE using only 90k training trajectories | 08/18/2026 | 📄 Paper | - | - |
| ZSON: Zero-Shot Object-Goal Navigation using Multimodal Goal Embeddings | 2022 | 📄 Paper | - | - |
| LOC-ZSON: Language-driven Object-Centric Zero-Shot Object Retrieval and Navigation | 2024 | 📄 Paper | - | - |
| LM-Nav: Robotic Navigation with Large Pre-Trained Models of Language, Vision, and Action | 2022 | 📄 Paper | 🌍 Website | - |
| NaVILA: Legged Robot Vision-Language-Action Model for Navigation | 2022 | 📄 Paper | 🌍 Website | - |
| VLFM: Vision-Language Frontier Maps for Zero-Shot Semantic Navigation | 2024 | 📄 Paper | - | - |
| Navigation with Large Language Models: Semantic Guesswork as a Heuristic for Planning | 2023 | 📄 Paper | 🌍 Website | - |
| Vi-LAD: Vision-Language Attention Distillation for Socially-Aware Robot Navigation in Dynamic Environments | 2025 | 📄 Paper | - | - |
| Navigation World Models | 2024 | 📄 Paper | 🌍 Website | - |
4.3.3. Human-robot Interaction
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| MUTEX: Learning Unified Policies from Multimodal Task Specifications | 2023 | 📄 Paper | 🌍 Website | - |
| LaMI: Large Language Models for Multi-Modal Human-Robot Interaction | 2024 | 📄 Paper | 🌍 Website | - |
| VLM-Social-Nav: Socially Aware Robot Navigation through Scoring using Vision-Language Models | 2024 | 📄 Paper | - | - |
4.3.4. Autonomous Driving
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Qwen-Drive-1.0 (Alibaba): first VL foundation model for autonomous driving — pretrained VLM backbone + BEV perception head + Planning Expert | 08/31/2026 | 📄 Paper | - | 💾 Code |
| SimWAM: Simple World-Action Model for End-to-End Autonomous Driving — 91.5 PDMS NAVSIM, zero-shot to nuScenes | 08/07/2026 | 📄 Paper | - | 💾 Code |
| RT-VLA: Real-Time VLA via Knowledge Distillation (44.8× faster inference) | 06/12/2026 | 📄 Paper | - | - |
| Fast-dDrive: Efficient Block-Diffusion VLM for Autonomous Driving (12× throughput, 0.32m L2 nuScenes) | 05/22/2026 | 📄 Paper | - | - |
| CLOVER: Closed-Loop Value Estimation & Ranking for E2E Driving Planning (94.5 PDMS NAVSIM SoTA) | 05/14/2026 | 📄 Paper | - | - |
| CoWorld-VLA: Thinking in a Multi-Expert World Model for Autonomous Driving | 05/11/2026 | 📄 Paper | - | - |
| MindVLA-U1: Unified Streaming VLA for Autonomous Driving (surpasses human-level driving) | 05/12/2026 | 📄 Paper | - | - |
| VLADriver-RAG: Retrieval-Augmented VLA for Autonomous Driving | 05/08/2026 | 📄 Paper | - | - |
| OneDrive: Unified Heterogeneous Decoding for Driving VLMs | 04/2026 | 📄 Paper | - | - |
| UniDriveVLA: Unifying Understanding, Perception, and Action Planning for Autonomous Driving | 04/2026 | 📄 Paper | - | - |
| AutoMoT: A Unified Vision-Language-Action Model with Asynchronous Mixture-of-Transformers for End-to-End Autonomous Driving | 03/2026 | 📄 Paper | - | - |
| DriveVLM-RL: Neuroscience-Inspired Reinforcement Learning with Vision-Language Models for Safe Autonomous Driving | 03/2026 | 📄 Paper | - | - |
| HiST-VLA: A Hierarchical Spatio-Temporal Vision-Language-Action Model for End-to-End Autonomous Driving | 02/2026 | 📄 Paper | - | - |
| OpenDriveVLA: Towards End-to-end Autonomous Driving with Large Vision Language Action Model | 03/2025 | 📄 Paper | - | - |
| Are VLMs Ready for Autonomous Driving? An Empirical Study from the Reliability, Data, and Metric Perspectives | 01/07/2025 | 📄 Paper | 🌍 Website | - |
| DriveVLM: The Convergence of Autonomous Driving and Large Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| GPT-Driver: Learning to Drive with GPT | 2023 | 📄 Paper | - | - |
| LanguageMPC: Large Language Models as Decision Makers for Autonomous Driving | 2023 | 📄 Paper | 🌍 Website | - |
| Driving with LLMs: Fusing Object-Level Vector Modality for Explainable Autonomous Driving | 2023 | 📄 Paper | - | - |
| Referring Multi-Object Tracking | 2023 | 📄 Paper | - | 💾 Code |
| VLPD: Context-Aware Pedestrian Detection via Vision-Language Semantic Self-Supervision | 2023 | 📄 Paper | - | 💾 Code |
| MotionLM: Multi-Agent Motion Forecasting as Language Modeling | 2023 | 📄 Paper | - | - |
| DiLu: A Knowledge-Driven Approach to Autonomous Driving with Large Language Models | 2023 | 📄 Paper | 🌍 Website | - |
| VLP: Vision Language Planning for Autonomous Driving | 2024 | 📄 Paper | - | - |
| DriveGPT4: Interpretable End-to-end Autonomous Driving via Large Language Model | 2023 | 📄 Paper | - | - |
4.4. Human-Centered AI
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| DLF: Disentangled-Language-Focused Multimodal Sentiment Analysis | 2024 | 📄 Paper | - | 💾 Code |
| LIT: Large Language Model Driven Intention Tracking for Proactive Human-Robot Collaboration – A Robot Sous-Chef Application | 2024 | 📄 Paper | - | - |
| Pretrained Language Models as Visual Planners for Human Assistance | 2023 | 📄 Paper | - | - |
| Promoting AI Equity in Science: Generalized Domain Prompt Learning for Accessible VLM Research | 2024 | 📄 Paper | - | - |
| Image and Data Mining in Reticular Chemistry Using GPT-4V | 2023 | 📄 Paper | - | - |
4.4.1. Web Agent
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Video-DeepResearch: Towards the Next-Generation Multimodal Deepresearch Agent | 08/05/2026 | 📄 Paper | - | - |
| StateAct: Program State, before Pixels, for Long-Horizon Computer-Use Agents | 07/24/2026 | 📄 Paper | - | - |
| A Real-World WebAgent with Planning, Long Context Understanding, and Program Synthesis | 2023 | 📄 Paper | - | - |
| CogAgent: A Visual Language Model for GUI Agents | 2023 | 📄 Paper | - | 💾 Code |
| WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models | 2024 | 📄 Paper | - | 💾 Code |
| ShowUI: One Vision-Language-Action Model for GUI Visual Agent | 2024 | 📄 Paper | - | 💾 Code |
| ScreenAgent: A Vision Language Model-driven Computer Control Agent | 2024 | 📄 Paper | - | 💾 Code |
| Web Agents with World Models: Learning and Leveraging Environment Dynamics in Web Navigation | 2024 | 📄 Paper | - | 💾 Code |
| VisCritic: Visual State Comparison as Process Reward for GUI Agents | 06/23/2026 | 📄 Paper | - | - |
| LiteGUI: Distilling Compact GUI Agents with Reinforcement Learning (SFT-free, 2B/3B) | 05/08/2026 | 📄 Paper | - | - |
| LAMO: Scalable Lightweight GUI Agents via Multi-Role Orchestration | 04/2026 | 📄 Paper | - | - |
| ScreenExplorer: Autonomous GUI Exploration via Curiosity-Driven VLM Agents | 2026 (ICLR) | 📄 Paper | - | - |
| InfiGUIAgent: Generalist GUI Agent with Native Reasoning and Reflection | 2026 (EACL) | 📄 Paper | - | - |
| MolmoWeb: Open Visual Web Agent and Open Data for the Open Web | 04/2026 | 📄 Paper | 🌍 Website | 💾 Code |
4.4.2. Accessibility
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| X-World: Accessibility, Vision, and Autonomy Meet | 2021 | 📄 Paper | - | - |
| Context-Aware Image Descriptions for Web Accessibility | 2024 | 📄 Paper | - | - |
| Improving VR Accessibility Through Automatic 360 Scene Description Using Multimodal Large Language Models | 2024 | 📄 Paper | - | - |
4.4.3. Healthcare
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| RESPClinBench: Multimodal Clinical Decision-Making and Longitudinal Disease Tracking | 08/07/2026 | 📄 Paper | - | - |
| IMCBench: Multimodal LLMs in Image-grounded Medical Conversations (safety drops on malignant/rare conditions) | 06/26/2026 | 📄 Paper | - | - |
| HalluCXR: Benchmarking & Mitigating Hallucinations in Medical VLMs for Chest Radiographs (61.9–82.3% outputs hallucinate) | 05/19/2026 | 📄 Paper | - | - |
| Medical Thinking with Multiple Images (MedThinkVQA) | 04/2026 | 📄 Paper | - | - |
| MedVRAG: Iterative Multimodal RAG for Medical QA | 04/2026 | 📄 Paper | - | - |
| GMAI-VL: General Medical AI Vision-Language Model | 2026 (AAAI) | 📄 Paper | - | - |
| CARE: Towards Clinical Accountability in Multi-Modal Medical Reasoning with an Evidence-Grounded Agentic Framework | 03/2026 | 📄 Paper | - | - |
| MedMO: Grounding and Understanding Multimodal Large Language Model for Medical Images | 02/2026 | 📄 Paper | - | - |
| Colon-X: Advancing Intelligent Colonoscopy from Multimodal Understanding to Clinical Reasoning | 12/2025 | 📄 Paper | - | 💾 Code |
| Frontiers in Intelligent Colonoscopy | 02/2025 | 📄 Paper | - | 💾 Code |
| VisionUnite: A Vision-Language Foundation Model for Ophthalmology Enhanced with Clinical Knowledge | 2024 | 📄 Paper | - | 💾 Code |
| Multimodal Healthcare AI: Identifying and Designing Clinically Relevant Vision-Language Applications for Radiology | 2024 | 📄 Paper | - | - |
| M-FLAG: Medical Vision-Language Pre-training with Frozen Language Models and Latent Space Geometry Optimization | 2023 | 📄 Paper | - | - |
| MedCLIP: Contrastive Learning from Unpaired Medical Images and Text | 2022 | 📄 Paper | - | 💾 Code |
| Med-Flamingo: A Multimodal Medical Few-Shot Learner | 2023 | 📄 Paper | - | 💾 Code |
4.4.4. Social Goodness
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Analyzing K-12 AI Education: A Large Language Model Study of Classroom Instruction on Learning Theories, Pedagogy, Tools, and AI Literacy | 2024 | 📄 Paper | - | - |
| Students Rather Than Experts: A New AI for Education Pipeline to Model More Human-Like and Personalized Early Adolescence | 2024 | 📄 Paper | - | - |
| Harnessing Large Vision and Language Models in Agriculture: A Review | 2024 | 📄 Paper | - | - |
| A Vision-Language Model for Predicting Potential Distribution Land of Soybean Double Cropping | 2024 | 📄 Paper | - | - |
| Vision-Language Model is NOT All You Need: Augmentation Strategies for Molecule Language Models | 2024 | 📄 Paper | - | 💾 Code |
| DrawEduMath: Evaluating Vision Language Models with Expert-Annotated Students’ Hand-Drawn Math Images | 2024 | 📄 Paper | - | - |
| MultiMath: Bridging Visual and Mathematical Reasoning for Large Language Models | 2024 | 📄 Paper | - | 💾 Code |
| Vision-Language Models Meet Meteorology: Developing Models for Extreme Weather Events Detection with Heatmaps | 2024 | 📄 Paper | - | 💾 Code |
| He is Very Intelligent, She is Very Beautiful? On Mitigating Social Biases in Language Modeling and Generation | 2021 | 📄 Paper | - | - |
| UrbanVLP: Multi-Granularity Vision-Language Pretraining for Urban Region Profiling | 2024 | 📄 Paper | - | - |
5. Challenges
5.1 Hallucination
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| TruthLens: Object Hallucination Detection via Self-Evaluating Truthfulness Scores in LVLMs | 08/07/2026 | 📄 Paper | - | - |
| MVI-Bench: A Comprehensive Benchmark for Evaluating Robustness to Misleading Visual Inputs in LVLMs | 11/2025 | 📄 Paper | 🌍 ICML 2026 | 💾 Code |
| VL-Calibration: Decoupled Confidence Calibration for VLM Reasoning | 04/2026 | 📄 Paper | - | - |
| Focus Matters: Phase-Aware Suppression for Hallucination in Vision-Language Models | 04/2026 | 📄 Paper | - | - |
| VLMs Need Words: Vision Language Models Ignore Visual Detail in Favor of Semantic Anchors | 04/2026 | 📄 Paper | - | - |
| HALP: Detecting Hallucinations in Vision-Language Models without Generating a Single Token | 03/2026 | 📄 Paper | 🌍 ACL | - |
| Tone Matters: The Impact of Linguistic Tone on Hallucination in VLMs | 01/2026 | 📄 Paper | - | - |
| Object Hallucination in Image Captioning | 2018 | 📄 Paper | - | - |
| Evaluating Object Hallucination in Large Vision-Language Models | 2023 | 📄 Paper | - | 💾 Code |
| Detecting and Preventing Hallucinations in Large Vision Language Models | 2023 | 📄 Paper | - | - |
| HallE-Control: Controlling Object Hallucination in Large Multimodal Models | 2023 | 📄 Paper | - | 💾 Code |
| Hallu-PI: Evaluating Hallucination in Multi-modal Large Language Models within Perturbed Inputs | 2024 | 📄 Paper | - | 💾 Code |
| BEAF: Observing BEfore-AFter Changes to Evaluate Hallucination in Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| HallusionBench: An Advanced Diagnostic Suite for Entangled Language Hallucination and Visual Illusion in Large Vision-Language Models | 2023 | 📄 Paper | - | 💾 Code |
| AUTOHALLUSION: Automatic Generation of Hallucination Benchmarks for Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| Mitigating Hallucination in Large Multi-Modal Models via Robust Instruction Tuning | 2023 | 📄 Paper | - | 💾 Code |
| Hal-Eval: A Universal and Fine-grained Hallucination Evaluation Framework for Large Vision Language Models | 2024 | 📄 Paper | - | 💾 Code |
| AMBER: An LLM-free Multi-dimensional Benchmark for MLLMs Hallucination Evaluation | 2023 | 📄 Paper | - | 💾 Code |
5.2 Safety
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| SaFeR-VLM: Safety into Multimodal Reasoning via Reinforcement Learning | 2026 (ICLR) | 📄 Paper | - | - |
| HoliSafe: Holistic Safety Evaluation for Vision-Language Models | 2026 (ICLR) | 📄 Paper | - | - |
| JailbreakZoo: Survey, Landscapes, and Horizons in Jailbreaking Large Language and Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| Safe-VLN: Collision Avoidance for Vision-and-Language Navigation of Autonomous Robots Operating in Continuous Environments | 2023 | 📄 Paper | - | - |
| SafeBench: A Safety Evaluation Framework for Multimodal Large Language Models | 2024 | 📄 Paper | - | - |
| JailBreakV: A Benchmark for Assessing the Robustness of MultiModal Large Language Models against Jailbreak Attacks | 2024 | 📄 Paper | - | - |
| SHIELD: An Evaluation Benchmark for Face Spoofing and Forgery Detection with Multimodal Large Language Models | 2024 | 📄 Paper | - | 💾 Code |
| Images are Achilles' Heel of Alignment: Exploiting Visual Vulnerabilities for Jailbreaking Multimodal Large Language Models | 2024 | 📄 Paper | - | - |
| Jailbreaking Attack against Multimodal Large Language Model | 2024 | 📄 Paper | - | - |
| Embodied Red Teaming for Auditing Robotic Foundation Models | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| Safety Guardrails for LLM-Enabled Robots | 2025 | 📄 Paper | - | - |
5.3 Fairness
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Hallucination of Multimodal Large Language Models: A Survey | 2024 | 📄 Paper | - | - |
| Bias and Fairness in Large Language Models: A Survey | 2023 | 📄 Paper | - | - |
| Fairness and Bias in Multimodal AI: A Survey | 2024 | 📄 Paper | - | - |
| Multi-Modal Bias: Introducing a Framework for Stereotypical Bias Assessment beyond Gender and Race in Vision–Language Models | 2023 | 📄 Paper | - | - |
| FMBench: Benchmarking Fairness in Multimodal Large Language Models on Medical Tasks | 2024 | 📄 Paper | - | - |
| FairCLIP: Harnessing Fairness in Vision-Language Learning | 2024 | 📄 Paper | - | - |
| FairMedFM: Fairness Benchmarking for Medical Imaging Foundation Models | 2024 | 📄 Paper | - | - |
| Benchmarking Vision Language Models for Cultural Understanding | 2024 | 📄 Paper | - | - |
5.4 Alignment
5.4.1 Multi-modality Alignment
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Mitigating Hallucinations in Large Vision-Language Models with Instruction Contrastive Decoding | 2024 | 📄 Paper | - | - |
| Enhancing Visual-Language Modality Alignment in Large Vision Language Models via Self-Improvement | 2024 | 📄 Paper | - | - |
| Assessing and Learning Alignment of Unimodal Vision and Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| Extending Multi-modal Contrastive Representations | 2023 | 📄 Paper | - | 💾 Code |
| OneLLM: One Framework to Align All Modalities with Language | 2023 | 📄 Paper | - | 💾 Code |
| What You See is What You Read? Improving Text-Image Alignment Evaluation | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
| Critic-V: VLM Critics Help Catch VLM Errors in Multimodal Reasoning | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
5.4.2 Commonsense and Physics Alignment
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| VBench: Comprehensive BenchmarkSuite for Video Generative Models | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
| VBench++: Comprehensive and Versatile Benchmark Suite for Video Generative Models | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| PhysBench: Benchmarking and Enhancing VLMs for Physical World Understanding | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| VideoPhy: Evaluating Physical Commonsense for Video Generation | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| WorldSimBench: Towards Video Generation Models as World Simulators | 2024 | 📄 Paper | 🌍 Website | - |
| WorldModelBench: Judging Video Generation Models As World Models | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| VideoScore: Building Automatic Metrics to Simulate Fine-grained Human Feedback for Video Generation | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| WISE: A World Knowledge-Informed Semantic Evaluation for Text-to-Image Generation | 2025 | 📄 Paper | - | 💾 Code |
| Content-Rich AIGC Video Quality Assessment via Intricate Text Alignment and Motion-Aware Consistency | 2025 | 📄 Paper | - | 💾 Code |
| Your Large Vision-Language Model Only Needs A Few Attention Heads For Visual Grounding | 2025 | 📄 Paper | - | - |
| SpatialVLM: Endowing Vision-Language Models with Spatial Reasoning Capabilities | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| Do generative video models understand physical principles? | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| PhysGen: Rigid-Body Physics-Grounded Image-to-Video Generation | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| How Far is Video Generation from World Model: A Physical Law Perspective | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| Imagine while Reasoning in Space: Multimodal Visualization-of-Thought | 2025 | 📄 Paper | - | - |
| VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
5.5 Efficient Training and Fine-Tuning
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| OmniPack: Unified Token Compression for Efficient Omni-modal Large Language Models | 08/05/2026 | 📄 Paper | - | - |
| GSTEP: Global Spatio-Temporal Density-Driven Visual Token Pruning for Efficient Video LLMs | 08/05/2026 | 📄 Paper | - | - |
| FastOCR: Dynamic Visual Fixation via KV Cache Pruning (98% accuracy at 5% visual tokens, 3.0× faster) | 05/17/2026 | 📄 Paper | - | - |
| WindowQuant: Mixed-Precision KV Cache Quantization via Window-Level Similarity | 05/04/2026 | 📄 Paper | - | - |
| MODIX: Training-Free Multimodal Information-Driven Positional Index Scaling | 04/2026 | 📄 Paper | - | - |
| QAPruner: Quantization-Aware Vision Token Pruning for MLLMs | 04/2026 | 📄 Paper | - | - |
| Firebolt-VL: Efficient Vision-Language Understanding with Cross-Modality Modulation | 04/2026 | 📄 Paper | - | - |
| CoME-VL: Scaling Complementary Multi-Encoder Vision-Language Learning | 04/2026 | 📄 Paper | - | - |
| LoRA-Squeeze: Simple and Effective Post-Tuning and In-Tuning Compression of LoRA Modules | 02/2026 | 📄 Paper | - | - |
| GRACE: Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs | 01/2026 | 📄 Paper | - | - |
| VLMQ: Post-Training Quantization for Large Vision-Language Models | 2026 (ICLR) | 📄 Paper | - | - |
| VILA: On Pre-training for Visual Language Models | 2023 | 📄 Paper | - | - |
| SimVLM: Simple Visual Language Model Pretraining with Weak Supervision | 2021 | 📄 Paper | - | - |
| LoRA: Low-Rank Adaptation of Large Language Models | 2021 | 📄 Paper | - | 💾 Code |
| QLoRA: Efficient Finetuning of Quantized LLMs | 2023 | 📄 Paper | - | - |
| Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback | 2022 | 📄 Paper | - | 💾 Code |
| RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback | 2023 | 📄 Paper | - | - |
5.6 Scarce of High-quality Dataset
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| A Prescription for Better VLMs through Data Curation Alone (20/20 Vision) | 05/2026 | 📄 Paper | - | - |
| A Survey on Bridging VLMs and Synthetic Data | 2025 | 📄 Paper | - | 💾 Code |
| Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning | 2024 | 📄 Paper | Website | 💾 Code |
| SLIP: Self-supervision meets Language-Image Pre-training | 2021 | 📄 Paper | - | 💾 Code |
| Synthetic Vision: Training Vision-Language Models to Understand Physics | 2024 | 📄 Paper | - | - |
| Synth2: Boosting Visual-Language Models with Synthetic Captions and Image Embeddings | 2024 | 📄 Paper | - | - |
| KALIE: Fine-Tuning Vision-Language Models for Open-World Manipulation without Robot Data | 2024 | 📄 Paper | - | - |
| Web Agents with World Models: Learning and Leveraging Environment Dynamics in Web Navigation | 2024 | 📄 Paper | - | - |
Contributors


Similar repos


Languages
HTML
88.4%
Python
11.6%
A most Frontend Collection and survey of vision-language model papers, and models GitHub repository. Continuous updates.
HTML
720
189 commits
updated Sep 14, 2026
README
Frontier Vision-Language Models: Architectural Evolution, Benchmarks, Applications, and Challenges
🌐 Language: English · 简体中文
A most Frontend Collection and survey of vision-language model papers, and models GitHub repository
🧭 The Evolution of VLM Architectures
VLM design has gone through four distinct architectural eras in just six years — and Era 3 has split into two parallel branches. Early models kept frozen vision and language towers, aligned contrastively (CLIP) or bridged by a learnable connector into a frozen LM (BLIP-2, Flamingo). The 2023–2025 generation made a pretrained LLM the trunk and treated vision as a bolt-on adapter (LLaVA, Qwen2.5-VL, GPT-4V). The 2025–2026 generation drops the bridge entirely and early-fuses all modalities into a single transformer — forking along the output axis — and in 2026 the trunk is becoming a world model that predicts and acts:
- Era 3a — Native Multimodal Input → Text Out. Image, video, and (sometimes) audio enter a single early-fused token stream, but generation is still autoregressive text. This is the design used by today's general-purpose flagships: Qwen3.5 / Qwen3.6, Gemma 4, Gemini 3, GPT-5.4, Phi-4-Reasoning-Vision, Claude Opus 4.6, Nemotron 3 Nano Omni.
- Era 3b — Omni-Modal Unified I/O. The same fused trunk plus dedicated image / video decoder (VAE / DiT / flow-matching) and/or audio codec decoder heads, so the model can also generate images, video, and speech — via autoregression or, increasingly, discrete diffusion / AR-Diffusion (LLaDA2.0-Uni, Mamoda2.5) — and the newest 3b models (SenseNova-U1.5, 09/2026) are dropping the VAE too, running understanding + reasoning + generation through one encoder-free and VAE-free mixture-of-transformers trunk. This is the design used by unified models: SenseNova-U1.5, BAGEL, Qwen3.5-Omni, InternVL-U, Emu3 / Emu3.5, Erin 5.0, DeepSeek-Janus-Pro, LLaDA2.0-Uni, Mamoda2.5. Generation-only specialists share the same decoder stack without the understanding half — Sora 2, Veo 3, Kling now generate video with synchronized audio, and they double as the substrate for Era 4 world models (DreamX-World builds on Wan, OmniDreams on Cosmos, SolarWM on Wan2.2 / LTX-2.5 / MiniMax-H3).
- Era 4 — World-Action Models (2026 →). The unified trunk adds action as a first-class modality and closes the loop with the environment: it predicts future observations, maintains persistent state and spatial memory, and emits actions — generator, perceiver, and policy in one network. Founding releases: Cosmos 3, Kairos, DreamX-World 1.0, OmniDreams; the 08–09/2026 wave: DreamX-Phi 1.0 (WorldArena 2.0 winner), SimWAM (91.5 PDMS NAVSIM), ZimaBlue (120k h video pretraining), G0.5 (one AR stream for reasoning+action), Puffin-World (native 3D world states), SolarWM (open 5B–33B, real-time minute-to-hour rollouts) (see §1.1 World Models).
Reading the diagram (left → right). Era 1 uses a two-tower design — aligned contrastively (CLIP: no generative decoder) or with a learnable cross-modal bridge (e.g. Q-Former) into a frozen LM — text-only output. Era 2 puts a pretrained LLM at the center; an MLP/Resampler projects visual tokens into the LLM's vocabulary, and the LLM does all the reasoning — still text-only output. Era 3a drops the bridge: image, video, audio, and text share a single tokenizer/embedding space and flow through one early-fused transformer — but the output is still autoregressive text. Era 3b keeps that fused trunk and adds decoder heads (image/video DiT, VAE, audio codec) so the model can natively output text, image, video, and/or speech — generation-only video models (Sora 2, Veo 3, Kling) reuse this decoder stack, now with synchronized audio. Era 4 adds an action token stream, persistent state, and a policy head, closing the observation → action → next-observation loop: the world-action model is generator, perceiver, and policy at once. Eras 3a, 3b, and 4 coexist; the choice is essentially "how much do you want the model to generate — and to act?"
🆕 What's in this repo
Below we compile awesome papers and model and github repositories that
- State-of-the-Art VLMs Collection of newest to oldest VLMs (we'll keep updating new models and benchmarks).
- Evaluate VLM benchmarks and corresponding link to the works
- Post-training/Alignment Newest related work for VLM alignment including RL, sft.
- Applications applications of VLMs in embodied AI, robotics, etc.
- Contribute surveys, perspectives, and datasets on the above topics.
📡 VLM Trends
VLM Trends is the live companion to this repository. This README records what exists; VLM Trends tracks what changed today — new model releases, papers, benchmarks, and datasets pulled daily from arXiv, Hugging Face, GitHub, and Semantic Scholar, scored on a published rubric, and grouped by topic and model family. It also makes this survey browsable, and charts how each research direction is moving over time.
Progressive research reports
We track new VLMs, benchmarks, and post-training methods that haven't yet been folded into the main tables in dated mini-surveys:
📂 Expand all 10 reports — latest: 2026-09-13, Era 4 fills out and the unified trunk drops the VAE (50 new entries)
-
📰
2026-09-13— latest: Era 4 becomes a paradigm — six world-action systems ship in five weeks: DreamX-Phi 1.0 (WorldArena 2.0 winner), SimWAM (91.5 PDMS NAVSIM), ZimaBlue (120k h video pretraining, 30 Hz on RTX 4090), G0.5 (one AR stream for reasoning+action), Puffin-World (native 3D world states), SolarWM (open 5B–33B). Unified stack keeps shedding components — SenseNova-U1.5 ships 8B mixture-of-transformers encoder-free and VAE-free at native 4K. First VL foundation model for driving: Qwen-Drive-1.0 (Alibaba). Speech unification: AuK (Tencent Hunyuan, 4.5× via 4-step). First open >700B multimodal RL post-training stack: Miles v0.1 (GLM-5.2 744B-A40B, 64 GB300s, 263s/step). Frontier eval reopens on continuous settings — VideoGAIA puts GPT-5.5/Kimi K3 <60%; EgoMonth: 71.8% Gemini vs 94.2% human; StateSight probes latent state; WorldReward and PAWBench add reward/probabilistic-alignment axes for world models — 50 new entries since August 10. -
📰
2026-08-10— Evaluation stops asking whether a model sees — HumanCLAW (can a VLM act through a body?), GST-Bench (global spatial awareness from video), ChronoVision (temporal reasoning via latent state), WorldExam (reactivity over appearance); judging becomes its own research problem via OSReward, ConfBench, TruthLens. On the model side: Qwen3.8-Max (2.4T · 95B active, Vision Arena #2), DiffusionGemma (26B-A4B diffusion Gemma), Hunyuan3D-Buffalo 1.0 (unified 3D); plus N₀-VTLA (tactile VLA), Metis, Ego2Robot, VideoCoCo, OmniPack — 29 new entries since July 22. -
📰
2026-07-22— World models become the evaluators — GigaWorld-1 + WMBench, RoboWorld (r = 0.989 vs real-world), World-Action-Model tutorial; Gemma 4 tech report (encoder-free 12B), PRA-GRPO (93.2% V-Star at 4B), VRRL (trained self-reflection), LingBot-VLA 2.0 (60,000-hour corpus), ROSA (robot-factory serving), ISPA (50% KV-cache cut), OmniFocus, MoHallBench / LongVQUBench / SciVis-literacy benchmarks; plus the July frontier wave: Gemini 3.6 Flash, Kimi K3 (2.8T open MoE), GPT-5.5 / GPT-5.6 Sol, Grok 4.5, Qwen3.7-Plus — 19 new entries since June 27. -
📰
2026-06-27— World-model foundation releases — Cosmos 3 (NVIDIA omnimodal family: best open T2I/I2V + best RoboArena policy), Kairos (4B edge-real-time world-model stack, beats 14B), DreamX-World 1.0 (5B MIT-licensed interactive world model); "Persistent State Core" critique + Echo-Memory; ZPPO (teacher-in-prompts beats GRPO), Qwen-RobotManip (38,100-hour corpus), Supervise What Survives, VisCritic (visual process rewards for GUI), HPP (long video), IMCBench (medical dialogue safety) — 11 new entries since June 23. -
📰
2026-06-23— World Models focus — NVIDIA OmniDreams (real-time closed-loop driving world model), Mirage (latent spatial memory), Reward-as-Agent (GRPO for world models), WorldOlympiad & LongSpace-Bench (world-model benchmarks); plus PP-OCRv6 (34.5M beats 235B VLMs on OCR), Occ-VLM (3D-grounded), discrete-diffusion RL reasoning, VLA layer pruning, Hy-Embodied-0.5-VLA, RT-VLA (44.8× faster driving), VLA language steering — 12 new entries since June 2. -
📰
2026-06-02— Mamoda2.5 (AR-Diffusion DiT-MoE, 95.9× faster editing), VLM3 (native 3D learners), AlphaGRPO (RL for unified-model generation), Stage-wise Preference Optimization, FastOCR / WindowQuant (KV-cache efficiency), Fast-dDrive / CLOVER / CoWorld-VLA (driving VLA), Lost in Fog (reasoning-as-safety-signal), LiteGUI (SFT-free GUI agents), Health-Conditioned VLA, POLAR, TOC-Bench / VGenST-Bench (video), HalluCXR (medical) — 16 new entries since May 16. -
📰
2026-05-16— LensVLM (Apple), Nemotron 3 Nano Omni (NVIDIA), LLaDA2.0-Uni, PLaMo 2.1-VL, S-GRPO / Faithful GRPO / GRPO-TTA / OpenSearch-VL, MindVLA-U1 (surpasses human driving), VLADriver-RAG, Green-VLA, Anticipation-VLA, VLA Foundry, LAMO, ScreenExplorer, VideoZeroBench, Video-Oasis, MedThinkVQA, data curation at 87× less compute — 34 new entries since April 28. -
📰
2026-04-28— Qwen3.6-27B & Qwen3.6-35B-A3B, Claude Mythos (gated), S1-VL, GLM-5V-Turbo, FreshPER / GMPO / ARPO / GRPO-VPS, QUOTA, Fast-dVLM, VLA-World, SpanVLA, VLA-Forget, R-VLM, UILoop, WebForge, WorldMark, Video-MME-v2, CrossMath, BabyVision, SlowBA — 30 new entries since April 13. -
📰
2026-04-13— LFM2.5-VL-450M, EXAONE 4.5, Gemma 4, Granite 4.0 3B Vision, InternVL-U, GLM-4.6V, Vero, MolmoWeb, UniDriveVLA, QAPruner, Firebolt-VL, CoME-VL, and more. -
📰
2026-03-25— GPT-5.4, Phi-4-Reasoning-Vision-15B, Gemini 3.0, Qwen3.5, Claude Opus 4.6, Molmo2, and more.
Welcome to contribute and discuss!
🤩 Papers marked with a ⭐️ are contributed by the maintainers of this repository. If you find them useful, we would greatly appreciate it if you could give the repository a star or cite our paper.
Table of Contents
-
- 1.1. 🌍 World Models
-
- 3.1. RL Alignment for VLM
- 3.2. Regular finetuning (SFT)
- 3.3. VLM Alignment Github
- 3.4. Prompt Engineering
-
- 4.1. Embodied VLM agents
- 4.2. Generative Visual Media Applications
- 4.3. Robotics and Embodied AI
- 4.3.1. Manipulation
- 4.3.2. Navigation
- 4.3.3. Human-robot Interaction
- 4.3.4. Autonomous Driving
- 4.4. Human-Centered AI
- 4.4.1. Web Agent
- 4.4.2. Accessibility
- 4.4.3. Medical and Healthcare
- 4.4.4. Social Goodness
-
- 5.1. Hallucination
- 5.2. Safety
- 5.3. Fairness
- 5.4. Alignment
- 5.4.1. Multi-modality Alignment
- 5.5. Efficient Training and Fine-Tuning
- 5.6. Scarce of High-quality Dataset
0. Citation
@InProceedings{Li_2025_CVPR,
    author    = {Li, Zongxia and Wu, Xiyang and Du, Hongyang and Liu, Fuxiao and Nghiem, Huy and Shi, Guangyao},
    title     = {A Survey of State of the Art Large Vision Language Models: Benchmark Evaluations and Challenges},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops},
    month     = {June},
    year      = {2025},
    pages     = {1587-1606}
}
1. 📚 SoTA VLMs
| Model | Year | Architecture | Training Data | Parameters | Vision Encoder/Tokenizer | Pretrained Backbone Model |
|---|---|---|---|---|---|---|
| SenseNova-U1.5 | 09/10/2026 | Encoder-free and VAE-free native unified visual intelligence; mixture-of-transformers; understanding + reasoning + generation in one trunk; native resolutions up to 4K | Undisclosed | 8B MoT | None (encoder-free) | Trained from scratch — HF · Code |
| Qwen3.8-Max (Alibaba) | 08/03/2026 | Sparse MoE + hybrid attention; text + vision in, 1M context; Vision Arena #2 | Undisclosed | 2.4T total · 95B active | Native multimodal | Qwen3.8 |
| DiffusionGemma (Google) | 08/05/2026 | Diffusion (non-autoregressive) language model in the Gemma family | Undisclosed | 26B total · 4B active | Native multimodal | Gemma |
| Hunyuan3D-Buffalo 1.0 (Tencent) | 08/05/2026 | Unified multimodal — 3D generation + understanding + editing | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Gemini 3.6 Flash (Google) | 07/21/2026 | Decoder-only / natively multimodal input (text, image, speech, video → text) | Undisclosed | Undisclosed | Native multimodal | Gemini 3.x |
| Kimi K3 (Moonshot AI) | 07/17/2026 | MoE, natively multimodal reasoning — text + image + video in one trunk (no separate vision module); 1M context; open weights due 07/27/2026 | Undisclosed | ~2.8T total (MoE) | Native (encoder-integrated) | New architecture |
| GPT-5.6 Sol (OpenAI) | 07/09/2026 | Decoder-only; text + image in, 1.05M context / 128K output; max & ultra reasoning modes, sub-agent orchestration (Ultra); family: Luna / Terra / Sol | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Grok 4.5 (xAI) | 07/08/2026 | Decoder-only reasoning (extended thinking); text + image + files in, 500K context | Undisclosed | ~1.5T (reported) | Undisclosed | Undisclosed |
| Qwen3.7-Plus (Alibaba) | 06/01/2026 | Natively multimodal agent — image + video understanding, GUI grounding, tool invocation (note: Qwen3.7-Max is text-only) | Undisclosed | Undisclosed | Native multimodal ViT | Qwen3.7 |
| Mamoda2.5 (InclusionAI) | 05/04/2026 | AR-Diffusion + DiT-MoE (unified understanding + generation; 128 experts, Top-8) | Multimodal und. + image/video generation & editing | 25B total · 3B active | Semantic tokenizer + DiT decoder head | Mamoda2 |
| Nemotron 3 Nano Omni (NVIDIA) | 04/28/2026 | Hybrid MoE (omni-modal: vision + audio + text) | Vision + audio + text joint training | 30B total · 3B active | Dynamic-res ViT + Conv3D temporal | Nemotron 3 |
| GPT-5.5 (OpenAI) | 04/23/2026 | Decoder-only; text + image in (GPT-5 input stack), computer-use screen reading in Codex; topped AA Intelligence Index at release | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Qwen3.6-27B (Alibaba) | 04/22/2026 | Decoder-only / natively multimodal input (thinking + non-thinking) | Multimodal pretraining + agentic mid-training | 27B dense | Native multimodal ViT | Qwen3.6 |
| Qwen3.6-35B-A3B (Alibaba) | 04/15/2026 | MoE / natively multimodal input | Multimodal pretraining + agentic SFT/RL | 35B total · 3B active | Native multimodal ViT | Qwen3.6 |
| LFM2.5-VL-450M (Liquid AI) | 04/11/2026 | Liquid Foundation Model | Undisclosed | 450M | Non-overlapping tile ViT | LFM2.5 |
| EXAONE 4.5 (LG AI Research) | 04/09/2026 | Unified VL | Undisclosed | 33B | Proprietary vision encoder | EXAONE 4.5 |
| Claude Mythos (Anthropic, gated preview) | 04/07/2026 | Decoder-only (frontier; Project Glasswing gated) | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Gemma 4 (Google) | 04/02/2026 | Decoder-only / MoE | Undisclosed (140+ languages) | E2B / E4B / 26B MoE / 31B Dense | Native multimodal | Gemini 3 |
| Granite 4.0 3B Vision (IBM) | 04/01/2026 | Decoder-only | Enterprise document corpora | 3B | Undisclosed | Granite 4.0 |
| GLM-5V-Turbo (Zhipu / Z.AI) | 04/01/2026 | Natively multimodal (vision-coding) with Multi-Token Prediction | 30+ task joint RL | Undisclosed | CogViT | GLM-5 |
| InternVL-U (Shanghai AI Lab) | 03/10/2026 | Unified (MLLM + MMDiT) | Multimodal understanding + generation | 4B | InternViT | InternVL |
| GPT-5.4 / GPT-5.4 Thinking (OpenAI) | 03/06/2026 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Phi-4-Reasoning-Vision-15B (Microsoft) | 03/04/2026 | Decoder-only | Curated synthetic + filtered data | 15B | High-res dynamic-resolution ViT | Phi-4 |
| Gemini 3.0 (Google) | 03/2026 | Unified Model | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Qwen3.5 (Alibaba) | 02/16/2026 | Unified VL (early fusion) | Trillions of multimodal tokens | 0.8B–397B (MoE, 17B active) | ViT (native) | Qwen3.5 |
| Claude Opus 4.6 (Anthropic) | 02/2026 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Erin 5.0 (Baidu) | 02/05/2026 | Unified Model (Visual, Text, Audio) | Unified Modality Dataset | - | CNN–ViT (Understanding)/Next-Frame-and-Scale Prediction (Generation) | Unified Autoregressive Transformer |
| Molmo2 (Allen AI) | 01/15/2026 | Decoder-only | 7 new video + 2 multi-image datasets (9.19M videos) | 4B / 7B / 8B | Bi-directional attention ViT | Qwen 3 / OLMo |
| Gemini 3 | 11/18/2025 | Unified Model | Undisclosed | - | - | - |
| Emu3.5 | 10/30/2025 | Deconder-only | Unified Modality Dataset | - | SigLIP | Qwen3 |
| DeepSeek-OCR | 10/20/2025 | Encoder-Deconder | 70% OCR, 20% general vision, 10% text-only | 3B | DeepEncoder | DeepSeek-3B |
| Qwen3-VL | 10/11/2025 | Decoder-Only | - | 8B/4B | ViT | Qwen3 |
| Qwen3-VL-MoE | 09/25/2025 | Decoder-Only | - | 235B-A22B | ViT | Qwen3 |
| Qwen3-Omni (Visual/Audio/Text) | 09/21/2025 | - | Video/Audio/Image | 30B | ViT | Qwen3-Omni-MoE-Thinker |
| LLaVA-Onevision-1.5 | 09/15/2025 | - | Mid-Training-85M & SFT | 8B | Qwen2VLImageProcessor | Qwen3 |
| InternVL3.5 | 08/25/2025 | Decoder-Only | multimodal & text-only | 30B/38B/241B | InternViT-300M/6B | Qwen3 / GPT-OSS |
| SkyWork-Unipic-1.5B | 07/29/2025 | - | image/video.. | - | - | - |
| Grok 4 | 07/09/2025 | - | image/video.. | 1-2 Trillion | - | - |
| Kwai Keye-VL (Kuaishou) | 07/02/2025 | Decdoer-only | image/video.. | 8B | ViT | QWen-3-8B |
| OmniGen2 | 06/23/2025 | Decdoer-only & VAE | LLaVA-OneVision/ SAM-LLaVA.. | - | ViT | QWen-2.5-VL |
| Gemini-2.5-Pro | 06/17/2025 | - | - | - | - | - |
| GPT-o3/o4-mini | 06/10/2025 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| Mimo-VL (Xiaomi) | 06/04/2025 | Decdoer-only | 24 Trillion MLLM tokens | 7B | [Qwen2.5-ViT | Mimo-7B-base |
| BAGEL (Bytedance) | 05/20/2025 | Unified Model | Video/Image/Text | 7B | SigLIP2-so400m/14](https://arxiv.org/abs/2502.14786) | Qwen2.5 |
| BLIP3-o | 05/14/2025 | Decdoer-only | (BLIP3-o 60K) GPT-4o Generated Image Generation Data | 4/8B | ViT | QWen-2.5-VL |
| InternVL-3 | 04/14/2025 | Decdoer-only | 200 Billion Tokens | 1/2/8/9/14/38/78B | ViT-300M/6B | InterLM2.5/QWen2.5 |
| LLaMA4-Scout/Maverick | 04/04/2025 | Decdoer-only | 40/20 Trillion Tokens | 17B | MetaClip | LLaMA4 |
| Qwen2.5-Omni | 03/26/2025 | Decdoer-only | Video/Audio/Image/Text | 7B | Qwen2-Audio/Qwen2.5-VL ViT | End-to-End Mini-Omni |
| QWen2.5-VL | 01/28/2025 | Decdoer-only | Image caption, VQA, grounding agent, long video | 3B/7B/72B | Redesigned ViT | Qwen2.5 |
| GLM-4.6V (Zhipu / Z.AI) | 12/2025 | Decoder-only | Undisclosed | 106B / 9B (Flash) | Undisclosed | GLM-4.6 |
| Ola | 2025 | Decoder-only | Image/Video/Audio/Text | 7B | OryxViT | Qwen-2.5-7B, SigLIP-400M, Whisper-V3-Large, BEATs-AS2M(cpt2) |
| Ocean-OCR | 2025 | Decdoer-only | Pure Text, Caption, Interleaved, OCR | 3B | NaViT | Pretrained from scratch |
| SmolVLM | 2025 | Decoder-only | SmolVLM-Instruct | 250M & 500M | SigLIP | SmolLM |
| DeepSeek-Janus-Pro | 2025 | Decoder-only | Undisclosed | 7B | SigLIP | DeepSeek-Janus-Pro |
| Inst-IT | 2024 | Decoder-only | Inst-IT Dataset, LLaVA-NeXT-Data | 7B | CLIP/Vicuna, SigLIP/Qwen2 | LLaVA-NeXT |
| DeepSeek-VL2 | 2024 | Decoder-only | WiT, WikiHow | 4.5B x 74 | SigLIP/SAMB | DeepSeekMoE |
| xGen-MM (BLIP-3) | 2024 | Decoder-only | MINT-1T, OBELICS, Caption | 4B | ViT + Perceiver Resampler | Phi-3-mini |
| TransFusion | 2024 | Encoder-decoder | Undisclosed | 7B | VAE Encoder | Pretrained from scratch on transformer architecture |
| Baichuan Ocean Mini | 2024 | Decoder-only | Image/Video/Audio/Text | 7B | CLIP ViT-L/14 | Baichuan |
| LLaMA 3.2-vision | 2024 | Decoder-only | Undisclosed | 11B-90B | CLIP | LLaMA-3.1 |
| Pixtral | 2024 | Decoder-only | Undisclosed | 12B | CLIP ViT-L/14 | Mistral Large 2 |
| Qwen2-VL | 2024 | Decoder-only | Undisclosed | 7B-14B | EVA-CLIP ViT-L | Qwen-2 |
| NVLM | 2024 | Encoder-decoder | LAION-115M | 8B-24B | Custom ViT | Qwen-2-Instruct |
| Emu3 | 2024 | Decoder-only | Aquila | 7B | MoVQGAN | LLaMA-2 |
| Claude 3 | 2024 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| InternVL | 2023 | Encoder-decoder | LAION-en, LAION- multi | 7B/20B | Eva CLIP ViT-g | QLLaMA |
| InstructBLIP | 2023 | Encoder-decoder | CoCo, VQAv2 | 13B | ViT | Flan-T5, Vicuna |
| CogVLM | 2023 | Encoder-decoder | LAION-2B ,COYO-700M | 18B | CLIP ViT-L/14 | Vicuna |
| PaLM-E | 2023 | Decoder-only | All robots, WebLI | 562B | ViT | PaLM |
| LLaVA-1.5 | 2023 | Decoder-only | COCO | 13B | CLIP ViT-L/14 | Vicuna |
| Gemini | 2023 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| GPT-4V | 2023 | Decoder-only | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
| BLIP-2 | 2023 | Encoder-decoder | COCO, Visual Genome | 7B-13B | ViT-g | Open Pretrained Transformer (OPT) |
| Flamingo | 2022 | Decoder-only | M3W, ALIGN | 80B | Custom | Chinchilla |
| BLIP | 2022 | Encoder-decoder | COCO, Visual Genome | 223M-400M | ViT-B/L/g | Pretrained from scratch |
| CLIP | 2021 | Encoder-decoder | 400M image-text pairs | 63M-355M | ViT/ResNet | Pretrained from scratch |
1.1. 🌍 World Models
World models moved from research demos to release-grade artifacts in mid-2026: unified trunks that serve as generator, perceiver, and policy at once. Foundation releases first, then memory/state analyses and benchmarks.
| Model | Date | Type | Scale / License | Key Result | Links |
|---|---|---|---|---|---|
| Puffin-World | 09/03/2026 | Unified multimodal model with native 3D world states — jointly models gravity/latitude, depth, and image via Omni-Camera representation | Puffin-16M dataset; open code + weights | Ties physical understanding, spatial simulation, and 3D world generation/reconstruction into one architecture | Paper · Project |
| SolarWM | 09/02/2026 | Open foundation for interactive video world models; reconfigurable multi-source data engine + backbone-native adaptation on Wan2.2 / LTX-2.5 / MiniMax-H3 | 5B, 12B, 20B, 33B; CC BY 4.0 | Real-time minute-to-hour rollouts after training on only 5 s sequences; data + pipeline + weights + framework released | Paper · Project |
| ZimaBlue | 08/31/2026 | Generalizable world-action model via video pre-training on >120k h human + robot egocentric video; asynchronous Slow-Fast | 120k+ h | Zero-shot real-robot success 36.1% → 77.8% as pretraining video scales; 30 Hz on an RTX 4090 | Paper |
| Matrix-Game 3.5 | 08/30/2026 | Real-time streaming interactive world model with parameter-free patch memory + tiled-PRoPE geometry-aware memory + two-stage distillation | — | Minute-long real-time generation; extends v3.0 to answer the persistent-state critique | Paper · Project |
| DreamX-Phi 1.0 | 08/13/2026 | Action-conditioned video world model for robotic manipulation; per-arm SE(3) via PRoPE + depth branch + SAM3/V-JEPA object consistency + DMD few-step distillation | Open weights + code | 1st on Track 1, 2nd on Track 2 of the WorldArena 2.0 Challenge | Paper · Code |
| SimWAM | 08/07/2026 | World-Action Model for end-to-end autonomous driving; video expert + lightweight action expert co-trained via flow matching + RL | Open weights + code (CC BY 4.0) | 91.5 PDMS on NAVSIM with zero-shot nuScenes transfer | Paper · Code |
| G0.5 | 08/12/2026 | One AR stream for robot reasoning and action — single transformer emits reasoning + action tokens under one objective; cross-embodiment action tokenizer + multi-second visual memory | — | 76.7% R1lite/R1pro (vs π0.5 53.3%, GR00T-N1.7 24.4%), 82.5% zero-shot DROID, 98.9% LIBERO, 87.3% SimplerEnv-Bridge | Paper |
| HelloWorld | 08/06/2026 | Video world model with socially interactive characters | — | Pushes world models past physics and navigation into social dynamics: characters that respond to the viewer rather than merely persisting | Paper |
| VideoCoCo | 07/31/2026 | Agentic dual-engine text-to-video with Code-as-CoT | — | Infers temporal evolution symbolically via generated code instead of implicitly, then renders — a hybrid attack on physics violations in T2V | Paper |
| StatePlay | 07/29/2026 | State-aware game world model | — | Enforces mechanics consistency through explicit state, an answer to the persistent-state critique below | Paper |
| Cosmos 3 (NVIDIA) | 06/01/2026 | Omnimodal world-model family (language, image, video, audio, action) — mixture-of-transformers | Family; open code/checkpoints/data (OpenMDW-1.1) | SoTA across VL, video generation, robot policy; best open T2I/I2V + best RoboArena policy | Paper |
| Kairos | 06/15/2026 | Native world-model stack (understanding + generation + prediction) | 4B unified; Hybrid Linear Temporal Attention | Cross-embodiment data curriculum; real-time rollout on edge hardware; beats 14B on embodied benchmarks | Paper |
| DreamX-World 1.0 (Alibaba AMAP) | 06/15/2026 | General-purpose interactive T/I-to-video world model | 5B (Wan2.2-T2V-5B base); MIT open weights | Camera navigation, revisit consistency, promptable events; E-PRoPE encoding; few-step AR via causal forcing + DMD distillation | HF · Code |
| NVIDIA OmniDreams | 06/02/2026 | Real-time generative world model for closed-loop AV simulation | Mid/post-trained from Cosmos on 21k h driving | Action-conditioned sensor video; derived world-action model beats VLA-based Alpamayo 1.5 at 1/5 params | Paper |
| Mirage | 06/08/2026 | Latent spatial memory for video world models | — | 3D scene memory in diffusion latent space via depth-guided back-projection; faster + lighter than explicit-3D baselines | Paper |
| Reward as An Agent | 06/18/2026 | RL post-training for embodied world models | — | DynDiff-GRPO diversifies action-space exploration; agentic reward verification curbs reward hacking | Paper |
Benchmarks & analyses
| Title | Date | What It Shows | Link |
|---|---|---|---|
| WorldReward | 09/03/2026 | First VLM-based pairwise preference reward model for camera-conditioned world models; decomposes paired videos into action-aligned chunks with structured visual evidence; beats GPT-5.5 by 3.42/1.45/3.56 pts on three WorldReward-Bench dimensions and improves HY-WorldPlay 1.5 in RL post-training | Paper |
| PAWBench | 08/27/2026 | Probabilistic alignment: evaluates video generators as stochastic samplers of world dynamics via PAWEval (repeated rollouts → empirical outcome distributions); no model across 50 scenarios / 11 systems consistently matches reference probabilities while covering valid behaviors | Paper |
| GUI-CC | 09/01/2026 | Benchmarks contextual consistency of GUI world models as agent environments — extends the world-model-as-environment critique to computer-use | Paper |
| WorldExam | 08/04/2026 | Separates apparent appearance from inherent reactivity: a world model can look right while reacting wrong, formalising the critique that visual realism has been over-weighted | Paper |
| WorldOlympiad | 06/09/2026 | Physics / geometry / interaction "triathlon": SoTA world models show substantial gaps in physical reasoning, 3D consistency, long-horizon control | Paper |
| Current World Models Lack a Persistent State Core | 06/18/2026 | World models treat the world as a "tracking shot" — off-screen entities freeze instead of evolving; persists across architectures and scales | Paper |
| Echo-Memory | 06/08/2026 | Controlled memory study: raw context beats compressed memory for capacity; state-space recurrence best for revisit consistency | Paper |
| LongSpace / LongSpace-Bench | 06/04/2026 | Video MLLMs fail long-horizon spatial recall without explicit spatial memory (3D cues + layer-aware retrieval) | Paper |
See also the earlier world-model entries in §2.3 (UniSim, GAIA-1, LWM, Genesis, RoboGen) and the
2026-06-23/2026-06-27/2026-09-13progressive reports.
2. 🗂️ Benchmarks and Evaluation
2.1. Datasets for Training VLMs
| Dataset | Task | Size |
|---|---|---|
| 20/20 Vision — Data Curation (DatologyAI)(05/2026) | Data Curation for VLM Training | +11.7pp avg improvement; 17–87× less compute |
| MolmoWebMix (Allen AI)(04/2026) | Web Agent Training Trajectories | 100K+ synthetic + 30K human demos |
| Vero-600K(04/2026) | Broad Visual Reasoning RL Training | 600K samples from 59 datasets, 6 task categories |
| BigEarthNet.txt(03/2026) | Multi-sensor Earth Observation Image-Text | 464K images, 9.6M text annotations |
| OmniScience(02/2026) | Scientific Image Understanding | 1.5M figure-caption-context triplets |
| MaD-Mix(02/2026) | Multi-modal Data Mixture Optimization | Framework (0.5B–7B scale) |
| OVID(2026) | Open Video Pre-training | 10M hours, 300M frame-caption pairs |
| Molmo2 Video Datasets(01/2026) | Video Captions, QA, Tracking, Pointing | 9.19M videos (7 video + 2 multi-image datasets) |
| MMFineReason(/1/30/2026) | REasoning | 1.8M |
| FineVision(09/04/2025) | Mixed Domain | 24.3 M/4.48TB |
2.2. Datasets and Evaluation for VLM
🧮 Visual Math (+ Visual Math Reasoning)
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| MathVision | Visual Math | MC / Answer Match | Human | 3.04 | Repo |
| MathVista | Visual Math | MC / Answer Match | Human | 6 | Repo |
| MathVerse | Visual Math | MC | Human | 4.6 | Repo |
| VisNumBench | Visual Number Reasoning | MC | Python Program generated/Web Collection/Real life photos | 1.91 | Repo |
💬 Benchmark for Unified Models
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| ROVER | Reciprocal Cross-Modal Reasoning | Visual Gen + Verbal Gen Eval | Human | 1.3 (1,876 images) | Paper |
| RealUnify | Math, World knowledge, Image Gen | Direct & StepWise Eval (Sec 3.3) | Script & Humanverification | 1.0 | Repo |
| Uni-MMMU | Science, Code, Image Gen | DreamSim (Image Gen Eval) & String Matching (Understanding Eval) | - | 1.0 | Repo |
🎞️ Video Understanding
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| VideoGAIA | Agentic Video Understanding (tool-augmented multi-turn) | Human/model co-designed, triple-expert-verified | Expert | 0.27 (271 tasks) | Paper |
| OmniAssistBench | Real-Time Omni-LLM Assistants | Multi-turn guided interaction with predefined route priors | Expert (>1000 h) | - | Project |
| EgoMonth | Month-Level Egocentric Video / Long-Term Spatiotemporal Memory | 14-task Schema Consolidation / Episodic Indexing / Cascading Reasoning framework | Human | 1.44 (300+ h from 20 participants) | Paper |
| Video-IFBench | Instruction Following in Video Understanding | - | - | - | Paper |
| GST-Bench | Global Spatial Awareness from Continuous Video | Long-traversal scene integration (vs. single-viewpoint local perception) | - | - | Paper |
| ChronoVision | Multi-step Temporal Reasoning | Latent state reconstruction | - | - | Paper |
| VGenST-Bench | Spatio-temporal Reasoning via Active Video Synthesis | 3×2×2 taxonomy; synthesized controlled scenes decouple perception from reasoning | Multi-agent + Human QC | — | Paper |
| TOC-Bench | Temporal Object Consistency for Video-LLMs | 3-layer temporal-necessity filtering; identity/continuity through occlusion & state change | Human-verified | 2.3 (2,323 QA / 1,951 videos) | Paper |
| VideoZeroBench | Spatio-temporal Evidence Verification for Long-Video QA | 5-level progressive evidence tightening | Human | 0.5 (500 questions, 13 domains) | Paper |
| Video-Oasis | Diagnostic Meta-benchmark for Video Understanding | Measures % solvable without visual/temporal context | Meta-analysis | — | Paper |
| LoVR | Long Video Retrieval in Multimodal Contexts | Retrieval accuracy | — | — | Paper |
| MMOU | Omni-modal Long Video Understanding | MC | Human | 15 (9,038 videos) | Paper |
| Video-MMMU | Knowledge Acquisition from Professional Videos | MC + Knowledge Gain | Expert | 0.9 (300 videos) | Paper |
| MMVU | Expert-Level Multi-Discipline Video Understanding | MC | Expert | 3 (27 subjects) | Paper |
| VideoHallu | Video Understanding | LLM Eval | Human | 3.2 | Repo |
| Video SimpleQA | Video Understanding | LLM Eval | Human | 2.03 | Repo |
| MovieChat | Video Understanding | LLM Eval | Human | 1 | Repo |
| Perception‑Test | Video Understanding | MC | Crowd | 11.6 | Repo |
| VideoMME | Video Understanding | MC | Experts | 2.7 | Site |
| EgoSchem | Video Understanding | MC | Synth / Human | 5 | Site |
| Inst‑IT‑Bench | Fine‑grained Image & Video | MC & LLM | Human / Synth | 2 | Repo |
💬 Multimodal Conversation
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| VisionArena | Multimodal Conversation | Pairwise Pref | Human | 23 | Repo |
🧠 Multimodal General Intelligence
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| StateSight | Latent Spatial-State Reconstruction | Procedural single-image tasks (cube-nets, occluded towers, connected components); companion StateSight-Steps for intermediate visual states | Synth + oracle | 0.9 (300 items × 3 families) + 0.9 with interleaved steps | Paper |
| GUI-Primitives | Spatial Reasoning in GUI Grounding | 7 spatial relations; contrastive pairs; strict point-in-box | Human validated | 0.99 (994 pairs) | Paper |
| MBA | Real-World Business Ideation Agents | Multimodal agentic task quality | - | - | Paper |
| HumanCLAW | Can a VLM Act Through a Body? | Decouples the decision from motor control so failures attribute to perception, planning, or actuation | - | - | Paper |
| PerceptionBench | Atomic Visual Perception | Decomposes perception into primitive operations rather than end-task accuracy | - | - | Paper |
| C$^3$PO | Cross-Modal Composition & Counterfactuals (omni-modal) | Compositional and counterfactual probes for any-to-any models | - | - | Paper |
| OmniEarth | Geospatial / Remote Sensing VLM Eval | MC + Open VQA | Human (verified) | 44.2 (9,275 images, 28 tasks) | Paper |
| MultiHaystack | Multimodal Retrieval & Reasoning | Retrieval + QA | Human | 0.75 (46K+ candidates) | Paper |
| DatBench | Discriminative, Faithful VLM Eval | MC (format-aware) | Synth | - | Paper |
| MMLU | General MM | MC | Human | 15.9 | Repo |
| MMStar | General MM | MC | Human | 1.5 | Site |
| NaturalBench | General MM | Yes/No, MC | Human | 10 | HF |
| PHYSBENCH | Visual Math Reasoning | MC | Grad STEM | 0.10 | Repo |
🔎 Visual Reasoning / VQA (+ Multilingual & OCR)
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| EMMA | Visual Reasoning | MC | Human + Synth | 2.8 | Repo |
| MMTBENCH | Visual Reasoning & QA | MC | AI Experts | 30.1 | Repo |
| MM‑Vet | OCR / Visual Reasoning | LLM Eval | Human | 0.2 | Repo |
| MM‑En/CN | Multilingual MM Understanding | MC | Human | 3.2 | Repo |
| GQA | Visual Reasoning & QA | Answer Match | Seed + Synth | 22 | Site |
| VCR | Visual Reasoning & QA | MC | MTurks | 290 | Site |
| VQAv2 | Visual Reasoning & QA | Yes/No, Ans Match | MTurks | 1100 | Repo |
| MMMU | Visual Reasoning & QA | Ans Match, MC | College | 11.5 | Site |
| MMMU-Pro | Visual Reasoning & QA | Ans Match, MC | College | 5.19 | Site |
| R1‑Onevision | Visual Reasoning & QA | MC | Human | 155 | Repo |
| VLM²‑Bench | Visual Reasoning & QA | Ans Match, MC | Human | 3 | Site |
| VisualWebInstruct | Visual Reasoning & QA | LLM Eval | Web | 0.9 | Site |
📝 Visual Text / Document Understanding (+ Charts)
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| ExtractBench | Schema-Guided Enterprise Document Extraction | Scored against a target schema rather than free-form answers | - | - | Paper |
| ConfBench | Confidence Calibration on Document Extraction | Asks whether the model knows when it is wrong, not only whether it is right | - | - | Paper |
| TableVision | Spatially Grounded Table Reasoning | 3-level Cognitive Eval | Human | 6.8 (13 sub-categories) | Paper |
| TextVQA | Visual Text Understanding | Ans Match | Expert | 28.6 | Repo |
| DocVQA | Document VQA | Ans Match | Crowd | 50 | Site |
| ChartQA | Chart Graphic Understanding | Ans Match | Crowd / Synth | 32.7 | Repo |
🌄 Text‑to‑Image Generation
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| Sci-VBench | Knowledge- & Reasoning-Intensive Video Generation (Science) | Rubric-based (Prompt Grounding, Scientific/Causal Correctness); MLLM-as-Judge validated | Expert | 1.25 (1,253 prompts × 60 subjects) | Paper |
| PAWBench | Probabilistically Aligned World Modeling | PAWEval — repeated rollouts → empirical outcome distributions | Reference distributions | 50 scenarios × 11 systems | Paper |
| VGI-Bench | Visual Intelligence in Video Generation Models | Probes scene understanding inside the generator | - | - | Paper |
| FilmBench | Film-Grade Cinematic Video Generation | Craft criteria — shot grammar, continuity, staging | - | - | Paper |
| MPIE-Bench | Anatomically Plausible Multi-Person Interaction Editing | Anatomical plausibility under multi-subject edits | - | - | Paper |
| MSCOCO‑30K | Text‑to‑Image | BLEU, ROUGE, Sim | MTurks | 30 | Site |
| GenAI‑Bench | Text‑to‑Image | Human Rating | Human | 80 | HF |
🚨 Hallucination Detection / Control
| Dataset | Task | Eval Protocol | Annotators | Size (K) | Code / Site |
|---|---|---|---|---|---|
| HallusionBench | Hallucination | Yes/No | Human | 1.13 | Repo |
| POPE | Hallucination | Yes/No | Human | 9 | Repo |
| CHAIR | Hallucination | Yes/No | Human | 124 | Repo |
| MHalDetect | Hallucination | Ans Match | Human | 4 | Repo |
| Hallu‑Pi | Hallucination | Ans Match | Human | 1.26 | Repo |
| HallE‑Control | Hallucination | Yes/No | Human | 108 | Repo |
| AutoHallusion | Hallucination | Ans Match | Synth | 3.129 | Repo |
| BEAF | Hallucination | Yes/No | Human | 26 | Site |
| GAIVE | Hallucination | Ans Match | Synth | 320 | Repo |
| HalEval | Hallucination | Yes/No | Crowd / Synth | 2 | Repo |
| AMBER | Hallucination | Ans Match | Human | 15.22 | Repo |
| MVI-Bench | Misleading Visual Inputs | Ans Match | Human | 1.25 | Repo |
2.3. Benchmark Datasets, Simulators, and Generative Models for Embodied VLM
| Benchmark | Domain | Type | Project |
|---|---|---|---|
| OSReward | Computer-Use Agents | Cross-platform reward-model evaluation | Paper |
| Drive-Bench | Embodied AI | Autonomous Driving | Website |
| Habitat, Habitat 2.0, Habitat 3.0 | Robotics (Navigation) | Simulator + Dataset | Website |
| Gibson | Robotics (Navigation) | Simulator + Dataset | Website, Github Repo |
| iGibson1.0, iGibson2.0 | Robotics (Navigation) | Simulator + Dataset | Website, Document |
| Isaac Gym | Robotics (Navigation) | Simulator | Website, Github Repo |
| Isaac Lab | Robotics (Navigation) | Simulator | Website, Github Repo |
| AI2THOR | Robotics (Navigation) | Simulator | Website, Github Repo |
| ProcTHOR | Robotics (Navigation) | Simulator + Dataset | Website, Github Repo |
| VirtualHome | Robotics (Navigation) | Simulator | Website, Github Repo |
| ThreeDWorld | Robotics (Navigation) | Simulator | Website, Github Repo |
| VIMA-Bench | Robotics (Manipulation) | Simulator | Website, Github Repo |
| VLMbench | Robotics (Manipulation) | Simulator | Github Repo |
| CALVIN | Robotics (Manipulation) | Simulator | Website, Github Repo |
| GemBench | Robotics (Manipulation) | Simulator | Website, Github Repo |
| WebArena | Web Agent | Simulator | Website, Github Repo |
| UniSim | Robotics (Manipulation) | Generative Model, World Model | Website |
| GAIA-1 | Robotics (Automonous Driving) | Generative Model, World Model | Website |
| LWM | Embodied AI | Generative Model, World Model | Website, Github Repo |
| Genesis | Embodied AI | Generative Model, World Model | Github Repo |
| EMMOE | Embodied AI | Generative Model, World Model | Paper |
| RoboGen | Embodied AI | Generative Model, World Model | Website |
| UnrealZoo | Embodied AI (Tracking, Navigation, Multi Agent) | Simulator | Website |
3. ⚒️ Post-Training
3.1. RL Alignment for VLM
| Title | Year | Paper | RL | Code |
|---|---|---|---|---|
| Miles v0.1: Production-Level Post-Training | 09/08/2026 | Paper | Full-stack open async agentic RL; demonstrated on GLM-5.2 744B-A40B MoE across 64 NVIDIA GB300 GPUs (263 s median step) | Code |
| Reason Through the Latent! (CVRR) | 09/06/2026 | Paper | Causal Visual Recurrent Reasoning — strips visual KV cache before decoding to force latent reasoning; strong retention on V*, MMVP, BLINK, MME-RealWorld-Lite | - |
| Beyond Data Scaling: Representation-Centric Continued Pre-training for VLAs (VLAct) | 08/27/2026 | Paper | VLM-prior preservation + multi-head continuous action co-supervision + partial cross-embodiment unification; 82.6% LIBERO-Plus, 92.5% RoboTwin 2.0 with 20% of trajectories | Project |
| Co-RL: Unsupervised Reasoning Emerges from Diverse Cohort in Multi-Agent RL | 08/18/2026 | Paper | Multi-agent cooperative RL with peer-derived rewards — no ground-truth labels; 3.0–8.6% avg gain on 7 LLM benchmarks, 2.3–7.2% on 4 VLM benchmarks | Code |
| Spatial Memory Agent | 08/13/2026 | Paper | Experience-grounded runtime — self-evolves a frozen VLM's spatial reasoning via verifier-guided reflection distilled into lessons scored by a Transfer Reliability Score | - |
| Evidence-RL: Towards Evidence-intensive Visual Reasoning | 08/08/2026 | Paper | Counterfactual Evidence Disentanglement inside GRPO — rewards evidence-grounded answers without evidence annotations; gains on 9 benchmarks × 4 backbones | - |
| ZPPO: Zone of Proximal Policy Optimization — Teacher in Prompts, Not Gradients | 06/16/2026 | Paper | Teacher guidance via reformulated prompts; beats distillation & GRPO on Qwen3.5 VLMs (0.8B–9B, 31-benchmark suite) | - |
| Efficient Reinforcement for Visual-Textual Thinking with Discrete Diffusion | 06/11/2026 | Paper | GRPO over multimodal discrete diffusion; localized visual editing cuts rollout compute 26.9% vs AR | - |
| AlphaGRPO: Self-Reflective Multimodal Generation in UMMs | 05/12/2026 | Paper | GRPO for unified-model generation; LLM-decomposed verifiable reward (GenEval, TIIF, DPG, WISE) | - |
| OpenSearch-VL: Multi-Turn Fatal-Aware GRPO for Multimodal Search Agents | 05/07/2026 | Paper | Fatal-aware GRPO; handles tool-call failures in agentic multi-turn RL | - |
| GRPO-TTA: Test-Time Visual Tuning via GRPO-Driven RL | 05/05/2026 | Paper | GRPO for test-time visual encoder tuning; no ground-truth labels needed | - |
| S-GRPO: Unified Post-Training for Large VLMs | 04/2026 | Paper | Supervised GRPO; injects ground-truth trajectories to solve cold-start | - |
| Faithful GRPO (FGRPO): Constrained Policy Optimization for Visual Spatial Reasoning | 04/2026 | Paper | Lagrangian-constrained GRPO; inconsistency 24.5% → 1.7% | - |
| Vero: An Open RL Recipe for General Visual Reasoning | 04/2026 | Paper | Task-routed rewards; GRPO-based | Code |
| wDPO: Winsorized Direct Preference Optimization for Robust Alignment | 03/2026 | Paper | wDPO | - |
| f-GRPO and Beyond: Divergence-Based RL for General LLM Alignment | 02/2026 | Paper | f-GRPO / f-HAL | - |
| From Sight to Insight: Improving Visual Reasoning of MLLMs via Reinforcement Learning | 01/2026 | Paper | GRPO (6 reward functions) | - |
| SaFeR-VLM: Safety-Aware Reinforcement Learning for Multimodal Reasoning | 2026 (ICLR) | Paper | GRPO + safety reward | - |
| SAIL-RL: Guiding MLLMs in When and How to Think via Dual-Reward RL Tuning | 11/2025 | Paper | Dual-Reward (Thinking + Judging) | - |
| GIFT: Group-relative Implicit Fine Tuning Integrates GRPO with DPO and UNA | 10/2025 | Paper | GIFT (convex MSE loss) | - |
| Game-RL: Synthesizing Multimodal Verifiable Game Data to Boost VLMs' General Reasoning | 10/12/2025 | Paper | GRPO | - |
| Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | 09/29/2025 | Paper | GRPO | - |
| Vision-SR1: Self-rewarding vision-language model via reasoning decomposition | 08/26/2025 | Paper | GRPO | - |
| Group Sequence Policy Optimization | 06/24/2025 | Paper | GSPO | - |
| Visionary-R1: Mitigating Shortcuts in Visual Reasoning with Reinforcement Learning | 05/20/2025 | Paper | GRPO | - |
| VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning | 2025/04/10 | Paper | GRPO | Code |
| OpenVLThinker: An Early Exploration to Complex Vision-Language Reasoning via Iterative Self-Improvement | 2025/03/21 | Paper | GRPO | Code |
| Boosting the Generalization and Reasoning of Vision Language Models with Curriculum Reinforcement Learning | 2025/03/10 | Paper | GRPO | Code |
| OmniAlign-V: Towards Enhanced Alignment of MLLMs with Human Preference | 2025 | Paper | DPO | Code |
| Multimodal Open R1/R1-Multimodal-Journey | 2025 | - | GRPO | Code |
| R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization | 2025 | Paper | GRPO | Code |
| Agent-R1: Training Powerful LLM Agents with End-to-End Reinforcement Learning | 2025 | - | PPO/REINFORCE++/GRPO | Code |
| MM-Eureka: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning | 2025 | Paper | REINFORCE Leave-One-Out (RLOO) | Code |
| MM-RLHF: The Next Step Forward in Multimodal LLM Alignment | 2025 | Paper | DPO | Code |
| LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL | 2025 | Paper | PPO | Code |
| Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models | 2025 | Paper | GRPO | Code |
| Unified Reward Model for Multimodal Understanding and Generation | 2025 | Paper | DPO | Code |
| Can We Generate Images with CoT? Let's Verify and Reinforce Image Generation Step by Step | 2025 | Paper | DPO | Code |
| All Roads Lead to Likelihood: The Value of Reinforcement Learning in Fine-Tuning | 2025 | Paper | Online RL | - |
| Video-R1: Reinforcing Video Reasoning in MLLMs | 2025 | Paper | GRPO | Code |
3.2. Finetuning for VLM
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes | 08/2026 | Paper | - | - |
| SpatialCLI: Learning to Reason With Spatial Tools, Then Without Them | 07/2026 | Paper | - | - |
| Why Does RL Generalize Better Than SFT? A Data-Centric Perspective (DC-SFT) | 02/2026 | Paper | - | - |
| The Synergy Dilemma of Long-CoT SFT and RL | 2026 (TMLR) | Paper | - | - |
| Layer-wise Analysis of Supervised Fine-Tuning | 04/2026 | Paper | - | - |
| AGFT: Alignment-Guided Fine-Tuning for Zero-Shot Adversarial Robustness of VLMs | 2026/03 | Paper | - | - |
| CoVFT: Context-aware Visual Fine-tuning for Multimodal Large Language Models | 2026/03 | Paper | - | - |
| MERGETUNE: Continued Fine-Tuning of Vision-Language Models | 2026/01 (ICLR 2026) | Paper | - | - |
| Mask Fine-Tuning (MFT): Unlocking Hidden Capabilities in Vision-Language Models | 2025/12 | Paper | - | - |
| Image-LoRA: Towards Minimal Fine-Tuning of VLMs | 2025/12 | Paper | - | - |
| Reassessing the Role of Supervised Fine-Tuning: An Empirical Study in VLM Reasoning | 2025/12 | Paper | - | - |
| Eagle 2.5: Boosting Long-Context Post-Training for Frontier Vision-Language Models | 2025/04/21 | Paper | Website | Code |
| OMNICAPTIONER: One Captioner to Rule Them All | 2025/04/09 | Paper | Website | Code |
| Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning | 2024 | Paper | Website | Code |
| LLaVolta: Efficient Multi-modal Models via Stage-wise Visual Context Compression | 2024 | Paper | Website | Code |
| ViTamin: Designing Scalable Vision Models in the Vision-Language Era | 2024 | Paper | Website | Code |
| Espresso: High Compression For Rich Extraction From Videos for Your Vision-Language Model | 2024 | Paper | - | - |
| Should VLMs be Pre-trained with Image Data? | 2025 | Paper | - | - |
| VisionArena: 230K Real World User-VLM Conversations with Preference Labels | 2024 | Paper | - | Code |
3.3. VLM Alignment github
| Project | Repository Link |
|---|---|
| Verl | 🔗 GitHub |
| EasyR1 | 🔗 GitHub |
| OpenR1 | 🔗 GitHub |
| LLaMAFactory | 🔗 GitHub |
| MM-Eureka-Zero | 🔗 GitHub |
| MM-RLHF | 🔗 GitHub |
| LMM-R1 | 🔗 GitHub |
3.4. Prompt Optimization
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| EvoPrompt: Evolving Prompt Adaptation for Vision-Language Models | 2026/03 | Paper | - | - |
| MMLoP: Multi-Modal Low-Rank Prompting for Efficient Vision-Language Adaptation | 2026/02 | Paper | - | - |
| Multimodal Prompt Optimizer (MPO): Joint Optimization of Multimodal Prompts | 2025/10 | Paper | - | - |
| Evolutionary Prompt Optimization Discovers Emergent Multimodal Reasoning Strategies | 2025/03 | Paper | - | - |
| In-ContextEdit:EnablingInstructionalImageEditingwithIn-Context GenerationinLargeScaleDiffusionTransformer | 2025/04/30 | Paper | Website | Code |
4. ⚒️ Applications
4.1 Embodied VLM Agents
| Title | Year | Paper Link |
|---|---|---|
| Intern-S2-Preview: Scientific Agentic Foundation Model — 397B backbone + 4B memory decoder (Intern-MemDec-4B); Biology-Instructions 56.92 → 60.32 without touching the backbone | 08/13/2026 | Paper |
| G0.5: One Autoregressive Stream for Robot Reasoning and Action | 08/12/2026 | Paper |
| LightNav-0: Eliciting VLM Spatial Intelligence for Generalist Embodied Navigation | 08/31/2026 | Paper |
| Embodied-Navigator (TAMP-Nav): Point, Think, Memorize, Align — 66.2% SR on R2R-CE | 08/18/2026 | Paper |
| SimpleMemVLA: Native-Video Memory for Vision-Language-Action Models | 09/06/2026 | Paper |
| UI-Mate: Open-Weight Foundation GUI Agent (UI-Mate-27B on Qwen3.6-27B; 77.0% OSWorld-Verified, 66.2% WindowsAgentArena) | 08/16/2026 | Paper |
| UI-Venus-2 Technical Report — open-source foundation GUI agent (mobile, web, desktop) | 08/27/2026 | Paper |
| WM-R1: Training GUI Agents to Reason and Leverage World Models with RL | 09/01/2026 | Paper |
| ComBodied Agents: A New Paradigm of Human-Centric Agentic AI | 08/14/2026 | Paper |
| Metis: Memory Foundation Model | 07/2026 | Paper |
| Aligning Cyber Space with Physical World: A Comprehensive Survey on Embodied AI | 2024 | Paper |
| ScreenAI: A Vision-Language Model for UI and Infographics Understanding | 2024 | Paper |
| ChartLlama: A Multimodal LLM for Chart Understanding and Generation | 2023 | Paper |
| SciDoc2Diagrammer-MAF: Towards Generation of Scientific Diagrams from Documents guided by Multi-Aspect Feedback Refinement | 2024 | 📄 Paper |
| Training a Vision Language Model as Smartphone Assistant | 2024 | Paper |
| ScreenAgent: A Vision-Language Model-Driven Computer Control Agent | 2024 | Paper |
| Embodied Vision-Language Programmer from Environmental Feedback | 2024 | Paper |
| VLMs Play StarCraft II: A Benchmark and Multimodal Decision Method | 2025 | 📄 Paper |
| MP-GUI: Modality Perception with MLLMs for GUI Understanding | 2025 | 📄 Paper |
4.2. Generative Visual Media Applications
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| AuK (Tencent Hunyuan): open-source foundation model for speech generation and editing — multimodal LLM + jointly trained VAE + hybrid rectified-flow Transformer (MMDiT → single-stream DiT); AuK-Flash gives 4.5× wall-clock speedup via 4-step inference; trained on ~3.03B instruction-audio instances / 1.95M h | 09/08/2026 | 📄 Paper | - | 💾 Code |
| Chimera: Designing and Chinchilla-Scaling Hybrid Visual Diffusion Transformers | 07/2026 | 📄 Paper | - | - |
| GPT4Motion: Scripting Physical Motions in Text-to-Video Generation via Blender-Oriented GPT Planning | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
| Spurious Correlation in Multimodal LLMs | 2025 | 📄 Paper | - | - |
| WeGen: A Unified Model for Interactive Multimodal Generation as We Chat | 2025 | 📄 Paper | - | 💾 Code |
| VideoMind: A Chain-of-LoRA Agent for Long Video Reasoning | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
4.3. Robotics and Embodied AI
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| AHA: A Vision-Language-Model for Detecting and Reasoning Over Failures in Robotic Manipulation | 2024 | 📄 Paper | 🌍 Website | - |
| SpatialVLM: Endowing Vision-Language Models with Spatial Reasoning Capabilities | 2024 | 📄 Paper | 🌍 Website | - |
| Vision-language model-driven scene understanding and robotic object manipulation | 2024 | 📄 Paper | - | - |
| Guiding Long-Horizon Task and Motion Planning with Vision Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| AutoTAMP: Autoregressive Task and Motion Planning with LLMs as Translators and Checkers | 2023 | 📄 Paper | 🌍 Website | - |
| VLM See, Robot Do: Human Demo Video to Robot Action Plan via Vision Language Model | 2024 | 📄 Paper | - | - |
| Scalable Multi-Robot Collaboration with Large Language Models: Centralized or Decentralized Systems? | 2023 | 📄 Paper | 🌍 Website | - |
| DART-LLM: Dependency-Aware Multi-Robot Task Decomposition and Execution using Large Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| MotionGPT: Human Motion as a Foreign Language | 2023 | 📄 Paper | - | 💾 Code |
| Learning Reward for Robot Skills Using Large Language Models via Self-Alignment | 2024 | 📄 Paper | - | - |
| Language to Rewards for Robotic Skill Synthesis | 2023 | 📄 Paper | 🌍 Website | - |
| Eureka: Human-Level Reward Design via Coding Large Language Models | 2023 | 📄 Paper | 🌍 Website | - |
| Integrated Task and Motion Planning | 2020 | 📄 Paper | - | - |
| Jailbreaking LLM-Controlled Robots | 2024 | 📄 Paper | 🌍 Website | - |
| Robots Enact Malignant Stereotypes | 2022 | 📄 Paper | 🌍 Website | - |
| LLM-Driven Robots Risk Enacting Discrimination, Violence, and Unlawful Actions | 2024 | 📄 Paper | - | - |
| Highlighting the Safety Concerns of Deploying LLMs/VLMs in Robotics | 2024 | 📄 Paper | 🌍 Website | - |
| EmbodiedBench: Comprehensive Benchmarking Multi-modal Large Language Models for Vision-Driven Embodied Agents | 2025 | 📄 Paper | 🌍 Website | 💾 Code & Dataset |
| Gemini Robotics: Bringing AI into the Physical World | 2025 | 📄 Technical Report | 🌍 Website | - |
| GR-2: A Generative Video-Language-Action Model with Web-Scale Knowledge for Robot Manipulation | 2024 | 📄 Paper | 🌍 Website | - |
| Magma: A Foundation Model for Multimodal AI Agents | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| DayDreamer: World Models for Physical Robot Learning | 2022 | 📄 Paper | 🌍 Website | 💾 Code |
| Hi Robot: Open-Ended Instruction Following with Hierarchical Vision-Language-Action Models | 2025 | 📄 Paper | - | - |
| RL-VLM-F: Reinforcement Learning from Vision Language Foundation Model Feedback | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| KALIE: Fine-Tuning Vision-Language Models for Open-World Manipulation without Robot Data | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| Unified Video Action Model | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| HybridVLA: Collaborative Diffusion and Autoregression in a Unified Vision-Language-Action Model | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| Anticipation-VLA: Long-Horizon Embodied Tasks via Anticipation-Based Subgoal Generation | 05/02/2026 | 📄 Paper | - | - |
| Green-VLA: Staged VLA for Generalist Robots | 05/2026 | 📄 Paper | 🌍 Website | - |
| VLA Foundry: Unified Framework for Training VLAs | 04/2026 | 📄 Paper | - | - |
| OmniVLA-RL: Spatial Understanding + Online RL for VLA | 04/2026 | 📄 Paper | - | - |
| DAM-VLA: A Dynamic Action Model-Based Vision-Language-Action Framework for Robot Manipulation | 03/2026 | 📄 Paper | - | - |
| NS-VLA: Towards Neuro-Symbolic Vision-Language-Action Models | 03/2026 | 📄 Paper | - | - |
| Steerable Vision-Language-Action Policies for Embodied Reasoning and Hierarchical Control | 02/2026 | 📄 Paper | - | - |
| ST4VLA: Spatial Guided Training for Vision-Language-Action Models | 02/2026 | 📄 Paper | - | - |
4.3.1. Manipulation
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| G0.5: One Autoregressive Stream for Robot Reasoning and Action — 76.7% R1lite/R1pro, 82.5% zero-shot DROID, 98.9% LIBERO | 08/12/2026 | 📄 Paper | - | - |
| DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation — WorldArena 2.0 Track 1 winner | 08/13/2026 | 📄 Paper | - | 💾 Code |
| ZimaBlue: Evolving Generalizable World-Action Models via >120k h video pre-training — 30 Hz on RTX 4090, 36.1% → 77.8% zero-shot real-robot success | 08/31/2026 | 📄 Paper | - | - |
| Beyond Data Scaling: Representation-Centric Continued Pre-training for VLAs (VLAct) — 82.6% LIBERO-Plus, 92.5% RoboTwin 2.0 with 20% of trajectories | 08/27/2026 | 📄 Paper | 🌍 Project | - |
| SimpleMemVLA: Native-Video Memory for Vision-Language-Action Models | 09/06/2026 | 📄 Paper | - | - |
| Ego2Robot: Scalable Robot Data Synthesis from Egocentric Human Data | 08/03/2026 | 📄 Paper | - | - |
| N₀-VTLA: Scaling Vision-Tactile-Language-Action Model with Latent Tactile Tokens | 07/26/2026 | 📄 Paper | - | - |
| Supervise What Survives: Geometry-Guided VLA Adaptation from Synthetic Robot Videos | 06/23/2026 | 📄 Paper | - | - |
| Qwen-RobotManip: Alignment Unlocks Scale for Robotic Manipulation Foundation Models (38,100-hour corpus) | 06/16/2026 | 📄 Paper | - | - |
| Hy-Embodied-0.5-VLA: From VLA Models to a Real-World Robot Learning Stack (10,000-hour UMI corpus) | 06/12/2026 | 📄 Paper | - | - |
| Learning What to Say to Your VLA: Mostly Harmless VLA Steering | 06/10/2026 | 📄 Paper | - | - |
| Finetuning VLA Models Requires Fewer Layers Than You Think (50% depth pruning) | 06/18/2026 | 📄 Paper | - | - |
| Health-Conditioned VLA for Malfunction-Aware Robot Control | 05/15/2026 | 📄 Paper | - | - |
| VIMA: General Robot Manipulation with Multimodal Prompts | 2022 | 📄 Paper | 🌍 Website | |
| Instruct2Act: Mapping Multi-Modality Instructions to Robotic Actions with Large Language Model | 2023 | 📄 Paper | - | - |
| Creative Robot Tool Use with Large Language Models | 2023 | 📄 Paper | 🌍 Website | - |
| RoboVQA: Multimodal Long-Horizon Reasoning for Robotics | 2024 | 📄 Paper | - | - |
| RT-1: Robotics Transformer for Real-World Control at Scale | 2022 | 📄 Paper | 🌍 Website | - |
| RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control | 2023 | 📄 Paper | 🌍 Website | - |
| Open X-Embodiment: Robotic Learning Datasets and RT-X Models | 2023 | 📄 Paper | 🌍 Website | - |
| ExploRLLM: Guiding Exploration in Reinforcement Learning with Large Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| AnyTouch: Learning Unified Static-Dynamic Representation across Multiple Visuo-tactile Sensors | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| Masked World Models for Visual Control | 2022 | 📄 Paper | 🌍 Website | 💾 Code |
| Multi-View Masked World Models for Visual Robotic Manipulation | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
4.3.2. Navigation
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| LightNav-0: Eliciting VLM Spatial Intelligence for Generalist Embodied Navigation — dual-channel pointing + residual-VQ action tokenizer; SoTA monocular success across 10 navigation sims | 08/31/2026 | 📄 Paper | - | - |
| Embodied-Navigator (TAMP-Nav): Point-Think-Memorize-Align with Space-Time Indicator memory — 66.2% SR on R2R-CE using only 90k training trajectories | 08/18/2026 | 📄 Paper | - | - |
| ZSON: Zero-Shot Object-Goal Navigation using Multimodal Goal Embeddings | 2022 | 📄 Paper | - | - |
| LOC-ZSON: Language-driven Object-Centric Zero-Shot Object Retrieval and Navigation | 2024 | 📄 Paper | - | - |
| LM-Nav: Robotic Navigation with Large Pre-Trained Models of Language, Vision, and Action | 2022 | 📄 Paper | 🌍 Website | - |
| NaVILA: Legged Robot Vision-Language-Action Model for Navigation | 2022 | 📄 Paper | 🌍 Website | - |
| VLFM: Vision-Language Frontier Maps for Zero-Shot Semantic Navigation | 2024 | 📄 Paper | - | - |
| Navigation with Large Language Models: Semantic Guesswork as a Heuristic for Planning | 2023 | 📄 Paper | 🌍 Website | - |
| Vi-LAD: Vision-Language Attention Distillation for Socially-Aware Robot Navigation in Dynamic Environments | 2025 | 📄 Paper | - | - |
| Navigation World Models | 2024 | 📄 Paper | 🌍 Website | - |
4.3.3. Human-robot Interaction
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| MUTEX: Learning Unified Policies from Multimodal Task Specifications | 2023 | 📄 Paper | 🌍 Website | - |
| LaMI: Large Language Models for Multi-Modal Human-Robot Interaction | 2024 | 📄 Paper | 🌍 Website | - |
| VLM-Social-Nav: Socially Aware Robot Navigation through Scoring using Vision-Language Models | 2024 | 📄 Paper | - | - |
4.3.4. Autonomous Driving
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Qwen-Drive-1.0 (Alibaba): first VL foundation model for autonomous driving — pretrained VLM backbone + BEV perception head + Planning Expert | 08/31/2026 | 📄 Paper | - | 💾 Code |
| SimWAM: Simple World-Action Model for End-to-End Autonomous Driving — 91.5 PDMS NAVSIM, zero-shot to nuScenes | 08/07/2026 | 📄 Paper | - | 💾 Code |
| RT-VLA: Real-Time VLA via Knowledge Distillation (44.8× faster inference) | 06/12/2026 | 📄 Paper | - | - |
| Fast-dDrive: Efficient Block-Diffusion VLM for Autonomous Driving (12× throughput, 0.32m L2 nuScenes) | 05/22/2026 | 📄 Paper | - | - |
| CLOVER: Closed-Loop Value Estimation & Ranking for E2E Driving Planning (94.5 PDMS NAVSIM SoTA) | 05/14/2026 | 📄 Paper | - | - |
| CoWorld-VLA: Thinking in a Multi-Expert World Model for Autonomous Driving | 05/11/2026 | 📄 Paper | - | - |
| MindVLA-U1: Unified Streaming VLA for Autonomous Driving (surpasses human-level driving) | 05/12/2026 | 📄 Paper | - | - |
| VLADriver-RAG: Retrieval-Augmented VLA for Autonomous Driving | 05/08/2026 | 📄 Paper | - | - |
| OneDrive: Unified Heterogeneous Decoding for Driving VLMs | 04/2026 | 📄 Paper | - | - |
| UniDriveVLA: Unifying Understanding, Perception, and Action Planning for Autonomous Driving | 04/2026 | 📄 Paper | - | - |
| AutoMoT: A Unified Vision-Language-Action Model with Asynchronous Mixture-of-Transformers for End-to-End Autonomous Driving | 03/2026 | 📄 Paper | - | - |
| DriveVLM-RL: Neuroscience-Inspired Reinforcement Learning with Vision-Language Models for Safe Autonomous Driving | 03/2026 | 📄 Paper | - | - |
| HiST-VLA: A Hierarchical Spatio-Temporal Vision-Language-Action Model for End-to-End Autonomous Driving | 02/2026 | 📄 Paper | - | - |
| OpenDriveVLA: Towards End-to-end Autonomous Driving with Large Vision Language Action Model | 03/2025 | 📄 Paper | - | - |
| Are VLMs Ready for Autonomous Driving? An Empirical Study from the Reliability, Data, and Metric Perspectives | 01/07/2025 | 📄 Paper | 🌍 Website | - |
| DriveVLM: The Convergence of Autonomous Driving and Large Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| GPT-Driver: Learning to Drive with GPT | 2023 | 📄 Paper | - | - |
| LanguageMPC: Large Language Models as Decision Makers for Autonomous Driving | 2023 | 📄 Paper | 🌍 Website | - |
| Driving with LLMs: Fusing Object-Level Vector Modality for Explainable Autonomous Driving | 2023 | 📄 Paper | - | - |
| Referring Multi-Object Tracking | 2023 | 📄 Paper | - | 💾 Code |
| VLPD: Context-Aware Pedestrian Detection via Vision-Language Semantic Self-Supervision | 2023 | 📄 Paper | - | 💾 Code |
| MotionLM: Multi-Agent Motion Forecasting as Language Modeling | 2023 | 📄 Paper | - | - |
| DiLu: A Knowledge-Driven Approach to Autonomous Driving with Large Language Models | 2023 | 📄 Paper | 🌍 Website | - |
| VLP: Vision Language Planning for Autonomous Driving | 2024 | 📄 Paper | - | - |
| DriveGPT4: Interpretable End-to-end Autonomous Driving via Large Language Model | 2023 | 📄 Paper | - | - |
4.4. Human-Centered AI
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| DLF: Disentangled-Language-Focused Multimodal Sentiment Analysis | 2024 | 📄 Paper | - | 💾 Code |
| LIT: Large Language Model Driven Intention Tracking for Proactive Human-Robot Collaboration – A Robot Sous-Chef Application | 2024 | 📄 Paper | - | - |
| Pretrained Language Models as Visual Planners for Human Assistance | 2023 | 📄 Paper | - | - |
| Promoting AI Equity in Science: Generalized Domain Prompt Learning for Accessible VLM Research | 2024 | 📄 Paper | - | - |
| Image and Data Mining in Reticular Chemistry Using GPT-4V | 2023 | 📄 Paper | - | - |
4.4.1. Web Agent
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Video-DeepResearch: Towards the Next-Generation Multimodal Deepresearch Agent | 08/05/2026 | 📄 Paper | - | - |
| StateAct: Program State, before Pixels, for Long-Horizon Computer-Use Agents | 07/24/2026 | 📄 Paper | - | - |
| A Real-World WebAgent with Planning, Long Context Understanding, and Program Synthesis | 2023 | 📄 Paper | - | - |
| CogAgent: A Visual Language Model for GUI Agents | 2023 | 📄 Paper | - | 💾 Code |
| WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models | 2024 | 📄 Paper | - | 💾 Code |
| ShowUI: One Vision-Language-Action Model for GUI Visual Agent | 2024 | 📄 Paper | - | 💾 Code |
| ScreenAgent: A Vision Language Model-driven Computer Control Agent | 2024 | 📄 Paper | - | 💾 Code |
| Web Agents with World Models: Learning and Leveraging Environment Dynamics in Web Navigation | 2024 | 📄 Paper | - | 💾 Code |
| VisCritic: Visual State Comparison as Process Reward for GUI Agents | 06/23/2026 | 📄 Paper | - | - |
| LiteGUI: Distilling Compact GUI Agents with Reinforcement Learning (SFT-free, 2B/3B) | 05/08/2026 | 📄 Paper | - | - |
| LAMO: Scalable Lightweight GUI Agents via Multi-Role Orchestration | 04/2026 | 📄 Paper | - | - |
| ScreenExplorer: Autonomous GUI Exploration via Curiosity-Driven VLM Agents | 2026 (ICLR) | 📄 Paper | - | - |
| InfiGUIAgent: Generalist GUI Agent with Native Reasoning and Reflection | 2026 (EACL) | 📄 Paper | - | - |
| MolmoWeb: Open Visual Web Agent and Open Data for the Open Web | 04/2026 | 📄 Paper | 🌍 Website | 💾 Code |
4.4.2. Accessibility
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| X-World: Accessibility, Vision, and Autonomy Meet | 2021 | 📄 Paper | - | - |
| Context-Aware Image Descriptions for Web Accessibility | 2024 | 📄 Paper | - | - |
| Improving VR Accessibility Through Automatic 360 Scene Description Using Multimodal Large Language Models | 2024 | 📄 Paper | - | - |
4.4.3. Healthcare
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| RESPClinBench: Multimodal Clinical Decision-Making and Longitudinal Disease Tracking | 08/07/2026 | 📄 Paper | - | - |
| IMCBench: Multimodal LLMs in Image-grounded Medical Conversations (safety drops on malignant/rare conditions) | 06/26/2026 | 📄 Paper | - | - |
| HalluCXR: Benchmarking & Mitigating Hallucinations in Medical VLMs for Chest Radiographs (61.9–82.3% outputs hallucinate) | 05/19/2026 | 📄 Paper | - | - |
| Medical Thinking with Multiple Images (MedThinkVQA) | 04/2026 | 📄 Paper | - | - |
| MedVRAG: Iterative Multimodal RAG for Medical QA | 04/2026 | 📄 Paper | - | - |
| GMAI-VL: General Medical AI Vision-Language Model | 2026 (AAAI) | 📄 Paper | - | - |
| CARE: Towards Clinical Accountability in Multi-Modal Medical Reasoning with an Evidence-Grounded Agentic Framework | 03/2026 | 📄 Paper | - | - |
| MedMO: Grounding and Understanding Multimodal Large Language Model for Medical Images | 02/2026 | 📄 Paper | - | - |
| Colon-X: Advancing Intelligent Colonoscopy from Multimodal Understanding to Clinical Reasoning | 12/2025 | 📄 Paper | - | 💾 Code |
| Frontiers in Intelligent Colonoscopy | 02/2025 | 📄 Paper | - | 💾 Code |
| VisionUnite: A Vision-Language Foundation Model for Ophthalmology Enhanced with Clinical Knowledge | 2024 | 📄 Paper | - | 💾 Code |
| Multimodal Healthcare AI: Identifying and Designing Clinically Relevant Vision-Language Applications for Radiology | 2024 | 📄 Paper | - | - |
| M-FLAG: Medical Vision-Language Pre-training with Frozen Language Models and Latent Space Geometry Optimization | 2023 | 📄 Paper | - | - |
| MedCLIP: Contrastive Learning from Unpaired Medical Images and Text | 2022 | 📄 Paper | - | 💾 Code |
| Med-Flamingo: A Multimodal Medical Few-Shot Learner | 2023 | 📄 Paper | - | 💾 Code |
4.4.4. Social Goodness
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Analyzing K-12 AI Education: A Large Language Model Study of Classroom Instruction on Learning Theories, Pedagogy, Tools, and AI Literacy | 2024 | 📄 Paper | - | - |
| Students Rather Than Experts: A New AI for Education Pipeline to Model More Human-Like and Personalized Early Adolescence | 2024 | 📄 Paper | - | - |
| Harnessing Large Vision and Language Models in Agriculture: A Review | 2024 | 📄 Paper | - | - |
| A Vision-Language Model for Predicting Potential Distribution Land of Soybean Double Cropping | 2024 | 📄 Paper | - | - |
| Vision-Language Model is NOT All You Need: Augmentation Strategies for Molecule Language Models | 2024 | 📄 Paper | - | 💾 Code |
| DrawEduMath: Evaluating Vision Language Models with Expert-Annotated Students’ Hand-Drawn Math Images | 2024 | 📄 Paper | - | - |
| MultiMath: Bridging Visual and Mathematical Reasoning for Large Language Models | 2024 | 📄 Paper | - | 💾 Code |
| Vision-Language Models Meet Meteorology: Developing Models for Extreme Weather Events Detection with Heatmaps | 2024 | 📄 Paper | - | 💾 Code |
| He is Very Intelligent, She is Very Beautiful? On Mitigating Social Biases in Language Modeling and Generation | 2021 | 📄 Paper | - | - |
| UrbanVLP: Multi-Granularity Vision-Language Pretraining for Urban Region Profiling | 2024 | 📄 Paper | - | - |
5. Challenges
5.1 Hallucination
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| TruthLens: Object Hallucination Detection via Self-Evaluating Truthfulness Scores in LVLMs | 08/07/2026 | 📄 Paper | - | - |
| MVI-Bench: A Comprehensive Benchmark for Evaluating Robustness to Misleading Visual Inputs in LVLMs | 11/2025 | 📄 Paper | 🌍 ICML 2026 | 💾 Code |
| VL-Calibration: Decoupled Confidence Calibration for VLM Reasoning | 04/2026 | 📄 Paper | - | - |
| Focus Matters: Phase-Aware Suppression for Hallucination in Vision-Language Models | 04/2026 | 📄 Paper | - | - |
| VLMs Need Words: Vision Language Models Ignore Visual Detail in Favor of Semantic Anchors | 04/2026 | 📄 Paper | - | - |
| HALP: Detecting Hallucinations in Vision-Language Models without Generating a Single Token | 03/2026 | 📄 Paper | 🌍 ACL | - |
| Tone Matters: The Impact of Linguistic Tone on Hallucination in VLMs | 01/2026 | 📄 Paper | - | - |
| Object Hallucination in Image Captioning | 2018 | 📄 Paper | - | - |
| Evaluating Object Hallucination in Large Vision-Language Models | 2023 | 📄 Paper | - | 💾 Code |
| Detecting and Preventing Hallucinations in Large Vision Language Models | 2023 | 📄 Paper | - | - |
| HallE-Control: Controlling Object Hallucination in Large Multimodal Models | 2023 | 📄 Paper | - | 💾 Code |
| Hallu-PI: Evaluating Hallucination in Multi-modal Large Language Models within Perturbed Inputs | 2024 | 📄 Paper | - | 💾 Code |
| BEAF: Observing BEfore-AFter Changes to Evaluate Hallucination in Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| HallusionBench: An Advanced Diagnostic Suite for Entangled Language Hallucination and Visual Illusion in Large Vision-Language Models | 2023 | 📄 Paper | - | 💾 Code |
| AUTOHALLUSION: Automatic Generation of Hallucination Benchmarks for Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| Mitigating Hallucination in Large Multi-Modal Models via Robust Instruction Tuning | 2023 | 📄 Paper | - | 💾 Code |
| Hal-Eval: A Universal and Fine-grained Hallucination Evaluation Framework for Large Vision Language Models | 2024 | 📄 Paper | - | 💾 Code |
| AMBER: An LLM-free Multi-dimensional Benchmark for MLLMs Hallucination Evaluation | 2023 | 📄 Paper | - | 💾 Code |
5.2 Safety
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| SaFeR-VLM: Safety into Multimodal Reasoning via Reinforcement Learning | 2026 (ICLR) | 📄 Paper | - | - |
| HoliSafe: Holistic Safety Evaluation for Vision-Language Models | 2026 (ICLR) | 📄 Paper | - | - |
| JailbreakZoo: Survey, Landscapes, and Horizons in Jailbreaking Large Language and Vision-Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| Safe-VLN: Collision Avoidance for Vision-and-Language Navigation of Autonomous Robots Operating in Continuous Environments | 2023 | 📄 Paper | - | - |
| SafeBench: A Safety Evaluation Framework for Multimodal Large Language Models | 2024 | 📄 Paper | - | - |
| JailBreakV: A Benchmark for Assessing the Robustness of MultiModal Large Language Models against Jailbreak Attacks | 2024 | 📄 Paper | - | - |
| SHIELD: An Evaluation Benchmark for Face Spoofing and Forgery Detection with Multimodal Large Language Models | 2024 | 📄 Paper | - | 💾 Code |
| Images are Achilles' Heel of Alignment: Exploiting Visual Vulnerabilities for Jailbreaking Multimodal Large Language Models | 2024 | 📄 Paper | - | - |
| Jailbreaking Attack against Multimodal Large Language Model | 2024 | 📄 Paper | - | - |
| Embodied Red Teaming for Auditing Robotic Foundation Models | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| Safety Guardrails for LLM-Enabled Robots | 2025 | 📄 Paper | - | - |
5.3 Fairness
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Hallucination of Multimodal Large Language Models: A Survey | 2024 | 📄 Paper | - | - |
| Bias and Fairness in Large Language Models: A Survey | 2023 | 📄 Paper | - | - |
| Fairness and Bias in Multimodal AI: A Survey | 2024 | 📄 Paper | - | - |
| Multi-Modal Bias: Introducing a Framework for Stereotypical Bias Assessment beyond Gender and Race in Vision–Language Models | 2023 | 📄 Paper | - | - |
| FMBench: Benchmarking Fairness in Multimodal Large Language Models on Medical Tasks | 2024 | 📄 Paper | - | - |
| FairCLIP: Harnessing Fairness in Vision-Language Learning | 2024 | 📄 Paper | - | - |
| FairMedFM: Fairness Benchmarking for Medical Imaging Foundation Models | 2024 | 📄 Paper | - | - |
| Benchmarking Vision Language Models for Cultural Understanding | 2024 | 📄 Paper | - | - |
5.4 Alignment
5.4.1 Multi-modality Alignment
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| Mitigating Hallucinations in Large Vision-Language Models with Instruction Contrastive Decoding | 2024 | 📄 Paper | - | - |
| Enhancing Visual-Language Modality Alignment in Large Vision Language Models via Self-Improvement | 2024 | 📄 Paper | - | - |
| Assessing and Learning Alignment of Unimodal Vision and Language Models | 2024 | 📄 Paper | 🌍 Website | - |
| Extending Multi-modal Contrastive Representations | 2023 | 📄 Paper | - | 💾 Code |
| OneLLM: One Framework to Align All Modalities with Language | 2023 | 📄 Paper | - | 💾 Code |
| What You See is What You Read? Improving Text-Image Alignment Evaluation | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
| Critic-V: VLM Critics Help Catch VLM Errors in Multimodal Reasoning | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
5.4.2 Commonsense and Physics Alignment
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| VBench: Comprehensive BenchmarkSuite for Video Generative Models | 2023 | 📄 Paper | 🌍 Website | 💾 Code |
| VBench++: Comprehensive and Versatile Benchmark Suite for Video Generative Models | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| PhysBench: Benchmarking and Enhancing VLMs for Physical World Understanding | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| VideoPhy: Evaluating Physical Commonsense for Video Generation | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| WorldSimBench: Towards Video Generation Models as World Simulators | 2024 | 📄 Paper | 🌍 Website | - |
| WorldModelBench: Judging Video Generation Models As World Models | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| VideoScore: Building Automatic Metrics to Simulate Fine-grained Human Feedback for Video Generation | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| WISE: A World Knowledge-Informed Semantic Evaluation for Text-to-Image Generation | 2025 | 📄 Paper | - | 💾 Code |
| Content-Rich AIGC Video Quality Assessment via Intricate Text Alignment and Motion-Aware Consistency | 2025 | 📄 Paper | - | 💾 Code |
| Your Large Vision-Language Model Only Needs A Few Attention Heads For Visual Grounding | 2025 | 📄 Paper | - | - |
| SpatialVLM: Endowing Vision-Language Models with Spatial Reasoning Capabilities | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| Do generative video models understand physical principles? | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
| PhysGen: Rigid-Body Physics-Grounded Image-to-Video Generation | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| How Far is Video Generation from World Model: A Physical Law Perspective | 2024 | 📄 Paper | 🌍 Website | 💾 Code |
| Imagine while Reasoning in Space: Multimodal Visualization-of-Thought | 2025 | 📄 Paper | - | - |
| VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness | 2025 | 📄 Paper | 🌍 Website | 💾 Code |
5.5 Efficient Training and Fine-Tuning
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| OmniPack: Unified Token Compression for Efficient Omni-modal Large Language Models | 08/05/2026 | 📄 Paper | - | - |
| GSTEP: Global Spatio-Temporal Density-Driven Visual Token Pruning for Efficient Video LLMs | 08/05/2026 | 📄 Paper | - | - |
| FastOCR: Dynamic Visual Fixation via KV Cache Pruning (98% accuracy at 5% visual tokens, 3.0× faster) | 05/17/2026 | 📄 Paper | - | - |
| WindowQuant: Mixed-Precision KV Cache Quantization via Window-Level Similarity | 05/04/2026 | 📄 Paper | - | - |
| MODIX: Training-Free Multimodal Information-Driven Positional Index Scaling | 04/2026 | 📄 Paper | - | - |
| QAPruner: Quantization-Aware Vision Token Pruning for MLLMs | 04/2026 | 📄 Paper | - | - |
| Firebolt-VL: Efficient Vision-Language Understanding with Cross-Modality Modulation | 04/2026 | 📄 Paper | - | - |
| CoME-VL: Scaling Complementary Multi-Encoder Vision-Language Learning | 04/2026 | 📄 Paper | - | - |
| LoRA-Squeeze: Simple and Effective Post-Tuning and In-Tuning Compression of LoRA Modules | 02/2026 | 📄 Paper | - | - |
| GRACE: Gated Relational Alignment via Confidence-based Distillation for Efficient VLMs | 01/2026 | 📄 Paper | - | - |
| VLMQ: Post-Training Quantization for Large Vision-Language Models | 2026 (ICLR) | 📄 Paper | - | - |
| VILA: On Pre-training for Visual Language Models | 2023 | 📄 Paper | - | - |
| SimVLM: Simple Visual Language Model Pretraining with Weak Supervision | 2021 | 📄 Paper | - | - |
| LoRA: Low-Rank Adaptation of Large Language Models | 2021 | 📄 Paper | - | 💾 Code |
| QLoRA: Efficient Finetuning of Quantized LLMs | 2023 | 📄 Paper | - | - |
| Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback | 2022 | 📄 Paper | - | 💾 Code |
| RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback | 2023 | 📄 Paper | - | - |
5.6 Scarce of High-quality Dataset
| Title | Year | Paper | Website | Code |
|---|---|---|---|---|
| A Prescription for Better VLMs through Data Curation Alone (20/20 Vision) | 05/2026 | 📄 Paper | - | - |
| A Survey on Bridging VLMs and Synthetic Data | 2025 | 📄 Paper | - | 💾 Code |
| Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning | 2024 | 📄 Paper | Website | 💾 Code |
| SLIP: Self-supervision meets Language-Image Pre-training | 2021 | 📄 Paper | - | 💾 Code |
| Synthetic Vision: Training Vision-Language Models to Understand Physics | 2024 | 📄 Paper | - | - |
| Synth2: Boosting Visual-Language Models with Synthetic Captions and Image Embeddings | 2024 | 📄 Paper | - | - |
| KALIE: Fine-Tuning Vision-Language Models for Open-World Manipulation without Robot Data | 2024 | 📄 Paper | - | - |
| Web Agents with World Models: Learning and Leveraging Environment Dynamics in Web Navigation | 2024 | 📄 Paper | - | - |
Similar repos
Contributors
Languages
HTML
88.4%
Python
11.6%