
README
Awesome Unified Multimodal Models
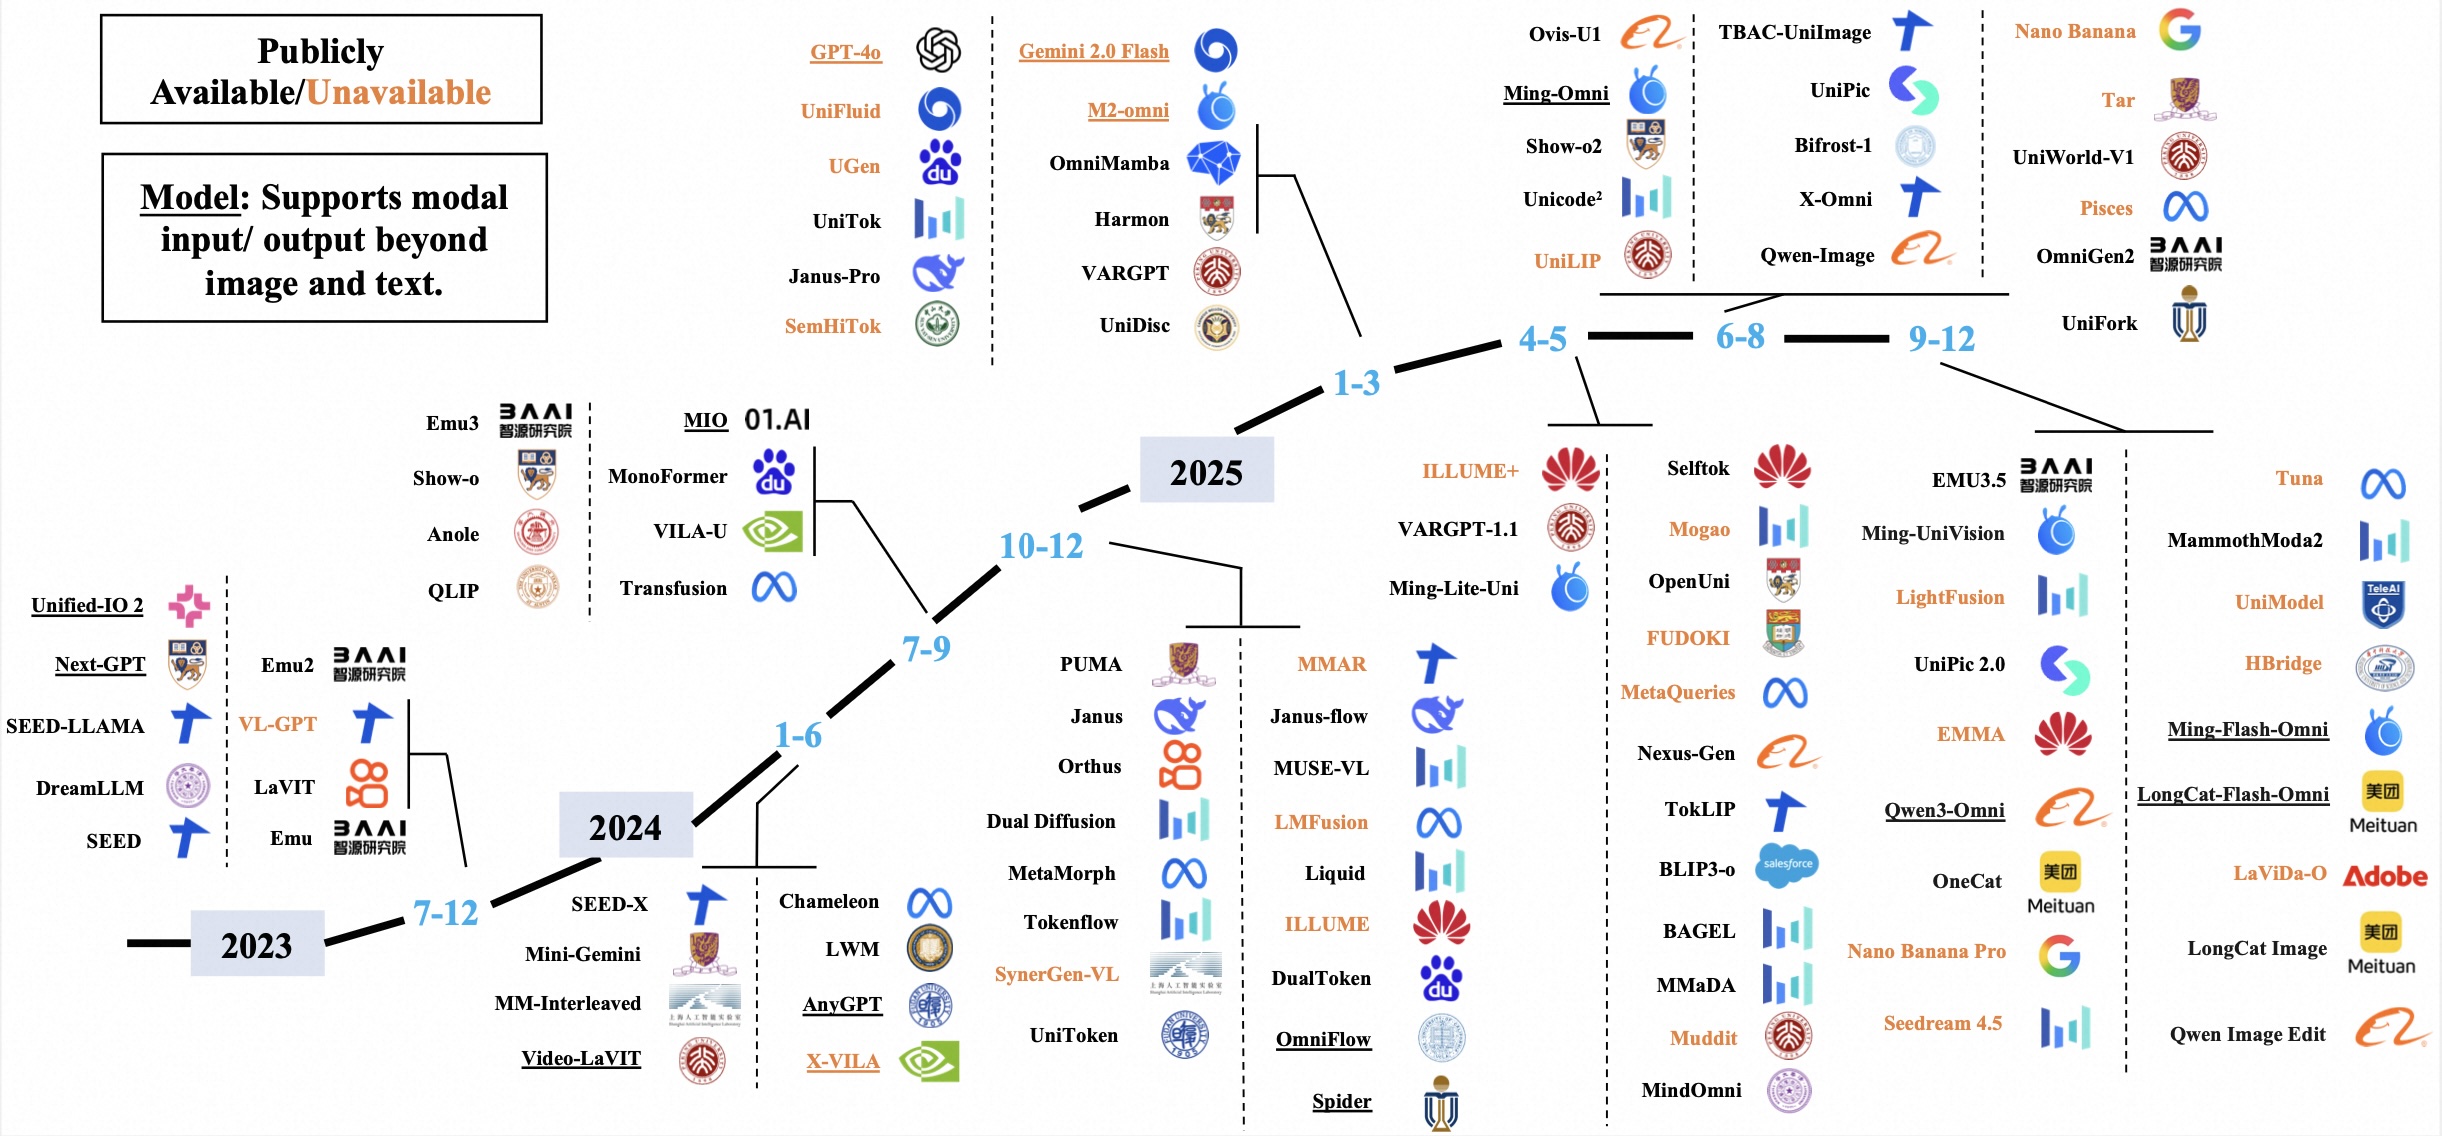
Figure 1: Timeline of Publicly Available and Unavailable Unified Multimodal Models. The models are categorized by their release years, from 2023 to 2025. Models underlined in the diagram represent any-to-any multimodal models, capable of handling inputs or outputs beyond text and image, such as audio, video, and speech. The timeline highlights the rapid growth in this field.
🔥 We are hiring!
We are looking for both interns and full-time researchers to join our team, focusing on multimodal understanding, generation, reasoning, AI agents, and unified multimodal models. If you are interested in exploring these exciting areas, please reach out to us at qingguo.cqg@alibaba-inc.com.
👉 What is This Repo for?
This repository provides a comprehensive collection of resources related to unified multimodal models, featuring:
- A survey of advances, challenges, and timelines for unified models
- Categorized lists of diffusion-based, autoregressive (MLLM), and hybrid architectures for unified image–text understanding and generation
- Benchmarks for evaluating multimodal comprehension, image generation, and interleaved image–text tasks
- Representative datasets covering multimodal understanding, text-to-image synthesis, image editing, and interleaved interactions
Designed to help researchers and practitioners explore, compare, and build state-of-the-art unified multimodal systems.
Awesome Papers & Datasets
- Text-and-Image Unified Models
- Any-to-Any Multimodal models
- Benchmark for Evaluation
- Dataset
- Applications and Opportunities
Text-and-Image Unified Models
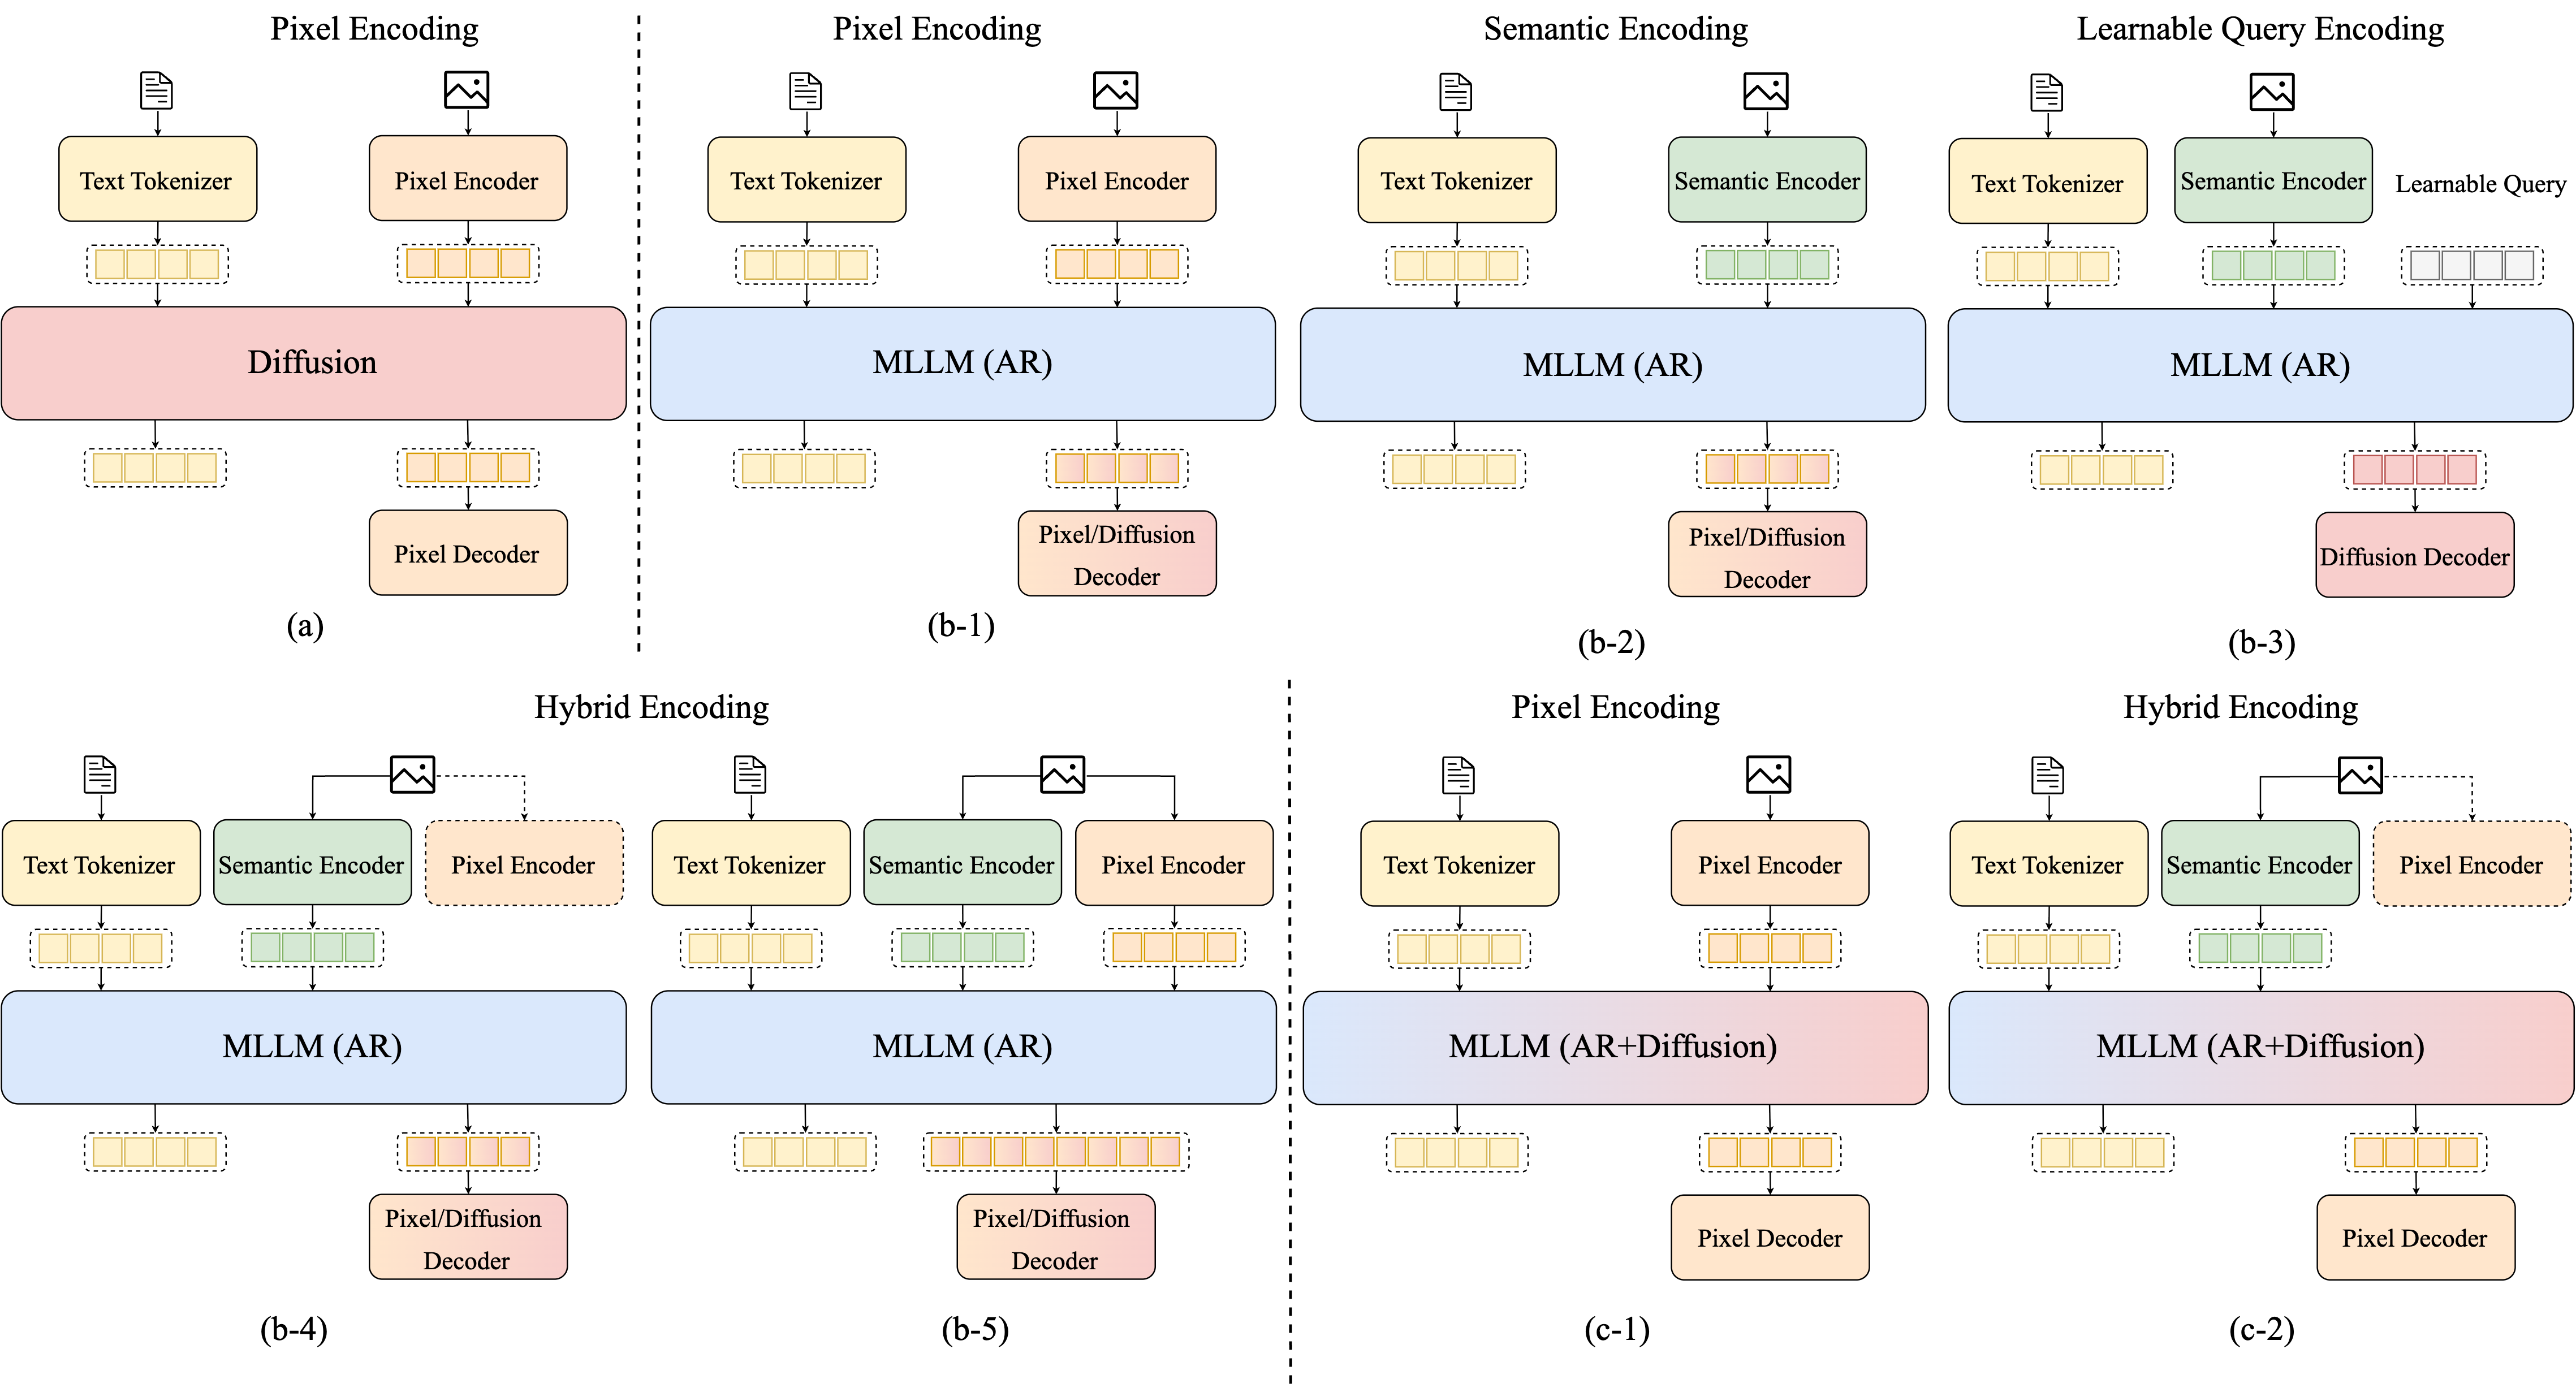
Figure 2: Classification of Unified Multimodal Understanding and Generation Models. The models are divided into three main categories based on their backbone architecture: Diffusion, MLLM (AR), and MLLM (AR + Diffusion). Each category is further subdivided according to the encoding strategy employed, including Pixel Encoding, Semantic Encoding, Learnable Query Encoding, and Hybrid Encoding. We illustrate the architectural variations within these categories and their corresponding encoder-decoder configurations.
Diffusion
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| UniModel | UniModel: A Visual-Only Framework for Unified Multimodal Understanding and Generation | arXiv | 2025/11/21 | - | - |
| Lavida-O | Lavida-O: Elastic Large Masked Diffusion Models for Unified Multimodal Understanding and Generation  | arXiv | 2025/09/24 | Github | - |
| Muddit | Muddit: Liberating Generation Beyond Text-to-Image with a Unified Discrete Diffusion Model  | arXiv | 2025/05/23 | Github | - |
| FUDOKI | FUDOKI: Discrete Flow-based Unified Understanding and Generation via Kinetic-Optimal Velocities | arXiv | 2025/05/20 | - | - |
| MMaDA | MMaDA: Multimodal Large Diffusion Language Models  | arXiv | 2025/05/21 | Github | Demo |
| UniDisc | Unified Multimodal Discrete Diffusion  | arXiv | 2025/03/20 | Github | - |
| Dual Diffusion | Dual Diffusion for Unified Image Generation and Understanding  | arXiv | 2024/12/31 | Github | - |
MLLM AR
b-1: Pixel Encoding


b-2: Semantic Encoding


b-3: Learnable Query Encoding


b-4: Hybrid Encoding (Pseduo)
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| Skywork UniPic | Skywork UniPic: Unified Autoregressive Modeling for Visual Understanding and Generation  | arXiv | 2025/08/05 | Github | Demo |
| MindOmni | MindOmni: Unleashing Reasoning Generation in Vision Language Models with RGPO  | arXiv | 2025/05/13 | Github | Demo |
| UniFluid | Unified Autoregressive Visual Generation and Understanding with Continuous Tokens | arXiv | 2025/03/17 | - | - |
| OmniMamba | OmniMamba: Efficient and Unified Multimodal Understanding and Generation via State Space Models  | arXiv | 2025/03/11 | Github | - |
| Janus-Pro | Janus-Pro: Unified Multimodal Understanding and Generation with Data and Model Scaling  | arXiv | 2025/01/29 | Github | Demo |
| Janus | Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation | arXiv | 2024/10/17 | Github | Demo |
b-5: Hybrid Encoding (Joint)
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| Show-o2 | Show-o2: Improved Native Unified Multimodal Models  | arXiv | 2025/06/15 | Github | - |
| UniToken | UniToken: Harmonizing Multimodal Understanding and Generation through Unified Visual Encoding  | CVPRW | 2025/04/06 | Github | - |
| VARGPT-v1.1 | VARGPT-v1.1: Improve Visual Autoregressive Large Unified Model via Iterative Instruction Tuning and Reinforcement Learning  | arXiv | 2025/04/03 | Github | - |
| ILLUME+ | ILLUME+: Illuminating Unified MLLM with Dual Visual Tokenization and Diffusion Refinement  | arXiv | 2025/04/02 | Github | - |
| SemHiTok | SemHiTok: A Unified Image Tokenizer via Semantic-Guided Hierarchical Codebook for Multimodal Understanding and Generation | arXiv | 2025/03/06 | - | - |
| VARGPT | VARGPT: Unified Understanding and Generation in a Visual Autoregressive Multimodal Large Language Model  | arXiv | 2025/01/21 | Github | - |
| TokenFlow | TokenFlow: Unified Image Tokenizer for Multimodal Understanding and Generation  | CVPR | 2024/12/04 | Github | - |
| MUSE-VL | MUSE-VL: Modeling Unified VLM through Semantic Discrete Encoding | arXiv | 2024/11/26 | - | - |
MLLM AR-Diffusion
c-1: Pxiel Encoding
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| TUNA | Tuna: Taming Unified Visual Representations for Native Unified Multimodal Models  | arXiv | 2025/12/01 | Github | - |
| LMFusion | LMFusion: Adapting Pretrained Language Models for Multimodal Generation | arXiv | 2024/12/19 | - | - |
| MonoFormer | MonoFormer: One Transformer for Both Diffusion and Autoregression  | arXiv | 2024/09/24 | Github | - |
| Show-o | Show-o: One Single Transformer to Unify Multimodal Understanding and Generation | ICLR | 2024/08/22 | Github | Demo |
| Transfusion | Transfusion: Predict the Next Token and Diffuse Images with One Multi-Modal Model  | ICLR | 2024/08/20 | Github | - |
c-2: Hybrid Encoding (Pseduo)
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| EMMA | EMMA: Efficient Multimodal Understanding, Generation, and Editing with a Unified Architecture  | arXiv | 2025/12/15 | Github | - |
| HBridge | HBridge: H-Shape Bridging of Heterogeneous Experts for Unified Multimodal Understanding and Generation | arXiv | 2025/11/25 | - | - |
| LightFusion | LightFusion: A Light-weighted, Double Fusion Framework for Unified Multimodal Understanding and Generation  | arXiv | 2025/10/27 | Github | - |
| BAGEL | Emerging Properties in Unified Multimodal Pretraining  | arXiv | 2025/05/20 | Github | Demo |
| Mogao | Mogao: An Omni Foundation Model for Interleaved Multi-Modal Generation | arXiv | 2025/05/08 | - | - |
| JanusFlow | JanusFlow: Harmonizing Autoregression and Rectified Flow for Unified Multimodal Understanding and Generation | arXiv | 2024/11/12 | Github | Demo |
Any-to-Any Multimodal models


Benchmark for Evaluation
Benchmarks on Understanding Tasks


Benchmarks on Image Generation Tasks


Benchmarks on Interleaved / Compositional / Other Tasks
| Name | Paper | Venue | Date | Code |
|---|---|---|---|---|
| VTBench | VTBench: Evaluating Visual Tokenizers for Autoregressive Image Generation  | arXiv | 2025/05/19 | Github |
| UniBench | UniEval: Unified Holistic Evaluation for Unified Multimodal Understanding and Generation  | arXiv | 2025/05/15 | Github |
| OpenING | OpenING: A Comprehensive Benchmark for Judging Open-ended Interleaved Image-Text Generation  | CVPR | 2024/11/27 | Github |
| ISG | Interleaved Scene Graphs for Interleaved Text-and-Image Generation Assessment  | ICLR | 2024/11/26 | Github |
| MMIE | MMIE: Massive Multimodal Interleaved Comprehension Benchmark for Large Vision-Language Models  | ICLR | 2024/10/14 | Github |
| InterleavedBench | Holistic Evaluation for Interleaved Text-and-Image Generation | EMNLP | 2024/06/20 | HuggingFace |
| OpenLEAF | OpenLEAF: Open-Domain Interleaved Image-Text Generation and Evaluation | MM | 2023/10/01 | - |
Dataset
Multimodal Understanding
Text-to-Image
Image Editing
Interleaved Image-Text
| Dataset | Samples | Paper | Venue | Date |
|---|---|---|---|---|
| OmniCorpus | 8B | OmniCorpus: A Unified Multimodal Corpus of 10 Billion-Level Images Interleaved with Text | ICLR | 2024/10/22 |
| CoMM | 227K | Comm: A coherent interleaved image-text dataset for multimodal understanding and generation | CVPR | 2024/06/15 |
| OBELICS | 141M | Obelics: An open web-scale filtered dataset of interleaved image-text documents | NeurIPS | 2023/06/21 |
| Multimodal C4 | 101.2M | Multimodal c4: An open, billion-scale corpus of images interleaved with text | NeurIPS | 2023/04/14 |
Other Text-Image-to-Image
| Dataset | Samples | Paper | Venue | Date |
|---|---|---|---|---|
| Echo-4o-Image | 73K | Echo-4o: Harnessing the Power of GPT-4o Synthetic Images for Improved Image Generation | arXiv | 2025/08/13 |
| MetaQuery Instruct 2.4M | 2.4M | Transfer between Modalities with MetaQueries | arXiv | 2025/06/24 |
| Graph200K | 200K | VisualCloze: A Universal Image Generation Framework via Visual In-Context Learning | arXiv | 2025/03/30 |
| SynCD | 95K | Generating multi-image synthetic data for text-to-image customization | arXiv | 2025/02/03 |
| X2I-subject-driven | 2.5M | OmniGen: Unified Image Generation | arXiv | 2024/12/14 |
| Subjects200K | 200K | Ominicontrol: Minimal and universal control for diffusion transformer | arXiv | 2024/11/22 |
| MultiGen-20M | 20M | Unicontrol: A unified diffusion model for controllable visual generation in the wild | NeurIPS | 2023/05/18 |
| LAION-Face | 50M | General facial representation learning in a visual-linguistic manner | CVPR | 2021/12/06 |
Applications and Opportunities
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| UniGame | UniGame: Turning a Unified Multimodal Model Into Its Own Adversary  | arXiv | 2025/11/24 | Github | - |
| UniCTokens | UniCTokens: Boosting Personalized Understanding and Generation via Unified Concept Tokens  | arXiv | 2025/05/20 | Github | - |
| Fair-UMLLM | On Fairness of Unified Multimodal Large Language Model for Image Generation | arXiv | 2025/02/05 | - | - |
| T2I-R1 | T2I-R1: Reinforcing Image Generation with Collaborative Semantic-level and Token-level CoT  | arXiv | 2025/01/29 | Github | - |
Citation
If you find this repo is helpful for your research, please cite our paper:
@article{zhang2025unified,
  title={Unified Multimodal Understanding and Generation Models: Advances, Challenges, and Opportunities},
  author={Zhang, Xinjie and Guo, Jintao and Zhao, Shanshan and Fu, Minghao and Duan, Lunhao and Hu, Jiakui and Chng, Yong Xien and Wang, Guo-Hua and Chen, Qing-Guo and Xu, Zhao and Luo, Weihua and Zhang, Kaifu},
  journal={arXiv preprint arXiv:2505.02567},
  year={2025}
}
Contributors


Similar repos


README
Awesome Unified Multimodal Models
Figure 1: Timeline of Publicly Available and Unavailable Unified Multimodal Models. The models are categorized by their release years, from 2023 to 2025. Models underlined in the diagram represent any-to-any multimodal models, capable of handling inputs or outputs beyond text and image, such as audio, video, and speech. The timeline highlights the rapid growth in this field.
🔥 We are hiring!
We are looking for both interns and full-time researchers to join our team, focusing on multimodal understanding, generation, reasoning, AI agents, and unified multimodal models. If you are interested in exploring these exciting areas, please reach out to us at qingguo.cqg@alibaba-inc.com.
👉 What is This Repo for?
This repository provides a comprehensive collection of resources related to unified multimodal models, featuring:
- A survey of advances, challenges, and timelines for unified models
- Categorized lists of diffusion-based, autoregressive (MLLM), and hybrid architectures for unified image–text understanding and generation
- Benchmarks for evaluating multimodal comprehension, image generation, and interleaved image–text tasks
- Representative datasets covering multimodal understanding, text-to-image synthesis, image editing, and interleaved interactions
Designed to help researchers and practitioners explore, compare, and build state-of-the-art unified multimodal systems.
Awesome Papers & Datasets
- Text-and-Image Unified Models
- Any-to-Any Multimodal models
- Benchmark for Evaluation
- Dataset
- Applications and Opportunities
Text-and-Image Unified Models
Figure 2: Classification of Unified Multimodal Understanding and Generation Models. The models are divided into three main categories based on their backbone architecture: Diffusion, MLLM (AR), and MLLM (AR + Diffusion). Each category is further subdivided according to the encoding strategy employed, including Pixel Encoding, Semantic Encoding, Learnable Query Encoding, and Hybrid Encoding. We illustrate the architectural variations within these categories and their corresponding encoder-decoder configurations.
Diffusion
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| UniModel | UniModel: A Visual-Only Framework for Unified Multimodal Understanding and Generation | arXiv | 2025/11/21 | - | - |
| Lavida-O | Lavida-O: Elastic Large Masked Diffusion Models for Unified Multimodal Understanding and Generation | arXiv | 2025/09/24 | Github | - |
| Muddit | Muddit: Liberating Generation Beyond Text-to-Image with a Unified Discrete Diffusion Model | arXiv | 2025/05/23 | Github | - |
| FUDOKI | FUDOKI: Discrete Flow-based Unified Understanding and Generation via Kinetic-Optimal Velocities | arXiv | 2025/05/20 | - | - |
| MMaDA | MMaDA: Multimodal Large Diffusion Language Models | arXiv | 2025/05/21 | Github | Demo |
| UniDisc | Unified Multimodal Discrete Diffusion | arXiv | 2025/03/20 | Github | - |
| Dual Diffusion | Dual Diffusion for Unified Image Generation and Understanding | arXiv | 2024/12/31 | Github | - |
MLLM AR
b-1: Pixel Encoding
b-2: Semantic Encoding
b-3: Learnable Query Encoding
b-4: Hybrid Encoding (Pseduo)
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| Skywork UniPic | Skywork UniPic: Unified Autoregressive Modeling for Visual Understanding and Generation | arXiv | 2025/08/05 | Github | Demo |
| MindOmni | MindOmni: Unleashing Reasoning Generation in Vision Language Models with RGPO | arXiv | 2025/05/13 | Github | Demo |
| UniFluid | Unified Autoregressive Visual Generation and Understanding with Continuous Tokens | arXiv | 2025/03/17 | - | - |
| OmniMamba | OmniMamba: Efficient and Unified Multimodal Understanding and Generation via State Space Models | arXiv | 2025/03/11 | Github | - |
| Janus-Pro | Janus-Pro: Unified Multimodal Understanding and Generation with Data and Model Scaling | arXiv | 2025/01/29 | Github | Demo |
| Janus | Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation | arXiv | 2024/10/17 | Github | Demo |
b-5: Hybrid Encoding (Joint)
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| Show-o2 | Show-o2: Improved Native Unified Multimodal Models | arXiv | 2025/06/15 | Github | - |
| UniToken | UniToken: Harmonizing Multimodal Understanding and Generation through Unified Visual Encoding | CVPRW | 2025/04/06 | Github | - |
| VARGPT-v1.1 | VARGPT-v1.1: Improve Visual Autoregressive Large Unified Model via Iterative Instruction Tuning and Reinforcement Learning | arXiv | 2025/04/03 | Github | - |
| ILLUME+ | ILLUME+: Illuminating Unified MLLM with Dual Visual Tokenization and Diffusion Refinement | arXiv | 2025/04/02 | Github | - |
| SemHiTok | SemHiTok: A Unified Image Tokenizer via Semantic-Guided Hierarchical Codebook for Multimodal Understanding and Generation | arXiv | 2025/03/06 | - | - |
| VARGPT | VARGPT: Unified Understanding and Generation in a Visual Autoregressive Multimodal Large Language Model | arXiv | 2025/01/21 | Github | - |
| TokenFlow | TokenFlow: Unified Image Tokenizer for Multimodal Understanding and Generation | CVPR | 2024/12/04 | Github | - |
| MUSE-VL | MUSE-VL: Modeling Unified VLM through Semantic Discrete Encoding | arXiv | 2024/11/26 | - | - |
MLLM AR-Diffusion
c-1: Pxiel Encoding
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| TUNA | Tuna: Taming Unified Visual Representations for Native Unified Multimodal Models | arXiv | 2025/12/01 | Github | - |
| LMFusion | LMFusion: Adapting Pretrained Language Models for Multimodal Generation | arXiv | 2024/12/19 | - | - |
| MonoFormer | MonoFormer: One Transformer for Both Diffusion and Autoregression | arXiv | 2024/09/24 | Github | - |
| Show-o | Show-o: One Single Transformer to Unify Multimodal Understanding and Generation | ICLR | 2024/08/22 | Github | Demo |
| Transfusion | Transfusion: Predict the Next Token and Diffuse Images with One Multi-Modal Model | ICLR | 2024/08/20 | Github | - |
c-2: Hybrid Encoding (Pseduo)
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| EMMA | EMMA: Efficient Multimodal Understanding, Generation, and Editing with a Unified Architecture | arXiv | 2025/12/15 | Github | - |
| HBridge | HBridge: H-Shape Bridging of Heterogeneous Experts for Unified Multimodal Understanding and Generation | arXiv | 2025/11/25 | - | - |
| LightFusion | LightFusion: A Light-weighted, Double Fusion Framework for Unified Multimodal Understanding and Generation | arXiv | 2025/10/27 | Github | - |
| BAGEL | Emerging Properties in Unified Multimodal Pretraining | arXiv | 2025/05/20 | Github | Demo |
| Mogao | Mogao: An Omni Foundation Model for Interleaved Multi-Modal Generation | arXiv | 2025/05/08 | - | - |
| JanusFlow | JanusFlow: Harmonizing Autoregression and Rectified Flow for Unified Multimodal Understanding and Generation | arXiv | 2024/11/12 | Github | Demo |
Any-to-Any Multimodal models
Benchmark for Evaluation
Benchmarks on Understanding Tasks
Benchmarks on Image Generation Tasks
Benchmarks on Interleaved / Compositional / Other Tasks
| Name | Paper | Venue | Date | Code |
|---|---|---|---|---|
| VTBench | VTBench: Evaluating Visual Tokenizers for Autoregressive Image Generation | arXiv | 2025/05/19 | Github |
| UniBench | UniEval: Unified Holistic Evaluation for Unified Multimodal Understanding and Generation | arXiv | 2025/05/15 | Github |
| OpenING | OpenING: A Comprehensive Benchmark for Judging Open-ended Interleaved Image-Text Generation | CVPR | 2024/11/27 | Github |
| ISG | Interleaved Scene Graphs for Interleaved Text-and-Image Generation Assessment | ICLR | 2024/11/26 | Github |
| MMIE | MMIE: Massive Multimodal Interleaved Comprehension Benchmark for Large Vision-Language Models | ICLR | 2024/10/14 | Github |
| InterleavedBench | Holistic Evaluation for Interleaved Text-and-Image Generation | EMNLP | 2024/06/20 | HuggingFace |
| OpenLEAF | OpenLEAF: Open-Domain Interleaved Image-Text Generation and Evaluation | MM | 2023/10/01 | - |
Dataset
Multimodal Understanding
Text-to-Image
Image Editing
Interleaved Image-Text
| Dataset | Samples | Paper | Venue | Date |
|---|---|---|---|---|
| OmniCorpus | 8B | OmniCorpus: A Unified Multimodal Corpus of 10 Billion-Level Images Interleaved with Text | ICLR | 2024/10/22 |
| CoMM | 227K | Comm: A coherent interleaved image-text dataset for multimodal understanding and generation | CVPR | 2024/06/15 |
| OBELICS | 141M | Obelics: An open web-scale filtered dataset of interleaved image-text documents | NeurIPS | 2023/06/21 |
| Multimodal C4 | 101.2M | Multimodal c4: An open, billion-scale corpus of images interleaved with text | NeurIPS | 2023/04/14 |
Other Text-Image-to-Image
| Dataset | Samples | Paper | Venue | Date |
|---|---|---|---|---|
| Echo-4o-Image | 73K | Echo-4o: Harnessing the Power of GPT-4o Synthetic Images for Improved Image Generation | arXiv | 2025/08/13 |
| MetaQuery Instruct 2.4M | 2.4M | Transfer between Modalities with MetaQueries | arXiv | 2025/06/24 |
| Graph200K | 200K | VisualCloze: A Universal Image Generation Framework via Visual In-Context Learning | arXiv | 2025/03/30 |
| SynCD | 95K | Generating multi-image synthetic data for text-to-image customization | arXiv | 2025/02/03 |
| X2I-subject-driven | 2.5M | OmniGen: Unified Image Generation | arXiv | 2024/12/14 |
| Subjects200K | 200K | Ominicontrol: Minimal and universal control for diffusion transformer | arXiv | 2024/11/22 |
| MultiGen-20M | 20M | Unicontrol: A unified diffusion model for controllable visual generation in the wild | NeurIPS | 2023/05/18 |
| LAION-Face | 50M | General facial representation learning in a visual-linguistic manner | CVPR | 2021/12/06 |
Applications and Opportunities
| Name | Title | Venue | Date | Code | Demo |
|---|---|---|---|---|---|
| UniGame | UniGame: Turning a Unified Multimodal Model Into Its Own Adversary | arXiv | 2025/11/24 | Github | - |
| UniCTokens | UniCTokens: Boosting Personalized Understanding and Generation via Unified Concept Tokens | arXiv | 2025/05/20 | Github | - |
| Fair-UMLLM | On Fairness of Unified Multimodal Large Language Model for Image Generation | arXiv | 2025/02/05 | - | - |
| T2I-R1 | T2I-R1: Reinforcing Image Generation with Collaborative Semantic-level and Token-level CoT | arXiv | 2025/01/29 | Github | - |
Citation
If you find this repo is helpful for your research, please cite our paper:
@article{zhang2025unified,
  title={Unified Multimodal Understanding and Generation Models: Advances, Challenges, and Opportunities},
  author={Zhang, Xinjie and Guo, Jintao and Zhao, Shanshan and Fu, Minghao and Duan, Lunhao and Hu, Jiakui and Chng, Yong Xien and Wang, Guo-Hua and Chen, Qing-Guo and Xu, Zhao and Luo, Weihua and Zhang, Kaifu},
  journal={arXiv preprint arXiv:2505.02567},
  year={2025}
}