
A Survey on Vision-Language Geo-Foundation Models (VLGFMs)
180
64 commits
updated May 24, 2025
README


Towards Vision-Language Geo-Foundation Models: A Survey
arXiv, 2024
Yue Zhou
·
Litong Feng
·
Xue Jiang
·
Junchi Yan
·
Xue Yang
·
Wayne Zhang

This repo is used for recording, tracking, and benchmarking several recent vision-language geo-foundation models (VLGFM) to supplement our survey. If you find any work missing or have any suggestions (papers, implementations, and other resources), feel free to pull requests. We will add the missing papers to this repo as soon as possible.
🙌 Add Your Paper in our Repo and Survey!!!!!
-
You are welcome to give us an issue or PR for your VLGFM work !!!!!
-
Note that: Due to the huge paper in Arxiv, we are sorry to cover all in our survey. You can directly present a PR into this repo and we will record it for next version update of our survey.
🥳 New
🔥🔥🔥 Last Updated on 2025.05.24 🔥🔥🔥
- 2025.05.24: Update ImageRAG.
- 2025.02.16: Update UniRS, REO-VLM, GeoPixel.
- 2025.01.14: Update GeoPix.
- 2024.12.25: Update VHM (accepted by AAAI'2025), which is a new version of H2RSVLM.
- 2024.12.21: Update EarthDial.
✨ Highlight!!
-
The first survey for vision-language geo-foundation models, including contrastive/conversational/generative geo-foundation models.
-
It also contains several related works, including exploration and application of some downstream tasks.
-
We list detailed results for the most representative works and give a fairer and clearer comparison of different approaches.
📖 Introduction
This survey presents the first detailed survey on remote sensing vision language foundation models, including Contrastive/Conversational/Generative VLGFMs.
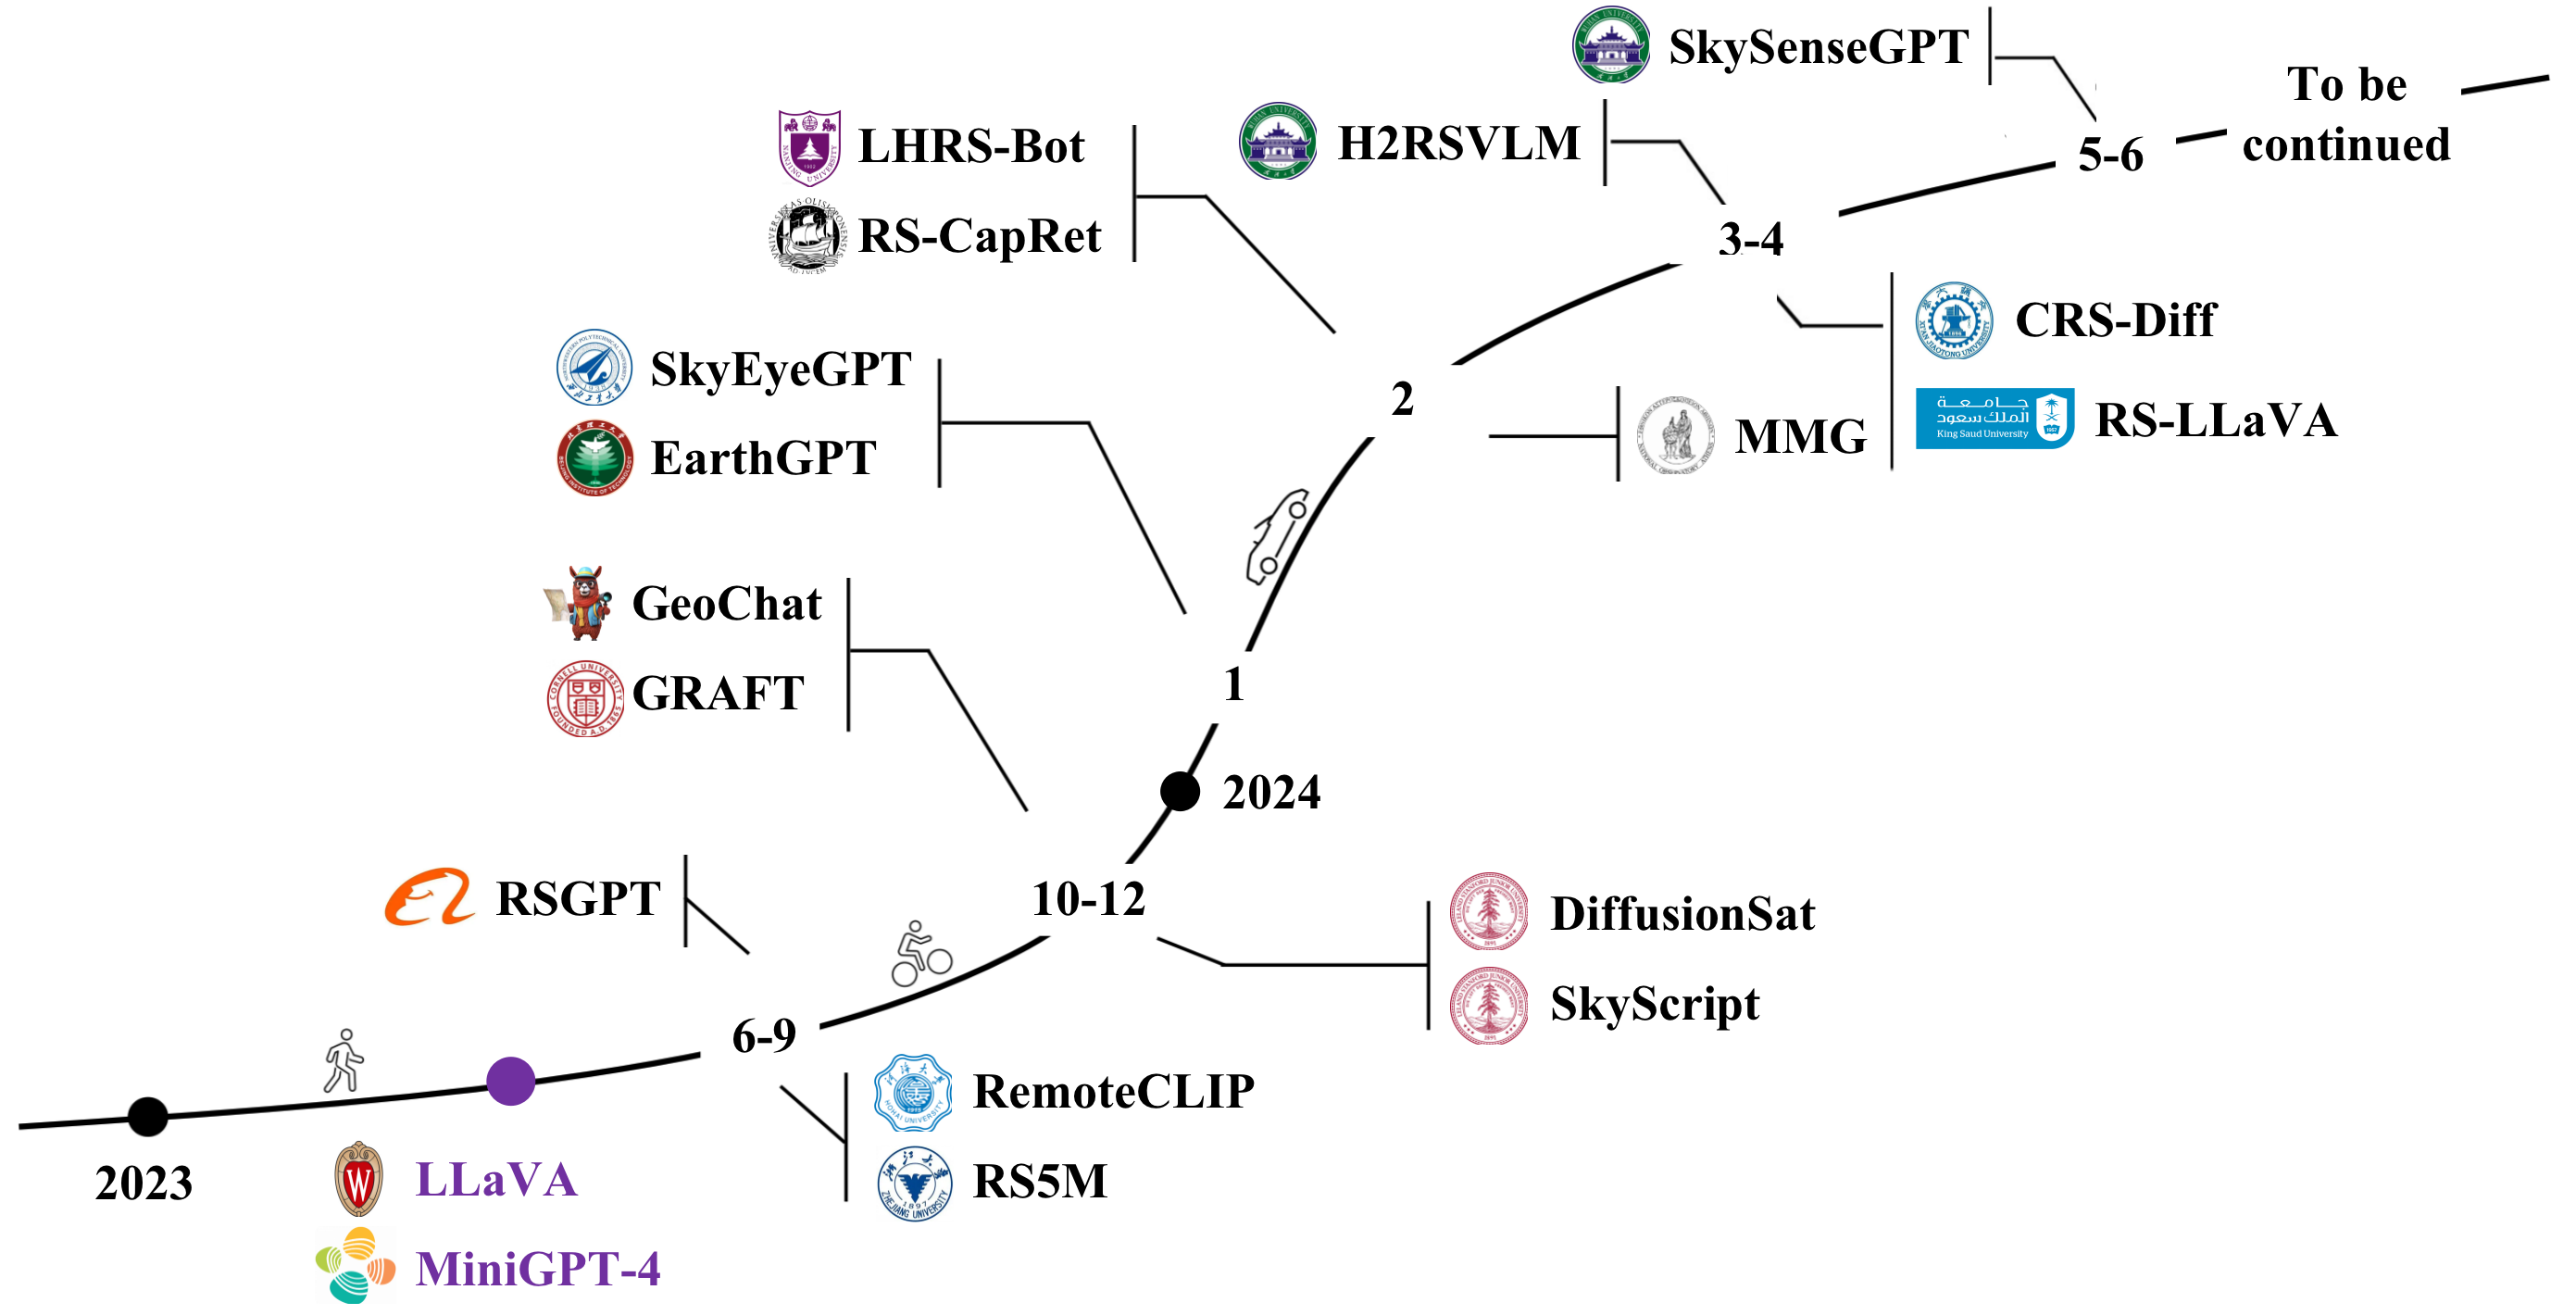
📗 Summary of Contents
- 📖 Introduction
- 📗 Summary of Contents
- 📚 Methods: A Survey
- 🕹️ Application
- 📊 Exploration
- 👨🏫 Survey
- 🖊️ Citation
- 🐲 Contact
📚 Methods: A Survey
Keywords
clip: Use CLIPllm: Use LLM (Large Language Model)sam: Use SAM (Segment Anything Model)i-t: Annotate using image-text tuplesv-t: Annotate using video-text tuplesi-t-b: Annotate using image-text-box tripletsi-t-m: Annotate using image-text-mask triplets
image-caption-mask triplets
Contrastive VLGFMs
Conversational VLGFMs
Generative VLGFMs
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2024 | ICLR | DiffusionSat: A Generative Foundation Model for Satellite Imagery | Code | |
| 2024 | arXiv | CRS-Diff: Controllable Generative Remote Sensing Foundation Model | N/A | |
| 2024 | arXiv | MetaEarth: A Generative Foundation Model for Global-Scale Remote Sensing Image Generation | Code | |
| 2024 | arXiv | HSIGene: A Foundation Model For Hyperspectral Image Generation | Code |
Datasets & Benchmark
🕹️ Application
Captioning
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | TGRS | llm | A Decoupling Paradigm With Prompt Learning for Remote Sensing Image Change Captioning | Code |
| 2023 | JSEE | llm | VLCA: vision-language aligning model with cross-modal attention for bilingual remote sensing image captioning | N/A |
Visual Question Answering
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | CVPRW | Prompt-RSVQA: Prompting visual context to a language model for remote sensing visual question answering | N/A | |
| 2024 | AAAI | EarthVQA: Towards Queryable Earth via Relational Reasoning-Based Remote Sensing Visual Question Answering | Project |
Change Detection
Scene Classification
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | IJAEOG | clip | RS-CLIP: Zero shot remote sensing scene classification via contrastive vision-language supervision | Code |
Referring Expression Segmentation (RES)
|2024|TGRS||RRSIS: Referring Remote Sensing Image Segmentation|Code| |2024|CVPR||Rotated Multi-Scale Interaction Network for Referring Remote Sensing Image Segmentation|Code|
Geospatial Localization
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | clip | Learning Generalized Zero-Shot Learners for Open-Domain Image Geolocalization | Code |
| 2023 | ICML | clip | CSP: Self-Supervised Contrastive Spatial Pre-Training for Geospatial-Visual Representations | Code |
| 2023 | NeurIPS | clip | GeoCLIP: Clip-Inspired Alignment between Locations and Images for Effective Worldwide Geo-localization | Code |
| 2023 | arXiv | clip | SatCLIP: Global, General-Purpose Location Embeddings with Satellite Imagery | Code |
Retrieval
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | VT | llm | CLIP-RS: A Cross-modal Remote Sensing Image Retrieval Based on CLIP, a Northern Virginia Case Study | N/A |
| 2024 | arXiv | llm | Multi-Spectral Remote Sensing Image Retrieval Using Geospatial Foundation Models | Code |
Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | sam clip | Text2Seg: Remote Sensing Image Semantic Segmentation via Text-Guided Vision Foundation Models | Code |
| 2024 | WACV | CPSeg: Finer-grained Image Semantic Segmentation via Chain-of-Thought Language Prompting | N/A |
Object Detection
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | clip | Stable Diffusion For Aerial Object Detection | N/A |
Super-Resolution
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | clip | Zooming Out on Zooming In: Advancing Super-Resolution for Remote Sensing | Code |
📊 Exploration
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | TGRS | An Empirical Study of Remote Sensing Pretraining | Code | |
| 2023 | arXiv | Autonomous GIS: the next-generation AI-powered GIS | N/A | |
| 2023 | arXiv | GPT4GEO: How a Language Model Sees the World's Geography | Code | |
| 2023 | arXiv | Charting New Territories: Exploring the Geographic and Geospatial Capabilities of Multimodal LLMs | Code | |
| 2023 | arXiv | The Potential of Visual ChatGPT For Remote Sensing | N/A |
👨🏫 Survey
🖊️ Citation
If you find our survey and repository useful for your research project, please consider citing our paper:
@article{zhou2024vlgfm,
  title={Towards Vision-Language Geo-Foundation Models: A Survey},
  author={Yue Zhou and Litong Feng and Yiping Ke and Xue Jiang and Junchi Yan and Xue Yang and Wayne Zhang},
  journal={arXiv preprint arXiv:2406.09385},
  year={2024}
}
🐲 Contact
yue.zhou@ntu.edu.sg
Contributors

64 commits


A Survey on Vision-Language Geo-Foundation Models (VLGFMs)
180
64 commits
updated May 24, 2025
README
Towards Vision-Language Geo-Foundation Models: A Survey
arXiv, 2024
Yue Zhou
·
Litong Feng
·
Xue Jiang
·
Junchi Yan
·
Xue Yang
·
Wayne Zhang
This repo is used for recording, tracking, and benchmarking several recent vision-language geo-foundation models (VLGFM) to supplement our survey. If you find any work missing or have any suggestions (papers, implementations, and other resources), feel free to pull requests. We will add the missing papers to this repo as soon as possible.
🙌 Add Your Paper in our Repo and Survey!!!!!
-
You are welcome to give us an issue or PR for your VLGFM work !!!!!
-
Note that: Due to the huge paper in Arxiv, we are sorry to cover all in our survey. You can directly present a PR into this repo and we will record it for next version update of our survey.
🥳 New
🔥🔥🔥 Last Updated on 2025.05.24 🔥🔥🔥
- 2025.05.24: Update ImageRAG.
- 2025.02.16: Update UniRS, REO-VLM, GeoPixel.
- 2025.01.14: Update GeoPix.
- 2024.12.25: Update VHM (accepted by AAAI'2025), which is a new version of H2RSVLM.
- 2024.12.21: Update EarthDial.
✨ Highlight!!
-
The first survey for vision-language geo-foundation models, including contrastive/conversational/generative geo-foundation models.
-
It also contains several related works, including exploration and application of some downstream tasks.
-
We list detailed results for the most representative works and give a fairer and clearer comparison of different approaches.
📖 Introduction
This survey presents the first detailed survey on remote sensing vision language foundation models, including Contrastive/Conversational/Generative VLGFMs.
📗 Summary of Contents
- 📖 Introduction
- 📗 Summary of Contents
- 📚 Methods: A Survey
- 🕹️ Application
- 📊 Exploration
- 👨🏫 Survey
- 🖊️ Citation
- 🐲 Contact
📚 Methods: A Survey
Keywords
clip: Use CLIPllm: Use LLM (Large Language Model)sam: Use SAM (Segment Anything Model)i-t: Annotate using image-text tuplesv-t: Annotate using video-text tuplesi-t-b: Annotate using image-text-box tripletsi-t-m: Annotate using image-text-mask triplets
image-caption-mask triplets
Contrastive VLGFMs
Conversational VLGFMs
Generative VLGFMs
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2024 | ICLR | DiffusionSat: A Generative Foundation Model for Satellite Imagery | Code | |
| 2024 | arXiv | CRS-Diff: Controllable Generative Remote Sensing Foundation Model | N/A | |
| 2024 | arXiv | MetaEarth: A Generative Foundation Model for Global-Scale Remote Sensing Image Generation | Code | |
| 2024 | arXiv | HSIGene: A Foundation Model For Hyperspectral Image Generation | Code |
Datasets & Benchmark
🕹️ Application
Captioning
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | TGRS | llm | A Decoupling Paradigm With Prompt Learning for Remote Sensing Image Change Captioning | Code |
| 2023 | JSEE | llm | VLCA: vision-language aligning model with cross-modal attention for bilingual remote sensing image captioning | N/A |
Visual Question Answering
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | CVPRW | Prompt-RSVQA: Prompting visual context to a language model for remote sensing visual question answering | N/A | |
| 2024 | AAAI | EarthVQA: Towards Queryable Earth via Relational Reasoning-Based Remote Sensing Visual Question Answering | Project |
Change Detection
Scene Classification
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | IJAEOG | clip | RS-CLIP: Zero shot remote sensing scene classification via contrastive vision-language supervision | Code |
Referring Expression Segmentation (RES)
|2024|TGRS||RRSIS: Referring Remote Sensing Image Segmentation|Code| |2024|CVPR||Rotated Multi-Scale Interaction Network for Referring Remote Sensing Image Segmentation|Code|
Geospatial Localization
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | clip | Learning Generalized Zero-Shot Learners for Open-Domain Image Geolocalization | Code |
| 2023 | ICML | clip | CSP: Self-Supervised Contrastive Spatial Pre-Training for Geospatial-Visual Representations | Code |
| 2023 | NeurIPS | clip | GeoCLIP: Clip-Inspired Alignment between Locations and Images for Effective Worldwide Geo-localization | Code |
| 2023 | arXiv | clip | SatCLIP: Global, General-Purpose Location Embeddings with Satellite Imagery | Code |
Retrieval
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | VT | llm | CLIP-RS: A Cross-modal Remote Sensing Image Retrieval Based on CLIP, a Northern Virginia Case Study | N/A |
| 2024 | arXiv | llm | Multi-Spectral Remote Sensing Image Retrieval Using Geospatial Foundation Models | Code |
Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | sam clip | Text2Seg: Remote Sensing Image Semantic Segmentation via Text-Guided Vision Foundation Models | Code |
| 2024 | WACV | CPSeg: Finer-grained Image Semantic Segmentation via Chain-of-Thought Language Prompting | N/A |
Object Detection
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | clip | Stable Diffusion For Aerial Object Detection | N/A |
Super-Resolution
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | arXiv | clip | Zooming Out on Zooming In: Advancing Super-Resolution for Remote Sensing | Code |
📊 Exploration
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | TGRS | An Empirical Study of Remote Sensing Pretraining | Code | |
| 2023 | arXiv | Autonomous GIS: the next-generation AI-powered GIS | N/A | |
| 2023 | arXiv | GPT4GEO: How a Language Model Sees the World's Geography | Code | |
| 2023 | arXiv | Charting New Territories: Exploring the Geographic and Geospatial Capabilities of Multimodal LLMs | Code | |
| 2023 | arXiv | The Potential of Visual ChatGPT For Remote Sensing | N/A |
👨🏫 Survey
🖊️ Citation
If you find our survey and repository useful for your research project, please consider citing our paper:
@article{zhou2024vlgfm,
  title={Towards Vision-Language Geo-Foundation Models: A Survey},
  author={Yue Zhou and Litong Feng and Yiping Ke and Xue Jiang and Junchi Yan and Xue Yang and Wayne Zhang},
  journal={arXiv preprint arXiv:2406.09385},
  year={2024}
}
🐲 Contact
yue.zhou@ntu.edu.sg
Similar repos
Contributors
64 commits