JackYFL/awesome-VLLMs

This repository collects papers on VLLM applications. We will update new papers irregularly.

221

229 commits

updated Feb 23, 2026

See the code

README

Awesome Visual Large Language Models (VLLMs)

Maintenance Awesome PR's Welcome

🔥🔥🔥 Visual Large Language Models for Generalized and Specialized Applications

Vision language models (VLMs) have emerged as powerful tools for learning unified embedding spaces that integrate vision and language. Inspired by the success of large language models (LLMs), which have demonstrated remarkable reasoning and multi-task capabilities, visual large language models (VLLMs) are gaining significant attention for developing both general-purpose and specialized VLMs.

In this repository, we provide a comprehensive summary of the current literature from an application-oriented perspective. We hope this resource serves as a valuable reference for the VLLM research community.

If you are interested in this project, you can contribute to this repo by pulling requests 😊😊😊

If you think our paper is helpful for your research, you can cite through this bib tex entry!

@article{li2025visual,
  title={Visual Large Language Models for Generalized and Specialized Applications},
  author={Li, Yifan and Lai, Zhixin and Bao, Wentao and Tan, Zhen and Dao, Anh and Sui, Kewei and Shen, Jiayi and Liu, Dong and Liu, Huan and Kong, Yu},
  journal={arXiv preprint arXiv:2501.02765},
  year={2025}
}

📢 News

🚀 What's New in This Update:

  • [2026.2.23]: 🔥 Adding three papers on VLLM explanation! Thanks Ruoyu!
  • [2025.7.28]: 🔥 Adding five papers on autonomous driving, vision generation and video understanding!
  • [2025.4.25]: 🔥 Adding eleven papers on complex reasoning, face, video understanding and medical!
  • [2025.4.18]: 🔥 Adding three papers on complex reasoning!
  • [2025.4.12]: 🔥 Adding one paper on complex reasoning and one paper on efficiency!
  • [2025.3.20]: 🔥 Adding eleven papers and 1 wonderful repo on complex reasoning!
  • [2025.3.10]: 🔥 Adding three papers on complex reasoning, efficiency and face!
  • [2025.3.6]: 🔥 Adding one paper on complex reasoning!
  • [2025.3.2]: 🔥 Adding two projects on complex reasoning: R1-V and VLM-R1!
  • [2025.2.23]: 🔥 Adding one video-to-action paper and one vision-to-text paper!
  • [2025.2.1]: 🔥 Adding four video-to-text papers!
  • [2025.1.22]: 🔥 Adding one video-to-text paper!
  • [2025.1.17]: 🔥 Adding three video-to-text papers, thanks for the contributions from Enxin!
  • [2025.1.14]: 🔥 Adding two complex reasoning papers and one video-to-text paper!
  • [2025.1.13]: 🔥 Adding one VFM survey paper!
  • [2025.1.12]: 🔥 Adding one efficient MLLM paper!
  • [2025.1.9]: 🔥🔥🔥 Adding one efficient MLLM survey!
  • [2025.1.7]: 🔥🔥🔥 Our survey paper is released! Please check this link for more information. We add more tool management papers in our paper list.
  • [2025.1.6]: 🔥 We add one OS Agent survey paper in our paper list, and a new category: complex reasoning!
  • [2025.1.4]: 🔥 We updated the general domain and egocentric video papers in our paper list, thanks for the contributions from Wentao!
  • [2025.1.2]: 🔥 We add more interpretation papers to our paper list, thanks for the contributions from Ruoyu!
  • [2024.12.15]: 🔥 We release our VLLM application paper list repo!

:rainbow: Table of Contents

Existing VLM surveys

VLM surveys

🎯Back to Top

MLLM surveys

TitleVenueDateCodeProject
OS Agents: A Survey on MLLM-based Agents for General Computing Devices Use
ArXiv2024-12-27GithubProject
Towards Explainable and Interpretable Multimodal Large Language Models: A Comprehensive Survey
ArXiv2024-12-3GithubProject
Star
A Survey on Multimodal Large Language Models
T-PAMI2024-11-29GithubProject
Star
MME-Survey: A Comprehensive Survey on Evaluation of Multimodal LLMs
ArXiv2024-11-22GithubProject
A Survey on Multimodal Large Language Models
National Science Review2024-11-12GithubProject
Video Understanding with Large Language Models: A Survey
ArXiv2024-6-24GithubProject
Star
A Survey on Multimodal Benchmarks: In the Era of Large AI Models
ArXiv2024-9-21GithubProject
Star
The Revolution of Multimodal Large Language Models: A Survey
ArXiv2024-6-6GithubProject
Star
Efficient Multimodal Large Language Models: A Survey
ArXiv2024-5-17GithubProject
Star
A Survey on Hallucination in Large Vision-Language Models
ArXiv2024-5-6GithubProject
Star
Hallucination of multimodal large language models: A survey
ArXiv2024-4-29GithubProject
Exploring the Frontier of Vision-Language Models: A Survey of Current Methodologies and Future Directions
ArXiv2024-4-12GithubProject
Star
MM-LLMs: Recent Advances in MultiModal Large Language Models
ArXiv2024-2-20GithubProject
Exploring the Reasoning Abilities of Multimodallarge Language Models (mllms): a Comprehensive survey on Emerging Trends in Multimodal Reasonings
ArXiv2024-1-18GithubProject
Visual Instruction Tuning towards General-Purpose Multimodal Model: A Survey
ArXiv2023-12-27GithubProject
Multimodal Large Language Models: A Survey
BigData2023-12-15GithubProject

🎯Back to Top

Vision-to-text

Image-to-text

General domain

General ability
NameTitleVenueDateCodeProject
UniMEStar
Breaking the Modality Barrier: Universal Embedding Learning with Multimodal LLMs
ArXiv2025-4-24GithubProject
InternVL2.5Star
Expanding Performance Boundaries of Open-Source Multimodal Models with Model, Data, and Test-Time Scaling
ArXiv2024-12-17GithubProject
CompCapCompCap: Improving Multimodal Large Language Models with Composite CaptionsArXiv2024-12-06GithubProject
NVILANVILA: Efficient Frontier Visual Language ModelsArXiv2024-12-05GithubProject
Molmo and PixMoStar
Molmo and PixMo: Open Weights and Open Data for State-of-the-Art Vision-Language Models
ArXiv2024-09-25GithubProject
Qwen2-VLStar
Qwen2-VL: Enhancing Vision-Language Model’s Perception of the World at Any Resolution
ArXiv2024-09-18GithubProject
mPLUG-Owl3Star
mPLUG-Owl3: Towards Long Image-Sequence Understanding in Multi-Modal Large Language Models
ArXiv2024-08-09GithubProject
LLaVA-OneVisionStar
LLaVA-OneVision: Easy Visual Task Transfer
ArXiv2024-08-06GithubProject
VILA$^{2}$VILA $^2$: VILA Augmented VILAArXiv2024-07-24GithubProject
EVLMEVLM: An Efficient Vision-Language Model for Visual UnderstandingArXiv2024-07-19GithubProject
MG-LLaVAMG-LLaVA: Towards Multi-Granularity Visual Instruction TuningArXiv2024-06-27GithubProject
Cambrian-1Star
Cambrian-1: A Fully Open, Vision-Centric Exploration of Multimodal LLMs
ArXiv2024-06-24GithubProject
OvisStar
Ovis: Structural Embedding Alignment for Multimodal Large Language Model
ArXiv2024-05-31GithubProject
ConvLLaVAStar
ConvLLaVA: Hierarchical Backbones as Visual Encoder for Large Multimodal Models
ArXiv2024-05-24GithubProject
MeteorStar
Meteor: Mamba-based Traversal of Rationale for Large Language and Vision Models
NeurIPS2024-05-24GithubProject
CuMoStar
CuMo: Scaling Multimodal LLM with Co-Upcycled Mixture-of-Experts
ArXiv2024-05-09GithubProject
Mini-GeminiStar
Mini-Gemini: Mining the Potential of Multi-modality Vision Language Models
ArXiv2024-03-27GithubProject
MM1MM1: Methods, Analysis & Insights from Multimodal LLM Pre-trainingArXiv2024-03-14GithubProject
DeepSeek-VLStar
DeepSeek-VL: Towards Real-World Vision-Language Understanding
ArXiv2024-03-08GithubProject
InternLM-XComposer2Star
InternLM-XComposer2: Mastering Free-form Text-Image Composition and Comprehension in Vision-Language Large Model
ArXiv2024-01-29GithubProject
MoE-LLaVAStar
MoE-LLaVA: Mixture of Experts for Large Vision-Language Models
ArXiv2024-01-29GithubProject
InternVLStar
InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks
CVPR2023-12-21GithubProject
VILAStar
VILA: On Pre-training for Visual Language Models
ArXiv2023-12-12GithubProject
VaryStar
Vary: Scaling up the Vision Vocabulary for Large Vision-Language Models
ECCV2023-12-11GithubProject
HoneybeeStar
Honeybee: Locality-enhanced Projector for Multimodal LLM
CVPR2023-11-11GithubProject
OtterHDStar
OtterHD: A High-Resolution Multi-modality Model
ArXiv2023-11-07GithubProject
mPLUG-Owl2Star
mPLUG-Owl2: Revolutionizing Multi-modal Large Language Model with Modality Collaboration
CVPR2023-11-07GithubProject
FuyuStar
Fuyu-8B: A Multimodal Architecture for AI Agents
ArXiv2023-10-17GithubProject
MiniGPT-v2Star
MiniGPT-v2: large language model as a unified interface for vision-language multi-task learning
ArXiv2023-10-14GithubProject
LLaVA 1.5Star
Improved Baselines with Visual Instruction Tuning
ArXiv2023-10-05GithubProject
InternLM-XComposerStar
InternLM-XComposer: A Vision-Language Large Model for Advanced Text-image Comprehension and Composition
ArXiv2023-09-26GithubProject
Qwen-VLStar
Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond
ArXiv2023-08-24GithubProject
StableLLaVAStar
StableLLaVA: Enhanced Visual Instruction Tuning with Synthesized Image-Dialogue Data
ArXiv2023-08-20GithubProject
BLIVAStar
BLIVA: A Simple Multimodal LLM for Better Handling of Text-Rich Visual Questions
AAAI2023-08-19GithubProject
SVITStar
SVIT: Scaling up Visual Instruction Tuning
ArXiv2023-07-09GithubProject
LaVINStar
Cheap and Quick: Efficient Vision-Language Instruction Tuning for Large Language Models
NeurIPS2023-05-24GithubProject
InstructBLIPStar
InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning
NeurIPS2023-05-11GithubProject
MultiModal-GPTStar
MultiModal-GPT: A Vision and Language Model for Dialogue with Humans
ArXiv2023-05-08GithubProject
OtterStar
Otter: A Multi-Modal Model with In-Context Instruction Tuning
ArXiv2023-05-05GithubProject
mPLUG-OwlStar
mPLUG-Owl: Modularization Empowers Large Language Models with Multimodality
ArXiv2023-04-27GithubProject
LLaMA-Adapter V2Star
LLaMA-Adapter V2: Parameter-Efficient Visual Instruction Model
ArXiv2023-04-28GithubProject
MiniGPT-4Star
MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language Models
NeurIPS2023-04-20GithubProject
LLaVAStar
Visual Instruction Tuning
NeurIPS2023-04-17GithubProject
LLaMA-AdapterStar
LLaMA-Adapter: Efficient Fine-tuning of Large Language Models with Zero-initialized Attention
ICLR2023-03-28GithubProject
Kosmos-1Star
Language Is Not All You Need: Aligning Perception with Language Models
NeurIPS2023-02-27GithubProject
FlamingoStar
Flamingo: a Visual Language Model for Few-Shot Learning
NeurIPS2022-04-29GithubProject

🎯Back to Top

REC
NameTitleVenueDateCodeProject
ChatRexStar
ChatRex: Taming Multimodal LLM for Joint Perception and Understanding
ArXiv2024-11-27GithubProject
Griffon-GStar
Griffon-G: Bridging Vision-Language and Vision-Centric Tasks via Large Multimodal Models
ArXiv2024-10-21GithubProject
FerretStar
Ferret: Refer and Ground Anything Anywhere at Any Granularity
ICLR2024-10-11GithubProject
OMG-LLaVAStar
OMG-LLaVA: Bridging Image-level, Object-level, Pixel-level Reasoning and Understanding
NeurIPS2024-06-27GithubProject
VisionLLMv2Star
VisionLLM v2: An End-to-End Generalist Multimodal Large Language Model for Hundreds of Vision-Language Tasks
ArXiv2024-06-12GithubProject
GromaStar
Groma: Localized Visual Tokenization for Grounding Multimodal Large Language Models
ECCV2024-04-19GithubProject
Griffonv2Star
Griffon v2: Advancing Multimodal Perception with High-Resolution Scaling and Visual-Language Co-Referring
ArXiv2024-03-14GithubProject
ASMv2Star
The All-Seeing Project V2: Towards General Relation Comprehension of the Open World
ECCV2024-02-29GithubProject
SPHINX-XSPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language ModelsArXiv2024-02-08GithubProject
ChatterBoxStar
ChatterBox: Multi-round Multimodal Referring and Grounding
ArXiv2024-01-24GithubProject
LEGOStar
LEGO: Language Enhanced Multi-modal Grounding Model
ArXiv2024-01-12GithubProject
GroundingGPTStar
GroundingGPT: Language Enhanced Multi-modal Grounding Model
ACL2024-01-11GithubProject
BuboGPTStar
BuboGPT: Enabling Visual Grounding in Multi-Modal LLMs
ArXiv2024-07-17GithubProject
Ferret-v2Star
Ferret-v2: An Improved Baseline for Referring and Grounding with Large Language Models
COLM2024-04-11GithubProject
InfMLLMStar
InfLLM: Training-Free Long-Context Extrapolation for LLMs with an Efficient Context Memory
NeurIPS2024-02-07GithubProject
VistaLLMJack of All Tasks, Master of Many: Designing General-purpose Coarse-to-Fine Vision-Language ModelECCV2023-12-19GithubProject
LLaVA-GroundingStar
LLaVA-Grounding: Grounded Visual Chat with Large Multimodal Models
ArXiv2023-12-05GithubProject
LennaStar
Lenna: Language Enhanced Reasoning Detection Assistant
ArXiv2023-12-05GithubProject
GriffonStar
Griffon: Spelling out All Object Locations at Any Granularity with Large Language Models
ECCV2023-11-24GithubProject
LionStar
Lion: Empowering multimodal large language model with dual-level visual knowledge
CVPR2023-11-20GithubProject
SPHINXSPHINX: The Joint Mixing of Weights, Tasks, and Visual Embeddings for Multi-modal Large Language ModelsArXiv2023-11-13GithubProject
NExT-ChatStar
NExT-Chat: An LMM for Chat, Detection and Segmentation
ArXiv2023-11-08GithubProject
GLaMMStar
GLaMM: Pixel Grounding Large Multimodal Model
CVPR2023-11-06GithubProject
CogVLMStar
CogVLM: Visual Expert for Pretrained Language Models
ArXiv2023-11-06GithubProject
PinkStar
Pink: Unveiling the Power of Referential Comprehension for Multi-modal LLMs
CVPR2023-10-01GithubProject
PVITStar
Position-Enhanced Visual Instruction Tuning for Multimodal Large Language Models
ArXiv2023-08-25GithubProject
ASMStar
The all-seeing project: Towards panoptic visual recognition and understanding of the open world
ICLR2023-08-03GithubProject
ShikraStar
Shikra: Unleashing Multimodal LLM's Referential Dialogue Magic
ArXiv2023-06-27GithubProject
Kosmos-2Star
KOSMOS-2: Grounding Multimodal Large LanguageModels to the World
ICLR2023-06-26GithubProject
ChatSpotStar
ChatSpot: Bootstrapping Multimodal LLMs via Precise Referring Instruction Tuning
ArXiv2023-07-18GithubProject
GPT4RoIStar
GPT4RoI: Instruction Tuning Large Language Model on Region-of-Interest
IJCAI2023-07-07GithubProject
ContextDETStar
Contextual Object Detection with Multimodal Large Language Models
ArXiv2023-05-29GithubProject
DetGPTStar
DetGPT: Detect What You Need via Reasoning
ArXiv2023-05-23GithubProject
VisionLLMStar
VisionLLM: Large Language Model is also an Open-Ended Decoder for Vision-Centric Tasks
ArXiv2023-05-18GithubProject

🎯Back to Top

RES
NameTitleVenueDateCodeProject
SpectrumLearning 3D Texture-Aware Representations for Parsing Diverse Human Clothing and Body PartsAAAI2025-12-18GithubProject
OMG-LLaVAStar
OMG-LLaVA: Bridging Image-level, Object-level, Pixel-level Reasoning and Understanding
NeurIPS2024-06-27GithubProject
VisionLLMv2Star
VisionLLM v2: An End-to-End Generalist Multimodal Large Language Model for Hundreds of Vision-Language Tasks
ArXiv2024-06-12GithubProject
LLM-SegLLM-Seg: Bridging Image Segmentation and Large Language Model ReasoningCVPR2024-04-12GithubProject
PSALMStar
PSALM: Pixelwise SegmentAtion with Large Multi-Modal Model
ECCV2024-03-21GithubProject
GROUNDHOGStar
GROUNDHOG: Grounding Large Language Models to Holistic Segmentation
CVPR2024-02-26GithubProject
GELLAGeneralizable Entity Grounding via Assistance of Large Language ModelECCV2024-02-04GithubProject
OMG-SegStar
OMG-Seg: Is One Model Good Enough For All Segmentation?
CVPR2024-01-18GithubProject
LISA++Star
LISA++: An Improved Baseline for Reasoning Segmentation with Large Language Model
ArXiv2023-12-28GithubProject
VistaLLMStar
Jack of All Tasks, Master of Many: Designing General-purpose Coarse-to-Fine Vision-Language Model
ECCV2023-12-19GithubProject
OspreyStar
Osprey: Pixel Understanding with Visual Instruction Tuning
CVPR2023-12-15GithubProject
GSVAStar
GSVA: Generalized Segmentation via Multimodal Large Language Models
CVPR2023-12-05GithubProject
PixelLMStar
PixelLM: Pixel Reasoning with Large Multimodal Model
CVPR2023-12-04GithubProject
PixelLLMStar
PixelLM: Pixel Reasoning with Large Multimodal Model
ECCV2023-12-04GithubProject
LLaFSStar
LLaFS: When Large Language Models Meet Few-Shot Segmentation
CVPR2023-11-28GithubProject
NExT-ChatStar
NExT-Chat: An LMM for Chat, Detection and Segmentation
ArXiv2023-11-08GithubProject
GLaMMStar
GLaMM: Pixel Grounding Large Multimodal Model
CVPR2023-11-06GithubProject
LISAStar
LISA: Reasoning Segmentation via Large Language Model
CVPR2023-08-01GithubProject
ContextDETStar
Contextual Object Detection with Multimodal Large Language Models
ArXiv2023-05-29GithubProject
VisionLLMStar
VisionLLM: Large Language Model is also an Open-Ended Decoder for Vision-Centric Tasks
ArXiv2023-05-18GithubProject

🎯Back to Top

OCR
NameTitleVenueDateCodeProject
TextHawk2Star
TextHawk2: A Large Vision-Language Model Excels in Bilingual OCR and Grounding with 16x Fewer Tokens
ArXiv2024-10-07GithubProject
DockylinStar
DocKylin: A Large Multimodal Model for Visual Document Understanding with Efficient Visual Slimming
AAAI2024-06-27GithubProject
StrucTexTv3StrucTexTv3: An Efficient Vision-Language Model for Text-rich Image Perception, Comprehension, and BeyondArXiv2024-05-31GithubProject
FoxStar
Focus Anywhere for Fine-grained Multi-page Document Understanding
ArXiv2024-05-23GithubProject
TextMonkeyStar
TextMonkey: An OCR-Free Large Multimodal Model for Understanding Document
ArXiv2024-05-07GithubProject
TinyChartStar
TinyChart: Efficient Chart Understanding with Visual Token Merging and Program-of-Thoughts Learning
ACL2024-04-25GithubProject
TextHawkStar
TextHawk: Exploring Efficient Fine-Grained Perception of Multimodal Large Language Models
ArXiv2024-04-14GithubProject
HRVDAHRVDA: High-Resolution Visual Document AssistantCVPR2024-04-10GithubProject
InternLM-XComposer2-4KHDStar
InternLM-XComposer2-4KHD: A Pioneering Large Vision-Language Model Handling Resolutions from 336 Pixels to 4K HD
NeurIPS2024-04-09GithubProject
LayoutLLMLayoutLLM: Layout Instruction Tuning with Large Language Models for Document UnderstandingCVPR2024-04-08GithubProject
ViTLPStar
Visually Guided Generative Text-Layout Pre-training for Document Intelligence
NAACL2024-03-25GithubProject
mPLUG-DocOwl 1.5Star
mPLUG-DocOwl 1.5: Unified Structure Learning for OCR-free Document Understanding
ArXiv2024-03-19GithubProject
DoCoEnhancing Visual Document Understanding with Contrastive Learning in Large Visual-Language ModelsCVPR2024-02-29GithubProject
TGDocStar
Towards Improving Document Understanding: An Exploration on Text-Grounding via MLLMs
ArXiv2023-11-22GithubProject
DocPediaDocPedia: Unleashing the Power of Large Multimodal Model in the Frequency Domain for Versatile Document UnderstandingArXiv2023-11-20GithubProject
UReaderStar
UReader: Universal OCR-free Visually-situated Language Understanding with Multimodal Large Language Model
ACL2023-10-08GithubProject
UniDocUniDoc: A Universal Large Multimodal Model for Simultaneous Text Detection, Recognition, Spotting and UnderstandingArXiv2023-08-19GithubProject
mPLUG-DocOwlStar
mPLUG-DocOwl: Modularized Multimodal Large Language Model for Document Understanding
ArXiv2023-07-04GithubProject
LLaVARStar
LLaVAR: Enhanced Visual Instruction Tuning for Text-Rich Image Understanding
ArXiv2023-06-29GithubProject

🎯Back to Top

Retrieval

🎯Back to Top

VLLM+X

Remote sensing

🎯Back to Top

Medical

🎯Back to Top

Science and math

🎯Back to Top

Graphics and UI
NameTitleVenueDateCodeProject
GraphistStar
Graphic Design with Large Multimodal Model
ArXiv2024-04-22GithubProject
Ferret-UIFerret-UI: Grounded Mobile UI Understanding with Multimodal LLMs
ECCV2024-04-08GithubProject
CogAgentStar
CogAgent: A Visual Language Model for GUI Agents
CVPR2023-12-21GithubProject

🎯Back to Top

Financial analysis

🎯Back to Top

Video-to-text

General domain

NameTitleVenueDateCodeProject
TimeSoccerTimeSoccer: An End-to-End Multimodal Large Language Model for Soccer Commentary GenerationArXiv2025-4-24GithubProject
Eagle 2.5Star
Eagle 2.5: Boosting Long-Context Post-Training for Frontier Vision-Language Models
ArXiv2025-4-21GithubProject
Camera-BenchStar
Towards Understanding Camera Motions in Any Video
ArXiv2025-4-21GithubProject
IV-BenchStar
IV-Bench: A Benchmark for Image-Grounded Video Perception and Reasoning in Multimodal LLMs
ArXiv2025-4-21GithubProject
VideoChat-OnlineStar
Online Video Understanding: OVBench and VideoChat-Online
CVPR2025-4-21GithubProject
MavorsStar
Mavors: Multi-granularity Video Representation for Multimodal Large Language Model
ArXiv2025-4-14GithubProject
VideoLLaMA3Star
VideoLLaMA 3: Frontier Multimodal Foundation Models for Image and Video Understanding
ArXiv2025-1-22GithubProject
AriaStar
ARIA : An Open Multimodal Native Mixture-of-Experts Model
ArXiv2024-12-17GithubProject
ApolloApollo: An Exploration of Video Understanding in Large Multimodal ModelsArXiv2024-12-13GithubProject
LinVTStar
LinVT: Empower Your Image-level Large Language Model to Understand Videos
ArXiv2024-12-11GithubProject
Video-LLaMA2Star
VideoLLaMA 2: Advancing Spatial-Temporal Modeling and Audio Understanding in Video-LLMs
ArXiv2024-10-30GithubProject
LLaVA-OneVisionStar
LLaVA-OneVision: Easy Visual Task Transfer
ArXiv2024-10-26GithubProject
OryxStar
Oryx MLLM: On-Demand Spatial-Temporal Understanding at Arbitrary Resolution
ICLR2024-10-22GithubProject
LongVUStar
LongVU: Spatiotemporal Adaptive Compression for Long Video-Language Understanding
ArXiv2024-10-22GithubProject
AuroraCapStar
AuroraCap: Efficient, Performant Video Detailed Captioning and a New Benchmark
Arxiv2024-10-4GithubProject
LLaVA-VideoStar
Video Instruction Tuning With Synthetic Data
ArXiv2024-10-04GithubProject
SlowFast-LLaVAStar
SlowFast-LLaVA: A Strong Training-Free Baseline for Video Large Language Models
ArXiv2024-9-15GithubProject
InternVideo2Star
InternVideo2: Scaling Foundation Models for Multimodal Video Understanding
ArXiv2024-8-14GithubProject
mPLUG-Owl3Star
mPLUG-Owl3: Towards Long Image-Sequence Understanding in Multi-Modal Large Language Models
ArXiv2024-08-13GithubProject
GoldfishStar
Goldfish: Vision-Language Understanding of Arbitrarily Long Videos
ECCV2024-07-17GithubProject
VoTStar
Video-of-Thought: Step-by-Step Video Reasoning from Perception to Cognition
ICML2024-07-17GithubProject
Flash-VStreamStar
Flash-VStream: Memory-Based Real-Time Understanding for Long Video Streams
ArXiv2024-06-30GithubProject
LLaVA-Next-VideoStar
LLaVA-NeXT: A Strong Zero-shot Video Understanding Model
online2024-04-30GithubProject
PLLaVAStar
PLLaVA: Parameter-free LLaVA Extension from Images to Videos for Video Dense Captioning
Arxiv2023-4-29GithubProject
MovieChat+Star
MovieChat+: Question-aware Sparse Memory for Long Video Question Answering
Arxiv2023-4-26GithubProject
MiniGPT4-VideoStar
MiniGPT4-video: Advancing multimodal llms for video understanding with interleaved visual-textual tokens
CVPR Workshop2024-04-04GithubProject
ST-LLMStar
ST-LLM: Large language models are effective temporal learners
ECCV2024-03-30GithubProject
LLaMA-VIDStar
LLaMA-VID: An Image is Worth 2 Tokens in Large Language Models
ECCV2023-11-28GithubProject
MovieChatStar
Moviechat: From dense token to sparse memory for long video understanding
CVPR2023-7-31GithubProject
Video-LLaMAStar
Video-LLaMA: An Instruction-tuned Audio-Visual Language Model for Video Understanding
EMNLP2023-10-25GithubProject
Vid2SeqStar
Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning
CVPR2023-03-21GithubProject
LaViLaStar
Learning Video Representations from Large Language Models
CVPR2022-12-08GithubProject
VideoBERTStar
VideoBERT: A joint model for video and language representation learning
ICCV2019-09-11GithubProject

🎯Back to Top

Video conversation

🎯Back to Top

Egocentric view

🎯Back to Top

Vision-to-action

Autonomous driving

Perception

🎯Back to Top

Planning

🎯Back to Top

Prediction

🎯Back to Top

Embodied AI

Perception

🎯Back to Top

Manipulation

🎯Back to Top

Planning

🎯Back to Top

🎯Back to Top

Automated tool management

NameTitleVenueDateCodeProject
Falcon-UIFalcon-UI: Understanding GUI Before Following User InstructionsarXiv2024-12-12GithubProject
AGENTTREKAgentTrek: Agent Trajectory Synthesis via Guiding Replay with Web TutorialsarXiv2024-12-12GithubProject
AguvisStar
Aguvis: Unified Pure Vision Agents for Autonomous GUI Interaction
arXiv2024-12-12GithubProject
ScribeAgentStar
ScribeAgent: Towards Specialized Web Agents Using Production-Scale Workflow Data
ArXiv2024-12-5GithubProject
ShowUIStar
ShowUI: One Vision-Language-Action Model for GUI Visual Agent
NeurlPS Workshop2024-11-26GithubProject
MultiUIStar
Harnessing Webpage UIs for Text-Rich Visual Understanding
ArXiv2024-11-6GithubProject
EDGEEDGE: Enhanced Grounded GUI Understanding with Enriched Multi-Granularity Synthetic DataArXiv2024-11-2GithubProject
AndroidLabStar
AndroidLab: Training and Systematic Benchmarking of Android Autonomous Agents
NeurlPS Workshop2024-10-30GithubProject
OS-ATLASStar
OS-ATLAS: A Foundation Action Model for Generalist GUI Agents
ArXiv2024-10-30GithubProject
AutoGLMAutoGLM: Autonomous Foundation Agents for GUIsArXiv2024-10-30GithubProject
Ferret-UI 2Ferret-UI 2: Mastering Universal User Interface Understanding Across PlatformsArXiv2024-10-24GithubProject
Tool-LMMStar
Tool-LMM: A Large Multi-Modal Model for Tool Agent Learning
arXiv2024-1-19GithubProject
CLOVAStar
CLOVA: A Closed-loop Visual Assistant with Tool Usage and Update
CVPR2023-12-18GithubProject
CRAFTStar
CRAFT: Customizing LLMs by Creating and Retrieving from Specialized Toolsets
arXiv2023-9-29GithubProject
ConfuciusStar
Confucius: Iterative tool learning from introspection feedback by easy-to-difficult curriculum
AAAI2023-8-27GithubProject
AVISAvis: Autonomous visual information seeking with large language model agentNeurIPS2023-6-13GithubProject
GPT4ToolsStar
GPT4Tools: Teaching large language model to use tools via self-instruction
NeurIPS2023-5-30GithubProject
ToolkenGPTStar
ToolkenGPT: Augmenting frozen language models with massive tools via tool embeddings
NeurIPS2023-5-19GithubProject
ChameleonStar
Chameleon: Plug-and-play compositional reasoning with large language models
NeurIPS2023-4-19GithubProject
HuggingGPTStar
HuggingGPT: Solving AI Tasks with ChatGPT and its Friends in Hugging Face
NeurIPS2023-3-30GithubProject
TaskMatrix.AITaskMatrix.AI: Completing tasks by connecting foundation models with millions of APIsIntelligent Computing (AAAS)2023-3-29GithubProjecct
MM-ReACTStar
MM-ReACT: Prompting ChatGPT for Multimodal Reasoning and Action
arXiv2023-3-20GithubProject
ViperGPTStar
ViperGPT: Visual Inference via Python Execution for Reasoning
ICCV2023-3-14GithubProject
MIND’S EYEMIND’S EYE: GROUNDED LANGUAGE MODEL REASONING THROUGH SIMULATIONarXiv2022-10-11GitHubProject

🎯Back to Top

Text-to-vision

Text-to-image

NameTitleVenueDateCodeProject
FLUX.1 KontextStar
FLUX.1 Kontext: Flow Matching for In-Context Image Generation and Editing in Latent Space
ArXiv2025-6-17GitHubProject
BAGELStar
Emerging Properties in Unified Multimodal Pretraining
ArXiv2025-5-23GitHubProject
X-FusionX-Fusion: Introducing New Modality to Frozen Large Language ModelsICCV2025-4-29GitHubProject
Janus-ProStar
Janus-Pro: Unified Multimodal Understanding and Generation with Data and Model Scaling
ArXiv2025-1-29GitHubProject
JanusFlowStar
JanusFlow: Harmonizing Autoregression and Rectified Flow for Unified Multimodal Understanding and Generation
ArXiv2024-11-12GitHubProject
JanusStar
Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation
ArXiv2024-10-17GitHubProject
FLUX.1Star
FLUX
None2024-8-1GitHubProject
LLMGAStar
LLMGA: Multimodal Large Language Model based Generation Assistant
ECCV2024-7-27GitHubProject
EmuStar
Generative pretraining in multimodality,
ICLR2024-5-8GitHubProject
Kosmos-GKosmos-G: Generating Images in Context with Multimodal Large Language ModelsICLR2024-4-26GitHubProject
LaVITStar
Unified Language-Vision Pretraining in LLM with Dynamic Discrete Visual Tokenization
ICLR2024-3-22GitHubProject
MiniGPT-5Star
MiniGPT-5: Interleaved Vision-and-Language Generation via Generative Vokens
ArXiv2024-3-15GitHubProject
LMDStar
LLM-grounded Diffusion: Enhancing Prompt Understanding of Text-to-Image Diffusion Models with Large Language Models
TMLR2024-3-4GitHubProject
DiffusionGPTStar
DiffusionGPT: LLM-Driven Text-to-Image Generation System
ArXiv2024-1-18GitHubProject
VL-GPTStar
VL-GPT: A Generative Pre-trained Transformer for Vision and Language Understanding and Generation
ArXiv2023-12-4GitHubProject
CoDi-2Star
CoDi-2: In-Context, Interleaved, and Interactive Any-to-Any Generation
CVPR2023-11-30GitHubProject
SEED-LLAMAStar
Making LLaMA SEE and Draw with SEED Tokenizer
CVPR2023-10-3GitHubProject
JAMJointly Training Large Autoregressive Multimodal ModelsICLR2023-9-28GitHubProject
CM3LeonScaling Autoregressive Multi-Modal Models: Pretraining and Instruction TuningArXiv2023-9-5GitHubProject
SEEDStar
Planting a SEED of Vision in Large Language Model
ICLR2023-8-12GitHubProject
GILLStar
Generating Images with Multimodal Language Models
NeurlPS2023-5-26GitHubProject

🎯Back to Top

Text-to-3D

🎯Back to Top

Text-to-video

🎯Back to Top

Other applications

Face

🎯Back to Top

Anomaly Detetcion

🎯Back to Top

Gaming

🎯Back to Top

Challenges

Efficiency

NameTitleVenueDateCodeProject
WiCoStar
Window Token Concatenation for Efficient Visual Large Language Models
CVPRW2025-4-5GithubProject
DARTStop Looking for “Important Tokens” in Multimodal Language Models: Duplication Matters MoreArXiv2025-2-17GithubProject
LLaVA-MiniStar
LLaVA-Mini: Efficient Image and Video Large Multimodal Models with One Vision Token
ICLR2025-1-7GithubProject
Dynamic-VLMDynamic-VLM: Simple Dynamic Visual Token Compression for VideoLLMArXiv2024-12-12GithubProject
PVCStar
PVC: Progressive Visual Token Compression for Unified Image and Video Processing in Large Vision-Language Models
ArXiv2024-12-12GithubProject
iLLaVAStar
iLLaVA: An Image is Worth Fewer Than 1/3 Input Tokens in Large Multimodal Models
ArXiv2024-12-8GithubProject
VTC-CLSStar
[CLS] Token Tells Everything Needed for Training-free Efficient MLLMs
ArXiv2024-12-8GithubProject
NegToMeStar
Negative Token Merging: Image-based Adversarial Feature Guidance
ArXiv2024-12-5GithubProject
VisionZipStar
VisionZip: Longer is Better but Not Necessary in Vision Language Models
ArXiv2024-12-5GithubProject
AIMStar
AIM: Adaptive Inference of Multi-Modal LLMs via Token Merging and Pruning
ArXiv2024-12-4GithubProject
Dynamic-LLaVAStar
Dynamic-LLaVA: Efficient Multimodal Large Language Models via Dynamic Vision-language Context Sparsification
ArXiv2024-12-3GithubProject
ATP-LLaVAATP-LLaVA: Adaptive Token Pruning for Large Vision Language ModelsArXiv2024-11-30GithubProject
YOPOStar
Treat Visual Tokens as Text? But Your MLLM Only Needs Fewer Efforts to See
ArXiv2024-11-30GithubProject
DyCokeStar
DyCoke: Dynamic Compression of Tokens for Fast Video Large Language Models
ArXiv2024-11-22GithubProject
LLaVA-MRLLaVA-MR: Large Language-and-Vision Assistant for Video Moment RetrievalArXiv2024-11-21GithubProject
FoPruFoPru: Focal Pruning for Efficient Large Vision-Language ModelsArXiv2024-11-21GithubProject
FocusLLaVAFocusLLaVA: A Coarse-to-Fine Approach for Efficient and Effective Visual Token CompressionArXiv2024-11-21GithubProject
RLTStar
Don't Look Twice: Faster Video Transformers with Run-Length Tokenization
NeurlPS2024-11-7GithubProject
LLaVoltaStar
Efficient Large Multi-modal Models via Visual Context Compression
NeurlPS2024-11-6GithubProject
QueCCStar
Inference Optimal VLMs Need Only One Visual Token but Larger Models
ArXiv2024-11-5GithubProject
PyramidDropStar
PyramidDrop: Accelerating Your Large Vision-Language Models via Pyramid Visual Redundancy Reduction
ArXiv2024-10-22GithubProject
VictorEfficient Vision-Language Models by Summarizing Visual Tokens into Compact RegistersArXiv2024-10-17GithubProject
AVG-LLaVAStar
AVG-LLaVA: A Large Multimodal Model with Adaptive Visual Granularity
ArXiv2024-10-4GithubProject
TRIMStar
Less is More: A Simple yet Effective Token Reduction Method for Efficient Multi-modal LLMs
COLING2024-9-28GithubProject
TokenPackerStar
TokenPacker: Efficient Visual Projector for Multimodal LLM
ArXiv2024-8-28GithubProject
MaVEnMaVEn: An Effective Multi-granularity Hybrid Visual Encoding Framework for Multimodal Large Language ModelNeurlPS2024-8-26GithubProject
HiREDStar
HiRED: Attention-Guided Token Dropping for Efficient Inference of High-Resolution Vision-Language Models in Resource-Constrained Environments
AAAI2024-8-20GithubProject
VoCo-LLaMAStar
VoCo-LLaMA: Towards Vision Compression with Large Language Models
ArXiv2024-6-18GithubProject
DeCoStar
DeCo: Decoupling Token Compression from Semantic Abstraction in Multimodal Large Language Models
ArXiv2024-5-31GithubProject
LLaVA-PruMergeStar
LLaVA-PruMerge: Adaptive Token Reduction for Efficient Large Multimodal Models
ArXiv2024-5-22GithubProject
FastVStar
An Image is Worth 1/2 Tokens After Layer 2: Plug-and-Play Inference Acceleration for Large Vision-Language Models
ECCV2024-5-5GithubProject
LLaVA-HRStar
HFeast Your Eyes: Mixture-of-Resolution Adaptation for Multimodal Large Language Models
ArXiv2024-3-5GithubProject

🎯Back to Top

Security

🎯Back to Top

Interpretability and explainability

NameTitleVenueDateCodeProject
EAGLEStar
Where MLLMs Attend and What They Rely On: Explaining Autoregressive Token Generation
CVPR2026-02-21GithubProject
TAMStar
Token Activation Map to Visually Explain Multimodal LLMs
ICCV2025-06-29GithubProject
IGOS++ (w/ GNC)Star
Where do Large Vision-Language Models Look at when Answering Questions?
ArXiv2025-03-18GithubProject
LLaVA-CAMStar
From Redundancy to Relevance: Information Flow in LVLMs Across Reasoning Tasks
NAACL2025GithubProject
MultiTrustStar
MULTITRUST: A Comprehensive Benchmark Towards Trustworthy Multimodal Large Language Models
ArXiv2024-12-6GithubProject
XL-VLMsStar
A Concept-Based Explainability Framework for Large Multimodal Models
NeurlPS2024-11-30GithubProject
VPSStar
Interpreting Object-level Foundation Models via Visual Precision Search
Arxiv2024-11-25GithubProject
SAE
Large Multi-modal Models Can Interpret Features in Large Multi-modal Models
ArXiv2024-11-22GithubProject
MLLM-Probe
Probing Multimodal Large Language Models for Global and Local Semantic Representations
ArXiv2024-11-21GithubProject
LexVLAStar
Unified Lexical Representation for Interpretable Visual-Language Alignment
NeurlPS2024-11-11GithubProject
MUBStar
Exploring Response Uncertainty in MLLMs: An Empirical Evaluation under Misleading Scenarios
ArXiv2024-11-5GithubProject
LLaVA-CAMStar
From Redundancy to Relevance: Information Flow in LVLMs Across Reasoning Tasks
ArXiv2024-10-17GithubProject
LLaVA-InterpStar
Towards Interpreting Visual Information Processing in Vision-Language Models
ArXiv2024-10-9GithubProject
MINERStar
MINER: Mining the Underlying Pattern of Modality-Specific Neurons in Multimodal Large Language Models
ArXiv2024-10-7GithubProject
VL-InterpretStar
Interpreting and Editing Vision-Language Representations to Mitigate Hallucinations
ArXiv2024-10-3GithubProject
MMNeuronStar
MMNeuron: Discovering Neuron-Level Domain-Specific Interpretation in Multimodal Large Language Model
ArXiv2024-10-1GithubProject
MLLM-ONTOStar
Enhancing Explainability in Multimodal Large Language Models Using Ontological Context
ArXiv2024-9-27GithubProject
EAGLEStar
Eagle: Exploring The Design Space for Multimodal LLMs with Mixture of Encoders
ArXiv2024-8-28GithubProject
MLLM-LawStar
Law of Vision Representation in MLLMs
ArXiv2024-8-24CodeProject
VALEVALE: A Multimodal Visual and Language Explanation Framework for Image Classifiers using eXplainable AI and Language ModelsArXiv2024-8-23CodeProject
DistTrainDistTrain: Addressing Model and Data Heterogeneity with Disaggregated Training for Multimodal Large Language ModelsArXiv2024-8-15GithubProject
MLLM-ProjectionStar
Cross-Modal Projection in Multimodal LLMs Doesn’t Really Project Visual Attributes to Textual Space
ArXiv2024-8-9GithubProject
Reason2DriveStar
Reason2Drive: Towards Interpretable and Chain-based Reasoning for Autonomous Driving
ECCV2024-7-20GithubProject
LVLM-LPStar
The First to Know: How Token Distributions Reveal Hidden Knowledge in Large Vision-Language Models?
ECCV2024-7-17GithubProject
CLIP-NeuronsStar
Interpreting the Second-Order Effects of Neurons in CLIP
ArXiv2024-6-24GithubProject
LVLM-InterpretStar
LVLM-Interpret: An Interpretability Tool for Large Vision-Language Models
ArXiv2024-6-24GithubProject
Holmes-VADHolmes-VAD: Towards Unbiased and Explainable Video Anomaly Detection via Multi-modal LLMArXiv2024-6-18GithubProject
MMNeuronsStar
Finding and Editing Multi-Modal Neurons in Pre-Trained Transformers
ACL2024-6-11GithubProject
DeCoStar
DeCo: Decoupling Token Compression from Semantic Abstraction in Multimodal Large Language Models
ICML2024-5-31GithubProject
MAIAStar
A Multimodal Automated Interpretability Agent
ICML2024-4-22GithubProject
CDLStar
Pre-trained Vision-Language Models Learn Discoverable Visual Concepts
ArXiv2024-4-19GithubProject
OLIVEStar
What Are We Measuring When We Evaluate Large Vision-Language Models? An Analysis of Latent Factors and Biases
NAACL2024-4-3GithubProject
OPERAStar
OPERA: Alleviating Hallucination in Multi-Modal Large Language Models via Over-Trust Penalty and Retrospection-Allocation
CVPR2024-3-12GithubProject
RLHF-VStar
RLHF-V: Towards Trustworthy MLLMs via Behavior Alignment from Fine-grained Correctional Human Feedback
CVPR2024-3-8GithubProject
HA-DPOStar
Aligning Modalities in Vision Large Language Models via Preference Fine-tuning
ArXiv2024-2-18GithubProject
HA-DPOStar
Beyond Hallucinations: Enhancing LVLMs through Hallucination-Aware Direct Preference Optimization
ArXiv2024-2-6GithubProject
BenchLMMStar
BenchLMM: Benchmarking Cross-style Visual Capability of Large Multimodal Models
ECCV2023-12-6GithubProject
VCDStar
VCD: Mitigating Object Hallucinations in Large Vision-Language Models through Visual Contrastive Decoding
CVPR2023-11-28GithubProject
LLaVA-RLHFStar
LLaVA-RLHF: Aligning Large Multimodal Models with Factually Augmented RLHF
ArXiv2023-9-25GithubProject

🎯Back to Top

Complex reasoning

NameTitleVenueDateCodeProject
FEALLMStar
FEALLM: Advancing Facial Emotion Analysis in Multimodal Large Language Models with Emotional Synergy and Reasoning
ArXiv2025-5-19GithubProject
VisionReasonerStar
VisionReasoner: Unified Visual Perception and Reasoning via Reinforcement Learning
ArXiv2025-5-17GithubProject
Skywork R1V2Star
Skywork R1V2: Multimodal Hybrid Reinforcement Learning for Reasoning
ArXiv2025-4-23GithubProject
VisuLogicStar
VisuLogic: A Benchmark for Evaluating Visual Reasoning in Multi-modal Large Language Models
ArXiv2025-4-21GithubProject
Embodied-REmbodied-R: Collaborative Framework for Activating Embodied Spatial Reasoning in Foundation Models via Reinforcement LearningArXiv2025-4-17GithubProject
ThinkLite-VLStar
SoTA with Less: MCTS-Guided Sample Selection for Data-Efficient Visual Reasoning Self-Improvement
ArXiv2025-4-10GithubProject
Video-R1Star
Video-R1: Reinforcing Video Reasoning in MLLMs
Github2025-3-27GithubProject
Easy-R1Star
EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework
Github2025-3-19GithubProject
MedVLM-R1MedVLM-R1: Incentivizing Medical Reasoning Capability of Vision-Language Models (VLMs) via Reinforcement LearningArXiv2025-3-19GithubProject
Skywork R1VStar
Skywork R1V: Pioneering Multimodal Reasoning with Chain-of-Thought
GitHub2025-3-18GithubProject
TimeZeroStar
TimeZero: Temporal Video Grounding with Reasoning-Guided LVLM
ArXiv2025-3-17GithubProject
R1-VLStar
R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization
ArXiv2025-3-17GithubProject
VisualPRMVisualPRM: An Effective Process Reward Model for Multimodal ReasoningArXiv2025-3-13GithubProject
LMM-R1Star
LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL
ArXiv2025-3-11GithubProject
VisualThinker-R1-ZeroStar
R1-Zero's “Aha Moment” in Visual Reasoning on a 2B Non-SFT Mode
ArXiv2025-3-10GithubProject
R1-OmniStar
R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning
ArXiv2025-3-10GithubProject
Vision-R1Star
Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models
ArXiv2025-3-9GithubProject
Seg-ZeroStar
Seg-Zero: Reasoning-Chain Guided Segmentation via Cognitive Reinforcement
ArXiv2025-3-9GithubProject
MM-EUREKAStar
MM-EUREKA: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning
Github2025-3-7GithubProject
Visual-RFTStar
Visual-RFT: Visual Reinforcement Fine-Tuning
ArXiv2025-3-3GithubProject
VLM-R1Star
VLM-R1: A stable and generalizable R1-style Large Vision-Language Model
None2025-2-15GithubProject
R1-VStar
R1-V: Reinforcing Super Generalization Ability in Vision Language Models with Less Than $3
Blog2025-2-3GithubProject
TPOStar
Temporal Preference Optimization for Long-Form Video Understanding
ArXiv2025-1-10GithubProject
LlamaV-o1Star
LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLMs
ArXiv2025-1-10GithubProject
InternVL2-MPOStar
Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization
ArXiv2025-1-10GithubProject
VirgoStar
Virgo: A Preliminary Exploration on Reproducing o1-like MLLM
ArXiv2025-1-3GithubProject
MulberryStar
Mulberry: Empowering mllm with o1-like reasoning and reflection via collective monte carlo tree search
ArXiv2024-12-31GithubProject
LLaVA-CoTStar
LLaVA-CoT: Let Vision Language Models Reason Step-by-Step
ArXiv2024-11-25GithubProject

🎯Back to Top

Contributors

Thanks to all the contributors! You are awesome!

Star history

Star History Chart
application
embodied
llm
mllm
reasoning-agent
survey
vllm
vlm
vqa

Contributors

JackYFL

204 commits

Cogito2012

6 commits

Zhen-Tan-dmml

4 commits

mghiasvand1

3 commits

JackYFL/awesome-VLLMs

This repository collects papers on VLLM applications. We will update new papers irregularly.

221

229 commits

updated Feb 23, 2026

See the code

README

Awesome Visual Large Language Models (VLLMs)

Maintenance Awesome PR's Welcome

🔥🔥🔥 Visual Large Language Models for Generalized and Specialized Applications
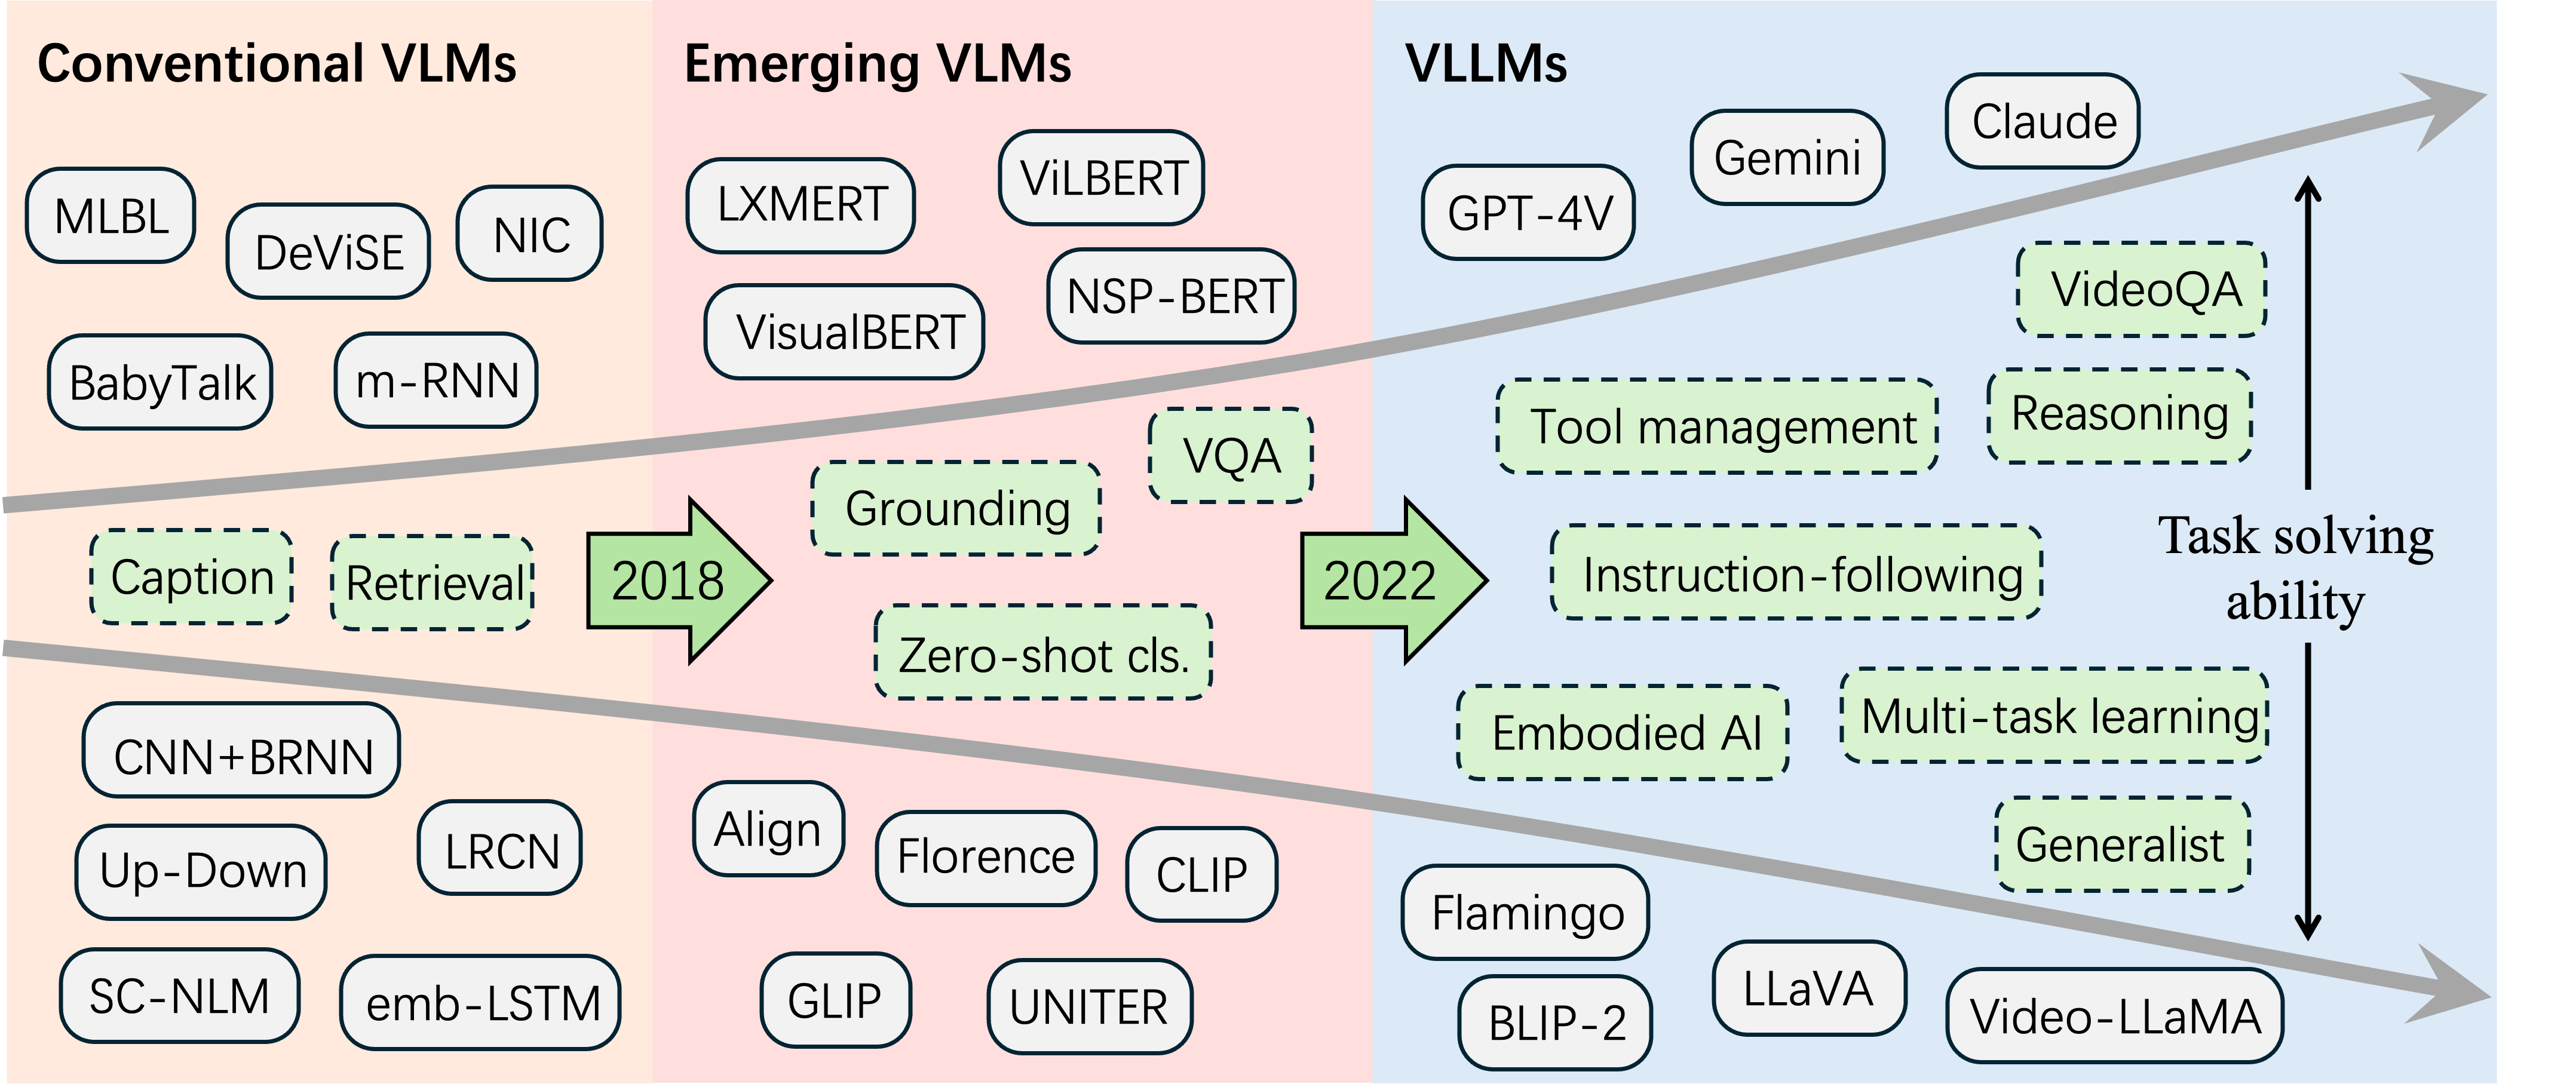
Vision language models (VLMs) have emerged as powerful tools for learning unified embedding spaces that integrate vision and language. Inspired by the success of large language models (LLMs), which have demonstrated remarkable reasoning and multi-task capabilities, visual large language models (VLLMs) are gaining significant attention for developing both general-purpose and specialized VLMs.

In this repository, we provide a comprehensive summary of the current literature from an application-oriented perspective. We hope this resource serves as a valuable reference for the VLLM research community.

If you are interested in this project, you can contribute to this repo by pulling requests 😊😊😊

If you think our paper is helpful for your research, you can cite through this bib tex entry!

@article{li2025visual,
  title={Visual Large Language Models for Generalized and Specialized Applications},
  author={Li, Yifan and Lai, Zhixin and Bao, Wentao and Tan, Zhen and Dao, Anh and Sui, Kewei and Shen, Jiayi and Liu, Dong and Liu, Huan and Kong, Yu},
  journal={arXiv preprint arXiv:2501.02765},
  year={2025}
}

📢 News

🚀 What's New in This Update:

  • [2026.2.23]: 🔥 Adding three papers on VLLM explanation! Thanks Ruoyu!
  • [2025.7.28]: 🔥 Adding five papers on autonomous driving, vision generation and video understanding!
  • [2025.4.25]: 🔥 Adding eleven papers on complex reasoning, face, video understanding and medical!
  • [2025.4.18]: 🔥 Adding three papers on complex reasoning!
  • [2025.4.12]: 🔥 Adding one paper on complex reasoning and one paper on efficiency!
  • [2025.3.20]: 🔥 Adding eleven papers and 1 wonderful repo on complex reasoning!
  • [2025.3.10]: 🔥 Adding three papers on complex reasoning, efficiency and face!
  • [2025.3.6]: 🔥 Adding one paper on complex reasoning!
  • [2025.3.2]: 🔥 Adding two projects on complex reasoning: R1-V and VLM-R1!
  • [2025.2.23]: 🔥 Adding one video-to-action paper and one vision-to-text paper!
  • [2025.2.1]: 🔥 Adding four video-to-text papers!
  • [2025.1.22]: 🔥 Adding one video-to-text paper!
  • [2025.1.17]: 🔥 Adding three video-to-text papers, thanks for the contributions from Enxin!
  • [2025.1.14]: 🔥 Adding two complex reasoning papers and one video-to-text paper!
  • [2025.1.13]: 🔥 Adding one VFM survey paper!
  • [2025.1.12]: 🔥 Adding one efficient MLLM paper!
  • [2025.1.9]: 🔥🔥🔥 Adding one efficient MLLM survey!
  • [2025.1.7]: 🔥🔥🔥 Our survey paper is released! Please check this link for more information. We add more tool management papers in our paper list.
  • [2025.1.6]: 🔥 We add one OS Agent survey paper in our paper list, and a new category: complex reasoning!
  • [2025.1.4]: 🔥 We updated the general domain and egocentric video papers in our paper list, thanks for the contributions from Wentao!
  • [2025.1.2]: 🔥 We add more interpretation papers to our paper list, thanks for the contributions from Ruoyu!
  • [2024.12.15]: 🔥 We release our VLLM application paper list repo!

:rainbow: Table of Contents

Existing VLM surveys

VLM surveys

🎯Back to Top

MLLM surveys

TitleVenueDateCodeProject
OS Agents: A Survey on MLLM-based Agents for General Computing Devices Use
ArXiv2024-12-27GithubProject
Towards Explainable and Interpretable Multimodal Large Language Models: A Comprehensive Survey
ArXiv2024-12-3GithubProject
Star
A Survey on Multimodal Large Language Models
T-PAMI2024-11-29GithubProject
Star
MME-Survey: A Comprehensive Survey on Evaluation of Multimodal LLMs
ArXiv2024-11-22GithubProject
A Survey on Multimodal Large Language Models
National Science Review2024-11-12GithubProject
Video Understanding with Large Language Models: A Survey
ArXiv2024-6-24GithubProject
Star
A Survey on Multimodal Benchmarks: In the Era of Large AI Models
ArXiv2024-9-21GithubProject
Star
The Revolution of Multimodal Large Language Models: A Survey
ArXiv2024-6-6GithubProject
Star
Efficient Multimodal Large Language Models: A Survey
ArXiv2024-5-17GithubProject
Star
A Survey on Hallucination in Large Vision-Language Models
ArXiv2024-5-6GithubProject
Star
Hallucination of multimodal large language models: A survey
ArXiv2024-4-29GithubProject
Exploring the Frontier of Vision-Language Models: A Survey of Current Methodologies and Future Directions
ArXiv2024-4-12GithubProject
Star
MM-LLMs: Recent Advances in MultiModal Large Language Models
ArXiv2024-2-20GithubProject
Exploring the Reasoning Abilities of Multimodallarge Language Models (mllms): a Comprehensive survey on Emerging Trends in Multimodal Reasonings
ArXiv2024-1-18GithubProject
Visual Instruction Tuning towards General-Purpose Multimodal Model: A Survey
ArXiv2023-12-27GithubProject
Multimodal Large Language Models: A Survey
BigData2023-12-15GithubProject

🎯Back to Top

Vision-to-text

Image-to-text

General domain

General ability
NameTitleVenueDateCodeProject
UniMEStar
Breaking the Modality Barrier: Universal Embedding Learning with Multimodal LLMs
ArXiv2025-4-24GithubProject
InternVL2.5Star
Expanding Performance Boundaries of Open-Source Multimodal Models with Model, Data, and Test-Time Scaling
ArXiv2024-12-17GithubProject
CompCapCompCap: Improving Multimodal Large Language Models with Composite CaptionsArXiv2024-12-06GithubProject
NVILANVILA: Efficient Frontier Visual Language ModelsArXiv2024-12-05GithubProject
Molmo and PixMoStar
Molmo and PixMo: Open Weights and Open Data for State-of-the-Art Vision-Language Models
ArXiv2024-09-25GithubProject
Qwen2-VLStar
Qwen2-VL: Enhancing Vision-Language Model’s Perception of the World at Any Resolution
ArXiv2024-09-18GithubProject
mPLUG-Owl3Star
mPLUG-Owl3: Towards Long Image-Sequence Understanding in Multi-Modal Large Language Models
ArXiv2024-08-09GithubProject
LLaVA-OneVisionStar
LLaVA-OneVision: Easy Visual Task Transfer
ArXiv2024-08-06GithubProject
VILA$^{2}$VILA $^2$: VILA Augmented VILAArXiv2024-07-24GithubProject
EVLMEVLM: An Efficient Vision-Language Model for Visual UnderstandingArXiv2024-07-19GithubProject
MG-LLaVAMG-LLaVA: Towards Multi-Granularity Visual Instruction TuningArXiv2024-06-27GithubProject
Cambrian-1Star
Cambrian-1: A Fully Open, Vision-Centric Exploration of Multimodal LLMs
ArXiv2024-06-24GithubProject
OvisStar
Ovis: Structural Embedding Alignment for Multimodal Large Language Model
ArXiv2024-05-31GithubProject
ConvLLaVAStar
ConvLLaVA: Hierarchical Backbones as Visual Encoder for Large Multimodal Models
ArXiv2024-05-24GithubProject
MeteorStar
Meteor: Mamba-based Traversal of Rationale for Large Language and Vision Models
NeurIPS2024-05-24GithubProject
CuMoStar
CuMo: Scaling Multimodal LLM with Co-Upcycled Mixture-of-Experts
ArXiv2024-05-09GithubProject
Mini-GeminiStar
Mini-Gemini: Mining the Potential of Multi-modality Vision Language Models
ArXiv2024-03-27GithubProject
MM1MM1: Methods, Analysis & Insights from Multimodal LLM Pre-trainingArXiv2024-03-14GithubProject
DeepSeek-VLStar
DeepSeek-VL: Towards Real-World Vision-Language Understanding
ArXiv2024-03-08GithubProject
InternLM-XComposer2Star
InternLM-XComposer2: Mastering Free-form Text-Image Composition and Comprehension in Vision-Language Large Model
ArXiv2024-01-29GithubProject
MoE-LLaVAStar
MoE-LLaVA: Mixture of Experts for Large Vision-Language Models
ArXiv2024-01-29GithubProject
InternVLStar
InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks
CVPR2023-12-21GithubProject
VILAStar
VILA: On Pre-training for Visual Language Models
ArXiv2023-12-12GithubProject
VaryStar
Vary: Scaling up the Vision Vocabulary for Large Vision-Language Models
ECCV2023-12-11GithubProject
HoneybeeStar
Honeybee: Locality-enhanced Projector for Multimodal LLM
CVPR2023-11-11GithubProject
OtterHDStar
OtterHD: A High-Resolution Multi-modality Model
ArXiv2023-11-07GithubProject
mPLUG-Owl2Star
mPLUG-Owl2: Revolutionizing Multi-modal Large Language Model with Modality Collaboration
CVPR2023-11-07GithubProject
FuyuStar
Fuyu-8B: A Multimodal Architecture for AI Agents
ArXiv2023-10-17GithubProject
MiniGPT-v2Star
MiniGPT-v2: large language model as a unified interface for vision-language multi-task learning
ArXiv2023-10-14GithubProject
LLaVA 1.5Star
Improved Baselines with Visual Instruction Tuning
ArXiv2023-10-05GithubProject
InternLM-XComposerStar
InternLM-XComposer: A Vision-Language Large Model for Advanced Text-image Comprehension and Composition
ArXiv2023-09-26GithubProject
Qwen-VLStar
Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond
ArXiv2023-08-24GithubProject
StableLLaVAStar
StableLLaVA: Enhanced Visual Instruction Tuning with Synthesized Image-Dialogue Data
ArXiv2023-08-20GithubProject
BLIVAStar
BLIVA: A Simple Multimodal LLM for Better Handling of Text-Rich Visual Questions
AAAI2023-08-19GithubProject
SVITStar
SVIT: Scaling up Visual Instruction Tuning
ArXiv2023-07-09GithubProject
LaVINStar
Cheap and Quick: Efficient Vision-Language Instruction Tuning for Large Language Models
NeurIPS2023-05-24GithubProject
InstructBLIPStar
InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning
NeurIPS2023-05-11GithubProject
MultiModal-GPTStar
MultiModal-GPT: A Vision and Language Model for Dialogue with Humans
ArXiv2023-05-08GithubProject
OtterStar
Otter: A Multi-Modal Model with In-Context Instruction Tuning
ArXiv2023-05-05GithubProject
mPLUG-OwlStar
mPLUG-Owl: Modularization Empowers Large Language Models with Multimodality
ArXiv2023-04-27GithubProject
LLaMA-Adapter V2Star
LLaMA-Adapter V2: Parameter-Efficient Visual Instruction Model
ArXiv2023-04-28GithubProject
MiniGPT-4Star
MiniGPT-4: Enhancing Vision-Language Understanding with Advanced Large Language Models
NeurIPS2023-04-20GithubProject
LLaVAStar
Visual Instruction Tuning
NeurIPS2023-04-17GithubProject
LLaMA-AdapterStar
LLaMA-Adapter: Efficient Fine-tuning of Large Language Models with Zero-initialized Attention
ICLR2023-03-28GithubProject
Kosmos-1Star
Language Is Not All You Need: Aligning Perception with Language Models
NeurIPS2023-02-27GithubProject
FlamingoStar
Flamingo: a Visual Language Model for Few-Shot Learning
NeurIPS2022-04-29GithubProject

🎯Back to Top

REC
NameTitleVenueDateCodeProject
ChatRexStar
ChatRex: Taming Multimodal LLM for Joint Perception and Understanding
ArXiv2024-11-27GithubProject
Griffon-GStar
Griffon-G: Bridging Vision-Language and Vision-Centric Tasks via Large Multimodal Models
ArXiv2024-10-21GithubProject
FerretStar
Ferret: Refer and Ground Anything Anywhere at Any Granularity
ICLR2024-10-11GithubProject
OMG-LLaVAStar
OMG-LLaVA: Bridging Image-level, Object-level, Pixel-level Reasoning and Understanding
NeurIPS2024-06-27GithubProject
VisionLLMv2Star
VisionLLM v2: An End-to-End Generalist Multimodal Large Language Model for Hundreds of Vision-Language Tasks
ArXiv2024-06-12GithubProject
GromaStar
Groma: Localized Visual Tokenization for Grounding Multimodal Large Language Models
ECCV2024-04-19GithubProject
Griffonv2Star
Griffon v2: Advancing Multimodal Perception with High-Resolution Scaling and Visual-Language Co-Referring
ArXiv2024-03-14GithubProject
ASMv2Star
The All-Seeing Project V2: Towards General Relation Comprehension of the Open World
ECCV2024-02-29GithubProject
SPHINX-XSPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language ModelsArXiv2024-02-08GithubProject
ChatterBoxStar
ChatterBox: Multi-round Multimodal Referring and Grounding
ArXiv2024-01-24GithubProject
LEGOStar
LEGO: Language Enhanced Multi-modal Grounding Model
ArXiv2024-01-12GithubProject
GroundingGPTStar
GroundingGPT: Language Enhanced Multi-modal Grounding Model
ACL2024-01-11GithubProject
BuboGPTStar
BuboGPT: Enabling Visual Grounding in Multi-Modal LLMs
ArXiv2024-07-17GithubProject
Ferret-v2Star
Ferret-v2: An Improved Baseline for Referring and Grounding with Large Language Models
COLM2024-04-11GithubProject
InfMLLMStar
InfLLM: Training-Free Long-Context Extrapolation for LLMs with an Efficient Context Memory
NeurIPS2024-02-07GithubProject
VistaLLMJack of All Tasks, Master of Many: Designing General-purpose Coarse-to-Fine Vision-Language ModelECCV2023-12-19GithubProject
LLaVA-GroundingStar
LLaVA-Grounding: Grounded Visual Chat with Large Multimodal Models
ArXiv2023-12-05GithubProject
LennaStar
Lenna: Language Enhanced Reasoning Detection Assistant
ArXiv2023-12-05GithubProject
GriffonStar
Griffon: Spelling out All Object Locations at Any Granularity with Large Language Models
ECCV2023-11-24GithubProject
LionStar
Lion: Empowering multimodal large language model with dual-level visual knowledge
CVPR2023-11-20GithubProject
SPHINXSPHINX: The Joint Mixing of Weights, Tasks, and Visual Embeddings for Multi-modal Large Language ModelsArXiv2023-11-13GithubProject
NExT-ChatStar
NExT-Chat: An LMM for Chat, Detection and Segmentation
ArXiv2023-11-08GithubProject
GLaMMStar
GLaMM: Pixel Grounding Large Multimodal Model
CVPR2023-11-06GithubProject
CogVLMStar
CogVLM: Visual Expert for Pretrained Language Models
ArXiv2023-11-06GithubProject
PinkStar
Pink: Unveiling the Power of Referential Comprehension for Multi-modal LLMs
CVPR2023-10-01GithubProject
PVITStar
Position-Enhanced Visual Instruction Tuning for Multimodal Large Language Models
ArXiv2023-08-25GithubProject
ASMStar
The all-seeing project: Towards panoptic visual recognition and understanding of the open world
ICLR2023-08-03GithubProject
ShikraStar
Shikra: Unleashing Multimodal LLM's Referential Dialogue Magic
ArXiv2023-06-27GithubProject
Kosmos-2Star
KOSMOS-2: Grounding Multimodal Large LanguageModels to the World
ICLR2023-06-26GithubProject
ChatSpotStar
ChatSpot: Bootstrapping Multimodal LLMs via Precise Referring Instruction Tuning
ArXiv2023-07-18GithubProject
GPT4RoIStar
GPT4RoI: Instruction Tuning Large Language Model on Region-of-Interest
IJCAI2023-07-07GithubProject
ContextDETStar
Contextual Object Detection with Multimodal Large Language Models
ArXiv2023-05-29GithubProject
DetGPTStar
DetGPT: Detect What You Need via Reasoning
ArXiv2023-05-23GithubProject
VisionLLMStar
VisionLLM: Large Language Model is also an Open-Ended Decoder for Vision-Centric Tasks
ArXiv2023-05-18GithubProject

🎯Back to Top

RES
NameTitleVenueDateCodeProject
SpectrumLearning 3D Texture-Aware Representations for Parsing Diverse Human Clothing and Body PartsAAAI2025-12-18GithubProject
OMG-LLaVAStar
OMG-LLaVA: Bridging Image-level, Object-level, Pixel-level Reasoning and Understanding
NeurIPS2024-06-27GithubProject
VisionLLMv2Star
VisionLLM v2: An End-to-End Generalist Multimodal Large Language Model for Hundreds of Vision-Language Tasks
ArXiv2024-06-12GithubProject
LLM-SegLLM-Seg: Bridging Image Segmentation and Large Language Model ReasoningCVPR2024-04-12GithubProject
PSALMStar
PSALM: Pixelwise SegmentAtion with Large Multi-Modal Model
ECCV2024-03-21GithubProject
GROUNDHOGStar
GROUNDHOG: Grounding Large Language Models to Holistic Segmentation
CVPR2024-02-26GithubProject
GELLAGeneralizable Entity Grounding via Assistance of Large Language ModelECCV2024-02-04GithubProject
OMG-SegStar
OMG-Seg: Is One Model Good Enough For All Segmentation?
CVPR2024-01-18GithubProject
LISA++Star
LISA++: An Improved Baseline for Reasoning Segmentation with Large Language Model
ArXiv2023-12-28GithubProject
VistaLLMStar
Jack of All Tasks, Master of Many: Designing General-purpose Coarse-to-Fine Vision-Language Model
ECCV2023-12-19GithubProject
OspreyStar
Osprey: Pixel Understanding with Visual Instruction Tuning
CVPR2023-12-15GithubProject
GSVAStar
GSVA: Generalized Segmentation via Multimodal Large Language Models
CVPR2023-12-05GithubProject
PixelLMStar
PixelLM: Pixel Reasoning with Large Multimodal Model
CVPR2023-12-04GithubProject
PixelLLMStar
PixelLM: Pixel Reasoning with Large Multimodal Model
ECCV2023-12-04GithubProject
LLaFSStar
LLaFS: When Large Language Models Meet Few-Shot Segmentation
CVPR2023-11-28GithubProject
NExT-ChatStar
NExT-Chat: An LMM for Chat, Detection and Segmentation
ArXiv2023-11-08GithubProject
GLaMMStar
GLaMM: Pixel Grounding Large Multimodal Model
CVPR2023-11-06GithubProject
LISAStar
LISA: Reasoning Segmentation via Large Language Model
CVPR2023-08-01GithubProject
ContextDETStar
Contextual Object Detection with Multimodal Large Language Models
ArXiv2023-05-29GithubProject
VisionLLMStar
VisionLLM: Large Language Model is also an Open-Ended Decoder for Vision-Centric Tasks
ArXiv2023-05-18GithubProject

🎯Back to Top

OCR
NameTitleVenueDateCodeProject
TextHawk2Star
TextHawk2: A Large Vision-Language Model Excels in Bilingual OCR and Grounding with 16x Fewer Tokens
ArXiv2024-10-07GithubProject
DockylinStar
DocKylin: A Large Multimodal Model for Visual Document Understanding with Efficient Visual Slimming
AAAI2024-06-27GithubProject
StrucTexTv3StrucTexTv3: An Efficient Vision-Language Model for Text-rich Image Perception, Comprehension, and BeyondArXiv2024-05-31GithubProject
FoxStar
Focus Anywhere for Fine-grained Multi-page Document Understanding
ArXiv2024-05-23GithubProject
TextMonkeyStar
TextMonkey: An OCR-Free Large Multimodal Model for Understanding Document
ArXiv2024-05-07GithubProject
TinyChartStar
TinyChart: Efficient Chart Understanding with Visual Token Merging and Program-of-Thoughts Learning
ACL2024-04-25GithubProject
TextHawkStar
TextHawk: Exploring Efficient Fine-Grained Perception of Multimodal Large Language Models
ArXiv2024-04-14GithubProject
HRVDAHRVDA: High-Resolution Visual Document AssistantCVPR2024-04-10GithubProject
InternLM-XComposer2-4KHDStar
InternLM-XComposer2-4KHD: A Pioneering Large Vision-Language Model Handling Resolutions from 336 Pixels to 4K HD
NeurIPS2024-04-09GithubProject
LayoutLLMLayoutLLM: Layout Instruction Tuning with Large Language Models for Document UnderstandingCVPR2024-04-08GithubProject
ViTLPStar
Visually Guided Generative Text-Layout Pre-training for Document Intelligence
NAACL2024-03-25GithubProject
mPLUG-DocOwl 1.5Star
mPLUG-DocOwl 1.5: Unified Structure Learning for OCR-free Document Understanding
ArXiv2024-03-19GithubProject
DoCoEnhancing Visual Document Understanding with Contrastive Learning in Large Visual-Language ModelsCVPR2024-02-29GithubProject
TGDocStar
Towards Improving Document Understanding: An Exploration on Text-Grounding via MLLMs
ArXiv2023-11-22GithubProject
DocPediaDocPedia: Unleashing the Power of Large Multimodal Model in the Frequency Domain for Versatile Document UnderstandingArXiv2023-11-20GithubProject
UReaderStar
UReader: Universal OCR-free Visually-situated Language Understanding with Multimodal Large Language Model
ACL2023-10-08GithubProject
UniDocUniDoc: A Universal Large Multimodal Model for Simultaneous Text Detection, Recognition, Spotting and UnderstandingArXiv2023-08-19GithubProject
mPLUG-DocOwlStar
mPLUG-DocOwl: Modularized Multimodal Large Language Model for Document Understanding
ArXiv2023-07-04GithubProject
LLaVARStar
LLaVAR: Enhanced Visual Instruction Tuning for Text-Rich Image Understanding
ArXiv2023-06-29GithubProject

🎯Back to Top

Retrieval

🎯Back to Top

VLLM+X

Remote sensing

🎯Back to Top

Medical

🎯Back to Top

Science and math

🎯Back to Top

Graphics and UI
NameTitleVenueDateCodeProject
GraphistStar
Graphic Design with Large Multimodal Model
ArXiv2024-04-22GithubProject
Ferret-UIFerret-UI: Grounded Mobile UI Understanding with Multimodal LLMs
ECCV2024-04-08GithubProject
CogAgentStar
CogAgent: A Visual Language Model for GUI Agents
CVPR2023-12-21GithubProject

🎯Back to Top

Financial analysis

🎯Back to Top

Video-to-text

General domain

NameTitleVenueDateCodeProject
TimeSoccerTimeSoccer: An End-to-End Multimodal Large Language Model for Soccer Commentary GenerationArXiv2025-4-24GithubProject
Eagle 2.5Star
Eagle 2.5: Boosting Long-Context Post-Training for Frontier Vision-Language Models
ArXiv2025-4-21GithubProject
Camera-BenchStar
Towards Understanding Camera Motions in Any Video
ArXiv2025-4-21GithubProject
IV-BenchStar
IV-Bench: A Benchmark for Image-Grounded Video Perception and Reasoning in Multimodal LLMs
ArXiv2025-4-21GithubProject
VideoChat-OnlineStar
Online Video Understanding: OVBench and VideoChat-Online
CVPR2025-4-21GithubProject
MavorsStar
Mavors: Multi-granularity Video Representation for Multimodal Large Language Model
ArXiv2025-4-14GithubProject
VideoLLaMA3Star
VideoLLaMA 3: Frontier Multimodal Foundation Models for Image and Video Understanding
ArXiv2025-1-22GithubProject
AriaStar
ARIA : An Open Multimodal Native Mixture-of-Experts Model
ArXiv2024-12-17GithubProject
ApolloApollo: An Exploration of Video Understanding in Large Multimodal ModelsArXiv2024-12-13GithubProject
LinVTStar
LinVT: Empower Your Image-level Large Language Model to Understand Videos
ArXiv2024-12-11GithubProject
Video-LLaMA2Star
VideoLLaMA 2: Advancing Spatial-Temporal Modeling and Audio Understanding in Video-LLMs
ArXiv2024-10-30GithubProject
LLaVA-OneVisionStar
LLaVA-OneVision: Easy Visual Task Transfer
ArXiv2024-10-26GithubProject
OryxStar
Oryx MLLM: On-Demand Spatial-Temporal Understanding at Arbitrary Resolution
ICLR2024-10-22GithubProject
LongVUStar
LongVU: Spatiotemporal Adaptive Compression for Long Video-Language Understanding
ArXiv2024-10-22GithubProject
AuroraCapStar
AuroraCap: Efficient, Performant Video Detailed Captioning and a New Benchmark
Arxiv2024-10-4GithubProject
LLaVA-VideoStar
Video Instruction Tuning With Synthetic Data
ArXiv2024-10-04GithubProject
SlowFast-LLaVAStar
SlowFast-LLaVA: A Strong Training-Free Baseline for Video Large Language Models
ArXiv2024-9-15GithubProject
InternVideo2Star
InternVideo2: Scaling Foundation Models for Multimodal Video Understanding
ArXiv2024-8-14GithubProject
mPLUG-Owl3Star
mPLUG-Owl3: Towards Long Image-Sequence Understanding in Multi-Modal Large Language Models
ArXiv2024-08-13GithubProject
GoldfishStar
Goldfish: Vision-Language Understanding of Arbitrarily Long Videos
ECCV2024-07-17GithubProject
VoTStar
Video-of-Thought: Step-by-Step Video Reasoning from Perception to Cognition
ICML2024-07-17GithubProject
Flash-VStreamStar
Flash-VStream: Memory-Based Real-Time Understanding for Long Video Streams
ArXiv2024-06-30GithubProject
LLaVA-Next-VideoStar
LLaVA-NeXT: A Strong Zero-shot Video Understanding Model
online2024-04-30GithubProject
PLLaVAStar
PLLaVA: Parameter-free LLaVA Extension from Images to Videos for Video Dense Captioning
Arxiv2023-4-29GithubProject
MovieChat+Star
MovieChat+: Question-aware Sparse Memory for Long Video Question Answering
Arxiv2023-4-26GithubProject
MiniGPT4-VideoStar
MiniGPT4-video: Advancing multimodal llms for video understanding with interleaved visual-textual tokens
CVPR Workshop2024-04-04GithubProject
ST-LLMStar
ST-LLM: Large language models are effective temporal learners
ECCV2024-03-30GithubProject
LLaMA-VIDStar
LLaMA-VID: An Image is Worth 2 Tokens in Large Language Models
ECCV2023-11-28GithubProject
MovieChatStar
Moviechat: From dense token to sparse memory for long video understanding
CVPR2023-7-31GithubProject
Video-LLaMAStar
Video-LLaMA: An Instruction-tuned Audio-Visual Language Model for Video Understanding
EMNLP2023-10-25GithubProject
Vid2SeqStar
Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning
CVPR2023-03-21GithubProject
LaViLaStar
Learning Video Representations from Large Language Models
CVPR2022-12-08GithubProject
VideoBERTStar
VideoBERT: A joint model for video and language representation learning
ICCV2019-09-11GithubProject

🎯Back to Top

Video conversation

🎯Back to Top

Egocentric view

🎯Back to Top

Vision-to-action

Autonomous driving

Perception

🎯Back to Top

Planning

🎯Back to Top

Prediction

🎯Back to Top

Embodied AI

Perception

🎯Back to Top

Manipulation

🎯Back to Top

Planning

🎯Back to Top

🎯Back to Top

Automated tool management

NameTitleVenueDateCodeProject
Falcon-UIFalcon-UI: Understanding GUI Before Following User InstructionsarXiv2024-12-12GithubProject
AGENTTREKAgentTrek: Agent Trajectory Synthesis via Guiding Replay with Web TutorialsarXiv2024-12-12GithubProject
AguvisStar
Aguvis: Unified Pure Vision Agents for Autonomous GUI Interaction
arXiv2024-12-12GithubProject
ScribeAgentStar
ScribeAgent: Towards Specialized Web Agents Using Production-Scale Workflow Data
ArXiv2024-12-5GithubProject
ShowUIStar
ShowUI: One Vision-Language-Action Model for GUI Visual Agent
NeurlPS Workshop2024-11-26GithubProject
MultiUIStar
Harnessing Webpage UIs for Text-Rich Visual Understanding
ArXiv2024-11-6GithubProject
EDGEEDGE: Enhanced Grounded GUI Understanding with Enriched Multi-Granularity Synthetic DataArXiv2024-11-2GithubProject
AndroidLabStar
AndroidLab: Training and Systematic Benchmarking of Android Autonomous Agents
NeurlPS Workshop2024-10-30GithubProject
OS-ATLASStar
OS-ATLAS: A Foundation Action Model for Generalist GUI Agents
ArXiv2024-10-30GithubProject
AutoGLMAutoGLM: Autonomous Foundation Agents for GUIsArXiv2024-10-30GithubProject
Ferret-UI 2Ferret-UI 2: Mastering Universal User Interface Understanding Across PlatformsArXiv2024-10-24GithubProject
Tool-LMMStar
Tool-LMM: A Large Multi-Modal Model for Tool Agent Learning
arXiv2024-1-19GithubProject
CLOVAStar
CLOVA: A Closed-loop Visual Assistant with Tool Usage and Update
CVPR2023-12-18GithubProject
CRAFTStar
CRAFT: Customizing LLMs by Creating and Retrieving from Specialized Toolsets
arXiv2023-9-29GithubProject
ConfuciusStar
Confucius: Iterative tool learning from introspection feedback by easy-to-difficult curriculum
AAAI2023-8-27GithubProject
AVISAvis: Autonomous visual information seeking with large language model agentNeurIPS2023-6-13GithubProject
GPT4ToolsStar
GPT4Tools: Teaching large language model to use tools via self-instruction
NeurIPS2023-5-30GithubProject
ToolkenGPTStar
ToolkenGPT: Augmenting frozen language models with massive tools via tool embeddings
NeurIPS2023-5-19GithubProject
ChameleonStar
Chameleon: Plug-and-play compositional reasoning with large language models
NeurIPS2023-4-19GithubProject
HuggingGPTStar
HuggingGPT: Solving AI Tasks with ChatGPT and its Friends in Hugging Face
NeurIPS2023-3-30GithubProject
TaskMatrix.AITaskMatrix.AI: Completing tasks by connecting foundation models with millions of APIsIntelligent Computing (AAAS)2023-3-29GithubProjecct
MM-ReACTStar
MM-ReACT: Prompting ChatGPT for Multimodal Reasoning and Action
arXiv2023-3-20GithubProject
ViperGPTStar
ViperGPT: Visual Inference via Python Execution for Reasoning
ICCV2023-3-14GithubProject
MIND’S EYEMIND’S EYE: GROUNDED LANGUAGE MODEL REASONING THROUGH SIMULATIONarXiv2022-10-11GitHubProject

🎯Back to Top

Text-to-vision

Text-to-image

NameTitleVenueDateCodeProject
FLUX.1 KontextStar
FLUX.1 Kontext: Flow Matching for In-Context Image Generation and Editing in Latent Space
ArXiv2025-6-17GitHubProject
BAGELStar
Emerging Properties in Unified Multimodal Pretraining
ArXiv2025-5-23GitHubProject
X-FusionX-Fusion: Introducing New Modality to Frozen Large Language ModelsICCV2025-4-29GitHubProject
Janus-ProStar
Janus-Pro: Unified Multimodal Understanding and Generation with Data and Model Scaling
ArXiv2025-1-29GitHubProject
JanusFlowStar
JanusFlow: Harmonizing Autoregression and Rectified Flow for Unified Multimodal Understanding and Generation
ArXiv2024-11-12GitHubProject
JanusStar
Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation
ArXiv2024-10-17GitHubProject
FLUX.1Star
FLUX
None2024-8-1GitHubProject
LLMGAStar
LLMGA: Multimodal Large Language Model based Generation Assistant
ECCV2024-7-27GitHubProject
EmuStar
Generative pretraining in multimodality,
ICLR2024-5-8GitHubProject
Kosmos-GKosmos-G: Generating Images in Context with Multimodal Large Language ModelsICLR2024-4-26GitHubProject
LaVITStar
Unified Language-Vision Pretraining in LLM with Dynamic Discrete Visual Tokenization
ICLR2024-3-22GitHubProject
MiniGPT-5Star
MiniGPT-5: Interleaved Vision-and-Language Generation via Generative Vokens
ArXiv2024-3-15GitHubProject
LMDStar
LLM-grounded Diffusion: Enhancing Prompt Understanding of Text-to-Image Diffusion Models with Large Language Models
TMLR2024-3-4GitHubProject
DiffusionGPTStar
DiffusionGPT: LLM-Driven Text-to-Image Generation System
ArXiv2024-1-18GitHubProject
VL-GPTStar
VL-GPT: A Generative Pre-trained Transformer for Vision and Language Understanding and Generation
ArXiv2023-12-4GitHubProject
CoDi-2Star
CoDi-2: In-Context, Interleaved, and Interactive Any-to-Any Generation
CVPR2023-11-30GitHubProject
SEED-LLAMAStar
Making LLaMA SEE and Draw with SEED Tokenizer
CVPR2023-10-3GitHubProject
JAMJointly Training Large Autoregressive Multimodal ModelsICLR2023-9-28GitHubProject
CM3LeonScaling Autoregressive Multi-Modal Models: Pretraining and Instruction TuningArXiv2023-9-5GitHubProject
SEEDStar
Planting a SEED of Vision in Large Language Model
ICLR2023-8-12GitHubProject
GILLStar
Generating Images with Multimodal Language Models
NeurlPS2023-5-26GitHubProject

🎯Back to Top

Text-to-3D

🎯Back to Top

Text-to-video

🎯Back to Top

Other applications

Face

🎯Back to Top

Anomaly Detetcion

🎯Back to Top

Gaming

🎯Back to Top

Challenges

Efficiency

NameTitleVenueDateCodeProject
WiCoStar
Window Token Concatenation for Efficient Visual Large Language Models
CVPRW2025-4-5GithubProject
DARTStop Looking for “Important Tokens” in Multimodal Language Models: Duplication Matters MoreArXiv2025-2-17GithubProject
LLaVA-MiniStar
LLaVA-Mini: Efficient Image and Video Large Multimodal Models with One Vision Token
ICLR2025-1-7GithubProject
Dynamic-VLMDynamic-VLM: Simple Dynamic Visual Token Compression for VideoLLMArXiv2024-12-12GithubProject
PVCStar
PVC: Progressive Visual Token Compression for Unified Image and Video Processing in Large Vision-Language Models
ArXiv2024-12-12GithubProject
iLLaVAStar
iLLaVA: An Image is Worth Fewer Than 1/3 Input Tokens in Large Multimodal Models
ArXiv2024-12-8GithubProject
VTC-CLSStar
[CLS] Token Tells Everything Needed for Training-free Efficient MLLMs
ArXiv2024-12-8GithubProject
NegToMeStar
Negative Token Merging: Image-based Adversarial Feature Guidance
ArXiv2024-12-5GithubProject
VisionZipStar
VisionZip: Longer is Better but Not Necessary in Vision Language Models
ArXiv2024-12-5GithubProject
AIMStar
AIM: Adaptive Inference of Multi-Modal LLMs via Token Merging and Pruning
ArXiv2024-12-4GithubProject
Dynamic-LLaVAStar
Dynamic-LLaVA: Efficient Multimodal Large Language Models via Dynamic Vision-language Context Sparsification
ArXiv2024-12-3GithubProject
ATP-LLaVAATP-LLaVA: Adaptive Token Pruning for Large Vision Language ModelsArXiv2024-11-30GithubProject
YOPOStar
Treat Visual Tokens as Text? But Your MLLM Only Needs Fewer Efforts to See
ArXiv2024-11-30GithubProject
DyCokeStar
DyCoke: Dynamic Compression of Tokens for Fast Video Large Language Models
ArXiv2024-11-22GithubProject
LLaVA-MRLLaVA-MR: Large Language-and-Vision Assistant for Video Moment RetrievalArXiv2024-11-21GithubProject
FoPruFoPru: Focal Pruning for Efficient Large Vision-Language ModelsArXiv2024-11-21GithubProject
FocusLLaVAFocusLLaVA: A Coarse-to-Fine Approach for Efficient and Effective Visual Token CompressionArXiv2024-11-21GithubProject
RLTStar
Don't Look Twice: Faster Video Transformers with Run-Length Tokenization
NeurlPS2024-11-7GithubProject
LLaVoltaStar
Efficient Large Multi-modal Models via Visual Context Compression
NeurlPS2024-11-6GithubProject
QueCCStar
Inference Optimal VLMs Need Only One Visual Token but Larger Models
ArXiv2024-11-5GithubProject
PyramidDropStar
PyramidDrop: Accelerating Your Large Vision-Language Models via Pyramid Visual Redundancy Reduction
ArXiv2024-10-22GithubProject
VictorEfficient Vision-Language Models by Summarizing Visual Tokens into Compact RegistersArXiv2024-10-17GithubProject
AVG-LLaVAStar
AVG-LLaVA: A Large Multimodal Model with Adaptive Visual Granularity
ArXiv2024-10-4GithubProject
TRIMStar
Less is More: A Simple yet Effective Token Reduction Method for Efficient Multi-modal LLMs
COLING2024-9-28GithubProject
TokenPackerStar
TokenPacker: Efficient Visual Projector for Multimodal LLM
ArXiv2024-8-28GithubProject
MaVEnMaVEn: An Effective Multi-granularity Hybrid Visual Encoding Framework for Multimodal Large Language ModelNeurlPS2024-8-26GithubProject
HiREDStar
HiRED: Attention-Guided Token Dropping for Efficient Inference of High-Resolution Vision-Language Models in Resource-Constrained Environments
AAAI2024-8-20GithubProject
VoCo-LLaMAStar
VoCo-LLaMA: Towards Vision Compression with Large Language Models
ArXiv2024-6-18GithubProject
DeCoStar
DeCo: Decoupling Token Compression from Semantic Abstraction in Multimodal Large Language Models
ArXiv2024-5-31GithubProject
LLaVA-PruMergeStar
LLaVA-PruMerge: Adaptive Token Reduction for Efficient Large Multimodal Models
ArXiv2024-5-22GithubProject
FastVStar
An Image is Worth 1/2 Tokens After Layer 2: Plug-and-Play Inference Acceleration for Large Vision-Language Models
ECCV2024-5-5GithubProject
LLaVA-HRStar
HFeast Your Eyes: Mixture-of-Resolution Adaptation for Multimodal Large Language Models
ArXiv2024-3-5GithubProject

🎯Back to Top

Security

🎯Back to Top

Interpretability and explainability

NameTitleVenueDateCodeProject
EAGLEStar
Where MLLMs Attend and What They Rely On: Explaining Autoregressive Token Generation
CVPR2026-02-21GithubProject
TAMStar
Token Activation Map to Visually Explain Multimodal LLMs
ICCV2025-06-29GithubProject
IGOS++ (w/ GNC)Star
Where do Large Vision-Language Models Look at when Answering Questions?
ArXiv2025-03-18GithubProject
LLaVA-CAMStar
From Redundancy to Relevance: Information Flow in LVLMs Across Reasoning Tasks
NAACL2025GithubProject
MultiTrustStar
MULTITRUST: A Comprehensive Benchmark Towards Trustworthy Multimodal Large Language Models
ArXiv2024-12-6GithubProject
XL-VLMsStar
A Concept-Based Explainability Framework for Large Multimodal Models
NeurlPS2024-11-30GithubProject
VPSStar
Interpreting Object-level Foundation Models via Visual Precision Search
Arxiv2024-11-25GithubProject
SAE
Large Multi-modal Models Can Interpret Features in Large Multi-modal Models
ArXiv2024-11-22GithubProject
MLLM-Probe
Probing Multimodal Large Language Models for Global and Local Semantic Representations
ArXiv2024-11-21GithubProject
LexVLAStar
Unified Lexical Representation for Interpretable Visual-Language Alignment
NeurlPS2024-11-11GithubProject
MUBStar
Exploring Response Uncertainty in MLLMs: An Empirical Evaluation under Misleading Scenarios
ArXiv2024-11-5GithubProject
LLaVA-CAMStar
From Redundancy to Relevance: Information Flow in LVLMs Across Reasoning Tasks
ArXiv2024-10-17GithubProject
LLaVA-InterpStar
Towards Interpreting Visual Information Processing in Vision-Language Models
ArXiv2024-10-9GithubProject
MINERStar
MINER: Mining the Underlying Pattern of Modality-Specific Neurons in Multimodal Large Language Models
ArXiv2024-10-7GithubProject
VL-InterpretStar
Interpreting and Editing Vision-Language Representations to Mitigate Hallucinations
ArXiv2024-10-3GithubProject
MMNeuronStar
MMNeuron: Discovering Neuron-Level Domain-Specific Interpretation in Multimodal Large Language Model
ArXiv2024-10-1GithubProject
MLLM-ONTOStar
Enhancing Explainability in Multimodal Large Language Models Using Ontological Context
ArXiv2024-9-27GithubProject
EAGLEStar
Eagle: Exploring The Design Space for Multimodal LLMs with Mixture of Encoders
ArXiv2024-8-28GithubProject
MLLM-LawStar
Law of Vision Representation in MLLMs
ArXiv2024-8-24CodeProject
VALEVALE: A Multimodal Visual and Language Explanation Framework for Image Classifiers using eXplainable AI and Language ModelsArXiv2024-8-23CodeProject
DistTrainDistTrain: Addressing Model and Data Heterogeneity with Disaggregated Training for Multimodal Large Language ModelsArXiv2024-8-15GithubProject
MLLM-ProjectionStar
Cross-Modal Projection in Multimodal LLMs Doesn’t Really Project Visual Attributes to Textual Space
ArXiv2024-8-9GithubProject
Reason2DriveStar
Reason2Drive: Towards Interpretable and Chain-based Reasoning for Autonomous Driving
ECCV2024-7-20GithubProject
LVLM-LPStar
The First to Know: How Token Distributions Reveal Hidden Knowledge in Large Vision-Language Models?
ECCV2024-7-17GithubProject
CLIP-NeuronsStar
Interpreting the Second-Order Effects of Neurons in CLIP
ArXiv2024-6-24GithubProject
LVLM-InterpretStar
LVLM-Interpret: An Interpretability Tool for Large Vision-Language Models
ArXiv2024-6-24GithubProject
Holmes-VADHolmes-VAD: Towards Unbiased and Explainable Video Anomaly Detection via Multi-modal LLMArXiv2024-6-18GithubProject
MMNeuronsStar
Finding and Editing Multi-Modal Neurons in Pre-Trained Transformers
ACL2024-6-11GithubProject
DeCoStar
DeCo: Decoupling Token Compression from Semantic Abstraction in Multimodal Large Language Models
ICML2024-5-31GithubProject
MAIAStar
A Multimodal Automated Interpretability Agent
ICML2024-4-22GithubProject
CDLStar
Pre-trained Vision-Language Models Learn Discoverable Visual Concepts
ArXiv2024-4-19GithubProject
OLIVEStar
What Are We Measuring When We Evaluate Large Vision-Language Models? An Analysis of Latent Factors and Biases
NAACL2024-4-3GithubProject
OPERAStar
OPERA: Alleviating Hallucination in Multi-Modal Large Language Models via Over-Trust Penalty and Retrospection-Allocation
CVPR2024-3-12GithubProject
RLHF-VStar
RLHF-V: Towards Trustworthy MLLMs via Behavior Alignment from Fine-grained Correctional Human Feedback
CVPR2024-3-8GithubProject
HA-DPOStar
Aligning Modalities in Vision Large Language Models via Preference Fine-tuning
ArXiv2024-2-18GithubProject
HA-DPOStar
Beyond Hallucinations: Enhancing LVLMs through Hallucination-Aware Direct Preference Optimization
ArXiv2024-2-6GithubProject
BenchLMMStar
BenchLMM: Benchmarking Cross-style Visual Capability of Large Multimodal Models
ECCV2023-12-6GithubProject
VCDStar
VCD: Mitigating Object Hallucinations in Large Vision-Language Models through Visual Contrastive Decoding
CVPR2023-11-28GithubProject
LLaVA-RLHFStar
LLaVA-RLHF: Aligning Large Multimodal Models with Factually Augmented RLHF
ArXiv2023-9-25GithubProject

🎯Back to Top

Complex reasoning

NameTitleVenueDateCodeProject
FEALLMStar
FEALLM: Advancing Facial Emotion Analysis in Multimodal Large Language Models with Emotional Synergy and Reasoning
ArXiv2025-5-19GithubProject
VisionReasonerStar
VisionReasoner: Unified Visual Perception and Reasoning via Reinforcement Learning
ArXiv2025-5-17GithubProject
Skywork R1V2Star
Skywork R1V2: Multimodal Hybrid Reinforcement Learning for Reasoning
ArXiv2025-4-23GithubProject
VisuLogicStar
VisuLogic: A Benchmark for Evaluating Visual Reasoning in Multi-modal Large Language Models
ArXiv2025-4-21GithubProject
Embodied-REmbodied-R: Collaborative Framework for Activating Embodied Spatial Reasoning in Foundation Models via Reinforcement LearningArXiv2025-4-17GithubProject
ThinkLite-VLStar
SoTA with Less: MCTS-Guided Sample Selection for Data-Efficient Visual Reasoning Self-Improvement
ArXiv2025-4-10GithubProject
Video-R1Star
Video-R1: Reinforcing Video Reasoning in MLLMs
Github2025-3-27GithubProject
Easy-R1Star
EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework
Github2025-3-19GithubProject
MedVLM-R1MedVLM-R1: Incentivizing Medical Reasoning Capability of Vision-Language Models (VLMs) via Reinforcement LearningArXiv2025-3-19GithubProject
Skywork R1VStar
Skywork R1V: Pioneering Multimodal Reasoning with Chain-of-Thought
GitHub2025-3-18GithubProject
TimeZeroStar
TimeZero: Temporal Video Grounding with Reasoning-Guided LVLM
ArXiv2025-3-17GithubProject
R1-VLStar
R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization
ArXiv2025-3-17GithubProject
VisualPRMVisualPRM: An Effective Process Reward Model for Multimodal ReasoningArXiv2025-3-13GithubProject
LMM-R1Star
LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL
ArXiv2025-3-11GithubProject
VisualThinker-R1-ZeroStar
R1-Zero's “Aha Moment” in Visual Reasoning on a 2B Non-SFT Mode
ArXiv2025-3-10GithubProject
R1-OmniStar
R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning
ArXiv2025-3-10GithubProject
Vision-R1Star
Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models
ArXiv2025-3-9GithubProject
Seg-ZeroStar
Seg-Zero: Reasoning-Chain Guided Segmentation via Cognitive Reinforcement
ArXiv2025-3-9GithubProject
MM-EUREKAStar
MM-EUREKA: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning
Github2025-3-7GithubProject
Visual-RFTStar
Visual-RFT: Visual Reinforcement Fine-Tuning
ArXiv2025-3-3GithubProject
VLM-R1Star
VLM-R1: A stable and generalizable R1-style Large Vision-Language Model
None2025-2-15GithubProject
R1-VStar
R1-V: Reinforcing Super Generalization Ability in Vision Language Models with Less Than $3
Blog2025-2-3GithubProject
TPOStar
Temporal Preference Optimization for Long-Form Video Understanding
ArXiv2025-1-10GithubProject
LlamaV-o1Star
LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLMs
ArXiv2025-1-10GithubProject
InternVL2-MPOStar
Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization
ArXiv2025-1-10GithubProject
VirgoStar
Virgo: A Preliminary Exploration on Reproducing o1-like MLLM
ArXiv2025-1-3GithubProject
MulberryStar
Mulberry: Empowering mllm with o1-like reasoning and reflection via collective monte carlo tree search
ArXiv2024-12-31GithubProject
LLaVA-CoTStar
LLaVA-CoT: Let Vision Language Models Reason Step-by-Step
ArXiv2024-11-25GithubProject

🎯Back to Top

Contributors

Thanks to all the contributors! You are awesome!

Star history

Star History Chart
application
embodied
llm
mllm
reasoning-agent
survey
vllm
vlm
vqa

Contributors

JackYFL

204 commits

Cogito2012

6 commits

Zhen-Tan-dmml

4 commits

mghiasvand1

3 commits