
A collection of multimodal reasoning papers, codes, datasets, benchmarks and resources.
43
115 commits
updated Jul 31, 2026
README
Awesome-MLLM-Reasoning-Collection


⚠️ Repository notice
On 31 May 2026, this repository was targeted by an apparent coordinated fake-star attack that also affected many other open-source repositories. Its star count rose abnormally from approximately 673 to more than 14,000 within a single day, despite no promotion or involvement from the maintainers. We reported the incident to GitHub but have not received a substantive response. We remain sincerely grateful to the 670+ genuine supporters whose earlier stars may no longer be displayed—your support and trust have always been deeply appreciated. 💙
👏 Welcome to the Awesome-MLLM-Reasoning-Collections repository! This repository is a carefully curated collection of papers, code, datasets, benchmarks, and resources focused on reasoning within Multimodal Large Language Models (MLLMs).
Feel free to ⭐ star and fork this repository to keep up with the latest advancements and contribute to the community.
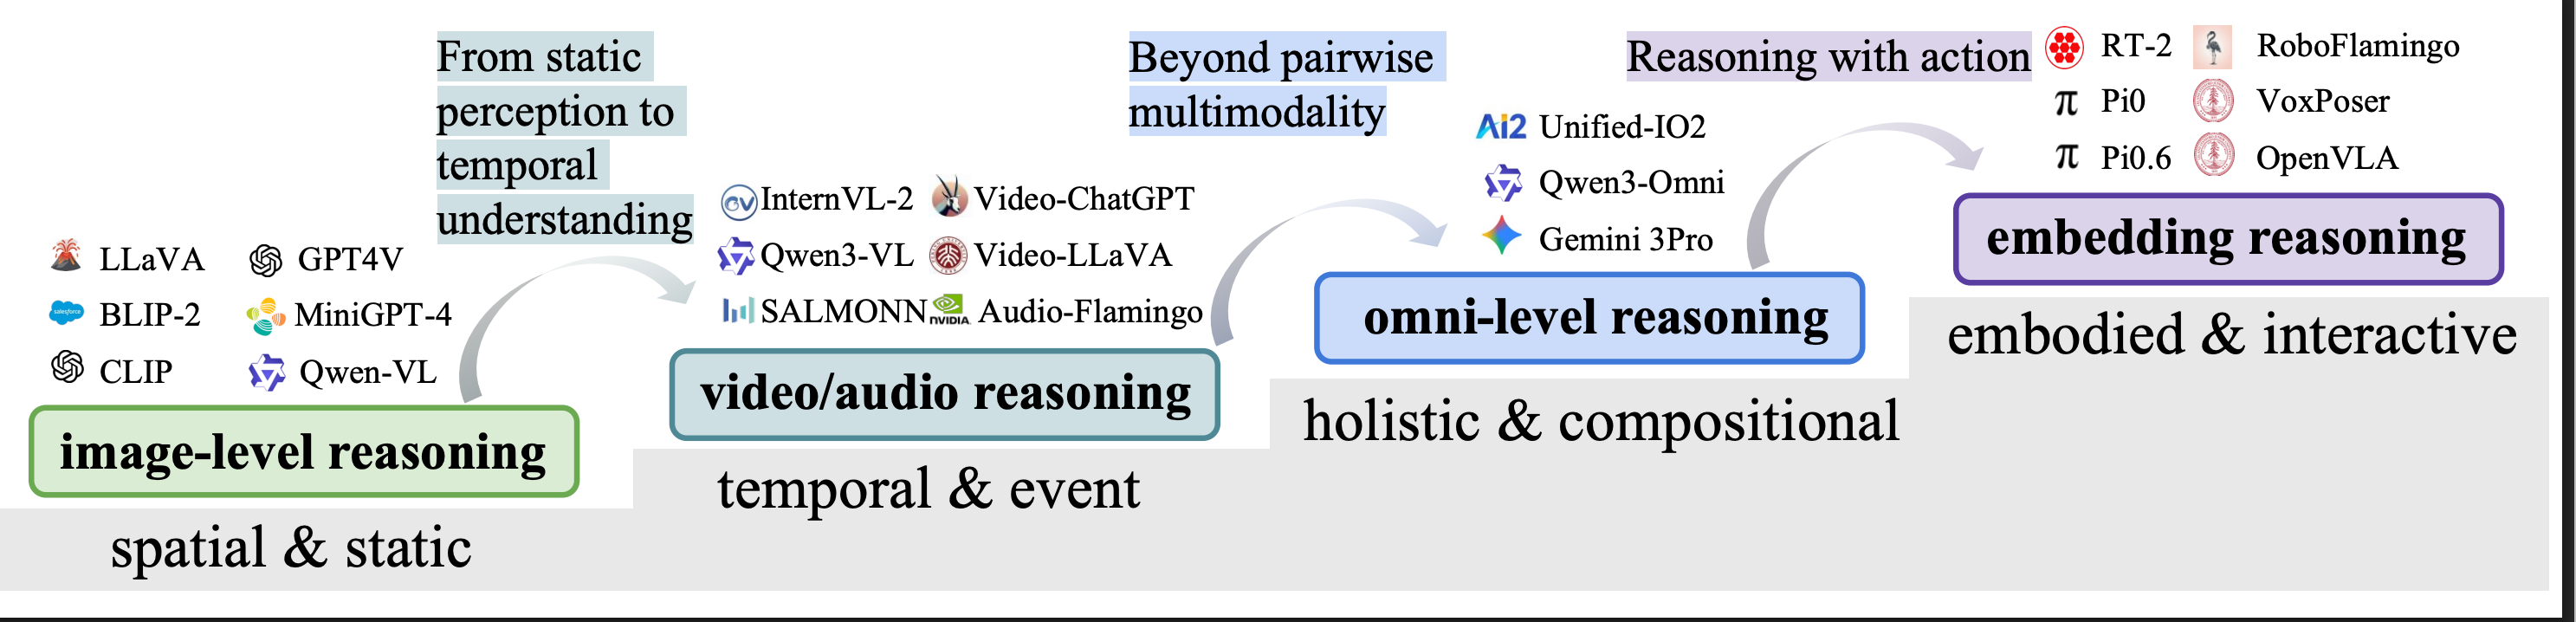
A conceptual trajectory of multimodal reasoning, evolving from static image-level understanding, through temporal video and audio reasoning, to holistic omni-level reasoning, and finally toward embodied embedding reasoning with perception–action interaction. This progression reflects increasing reasoning scope, compositionality, and interactivity.
Citation
If you find this repository or our survey useful for your research, please consider citing:
@article{hu2026static,
  title   = {From Static Perception to Interactive Decision: A Survey of Multimodal Reasoning},
  author  = {Hu, Jian and Cheng, Zixu and Ma, Yinghao and Dixit, Satvik and Pan, Bikang and Chen, Lei and Ma, Lin and Zeng, Zhixiong and Wang, Jiangya and Benetos, Emmanouil and others},
  journal = {researchgate preprint},
  year    = {2026}
}
Table of Contents
- Awesome-MLLM-Reasoning-Collection
- Table of Contents
- Papers and Projects 📄
- Benchmarks 📊
- Open-source Projects
- Contributing
Papers and Projects 📄
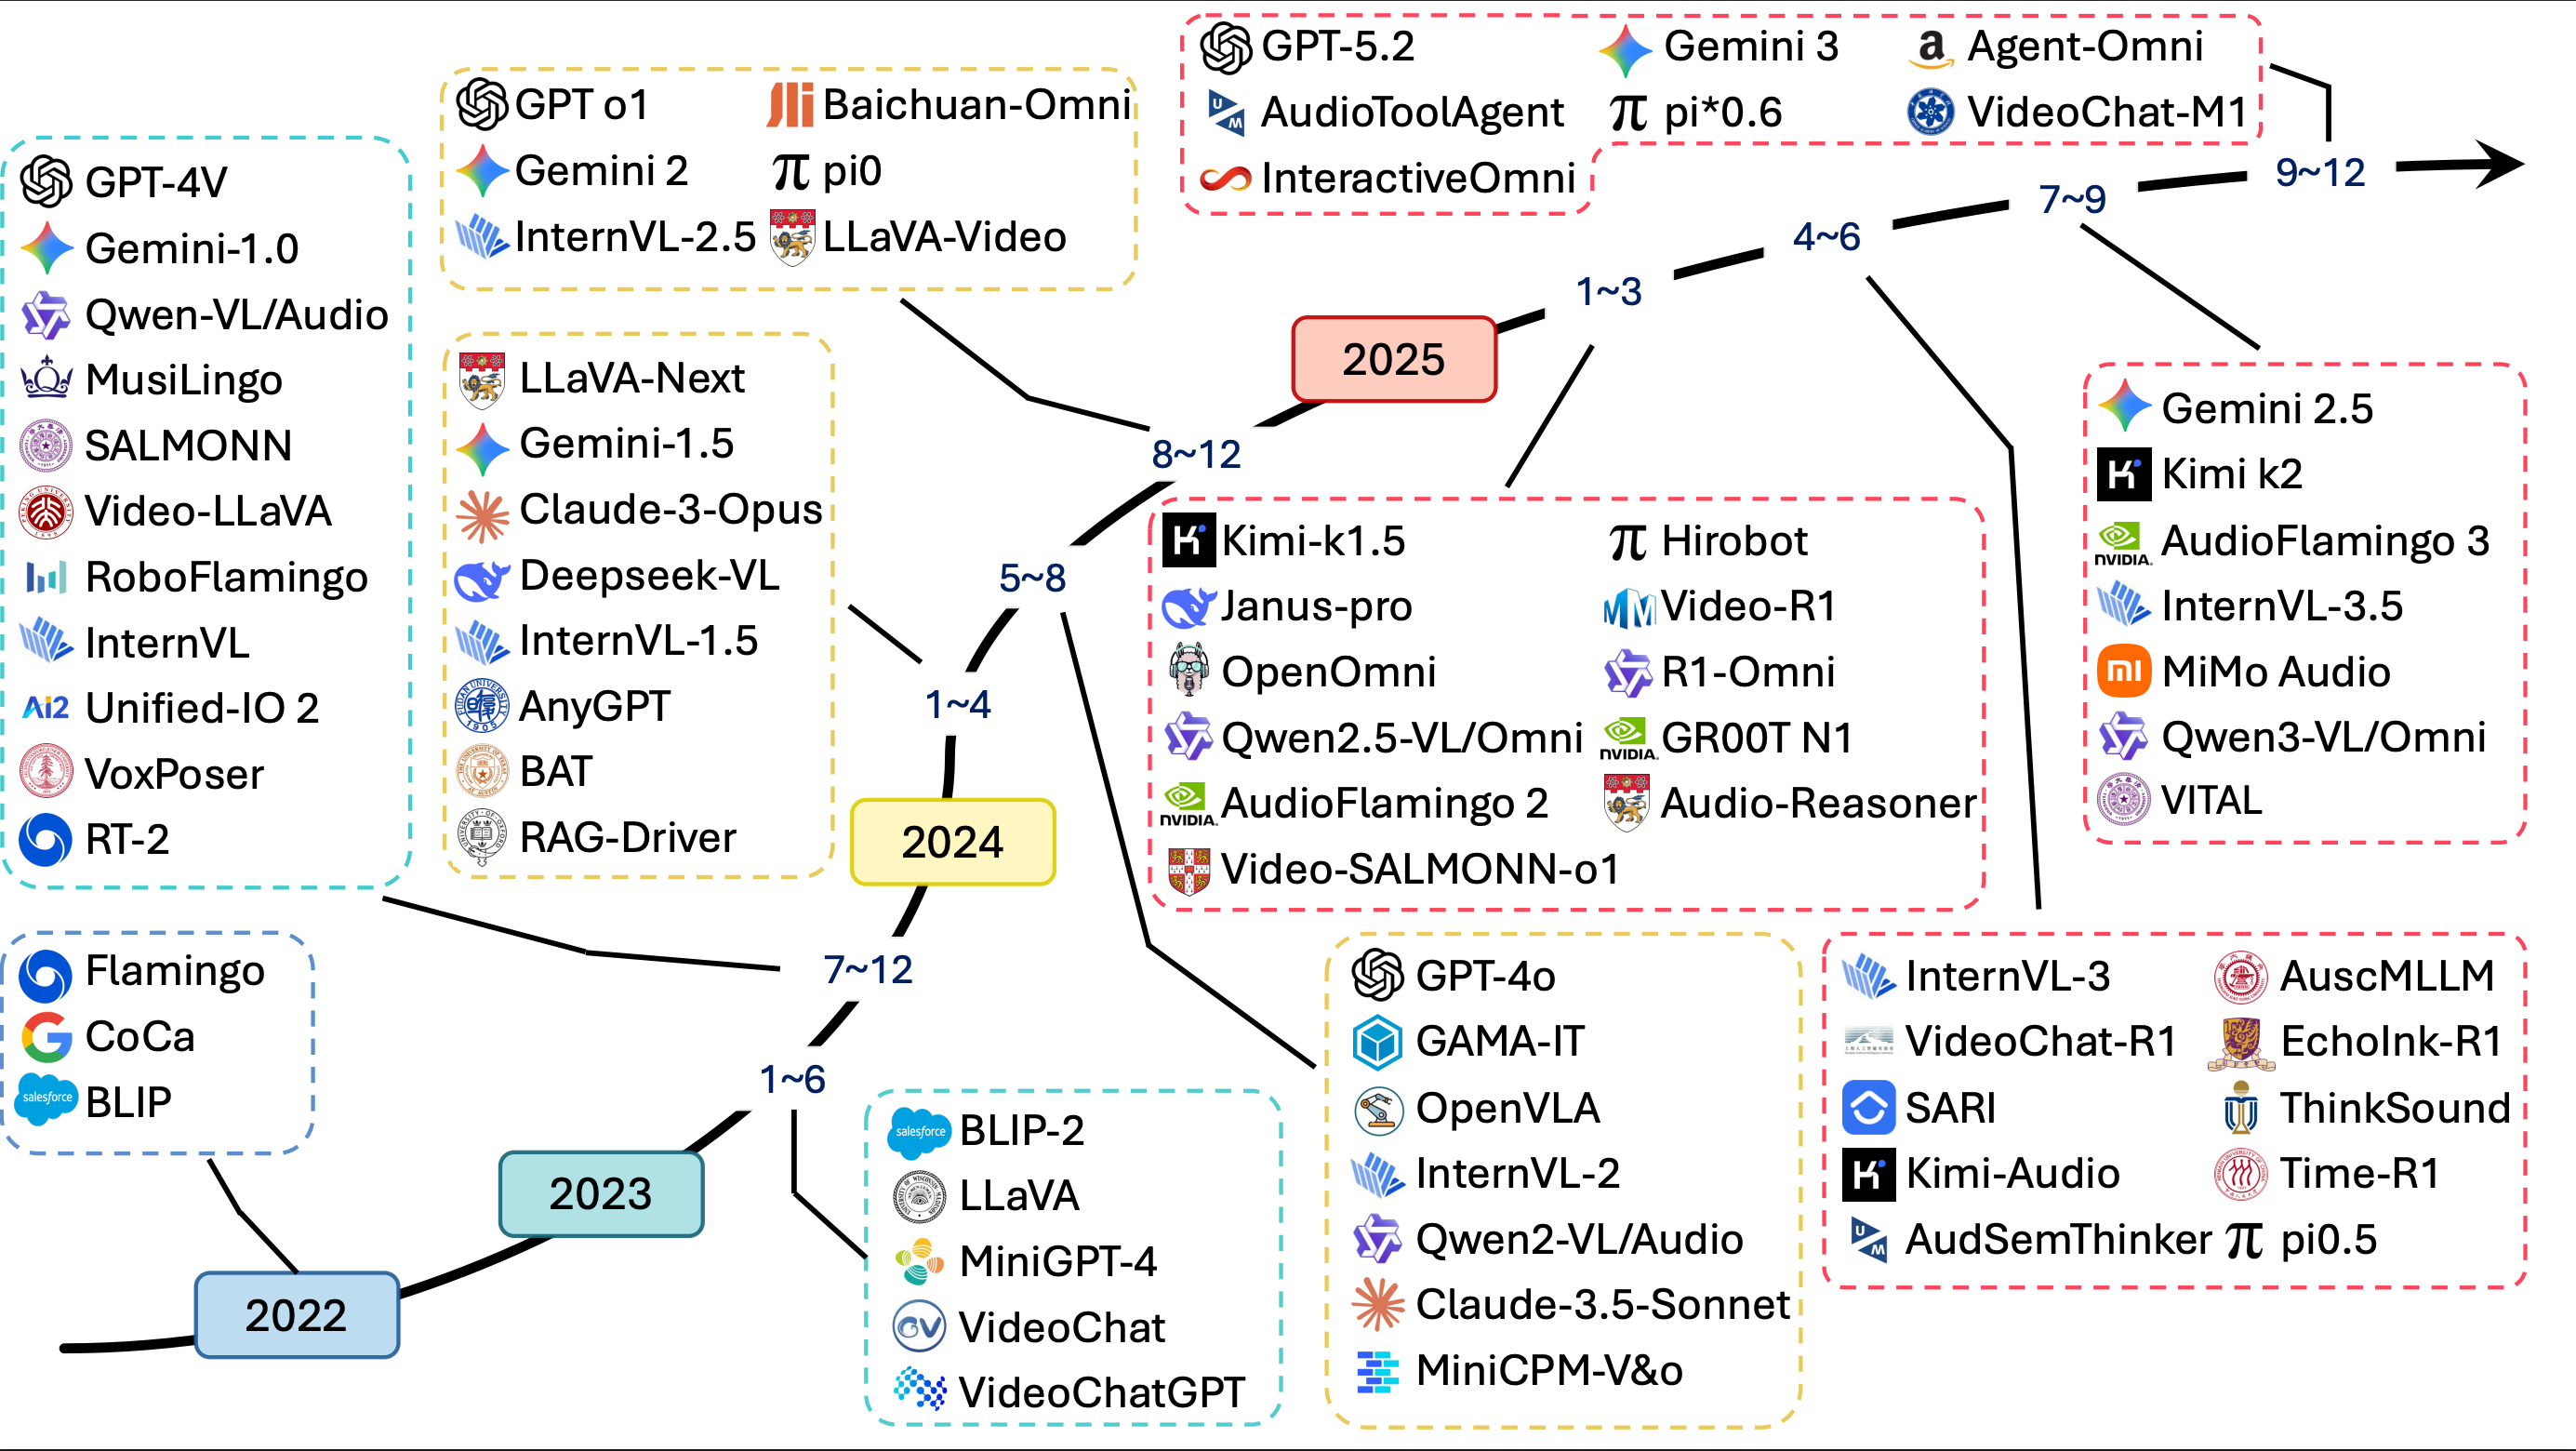
An evolutionary landscape of several representative multi-modal reasoning frameworks from 2022 to 2025.
Commonsense Reasoning
Image MLLM
- 26.03 Phi-4-reasoning-vision-15B Technical Report | Paper📑 Model🤗
- Compact 15B open-weight multimodal reasoning model excelling at scientific/math reasoning and UI understanding via careful architecture choices, data curation, and hybrid reasoning/non-reasoning training. | Task: Reasoning & Understanding
- 26.03 Beyond Language Modeling: An Exploration of Multimodal Pretraining | Paper📑
- Systematic empirical study of unified multimodal pretraining from scratch using Transfusion, finding vision and language are complementary and world modeling emerges from general pretraining. | Task: Reasoning & Understanding
- 26.03 Unified Vision-Language Modeling via Concept Space Alignment | Paper📑
- v-LCM extends the Large Concept Model with vision-language instruction tuning in a unified latent embedding space, outperforming SOTA VLMs across 61 languages. | Task: Reasoning & Understanding
- 26.03 MMR-Life: Piecing Together Real-life Scenes for Multimodal Multi-image Reasoning | Paper📑 Project🌐
- Benchmark of 2,646 QAs on 19,108 images across 7 reasoning types for multi-image reasoning; even GPT-5 achieves only 58% accuracy vs. human performance. | Task: Reasoning & Understanding
- 26.03 Ref-Adv: Exploring MLLM Visual Reasoning in Referring Expression Tasks | Paper📑 Project🌐
- REC benchmark suppressing shortcuts with linguistically nontrivial expressions, revealing MLLM reliance on shortcuts and gaps in visual reasoning and grounding. | Task: Reasoning & Understanding
- 26.03 Recursive Think-Answer Process for LLMs and VLMs | Paper📑
- Recursive think-answer process enabling iterative reasoning refinement in VLMs for improved multimodal reasoning performance. | Task: Reasoning & Understanding
- 26.02 From Blind Spots to Gains: Diagnostic-Driven Iterative Training for Large Multimodal Models | Paper📑 Code🖥️ Model🤗
- Spiral-loop framework diagnosing capability gaps in MLLMs and generating targeted data and RL training to close them iteratively. | Task: Reasoning & Understanding
- 26.02 Imagination Helps Visual Reasoning, But Not Yet in Latent Space | Paper📑 Code🖥️
- CapImagine proposes text-based explicit imagination outperforming latent-space baselines on vision-centric benchmarks via causal mediation analysis. | Task: Reasoning & Understanding
- 26.02 NoLan: Mitigating Object Hallucinations in Large Vision-Language Models via Dynamic Suppression of Language Priors | Paper📑 Code🖥️
- Training-free decoding dynamically suppressing language priors by comparing multimodal vs. text-only output distributions, achieving +6.45/+7.21 accuracy on POPE. | Task: Reasoning & Understanding
- 26.02 Selective Training for Large Vision Language Models via Visual Information Gain | Paper📑
- Visual Information Gain (VIG) metric quantifying how much visual input reduces prediction uncertainty for improved visual grounding and reduced language bias. | Task: Reasoning & Understanding
- 26.02 MetaphorStar: Image Metaphor Understanding and Reasoning with End-to-End Visual Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- End-to-end visual RL framework for image metaphor comprehension with TFQ-GRPO method, achieving 82.6% average improvement on image implication benchmarks. | Task: Reasoning & Understanding
- 26.02 Learning Self-Correction in Vision-Language Models via Rollout Augmentation | Paper📑 Model🤗
- Octopus synthesizes dense self-correction examples for VLMs via RL, achieving SOTA among open-source VLMs on 7 benchmarks. | Task: Reasoning & Understanding
- 26.02 SPARC: Separating Perception And Reasoning Circuits for Test-time Scaling of VLMs | Paper📑
- Decouples visual perception from reasoning in VLMs via a two-stage pipeline, enabling efficient test-time scaling with 200× lower token budget. | Task: Reasoning & Understanding
- 26.02 Modality Gap-Driven Subspace Alignment Training Paradigm For Multimodal Large Language Models | Paper📑 Code🖥️
- Fixed-frame Modality Gap Theory with training-free ReAlign alignment and scalable ReVision pretraining using unpaired data to bridge the modality gap. | Task: Reasoning & Understanding
- 26.02 Kimi K2.5: Visual Agentic Intelligence | Paper📑 Code🖥️ Model🤗
- Open-source multimodal agentic model achieving SOTA across coding, vision, reasoning, and agentic tasks via joint text-vision RL and Agent Swarm parallel execution. | Task: Reasoning & Understanding
- 26.02 Toward Cognitive Supersensing in Multimodal Large Language Model | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Trains MLLMs to generate internal visual imagery sequences for abstract visual reasoning, evaluated on CogSense-Bench spanning five cognitive dimensions. | Task: Reasoning & Understanding
- 26.02 Thinking with Comics: Enhancing Multimodal Reasoning through Structured Visual Storytelling | Paper📑 Code🖥️
- Uses comics as a visual medium to improve multimodal reasoning efficiency while preserving temporal structure and narrative coherence. | Task: Reasoning & Understanding
- 26.02 SwimBird: Eliciting Switchable Reasoning Mode in Hybrid Autoregressive MLLMs | Paper📑 Code🖥️ Dataset🤗
- Hybrid autoregressive MLLM dynamically switching between text-only, vision-only, and interleaved vision-text reasoning modes based on input queries. | Task: Reasoning & Understanding
- 26.02 What does RL improve for Visual Reasoning? A Frankenstein-Style Analysis | Paper📑 Code🖥️ Model🤗
- Analyzes what RL actually improves in VLMs for visual reasoning, finding RL primarily refines mid-to-late transformer layers that improve vision-to-reasoning alignment. | Task: Reasoning & Understanding
- 26.02 On Robustness and Chain-of-Thought Consistency of RL-Finetuned VLMs | Paper📑
- Shows RL fine-tuning of VLMs introduces vulnerability to textual perturbations and reveals an accuracy-faithfulness trade-off undermining chain-of-thought reliability. | Task: Reasoning & Understanding
- 26.02 Thinking with Drafting: Optical Decompression via Logical Reconstruction | Paper📑
- TwD reconstructs logical structures from compressed visual tokens via Domain-Specific Language, forcing models to draft reasoning as executable code for self-verification. | Task: Reasoning & Understanding
- 26.02 Visual Persuasion: What Influences Decisions of Vision-Language Models? | Paper📑
- Studies VLM visual decision-making through controlled image-based choice tasks with systematic perturbations to identify visual vulnerabilities and safety concerns. | Task: Reasoning & Understanding
- 26.02 Adapting Vision-Language Models for E-commerce Understanding at Scale | Paper📑
- Adapts general-purpose VLMs for e-commerce product understanding via a 4M-item visual instruction tuning dataset covering deep product attributes and dynamic extraction. | Task: Reasoning & Understanding
- 26.02 Zooming without Zooming: Region-to-Image Distillation for Fine-Grained Multimodal Perception | Paper📑 Code🖥️ Model🤗
- Trains MLLMs to internally perform iterative zooming during inference via distillation, eliminating repeated tool calls while improving fine-grained visual perception. | Task: Reasoning & Understanding
- 26.02 DeepImageSearch: Benchmarking Multimodal Agents for Context-Aware Image Retrieval in Visual Histories | Paper📑 Code🖥️ Dataset🤗
- Reformulates image retrieval as multi-step reasoning over visual histories with DISBench benchmark and a modular agent with dual-memory system. | Task: Reasoning & Understanding
- 26.01 MMFineReason: Closing the Multimodal Reasoning Gap via Open Data-Centric Methods | Paper📑 Model🤗 Dataset🤗
- A 1.8M-sample multimodal reasoning dataset with high-quality CoT annotations; the 8B model approaches Qwen3-VL-32B-Thinking performance. | Task: Reasoning & Understanding
- 26.01 DiffThinker: Towards Generative Multimodal Reasoning with Diffusion Models | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Reformulates multimodal reasoning as a native image-to-image generative task using diffusion models. | Task: Reasoning & Understanding
- 26.01 Visual Generation Unlocks Human-Like Reasoning through Multimodal World Models | Paper📑 Code🖥️ Dataset🤗
- Proposes the visual superiority hypothesis: visual generation serves as a more natural world model for physical/spatial reasoning tasks. | Task: Reasoning & Understanding
- 26.01 VTC-R1: Vision-Text Compression for Efficient Long-Context Reasoning | Paper📑 Code🖥️
- Compresses textual reasoning traces into compact images as "optical memory" for VLMs, achieving 3.4x token compression. | Task: Reasoning & Understanding
- 26.01 UniCorn: Towards Self-Improving Unified Multimodal Models through Self-Generated Supervision | Paper📑 Code🖥️ Model🤗
- Self-improvement framework partitioning a single model into Proposer/Solver/Judge roles via self-play to improve comprehension and generation. | Task: Reasoning & Understanding
- 26.01 LaViT: Aligning Latent Visual Thoughts for Multi-modal Reasoning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Addresses the "Perception Gap" by aligning latent visual thoughts (attention trajectories) between teacher and student models. | Task: Reasoning & Understanding
- 26.01 STEP3-VL-10B Technical Report | Paper📑 Code🖥️ Model🤗
- A 10B multimodal foundation model with Parallel Coordinated Reasoning (PaCoRe) for test-time compute scaling. | Task: Reasoning & Understanding
- 26.01 Generation Enhances Understanding in Unified Multimodal Models via Multi-Representation Generation | Paper📑 Code🖥️
- Trains unified multimodal models to generate pixel, depth, and segmentation representations alongside understanding. | Task: Reasoning & Understanding
- 26.01 What Matters in Data Curation for Multimodal Reasoning? Insights from the DCVLR Challenge | Paper📑
- First-place NeurIPS 2025 DCVLR challenge submission revealing difficulty-based example selection as dominant driver in data curation. | Task: Reasoning & Understanding
- 26.01 MAD: Modality-Adaptive Decoding for Mitigating Cross-Modal Hallucinations in Multimodal Large Language Models | Paper📑
- Modality-adaptive decoding to mitigate cross-modal hallucinations in MLLMs by dynamically adjusting decoding. | Task: Reasoning & Understanding
- 25.12 OneThinker: All-in-one Reasoning Model for Image and Video | Paper📑
- Unifies image and video understanding across diverse visual tasks using RL with EMA-GRPO technique. | Task: Reasoning & Understanding
- 25.12 Puzzle Curriculum GRPO for Vision-Centric Reasoning | Paper📑
- Supervision-free RL method enhancing visual reasoning in VLMs through self-supervised puzzle environments. | Task: Reasoning & Understanding
- 25.12 Robust-R1: Degradation-Aware Reasoning for Robust Visual Understanding | Paper📑
- Enhances MLLM robustness to visual degradations by modeling degradation parameters through structured reasoning chains. | Task: Reasoning & Understanding
- 25.12 See Less, See Right: Bi-directional Perceptual Shaping For Multimodal Reasoning | Paper📑
- Improves VLM multimodal reasoning via paired masked views to enforce fine-grained visual reliance. | Task: Reasoning & Understanding
- 25.11 OpenMMReasoner: Pushing the Frontiers for Multimodal Reasoning with an Open and General Recipe | Paper📑
- Open general-purpose framework for advancing multimodal reasoning. | Task: Reasoning & Understanding
- 25.11 ThinkMorph: Emergent Properties in Multimodal Interleaved Chain-of-Thought Reasoning | Paper📑
- Studies emergent properties in multimodal interleaved chain-of-thought reasoning. | Task: Reasoning & Understanding
- 25.11 TiDAR: Think in Diffusion, Talk in Autoregression | Paper📑
- Combines diffusion-based thinking with autoregressive generation for multimodal reasoning. | Task: Reasoning & Understanding
- 25.10 TTRV: Test-Time Reinforcement Learning for Vision Language Models | Paper📑
- Test-time reinforcement learning applied to vision-language models for improved reasoning. | Task: Reasoning & Understanding
- 25.10 VLM-FO1: Bridging the Gap Between High-Level Reasoning and Fine-Grained Perception in VLMs | Paper📑
- Improves VLMs' ability to combine high-level reasoning with detailed visual perception. | Task: Reasoning & Understanding
- 25.10 ARES: Multimodal Adaptive Reasoning via Difficulty-Aware Token-Level Entropy Shaping | Paper📑
- Adaptive reasoning for multimodal models using entropy shaping. | Task: Reasoning & Understanding
- 25.09 R-4B: Incentivizing General-Purpose Auto-Thinking Capability in MLLMs via Bi-Mode Annealing and RL | Paper📑
- Training method using RL and annealing to improve auto-thinking and reasoning in multimodal LLMs. | Task: Reasoning & Understanding
- 25.09 LLaVA-OneVision-1.5: Fully Open Framework for Democratized Multimodal Training | Paper📑
- Open-source framework for training multimodal vision-language models. | Task: Reasoning & Understanding
- 25.08 Thyme: Think Beyond Images | Paper📑
- Multimodal reasoning system that extends beyond surface-level image understanding to higher-level thinking. | Task: Reasoning & Understanding
- 25.08 Controlling Multimodal LLMs via Reward-guided Decoding | Paper📑
- Controls MLLM reasoning outputs through reward-based generation guidance at decoding time. | Task: Reasoning & Understanding
- 25.08 Self-Rewarding Vision-Language Model via Reasoning Decomposition | Paper📑
- VLM that uses reasoning decomposition and self-reward to improve visual reasoning quality. | Task: Reasoning & Understanding
- 25.08 GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models | Paper📑
- Foundation model with strong agentic, reasoning, and coding capabilities across modalities. | Task: Reasoning & Understanding
- 25.07 GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning | Paper📑 Code🖥️
- A reasoning-centric training framework for general-purpose multimodal reasoning. | Task: Reasoning & Understainding
- 25.07 MiCo: Multi-image Contrast for Reinforcement Visual Reasoning | Paper📑
- Construct image triplets comprising two augmented views of the same image and a third, similar but distinct image. | Task: Reasoning & Understainding
- 25.06 Vision Matters: Simple Visual Perturbations Can Boost Multimodal Math Reasoning | Paper📑 Code🖥️ Model🤗
- Simple visual perturbation framework that can be easily integrated into existing post-training pipelines including SFT, DPO, and GRPO. | Task: Reasoning & Understainding
- 25.05 Visionary-R1: Mitigating Shortcuts in Visual Reasoning with Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- 25.05 Sherlock: Self-Correcting Reasoning in Vision-Language Models | Paper📑 Code🖥️ Model🤗
- Explore self-correction as a strategy to enhance reasoning VLMs | Task: Reasoning & Understainding
- 25.05 EchoInk-R1: Exploring Audio-Visual Reasoning in Multimodal LLMs via Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- The first general framework for unified audio-visual reasoning via reinforcement learning | Task: Reasoning & Understainding
- 25.03 Skywork-R1V: Pioneering Multimodal Reasoning with CoT | Paper📑 Code🖥️ Model🤗
- The first industry open-sourced multimodal reasoning model with advanced visual chain-of-thought capabilities | Task: Reasoning & Understainding
- 25.03 CMMCoT: Enhancing Complex Multi-Image Comprehension via Multi-Modal Chain-of-Thought and Memory Augmentation | Paper📑
- Mimic human-like ”slow thinking” for multi-image understanding. | Task: VQA
- 25.03 DAPO: an Open-Source LLM Reinforcement Learning System at Scale | Paper📑 Code🖥️ Data🤗
- Propose the Decoupled Clip and Dynamic sAmpling Policy Optimization (DAPO) algorithm. | Task: Math
- 25.03 VisRL: Intention-Driven Visual Perception via Reinforced Reasoning | Paper📑 Code🖥️
- The first framework that applies reinforcement learning (RL) to the problem of intention-driven visual perception | Task: VQA
- 25.03 Unified Reward Model for Multimodal Understanding and Generation | Paper📑 Code🖥️ Dataset🤗
- Improve MLLM's understanding and generation ability with DPO | Task: VQA & Generation
- 25.02 Qwen2.5-VL Technical Report | Paper📑 Code🖥️ Huggingface🤗
- The latest flagship model of Qwen vision-language series for various multimodal tasks | Task: Reasoning & Understainding
- 25.02 MM-RLHF: The Next Step Forward in Multimodal LLM Alignment | Paper📑 Project🌐
- A comprehensive project for aligning MlLMs with human preferences | Task: Reward & VQA
- 25.01 Kimi k1.5: Scaling Reinforcement Learning with LLMs (MoonshotAI) | Project🌐
- The latest flagship model of Kimi series for various multimodal tasks | Task: Reasoning & Understainding
- 25.01 InternLM-XComposer2.5-Reward: A Simple Yet Effective Multi-Modal Reward Model | Paper📑 Code🖥️
- A simple yet effective multi-modal reward model that aligns MLLMs with human preferences | Reward & VQA
- 25.01 LlamaV-o1: Rethinking Step-By-Step Visual Reasoning in LLMs | Paper📑 Code🖥️
- A combined multi-step curriculum learning and beam search multimodal reasoning model | VQA
- 25.01 ReFocus: Visual Editing as a Chain of Thought for Structured Image Understanding | Paper📑 Code🖥️ Model🤗
- Perform visual chain of thought via input-image editing to help multimodal reasoning. | Task: VQA
- 24.12 Mulberry: Empowering MLLM with o1-like Reasoning and Reflection via Collective Monte Carlo Tree Search | Paper📑 Code🖥️ Dataset🤗
- Improve MLLM reasoning ability via collective monte carlo tree search | VQA
- 24.11 LLaVA-CoT: Let Vision Language Models Reason Step-by-Step | Paper📑 Code🖥️ Model🤗
- A novel MLLM designed to conduct autonomous multistage reasoning. | VQA
- 24.11 Insight-V: Exploring Long-Chain Visual Reasoning with Multimodal Large Language Models | Paper📑 Code🖥️ Model🤗
- Explore long-chain visual reasoning with MLLMs | VQA
- 24.11 Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization | Paper📑 Code🖥️ Model🤗
- A preference optimization (PO) process to enhance the multimodal reasoning capabilities of MLLMs. | VQA
- 24.10 Improve Vision Language Model Chain-of-thought Reasoning | Paper📑 Code🖥️
- Apply reinforcement learning on 193k CoT sft data for reasoning | VQA
- 24.03 (NeurIPS24)Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought Reasoning | Paper📑 Code🖥️
Dataset🤗
- Visual CoT for improve MLLMs' reasoning ability | VQA
- 23.02 Multimodal Chain-of-Thought Reasoning in Language Models | Paper📑 Code🖥️
- Visual CoT for MLLM reasoning | VQA
Video MLLM
- 26.03 LongVideo-R1: Smart Navigation for Low-cost Long Video Understanding | Paper📑 Code🖥️
- Active reasoning-equipped MLLM agent for efficient long video navigation using hierarchical visual summaries and iterative clip refinement, trained via SFT+RL on 33K CoT trajectories. | Task: Video Understanding & Reasoning
- 26.03 Proact-VL: A Proactive VideoLLM for Real-Time AI Companions | Paper📑
- Framework enabling real-time proactive AI companions via chunk-wise video processing with autonomous response timing decisions, evaluated on Live Gaming Benchmark. | Task: Video Understanding & Reasoning
- 26.02 A Very Big Video Reasoning Suite | Paper📑 Model🤗 Dataset🤗
- 1M+ video clip dataset spanning 200 reasoning tasks (VBVR) with VBVR-Bench for verifiable evaluation, enabling emergent generalization via large-scale scaling. | Task: Video Understanding & Reasoning
- 26.02 Thinking in Frames: How Visual Context and Test-Time Scaling Empower Video Reasoning | Paper📑 Project🌐
- Video generation models achieve zero-shot generalization for visual reasoning by using generated frames as intermediate reasoning steps with a visual test-time scaling law. | Task: Video Understanding & Reasoning
- 26.02 Multimodal Fact-Level Attribution for Verifiable Reasoning | Paper📑 Code🖥️
- MuRGAt benchmark requiring MLLMs to provide precise fact-level citations across video, audio, and modalities, finding strong models frequently hallucinate citations despite correct reasoning. | Task: Video Understanding & Reasoning
- 26.02 Towards Universal Video MLLMs with Attribute-Structured and Quality-Verified Instructions | Paper📑 Code🖥️ Model🤗 Dataset🤗
- ASID-Caption suite with 1M structured audiovisual annotations and quality verification pipeline for fine-grained audiovisual video understanding across multiple attribute dimensions. | Task: Video Understanding & Reasoning
- 26.02 VisPhyWorld: Probing Physical Reasoning via Code-Driven Video Reconstruction | Paper📑 Code🖥️
- Execution-based framework evaluating physical reasoning in MLLMs by requiring executable simulator code from visual observations; VisPhyBench (209 scenes) reveals MLLMs struggle to infer physical parameters. | Task: Video Understanding & Reasoning
- 26.01 Taming Hallucinations: Boosting MLLMs' Video Understanding via Counterfactual Video Generation | Paper📑
- Uses counterfactual video generation to reduce hallucinations and improve temporal reasoning in multimodal LLMs. | Task: Video Understanding & Reasoning
- 25.12 Rethinking Chain-of-Thought Reasoning for Videos | Paper📑
- Proposes improved chain-of-thought reasoning strategies specifically designed for video understanding tasks. | Task: Video Understanding & Reasoning
- 25.12 SAGE: Training Smart Any-Horizon Agents for Long Video Reasoning with RL | Paper📑
- RL-based framework training agents for long-horizon video reasoning across variable time spans. | Task: Video Understanding & Reasoning
- 25.11 Video-R4: Reinforcing Text-Rich Video Reasoning with Visual Rumination | Paper📑
- Enhances reasoning over text-rich video content via visual rumination. | Task: Video Understanding & Reasoning
- 25.10 Video-Thinker: Sparking "Thinking with Videos" via Reinforcement Learning | Paper📑
- Reasoning framework enabling models to think with video inputs via RL. | Task: Video Understanding & Reasoning
- 25.10 StreamingVLM: Real-Time Understanding for Infinite Video Streams | Paper📑
- Real-time video stream understanding with multimodal LLMs. | Task: Video Understanding & Reasoning
- 25.09 Video models are zero-shot learners and reasoners | Paper📑
- Demonstrates zero-shot reasoning capabilities in video models. | Task: Video Understanding & Reasoning
- 25.07 Scaling RL to Long Videos| Paper📑 Model🤗 Code🖥️
- 25.06 DeepVideo-R1: Video Reinforcement Fine-Tuning via Difficulty-aware Regressive GRPO|Paper📑
- 25.06 VideoRFT: Incentivizing Video Reasoning Capability in MLLMs via Reinforced Fine-Tuning | Paper📑 Model🤗 Code🖥️
- Extend Reinforcement Fine-Tuning (RFT) to the video reasoning domain, a long-standing challenge. | Task: Video Understanding & Reasoning
- 25.06 VersaVid-R1: A Versatile Video Understanding and Reasoning Model from Question Answering to Captioning Tasks|Paper📑 Model🤗 Code🖥️
- 25.05 SpaceR: Reinforcing MLLMs in Video Spatial Reasoning|Paper📑 Model🤗 Code🖥️
- 25.05 Video-R1: Reinforcing Video Reasoning in MLLMs | Paper📑Model🤗 Code🖥️
- 25.04 TinyLLaVA-Video-R1: Towards Smaller LMMs for Video Reasoning | Paper📑 Model🤗 Code🖥️
- 25.04 Unified Multimodal Chain-of-Thought Reward Model through Reinforcement Fine-Tuning | Paper📑 Project🌐 Code🖥️
- The first unified multimodal CoT reward model, capable of step-by-step long-chain reasoning for visual understanding and generation reward tasks. | Task: Video Understanding and Feneration
- 25.04 ViSMaP: Unsupervised Hour-long Video Summarisation by Meta-Prompting | Paper📑
- A system to summarise hour long videos with no-supervision. | Task: Video Summary
- 25.04 TinyLLaVA-Video-R1: Towards Smaller LMMs for Video Reasoning | Paper📑 Code🖥️ | Model🤗
- Present the small-scale video reasoning model TinyLLaVA-Video-R1 | Task: Video QA
- 25.04 VideoMind: A Chain-of-LoRA Agent for Long Video Reasoning | Paper📑 Code🖥️ | Dataset🤗
- A novel video-language agent designed for temporal-grounded video understanding. | Task: Video QA
- 25.04 Exploring the Effect of Reinforcement Learning on Video Understanding: Insights from SEED-Bench-R1 | Paper📑 Code🖥️ | Dataset🤗
- Reveals that RL enhances visual perception but often produces less logically coherent reasoning chains. | Task: Video QA
- 25.03 VIDEOTREE: Adaptive Tree-based Video Representation for LLM Reasoning on Long Videos |Paper📑 Code🖥️
- 25.02 CoS: Chain-of-Shot Prompting for Long Video Understanding | Paper📑 Code🖥️
- Approach long video understanding by optimising input video information to fully utilise MLLM’s ability to comprehend long videos. | Task: Video VQA
- 25.02 video-SALMONN-o1: Reasoning-enhanced Audio-visual Large Language Model | Paper📑 Demo🖥️
- A open-source reasoning-enhanced audio-visual LLM designed for general video understanding tasks. | Task: Video QA
- 25.02 Open-R1-Video | Code🖥️ Dataset🤗
- A open-source R1-style video understanding model | Task: Video QA
- 25.01 Temporal Preference Optimization for Long-Form Video Understanding | Paper📑Code🖥️
- A novel post-training framework designed to enhance the temporal grounding capabilities of video-LMMs through preference learning | Task: Video QA
- 25.01 Tarsier2: Advancing Large Vision-Language Models from Detailed Video Description to Comprehensive Video Understanding | Paper📑 Code🖥️
Model🤗
- A family of VLMs designed for high-quality video captioning and understanding | Task: Video captioning & QA
- 24.12 (ECCV24) VideoAgent: A Memory-augmented Multimodal Agent for Video Understanding | Paper📑 Code🖥️ Project🌐
- Explore how reconciling several foundation models with a novel unified memory mechanism could tackle the challenging video understanding problem | Task: Video captioning & QA
Audio MLLM
- 25.10 UALM: Unified Audio Language Model for Understanding, Generation and Reasoning Project🌐
- 25.09 MiMo Audio: Audio Language Models are Few-Shot Learners Project🌐 Code🖥️
- 25.07 Audio Entailment: Assessing Deductive Reasoning for Audio Understanding
- 25.07 Audio Flamingo 3: Advancing Audio Intelligence with Fully Open Large Audio Language Models
- 25.05 AudSemThinker: Enhancing Audio-Language Models Through Reasoning over Semantics of Sound
- 25.05 Omni-R1: Do You Really Need Audio to Fine-Tune Your Audio LLM?
- Utilizing GRPO to enhance audio reasoning performance
- 25.04 SARI: Structured Audio Reasoning via Curriculum-Guided Reinforcement Learning
- 25.04 Kimi-Audio Technical Report Code🖥️
- 25.03 Reinforcement Learning Outperforms Supervised Fine-Tuning: A Case Study on Audio Question Answering
- 25.03 Audio-Reasoner: Improving Reasoning Capability in Large Audio Language Models Project🌐
- Utilizing CoT data for audio understanding tasks.
- 25.03 Mellow: a small audio language model for reasoning Code🖥️
- Small audio-language model (167M) designed for audio understanding, audio entailment, audio difference and captioning.
- 25.03 Audio Flamingo 2: An Audio-Language Model with Long-Audio Understanding and Expert Reasoning Abilities Project🌐
- NVIDIA audio-language for various audio understanding and reasoning.
- 25.02 Step-Audio: Unified Understanding and Generation in Intelligent Speech Interaction Code🖥️
- 25.01 Audio-CoT: Exploring Chain-of-Thought Reasoning in Large Audio Language Model
- Finetuning Qwen2-Audio with CoT data for audio understanding and retrieval tasks.
- 24.07 Qwen2-Audio Technical Report Paper📑 Code🖥️
- Qwen audio-language series for various audio understanding tasks especially for speech.
- 24.07 (EMNLP2024) GAMA: A Large Audio-Language Model with Advanced Audio Understanding and Complex Reasoning Abilities Project🌐
- NVIDIA audio-language for various audio understanding and reasoning.
- 24.02 (ICML2024)Audio Flamingo: A Novel Audio Language Model with Few-Shot Learning and Dialogue Abilities Code🖥️
- audio-language for various audio understanding and reasoning with Q-formers.
- 23.11 Qwen-Audio: Advancing Universal Audio Understanding via Unified Large-Scale Audio-Language Models Code🖥️
- Qwen audio-language series for various audio understanding tasks in speech sound and music.
- 23.10 (ICLR2024) SALMONN: Towards Generic Hearing Abilities for Large Language Models Code🖥️
- Bytedance audio-language for various audio understanding tasks especially for speech and sound with Q-former.
- 23.09 (NAACL2024) MusiLingo: Bridging Music and Text with Pre-trained Language Models for Music Captioning and Query Response
- Music-language for understanding and captioning tasks.
Omni MLLM
- 26.05 Boosting Omni-Modal Language Models: Staged Post-Training with Visually Debiased Evaluation Project Dataset🤗
- 26.02 OmniGAIA: Towards Native Omni-Modal AI Agents | Paper📑 Code🖥️ Model🤗 Dataset🤗
- OmniGAIA benchmark for omni-modal agent evaluation on cross-modal reasoning and tool-use, with OmniAtlas agent trained via hindsight-guided tree exploration and OmniDPO. | Task: Reasoning & Understanding
- 26.02 Mobile-O: Unified Multimodal Understanding and Generation on Mobile Device | Paper📑 Code🖥️ Model🤗
- Compact on-device unified multimodal model (~3s/512×512 on iPhone) outperforming Show-O and JanusFlow on generation and visual understanding benchmarks. | Task: Reasoning & Understanding
- 26.02 OmniVideo-R1: Reinforcing Audio-visual Reasoning with Query Intention and Modality Attention | Paper📑
- Reinforced framework for omnivideo models improving mixed-modality reasoning by combining query-intensive grounding and modality-attentive fusion via contrastive learning. | Task: Reasoning & Understanding
- 26.02 UniT: Unified Multimodal Chain-of-Thought Test-time Scaling | Paper📑
- Framework enabling unified multimodal models to perform iterative CoT test-time scaling, showing sequential reasoning is more efficient than parallel sampling for both generation and understanding. | Task: Reasoning & Understanding
- 26.02 Best of Both Worlds: Multimodal Reasoning and Generation via Unified Discrete Flow Matching | Paper📑
- UniDFlow, a unified discrete flow-matching framework decoupling understanding and generation via low-rank adapters and multimodal preference alignment, achieving SOTA across 8 benchmarks. | Task: Reasoning & Understanding
- 26.02 Understanding vs. Generation: Navigating Optimization Dilemma in Multimodal Models | Paper📑 Code🖥️
- R3 (Reason-Reflect-Refine) framework reformulating single-step generation into multi-step generate-understand-regenerate process to resolve the trade-off between multimodal understanding and generation. | Task: Reasoning & Understanding
- 26.02 BrowseComp-V3: A Visual, Vertical, and Verifiable Benchmark for Multimodal Browsing Agents | Paper📑
- 300-question benchmark for complex multi-hop reasoning across text and visual modalities with deep web search; even SOTA models achieve only 36% accuracy, with the OmniSeeker unified browsing agent. | Task: Reasoning & Understanding
- 25.12 Qwen3-VL Technical Report | Paper📑
- Advanced VLM excelling in text and multimodal understanding supporting up to 256K tokens of interleaved text, images, and video. | Task: Reasoning & Understanding
- 25.10 InteractiveOmni: A Unified Omni-modal Model for Audio-Visual Multi-turn Dialogue
- 25.10 Ming-Flash-Omni: A Sparse, Unified Architecture for Multimodal Perception and Generation | Paper📑
- Unified sparse architecture for multimodal perception and generation across modalities. | Task: Reasoning & Understanding
- 25.10 OmniVinci: Enhancing Architecture and Data for Omni-Modal Understanding LLM | Paper📑
- Multimodal LLM for comprehensive understanding across all modalities. | Task: Reasoning & Understanding
- 25.09 Qwen3-Omni Technical Report
- 25.09 Lavida-O: Elastic Large Masked Diffusion Models for Unified Multimodal Understanding and Generation | Paper📑
- Unified model for multimodal understanding and generation across modalities. | Task: Reasoning & Understanding
- 25.07 Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next Generation Agentic Capabilities
- 25.05 EchoInk-R1: Exploring Audio-Visual Reasoning in Multimodal LLMs via Reinforcement Learning
- 25.03 Qwen2.5-Omni Technical Report
- 25.2 NEXUS-O: An Omni-Perceptive and -Interactive Model for Language, Audio, and Vision
- 25.01 OpenOmni: Advancing Open-Source Omnimodal Large Language Models with Progressive Multimodal Alignment and Real-Time Self-Aware Emotional Speech Synthesis
- 24.10 Baichuan-Omni Technical Report
- 24.09 MIO: A Foundation Model on Multimodal Tokens
- 24.08 MiniCPM-V: A GPT-4V Level MLLM on Your Phone [Code]
- 24.02 AnyGPT: Unified Multimodal LLM with Discrete Sequence Modeling
- 23.12 Unified-IO 2: Scaling Autoregressive Multimodal Models with Vision, Language, Audio, and Action
Reasoning Segmentation and Detection
Image MLLM
- 26.02 Retrieve and Segment: Are a Few Examples Enough to Bridge the Supervision Gap in Open-Vocabulary Segmentation? | Paper📑 Code🖥️
- Retrieval-augmented test-time adapter for open-vocabulary segmentation fusing textual prompts with pixel-annotated visual support features to narrow zero-shot vs. supervised gap. | Task: Reasoning Segmentation
- 26.02 Seg-ReSearch: Segmentation with Interleaved Reasoning and External Search | Paper📑 Code🖥️ Dataset🤗
- Novel segmentation paradigm enabling interleaved reasoning and external search to overcome knowledge bottlenecks, with OK-VOS benchmark for open-knowledge video object segmentation. | Task: Reasoning Segmentation
- 26.02 Conversational Image Segmentation: Grounding Abstract Concepts with Scalable Supervision | Paper📑 Code🖥️
- CIS task grounding abstract intent-driven concepts into pixel-accurate masks beyond categorical queries, with ConverSeg benchmark, ConverSeg-Net model, and AI-powered scalable data engine. | Task: Reasoning Segmentation
- 26.03 HDINO: A Concise and Efficient Open-Vocabulary Detector | Paper📑
- Concise open-vocabulary detector with one-to-many semantic alignment achieving strong performance with reduced complexity compared to Grounding DINO. | Task: Detection & Grounding
- 26.01 Urban Socio-Semantic Segmentation with Vision-Language Reasoning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Vision-language reasoning framework for urban satellite segmentation identifying both physical and social categories via multi-stage reasoning. | Task: Reasoning Segmentation
- 26.01 SAMTok: Representing Any Mask with Two Words | Paper📑
- Efficient mask tokenization representing arbitrary segmentation masks with just two tokens, enabling reasoning-driven segmentation. | Task: Reasoning Segmentation
- 26.01 Towards Pixel-Level VLM Perception via Simple Points Prediction | Paper📑
- Enables pixel-level perception in VLMs through simple points prediction, bridging VLM reasoning and fine-grained spatial detection. | Task: Detection & Grounding
- 25.12 ReVSeg: Incentivizing the Reasoning Chain for Video Segmentation with Reinforcement Learning | Paper📑
- Uses RL to incentivize reasoning chains for improved video segmentation. | Task: Reasoning Segmentation
- 25.12 InSight-o3: Empowering Multimodal Foundation Models with Generalized Visual Search | Paper📑
- Enhances multimodal models with generalized visual search for improved grounding. | Task: Detection & Grounding
- 25.11 SAM 3: Segment Anything with Concepts | Paper📑
- Advances segmentation with concept-based reasoning. | Task: Reasoning Segmentation
- 25.10 Decomposed Attention Fusion in MLLMs for Training-Free Video Reasoning Segmentation | Paper📑
- Video reasoning and segmentation with multimodal models without training. | Task: Reasoning Segmentation
- 25.09 RefAM: Attention Magnets for Zero-Shot Referral Segmentation | Paper📑
- Zero-shot referral segmentation using attention-based visual reasoning. | Task: Reasoning Segmentation
- 25.07 UrbanLLaVA: A Multi-modal Large Language Model for Urban Intelligence with Spatial Reasoning and Understanding | Paper📑 Code🖥️
- A multi-stage training framework that decouples spatial reasoning enhancement from domain knowledge learning, thereby improving performance across diverse urban tasks. | Task: Urban tasks
- 25.07 Fine-Grained Preference Optimization Improves Spatial Reasoning in VLMs | Paper📑
- A novel fine-grained preference optimization approach that significantly improves spatial reasoning capabilities in VLMs | Task: Spatial Tasks
- 25.06 Rex-Thinker: Grounded Object Referring via Chain-of-Thought Reasoning | Paper📑 Code🖥️
Model🤗
- a grounded model reasons step-by-step—just like a human would | Task: Detection & Grounding
- 25.03 Visual-RFT: Visual Reinforcement Fine-Tuning | Paper📑 Code🖥️
Dataset🤗
- Extend Reinforcement Fine-Tuning on visual tasks with GRPO | Task: Detection & Grounding & Classification
- 25.03 Boosting the Generalization and Reasoning of Vision Language Models with Curriculum Reinforcement Learning | Paper📑
- Improve generalization and reasoning of VLMs with GRPO | Task: Detection & Classification & Math
- 25.03 Seg-Zero: Reasoning-Chain Guided Segmentation via Cognitive Reinforcement | Paper📑 Code🖥️ Model🤗
- Address object detection and segmentation with GRPO | Task: Object Detection & Object Segmentation
- 24.08 (NeurIPS) Leveraging Hallucinations to Reduce Manual Prompt Dependency in Promptable Segmentation | Paper📑 Code🖥️
- Utilize hallucinations to mine task-related information from images and verify its accuracy for enhancing precision of the generated prompts. | Task: Reasoning Segmentation
- 24.07 (CVPR24) Learning to Localize Objects Improves Spatial Reasoning in Visual-LLMs | Paper📑
- Explore how instruction fine-tuning objectives could inject spatial awareness into V-LLMs| | Task: Reasoning Localization
- 23.04 (AAAI24) Relax Image-Specific Prompt Requirement in SAM: A Single Generic Prompt for Segmenting Camouflaged Objects | Paper📑 Code🖥️
- Employ Cross-modal Chains of Thought Prompting (CCTP) to reason visual prompts using the semantic information given by a generic text prompt. | Task: Reasoning segmentation
- 23.12 (CVPR24) PixelLM:Pixel Reasoning with Large Multimodal Model | Paper📑 Code🖥️
- An effective and efficient LMM for pixel-level reasoning and understanding | Task: Reasoning Segmentation
- 23.08 (CVPR24)LISA: Reasoning Segmentation via Large Language Model | Paper📑 Code🖥️ Dataset🤗
- Inherit the language generation capabilities of the MLLM while also possessing the ability to produce segmentation masks. | Task: Reasoning Segmentation
Video MLLM
- 26.02 VidEoMT: Your ViT is Secretly Also a Video Segmentation Model | Paper📑 Code🖥️ Model🤗
- Lightweight encoder-only video segmentation on plain ViT with query propagation and fusion, achieving 160 FPS with ViT-L without dedicated tracking modules. | Task: Reasoning Segmentation
- 26.02 Learning Cross-View Object Correspondence via Cycle-Consistent Mask Prediction | Paper📑 Code🖥️
- Conditional binary segmentation with cycle-consistency training for object-level correspondence across egocentric/exocentric viewpoints without ground-truth annotations (CVPR 2026). | Task: Reasoning Segmentation
- 24.08 (ECCV24)VISA: Reasoning Video Object Segmentation via Large Language Model | Paper📑 Code🖥️ Dataset🤗
- Leverage the world knowledge reasoning capabilities of MLLMs while possessing the ability to segment and track objects in videos with a mask decoder | Task: Reasoning Segmentation
- 24.07 (NeruIPS24)One Token to Seg Them All: Language Instructed Reasoning Segmentation in Videos | Paper📑 Code🖥️ Model🤗
- Integrating a Sparse Dense Sampling strategy into the video-LLM to balance temporal context and spatial detail within computational constraints | Task: Reasoning Segmentation
- 24.01 (CVPR24) OMG-LLaVA: Bridging Image-level, Object-level, Pixel-level Reasoning and Understanding | Paper📑 Code🖥️
- A transformer-based encoder-decoder architecture with task-specific queries and outputs for multiple tasks | Task: Reasoning Segmentation/Detection
Audio MLLM
Omni MLLM
- 25.07 Towards Omnimodal Expressions and Reasoning in Referring Audio-Visual Segmentation
- 24.08 Unleashing the Temporal-Spatial Reasoning Capacity of GPT for Training-Free Audio and Language Referenced Video Object Segmentation
Spatial and Temporal Grounding and Understanding
Image MLLM
- 26.02 GeoWorld: Geometric World Models | Paper📑
- Hyperbolic JEPA preserving latent state structures for improved long-horizon world model prediction and Geometric RL planning (CVPR 2026). | Task: Spatial Reasoning
- 26.02 When and How Much to Imagine: Adaptive Test-Time Scaling with World Models for Visual Spatial Reasoning | Paper📑 Code🖥️
- AVIC adaptively invokes visual imagination via world models to match or outperform fixed imagination strategies for spatial reasoning with far fewer calls. | Task: Spatial Reasoning
- 26.02 Theory of Space: Can Foundation Models Construct Spatial Beliefs through Active Exploration? | Paper📑 Code🖥️ Dataset🤗
- Evaluates VLMs' ability to construct spatial beliefs through active exploration, revealing Active-Passive Gap and Belief Inertia—VLMs fail to update stale spatial priors. | Task: Spatial Understanding
- 26.02 SpatiaLab: Can Vision-Language Models Perform Spatial Reasoning in the Wild? | Paper📑 Code🖥️ Dataset🤗
- Benchmark of 1,400 VQA pairs across six spatial reasoning categories revealing VLMs achieve only ~55% vs. 87.6% human accuracy (ICLR 2026). | Task: Spatial Reasoning
- 26.02 LangMap: A Hierarchical Benchmark for Open-Vocabulary Goal Navigation | Paper📑 Code🖥️
- Multi-granularity open-vocabulary navigation task with 414 object categories and 18K+ navigation tasks across scene, room, region, and instance levels. | Task: Spatial Grounding & Navigation
- 26.02 GeoAgent: Learning to Geolocate Everywhere with Reinforced Geographic Characteristics | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Geolocation reasoning model using RL with geo-similarity and consistency rewards over GeoSeek dataset, enabling fine-grained address-level localization with human-like reasoning. | Task: Spatial Reasoning
- 26.03 Enhancing Spatial Understanding in Image Generation via Reward Modeling | Paper📑 Project🌐
- SpatialReward-Dataset (80K preference pairs) and SpatialScore reward model for evaluating spatial relationship accuracy; enables online RL to significantly enhance spatial reasoning in image generation. | Task: Spatial Reasoning
- 26.01 CoV: Chain-of-View Prompting for Spatial Reasoning | Paper📑 Code🖥️
- Training-free test-time reasoning framework transforming VLMs into active viewpoint reasoners through coarse-to-fine 3D exploration, +11.56% on OpenEQA. | Task: Spatial Reasoning
- 26.01 Think3D: Thinking with Space for Spatial Reasoning | Paper📑
- Framework for spatial reasoning enabling models to reason in 3D space for improved visual understanding tasks. | Task: Spatial Reasoning & 3D Understanding
- 25.12 SpaceTools: Tool-Augmented Spatial Reasoning via Double Interactive RL | Paper📑
- Tool-augmented spatial reasoning using double interactive reinforcement learning. | Task: Spatial Reasoning
- 25.12 COOPER: A Unified Model for Cooperative Perception and Reasoning in Spatial Intelligence | Paper📑
- Unified model combining cooperative perception with spatial intelligence reasoning. | Task: Spatial Reasoning
- 25.11 SpatialThinker: Reinforcing 3D Reasoning in Multimodal LLMs via Spatial Rewards | Paper📑
- Uses reinforcement learning with spatial rewards to improve 3D reasoning in MLLMs. | Task: Spatial Reasoning & 3D Understanding
- 25.11 G2VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning | Paper📑
- Unifies 3D reconstruction and spatial reasoning in a geometry-grounded VLM. | Task: Spatial Reasoning & 3D Understanding
- 25.10 SpaceVista: All-Scale Visual Spatial Reasoning from mm to km | Paper📑
- Spatial reasoning across multiple scales in visual understanding. | Task: Spatial Reasoning
- 25.08 3D-R1: Enhancing Reasoning in 3D VLMs for Unified Scene Understanding | Paper📑
- Enhances reasoning capabilities of 3D vision-language models for unified 3D scene understanding. | Task: Spatial Reasoning & 3D Understanding
- 25.04 Perspective-Aware Reasoning in Vision-Language Models via Mental Imagery Simulation | Paper📑 Project🌐 Code🖥️
- A framework for perspective-aware reasoning in vision-language models (VLMs) through mental imagery simulation. | Task: Spatial Reasoning & Understanding
- 25.04 Reason-RFT: Reinforcement Fine-Tuning for Visual Reasoning | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Introduce a combined RL and SFT training paradigm to enhance visual reasoning capabilities in multimodal models. | Task: Spatial Reasoning & Understanding
- 25.04 InteractVLM: 3D Interaction Reasoning from 2D Foundational Models | Paper📑 Code💻
- Harnesses the broad visual knowledge of large Vision-Language Models (VLMs), fine-tuned with limited 3D contact data. Task: 3D Reconstruction
- 25.03 Embodied-Reasoner: Synergizing Visual Search, Reasoning, and Action for Embodied Interactive Tasks | Paper📑 Code💻 Project🌐 Dataset🤗
- A model that extends O1-style reasoning to interactive embodied tasks. | Task: Interactive Embodied Tasks
- 25.03 VisualThinker-R1-Zero | Paper📑 Code💻
- R1-Zero's "Aha Moment" in Visual Reasoning on a 2B Non-SFT Model | Task: Counting & Reasoning & 3D Understanding (CV-Bench)
- 25.03 (CVPR2025)GFlowVLM: Enhancing Multi-step Reasoning in Vision-Language Models with Generative Flow Networks | Paper📑
- Fine-tune VLMs using GFlowNet to promote generation of diverse solutions.| Task: NumberLine (NL) & BlackJack (BJ)
- 25.02 R1-V: Reinforcing Super Generalization Ability in Vision Language Models with Less Than $3 | Code🖥️
- A open-source project for VLM reasoning with GRPO | Task: Counting, Number Related Reasoning and Geometry Reasoning
- 25.01 Imagine while Reasoning in Space: Multimodal Visualization-of-Thought | Paper📑
- Enables visual thinking in MLLMs by generating image visualizations of their reasoning traces. | Task: Spatial Reasoning
Video MLLM
- 26.02 TimeChat-Captioner: Scripting Multi-Scene Videos with Time-Aware and Structural Audio-Visual Captions | Paper📑 Code🖥️ Model🤗
- Omni Dense Captioning with six-dimensional structural schema generating time-aware audio-visual narratives with explicit timestamps, surpassing Gemini-2.5-Pro on the task. | Task: Temporal Grounding/Understanding
- 26.02 4RC: 4D Reconstruction via Conditional Querying Anytime and Anywhere | Paper📑
- 4D dynamic scene reconstruction framework with conditional querying at arbitrary space-time locations for flexible spatiotemporal understanding of dynamic scenes. | Task: Spatial-Temporal Understanding
- 26.02 Learning Situated Awareness in the Real World | Paper📑
- SAW-Bench evaluates egocentric situated awareness using 786 real-world videos from smart glasses with 2,071+ QA pairs, revealing a 37.66% human-model performance gap in observer-centric spatial reasoning. | Task: Temporal Grounding/Understanding
- 26.02 MoRL: Reinforced Reasoning for Unified Motion Understanding and Generation | Paper📑 Code🖥️
- Unified multimodal motion model combining SFT and RL with Chain-of-Motion (CoM) reasoning and large-scale CoT datasets for human motion understanding and generation. | Task: Spatial-Temporal Understanding
- 26.03 RIVER: A Real-Time Interaction Benchmark for Video LLMs | Paper📑
- Benchmark evaluating real-time interaction in Video LLMs with Retrospective Memory, Live-Perception, and Proactive Response tasks, revealing gaps in long-term memory and future perception. | Task: Temporal Understanding
- 26.01 VideoLoom: A Video Large Language Model for Joint Spatial-Temporal Understanding | Paper📑 Code🖥️ Model🤗
- Unified Video LLM for joint spatial-temporal understanding with LoomData-8.7k dataset and LoomBench benchmark. | Task: Spatial-Temporal Understanding
- 26.01 VideoAuto-R1: Video Auto Reasoning via Thinking Once, Answering Twice | Paper📑 Code🖥️
- Video understanding framework with "reason-when-necessary" strategy using confidence-based reasoning activation, reducing response length 3.3x. | Task: Video Understanding & Reasoning
- 26.01 Molmo2: Open Weights and Data for Vision-Language Models with Video Understanding and Grounding | Paper📑 Code🖥️
- Open-source video-language model family with point-driven grounding and video tracking capabilities surpassing Gemini 3 Pro on grounding. | Task: Spatial Understanding & Grounding
- 26.01 PROGRESSLM: Towards Progress Reasoning in Vision-Language Models | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Addresses task progress estimation in VLMs with Progress-Bench benchmark and ProgressLM-3B model. | Task: Temporal Reasoning & Understanding
- 26.01 HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video Understanding | Paper📑
- Efficient streaming video understanding via hierarchical KV cache memory enabling temporal reasoning over long videos. | Task: Temporal Reasoning
- 25.12 4D-RGPT: Toward Region-level 4D Understanding via Perceptual Distillation | Paper📑
- Region-level 4D (3D + temporal) understanding through perceptual distillation. | Task: Spatial-Temporal Understanding
- 25.12 MMSI-Video-Bench: A Holistic Benchmark for Video-Based Spatial Intelligence | Paper📑
- Comprehensive benchmark for evaluating spatial intelligence in video understanding. | Task: Spatial-Temporal Understanding
- 25.11 VLA-4D: Embedding 4D Awareness into Vision-Language-Action Models for SpatioTemporally Coherent Robotic Manipulation | Paper📑
- Incorporates 4D spatiotemporal awareness into VLA models for coherent robotic manipulation. | Task: Spatial-Temporal Understanding
- 25.10 Trace Anything: Representing Any Video in 4D via Trajectory Fields | Paper📑
- 4D spatial-temporal representation learning from video. | Task: Spatial-Temporal Understanding
- 25.08 VLM4D: Towards Spatiotemporal Awareness in Vision Language Models | Paper📑
- Extends VLMs with spatiotemporal reasoning for understanding spatial and temporal dynamics. | Task: Spatial-Temporal Understanding
- 25.05 MUSEG: Reinforcing Video Temporal Understanding via Timestamp-Aware Multi-Segment Grounding | Paper📑 Code💻
- 25.04 VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning | Paper📑 Code💻
- A novel spatiao-temporal perception framework with GRPO | Task: Spatial Understanding and Grounding
- 25.04 VisuoThink: Empowering LVLM Reasoning with Multimodal Tree Search | Paper📑 Code💻
- A novel framework that seamlessly integrates visuospatial and linguistic domains | Task: Geometry and Spatial Reasoning
- 25.04 Improved Visual-Spatial Reasoning via R1-Zero-Like Training | Paper📑 Code💻
- Incorporate GRPO training for improved visual-spatial reasoning, using the carefully curated VSI-100k dataset. | Task: Video Understanding
- 25.03 Envolving Temporal Reasoning Capability into LMMs via Temporal Consistent Reward | Code💻 Model🤗
- Investigate the potential of GRPO in the video temporal grounding task, which demands precise temporal alignment between visual and linguistic modalities as well as advanced reasoning capabilities | Task: Temporal Grounding
- 25.03 TimeZero: Temporal Video Grounding with Reasoning-Guided LVLM | Paper📑 Code💻 Model🤗
- A reasoning-guided MLLM for temporal video grounding, trained with GRPO. | Task: Temporal Grounding
- 25.03 LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding | Paper📑 Code💻
- A MLLM for fine-grained spatial-temporal multimodal understanding. | Task: Spatial-Temporal Understanding
- 25.03 MetaSpatial: Reinforcing 3D Spatial Reasoning in VLMs for the Metaverse | Code🖥️
- Enhance spatial reasoning in VLMs using GRPO | Task: 3D Spatial Reasoning
- 25.02 Video-R1: Towards Super Reasoning Ability in Video Understanding | Code🖥️
- Integrate deep thinking capabilities into video understanding tasks through the R1 paradigm | Task: Video Counting
- 24.12 TIMEREFINE: Temporal Grounding with Time Refining Video LLM | Paper📑 | Code🖥️
- Enhance Video LLMs to handle the temporal grounding task by modifying the learning objective | Task: Temporal Grounding
- 24.11 (CVPR2025) Number it: Temporal Grounding Videos like Flipping Manga | Paper📑 | Code💻
- Enhances Video-LLMs by overlaying frame numbers onto video frames | Task: Temporal Grounding
- 24.11 TimeMarker: A Versatile Video-LLM for Long and Short Video Understanding with Superior Temporal Localization Ability | Paper📑 | Code💻
- A versatile Video-LLM featuring robust temporal localization abilities | Task: Temporal Grounding and Video QA
- 24.08 (AAAI2025) Grounded Multi-Hop VideoQA in Long-Form Egocentric Videos | Paper📑 | Code💻
- Leverage the world knowledge reasoning capabilities of MLLMs to retrieve temporal evidence in the video with flexible grounding tokens. | Task: Multi-Hop VideoQA
- 24.08 (ICLR2025) TRACE: Temporal Grounding Video LLM via Casual Event Modeling | Paper📑 | Code💻
- Tailored to implement the causal event modeling framework through timestamps, salient scores, and textual captions. | Task: Temporal Grounding
Audio MLLM
- 25.07 Towards Spatial Audio Understanding via Question Answering
- 24.06 (InterSpeech 2024) Can Large Language Models Understand Spatial Audio? |
- 24.02 (ICML 2024)BAT: Learning to Reason about Spatial Sounds with Large Language Models |
Omni MLLM
Math Reasoning
Image MLLM
- 26.02 P1-VL: Bridging Visual Perception and Scientific Reasoning in Physics Olympiads | Paper📑 Code🖥️ Model🤗
- Open-source VLM family for advanced scientific reasoning using curriculum RL and agentic augmentation, achieving the first open-source model winning 12 gold medals at physics olympiad level. | Task: Math
- 26.02 DeepVision-103K: A Visually Diverse, Broad-Coverage, and Verifiable Mathematical Dataset for Multimodal Reasoning | Paper📑 Code🖥️ Dataset🤗
- 103K-sample RLVR training dataset for multimodal K12 mathematical reasoning with diverse topics and rich visual elements, generalizing to general multimodal reasoning tasks. | Task: Math
- 26.02 Vision-DeepResearch: Incentivizing DeepResearch Capability in Multimodal Large Language Models | Paper📑 Code🖥️
- Multimodal deep-research paradigm enabling multi-turn, multi-entity, multi-scale visual and textual search via cold-start supervision and RL. | Task: Math
- 26.02 LaViDa-R1: Advancing Reasoning for Unified Multimodal Diffusion Language Models | Paper📑
- Multimodal reasoning diffusion LM using SFT + multi-task RL with answer-forcing, tree search, and complementary likelihood estimation for visual math reasoning and image editing. | Task: Math
- 26.02 Embed-RL: Reinforcement Learning for Reasoning-Driven Multimodal Embeddings | Paper📑 Code🖥️
- Reasoning-driven multimodal embedding framework using Embedder-Guided RL (EG-RL) to optimize Traceability Chain-of-Thought generation for improved cross-modal semantic consistency. | Task: Math
- 26.01 CogFlow: Bridging Perception and Reasoning through Knowledge Internalization for Visual Mathematical Problem Solving | Paper📑 Project🌐
- Cognitive-inspired three-stage framework (Perception-Internalization-Reasoning) for visual math with MathCog dataset of 120K+ annotations. | Task: Math
- 26.01 MindWatcher: Toward Smarter Multimodal Tool-Integrated Reasoning | Paper📑
- Multimodal tool-integrated reasoning framework enhancing chain-of-thought with tool use for complex math/science problems. | Task: Math
- 26.01 MMFormalizer: Multimodal Autoformalization in the Wild | Paper📑
- Framework for automatically formalizing multimodal mathematical content from images and text into formal representations. | Task: Math
- 25.11 MathSE: Improving Multimodal Mathematical Reasoning via Self-Evolving Iterative Reflection and Reward-Guided Fine-Tuning | Paper📑
- Improves multimodal math reasoning via iterative self-evolution and reward-guided training. | Task: Math
- 25.10 Training Vision-Language Process Reward Models for Test-Time Scaling in Multimodal Reasoning | Paper📑
- Process reward models for scaling multimodal reasoning at test time. | Task: Math
- 25.09 BaseReward: A Strong Baseline for Multimodal Reward Model | Paper📑
- Strong baseline reward model for multimodal RL-based alignment. | Task: Math
- 25.08 MathReal: A Real Scene Benchmark for Evaluating Math Reasoning in MLLMs | Paper📑
- Benchmark for evaluating multimodal math reasoning using real-world scene photographs. | Task: Math
- 25.11 Perceptual-Evidence Anchored Reinforced Learning for Multimodal Reasoning | Paper📑 Code🖥️ Model🤗
- Introduce a perception checklist to anchor RL policy updates in verified visual evidence and prevent hallucinations. | Task: Math
- 25.11 Metis-HOME: Hybrid Optimized Mixture-of-Experts for Multimodal Reasoning | Paper📑 Code🖥️ Model🤗
- Use a mixture-of-experts framework with dynamic routing for balancing complex reasoning and general tasks. | Task: Math
- 25.10 Metis-SPECS: Decoupling Multimodal Learning via Self-distilled Preference-based Cold Start | Paper📑 Code🖥️
- Replace supervised fine-tuning with self-distilled, preference-based cold starts to improve RL generalization. | Task: Math
- 25.09 DeepSketcher: Internalizing Visual Manipulation for Multimodal Reasoning | Paper📑 Code🖥️
- Internalize visual reasoning by directly manipulating visual embeddings using code-rendered trajectories, bypassing external tools and reducing grounding noise. | Task: Math
- 25.07 The Synergy Dilemma of Long-CoT SFT and RL: Investigating Post-Training Techniques for Reasoning VLMs Paper📑 Code🖥️
- a systematic investigation into the distinct roles and interplay of long-CoT SFT and RL across multiple multimodal reasoning benchmarks. | Task: Math
- 25.06 Metis-RISE: RL Incentivizes and SFT Enhances Multimodal Reasoning Model Learning | Paper📑 Code🖥️ Model🤗
- Reverse the training pipeline by first using RL for reasoning exploration, then applying SFT with self-distilled and expert-augmented trajectories for stability and capability enhancement. | Task: Math
- 25.06 SynthRL: Scaling Visual Reasoning with Verifiable Data Synthesis Paper📑 Code🖥️ Model🤗
- A novel framework that enhances the reasoning capabilities of multimodal large language models. | Task: Math
- 25.06 SRPO: Enhancing Multimodal LLM Reasoning via Reflection-Aware Reinforcement Learning Paper📑 Code🖥️ Model🤗
- scale the training data with correctness and distribution guarantees to achieve better performance. | Task: Math
- 25.05 Unsupervised Post-Training for Multi-Modal LLM Reasoning via GRPO Paper📑 Code🖥️
- A Unsupervised Post-Training for Multi-Modal LLM Reasoning via GRPO. | Task: Math
- 25.05 X-Reasoner: Towards Generalizable Reasoning Across Modalities and Domains | Paper📑 Code🖥️
- A training recipe that optimizes the reasoning capability of VLMs with SFT and RL on general-domain text-only data. | Task: Math
- 25.04 NoisyRollout: Reinforcing Visual Reasoning with Data Augmentation | Paper📑 Code🖥️ Model🤗
- Introduces targeted rollout diversity by mixing rollouts from both clean and moderately distorted images, encouraging the model to learn more robust behaviors. | Task: Math
- 25.04 VL-Rethinker: Incentivizing Self-Reflection of Vision-Language Models with Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- Aim to enhance the slow-thinking capabilities of vision-language models using reinforcement learning (without relying on distillation) to advance the SOTA. | Task: Math
- 25.04 SoTA with Less: MCTS-Guided Sample Selection for Data-Efficient Visual Reasoning Self-Improvement | Paper📑 Code🖥️
- Propose a novel way of repurposing Monte Carlo Tree Search (MCTS) to enable effective data filtering. | Task: Math reasoning
- 25.04 GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning | Paper📑 Project🌐 Code🖥️
- A generative process reward model that performs explicit COT reasoning with code verification before providing judgment for each reasoning step. | Task: Math
- 25.03 OpenVLThinker: An Early Exploration to Vision-Language Reasoning via Iterative Self-Improvement | Paper📑 Code🖥️ Dataset🤗
- Investigate whether R1-like reasoning capabilities can be successfully integrated into LVLMs and assesses their impact on challenging multimodal reasoning tasks. | Task: Math
- 25.03 R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization | Paper📑 Code🖥️ Dataset🤗
- Design Step-wise Group Relative Policy Optimization (StepGRPO) that enables MLLMs to self-improve reasoning ability. | Task: Math
- 25.03 LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL | Paper📑 Code🖥️ Dataset🤗
- A two-stage rule-based RL framework that efficiently enhances reasoning capabilities | Task: Math & Sokoban
- 25.03 VisualPRM: An Effective Process Reward Model for Multimodal Reasoning | Paper📑 Code🖥️ Dataset🤗
- Improve the reasoning abilities of existing MLLMs with Best-of-N evaluation strategies | Task: Math & MMMU
- 25.03 R1-Onevision: Advancing Generalized Multimodal Reasoning through Cross-Modal Formalization | Paper📑 Code🖥️ Dataset🤗
- A multimodal reasoning model bridged the gap between multimodal capabilities and reasoning abilities with GRPO | Task: Math
- 25.03 MMR1: Advancing the Frontiers of Multimodal Reasoning | Code🖥️
- a Large Multimodal Model specialized in mathematical tasks using GRPO | Task: Math
- 25.03 Boosting the Generalization and Reasoning of Vision Language Models with Curriculum Reinforcement Learning | Paper📑
- Improve generalization and reasoning of VLMs with GRPO | Task: Detection & Classification & Math
- 25.03 Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models | Paper📑Code🖥️
- Improve reasoning ability of MLLM with GRPO | Task: Math
- 25.03 MM-EUREKA: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning | Paper📑 Code🖥️ Dataset🤗
- Extend large-scale rule-based reinforcement learning to multimodal reasoning | Task: Math
- 25.03 [EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework] Code🖥️
- A Multimodal GRPO training framework | Task: Math
- 25.02 [Qwen2.5-VL] Qwen2.5-VL Technical Report | Paper📑 Code🖥️ Huggingface🤗
- The latest flagship model of Qwen vision-language series for various multimodal tasks | Task: Reasoning & Understainding * 25.02 Multimodal Open R1 | Code🖥️
- A open-source database for video R1 reproduce. | Task: Math
- 25.02 Boosting Multimodal Reasoning with MCTS-Automated Structured Thinking | Paper📑
- An automated structured thinking paradigm for multimodal reasoning via Monte Carlo Tree Search | Task: Math
- 25.02 MM-Verify: Enhancing Multimodal Reasoning with Chain-of-Thought Verification | Paper📑 Code🖥️
- Enhance multimodal reasoning through longer inference and more robust verification. | Task: Math
- 25.01 Kimi k1.5: Scaling Reinforcement Learning with LLMs (MoonshotAI) | Project🌐
- The latest flagship model of Kimi series for various multimodal tasks | Task: Reasoning & Understainding
- 25.01 Virgo: A Preliminary Exploration on Reproducing o1-like MLLM | Paper📑 Code🖥️ Model🤗
- A o1-like MLLM for multimodal reasoning |Task: Math & MMMU
Chart Rasoning
- 26.03 FireRed-OCR Technical Report | Paper📑
- Framework transforming general VLMs into pixel-precise document parsing experts via three-stage progressive training (pre-alignment, SFT, format-constrained GRPO), achieving 92.94% SOTA on OmniDocBench v1.5. | Task: Document Reasoning
- 26.02 OCR-Agent: Agentic OCR with Capability and Memory Reflection | Paper📑 Code🖥️
- Iterative self-correction framework using Capability Reflection (error diagnosis) and Memory Reflection (avoiding repeated attempts), achieving SOTA on OCRBench v2 without training. | Task: Document Reasoning
- 26.02 OmniOCR: Generalist OCR for Ethnic Minority Languages | Paper📑 Code🖥️
- Universal OCR framework using Dynamic LoRA for low-resource ethnic minority scripts, achieving 39-66% accuracy improvements on Tibetan, Shui, and other scripts. | Task: Document Reasoning
- 26.02 DODO: Discrete OCR Diffusion Models | Paper📑
- Adapts block discrete diffusion for OCR enabling parallel token processing, achieving up to 3× faster inference while maintaining near-SOTA accuracy. | Task: Document Reasoning
- 26.02 PaddleOCR-VL-1.5: Towards a Multi-Task 0.9B VLM for Robust In-the-Wild Document Parsing | Paper📑
- Compact 0.9B VLM for multi-task document parsing in diverse real-world conditions covering OCR, layout understanding, and chart comprehension. | Task: Document Reasoning
- 26.02 ExStrucTiny: A Benchmark for Schema-Variable Structured Information Extraction from Document Images | Paper📑
- Benchmark unifying key entity extraction, relation extraction, and VQA for structured information extraction from document images, evaluating VLMs on schema adaptation and answer localization. | Task: Document Reasoning
- 26.02 MemOCR: Layout-Aware Visual Memory for Efficient Long-Horizon Reasoning | Paper📑
- Layout-aware visual memory mechanisms for MLLMs to improve long-horizon document and OCR reasoning efficiency. | Task: Document Reasoning
- 26.01 ChartVerse: Scaling Chart Reasoning via Reliable Programmatic Synthesis from Scratch | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Scalable chart reasoning framework using Rollout Posterior Entropy; ChartVerse-8B surpasses its teacher model Qwen3-VL-30B. | Task: Chart Reasoning
- 25.10 From Charts to Code: A Hierarchical Benchmark for Multimodal Models | Paper📑
- Benchmark for chart understanding and code generation from charts. | Task: Chart Reasoning
- 25.09 Visual-TableQA: Open-Domain Benchmark for Reasoning over Table Images | Paper📑
- Benchmark for visual question answering and reasoning over table images. | Task: Chart Reasoning
- 25.09 MinerU2.5: A Decoupled Vision-Language Model for Efficient High-Resolution Document Parsing | Paper📑
- Efficient VLM for parsing and understanding high-resolution documents. | Task: Document Reasoning
- 25.09 Visual Programmability: A Guide for Code-as-Thought in Chart Understanding | Paper📑 Code🖥️
- Introduce an adaptive framework that enables VLMs to dynamically choose between code-based and visual reasoning pathways for chart understanding. | Task: Chart Reasoning
- 25.07 Chart-R1: Chain-of-Thought Supervision and Reinforcement for Advanced Chart Reasoner | Paper📑 Code🖥️ Model🤗
- Combine chain-of-thought supervision with reinforcement learning, supported by programmatically synthesized step-by-step reasoning data. | Task: Chart Reasoning
- 25.06 ChartReasoner: Code-Driven Modality Bridging for Long-Chain Reasoning in Chart Question Answering | Paper📑
- Combine chart code generation with long-chain reasoning LLMs to produce detailed reasoning processes. | Task: Chart Reasoning
- 25.05 Point-RFT: Improving Multimodal Reasoning with Visually Grounded Reinforcement Finetuning | Paper📑
- Introduce a visually grounded chain-of-thought (CoT) paradigm, enabling the model to generate CoT reasoning aligned with visual elements. | Task: Chart Reasoning
- 25.04 Bespoke-MiniChart-7B: Pushing The Frontiers Of Open VLMs For Chart Understanding | Project🌐 Model🤗
- Employ a three-stage training process, combining rejection sampling and DPO optimization to enhance out-of-distribution generalization. | Task: Chart Reasoning
- 25.03 MDocAgent: A Multi-Modal Multi-Agent Framework for Document Understanding | Paper📑 Code🖥️
- Integrate text and image retrieval through various agents, enabling collaborative reasoning across modalities. | Task: Document Reasoning
- 24.11 ChartGemma: Visual Instruction-tuning for Chart Reasoning in the Wild | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Generate multi-task instruction-tuning data from real chart images and integrating both COT and POT reasoning pathways. | Task: Chart Reasoning
- 24.09 (ICLR25 Oral) ChartMoE: Mixture of Diversely Aligned Expert Connector for Chart Understanding | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Utilize diverse chart-text aligned tasks (chart -> table/json/python-code) to augment chart understanding and reasoning. | Task: Chart Reasoning
- 24.09 ChartX & ChartVLM: A Versatile Benchmark and Foundation Model for Complicated Chart Reasoning | Project🌐 Paper📑 Code🖥️
- Offer a new perspective on handling chart reasoning tasks that strongly depend on interpretable patterns. | Task: Chart Reasoning
- 24.07 (EMNLP24) Multimodal Self-Instruct: Synthetic Abstract Image and Visual Reasoning Instruction Using Language Model | Paper📑 Project🌐 Code🖥️ Dataset🤗
- A multi-modal self-instruct, utilizing large language models and their code capabilities to synthesize massive abstract images and visual reasoning instructions across daily scenarios. | Task: Chart Reasoning
- 24.04 (EMNLP24) TinyChart: Efficient Chart Understanding with Visual Token Merging and Program-of-Thoughts Learning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Employ PoT learning for numerical reasoning and Vision Token Merging to compress visual features from high-resolution images. | Task: Chart Reasoning
- 24.04 (MM24) OneChart: Purify the Chart Structural Extraction via One Auxiliary Token | Paper📑 Project🌐 Code🖥️ Model🤗
- Introduce an auxiliary token and decoder combined with a customized L1 loss to enhance the reliability of structured and numerical information extraction. | Task: Chart Reasoning
- 24.04 (MM24) NovaChart: A Large-scale Dataset towards Chart Understanding and Generation of Multimodal Large Language Models | Paper📑 Code🖥️ Dataset🤗
- Construct a large-scale dataset for chart understanding and generation, covering 18 different chart types and 15 unique tasks. | Task: Chart Reasoning
- 24.02 (ACL24) ChartAssisstant: A Universal Chart Multimodal Language Model via Chart-to-Table Pre-training and Multitask Instruction Tuning | Paper📑 Code🖥️ Dataset🤗
- Use large-scale chart data to align and instruction tuning | Task: Chart Reasoning
- 23.11 ChartLlama: A Multimodal LLM for Chart Understanding and Generation | Paper📑 Project🌐 Code🖥️ Model🤗 Dataset🤗
- Generate a diverse and high-quality instruction-tuning dataset using GPT-4, and use LLaVA for unified multi-task training. | Task: Chart Reasoning
- 23.10 (EMNLP23) UniChart: A Universal Vision-language Pretrained Model for
Chart Comprehension and Reasoning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Pretrains on a large and diverse chart dataset, explicitly modeling visual elements and structures. | Task: Chart Reasoning
Benchmark
- 25.11 (EMNLP25) ChartM3: A Multi-Stage Code-Driven Pipeline for Constructing Multi-Dimensional and Multi-Step Visual Reasoning Data in Chart Comprehension | Paper📑
- Provide an evaluation set of 2,871 high-quality samples covering 62 chart types and 60 real-world scenarios, focusing on multi-dimensional and multi-step visual reasoning and complex business analysis. | Task: Chart Reasoning
- 25.05 ChartMuseum: Testing Visual Reasoning Capabilities of Large Vision-Language Models | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Feature real-world chart images and four distinct question types that assess textual, visual, combined, and synthesis reasoning abilities. | Task: Chart Reasoning
- 25.04 CHARTQAPRO : A More Diverse and Challenging Benchmark for Chart Question Answering | Paper📑 Code🖥️ Dataset🤗
- Introduce a diverse benchmark with 1,341 charts and 1,948 questions covering various chart types and question formats, designed to rigorously evaluate the chart reasoning capabilities of large vision-language models in real-world scenarios. | Task: Chart Reasoning
- 25.01 (AAAI25) EvoChart: A Benchmark and a Self-Training Approach Towards Real-World Chart Understanding | Paper📑 Code🖥️ Dataset🤗
- Feature 650 real-world charts, 1,250 expert-curated questions, and strict and flexible automatic evaluation metrics to assess chart comprehension abilities of VLMs in practical scenarios. | Task: Chart Reasoning
- 24.06 (NIPS24) CharXiv: Charting Gaps in Realistic Chart Understanding in Multimodal LLMs | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Focus on real and complex charts from arXiv papers, covering eight major domains. All content is expert-curated and verified, with evaluation using GPT-4o scoring and binary correctness metrics. | Task: Chart Reasoning
- 24.06 (VRISP25) ChartBench: A Benchmark for Complex Visual Reasoning in Charts | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Cover 9 major categories and 42 subcategories of charts without data point annotations, emphasizing numerical extraction ability. | Task: Chart Reasoning
- 24.04 (NAACL24) MMC: Advancing Multimodal Chart Understanding with Large-scale Instruction Tuning | Paper📑 Code🖥️ Dataset🤗
- Propose a comprehensive human-annotated benchmark with nine distinct tasks evaluating reasoning capabilities over various charts, and support both GPT-4 scoring and multiple-choice exact matching. | Task: Chart Reasoning
- 22.05 (ACL22) ChartQA: A Benchmark for Question Answering about Charts with Visual and Logical Reasoning | Paper📑 Code🖥️ Dataset🤗
- Use real-world charts and open-ended questions to evaluate chart understanding, reasoning, and data extraction, with relaxed accuracy as the metric. | Task: Chart Reasoning
Visual-Audio Generation
Image MLLM
- 26.02 DeepGen 1.0: A Lightweight Unified Multimodal Model for Advancing Image Generation and Editing | Paper📑 Code🖥️ Model🤗
- Lightweight 5B unified model for image generation and editing using hierarchical feature extraction, learnable think tokens, and MR-GRPO reinforcement learning, outperforming much larger models. | Task: Image Generation
- 26.02 UniWeTok: An Unified Binary Tokenizer with Codebook Size 2^128 for Unified Multimodal Large Language Model | Paper📑 Code🖥️
- Unified discrete tokenizer with massive binary codebook (2^128) for high-fidelity image reconstruction and generation in multimodal LLMs, achieving FID 1.38 with lower training compute. | Task: Image Generation
- 26.02 UniReason 1.0: A Unified Reasoning Framework for World Knowledge Aligned Image Generation and Editing | Paper📑 Code🖥️ Model🤗
- Integrates text-to-image generation and editing through dual reasoning with world knowledge planning and visual refinement on reasoning-intensive benchmarks. | Task: Image Generation
- 26.02 Generated Reality: Human-centric World Simulation using Interactive Video Generation | Paper📑 Project🌐
- Human-centric video world model conditioned on tracked head and hand poses via bidirectional video diffusion for dexterous XR interactions. | Task: Image/Video Generation
- 26.01 Think-Then-Generate: Reasoning-Aware Text-to-Image Diffusion with LLM Encoders | Paper📑 Code🖥️
- "Think-then-generate" paradigm where LLM encoders reason about prompts before image generation using Dual-GRPO reinforcement optimization. | Task: Image Generation
- 26.01 Re-Align: Structured Reasoning-guided Alignment for In-Context Image Generation and Editing | Paper📑 Code🖥️
- Bridges multimodal understanding and image generation via In-Context Chain-of-Thought (IC-CoT) with RL-based training. | Task: Image Generation & Editing
- 26.01 Unified Thinker: A General Reasoning Modular Core for Image Generation | Paper📑
- General reasoning modular core enhancing image generation models with chain-of-thought reasoning capabilities. | Task: Image Generation
- 25.12 REASONEDIT: Towards Reasoning-Enhanced Image Editing Models | Paper📑
- Enhances image editing models with explicit reasoning capabilities. | Task: Image Editing
- 25.12 EditThinker: Unlocking Iterative Reasoning for Any Image Editor | Paper📑
- Enables iterative reasoning in image editing through a reasoning-aware framework. | Task: Image Editing
- 25.11 IE-Critic-R1: Advancing the Explanatory Measurement of Text-Driven Image Editing for Human Perception Alignment | Paper📑 Code🖥️ Model🤗 Dataset🤗 ColdStart SFT🤗
- IE-Critic-R1 treats image editing quality assessment as a reasoning task and implement "R1 moment" (longer reasoning thoughts, better performance). It is a pointwise, generative reward model, leveraging Chain-of-Thought (CoT) reasoning SFT and RLVR to provide accurate, human-aligned evaluations of image editing. | Task: Image Editing Quality Asssessment
- 25.05 T2I-R1: Reinforcing Image Generation with Collaborative Semantic-level and Token-level CoT | Paper📑 Code🖥️
- A novel reasoning-enhanced text-to-image generation model powered by RL with a bi-level CoT reasoning process | Task: Video Generation
- 25.03 GoT: Unleashing Reasoning Capability of Multimodal Large Language Model for Visual Generation and Editing | Paper📑
- A paradigm that enables generation and editing through an explicit language reasoning process before outputting images | Task: Image Generation
- 25.03 Unified Reward Model for Multimodal Understanding and Generation | Paper📑 Code🖥️ Dataset🤗
- Improve MLLM's understanding and generation ability with DPO | Task: VQA & Generation
- 25.01 (CVPR25) Can We Generate Images with CoT? Let's Verify and Reinforce Image Generation Step by Step | Paper📑 Code🖥️ Model🤗
- The first comprehensive investigation of the potential of CoT reasoning to enhance autoregressive image generation. | Task: Image Generation
- 24.12 EVLM: Self-Reflective Multimodal Reasoning for Cross-Dimensional Visual Editing | Paper📑
- A system designed to interpret such instructions in conjunction with reference visuals, producing precise and context-aware editing prompts. | Task: Image Generation
Video MLLM
- 26.02 SkyReels-V4: Multi-modal Video-Audio Generation, Inpainting and Editing model | Paper📑
- Unified multimodal video foundation model enabling simultaneous video+audio generation, editing, and inpainting via dual-stream architecture, supporting 1080p/32FPS/15s with synchronized audio. | Task: Video Generation
- 26.03 Helios: Real Real-Time Long Video Generation Model | Paper📑 Code🖥️ Model🤗
- 14B autoregressive diffusion model achieving real-time video generation at 19.5 FPS on a single H100 GPU while supporting minute-scale synthesis without conventional anti-drifting heuristics. | Task: Video Generation
- 26.03 DreamWorld: Unified World Modeling in Video Generation | Paper📑
- Unified world modeling framework in video generation with representation alignment for improved physical consistency and scene understanding. | Task: Video Generation
- 26.03 RealWonder: Real-Time Physical Action-Conditioned Video Generation | Paper📑 Project🌐
- First real-time system for action-conditioned video generation using physics simulation as intermediate bridge, achieving 13.2 FPS at 480×832 for interactive exploration of forces and robot actions. | Task: Video Generation
- 26.02 AnchorWeave: World-Consistent Video Generation with Retrieved Local Spatial Memories | Paper📑 Code🖥️
- Addresses long-term video generation consistency using multiple local geometric memories and multi-anchor weaving controller for camera-controllable long-horizon scene generation. | Task: Video Generation
- 26.02 OneVision-Encoder: Codec-Aligned Sparsity as a Foundational Principle for Multimodal Intelligence | Paper📑 Code🖥️ Model🤗
- Vision encoder applying codec-aligned sparsity to focus on 3.1%-25% of signal-rich patches, outperforming Qwen3-ViT and SigLIP2 across 16 benchmarks with 4.1% average improvement on video understanding. | Task: Video Understanding
- 26.02 CoPE-VideoLM: Codec Primitives For Efficient Video Language Models | Paper📑
- Uses video codec primitives (motion vectors and residuals) instead of dense per-frame embeddings, reducing time-to-first-token by up to 86% and token usage by up to 93% across 14 video benchmarks. | Task: Video Understanding
- 26.02 Solaris: Building a Multiplayer Video World Model in Minecraft | Paper📑 Code🖥️ Model🤗
- Multiplayer video world model for consistent multi-view observations in coordinated multi-agent Minecraft environments using Checkpointed Self Forcing technique. | Task: Video Generation
- 26.02 MOVA: Towards Scalable and Synchronized Video-Audio Generation | Paper📑 Code🖥️ Model🤗
- Open-source 32B MoE model generating high-quality synchronized audio-visual content including lip-synced speech, environment sounds, and music from image-text inputs. | Task: Video-Audio Generation
- 25.11 Kandinsky 5.0: A Family of Foundation Models for Image and Video Generation | Paper📑
- Foundation model family for image and video generation. | Task: Video Generation
- 25.11 Planning with Sketch-Guided Verification for Physics-Aware Video Generation | Paper📑
- Physics-aware video generation with sketch-based planning and verification. | Task: Video Generation
- 25.10 PhysMaster: Mastering Physical Representation for Video Generation via RL | Paper📑
- Physical reasoning for video generation with reinforcement learning. | Task: Video Generation
- 25.02 C-Drag:Chain-of-Thought Driven Motion Controller for Video Generation | Paper📑 Code🖥️ Dataset🤗
- A Chain-of-Thought-based motion controller for controllable video generation | Task: Video Generation
Audio MLLM
- 26.02 AVERE: Improving Audiovisual Emotion Reasoning with Preference Optimization | Paper📑 Dataset🤗
- AVEm-DPO preference optimization improves audiovisual emotion reasoning in MLLMs by aligning responses with audiovisual cues and reducing text-prior hallucinations. | Task: Audio-Visual Reasoning
- 26.02 EgoAVU: Egocentric Audio-Visual Understanding | Paper📑 Dataset🤗
- Scalable data engine and 3M-sample dataset for egocentric audio-visual understanding, enabling up to 113% performance improvement on joint audio-visual reasoning tasks. | Task: Audio-Visual Reasoning
- 26.01 LTX-2: Efficient Joint Audio-Visual Foundation Model | Paper📑 Code🖥️ Model🤗
- Open-source 14B+5B asymmetric dual-stream audiovisual diffusion model generating synchronized video and audio with bidirectional cross-attention. | Task: Audio-Visual Generation
- 25.11 UniAVGen: Unified Audio and Video Generation with Asymmetric Cross-Modal Interactions | Paper📑
- Unified audio-video generation using cross-modal interactions. | Task: Audio-Visual Generation
- 25.11 Harmony: Harmonizing Audio and Video Generation through Cross-Task Synergy | Paper📑
- Harmonizes audio and video generation via cross-task synergy. | Task: Audio-Visual Generation
- 25.06 ThinkSound: Chain-of-Thought Reasoning in Multimodal Large Language Models for Audio Generation and Editing
Reasoning with Agent/Tool
- 26.02 Mobile-Agent-v3.5: Multi-platform Fundamental GUI Agents | Paper📑 Code🖥️ Model🤗
- GUI-Owl-1.5 multi-platform GUI agent family achieving SOTA on GUI automation (56.5 OSWorld, 71.6 AndroidWorld) and grounding (80.3 ScreenSpotPro) via MRPO multi-platform RL. | Task: GUI Agent
- 26.02 GUI-Libra: Training Native GUI Agents to Reason and Act with Action-aware Supervision and Partially Verifiable RL | Paper📑 Code🖥️ Model🤗
- Trains open-source GUI agents using action-aware SFT (81K curated dataset) and conservative RL with KL regularization for web and mobile tasks. | Task: GUI Agent
- 26.02 PyVision-RL: Forging Open Agentic Vision Models via RL | Paper📑 Code🖥️ Model🤗
- RL framework for open-weight multimodal agents using oversampling-filtering-ranking rollout; releases PyVision-Image-7B and PyVision-Video-7B for tool-augmented reasoning. | Task: Agent/Tool Use
- 26.02 Computer-Using World Model | Paper📑
- World model for desktop software predicting UI state changes via two-stage factorization to help agents simulate candidate actions before execution. | Task: GUI Agent
- 26.02 V-Retrver: Evidence-Driven Agentic Reasoning for Universal Multimodal Retrieval | Paper📑 Code🖥️ Model🤗
- Reformulates multimodal retrieval as an agentic reasoning process where an MLLM selectively acquires visual evidence via external tools, achieving 23% average improvement. | Task: Agent/Tool Use
- 26.02 Reasoning-Augmented Representations for Multimodal Retrieval | Paper📑 Code🖥️
- Data-centric framework externalizing reasoning before retrieval by using VLMs to densely caption visual evidence and resolve ambiguous multimodal queries. | Task: Agent/Tool Use
- 26.02 WebArbiter: A Principle-Guided Reasoning Process Reward Model for Web Agents | Paper📑 Code🖥️
- Reasoning-first WebPRM formulating reward modeling as text generation to improve web navigation through structured justifications and preference verdicts (ICLR 2026). | Task: GUI Agent
- 26.02 Sparse Video Generation Propels Real-World Beyond-the-View Vision-Language Navigation | Paper📑 Code🖥️
- SparseVideoNav uses video generation for sparse future planning in beyond-the-view VLN tasks, achieving 27× speed-up and 2.5× higher success rate over LLM baselines. | Task: Visual Reasoning Agent
- 26.02 WebWorld: A Large-Scale World Model for Web Agent Training | Paper📑
- Open-web simulator trained on 1M+ interactions enabling long-horizon reasoning for web agents; models trained on WebWorld-synthesized trajectories show +9.2% improvement on WebArena. | Task: GUI Agent
- 26.02 AutoWebWorld: Synthesizing Infinite Verifiable Web Environments via Finite State Machines | Paper📑
- Synthesizes controllable web environments as FSMs translated to interactive websites by coding agents for automated trajectory generation at $0.04/trajectory, with 7B agent outperforming baselines on WebVoyager. | Task: GUI Agent
- 26.02 MMA: Multimodal Memory Agent | Paper📑 Code🖥️
- Improves long-horizon multimodal agent performance via dynamic memory reliability scoring and introduces the "Visual Placebo Effect" with MMA-Bench for evaluating belief dynamics. | Task: Multimodal Agent
- 26.03 CoVe: Training Interactive Tool-Use Agents via Constraint-Guided Verification | Paper📑
- Post-training data synthesis framework for interactive tool-use agents using constraint-guided verification; compact 4B model achieves success rates competitive with 17× larger models on τ²-bench. | Task: Tool Use Agent
- 26.03 AgentVista: Evaluating Multimodal Agents in Ultra-Challenging Realistic Visual Scenarios | Paper📑
- Benchmark evaluating multimodal agents in ultra-challenging realistic visual scenarios requiring complex visual reasoning and multi-step planning. | Task: Multimodal Agent
- 26.01 AdaReasoner: Dynamic Tool Orchestration for Iterative Visual Reasoning | Paper📑 Code🖥️ Model🤗
- Multimodal model family learning tool usage as a reasoning skill via Tool-GRPO, +24.9% improvement surpassing GPT-4 on visual reasoning benchmarks. | Task: Visual Reasoning with Tools
- 26.01 SenseNova-MARS: Empowering Multimodal Agentic Reasoning and Search via Reinforcement Learning | Paper📑
- Multimodal agentic reasoning and search framework using RL to empower visual reasoning with agent capabilities. | Task: Multimodal Agentic Reasoning
- 26.01 EvoCUA: Evolving Computer Use Agents via Learning from Scalable Synthetic Experience | Paper📑 Code🖥️ Model🤗
- SOTA computer-use agent (56.7% OSWorld) using autonomous task generation and iterative evolving learning with self-correction. | Task: GUI Agent
- 26.01 DocDancer: Towards Agentic Document-Grounded Information Seeking | Paper📑
- Agentic framework for document-grounded multimodal information seeking and reasoning. | Task: Document Reasoning Agent
- 26.01 ShowUI-pi: Flow-based Generative Models as GUI Dexterous Hands | Paper📑
- Flow-based generative models applied as GUI interaction agents with visual reasoning capabilities. | Task: GUI Agent
- 26.01 PersonalAlign: Hierarchical Implicit Intent Alignment for Personalized GUI Agent | Paper📑
- Personalized GUI agent aligning hierarchical implicit user intent with long-term user-centric records. | Task: GUI Agent
- 25.12 Step-GUI Technical Report | Paper📑
- Step-by-step GUI agent with visual understanding. | Task: GUI Agent
- 25.12 MAI-UI Technical Report: Real-World Centric Foundation GUI Agents | Paper📑
- Foundation model for real-world GUI agent interaction with visual grounding. | Task: GUI Agent
- 25.11 Agent-Omni: Test-Time Multimodal Reasoning via Model Coordination for Understanding Anything
- 25.11 DeepEyesV2: Toward Agentic Multimodal Model | Paper📑
- Agentic multimodal model with tool-use and reasoning capabilities. | Task: Multimodal Agent
- 25.11 GeoVista: Web-Augmented Agentic Visual Reasoning for Geolocalization | Paper📑
- Combines visual reasoning with web augmentation for agentic geolocalization. | Task: Visual Reasoning Agent
- 25.10 AudioToolAgent: An Agentic Framework for Audio-Language Models | Paper📑
- 25.10 GUI-KV: Efficient GUI Agents via KV Cache with Spatio-Temporal Awareness | Paper📑
- Efficient GUI interaction agents using visual understanding with spatio-temporal KV cache. | Task: GUI Agent
- 25.09 UItron: Foundational GUI Agent with Advanced Perception and Planning | Paper📑
- Multimodal agent for GUI understanding and interaction. | Task: GUI Agent
- 25.09 BTL-UI: Blink-Think-Link Reasoning Model for GUI Agent | Paper📑
- Reasoning model for GUI agent visual understanding and interaction. | Task: GUI Agent
- 25.08 Think Before You Segment: An Object-aware Reasoning Agent for Referring Audio-Visual Segmentation
- 25.08 OS Agents: A Survey on MLLM-based Agents for General Computing Devices Use | Paper📑
- Survey of MLLM-based agents that operate computing devices via visual understanding. | Task: GUI Agent
- 25.08 InfiGUI-G1: Advancing GUI Grounding with Adaptive Exploration Policy Optimization | Paper📑
- Multimodal agent for GUI understanding with visual grounding and adaptive exploration. | Task: GUI Agent
- 25.08 CODA: Coordinating the Cerebrum and Cerebellum for a Dual-Brain Computer Use Agent | Paper📑
- Dual-brain architecture for multimodal computer-use agent with decoupled RL. | Task: GUI Agent
- 25.06 Ego-R1: Chain-of-Tool-Thought for Ultra-Long Egocentric Video Reasoning|Paper📑 Code🖥️ Project🌐
- 25.05 ReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning | Paper📑 Code🖥️
- 25.05 Reinforcement Learning for Long-Horizon Interactive LLM Agents|Paper📑
- 25.05 RAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning |Paper📑 Code🖥️ Project🌐
- 25.05 Nemotron-Research-Tool-N1: Exploring Tool-Using Language Models with Reinforced Reasoning | Paper📑 Code🖥️
- 25.05 Agent RL Scaling Law: Spontaneous Code Execution for Mathematical Problem Solving| Paper📑 Code🖥️
- 25.04 ToolRL: Reward is All Tool Learning Needs|Paper📑 Code🖥️
- 25.04 Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning | Paper📑 Code🖥️
- 25.04 Acting Less is Reasoning More! Teaching Model to Act Efficiently
- 25.04 Agentic Reasoning and Tool Integration for LLMs via Reinforcement Learning | Paper📑
- 25.04 DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments |Paper📑 Code🖥️
- 25.03 TORL: Scaling Tool-Integrated RL | Paper📑 Code🖥️
- 25.03 R1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning | Paper📑
- 25.02 (CVPR25)Enhancing Video-LLM Reasoning via Agent-of-Thoughts Distillation | Paper📑
- 24.12 (ECCV24) VideoAgent: A Memory-augmented Multimodal Agent for Video Understanding | Paper📑 Code🖥️ Project🌐
- Explore how reconciling several foundation models with a novel unified memory mechanism could tackle the challenging video understanding problem | Task: Video captioning & QA
Medical Reasoning
Image MLLM
- 26.02 MediX-R1: Open Ended Medical Reinforcement Learning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Open-ended RL framework for medical MLLMs enabling free-form clinical answers via Group-Based RL with composite rewards; 8B model outperforms 27B MedGemma with ~51K training samples. | Task: Medical Reasoning
- 26.02 Baichuan-M3: Modeling Clinical Inquiry for Reliable Medical Decision-Making | Paper📑 Code🖥️ Model🤗
- Medical LLM shifting from passive Q&A to active clinical-grade decision support via proactive information acquisition, long-horizon reasoning, and hallucination suppression, achieving SOTA on HealthBench. | Task: Medical Reasoning
- 26.02 MedSAM-Agent: Empowering Interactive Medical Image Segmentation with Multi-turn Agentic Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- Reformulates medical image segmentation as multi-step decision-making using hybrid prompting and two-stage training with process rewards for autonomous reasoning. | Task: Medical Reasoning
- 26.02 Hepato-LLaVA: An Expert MLLM for Hepatocellular Pathology Analysis on Whole Slide Images | Paper📑 Project🌐
- Specialized MLLM for hepatocellular carcinoma diagnosis with Sparse Topo-Pack Attention modeling tissue topology; includes HepatoPathoVQA (33K expert-validated Q&A pairs). | Task: Medical Reasoning
- 26.02 MedCLIPSeg: Probabilistic Vision-Language Adaptation for Medical Image Segmentation | Paper📑 Code🖥️ Model🤗
- Adapts CLIP for medical image segmentation via Probabilistic Vision-Language Adapter with uncertainty-aware attention, tested across 16 datasets spanning 5 modalities and 6 organs. | Task: Medical Reasoning
- 26.02 MedXIAOHE: A Comprehensive Recipe for Building Medical MLLMs | Paper📑
- Medical VLM combining entity-aware continual pretraining for rare diseases, RL for expert-level reasoning, and tool-augmented agentic training for multi-step diagnostic reasoning with reduced hallucination. | Task: Medical Reasoning
- 26.02 ClinAlign: Scaling Healthcare Alignment from Clinician Preference | Paper📑 Code🖥️ Model🤗
- Two-stage LLM alignment using physician-verified examples and distilled clinical principles, with a 30B model activating 3B parameters at inference achieving SOTA on medical benchmarks. | Task: Medical Reasoning
- 26.02 Uncertainty-Aware Vision-Language Segmentation for Medical Imaging | Paper📑 Code🖥️
- Multimodal segmentation with Modality Decoding Attention Blocks (MoDAB) and Spectral-Entropic Uncertainty Loss for medical image segmentation from radiological images and clinical text. | Task: Medical Reasoning
- 26.03 When Does RL Help Medical VLMs? Disentangling Vision, SFT, and RL Gains | Paper📑 Project🌐
- Controlled study disentangling vision, SFT, and RL effects in medical VLMs, proposing a boundary-aware recipe: bridge support first, then sharpen with RL for optimal medical reasoning. | Task: Medical Reasoning
- 26.01 UniX: Unifying Autoregression and Diffusion for Chest X-Ray Understanding and Generation | Paper📑 Code🖥️ Model🤗
- Unified medical foundation model combining autoregressive understanding and diffusion generation for chest X-rays, +46.1% in understanding. | Task: Medical Image Understanding & Generation
- 25.12 OralGPT-Omni: A Versatile Dental Multimodal Large Language Model | Paper📑
- Versatile dental MLLM for oral health diagnosis and reasoning across modalities. | Task: Medical Reasoning
- 25.12 DentalGPT: Incentivizing Multimodal Complex Reasoning in Dentistry | Paper📑
- Incentivizes complex multimodal reasoning for dental diagnosis and treatment. | Task: Medical Reasoning
- 25.12 Colon-X: Advancing Intelligent Colonoscopy from Multimodal Understanding to Clinical Reasoning | Paper📑
- Advances colonoscopy with multimodal understanding and clinical reasoning capabilities. | Task: Medical Reasoning
- 25.10 M3Retrieve: Benchmarking Multimodal Retrieval for Medicine | Paper📑
- Multimodal retrieval benchmark for medical domain. | Task: Medical Reasoning
- 25.09 MedVista3D: Vision-Language Modeling for Reducing Diagnostic Errors in 3D CT Disease Detection | Paper📑
- VLM for medical 3D CT analysis to reduce diagnostic errors. | Task: Medical Reasoning
- 25.08 MedBLINK: Probing Basic Perception in Multimodal Language Models for Medicine | Paper📑
- Tests multimodal LLMs on basic medical visual perception tasks. | Task: Medical Reasoning
Audio MLLM
- 25.04 (ICASSP 2025) AuscMLLM: Bridging Classification and Reasoning in Heart Sound Analysis with a Multimodal Large Language Model |
- 24.09 (JBHI 2024) Multi-Task Learning for Audio-Based Infant Cry Detection and Reasoning |
Omni MLLM
- 25.06 (ACL 2025) MAM: Modular Multi-Agent Framework for Multi-Modal Medical Diagnosis via Role-Specialized Collaboration | Paper📑 Code🖥️
Embodied Reasoning
-
26.02 VLANeXt: Recipes for Building Strong VLA Models | Paper📑 Code🖥️ Model🤗
- Systematically identifies 12 key design findings across foundational components for VLA models, yielding SOTA simulation and real-world benchmark performance (CVPR 2026). | Task: Robot Control
-
26.02 SimVLA: A Simple VLA Baseline for Robotic Manipulation | Paper📑 Code🖥️ Model🤗
- Minimal VLA baseline strictly decoupling perception from control with standard VL backbone, achieving SOTA on simulation benchmarks with only 0.5B parameters. | Task: Robotic Manipulation
-
26.02 GigaBrain-0.5M*: a VLA That Learns From World Model-Based Reinforcement Learning | Paper📑 Code🖥️ Project🌐
- VLA trained via world model-based RL (RAMP) on 10,000+ hours of robot data, achieving ~30% improvement on challenging tasks like laundry folding and espresso preparation. | Task: Robotic Manipulation
-
26.02 Recurrent-Depth VLA: Implicit Test-Time Compute Scaling of Vision-Language-Action Models via Latent Iterative Reasoning | Paper📑 Code🖥️ Project🌐
- Recurrent VLA using latent iterative refinement instead of chain-of-thought tokens to adaptively scale compute at inference, achieving 0%→90%+ task success with 4 iterations. | Task: Robotic Manipulation
-
26.02 VLA-JEPA: Enhancing Vision-Language-Action Model with Latent World Model | Paper📑 Code🖥️ Model🤗
- JEPA-style pretraining for VLA policies predicting future latent states from current observations, improving robustness to camera motion and irrelevant backgrounds. | Task: Robotic Manipulation
-
26.02 DreamDojo: A Generalist Robot World Model from Large-Scale Human Videos | Paper📑 Model🤗 Project🌐
- Foundation world model trained on 44k hours of egocentric human video enabling teleoperation, policy evaluation, and model-based planning for dexterous robotics at 10.81 FPS. | Task: Robotic Manipulation
-
26.02 ABot-N0: Technical Report on the VLA Foundation Model for Versatile Embodied Navigation | Paper📑 Code🖥️ Project🌐
- Unified VLA navigation model with hierarchical Brain-Action architecture achieving SOTA on 7 benchmarks across 5 navigation task types, trained on 16.9M expert trajectories. | Task: Embodied Navigation
-
26.02 TIC-VLA: A Think-in-Control Vision-Language-Action Model for Robot Navigation in Dynamic Environments | Paper📑 Code🖥️ Project🌐
- Latency-aware VLA framework modeling delayed semantic reasoning during action generation via delayed semantic-control interface for real-time navigation. | Task: Embodied Navigation
-
26.02 QuantVLA: Scale-Calibrated Post-Training Quantization for Vision-Language-Action Models | Paper📑 Code🖥️
- Training-free PTQ framework for VLA models combining selective quantization, attention temperature matching, and output head balancing, achieving ~70% memory savings (CVPR 2026). | Task: Robot Control
-
26.02 FRAPPE: Infusing World Modeling into Generalist Policies via Multiple Future Representation Alignment | Paper📑 Code🖥️ Model🤗
- Improves world-awareness in robotic policies via parallel progressive latent alignment with visual foundation models, reducing error accumulation in multi-step prediction. | Task: Robotic Manipulation
-
26.02 TactAlign: Human-to-Robot Policy Transfer via Tactile Alignment | Paper📑 Project🌐
- Cross-embodiment tactile alignment using rectified flow for zero-shot transfer on contact-rich manipulation tasks including pivoting, insertion, and lid closing. | Task: Robotic Manipulation
-
26.02 World Guidance: World Modeling in Condition Space for Action Generation | Paper📑 Project🌐
- WoG maps predicted future observations into compact condition representations for fine-grained action generation, validated across simulation and real-world robot environments. | Task: Robot Control
-
26.02 Green-VLA: Staged Vision-Language-Action Model for Generalist Robots | Paper📑 Code🖥️
- Five-stage VLA framework for real-world robot deployment achieving generalization across embodiments via multimodal training and RL, reaching 69.5% success on ALOHA Table-Cleaning. | Task: Robotic Manipulation
-
26.02 Learning from Trials and Errors: Reflective Test-Time Planning for Embodied LLMs | Paper📑 Code🖥️
- Reflective Test-Time Planning with reflection-in-action and reflection-on-action enabling long-horizon credit assignment in robot decision-making. | Task: Embodied Reasoning
-
26.02 RISE: Self-Improving Robot Policy with Compositional World Model | Paper📑
- Addresses VLA brittleness in contact-rich manipulation using a compositional world model to predict multi-view futures and evaluate imagined outcomes, achieving +35-45% gains across real-world tasks. | Task: Robotic Manipulation
-
26.02 chi_0: Resource-Aware Robust Manipulation via Taming Distributional Inconsistencies | Paper📑 Code🖥️ Model🤗
- Resource-efficient robotic manipulation using model arithmetic weight-space merging and stage-aware advantage estimation for dual-arm garment tasks, achieving 250% higher success than pi_0.5. | Task: Robotic Manipulation
-
26.02 EgoHumanoid: Unlocking In-the-Wild Loco-Manipulation with Robot-Free Egocentric Demonstration | Paper📑
- Enables humanoid loco-manipulation via co-training VLA policies using abundant egocentric human demonstrations with limited robot data, achieving 51% improvement over robot-only baselines. | Task: Robotic Manipulation
-
26.02 MolmoSpaces: A Large-Scale Open Ecosystem for Robot Navigation and Manipulation | Paper📑 Code🖥️
- Open ecosystem with 230k+ diverse indoor environments and 130k annotated assets supporting MuJoCo/Isaac/ManiSkill, with 8 benchmark tasks and strong sim-to-real correlation (R=0.96). | Task: Robot Simulation
-
26.02 ABot-M0: VLA Foundation Model for Robotic Manipulation with Action Manifold Learning | Paper📑 Code🖥️ Model🤗
- Unified robotic manipulation framework standardizing 6M+ trajectories and introducing Action Manifold Learning (AML) for improved action prediction on low-dimensional manifolds. | Task: Robotic Manipulation
-
26.02 RLinf-Co: Reinforcement Learning-Based Sim-Real Co-Training for VLA Models | Paper📑
- RL-based sim-real co-training for VLA policies using two-stage warm-start SFT + RL fine-tuning with auxiliary supervised loss, achieving +24% on OpenVLA and +20% on pi_0.5 in real-world success. | Task: Robotic Manipulation
-
26.02 Xiaomi-Robotics-0: An Open-Sourced Vision-Language-Action Model with Real-Time Execution | Paper📑 Code🖥️
- Open-source VLA combining large-scale cross-embodiment pretraining with asynchronous execution for real-time deployment, achieving SOTA on simulation benchmarks with consumer-grade GPU compatibility. | Task: Robotic Manipulation
-
26.02 GeneralVLA: Generalizable Vision-Language-Action Models with Knowledge-Guided Trajectory Planning | Paper📑 Code🖥️
- Hierarchical VLA for zero-shot robotic manipulation via affordance segmentation, 3D trajectory planning, and 3D-aware control policy, outperforming VoxPoser without real-world demonstrations. | Task: Robotic Manipulation
-
26.02 RynnBrain: Open Embodied Foundation Models | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Open-source spatiotemporal foundation model unifying perception, reasoning, and planning for embodied intelligence, outperforming existing models on 20 embodied benchmarks. | Task: Embodied Reasoning
-
26.02 Learning Humanoid End-Effector Control for Open-Vocabulary Visual Loco-Manipulation | Paper📑
- HERO enables humanoid robots to manipulate diverse real-world objects using inverse kinematics and neural forward model, reducing end-effector tracking error 3.2x for reliable surface manipulation. | Task: Robotic Manipulation
-
26.02 World Action Models are Zero-shot Policies | Paper📑 Code🖥️
- DreamZero uses video diffusion as a World Action Model (WAM) for robot skill generalization with 2x improvement in novel environments at real-time 7Hz closed-loop control. | Task: Robotic Manipulation
-
26.02 Learning Native Continuation for Action Chunking Flow Policies | Paper📑
- Legato, a training-time continuation method for action-chunked VLA policies producing smoother trajectories, achieving ~10% improvements in smoothness and task completion across 5 manipulation tasks. | Task: Robotic Manipulation
-
26.02 BiManiBench: A Hierarchical Benchmark for Evaluating Bimanual Coordination of Multimodal Large Language Models | Paper📑 Code🖥️
- Evaluates 30+ MLLMs on bimanual robotic tasks across spatial reasoning, action planning, and end-effector control tiers, finding persistent failures in dual-arm spatial grounding. | Task: Robotic Manipulation
-
26.03 RoboPocket: Improve Robot Policies Instantly with Your Phone | Paper📑 Project🌐
- Portable system enabling robot-free instant policy iteration via smartphone AR visualization of predicted trajectories, doubling data efficiency with asynchronous online finetuning. | Task: Robotic Manipulation
-
26.03 UltraDexGrasp: Learning Universal Dexterous Grasping for Bimanual Robots with Synthetic Data | Paper📑 Project🌐
- Framework for universal dexterous grasping with UltraDexGrasp-20M dataset (20M frames across 1,000 objects), achieving robust zero-shot sim-to-real transfer for multi-strategy bimanual grasping. | Task: Robotic Manipulation
-
26.03 EmbodiedSplat: Online Feed-Forward Semantic 3DGS for Open-Vocabulary 3D Scene Understanding | Paper📑 Project🌐
- Online feed-forward 3D Gaussian Splatting framework enabling real-time semantic scene understanding from streaming images at 5-6 FPS without per-scene optimization. | Task: Embodied Scene Understanding
-
26.03 Lightweight Visual Reasoning for Socially-Aware Robots | Paper📑
- Lightweight language-to-vision feedback module improving VLM reasoning for robotic tasks (navigation, scene description, human-intention recognition) with less than 3% extra parameters. | Task: Embodied Reasoning
-
26.01 ACoT-VLA: Action Chain-of-Thought for Vision-Language-Action Models | Paper📑
- Action Chain-of-Thought paradigm for VLA models with Explicit and Implicit Action Reasoner components, achieving 98.5% on LIBERO. | Task: Robotic Manipulation
-
26.01 Cosmos Policy: Fine-Tuning Video Models for Visuomotor Control and Planning | Paper📑 Model🤗
- Adapts pretrained video models into robot policies through single-stage post-training, achieving 98.5% on LIBERO and SOTA on real-world bimanual manipulation. | Task: Robot Control
-
26.01 DynamicVLA: A Vision-Language-Action Model for Dynamic Object Manipulation | Paper📑 Code🖥️ Dataset🤗
- Compact 0.4B VLA model for dynamic object manipulation with continuous inference and latent-aware action streaming. | Task: Robotic Manipulation
-
26.01 SOP: A Scalable Online Post-Training System for Vision-Language-Action Models | Paper📑 Project🌐
- Scalable online distributed post-training system for VLA models enabling real-world robot policy adaptation through fleet learning. | Task: Robot Control
-
26.01 FantasyVLN: Unified Multimodal Chain-of-Thought Reasoning for Vision-Language Navigation | Paper📑 Code🖥️ Model🤗
- Implicit reasoning framework for vision-language navigation encoding imagined visual tokens in latent space, reducing inference latency by an order of magnitude. | Task: Vision-Language Navigation
-
26.01 RoboVIP: Multi-View Video Generation with Visual Identity Prompting Augments Robot Manipulation | Paper📑 Code🖥️
- Visual identity prompting for multi-view video generation to augment robot manipulation data. | Task: Robotic Manipulation
-
26.01 VLingNav: Embodied Navigation with Adaptive Reasoning and Visual-Assisted Linguistic Memory | Paper📑
- Embodied navigation agent with adaptive reasoning combining visual perception and linguistic memory. | Task: Embodied Navigation
-
25.12 DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action | Paper📑
- Decouples reasoning and action for more generalizable embodied agents. | Task: Robotic Manipulation
-
25.12 HiF-VLA: Hindsight, Insight and Foresight through Motion Representation for VLA Models | Paper📑
- Enriches VLA models with hindsight, insight, and foresight via motion representations. | Task: Robotic Manipulation
-
25.12 LEO-RobotAgent: A General-purpose Robotic Agent for Language-driven Embodied Operator | Paper📑
- General-purpose language-driven robotic agent for embodied task execution. | Task: Robotic Manipulation
-
25.12 Steering VLA Models as Anti-Exploration: A Test-Time Scaling Approach | Paper📑
- Test-time scaling approach for steering VLA models for safe embodied behavior. | Task: Robot Control
-
25.11 WMPO: World Model-based Policy Optimization for Vision-Language-Action Models | Paper📑
- World model-based policy optimization for VLA models in robotics. | Task: Robot Control
-
25.11 RynnVLA-002: A Unified Vision-Language-Action and World Model | Paper📑
- Unified VLA and world model for robotic manipulation. | Task: Robot Control
-
25.11 Mantis: A Versatile Vision-Language-Action Model with Disentangled Visual Foresight | Paper📑
- VLA model with disentangled visual foresight for robotic control. | Task: Robot Control
-
25.11 MobileVLA-R1: Reinforcing Vision-Language-Action for Mobile Robots | Paper📑
- Reinforcement-based VLA model for mobile robot tasks. | Task: Robot Control
-
25.10 VLA-RFT: Vision-Language-Action Reinforcement Fine-tuning with Verified Rewards | Paper📑
- Fine-tuning VLA models using RL with verified rewards in world simulators. | Task: Robot Control
-
25.10 InternVLA-M1: A Spatially Guided Vision-Language-Action Framework for Generalist Robot Policy | Paper📑
- VLA framework for robotic control with spatial grounding. | Task: Robot Control
-
25.10 X-VLA: Soft-Prompted Transformer as Scalable Cross-Embodiment Vision-Language-Action Model | Paper📑
- Cross-embodiment VLA model for scalable robot learning. | Task: Robot Control
-
25.10 GigaBrain-0: A World Model-Powered Vision-Language-Action Model | Paper📑
- VLA model integrating world models for robot reasoning. | Task: Robot Control
-
25.09 Robix: A Unified Model for Robot Interaction, Reasoning and Planning | Paper📑
- Unified robotics model combining visual reasoning with interaction and planning. | Task: Robot Control
-
25.09 FLOWER: Democratizing Generalist Robot Policies with Efficient VLA Flow Policies | Paper📑
- Vision-language-action model for generalist robot policies. | Task: Robot Control
-
25.08 RynnEC: Bringing MLLMs into Embodied World | Paper📑
- Integrates multimodal LLMs into embodied AI settings for physical-world reasoning. | Task: Embodied Reasoning
-
25.08 Do What? Teaching Vision-Language-Action Models to Reject the Impossible | Paper📑
- Trains VLA models to reason about task feasibility and reject impossible instructions. | Task: Robot Control
-
25.08 Discrete Diffusion VLA: Bringing Discrete Diffusion to Action Decoding in VLA Policies | Paper📑
- Uses discrete diffusion for action decoding in vision-language-action robotic policies. | Task: Robot Control
-
23.07 RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control | Paper📑 Project🌐
- Co-finetunes a VLM on web and robot data, establishing the VLA paradigm by transferring internet-scale knowledge to robot control. | Task: General Robotic Manipulation
-
24.05 Octo: An Open-Source Generalist Robot Policy | Paper📑 Code🖥️ Project🌐 Model🤗
- An open-source, generalist transformer policy pretrained on the large-scale Open X-Embodiment dataset, designed for efficient fine-tuning to new robots and tasks. | Task: Robotics
-
24.06 OpenVLA: An Open-Source Vision-Language-Action Model | Paper📑 Code🖥️ Project🌐 Model🤗
- A 7B-parameter open-source VLA model trained on the Open X-Embodiment dataset, achieving state-of-the-art performance for generalist manipulation. | Task: VLA
-
24.10 π₀: A Vision-Language-Action Flow Model for General Robot Control | Paper📑 Code🖥️
- A generalist policy using a novel flow matching architecture atop a pretrained VLM, enabling zero-shot generalization for dexterous manipulation. | Task: Robot Control
-
25.01 FAST: Efficient Action Tokenization for Vision-Language-Action Models | Paper📑 Code🖥️
- A compression-based action tokenization scheme that accelerates autoregressive VLA training by 5x with performance comparable to diffusion models. | Task: Robot Control
-
25.02 Hi Robot: Open-Ended Instruction Following with Hierarchical Vision-Language-Action Models | Paper📑
- A hierarchical VLA model with a high-level VLM for reasoning and a low-level VLA for execution, enabling complex, open-ended instruction following. | Task: Robot Control
-
25.03 Gemini Robotics: Bringing AI into the Physical World | Paper📑 Code🖥️ Project🌐 Dataset🤗
- A VLA model built on the Gemini foundation model, demonstrating significant improvements in generality, interactivity, and dexterity for complex tasks. | Task: Advanced & Dexterous Manipulation
-
25.03 COT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models | Paper📑 Project🌐
- A method that incorporates explicit visual CoT reasoning into VLAs by predicting future image frames autoregressively as visual goals before generating a short action sequence to achieve these goals. | Task: Robotics
-
25.03 GR00T: A Foundation Model for General-Purpose Robotics | Paper📑 Code🖥️ Model🤗 Dataset🤗
- A general-purpose foundation model for robot learning that takes multimodal instructions and past observations to generate actions for the robot to execute. | Task: Robotics
-
25.04 π0.5: a Vision-Language-Action Model with Open-World Generalization | Paper📑
- An evolution of π₀ that uses co-training on diverse tasks to achieve long-horizon, dexterous manipulation in novel, unseen environments. | Task: Robot Control
-
25.06 Chain-of-Action: Faithful and Deterministic Robot Policy via Language-guided State-Action Augmentation | Paper📑 Code🖥️ Project🌐 Model🤗
- A novel robot policy, Chain-of-Action (CoA), that uses language as an intermediate representation to explicitly reason about the chain of actions for a given task, while being fully deterministic during inference. | Task: Robotics
-
25.07 Vision-Language-Action Instruction Tuning: From Understanding to Manipulation | Paper📑 Code🖥️ Project🌐 Model🤗
- An end-to-end VLA model, InstructVLA, that introduces a novel training paradigm called Vision-Language-Action Instruction Tuning (VLA-IT) to preserve the flexible reasoning of VLMs while delivering high-performance robotic manipulation. | Task: Robotic
-
25.07 MinD: Learning A Dual-System World Model for Real-Time Planning and Implicit Risk Analysis | Paper📑 Code🖥️ Project🌐
- A dual-system world model, MinD, that enables real-time, risk-aware planning by conditioning a high-frequency action policy on single-step latent predictions from a low-frequency video generation model. | Task: Robotic
Others
Image MLLM
- 26.03 UniG2U-Bench: Towards Comprehensive Benchmarking of Unified Generation and Understanding MLLMs | Paper📑
- Comprehensive benchmark evaluating MLLMs on both generation and understanding capabilities in a unified framework. | Task: Multimodal Evaluation
- 26.03 Towards Multimodal Lifelong Understanding | Paper📑
- MM-Lifelong dataset and ReMA agent for multimodal lifelong understanding, enabling continual learning across modalities. | Task: Lifelong Learning
- 26.02 VISTA-Bench: Do Vision-Language Models Really Understand Visualized Text as Well as Pure Text? | Paper📑
- Benchmark testing whether VLMs truly understand text rendered visually in images as well as plain text, revealing a significant comprehension gap. | Task: Reasoning
- 26.02 From Perception to Action: An Interactive Benchmark for Vision Reasoning | Paper📑 Code🖥️
- CHAIN 3D physics-driven interactive benchmark evaluating whether VLMs understand causal constraints and execute structured action sequences in mechanical puzzles. | Task: Reasoning
- 26.02 SAM 3D Body: Robust Full-Body Human Mesh Recovery | Paper📑 Code🖥️
- Promptable model for single-image 3D human mesh recovery using the Momentum Human Rig (MHR) parametric representation, supporting 2D keypoint/mask prompts with strong generalization. | Task: 3D Human Pose Estimation
- 26.01 CoF-T2I: Video Models as Pure Visual Reasoners for Text-to-Image Generation | Paper📑
- Uses video generation models as visual reasoners for text-to-image generation, showing temporal modeling transfers to improved spatial reasoning. | Task: Image Generation
- 26.01 OCRVerse: Towards Holistic OCR in End-to-End Vision-Language Models | Paper📑
- Holistic OCR framework within end-to-end vision-language models for comprehensive text understanding in images. | Task: OCR & Document Understanding
- 25.12 GroundingME: Exposing the Visual Grounding Gap in MLLMs through Multi-Dimensional Evaluation | Paper📑
- Exposes and evaluates visual grounding gaps in MLLMs across multiple dimensions. | Task: Visual Grounding
- 25.11 Monet: Reasoning in Latent Visual Space Beyond Images and Language | Paper📑
- Enables vision-language reasoning in latent visual space, going beyond standard image-text paradigms. | Task: Reasoning
- 25.10 SeeingEye: Agentic Information Flow Unlocks Multimodal Reasoning In Text-only LLMs | Paper📑
- Enables multimodal reasoning in text-only LLMs through agentic information flow. | Task: Reasoning
- 25.04 InfiGUI-R1: Advancing Multimodal GUI Agents from Reactive Actors to Deliberative Reasoners | Paper📑 Code🖥️
- an MLLM-based GUI agent designed to progressively evolve agents from Reactive Actors to Deliberative Reasoners. | task: UI
- 25.04 GUI-R1 : A Generalist R1-Style Vision-Language Action Model For GUI Agents | Paper📑
- Enhances GUI agent through RL with unified action space modeling, achieving superior cross-platform performance using only 0.02% of the data required by previous methods. | Task: UI
- 25.03 UI-R1: Enhancing Action Prediction of GUI Agents by Reinforcement Learning | Paper📑
- Introduce a unified rule-based action reward, enabling model optimization via policy-based algorithms like GRPO. | Task: UI
- 25.03 VLM-R1: A stable and generalizable R1-style Large Vision-Language Model Code🖥️ Dataset🤗 Model🤗
- A reproduced R1-style VLM | Task: Referring Expression Comprehension
- 25.02 MedVLM-R1: Incentivizing Medical Reasoning Capability of Vision-Language Models (VLMs) via Reinforcement Learning| Paper📑
- A MLLM trained with GRPO for medical image VQA.| Task: Medical Image VQA
Video MLLM
- 25.03 R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- Impove reasoning capability, emotion recognition accuracy, and generalization ability with RLVR. | Task: Emotion recognition
Audio MLLM
- 26.01 The Sonar Moment: Benchmarking Audio-Language Models in Audio Geo-Localization | Paper📑
- Benchmark for audio-language models on spatial audio geo-localization reasoning tasks. | Task: Audio Reasoning
- 25.02 ADIFF: Explaining audio difference using natural language Code🖥️ Model
- 24.09 What Are They Doing? Joint Audio-Speech Co-Reasoning
- 24.09 Chain-of-Thought Prompting for Speech Translation
Omni LLM
- 26.01 FutureOmni: Evaluating Future Forecasting from Omni-Modal Context for Multimodal LLMs | Paper📑
- Benchmark evaluating multimodal LLMs' ability to forecast future events from omni-modal context including temporal reasoning. | Task: Omni Reasoning
- 25.05 AVCD: Mitigating Hallucinations in Audio-Visual Large Language Models through Contrastive Decoding
- 25.03 R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning
- 23.11 X-InstructBLIP: A Framework for Aligning Image, 3D, Audio, Video to LLMs and its Emergent Cross-Modal Reasoning
Benchmarks 📊
| Date | Project | Task | Links |
|---|---|---|---|
| 26.03 | MMR-Life: Piecing Together Real-life Scenes for Multimodal Multi-image Reasoning | Multi-image Reasoning | [📑 Paper] [🌐 Project] |
| 26.03 | RIVER: A Benchmark for Real-World Video Reasoning in Long and Short Contexts | Video Temporal Reasoning | [📑 Paper] |
| 26.03 | UniG2U-Bench: Comprehensive Benchmark for Unified Generation and Understanding MLLMs | Multimodal Evaluation | [📑 Paper] |
| 26.03 | AgentVista: Generalizable Multi-Task Agent with Diverse Visual Manipulation | Multi-Task Agent | [📑 Paper] |
| 26.02 | A Very Big Video Reasoning Suite (VBVR): 1M+ video clips across 200 reasoning tasks | Video Reasoning | [📑 Paper] [🤗 Model] [🤗 Data] |
| 26.02 | OmniGAIA: Omni-Modal AI Agent Benchmark with hindsight-guided exploration | Omni-Modal Agent Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | SpatiaLab: Wild Spatial Reasoning benchmark across 6 VQA categories | Spatial Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | MuRGAt: Multimodal Fact-Level Attribution benchmark for verifiable reasoning | Multimodal Attribution | [📑 Paper] [💻 Code] |
| 26.02 | DeepVision-103K: Verifiable multimodal math dataset for RLVR training | Math Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | UniVBench: Unified evaluation for video foundation models across understanding, generation, editing | Video Foundation Model Evaluation | [📑 Paper] [💻 Code] |
| 26.02 | RISE-Video: Benchmark for video generators decoding implicit world rules | Video Generation Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | SAW-Bench: Egocentric Situated Awareness evaluation with 786 smart-glass videos and 2,071+ QA pairs | Spatial Reasoning | [📑 Paper] |
| 26.02 | BrowseComp-V3: 300-question visual benchmark for complex multi-hop multimodal web search | Multimodal Browsing | [📑 Paper] |
| 26.02 | BiManiBench: Hierarchical benchmark for bimanual coordination evaluation in MLLMs | Bimanual Robotics | [📑 Paper] [💻 Code] |
| 26.01 | MMFineReason: Closing the Multimodal Reasoning Gap via Open Data-Centric Methods | Multimodal Reasoning | [📑 Paper] [🤗 Model] [🤗 Data] |
| 26.01 | ChartVerse: Scaling Chart Reasoning via Reliable Programmatic Synthesis | Chart Reasoning | [📑 Paper] [💻 Code] [🤗 Model] [🤗 Data] |
| 26.01 | VideoLoom: Joint Spatial-Temporal Understanding with LoomBench | Spatial-Temporal Reasoning | [📑 Paper] [💻 Code] [🤗 Model] |
| 26.01 | PROGRESSLM: Towards Progress Reasoning in Vision-Language Models | Task Progress Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.01 | FutureOmni: Evaluating Future Forecasting from Omni-Modal Context | Omni-Modal Temporal Reasoning | [📑 Paper] |
| 26.01 | Afri-MCQA: Multimodal Cultural Question Answering for African Languages | Multilingual Multimodal Reasoning | [📑 Paper] |
| 26.01 | AVMeme Exam: A Multimodal Multilingual Multicultural Benchmark | Cultural Multimodal Reasoning | [📑 Paper] |
| 25.12 | HERBench: Multi-Evidence Integration in Video Question Answering | Video Reasoning | [📑 Paper] |
| 25.12 | SVBench: Evaluation of Video Generation Models on Social Reasoning | Video Social Reasoning | [📑 Paper] |
| 25.12 | IF-Bench: Benchmarking MLLMs for Infrared Images | Infrared Image Understanding | [📑 Paper] |
| 25.12 | VABench: Comprehensive Benchmark for Audio-Video Generation | Audio-Video Generation | [📑 Paper] |
| 25.11 | MME-CC: Challenging Multi-Modal Evaluation Benchmark of Cognitive Capacity | Cognitive Capacity | [📑 Paper] |
| 25.11 | GGBench: Geometric Generative Reasoning Benchmark for Unified Multimodal Models | Geometric Reasoning | [📑 Paper] |
| 25.11 | WEAVE: Benchmarking In-context Interleaved Comprehension and Generation | Multimodal Comprehension & Generation | [📑 Paper] |
| 25.10 | Uni-MMMU: Massive Multi-discipline Multimodal Unified Benchmark | Multimodal Multi-discipline Reasoning | [📑 Paper] |
| 25.10 | PhysToolBench: Benchmarking Physical Tool Understanding for MLLMs | Physical Tool Understanding | [📑 Paper] |
| 25.10 | BEAR: Benchmarking Multimodal Language Models for Atomic Embodied Capabilities | Embodied AI Capabilities | [📑 Paper] |
| 25.10 | OmniVideoBench: Towards Audio-Visual Understanding Evaluation for Omni MLLMs | Long-context, Video-Audio Unerstanding & Reasonin | [📑 Paper] [💻 Code] [🌐 Project] [🤗 Data] |
| 25.10 | XModBench: Benchmarking Cross-Modal Capabilities and Consistency in Omni-Language Models | Capability Balancing among Different Modalities | [📑 Paper] [💻 Code] [🌐 Project] |
| 25.10 | StreamingCoT: A Dataset for Temporal Dynamics and Multimodal Chain-of-Thought Reasoning in Streaming VideoQA | Termporal Reasoning | [📑 Paper] |
| 25.10 | Valor32k-AVQA v2.0: Open-Ended Audio-Visual Question Answering Dataset and Benchmark | Common Sense Omni Reasoning | [📑 Paper] |
| 25.09 | MARS2 2025 Challenge on Multimodal Reasoning | Multimodal Reasoning Challenge | [📑 Paper] |
| 25.09 | Visual-TableQA: Open-Domain Benchmark for Reasoning over Table Images | Table Reasoning | [📑 Paper] |
| 25.09 | AHELM: A Holistic Evaluation of Audio-Language Models | Audio-Language Understanding | [📑 Paper] |
| 25.09 | MDAR: A Multi-scene Dynamic Audio Reasoning Benchmark | Complex, Multi-scene, & Dynamically Evolving Speech & Audio Reasonin | [📑 Paper] [💻 Code] |
| 25.09 | MiMo-Audio-Eval Toolkit | Speech/Sound/Music Reasoning | [💻 Code] |
| 25.08 | SpeechR: A Benchmark for Speech Reasoning in Large Audio-Language Models | Speech Reasoning | [📑 Paper] [💻 Code] [Data] |
| 25.08 | MMAU-Pro: A Challenging and Comprehensive Benchmark for Holistic Evaluation of Audio General Intelligence | Long-form, Spatial, and Multi-audio Reasoning on Speech/Music/Sound | [📑 Paper] [🤗 Data] |
| 25.08 | R²-AVSBench: Think Before You Segment: An Object-aware Reasoning Agent for Referring Audio-Visual Segmentation | Segmentation Reasoning | [📑 Paper] [🤗 Data] |
| 25.07 | Towards Video Thinking Test: A Holistic Benchmark for Advanced Video Reasoning and Understanding | Video Reasoning and Understanding | [📑 Paper]. [🌐 Project] [🤗 Data] |
| 25.06 | FinMME: Benchmark Dataset for Financial Multi-Modal Reasoning Evaluation | Financial Multi-Modal Reasoning Reasoning | [📑 Paper]. [💻 Code]. [🤗 Data] |
| 25.06 | MMR-V: What's Left Unsaid? A Benchmark for Multimodal Deep Reasoning in Videos | Video Reasoning | [📑 Paper]. [💻 Code]. [🌐 Project] [🤗 Data] |
| 25.06 | OmniSpatial: Towards Comprehensive Spatial Reasoning Benchmark for Vision Language Models | Spatial Reasoning | [📑 Paper]. [💻 Code]. [🌐 Project] [🤗 Data] |
| 25.06 | MMSU: A Massive Multi-task Spoken Language Understanding and Reasoning Benchmark | Phonatics, Prosody, Rhetoric, Syntactics, Semantics, and Paralinguistics in Speech Understanding & Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 25.05 | Daily-Omni: Towards Audio-Visual Reasoning with Temporal Alignment across Modalities | Video&Audio Reasoning | [📑 Paper] [💻 Code] [🌐 Project] [🤗 Data] |
| 25.05 | MMAR: A Challenging Benchmark for Deep Reasoning in Speech, Audio, Music, and Their Mix | Multi-step Audio Reasoning | [📑 Paper]. [💻 Code]. [🎥 demo] [🤗 Data] |
| 25.05 | On Path to Multimodal Generalist: General-Level and General-Bench | Multimodal Generation | [🌐 Project] [📑 Paper] [🤗 Data] |
| 25.04 | VisuLogic: A Benchmark for Evaluating Visual Reasoning in Multi-modal Large Language Models | Visual Reasoning | [🌐 Project] [📑 Paper] [💻 Code] [🤗 Data] |
| 25.04 | IV-Bench: A Benchmark for Image-Grounded Video Perception and Reasoning in Multimodal LLMs | Image-Grounded Video Perception and Reasoning | [📑 Paper] [💻 Code] |
| 25.04 | Envisioning Beyond the Pixels: Benchmarking Reasoning-Informed Visual Editing | Reasoning-Informed viSual Editing | [📑 Paper] [💻 Code] |
| 25.04 | CMI-Bench: A Comprehensive Benchmark for Evaluating Music Instruction Following | Music Information Retrieval & Knowledge | [📑 Paper] [💻 Code] |
| 25.03 | MAVERIX: Multimodal Audio-Visual Evaluation Reasoning IndeX | Common Sense Omni Reasoning | [📑 Paper] [🌐 Project] |
| 25.03 | V-STaR : Benchmarking Video-LLMs on Video Spatio-Temporal Reasoning | Spatio-temporal Reasoning | [🌐 Project] [📑 Paper] [🤗 Data] |
| 25.03 | MM-Spatial: Exploring 3D Spatial Understanding in Multimodal LLMs | Spatio-temporal Understanding | [📑Paper] |
| 25.03 | Integrating Chain-of-Thought for Multimodal Alignment: A Study on 3D Vision-Language Learning | 3D-CoT | [📑 Paper] [🤗 Data] |
| 25.02 | MM-IQ: Benchmarking Human-Like Abstraction and Reasoning in Multimodal Models | MM-IQ | [📑 Paper] [💻 Code] |
| 25.02 | MM-RLHF: The Next Step Forward in Multimodal LLM Alignment | MM-RLHF-RewardBench, MM-RLHF-SafetyBench | [📑 Paper] |
| 25.02 | ZeroBench: An Impossible* Visual Benchmark for Contemporary Large Multimodal Models | ZeroBench | [🌐 Project] [🤗 Dataset] [💻 Code] |
| 25.02 | MME-CoT: Benchmarking Chain-of-Thought in LMMs for Reasoning Quality, Robustness, and Efficiency | MME-CoT | [📑 Paper] [💻 Code] |
| 25.02 | OmniAlign-V: Towards Enhanced Alignment of MLLMs with Human Preference | MM-AlignBench | [📑 Paper] [💻 Code] |
| 25.01 | AVTrustBench: Assessing and Enhancing Reliability and Robustness in Audio-Visual LLMs | Adversarial attack, Compositional reasoning, and Modality-specific dependency in Visual&Audio | [📑 Paper] |
| 25.01 | LlamaV-o1: Rethinking Step-By-Step Visual Reasoning in LLM |
Truncated — view the full README on GitHub.
Contributors


Similar repos


A collection of multimodal reasoning papers, codes, datasets, benchmarks and resources.
43
115 commits
updated Jul 31, 2026
README
Awesome-MLLM-Reasoning-Collection
⚠️ Repository notice
On 31 May 2026, this repository was targeted by an apparent coordinated fake-star attack that also affected many other open-source repositories. Its star count rose abnormally from approximately 673 to more than 14,000 within a single day, despite no promotion or involvement from the maintainers. We reported the incident to GitHub but have not received a substantive response. We remain sincerely grateful to the 670+ genuine supporters whose earlier stars may no longer be displayed—your support and trust have always been deeply appreciated. 💙
👏 Welcome to the Awesome-MLLM-Reasoning-Collections repository! This repository is a carefully curated collection of papers, code, datasets, benchmarks, and resources focused on reasoning within Multimodal Large Language Models (MLLMs).
Feel free to ⭐ star and fork this repository to keep up with the latest advancements and contribute to the community.
A conceptual trajectory of multimodal reasoning, evolving from static image-level understanding, through temporal video and audio reasoning, to holistic omni-level reasoning, and finally toward embodied embedding reasoning with perception–action interaction. This progression reflects increasing reasoning scope, compositionality, and interactivity.
Citation
If you find this repository or our survey useful for your research, please consider citing:
@article{hu2026static,
  title   = {From Static Perception to Interactive Decision: A Survey of Multimodal Reasoning},
  author  = {Hu, Jian and Cheng, Zixu and Ma, Yinghao and Dixit, Satvik and Pan, Bikang and Chen, Lei and Ma, Lin and Zeng, Zhixiong and Wang, Jiangya and Benetos, Emmanouil and others},
  journal = {researchgate preprint},
  year    = {2026}
}
Table of Contents
- Awesome-MLLM-Reasoning-Collection
- Table of Contents
- Papers and Projects 📄
- Benchmarks 📊
- Open-source Projects
- Contributing
Papers and Projects 📄
An evolutionary landscape of several representative multi-modal reasoning frameworks from 2022 to 2025.
Commonsense Reasoning
Image MLLM
- 26.03 Phi-4-reasoning-vision-15B Technical Report | Paper📑 Model🤗
- Compact 15B open-weight multimodal reasoning model excelling at scientific/math reasoning and UI understanding via careful architecture choices, data curation, and hybrid reasoning/non-reasoning training. | Task: Reasoning & Understanding
- 26.03 Beyond Language Modeling: An Exploration of Multimodal Pretraining | Paper📑
- Systematic empirical study of unified multimodal pretraining from scratch using Transfusion, finding vision and language are complementary and world modeling emerges from general pretraining. | Task: Reasoning & Understanding
- 26.03 Unified Vision-Language Modeling via Concept Space Alignment | Paper📑
- v-LCM extends the Large Concept Model with vision-language instruction tuning in a unified latent embedding space, outperforming SOTA VLMs across 61 languages. | Task: Reasoning & Understanding
- 26.03 MMR-Life: Piecing Together Real-life Scenes for Multimodal Multi-image Reasoning | Paper📑 Project🌐
- Benchmark of 2,646 QAs on 19,108 images across 7 reasoning types for multi-image reasoning; even GPT-5 achieves only 58% accuracy vs. human performance. | Task: Reasoning & Understanding
- 26.03 Ref-Adv: Exploring MLLM Visual Reasoning in Referring Expression Tasks | Paper📑 Project🌐
- REC benchmark suppressing shortcuts with linguistically nontrivial expressions, revealing MLLM reliance on shortcuts and gaps in visual reasoning and grounding. | Task: Reasoning & Understanding
- 26.03 Recursive Think-Answer Process for LLMs and VLMs | Paper📑
- Recursive think-answer process enabling iterative reasoning refinement in VLMs for improved multimodal reasoning performance. | Task: Reasoning & Understanding
- 26.02 From Blind Spots to Gains: Diagnostic-Driven Iterative Training for Large Multimodal Models | Paper📑 Code🖥️ Model🤗
- Spiral-loop framework diagnosing capability gaps in MLLMs and generating targeted data and RL training to close them iteratively. | Task: Reasoning & Understanding
- 26.02 Imagination Helps Visual Reasoning, But Not Yet in Latent Space | Paper📑 Code🖥️
- CapImagine proposes text-based explicit imagination outperforming latent-space baselines on vision-centric benchmarks via causal mediation analysis. | Task: Reasoning & Understanding
- 26.02 NoLan: Mitigating Object Hallucinations in Large Vision-Language Models via Dynamic Suppression of Language Priors | Paper📑 Code🖥️
- Training-free decoding dynamically suppressing language priors by comparing multimodal vs. text-only output distributions, achieving +6.45/+7.21 accuracy on POPE. | Task: Reasoning & Understanding
- 26.02 Selective Training for Large Vision Language Models via Visual Information Gain | Paper📑
- Visual Information Gain (VIG) metric quantifying how much visual input reduces prediction uncertainty for improved visual grounding and reduced language bias. | Task: Reasoning & Understanding
- 26.02 MetaphorStar: Image Metaphor Understanding and Reasoning with End-to-End Visual Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- End-to-end visual RL framework for image metaphor comprehension with TFQ-GRPO method, achieving 82.6% average improvement on image implication benchmarks. | Task: Reasoning & Understanding
- 26.02 Learning Self-Correction in Vision-Language Models via Rollout Augmentation | Paper📑 Model🤗
- Octopus synthesizes dense self-correction examples for VLMs via RL, achieving SOTA among open-source VLMs on 7 benchmarks. | Task: Reasoning & Understanding
- 26.02 SPARC: Separating Perception And Reasoning Circuits for Test-time Scaling of VLMs | Paper📑
- Decouples visual perception from reasoning in VLMs via a two-stage pipeline, enabling efficient test-time scaling with 200× lower token budget. | Task: Reasoning & Understanding
- 26.02 Modality Gap-Driven Subspace Alignment Training Paradigm For Multimodal Large Language Models | Paper📑 Code🖥️
- Fixed-frame Modality Gap Theory with training-free ReAlign alignment and scalable ReVision pretraining using unpaired data to bridge the modality gap. | Task: Reasoning & Understanding
- 26.02 Kimi K2.5: Visual Agentic Intelligence | Paper📑 Code🖥️ Model🤗
- Open-source multimodal agentic model achieving SOTA across coding, vision, reasoning, and agentic tasks via joint text-vision RL and Agent Swarm parallel execution. | Task: Reasoning & Understanding
- 26.02 Toward Cognitive Supersensing in Multimodal Large Language Model | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Trains MLLMs to generate internal visual imagery sequences for abstract visual reasoning, evaluated on CogSense-Bench spanning five cognitive dimensions. | Task: Reasoning & Understanding
- 26.02 Thinking with Comics: Enhancing Multimodal Reasoning through Structured Visual Storytelling | Paper📑 Code🖥️
- Uses comics as a visual medium to improve multimodal reasoning efficiency while preserving temporal structure and narrative coherence. | Task: Reasoning & Understanding
- 26.02 SwimBird: Eliciting Switchable Reasoning Mode in Hybrid Autoregressive MLLMs | Paper📑 Code🖥️ Dataset🤗
- Hybrid autoregressive MLLM dynamically switching between text-only, vision-only, and interleaved vision-text reasoning modes based on input queries. | Task: Reasoning & Understanding
- 26.02 What does RL improve for Visual Reasoning? A Frankenstein-Style Analysis | Paper📑 Code🖥️ Model🤗
- Analyzes what RL actually improves in VLMs for visual reasoning, finding RL primarily refines mid-to-late transformer layers that improve vision-to-reasoning alignment. | Task: Reasoning & Understanding
- 26.02 On Robustness and Chain-of-Thought Consistency of RL-Finetuned VLMs | Paper📑
- Shows RL fine-tuning of VLMs introduces vulnerability to textual perturbations and reveals an accuracy-faithfulness trade-off undermining chain-of-thought reliability. | Task: Reasoning & Understanding
- 26.02 Thinking with Drafting: Optical Decompression via Logical Reconstruction | Paper📑
- TwD reconstructs logical structures from compressed visual tokens via Domain-Specific Language, forcing models to draft reasoning as executable code for self-verification. | Task: Reasoning & Understanding
- 26.02 Visual Persuasion: What Influences Decisions of Vision-Language Models? | Paper📑
- Studies VLM visual decision-making through controlled image-based choice tasks with systematic perturbations to identify visual vulnerabilities and safety concerns. | Task: Reasoning & Understanding
- 26.02 Adapting Vision-Language Models for E-commerce Understanding at Scale | Paper📑
- Adapts general-purpose VLMs for e-commerce product understanding via a 4M-item visual instruction tuning dataset covering deep product attributes and dynamic extraction. | Task: Reasoning & Understanding
- 26.02 Zooming without Zooming: Region-to-Image Distillation for Fine-Grained Multimodal Perception | Paper📑 Code🖥️ Model🤗
- Trains MLLMs to internally perform iterative zooming during inference via distillation, eliminating repeated tool calls while improving fine-grained visual perception. | Task: Reasoning & Understanding
- 26.02 DeepImageSearch: Benchmarking Multimodal Agents for Context-Aware Image Retrieval in Visual Histories | Paper📑 Code🖥️ Dataset🤗
- Reformulates image retrieval as multi-step reasoning over visual histories with DISBench benchmark and a modular agent with dual-memory system. | Task: Reasoning & Understanding
- 26.01 MMFineReason: Closing the Multimodal Reasoning Gap via Open Data-Centric Methods | Paper📑 Model🤗 Dataset🤗
- A 1.8M-sample multimodal reasoning dataset with high-quality CoT annotations; the 8B model approaches Qwen3-VL-32B-Thinking performance. | Task: Reasoning & Understanding
- 26.01 DiffThinker: Towards Generative Multimodal Reasoning with Diffusion Models | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Reformulates multimodal reasoning as a native image-to-image generative task using diffusion models. | Task: Reasoning & Understanding
- 26.01 Visual Generation Unlocks Human-Like Reasoning through Multimodal World Models | Paper📑 Code🖥️ Dataset🤗
- Proposes the visual superiority hypothesis: visual generation serves as a more natural world model for physical/spatial reasoning tasks. | Task: Reasoning & Understanding
- 26.01 VTC-R1: Vision-Text Compression for Efficient Long-Context Reasoning | Paper📑 Code🖥️
- Compresses textual reasoning traces into compact images as "optical memory" for VLMs, achieving 3.4x token compression. | Task: Reasoning & Understanding
- 26.01 UniCorn: Towards Self-Improving Unified Multimodal Models through Self-Generated Supervision | Paper📑 Code🖥️ Model🤗
- Self-improvement framework partitioning a single model into Proposer/Solver/Judge roles via self-play to improve comprehension and generation. | Task: Reasoning & Understanding
- 26.01 LaViT: Aligning Latent Visual Thoughts for Multi-modal Reasoning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Addresses the "Perception Gap" by aligning latent visual thoughts (attention trajectories) between teacher and student models. | Task: Reasoning & Understanding
- 26.01 STEP3-VL-10B Technical Report | Paper📑 Code🖥️ Model🤗
- A 10B multimodal foundation model with Parallel Coordinated Reasoning (PaCoRe) for test-time compute scaling. | Task: Reasoning & Understanding
- 26.01 Generation Enhances Understanding in Unified Multimodal Models via Multi-Representation Generation | Paper📑 Code🖥️
- Trains unified multimodal models to generate pixel, depth, and segmentation representations alongside understanding. | Task: Reasoning & Understanding
- 26.01 What Matters in Data Curation for Multimodal Reasoning? Insights from the DCVLR Challenge | Paper📑
- First-place NeurIPS 2025 DCVLR challenge submission revealing difficulty-based example selection as dominant driver in data curation. | Task: Reasoning & Understanding
- 26.01 MAD: Modality-Adaptive Decoding for Mitigating Cross-Modal Hallucinations in Multimodal Large Language Models | Paper📑
- Modality-adaptive decoding to mitigate cross-modal hallucinations in MLLMs by dynamically adjusting decoding. | Task: Reasoning & Understanding
- 25.12 OneThinker: All-in-one Reasoning Model for Image and Video | Paper📑
- Unifies image and video understanding across diverse visual tasks using RL with EMA-GRPO technique. | Task: Reasoning & Understanding
- 25.12 Puzzle Curriculum GRPO for Vision-Centric Reasoning | Paper📑
- Supervision-free RL method enhancing visual reasoning in VLMs through self-supervised puzzle environments. | Task: Reasoning & Understanding
- 25.12 Robust-R1: Degradation-Aware Reasoning for Robust Visual Understanding | Paper📑
- Enhances MLLM robustness to visual degradations by modeling degradation parameters through structured reasoning chains. | Task: Reasoning & Understanding
- 25.12 See Less, See Right: Bi-directional Perceptual Shaping For Multimodal Reasoning | Paper📑
- Improves VLM multimodal reasoning via paired masked views to enforce fine-grained visual reliance. | Task: Reasoning & Understanding
- 25.11 OpenMMReasoner: Pushing the Frontiers for Multimodal Reasoning with an Open and General Recipe | Paper📑
- Open general-purpose framework for advancing multimodal reasoning. | Task: Reasoning & Understanding
- 25.11 ThinkMorph: Emergent Properties in Multimodal Interleaved Chain-of-Thought Reasoning | Paper📑
- Studies emergent properties in multimodal interleaved chain-of-thought reasoning. | Task: Reasoning & Understanding
- 25.11 TiDAR: Think in Diffusion, Talk in Autoregression | Paper📑
- Combines diffusion-based thinking with autoregressive generation for multimodal reasoning. | Task: Reasoning & Understanding
- 25.10 TTRV: Test-Time Reinforcement Learning for Vision Language Models | Paper📑
- Test-time reinforcement learning applied to vision-language models for improved reasoning. | Task: Reasoning & Understanding
- 25.10 VLM-FO1: Bridging the Gap Between High-Level Reasoning and Fine-Grained Perception in VLMs | Paper📑
- Improves VLMs' ability to combine high-level reasoning with detailed visual perception. | Task: Reasoning & Understanding
- 25.10 ARES: Multimodal Adaptive Reasoning via Difficulty-Aware Token-Level Entropy Shaping | Paper📑
- Adaptive reasoning for multimodal models using entropy shaping. | Task: Reasoning & Understanding
- 25.09 R-4B: Incentivizing General-Purpose Auto-Thinking Capability in MLLMs via Bi-Mode Annealing and RL | Paper📑
- Training method using RL and annealing to improve auto-thinking and reasoning in multimodal LLMs. | Task: Reasoning & Understanding
- 25.09 LLaVA-OneVision-1.5: Fully Open Framework for Democratized Multimodal Training | Paper📑
- Open-source framework for training multimodal vision-language models. | Task: Reasoning & Understanding
- 25.08 Thyme: Think Beyond Images | Paper📑
- Multimodal reasoning system that extends beyond surface-level image understanding to higher-level thinking. | Task: Reasoning & Understanding
- 25.08 Controlling Multimodal LLMs via Reward-guided Decoding | Paper📑
- Controls MLLM reasoning outputs through reward-based generation guidance at decoding time. | Task: Reasoning & Understanding
- 25.08 Self-Rewarding Vision-Language Model via Reasoning Decomposition | Paper📑
- VLM that uses reasoning decomposition and self-reward to improve visual reasoning quality. | Task: Reasoning & Understanding
- 25.08 GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models | Paper📑
- Foundation model with strong agentic, reasoning, and coding capabilities across modalities. | Task: Reasoning & Understanding
- 25.07 GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning | Paper📑 Code🖥️
- A reasoning-centric training framework for general-purpose multimodal reasoning. | Task: Reasoning & Understainding
- 25.07 MiCo: Multi-image Contrast for Reinforcement Visual Reasoning | Paper📑
- Construct image triplets comprising two augmented views of the same image and a third, similar but distinct image. | Task: Reasoning & Understainding
- 25.06 Vision Matters: Simple Visual Perturbations Can Boost Multimodal Math Reasoning | Paper📑 Code🖥️ Model🤗
- Simple visual perturbation framework that can be easily integrated into existing post-training pipelines including SFT, DPO, and GRPO. | Task: Reasoning & Understainding
- 25.05 Visionary-R1: Mitigating Shortcuts in Visual Reasoning with Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- 25.05 Sherlock: Self-Correcting Reasoning in Vision-Language Models | Paper📑 Code🖥️ Model🤗
- Explore self-correction as a strategy to enhance reasoning VLMs | Task: Reasoning & Understainding
- 25.05 EchoInk-R1: Exploring Audio-Visual Reasoning in Multimodal LLMs via Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- The first general framework for unified audio-visual reasoning via reinforcement learning | Task: Reasoning & Understainding
- 25.03 Skywork-R1V: Pioneering Multimodal Reasoning with CoT | Paper📑 Code🖥️ Model🤗
- The first industry open-sourced multimodal reasoning model with advanced visual chain-of-thought capabilities | Task: Reasoning & Understainding
- 25.03 CMMCoT: Enhancing Complex Multi-Image Comprehension via Multi-Modal Chain-of-Thought and Memory Augmentation | Paper📑
- Mimic human-like ”slow thinking” for multi-image understanding. | Task: VQA
- 25.03 DAPO: an Open-Source LLM Reinforcement Learning System at Scale | Paper📑 Code🖥️ Data🤗
- Propose the Decoupled Clip and Dynamic sAmpling Policy Optimization (DAPO) algorithm. | Task: Math
- 25.03 VisRL: Intention-Driven Visual Perception via Reinforced Reasoning | Paper📑 Code🖥️
- The first framework that applies reinforcement learning (RL) to the problem of intention-driven visual perception | Task: VQA
- 25.03 Unified Reward Model for Multimodal Understanding and Generation | Paper📑 Code🖥️ Dataset🤗
- Improve MLLM's understanding and generation ability with DPO | Task: VQA & Generation
- 25.02 Qwen2.5-VL Technical Report | Paper📑 Code🖥️ Huggingface🤗
- The latest flagship model of Qwen vision-language series for various multimodal tasks | Task: Reasoning & Understainding
- 25.02 MM-RLHF: The Next Step Forward in Multimodal LLM Alignment | Paper📑 Project🌐
- A comprehensive project for aligning MlLMs with human preferences | Task: Reward & VQA
- 25.01 Kimi k1.5: Scaling Reinforcement Learning with LLMs (MoonshotAI) | Project🌐
- The latest flagship model of Kimi series for various multimodal tasks | Task: Reasoning & Understainding
- 25.01 InternLM-XComposer2.5-Reward: A Simple Yet Effective Multi-Modal Reward Model | Paper📑 Code🖥️
- A simple yet effective multi-modal reward model that aligns MLLMs with human preferences | Reward & VQA
- 25.01 LlamaV-o1: Rethinking Step-By-Step Visual Reasoning in LLMs | Paper📑 Code🖥️
- A combined multi-step curriculum learning and beam search multimodal reasoning model | VQA
- 25.01 ReFocus: Visual Editing as a Chain of Thought for Structured Image Understanding | Paper📑 Code🖥️ Model🤗
- Perform visual chain of thought via input-image editing to help multimodal reasoning. | Task: VQA
- 24.12 Mulberry: Empowering MLLM with o1-like Reasoning and Reflection via Collective Monte Carlo Tree Search | Paper📑 Code🖥️ Dataset🤗
- Improve MLLM reasoning ability via collective monte carlo tree search | VQA
- 24.11 LLaVA-CoT: Let Vision Language Models Reason Step-by-Step | Paper📑 Code🖥️ Model🤗
- A novel MLLM designed to conduct autonomous multistage reasoning. | VQA
- 24.11 Insight-V: Exploring Long-Chain Visual Reasoning with Multimodal Large Language Models | Paper📑 Code🖥️ Model🤗
- Explore long-chain visual reasoning with MLLMs | VQA
- 24.11 Enhancing the Reasoning Ability of Multimodal Large Language Models via Mixed Preference Optimization | Paper📑 Code🖥️ Model🤗
- A preference optimization (PO) process to enhance the multimodal reasoning capabilities of MLLMs. | VQA
- 24.10 Improve Vision Language Model Chain-of-thought Reasoning | Paper📑 Code🖥️
- Apply reinforcement learning on 193k CoT sft data for reasoning | VQA
- 24.03 (NeurIPS24)Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought Reasoning | Paper📑 Code🖥️
Dataset🤗
- Visual CoT for improve MLLMs' reasoning ability | VQA
- 23.02 Multimodal Chain-of-Thought Reasoning in Language Models | Paper📑 Code🖥️
- Visual CoT for MLLM reasoning | VQA
Video MLLM
- 26.03 LongVideo-R1: Smart Navigation for Low-cost Long Video Understanding | Paper📑 Code🖥️
- Active reasoning-equipped MLLM agent for efficient long video navigation using hierarchical visual summaries and iterative clip refinement, trained via SFT+RL on 33K CoT trajectories. | Task: Video Understanding & Reasoning
- 26.03 Proact-VL: A Proactive VideoLLM for Real-Time AI Companions | Paper📑
- Framework enabling real-time proactive AI companions via chunk-wise video processing with autonomous response timing decisions, evaluated on Live Gaming Benchmark. | Task: Video Understanding & Reasoning
- 26.02 A Very Big Video Reasoning Suite | Paper📑 Model🤗 Dataset🤗
- 1M+ video clip dataset spanning 200 reasoning tasks (VBVR) with VBVR-Bench for verifiable evaluation, enabling emergent generalization via large-scale scaling. | Task: Video Understanding & Reasoning
- 26.02 Thinking in Frames: How Visual Context and Test-Time Scaling Empower Video Reasoning | Paper📑 Project🌐
- Video generation models achieve zero-shot generalization for visual reasoning by using generated frames as intermediate reasoning steps with a visual test-time scaling law. | Task: Video Understanding & Reasoning
- 26.02 Multimodal Fact-Level Attribution for Verifiable Reasoning | Paper📑 Code🖥️
- MuRGAt benchmark requiring MLLMs to provide precise fact-level citations across video, audio, and modalities, finding strong models frequently hallucinate citations despite correct reasoning. | Task: Video Understanding & Reasoning
- 26.02 Towards Universal Video MLLMs with Attribute-Structured and Quality-Verified Instructions | Paper📑 Code🖥️ Model🤗 Dataset🤗
- ASID-Caption suite with 1M structured audiovisual annotations and quality verification pipeline for fine-grained audiovisual video understanding across multiple attribute dimensions. | Task: Video Understanding & Reasoning
- 26.02 VisPhyWorld: Probing Physical Reasoning via Code-Driven Video Reconstruction | Paper📑 Code🖥️
- Execution-based framework evaluating physical reasoning in MLLMs by requiring executable simulator code from visual observations; VisPhyBench (209 scenes) reveals MLLMs struggle to infer physical parameters. | Task: Video Understanding & Reasoning
- 26.01 Taming Hallucinations: Boosting MLLMs' Video Understanding via Counterfactual Video Generation | Paper📑
- Uses counterfactual video generation to reduce hallucinations and improve temporal reasoning in multimodal LLMs. | Task: Video Understanding & Reasoning
- 25.12 Rethinking Chain-of-Thought Reasoning for Videos | Paper📑
- Proposes improved chain-of-thought reasoning strategies specifically designed for video understanding tasks. | Task: Video Understanding & Reasoning
- 25.12 SAGE: Training Smart Any-Horizon Agents for Long Video Reasoning with RL | Paper📑
- RL-based framework training agents for long-horizon video reasoning across variable time spans. | Task: Video Understanding & Reasoning
- 25.11 Video-R4: Reinforcing Text-Rich Video Reasoning with Visual Rumination | Paper📑
- Enhances reasoning over text-rich video content via visual rumination. | Task: Video Understanding & Reasoning
- 25.10 Video-Thinker: Sparking "Thinking with Videos" via Reinforcement Learning | Paper📑
- Reasoning framework enabling models to think with video inputs via RL. | Task: Video Understanding & Reasoning
- 25.10 StreamingVLM: Real-Time Understanding for Infinite Video Streams | Paper📑
- Real-time video stream understanding with multimodal LLMs. | Task: Video Understanding & Reasoning
- 25.09 Video models are zero-shot learners and reasoners | Paper📑
- Demonstrates zero-shot reasoning capabilities in video models. | Task: Video Understanding & Reasoning
- 25.07 Scaling RL to Long Videos| Paper📑 Model🤗 Code🖥️
- 25.06 DeepVideo-R1: Video Reinforcement Fine-Tuning via Difficulty-aware Regressive GRPO|Paper📑
- 25.06 VideoRFT: Incentivizing Video Reasoning Capability in MLLMs via Reinforced Fine-Tuning | Paper📑 Model🤗 Code🖥️
- Extend Reinforcement Fine-Tuning (RFT) to the video reasoning domain, a long-standing challenge. | Task: Video Understanding & Reasoning
- 25.06 VersaVid-R1: A Versatile Video Understanding and Reasoning Model from Question Answering to Captioning Tasks|Paper📑 Model🤗 Code🖥️
- 25.05 SpaceR: Reinforcing MLLMs in Video Spatial Reasoning|Paper📑 Model🤗 Code🖥️
- 25.05 Video-R1: Reinforcing Video Reasoning in MLLMs | Paper📑Model🤗 Code🖥️
- 25.04 TinyLLaVA-Video-R1: Towards Smaller LMMs for Video Reasoning | Paper📑 Model🤗 Code🖥️
- 25.04 Unified Multimodal Chain-of-Thought Reward Model through Reinforcement Fine-Tuning | Paper📑 Project🌐 Code🖥️
- The first unified multimodal CoT reward model, capable of step-by-step long-chain reasoning for visual understanding and generation reward tasks. | Task: Video Understanding and Feneration
- 25.04 ViSMaP: Unsupervised Hour-long Video Summarisation by Meta-Prompting | Paper📑
- A system to summarise hour long videos with no-supervision. | Task: Video Summary
- 25.04 TinyLLaVA-Video-R1: Towards Smaller LMMs for Video Reasoning | Paper📑 Code🖥️ | Model🤗
- Present the small-scale video reasoning model TinyLLaVA-Video-R1 | Task: Video QA
- 25.04 VideoMind: A Chain-of-LoRA Agent for Long Video Reasoning | Paper📑 Code🖥️ | Dataset🤗
- A novel video-language agent designed for temporal-grounded video understanding. | Task: Video QA
- 25.04 Exploring the Effect of Reinforcement Learning on Video Understanding: Insights from SEED-Bench-R1 | Paper📑 Code🖥️ | Dataset🤗
- Reveals that RL enhances visual perception but often produces less logically coherent reasoning chains. | Task: Video QA
- 25.03 VIDEOTREE: Adaptive Tree-based Video Representation for LLM Reasoning on Long Videos |Paper📑 Code🖥️
- 25.02 CoS: Chain-of-Shot Prompting for Long Video Understanding | Paper📑 Code🖥️
- Approach long video understanding by optimising input video information to fully utilise MLLM’s ability to comprehend long videos. | Task: Video VQA
- 25.02 video-SALMONN-o1: Reasoning-enhanced Audio-visual Large Language Model | Paper📑 Demo🖥️
- A open-source reasoning-enhanced audio-visual LLM designed for general video understanding tasks. | Task: Video QA
- 25.02 Open-R1-Video | Code🖥️ Dataset🤗
- A open-source R1-style video understanding model | Task: Video QA
- 25.01 Temporal Preference Optimization for Long-Form Video Understanding | Paper📑Code🖥️
- A novel post-training framework designed to enhance the temporal grounding capabilities of video-LMMs through preference learning | Task: Video QA
- 25.01 Tarsier2: Advancing Large Vision-Language Models from Detailed Video Description to Comprehensive Video Understanding | Paper📑 Code🖥️
Model🤗
- A family of VLMs designed for high-quality video captioning and understanding | Task: Video captioning & QA
- 24.12 (ECCV24) VideoAgent: A Memory-augmented Multimodal Agent for Video Understanding | Paper📑 Code🖥️ Project🌐
- Explore how reconciling several foundation models with a novel unified memory mechanism could tackle the challenging video understanding problem | Task: Video captioning & QA
Audio MLLM
- 25.10 UALM: Unified Audio Language Model for Understanding, Generation and Reasoning Project🌐
- 25.09 MiMo Audio: Audio Language Models are Few-Shot Learners Project🌐 Code🖥️
- 25.07 Audio Entailment: Assessing Deductive Reasoning for Audio Understanding
- 25.07 Audio Flamingo 3: Advancing Audio Intelligence with Fully Open Large Audio Language Models
- 25.05 AudSemThinker: Enhancing Audio-Language Models Through Reasoning over Semantics of Sound
- 25.05 Omni-R1: Do You Really Need Audio to Fine-Tune Your Audio LLM?
- Utilizing GRPO to enhance audio reasoning performance
- 25.04 SARI: Structured Audio Reasoning via Curriculum-Guided Reinforcement Learning
- 25.04 Kimi-Audio Technical Report Code🖥️
- 25.03 Reinforcement Learning Outperforms Supervised Fine-Tuning: A Case Study on Audio Question Answering
- 25.03 Audio-Reasoner: Improving Reasoning Capability in Large Audio Language Models Project🌐
- Utilizing CoT data for audio understanding tasks.
- 25.03 Mellow: a small audio language model for reasoning Code🖥️
- Small audio-language model (167M) designed for audio understanding, audio entailment, audio difference and captioning.
- 25.03 Audio Flamingo 2: An Audio-Language Model with Long-Audio Understanding and Expert Reasoning Abilities Project🌐
- NVIDIA audio-language for various audio understanding and reasoning.
- 25.02 Step-Audio: Unified Understanding and Generation in Intelligent Speech Interaction Code🖥️
- 25.01 Audio-CoT: Exploring Chain-of-Thought Reasoning in Large Audio Language Model
- Finetuning Qwen2-Audio with CoT data for audio understanding and retrieval tasks.
- 24.07 Qwen2-Audio Technical Report Paper📑 Code🖥️
- Qwen audio-language series for various audio understanding tasks especially for speech.
- 24.07 (EMNLP2024) GAMA: A Large Audio-Language Model with Advanced Audio Understanding and Complex Reasoning Abilities Project🌐
- NVIDIA audio-language for various audio understanding and reasoning.
- 24.02 (ICML2024)Audio Flamingo: A Novel Audio Language Model with Few-Shot Learning and Dialogue Abilities Code🖥️
- audio-language for various audio understanding and reasoning with Q-formers.
- 23.11 Qwen-Audio: Advancing Universal Audio Understanding via Unified Large-Scale Audio-Language Models Code🖥️
- Qwen audio-language series for various audio understanding tasks in speech sound and music.
- 23.10 (ICLR2024) SALMONN: Towards Generic Hearing Abilities for Large Language Models Code🖥️
- Bytedance audio-language for various audio understanding tasks especially for speech and sound with Q-former.
- 23.09 (NAACL2024) MusiLingo: Bridging Music and Text with Pre-trained Language Models for Music Captioning and Query Response
- Music-language for understanding and captioning tasks.
Omni MLLM
- 26.05 Boosting Omni-Modal Language Models: Staged Post-Training with Visually Debiased Evaluation Project Dataset🤗
- 26.02 OmniGAIA: Towards Native Omni-Modal AI Agents | Paper📑 Code🖥️ Model🤗 Dataset🤗
- OmniGAIA benchmark for omni-modal agent evaluation on cross-modal reasoning and tool-use, with OmniAtlas agent trained via hindsight-guided tree exploration and OmniDPO. | Task: Reasoning & Understanding
- 26.02 Mobile-O: Unified Multimodal Understanding and Generation on Mobile Device | Paper📑 Code🖥️ Model🤗
- Compact on-device unified multimodal model (~3s/512×512 on iPhone) outperforming Show-O and JanusFlow on generation and visual understanding benchmarks. | Task: Reasoning & Understanding
- 26.02 OmniVideo-R1: Reinforcing Audio-visual Reasoning with Query Intention and Modality Attention | Paper📑
- Reinforced framework for omnivideo models improving mixed-modality reasoning by combining query-intensive grounding and modality-attentive fusion via contrastive learning. | Task: Reasoning & Understanding
- 26.02 UniT: Unified Multimodal Chain-of-Thought Test-time Scaling | Paper📑
- Framework enabling unified multimodal models to perform iterative CoT test-time scaling, showing sequential reasoning is more efficient than parallel sampling for both generation and understanding. | Task: Reasoning & Understanding
- 26.02 Best of Both Worlds: Multimodal Reasoning and Generation via Unified Discrete Flow Matching | Paper📑
- UniDFlow, a unified discrete flow-matching framework decoupling understanding and generation via low-rank adapters and multimodal preference alignment, achieving SOTA across 8 benchmarks. | Task: Reasoning & Understanding
- 26.02 Understanding vs. Generation: Navigating Optimization Dilemma in Multimodal Models | Paper📑 Code🖥️
- R3 (Reason-Reflect-Refine) framework reformulating single-step generation into multi-step generate-understand-regenerate process to resolve the trade-off between multimodal understanding and generation. | Task: Reasoning & Understanding
- 26.02 BrowseComp-V3: A Visual, Vertical, and Verifiable Benchmark for Multimodal Browsing Agents | Paper📑
- 300-question benchmark for complex multi-hop reasoning across text and visual modalities with deep web search; even SOTA models achieve only 36% accuracy, with the OmniSeeker unified browsing agent. | Task: Reasoning & Understanding
- 25.12 Qwen3-VL Technical Report | Paper📑
- Advanced VLM excelling in text and multimodal understanding supporting up to 256K tokens of interleaved text, images, and video. | Task: Reasoning & Understanding
- 25.10 InteractiveOmni: A Unified Omni-modal Model for Audio-Visual Multi-turn Dialogue
- 25.10 Ming-Flash-Omni: A Sparse, Unified Architecture for Multimodal Perception and Generation | Paper📑
- Unified sparse architecture for multimodal perception and generation across modalities. | Task: Reasoning & Understanding
- 25.10 OmniVinci: Enhancing Architecture and Data for Omni-Modal Understanding LLM | Paper📑
- Multimodal LLM for comprehensive understanding across all modalities. | Task: Reasoning & Understanding
- 25.09 Qwen3-Omni Technical Report
- 25.09 Lavida-O: Elastic Large Masked Diffusion Models for Unified Multimodal Understanding and Generation | Paper📑
- Unified model for multimodal understanding and generation across modalities. | Task: Reasoning & Understanding
- 25.07 Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next Generation Agentic Capabilities
- 25.05 EchoInk-R1: Exploring Audio-Visual Reasoning in Multimodal LLMs via Reinforcement Learning
- 25.03 Qwen2.5-Omni Technical Report
- 25.2 NEXUS-O: An Omni-Perceptive and -Interactive Model for Language, Audio, and Vision
- 25.01 OpenOmni: Advancing Open-Source Omnimodal Large Language Models with Progressive Multimodal Alignment and Real-Time Self-Aware Emotional Speech Synthesis
- 24.10 Baichuan-Omni Technical Report
- 24.09 MIO: A Foundation Model on Multimodal Tokens
- 24.08 MiniCPM-V: A GPT-4V Level MLLM on Your Phone [Code]
- 24.02 AnyGPT: Unified Multimodal LLM with Discrete Sequence Modeling
- 23.12 Unified-IO 2: Scaling Autoregressive Multimodal Models with Vision, Language, Audio, and Action
Reasoning Segmentation and Detection
Image MLLM
- 26.02 Retrieve and Segment: Are a Few Examples Enough to Bridge the Supervision Gap in Open-Vocabulary Segmentation? | Paper📑 Code🖥️
- Retrieval-augmented test-time adapter for open-vocabulary segmentation fusing textual prompts with pixel-annotated visual support features to narrow zero-shot vs. supervised gap. | Task: Reasoning Segmentation
- 26.02 Seg-ReSearch: Segmentation with Interleaved Reasoning and External Search | Paper📑 Code🖥️ Dataset🤗
- Novel segmentation paradigm enabling interleaved reasoning and external search to overcome knowledge bottlenecks, with OK-VOS benchmark for open-knowledge video object segmentation. | Task: Reasoning Segmentation
- 26.02 Conversational Image Segmentation: Grounding Abstract Concepts with Scalable Supervision | Paper📑 Code🖥️
- CIS task grounding abstract intent-driven concepts into pixel-accurate masks beyond categorical queries, with ConverSeg benchmark, ConverSeg-Net model, and AI-powered scalable data engine. | Task: Reasoning Segmentation
- 26.03 HDINO: A Concise and Efficient Open-Vocabulary Detector | Paper📑
- Concise open-vocabulary detector with one-to-many semantic alignment achieving strong performance with reduced complexity compared to Grounding DINO. | Task: Detection & Grounding
- 26.01 Urban Socio-Semantic Segmentation with Vision-Language Reasoning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Vision-language reasoning framework for urban satellite segmentation identifying both physical and social categories via multi-stage reasoning. | Task: Reasoning Segmentation
- 26.01 SAMTok: Representing Any Mask with Two Words | Paper📑
- Efficient mask tokenization representing arbitrary segmentation masks with just two tokens, enabling reasoning-driven segmentation. | Task: Reasoning Segmentation
- 26.01 Towards Pixel-Level VLM Perception via Simple Points Prediction | Paper📑
- Enables pixel-level perception in VLMs through simple points prediction, bridging VLM reasoning and fine-grained spatial detection. | Task: Detection & Grounding
- 25.12 ReVSeg: Incentivizing the Reasoning Chain for Video Segmentation with Reinforcement Learning | Paper📑
- Uses RL to incentivize reasoning chains for improved video segmentation. | Task: Reasoning Segmentation
- 25.12 InSight-o3: Empowering Multimodal Foundation Models with Generalized Visual Search | Paper📑
- Enhances multimodal models with generalized visual search for improved grounding. | Task: Detection & Grounding
- 25.11 SAM 3: Segment Anything with Concepts | Paper📑
- Advances segmentation with concept-based reasoning. | Task: Reasoning Segmentation
- 25.10 Decomposed Attention Fusion in MLLMs for Training-Free Video Reasoning Segmentation | Paper📑
- Video reasoning and segmentation with multimodal models without training. | Task: Reasoning Segmentation
- 25.09 RefAM: Attention Magnets for Zero-Shot Referral Segmentation | Paper📑
- Zero-shot referral segmentation using attention-based visual reasoning. | Task: Reasoning Segmentation
- 25.07 UrbanLLaVA: A Multi-modal Large Language Model for Urban Intelligence with Spatial Reasoning and Understanding | Paper📑 Code🖥️
- A multi-stage training framework that decouples spatial reasoning enhancement from domain knowledge learning, thereby improving performance across diverse urban tasks. | Task: Urban tasks
- 25.07 Fine-Grained Preference Optimization Improves Spatial Reasoning in VLMs | Paper📑
- A novel fine-grained preference optimization approach that significantly improves spatial reasoning capabilities in VLMs | Task: Spatial Tasks
- 25.06 Rex-Thinker: Grounded Object Referring via Chain-of-Thought Reasoning | Paper📑 Code🖥️
Model🤗
- a grounded model reasons step-by-step—just like a human would | Task: Detection & Grounding
- 25.03 Visual-RFT: Visual Reinforcement Fine-Tuning | Paper📑 Code🖥️
Dataset🤗
- Extend Reinforcement Fine-Tuning on visual tasks with GRPO | Task: Detection & Grounding & Classification
- 25.03 Boosting the Generalization and Reasoning of Vision Language Models with Curriculum Reinforcement Learning | Paper📑
- Improve generalization and reasoning of VLMs with GRPO | Task: Detection & Classification & Math
- 25.03 Seg-Zero: Reasoning-Chain Guided Segmentation via Cognitive Reinforcement | Paper📑 Code🖥️ Model🤗
- Address object detection and segmentation with GRPO | Task: Object Detection & Object Segmentation
- 24.08 (NeurIPS) Leveraging Hallucinations to Reduce Manual Prompt Dependency in Promptable Segmentation | Paper📑 Code🖥️
- Utilize hallucinations to mine task-related information from images and verify its accuracy for enhancing precision of the generated prompts. | Task: Reasoning Segmentation
- 24.07 (CVPR24) Learning to Localize Objects Improves Spatial Reasoning in Visual-LLMs | Paper📑
- Explore how instruction fine-tuning objectives could inject spatial awareness into V-LLMs| | Task: Reasoning Localization
- 23.04 (AAAI24) Relax Image-Specific Prompt Requirement in SAM: A Single Generic Prompt for Segmenting Camouflaged Objects | Paper📑 Code🖥️
- Employ Cross-modal Chains of Thought Prompting (CCTP) to reason visual prompts using the semantic information given by a generic text prompt. | Task: Reasoning segmentation
- 23.12 (CVPR24) PixelLM:Pixel Reasoning with Large Multimodal Model | Paper📑 Code🖥️
- An effective and efficient LMM for pixel-level reasoning and understanding | Task: Reasoning Segmentation
- 23.08 (CVPR24)LISA: Reasoning Segmentation via Large Language Model | Paper📑 Code🖥️ Dataset🤗
- Inherit the language generation capabilities of the MLLM while also possessing the ability to produce segmentation masks. | Task: Reasoning Segmentation
Video MLLM
- 26.02 VidEoMT: Your ViT is Secretly Also a Video Segmentation Model | Paper📑 Code🖥️ Model🤗
- Lightweight encoder-only video segmentation on plain ViT with query propagation and fusion, achieving 160 FPS with ViT-L without dedicated tracking modules. | Task: Reasoning Segmentation
- 26.02 Learning Cross-View Object Correspondence via Cycle-Consistent Mask Prediction | Paper📑 Code🖥️
- Conditional binary segmentation with cycle-consistency training for object-level correspondence across egocentric/exocentric viewpoints without ground-truth annotations (CVPR 2026). | Task: Reasoning Segmentation
- 24.08 (ECCV24)VISA: Reasoning Video Object Segmentation via Large Language Model | Paper📑 Code🖥️ Dataset🤗
- Leverage the world knowledge reasoning capabilities of MLLMs while possessing the ability to segment and track objects in videos with a mask decoder | Task: Reasoning Segmentation
- 24.07 (NeruIPS24)One Token to Seg Them All: Language Instructed Reasoning Segmentation in Videos | Paper📑 Code🖥️ Model🤗
- Integrating a Sparse Dense Sampling strategy into the video-LLM to balance temporal context and spatial detail within computational constraints | Task: Reasoning Segmentation
- 24.01 (CVPR24) OMG-LLaVA: Bridging Image-level, Object-level, Pixel-level Reasoning and Understanding | Paper📑 Code🖥️
- A transformer-based encoder-decoder architecture with task-specific queries and outputs for multiple tasks | Task: Reasoning Segmentation/Detection
Audio MLLM
Omni MLLM
- 25.07 Towards Omnimodal Expressions and Reasoning in Referring Audio-Visual Segmentation
- 24.08 Unleashing the Temporal-Spatial Reasoning Capacity of GPT for Training-Free Audio and Language Referenced Video Object Segmentation
Spatial and Temporal Grounding and Understanding
Image MLLM
- 26.02 GeoWorld: Geometric World Models | Paper📑
- Hyperbolic JEPA preserving latent state structures for improved long-horizon world model prediction and Geometric RL planning (CVPR 2026). | Task: Spatial Reasoning
- 26.02 When and How Much to Imagine: Adaptive Test-Time Scaling with World Models for Visual Spatial Reasoning | Paper📑 Code🖥️
- AVIC adaptively invokes visual imagination via world models to match or outperform fixed imagination strategies for spatial reasoning with far fewer calls. | Task: Spatial Reasoning
- 26.02 Theory of Space: Can Foundation Models Construct Spatial Beliefs through Active Exploration? | Paper📑 Code🖥️ Dataset🤗
- Evaluates VLMs' ability to construct spatial beliefs through active exploration, revealing Active-Passive Gap and Belief Inertia—VLMs fail to update stale spatial priors. | Task: Spatial Understanding
- 26.02 SpatiaLab: Can Vision-Language Models Perform Spatial Reasoning in the Wild? | Paper📑 Code🖥️ Dataset🤗
- Benchmark of 1,400 VQA pairs across six spatial reasoning categories revealing VLMs achieve only ~55% vs. 87.6% human accuracy (ICLR 2026). | Task: Spatial Reasoning
- 26.02 LangMap: A Hierarchical Benchmark for Open-Vocabulary Goal Navigation | Paper📑 Code🖥️
- Multi-granularity open-vocabulary navigation task with 414 object categories and 18K+ navigation tasks across scene, room, region, and instance levels. | Task: Spatial Grounding & Navigation
- 26.02 GeoAgent: Learning to Geolocate Everywhere with Reinforced Geographic Characteristics | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Geolocation reasoning model using RL with geo-similarity and consistency rewards over GeoSeek dataset, enabling fine-grained address-level localization with human-like reasoning. | Task: Spatial Reasoning
- 26.03 Enhancing Spatial Understanding in Image Generation via Reward Modeling | Paper📑 Project🌐
- SpatialReward-Dataset (80K preference pairs) and SpatialScore reward model for evaluating spatial relationship accuracy; enables online RL to significantly enhance spatial reasoning in image generation. | Task: Spatial Reasoning
- 26.01 CoV: Chain-of-View Prompting for Spatial Reasoning | Paper📑 Code🖥️
- Training-free test-time reasoning framework transforming VLMs into active viewpoint reasoners through coarse-to-fine 3D exploration, +11.56% on OpenEQA. | Task: Spatial Reasoning
- 26.01 Think3D: Thinking with Space for Spatial Reasoning | Paper📑
- Framework for spatial reasoning enabling models to reason in 3D space for improved visual understanding tasks. | Task: Spatial Reasoning & 3D Understanding
- 25.12 SpaceTools: Tool-Augmented Spatial Reasoning via Double Interactive RL | Paper📑
- Tool-augmented spatial reasoning using double interactive reinforcement learning. | Task: Spatial Reasoning
- 25.12 COOPER: A Unified Model for Cooperative Perception and Reasoning in Spatial Intelligence | Paper📑
- Unified model combining cooperative perception with spatial intelligence reasoning. | Task: Spatial Reasoning
- 25.11 SpatialThinker: Reinforcing 3D Reasoning in Multimodal LLMs via Spatial Rewards | Paper📑
- Uses reinforcement learning with spatial rewards to improve 3D reasoning in MLLMs. | Task: Spatial Reasoning & 3D Understanding
- 25.11 G2VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning | Paper📑
- Unifies 3D reconstruction and spatial reasoning in a geometry-grounded VLM. | Task: Spatial Reasoning & 3D Understanding
- 25.10 SpaceVista: All-Scale Visual Spatial Reasoning from mm to km | Paper📑
- Spatial reasoning across multiple scales in visual understanding. | Task: Spatial Reasoning
- 25.08 3D-R1: Enhancing Reasoning in 3D VLMs for Unified Scene Understanding | Paper📑
- Enhances reasoning capabilities of 3D vision-language models for unified 3D scene understanding. | Task: Spatial Reasoning & 3D Understanding
- 25.04 Perspective-Aware Reasoning in Vision-Language Models via Mental Imagery Simulation | Paper📑 Project🌐 Code🖥️
- A framework for perspective-aware reasoning in vision-language models (VLMs) through mental imagery simulation. | Task: Spatial Reasoning & Understanding
- 25.04 Reason-RFT: Reinforcement Fine-Tuning for Visual Reasoning | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Introduce a combined RL and SFT training paradigm to enhance visual reasoning capabilities in multimodal models. | Task: Spatial Reasoning & Understanding
- 25.04 InteractVLM: 3D Interaction Reasoning from 2D Foundational Models | Paper📑 Code💻
- Harnesses the broad visual knowledge of large Vision-Language Models (VLMs), fine-tuned with limited 3D contact data. Task: 3D Reconstruction
- 25.03 Embodied-Reasoner: Synergizing Visual Search, Reasoning, and Action for Embodied Interactive Tasks | Paper📑 Code💻 Project🌐 Dataset🤗
- A model that extends O1-style reasoning to interactive embodied tasks. | Task: Interactive Embodied Tasks
- 25.03 VisualThinker-R1-Zero | Paper📑 Code💻
- R1-Zero's "Aha Moment" in Visual Reasoning on a 2B Non-SFT Model | Task: Counting & Reasoning & 3D Understanding (CV-Bench)
- 25.03 (CVPR2025)GFlowVLM: Enhancing Multi-step Reasoning in Vision-Language Models with Generative Flow Networks | Paper📑
- Fine-tune VLMs using GFlowNet to promote generation of diverse solutions.| Task: NumberLine (NL) & BlackJack (BJ)
- 25.02 R1-V: Reinforcing Super Generalization Ability in Vision Language Models with Less Than $3 | Code🖥️
- A open-source project for VLM reasoning with GRPO | Task: Counting, Number Related Reasoning and Geometry Reasoning
- 25.01 Imagine while Reasoning in Space: Multimodal Visualization-of-Thought | Paper📑
- Enables visual thinking in MLLMs by generating image visualizations of their reasoning traces. | Task: Spatial Reasoning
Video MLLM
- 26.02 TimeChat-Captioner: Scripting Multi-Scene Videos with Time-Aware and Structural Audio-Visual Captions | Paper📑 Code🖥️ Model🤗
- Omni Dense Captioning with six-dimensional structural schema generating time-aware audio-visual narratives with explicit timestamps, surpassing Gemini-2.5-Pro on the task. | Task: Temporal Grounding/Understanding
- 26.02 4RC: 4D Reconstruction via Conditional Querying Anytime and Anywhere | Paper📑
- 4D dynamic scene reconstruction framework with conditional querying at arbitrary space-time locations for flexible spatiotemporal understanding of dynamic scenes. | Task: Spatial-Temporal Understanding
- 26.02 Learning Situated Awareness in the Real World | Paper📑
- SAW-Bench evaluates egocentric situated awareness using 786 real-world videos from smart glasses with 2,071+ QA pairs, revealing a 37.66% human-model performance gap in observer-centric spatial reasoning. | Task: Temporal Grounding/Understanding
- 26.02 MoRL: Reinforced Reasoning for Unified Motion Understanding and Generation | Paper📑 Code🖥️
- Unified multimodal motion model combining SFT and RL with Chain-of-Motion (CoM) reasoning and large-scale CoT datasets for human motion understanding and generation. | Task: Spatial-Temporal Understanding
- 26.03 RIVER: A Real-Time Interaction Benchmark for Video LLMs | Paper📑
- Benchmark evaluating real-time interaction in Video LLMs with Retrospective Memory, Live-Perception, and Proactive Response tasks, revealing gaps in long-term memory and future perception. | Task: Temporal Understanding
- 26.01 VideoLoom: A Video Large Language Model for Joint Spatial-Temporal Understanding | Paper📑 Code🖥️ Model🤗
- Unified Video LLM for joint spatial-temporal understanding with LoomData-8.7k dataset and LoomBench benchmark. | Task: Spatial-Temporal Understanding
- 26.01 VideoAuto-R1: Video Auto Reasoning via Thinking Once, Answering Twice | Paper📑 Code🖥️
- Video understanding framework with "reason-when-necessary" strategy using confidence-based reasoning activation, reducing response length 3.3x. | Task: Video Understanding & Reasoning
- 26.01 Molmo2: Open Weights and Data for Vision-Language Models with Video Understanding and Grounding | Paper📑 Code🖥️
- Open-source video-language model family with point-driven grounding and video tracking capabilities surpassing Gemini 3 Pro on grounding. | Task: Spatial Understanding & Grounding
- 26.01 PROGRESSLM: Towards Progress Reasoning in Vision-Language Models | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Addresses task progress estimation in VLMs with Progress-Bench benchmark and ProgressLM-3B model. | Task: Temporal Reasoning & Understanding
- 26.01 HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video Understanding | Paper📑
- Efficient streaming video understanding via hierarchical KV cache memory enabling temporal reasoning over long videos. | Task: Temporal Reasoning
- 25.12 4D-RGPT: Toward Region-level 4D Understanding via Perceptual Distillation | Paper📑
- Region-level 4D (3D + temporal) understanding through perceptual distillation. | Task: Spatial-Temporal Understanding
- 25.12 MMSI-Video-Bench: A Holistic Benchmark for Video-Based Spatial Intelligence | Paper📑
- Comprehensive benchmark for evaluating spatial intelligence in video understanding. | Task: Spatial-Temporal Understanding
- 25.11 VLA-4D: Embedding 4D Awareness into Vision-Language-Action Models for SpatioTemporally Coherent Robotic Manipulation | Paper📑
- Incorporates 4D spatiotemporal awareness into VLA models for coherent robotic manipulation. | Task: Spatial-Temporal Understanding
- 25.10 Trace Anything: Representing Any Video in 4D via Trajectory Fields | Paper📑
- 4D spatial-temporal representation learning from video. | Task: Spatial-Temporal Understanding
- 25.08 VLM4D: Towards Spatiotemporal Awareness in Vision Language Models | Paper📑
- Extends VLMs with spatiotemporal reasoning for understanding spatial and temporal dynamics. | Task: Spatial-Temporal Understanding
- 25.05 MUSEG: Reinforcing Video Temporal Understanding via Timestamp-Aware Multi-Segment Grounding | Paper📑 Code💻
- 25.04 VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning | Paper📑 Code💻
- A novel spatiao-temporal perception framework with GRPO | Task: Spatial Understanding and Grounding
- 25.04 VisuoThink: Empowering LVLM Reasoning with Multimodal Tree Search | Paper📑 Code💻
- A novel framework that seamlessly integrates visuospatial and linguistic domains | Task: Geometry and Spatial Reasoning
- 25.04 Improved Visual-Spatial Reasoning via R1-Zero-Like Training | Paper📑 Code💻
- Incorporate GRPO training for improved visual-spatial reasoning, using the carefully curated VSI-100k dataset. | Task: Video Understanding
- 25.03 Envolving Temporal Reasoning Capability into LMMs via Temporal Consistent Reward | Code💻 Model🤗
- Investigate the potential of GRPO in the video temporal grounding task, which demands precise temporal alignment between visual and linguistic modalities as well as advanced reasoning capabilities | Task: Temporal Grounding
- 25.03 TimeZero: Temporal Video Grounding with Reasoning-Guided LVLM | Paper📑 Code💻 Model🤗
- A reasoning-guided MLLM for temporal video grounding, trained with GRPO. | Task: Temporal Grounding
- 25.03 LLaVA-ST: A Multimodal Large Language Model for Fine-Grained Spatial-Temporal Understanding | Paper📑 Code💻
- A MLLM for fine-grained spatial-temporal multimodal understanding. | Task: Spatial-Temporal Understanding
- 25.03 MetaSpatial: Reinforcing 3D Spatial Reasoning in VLMs for the Metaverse | Code🖥️
- Enhance spatial reasoning in VLMs using GRPO | Task: 3D Spatial Reasoning
- 25.02 Video-R1: Towards Super Reasoning Ability in Video Understanding | Code🖥️
- Integrate deep thinking capabilities into video understanding tasks through the R1 paradigm | Task: Video Counting
- 24.12 TIMEREFINE: Temporal Grounding with Time Refining Video LLM | Paper📑 | Code🖥️
- Enhance Video LLMs to handle the temporal grounding task by modifying the learning objective | Task: Temporal Grounding
- 24.11 (CVPR2025) Number it: Temporal Grounding Videos like Flipping Manga | Paper📑 | Code💻
- Enhances Video-LLMs by overlaying frame numbers onto video frames | Task: Temporal Grounding
- 24.11 TimeMarker: A Versatile Video-LLM for Long and Short Video Understanding with Superior Temporal Localization Ability | Paper📑 | Code💻
- A versatile Video-LLM featuring robust temporal localization abilities | Task: Temporal Grounding and Video QA
- 24.08 (AAAI2025) Grounded Multi-Hop VideoQA in Long-Form Egocentric Videos | Paper📑 | Code💻
- Leverage the world knowledge reasoning capabilities of MLLMs to retrieve temporal evidence in the video with flexible grounding tokens. | Task: Multi-Hop VideoQA
- 24.08 (ICLR2025) TRACE: Temporal Grounding Video LLM via Casual Event Modeling | Paper📑 | Code💻
- Tailored to implement the causal event modeling framework through timestamps, salient scores, and textual captions. | Task: Temporal Grounding
Audio MLLM
- 25.07 Towards Spatial Audio Understanding via Question Answering
- 24.06 (InterSpeech 2024) Can Large Language Models Understand Spatial Audio? |
- 24.02 (ICML 2024)BAT: Learning to Reason about Spatial Sounds with Large Language Models |
Omni MLLM
Math Reasoning
Image MLLM
- 26.02 P1-VL: Bridging Visual Perception and Scientific Reasoning in Physics Olympiads | Paper📑 Code🖥️ Model🤗
- Open-source VLM family for advanced scientific reasoning using curriculum RL and agentic augmentation, achieving the first open-source model winning 12 gold medals at physics olympiad level. | Task: Math
- 26.02 DeepVision-103K: A Visually Diverse, Broad-Coverage, and Verifiable Mathematical Dataset for Multimodal Reasoning | Paper📑 Code🖥️ Dataset🤗
- 103K-sample RLVR training dataset for multimodal K12 mathematical reasoning with diverse topics and rich visual elements, generalizing to general multimodal reasoning tasks. | Task: Math
- 26.02 Vision-DeepResearch: Incentivizing DeepResearch Capability in Multimodal Large Language Models | Paper📑 Code🖥️
- Multimodal deep-research paradigm enabling multi-turn, multi-entity, multi-scale visual and textual search via cold-start supervision and RL. | Task: Math
- 26.02 LaViDa-R1: Advancing Reasoning for Unified Multimodal Diffusion Language Models | Paper📑
- Multimodal reasoning diffusion LM using SFT + multi-task RL with answer-forcing, tree search, and complementary likelihood estimation for visual math reasoning and image editing. | Task: Math
- 26.02 Embed-RL: Reinforcement Learning for Reasoning-Driven Multimodal Embeddings | Paper📑 Code🖥️
- Reasoning-driven multimodal embedding framework using Embedder-Guided RL (EG-RL) to optimize Traceability Chain-of-Thought generation for improved cross-modal semantic consistency. | Task: Math
- 26.01 CogFlow: Bridging Perception and Reasoning through Knowledge Internalization for Visual Mathematical Problem Solving | Paper📑 Project🌐
- Cognitive-inspired three-stage framework (Perception-Internalization-Reasoning) for visual math with MathCog dataset of 120K+ annotations. | Task: Math
- 26.01 MindWatcher: Toward Smarter Multimodal Tool-Integrated Reasoning | Paper📑
- Multimodal tool-integrated reasoning framework enhancing chain-of-thought with tool use for complex math/science problems. | Task: Math
- 26.01 MMFormalizer: Multimodal Autoformalization in the Wild | Paper📑
- Framework for automatically formalizing multimodal mathematical content from images and text into formal representations. | Task: Math
- 25.11 MathSE: Improving Multimodal Mathematical Reasoning via Self-Evolving Iterative Reflection and Reward-Guided Fine-Tuning | Paper📑
- Improves multimodal math reasoning via iterative self-evolution and reward-guided training. | Task: Math
- 25.10 Training Vision-Language Process Reward Models for Test-Time Scaling in Multimodal Reasoning | Paper📑
- Process reward models for scaling multimodal reasoning at test time. | Task: Math
- 25.09 BaseReward: A Strong Baseline for Multimodal Reward Model | Paper📑
- Strong baseline reward model for multimodal RL-based alignment. | Task: Math
- 25.08 MathReal: A Real Scene Benchmark for Evaluating Math Reasoning in MLLMs | Paper📑
- Benchmark for evaluating multimodal math reasoning using real-world scene photographs. | Task: Math
- 25.11 Perceptual-Evidence Anchored Reinforced Learning for Multimodal Reasoning | Paper📑 Code🖥️ Model🤗
- Introduce a perception checklist to anchor RL policy updates in verified visual evidence and prevent hallucinations. | Task: Math
- 25.11 Metis-HOME: Hybrid Optimized Mixture-of-Experts for Multimodal Reasoning | Paper📑 Code🖥️ Model🤗
- Use a mixture-of-experts framework with dynamic routing for balancing complex reasoning and general tasks. | Task: Math
- 25.10 Metis-SPECS: Decoupling Multimodal Learning via Self-distilled Preference-based Cold Start | Paper📑 Code🖥️
- Replace supervised fine-tuning with self-distilled, preference-based cold starts to improve RL generalization. | Task: Math
- 25.09 DeepSketcher: Internalizing Visual Manipulation for Multimodal Reasoning | Paper📑 Code🖥️
- Internalize visual reasoning by directly manipulating visual embeddings using code-rendered trajectories, bypassing external tools and reducing grounding noise. | Task: Math
- 25.07 The Synergy Dilemma of Long-CoT SFT and RL: Investigating Post-Training Techniques for Reasoning VLMs Paper📑 Code🖥️
- a systematic investigation into the distinct roles and interplay of long-CoT SFT and RL across multiple multimodal reasoning benchmarks. | Task: Math
- 25.06 Metis-RISE: RL Incentivizes and SFT Enhances Multimodal Reasoning Model Learning | Paper📑 Code🖥️ Model🤗
- Reverse the training pipeline by first using RL for reasoning exploration, then applying SFT with self-distilled and expert-augmented trajectories for stability and capability enhancement. | Task: Math
- 25.06 SynthRL: Scaling Visual Reasoning with Verifiable Data Synthesis Paper📑 Code🖥️ Model🤗
- A novel framework that enhances the reasoning capabilities of multimodal large language models. | Task: Math
- 25.06 SRPO: Enhancing Multimodal LLM Reasoning via Reflection-Aware Reinforcement Learning Paper📑 Code🖥️ Model🤗
- scale the training data with correctness and distribution guarantees to achieve better performance. | Task: Math
- 25.05 Unsupervised Post-Training for Multi-Modal LLM Reasoning via GRPO Paper📑 Code🖥️
- A Unsupervised Post-Training for Multi-Modal LLM Reasoning via GRPO. | Task: Math
- 25.05 X-Reasoner: Towards Generalizable Reasoning Across Modalities and Domains | Paper📑 Code🖥️
- A training recipe that optimizes the reasoning capability of VLMs with SFT and RL on general-domain text-only data. | Task: Math
- 25.04 NoisyRollout: Reinforcing Visual Reasoning with Data Augmentation | Paper📑 Code🖥️ Model🤗
- Introduces targeted rollout diversity by mixing rollouts from both clean and moderately distorted images, encouraging the model to learn more robust behaviors. | Task: Math
- 25.04 VL-Rethinker: Incentivizing Self-Reflection of Vision-Language Models with Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- Aim to enhance the slow-thinking capabilities of vision-language models using reinforcement learning (without relying on distillation) to advance the SOTA. | Task: Math
- 25.04 SoTA with Less: MCTS-Guided Sample Selection for Data-Efficient Visual Reasoning Self-Improvement | Paper📑 Code🖥️
- Propose a novel way of repurposing Monte Carlo Tree Search (MCTS) to enable effective data filtering. | Task: Math reasoning
- 25.04 GenPRM: Scaling Test-Time Compute of Process Reward Models via Generative Reasoning | Paper📑 Project🌐 Code🖥️
- A generative process reward model that performs explicit COT reasoning with code verification before providing judgment for each reasoning step. | Task: Math
- 25.03 OpenVLThinker: An Early Exploration to Vision-Language Reasoning via Iterative Self-Improvement | Paper📑 Code🖥️ Dataset🤗
- Investigate whether R1-like reasoning capabilities can be successfully integrated into LVLMs and assesses their impact on challenging multimodal reasoning tasks. | Task: Math
- 25.03 R1-VL: Learning to Reason with Multimodal Large Language Models via Step-wise Group Relative Policy Optimization | Paper📑 Code🖥️ Dataset🤗
- Design Step-wise Group Relative Policy Optimization (StepGRPO) that enables MLLMs to self-improve reasoning ability. | Task: Math
- 25.03 LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL | Paper📑 Code🖥️ Dataset🤗
- A two-stage rule-based RL framework that efficiently enhances reasoning capabilities | Task: Math & Sokoban
- 25.03 VisualPRM: An Effective Process Reward Model for Multimodal Reasoning | Paper📑 Code🖥️ Dataset🤗
- Improve the reasoning abilities of existing MLLMs with Best-of-N evaluation strategies | Task: Math & MMMU
- 25.03 R1-Onevision: Advancing Generalized Multimodal Reasoning through Cross-Modal Formalization | Paper📑 Code🖥️ Dataset🤗
- A multimodal reasoning model bridged the gap between multimodal capabilities and reasoning abilities with GRPO | Task: Math
- 25.03 MMR1: Advancing the Frontiers of Multimodal Reasoning | Code🖥️
- a Large Multimodal Model specialized in mathematical tasks using GRPO | Task: Math
- 25.03 Boosting the Generalization and Reasoning of Vision Language Models with Curriculum Reinforcement Learning | Paper📑
- Improve generalization and reasoning of VLMs with GRPO | Task: Detection & Classification & Math
- 25.03 Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models | Paper📑Code🖥️
- Improve reasoning ability of MLLM with GRPO | Task: Math
- 25.03 MM-EUREKA: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning | Paper📑 Code🖥️ Dataset🤗
- Extend large-scale rule-based reinforcement learning to multimodal reasoning | Task: Math
- 25.03 [EasyR1: An Efficient, Scalable, Multi-Modality RL Training Framework] Code🖥️
- A Multimodal GRPO training framework | Task: Math
- 25.02 [Qwen2.5-VL] Qwen2.5-VL Technical Report | Paper📑 Code🖥️ Huggingface🤗
- The latest flagship model of Qwen vision-language series for various multimodal tasks | Task: Reasoning & Understainding * 25.02 Multimodal Open R1 | Code🖥️
- A open-source database for video R1 reproduce. | Task: Math
- 25.02 Boosting Multimodal Reasoning with MCTS-Automated Structured Thinking | Paper📑
- An automated structured thinking paradigm for multimodal reasoning via Monte Carlo Tree Search | Task: Math
- 25.02 MM-Verify: Enhancing Multimodal Reasoning with Chain-of-Thought Verification | Paper📑 Code🖥️
- Enhance multimodal reasoning through longer inference and more robust verification. | Task: Math
- 25.01 Kimi k1.5: Scaling Reinforcement Learning with LLMs (MoonshotAI) | Project🌐
- The latest flagship model of Kimi series for various multimodal tasks | Task: Reasoning & Understainding
- 25.01 Virgo: A Preliminary Exploration on Reproducing o1-like MLLM | Paper📑 Code🖥️ Model🤗
- A o1-like MLLM for multimodal reasoning |Task: Math & MMMU
Chart Rasoning
- 26.03 FireRed-OCR Technical Report | Paper📑
- Framework transforming general VLMs into pixel-precise document parsing experts via three-stage progressive training (pre-alignment, SFT, format-constrained GRPO), achieving 92.94% SOTA on OmniDocBench v1.5. | Task: Document Reasoning
- 26.02 OCR-Agent: Agentic OCR with Capability and Memory Reflection | Paper📑 Code🖥️
- Iterative self-correction framework using Capability Reflection (error diagnosis) and Memory Reflection (avoiding repeated attempts), achieving SOTA on OCRBench v2 without training. | Task: Document Reasoning
- 26.02 OmniOCR: Generalist OCR for Ethnic Minority Languages | Paper📑 Code🖥️
- Universal OCR framework using Dynamic LoRA for low-resource ethnic minority scripts, achieving 39-66% accuracy improvements on Tibetan, Shui, and other scripts. | Task: Document Reasoning
- 26.02 DODO: Discrete OCR Diffusion Models | Paper📑
- Adapts block discrete diffusion for OCR enabling parallel token processing, achieving up to 3× faster inference while maintaining near-SOTA accuracy. | Task: Document Reasoning
- 26.02 PaddleOCR-VL-1.5: Towards a Multi-Task 0.9B VLM for Robust In-the-Wild Document Parsing | Paper📑
- Compact 0.9B VLM for multi-task document parsing in diverse real-world conditions covering OCR, layout understanding, and chart comprehension. | Task: Document Reasoning
- 26.02 ExStrucTiny: A Benchmark for Schema-Variable Structured Information Extraction from Document Images | Paper📑
- Benchmark unifying key entity extraction, relation extraction, and VQA for structured information extraction from document images, evaluating VLMs on schema adaptation and answer localization. | Task: Document Reasoning
- 26.02 MemOCR: Layout-Aware Visual Memory for Efficient Long-Horizon Reasoning | Paper📑
- Layout-aware visual memory mechanisms for MLLMs to improve long-horizon document and OCR reasoning efficiency. | Task: Document Reasoning
- 26.01 ChartVerse: Scaling Chart Reasoning via Reliable Programmatic Synthesis from Scratch | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Scalable chart reasoning framework using Rollout Posterior Entropy; ChartVerse-8B surpasses its teacher model Qwen3-VL-30B. | Task: Chart Reasoning
- 25.10 From Charts to Code: A Hierarchical Benchmark for Multimodal Models | Paper📑
- Benchmark for chart understanding and code generation from charts. | Task: Chart Reasoning
- 25.09 Visual-TableQA: Open-Domain Benchmark for Reasoning over Table Images | Paper📑
- Benchmark for visual question answering and reasoning over table images. | Task: Chart Reasoning
- 25.09 MinerU2.5: A Decoupled Vision-Language Model for Efficient High-Resolution Document Parsing | Paper📑
- Efficient VLM for parsing and understanding high-resolution documents. | Task: Document Reasoning
- 25.09 Visual Programmability: A Guide for Code-as-Thought in Chart Understanding | Paper📑 Code🖥️
- Introduce an adaptive framework that enables VLMs to dynamically choose between code-based and visual reasoning pathways for chart understanding. | Task: Chart Reasoning
- 25.07 Chart-R1: Chain-of-Thought Supervision and Reinforcement for Advanced Chart Reasoner | Paper📑 Code🖥️ Model🤗
- Combine chain-of-thought supervision with reinforcement learning, supported by programmatically synthesized step-by-step reasoning data. | Task: Chart Reasoning
- 25.06 ChartReasoner: Code-Driven Modality Bridging for Long-Chain Reasoning in Chart Question Answering | Paper📑
- Combine chart code generation with long-chain reasoning LLMs to produce detailed reasoning processes. | Task: Chart Reasoning
- 25.05 Point-RFT: Improving Multimodal Reasoning with Visually Grounded Reinforcement Finetuning | Paper📑
- Introduce a visually grounded chain-of-thought (CoT) paradigm, enabling the model to generate CoT reasoning aligned with visual elements. | Task: Chart Reasoning
- 25.04 Bespoke-MiniChart-7B: Pushing The Frontiers Of Open VLMs For Chart Understanding | Project🌐 Model🤗
- Employ a three-stage training process, combining rejection sampling and DPO optimization to enhance out-of-distribution generalization. | Task: Chart Reasoning
- 25.03 MDocAgent: A Multi-Modal Multi-Agent Framework for Document Understanding | Paper📑 Code🖥️
- Integrate text and image retrieval through various agents, enabling collaborative reasoning across modalities. | Task: Document Reasoning
- 24.11 ChartGemma: Visual Instruction-tuning for Chart Reasoning in the Wild | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Generate multi-task instruction-tuning data from real chart images and integrating both COT and POT reasoning pathways. | Task: Chart Reasoning
- 24.09 (ICLR25 Oral) ChartMoE: Mixture of Diversely Aligned Expert Connector for Chart Understanding | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Utilize diverse chart-text aligned tasks (chart -> table/json/python-code) to augment chart understanding and reasoning. | Task: Chart Reasoning
- 24.09 ChartX & ChartVLM: A Versatile Benchmark and Foundation Model for Complicated Chart Reasoning | Project🌐 Paper📑 Code🖥️
- Offer a new perspective on handling chart reasoning tasks that strongly depend on interpretable patterns. | Task: Chart Reasoning
- 24.07 (EMNLP24) Multimodal Self-Instruct: Synthetic Abstract Image and Visual Reasoning Instruction Using Language Model | Paper📑 Project🌐 Code🖥️ Dataset🤗
- A multi-modal self-instruct, utilizing large language models and their code capabilities to synthesize massive abstract images and visual reasoning instructions across daily scenarios. | Task: Chart Reasoning
- 24.04 (EMNLP24) TinyChart: Efficient Chart Understanding with Visual Token Merging and Program-of-Thoughts Learning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Employ PoT learning for numerical reasoning and Vision Token Merging to compress visual features from high-resolution images. | Task: Chart Reasoning
- 24.04 (MM24) OneChart: Purify the Chart Structural Extraction via One Auxiliary Token | Paper📑 Project🌐 Code🖥️ Model🤗
- Introduce an auxiliary token and decoder combined with a customized L1 loss to enhance the reliability of structured and numerical information extraction. | Task: Chart Reasoning
- 24.04 (MM24) NovaChart: A Large-scale Dataset towards Chart Understanding and Generation of Multimodal Large Language Models | Paper📑 Code🖥️ Dataset🤗
- Construct a large-scale dataset for chart understanding and generation, covering 18 different chart types and 15 unique tasks. | Task: Chart Reasoning
- 24.02 (ACL24) ChartAssisstant: A Universal Chart Multimodal Language Model via Chart-to-Table Pre-training and Multitask Instruction Tuning | Paper📑 Code🖥️ Dataset🤗
- Use large-scale chart data to align and instruction tuning | Task: Chart Reasoning
- 23.11 ChartLlama: A Multimodal LLM for Chart Understanding and Generation | Paper📑 Project🌐 Code🖥️ Model🤗 Dataset🤗
- Generate a diverse and high-quality instruction-tuning dataset using GPT-4, and use LLaVA for unified multi-task training. | Task: Chart Reasoning
- 23.10 (EMNLP23) UniChart: A Universal Vision-language Pretrained Model for
Chart Comprehension and Reasoning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Pretrains on a large and diverse chart dataset, explicitly modeling visual elements and structures. | Task: Chart Reasoning
Benchmark
- 25.11 (EMNLP25) ChartM3: A Multi-Stage Code-Driven Pipeline for Constructing Multi-Dimensional and Multi-Step Visual Reasoning Data in Chart Comprehension | Paper📑
- Provide an evaluation set of 2,871 high-quality samples covering 62 chart types and 60 real-world scenarios, focusing on multi-dimensional and multi-step visual reasoning and complex business analysis. | Task: Chart Reasoning
- 25.05 ChartMuseum: Testing Visual Reasoning Capabilities of Large Vision-Language Models | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Feature real-world chart images and four distinct question types that assess textual, visual, combined, and synthesis reasoning abilities. | Task: Chart Reasoning
- 25.04 CHARTQAPRO : A More Diverse and Challenging Benchmark for Chart Question Answering | Paper📑 Code🖥️ Dataset🤗
- Introduce a diverse benchmark with 1,341 charts and 1,948 questions covering various chart types and question formats, designed to rigorously evaluate the chart reasoning capabilities of large vision-language models in real-world scenarios. | Task: Chart Reasoning
- 25.01 (AAAI25) EvoChart: A Benchmark and a Self-Training Approach Towards Real-World Chart Understanding | Paper📑 Code🖥️ Dataset🤗
- Feature 650 real-world charts, 1,250 expert-curated questions, and strict and flexible automatic evaluation metrics to assess chart comprehension abilities of VLMs in practical scenarios. | Task: Chart Reasoning
- 24.06 (NIPS24) CharXiv: Charting Gaps in Realistic Chart Understanding in Multimodal LLMs | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Focus on real and complex charts from arXiv papers, covering eight major domains. All content is expert-curated and verified, with evaluation using GPT-4o scoring and binary correctness metrics. | Task: Chart Reasoning
- 24.06 (VRISP25) ChartBench: A Benchmark for Complex Visual Reasoning in Charts | Paper📑 Project🌐 Code🖥️ Dataset🤗
- Cover 9 major categories and 42 subcategories of charts without data point annotations, emphasizing numerical extraction ability. | Task: Chart Reasoning
- 24.04 (NAACL24) MMC: Advancing Multimodal Chart Understanding with Large-scale Instruction Tuning | Paper📑 Code🖥️ Dataset🤗
- Propose a comprehensive human-annotated benchmark with nine distinct tasks evaluating reasoning capabilities over various charts, and support both GPT-4 scoring and multiple-choice exact matching. | Task: Chart Reasoning
- 22.05 (ACL22) ChartQA: A Benchmark for Question Answering about Charts with Visual and Logical Reasoning | Paper📑 Code🖥️ Dataset🤗
- Use real-world charts and open-ended questions to evaluate chart understanding, reasoning, and data extraction, with relaxed accuracy as the metric. | Task: Chart Reasoning
Visual-Audio Generation
Image MLLM
- 26.02 DeepGen 1.0: A Lightweight Unified Multimodal Model for Advancing Image Generation and Editing | Paper📑 Code🖥️ Model🤗
- Lightweight 5B unified model for image generation and editing using hierarchical feature extraction, learnable think tokens, and MR-GRPO reinforcement learning, outperforming much larger models. | Task: Image Generation
- 26.02 UniWeTok: An Unified Binary Tokenizer with Codebook Size 2^128 for Unified Multimodal Large Language Model | Paper📑 Code🖥️
- Unified discrete tokenizer with massive binary codebook (2^128) for high-fidelity image reconstruction and generation in multimodal LLMs, achieving FID 1.38 with lower training compute. | Task: Image Generation
- 26.02 UniReason 1.0: A Unified Reasoning Framework for World Knowledge Aligned Image Generation and Editing | Paper📑 Code🖥️ Model🤗
- Integrates text-to-image generation and editing through dual reasoning with world knowledge planning and visual refinement on reasoning-intensive benchmarks. | Task: Image Generation
- 26.02 Generated Reality: Human-centric World Simulation using Interactive Video Generation | Paper📑 Project🌐
- Human-centric video world model conditioned on tracked head and hand poses via bidirectional video diffusion for dexterous XR interactions. | Task: Image/Video Generation
- 26.01 Think-Then-Generate: Reasoning-Aware Text-to-Image Diffusion with LLM Encoders | Paper📑 Code🖥️
- "Think-then-generate" paradigm where LLM encoders reason about prompts before image generation using Dual-GRPO reinforcement optimization. | Task: Image Generation
- 26.01 Re-Align: Structured Reasoning-guided Alignment for In-Context Image Generation and Editing | Paper📑 Code🖥️
- Bridges multimodal understanding and image generation via In-Context Chain-of-Thought (IC-CoT) with RL-based training. | Task: Image Generation & Editing
- 26.01 Unified Thinker: A General Reasoning Modular Core for Image Generation | Paper📑
- General reasoning modular core enhancing image generation models with chain-of-thought reasoning capabilities. | Task: Image Generation
- 25.12 REASONEDIT: Towards Reasoning-Enhanced Image Editing Models | Paper📑
- Enhances image editing models with explicit reasoning capabilities. | Task: Image Editing
- 25.12 EditThinker: Unlocking Iterative Reasoning for Any Image Editor | Paper📑
- Enables iterative reasoning in image editing through a reasoning-aware framework. | Task: Image Editing
- 25.11 IE-Critic-R1: Advancing the Explanatory Measurement of Text-Driven Image Editing for Human Perception Alignment | Paper📑 Code🖥️ Model🤗 Dataset🤗 ColdStart SFT🤗
- IE-Critic-R1 treats image editing quality assessment as a reasoning task and implement "R1 moment" (longer reasoning thoughts, better performance). It is a pointwise, generative reward model, leveraging Chain-of-Thought (CoT) reasoning SFT and RLVR to provide accurate, human-aligned evaluations of image editing. | Task: Image Editing Quality Asssessment
- 25.05 T2I-R1: Reinforcing Image Generation with Collaborative Semantic-level and Token-level CoT | Paper📑 Code🖥️
- A novel reasoning-enhanced text-to-image generation model powered by RL with a bi-level CoT reasoning process | Task: Video Generation
- 25.03 GoT: Unleashing Reasoning Capability of Multimodal Large Language Model for Visual Generation and Editing | Paper📑
- A paradigm that enables generation and editing through an explicit language reasoning process before outputting images | Task: Image Generation
- 25.03 Unified Reward Model for Multimodal Understanding and Generation | Paper📑 Code🖥️ Dataset🤗
- Improve MLLM's understanding and generation ability with DPO | Task: VQA & Generation
- 25.01 (CVPR25) Can We Generate Images with CoT? Let's Verify and Reinforce Image Generation Step by Step | Paper📑 Code🖥️ Model🤗
- The first comprehensive investigation of the potential of CoT reasoning to enhance autoregressive image generation. | Task: Image Generation
- 24.12 EVLM: Self-Reflective Multimodal Reasoning for Cross-Dimensional Visual Editing | Paper📑
- A system designed to interpret such instructions in conjunction with reference visuals, producing precise and context-aware editing prompts. | Task: Image Generation
Video MLLM
- 26.02 SkyReels-V4: Multi-modal Video-Audio Generation, Inpainting and Editing model | Paper📑
- Unified multimodal video foundation model enabling simultaneous video+audio generation, editing, and inpainting via dual-stream architecture, supporting 1080p/32FPS/15s with synchronized audio. | Task: Video Generation
- 26.03 Helios: Real Real-Time Long Video Generation Model | Paper📑 Code🖥️ Model🤗
- 14B autoregressive diffusion model achieving real-time video generation at 19.5 FPS on a single H100 GPU while supporting minute-scale synthesis without conventional anti-drifting heuristics. | Task: Video Generation
- 26.03 DreamWorld: Unified World Modeling in Video Generation | Paper📑
- Unified world modeling framework in video generation with representation alignment for improved physical consistency and scene understanding. | Task: Video Generation
- 26.03 RealWonder: Real-Time Physical Action-Conditioned Video Generation | Paper📑 Project🌐
- First real-time system for action-conditioned video generation using physics simulation as intermediate bridge, achieving 13.2 FPS at 480×832 for interactive exploration of forces and robot actions. | Task: Video Generation
- 26.02 AnchorWeave: World-Consistent Video Generation with Retrieved Local Spatial Memories | Paper📑 Code🖥️
- Addresses long-term video generation consistency using multiple local geometric memories and multi-anchor weaving controller for camera-controllable long-horizon scene generation. | Task: Video Generation
- 26.02 OneVision-Encoder: Codec-Aligned Sparsity as a Foundational Principle for Multimodal Intelligence | Paper📑 Code🖥️ Model🤗
- Vision encoder applying codec-aligned sparsity to focus on 3.1%-25% of signal-rich patches, outperforming Qwen3-ViT and SigLIP2 across 16 benchmarks with 4.1% average improvement on video understanding. | Task: Video Understanding
- 26.02 CoPE-VideoLM: Codec Primitives For Efficient Video Language Models | Paper📑
- Uses video codec primitives (motion vectors and residuals) instead of dense per-frame embeddings, reducing time-to-first-token by up to 86% and token usage by up to 93% across 14 video benchmarks. | Task: Video Understanding
- 26.02 Solaris: Building a Multiplayer Video World Model in Minecraft | Paper📑 Code🖥️ Model🤗
- Multiplayer video world model for consistent multi-view observations in coordinated multi-agent Minecraft environments using Checkpointed Self Forcing technique. | Task: Video Generation
- 26.02 MOVA: Towards Scalable and Synchronized Video-Audio Generation | Paper📑 Code🖥️ Model🤗
- Open-source 32B MoE model generating high-quality synchronized audio-visual content including lip-synced speech, environment sounds, and music from image-text inputs. | Task: Video-Audio Generation
- 25.11 Kandinsky 5.0: A Family of Foundation Models for Image and Video Generation | Paper📑
- Foundation model family for image and video generation. | Task: Video Generation
- 25.11 Planning with Sketch-Guided Verification for Physics-Aware Video Generation | Paper📑
- Physics-aware video generation with sketch-based planning and verification. | Task: Video Generation
- 25.10 PhysMaster: Mastering Physical Representation for Video Generation via RL | Paper📑
- Physical reasoning for video generation with reinforcement learning. | Task: Video Generation
- 25.02 C-Drag:Chain-of-Thought Driven Motion Controller for Video Generation | Paper📑 Code🖥️ Dataset🤗
- A Chain-of-Thought-based motion controller for controllable video generation | Task: Video Generation
Audio MLLM
- 26.02 AVERE: Improving Audiovisual Emotion Reasoning with Preference Optimization | Paper📑 Dataset🤗
- AVEm-DPO preference optimization improves audiovisual emotion reasoning in MLLMs by aligning responses with audiovisual cues and reducing text-prior hallucinations. | Task: Audio-Visual Reasoning
- 26.02 EgoAVU: Egocentric Audio-Visual Understanding | Paper📑 Dataset🤗
- Scalable data engine and 3M-sample dataset for egocentric audio-visual understanding, enabling up to 113% performance improvement on joint audio-visual reasoning tasks. | Task: Audio-Visual Reasoning
- 26.01 LTX-2: Efficient Joint Audio-Visual Foundation Model | Paper📑 Code🖥️ Model🤗
- Open-source 14B+5B asymmetric dual-stream audiovisual diffusion model generating synchronized video and audio with bidirectional cross-attention. | Task: Audio-Visual Generation
- 25.11 UniAVGen: Unified Audio and Video Generation with Asymmetric Cross-Modal Interactions | Paper📑
- Unified audio-video generation using cross-modal interactions. | Task: Audio-Visual Generation
- 25.11 Harmony: Harmonizing Audio and Video Generation through Cross-Task Synergy | Paper📑
- Harmonizes audio and video generation via cross-task synergy. | Task: Audio-Visual Generation
- 25.06 ThinkSound: Chain-of-Thought Reasoning in Multimodal Large Language Models for Audio Generation and Editing
Reasoning with Agent/Tool
- 26.02 Mobile-Agent-v3.5: Multi-platform Fundamental GUI Agents | Paper📑 Code🖥️ Model🤗
- GUI-Owl-1.5 multi-platform GUI agent family achieving SOTA on GUI automation (56.5 OSWorld, 71.6 AndroidWorld) and grounding (80.3 ScreenSpotPro) via MRPO multi-platform RL. | Task: GUI Agent
- 26.02 GUI-Libra: Training Native GUI Agents to Reason and Act with Action-aware Supervision and Partially Verifiable RL | Paper📑 Code🖥️ Model🤗
- Trains open-source GUI agents using action-aware SFT (81K curated dataset) and conservative RL with KL regularization for web and mobile tasks. | Task: GUI Agent
- 26.02 PyVision-RL: Forging Open Agentic Vision Models via RL | Paper📑 Code🖥️ Model🤗
- RL framework for open-weight multimodal agents using oversampling-filtering-ranking rollout; releases PyVision-Image-7B and PyVision-Video-7B for tool-augmented reasoning. | Task: Agent/Tool Use
- 26.02 Computer-Using World Model | Paper📑
- World model for desktop software predicting UI state changes via two-stage factorization to help agents simulate candidate actions before execution. | Task: GUI Agent
- 26.02 V-Retrver: Evidence-Driven Agentic Reasoning for Universal Multimodal Retrieval | Paper📑 Code🖥️ Model🤗
- Reformulates multimodal retrieval as an agentic reasoning process where an MLLM selectively acquires visual evidence via external tools, achieving 23% average improvement. | Task: Agent/Tool Use
- 26.02 Reasoning-Augmented Representations for Multimodal Retrieval | Paper📑 Code🖥️
- Data-centric framework externalizing reasoning before retrieval by using VLMs to densely caption visual evidence and resolve ambiguous multimodal queries. | Task: Agent/Tool Use
- 26.02 WebArbiter: A Principle-Guided Reasoning Process Reward Model for Web Agents | Paper📑 Code🖥️
- Reasoning-first WebPRM formulating reward modeling as text generation to improve web navigation through structured justifications and preference verdicts (ICLR 2026). | Task: GUI Agent
- 26.02 Sparse Video Generation Propels Real-World Beyond-the-View Vision-Language Navigation | Paper📑 Code🖥️
- SparseVideoNav uses video generation for sparse future planning in beyond-the-view VLN tasks, achieving 27× speed-up and 2.5× higher success rate over LLM baselines. | Task: Visual Reasoning Agent
- 26.02 WebWorld: A Large-Scale World Model for Web Agent Training | Paper📑
- Open-web simulator trained on 1M+ interactions enabling long-horizon reasoning for web agents; models trained on WebWorld-synthesized trajectories show +9.2% improvement on WebArena. | Task: GUI Agent
- 26.02 AutoWebWorld: Synthesizing Infinite Verifiable Web Environments via Finite State Machines | Paper📑
- Synthesizes controllable web environments as FSMs translated to interactive websites by coding agents for automated trajectory generation at $0.04/trajectory, with 7B agent outperforming baselines on WebVoyager. | Task: GUI Agent
- 26.02 MMA: Multimodal Memory Agent | Paper📑 Code🖥️
- Improves long-horizon multimodal agent performance via dynamic memory reliability scoring and introduces the "Visual Placebo Effect" with MMA-Bench for evaluating belief dynamics. | Task: Multimodal Agent
- 26.03 CoVe: Training Interactive Tool-Use Agents via Constraint-Guided Verification | Paper📑
- Post-training data synthesis framework for interactive tool-use agents using constraint-guided verification; compact 4B model achieves success rates competitive with 17× larger models on τ²-bench. | Task: Tool Use Agent
- 26.03 AgentVista: Evaluating Multimodal Agents in Ultra-Challenging Realistic Visual Scenarios | Paper📑
- Benchmark evaluating multimodal agents in ultra-challenging realistic visual scenarios requiring complex visual reasoning and multi-step planning. | Task: Multimodal Agent
- 26.01 AdaReasoner: Dynamic Tool Orchestration for Iterative Visual Reasoning | Paper📑 Code🖥️ Model🤗
- Multimodal model family learning tool usage as a reasoning skill via Tool-GRPO, +24.9% improvement surpassing GPT-4 on visual reasoning benchmarks. | Task: Visual Reasoning with Tools
- 26.01 SenseNova-MARS: Empowering Multimodal Agentic Reasoning and Search via Reinforcement Learning | Paper📑
- Multimodal agentic reasoning and search framework using RL to empower visual reasoning with agent capabilities. | Task: Multimodal Agentic Reasoning
- 26.01 EvoCUA: Evolving Computer Use Agents via Learning from Scalable Synthetic Experience | Paper📑 Code🖥️ Model🤗
- SOTA computer-use agent (56.7% OSWorld) using autonomous task generation and iterative evolving learning with self-correction. | Task: GUI Agent
- 26.01 DocDancer: Towards Agentic Document-Grounded Information Seeking | Paper📑
- Agentic framework for document-grounded multimodal information seeking and reasoning. | Task: Document Reasoning Agent
- 26.01 ShowUI-pi: Flow-based Generative Models as GUI Dexterous Hands | Paper📑
- Flow-based generative models applied as GUI interaction agents with visual reasoning capabilities. | Task: GUI Agent
- 26.01 PersonalAlign: Hierarchical Implicit Intent Alignment for Personalized GUI Agent | Paper📑
- Personalized GUI agent aligning hierarchical implicit user intent with long-term user-centric records. | Task: GUI Agent
- 25.12 Step-GUI Technical Report | Paper📑
- Step-by-step GUI agent with visual understanding. | Task: GUI Agent
- 25.12 MAI-UI Technical Report: Real-World Centric Foundation GUI Agents | Paper📑
- Foundation model for real-world GUI agent interaction with visual grounding. | Task: GUI Agent
- 25.11 Agent-Omni: Test-Time Multimodal Reasoning via Model Coordination for Understanding Anything
- 25.11 DeepEyesV2: Toward Agentic Multimodal Model | Paper📑
- Agentic multimodal model with tool-use and reasoning capabilities. | Task: Multimodal Agent
- 25.11 GeoVista: Web-Augmented Agentic Visual Reasoning for Geolocalization | Paper📑
- Combines visual reasoning with web augmentation for agentic geolocalization. | Task: Visual Reasoning Agent
- 25.10 AudioToolAgent: An Agentic Framework for Audio-Language Models | Paper📑
- 25.10 GUI-KV: Efficient GUI Agents via KV Cache with Spatio-Temporal Awareness | Paper📑
- Efficient GUI interaction agents using visual understanding with spatio-temporal KV cache. | Task: GUI Agent
- 25.09 UItron: Foundational GUI Agent with Advanced Perception and Planning | Paper📑
- Multimodal agent for GUI understanding and interaction. | Task: GUI Agent
- 25.09 BTL-UI: Blink-Think-Link Reasoning Model for GUI Agent | Paper📑
- Reasoning model for GUI agent visual understanding and interaction. | Task: GUI Agent
- 25.08 Think Before You Segment: An Object-aware Reasoning Agent for Referring Audio-Visual Segmentation
- 25.08 OS Agents: A Survey on MLLM-based Agents for General Computing Devices Use | Paper📑
- Survey of MLLM-based agents that operate computing devices via visual understanding. | Task: GUI Agent
- 25.08 InfiGUI-G1: Advancing GUI Grounding with Adaptive Exploration Policy Optimization | Paper📑
- Multimodal agent for GUI understanding with visual grounding and adaptive exploration. | Task: GUI Agent
- 25.08 CODA: Coordinating the Cerebrum and Cerebellum for a Dual-Brain Computer Use Agent | Paper📑
- Dual-brain architecture for multimodal computer-use agent with decoupled RL. | Task: GUI Agent
- 25.06 Ego-R1: Chain-of-Tool-Thought for Ultra-Long Egocentric Video Reasoning|Paper📑 Code🖥️ Project🌐
- 25.05 ReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning | Paper📑 Code🖥️
- 25.05 Reinforcement Learning for Long-Horizon Interactive LLM Agents|Paper📑
- 25.05 RAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning |Paper📑 Code🖥️ Project🌐
- 25.05 Nemotron-Research-Tool-N1: Exploring Tool-Using Language Models with Reinforced Reasoning | Paper📑 Code🖥️
- 25.05 Agent RL Scaling Law: Spontaneous Code Execution for Mathematical Problem Solving| Paper📑 Code🖥️
- 25.04 ToolRL: Reward is All Tool Learning Needs|Paper📑 Code🖥️
- 25.04 Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning | Paper📑 Code🖥️
- 25.04 Acting Less is Reasoning More! Teaching Model to Act Efficiently
- 25.04 Agentic Reasoning and Tool Integration for LLMs via Reinforcement Learning | Paper📑
- 25.04 DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments |Paper📑 Code🖥️
- 25.03 TORL: Scaling Tool-Integrated RL | Paper📑 Code🖥️
- 25.03 R1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning | Paper📑
- 25.02 (CVPR25)Enhancing Video-LLM Reasoning via Agent-of-Thoughts Distillation | Paper📑
- 24.12 (ECCV24) VideoAgent: A Memory-augmented Multimodal Agent for Video Understanding | Paper📑 Code🖥️ Project🌐
- Explore how reconciling several foundation models with a novel unified memory mechanism could tackle the challenging video understanding problem | Task: Video captioning & QA
Medical Reasoning
Image MLLM
- 26.02 MediX-R1: Open Ended Medical Reinforcement Learning | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Open-ended RL framework for medical MLLMs enabling free-form clinical answers via Group-Based RL with composite rewards; 8B model outperforms 27B MedGemma with ~51K training samples. | Task: Medical Reasoning
- 26.02 Baichuan-M3: Modeling Clinical Inquiry for Reliable Medical Decision-Making | Paper📑 Code🖥️ Model🤗
- Medical LLM shifting from passive Q&A to active clinical-grade decision support via proactive information acquisition, long-horizon reasoning, and hallucination suppression, achieving SOTA on HealthBench. | Task: Medical Reasoning
- 26.02 MedSAM-Agent: Empowering Interactive Medical Image Segmentation with Multi-turn Agentic Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- Reformulates medical image segmentation as multi-step decision-making using hybrid prompting and two-stage training with process rewards for autonomous reasoning. | Task: Medical Reasoning
- 26.02 Hepato-LLaVA: An Expert MLLM for Hepatocellular Pathology Analysis on Whole Slide Images | Paper📑 Project🌐
- Specialized MLLM for hepatocellular carcinoma diagnosis with Sparse Topo-Pack Attention modeling tissue topology; includes HepatoPathoVQA (33K expert-validated Q&A pairs). | Task: Medical Reasoning
- 26.02 MedCLIPSeg: Probabilistic Vision-Language Adaptation for Medical Image Segmentation | Paper📑 Code🖥️ Model🤗
- Adapts CLIP for medical image segmentation via Probabilistic Vision-Language Adapter with uncertainty-aware attention, tested across 16 datasets spanning 5 modalities and 6 organs. | Task: Medical Reasoning
- 26.02 MedXIAOHE: A Comprehensive Recipe for Building Medical MLLMs | Paper📑
- Medical VLM combining entity-aware continual pretraining for rare diseases, RL for expert-level reasoning, and tool-augmented agentic training for multi-step diagnostic reasoning with reduced hallucination. | Task: Medical Reasoning
- 26.02 ClinAlign: Scaling Healthcare Alignment from Clinician Preference | Paper📑 Code🖥️ Model🤗
- Two-stage LLM alignment using physician-verified examples and distilled clinical principles, with a 30B model activating 3B parameters at inference achieving SOTA on medical benchmarks. | Task: Medical Reasoning
- 26.02 Uncertainty-Aware Vision-Language Segmentation for Medical Imaging | Paper📑 Code🖥️
- Multimodal segmentation with Modality Decoding Attention Blocks (MoDAB) and Spectral-Entropic Uncertainty Loss for medical image segmentation from radiological images and clinical text. | Task: Medical Reasoning
- 26.03 When Does RL Help Medical VLMs? Disentangling Vision, SFT, and RL Gains | Paper📑 Project🌐
- Controlled study disentangling vision, SFT, and RL effects in medical VLMs, proposing a boundary-aware recipe: bridge support first, then sharpen with RL for optimal medical reasoning. | Task: Medical Reasoning
- 26.01 UniX: Unifying Autoregression and Diffusion for Chest X-Ray Understanding and Generation | Paper📑 Code🖥️ Model🤗
- Unified medical foundation model combining autoregressive understanding and diffusion generation for chest X-rays, +46.1% in understanding. | Task: Medical Image Understanding & Generation
- 25.12 OralGPT-Omni: A Versatile Dental Multimodal Large Language Model | Paper📑
- Versatile dental MLLM for oral health diagnosis and reasoning across modalities. | Task: Medical Reasoning
- 25.12 DentalGPT: Incentivizing Multimodal Complex Reasoning in Dentistry | Paper📑
- Incentivizes complex multimodal reasoning for dental diagnosis and treatment. | Task: Medical Reasoning
- 25.12 Colon-X: Advancing Intelligent Colonoscopy from Multimodal Understanding to Clinical Reasoning | Paper📑
- Advances colonoscopy with multimodal understanding and clinical reasoning capabilities. | Task: Medical Reasoning
- 25.10 M3Retrieve: Benchmarking Multimodal Retrieval for Medicine | Paper📑
- Multimodal retrieval benchmark for medical domain. | Task: Medical Reasoning
- 25.09 MedVista3D: Vision-Language Modeling for Reducing Diagnostic Errors in 3D CT Disease Detection | Paper📑
- VLM for medical 3D CT analysis to reduce diagnostic errors. | Task: Medical Reasoning
- 25.08 MedBLINK: Probing Basic Perception in Multimodal Language Models for Medicine | Paper📑
- Tests multimodal LLMs on basic medical visual perception tasks. | Task: Medical Reasoning
Audio MLLM
- 25.04 (ICASSP 2025) AuscMLLM: Bridging Classification and Reasoning in Heart Sound Analysis with a Multimodal Large Language Model |
- 24.09 (JBHI 2024) Multi-Task Learning for Audio-Based Infant Cry Detection and Reasoning |
Omni MLLM
- 25.06 (ACL 2025) MAM: Modular Multi-Agent Framework for Multi-Modal Medical Diagnosis via Role-Specialized Collaboration | Paper📑 Code🖥️
Embodied Reasoning
-
26.02 VLANeXt: Recipes for Building Strong VLA Models | Paper📑 Code🖥️ Model🤗
- Systematically identifies 12 key design findings across foundational components for VLA models, yielding SOTA simulation and real-world benchmark performance (CVPR 2026). | Task: Robot Control
-
26.02 SimVLA: A Simple VLA Baseline for Robotic Manipulation | Paper📑 Code🖥️ Model🤗
- Minimal VLA baseline strictly decoupling perception from control with standard VL backbone, achieving SOTA on simulation benchmarks with only 0.5B parameters. | Task: Robotic Manipulation
-
26.02 GigaBrain-0.5M*: a VLA That Learns From World Model-Based Reinforcement Learning | Paper📑 Code🖥️ Project🌐
- VLA trained via world model-based RL (RAMP) on 10,000+ hours of robot data, achieving ~30% improvement on challenging tasks like laundry folding and espresso preparation. | Task: Robotic Manipulation
-
26.02 Recurrent-Depth VLA: Implicit Test-Time Compute Scaling of Vision-Language-Action Models via Latent Iterative Reasoning | Paper📑 Code🖥️ Project🌐
- Recurrent VLA using latent iterative refinement instead of chain-of-thought tokens to adaptively scale compute at inference, achieving 0%→90%+ task success with 4 iterations. | Task: Robotic Manipulation
-
26.02 VLA-JEPA: Enhancing Vision-Language-Action Model with Latent World Model | Paper📑 Code🖥️ Model🤗
- JEPA-style pretraining for VLA policies predicting future latent states from current observations, improving robustness to camera motion and irrelevant backgrounds. | Task: Robotic Manipulation
-
26.02 DreamDojo: A Generalist Robot World Model from Large-Scale Human Videos | Paper📑 Model🤗 Project🌐
- Foundation world model trained on 44k hours of egocentric human video enabling teleoperation, policy evaluation, and model-based planning for dexterous robotics at 10.81 FPS. | Task: Robotic Manipulation
-
26.02 ABot-N0: Technical Report on the VLA Foundation Model for Versatile Embodied Navigation | Paper📑 Code🖥️ Project🌐
- Unified VLA navigation model with hierarchical Brain-Action architecture achieving SOTA on 7 benchmarks across 5 navigation task types, trained on 16.9M expert trajectories. | Task: Embodied Navigation
-
26.02 TIC-VLA: A Think-in-Control Vision-Language-Action Model for Robot Navigation in Dynamic Environments | Paper📑 Code🖥️ Project🌐
- Latency-aware VLA framework modeling delayed semantic reasoning during action generation via delayed semantic-control interface for real-time navigation. | Task: Embodied Navigation
-
26.02 QuantVLA: Scale-Calibrated Post-Training Quantization for Vision-Language-Action Models | Paper📑 Code🖥️
- Training-free PTQ framework for VLA models combining selective quantization, attention temperature matching, and output head balancing, achieving ~70% memory savings (CVPR 2026). | Task: Robot Control
-
26.02 FRAPPE: Infusing World Modeling into Generalist Policies via Multiple Future Representation Alignment | Paper📑 Code🖥️ Model🤗
- Improves world-awareness in robotic policies via parallel progressive latent alignment with visual foundation models, reducing error accumulation in multi-step prediction. | Task: Robotic Manipulation
-
26.02 TactAlign: Human-to-Robot Policy Transfer via Tactile Alignment | Paper📑 Project🌐
- Cross-embodiment tactile alignment using rectified flow for zero-shot transfer on contact-rich manipulation tasks including pivoting, insertion, and lid closing. | Task: Robotic Manipulation
-
26.02 World Guidance: World Modeling in Condition Space for Action Generation | Paper📑 Project🌐
- WoG maps predicted future observations into compact condition representations for fine-grained action generation, validated across simulation and real-world robot environments. | Task: Robot Control
-
26.02 Green-VLA: Staged Vision-Language-Action Model for Generalist Robots | Paper📑 Code🖥️
- Five-stage VLA framework for real-world robot deployment achieving generalization across embodiments via multimodal training and RL, reaching 69.5% success on ALOHA Table-Cleaning. | Task: Robotic Manipulation
-
26.02 Learning from Trials and Errors: Reflective Test-Time Planning for Embodied LLMs | Paper📑 Code🖥️
- Reflective Test-Time Planning with reflection-in-action and reflection-on-action enabling long-horizon credit assignment in robot decision-making. | Task: Embodied Reasoning
-
26.02 RISE: Self-Improving Robot Policy with Compositional World Model | Paper📑
- Addresses VLA brittleness in contact-rich manipulation using a compositional world model to predict multi-view futures and evaluate imagined outcomes, achieving +35-45% gains across real-world tasks. | Task: Robotic Manipulation
-
26.02 chi_0: Resource-Aware Robust Manipulation via Taming Distributional Inconsistencies | Paper📑 Code🖥️ Model🤗
- Resource-efficient robotic manipulation using model arithmetic weight-space merging and stage-aware advantage estimation for dual-arm garment tasks, achieving 250% higher success than pi_0.5. | Task: Robotic Manipulation
-
26.02 EgoHumanoid: Unlocking In-the-Wild Loco-Manipulation with Robot-Free Egocentric Demonstration | Paper📑
- Enables humanoid loco-manipulation via co-training VLA policies using abundant egocentric human demonstrations with limited robot data, achieving 51% improvement over robot-only baselines. | Task: Robotic Manipulation
-
26.02 MolmoSpaces: A Large-Scale Open Ecosystem for Robot Navigation and Manipulation | Paper📑 Code🖥️
- Open ecosystem with 230k+ diverse indoor environments and 130k annotated assets supporting MuJoCo/Isaac/ManiSkill, with 8 benchmark tasks and strong sim-to-real correlation (R=0.96). | Task: Robot Simulation
-
26.02 ABot-M0: VLA Foundation Model for Robotic Manipulation with Action Manifold Learning | Paper📑 Code🖥️ Model🤗
- Unified robotic manipulation framework standardizing 6M+ trajectories and introducing Action Manifold Learning (AML) for improved action prediction on low-dimensional manifolds. | Task: Robotic Manipulation
-
26.02 RLinf-Co: Reinforcement Learning-Based Sim-Real Co-Training for VLA Models | Paper📑
- RL-based sim-real co-training for VLA policies using two-stage warm-start SFT + RL fine-tuning with auxiliary supervised loss, achieving +24% on OpenVLA and +20% on pi_0.5 in real-world success. | Task: Robotic Manipulation
-
26.02 Xiaomi-Robotics-0: An Open-Sourced Vision-Language-Action Model with Real-Time Execution | Paper📑 Code🖥️
- Open-source VLA combining large-scale cross-embodiment pretraining with asynchronous execution for real-time deployment, achieving SOTA on simulation benchmarks with consumer-grade GPU compatibility. | Task: Robotic Manipulation
-
26.02 GeneralVLA: Generalizable Vision-Language-Action Models with Knowledge-Guided Trajectory Planning | Paper📑 Code🖥️
- Hierarchical VLA for zero-shot robotic manipulation via affordance segmentation, 3D trajectory planning, and 3D-aware control policy, outperforming VoxPoser without real-world demonstrations. | Task: Robotic Manipulation
-
26.02 RynnBrain: Open Embodied Foundation Models | Paper📑 Code🖥️ Model🤗 Dataset🤗
- Open-source spatiotemporal foundation model unifying perception, reasoning, and planning for embodied intelligence, outperforming existing models on 20 embodied benchmarks. | Task: Embodied Reasoning
-
26.02 Learning Humanoid End-Effector Control for Open-Vocabulary Visual Loco-Manipulation | Paper📑
- HERO enables humanoid robots to manipulate diverse real-world objects using inverse kinematics and neural forward model, reducing end-effector tracking error 3.2x for reliable surface manipulation. | Task: Robotic Manipulation
-
26.02 World Action Models are Zero-shot Policies | Paper📑 Code🖥️
- DreamZero uses video diffusion as a World Action Model (WAM) for robot skill generalization with 2x improvement in novel environments at real-time 7Hz closed-loop control. | Task: Robotic Manipulation
-
26.02 Learning Native Continuation for Action Chunking Flow Policies | Paper📑
- Legato, a training-time continuation method for action-chunked VLA policies producing smoother trajectories, achieving ~10% improvements in smoothness and task completion across 5 manipulation tasks. | Task: Robotic Manipulation
-
26.02 BiManiBench: A Hierarchical Benchmark for Evaluating Bimanual Coordination of Multimodal Large Language Models | Paper📑 Code🖥️
- Evaluates 30+ MLLMs on bimanual robotic tasks across spatial reasoning, action planning, and end-effector control tiers, finding persistent failures in dual-arm spatial grounding. | Task: Robotic Manipulation
-
26.03 RoboPocket: Improve Robot Policies Instantly with Your Phone | Paper📑 Project🌐
- Portable system enabling robot-free instant policy iteration via smartphone AR visualization of predicted trajectories, doubling data efficiency with asynchronous online finetuning. | Task: Robotic Manipulation
-
26.03 UltraDexGrasp: Learning Universal Dexterous Grasping for Bimanual Robots with Synthetic Data | Paper📑 Project🌐
- Framework for universal dexterous grasping with UltraDexGrasp-20M dataset (20M frames across 1,000 objects), achieving robust zero-shot sim-to-real transfer for multi-strategy bimanual grasping. | Task: Robotic Manipulation
-
26.03 EmbodiedSplat: Online Feed-Forward Semantic 3DGS for Open-Vocabulary 3D Scene Understanding | Paper📑 Project🌐
- Online feed-forward 3D Gaussian Splatting framework enabling real-time semantic scene understanding from streaming images at 5-6 FPS without per-scene optimization. | Task: Embodied Scene Understanding
-
26.03 Lightweight Visual Reasoning for Socially-Aware Robots | Paper📑
- Lightweight language-to-vision feedback module improving VLM reasoning for robotic tasks (navigation, scene description, human-intention recognition) with less than 3% extra parameters. | Task: Embodied Reasoning
-
26.01 ACoT-VLA: Action Chain-of-Thought for Vision-Language-Action Models | Paper📑
- Action Chain-of-Thought paradigm for VLA models with Explicit and Implicit Action Reasoner components, achieving 98.5% on LIBERO. | Task: Robotic Manipulation
-
26.01 Cosmos Policy: Fine-Tuning Video Models for Visuomotor Control and Planning | Paper📑 Model🤗
- Adapts pretrained video models into robot policies through single-stage post-training, achieving 98.5% on LIBERO and SOTA on real-world bimanual manipulation. | Task: Robot Control
-
26.01 DynamicVLA: A Vision-Language-Action Model for Dynamic Object Manipulation | Paper📑 Code🖥️ Dataset🤗
- Compact 0.4B VLA model for dynamic object manipulation with continuous inference and latent-aware action streaming. | Task: Robotic Manipulation
-
26.01 SOP: A Scalable Online Post-Training System for Vision-Language-Action Models | Paper📑 Project🌐
- Scalable online distributed post-training system for VLA models enabling real-world robot policy adaptation through fleet learning. | Task: Robot Control
-
26.01 FantasyVLN: Unified Multimodal Chain-of-Thought Reasoning for Vision-Language Navigation | Paper📑 Code🖥️ Model🤗
- Implicit reasoning framework for vision-language navigation encoding imagined visual tokens in latent space, reducing inference latency by an order of magnitude. | Task: Vision-Language Navigation
-
26.01 RoboVIP: Multi-View Video Generation with Visual Identity Prompting Augments Robot Manipulation | Paper📑 Code🖥️
- Visual identity prompting for multi-view video generation to augment robot manipulation data. | Task: Robotic Manipulation
-
26.01 VLingNav: Embodied Navigation with Adaptive Reasoning and Visual-Assisted Linguistic Memory | Paper📑
- Embodied navigation agent with adaptive reasoning combining visual perception and linguistic memory. | Task: Embodied Navigation
-
25.12 DualVLA: Building a Generalizable Embodied Agent via Partial Decoupling of Reasoning and Action | Paper📑
- Decouples reasoning and action for more generalizable embodied agents. | Task: Robotic Manipulation
-
25.12 HiF-VLA: Hindsight, Insight and Foresight through Motion Representation for VLA Models | Paper📑
- Enriches VLA models with hindsight, insight, and foresight via motion representations. | Task: Robotic Manipulation
-
25.12 LEO-RobotAgent: A General-purpose Robotic Agent for Language-driven Embodied Operator | Paper📑
- General-purpose language-driven robotic agent for embodied task execution. | Task: Robotic Manipulation
-
25.12 Steering VLA Models as Anti-Exploration: A Test-Time Scaling Approach | Paper📑
- Test-time scaling approach for steering VLA models for safe embodied behavior. | Task: Robot Control
-
25.11 WMPO: World Model-based Policy Optimization for Vision-Language-Action Models | Paper📑
- World model-based policy optimization for VLA models in robotics. | Task: Robot Control
-
25.11 RynnVLA-002: A Unified Vision-Language-Action and World Model | Paper📑
- Unified VLA and world model for robotic manipulation. | Task: Robot Control
-
25.11 Mantis: A Versatile Vision-Language-Action Model with Disentangled Visual Foresight | Paper📑
- VLA model with disentangled visual foresight for robotic control. | Task: Robot Control
-
25.11 MobileVLA-R1: Reinforcing Vision-Language-Action for Mobile Robots | Paper📑
- Reinforcement-based VLA model for mobile robot tasks. | Task: Robot Control
-
25.10 VLA-RFT: Vision-Language-Action Reinforcement Fine-tuning with Verified Rewards | Paper📑
- Fine-tuning VLA models using RL with verified rewards in world simulators. | Task: Robot Control
-
25.10 InternVLA-M1: A Spatially Guided Vision-Language-Action Framework for Generalist Robot Policy | Paper📑
- VLA framework for robotic control with spatial grounding. | Task: Robot Control
-
25.10 X-VLA: Soft-Prompted Transformer as Scalable Cross-Embodiment Vision-Language-Action Model | Paper📑
- Cross-embodiment VLA model for scalable robot learning. | Task: Robot Control
-
25.10 GigaBrain-0: A World Model-Powered Vision-Language-Action Model | Paper📑
- VLA model integrating world models for robot reasoning. | Task: Robot Control
-
25.09 Robix: A Unified Model for Robot Interaction, Reasoning and Planning | Paper📑
- Unified robotics model combining visual reasoning with interaction and planning. | Task: Robot Control
-
25.09 FLOWER: Democratizing Generalist Robot Policies with Efficient VLA Flow Policies | Paper📑
- Vision-language-action model for generalist robot policies. | Task: Robot Control
-
25.08 RynnEC: Bringing MLLMs into Embodied World | Paper📑
- Integrates multimodal LLMs into embodied AI settings for physical-world reasoning. | Task: Embodied Reasoning
-
25.08 Do What? Teaching Vision-Language-Action Models to Reject the Impossible | Paper📑
- Trains VLA models to reason about task feasibility and reject impossible instructions. | Task: Robot Control
-
25.08 Discrete Diffusion VLA: Bringing Discrete Diffusion to Action Decoding in VLA Policies | Paper📑
- Uses discrete diffusion for action decoding in vision-language-action robotic policies. | Task: Robot Control
-
23.07 RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control | Paper📑 Project🌐
- Co-finetunes a VLM on web and robot data, establishing the VLA paradigm by transferring internet-scale knowledge to robot control. | Task: General Robotic Manipulation
-
24.05 Octo: An Open-Source Generalist Robot Policy | Paper📑 Code🖥️ Project🌐 Model🤗
- An open-source, generalist transformer policy pretrained on the large-scale Open X-Embodiment dataset, designed for efficient fine-tuning to new robots and tasks. | Task: Robotics
-
24.06 OpenVLA: An Open-Source Vision-Language-Action Model | Paper📑 Code🖥️ Project🌐 Model🤗
- A 7B-parameter open-source VLA model trained on the Open X-Embodiment dataset, achieving state-of-the-art performance for generalist manipulation. | Task: VLA
-
24.10 π₀: A Vision-Language-Action Flow Model for General Robot Control | Paper📑 Code🖥️
- A generalist policy using a novel flow matching architecture atop a pretrained VLM, enabling zero-shot generalization for dexterous manipulation. | Task: Robot Control
-
25.01 FAST: Efficient Action Tokenization for Vision-Language-Action Models | Paper📑 Code🖥️
- A compression-based action tokenization scheme that accelerates autoregressive VLA training by 5x with performance comparable to diffusion models. | Task: Robot Control
-
25.02 Hi Robot: Open-Ended Instruction Following with Hierarchical Vision-Language-Action Models | Paper📑
- A hierarchical VLA model with a high-level VLM for reasoning and a low-level VLA for execution, enabling complex, open-ended instruction following. | Task: Robot Control
-
25.03 Gemini Robotics: Bringing AI into the Physical World | Paper📑 Code🖥️ Project🌐 Dataset🤗
- A VLA model built on the Gemini foundation model, demonstrating significant improvements in generality, interactivity, and dexterity for complex tasks. | Task: Advanced & Dexterous Manipulation
-
25.03 COT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models | Paper📑 Project🌐
- A method that incorporates explicit visual CoT reasoning into VLAs by predicting future image frames autoregressively as visual goals before generating a short action sequence to achieve these goals. | Task: Robotics
-
25.03 GR00T: A Foundation Model for General-Purpose Robotics | Paper📑 Code🖥️ Model🤗 Dataset🤗
- A general-purpose foundation model for robot learning that takes multimodal instructions and past observations to generate actions for the robot to execute. | Task: Robotics
-
25.04 π0.5: a Vision-Language-Action Model with Open-World Generalization | Paper📑
- An evolution of π₀ that uses co-training on diverse tasks to achieve long-horizon, dexterous manipulation in novel, unseen environments. | Task: Robot Control
-
25.06 Chain-of-Action: Faithful and Deterministic Robot Policy via Language-guided State-Action Augmentation | Paper📑 Code🖥️ Project🌐 Model🤗
- A novel robot policy, Chain-of-Action (CoA), that uses language as an intermediate representation to explicitly reason about the chain of actions for a given task, while being fully deterministic during inference. | Task: Robotics
-
25.07 Vision-Language-Action Instruction Tuning: From Understanding to Manipulation | Paper📑 Code🖥️ Project🌐 Model🤗
- An end-to-end VLA model, InstructVLA, that introduces a novel training paradigm called Vision-Language-Action Instruction Tuning (VLA-IT) to preserve the flexible reasoning of VLMs while delivering high-performance robotic manipulation. | Task: Robotic
-
25.07 MinD: Learning A Dual-System World Model for Real-Time Planning and Implicit Risk Analysis | Paper📑 Code🖥️ Project🌐
- A dual-system world model, MinD, that enables real-time, risk-aware planning by conditioning a high-frequency action policy on single-step latent predictions from a low-frequency video generation model. | Task: Robotic
Others
Image MLLM
- 26.03 UniG2U-Bench: Towards Comprehensive Benchmarking of Unified Generation and Understanding MLLMs | Paper📑
- Comprehensive benchmark evaluating MLLMs on both generation and understanding capabilities in a unified framework. | Task: Multimodal Evaluation
- 26.03 Towards Multimodal Lifelong Understanding | Paper📑
- MM-Lifelong dataset and ReMA agent for multimodal lifelong understanding, enabling continual learning across modalities. | Task: Lifelong Learning
- 26.02 VISTA-Bench: Do Vision-Language Models Really Understand Visualized Text as Well as Pure Text? | Paper📑
- Benchmark testing whether VLMs truly understand text rendered visually in images as well as plain text, revealing a significant comprehension gap. | Task: Reasoning
- 26.02 From Perception to Action: An Interactive Benchmark for Vision Reasoning | Paper📑 Code🖥️
- CHAIN 3D physics-driven interactive benchmark evaluating whether VLMs understand causal constraints and execute structured action sequences in mechanical puzzles. | Task: Reasoning
- 26.02 SAM 3D Body: Robust Full-Body Human Mesh Recovery | Paper📑 Code🖥️
- Promptable model for single-image 3D human mesh recovery using the Momentum Human Rig (MHR) parametric representation, supporting 2D keypoint/mask prompts with strong generalization. | Task: 3D Human Pose Estimation
- 26.01 CoF-T2I: Video Models as Pure Visual Reasoners for Text-to-Image Generation | Paper📑
- Uses video generation models as visual reasoners for text-to-image generation, showing temporal modeling transfers to improved spatial reasoning. | Task: Image Generation
- 26.01 OCRVerse: Towards Holistic OCR in End-to-End Vision-Language Models | Paper📑
- Holistic OCR framework within end-to-end vision-language models for comprehensive text understanding in images. | Task: OCR & Document Understanding
- 25.12 GroundingME: Exposing the Visual Grounding Gap in MLLMs through Multi-Dimensional Evaluation | Paper📑
- Exposes and evaluates visual grounding gaps in MLLMs across multiple dimensions. | Task: Visual Grounding
- 25.11 Monet: Reasoning in Latent Visual Space Beyond Images and Language | Paper📑
- Enables vision-language reasoning in latent visual space, going beyond standard image-text paradigms. | Task: Reasoning
- 25.10 SeeingEye: Agentic Information Flow Unlocks Multimodal Reasoning In Text-only LLMs | Paper📑
- Enables multimodal reasoning in text-only LLMs through agentic information flow. | Task: Reasoning
- 25.04 InfiGUI-R1: Advancing Multimodal GUI Agents from Reactive Actors to Deliberative Reasoners | Paper📑 Code🖥️
- an MLLM-based GUI agent designed to progressively evolve agents from Reactive Actors to Deliberative Reasoners. | task: UI
- 25.04 GUI-R1 : A Generalist R1-Style Vision-Language Action Model For GUI Agents | Paper📑
- Enhances GUI agent through RL with unified action space modeling, achieving superior cross-platform performance using only 0.02% of the data required by previous methods. | Task: UI
- 25.03 UI-R1: Enhancing Action Prediction of GUI Agents by Reinforcement Learning | Paper📑
- Introduce a unified rule-based action reward, enabling model optimization via policy-based algorithms like GRPO. | Task: UI
- 25.03 VLM-R1: A stable and generalizable R1-style Large Vision-Language Model Code🖥️ Dataset🤗 Model🤗
- A reproduced R1-style VLM | Task: Referring Expression Comprehension
- 25.02 MedVLM-R1: Incentivizing Medical Reasoning Capability of Vision-Language Models (VLMs) via Reinforcement Learning| Paper📑
- A MLLM trained with GRPO for medical image VQA.| Task: Medical Image VQA
Video MLLM
- 25.03 R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning | Paper📑 Code🖥️ Model🤗
- Impove reasoning capability, emotion recognition accuracy, and generalization ability with RLVR. | Task: Emotion recognition
Audio MLLM
- 26.01 The Sonar Moment: Benchmarking Audio-Language Models in Audio Geo-Localization | Paper📑
- Benchmark for audio-language models on spatial audio geo-localization reasoning tasks. | Task: Audio Reasoning
- 25.02 ADIFF: Explaining audio difference using natural language Code🖥️ Model
- 24.09 What Are They Doing? Joint Audio-Speech Co-Reasoning
- 24.09 Chain-of-Thought Prompting for Speech Translation
Omni LLM
- 26.01 FutureOmni: Evaluating Future Forecasting from Omni-Modal Context for Multimodal LLMs | Paper📑
- Benchmark evaluating multimodal LLMs' ability to forecast future events from omni-modal context including temporal reasoning. | Task: Omni Reasoning
- 25.05 AVCD: Mitigating Hallucinations in Audio-Visual Large Language Models through Contrastive Decoding
- 25.03 R1-Omni: Explainable Omni-Multimodal Emotion Recognition with Reinforcement Learning
- 23.11 X-InstructBLIP: A Framework for Aligning Image, 3D, Audio, Video to LLMs and its Emergent Cross-Modal Reasoning
Benchmarks 📊
| Date | Project | Task | Links |
|---|---|---|---|
| 26.03 | MMR-Life: Piecing Together Real-life Scenes for Multimodal Multi-image Reasoning | Multi-image Reasoning | [📑 Paper] [🌐 Project] |
| 26.03 | RIVER: A Benchmark for Real-World Video Reasoning in Long and Short Contexts | Video Temporal Reasoning | [📑 Paper] |
| 26.03 | UniG2U-Bench: Comprehensive Benchmark for Unified Generation and Understanding MLLMs | Multimodal Evaluation | [📑 Paper] |
| 26.03 | AgentVista: Generalizable Multi-Task Agent with Diverse Visual Manipulation | Multi-Task Agent | [📑 Paper] |
| 26.02 | A Very Big Video Reasoning Suite (VBVR): 1M+ video clips across 200 reasoning tasks | Video Reasoning | [📑 Paper] [🤗 Model] [🤗 Data] |
| 26.02 | OmniGAIA: Omni-Modal AI Agent Benchmark with hindsight-guided exploration | Omni-Modal Agent Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | SpatiaLab: Wild Spatial Reasoning benchmark across 6 VQA categories | Spatial Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | MuRGAt: Multimodal Fact-Level Attribution benchmark for verifiable reasoning | Multimodal Attribution | [📑 Paper] [💻 Code] |
| 26.02 | DeepVision-103K: Verifiable multimodal math dataset for RLVR training | Math Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | UniVBench: Unified evaluation for video foundation models across understanding, generation, editing | Video Foundation Model Evaluation | [📑 Paper] [💻 Code] |
| 26.02 | RISE-Video: Benchmark for video generators decoding implicit world rules | Video Generation Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.02 | SAW-Bench: Egocentric Situated Awareness evaluation with 786 smart-glass videos and 2,071+ QA pairs | Spatial Reasoning | [📑 Paper] |
| 26.02 | BrowseComp-V3: 300-question visual benchmark for complex multi-hop multimodal web search | Multimodal Browsing | [📑 Paper] |
| 26.02 | BiManiBench: Hierarchical benchmark for bimanual coordination evaluation in MLLMs | Bimanual Robotics | [📑 Paper] [💻 Code] |
| 26.01 | MMFineReason: Closing the Multimodal Reasoning Gap via Open Data-Centric Methods | Multimodal Reasoning | [📑 Paper] [🤗 Model] [🤗 Data] |
| 26.01 | ChartVerse: Scaling Chart Reasoning via Reliable Programmatic Synthesis | Chart Reasoning | [📑 Paper] [💻 Code] [🤗 Model] [🤗 Data] |
| 26.01 | VideoLoom: Joint Spatial-Temporal Understanding with LoomBench | Spatial-Temporal Reasoning | [📑 Paper] [💻 Code] [🤗 Model] |
| 26.01 | PROGRESSLM: Towards Progress Reasoning in Vision-Language Models | Task Progress Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 26.01 | FutureOmni: Evaluating Future Forecasting from Omni-Modal Context | Omni-Modal Temporal Reasoning | [📑 Paper] |
| 26.01 | Afri-MCQA: Multimodal Cultural Question Answering for African Languages | Multilingual Multimodal Reasoning | [📑 Paper] |
| 26.01 | AVMeme Exam: A Multimodal Multilingual Multicultural Benchmark | Cultural Multimodal Reasoning | [📑 Paper] |
| 25.12 | HERBench: Multi-Evidence Integration in Video Question Answering | Video Reasoning | [📑 Paper] |
| 25.12 | SVBench: Evaluation of Video Generation Models on Social Reasoning | Video Social Reasoning | [📑 Paper] |
| 25.12 | IF-Bench: Benchmarking MLLMs for Infrared Images | Infrared Image Understanding | [📑 Paper] |
| 25.12 | VABench: Comprehensive Benchmark for Audio-Video Generation | Audio-Video Generation | [📑 Paper] |
| 25.11 | MME-CC: Challenging Multi-Modal Evaluation Benchmark of Cognitive Capacity | Cognitive Capacity | [📑 Paper] |
| 25.11 | GGBench: Geometric Generative Reasoning Benchmark for Unified Multimodal Models | Geometric Reasoning | [📑 Paper] |
| 25.11 | WEAVE: Benchmarking In-context Interleaved Comprehension and Generation | Multimodal Comprehension & Generation | [📑 Paper] |
| 25.10 | Uni-MMMU: Massive Multi-discipline Multimodal Unified Benchmark | Multimodal Multi-discipline Reasoning | [📑 Paper] |
| 25.10 | PhysToolBench: Benchmarking Physical Tool Understanding for MLLMs | Physical Tool Understanding | [📑 Paper] |
| 25.10 | BEAR: Benchmarking Multimodal Language Models for Atomic Embodied Capabilities | Embodied AI Capabilities | [📑 Paper] |
| 25.10 | OmniVideoBench: Towards Audio-Visual Understanding Evaluation for Omni MLLMs | Long-context, Video-Audio Unerstanding & Reasonin | [📑 Paper] [💻 Code] [🌐 Project] [🤗 Data] |
| 25.10 | XModBench: Benchmarking Cross-Modal Capabilities and Consistency in Omni-Language Models | Capability Balancing among Different Modalities | [📑 Paper] [💻 Code] [🌐 Project] |
| 25.10 | StreamingCoT: A Dataset for Temporal Dynamics and Multimodal Chain-of-Thought Reasoning in Streaming VideoQA | Termporal Reasoning | [📑 Paper] |
| 25.10 | Valor32k-AVQA v2.0: Open-Ended Audio-Visual Question Answering Dataset and Benchmark | Common Sense Omni Reasoning | [📑 Paper] |
| 25.09 | MARS2 2025 Challenge on Multimodal Reasoning | Multimodal Reasoning Challenge | [📑 Paper] |
| 25.09 | Visual-TableQA: Open-Domain Benchmark for Reasoning over Table Images | Table Reasoning | [📑 Paper] |
| 25.09 | AHELM: A Holistic Evaluation of Audio-Language Models | Audio-Language Understanding | [📑 Paper] |
| 25.09 | MDAR: A Multi-scene Dynamic Audio Reasoning Benchmark | Complex, Multi-scene, & Dynamically Evolving Speech & Audio Reasonin | [📑 Paper] [💻 Code] |
| 25.09 | MiMo-Audio-Eval Toolkit | Speech/Sound/Music Reasoning | [💻 Code] |
| 25.08 | SpeechR: A Benchmark for Speech Reasoning in Large Audio-Language Models | Speech Reasoning | [📑 Paper] [💻 Code] [Data] |
| 25.08 | MMAU-Pro: A Challenging and Comprehensive Benchmark for Holistic Evaluation of Audio General Intelligence | Long-form, Spatial, and Multi-audio Reasoning on Speech/Music/Sound | [📑 Paper] [🤗 Data] |
| 25.08 | R²-AVSBench: Think Before You Segment: An Object-aware Reasoning Agent for Referring Audio-Visual Segmentation | Segmentation Reasoning | [📑 Paper] [🤗 Data] |
| 25.07 | Towards Video Thinking Test: A Holistic Benchmark for Advanced Video Reasoning and Understanding | Video Reasoning and Understanding | [📑 Paper]. [🌐 Project] [🤗 Data] |
| 25.06 | FinMME: Benchmark Dataset for Financial Multi-Modal Reasoning Evaluation | Financial Multi-Modal Reasoning Reasoning | [📑 Paper]. [💻 Code]. [🤗 Data] |
| 25.06 | MMR-V: What's Left Unsaid? A Benchmark for Multimodal Deep Reasoning in Videos | Video Reasoning | [📑 Paper]. [💻 Code]. [🌐 Project] [🤗 Data] |
| 25.06 | OmniSpatial: Towards Comprehensive Spatial Reasoning Benchmark for Vision Language Models | Spatial Reasoning | [📑 Paper]. [💻 Code]. [🌐 Project] [🤗 Data] |
| 25.06 | MMSU: A Massive Multi-task Spoken Language Understanding and Reasoning Benchmark | Phonatics, Prosody, Rhetoric, Syntactics, Semantics, and Paralinguistics in Speech Understanding & Reasoning | [📑 Paper] [💻 Code] [🤗 Data] |
| 25.05 | Daily-Omni: Towards Audio-Visual Reasoning with Temporal Alignment across Modalities | Video&Audio Reasoning | [📑 Paper] [💻 Code] [🌐 Project] [🤗 Data] |
| 25.05 | MMAR: A Challenging Benchmark for Deep Reasoning in Speech, Audio, Music, and Their Mix | Multi-step Audio Reasoning | [📑 Paper]. [💻 Code]. [🎥 demo] [🤗 Data] |
| 25.05 | On Path to Multimodal Generalist: General-Level and General-Bench | Multimodal Generation | [🌐 Project] [📑 Paper] [🤗 Data] |
| 25.04 | VisuLogic: A Benchmark for Evaluating Visual Reasoning in Multi-modal Large Language Models | Visual Reasoning | [🌐 Project] [📑 Paper] [💻 Code] [🤗 Data] |
| 25.04 | IV-Bench: A Benchmark for Image-Grounded Video Perception and Reasoning in Multimodal LLMs | Image-Grounded Video Perception and Reasoning | [📑 Paper] [💻 Code] |
| 25.04 | Envisioning Beyond the Pixels: Benchmarking Reasoning-Informed Visual Editing | Reasoning-Informed viSual Editing | [📑 Paper] [💻 Code] |
| 25.04 | CMI-Bench: A Comprehensive Benchmark for Evaluating Music Instruction Following | Music Information Retrieval & Knowledge | [📑 Paper] [💻 Code] |
| 25.03 | MAVERIX: Multimodal Audio-Visual Evaluation Reasoning IndeX | Common Sense Omni Reasoning | [📑 Paper] [🌐 Project] |
| 25.03 | V-STaR : Benchmarking Video-LLMs on Video Spatio-Temporal Reasoning | Spatio-temporal Reasoning | [🌐 Project] [📑 Paper] [🤗 Data] |
| 25.03 | MM-Spatial: Exploring 3D Spatial Understanding in Multimodal LLMs | Spatio-temporal Understanding | [📑Paper] |
| 25.03 | Integrating Chain-of-Thought for Multimodal Alignment: A Study on 3D Vision-Language Learning | 3D-CoT | [📑 Paper] [🤗 Data] |
| 25.02 | MM-IQ: Benchmarking Human-Like Abstraction and Reasoning in Multimodal Models | MM-IQ | [📑 Paper] [💻 Code] |
| 25.02 | MM-RLHF: The Next Step Forward in Multimodal LLM Alignment | MM-RLHF-RewardBench, MM-RLHF-SafetyBench | [📑 Paper] |
| 25.02 | ZeroBench: An Impossible* Visual Benchmark for Contemporary Large Multimodal Models | ZeroBench | [🌐 Project] [🤗 Dataset] [💻 Code] |
| 25.02 | MME-CoT: Benchmarking Chain-of-Thought in LMMs for Reasoning Quality, Robustness, and Efficiency | MME-CoT | [📑 Paper] [💻 Code] |
| 25.02 | OmniAlign-V: Towards Enhanced Alignment of MLLMs with Human Preference | MM-AlignBench | [📑 Paper] [💻 Code] |
| 25.01 | AVTrustBench: Assessing and Enhancing Reliability and Robustness in Audio-Visual LLMs | Adversarial attack, Compositional reasoning, and Modality-specific dependency in Visual&Audio | [📑 Paper] |
| 25.01 | LlamaV-o1: Rethinking Step-By-Step Visual Reasoning in LLM |
Truncated — view the full README on GitHub.