TikTok TechJam 2026 - AI-generated image detection model training
Python
1
87 commits
updated Sep 1, 2026
TikTok TechJam 2026 · Problem Statement 5 — build a prototype that tells AI-generated images from authentic photographs, and keeps working after the compression, blur, resizing and noise every image picks up in circulation.
Result: Final Score
0.9362on the organisers' benchmark composition (WildFake vs COCO, resolution-matched), measured on five generator families with zero representation in training — from a 21.7M-parameter ViT, no ensemble, no second branch.
| Live demo | run serve_demo.ps1 → a public https://<...>.trycloudflare.com URL (see Try it) |
| Model weights | v1.0 release — 21.7M params, 87 MB, Apache-2.0 (inference.py fetches it automatically) |
| Browser extension | extension/ — right-click any page → Check the main image, video included |
| Demo video | (link in the Devpost submission) |
| Robustness table | below · full: docs/ERROR_ANALYSIS.md |
| Error-analysis note | docs/ERROR_ANALYSIS.md + FP/FN montages below |
| Reproducibility | every number here comes from the committed config.yaml + scripts/build_corpus.py — nothing lives outside this repo |
pred is the likelihood the image is AI-generated (0 → authentic, 1 → AI-generated).
From the briefing deck:
| family | settings |
|---|---|
| JPEG compression | quality 90, 70, 50, 30 |
| Gaussian blur | σ = 0.5, 1.0, 2.0 |
| Resize | 0.5× / 0.25× then upscale back |
| Gaussian noise | σ = 0.02, 0.05, 0.10 |
| Colour jitter | brightness / contrast / saturation ±20% |
| Centre crop | 80% then resize back |
Implemented once in detector/transforms.py and
used identically for training augmentation and evaluation.
All held-out. The organiser composition is the reporting number.
| Benchmark | Final Score | AUC(clean) | AUC(robust) |
|---|---|---|---|
| Organiser composition — WildFake pixel-diffusion (ADM, DALL·E, DDIM, DDPM, VQDM) vs COCO, resolution-matched | 0.9362 | 0.9597 | 0.9127 |
| DRAGON — 8 unseen latent-diffusion generators (Flux, SDXL-Turbo, SD3, Kolors, …) | 0.9779 | 0.9883 | 0.9675 |
| SID_Set — mixed full-synthetic and locally-tampered images | 0.8481 | 0.8576 | 0.8386 |
The SID_Set row is the hardest of the three because it includes tampered images — real photographs with a locally edited region — which this detector is not built for: it answers "was this image generated?", not "was part of it edited?". It is reported anyway rather than dropped.
Per-generator ROC-AUC on the organiser set (all five are pixel-space diffusion; none appear in training):
| ADM | DDPM | DDIM | DALL·E | VQDM | |
|---|---|---|---|---|---|
| clean | 0.937 | 0.913 | 0.970 | 0.984 | 0.995 |
| mean-robust | 0.870 | 0.855 | 0.918 | 0.962 | 0.958 |
ADM and DDPM are the hard cases and the reason for a deliberate data choice: pixel-space diffusion leaves no VAE fingerprint for a latent-diffusion-trained detector to key on. Adding 5,000 GenImage ADM/GLIDE images to training moved ADM's clean AUC from 0.478 — below chance — to 0.937.
Operating threshold 0.51 (calibrated on withheld generators). The Final Score is threshold-free; FPR/FNR are shown for completeness.
| Condition | ROC-AUC | FPR | FNR |
|---|---|---|---|
| clean | 0.9597 | 0.067 | 0.163 |
| jpeg q90 / q70 / q50 / q30 | 0.938 / 0.923 / 0.890 / 0.830 | 0.071 / 0.075 / 0.073 / 0.099 | 0.241 / 0.289 / 0.387 / 0.493 |
| blur σ0.5 / σ1 / σ2 | 0.960 / 0.955 / 0.898 | 0.058 / 0.071 / 0.262 | 0.180 / 0.190 / 0.145 |
| resize 0.5× / 0.25× | 0.958 / 0.871 | 0.073 / 0.134 | 0.171 / 0.315 |
| noise σ0.02 / σ0.05 / σ0.10 | 0.928 / 0.890 / 0.830 | 0.059 / 0.075 / 0.102 | 0.325 / 0.438 / 0.540 |
| colour jitter ±20% | 0.957 | 0.075 | 0.178 |
| centre crop 80% | 0.949 | 0.080 | 0.181 |
Weakest conditions: JPEG q30 and sensor noise σ0.10 (both AUC 0.830) —
heavy re-compression and additive noise are the two transforms that most
directly overwrite the high-frequency evidence detectors lean on. Note the
floor: even there, AUC stays well above chance. Regenerate this table for any
checkpoint with bash evaluate.sh <ckpt> <tag>.
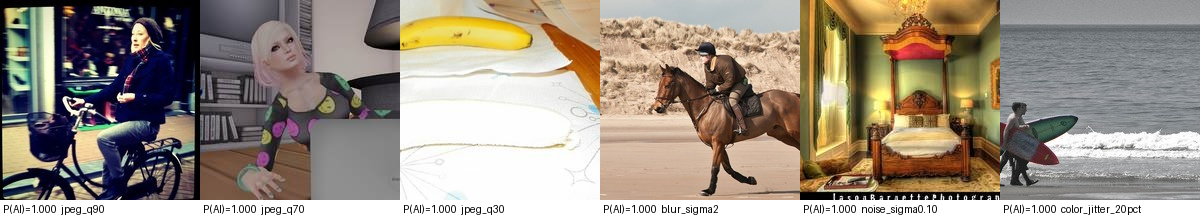 Authentic COCO photos the detector was surest were AI — all high-contrast,
low-noise studio shots whose statistics resemble the "too clean" look of a
generator.
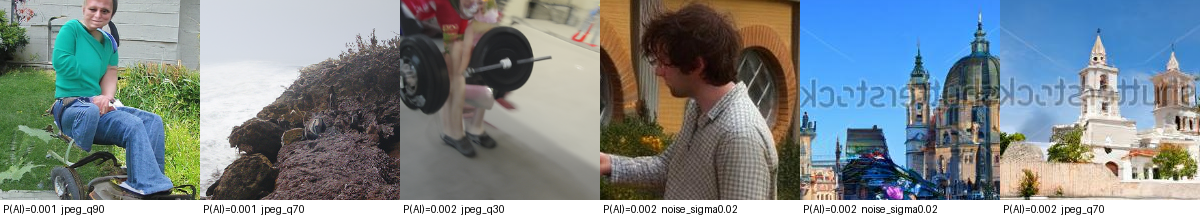 AI images (all ADM/DDPM — 2021-era pixel diffusion) the detector was surest
were real. ADM's iterative denoising leaves almost no spectral fingerprint,
and the content is plausible ImageNet fauna/objects.
Full note, per-condition FPR/FNR, and the file lists: docs/ERROR_ANALYSIS.md.
Community Forensics ViT-S/16 @224 21,666,049 params → logit → P(AI)
That is the whole model. The interesting work is in the two things feeding it — the preprocessing and the corpus — which is exactly what deck slide 10 predicts: "the biggest lever isn't a fancier model — it's what you train on." We took that literally, and then tested it.
OwensLab/commfor-model-224 (timm
vit_small_patch16_224.augreg_in21k_ft_in1k). A purpose-built AI-image
detector; an independent 2026 benchmark ranks it #1 of 23 open detectors.Resize(256)
is a low-pass filter: it destroys the high-frequency artifact before the
model ever sees it. We crop 224×224 out of the original resolution instead.RandomRotation(180) + 16px patch masking, which
kill the colour and semantic shortcuts a detector will otherwise learn
instead of the artifact.demo_images/ score 6/6 correct there.This is the part we'd most want a judge to read. Three separate attempts to add a second branch, across two independent implementations, all failed to transfer — and the failures are what justify the simple final architecture.
| Attempt | Seen validation | Held-out transfer | Verdict |
|---|---|---|---|
| DWT wavelet branch (iter5b) | +0.0006 AUC | organiser 0.8804 → 0.8800, DRAGON flat | dropped |
| Frozen CLIP-B branch (iter6b) | +0.0002 AUC | organiser 0.9362 → 0.9362, every generator within ±0.001 | dropped |
| FFT spectrum branch (earlier) | positive | 0.457 AUC on unseen generators — worse than chance | dropped |
The pattern: an auxiliary branch's value is bounded by what the base ViT is still missing. On a weaker base (no native-crop, no pixel-diffusion data) a frozen CLIP branch is worth ~+0.02 Final Score. On the base described above, it is worth nothing measurable — the training-side fixes had already closed the gap it was compensating for. So we shipped the model without it: same accuracy, ⅕ the parameters, one checkpoint, no separate fusion-head training pass.
Full ablation tables and the reasoning at each step:
docs/EXPERIMENTS_LOG.md.
Our first organiser-set score was 0.8131. Then a size-only probe — a "classifier" that sees nothing but the image's pixel count — scored AUC 1.000 on that set. WildFake ships fakes at fixed 256×256; COCO reals are photographic resolutions. Every fake was smaller than every real, so the set was partly measuring file headers, not detection.
We rebuilt it by centre-cropping both classes to a common native size (size-only AUC → 0.500) and re-scored. The honest number was 0.7007, and we published the correction rather than the flattering original. Every result in this README is measured on the corrected set.
detector/calibrate.py lets an operator refit per deployment.There is no silver bullet — modern flow/DiT generators (SD3, Flux, Firefly) are the frontier where every open detector still collapses, and they are named honestly in Limitations.
| Rule | This submission |
|---|---|
| Model < 2B parameters | 21,666,049 (92× under) |
| Public pretrained backbones only | OwensLab/commfor-model-224 — public, Apache-2.0 |
| Custom code MIT/Apache | Apache-2.0 (this repo) |
| Public/licensed data only, no test-label training | SID_Set · DRAGON · Community-Forensics-Small · GenImage. detector/data.py:assert_not_eval_only hard-fails if an eval_only_* path reaches the training or calibration code |
| Augmentation scripts included | detector/transforms.py, scripts/build_corpus.py |
| No "directly replicate an existing model" | a public backbone plus an original preprocessing + corpus design, with three documented negative results establishing why the simple architecture is the right one |
| Winning teams open-source everything | pipeline, hyperparameters (config.yaml), corpus builder, eval code, and weights are all in this repo or its release — config.yaml as committed reproduces the shipped checkpoint, with nothing held back locally |
| Submission: repo + run script + Devpost + demo video | this repo, inference.py, Devpost, YouTube |
Scope (slide 17): image-level binary detection only — no video/audio, no production deployment, no localisation. Consistent with this project.
Fastest path — score a folder in one command. No flags, no menu, no prompts. It downloads the weights itself on first run:
pip install -r requirements-cuda.txt      # NVIDIA / CPU
python inference.py <folder_of_images>    # → predictions.json
That is the whole thing. python inference.py demo_images scores the six
bundled samples and should return 6/6 correct on CPU in about ten seconds.
Or do it by hand:
1 — set up the environment (Python 3.10–3.12):
python -m venv .venv
# Windows:  .venv\Scripts\activate      Linux/macOS:  source .venv/bin/activate
pip install -r requirements-cuda.txt          # NVIDIA / CPU
2 — predict a folder of images (the required deliverable format):
python pipeline.py predict \
  --input demo_images \
  --output predictions.json \
  --checkpoint checkpoints/detector.pt \
  --device auto
Both entry points write the same two files:
// predictions.json
[{"image_path": "...", "pred": 0.9993, "label": 1}]
Matching the brief: "a confidence score for each image, indicating the
likelihood that it is AIGC-generated ... a JSON file containing image_path
and pred". pred is that likelihood — a float in [0, 1], not a rounded
label. This matters for scoring: ROC-AUC computed over 0/1 predictions
collapses into a step function and understates any model. label carries the
thresholded call for consumers that want a decision rather than a score, and
predictions.scores.csv repeats the probability alongside confidence for
spreadsheet use.
checkpoints/detector.ptis ~87 MB and not in git (large binary).inference.pyfetches it automatically from thev1.0release; the direct link is in that release if you would rather download it by hand.
3 — the interactive demo:
pip install fastapi uvicorn python-multipart
DETECTOR_CHECKPOINT=checkpoints/detector.pt uvicorn webapp.server:app --port 8000
# open http://localhost:8000
Three views: single image (verdict + confidence band), robustness grid (that image re-scored under all 15 conditions), batch (drop a folder → sorted table + CSV, up to 200 images).
4 — a public URL for a judging session (free, no account, temporary):
powershell -ExecutionPolicy Bypass -File serve_demo.ps1
Prints a https://<...>.trycloudflare.com link; Ctrl+C stops it.
5 — check what is on screen, in the browser you already use (optional):
Load extension/ at chrome://extensions → Developer mode
→ Load unpacked, paste the detector URL into its popup, then click Check main
image in the corner of any page (or press Alt+Shift+A, or right-click →
Check the main image on this page).
It ranks candidates by visible area weighted toward the centre of the viewport, so on a social feed it reads the post rather than the sidebar thumbnails and avatars, and it rings its choice on the page so you can see what it picked before you trust the number. Video works too — there is no image URL to fetch and a canvas frame grab is blocked by cross-origin tainting, so it crops a screenshot of the tab. That path is labelled "from screen capture" in the panel, because a frame already scaled by the browser and already through the site's codec is weaker evidence than an image's original bytes — which is the same finding the detector itself is built on.
extension/README.md has the bands, the limits, and the
six bugs the browser tests caught.
Verify the smoke test (synthetic data, no dataset needed):
python pipeline.py smoke --device auto
Three steps, all from this repo — nothing is archived elsewhere.
# 1. build the corpus (streams from HuggingFace; ~66.5k images on disk)
python scripts/build_corpus.py     # SID_Set + DRAGON-17 + CF-Small + GenImage

# 2. train (10 epochs, ~3.5 h on an RTX 3050)
python pipeline.py train --config config.yaml

# 3. score every held-out set + regenerate the tables and montages
bash evaluate.sh checkpoints/detector.pt detector
config.yaml as committed is the exact configuration that produced the
shipped checkpoint — crop_from_native: true, safe_augment: true,
samples_per_epoch: 24000. Step 2 reads it, trains detector/,
and calibrates the threshold on withheld generators, never the test set.
Data — all public: saberzl/SID_Set (the tampered class is dropped —
localised editing, out of scope), lesc-unifi/dragon (17 generators in
training, 8 held out), OwensLab/CommunityForensics-Small (latent-diffusion +
GAN + pixel-diffusion, with LAION/ImageNet/CelebA/COCO reals), and
bitmind/GenImage_ADM + bitmind/GenImage_glide.
scripts/build_eval_set.py
builds the resolution-matched evaluation set.
inference.py          THE entry point: python inference.py <folder> → predictions.json
pipeline.py           ingest · train · evaluate · predict · smoke · materialize-sid-set
config.yaml           the exact training configuration behind the shipped checkpoint
detector/             model · data · transforms · training · evaluation · calibration
scripts/              corpus builders, matched-set builder, shortcut probe, stream-eval
webapp/               FastAPI demo — single · 15-condition robustness · batch
extension/            Chrome extension (MV3) — right-click → check the main image
serve_demo.ps1        one command → a public Cloudflare-tunnel URL
evaluate.sh           full 15-condition eval + FP/FN montages for a checkpoint
docs/                 error-analysis note, FP/FN montages, full experiment log
demo_images/          six labelled samples (4 AI, 2 authentic) to try it on
requirements*.txt     cuda / cpu
Env vars the scripts honour: PYTHON, TTJ_DATA, DEVICE, HF_HOME,
SYCL_CACHE_DIR, DETECTOR_CHECKPOINT, DETECTOR_DEVICE.
| split | role |
|---|---|
train | fit weights |
val | watch for training failure only — never an operating-point input |
genval | one withheld generator — fits the threshold value |
calval | a different withheld generator — picks the rule (minmax_fpfn) |
holdout | the reported metric — never an input to any decision |
python -m detector.calibrate runs/<name>/best.pt \
  --genval <dir> --calval <dir> --rule minmax_fpfn --apply
Calibrating on held-out generators instead of val took recall on unseen
fakes from ~25% to ~98% with no change to AUC — it fixes the operating
point, not the model.
Ranked by what we believe would actually move the number, based on where the measurements point rather than on what sounds impressive.
We would also replace the dHash contamination check described below with a
proper perceptual-hash sweep, and re-run the SID_Set evaluation split by
full_synthetic versus tampered so that number stops conflating two tasks.
The brief specifies that COCO val2017 and DALL·E Advanced must not be used in training. None of our four training sources draws from them, and we checked rather than assumed: a difference-hash comparison of all 26,361 training reals against the 1,000 COCO images in our evaluation set found no genuine duplicate. Thirteen apparent collisions all mapped to a single near-uniform eval image (pixel std 12.3) whose hash is degenerate; direct comparison put those pairs 45/255 apart in mean absolute pixel difference — different photographs.
Separately, detector/data.py:assert_not_eval_only hard-fails if a path
marked eval_only_* reaches training or calibration, so the guarantee is
enforced in code and not only by convention.
scripts/build_corpus.py), the
native-crop + SAFE training recipe, iteration 5a/5b/6a/6b and the ablations
behind them, inference.py, the web demo, and this documentation.(Replace or extend these lines with the split your team agrees on — they are recorded here from the commit history, which is the only record this repository has.)
Code and released weights: Apache-2.0. Backbones are used under their own
public licenses (OwensLab/commfor-model-224, Apache-2.0).
Training-data note, stated plainly: one of the four training sources, Community-Forensics-Small, is licensed CC-BY-NC-SA-4.0 — non-commercial, share-alike. Model weights are not a derivative work of the training data under most readings, and this is a research/hackathon artifact, but anyone considering commercial use should evaluate that themselves rather than rely on the Apache-2.0 tag alone. SID_Set, DRAGON and GenImage carry no such restriction.
TikTok TechJam 2026 - AI-generated image detection model training
Python
1
87 commits
updated Sep 1, 2026
TikTok TechJam 2026 · Problem Statement 5 — build a prototype that tells AI-generated images from authentic photographs, and keeps working after the compression, blur, resizing and noise every image picks up in circulation.
Result: Final Score
0.9362on the organisers' benchmark composition (WildFake vs COCO, resolution-matched), measured on five generator families with zero representation in training — from a 21.7M-parameter ViT, no ensemble, no second branch.
| Live demo | run serve_demo.ps1 → a public https://<...>.trycloudflare.com URL (see Try it) |
| Model weights | v1.0 release — 21.7M params, 87 MB, Apache-2.0 (inference.py fetches it automatically) |
| Browser extension | extension/ — right-click any page → Check the main image, video included |
| Demo video | (link in the Devpost submission) |
| Robustness table | below · full: docs/ERROR_ANALYSIS.md |
| Error-analysis note | docs/ERROR_ANALYSIS.md + FP/FN montages below |
| Reproducibility | every number here comes from the committed config.yaml + scripts/build_corpus.py — nothing lives outside this repo |
pred is the likelihood the image is AI-generated (0 → authentic, 1 → AI-generated).
From the briefing deck:
| family | settings |
|---|---|
| JPEG compression | quality 90, 70, 50, 30 |
| Gaussian blur | σ = 0.5, 1.0, 2.0 |
| Resize | 0.5× / 0.25× then upscale back |
| Gaussian noise | σ = 0.02, 0.05, 0.10 |
| Colour jitter | brightness / contrast / saturation ±20% |
| Centre crop | 80% then resize back |
Implemented once in detector/transforms.py and
used identically for training augmentation and evaluation.
All held-out. The organiser composition is the reporting number.
| Benchmark | Final Score | AUC(clean) | AUC(robust) |
|---|---|---|---|
| Organiser composition — WildFake pixel-diffusion (ADM, DALL·E, DDIM, DDPM, VQDM) vs COCO, resolution-matched | 0.9362 | 0.9597 | 0.9127 |
| DRAGON — 8 unseen latent-diffusion generators (Flux, SDXL-Turbo, SD3, Kolors, …) | 0.9779 | 0.9883 | 0.9675 |
| SID_Set — mixed full-synthetic and locally-tampered images | 0.8481 | 0.8576 | 0.8386 |
The SID_Set row is the hardest of the three because it includes tampered images — real photographs with a locally edited region — which this detector is not built for: it answers "was this image generated?", not "was part of it edited?". It is reported anyway rather than dropped.
Per-generator ROC-AUC on the organiser set (all five are pixel-space diffusion; none appear in training):
| ADM | DDPM | DDIM | DALL·E | VQDM | |
|---|---|---|---|---|---|
| clean | 0.937 | 0.913 | 0.970 | 0.984 | 0.995 |
| mean-robust | 0.870 | 0.855 | 0.918 | 0.962 | 0.958 |
ADM and DDPM are the hard cases and the reason for a deliberate data choice: pixel-space diffusion leaves no VAE fingerprint for a latent-diffusion-trained detector to key on. Adding 5,000 GenImage ADM/GLIDE images to training moved ADM's clean AUC from 0.478 — below chance — to 0.937.
Operating threshold 0.51 (calibrated on withheld generators). The Final Score is threshold-free; FPR/FNR are shown for completeness.
| Condition | ROC-AUC | FPR | FNR |
|---|---|---|---|
| clean | 0.9597 | 0.067 | 0.163 |
| jpeg q90 / q70 / q50 / q30 | 0.938 / 0.923 / 0.890 / 0.830 | 0.071 / 0.075 / 0.073 / 0.099 | 0.241 / 0.289 / 0.387 / 0.493 |
| blur σ0.5 / σ1 / σ2 | 0.960 / 0.955 / 0.898 | 0.058 / 0.071 / 0.262 | 0.180 / 0.190 / 0.145 |
| resize 0.5× / 0.25× | 0.958 / 0.871 | 0.073 / 0.134 | 0.171 / 0.315 |
| noise σ0.02 / σ0.05 / σ0.10 | 0.928 / 0.890 / 0.830 | 0.059 / 0.075 / 0.102 | 0.325 / 0.438 / 0.540 |
| colour jitter ±20% | 0.957 | 0.075 | 0.178 |
| centre crop 80% | 0.949 | 0.080 | 0.181 |
Weakest conditions: JPEG q30 and sensor noise σ0.10 (both AUC 0.830) —
heavy re-compression and additive noise are the two transforms that most
directly overwrite the high-frequency evidence detectors lean on. Note the
floor: even there, AUC stays well above chance. Regenerate this table for any
checkpoint with bash evaluate.sh <ckpt> <tag>.
Authentic COCO photos the detector was surest were AI — all high-contrast,
low-noise studio shots whose statistics resemble the "too clean" look of a
generator.
AI images (all ADM/DDPM — 2021-era pixel diffusion) the detector was surest
were real. ADM's iterative denoising leaves almost no spectral fingerprint,
and the content is plausible ImageNet fauna/objects.
Full note, per-condition FPR/FNR, and the file lists: docs/ERROR_ANALYSIS.md.
Community Forensics ViT-S/16 @224 21,666,049 params → logit → P(AI)
That is the whole model. The interesting work is in the two things feeding it — the preprocessing and the corpus — which is exactly what deck slide 10 predicts: "the biggest lever isn't a fancier model — it's what you train on." We took that literally, and then tested it.
OwensLab/commfor-model-224 (timm
vit_small_patch16_224.augreg_in21k_ft_in1k). A purpose-built AI-image
detector; an independent 2026 benchmark ranks it #1 of 23 open detectors.Resize(256)
is a low-pass filter: it destroys the high-frequency artifact before the
model ever sees it. We crop 224×224 out of the original resolution instead.RandomRotation(180) + 16px patch masking, which
kill the colour and semantic shortcuts a detector will otherwise learn
instead of the artifact.demo_images/ score 6/6 correct there.This is the part we'd most want a judge to read. Three separate attempts to add a second branch, across two independent implementations, all failed to transfer — and the failures are what justify the simple final architecture.
| Attempt | Seen validation | Held-out transfer | Verdict |
|---|---|---|---|
| DWT wavelet branch (iter5b) | +0.0006 AUC | organiser 0.8804 → 0.8800, DRAGON flat | dropped |
| Frozen CLIP-B branch (iter6b) | +0.0002 AUC | organiser 0.9362 → 0.9362, every generator within ±0.001 | dropped |
| FFT spectrum branch (earlier) | positive | 0.457 AUC on unseen generators — worse than chance | dropped |
The pattern: an auxiliary branch's value is bounded by what the base ViT is still missing. On a weaker base (no native-crop, no pixel-diffusion data) a frozen CLIP branch is worth ~+0.02 Final Score. On the base described above, it is worth nothing measurable — the training-side fixes had already closed the gap it was compensating for. So we shipped the model without it: same accuracy, ⅕ the parameters, one checkpoint, no separate fusion-head training pass.
Full ablation tables and the reasoning at each step:
docs/EXPERIMENTS_LOG.md.
Our first organiser-set score was 0.8131. Then a size-only probe — a "classifier" that sees nothing but the image's pixel count — scored AUC 1.000 on that set. WildFake ships fakes at fixed 256×256; COCO reals are photographic resolutions. Every fake was smaller than every real, so the set was partly measuring file headers, not detection.
We rebuilt it by centre-cropping both classes to a common native size (size-only AUC → 0.500) and re-scored. The honest number was 0.7007, and we published the correction rather than the flattering original. Every result in this README is measured on the corrected set.
detector/calibrate.py lets an operator refit per deployment.There is no silver bullet — modern flow/DiT generators (SD3, Flux, Firefly) are the frontier where every open detector still collapses, and they are named honestly in Limitations.
| Rule | This submission |
|---|---|
| Model < 2B parameters | 21,666,049 (92× under) |
| Public pretrained backbones only | OwensLab/commfor-model-224 — public, Apache-2.0 |
| Custom code MIT/Apache | Apache-2.0 (this repo) |
| Public/licensed data only, no test-label training | SID_Set · DRAGON · Community-Forensics-Small · GenImage. detector/data.py:assert_not_eval_only hard-fails if an eval_only_* path reaches the training or calibration code |
| Augmentation scripts included | detector/transforms.py, scripts/build_corpus.py |
| No "directly replicate an existing model" | a public backbone plus an original preprocessing + corpus design, with three documented negative results establishing why the simple architecture is the right one |
| Winning teams open-source everything | pipeline, hyperparameters (config.yaml), corpus builder, eval code, and weights are all in this repo or its release — config.yaml as committed reproduces the shipped checkpoint, with nothing held back locally |
| Submission: repo + run script + Devpost + demo video | this repo, inference.py, Devpost, YouTube |
Scope (slide 17): image-level binary detection only — no video/audio, no production deployment, no localisation. Consistent with this project.
Fastest path — score a folder in one command. No flags, no menu, no prompts. It downloads the weights itself on first run:
pip install -r requirements-cuda.txt      # NVIDIA / CPU
python inference.py <folder_of_images>    # → predictions.json
That is the whole thing. python inference.py demo_images scores the six
bundled samples and should return 6/6 correct on CPU in about ten seconds.
Or do it by hand:
1 — set up the environment (Python 3.10–3.12):
python -m venv .venv
# Windows:  .venv\Scripts\activate      Linux/macOS:  source .venv/bin/activate
pip install -r requirements-cuda.txt          # NVIDIA / CPU
2 — predict a folder of images (the required deliverable format):
python pipeline.py predict \
  --input demo_images \
  --output predictions.json \
  --checkpoint checkpoints/detector.pt \
  --device auto
Both entry points write the same two files:
// predictions.json
[{"image_path": "...", "pred": 0.9993, "label": 1}]
Matching the brief: "a confidence score for each image, indicating the
likelihood that it is AIGC-generated ... a JSON file containing image_path
and pred". pred is that likelihood — a float in [0, 1], not a rounded
label. This matters for scoring: ROC-AUC computed over 0/1 predictions
collapses into a step function and understates any model. label carries the
thresholded call for consumers that want a decision rather than a score, and
predictions.scores.csv repeats the probability alongside confidence for
spreadsheet use.
checkpoints/detector.ptis ~87 MB and not in git (large binary).inference.pyfetches it automatically from thev1.0release; the direct link is in that release if you would rather download it by hand.
3 — the interactive demo:
pip install fastapi uvicorn python-multipart
DETECTOR_CHECKPOINT=checkpoints/detector.pt uvicorn webapp.server:app --port 8000
# open http://localhost:8000
Three views: single image (verdict + confidence band), robustness grid (that image re-scored under all 15 conditions), batch (drop a folder → sorted table + CSV, up to 200 images).
4 — a public URL for a judging session (free, no account, temporary):
powershell -ExecutionPolicy Bypass -File serve_demo.ps1
Prints a https://<...>.trycloudflare.com link; Ctrl+C stops it.
5 — check what is on screen, in the browser you already use (optional):
Load extension/ at chrome://extensions → Developer mode
→ Load unpacked, paste the detector URL into its popup, then click Check main
image in the corner of any page (or press Alt+Shift+A, or right-click →
Check the main image on this page).
It ranks candidates by visible area weighted toward the centre of the viewport, so on a social feed it reads the post rather than the sidebar thumbnails and avatars, and it rings its choice on the page so you can see what it picked before you trust the number. Video works too — there is no image URL to fetch and a canvas frame grab is blocked by cross-origin tainting, so it crops a screenshot of the tab. That path is labelled "from screen capture" in the panel, because a frame already scaled by the browser and already through the site's codec is weaker evidence than an image's original bytes — which is the same finding the detector itself is built on.
extension/README.md has the bands, the limits, and the
six bugs the browser tests caught.
Verify the smoke test (synthetic data, no dataset needed):
python pipeline.py smoke --device auto
Three steps, all from this repo — nothing is archived elsewhere.
# 1. build the corpus (streams from HuggingFace; ~66.5k images on disk)
python scripts/build_corpus.py     # SID_Set + DRAGON-17 + CF-Small + GenImage

# 2. train (10 epochs, ~3.5 h on an RTX 3050)
python pipeline.py train --config config.yaml

# 3. score every held-out set + regenerate the tables and montages
bash evaluate.sh checkpoints/detector.pt detector
config.yaml as committed is the exact configuration that produced the
shipped checkpoint — crop_from_native: true, safe_augment: true,
samples_per_epoch: 24000. Step 2 reads it, trains detector/,
and calibrates the threshold on withheld generators, never the test set.
Data — all public: saberzl/SID_Set (the tampered class is dropped —
localised editing, out of scope), lesc-unifi/dragon (17 generators in
training, 8 held out), OwensLab/CommunityForensics-Small (latent-diffusion +
GAN + pixel-diffusion, with LAION/ImageNet/CelebA/COCO reals), and
bitmind/GenImage_ADM + bitmind/GenImage_glide.
scripts/build_eval_set.py
builds the resolution-matched evaluation set.
inference.py          THE entry point: python inference.py <folder> → predictions.json
pipeline.py           ingest · train · evaluate · predict · smoke · materialize-sid-set
config.yaml           the exact training configuration behind the shipped checkpoint
detector/             model · data · transforms · training · evaluation · calibration
scripts/              corpus builders, matched-set builder, shortcut probe, stream-eval
webapp/               FastAPI demo — single · 15-condition robustness · batch
extension/            Chrome extension (MV3) — right-click → check the main image
serve_demo.ps1        one command → a public Cloudflare-tunnel URL
evaluate.sh           full 15-condition eval + FP/FN montages for a checkpoint
docs/                 error-analysis note, FP/FN montages, full experiment log
demo_images/          six labelled samples (4 AI, 2 authentic) to try it on
requirements*.txt     cuda / cpu
Env vars the scripts honour: PYTHON, TTJ_DATA, DEVICE, HF_HOME,
SYCL_CACHE_DIR, DETECTOR_CHECKPOINT, DETECTOR_DEVICE.
| split | role |
|---|---|
train | fit weights |
val | watch for training failure only — never an operating-point input |
genval | one withheld generator — fits the threshold value |
calval | a different withheld generator — picks the rule (minmax_fpfn) |
holdout | the reported metric — never an input to any decision |
python -m detector.calibrate runs/<name>/best.pt \
  --genval <dir> --calval <dir> --rule minmax_fpfn --apply
Calibrating on held-out generators instead of val took recall on unseen
fakes from ~25% to ~98% with no change to AUC — it fixes the operating
point, not the model.
Ranked by what we believe would actually move the number, based on where the measurements point rather than on what sounds impressive.
We would also replace the dHash contamination check described below with a
proper perceptual-hash sweep, and re-run the SID_Set evaluation split by
full_synthetic versus tampered so that number stops conflating two tasks.
The brief specifies that COCO val2017 and DALL·E Advanced must not be used in training. None of our four training sources draws from them, and we checked rather than assumed: a difference-hash comparison of all 26,361 training reals against the 1,000 COCO images in our evaluation set found no genuine duplicate. Thirteen apparent collisions all mapped to a single near-uniform eval image (pixel std 12.3) whose hash is degenerate; direct comparison put those pairs 45/255 apart in mean absolute pixel difference — different photographs.
Separately, detector/data.py:assert_not_eval_only hard-fails if a path
marked eval_only_* reaches training or calibration, so the guarantee is
enforced in code and not only by convention.
scripts/build_corpus.py), the
native-crop + SAFE training recipe, iteration 5a/5b/6a/6b and the ablations
behind them, inference.py, the web demo, and this documentation.(Replace or extend these lines with the split your team agrees on — they are recorded here from the commit history, which is the only record this repository has.)
Code and released weights: Apache-2.0. Backbones are used under their own
public licenses (OwensLab/commfor-model-224, Apache-2.0).
Training-data note, stated plainly: one of the four training sources, Community-Forensics-Small, is licensed CC-BY-NC-SA-4.0 — non-commercial, share-alike. Model weights are not a derivative work of the training data under most readings, and this is a research/hackathon artifact, but anyone considering commercial use should evaluate that themselves rather than rely on the Apache-2.0 tag alone. SID_Set, DRAGON and GenImage carry no such restriction.



