
Papers of "A Survey on Multimodal LLMs from the Perspective of Input-Output Space Extension"
21
29 commits
updated Feb 4, 2026
README
Awesome-Multimodal-Large-Language-Models
- Based on the structure of input-output spaces, we systematically review the existing models, including main-stream models based on discrete-continuous hybrid spaces and models with unified multi-modal discrete representations.
- Readers can refer to our [📖 Preprint Paper] for detailed explanations.
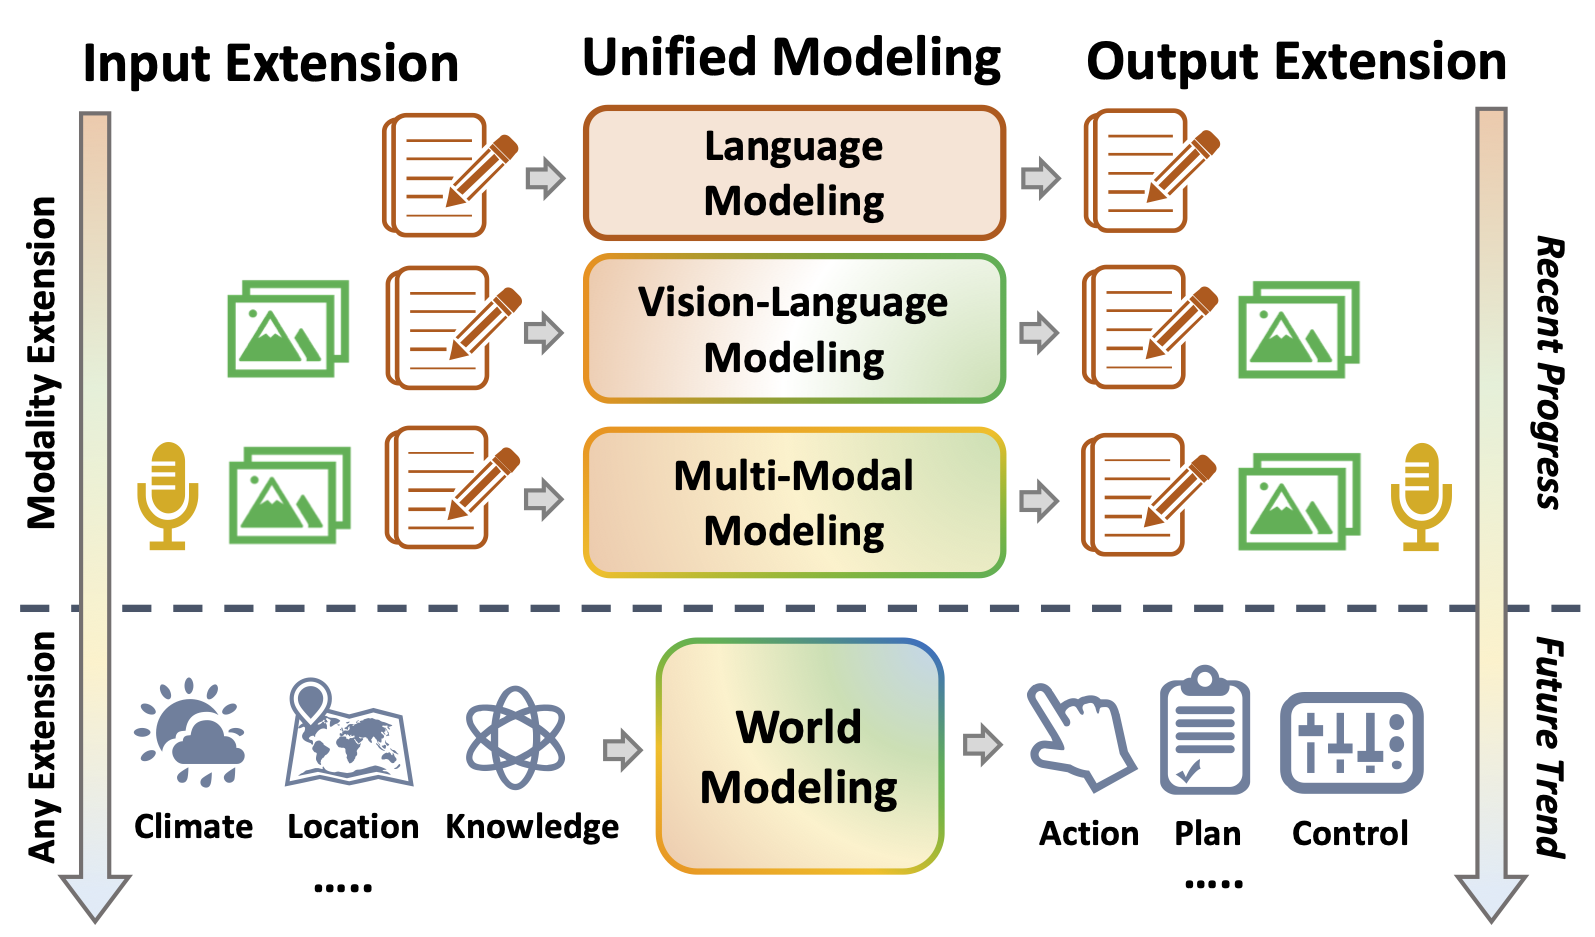
Preliminary
As presented in Figure below, the evolution of multi-modal research paradigms could be divided into three stages.
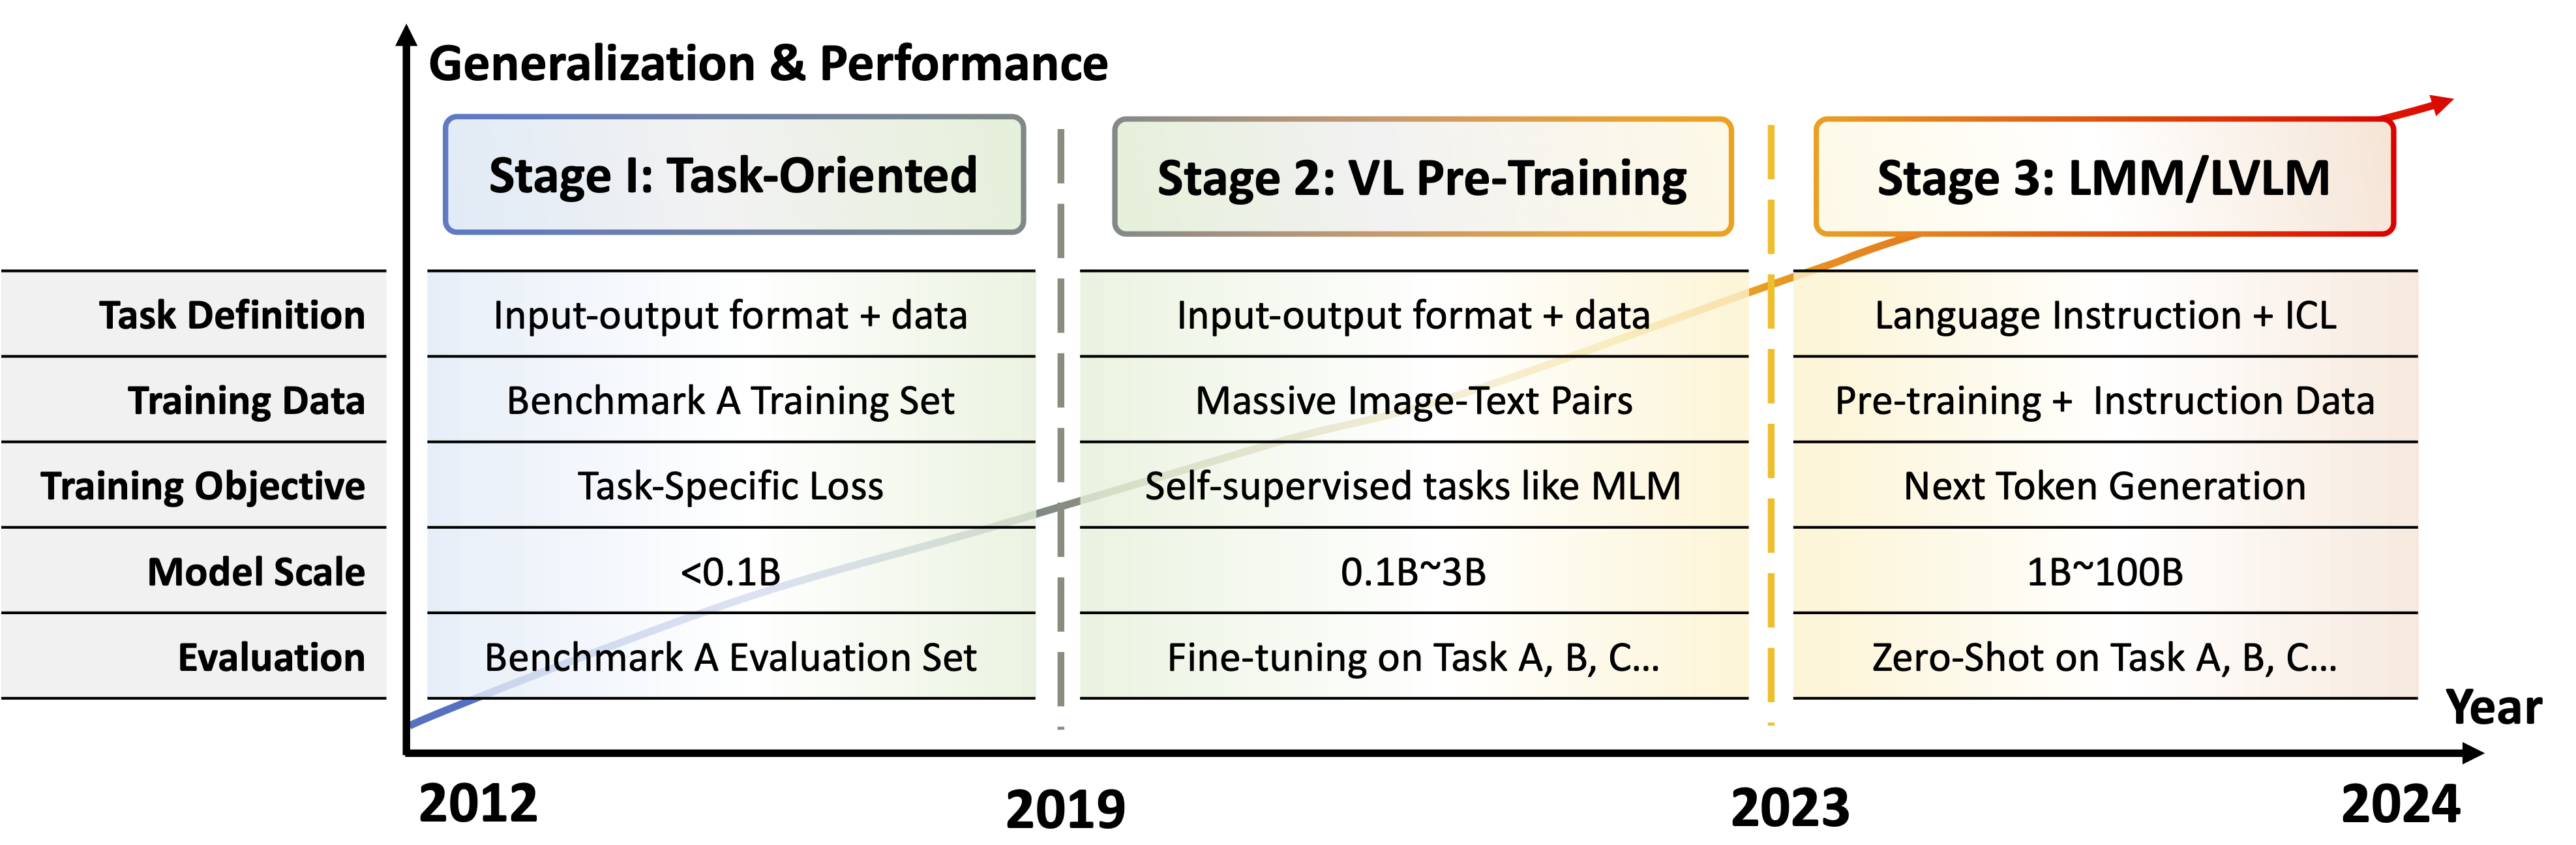
For readers to have a general picture about the development, we provide a tutorial here. The contents are summarized as follows:
- Part 1: Vision-Language Pre-Training
- Part 2: Architectures and Traning of MLLMs
- Part 3: Evaluation of MLLMs
- Part 4: Further Capability of MLLMs
- Part 5: Extension to Embodied Agents
Awesome Models (Sort by Time of Release) 📄
Modality
Text: 📝 Vision: 🖼️ Audio: 🔊 3D: 🧊
Input Type
Type A: Discrete 📝 Token + Continuous 🖼️🔊🧊 Feature
Type B: Discrete 📝 Token + Discrete 🖼️🔊🧊 Token
Output Type
Type 1: Discrete 📝 Token Only
Type 2: Discrete 📝 Token + Continuous 🖼️🔊🧊 Feature
Type 3: Discrete 📝 Token + Discrete 🖼️🔊🧊 Token
Architecture 🏗️
Large Vision-Language Models 🤗
Output Modality: 📝
| Model | Code | Input | Output | Architecture (LLM & Encoder & Conn.) | Res. | Date |
|---|---|---|---|---|---|---|
| Flamingo | 🔗 | A | 1 | Chinchilla & NFNet & Perceiver | 480 | 2022/04 |
| BLIP-2 | 🔗 | A | 1 | Flan-T5 / OPT & CLIP ViT-L / Eva-CLIP & Q-Former | 224 | 2023/01 |
| LLaMA-Adapter | 🔗 | A | 1 | LLaMA & CLIP-ViT-L/14 & MLP | 224 | 2023/03 |
| MiniGPT-4 | 🔗 | A | 1 | Vicuna & Eva-CLIP ViT-G/14 & Q-Former | 224 | 2023/04 |
| LLaVA | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Linear | 224 | 2023/04 |
| mPLUG-Owl | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Abstractor | 224 | 2023/04 |
| LLaMA-Adapter V2 | 🔗 | A | 1 | LLaMA & CLIP-ViT-L/14 & MLP | 224 | 2023/04 |
| InstructBLIP | 🔗 | A | 1 | Flan-T5 / Vicuna & Eva-CLIP ViT-G/14 & Q-Former | 224 | 2023/05 |
| Otter | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Perceiver | 224 | 2023/05 |
| LaVIN | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & MLP | 224 | 2023/05 |
| MultiModal-GPT | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Perceiver | 224 | 2023/05 |
| Shikra | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Linear | 224 | 2023/06 |
| Video-ChatGPT | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Linear | 224 | 2023/06 |
| Valley | 🔗 | A | 1 | Stable-Vicuna & CLIP ViT-L/14 & Temporal + Linear | 224 | 2023/06 |
| Lynx | 🔗 | A | 1 | Vicuna & EVA-1B & Resampler | 420 | 2023/07 |
| Qwen-VL | 🔗 | A | 1 | Qwen & OpenCLIP ViT-bigG & Cross-Attention | 448 | 2023/08 |
| BLIVA | 🔗 | A | 1 | Flan-T5 / Vicuna & Eva-CLIP ViT-G/14 & Q-Former + MLP | 224 | 2023/08 |
| IDEFICS | 🔗 | A | 1 | LLaMA & OpenCLIP ViT-H/14 & Perceiver | 224 | 2023/08 |
| OpenFlamingo | 🔗 | A | 1 | LLaMA / MPT & CLIP ViT-L/14 & Perceiver | 224 | 2023/08 |
| InternLM-XComposer | 🔗 | A | 1 | InternLM & Eva-CLIP ViT-G/14 & Perceiver | 224 | 2023/09 |
| LLaVA-1.5 | 🔗 | A | 1 | Vicuna 1.5 & CLIP ViT-L/14 & MLP | 336 | 2023/10 |
| MiniGPT-v2 | 🔗 | A | 1 | LLaMA-2 & EVA & Linear | 448 | 2023/10 |
| Fuyu-8B | 🔗 | A | 1 | Persimmon & - & Linear | ∞ | 2023/10 |
| UReader | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Abstractor | 224*20 | 2023/10 |
| CogVLM | 🔗 | A | 1 | Vicuna 1.5 & EVA2-CLIP-E & MLP | 490 | 2023/11 |
| Monkey | 🔗 | A | 1 | Qwen & OpenCLIP ViT-bigG & Cross-Attention | 896 | 2023/11 |
| ShareGPT4V | 🔗 | A | 1 | Vicuna-1.5 & CLIP ViT-L/14 & MLP | 336 | 2023/11 |
| mPLUG-Owl2 | 🔗 | A | 1 | LLaMA-2 & CLIP ViT-L/14 & Abstractor | 448 | 2023/11 |
| SPHINX | 🔗 | A | 1 | LLaMA-2 & CLIP/DINOv2 & Linear + Q-Former | 672 | 2023/11 |
| InternVL | 🔗 | A | 1 | Vicuna & InternViT & QLLaMA / MLP | 336 | 2023/12 |
| MobileVLM | 🔗 | A | 1 | MobileLLaMA & CLIP ViT-L/14 & LDP (conv) | 336 | 2023/12 |
| VILA | 🔗 | A | 1 | LLaMA-2 & CLIP ViT-L & Linear | 336 | 2023/12 |
| Osprey | 🔗 | A | 1 | Vicuna & CLIP ConvNeXt-L & MLP | 512 | 2023/12 |
| Honeybee | 🔗 | A | 1 | Vicuna-1.5 & CLIP ViT-L/14 & C/D-Abstractor | 336 | 2023/12 |
| Omni-SMoLA | - | A | 1 | UL2 & Siglip ViT-G/14 & Linear | 1064 | 2023/12 |
| LLaVA-NeXT | 🔗 | A | 1 | Vicuna/Mistral/Yi & CLIP ViT-L/14 & MLP | 672 | 2024/01 |
| InternLM-XComposer2 | 🔗 | A | 1 | InternLM-2 & CLIP ViT-L/14 & MLP | 490 | 2024/01 |
| MouSi | 🔗 | A | 1 | Vicuna-1.5 & Multi-Encoders & Poly-Expert Fusion | 1024 | 2024/01 |
| LLaVA-MoLE | 🔗 | A | 1 | Vicuna1.5 & CLIP ViT-L/14 & MLP | 336 | 2024/01 |
| MoE-LLaVA | 🔗 | A | 1 | StableL / Qwen / Phi-2 & CLIP ViT-L/14 & MLP | 336 | 2024/01 |
| MobileVLM V2 | 🔗 | A | 1 | MobileLLaMA & CLIP ViT-L/14 & LDP v2 | 336 | 2024/02 |
| Bunny | 🔗 | A | 1 | Phi/LLaMA/StableLM & SigLIP/EVA-CLIP & MLP | 1152 | 2024/02 |
| TinyLLaVA | 🔗 | A | 1 | TinyLLaMA/Phi-2/StableLM & SigLIP/CLIP & MLP | 336/384 | 2024/02 |
| SPHINX-X | 🔗 | A | 1 | Multi-LLM & CLIP/DINOv2 & Linear | 672 | 2024/02 |
| Mini-Gemini | 🔗 | A | 1 | Gemma/Vicuna/Mixtral & CLIP+ConvNext & Cross-Attn+MLP | 1536 | 2024/03 |
| DeepSeek-VL | 🔗 | A | 1 | Deepseek LLM & SigLIP-L / SAM-B & MLP | 1024 | 2024/03 |
| LLaVA-UHD | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Perceiver | 336*6 | 2024/03 |
| Yi-VL | 🔗 | A | 1 | Yi & CLIP ViT-H/14 & MLP | 448 | 2024/03 |
| MM1 | 🔗 | A | 1 | in-house LLM & CLIP ViT-H* & C-Abstractor | 1792 | 2024/03 |
| VL-Mamba | 🔗 | A | 1 | Mamba LLM & CLIP/SigLIP & VSS + MLP | 384 | 2024/03 |
| Cobra | 🔗 | A | 1 | Mamba-Zephyr & DINOv2 + SigLIP & MLP | 384 | 2024/03 |
| InternVL 1.5 | 🔗 | A | 1 | InternLM2 & InternViT-6B & MLP | 448*40 | 2024/04 |
| Phi-3-Vision | 🔗 | A | 1 | Phi-3 & CLIP ViT-L/14 & MLP | 336*16 | 2024/04 |
| PLLaVA | 🔗 | A | 1 | Vicuna/Mistral/Yi & CLIP ViT-L/14 & MLP + Pooling | 336 | 2024/04 |
| TextHawk | 🔗 | A | 1 | InternLM-1 & SigLIP-SO400M/14 & Resampler + MLP | ∞ | 2024/04 |
| Imp | 🔗 | A | 1 | Phi-2 & SigLIP & MLP | 384 | 2024/05 |
| IDEFICS2 | 🔗 | A | 1 | Mistral-v0.1 & SigLIP-SO400M/14 & Perceiver + MLP | 384*4 | 2024/05 |
| ConvLLaVA | 🔗 | A | 1 | Vicuna- & CLIP-ConvNeXt-L* & MLP | 1536 | 2024/05 |
| Ovis | 🔗 | A | 1 | LLaMA3 / Qwen1.5 & CLIP + Visual Emb. & - | 336 | 2024/05 |
| DeCo | 🔗 | A | 1 | Vicuna-1.5 & CLIP ViT-L/14 & MLP + Pooling | 336 | 2024/05 |
| CuMo | 🔗 | A | 1 | Mistral / Mixtral & CLIP ViT-L/14 & MLP | 336 | 2024/05 |
| Cambrian-1 | 🔗 | A | 1 | Vicuna/LLaMA/Yi & 4x Vision Encoders & Spatial Aggregator | 1024 | 2024/06 |
| GLM-4v | 🔗 | A | 1 | GLM4 & EVA-CLIP-E & Conv + SwiGLU | 1120 | 2024/06 |
| InternLM-XComposer-2.5 | 🔗 | A | 1 | InternLM-2 & CLIP ViT-L/14 & MLP | 560*24 | 2024/07 |
| IDEFICS3 | 🔗 | A | 1 | LLaMA 3.1 & SigLIP-SO400M/14 & Perceiver + MLP | 1820 | 2024/08 |
| mPLUG-Owl3 | 🔗 | A | 1 | Qwen2 & SigLIP-SO400M/14 & Linear | 384*6 | 2024/08 |
| CogVLM2 | 🔗 | A | 1 | LLaMA3 & EVA-CLIP-E & Conv + SwiGLU | 1344 | 2024/08 |
| CogVLM2-video | 🔗 | A | 1 | LLaMA3 & EVA-CLIP-E & Conv + SwiGLU | 224 | 2024/08 |
| LLaVA-OneVision | 🔗 | A | 1 | Qwen-2 & SigLIP-SO400M/14 & MLP | 384*36 | 2024/09 |
| Qwen2-VL | 🔗 | A | 1 | Qwen-2 & ViT-675M & MLP | ∞ | 2024/09 |
| Aria | 🔗 | A | 1 | Aria-MoE & SigLIP-SO400M & Cross-Attention + Linear | 980*n | 2024/10 |
| DeepSeek-VL2 | 🔗 | A | 1 | DeepSeekMoE & SigLIP & MLP | 384*9 | 2024/12 |
| InternVL-2.5 | 🔗 | A | 1 | InternLM2 / Qwen2... & InternViT & MLP | 448*48 | 2024/12 |
| SAIL-VL | 🔗 | A | 1 | Qwen2.5 & InternViT & MLP | 448*10 | 2025/01 |
| Qwen2.5-VL | 🔗 | A | 1 | Qwen2.5 & Modified ViT & MLP | ∞ | 2025/02 |
| Granite-Vision | 🔗 | A | 1 | Granite & SigLIP & MLP | 384*10 | 2025/02 |
| Gemma 3 | 🔗 | A | 1 | Gemma 3 & SigLIP & MLP | 896*n | 2025/03 |
| InternVL3 | 🔗 | A | 1 | InternLM3 / Qwen2.5 & InternViT & MLP | 448*48 | 2025/04 |
| Kimi-VL | 🔗 | A | 1 | MoonViT & Moolight & MLP | ∞ | 2025/06 |
| Mimo-VL | 🔗 | A | 1 | Qwen2.5-ViT & MiMo-Base & MLP | ∞ | 2025/06 |
| GLM-4.5V | 🔗 | A | 1 | GLM-4 & AIMv2 & MLP | ∞ | 2025/07 |
| InternVL3.5 | 🔗 | A | 1 | Qwen3 / GPT-OSS & InternViT & VRR + MLP | 448*48 | 2025/08 |
| Ovis2.5 | 🔗 | B | 1 | Qwen3 & SigLIP2 + Visual Embedding & - | ∞ | 2025/08 |
| VarCo-Vision-2 | 🔗 | A | 1 | Qwen3 & SigLIP-2 & MLP | 448*9 | 2025/09 |
| MiniCPM-V4.5 | 🔗 | A | 1 | Qwen3 & SigLIP & 3D Resampler | 448*9 | 2025/09 |
| Qwen3-VL | 🔗 | A | 1 | Qwen3 & SigLIP-2 & MLP | ∞ | 2025/11 |
Output Modality: 📝🖼️
| Model | Code | Input | Output | Architecture (LLM & Encoder & Decoder) | Date |
|---|---|---|---|---|---|
| GILL | 🔗 | A | 2 | OPT & CLIP ViT-L & SD | 2023/05 |
| Emu | 🔗 | A | 2 | LLaMA & EVA-02-CLIP-1B & SD | 2023/07 |
| LaVIT | 🔗 | A | 3 | LLaMA & Eva-CLIP ViT-G/14 + LaVIT Tokenizer & LaVIT De-Tokenizer | 2023/09 |
| CM3Leon | 🔗 | B | 3 | CM3Leon & Make-A-Scene & Make-A-Scene | 2023/09 |
| DreamLLM | 🔗 | A | 2 | Vicuna & CLIP ViT-L/14 & SD | 2023/09 |
| Kosmos-G | 🔗 | A | 2 | MAGNETO & CLIP ViT-L/14 & SD | 2023/10 |
| SEED-LLaMA | 🔗 | B | 3 | Vicuna / LLaMA-2 & SEED Tokenizer & SEED D e-Tokenizer | 2023/10 |
| MiniGPT-5 | 🔗 | A | 2 | Vicuna & Eva-CLIP ViT-G/14 & SD | 2023/10 |
| Emu-2 | 🔗 | A | 2 | LLaMA & EVA-02-CLIP-E-plus & SDXL | 2023/12 |
| Chameleon | 🔗 | B | 3 | Chameleon & Make-A-Scene & Make-A-Scene | 2024/05 |
| MoMa | - | B | 3 | Chameleon & Make-A-Scene & Make-A-Scene | 2024/07 |
| Show-o | 🔗 | B | 3 | Phi-1.5 & MAGVIT-v2 & MAGVIT-v2 | 2024/08 |
| Transfusion | 🔗 | A | 2 | from scratch & VAE & VAE | 2024/08 |
| VILA-U | 🔗 | B | 3 | LLaMA-2 & SigLIP + RQ-VAE & RQ-VAE | 2024/09 |
| MoMA | 🔗 | B | 3 | Chameleon & Make-A-Scene & Make-A-Scene | 2024/09 |
| Janus | 🔗 | A | 3 | DeepSeek-LLM & LlamaGen Tokenizer & LlamaGen Tokenizer | 2024/10 |
| Metaqueries | 🔗 | A | 2 | Qwen2.5 VL & QwenViT + VAE & SANA DiT | 2025/04 |
| BLIP3o | 🔗 | A | 2 | Qwen2.5 VL & QwenViT + VAE & SDXL | 2025/05 |
| Bagel | 🔗 | A | 2 | Qwen2.5 & QwenViT + VAE & VAE | 2025/05 |
| MMaDA | 🔗 | B | 3 | LLaDA & MAGVIT-v2 & MAGVIT-v2 | 2025/05 |
| Qwen-Image | 🔗 | A | 2 | Qwen2.5 VL & QwenViT + VAE & MMDiT | 2025/08 |
| BLIP3o-Next | 🔗 | A | 2 | Qwen2.5 VL & VQ-Siglip2 + VAE & SANA DiT | 2025/10 |
Large Audio-Language Models 🤗
| Model | Code | Input | Output | Output Modality | Architecture (LLM & Encoder & Decoder) | Date |
|---|---|---|---|---|---|---|
| SpeechGPT | 🔗 | B | 3 | 📝🔊 | LLaMA & HuBERT & Unit Vocoder | 2023/05 |
| Speech-LLaMA | - | A | 1 | 📝 | LLaMA & CTC compressor & - | 2023/07 |
| SALMONN | 🔗 | A | 1 | 📝 | Vicuna & Whisper-Large-v2 + BEATs & - | 2023/10 |
| Qwen-Audio | 🔗 | A | 1 | 📝 | Qwen & Whisper-Large-v2 & - | 2023/11 |
| SpeechGPT-Gen | 🔗 | B | 3 | 📝🔊 | LLaMA-2 & SpeechTokenizer & SpeechTokenizer | 2024/01 |
| SLAM-ASR | 🔗 | A | 1 | 📝 | LLaMA-2 & HuBERT & - | 2024/02 |
| WavLLM | 🔗 | A | 1 | 📝 | LLaMA-2 & Whisper-Large-v2 + WavLM-Base & - | 2024/04 |
| SpeechVerse | - | A | 1 | 📝 | Flan-T5-XL & WavLM-Large / Best-RQ & - | 2024/05 |
| Qwen2-Audio | 🔗 | A | 1 | 📝 | Qwen & Whisper-Large-v3 & - | 2024/07 |
| LLaMA-Omni | 🔗 | A | 2 | 📝🔊 | LLaMA-3.1 & Whisper-Large-v3 & Unit Vocoder | 2024/09 |
| SpeechGPT-Gen | 🔗 | B | 3 | 📝🔊 | LLaMA-2 & SpeechTokenizer & SpeechTokenizer | 2024/09 |
| Moshi | 🔗 | B | 3 | 📝🔊 | Helium & Mimi & Mimi | 2024/10 |
| GLM-4-Voice | 🔗 | B | 3 | 📝🔊 | GLM-4 & Whisper-Large-v3 + VQ & CosyVoice | 2024/12 |
| Slam-Omni | 🔗 | A | 3 | 📝🔊 | Qwen2 & Whisper-small & CosyVoice | 2024/12 |
| Step-Audio | 🔗 | B | 3 | 📝🔊 | Step-1 & Paraformer + CosyVoice & Step-A-TTS-3B | 2025/02 |
| Baichuan-Audio | 🔗 | B | 3 | 📝🔊 | Qwen2.5 (Specialized) & Baichuan-A Tokenizer & Baichuan-A Decoder | 2025/02 |
| Kimi-Audio | 🔗 | B | 3 | 📝🔊 | Qwen2.5 & GLM-4-Voice Tokenizer + Whisper-v3 & MoonCast | 2025/04 |
| LLaMA-Omni2 | 🔗 | A | 2 | 📝🔊 | Qwen2.5 & Whisper-Large-v3 & CosyVoice 2 | 2025/05 |
| Audio Flamingo 3 | 🔗 | A | 1 | 📝🔊 | Qwen2.5 & AF-Whisper & Streaming TTS | 2025/07 |
| MiMo-Audio | 🔗 | B | 3 | 📝🔊 | MiMo-7B-Base & MiMo-A-Tokenizer & MiMo-A-Tokenizer | 2025/09 |
Any-to-Any Modality Models 🤗
| Model | Code | Input | Input Modality | Output | Output Modality | Architecture (LLM & Encoder & Decoder) | Date |
|---|---|---|---|---|---|---|---|
| PandaGPT | 🔗 | A | 📝🖼️🔊... | 1 | 📝 | Vicuna & ImageBind & - | 2023/05 |
| ImageBind-LLM | 🔗 | A | 📝🖼️🔊🧊 | 1 | 📝 | Chinese-LLaMA & ImageBind + PointBind & - | 2023/09 |
| NExT-GPT | 🔗 | A | 📝🖼️🔊 | 2 | 📝🖼️🔊 | Vicuna & ImageBind & SD + AudioLDM + Zeriscope | 2023/09 |
| CoDi-2 | 🔗 | A | 📝🖼️🔊 | 2 | 📝🖼️🔊 | LLaMA-2 & ImageBind & SD + AudioLDM2 + zeroscope v2 | 2023/11 |
| Unified-IO 2 | 🔗 | A | 📝🖼️🔊 | 3 | 📝🖼️🔊 | UnifiedIO2 & OpenCLIP ViT-B + AST & VQ-GAN + ViT-VQGAN | 2023/12 |
| AnyGPT | 🔗 | B | 📝🖼️🔊 | 3 | 📝🖼️🔊 | LLaMA-2 & SEED + Encodec + SpeechTokenizer & SEED + Encodec + SpeechTokenizer | 2024/02 |
| Uni-MoE | 🔗 | A | 📝🖼️🔊 | 1 | 📝 | LLaMA & CLIP ViT-L/14 + Whisper-small + BEATs & - | 2024/05 |
| Mini-Omni2 | 🔗 | A | 📝🖼️🔊 | 3 | 📝🔊 | Qwen2 & CLIP ViT-B/32 + Whisper-small & SNAC | 2024/10 |
| Baichuan-Omni-1.5 | 🔗 | A | 📝🖼️🔊 | 1 | 📝🔊 | Baichuan LLM & QwenViT + Baichuan-A-Tokenizer & Baichuan-A-Tokenizer | 2025/01 |
| MiniCPM-o 2.6 | 🔗 | A | 📝🖼️🔊 | 2 | 📝🔊 | Qwen2.5 & SigLip-400M + Whisper-medium-300M & ChatTTS-200M | 2025/01 |
| Ola | 🔗 | A | 📝🖼️🔊 | 1 | 📝🔊 | Qwen2.5 & OryxViT + Whisper-V3 + BEATs & CosyVoice | 2025/02 |
| Phi-4-Multimodal | 🔗 | A | 📝🖼️🔊 | 1 | 📝 | Phi-4 & SigLIP + ConFormer & - | 2025/03 |
| Qwen2.5-Omni | 🔗 | A | 📝🖼️🔊 | 2 | 📝🔊 | Qwen2.5 & QwenViT + Whisper-large-v3 & Codec Decoder | 2025/05 |
| ShapeLLM-Omni | 🔗 | A | 📝🖼️🧊 | 3 | 📝🧊 | Qwen2.5 VL & QwenViT + 3D VQVAE & 3D VQVAE | 2025/06 |
| UniUGG | 🔗 | A | 📝🖼️ | 2 | 📝🧊 | Qwen2.5 & RADIOv2.5-L + Spatial-VAE & Unet + Spatial-VAE | 2025/08 |
| Qwen3-Omni | 🔗 | A | 📝🖼️🔊 | 2 | 📝🔊 | Qwen3 & QwenViT + AuT & Codec Decoder | 2025/09 |
| Next-Omni | - | B | 📝🖼️🔊 | 3 | 📝🖼️🔊 | Qwen2.5 & VQ-Whisper-Turbo + VQ-CLIP & VQ-Whisper-Turbo + VQ-CLIP | 2025/10 |
| Omni-View | 🔗 | A | 📝🖼️ | 2 | 📝🖼️🧊 | Qwen2.5 VL & SigLIP + VAE & VAE + VGGT | 2025/11 |
| UniMoE-2.0-Omni | 🔗 | A | 📝🖼️🔊 | 3 | 📝🖼️🔊 | Qwen2.5-7B & SigLIP + Whisper-Large-v3 + VAE & Codec Decoder + DiT | 2025/11 |
This repository includes a complete and structured overview of the architectural designs of existing MLLMs. For the 🗂️ Original Table, please refer to Google Sheets Link ⭐.
Training Details 🔧
Due to the length and complexity of the training details, we provide them in a separate table. Please refer to the ⚙️ Model Training Settings Table: Google Sheets Link ⭐
Contributing
If you find missing/incorrect entries, feel free to open a PR:
- Add the paper link
- Add code link (if available)
- Keep the table style consistent
License
This repository is intended for research and educational purposes. Please follow the license of each referenced project/paper.


Similar repos


Papers of "A Survey on Multimodal LLMs from the Perspective of Input-Output Space Extension"
21
29 commits
updated Feb 4, 2026
README
Awesome-Multimodal-Large-Language-Models
- Based on the structure of input-output spaces, we systematically review the existing models, including main-stream models based on discrete-continuous hybrid spaces and models with unified multi-modal discrete representations.
- Readers can refer to our [📖 Preprint Paper] for detailed explanations.
Preliminary
As presented in Figure below, the evolution of multi-modal research paradigms could be divided into three stages.
For readers to have a general picture about the development, we provide a tutorial here. The contents are summarized as follows:
- Part 1: Vision-Language Pre-Training
- Part 2: Architectures and Traning of MLLMs
- Part 3: Evaluation of MLLMs
- Part 4: Further Capability of MLLMs
- Part 5: Extension to Embodied Agents
Awesome Models (Sort by Time of Release) 📄
Modality
Text: 📝 Vision: 🖼️ Audio: 🔊 3D: 🧊
Input Type
Type A: Discrete 📝 Token + Continuous 🖼️🔊🧊 Feature
Type B: Discrete 📝 Token + Discrete 🖼️🔊🧊 Token
Output Type
Type 1: Discrete 📝 Token Only
Type 2: Discrete 📝 Token + Continuous 🖼️🔊🧊 Feature
Type 3: Discrete 📝 Token + Discrete 🖼️🔊🧊 Token
Architecture 🏗️
Large Vision-Language Models 🤗
Output Modality: 📝
| Model | Code | Input | Output | Architecture (LLM & Encoder & Conn.) | Res. | Date |
|---|---|---|---|---|---|---|
| Flamingo | 🔗 | A | 1 | Chinchilla & NFNet & Perceiver | 480 | 2022/04 |
| BLIP-2 | 🔗 | A | 1 | Flan-T5 / OPT & CLIP ViT-L / Eva-CLIP & Q-Former | 224 | 2023/01 |
| LLaMA-Adapter | 🔗 | A | 1 | LLaMA & CLIP-ViT-L/14 & MLP | 224 | 2023/03 |
| MiniGPT-4 | 🔗 | A | 1 | Vicuna & Eva-CLIP ViT-G/14 & Q-Former | 224 | 2023/04 |
| LLaVA | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Linear | 224 | 2023/04 |
| mPLUG-Owl | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Abstractor | 224 | 2023/04 |
| LLaMA-Adapter V2 | 🔗 | A | 1 | LLaMA & CLIP-ViT-L/14 & MLP | 224 | 2023/04 |
| InstructBLIP | 🔗 | A | 1 | Flan-T5 / Vicuna & Eva-CLIP ViT-G/14 & Q-Former | 224 | 2023/05 |
| Otter | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Perceiver | 224 | 2023/05 |
| LaVIN | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & MLP | 224 | 2023/05 |
| MultiModal-GPT | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Perceiver | 224 | 2023/05 |
| Shikra | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Linear | 224 | 2023/06 |
| Video-ChatGPT | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Linear | 224 | 2023/06 |
| Valley | 🔗 | A | 1 | Stable-Vicuna & CLIP ViT-L/14 & Temporal + Linear | 224 | 2023/06 |
| Lynx | 🔗 | A | 1 | Vicuna & EVA-1B & Resampler | 420 | 2023/07 |
| Qwen-VL | 🔗 | A | 1 | Qwen & OpenCLIP ViT-bigG & Cross-Attention | 448 | 2023/08 |
| BLIVA | 🔗 | A | 1 | Flan-T5 / Vicuna & Eva-CLIP ViT-G/14 & Q-Former + MLP | 224 | 2023/08 |
| IDEFICS | 🔗 | A | 1 | LLaMA & OpenCLIP ViT-H/14 & Perceiver | 224 | 2023/08 |
| OpenFlamingo | 🔗 | A | 1 | LLaMA / MPT & CLIP ViT-L/14 & Perceiver | 224 | 2023/08 |
| InternLM-XComposer | 🔗 | A | 1 | InternLM & Eva-CLIP ViT-G/14 & Perceiver | 224 | 2023/09 |
| LLaVA-1.5 | 🔗 | A | 1 | Vicuna 1.5 & CLIP ViT-L/14 & MLP | 336 | 2023/10 |
| MiniGPT-v2 | 🔗 | A | 1 | LLaMA-2 & EVA & Linear | 448 | 2023/10 |
| Fuyu-8B | 🔗 | A | 1 | Persimmon & - & Linear | ∞ | 2023/10 |
| UReader | 🔗 | A | 1 | LLaMA & CLIP ViT-L/14 & Abstractor | 224*20 | 2023/10 |
| CogVLM | 🔗 | A | 1 | Vicuna 1.5 & EVA2-CLIP-E & MLP | 490 | 2023/11 |
| Monkey | 🔗 | A | 1 | Qwen & OpenCLIP ViT-bigG & Cross-Attention | 896 | 2023/11 |
| ShareGPT4V | 🔗 | A | 1 | Vicuna-1.5 & CLIP ViT-L/14 & MLP | 336 | 2023/11 |
| mPLUG-Owl2 | 🔗 | A | 1 | LLaMA-2 & CLIP ViT-L/14 & Abstractor | 448 | 2023/11 |
| SPHINX | 🔗 | A | 1 | LLaMA-2 & CLIP/DINOv2 & Linear + Q-Former | 672 | 2023/11 |
| InternVL | 🔗 | A | 1 | Vicuna & InternViT & QLLaMA / MLP | 336 | 2023/12 |
| MobileVLM | 🔗 | A | 1 | MobileLLaMA & CLIP ViT-L/14 & LDP (conv) | 336 | 2023/12 |
| VILA | 🔗 | A | 1 | LLaMA-2 & CLIP ViT-L & Linear | 336 | 2023/12 |
| Osprey | 🔗 | A | 1 | Vicuna & CLIP ConvNeXt-L & MLP | 512 | 2023/12 |
| Honeybee | 🔗 | A | 1 | Vicuna-1.5 & CLIP ViT-L/14 & C/D-Abstractor | 336 | 2023/12 |
| Omni-SMoLA | - | A | 1 | UL2 & Siglip ViT-G/14 & Linear | 1064 | 2023/12 |
| LLaVA-NeXT | 🔗 | A | 1 | Vicuna/Mistral/Yi & CLIP ViT-L/14 & MLP | 672 | 2024/01 |
| InternLM-XComposer2 | 🔗 | A | 1 | InternLM-2 & CLIP ViT-L/14 & MLP | 490 | 2024/01 |
| MouSi | 🔗 | A | 1 | Vicuna-1.5 & Multi-Encoders & Poly-Expert Fusion | 1024 | 2024/01 |
| LLaVA-MoLE | 🔗 | A | 1 | Vicuna1.5 & CLIP ViT-L/14 & MLP | 336 | 2024/01 |
| MoE-LLaVA | 🔗 | A | 1 | StableL / Qwen / Phi-2 & CLIP ViT-L/14 & MLP | 336 | 2024/01 |
| MobileVLM V2 | 🔗 | A | 1 | MobileLLaMA & CLIP ViT-L/14 & LDP v2 | 336 | 2024/02 |
| Bunny | 🔗 | A | 1 | Phi/LLaMA/StableLM & SigLIP/EVA-CLIP & MLP | 1152 | 2024/02 |
| TinyLLaVA | 🔗 | A | 1 | TinyLLaMA/Phi-2/StableLM & SigLIP/CLIP & MLP | 336/384 | 2024/02 |
| SPHINX-X | 🔗 | A | 1 | Multi-LLM & CLIP/DINOv2 & Linear | 672 | 2024/02 |
| Mini-Gemini | 🔗 | A | 1 | Gemma/Vicuna/Mixtral & CLIP+ConvNext & Cross-Attn+MLP | 1536 | 2024/03 |
| DeepSeek-VL | 🔗 | A | 1 | Deepseek LLM & SigLIP-L / SAM-B & MLP | 1024 | 2024/03 |
| LLaVA-UHD | 🔗 | A | 1 | Vicuna & CLIP ViT-L/14 & Perceiver | 336*6 | 2024/03 |
| Yi-VL | 🔗 | A | 1 | Yi & CLIP ViT-H/14 & MLP | 448 | 2024/03 |
| MM1 | 🔗 | A | 1 | in-house LLM & CLIP ViT-H* & C-Abstractor | 1792 | 2024/03 |
| VL-Mamba | 🔗 | A | 1 | Mamba LLM & CLIP/SigLIP & VSS + MLP | 384 | 2024/03 |
| Cobra | 🔗 | A | 1 | Mamba-Zephyr & DINOv2 + SigLIP & MLP | 384 | 2024/03 |
| InternVL 1.5 | 🔗 | A | 1 | InternLM2 & InternViT-6B & MLP | 448*40 | 2024/04 |
| Phi-3-Vision | 🔗 | A | 1 | Phi-3 & CLIP ViT-L/14 & MLP | 336*16 | 2024/04 |
| PLLaVA | 🔗 | A | 1 | Vicuna/Mistral/Yi & CLIP ViT-L/14 & MLP + Pooling | 336 | 2024/04 |
| TextHawk | 🔗 | A | 1 | InternLM-1 & SigLIP-SO400M/14 & Resampler + MLP | ∞ | 2024/04 |
| Imp | 🔗 | A | 1 | Phi-2 & SigLIP & MLP | 384 | 2024/05 |
| IDEFICS2 | 🔗 | A | 1 | Mistral-v0.1 & SigLIP-SO400M/14 & Perceiver + MLP | 384*4 | 2024/05 |
| ConvLLaVA | 🔗 | A | 1 | Vicuna- & CLIP-ConvNeXt-L* & MLP | 1536 | 2024/05 |
| Ovis | 🔗 | A | 1 | LLaMA3 / Qwen1.5 & CLIP + Visual Emb. & - | 336 | 2024/05 |
| DeCo | 🔗 | A | 1 | Vicuna-1.5 & CLIP ViT-L/14 & MLP + Pooling | 336 | 2024/05 |
| CuMo | 🔗 | A | 1 | Mistral / Mixtral & CLIP ViT-L/14 & MLP | 336 | 2024/05 |
| Cambrian-1 | 🔗 | A | 1 | Vicuna/LLaMA/Yi & 4x Vision Encoders & Spatial Aggregator | 1024 | 2024/06 |
| GLM-4v | 🔗 | A | 1 | GLM4 & EVA-CLIP-E & Conv + SwiGLU | 1120 | 2024/06 |
| InternLM-XComposer-2.5 | 🔗 | A | 1 | InternLM-2 & CLIP ViT-L/14 & MLP | 560*24 | 2024/07 |
| IDEFICS3 | 🔗 | A | 1 | LLaMA 3.1 & SigLIP-SO400M/14 & Perceiver + MLP | 1820 | 2024/08 |
| mPLUG-Owl3 | 🔗 | A | 1 | Qwen2 & SigLIP-SO400M/14 & Linear | 384*6 | 2024/08 |
| CogVLM2 | 🔗 | A | 1 | LLaMA3 & EVA-CLIP-E & Conv + SwiGLU | 1344 | 2024/08 |
| CogVLM2-video | 🔗 | A | 1 | LLaMA3 & EVA-CLIP-E & Conv + SwiGLU | 224 | 2024/08 |
| LLaVA-OneVision | 🔗 | A | 1 | Qwen-2 & SigLIP-SO400M/14 & MLP | 384*36 | 2024/09 |
| Qwen2-VL | 🔗 | A | 1 | Qwen-2 & ViT-675M & MLP | ∞ | 2024/09 |
| Aria | 🔗 | A | 1 | Aria-MoE & SigLIP-SO400M & Cross-Attention + Linear | 980*n | 2024/10 |
| DeepSeek-VL2 | 🔗 | A | 1 | DeepSeekMoE & SigLIP & MLP | 384*9 | 2024/12 |
| InternVL-2.5 | 🔗 | A | 1 | InternLM2 / Qwen2... & InternViT & MLP | 448*48 | 2024/12 |
| SAIL-VL | 🔗 | A | 1 | Qwen2.5 & InternViT & MLP | 448*10 | 2025/01 |
| Qwen2.5-VL | 🔗 | A | 1 | Qwen2.5 & Modified ViT & MLP | ∞ | 2025/02 |
| Granite-Vision | 🔗 | A | 1 | Granite & SigLIP & MLP | 384*10 | 2025/02 |
| Gemma 3 | 🔗 | A | 1 | Gemma 3 & SigLIP & MLP | 896*n | 2025/03 |
| InternVL3 | 🔗 | A | 1 | InternLM3 / Qwen2.5 & InternViT & MLP | 448*48 | 2025/04 |
| Kimi-VL | 🔗 | A | 1 | MoonViT & Moolight & MLP | ∞ | 2025/06 |
| Mimo-VL | 🔗 | A | 1 | Qwen2.5-ViT & MiMo-Base & MLP | ∞ | 2025/06 |
| GLM-4.5V | 🔗 | A | 1 | GLM-4 & AIMv2 & MLP | ∞ | 2025/07 |
| InternVL3.5 | 🔗 | A | 1 | Qwen3 / GPT-OSS & InternViT & VRR + MLP | 448*48 | 2025/08 |
| Ovis2.5 | 🔗 | B | 1 | Qwen3 & SigLIP2 + Visual Embedding & - | ∞ | 2025/08 |
| VarCo-Vision-2 | 🔗 | A | 1 | Qwen3 & SigLIP-2 & MLP | 448*9 | 2025/09 |
| MiniCPM-V4.5 | 🔗 | A | 1 | Qwen3 & SigLIP & 3D Resampler | 448*9 | 2025/09 |
| Qwen3-VL | 🔗 | A | 1 | Qwen3 & SigLIP-2 & MLP | ∞ | 2025/11 |
Output Modality: 📝🖼️
| Model | Code | Input | Output | Architecture (LLM & Encoder & Decoder) | Date |
|---|---|---|---|---|---|
| GILL | 🔗 | A | 2 | OPT & CLIP ViT-L & SD | 2023/05 |
| Emu | 🔗 | A | 2 | LLaMA & EVA-02-CLIP-1B & SD | 2023/07 |
| LaVIT | 🔗 | A | 3 | LLaMA & Eva-CLIP ViT-G/14 + LaVIT Tokenizer & LaVIT De-Tokenizer | 2023/09 |
| CM3Leon | 🔗 | B | 3 | CM3Leon & Make-A-Scene & Make-A-Scene | 2023/09 |
| DreamLLM | 🔗 | A | 2 | Vicuna & CLIP ViT-L/14 & SD | 2023/09 |
| Kosmos-G | 🔗 | A | 2 | MAGNETO & CLIP ViT-L/14 & SD | 2023/10 |
| SEED-LLaMA | 🔗 | B | 3 | Vicuna / LLaMA-2 & SEED Tokenizer & SEED D e-Tokenizer | 2023/10 |
| MiniGPT-5 | 🔗 | A | 2 | Vicuna & Eva-CLIP ViT-G/14 & SD | 2023/10 |
| Emu-2 | 🔗 | A | 2 | LLaMA & EVA-02-CLIP-E-plus & SDXL | 2023/12 |
| Chameleon | 🔗 | B | 3 | Chameleon & Make-A-Scene & Make-A-Scene | 2024/05 |
| MoMa | - | B | 3 | Chameleon & Make-A-Scene & Make-A-Scene | 2024/07 |
| Show-o | 🔗 | B | 3 | Phi-1.5 & MAGVIT-v2 & MAGVIT-v2 | 2024/08 |
| Transfusion | 🔗 | A | 2 | from scratch & VAE & VAE | 2024/08 |
| VILA-U | 🔗 | B | 3 | LLaMA-2 & SigLIP + RQ-VAE & RQ-VAE | 2024/09 |
| MoMA | 🔗 | B | 3 | Chameleon & Make-A-Scene & Make-A-Scene | 2024/09 |
| Janus | 🔗 | A | 3 | DeepSeek-LLM & LlamaGen Tokenizer & LlamaGen Tokenizer | 2024/10 |
| Metaqueries | 🔗 | A | 2 | Qwen2.5 VL & QwenViT + VAE & SANA DiT | 2025/04 |
| BLIP3o | 🔗 | A | 2 | Qwen2.5 VL & QwenViT + VAE & SDXL | 2025/05 |
| Bagel | 🔗 | A | 2 | Qwen2.5 & QwenViT + VAE & VAE | 2025/05 |
| MMaDA | 🔗 | B | 3 | LLaDA & MAGVIT-v2 & MAGVIT-v2 | 2025/05 |
| Qwen-Image | 🔗 | A | 2 | Qwen2.5 VL & QwenViT + VAE & MMDiT | 2025/08 |
| BLIP3o-Next | 🔗 | A | 2 | Qwen2.5 VL & VQ-Siglip2 + VAE & SANA DiT | 2025/10 |
Large Audio-Language Models 🤗
| Model | Code | Input | Output | Output Modality | Architecture (LLM & Encoder & Decoder) | Date |
|---|---|---|---|---|---|---|
| SpeechGPT | 🔗 | B | 3 | 📝🔊 | LLaMA & HuBERT & Unit Vocoder | 2023/05 |
| Speech-LLaMA | - | A | 1 | 📝 | LLaMA & CTC compressor & - | 2023/07 |
| SALMONN | 🔗 | A | 1 | 📝 | Vicuna & Whisper-Large-v2 + BEATs & - | 2023/10 |
| Qwen-Audio | 🔗 | A | 1 | 📝 | Qwen & Whisper-Large-v2 & - | 2023/11 |
| SpeechGPT-Gen | 🔗 | B | 3 | 📝🔊 | LLaMA-2 & SpeechTokenizer & SpeechTokenizer | 2024/01 |
| SLAM-ASR | 🔗 | A | 1 | 📝 | LLaMA-2 & HuBERT & - | 2024/02 |
| WavLLM | 🔗 | A | 1 | 📝 | LLaMA-2 & Whisper-Large-v2 + WavLM-Base & - | 2024/04 |
| SpeechVerse | - | A | 1 | 📝 | Flan-T5-XL & WavLM-Large / Best-RQ & - | 2024/05 |
| Qwen2-Audio | 🔗 | A | 1 | 📝 | Qwen & Whisper-Large-v3 & - | 2024/07 |
| LLaMA-Omni | 🔗 | A | 2 | 📝🔊 | LLaMA-3.1 & Whisper-Large-v3 & Unit Vocoder | 2024/09 |
| SpeechGPT-Gen | 🔗 | B | 3 | 📝🔊 | LLaMA-2 & SpeechTokenizer & SpeechTokenizer | 2024/09 |
| Moshi | 🔗 | B | 3 | 📝🔊 | Helium & Mimi & Mimi | 2024/10 |
| GLM-4-Voice | 🔗 | B | 3 | 📝🔊 | GLM-4 & Whisper-Large-v3 + VQ & CosyVoice | 2024/12 |
| Slam-Omni | 🔗 | A | 3 | 📝🔊 | Qwen2 & Whisper-small & CosyVoice | 2024/12 |
| Step-Audio | 🔗 | B | 3 | 📝🔊 | Step-1 & Paraformer + CosyVoice & Step-A-TTS-3B | 2025/02 |
| Baichuan-Audio | 🔗 | B | 3 | 📝🔊 | Qwen2.5 (Specialized) & Baichuan-A Tokenizer & Baichuan-A Decoder | 2025/02 |
| Kimi-Audio | 🔗 | B | 3 | 📝🔊 | Qwen2.5 & GLM-4-Voice Tokenizer + Whisper-v3 & MoonCast | 2025/04 |
| LLaMA-Omni2 | 🔗 | A | 2 | 📝🔊 | Qwen2.5 & Whisper-Large-v3 & CosyVoice 2 | 2025/05 |
| Audio Flamingo 3 | 🔗 | A | 1 | 📝🔊 | Qwen2.5 & AF-Whisper & Streaming TTS | 2025/07 |
| MiMo-Audio | 🔗 | B | 3 | 📝🔊 | MiMo-7B-Base & MiMo-A-Tokenizer & MiMo-A-Tokenizer | 2025/09 |
Any-to-Any Modality Models 🤗
| Model | Code | Input | Input Modality | Output | Output Modality | Architecture (LLM & Encoder & Decoder) | Date |
|---|---|---|---|---|---|---|---|
| PandaGPT | 🔗 | A | 📝🖼️🔊... | 1 | 📝 | Vicuna & ImageBind & - | 2023/05 |
| ImageBind-LLM | 🔗 | A | 📝🖼️🔊🧊 | 1 | 📝 | Chinese-LLaMA & ImageBind + PointBind & - | 2023/09 |
| NExT-GPT | 🔗 | A | 📝🖼️🔊 | 2 | 📝🖼️🔊 | Vicuna & ImageBind & SD + AudioLDM + Zeriscope | 2023/09 |
| CoDi-2 | 🔗 | A | 📝🖼️🔊 | 2 | 📝🖼️🔊 | LLaMA-2 & ImageBind & SD + AudioLDM2 + zeroscope v2 | 2023/11 |
| Unified-IO 2 | 🔗 | A | 📝🖼️🔊 | 3 | 📝🖼️🔊 | UnifiedIO2 & OpenCLIP ViT-B + AST & VQ-GAN + ViT-VQGAN | 2023/12 |
| AnyGPT | 🔗 | B | 📝🖼️🔊 | 3 | 📝🖼️🔊 | LLaMA-2 & SEED + Encodec + SpeechTokenizer & SEED + Encodec + SpeechTokenizer | 2024/02 |
| Uni-MoE | 🔗 | A | 📝🖼️🔊 | 1 | 📝 | LLaMA & CLIP ViT-L/14 + Whisper-small + BEATs & - | 2024/05 |
| Mini-Omni2 | 🔗 | A | 📝🖼️🔊 | 3 | 📝🔊 | Qwen2 & CLIP ViT-B/32 + Whisper-small & SNAC | 2024/10 |
| Baichuan-Omni-1.5 | 🔗 | A | 📝🖼️🔊 | 1 | 📝🔊 | Baichuan LLM & QwenViT + Baichuan-A-Tokenizer & Baichuan-A-Tokenizer | 2025/01 |
| MiniCPM-o 2.6 | 🔗 | A | 📝🖼️🔊 | 2 | 📝🔊 | Qwen2.5 & SigLip-400M + Whisper-medium-300M & ChatTTS-200M | 2025/01 |
| Ola | 🔗 | A | 📝🖼️🔊 | 1 | 📝🔊 | Qwen2.5 & OryxViT + Whisper-V3 + BEATs & CosyVoice | 2025/02 |
| Phi-4-Multimodal | 🔗 | A | 📝🖼️🔊 | 1 | 📝 | Phi-4 & SigLIP + ConFormer & - | 2025/03 |
| Qwen2.5-Omni | 🔗 | A | 📝🖼️🔊 | 2 | 📝🔊 | Qwen2.5 & QwenViT + Whisper-large-v3 & Codec Decoder | 2025/05 |
| ShapeLLM-Omni | 🔗 | A | 📝🖼️🧊 | 3 | 📝🧊 | Qwen2.5 VL & QwenViT + 3D VQVAE & 3D VQVAE | 2025/06 |
| UniUGG | 🔗 | A | 📝🖼️ | 2 | 📝🧊 | Qwen2.5 & RADIOv2.5-L + Spatial-VAE & Unet + Spatial-VAE | 2025/08 |
| Qwen3-Omni | 🔗 | A | 📝🖼️🔊 | 2 | 📝🔊 | Qwen3 & QwenViT + AuT & Codec Decoder | 2025/09 |
| Next-Omni | - | B | 📝🖼️🔊 | 3 | 📝🖼️🔊 | Qwen2.5 & VQ-Whisper-Turbo + VQ-CLIP & VQ-Whisper-Turbo + VQ-CLIP | 2025/10 |
| Omni-View | 🔗 | A | 📝🖼️ | 2 | 📝🖼️🧊 | Qwen2.5 VL & SigLIP + VAE & VAE + VGGT | 2025/11 |
| UniMoE-2.0-Omni | 🔗 | A | 📝🖼️🔊 | 3 | 📝🖼️🔊 | Qwen2.5-7B & SigLIP + Whisper-Large-v3 + VAE & Codec Decoder + DiT | 2025/11 |
This repository includes a complete and structured overview of the architectural designs of existing MLLMs. For the 🗂️ Original Table, please refer to Google Sheets Link ⭐.
Training Details 🔧
Due to the length and complexity of the training details, we provide them in a separate table. Please refer to the ⚙️ Model Training Settings Table: Google Sheets Link ⭐
Contributing
If you find missing/incorrect entries, feel free to open a PR:
- Add the paper link
- Add code link (if available)
- Keep the table style consistent
License
This repository is intended for research and educational purposes. Please follow the license of each referenced project/paper.