
README
Efficient-Multimodal-LLMs-Survey
Efficient Multimodal Large Language Models: A Survey [arXiv]
Yizhang Jin12, Jian Li1, Yexin Liu3, Tianjun Gu4, Kai Wu1, Zhengkai Jiang1, Muyang He3, Bo Zhao3, Xin Tan4, Zhenye Gan1, Yabiao Wang1, Chengjie Wang1, Lizhuang Ma2
1Tencent YouTu Lab, 2SJTU, 3BAAI, 4ECNU
⚡We will actively maintain this repository and incorporate new research as it emerges. If you have any questions, please contact swordli@tencent.com. Welcome to collaborate on academic research and writing papers together..
@misc{jin2024efficient,
      title={Efficient Multimodal Large Language Models: A Survey},
      author={Yizhang Jin and Jian Li and Yexin Liu and Tianjun Gu and Kai Wu and Zhengkai Jiang and Muyang He and Bo Zhao and Xin Tan and Zhenye Gan and Yabiao Wang and Chengjie Wang and Lizhuang Ma},
      year={2024},
      eprint={2405.10739},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
📌 What is This Survey About?
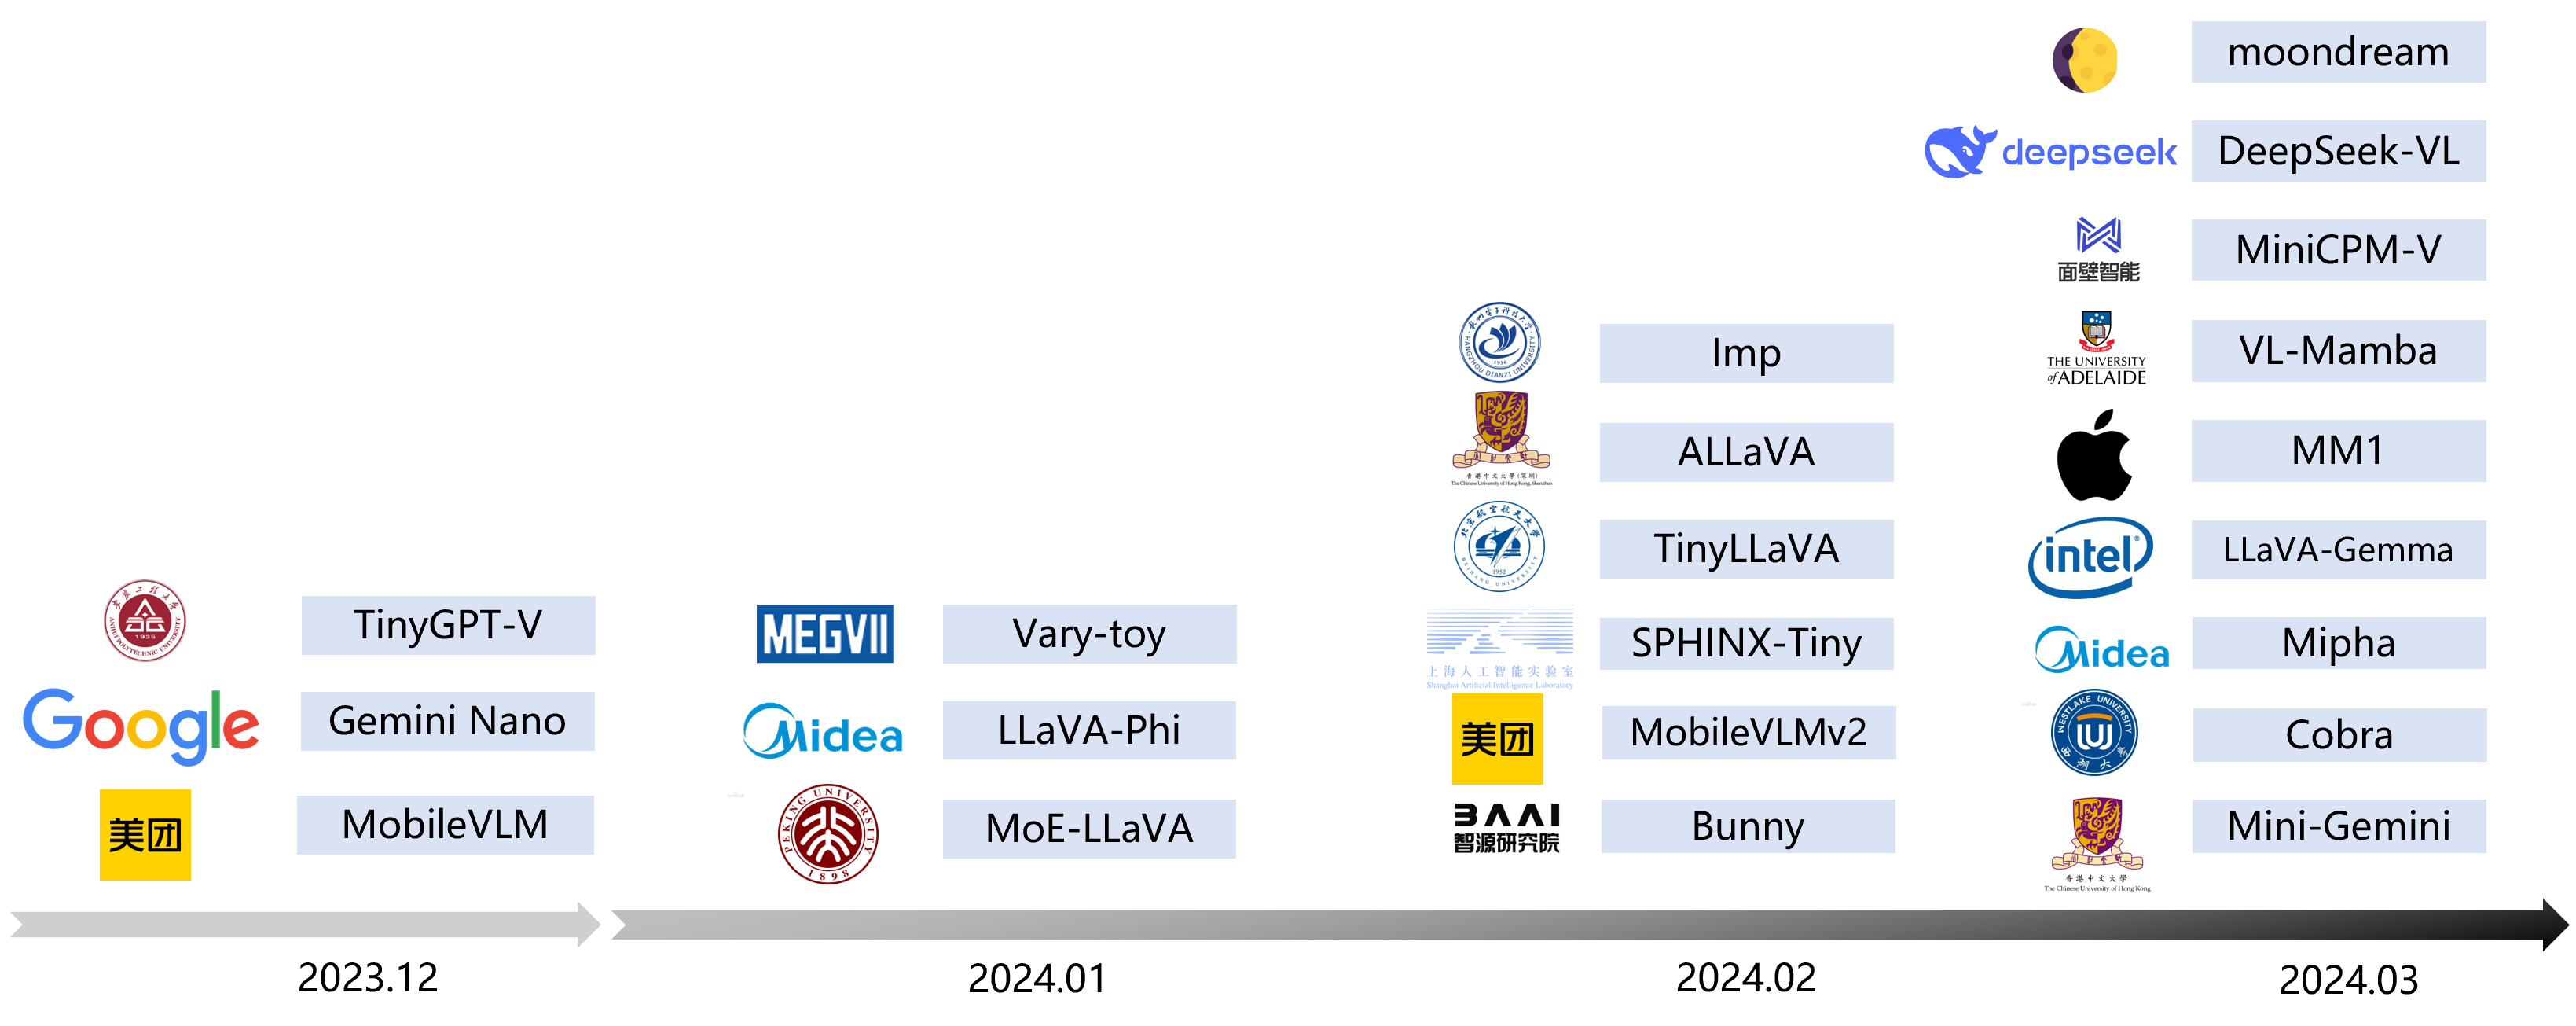
In the past year, Multimodal Large Language Models (MLLMs) have demonstrated remarkable performance in tasks such as visual question answering, visual understanding and reasoning. However, the extensive model size and high training and inference costs have hindered the widespread application of MLLMs in academia and industry. Thus, studying efficient and lightweight MLLMs has enormous potential, especially in edge computing scenarios. In this survey, we provide a comprehensive and systematic review of the current state of efficient MLLMs. Specifically, we summarize the timeline of representative efficient MLLMs, research state of efficient structures and strategies, and the applications. Finally, we discuss the limitations of current efficient MLLM research and promising future directions.
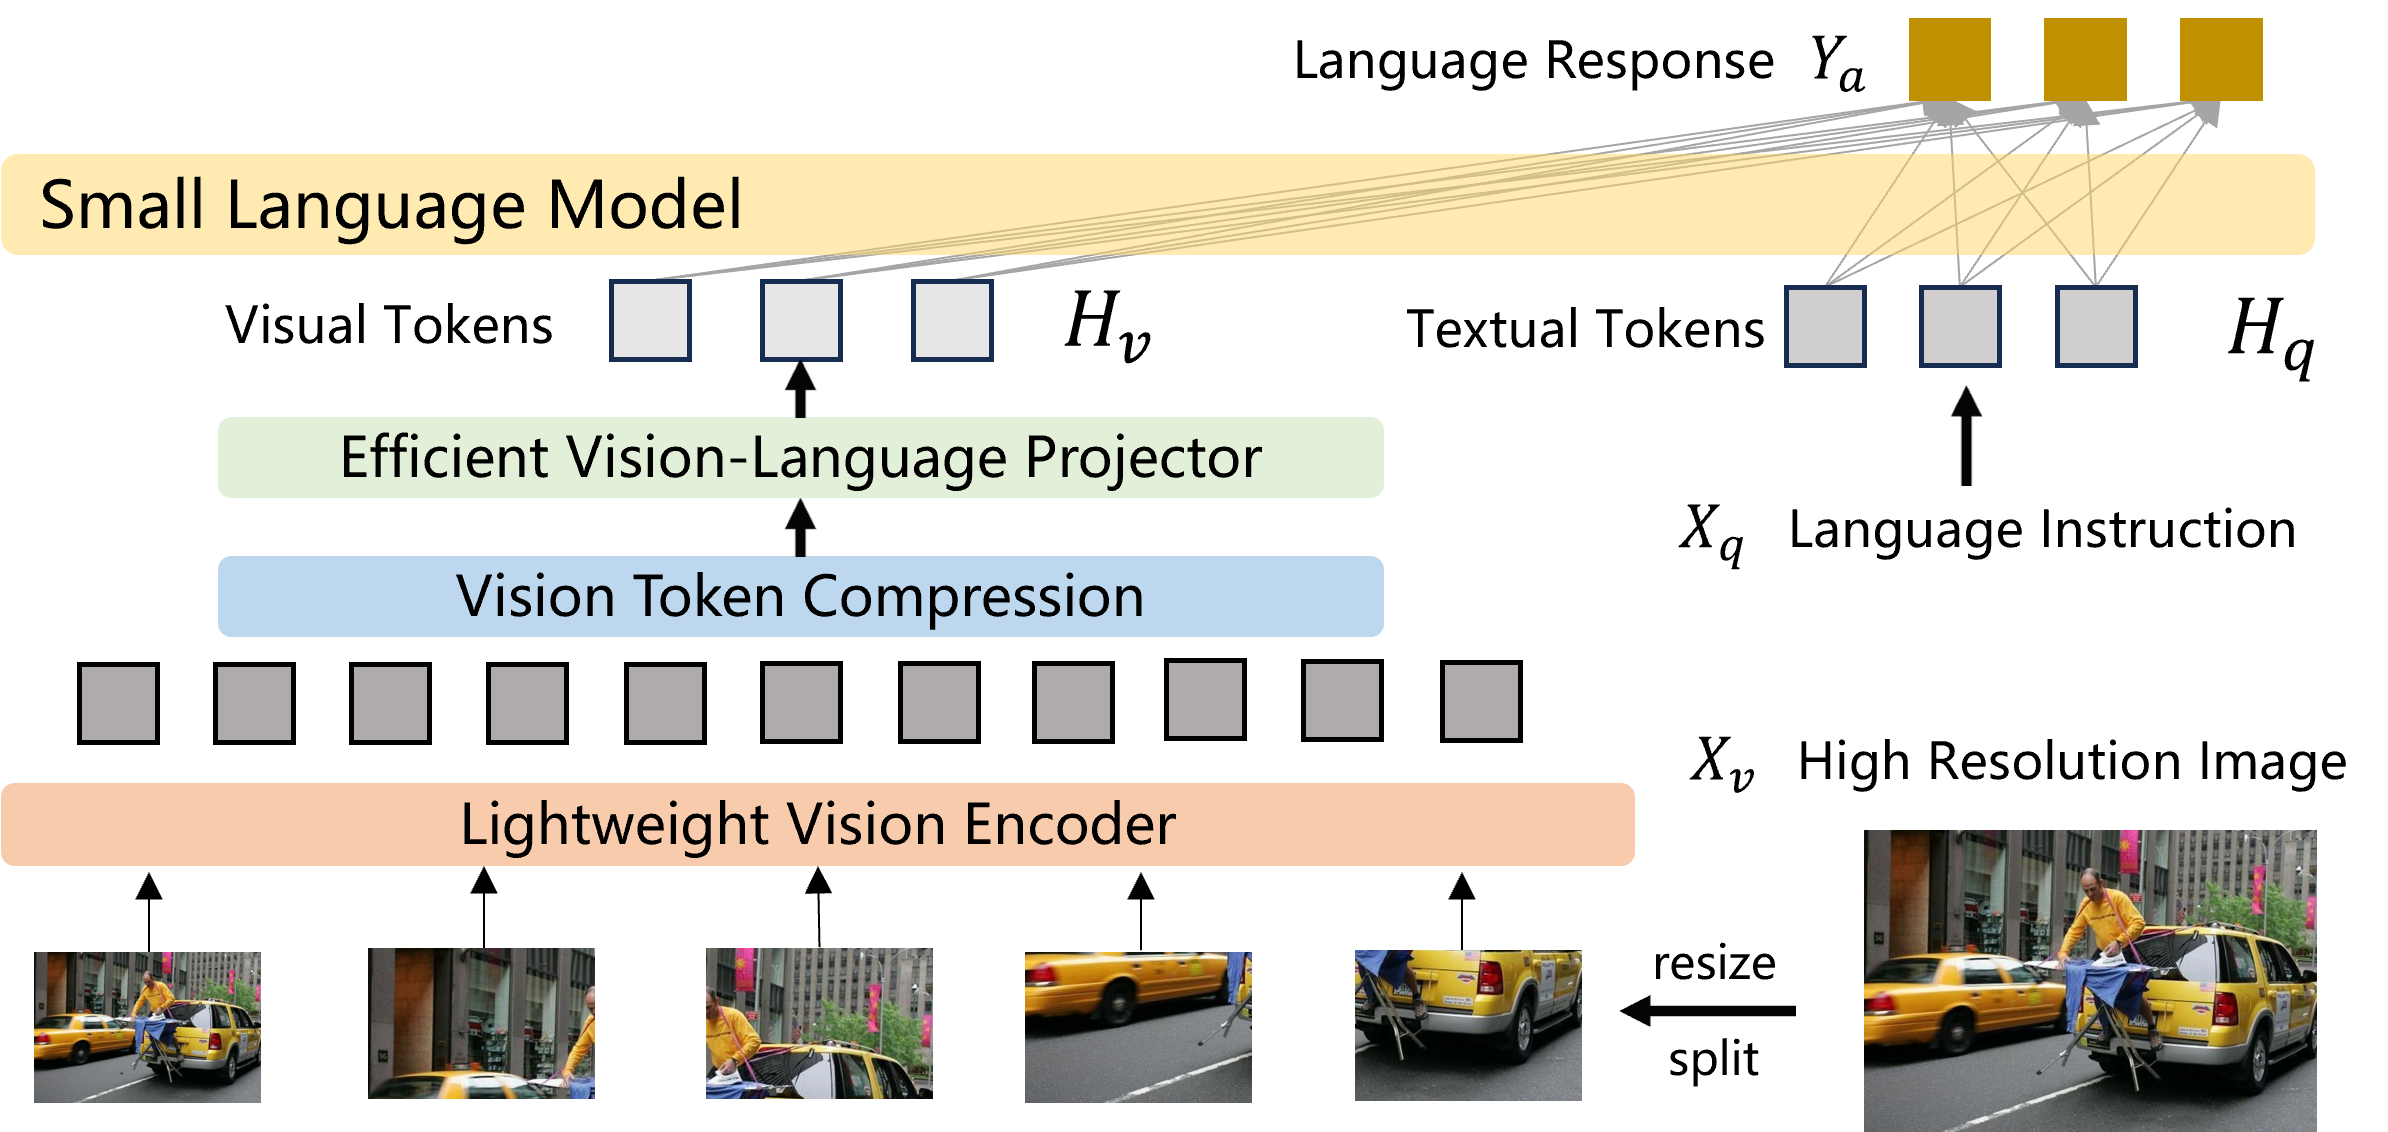
Summary of 17 Mainstream Efficient MLLMs
| Model | Vision Encoder | Resolution | Vision Encoder Parameter Size | LLM | LLM Parameter Size | Vision-LLM Projector | Timeline |
|---|---|---|---|---|---|---|---|
| MobileVLM | CLIP ViT-L/14 | 336 | 0.3B | MobileLLaMA | 2.7B | LDP | 2023-12 |
| LLaVA-Phi | CLIP ViT-L/14 | 336 | 0.3B | Phi-2 | 2.7B | MLP | 2024-01 |
| Imp-v1 | SigLIP | 384 | 0.4B | Phi-2 | 2.7B | - | 2024-02 |
| TinyLLaVA | SigLIP-SO | 384 | 0.4B | Phi-2 | 2.7B | MLP | 2024-02 |
| Bunny | SigLIP-SO | 384 | 0.4B | Phi-2 | 2.7B | MLP | 2024-02 |
| MobileVLM-v2-3B | CLIP ViT-L/14 | 336 | 0.3B | MobileLLaMA | 2.7B | LDPv2 | 2024-02 |
| MoE-LLaVA-3.6B | CLIP-Large | 384 | - | Phi-2 | 2.7B | MLP | 2024-02 |
| Cobra | DINOv2, SigLIP-SO | 384 | 0.3B+0.4B | Mamba-2.8b-Zephyr | 2.8B | MLP | 2024-03 |
| Mini-Gemini | CLIP-Large | 336 | - | Gemma | 2B | MLP | 2024-03 |
| Vary-toy | CLIP | 224 | - | Qwen | 1.8B | - | 2024-01 |
| TinyGPT-V | EVA | 224/448 | - | Phi-2 | 2.7B | Q-Former | 2024-01 |
| SPHINX-Tiny | DINOv2 , CLIP-ConvNeXt | 448 | - | TinyLlama | 1.1B | - | 2024-02 |
| ALLaVA-Longer | CLIP-ViT-L/14 | 336 | 0.3B | Phi-2 | 2.7B | - | 2024-02 |
| MM1-3B-MoE-Chat | CLIP_DFN-ViT-H | 378 | - | - | 3B | C-Abstractor | 2024-03 |
| LLaVA-Gemma | DinoV2 | - | - | Gemma-2b-it | 2B | - | 2024-03 |
| Mipha-3B | SigLIP | 384 | - | Phi-2 | 2.7B | - | 2024-03 |
| VL-Mamba | SigLIP-SO | 384 | - | Mamba-2.8B-Slimpj | 2.8B | VSS-L2 | 2024-03 |
| MiniCPM-V 2.0 | SigLIP | - | 0.4B | MiniCPM | 2.7B | Perceiver Resampler | 2024-03 |
| DeepSeek-VL | SigLIP-L | 384 | 0.4B | DeepSeek-LLM | 1.3B | MLP | 2024-03 |
| KarmaVLM | SigLIP-SO | 384 | 0.4B | Qwen1.5 | 0.5B | - | 2024-02 |
| moondream2 | SigLIP | - | - | Phi-1.5 | 1.3B | - | 2024-03 |
| Bunny-v1.1-4B | SigLIP | 1152 | - | Phi-3-Mini-4K | 3.8B | - | 2024-02 |
Efficient MLLMs
Architecture
- Mobilevlm: A fast, reproducible and strong vision language assistant for mobile devices. arXiv, 2023 [Paper]
- Llava-phi: Efficient multi-modal assistant with small language model. arXiv, 2024 [Paper]
- Imp-v1: An emprical study of multimodal small language models. arXiv, 2024 [Paper]
- TinyLLaVA: A Framework of Small-scale Large Multimodal Models. arxiv, 2024 [Paper]
- (Bunny)Efficient multimodal learning from data-centric perspective.arXiv, 2024 [Paper]
- Gemini: a family of highly capable multimodal modelsarXiv, 2023 [Paper]
- Mobilevlm v2: Faster and stronger baseline for vision language model. arXiv, 2024 [Paper]
- Moe-llava: Mixture of experts for large vision-language models. arXiv, 2024 [Paper]
- Cobra:Extending mamba to multi-modal large language model for efficient inference. arXiv, 2024 [Paper]
- Mini-gemini: Mining the potential of multi-modality vision language models. arXiv, 2024 [Paper]
- (Vary-toy)Small language model meets with reinforced vision vocabulary. arXiv, 2024 [Paper]
- Tinygpt-v: Efficient multimodal large language model via small backbones.arXiv, 2023 [Paper]
- SPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language Models.arXiv, 2024 [Paper]
- ALLaVA: Harnessing GPT4V-synthesized Data for A Lite Vision-Language Model.arXiv, 2024 [Paper]
- Mm1: Methods, analysis & insights from multimodal llm pre-training.arXiv, 2024 [Paper]
- LLaVA-Gemma: Accelerating Multimodal Foundation Models with a Compact Language Model.arXiv, 2024 [Paper]
- Mipha: A Comprehensive Overhaul of Multimodal Assistant with Small Language Models.arXiv, 2024 [Paper]
- VL-Mamba: Exploring State Space Models for Multimodal Learning.arXiv, 2024 [Paper]
- MiniCPM-V 2.0: An Efficient End-side MLLM with Strong OCR and Understanding Capabilities.github, 2024 [Github]
- DeepSeek-VL: Towards Real-World Vision-Language Understanding .arXiv, 2024 [Paper]
- KarmaVLM: A family of high efficiency and powerful visual language model.github, 2024 [Github]
- moondream: tiny vision language model.github, 2024 [Github]
Vision Encoder
Multiple Vision Encoders
- Broadening the visual encoding of vision-language models, arXiv, 2024 [Paper]
- Cobra: Extending Mamba to Multi-Modal Large Language Model for Efficient Inference, arXiv, 2024 [Paper]
- SPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language Models, arXiv, 2024 [Paper]
Lightweight Vision Encoder
- ViTamin: Designing Scalable Vision Models in the Vision-Language Era. arXiv, 2024 [Paper]
Vision-Language Projector
MLP-based
- Visual Instruction Tuning. arXiv, 2023 [Paper]
- Improved baselines with visual instruction tuning. arXiv, 2023 [Paper]
- TokenPacker: Efficient Visual Projector for Multimodal LLM. arXiv, 2024 [Paper]
Attention-based
- Flamingo: a Visual Language Model for Few-Shot Learning, arXiv, 2022 [Paper]
- BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models, arXiv, 2023 [Paper]
- Broadening the visual encoding of vision-language models, arXiv, 2024 [Paper]
CNN-based
- MobileVLM V2: Faster and Stronger Baseline for Vision Language Model, arXiv, 2023 [Paper]
- Mobilevlm: A fast, reproducible and strong vision language assistant for mobile devices. arXiv, 2023 [Paper]
Mamba-based
- Vl-mamba: Exploring state space models for multimodal learning.arXiv, 2024 [Paper]
Hybrid Structure
- Honeybee: Locality-enhanced projector for multimodal llm.arXiv, 2023 [Paper]
Small Language Models
- Llama: Open and efficient foundation language models. arXiv, 2023 [Paper]
- Vicuna: An open-source chatbot impressing gpt-4 with 90%* chatgpt quality.website, 2023 [[web](https://vicuna. lmsys. org)]
- Phi-2: The surprising power of small language models. blog 2023 [[blog](Microsoft Research Blog)]
- Gemma: Open models based on gemini research and technology. arXiv, 2024 [Paper]
- Phi-3 technical report: A highly capable language model locally on your phone. 2024
Vision Token Compression
Multi-view Input
- Llava-uhd: an lmm perceiving any aspect ratio and high-resolution images. arXiv, 2024 [Paper]
- A pioneering large vision- language model handling resolutions from 336 pixels to 4k hd. arXiv, 2024 [Paper]
Token processing
- Llava-uhd: an lmm perceiving any aspect ratio and high-resolution images. arXiv, 2024 [Paper]
- Texthawk: Exploring efficient fine-grained perception of multimodal large language models. arXiv, 2024 [Paper]
- Tiny- chart: Efficient chart understanding with visual token merging and program-of-thoughts learning.
- Llava-prumerge: Adaptive token reduction for efficient large multimodal models. arXiv, 2024 [Paper]
- Madtp: Multi- modal alignment-guided dynamic token pruning for accelerating vision-language transformer. arXiv, 2024 [Paper]
- CROSSGET: CROSS-GUIDED ENSEMBLE OF TOKENS FOR ACCELERATING VISION-LANGUAGE TRANSFORMERS. ICML, 2024 [Paper]
- Matryoshka Query Transformer for Large Vision-Language Models. arxiv, 2024 [Paper]
- Dynamic-LLaVA: Efficient Multimodal Large Language Models via Dynamic Vision-language Context Sparsification. ICLR, 2025 [Paper]
Multi-Scale Information Fusion
- Mini-gemini: Mining the potential of multi-modality vision language models. arXiv, 2024 [Paper]
- When do we not need larger vision models? arXiv, 2024 [Paper] arXiv, 2023 [Paper]
Vision Expert Agents
- Plug-and-play grounding of reasoning in multimodal large language models. arXiv, 2024 [Paper]
- Mova: Adapting mixture of vision experts to multimodal context. arXiv, 2024 [Paper]
Video-Specific Methods
- Elysium: Exploring object-level perception in videos via mllm. arXiv, 2024 [Paper]
- Extending video-language pretraining to n-modality by language-based semantic alignment. arXiv, 2023 [Paper]
- Video-llava: Learning united visual representation by alignment before projection. arXiv, 2023 [Paper]
Efficient Structures
Mixture of Experts
- Moe-llava: Mixture of experts for large vision-language models. arXiv, 2024 [Paper]
- Mm1: Methods, analysis & insights from multimodal llm pre-training. arXiv, 2024 [Paper]
- Mixtral of experts. arXiv, 2024 [Paper]
Mamba
- Cobra: Extending Mamba to Multi-Modal Large Language Model for Efficient Inference, arXiv, 2024 [Paper]
- Mamba: Linear-time sequence modeling with selective state spaces. arXiv, 2023 [Paper]
- Vl-mamba: Exploring state space models for multimodal learning. arXiv, 2024 [Paper]
Inferece Acceleration
- LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal Long-Context Inference. EMNLP Findings, 2024 [Paper] [Code]
- On speculative decoding for multimodal large language models. arXiv, 2024 [Paper]
- An image is worth 1/2 tokens after layer 2: Plug-and-play inference acceleration for large vision-language models. arXiv, 2024 [Paper]
- Boosting multimodal large language models with visual tokens withdrawal for rapid inference. arXiv, 2024 [Paper]
- Dynamic-LLaVA: Efficient Multimodal Large Language Models via Dynamic Vision-language Context Sparsification. ICLR, 2025 [Paper]
Training
Pre-Training
Which part to unfreeze
- Tinyllava: A framework of small-scale large multimodal models. arXiv, 2024 [Paper]
- Vila: On pre-training for visual language models. arXiv, 2023 [Paper]
- Sharegpt4v: Improving large multi-modal models with better captions. arXiv, 2023 [Paper]
Multi-stage pre-training
- What matters when building vision- language models? arXiv, 2024 [Paper]
Instruction-Tunining
Efficient IT
- Cheap and quick: Efficient vision-language instruction tuning for large language models. nips, 2023 [Paper]
- Hyperllava: Dynamic visual and language expert tuning for multimodal large language models. arXiv, 2024 [Paper]
Diverse Training Steps
- SPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language Models.arXiv, 2024 [Paper]
- Cobra:Extending mamba to multi-modal large language model for efficient inference. arXiv, 2024 [Paper]
- Tinygpt-v: Efficient multimodal large language model via small backbones.arXiv, 2023 [Paper]
Parameter Efficient Transfer Learning
- Not All Attention is Needed: Parameter and Computation Efficient Transfer Learning for Multi-modal Large Language Models. arXiv, 2024 [Paper]
- Memory-space visual prompting for efficient vision-language fine-tuning. arXiv, 2024 [Paper]
Applications
Biomedical Analysis
- Training small multimodal models to bridge biomedical competency gap: A case study in radiology imaging. arXiv, 2024 [[Paper]]
- Moe-tinymed: Mixture of experts for tiny medical large vision-language models. arXiv, 2024 [Paper]
Document Understanding
- Texthawk: Exploring efficient fine-grained perception of multimodal large language models. arXiv, 2024 [Paper]
- Tiny- chart: Efficient chart understanding with visual token merging and program-of-thoughts learning. arXiv, 2024 [Paper]
- Monkey: Image resolution and text label are important things for large multi-modal models. arXiv, 2024 [Paper]
- Hrvda: High-resolution visual document assistant. arXiv, 2023 [Paper]
Video Comprehension
- mplug-2: A modular- ized multi-modal foundation model across text, image and video. arXiv, 2023 [Paper]
- Video-llava: Learning united visual representation by alignment before projection. arXiv, 2023 [Paper]
- Ma-lmm: Memory-augmented large multimodal model for long-term video under- standing. arXiv, 2024 [Paper]
- Llama-vid: An image is worth 2 tokens in large language models. arXiv, 2023 [Paper]
Contributors


Similar repos


README
Efficient-Multimodal-LLMs-Survey
Efficient Multimodal Large Language Models: A Survey [arXiv]
Yizhang Jin12, Jian Li1, Yexin Liu3, Tianjun Gu4, Kai Wu1, Zhengkai Jiang1, Muyang He3, Bo Zhao3, Xin Tan4, Zhenye Gan1, Yabiao Wang1, Chengjie Wang1, Lizhuang Ma2
1Tencent YouTu Lab, 2SJTU, 3BAAI, 4ECNU
⚡We will actively maintain this repository and incorporate new research as it emerges. If you have any questions, please contact swordli@tencent.com. Welcome to collaborate on academic research and writing papers together..
@misc{jin2024efficient,
      title={Efficient Multimodal Large Language Models: A Survey},
      author={Yizhang Jin and Jian Li and Yexin Liu and Tianjun Gu and Kai Wu and Zhengkai Jiang and Muyang He and Bo Zhao and Xin Tan and Zhenye Gan and Yabiao Wang and Chengjie Wang and Lizhuang Ma},
      year={2024},
      eprint={2405.10739},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
📌 What is This Survey About?
In the past year, Multimodal Large Language Models (MLLMs) have demonstrated remarkable performance in tasks such as visual question answering, visual understanding and reasoning. However, the extensive model size and high training and inference costs have hindered the widespread application of MLLMs in academia and industry. Thus, studying efficient and lightweight MLLMs has enormous potential, especially in edge computing scenarios. In this survey, we provide a comprehensive and systematic review of the current state of efficient MLLMs. Specifically, we summarize the timeline of representative efficient MLLMs, research state of efficient structures and strategies, and the applications. Finally, we discuss the limitations of current efficient MLLM research and promising future directions.
Summary of 17 Mainstream Efficient MLLMs
| Model | Vision Encoder | Resolution | Vision Encoder Parameter Size | LLM | LLM Parameter Size | Vision-LLM Projector | Timeline |
|---|---|---|---|---|---|---|---|
| MobileVLM | CLIP ViT-L/14 | 336 | 0.3B | MobileLLaMA | 2.7B | LDP | 2023-12 |
| LLaVA-Phi | CLIP ViT-L/14 | 336 | 0.3B | Phi-2 | 2.7B | MLP | 2024-01 |
| Imp-v1 | SigLIP | 384 | 0.4B | Phi-2 | 2.7B | - | 2024-02 |
| TinyLLaVA | SigLIP-SO | 384 | 0.4B | Phi-2 | 2.7B | MLP | 2024-02 |
| Bunny | SigLIP-SO | 384 | 0.4B | Phi-2 | 2.7B | MLP | 2024-02 |
| MobileVLM-v2-3B | CLIP ViT-L/14 | 336 | 0.3B | MobileLLaMA | 2.7B | LDPv2 | 2024-02 |
| MoE-LLaVA-3.6B | CLIP-Large | 384 | - | Phi-2 | 2.7B | MLP | 2024-02 |
| Cobra | DINOv2, SigLIP-SO | 384 | 0.3B+0.4B | Mamba-2.8b-Zephyr | 2.8B | MLP | 2024-03 |
| Mini-Gemini | CLIP-Large | 336 | - | Gemma | 2B | MLP | 2024-03 |
| Vary-toy | CLIP | 224 | - | Qwen | 1.8B | - | 2024-01 |
| TinyGPT-V | EVA | 224/448 | - | Phi-2 | 2.7B | Q-Former | 2024-01 |
| SPHINX-Tiny | DINOv2 , CLIP-ConvNeXt | 448 | - | TinyLlama | 1.1B | - | 2024-02 |
| ALLaVA-Longer | CLIP-ViT-L/14 | 336 | 0.3B | Phi-2 | 2.7B | - | 2024-02 |
| MM1-3B-MoE-Chat | CLIP_DFN-ViT-H | 378 | - | - | 3B | C-Abstractor | 2024-03 |
| LLaVA-Gemma | DinoV2 | - | - | Gemma-2b-it | 2B | - | 2024-03 |
| Mipha-3B | SigLIP | 384 | - | Phi-2 | 2.7B | - | 2024-03 |
| VL-Mamba | SigLIP-SO | 384 | - | Mamba-2.8B-Slimpj | 2.8B | VSS-L2 | 2024-03 |
| MiniCPM-V 2.0 | SigLIP | - | 0.4B | MiniCPM | 2.7B | Perceiver Resampler | 2024-03 |
| DeepSeek-VL | SigLIP-L | 384 | 0.4B | DeepSeek-LLM | 1.3B | MLP | 2024-03 |
| KarmaVLM | SigLIP-SO | 384 | 0.4B | Qwen1.5 | 0.5B | - | 2024-02 |
| moondream2 | SigLIP | - | - | Phi-1.5 | 1.3B | - | 2024-03 |
| Bunny-v1.1-4B | SigLIP | 1152 | - | Phi-3-Mini-4K | 3.8B | - | 2024-02 |
Efficient MLLMs
Architecture
- Mobilevlm: A fast, reproducible and strong vision language assistant for mobile devices. arXiv, 2023 [Paper]
- Llava-phi: Efficient multi-modal assistant with small language model. arXiv, 2024 [Paper]
- Imp-v1: An emprical study of multimodal small language models. arXiv, 2024 [Paper]
- TinyLLaVA: A Framework of Small-scale Large Multimodal Models. arxiv, 2024 [Paper]
- (Bunny)Efficient multimodal learning from data-centric perspective.arXiv, 2024 [Paper]
- Gemini: a family of highly capable multimodal modelsarXiv, 2023 [Paper]
- Mobilevlm v2: Faster and stronger baseline for vision language model. arXiv, 2024 [Paper]
- Moe-llava: Mixture of experts for large vision-language models. arXiv, 2024 [Paper]
- Cobra:Extending mamba to multi-modal large language model for efficient inference. arXiv, 2024 [Paper]
- Mini-gemini: Mining the potential of multi-modality vision language models. arXiv, 2024 [Paper]
- (Vary-toy)Small language model meets with reinforced vision vocabulary. arXiv, 2024 [Paper]
- Tinygpt-v: Efficient multimodal large language model via small backbones.arXiv, 2023 [Paper]
- SPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language Models.arXiv, 2024 [Paper]
- ALLaVA: Harnessing GPT4V-synthesized Data for A Lite Vision-Language Model.arXiv, 2024 [Paper]
- Mm1: Methods, analysis & insights from multimodal llm pre-training.arXiv, 2024 [Paper]
- LLaVA-Gemma: Accelerating Multimodal Foundation Models with a Compact Language Model.arXiv, 2024 [Paper]
- Mipha: A Comprehensive Overhaul of Multimodal Assistant with Small Language Models.arXiv, 2024 [Paper]
- VL-Mamba: Exploring State Space Models for Multimodal Learning.arXiv, 2024 [Paper]
- MiniCPM-V 2.0: An Efficient End-side MLLM with Strong OCR and Understanding Capabilities.github, 2024 [Github]
- DeepSeek-VL: Towards Real-World Vision-Language Understanding .arXiv, 2024 [Paper]
- KarmaVLM: A family of high efficiency and powerful visual language model.github, 2024 [Github]
- moondream: tiny vision language model.github, 2024 [Github]
Vision Encoder
Multiple Vision Encoders
- Broadening the visual encoding of vision-language models, arXiv, 2024 [Paper]
- Cobra: Extending Mamba to Multi-Modal Large Language Model for Efficient Inference, arXiv, 2024 [Paper]
- SPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language Models, arXiv, 2024 [Paper]
Lightweight Vision Encoder
- ViTamin: Designing Scalable Vision Models in the Vision-Language Era. arXiv, 2024 [Paper]
Vision-Language Projector
MLP-based
- Visual Instruction Tuning. arXiv, 2023 [Paper]
- Improved baselines with visual instruction tuning. arXiv, 2023 [Paper]
- TokenPacker: Efficient Visual Projector for Multimodal LLM. arXiv, 2024 [Paper]
Attention-based
- Flamingo: a Visual Language Model for Few-Shot Learning, arXiv, 2022 [Paper]
- BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models, arXiv, 2023 [Paper]
- Broadening the visual encoding of vision-language models, arXiv, 2024 [Paper]
CNN-based
- MobileVLM V2: Faster and Stronger Baseline for Vision Language Model, arXiv, 2023 [Paper]
- Mobilevlm: A fast, reproducible and strong vision language assistant for mobile devices. arXiv, 2023 [Paper]
Mamba-based
- Vl-mamba: Exploring state space models for multimodal learning.arXiv, 2024 [Paper]
Hybrid Structure
- Honeybee: Locality-enhanced projector for multimodal llm.arXiv, 2023 [Paper]
Small Language Models
- Llama: Open and efficient foundation language models. arXiv, 2023 [Paper]
- Vicuna: An open-source chatbot impressing gpt-4 with 90%* chatgpt quality.website, 2023 [[web](https://vicuna. lmsys. org)]
- Phi-2: The surprising power of small language models. blog 2023 [[blog](Microsoft Research Blog)]
- Gemma: Open models based on gemini research and technology. arXiv, 2024 [Paper]
- Phi-3 technical report: A highly capable language model locally on your phone. 2024
Vision Token Compression
Multi-view Input
- Llava-uhd: an lmm perceiving any aspect ratio and high-resolution images. arXiv, 2024 [Paper]
- A pioneering large vision- language model handling resolutions from 336 pixels to 4k hd. arXiv, 2024 [Paper]
Token processing
- Llava-uhd: an lmm perceiving any aspect ratio and high-resolution images. arXiv, 2024 [Paper]
- Texthawk: Exploring efficient fine-grained perception of multimodal large language models. arXiv, 2024 [Paper]
- Tiny- chart: Efficient chart understanding with visual token merging and program-of-thoughts learning.
- Llava-prumerge: Adaptive token reduction for efficient large multimodal models. arXiv, 2024 [Paper]
- Madtp: Multi- modal alignment-guided dynamic token pruning for accelerating vision-language transformer. arXiv, 2024 [Paper]
- CROSSGET: CROSS-GUIDED ENSEMBLE OF TOKENS FOR ACCELERATING VISION-LANGUAGE TRANSFORMERS. ICML, 2024 [Paper]
- Matryoshka Query Transformer for Large Vision-Language Models. arxiv, 2024 [Paper]
- Dynamic-LLaVA: Efficient Multimodal Large Language Models via Dynamic Vision-language Context Sparsification. ICLR, 2025 [Paper]
Multi-Scale Information Fusion
- Mini-gemini: Mining the potential of multi-modality vision language models. arXiv, 2024 [Paper]
- When do we not need larger vision models? arXiv, 2024 [Paper] arXiv, 2023 [Paper]
Vision Expert Agents
- Plug-and-play grounding of reasoning in multimodal large language models. arXiv, 2024 [Paper]
- Mova: Adapting mixture of vision experts to multimodal context. arXiv, 2024 [Paper]
Video-Specific Methods
- Elysium: Exploring object-level perception in videos via mllm. arXiv, 2024 [Paper]
- Extending video-language pretraining to n-modality by language-based semantic alignment. arXiv, 2023 [Paper]
- Video-llava: Learning united visual representation by alignment before projection. arXiv, 2023 [Paper]
Efficient Structures
Mixture of Experts
- Moe-llava: Mixture of experts for large vision-language models. arXiv, 2024 [Paper]
- Mm1: Methods, analysis & insights from multimodal llm pre-training. arXiv, 2024 [Paper]
- Mixtral of experts. arXiv, 2024 [Paper]
Mamba
- Cobra: Extending Mamba to Multi-Modal Large Language Model for Efficient Inference, arXiv, 2024 [Paper]
- Mamba: Linear-time sequence modeling with selective state spaces. arXiv, 2023 [Paper]
- Vl-mamba: Exploring state space models for multimodal learning. arXiv, 2024 [Paper]
Inferece Acceleration
- LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal Long-Context Inference. EMNLP Findings, 2024 [Paper] [Code]
- On speculative decoding for multimodal large language models. arXiv, 2024 [Paper]
- An image is worth 1/2 tokens after layer 2: Plug-and-play inference acceleration for large vision-language models. arXiv, 2024 [Paper]
- Boosting multimodal large language models with visual tokens withdrawal for rapid inference. arXiv, 2024 [Paper]
- Dynamic-LLaVA: Efficient Multimodal Large Language Models via Dynamic Vision-language Context Sparsification. ICLR, 2025 [Paper]
Training
Pre-Training
Which part to unfreeze
- Tinyllava: A framework of small-scale large multimodal models. arXiv, 2024 [Paper]
- Vila: On pre-training for visual language models. arXiv, 2023 [Paper]
- Sharegpt4v: Improving large multi-modal models with better captions. arXiv, 2023 [Paper]
Multi-stage pre-training
- What matters when building vision- language models? arXiv, 2024 [Paper]
Instruction-Tunining
Efficient IT
- Cheap and quick: Efficient vision-language instruction tuning for large language models. nips, 2023 [Paper]
- Hyperllava: Dynamic visual and language expert tuning for multimodal large language models. arXiv, 2024 [Paper]
Diverse Training Steps
- SPHINX-X: Scaling Data and Parameters for a Family of Multi-modal Large Language Models.arXiv, 2024 [Paper]
- Cobra:Extending mamba to multi-modal large language model for efficient inference. arXiv, 2024 [Paper]
- Tinygpt-v: Efficient multimodal large language model via small backbones.arXiv, 2023 [Paper]
Parameter Efficient Transfer Learning
- Not All Attention is Needed: Parameter and Computation Efficient Transfer Learning for Multi-modal Large Language Models. arXiv, 2024 [Paper]
- Memory-space visual prompting for efficient vision-language fine-tuning. arXiv, 2024 [Paper]
Applications
Biomedical Analysis
- Training small multimodal models to bridge biomedical competency gap: A case study in radiology imaging. arXiv, 2024 [[Paper]]
- Moe-tinymed: Mixture of experts for tiny medical large vision-language models. arXiv, 2024 [Paper]
Document Understanding
- Texthawk: Exploring efficient fine-grained perception of multimodal large language models. arXiv, 2024 [Paper]
- Tiny- chart: Efficient chart understanding with visual token merging and program-of-thoughts learning. arXiv, 2024 [Paper]
- Monkey: Image resolution and text label are important things for large multi-modal models. arXiv, 2024 [Paper]
- Hrvda: High-resolution visual document assistant. arXiv, 2023 [Paper]
Video Comprehension
- mplug-2: A modular- ized multi-modal foundation model across text, image and video. arXiv, 2023 [Paper]
- Video-llava: Learning united visual representation by alignment before projection. arXiv, 2023 [Paper]
- Ma-lmm: Memory-augmented large multimodal model for long-term video under- standing. arXiv, 2024 [Paper]
- Llama-vid: An image is worth 2 tokens in large language models. arXiv, 2023 [Paper]