WeDefense: A Toolkit to Defend Against Fake Audio
See the code
| 📘 Tutorials | 📚 Documentation | 🤝 Contributing | 🤗 Demos |
⚠️ Warning / Disclaimer⚠️
Although the goal of this toolkit is to promote progress in fake detection, we acknowledge that any open-source software may be misused by malicious actors. We strongly discourage any use of the models or code for harmful purposes, such as:
- Bypassing biometric authentication
- Creating or enhancing systems that generate fake or deceptive audio
Some of the models included here perform well on public datasets, but may not generalize to unseen or adversarial scenarios. Please be aware of these limitations and use this repository responsibly and ethically.
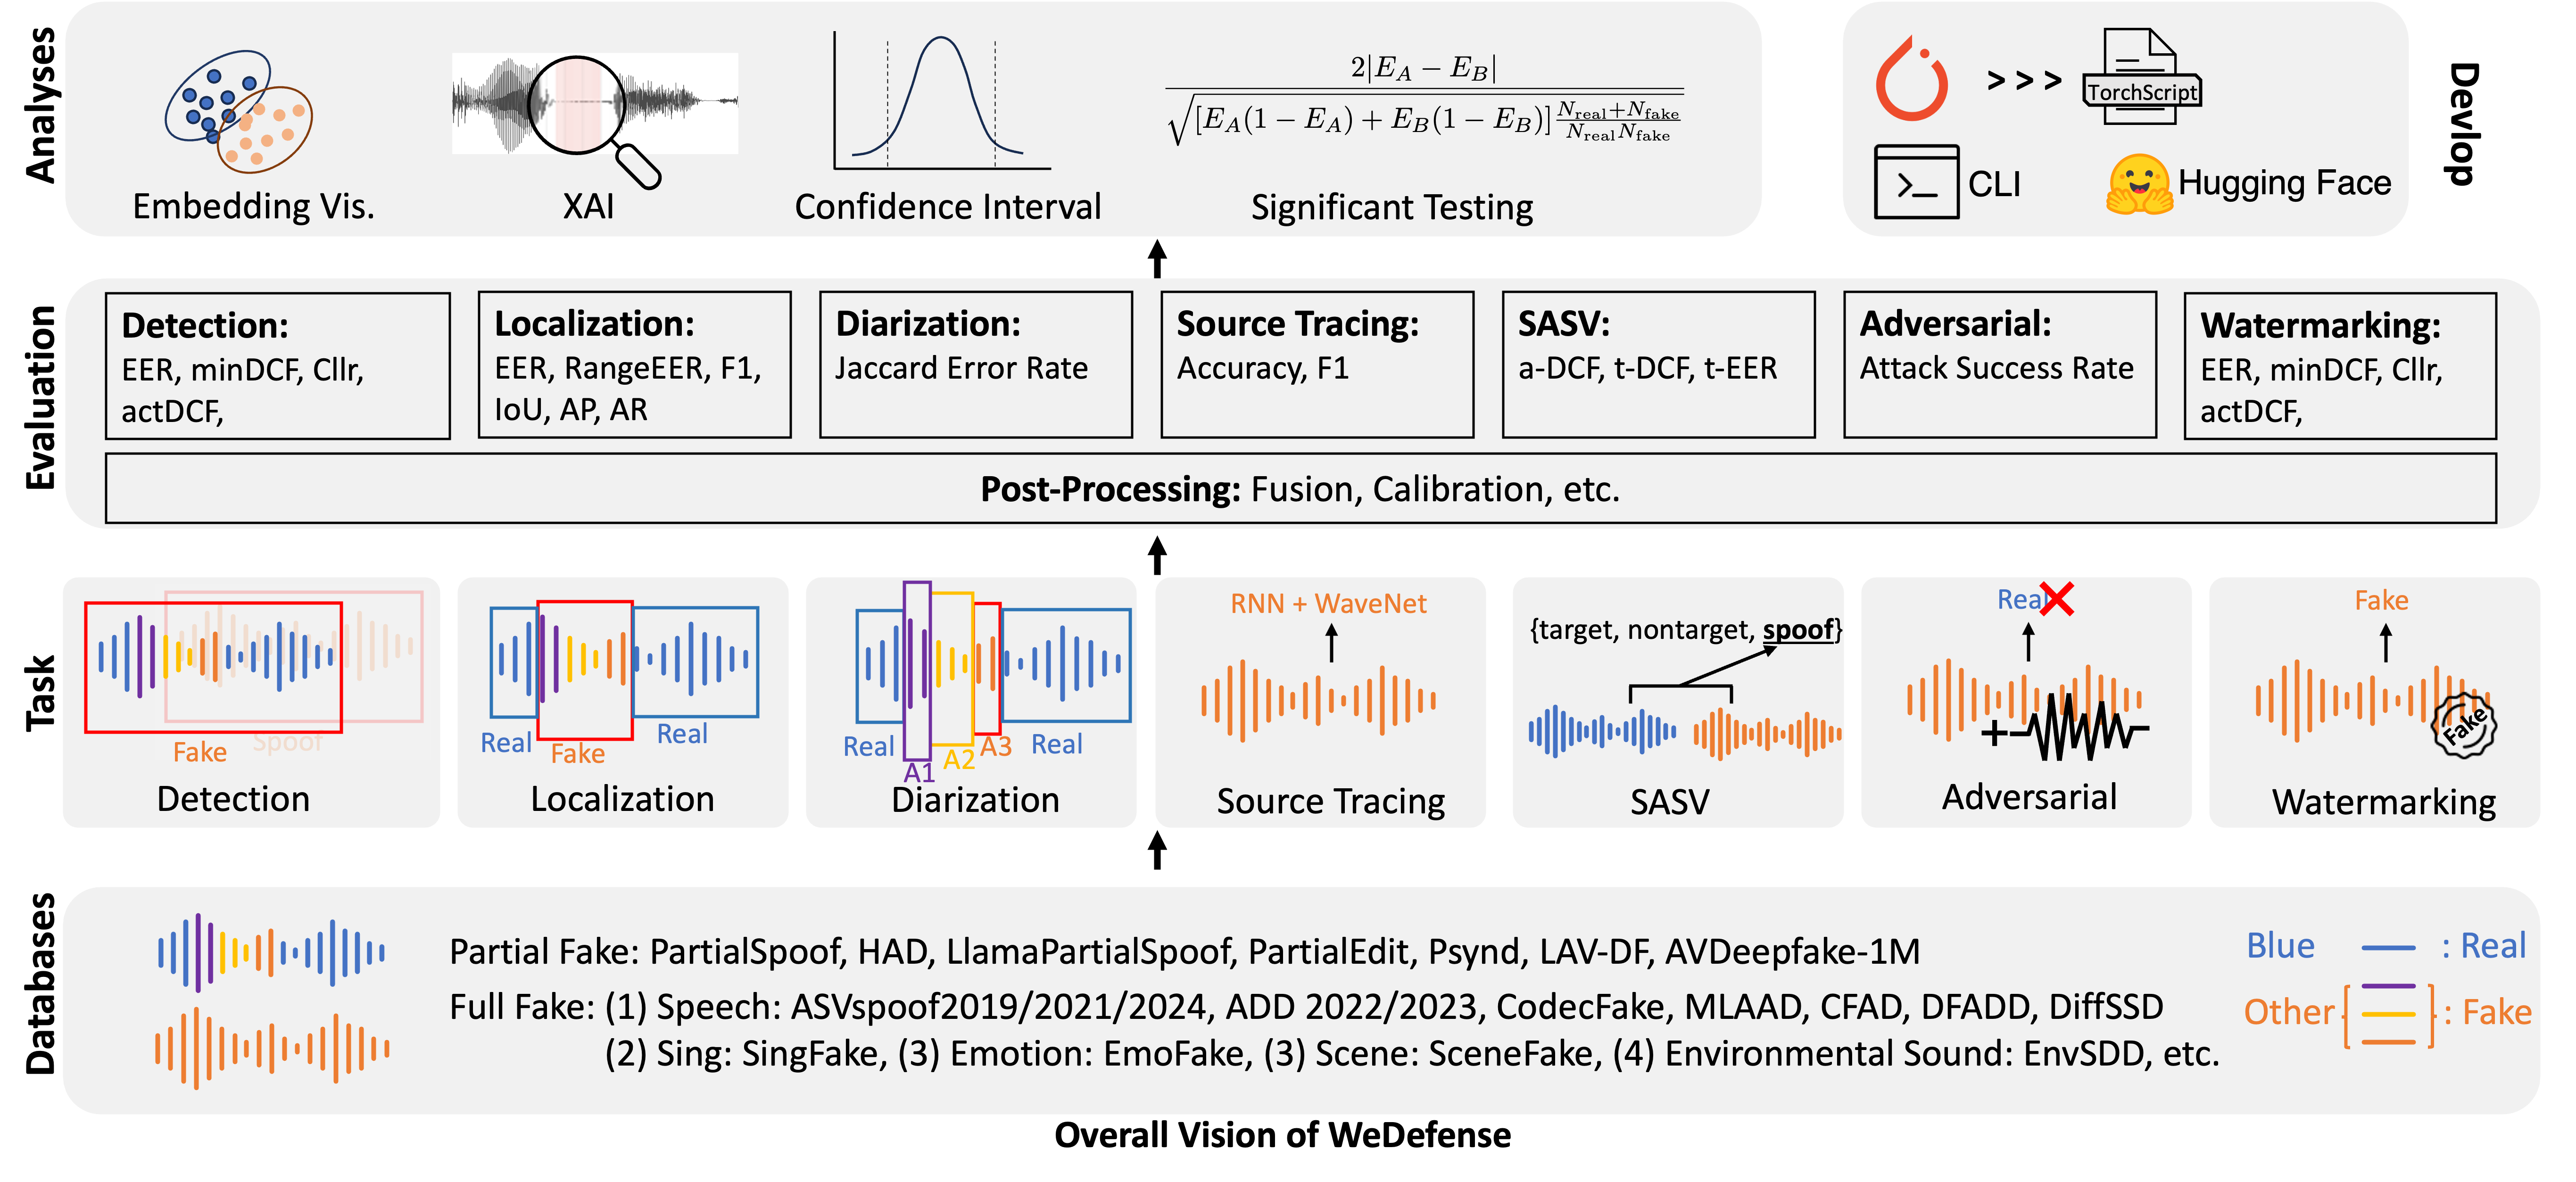
WeDefense aims to be a relatively light-weight, modular, and extensible toolkit tailored to defend against fake audio. Currently we supported detection and uniform frame-level segmentation. If you are interested to contribute, please feel free to contact us!
| Category | Supported ✅ | Planned ⏳ |
|---|---|---|
| Fully Spoof Databases | ASVspoof2019, ASVspoof 5 (2024), , ESDD2026, SpoofCeleb | ASVspoof2021, ADD22/23, ITW, ODSS, ShiftySpeech, MLAAD, ReplayDF, DeePen, FoR, DFADD, AI4T, Deepfake-Eval-2024, SpeechFake, AV-Deepfake1M/++, HAD, Psynd, LAV-DF, LlamaPartialSpoof, PartialEdit |
| Partial Spoof Databases | PartialSpoof | AV-Deepfake1M/AV-Deepfake1M++, HAD, Psynd, LAV-DF, LlamaPartialSpoof, PartialEdit |
| Augmentation | speed perturb, codec, raw boost, musan+rirs | |
| Models for Detection | LCNN-LSTM, ResNet, SSL-gmlp, SSL-AASIST, SSL_MHFA, SSL-res1d, SSL-SLS, AASIST | ALLM4ADD |
| Models for Localization | SSL-MHFA, SSL-SLS, SSL-BAM | CFPRF, PET, AGO, GNCL, UMMAformer, W-TDL, BA-TFD(+), VIGO |
More details please refer to support_status.md.
bash ./install_env.sh
conda activate wedefense
WeDefense aims to support tasks beyond detecting fake audio but also support other relevant tasks to protect the audio.
If you find WeDefense useful, please cite it as:
@article{zhang2025wedefense,
  title={WeDefense: A Toolkit to Defend Against Fake Audio},
  author={Lin Zhang, Johan Rohdin, Xin Wang, Junyi Peng, Tianchi Liu, You Zhang, Hieu-Thi Luong, Shuai Wang, Chengdong Liang, Anna Silnova, Nicholas Evans},
  journal={arXiv preprint arXiv:2601.15240},
  year={2025}
}
WeDefense: A Toolkit to Defend Against Fake Audio
See the code
| 📘 Tutorials | 📚 Documentation | 🤝 Contributing | 🤗 Demos |
⚠️ Warning / Disclaimer⚠️
Although the goal of this toolkit is to promote progress in fake detection, we acknowledge that any open-source software may be misused by malicious actors. We strongly discourage any use of the models or code for harmful purposes, such as:
- Bypassing biometric authentication
- Creating or enhancing systems that generate fake or deceptive audio
Some of the models included here perform well on public datasets, but may not generalize to unseen or adversarial scenarios. Please be aware of these limitations and use this repository responsibly and ethically.
WeDefense aims to be a relatively light-weight, modular, and extensible toolkit tailored to defend against fake audio. Currently we supported detection and uniform frame-level segmentation. If you are interested to contribute, please feel free to contact us!
| Category | Supported ✅ | Planned ⏳ |
|---|---|---|
| Fully Spoof Databases | ASVspoof2019, ASVspoof 5 (2024), , ESDD2026, SpoofCeleb | ASVspoof2021, ADD22/23, ITW, ODSS, ShiftySpeech, MLAAD, ReplayDF, DeePen, FoR, DFADD, AI4T, Deepfake-Eval-2024, SpeechFake, AV-Deepfake1M/++, HAD, Psynd, LAV-DF, LlamaPartialSpoof, PartialEdit |
| Partial Spoof Databases | PartialSpoof | AV-Deepfake1M/AV-Deepfake1M++, HAD, Psynd, LAV-DF, LlamaPartialSpoof, PartialEdit |
| Augmentation | speed perturb, codec, raw boost, musan+rirs | |
| Models for Detection | LCNN-LSTM, ResNet, SSL-gmlp, SSL-AASIST, SSL_MHFA, SSL-res1d, SSL-SLS, AASIST | ALLM4ADD |
| Models for Localization | SSL-MHFA, SSL-SLS, SSL-BAM | CFPRF, PET, AGO, GNCL, UMMAformer, W-TDL, BA-TFD(+), VIGO |
More details please refer to support_status.md.
bash ./install_env.sh
conda activate wedefense
WeDefense aims to support tasks beyond detecting fake audio but also support other relevant tasks to protect the audio.
If you find WeDefense useful, please cite it as:
@article{zhang2025wedefense,
  title={WeDefense: A Toolkit to Defend Against Fake Audio},
  author={Lin Zhang, Johan Rohdin, Xin Wang, Junyi Peng, Tianchi Liu, You Zhang, Hieu-Thi Luong, Shuai Wang, Chengdong Liang, Anna Silnova, Nicholas Evans},
  journal={arXiv preprint arXiv:2601.15240},
  year={2025}
}



