📖 arXiv | 📊 Benchmark Project (MECAT) | 📥 Download
ACAVCaps is a large-scale, fine-grained, and multi-faceted audio captioning dataset derived from the ACAV100M collection. It is designed to address the scarcity of high-quality, detailed audio descriptions at scale by utilizing a multi-expert pipeline and Chain-of-Thought (CoT) reasoning.
The following table compares ACAVCaps with existing caption datasets. The Unique Tokens column reports the total number of unique tokens within each dataset, as counted by the Qwen3 tokenizer.
Legend:
| Labeling | Dataset | Samples | Unique Tokens | Domain | Source |
|---|---|---|---|---|---|
| Manual | AudioCaps | 50k | 5.5k | Multi-Domain‡,◇ | AudioSet |
| Clotho | 3.8k | 5.5k | Multi-Domain‡,◇ | FreeSound | |
| SongDescriber | 0.4k | 2.4k | Music | MTG-Jamendo | |
| LLM | MusicCaps | 4.6k | 4.6k | Music | AudioSet |
| LPMusicCaps | 21.6k | 5.1k | Music | Audioset, MSD | |
| WavCaps | 0.4M | 23.1k | Multi-Domain‡,◇ | AudioSet | |
| Auto-ACD | 1.9M | 20.3k | Multi-Domain‡,◇ | AudioSet | |
| Sound-VeCaps | 1.6M | 42.7k | Multi-Domain‡,◇ | AudioSet | |
| AudioSetCaps | 2.0M | 20.9k | Multi-Domain‡,◇ | AudioSet | |
| MP-LLM† | ACAVCaps (Ours) | 4.7M | 76.7k | Extended Multi-Domain§ | ACAV100M |
Dataset Size vs. Lexical Diversity: When compared to a merged baseline combining four major datasets (AudioSetCaps, Auto-ACD, WavCaps, Sound-VeCaps) with 5.97M samples, ACAVCaps achieves superior lexical diversity with fewer samples. Specifically, ACAVCaps (4.7M samples) contains 76.7k unique tokens, representing a 61% increase over the 47.6k unique tokens found in the larger 6M-sample baseline, despite having 21% fewer samples.
The dataset is organized by content composition to facilitate targeted training and evaluation. The sample distribution across major categories is as follows:
| Category Code | Description | Sample Count |
|---|---|---|
| 00A | Pure Sound Events | 58,268 |
| 0M0 | Pure Music | 623,223 |
| 0MA | Music + Sound Events | 28,229 |
| S00 | Pure Speech | 2,209,982 |
| S0A | Speech + Sound Events | 446,834 |
| SM0 | Speech + Music | 1,209,545 |
| SMA | Speech + Music + Sound Events | 87,994 |
⚠️ Note on Data Access: Due to copyright restrictions, we only provide text information (captions and metadata) in the dataset. The original audio/video files are not included. Users can download the original content using the
keyfield in the JSONL files. Eachkeyrepresents the corresponding YouTube video ID and the start/end timestamps.
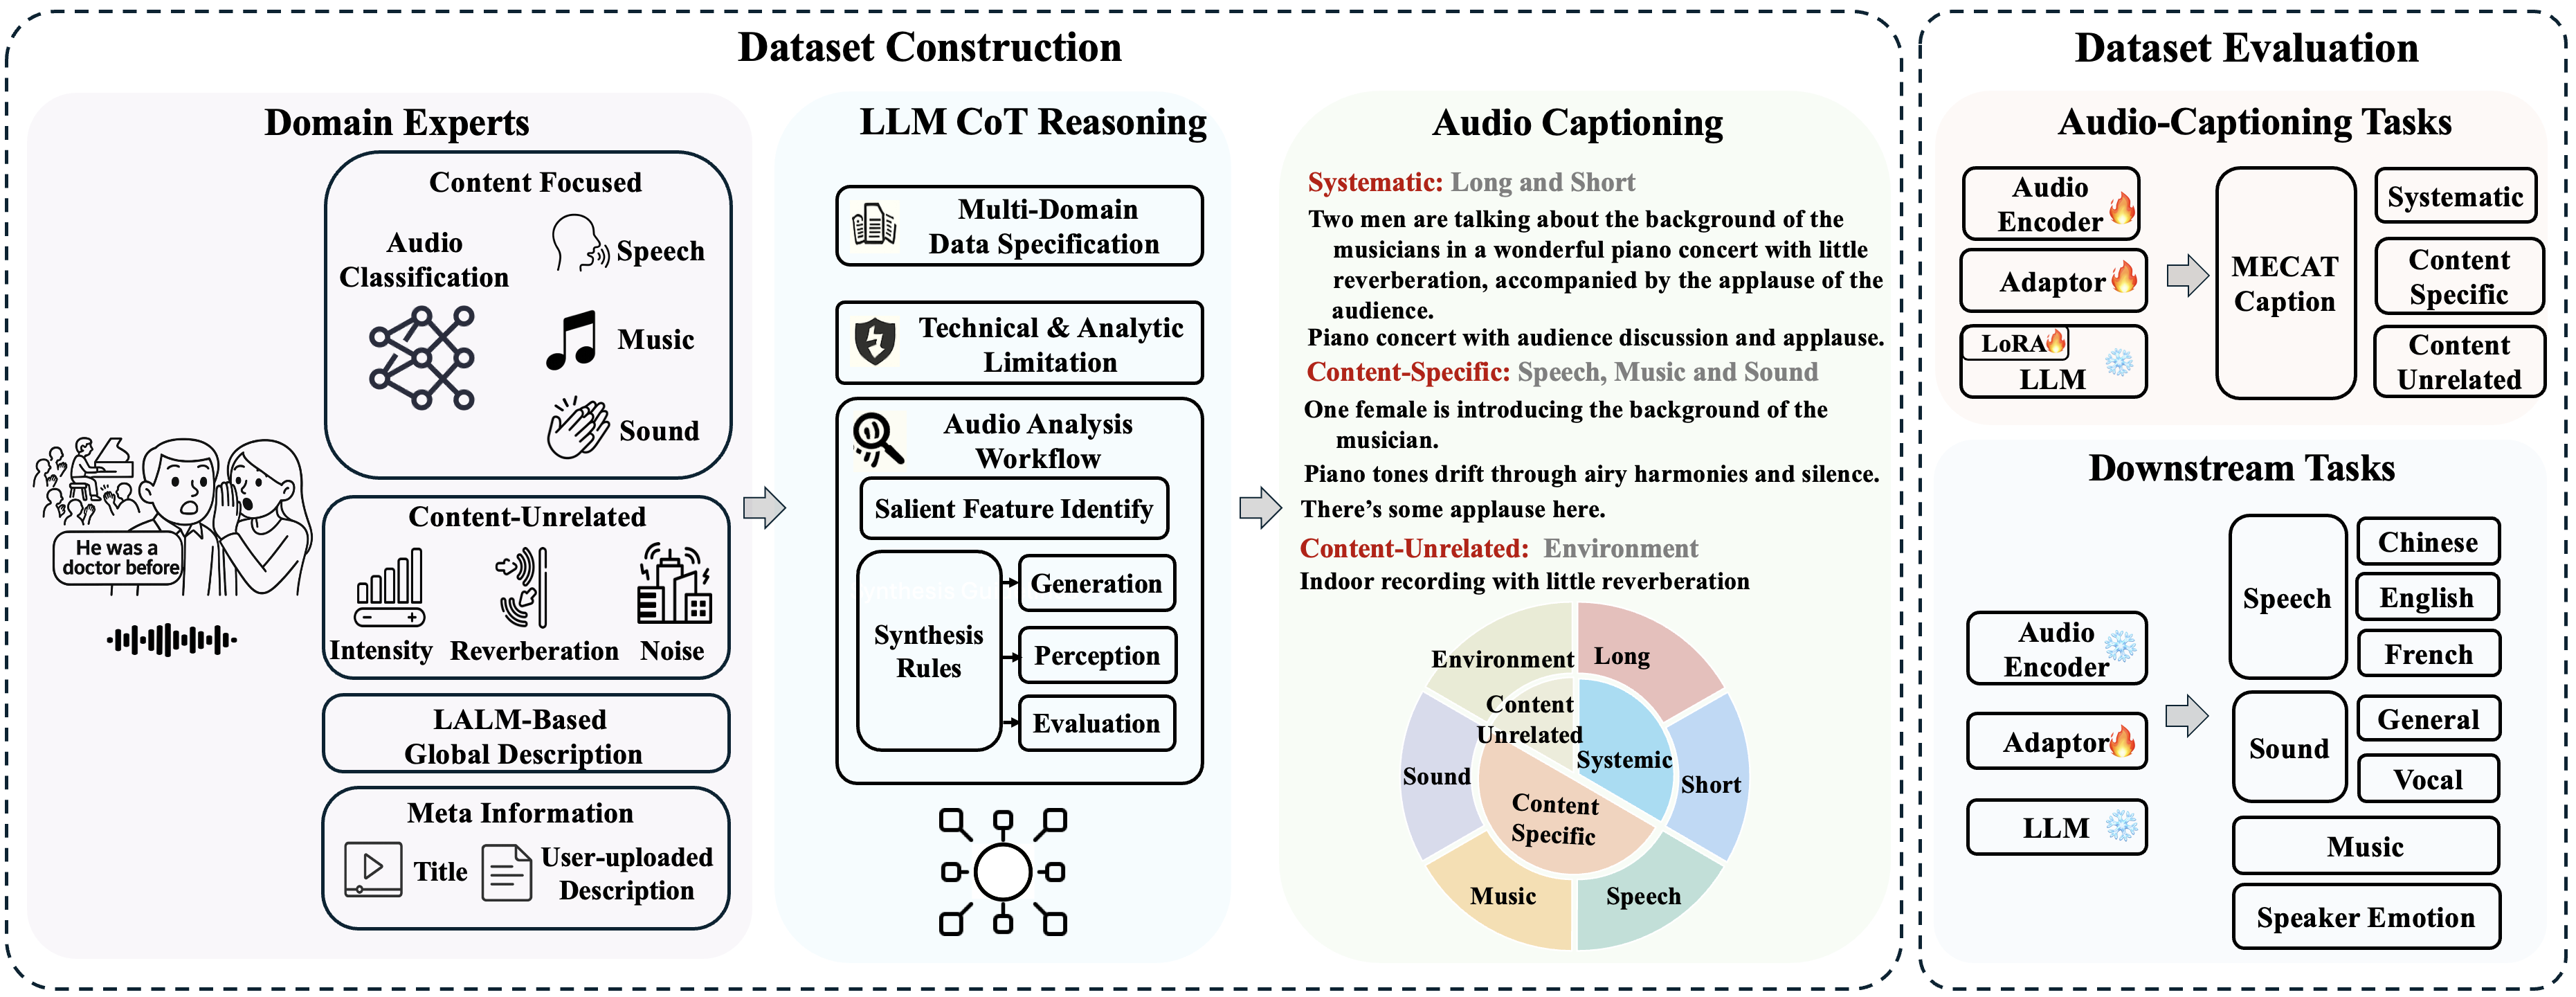
ACAVCaps captions are synthesized using a multi-stage process:
Multi-Expert Annotation: Audio is analyzed by specialized models to extract structured metadata, including AudioSet labels, speech transcripts (ASR), speaker attributes, music tempo/mood, and acoustic properties like reverberation and signal intensity.
LLM-CoT Synthesis: A Large Language Model (Deepseek-R1) employs a Chain-of-Thought strategy to distill these disparate outputs into rich, stylistically varied, and semantically consistent descriptions.
The following example demonstrates the data format in ACAVCaps. Each sample contains multi-faceted captions from different perspectives. The key field follows the format {YouTube_ID}_{start_time}_{end_time}, where the start and end times are in seconds (e.g., 166_48 represents 166.48 seconds).
{
  "wo8sFEF7sWM_166_48_176_48": {
    "long": [
      "A train horn sounds repeatedly while metallic clattering grows louder, accompanied by constant background static and electrical interference throughout the recording.",
      "Sustained train horn blasts merge with increasing rail friction noise and persistent audio distortion",
      "Metallic rolling sounds intensify alongside train horn signals, with continuous low-quality background hum"
    ],
    "short": [
      "Train horn blaring with metallic rolling sounds and persistent static",
      "Train movement noises with horn blast and electrical interference",
      "Railway sounds featuring locomotive horn and track rumble amid distortion"
    ],
    "speech": [
      "None",
      "No discernible speech content",
      "Absence of human vocalizations"
    ],
    "music": [
      "None",
      "No musical elements detected",
      "Absence of rhythmic or melodic content"
    ],
    "sound": [
      "Train horn activation followed by increasing metallic rolling friction sounds",
      "Locomotive warning signals accompanied by track vibration noises",
      "Rail transport sounds featuring horn bursts and wheel-rail interaction"
    ],
    "environment": [
      "Open-air recording with distant mechanical sources and electrical interference",
      "Outdoor environment capturing industrial noises with recording artifacts",
      "Field recording containing transportation sounds and equipment distortion"
    ]
  }
}
Key Format: wo8sFEF7sWM_166_48_176_48
wo8sFEF7sWMTo rigorously evaluate the effectiveness of ACAVCaps, we trained identical model architectures using different datasets. Our evaluation pipeline consists of two stages:
The table below presents the zero-shot audio captioning performance using the DATE metric. ACAVCaps achieves a comprehensive state-of-the-art across all fine-grained sub-categories.
| Training Dataset | Systematic | Content-Related | Content-Unrelated | Score | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Long | Short | Speech | Music | Sound | ||||||
| Pure | Mixed | Pure | Mixed | Pure | Mixed | Environment | ||||
| AudioSetCaps [10] | 52.4 | 52.0 | 30.2 | 31.4 | 44.3 | 30.9 | 52.4 | 21.6 | 15.4 | 37.4 |
| Auto-ACD [8] | 47.3 | 50.0 | 29.1 | 31.0 | 26.9 | 21.9 | 49.5 | 18.9 | 11.0 | 32.8 |
| WavCaps [7] | 47.3 | 50.9 | 27.3 | 30.1 | 15.9 | 19.4 | 46.5 | 20.0 | 9.2 | 31.4 |
| Sound-VeCaps [9] | 47.0 | 49.7 | 29.1 | 30.3 | 27.2 | 21.9 | 49.8 | 18.7 | 11.4 | 32.8 |
| Combined† | 52.2 | 54.1 | 30.2 | 32.2 | 45.4 | 23.3 | 52.7 | 20.2 | 11.1 | 36.6 |
| ACAVCaps (Ours) | 76.6 | 75.7 | 64.2 | 64.9 | 60.5 | 41.1 | 59.5 | 28.0 | 34.8 | 60.9 |
After the alignment stage, the frozen Audio Encoder and LLM are fine-tuned on various downstream datasets. The results demonstrate that models pre-trained on ACAVCaps yield substantial improvements, particularly in Speech tasks (measured by Error Rate, lower is better) and Emotion recognition.
| Training Dataset | Speech ↓ | Sound ↑ | Music ↑ | Other ↑ | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| AISHELL-2 | LibriSpeech | Common Voice | General (VGGSound) | Vocal (VocalSound) | Instrument (NSynth) | Emotion (IEMOCAP) | ||||
| Android | IOS | MIC | Clean | Other | French | |||||
| AudioSetCaps | 82.7 | 77.8 | 81.7 | 51.6 | 70.2 | 84.7 | 22.4 | 91.4 | 67.0 | 17.6 |
| Auto-ACD | 89.1 | 78.2 | 88.6 | 54.6 | 76.5 | 85.7 | 22.5 | 90.2 | 46.1 | 24.1 |
| WavCaps | 83.2 | 74.2 | 77.9 | 54.3 | 74.0 | 85.2 | 21.2 | 91.5 | 69.1 | 19.9 |
| Sound-VeCaps | 87.3 | 79.5 | 87.9 | 51.8 | 70.1 | 85.6 | 22.9 | 90.8 | 45.0 | 20.3 |
| Combined† | 84.2 | 76.4 | 82.3 | 41.5 | 59.4 | 83.0 | 34.6 | 92.6 | 44.0 | 19.8 |
| ACAVCaps (Ours) | 58.3 | 56.5 | 57.1 | 19.7 | 33.7 | 50.0 | 20.4 | 92.1 | 64.7 | 28.9 |
† Combined refers to the combination of AudioSetCaps, Auto-ACD, WavCaps, and Sound-VeCaps. For Speech tasks, the metric is Error Rate (lower is better, ↓). For Sound, Music, and Other tasks, the metric is Accuracy (higher is better, ↑). The best results are highlighted in bold, and the second best results are underlined.
If you find our repository useful in your research, please consider citing our corresponding papers depending on the specific resources you use:
For the training dataset (ACAVCaps):
@inproceedings{niu2026acavcaps,
  title={ACAVCaps: Enabling Large-Scale Training for Fine-Grained and Diverse Audio Understanding},
  author={Niu, Yadong and Wang, Tianzi and Dinkel, Heinrich and Sun, Xingwei and Zhou, Jiahao and Li, Gang and Liu, Jizhong and Zhang, Junbo and Luan, Jian},
  journal={arXiv preprint arXiv:2603.24038},
  year={2026}
}
For the evaluation benchmark (MECAT) or related testing methodologies:
@article{mecat2025,
  title={MECAT: A Multi-Experts Constructed Benchmark for Fine-Grained Audio Understanding Tasks},
  author={Niu, Yadong and Wang, Tianzi and Dinkel, Heinrich and Sun, Xingwei and Zhou, Jiahao and Li, Gang and Liu, Jizhong and Liu, Xunying and Zhang, Junbo and Luan, Jian},
  journal={arXiv preprint arXiv:2507.23511},
  year={2025}
}
Yadong Niu · Tianzi Wang · Heinrich Dinkel · Xingwei Sun · Jiahao Zhou · Gang Li · Jizhong Liu · Junbo Zhang · Jian Luan
The dataset of the project is under the Creative Commons Attribution-NonCommercial 4.0 International (CC-BY-NC 4.0) license.
219 followers · starred Mar 2026
72 followers · starred Mar 2026
223 followers · starred Mar 2026
📖 arXiv | 📊 Benchmark Project (MECAT) | 📥 Download
ACAVCaps is a large-scale, fine-grained, and multi-faceted audio captioning dataset derived from the ACAV100M collection. It is designed to address the scarcity of high-quality, detailed audio descriptions at scale by utilizing a multi-expert pipeline and Chain-of-Thought (CoT) reasoning.
The following table compares ACAVCaps with existing caption datasets. The Unique Tokens column reports the total number of unique tokens within each dataset, as counted by the Qwen3 tokenizer.
Legend:
| Labeling | Dataset | Samples | Unique Tokens | Domain | Source |
|---|---|---|---|---|---|
| Manual | AudioCaps | 50k | 5.5k | Multi-Domain‡,◇ | AudioSet |
| Clotho | 3.8k | 5.5k | Multi-Domain‡,◇ | FreeSound | |
| SongDescriber | 0.4k | 2.4k | Music | MTG-Jamendo | |
| LLM | MusicCaps | 4.6k | 4.6k | Music | AudioSet |
| LPMusicCaps | 21.6k | 5.1k | Music | Audioset, MSD | |
| WavCaps | 0.4M | 23.1k | Multi-Domain‡,◇ | AudioSet | |
| Auto-ACD | 1.9M | 20.3k | Multi-Domain‡,◇ | AudioSet | |
| Sound-VeCaps | 1.6M | 42.7k | Multi-Domain‡,◇ | AudioSet | |
| AudioSetCaps | 2.0M | 20.9k | Multi-Domain‡,◇ | AudioSet | |
| MP-LLM† | ACAVCaps (Ours) | 4.7M | 76.7k | Extended Multi-Domain§ | ACAV100M |
Dataset Size vs. Lexical Diversity: When compared to a merged baseline combining four major datasets (AudioSetCaps, Auto-ACD, WavCaps, Sound-VeCaps) with 5.97M samples, ACAVCaps achieves superior lexical diversity with fewer samples. Specifically, ACAVCaps (4.7M samples) contains 76.7k unique tokens, representing a 61% increase over the 47.6k unique tokens found in the larger 6M-sample baseline, despite having 21% fewer samples.
The dataset is organized by content composition to facilitate targeted training and evaluation. The sample distribution across major categories is as follows:
| Category Code | Description | Sample Count |
|---|---|---|
| 00A | Pure Sound Events | 58,268 |
| 0M0 | Pure Music | 623,223 |
| 0MA | Music + Sound Events | 28,229 |
| S00 | Pure Speech | 2,209,982 |
| S0A | Speech + Sound Events | 446,834 |
| SM0 | Speech + Music | 1,209,545 |
| SMA | Speech + Music + Sound Events | 87,994 |
⚠️ Note on Data Access: Due to copyright restrictions, we only provide text information (captions and metadata) in the dataset. The original audio/video files are not included. Users can download the original content using the
keyfield in the JSONL files. Eachkeyrepresents the corresponding YouTube video ID and the start/end timestamps.
ACAVCaps captions are synthesized using a multi-stage process:
Multi-Expert Annotation: Audio is analyzed by specialized models to extract structured metadata, including AudioSet labels, speech transcripts (ASR), speaker attributes, music tempo/mood, and acoustic properties like reverberation and signal intensity.
LLM-CoT Synthesis: A Large Language Model (Deepseek-R1) employs a Chain-of-Thought strategy to distill these disparate outputs into rich, stylistically varied, and semantically consistent descriptions.
The following example demonstrates the data format in ACAVCaps. Each sample contains multi-faceted captions from different perspectives. The key field follows the format {YouTube_ID}_{start_time}_{end_time}, where the start and end times are in seconds (e.g., 166_48 represents 166.48 seconds).
{
  "wo8sFEF7sWM_166_48_176_48": {
    "long": [
      "A train horn sounds repeatedly while metallic clattering grows louder, accompanied by constant background static and electrical interference throughout the recording.",
      "Sustained train horn blasts merge with increasing rail friction noise and persistent audio distortion",
      "Metallic rolling sounds intensify alongside train horn signals, with continuous low-quality background hum"
    ],
    "short": [
      "Train horn blaring with metallic rolling sounds and persistent static",
      "Train movement noises with horn blast and electrical interference",
      "Railway sounds featuring locomotive horn and track rumble amid distortion"
    ],
    "speech": [
      "None",
      "No discernible speech content",
      "Absence of human vocalizations"
    ],
    "music": [
      "None",
      "No musical elements detected",
      "Absence of rhythmic or melodic content"
    ],
    "sound": [
      "Train horn activation followed by increasing metallic rolling friction sounds",
      "Locomotive warning signals accompanied by track vibration noises",
      "Rail transport sounds featuring horn bursts and wheel-rail interaction"
    ],
    "environment": [
      "Open-air recording with distant mechanical sources and electrical interference",
      "Outdoor environment capturing industrial noises with recording artifacts",
      "Field recording containing transportation sounds and equipment distortion"
    ]
  }
}
Key Format: wo8sFEF7sWM_166_48_176_48
wo8sFEF7sWMTo rigorously evaluate the effectiveness of ACAVCaps, we trained identical model architectures using different datasets. Our evaluation pipeline consists of two stages:
The table below presents the zero-shot audio captioning performance using the DATE metric. ACAVCaps achieves a comprehensive state-of-the-art across all fine-grained sub-categories.
| Training Dataset | Systematic | Content-Related | Content-Unrelated | Score | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Long | Short | Speech | Music | Sound | ||||||
| Pure | Mixed | Pure | Mixed | Pure | Mixed | Environment | ||||
| AudioSetCaps [10] | 52.4 | 52.0 | 30.2 | 31.4 | 44.3 | 30.9 | 52.4 | 21.6 | 15.4 | 37.4 |
| Auto-ACD [8] | 47.3 | 50.0 | 29.1 | 31.0 | 26.9 | 21.9 | 49.5 | 18.9 | 11.0 | 32.8 |
| WavCaps [7] | 47.3 | 50.9 | 27.3 | 30.1 | 15.9 | 19.4 | 46.5 | 20.0 | 9.2 | 31.4 |
| Sound-VeCaps [9] | 47.0 | 49.7 | 29.1 | 30.3 | 27.2 | 21.9 | 49.8 | 18.7 | 11.4 | 32.8 |
| Combined† | 52.2 | 54.1 | 30.2 | 32.2 | 45.4 | 23.3 | 52.7 | 20.2 | 11.1 | 36.6 |
| ACAVCaps (Ours) | 76.6 | 75.7 | 64.2 | 64.9 | 60.5 | 41.1 | 59.5 | 28.0 | 34.8 | 60.9 |
After the alignment stage, the frozen Audio Encoder and LLM are fine-tuned on various downstream datasets. The results demonstrate that models pre-trained on ACAVCaps yield substantial improvements, particularly in Speech tasks (measured by Error Rate, lower is better) and Emotion recognition.
| Training Dataset | Speech ↓ | Sound ↑ | Music ↑ | Other ↑ | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| AISHELL-2 | LibriSpeech | Common Voice | General (VGGSound) | Vocal (VocalSound) | Instrument (NSynth) | Emotion (IEMOCAP) | ||||
| Android | IOS | MIC | Clean | Other | French | |||||
| AudioSetCaps | 82.7 | 77.8 | 81.7 | 51.6 | 70.2 | 84.7 | 22.4 | 91.4 | 67.0 | 17.6 |
| Auto-ACD | 89.1 | 78.2 | 88.6 | 54.6 | 76.5 | 85.7 | 22.5 | 90.2 | 46.1 | 24.1 |
| WavCaps | 83.2 | 74.2 | 77.9 | 54.3 | 74.0 | 85.2 | 21.2 | 91.5 | 69.1 | 19.9 |
| Sound-VeCaps | 87.3 | 79.5 | 87.9 | 51.8 | 70.1 | 85.6 | 22.9 | 90.8 | 45.0 | 20.3 |
| Combined† | 84.2 | 76.4 | 82.3 | 41.5 | 59.4 | 83.0 | 34.6 | 92.6 | 44.0 | 19.8 |
| ACAVCaps (Ours) | 58.3 | 56.5 | 57.1 | 19.7 | 33.7 | 50.0 | 20.4 | 92.1 | 64.7 | 28.9 |
† Combined refers to the combination of AudioSetCaps, Auto-ACD, WavCaps, and Sound-VeCaps. For Speech tasks, the metric is Error Rate (lower is better, ↓). For Sound, Music, and Other tasks, the metric is Accuracy (higher is better, ↑). The best results are highlighted in bold, and the second best results are underlined.
If you find our repository useful in your research, please consider citing our corresponding papers depending on the specific resources you use:
For the training dataset (ACAVCaps):
@inproceedings{niu2026acavcaps,
  title={ACAVCaps: Enabling Large-Scale Training for Fine-Grained and Diverse Audio Understanding},
  author={Niu, Yadong and Wang, Tianzi and Dinkel, Heinrich and Sun, Xingwei and Zhou, Jiahao and Li, Gang and Liu, Jizhong and Zhang, Junbo and Luan, Jian},
  journal={arXiv preprint arXiv:2603.24038},
  year={2026}
}
For the evaluation benchmark (MECAT) or related testing methodologies:
@article{mecat2025,
  title={MECAT: A Multi-Experts Constructed Benchmark for Fine-Grained Audio Understanding Tasks},
  author={Niu, Yadong and Wang, Tianzi and Dinkel, Heinrich and Sun, Xingwei and Zhou, Jiahao and Li, Gang and Liu, Jizhong and Liu, Xunying and Zhang, Junbo and Luan, Jian},
  journal={arXiv preprint arXiv:2507.23511},
  year={2025}
}
Yadong Niu · Tianzi Wang · Heinrich Dinkel · Xingwei Sun · Jiahao Zhou · Gang Li · Jizhong Liu · Junbo Zhang · Jian Luan
The dataset of the project is under the Creative Commons Attribution-NonCommercial 4.0 International (CC-BY-NC 4.0) license.
219 followers · starred Mar 2026
72 followers · starred Mar 2026
223 followers · starred Mar 2026