
Towards Fine-grained Audio Captioning with Multimodal Contextual Cues
Python
90
28 commits
updated Jan 4, 2026
README
FusionAudio-1.2M, Towards Fine-grained Audio Captioning with Multimodal Contextual Cues
🚀🚀🚀 Official implementation of FusionAudio-1.2M: Towards Fine-grained Audio Captioning with Multimodal Contextual Cues
- Authors: Shunian Chen*, Xinyuan Xie*, Zheshu Chen*, Liyan Zhao, Owen Lee, Zhan Su, Qilin Sun, Benyou Wang
- Institutions: The Chinese University of Hong Kong, Shenzhen
- Resources: 📄 Paper | 🤗 Huggingface |
ModelScope
- Models: 🤗FusionAudio
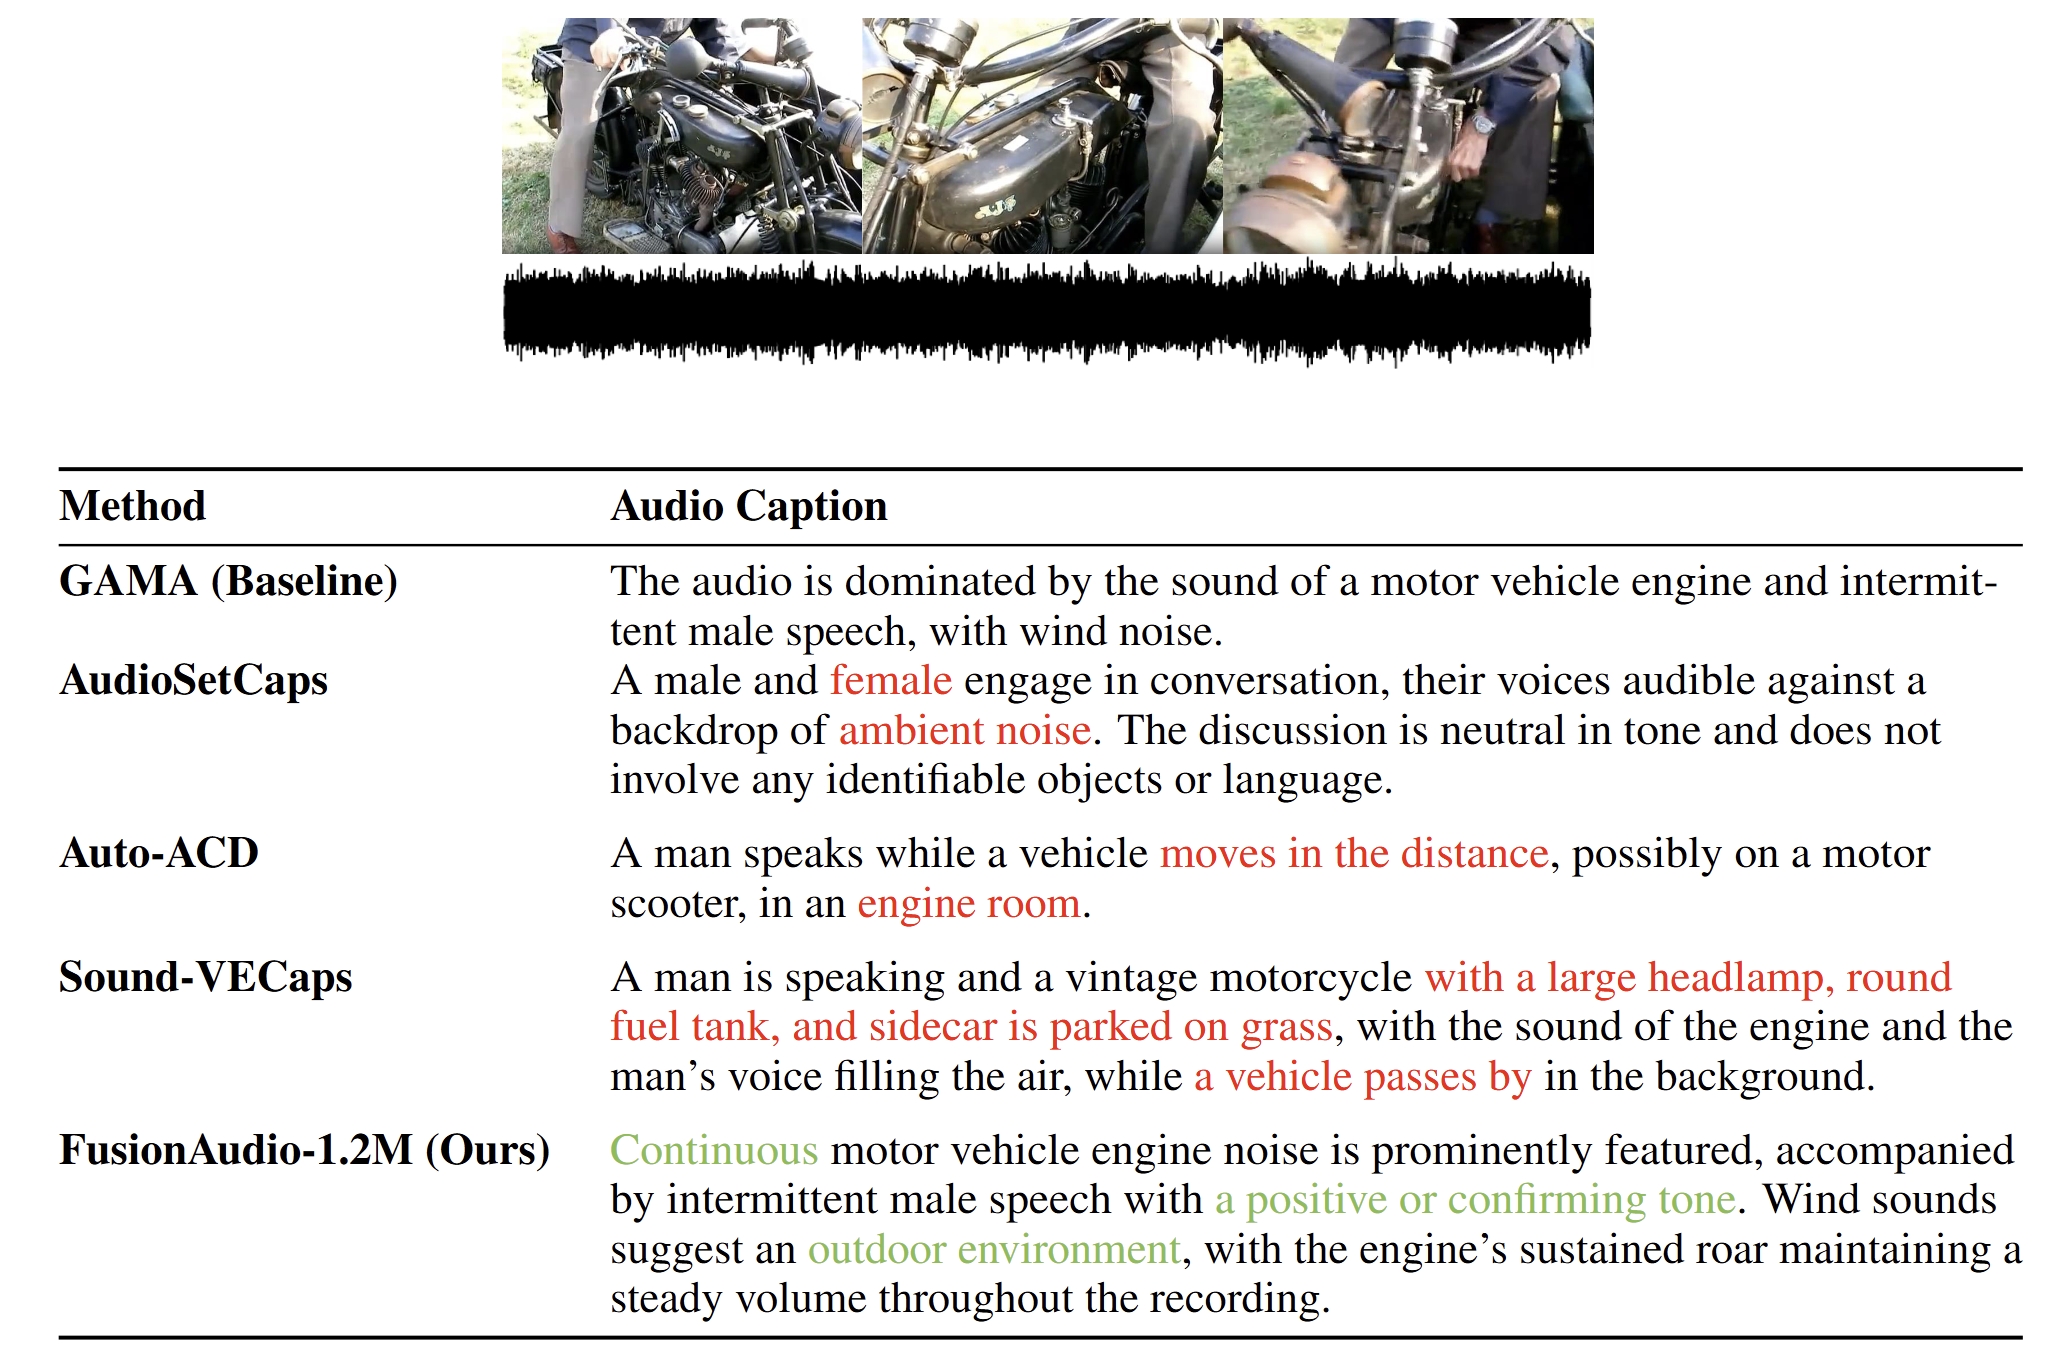
💡 Highlights
- 🔥 Large-scale high-quality audio captioning dataset FusionAudio-1.2M
- 🔥 Multimodal context fusion for more fine-grained audio understanding
- 🔥 SOTA performance achieving state-of-the-art results on multiple audio understanding benchmarks
📜 News
[2025/06/01] 🚀 Our papar FusionAudio-1.2M, Towards Fine-grained Audio Captioning with Multimodal Contextual Cues is available!
[2025/05/16] 🚀 Released FusionAudio-1.2M dataset, model, and code!
🚀 Quick Start
Environment Setup
# Create conda environment
conda create -n FusionAudio python=3.10
conda activate FusionAudio

# Install dependencies
pip install -r requirements.txt
pip install -e src/GAMA/hf-dev-train/transformers-main
pip install -e src/GAMA/peft-main
Quick Inference
We provide an easy-to-use inference script quick_inference.py that supports both command-line and Python API usage.
Command Line Usage
python quick_inference.py \
    --base_model /path/to/Llama-2-7b-chat-hf-qformer \
    --model_path /path/to/fusionaudio_checkpoint.pth \
    --audio /path/to/your/audio.wav \
    --question "Please describe this audio in detail."
Python API Usage
from quick_inference import FusionAudioInference

# Initialize inferencer
inferencer = FusionAudioInference(
    base_model_path="/path/to/Llama-2-7b-chat-hf-qformer",
    model_path="/path/to/fusionaudio_checkpoint.pth",
    device="cuda:0"
)

# Audio captioning
response = inferencer.predict(
    audio_path="/path/to/your/audio.wav",
    question="Please describe this audio in detail."
)
print(f"Audio description: {response}")
For detailed parameter descriptions, run python quick_inference.py --help.
📊 Dataset
FusionAudio-1.2M
We constructed a large-scale dataset containing 1.2 million high-quality audio-text pairs.
Caption&QA Dataset Download Link: 🤗 Hugging Face
Video Download:
# Preparation
# 1. Write a cookie for Google Account to a txt file
# 2. Change line 56,line 116,line 118 for the txt file and downloaded video path
# 3. run VideoDownload.py
# 4. If the download speed is slow,you can download videos on servers such as AWS

cd data
python VideoDownload.py
Data Format
[
  {
    "audio_id": "path_to_audio_file",
    "instruction": "Question",
    "input": "",
    "dataset": "dataset_name",
    "task": "type_of_task",
    "output": "correct_answer"
  }
]
🏋️ Training
Preprocessing
- Download Llama-2-7b-chat-hf-qformer model (refer to GAMA README)
- Update the model path in
src/GAMA/gama_finetune.pyat lines 96 and 101
Start Training
conda activate FusionAudio
cd scripts/train/
bash train.sh
📈 Evaluation
Classification Task Evaluation
cd scripts/eval
bash eval_cls.sh
Captioning Evaluation
cd scripts/eval
bash infer.sh
Retrieval Task Evaluation
# Environment preparation (refer to WavCaps repository)
# 1. Configure environment according to https://github.com/XinhaoMei/WavCaps/tree/master/retrieval
# 2. Set ckpt_path in inference.yaml
# 3. Put eval_retrieval.py into the downloaded retrieval folder

cd scripts
python eval_retrieval.py
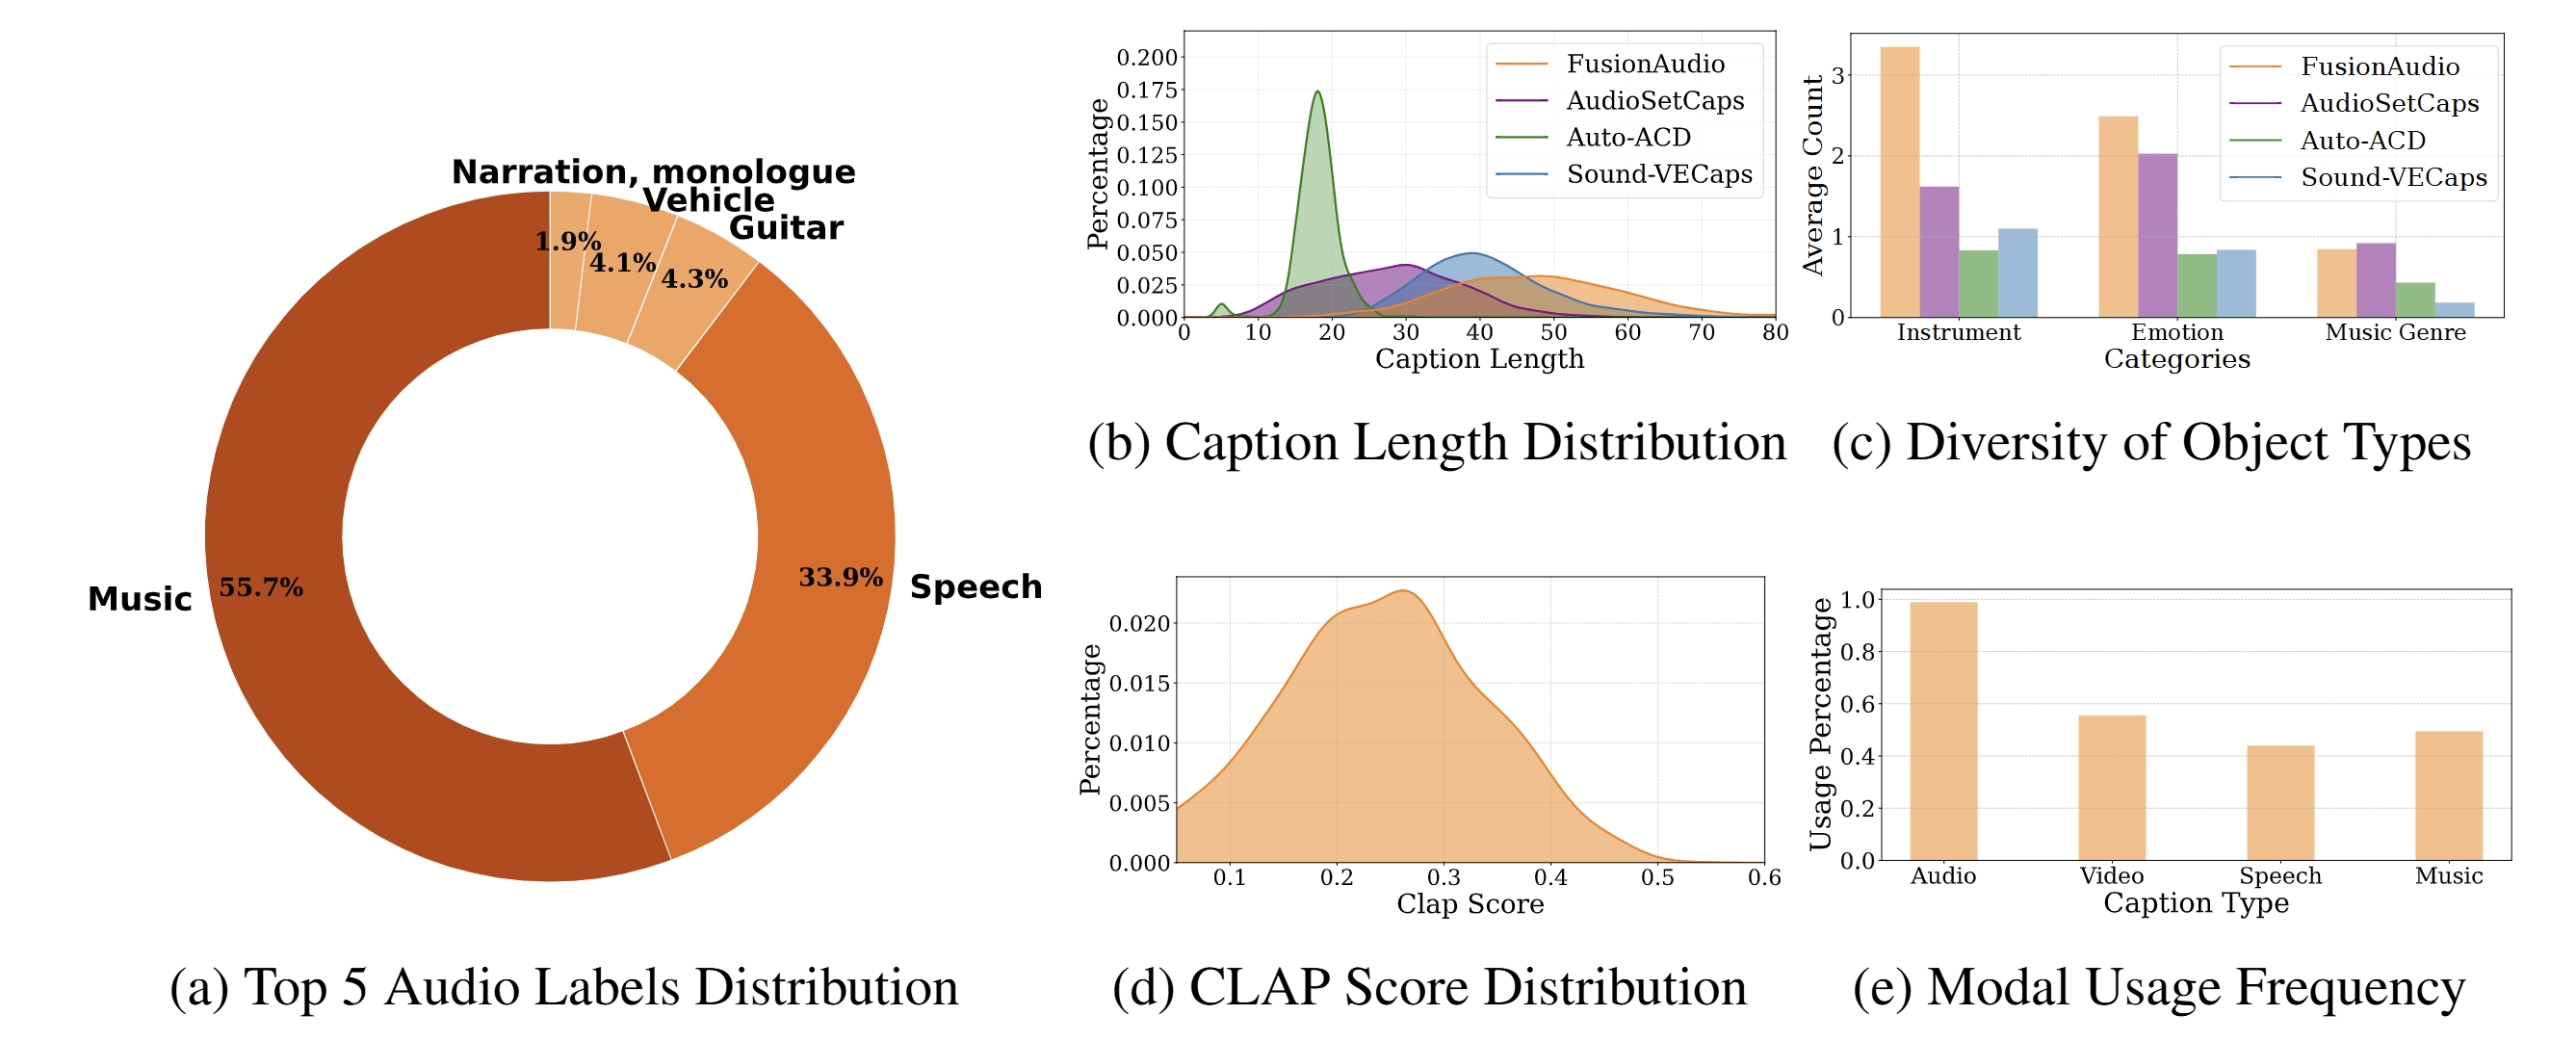
📋 Data Statistics
🛠️ Model Downloads
| Model Name | Purpose | Download Link |
|---|---|---|
| FusionAudio-25k/FusionAudio-25k-high | General audio understanding | 🤗 HuggingFace |
| FusionAudio-Retrieval | Audio retrieval | 🤗 HuggingFace |
❤️ Acknowledgments
- GAMA: Thanks for providing excellent infrastructure
- WavCaps: Thanks for pioneering work in audio captioning
- Llama: Thanks for providing powerful language model foundation
- AudioSet: Thanks for providing large-scale audio dataset and ontology
✒️ Citation
If our work is helpful for your research, please consider giving a star ⭐ and citing our paper 📝
@misc{chen2025fusionaudio12mfinegrainedaudiocaptioning,
      title={FusionAudio-1.2M: Towards Fine-grained Audio Captioning with Multimodal Contextual Fusion},
      author={Shunian Chen and Xinyuan Xie and Zheshu Chen and Liyan Zhao and Owen Lee and Zhan Su and Qilin Sun and Benyou Wang},
      year={2025},
      eprint={2506.01111},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2506.01111},
}
📄 License
Usage License: This dataset and models are intended for research use only. They are also restricted to uses that follow the license agreement of LLaMA, Vicuna and other related models. The dataset is CC BY NC 4.0 (allowing only non-commercial use) and models trained using the dataset should not be used outside of research purposes.
🌟 If this project helps you, please give us a Star! 🌟
Contributors


Similar repos



Languages
Python
82.6%
Jupyter Notebook
9.8%
MDX
7.1%
Towards Fine-grained Audio Captioning with Multimodal Contextual Cues
Python
90
28 commits
updated Jan 4, 2026
README
FusionAudio-1.2M, Towards Fine-grained Audio Captioning with Multimodal Contextual Cues
🚀🚀🚀 Official implementation of FusionAudio-1.2M: Towards Fine-grained Audio Captioning with Multimodal Contextual Cues
- Authors: Shunian Chen*, Xinyuan Xie*, Zheshu Chen*, Liyan Zhao, Owen Lee, Zhan Su, Qilin Sun, Benyou Wang
- Institutions: The Chinese University of Hong Kong, Shenzhen
- Resources: 📄 Paper | 🤗 Huggingface |
- Models: 🤗FusionAudio
💡 Highlights
- 🔥 Large-scale high-quality audio captioning dataset FusionAudio-1.2M
- 🔥 Multimodal context fusion for more fine-grained audio understanding
- 🔥 SOTA performance achieving state-of-the-art results on multiple audio understanding benchmarks
📜 News
[2025/06/01] 🚀 Our papar FusionAudio-1.2M, Towards Fine-grained Audio Captioning with Multimodal Contextual Cues is available!
[2025/05/16] 🚀 Released FusionAudio-1.2M dataset, model, and code!
🚀 Quick Start
Environment Setup
# Create conda environment
conda create -n FusionAudio python=3.10
conda activate FusionAudio

# Install dependencies
pip install -r requirements.txt
pip install -e src/GAMA/hf-dev-train/transformers-main
pip install -e src/GAMA/peft-main
Quick Inference
We provide an easy-to-use inference script quick_inference.py that supports both command-line and Python API usage.
Command Line Usage
python quick_inference.py \
    --base_model /path/to/Llama-2-7b-chat-hf-qformer \
    --model_path /path/to/fusionaudio_checkpoint.pth \
    --audio /path/to/your/audio.wav \
    --question "Please describe this audio in detail."
Python API Usage
from quick_inference import FusionAudioInference

# Initialize inferencer
inferencer = FusionAudioInference(
    base_model_path="/path/to/Llama-2-7b-chat-hf-qformer",
    model_path="/path/to/fusionaudio_checkpoint.pth",
    device="cuda:0"
)

# Audio captioning
response = inferencer.predict(
    audio_path="/path/to/your/audio.wav",
    question="Please describe this audio in detail."
)
print(f"Audio description: {response}")
For detailed parameter descriptions, run python quick_inference.py --help.
📊 Dataset
FusionAudio-1.2M
We constructed a large-scale dataset containing 1.2 million high-quality audio-text pairs.
Caption&QA Dataset Download Link: 🤗 Hugging Face
Video Download:
# Preparation
# 1. Write a cookie for Google Account to a txt file
# 2. Change line 56,line 116,line 118 for the txt file and downloaded video path
# 3. run VideoDownload.py
# 4. If the download speed is slow,you can download videos on servers such as AWS

cd data
python VideoDownload.py
Data Format
[
  {
    "audio_id": "path_to_audio_file",
    "instruction": "Question",
    "input": "",
    "dataset": "dataset_name",
    "task": "type_of_task",
    "output": "correct_answer"
  }
]
🏋️ Training
Preprocessing
- Download Llama-2-7b-chat-hf-qformer model (refer to GAMA README)
- Update the model path in
src/GAMA/gama_finetune.pyat lines 96 and 101
Start Training
conda activate FusionAudio
cd scripts/train/
bash train.sh
📈 Evaluation
Classification Task Evaluation
cd scripts/eval
bash eval_cls.sh
Captioning Evaluation
cd scripts/eval
bash infer.sh
Retrieval Task Evaluation
# Environment preparation (refer to WavCaps repository)
# 1. Configure environment according to https://github.com/XinhaoMei/WavCaps/tree/master/retrieval
# 2. Set ckpt_path in inference.yaml
# 3. Put eval_retrieval.py into the downloaded retrieval folder

cd scripts
python eval_retrieval.py
📋 Data Statistics
🛠️ Model Downloads
| Model Name | Purpose | Download Link |
|---|---|---|
| FusionAudio-25k/FusionAudio-25k-high | General audio understanding | 🤗 HuggingFace |
| FusionAudio-Retrieval | Audio retrieval | 🤗 HuggingFace |
❤️ Acknowledgments
- GAMA: Thanks for providing excellent infrastructure
- WavCaps: Thanks for pioneering work in audio captioning
- Llama: Thanks for providing powerful language model foundation
- AudioSet: Thanks for providing large-scale audio dataset and ontology
✒️ Citation
If our work is helpful for your research, please consider giving a star ⭐ and citing our paper 📝
@misc{chen2025fusionaudio12mfinegrainedaudiocaptioning,
      title={FusionAudio-1.2M: Towards Fine-grained Audio Captioning with Multimodal Contextual Fusion},
      author={Shunian Chen and Xinyuan Xie and Zheshu Chen and Liyan Zhao and Owen Lee and Zhan Su and Qilin Sun and Benyou Wang},
      year={2025},
      eprint={2506.01111},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2506.01111},
}
📄 License
Usage License: This dataset and models are intended for research use only. They are also restricted to uses that follow the license agreement of LLaMA, Vicuna and other related models. The dataset is CC BY NC 4.0 (allowing only non-commercial use) and models trained using the dataset should not be used outside of research purposes.
🌟 If this project helps you, please give us a Star! 🌟
Similar repos
Contributors
Languages
Python
82.6%
Jupyter Notebook
9.8%
MDX
7.1%