A 6-million Audio-Caption Paired Dataset Built with a LLMs and ALMs-based Automatic Pipeline
See the code
This project aims to build the largest audio-text paired dataset for scaling up future audio-language multimodal learning.
We provide:
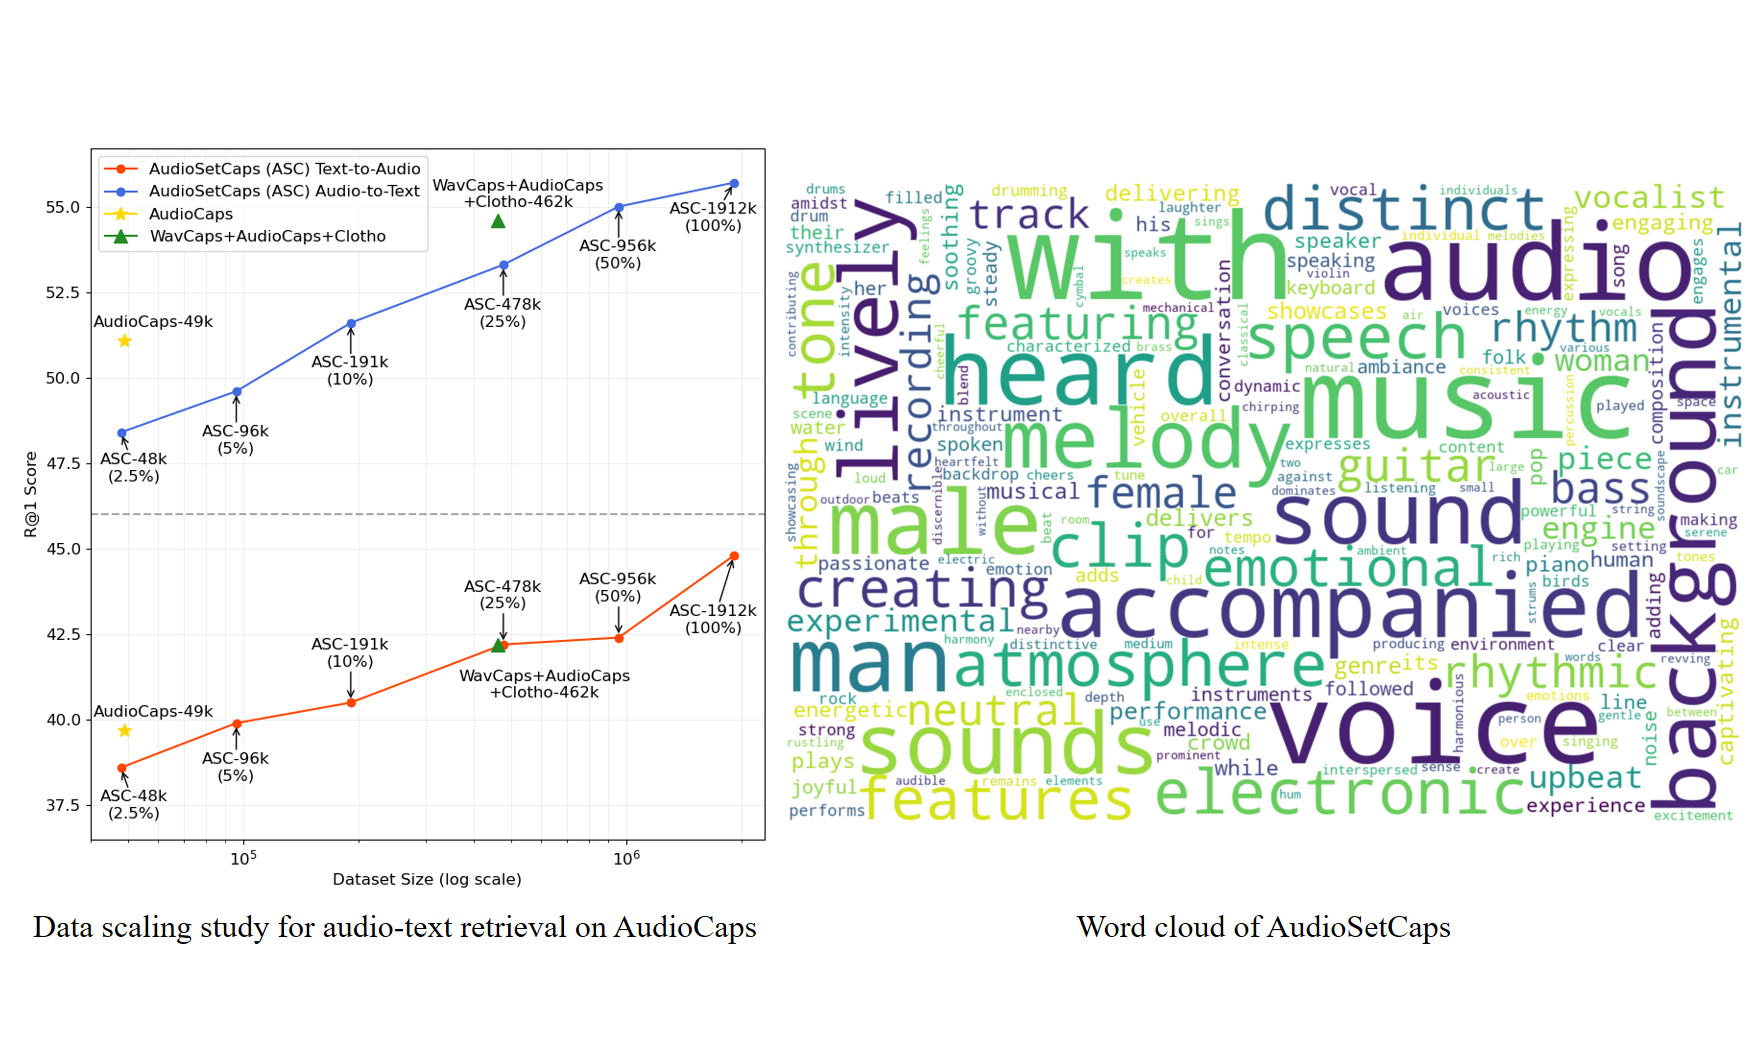
We show that model trained with AudioSetCaps achieves SOTA result on audio captioning (e.g., 84.8 CIDEr) and audio retrieval task (e.g., R@1 43.4-T2A & 57.3-A2T).
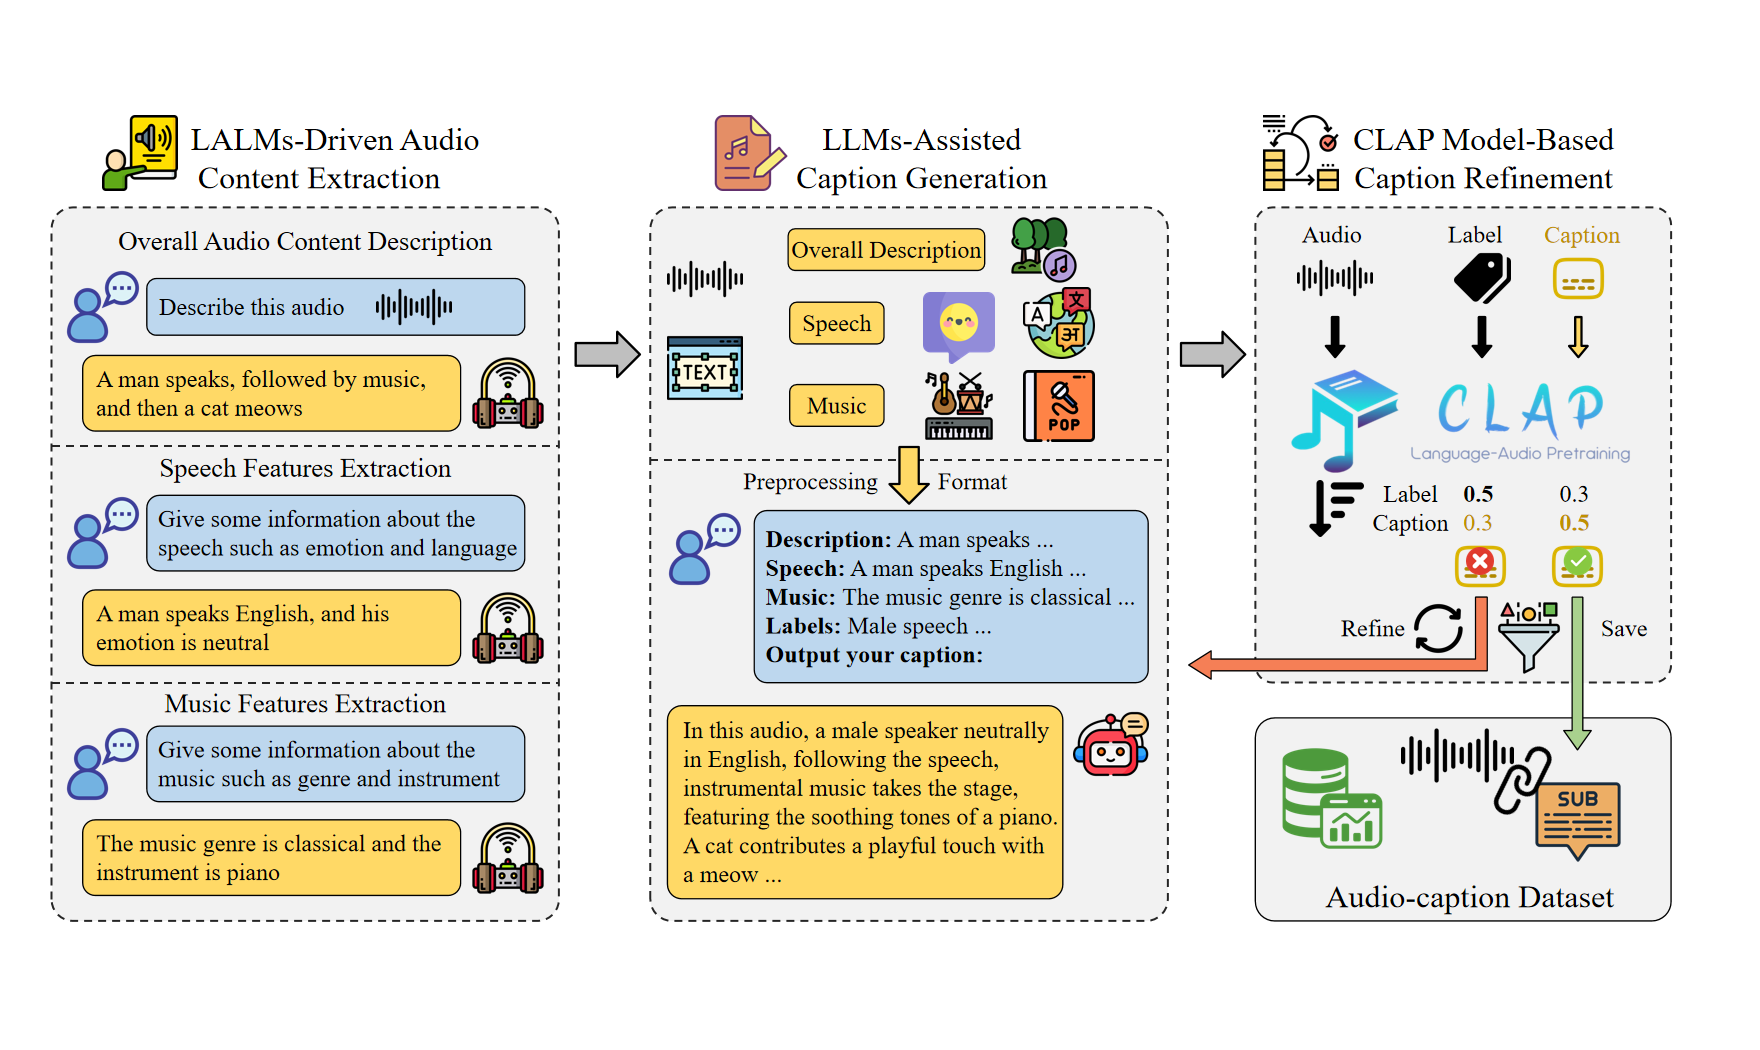 Overview of the proposed automated caption generation pipeline.
2024-12: Our full-length paper is publicly available on arXiv.
2024-10: To appear at NeurIPS 2024 Audio Imagination Workshop: NeurIPS 2024 Workshop AI-Driven Speech, Music, and Sound Generation.
We provide the caption and Q&A data for the following three datasets:
| Dataset | # Audio captions | # Q&A captions | Total |
|---|---|---|---|
| AudioSetCaps | 1910920 | 5736072 | 7646992 |
| YouTube-8M | 4023990 | 12086037 | 16110027 |
| VGGSound | 182189 | 592680 | 774869 |
| Total | 6117099 | 18414789 | 24531888 |
Note that:
For the 4M subset of YouTube-8M, you can download it through Google Drive.
For each audio clip, we assign a caption to it. Associated with the audio, there are also three Q&A pairs, which were used as the metadata to generate the final caption.
| Audio | Captions | Q&A captions 1 | Q&A captions 2 | Q&A captions 3 |
|---|---|---|---|---|
| -_7Xe9vD3Hpg_4_10.mp3 | A solemn instrumental piece unfolds, featuring the melancholic strains of a cello and the resonant tolling of a bell. The initial tempo is slow and deliberate, gradually building intensity with each successive bell ring. | Question: Describe this audio according to the sounds in it. Answer: The music starts with a slow string melody and continues with a bass note. The sound of a bell rings and the music becomes more intense. | Question: Based on the QAs, give some information about the speech, such as the emotion of the speaker, the gender of the speaker, and the spoken language, only if speech is present in this audio. Answer: I'm sorry, but there is no speech in the audio. | Question: Based on the QAs, give some information about the music, such as music genre and music instruments, only if music is present in this audio. Answer: The music genre is instrumental. The music instruments are the cello and the bell. |
| -TL8Mp3xcUM_0_10.mp3 | A woman expresses strong emotions with a noticeably high-pitched vocal tone. | Question: Describe this audio according to the sounds in it. Answer: A woman speaks with a high-pitched voice. | Question: Based on the QAs, give some information about the speech, such as the emotion of the speaker, the gender of the speaker, and the spoken language, only if speech is present in this audio. Answer: The speech is emotional, as the woman speaks in a high-pitched voice. | Question: Based on the QAs, give some information about the music, such as music genre and music instruments, only if music is present in this audio. Answer: There is no music in this audio. |
If you found this repo is helpful, please consider citing our papers:
@article{bai2024audiosetcaps,
  title={AudioSetCaps: An Enriched Audio-Caption Dataset using Automated Generation Pipeline with Large Audio and Language Models},
  author={Bai, Jisheng and Liu, Haohe and Wang, Mou and Shi, Dongyuan and Wang, Wenwu and Plumbley, Mark D and Gan, Woon-Seng and Chen, Jianfeng},
  journal={arXiv preprint arXiv:2411.18953},
  year={2024}
}
@inproceedings{
bai2024audiosetcapsnipsws,
title={AudioSetCaps: Enriched Audio Captioning Dataset Generation Using Large Audio Language Models},
author={Bai, Jisheng and Liu, Haohe and Wang, Mou and Shi, Dongyuan and Wang, Wenwu and Plumbley, Mark D and Gan, Woon-Seng and Chen, Jianfeng},
booktitle={Audio Imagination: NeurIPS 2024 Workshop AI-Driven Speech, Music, and Sound Generation},
year={2024},
url={https://openreview.net/forum?id=uez4PMZwzP}
}
219 followers · starred Oct 2024
148 followers · starred May 2025
200 followers · starred Dec 2024
254 followers · starred Nov 2024
A 6-million Audio-Caption Paired Dataset Built with a LLMs and ALMs-based Automatic Pipeline
See the code
This project aims to build the largest audio-text paired dataset for scaling up future audio-language multimodal learning.
We provide:
We show that model trained with AudioSetCaps achieves SOTA result on audio captioning (e.g., 84.8 CIDEr) and audio retrieval task (e.g., R@1 43.4-T2A & 57.3-A2T).
Overview of the proposed automated caption generation pipeline.
2024-12: Our full-length paper is publicly available on arXiv.
2024-10: To appear at NeurIPS 2024 Audio Imagination Workshop: NeurIPS 2024 Workshop AI-Driven Speech, Music, and Sound Generation.
We provide the caption and Q&A data for the following three datasets:
| Dataset | # Audio captions | # Q&A captions | Total |
|---|---|---|---|
| AudioSetCaps | 1910920 | 5736072 | 7646992 |
| YouTube-8M | 4023990 | 12086037 | 16110027 |
| VGGSound | 182189 | 592680 | 774869 |
| Total | 6117099 | 18414789 | 24531888 |
Note that:
For the 4M subset of YouTube-8M, you can download it through Google Drive.
For each audio clip, we assign a caption to it. Associated with the audio, there are also three Q&A pairs, which were used as the metadata to generate the final caption.
| Audio | Captions | Q&A captions 1 | Q&A captions 2 | Q&A captions 3 |
|---|---|---|---|---|
| -_7Xe9vD3Hpg_4_10.mp3 | A solemn instrumental piece unfolds, featuring the melancholic strains of a cello and the resonant tolling of a bell. The initial tempo is slow and deliberate, gradually building intensity with each successive bell ring. | Question: Describe this audio according to the sounds in it. Answer: The music starts with a slow string melody and continues with a bass note. The sound of a bell rings and the music becomes more intense. | Question: Based on the QAs, give some information about the speech, such as the emotion of the speaker, the gender of the speaker, and the spoken language, only if speech is present in this audio. Answer: I'm sorry, but there is no speech in the audio. | Question: Based on the QAs, give some information about the music, such as music genre and music instruments, only if music is present in this audio. Answer: The music genre is instrumental. The music instruments are the cello and the bell. |
| -TL8Mp3xcUM_0_10.mp3 | A woman expresses strong emotions with a noticeably high-pitched vocal tone. | Question: Describe this audio according to the sounds in it. Answer: A woman speaks with a high-pitched voice. | Question: Based on the QAs, give some information about the speech, such as the emotion of the speaker, the gender of the speaker, and the spoken language, only if speech is present in this audio. Answer: The speech is emotional, as the woman speaks in a high-pitched voice. | Question: Based on the QAs, give some information about the music, such as music genre and music instruments, only if music is present in this audio. Answer: There is no music in this audio. |
If you found this repo is helpful, please consider citing our papers:
@article{bai2024audiosetcaps,
  title={AudioSetCaps: An Enriched Audio-Caption Dataset using Automated Generation Pipeline with Large Audio and Language Models},
  author={Bai, Jisheng and Liu, Haohe and Wang, Mou and Shi, Dongyuan and Wang, Wenwu and Plumbley, Mark D and Gan, Woon-Seng and Chen, Jianfeng},
  journal={arXiv preprint arXiv:2411.18953},
  year={2024}
}
@inproceedings{
bai2024audiosetcapsnipsws,
title={AudioSetCaps: Enriched Audio Captioning Dataset Generation Using Large Audio Language Models},
author={Bai, Jisheng and Liu, Haohe and Wang, Mou and Shi, Dongyuan and Wang, Wenwu and Plumbley, Mark D and Gan, Woon-Seng and Chen, Jianfeng},
booktitle={Audio Imagination: NeurIPS 2024 Workshop AI-Driven Speech, Music, and Sound Generation},
year={2024},
url={https://openreview.net/forum?id=uez4PMZwzP}
}
219 followers · starred Oct 2024
148 followers · starred May 2025
200 followers · starred Dec 2024
254 followers · starred Nov 2024