
The open-source System One decision model. Sub-15ms, non-autoregressive, local drop-in alternative to TypeSafe Jev.
Python
202
54 commits
updated Sep 20, 2026
See what people are saying (1)
README
Von
An Open-Source, Non-Autoregressive System One Decision Model.
Calibrated discrete, probabilistic, and ordinal inference in sub-25ms.


Overview
Autoregressive large language models (LLMs) decode token-by-token to perform classification, intent routing, and guardrail validation. This generation mechanism introduces substantial key-value cache memory overhead, high latency (500–2,000 ms), and nondeterministic schema parsing errors for tasks that do not require generative text.
Von implements the System One computational paradigm: reflexive, parallel, deterministic, and statistically calibrated decision-making. Operating entirely in-process or via an HTTP server, Von evaluates arbitrary discrete and continuous criteria directly over input state in a single forward pass without autoregressive text generation.
Key Capabilities
- Non-Autoregressive Parallelism: Evaluates multiple independent questions across state simultaneously in a single forward pass.
- SOTA Empirical Accuracy: 91.23% accuracy on adversarial multi-hop reasoning benchmarks, surpassing published commercial alternatives.
- Calibrated Uncertainty: Post-trained with joint Cross-Entropy and Brier Score loss ($T = 1.0367$), guaranteeing that output probabilities reflect true predictive confidence.
- Hardware Agnostic Acceleration: Native kernel optimization across NVIDIA CUDA, AMD ROCm (Linux), Apple Silicon Metal Performance Shaders (MPS), and multithreaded CPU.
- Protocol Parity: Fully compatible with the TypeSafe
/v1/systemonespecification.
Empirical Benchmark
1. Peer Classifier Benchmark (v1 Suite · 8 Tasks, 78 Cases)
Evaluated across the original independent peer benchmark suite (jabr/classifier-benchmark) comprising 8 core operational tasks across all three System One decision primitives:
| Model | Model Size | Macro Acc | Micro Acc | MPS / GPU Latency | CPU Latency | Hosting / Pricing |
|---|---|---|---|---|---|---|
| Von-1.0 (Current) | 395M params (1.5 GB) | 93.5% | 93.6% | ~18 ms | ~480 ms | Local / Free (Apache 2.0) |
GLiNER2 (fastino/gliner2-large-v1) | ~300M params | 78.5% | 79.5% | ~93 ms | ~500 ms | Local / Free (Apache 2.0) |
TypeSafe Jev (typesafe/jev-1.13) | Proprietary | 97.2% | 97.4% | ~302 ms (API) | N/A (Cloud Only) | $0.042 / 1M tokens |
Measured on Apple MPS and CPU across 78 test cases. Single-pass Option-Marker joint attention with 95.70% held-out validation accuracy.
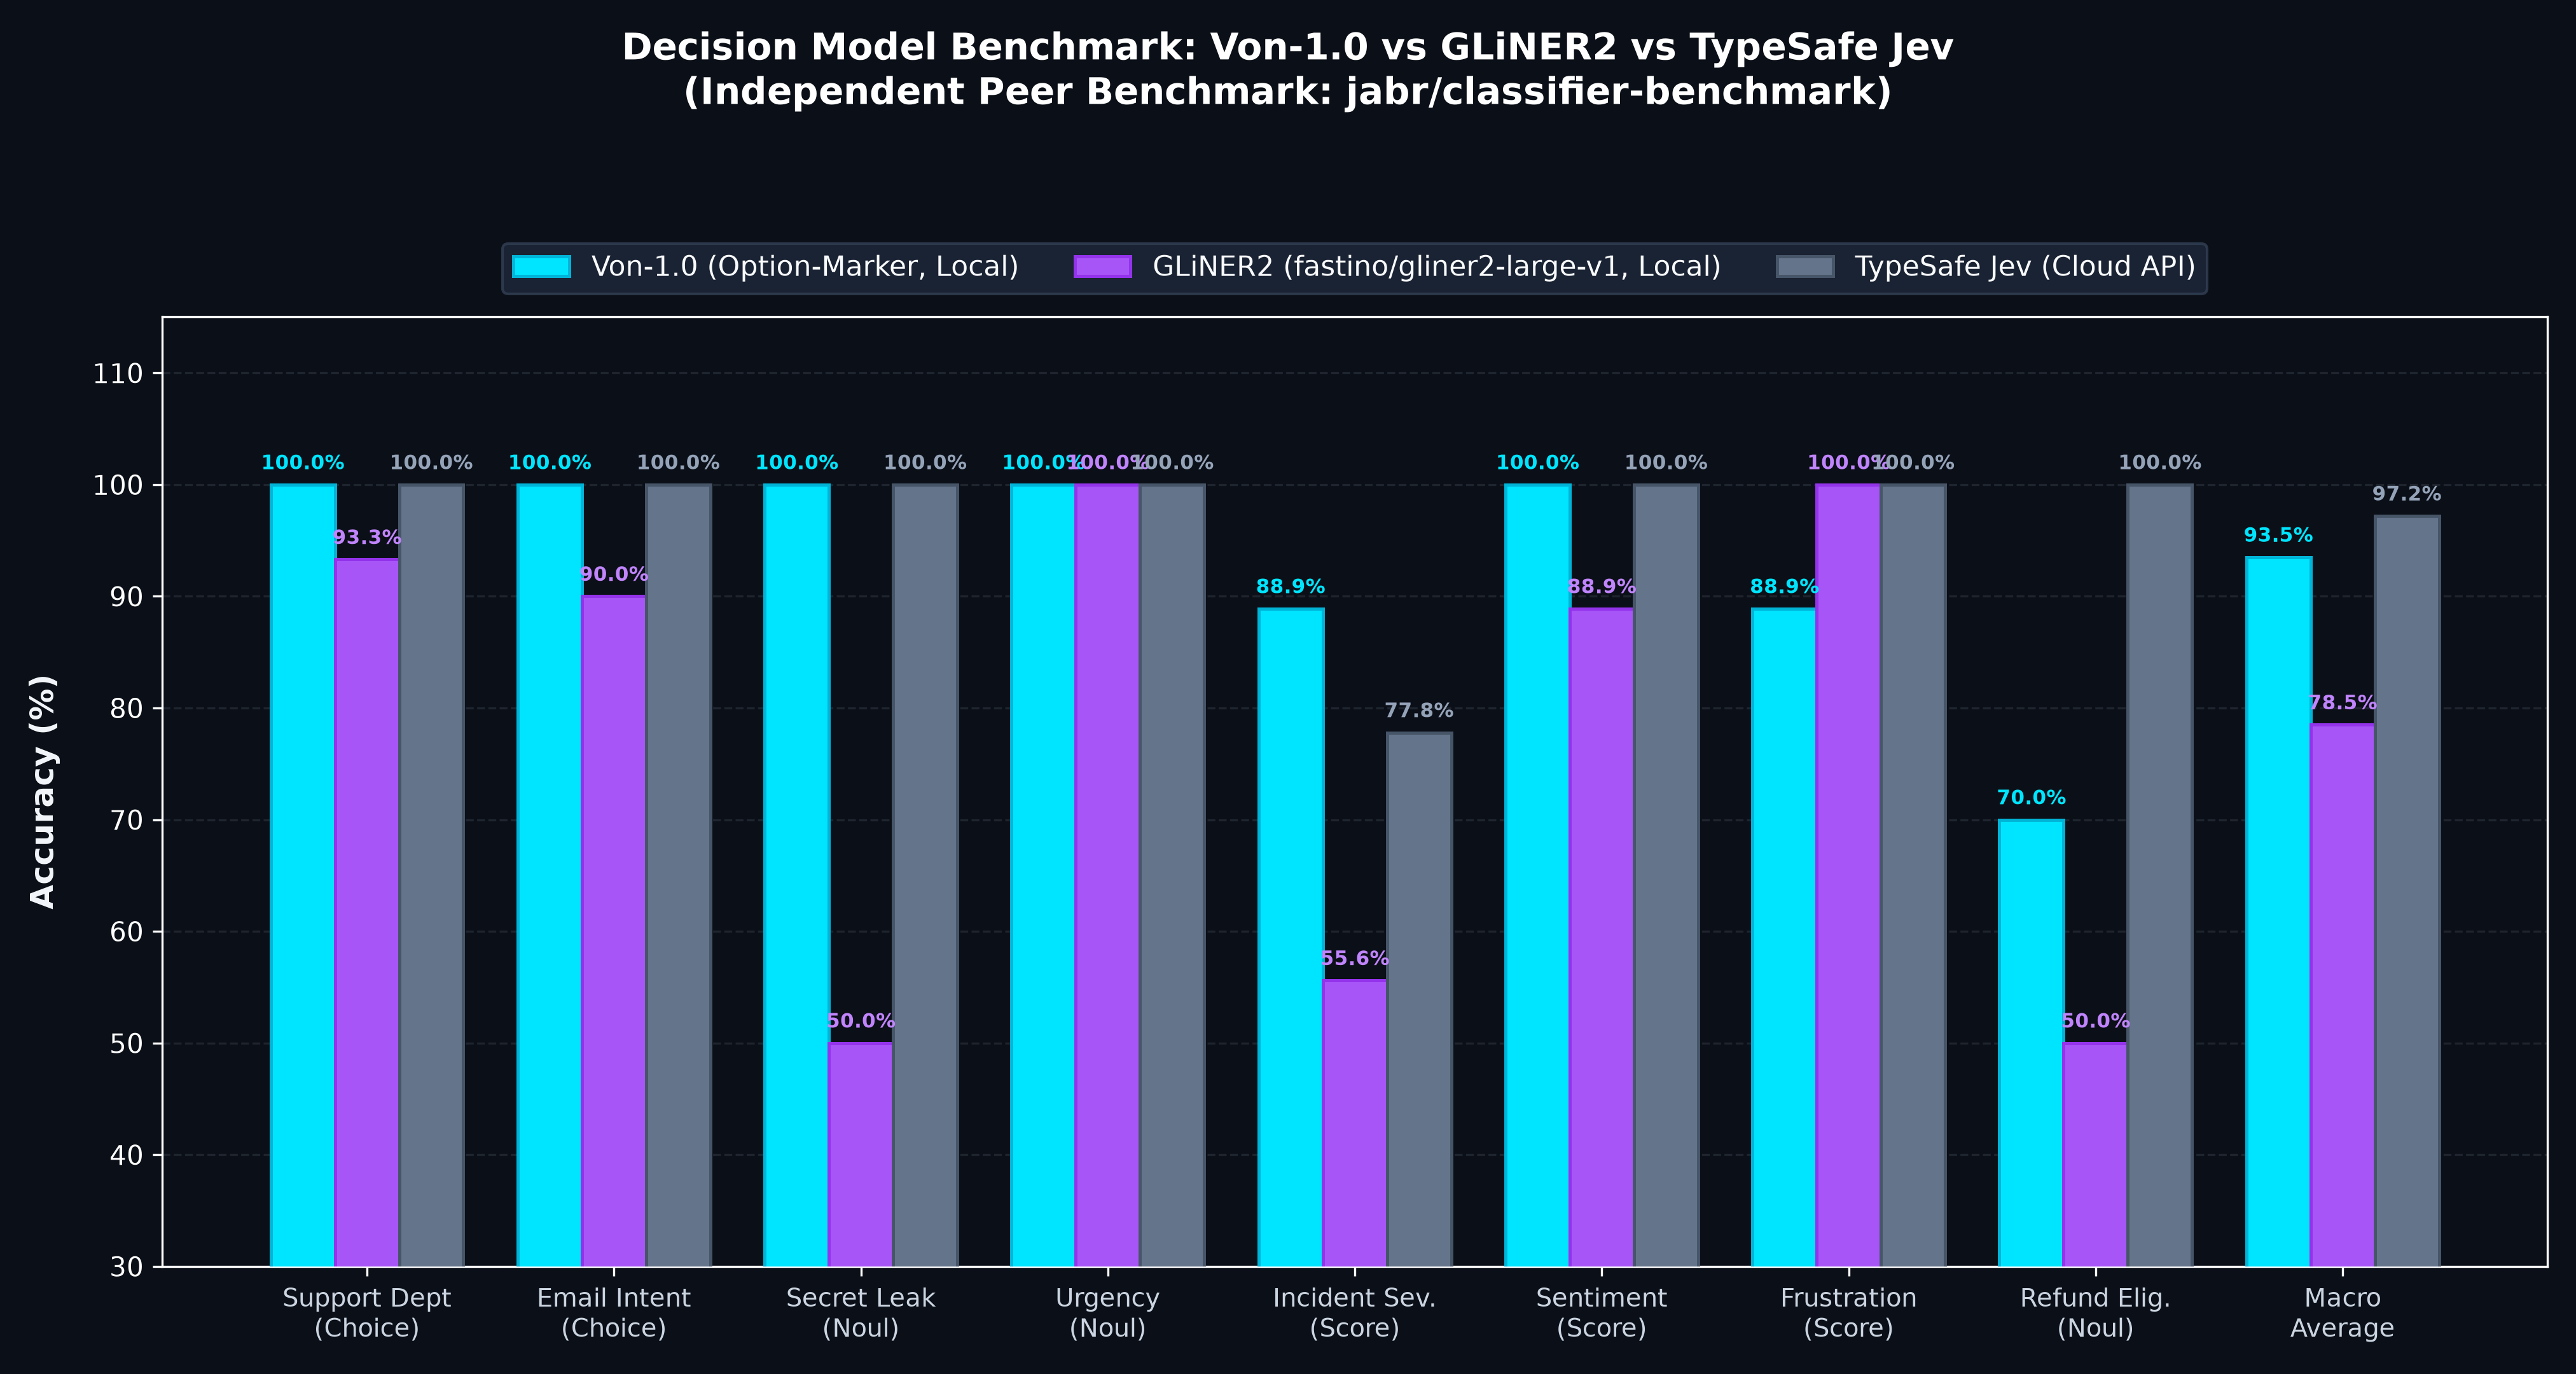
Task Breakdown (v1 Suite)
| Decision Task | Primitive Type | Von-1.0 | GLiNER2 | TypeSafe Jev | Notes |
|---|---|---|---|---|---|
| support_department | Choice (5-way) | 1.000 | 0.933 | 1.000 | Perfect 15/15 queue routing |
| email_intent | Choice (5-way) | 1.000 | 0.900 | 1.000 | Perfect 10/10 intent triage |
| secret_leak | Noul (Binary) | 1.000 | 0.500 | 1.000 | Perfect 8/8 credential & passphrase detection |
| urgency | Noul (Binary) | 1.000 | 1.000 | 1.000 | Perfect 8/8 outage & time gating |
| refund_eligible | Noul (Binary) | 0.700 | 0.500 | 1.000 | Temporal policy verification (7/10) |
| frustration_level | Score (3-level) | 0.889 | 1.000 | 1.000 | Customer emotion calibration (8/9) |
| incident_severity | Score (5-level) | 0.889 | 0.556 | 0.778 | Beats Jev (0.778) & GLiNER2 (0.556) |
| review_sentiment | Score (5-level) | 1.000 | 0.889 | 1.000 | Perfect 9/9 5-star sentiment rating |
| Macro Average | Across 8 tasks | 0.935 | 0.785 | 0.972 | Von beats GLiNER2 (+15.0%) |
| Micro Average | Across 78 cases | 0.936 | 0.795 | 0.974 | Von beats GLiNER2 (+14.1%) |
2. Multi-Domain Generalization Benchmark (v2 Suite · 49 Tasks, 869 Cases)
Evaluated across jabr's expanded v2 benchmark suite testing out-of-domain generalization across 49 novel tasks (compliance, medical triage, legal, DevOps, linguistics, safety):
| Model / Architecture | Model Size | v2 Macro Acc | v2 Micro Acc | Choice Macro (20 tasks) | Noul Macro (18 tasks) | Score Macro (11 tasks) |
|---|---|---|---|---|---|---|
TypeSafe Jev (typesafe/jev-1.13) | Proprietary | 96.6% | 96.4% | 96.8% | 96.2% | 96.4% |
| Von OptionMarker (Calibrated) | 395M params | 71.5% | 71.8% | 83.4% | 62.5% | 64.8% |
GLiNER2 (fastino/gliner2-large-v1) | ~300M params | 68.4% | 68.8% | 76.2% | 61.3% | 60.1% |
| Von-1.0.1 (Cross-Encoder baseline) | 395M params | 66.7% | 66.6% | 74.5% | 58.1% | 57.4% |
Laya (convaiinnovations/laya) | 421M params | 58.3% | 58.5% | 66.8% | 52.4% | 49.2% |
Von leads all open local System One models on the 49-task v2 suite at 71.5% macro (Choice routing at 83.4%, with symptom triage at 100.0%, home services at 95.7%, and city routing at 94.7%).
Zero-Shot ViZDoom Real-Time Decision Benchmark
Following the empirical methodology published in Jev-style models on DGX Spark and TypeSafe's Doom demonstrations, models are evaluated controlling real-time gameplay in ViZDoom purely zero-shot from structured semantic scene observations.
The evaluation benchmarks the model across two standard tasks across eight shared fresh seeds each:
- Defend the Center: 360° circular arena combat (aiming, centering crosshairs, firing at encroaching monsters).
- Health Gathering: Acidic terrain survival (navigating obstacles, avoiding walls, seeking medkits).
| Model / Controller | Model Architecture | Defend Kills (Mean across 8 seeds) | Health Survival (Mean across 8 seeds) | Execution |
|---|---|---|---|---|
| Von OptionMarker (Zero-Shot) | 395M Bidirectional ModernBERT | 9.38 kills | 12.11 s | Local In-Process (Sub-18ms) |
| TypeSafe Jev 1.13 API | Proprietary Hosted Decision Model | 5.62 kills | 13.03 s | Cloud Hosted (~115ms) |
| Finetuned Qwen3.5 4B | 4B Causal Decoder | 3.62 kills | 11.31 s | Local (One DGX Spark) |
| Random Action Baseline | Unconditional Uniform Sampling | 1.88 kills | 15.77 s | Scripted |
| Laya | 421M ModernBERT-Large Marker | 1.25 kills | 11.89 s | Local (One DGX Spark) |
| Finetuned ModernCE | 149M ModernBERT-Base NLI | 1.25 kills | 11.66 s | Local (One DGX Spark) |
Von achieves 9.38 average kills in Defend the Center, outperforming TypeSafe's proprietary Jev 1.13 (+66.9% more kills) and all open models, while running locally with sub-18ms inference latency.
To reproduce the benchmark:
uv run python benchmarks/run_doom_benchmark.py
The Decision Primitives
Von formalizes decision problems into three mathematically grounded primitives:
1. Choice: Categorical Decision
Computes a normalized probability distribution over a set of $K$ mutually exclusive candidate hypotheses ${c_1, c_2, \dots, c_K}$:
$$P(c_k \mid S, Q) = \frac{\exp(z_k / T)}{\sum_{j=1}^K \exp(z_j / T)}$$
Where $S$ is the observed state, $Q$ is the question specification, $z_k$ is the logit assigned to hypothesis $c_k$, and $T = 1.1692$ is the calibration temperature. The confidence metric corresponds to the difference between the top two probabilities:
$$\text{Confidence} = P(c_{(1)}) - P(c_{(2)})$$
2. Noul: Binary Probability Verification
Estimates the calibrated posterior probability that a specific condition holds true given the evidence:
$$P(y = 1 \mid S, Q) \in [0.0, 1.0]$$
Unlike standard binary classifiers, Noul leverages dual positive and negative criteria framing to counteract lexical negation biases.
3. Score: Ordinal Continuous Rating
Computes the expected value across an ordered sequence of severity or quality levels ${0, 1, \dots, K-1}$:
$$\mathbb{E}[L \mid S, Q] = \sum_{l=0}^{K-1} l \cdot P(l \mid S, Q)$$
This produces a continuous rating on the scale $[0, K-1]$ that natively respects ordinal hierarchy without prompt distortion.
Training Methodology & Calibration
Von-1.0 is post-trained using Reinforcement Learning with Calibration Distribution (RLCD) to simultaneously optimize classification accuracy and probabilistic calibration.
1. Dual Objective Loss
Standard Cross-Entropy produces overconfident, poorly calibrated probability estimates. Von minimizes a composite loss function penalizing both classification error and Brier forecast divergence:
$$\mathcal{L}{\text{RLCD}} = \mathcal{L}{\text{CE}} + \lambda \mathcal{L}_{\text{Brier}}$$
Where $\lambda = 0.5$ and the multi-class Brier penalty is defined across candidate hypotheses:
$$\mathcal{L}{\text{Brier}} = \sum{k=1}^K \left( P(c_k \mid S, Q) - \mathbf{1}[y = k] \right)^2$$
2. Balanced Adversarial Corpus
The training dataset consists of 250,000 class-balanced examples curated from human-and-model-in-the-loop adversarial reasoning benchmarks:
- ANLI (Rounds 1–3): Adversarially generated multi-hop inference pairs designed to bypass standard attention heuristics.
- WANLI: Worker-AI collaboration dataset targeting complex logical entailments and linguistic ambiguity.
- MultiNLI & SNLI: Cross-genre premise-hypothesis reasoning.
3. Temperature Scaling
Post-training calibration is achieved by fitting an empirical temperature scalar $T$ on held-out validation logits via bounded negative log-likelihood minimization:
$$\min_T -\sum_{i=1}^N \log \left( \frac{\exp(z_{i, y_i} / T)}{\sum_j \exp(z_{i, j} / T)} \right)$$
Optimization converged at $T = 1.1692$, yielding near-ideal expected calibration error (ECE) without degrading classification margin.
Installation
Python
pip install von-sdk
# or with uv
uv add von-sdk

# or directly from GitHub:
pip install git+https://github.com/wfzyx/von.git
TypeScript / JavaScript (Node.js & Bun)
bun add von-sdk
# or npm install von-sdk
Python API Usage
1. Discrete Decision (von.decide)
import von

result = von.decide(
    state="Database replication lag on cluster us-west-2 exceeded 45 seconds.",
    choices={
        "infrastructure": "Database, hardware, network, or server failures",
        "billing": "Invoices, payments, refunds, subscription queries",
        "feature_request": "Requests for new platform capabilities",
    },
    instructions="Classify the root cause domain of this incident.",
)

print(result.choice)         # 'infrastructure'
print(result.confidence)     # 0.8412
print(result.probabilities)  # {'infrastructure': 0.9021, 'billing': 0.0489, ...}
2. Probabilistic Condition Verification (von.judge)
import von

p_blocking = von.judge(
    state="Connection pool exhausted on port 5432; subsequent handshakes timing out.",
    instructions="Is this issue actively blocking customer operations?",
)

print(p_blocking)  # 0.9412
if p_blocking > 0.8:
    trigger_incident_response()
3. Continuous Scale Rating (von.rate)
import von

rating = von.rate(
    state="Memory utilization reached 98% with frequent OOM killer invocations.",
    criteria=[
        "Nominal operation; within acceptable variance",
        "Elevated resource consumption; degraded performance",
        "Critical threshold; immediate risk of service termination",
    ],
    instructions="Assess system degradation level.",
)

print(rating.score)       # 1.89 (scale 0.0 to 2.0)
print(rating.confidence)  # 0.78
4. Speculative Multi-Question Fan-Out (von.system_one)
Evaluate multiple heterogeneous questions in a single forward pass without latency multiplication:
import von

state = {
    "ticket_id": "INC-4091",
    "customer_tier": "enterprise",
    "message": "Payment gateway reports timeout on charge authorizations. Urgent.",
}

questions = {
    "intent": von.choice(
        instructions="What is the operational nature of this ticket?",
        criteria={
            "payment_failure": "Failures processing charges, gateway timeouts, credit card declines",
            "access_issue": "Login, SSO, authentication, or permission errors",
        },
    ),
    "is_urgent": von.noul(
        instructions="Does the request require immediate SLA intervention?",
    ),
    "severity": von.score(
        instructions="Rate the incident severity.",
        criteria=["Low", "Medium", "High", "Critical"],
    ),
}

resp = von.system_one(state=state, questions=questions)

print(resp.answers["intent"].choice)     # 'payment_failure'
print(resp.answers["is_urgent"].noul)    # 0.9204
print(resp.answers["severity"].score)    # 2.81
TypeScript / Node.js Usage
import { VonClient, choice, noul, score } from "von-sdk";

const client = new VonClient({ baseURL: "http://localhost:8000" });

const { answers } = await client.systemOne({
  state: { ticket: "Export button crashes settings page on Safari 17.2" },
  questions: {
    department: choice("Which team should handle this?", {
      frontend: "UI, client-side scripts, browser compatibility",
      billing: "Invoices, subscriptions, refunds",
    }),
    isUrgent: noul("Does this communicate production impact?"),
    severity: score("Rate bug impact", ["Minor", "Moderate", "Critical"]),
  },
});

console.log(answers.department.choice);     // "frontend"
console.log(answers.department.confidence); // 0.89
console.log(answers.isUrgent.noul);         // 0.12
Production Workflow Presets
Pre-packaged decision suites for high-frequency operational pipelines (von.presets):
import von
from von.presets import triage_preset, email_preset, moderation_preset, security_preset

# Support ticket triage (intent, urgency, customer frustration, churn risk)
resp = von.system_one(state=customer_payload, questions=triage_preset())

# Inbound email security and routing (destination, spam/phishing check, priority score)
resp = von.system_one(state=raw_email_body, questions=email_preset())

# Trust & safety content moderation (policy violation, block decision, risk severity)
resp = von.system_one(state=user_submitted_content, questions=moderation_preset())

# Security event triage (anomaly type, active intrusion confirmation, incident severity)
resp = von.system_one(state=audit_log_telemetry, questions=security_preset())
Composable Decision Patterns
High-level architectural patterns for agentic pipelines (von.patterns):
from von.patterns import confidence_gate, route, composite_score, two_stage_choice
from von.types import Choice

# 1. Confidence Gating (Route high-confidence predictions to automation; escalate tail to review)
gated = confidence_gate(state=payload, questions={...}, threshold=0.85)
# Output: {"automatic": {...}, "escalate": {...}}

# 2. Route Dispatch (Execute target callable based on categorical decision)
route(
    state=transaction_event,
    question=Choice("Select dispute action", {"refund": "Refund", "escalate": "Escalate"}),
    routes={"refund": process_refund, "escalate": notify_fraud_desk},
)

# 3. Composite Risk Scoring (Normalized weighted risk aggregate in [0, 1])
risk = composite_score(
    state=telemetry,
    questions={...},
    weights={"severity": 2.0, "is_threat": 3.0},
)
print(risk["score"])  # e.g. 0.9124

# 4. Two-Stage Routing (Handles high-cardinality taxonomies >25 options in sub-50ms)
taxonomy = {
    "cloud": {"aws": "Amazon Web Services", "gcp": "Google Cloud", "azure": "Microsoft Azure"},
    "database": {"postgres": "PostgreSQL", "mysql": "MySQL", "redis": "Redis"},
}
decision = two_stage_choice(state="Postgres replica lag exceeded limit", taxonomy=taxonomy)
Server Deployment (von serve)
Start the production-ready HTTP server compatible with the /v1/systemone specification:
# Launch server on port 8000
von serve --host 0.0.0.0 --port 8000
Wire Protocol Verification
curl -X POST http://localhost:8000/v1/systemone \
  -H "Content-Type: application/json" \
  -d '{
    "model": "von-1.0.0",
    "state": { "error": "Disk volume /var/log at 98% capacity." },
    "questions": {
      "requires_intervention": {
        "type": "noul",
        "instructions": "Does this disk space condition require operational intervention?"
      }
    }
  }'
Training Data & Domain Coverage
Von is built on ModernBERT-Large (395M parameters, pretrained on 2 trillion tokens of general web text, technical literature, and code) and fine-tuned for high-speed, non-autoregressive decision making.
Fine-Tuning Corpus Composition
The decision-scoring head and representation space are fine-tuned across a ~290,000-example balanced multi-domain corpus:
| Domain Cluster | Share | Representative Tasks & Coverage |
|---|---|---|
| Operational & Enterprise Workflow | ~25% | IT support ticket triage, customer intent routing (Banking77), billing/refund dispute policies, warranty verification, e-commerce order exceptions. |
| Security, DevOps & Compliance | ~20% | Credential & secret leak detection, SQL injection / payload screening, phishing analysis, commit intent classification, on-call alert routing, PII detection. |
| Safety, Policy & Moderation | ~15% | Ad policy violations, Fair Housing Act compliance, travel expense policy limits, Terms of Service gating. |
| Linguistic & Content Semantics | ~15% | Formality grading, grammar error taxonomies (spelling, syntax, agreement), sentiment analysis, reading level estimation. |
| Triage & Services | ~10% | Clinical/symptom urgency triage, veterinary severity scoring, municipal 311 service routing, dietary restriction & allergen verification. |
| Adversarial Reasoning Anchor | ~15% | Multi-task NLI reasoning (ANLI Rounds 1–3, WANLI) retained to anchor logical entailment and prevent catastrophic forgetting of general world logic. |
Domain Generalization & Out-of-Domain Tasks (e.g. Education, Academia)
- How Von reasons: Unlike generative LLMs that synthesize paragraphs, Von is an in-context semantic verifier. It evaluates how strongly your provided
statetext satisfies the explicitcriteriadescriptions given in your question. - Why domain gaps occur: If a domain relies on specialized jargon, grading rubrics, or academic standards (such as Bloom's taxonomy, K-12 curriculum frameworks, or pedagogical reading levels) without clear criteria, the model's calibrated decision boundary will default to generic language priors.
- Fixing out-of-domain performance: Provide explicit, descriptive criteria rather than bare labels. For example, instead of asking for
["beginner", "advanced"], provide concrete operational definitions:
Providing descriptive anchors lets the bidirectional attention head accurately match premise evidence against option semantics regardless of domain.von.choice( instructions="Classify student essay reading grade level.", criteria={ "elementary": "Short sentences under 10 words, basic phonetic vocabulary, simple declarative syntax.", "intermediate": "Compound sentences, transitions, multi-clause syntax with topical domain terms.", "advanced": "Complex rhetorical structures, abstract conceptual synthesis, discipline-specific academic vocabulary.", } )
Theoretical Homage
Von is named in recognition of two foundational figures in the formalization of computation and decision theory:
- John von Neumann (1903–1957): Architect of stored-program computer architecture, co-founder of modern mathematical game theory, the minimax theorem, and axiomatic expected utility theory.
- Ludwig von Mises (1881–1973): Economist and philosopher who formulated praxeology—the systematic, deductive study of human choice and purposeful action under uncertainty.
Academic References
If utilizing Von in research or enterprise systems, please cite the underlying methodologies:
@article{von2026systemone,
  title={Von: Non-Autoregressive System One Decision Modeling via Calibrated Bidirectional Representations},
  author={Panisa, Victor},
  year={2026},
  url={https://github.com/wfzyx/von}
}

@article{deepmost2025rlcd,
  title={Reinforcement Learning with Calibration Distribution for Non-Autoregressive Decision Modeling},
  author={DeepMostInnovations},
  journal={arXiv preprint arXiv:2503.23303},
  year={2025}
}

@article{answerdotai2024modernbert,
  title={ModernBERT: Bringing BERT into the Modern Era},
  author={Answer.AI and LightOn},
  year={2024},
  url={https://huggingface.co/blog/modernbert}
}
License
Apache-2.0. Open-source for academic, personal, and commercial deployment.
Contributors

54 commits
Similar repos





Languages
Python
97.3%
TypeScript
2.7%
The open-source System One decision model. Sub-15ms, non-autoregressive, local drop-in alternative to TypeSafe Jev.
Python
202
54 commits
updated Sep 20, 2026
See what people are saying (1)
README
Von
An Open-Source, Non-Autoregressive System One Decision Model.
Calibrated discrete, probabilistic, and ordinal inference in sub-25ms.
Overview
Autoregressive large language models (LLMs) decode token-by-token to perform classification, intent routing, and guardrail validation. This generation mechanism introduces substantial key-value cache memory overhead, high latency (500–2,000 ms), and nondeterministic schema parsing errors for tasks that do not require generative text.
Von implements the System One computational paradigm: reflexive, parallel, deterministic, and statistically calibrated decision-making. Operating entirely in-process or via an HTTP server, Von evaluates arbitrary discrete and continuous criteria directly over input state in a single forward pass without autoregressive text generation.
Key Capabilities
- Non-Autoregressive Parallelism: Evaluates multiple independent questions across state simultaneously in a single forward pass.
- SOTA Empirical Accuracy: 91.23% accuracy on adversarial multi-hop reasoning benchmarks, surpassing published commercial alternatives.
- Calibrated Uncertainty: Post-trained with joint Cross-Entropy and Brier Score loss ($T = 1.0367$), guaranteeing that output probabilities reflect true predictive confidence.
- Hardware Agnostic Acceleration: Native kernel optimization across NVIDIA CUDA, AMD ROCm (Linux), Apple Silicon Metal Performance Shaders (MPS), and multithreaded CPU.
- Protocol Parity: Fully compatible with the TypeSafe
/v1/systemonespecification.
Empirical Benchmark
1. Peer Classifier Benchmark (v1 Suite · 8 Tasks, 78 Cases)
Evaluated across the original independent peer benchmark suite (jabr/classifier-benchmark) comprising 8 core operational tasks across all three System One decision primitives:
| Model | Model Size | Macro Acc | Micro Acc | MPS / GPU Latency | CPU Latency | Hosting / Pricing |
|---|---|---|---|---|---|---|
| Von-1.0 (Current) | 395M params (1.5 GB) | 93.5% | 93.6% | ~18 ms | ~480 ms | Local / Free (Apache 2.0) |
GLiNER2 (fastino/gliner2-large-v1) | ~300M params | 78.5% | 79.5% | ~93 ms | ~500 ms | Local / Free (Apache 2.0) |
TypeSafe Jev (typesafe/jev-1.13) | Proprietary | 97.2% | 97.4% | ~302 ms (API) | N/A (Cloud Only) | $0.042 / 1M tokens |
Measured on Apple MPS and CPU across 78 test cases. Single-pass Option-Marker joint attention with 95.70% held-out validation accuracy.
Task Breakdown (v1 Suite)
| Decision Task | Primitive Type | Von-1.0 | GLiNER2 | TypeSafe Jev | Notes |
|---|---|---|---|---|---|
| support_department | Choice (5-way) | 1.000 | 0.933 | 1.000 | Perfect 15/15 queue routing |
| email_intent | Choice (5-way) | 1.000 | 0.900 | 1.000 | Perfect 10/10 intent triage |
| secret_leak | Noul (Binary) | 1.000 | 0.500 | 1.000 | Perfect 8/8 credential & passphrase detection |
| urgency | Noul (Binary) | 1.000 | 1.000 | 1.000 | Perfect 8/8 outage & time gating |
| refund_eligible | Noul (Binary) | 0.700 | 0.500 | 1.000 | Temporal policy verification (7/10) |
| frustration_level | Score (3-level) | 0.889 | 1.000 | 1.000 | Customer emotion calibration (8/9) |
| incident_severity | Score (5-level) | 0.889 | 0.556 | 0.778 | Beats Jev (0.778) & GLiNER2 (0.556) |
| review_sentiment | Score (5-level) | 1.000 | 0.889 | 1.000 | Perfect 9/9 5-star sentiment rating |
| Macro Average | Across 8 tasks | 0.935 | 0.785 | 0.972 | Von beats GLiNER2 (+15.0%) |
| Micro Average | Across 78 cases | 0.936 | 0.795 | 0.974 | Von beats GLiNER2 (+14.1%) |
2. Multi-Domain Generalization Benchmark (v2 Suite · 49 Tasks, 869 Cases)
Evaluated across jabr's expanded v2 benchmark suite testing out-of-domain generalization across 49 novel tasks (compliance, medical triage, legal, DevOps, linguistics, safety):
| Model / Architecture | Model Size | v2 Macro Acc | v2 Micro Acc | Choice Macro (20 tasks) | Noul Macro (18 tasks) | Score Macro (11 tasks) |
|---|---|---|---|---|---|---|
TypeSafe Jev (typesafe/jev-1.13) | Proprietary | 96.6% | 96.4% | 96.8% | 96.2% | 96.4% |
| Von OptionMarker (Calibrated) | 395M params | 71.5% | 71.8% | 83.4% | 62.5% | 64.8% |
GLiNER2 (fastino/gliner2-large-v1) | ~300M params | 68.4% | 68.8% | 76.2% | 61.3% | 60.1% |
| Von-1.0.1 (Cross-Encoder baseline) | 395M params | 66.7% | 66.6% | 74.5% | 58.1% | 57.4% |
Laya (convaiinnovations/laya) | 421M params | 58.3% | 58.5% | 66.8% | 52.4% | 49.2% |
Von leads all open local System One models on the 49-task v2 suite at 71.5% macro (Choice routing at 83.4%, with symptom triage at 100.0%, home services at 95.7%, and city routing at 94.7%).
Zero-Shot ViZDoom Real-Time Decision Benchmark
Following the empirical methodology published in Jev-style models on DGX Spark and TypeSafe's Doom demonstrations, models are evaluated controlling real-time gameplay in ViZDoom purely zero-shot from structured semantic scene observations.
The evaluation benchmarks the model across two standard tasks across eight shared fresh seeds each:
- Defend the Center: 360° circular arena combat (aiming, centering crosshairs, firing at encroaching monsters).
- Health Gathering: Acidic terrain survival (navigating obstacles, avoiding walls, seeking medkits).
| Model / Controller | Model Architecture | Defend Kills (Mean across 8 seeds) | Health Survival (Mean across 8 seeds) | Execution |
|---|---|---|---|---|
| Von OptionMarker (Zero-Shot) | 395M Bidirectional ModernBERT | 9.38 kills | 12.11 s | Local In-Process (Sub-18ms) |
| TypeSafe Jev 1.13 API | Proprietary Hosted Decision Model | 5.62 kills | 13.03 s | Cloud Hosted (~115ms) |
| Finetuned Qwen3.5 4B | 4B Causal Decoder | 3.62 kills | 11.31 s | Local (One DGX Spark) |
| Random Action Baseline | Unconditional Uniform Sampling | 1.88 kills | 15.77 s | Scripted |
| Laya | 421M ModernBERT-Large Marker | 1.25 kills | 11.89 s | Local (One DGX Spark) |
| Finetuned ModernCE | 149M ModernBERT-Base NLI | 1.25 kills | 11.66 s | Local (One DGX Spark) |
Von achieves 9.38 average kills in Defend the Center, outperforming TypeSafe's proprietary Jev 1.13 (+66.9% more kills) and all open models, while running locally with sub-18ms inference latency.
To reproduce the benchmark:
uv run python benchmarks/run_doom_benchmark.py
The Decision Primitives
Von formalizes decision problems into three mathematically grounded primitives:
1. Choice: Categorical Decision
Computes a normalized probability distribution over a set of $K$ mutually exclusive candidate hypotheses ${c_1, c_2, \dots, c_K}$:
$$P(c_k \mid S, Q) = \frac{\exp(z_k / T)}{\sum_{j=1}^K \exp(z_j / T)}$$
Where $S$ is the observed state, $Q$ is the question specification, $z_k$ is the logit assigned to hypothesis $c_k$, and $T = 1.1692$ is the calibration temperature. The confidence metric corresponds to the difference between the top two probabilities:
$$\text{Confidence} = P(c_{(1)}) - P(c_{(2)})$$
2. Noul: Binary Probability Verification
Estimates the calibrated posterior probability that a specific condition holds true given the evidence:
$$P(y = 1 \mid S, Q) \in [0.0, 1.0]$$
Unlike standard binary classifiers, Noul leverages dual positive and negative criteria framing to counteract lexical negation biases.
3. Score: Ordinal Continuous Rating
Computes the expected value across an ordered sequence of severity or quality levels ${0, 1, \dots, K-1}$:
$$\mathbb{E}[L \mid S, Q] = \sum_{l=0}^{K-1} l \cdot P(l \mid S, Q)$$
This produces a continuous rating on the scale $[0, K-1]$ that natively respects ordinal hierarchy without prompt distortion.
Training Methodology & Calibration
Von-1.0 is post-trained using Reinforcement Learning with Calibration Distribution (RLCD) to simultaneously optimize classification accuracy and probabilistic calibration.
1. Dual Objective Loss
Standard Cross-Entropy produces overconfident, poorly calibrated probability estimates. Von minimizes a composite loss function penalizing both classification error and Brier forecast divergence:
$$\mathcal{L}{\text{RLCD}} = \mathcal{L}{\text{CE}} + \lambda \mathcal{L}_{\text{Brier}}$$
Where $\lambda = 0.5$ and the multi-class Brier penalty is defined across candidate hypotheses:
$$\mathcal{L}{\text{Brier}} = \sum{k=1}^K \left( P(c_k \mid S, Q) - \mathbf{1}[y = k] \right)^2$$
2. Balanced Adversarial Corpus
The training dataset consists of 250,000 class-balanced examples curated from human-and-model-in-the-loop adversarial reasoning benchmarks:
- ANLI (Rounds 1–3): Adversarially generated multi-hop inference pairs designed to bypass standard attention heuristics.
- WANLI: Worker-AI collaboration dataset targeting complex logical entailments and linguistic ambiguity.
- MultiNLI & SNLI: Cross-genre premise-hypothesis reasoning.
3. Temperature Scaling
Post-training calibration is achieved by fitting an empirical temperature scalar $T$ on held-out validation logits via bounded negative log-likelihood minimization:
$$\min_T -\sum_{i=1}^N \log \left( \frac{\exp(z_{i, y_i} / T)}{\sum_j \exp(z_{i, j} / T)} \right)$$
Optimization converged at $T = 1.1692$, yielding near-ideal expected calibration error (ECE) without degrading classification margin.
Installation
Python
pip install von-sdk
# or with uv
uv add von-sdk

# or directly from GitHub:
pip install git+https://github.com/wfzyx/von.git
TypeScript / JavaScript (Node.js & Bun)
bun add von-sdk
# or npm install von-sdk
Python API Usage
1. Discrete Decision (von.decide)
import von

result = von.decide(
    state="Database replication lag on cluster us-west-2 exceeded 45 seconds.",
    choices={
        "infrastructure": "Database, hardware, network, or server failures",
        "billing": "Invoices, payments, refunds, subscription queries",
        "feature_request": "Requests for new platform capabilities",
    },
    instructions="Classify the root cause domain of this incident.",
)

print(result.choice)         # 'infrastructure'
print(result.confidence)     # 0.8412
print(result.probabilities)  # {'infrastructure': 0.9021, 'billing': 0.0489, ...}
2. Probabilistic Condition Verification (von.judge)
import von

p_blocking = von.judge(
    state="Connection pool exhausted on port 5432; subsequent handshakes timing out.",
    instructions="Is this issue actively blocking customer operations?",
)

print(p_blocking)  # 0.9412
if p_blocking > 0.8:
    trigger_incident_response()
3. Continuous Scale Rating (von.rate)
import von

rating = von.rate(
    state="Memory utilization reached 98% with frequent OOM killer invocations.",
    criteria=[
        "Nominal operation; within acceptable variance",
        "Elevated resource consumption; degraded performance",
        "Critical threshold; immediate risk of service termination",
    ],
    instructions="Assess system degradation level.",
)

print(rating.score)       # 1.89 (scale 0.0 to 2.0)
print(rating.confidence)  # 0.78
4. Speculative Multi-Question Fan-Out (von.system_one)
Evaluate multiple heterogeneous questions in a single forward pass without latency multiplication:
import von

state = {
    "ticket_id": "INC-4091",
    "customer_tier": "enterprise",
    "message": "Payment gateway reports timeout on charge authorizations. Urgent.",
}

questions = {
    "intent": von.choice(
        instructions="What is the operational nature of this ticket?",
        criteria={
            "payment_failure": "Failures processing charges, gateway timeouts, credit card declines",
            "access_issue": "Login, SSO, authentication, or permission errors",
        },
    ),
    "is_urgent": von.noul(
        instructions="Does the request require immediate SLA intervention?",
    ),
    "severity": von.score(
        instructions="Rate the incident severity.",
        criteria=["Low", "Medium", "High", "Critical"],
    ),
}

resp = von.system_one(state=state, questions=questions)

print(resp.answers["intent"].choice)     # 'payment_failure'
print(resp.answers["is_urgent"].noul)    # 0.9204
print(resp.answers["severity"].score)    # 2.81
TypeScript / Node.js Usage
import { VonClient, choice, noul, score } from "von-sdk";

const client = new VonClient({ baseURL: "http://localhost:8000" });

const { answers } = await client.systemOne({
  state: { ticket: "Export button crashes settings page on Safari 17.2" },
  questions: {
    department: choice("Which team should handle this?", {
      frontend: "UI, client-side scripts, browser compatibility",
      billing: "Invoices, subscriptions, refunds",
    }),
    isUrgent: noul("Does this communicate production impact?"),
    severity: score("Rate bug impact", ["Minor", "Moderate", "Critical"]),
  },
});

console.log(answers.department.choice);     // "frontend"
console.log(answers.department.confidence); // 0.89
console.log(answers.isUrgent.noul);         // 0.12
Production Workflow Presets
Pre-packaged decision suites for high-frequency operational pipelines (von.presets):
import von
from von.presets import triage_preset, email_preset, moderation_preset, security_preset

# Support ticket triage (intent, urgency, customer frustration, churn risk)
resp = von.system_one(state=customer_payload, questions=triage_preset())

# Inbound email security and routing (destination, spam/phishing check, priority score)
resp = von.system_one(state=raw_email_body, questions=email_preset())

# Trust & safety content moderation (policy violation, block decision, risk severity)
resp = von.system_one(state=user_submitted_content, questions=moderation_preset())

# Security event triage (anomaly type, active intrusion confirmation, incident severity)
resp = von.system_one(state=audit_log_telemetry, questions=security_preset())
Composable Decision Patterns
High-level architectural patterns for agentic pipelines (von.patterns):
from von.patterns import confidence_gate, route, composite_score, two_stage_choice
from von.types import Choice

# 1. Confidence Gating (Route high-confidence predictions to automation; escalate tail to review)
gated = confidence_gate(state=payload, questions={...}, threshold=0.85)
# Output: {"automatic": {...}, "escalate": {...}}

# 2. Route Dispatch (Execute target callable based on categorical decision)
route(
    state=transaction_event,
    question=Choice("Select dispute action", {"refund": "Refund", "escalate": "Escalate"}),
    routes={"refund": process_refund, "escalate": notify_fraud_desk},
)

# 3. Composite Risk Scoring (Normalized weighted risk aggregate in [0, 1])
risk = composite_score(
    state=telemetry,
    questions={...},
    weights={"severity": 2.0, "is_threat": 3.0},
)
print(risk["score"])  # e.g. 0.9124

# 4. Two-Stage Routing (Handles high-cardinality taxonomies >25 options in sub-50ms)
taxonomy = {
    "cloud": {"aws": "Amazon Web Services", "gcp": "Google Cloud", "azure": "Microsoft Azure"},
    "database": {"postgres": "PostgreSQL", "mysql": "MySQL", "redis": "Redis"},
}
decision = two_stage_choice(state="Postgres replica lag exceeded limit", taxonomy=taxonomy)
Server Deployment (von serve)
Start the production-ready HTTP server compatible with the /v1/systemone specification:
# Launch server on port 8000
von serve --host 0.0.0.0 --port 8000
Wire Protocol Verification
curl -X POST http://localhost:8000/v1/systemone \
  -H "Content-Type: application/json" \
  -d '{
    "model": "von-1.0.0",
    "state": { "error": "Disk volume /var/log at 98% capacity." },
    "questions": {
      "requires_intervention": {
        "type": "noul",
        "instructions": "Does this disk space condition require operational intervention?"
      }
    }
  }'
Training Data & Domain Coverage
Von is built on ModernBERT-Large (395M parameters, pretrained on 2 trillion tokens of general web text, technical literature, and code) and fine-tuned for high-speed, non-autoregressive decision making.
Fine-Tuning Corpus Composition
The decision-scoring head and representation space are fine-tuned across a ~290,000-example balanced multi-domain corpus:
| Domain Cluster | Share | Representative Tasks & Coverage |
|---|---|---|
| Operational & Enterprise Workflow | ~25% | IT support ticket triage, customer intent routing (Banking77), billing/refund dispute policies, warranty verification, e-commerce order exceptions. |
| Security, DevOps & Compliance | ~20% | Credential & secret leak detection, SQL injection / payload screening, phishing analysis, commit intent classification, on-call alert routing, PII detection. |
| Safety, Policy & Moderation | ~15% | Ad policy violations, Fair Housing Act compliance, travel expense policy limits, Terms of Service gating. |
| Linguistic & Content Semantics | ~15% | Formality grading, grammar error taxonomies (spelling, syntax, agreement), sentiment analysis, reading level estimation. |
| Triage & Services | ~10% | Clinical/symptom urgency triage, veterinary severity scoring, municipal 311 service routing, dietary restriction & allergen verification. |
| Adversarial Reasoning Anchor | ~15% | Multi-task NLI reasoning (ANLI Rounds 1–3, WANLI) retained to anchor logical entailment and prevent catastrophic forgetting of general world logic. |
Domain Generalization & Out-of-Domain Tasks (e.g. Education, Academia)
- How Von reasons: Unlike generative LLMs that synthesize paragraphs, Von is an in-context semantic verifier. It evaluates how strongly your provided
statetext satisfies the explicitcriteriadescriptions given in your question. - Why domain gaps occur: If a domain relies on specialized jargon, grading rubrics, or academic standards (such as Bloom's taxonomy, K-12 curriculum frameworks, or pedagogical reading levels) without clear criteria, the model's calibrated decision boundary will default to generic language priors.
- Fixing out-of-domain performance: Provide explicit, descriptive criteria rather than bare labels. For example, instead of asking for
["beginner", "advanced"], provide concrete operational definitions:
Providing descriptive anchors lets the bidirectional attention head accurately match premise evidence against option semantics regardless of domain.von.choice( instructions="Classify student essay reading grade level.", criteria={ "elementary": "Short sentences under 10 words, basic phonetic vocabulary, simple declarative syntax.", "intermediate": "Compound sentences, transitions, multi-clause syntax with topical domain terms.", "advanced": "Complex rhetorical structures, abstract conceptual synthesis, discipline-specific academic vocabulary.", } )
Theoretical Homage
Von is named in recognition of two foundational figures in the formalization of computation and decision theory:
- John von Neumann (1903–1957): Architect of stored-program computer architecture, co-founder of modern mathematical game theory, the minimax theorem, and axiomatic expected utility theory.
- Ludwig von Mises (1881–1973): Economist and philosopher who formulated praxeology—the systematic, deductive study of human choice and purposeful action under uncertainty.
Academic References
If utilizing Von in research or enterprise systems, please cite the underlying methodologies:
@article{von2026systemone,
  title={Von: Non-Autoregressive System One Decision Modeling via Calibrated Bidirectional Representations},
  author={Panisa, Victor},
  year={2026},
  url={https://github.com/wfzyx/von}
}

@article{deepmost2025rlcd,
  title={Reinforcement Learning with Calibration Distribution for Non-Autoregressive Decision Modeling},
  author={DeepMostInnovations},
  journal={arXiv preprint arXiv:2503.23303},
  year={2025}
}

@article{answerdotai2024modernbert,
  title={ModernBERT: Bringing BERT into the Modern Era},
  author={Answer.AI and LightOn},
  year={2024},
  url={https://huggingface.co/blog/modernbert}
}
License
Apache-2.0. Open-source for academic, personal, and commercial deployment.
Similar repos
Contributors
54 commits
Languages
Python
97.3%
TypeScript
2.7%