Fast CUDA matrix multiplication from scratch
See the codeStep-by-step optimization of matrix multiplication, implemented in CUDA. For an explanation of each kernel, see siboehm.com/CUDA-MMM.
Running the kernels on a NVIDIA A6000 (Ampere):
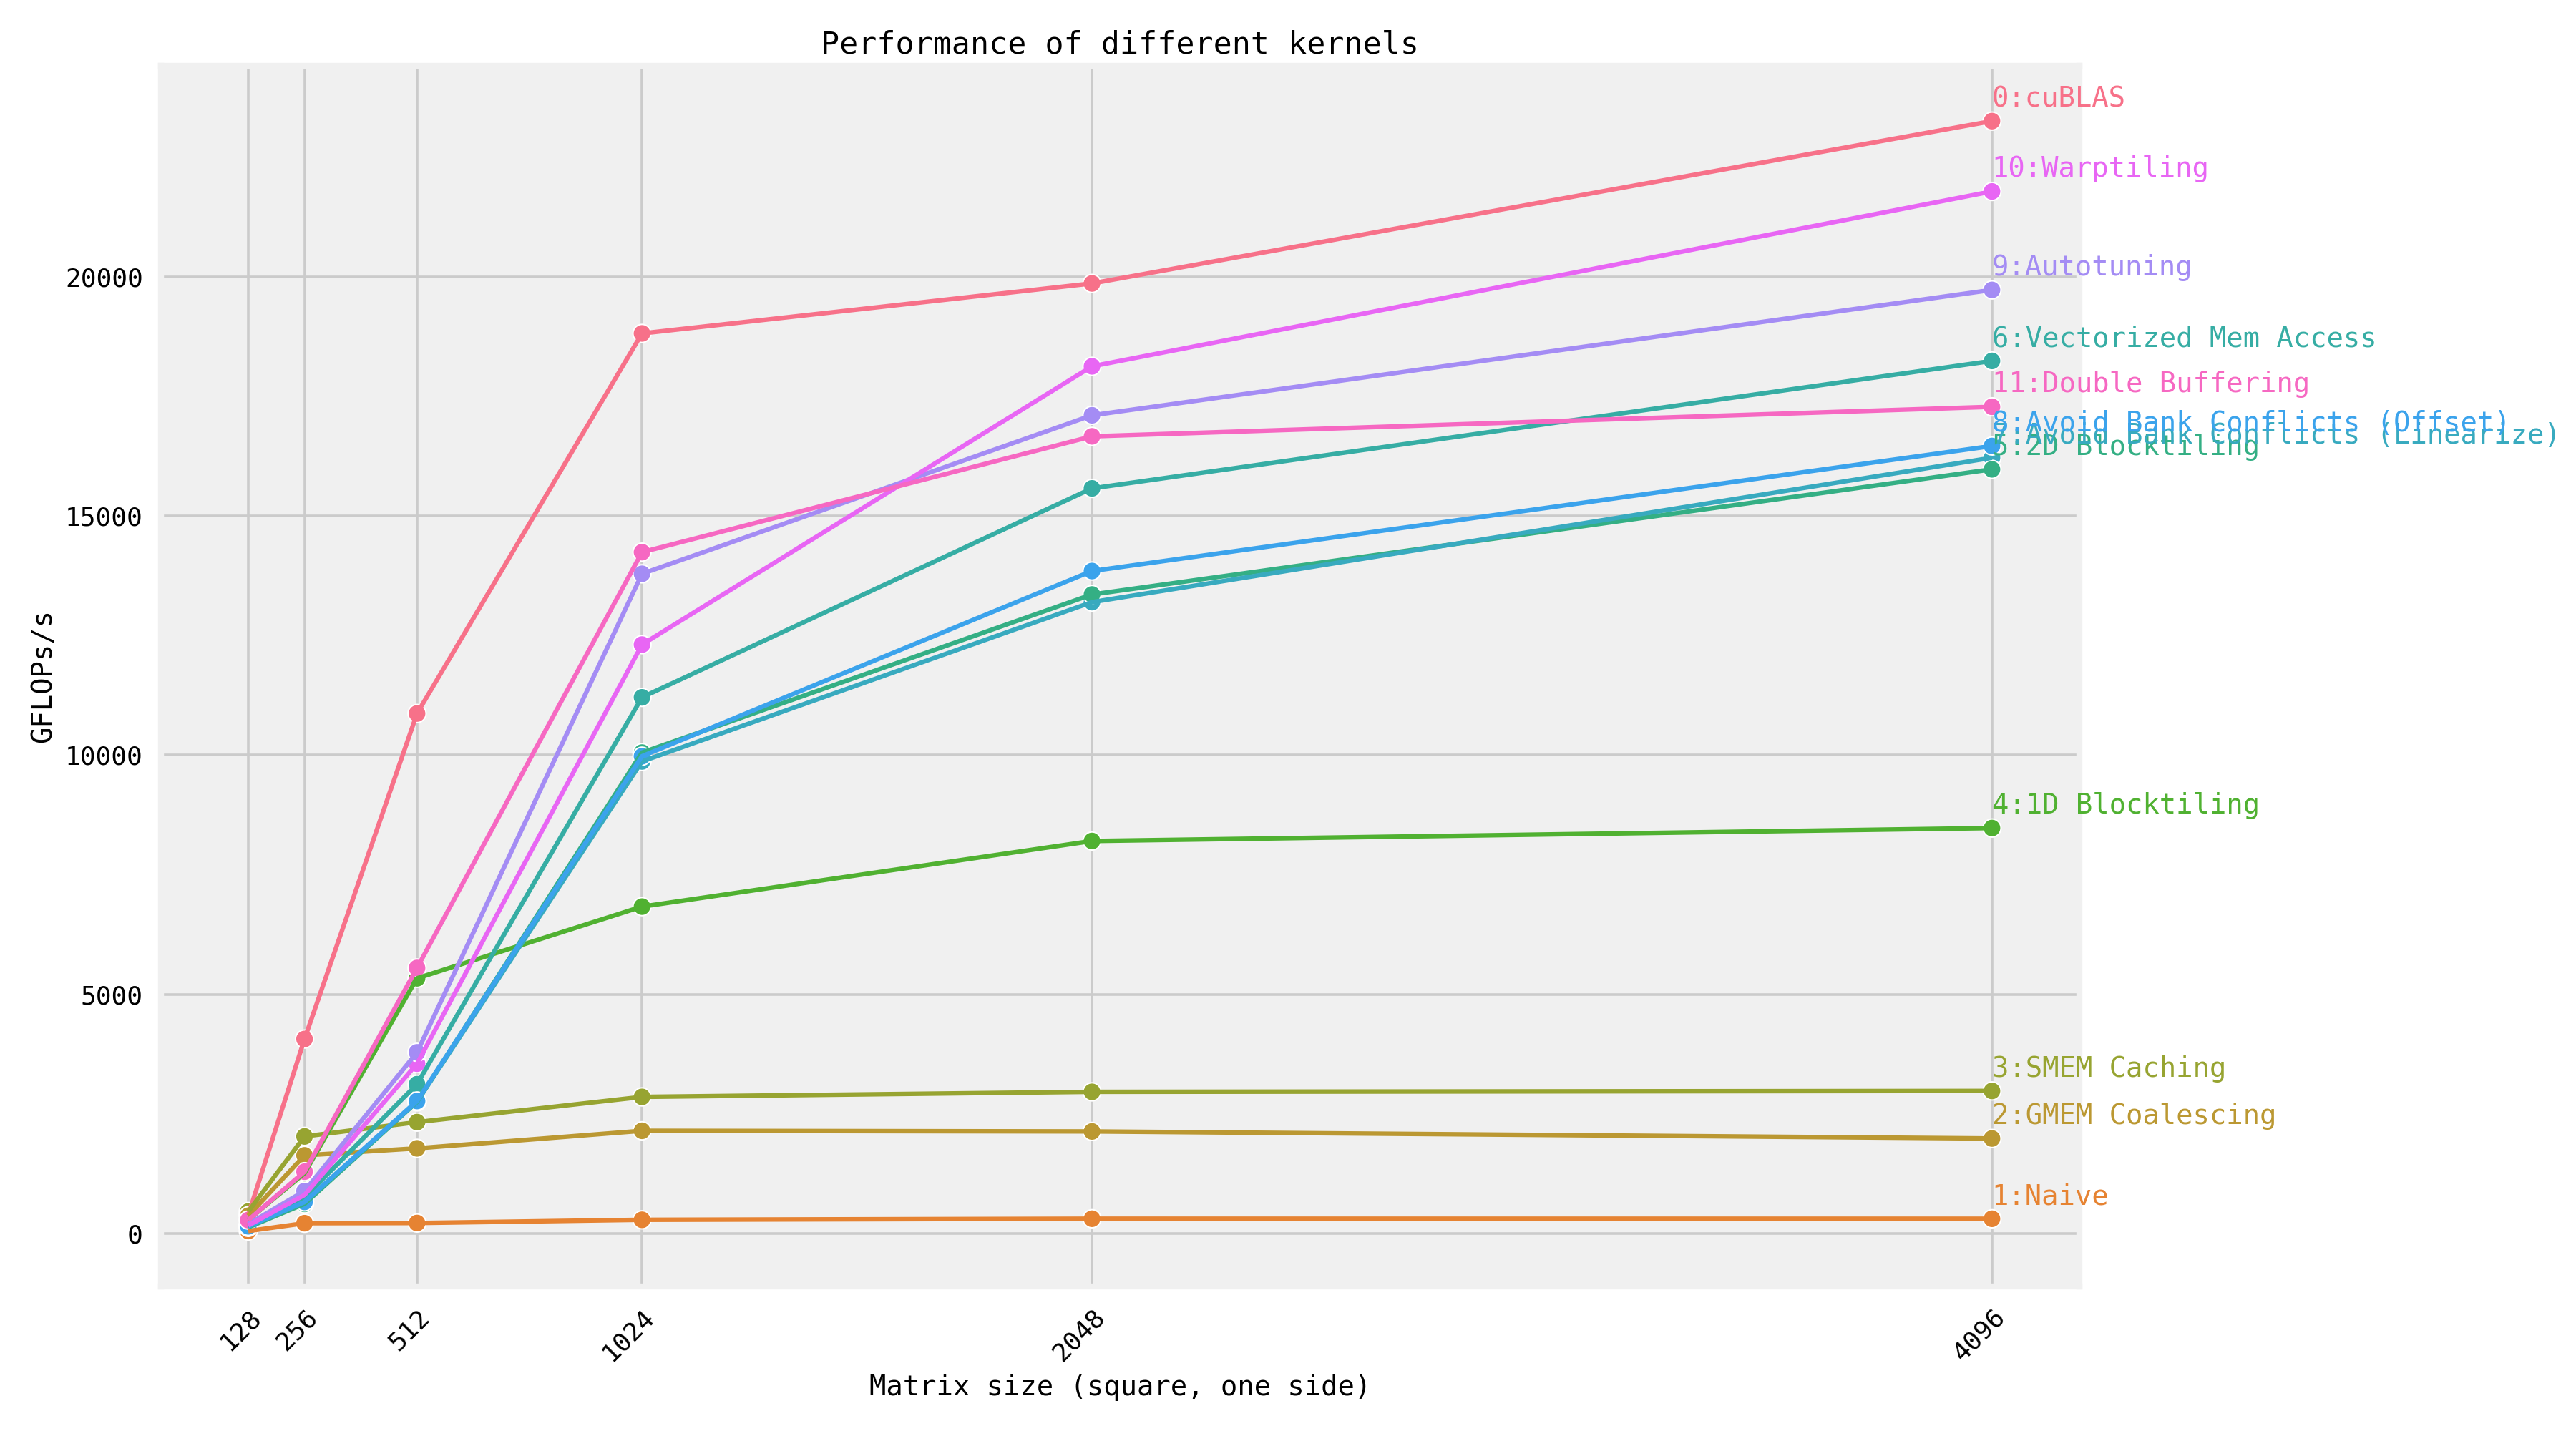
GFLOPs at matrix size 4096x4096:
| Kernel | GFLOPs/s | Performance relative to cuBLAS |
|---|---|---|
| 1: Naive | 309.0 | 1.3% |
| 2: GMEM Coalescing | 1986.5 | 8.5% |
| 3: SMEM Caching | 2980.3 | 12.8% |
| 4: 1D Blocktiling | 8474.7 | 36.5% |
| 5: 2D Blocktiling | 15971.7 | 68.7% |
| 7: Avoid Bank Conflicts (Linearize) | 16213.4 | 69.7% |
| 8: Avoid Bank Conflicts (Offset) | 16459.2 | 70.8% |
| 11: Double Buffering | 17278.3 | 74.3% |
| 6: Vectorized Mem Access | 18237.3 | 78.4% |
| 9: Autotuning | 19721.0 | 84.8% |
| 10: Warptiling | 21779.3 | 93.7% |
| 0: cuBLAS | 23249.6 | 100.0% |
CMakeLists.txt and change:
set(CUDA_COMPUTE_CAPABILITY 80)
mkdir build && cd build && cmake .. && cmake --build .DEVICE=<device_id> ./sgemm <kernel number>make profile KERNEL=<kernel number>Credit goes to wangzyon/NVIDIA_SGEMM_PRACTICE for the benchmarking setup.
(top 24 of 33)
244 followers · starred Sep 2026
941 followers · starred Dec 2023
3,249 followers · starred Apr 2023
4,915 followers · starred Mar 2023
Fast CUDA matrix multiplication from scratch
See the codeStep-by-step optimization of matrix multiplication, implemented in CUDA. For an explanation of each kernel, see siboehm.com/CUDA-MMM.
Running the kernels on a NVIDIA A6000 (Ampere):
GFLOPs at matrix size 4096x4096:
| Kernel | GFLOPs/s | Performance relative to cuBLAS |
|---|---|---|
| 1: Naive | 309.0 | 1.3% |
| 2: GMEM Coalescing | 1986.5 | 8.5% |
| 3: SMEM Caching | 2980.3 | 12.8% |
| 4: 1D Blocktiling | 8474.7 | 36.5% |
| 5: 2D Blocktiling | 15971.7 | 68.7% |
| 7: Avoid Bank Conflicts (Linearize) | 16213.4 | 69.7% |
| 8: Avoid Bank Conflicts (Offset) | 16459.2 | 70.8% |
| 11: Double Buffering | 17278.3 | 74.3% |
| 6: Vectorized Mem Access | 18237.3 | 78.4% |
| 9: Autotuning | 19721.0 | 84.8% |
| 10: Warptiling | 21779.3 | 93.7% |
| 0: cuBLAS | 23249.6 | 100.0% |
CMakeLists.txt and change:
set(CUDA_COMPUTE_CAPABILITY 80)
mkdir build && cd build && cmake .. && cmake --build .DEVICE=<device_id> ./sgemm <kernel number>make profile KERNEL=<kernel number>Credit goes to wangzyon/NVIDIA_SGEMM_PRACTICE for the benchmarking setup.
(top 24 of 33)
244 followers · starred Sep 2026
941 followers · starred Dec 2023
3,249 followers · starred Apr 2023
4,915 followers · starred Mar 2023



