This is an example repo for CUDA MatMul implementation. The aim of this repo is to provide some insights in high-performance kernel design for CUDA beginners. Currently, I only provide some implementation examples in
examples/matmul/this. Contributions for more kernels and other MatMul implementations are highly welcomed.
There is a detailed explanation about the different versions of MatMul kernels in examples/matmul/this.
examples:
matmul: The MatMul implementations
this-sm90: The Hopper version Matmulthis-sm80: The MatMul implemented by this repocublas: Call CuBLAS for performance testcutlass: Call CUTLASS for performance testmlir-gen: The cuda code generated by MLIRtriton: Call Triton for performance testtvm: Call Relay+CUTLASS/CuBLAS or TensorIR for performance testatom: The usage of single intrinsic/instructions
reduction: Some reduction kernels for epilogue
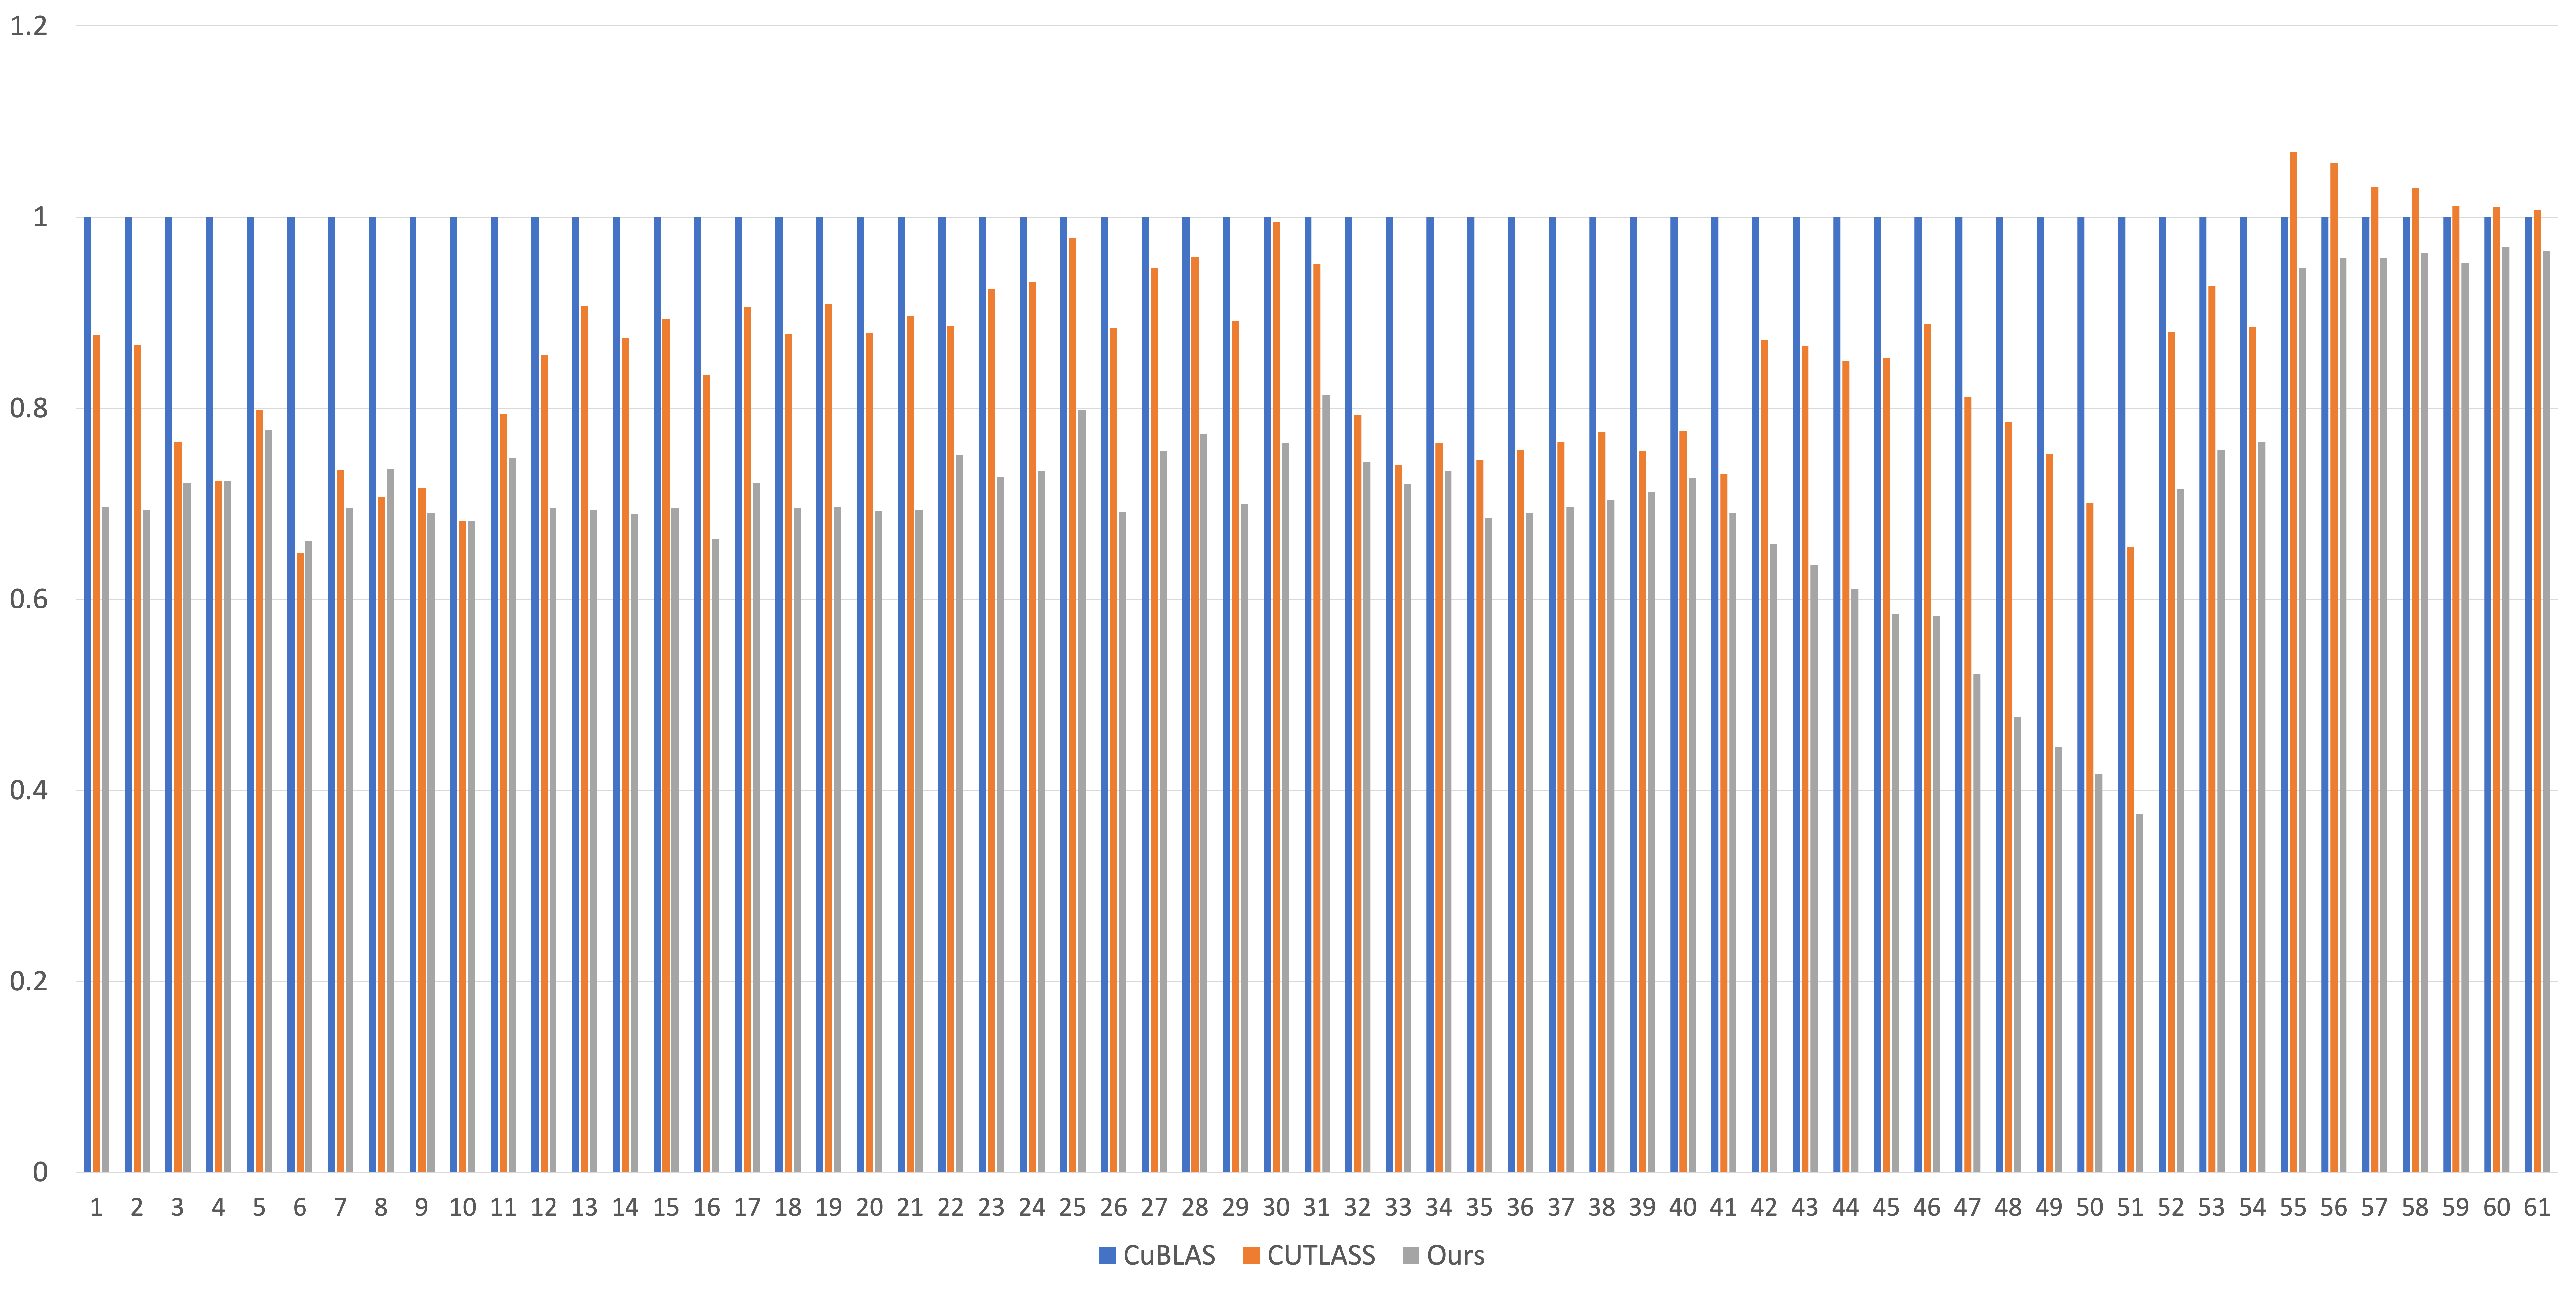 The current version only achieves on average 70% performance of CuBLAS. I am still working on improving the performance.
<img src=static/this.png alt="A100-GEMM-perf" width="2000" height="600"> The overall performance comparison among Relay, CuBLAS, CUTLASS, TensorIR, Triton, and our implementations. The y-axis is speedup to Relay+CUTLASS.
Overall, the geometric mean speedup to Relay+CUTLASS is 1.73x, to TensorIR (1000 tuning trials using MetaSchedule per case) is 1.22x, to CuBLAS is 1.00x, to CUTLASS is 0.999x, to Triton is 1.07x. The 61 shapes are:
| No. | M | N | K |
|---|---|---|---|
| 1 | 5376 | 5376 | 2048 |
| 2 | 5376-128 | 5376 | 2048 |
| 3 | 5376-2*128 | 5376 | 2048 |
| ... | ... | ... | ... |
| 11 | 5376-10*128 | 5376 | 2048 |
| 12 | 5376+128 | 5376 | 2048 |
| 13 | 5376+2*128 | 5376 | 2048 |
| ... | ... | ... | ... |
| 21 | 5376+10*128 | 5376 | 2048 |
| 22 | 5376 | 5376-128 | 2048 |
| 23 | 5376 | 5376-2*128 | 2048 |
| ... | ... | ... | ... |
| 31 | 5376 | 5376-10*128 | 2048 |
| 32 | 5376 | 5376+128 | 2048 |
| 33 | 5376 | 5376+2*128 | 2048 |
| ... | ... | ... | ... |
| 41 | 5376 | 5376+10*128 | 2048 |
| 42 | 5376 | 5376 | 2048-128 |
| 43 | 5376 | 5376 | 2048-2*128 |
| ... | ... | ... | ... |
| 51 | 5376 | 5376 | 2048-10*128 |
| 52 | 5376 | 5376 | 2048+128 |
| 53 | 5376 | 5376 | 2048+2*128 |
| ... | ... | ... | ... |
| 61 | 5376 | 5376 | 2048+10*128 |
I also use MLIR to generate MatMul kernels. The generated ones are in examples/matmul/mlir-gen. The performance to handwritten ones (examples/matmul/this) is shown as belows. As MLIR generated ones only implement part of the optimizations used by handwritten ones, we call the MLIR generated ones partial and the handwritten ones full.
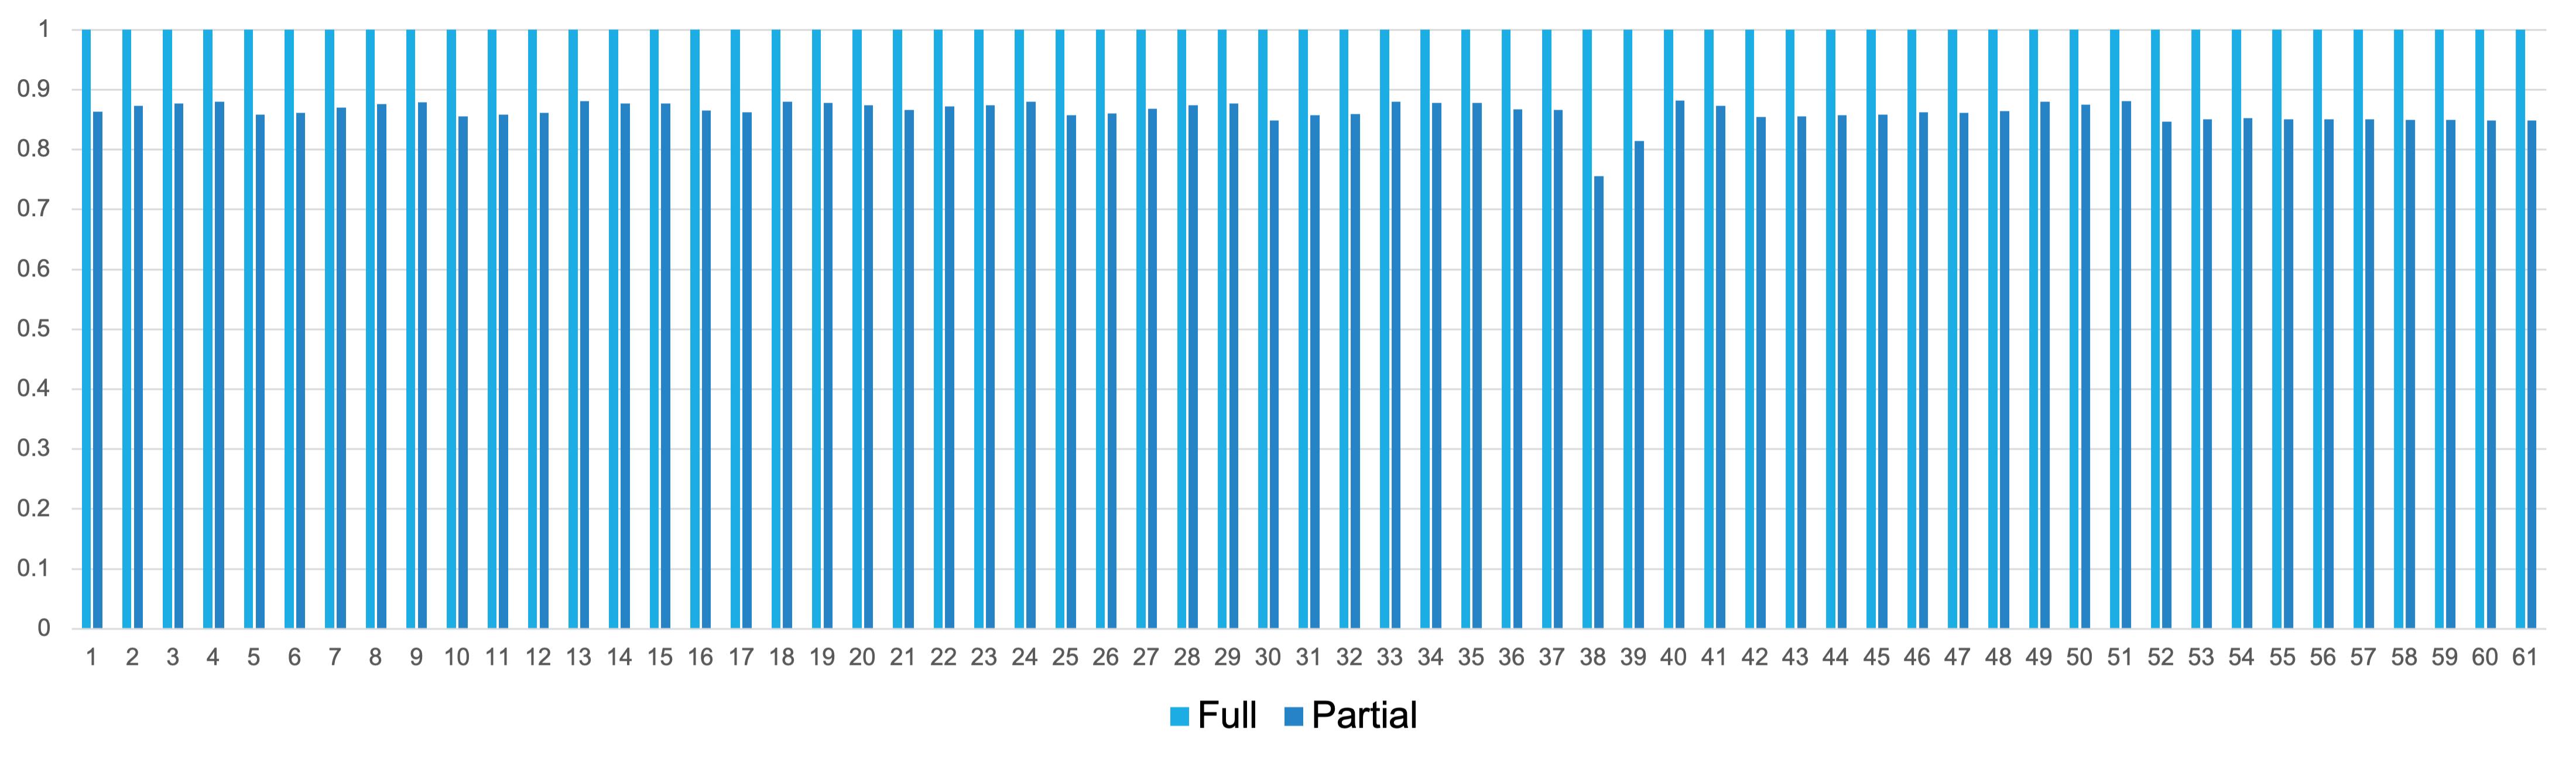 Overall, MLIR generated versions achieve 86% the performance of handwritten kernels.
I plan to implement kernels for other operators such as softmax in future.
There is a plan to use the CuTe interface of CUTLASS to implement high-performance kernels.
2,858 followers · starred Dec 2023
454 followers · starred Nov 2023
1,252 followers · starred Sep 2023
1,933 followers · starred Aug 2023
This is an example repo for CUDA MatMul implementation. The aim of this repo is to provide some insights in high-performance kernel design for CUDA beginners. Currently, I only provide some implementation examples in
examples/matmul/this. Contributions for more kernels and other MatMul implementations are highly welcomed.
There is a detailed explanation about the different versions of MatMul kernels in examples/matmul/this.
examples:
matmul: The MatMul implementations
this-sm90: The Hopper version Matmulthis-sm80: The MatMul implemented by this repocublas: Call CuBLAS for performance testcutlass: Call CUTLASS for performance testmlir-gen: The cuda code generated by MLIRtriton: Call Triton for performance testtvm: Call Relay+CUTLASS/CuBLAS or TensorIR for performance testatom: The usage of single intrinsic/instructions
reduction: Some reduction kernels for epilogue
The current version only achieves on average 70% performance of CuBLAS. I am still working on improving the performance.
<img src=static/this.png alt="A100-GEMM-perf" width="2000" height="600"> The overall performance comparison among Relay, CuBLAS, CUTLASS, TensorIR, Triton, and our implementations. The y-axis is speedup to Relay+CUTLASS.
Overall, the geometric mean speedup to Relay+CUTLASS is 1.73x, to TensorIR (1000 tuning trials using MetaSchedule per case) is 1.22x, to CuBLAS is 1.00x, to CUTLASS is 0.999x, to Triton is 1.07x. The 61 shapes are:
| No. | M | N | K |
|---|---|---|---|
| 1 | 5376 | 5376 | 2048 |
| 2 | 5376-128 | 5376 | 2048 |
| 3 | 5376-2*128 | 5376 | 2048 |
| ... | ... | ... | ... |
| 11 | 5376-10*128 | 5376 | 2048 |
| 12 | 5376+128 | 5376 | 2048 |
| 13 | 5376+2*128 | 5376 | 2048 |
| ... | ... | ... | ... |
| 21 | 5376+10*128 | 5376 | 2048 |
| 22 | 5376 | 5376-128 | 2048 |
| 23 | 5376 | 5376-2*128 | 2048 |
| ... | ... | ... | ... |
| 31 | 5376 | 5376-10*128 | 2048 |
| 32 | 5376 | 5376+128 | 2048 |
| 33 | 5376 | 5376+2*128 | 2048 |
| ... | ... | ... | ... |
| 41 | 5376 | 5376+10*128 | 2048 |
| 42 | 5376 | 5376 | 2048-128 |
| 43 | 5376 | 5376 | 2048-2*128 |
| ... | ... | ... | ... |
| 51 | 5376 | 5376 | 2048-10*128 |
| 52 | 5376 | 5376 | 2048+128 |
| 53 | 5376 | 5376 | 2048+2*128 |
| ... | ... | ... | ... |
| 61 | 5376 | 5376 | 2048+10*128 |
I also use MLIR to generate MatMul kernels. The generated ones are in examples/matmul/mlir-gen. The performance to handwritten ones (examples/matmul/this) is shown as belows. As MLIR generated ones only implement part of the optimizations used by handwritten ones, we call the MLIR generated ones partial and the handwritten ones full.
Overall, MLIR generated versions achieve 86% the performance of handwritten kernels.
I plan to implement kernels for other operators such as softmax in future.
There is a plan to use the CuTe interface of CUTLASS to implement high-performance kernels.
2,858 followers · starred Dec 2023
454 followers · starred Nov 2023
1,252 followers · starred Sep 2023
1,933 followers · starred Aug 2023



