
A curated list of reinforcement learning with verifiable rewards (continually updated)
328
10 commits
updated Jun 1, 2026
README
Awesome RLVR — Reinforcement Learning with Verifiable Rewards


A curated collection of surveys, tutorials, codebases and papers on
Reinforcement Learning with Verifiable Rewards (RLVR)—
a rapidly emerging paradigm that aligns both LLMs and other agents through
objective, externally verifiable signals.
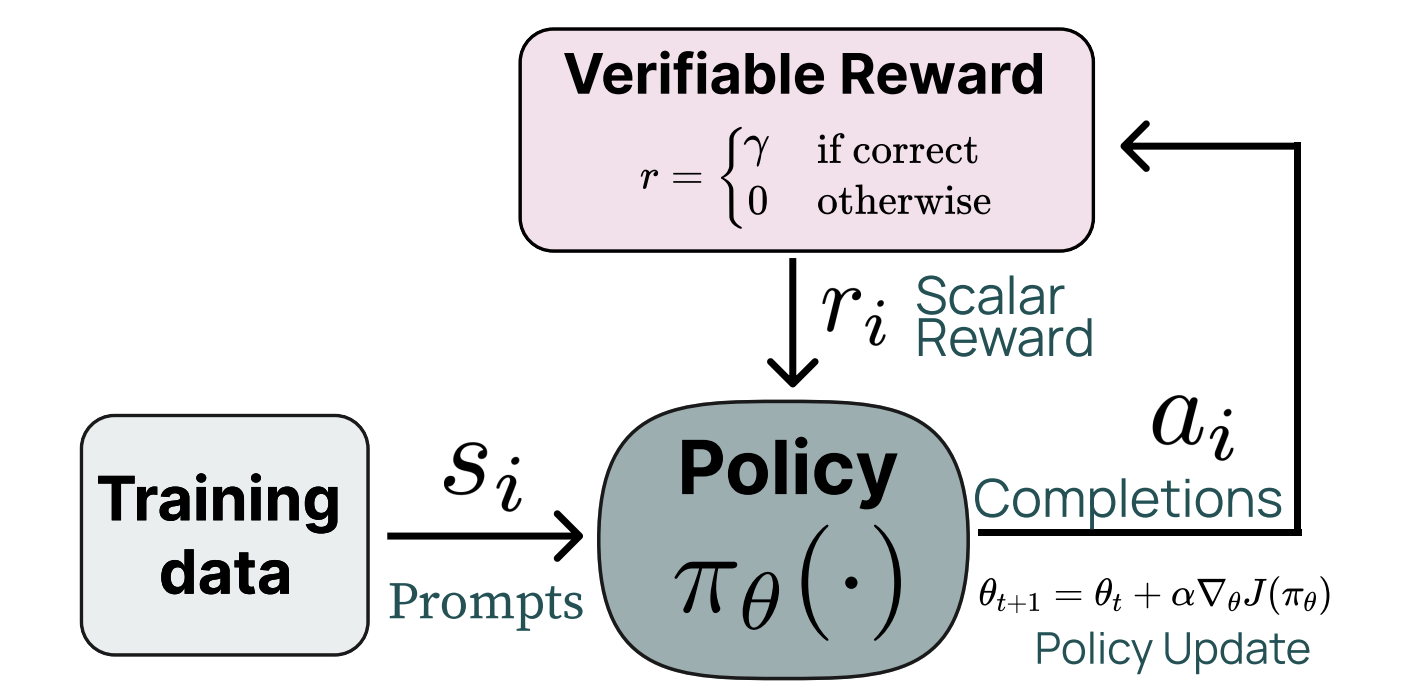
An overview of how Reinforcement Learning with Verifiable Rewards (RLVR) works.
(Figure taken from
“Tülu 3: Pushing Frontiers in
Open Language Model Post-Training”)
Why RLVR?
RLVR couples reinforcement learning with objective, externally verifiable signals, yielding a training paradigm that is simultaneously powerful and trustworthy:
- Ground-truth rewards – unit tests, formal proofs, or fact-checkers provide binary, tamper-proof feedback.
- Intrinsic safety & auditability – every reward can be traced back to a transparent verifier run, simplifying debugging and compliance.
- Strong generalization – models trained on verifiable objectives tend to extrapolate to unseen tasks with minimal extra data.
- Emergent “aha-moments” – sparse, high-precision rewards encourage systematic exploration that often yields sudden surges in capability when the correct strategy is discovered.
- Self-bootstrapping improvement – the agent can iteratively refine or even generate new verifiers, compounding its own learning signal.
- Domain-agnostic applicability – the same recipe works for code generation, theorem proving, robotics, games, and more.
How does it work?
- Sampling. We draw one or more candidate completions ( {a}{1..k} ) from a policy model ( \pi\theta ) given a prompt ( s ).
- Verification. A deterministic function ( r(s,{a}) ) checks each completion for correctness.
- Rewarding.
• If a completion is verifiably correct, it receives a reward ( r = \gamma ).
• Otherwise the reward is ( r = 0 ). - Policy update. Using the rewards, we update the policy parameters via RL (e.g., PPO).
- (Optional) Verifier refinement. The verifier itself can be trained, hardened, or expanded to cover new edge cases.
Through repeated iterations of this loop, the policy learns to maximise the externally verifiable reward while maintaining a clear audit trail for every decision it makes.
Pull requests are welcome 🎉 — see Contributing for guidelines.
[2026-05-06] New! Added 135 papers from ICLR 2026 and ICML 2026 🎉
[2025-07-03] Initial public release of Awesome-RLVR
Table of Contents
format:
- [title](paper link) (presentation type)
  - main authors or main affiliations
  - Key: key problems and insights
  - Data Domain: experiment environments
Surveys & Tutorials
Click to expand / collapse
-
Inference-Time Techniques for LLM Reasoning (Berkeley Lecture 2025)
- DeepMind & UC Berkeley (Xinyun Chen)
- Key: decoding-time search, self-consistency, verifier pipelines
- Data Domain: code/math reasoning benchmarks
-
Learning to Self-Improve & Reason with LLMs (Berkeley Talk 2025)
- Meta AI & NYU (Jason Weston)
- Key: continual self-improvement loops, alignment interplay
- Data Domain: open-ended dialogue & retrieval tasks
-
LLM Reasoning: Key Ideas and Limitations (Tutorial Slides 2024)
- DeepMind (Denny Zhou)
- Key: theoretical foundations & failure modes of reasoning
- Data Domain: slide examples, classroom demos
-
Can LLMs Reason & Plan? (ICML Tutorial 2024)
- Arizona State University (Subbarao Kambhampati)
- Key: planning-oriented reasoning, agent integration
- Data Domain: symbolic + LLM planning tasks
-
Towards Reasoning in Large Language Models (ACL Tutorial 2023)
- UIUC (Jie Huang)
- Key: survey of reasoning techniques & benchmarks
- Data Domain: academic tutorial datasets
-
From System 1 to System 2: A Survey of Reasoning Large Language Models (arXiv 2025)
- CAS & MBZUAI
- Key: cognitive-style taxonomy (fast vs. deliberative reasoning)
- Data Domain: logical, mathematical, commonsense datasets
-
Harnessing the Reasoning Economy: A Survey of Efficient Reasoning for Large Language Models (arXiv 2025)
- Chinese Univ. of Hong Kong
- Key: efficient reasoning, test-time-compute scaling
- Data Domain: math & code reasoning benchmarks
-
What, How, Where, and How Well? A Survey on Test-Time Scaling in Large Language Models (arXiv 2025)
- City University of Hong Kong
- Key: methods for scaling inference-time compute (CoT, search, self-consistency)
- Data Domain: diverse reasoning datasets
-
A Survey of Efficient Reasoning for Large Reasoning Models: Language, Multimodality, and Beyond (arXiv 2025)
- Shanghai AI Lab et al.
- Key: lifecycle-wide efficiency (pre-training → inference) for LRMs
- Data Domain: language + vision reasoning tasks
-
Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models (arXiv 2025)
- Rice University
- Key: “overthinking” phenomenon, length-control techniques
- Data Domain: GSM8K, MATH-500, AIME-24
-
A Visual Guide to Reasoning LLMs (Newsletter 2025)
- Maarten Grootendorst
- Key: illustrated test-time-compute concepts, DeepSeek-R1 case study
- Data Domain: graphical explanations & code demos
-
Understanding Reasoning LLMs – Methods and Strategies for Building and Refining Reasoning Models (Blog 2025)
- Sebastian Raschka
- Key: practical tutorial on data, architectures, evaluation
- Data Domain: Jupyter notebooks & open-source models
-
An Illusion of Progress? Assessing the Current State of Web Agents (arXiv 2025)
- Ohio State & UC Berkeley
- Key: empirical audit of LLM-based web agents, evaluation protocols
- Data Domain: autonomous web-navigation tasks
-
Agentic Large Language Models, A Survey (arXiv 2025)
- Leiden University
- Key: taxonomy of agentic LLM architectures & planning mechanisms
- Data Domain: multi-step reasoning / tool-use agents
-
A Comprehensive Survey of LLM Alignment Techniques: RLHF, RLAIF, PPO, DPO and More (arXiv 2024)
- Salesforce AI
- Key: reward modeling & preference-optimization pipelines
- Data Domain: alignment benchmarks, safety tasks
-
Self-Improvement of LLM Agents through Reinforcement Learning at Scale (MIT Scale-ML Talk 2024)
- MIT CSAIL & collaborators
- Key: large-scale RL for autonomous agent refinement
- Data Domain: simulated dialogue & tool-use agents
-
Reinforcement Learning from Verifiable Rewards (Book 2026)
- Kian Kyars
- Key: verifier design, outcome and process rewards, GRPO training signals, reward hacking, search/test-time verification, frontier RLVR, and agentic RLVR
- ExpEnv: math, code, proof, long-context QA, multimodal, and agentic verification examples
-
Reinforcement Learning from Verifiable Rewards (Blog 2025)
- Key: Uses binary, verifiable reward functions to inject precise, unbiased learning signals into RL pipelines for math, code, and other accuracy-critical tasks.
- Data Domain: Easily reproducible in Jupyter notebooks or any RL setup by plugging in auto-grading tools such as compilers, unit tests, or schema validators.
Codebases
Click to expand / collapse
| Project | Stars | Description |
|---|---|---|
| open-r1 |  | Fully open reproduction of the DeepSeek-R1 pipeline (SFT, distillation, GRPO, evaluation) |
| OpenRLHF |  | An Easy-to-use, Scalable and High-performance RLHF Framework based on Ray (PPO & GRPO & REINFORCE++ & vLLM & Ray & Dynamic Sampling & Async Agentic RL)* |
| verl |  | a flexible, efficient and production-ready RL training library for large language models |
| TinyZero |  | Minimal reproduction of DeepSeek R1-Zero |
| AReaL |  | Ant Reasoning Reinforcement Learning for LLMs |
| Open-Reasoner-Zero |  | one open source implementation of large-scale reasoning-oriented RL training focusing on scalability, simplicity and accessibility |
| ROLL |  | an Efficient and User-Friendly Scaling Library for Reinforcement Learning with Large Language Models |
| slime |  | an LLM post-training framework for RL scaling with high-performance training and flexible data generation |
| RAGEN |  | RAGEN (Reasoning AGENt, pronounced like "region") leverages reinforcement learning (RL) to train LLM reasoning agents in interactive, stochastic environments. |
| PRIME |  | PRIME (Process Reinforcement through IMplicit REwards), an open-source solution for online RL with process rewards |
| rllm |  | an open-source framework for post-training language agents via reinforcement learning |
| Nemo-Aligner |  | Scalable toolkit for efficient model alignment |
| Trinity-RFT |  | A unified RFT framework with plug-and-play modules (for algorithms, data pipelines, and synchronization) |
Papers
2026
ICML 2026
Click to expand / collapse
-
RuCL: Stratified Rubric-Based Curriculum Learning for Multimodal Large Language Model Reasoning
- Yukun Chen, Jiaming Li, Longze Chen, Ze Gong, Jingpeng Li, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MathVerse, MathVision, Geo3k, MMK12, We-Math
-
ResRL: Boosting LLM Reasoning via Negative Sample Projection Residual Reinforcement Learning
- Zihan Lin, Xiaohan Wang, Jie Cao, Jiajun Chai, Li Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, alignment
- Data Domain: Residual Reinforcement Learning, Calling
- Code: 1229095296/ResRL
-
- Zhengzhao Ma, Xueru Wen, Boxi Cao, Yaojie Lu, Hongyu Lin, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME, AMC, LiveCodeBench, HumanEval+
- Code: icip-cas/DCPO
-
See First, Reason Later: Mutual Information-Guided Reinforcement Learning for Vision-Language Models
- Junfeng Fang, Zonghan Wu, Yin Zhang, Jiaxuan Zhao, Zengxiang Li, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MathVerse, MathVision, MMMU
-
G$^2$RPO: Geometric GRPO; Escaping LLM's Reasoning Rut to Break Accuracy--Entropy Trade-off
- Ali Rad, Khashayar Filom, Darioush Keivan, Peyman Mohajerin Esfahani, Ehsan Kamalinejad
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, reasoning
- Data Domain: MATH, AIME
-
Rate or Fate? RLV$^{ arepsilon}$R: Reinforcement Learning with Verifiable Noisy Rewards
- Ali Rad, Khashayar Filom, Darioush Keivan, Peyman Mohajerin Esfahani, Ehsan Kamalinejad
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, grpo
- Data Domain: Python code tasks with synthetic noise
-
Anchored Policy Optimization: Mitigating Exploration Collapse via Support-Constrained Rectification
- Tianyi Wang, Long Li, Hongcan Guo, Yibiao Chen, Yixia Li, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, ppo
- Data Domain: MATH, AIME
-
Spurious Rewards: Rethinking Training Signals in RLVR
- Rulin Shao, Stella Li, Rui Xin, Scott Geng, Yiping Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH
-
- Johannes Ackermann, Michael Noukhovitch, Takashi Ishida, Masashi Sugiyama
- Key: verifiable reward, reinforcement learning, rlvr, language model, rlhf
- Data Domain: MATH
-
- Haechan Kim, Soohyun Ryu, Gyouk Chu, Doohyuk Jang, Eunho Yang
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Contextual Rollout Bandits for Reinforcement Learning with Verifiable Rewards
- Xiaodong Lu, Xiaohan Wang, Jiajun Chai, Guojun Yin, Wei Lin, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, ppo
- Data Domain: MATH, AIME
-
The Unlearnability Phenomenon in RLVR for Language Models
- Yulin Chen, He He, Chen Zhao
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Evaluating Parameter Efficient Methods for RLVR
- Qingyu Yin, Yulun Wu, Zhennan Shen, Sunbowen Lee, Zhilin Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, AIME
-
- Chuyi Tan, Peiwen Yuan, Xinglin Wang, Yiwei Li, Shaoxiong Feng, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Clipping Bottleneck: Stabilizing RLVR via Stochastic Recovery of Near-Boundary Signals
- Shuo Yang, Jinda Lu, Chiyu Ma, Kexin Huang, Haoming Meng, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, llm
- Data Domain: MATH, AIME
-
One-Way Policy Optimization for Self-Evolving LLMs
- Shuo Yang, Jinda Lu, Kexin Huang, Chiyu Ma, Shaohang Wei, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, AIME
-
Experience Augmented Policy Optimization for LLM Reasoning
- Jinda Lu, Kexin Huang, Junkang Wu, Shuo Yang, Jinghan Li, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH
-
- Yunjian Zhang, Sudong Wang, Yang Li, Peiran Xu, Conghao Zhou, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME
-
EchoRL: Reinforcement Learning via Rollout Echoing
- Jinhe Bi, Aniri -, Minglai Yang, Xingcheng Zhou, Wenke Huang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Jiaming Li, Longze Chen, Ze Gong, Yukun Chen, Lu Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME
- Code: ritzz-ai/PACS
-
ThoughtFold: Folding Reasoning Chains via Introspective Preference Learning
- Ziyan Liu, Xueda Shen, Yuzhe Gu, songyang gao, Kuikun Liu, et al.
- Key: verifiable reward, reinforcement learning, rlvr, preference learning, reasoning
- Data Domain: Chain-of-Thoughts
-
- Lecheng Yan, Ruizhe Li, Guanhua CHEN, Qing Li, Jiahui Geng, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, llm
- Data Domain: MATH, GSM8K
-
Noise-corrected GRPO: From Noisy Rewards to Unbiased Gradients
- Omar Elmansouri, Fathinah Izzati, Mohamed El Amine Seddik, Salem Lahlou
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, rlhf
- Data Domain: MATH
-
TGPO: Efficient Policy Optimization through Sequence Anchor and Information Gating
- Hang Ding, Dongqi Liu, Qiming Feng, Jian Li, Tong Lei, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, AIME
-
Provable Benefits of RLVR over SFT for Reasoning Models: Learning to Backtrack Efficiently
- Stanley Wei, Juno Kim
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH
-
Do We Need Adam? Surprisingly Strong and Sparse Reinforcement Learning with SGD in LLMs
- Sagnik Mukherjee, Lifan Yuan, Pavan Jayasinha, Dilek Hakkani-Tür, Hao Peng
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, GSM8K
-
Beyond Normalization: Rethinking the Partition Function as a Difficulty Scheduler for RLVR
- Dohyung Kim, Minbeom Kim, Jeonghye Kim, Lee Sangmook, Sojeong Rhee, et al.
- Key: reasoning, llm, grpo
- Data Domain: MATH, GSM8K
-
Learning Useful Supervision for Reinforcement Learning in Reasoning Models
- Liang CHEN, Xueting Han, Li Shen, Jing Bai, Kam-Fai Wong
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, AIME
-
The Obfuscation Atlas: Mapping Where Honesty Emerges in RLVR with Deception Probes
- Mohammad Taufeeque, Stefan Heimersheim, Adam Gleave, Chris Cundy
- Key: detector, training, deception, obfuscated, honest
- Data Domain: MATH, GSM8K
-
- Yi Ding, Ziliang Qiu, Bolian Li, Ruqi Zhang
- Key: reinforcement learning, rlvr, language model, reasoning
- Data Domain: MathVerse, MathVision
-
PLaID++: A Preference Aligned Language Model for Targeted Inorganic Materials Design
- Andy Xu, Rohan Desai, Larry Wang, Ethan Ritz, Gabriel Hope
- Key: verifiable reward, reinforcement learning, rlvr, llm, preference optimization
- Data Domain: Materials science domain data
-
Enhancing Multi-Modal LLMs Reasoning via Difficulty-Aware Group Normalization
- Jinghan Li, Junfeng Fang, Jinda Lu, Yuan Wang, Xiaoyan Guo, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MathVerse, MathVision, MMMU
-
Escaping the Mode: Multi-Answer Reinforcement Learning in LMs
- Isha Puri, Mehul Damani, Idan Shenfeld, Marzyeh Ghassemi, Jacob Andreas, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model
- Data Domain: MATH, GSM8K
-
Depth-Breadth Synergy in RLVR: Unlocking LLM Reasoning Gains with Adaptive Exploration
- Zhicheng Yang, Zhijiang Guo, Yinya Huang, Yongxin Wang, Dongchun Xie, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME
-
Reinforcement Learning via Self-Distillation
- Jonas Hübotter, Frederike Lübeck, Lejs Behric, Anton Baumann, Marco Bagatella, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, LiveCodeBench, Policy Optimization
- Code: lasgroup/SDPO
-
A Regret Minimization Framework on Preference Learning in Large Language Models
- Suhwan Kim, Taehyun Cho, Youngsoo Jang, Geon-Hyeong Kim, Yu Jin Kim, et al.
- Key: verifiable reward, reinforcement learning, rlvr, preference learning, language model
- Data Domain: MATH, GSM8K
-
Geometry-Preserving Orthonormal Initialization for Low-Rank Adaptation in Reinforcement Learning
- Ruijia Zhang, Jiacheng Zhu, Hanqing Zhu, Laixi Shi
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, GSM8K
-
- Zichao Li, Jie Lou, Fangchen Dong, Zhiyuan Fan, Mengjie Ren, et al.
- Key: reinforcement learning, rlvr, rlhf, reasoning, llm
- Data Domain: MATH, AIME, GSM8K
-
Scaling the Scaling Logic: Agentic Meta-Synthesis of Logic Reasoning
- Bowen LIU, Zhi Wu, RunquanXie, Zhanhui Kang, Jia Li
- Key: verifiable reward, reinforcement learning, rlvr, reasoning
- Data Domain: Protocol, SSLogic-evolved
-
Single-Rollout Hidden-State Dynamics for Training-Free RLVR Data Selection
- Jianghao Wu, Daniel F Schmidt, Weiqiang Wang, Jin Ye, Jianfei Cai, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning
- Data Domain: MATH, GSM8K
-
SAGE: Shaping Anchors for Guided Exploration in RLVR of LLMs
- Chanuk Lee, Minki Kang, Sung Ju Hwang
- Key: verifiable reward, reinforcement learning, rlvr, language model, ppo
- Data Domain: MATH-500, AIME, AMC23, Minerva
- Code: tally0818/SAGE
-
Outcome-Based Rewards Do Not Guarantee Faithful and Verifiable Reasoning
- Qinan Yu, Alexa Tartaglini, Peter Hase, Carlos Guestrin, Christopher Potts
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K, HotpotQA
-
Reward and Guidance through Rubrics: Promoting Exploration to Improve Multi-Domain Reasoning
- Baolong Bi, Shenghua Liu, Yiwei Wang, Siqian Tong, Lingrui Mei, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GPQA, MMLU
-
Advantage Collapse in Group Relative Policy Optimization: Diagnosis and Mitigation
- Xixiang He, Qiyao Sun, Ao Cheng, Xingming Li, Xuanyu Ji, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, AIME
-
Golden Goose: A Simple Trick to Synthesize Unlimited RLVR Tasks from Unverifiable Internet Text
- Ximing Lu, David Acuna, Jaehun Jung, Jian Hu, Di Zhang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: GooseReason-0.7M, MATH
-
Shrinking the Variance: Shrinkage Baselines for Reinforcement Learning with Verifiable Rewards
- Guanning Zeng, Zhaoyi Zhou, Daman Arora, Andrea Zanette
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, grpo
- Data Domain: MATH, AIME, GSM8K
-
Rubric Curriculum RL: Exploiting the Generation-Verification Gap in Creative Writing
- Tejas Krishnan, Sumeet Motwani, Charles London, Suhaas Bhat, Huitian Jiao, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reward model
- Data Domain: MATH
-
On the Learning Dynamics of RLVR at the Edge of Competence
- Yu Huang, Zixin Wen, Yuejie Chi, Yuting Wei, Aarti Singh, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning
- Data Domain: MATH, GSM8K
-
BroRL: Scaling Reinforcement Learning via Broadened Exploration
- Jian Hu, Mingjie Liu, Ximing Lu, Fang Wu, Zaid Harchaoui, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME, LiveCodeBench
-
Probing RLVR Training Instability through the Lens of Objective-Level Hacking
- Yiming Dong, Kun Fu, Haoyu Li, Xinyuan Zhu, Yurou Liu, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, alignment
- Data Domain: MATH, AIME
-
Monitorability as a Free Gift: How RLVR Spontaneously Aligns Reasoning
- Zidi Xiong, Shan Chen, Himabindu Lakkaraju
- Key: verifiable reward, reinforcement learning, safety, rlvr, reasoning
- Data Domain: MATH, GSM8K
-
PretrainZero: Reinforcement Active Pretraining
- Xingrun Xing, Zhiyuan Fan, Jie Lou, Guoqi Li, Jiajun Zhang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, fine-tuning, reward model
- Data Domain: MATH, MMLU, MMLU-Pro
-
- Ruicheng Ao, David Simchi-Levi, Xinshang Wang
- Key: rlvr, llm, models, through, solver
- Data Domain: MDP-based OR benchmarks
-
- Speed Zhu, Chuheng Zhang, Jianwei Cai, Guang Chen, Lulu Wu, et al.
- Key: verifiable reward, reinforcement learning, rlvr, fine-tuning, reasoning
- Data Domain: CodeForces
-
Reward Modeling from Natural Language Human Feedback
- Zongqi Wang, Rui Wang, Yuchuan Wu, Yiyao Yu, Pinyi Zhang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reward model, reward modeling
- Data Domain: MT-Bench, AlpacaEval, RewardBench
2025
NeurIPS 2025
ICLR 2026
Click to expand / collapse
-
RLVER: Reinforcement Learning with Verifiable Emotion Rewards for Empathetic Agents
- Peisong Wang, Ruotian Ma, Bang Zhang, Xingyu Chen, Zhiwei He, et al.
- Key: Large language models, Reinforcement Learning, Agent
- Data Domain: Empathetic dialogue benchmarks
- Code: Tencent/DigitalHuman/RLVER
-
Rectifying LLM Thought from Lens of Optimization
- Junnan Liu, Hongwei Liu, Songyang Zhang, Kai Chen
- Key: Large Lanugae Model, Large Lanugae Model Reasoning, Reinforcement Learning with Verifiable Rewards
- Data Domain: MATH, AIME, GSM8K
-
EEPO: Exploration-Enhanced Policy Optimization via Sample-Then-Forget
- Liang Chen, Xueting Han, Qizhou Wang, Bo Han, Jing Bai, et al.
- Key: large language models, reasoning models, reinforcement learning, RLVR, exploration, unlearning
- Data Domain: MATH, AIME, GSM8K
- Code: ChanLiang/EEPO
-
HiPO: Self-Hint Policy Optimization for RLVR
- Deng Qiyuan, Kehai Chen, Min Zhang, Zhongwen Xu
- Key: Reinforcement Learning, Large Language Models, Mathematical Reasoning
- Data Domain: AIME, CMIMC, BRUMO
-
Sparse but Critical: A Token-Level Analysis of Distributional Shifts in RLVR Fine-Tuning of LLMs
- Haoming Meng, Kexin Huang, Shaohang Wei, Chiyu Ma, Shuo Yang, et al.
- Key: LLM Reasoning, RLVR
- Data Domain: MATH, GSM8K
-
Supervised Reinforcement Learning: From Expert Trajectories to Step-wise Reasoning
- Yihe Deng, I-Hung Hsu, Jun Yan, Zifeng Wang, Rujun Han, et al.
- Key: Reinforcement learning, Reasoning, Large Language Model, Agent
- Data Domain: MATH, AIME, GSM8K
-
RLBFF: Binary Flexible Feedback to bridge between Human Feedback & Verifiable Rewards
- Zhilin Wang, Jiaqi Zeng, Olivier Delalleau, Ellie Evans, Daniel Egert, et al.
- Key: reward modeling, model alignment, inference-time control, customization, LLM post-training
- Data Domain: MT-Bench, WildBench, RM-Bench
-
The Markovian Thinker: Architecture-Agnostic Linear Scaling of Reasoning
- Milad Aghajohari, Kamran Chitsaz, Amirhossein Kazemnejad, Sarath Chandar, Alessandro Sordoni, et al.
- Key: LLM Reasoning, RL for LLMs, Reasoning Models, Scalable Reasoning, Test-Time Scaling
- Data Domain: DeepScaleR
-
Generalization of RLVR Using Causal Reasoning as a Testbed
- Brian Lu, Hongyu Zhao, Shuo Sun, Hao Peng, Rui Ding, et al.
- Key: Large Language Models, Reinforcement Learning with Verifiable Rewards, Generalization, Causal Reasoning
- Data Domain: Causal reasoning benchmarks, MATH
-
Rubrics as Rewards: Reinforcement Learning Beyond Verifiable Domains
- Anisha Gunjal, Anthony Wang, Elaine Lau, Vaskar Nath, Yunzhong He, et al.
- Key: representation learning for language, datasets and benchmarks, reward modeling, reinforcement learning, natural langauge processing, large language models, reasoning, alignment
- Data Domain: MATH, GPQA, HealthBench, GPQA-Diamond
-
References Improve LLM Alignment in Non-Verifiable Domains
- Kejian Shi, Yixin Liu, PeiFeng Wang, Alexander Fabbri, Shafiq Joty, et al.
- Key: LLM Alignment; LLM-as-a-Judge; Alignment Evaluation; Preference Optimization
- Data Domain: AlpacaEval, Arena-Hard
-
Parameter-Efficient Reinforcement Learning using Prefix Optimization
- Itamar Rocha Filho, Rosie Zhao, Sham M. Kakade, Eran Malach, Samy Jelassi
- Key: reinforcement learning with verifiable rewards, parameter efficient tuning
- Data Domain: MATH
-
HARDTESTGEN: A High-Quality RL Verifier Generation Pipeline for LLM Algorithmic Coding
- Zhongmou He, Yee Man Choi, Kexun Zhang, Ivan Bercovich, Jiabao Ji, et al.
- Key: LLMs, RLVR, code generation
- Data Domain: LiveCodeBench, CodeForces
-
- Aleksander Boruch-Gruszecki, Yangtian Zi, Zixuan Wu, Tejas Oberoi, Carolyn Jane Anderson, et al.
- Key: large language models, program synthesis, code generation, reinforcement learning, low-resource programming languages
- Data Domain: MBPP, LiveCodeBench, CodeForces, MultiPL-E
-
- Zhiheng Xi, Xin Guo, Yang Nan, Enyu Zhou, Junrui Shen, et al.
- Key: RLVR, LLM Reasoning
- Data Domain: AIME
- Code: WooooDyy/BAPO
-
Learning to Reason as Action Abstractions with Scalable Mid-Training RL
- Shenao Zhang, Donghan Yu, Yihao Feng, Bowen Jin, Zhaoran Wang, et al.
- Key: reinforcement learning, large language model
- Data Domain: HumanEval, MBPP, LiveCodeBench, CodeForces
-
Diversity-Enhanced Reasoning for Subjective Questions
- Yumeng Wang, Zhiyuan Fan, Jiayu Liu, Jen-tse Huang, Yi R. Fung
- Key: LLM, subjective reasoning, diversity-enhanced training
- Data Domain: MATH, AIME
-
PROS: Towards Compute-Efficient RLVR via Rollout Prefix Reuse
- Baizhou Huang, Xiaojun Wan
- Key: RLVR, reasoning
- Data Domain: MATH, GSM8K
-
LongRLVR: Long-Context Reinforcement Learning Requires Verifiable Context Rewards
- Guanzheng Chen, Michael Qizhe Shieh, Lidong Bing
- Key: Large Language Models, Long Context, Reinforcement Learning with Verifiable Rewards
- Data Domain: RULER-QA, LongBench
- Code: real-absolute-AI/LongRLVR
-
Selective Expert Guidance for Effective and Diverse Exploration in Reinforcement Learning of LLMs
- Zishang Jiang, Jinyi Han, tingyun li, Xinyi Wang, Sihang Jiang, et al.
- Key: Large Language Models, Group Relative Policy Optimization
- Data Domain: MATH, AIME, GSM8K
-
- Shangyu Xing, Siyuan Wang, Chenyuan Yang, Xinyu Dai, Xiang Ren
- Key: RLVR, GRPO, rollout, LLM, reasoning
- Data Domain: MATH, AIME, GSM8K
-
Controllable Exploration in Hybrid-Policy RLVR for Multi-Modal Reasoning
- Zhuoxu Huang, Mengxi Jia, Hao Sun, Xuelong Li, Jungong Han
- Key: Multi-Modal Reasoning, Reinforcement Learning from Verifiable Rewards
- Data Domain: MathVerse, MathVision, MMMU
-
Group Verification-based Policy Optimization for Interactive Coding Agents
- Silong Dai, Changzhi Sun, Haolun Wu, Huanran Zheng, Tao Ji, et al.
- Key: Large language model, Tool Learning, Reinforcement Learning
- Data Domain: AppWorld
-
Beyond Magnitude: Leveraging Direction of RLVR Updates for LLM Reasoning
- Kexin Huang, Haoming Meng, Junkang Wu, Jinda Lu, Chiyu Ma, et al.
- Key: RLVR, LLM reasoning
- Data Domain: MATH, AIME, DeepScaleR
-
Curriculum Reinforcement Learning from Easy to Hard Tasks Improves LLM Reasoning
- Shubham Parashar, Shurui Gui, Xiner Li, Hongyi Ling, Sushil Vemuri, et al.
- Key: LLM, Reinforcement Learning, Post Training
- Data Domain: MATH, AIME, GSM8K
-
ReVeal: Self-Evolving Code Agents via Reliable Self-Verification
- Yiyang Jin, Kunzhao Xu, Hang Li, Xueting Han, Yanmin Zhou, et al.
- Key: Large Language Model, Reinforcement Learning, Code LLM, multi-turn RL
- Data Domain: LiveCodeBench
-
Process-Verified Reinforcement Learning for Theorem Proving via Lean
- Minsu Kim, Se-Young Yun
- Key: Formal Reasoning, Large Language Models, Theorem Proving with LLMs, Lean4
- Data Domain: MiniF2F, ProofNet
-
RL Squeezes, SFT Expands: A Comparative Study of Reasoning LLMs
- Kohsei Matsutani, Shota Takashiro, Gouki Minegishi, Takeshi Kojima, Yusuke Iwasawa, et al.
- Key: LLMs, Reasoning, RLVR, Interpretability
- Data Domain: MATH, AIME, GSM8K
-
- Xingwu Chen, Tianle Li, Difan Zou
- Key: Reinforcement Learning, Language Models, Reasoning Patterns, Training Dynamics
- Data Domain: MATH, GSM8K
-
Evaluating and Improving Cultural Awareness of Reward Models for LLM Alignment
- Hongbin Zhang, Kehai Chen, Xuefeng Bai, Yang Xiang, Min Zhang
- Key: cultural awareness, reward model, LLM Alignment, RLHF, RL, Dataset, Benchmark, Multilingual Evaluation
- Data Domain: CARB, GlobalOpinionQA
-
Breaking Barriers: Do Reinforcement Post Training Gains Transfer To Unseen Domains?
- Chuxuan Hu, Yuxuan Zhu, Antony Kellermann, Caleb Biddulph, Suppakit Waiwitlikhit, et al.
- Key: large language models, reinforcement learning, supervised fine-tuning, generalizability
- Data Domain: MATH, GSM8K, MMLU
-
Tina: Tiny Reasoning Models via LoRA
- Shangshang Wang, Julian Asilis, Ömer Faruk Akgül, Enes Burak Bilgin, Ollie Liu, et al.
- Key: Reasoning models, efficient reasoning, LoRA, RLVR
- Data Domain: AIME24
-
Learning to Reason without External Rewards
- Xuandong Zhao, Zhewei Kang, Aosong Feng, Sergey Levine, Dawn Song
- Key: RL, Reasoning, LLM
- Data Domain: MATH, GSM8K
- Code: sunblaze-ucb/Intuitor
-
$ extbf{Re}^{2}$: Unlocking LLM Reasoning via Reinforcement Learning with Re-solving
- Pinzheng Wang, ShuliXu, Juntao Li, Yu Luo, Dong Li, et al.
- Key: LLM Reasoning, Reinforcement learning, Re-solving Mechanism, Test-time Scaling
- Data Domain: MATH, AIME, GSM8K
-
Co-rewarding: Stable Self-supervised RL for Eliciting Reasoning in Large Language Models
- Zizhuo Zhang, Jianing Zhu, Xinmu Ge, Zihua Zhao, Zhanke Zhou, et al.
- Key: Large language model reasoning, self-supervised RL
- Data Domain: GSM8K
-
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent
- Hongli Yu, Tinghong Chen, Jiangtao Feng, Jiangjie Chen, Weinan Dai, et al.
- Key: LLM, memory, agent, RLVR
- Data Domain: ViCrit-Bench, visual reasoning benchmarks
-
Diversity-Incentivized Exploration for Versatile Reasoning
- Zican Hu, Shilin Zhang, Yafu Li, Jianhao Yan, Xuyang Hu, et al.
- Key: LLM reasoning, Reinforcement learning with verifiable rewards, efficient exploration, diversity
- Data Domain: MATH, AIME, GSM8K
-
- Zijun Gao, Zhikun Xu, Xiao Ye, Ben Zhou
- Key: large language models, mathematical reasoning, conceptual understanding, fine-tuning, robustness
- Data Domain: MATH
-
Random Policy Valuation is Enough for LLM Reasoning with Verifiable Rewards
- Haoran He, Yuxiao Ye, Qingpeng Cai, Chen Hu, Binxing Jiao, et al.
- Key: Large Language Models (LLMs), Reinforcement Learning, RLVR, Math Reasoning, Diversity
- Data Domain: MATH, Markov Decision Process
-
ExGRPO: Learning to Reason from Experience
- Runzhe Zhan, Yafu Li, Zhi Wang, Xiaoye Qu, Dongrui Liu, et al.
- Key: Reinforcement Learning, Large Reasoning Model, Reinforcement Learning with Verifiable Rewards
- Data Domain: MATH, AIME, GSM8K
- Code: ElliottYan/LUFFY
-
MATH-Beyond: A Benchmark for RL to Expand Beyond the Base Model
- Prasanna Mayilvahanan, Ricardo Olmedo, Thaddäus Wiedemer, Wieland Brendel
- Key: RLVR, RL, Reasoning, Math, LLM Evaluation
- Data Domain: MATH, AIME, DeepScaleR, DAPO-Math, MATH-B
-
CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models
- Runpeng Dai, Linfeng Song, Haolin Liu, Zhenwen Liang, Dian Yu, et al.
- Key: Large language models, Reasoning, Exploration
- Data Domain: AIME
-
LaSeR: Reinforcement Learning with Last-Token Self-Rewarding
- Wenkai Yang, Weijie Liu, Ruobing Xie, Yiju Guo, Lulu Wu, et al.
- Key: Reinforcement Learning, LLM Reasoning, Self-Rewarding
- Data Domain: MATH, GSM8K
- Code: RUCBM/LaSeR
-
Learn More with Less: Uncertainty Consistency Guided Query Selection for RLVR
- Hao Yi, Yulan Hu, Xin Li, Sheng Ouyang, Lizhong Ding, et al.
- Key: Reinforcement learning; Large Language Model; Active Learning; Reasoning
- Data Domain: MATH, GSM8K
-
- Xumeng Wen, Zihan Liu, Shun Zheng, Shengyu Ye, Zhirong Wu, et al.
- Key: large language models, reasoning, reinforcement learning
- Data Domain: MATH, GSM8K
-
Spotlight on Token Perception for Multimodal Reinforcement Learning
- Siyuan Huang, Xiaoye Qu, Yafu Li, Yun Luo, Zefeng He, et al.
- Key: Multimodal Reasoning, LVLM, Reinforcement Learning
- Data Domain: MathVerse, DynaMath, Geo3k, MathVision, MMK12, We-Math, LogicVista, MMMU-Pro
-
SPECS: Decoupling Multimodal Learning via Self-distilled Preference-based Cold Start
- Kun Chen, Peng Shi, Haibo Qiu, Zhixiong Zeng, Siqi Yang, et al.
- Key: Vision Language Models, Reinforcement Learning, Reasoning, Cold-Start, Preference Optimization, Direct Preference Optimization (DPO), Self-Distillation
- Data Domain: MathVista, MEGA-Bench
-
Quagmires in SFT-RL Post-Training: When High SFT Scores Mislead and What to Use Instead
- Feiyang Kang, Michael Kuchnik, Karthik Padthe, Marin Vlastelica, Ruoxi Jia, et al.
- Key: Post-Training, Large Reasoning Models, Large Language Models, Performance Prediction, Reinforcement Learning with Verifiable Rewards
- Data Domain: MATH
-
- Fang Wu, Weihao Xuan, Heli Qi, Aaron Tu, Ximing Lu, et al.
- Key: MCTS, RLVR
- Data Domain: LiveCodeBench, AIME24
- Code: smiles724/DeepSearch
-
- Thanh-Long V. Le, Myeongho Jeon, Kim Vu, Viet Dac Lai, Eunho Yang
- Key: large language models, reinforcement learning with verifiable rewards, llm reasoning
- Data Domain: MATH
-
R-Horizon: How Far Can Your Large Reasoning Model Really Go in Breadth and Depth?
- Yi Lu, Jianing Wang, Linsen Guo, Wei He, Hongyin Tang, et al.
- Key: Large Reasoning Models, Long Horizon Reasoning
- Data Domain: R-HORIZON, AIME2024
- Code: meituan-longcat/R-HORIZON
-
DuPO: Enabling Reliable Self-Verification via Dual Preference Optimization
- Shuaijie She, Yu Bao, Yu Lu, Lu Xu, Tao Li, et al.
- Key: Self-Verification, Dual Learning, Preference Optimization, Large Language Model
- Data Domain: MATH, GSM8K, AIME
-
FAPO: Flawed-Aware Policy Optimization for Efficient and Reliable Reasoning
- Yuyang Ding, Chi Zhang, Juntao Li, Haibin Lin, Xin Liu, et al.
- Key: LLM Reasoning, Reinforcement Learning, Robust Learning
- Data Domain: MATH, AIME
- Code: volcengine/verl/recipe/fapo
-
Conditional Advantage Estimation for Reinforcement Learning in Large Reasoning Models
- Guanxu Chen, Yafu Li, Yuxian Jiang, Chen Qian, Qihan Ren, et al.
- Key: language models, reinforcement learning
- Data Domain: MATH
-
Quantile Advantage Estimation: Stabilizing RLVR for LLM Reasoning
- Junkang Wu, Kexin Huang, Jiancan Wu, An Zhang, Xiang Wang, et al.
- Key: RLVR, LLM reasoning, entropy explosion, advantage estimation
- Data Domain: AIME, AMC, MATH
-
Agentic Reinforced Policy Optimization
- Guanting Dong, Hangyu Mao, Kai Ma, Licheng Bao, Yifei Chen, et al.
- Key: Agentic Reinforcement Learning, Large Language Model, Agentic Reasoning, Tool-use Alignment
- Data Domain: GAIA, HLE, agent benchmarks
- Code: RUC-NLPIR/ARPO
-
Beyond Pass@ 1: Self-Play with Variational Problem Synthesis Sustains RLVR
- Xiao Liang, Zhong-Zhi Li, Yeyun Gong, yelong shen, Ying Nian Wu, et al.
- Key: LLM Reasoning; Reinforcement Learning; Self-envolving
- Data Domain: MATH, LiveCodeBench
- Code: MasterVito/SvS
-
AnesSuite: A Comprehensive Benchmark and Dataset Suite for Anesthesiology Reasoning in LLMs
- Xiang Feng, Wentao Jiang, Zengmao Wang, Yong Luo, Pingbo Xu, et al.
- Key: Large language model, Reasoning, Anesthesiology, Medicine
- Data Domain: AnesSuite, medical QA benchmarks
-
Native Reasoning Models: Training Language Models to Reason on Unverifiable Data
- Yuanfu Wang, Zhixuan Liu, Li xiangtian, Chaochao Lu, Chao Yang
- Key: LLM, Reinforcement Learning
- Data Domain: MATH, GSM8K
-
- Long Li, Zhijian Zhou, JIARAN HAO, Jason Klein Liu, Yanting Miao, et al.
- Key: Large Language Model, Reinforcement Learning with Verifiable Reward, f divergence
- Data Domain: MATH
-
Overthinking Reduction with Decoupled Rewards and Curriculum Data Scheduling
- Shuyang Jiang, Yusheng Liao, Ya Zhang, Yanfeng Wang, Yu Wang
- Key: efficient reasoning; curriculum sampling with decoupled reward
- Data Domain: MATH, AIME, GSM8K
-
- Yanqi Dai, Yuxiang Ji, Xiao Zhang, Yong Wang, Xiangxiang Chu, et al.
- Key: Mathematical Reasoning, Group Relative Policy Optimization, Question Reformulation
- Data Domain: MATH, AIME
-
Perception-R1: Advancing Multimodal Reasoning Capabilities of MLLMs via Visual Perception Reward
- Tong Xiao, Xin Xu, Zhenya Huang, Hongyu Gao, Quan Liu, et al.
- Key: Multimodal Large Language Models, Multimodal Reasoning, Reinforcement Learning
- Data Domain: MATH
-
- Xu Wan, Yansheng Wang, Wenqi Huang, Mingyang Sun
- Key: LLM post-training; off-policy RLVR
- Data Domain: MathVerse, MathVision, MMMU
-
QuRL: Low-Precision Reinforcement Learning for Efficient Reasoning
- Yuhang Li, Reena Elangovan, Xin Dong, Priyadarshini Panda, Brucek Khailany
- Key: Reinforcement Learning, Quantization
- Data Domain: DeepScaleR
-
Towards High Data Efficiency in Reinforcement Learning with Verifiable Reward
- Xinyu Tang, Zhenduo Zhang, Yurou Liu, Xin Zhao, zujie wen, et al.
- Key: Data Efficiency, Reinforcement Learning with Verifiable Reward
- Data Domain: AIME24, AIME25
-
Perception-Aware Policy Optimization for Multimodal Reasoning
- Zhenhailong Wang, Xuehang Guo, Sofia Stoica, Haiyang Xu, Hongru WANG, et al.
- Key: multimodal reasoning, reinforcement learning, policy optimization, large language models, visual perception, GRPO, DAPO
- Data Domain: MathVerse, MathVision, MMMU-Pro
-
Sample Lottery: Unsupervised Discovery of Critical Instances for LLM Reasoning
- Zhiping Xiao, Yusheng Zhao, Qixin Zhang, Jiaye Xie, Wanjia Zhao, et al.
- Key: Large Language Model, Reinforcement Learning with Verifiable Reward
- Data Domain: MATH, GSM8K
-
Scheduling Your LLM Reinforcement Learning with Reasoning Trees
- Hong Wang, Zhezheng Hao, Jian Luo, Chenxing Wei, Yao Shu, et al.
- Key: large language model, RLVR, Data Scheduling
- Data Domain: MATH
-
Risk-Sensitive Reinforcement Learning for Alleviating Exploration Dilemmas in Large Language Models
- Yuhua Jiang, Jiawei Huang, Yufeng Yuan, Xin Mao, YuYue, et al.
- Key: RLVR, Large Language Model, Reinforcement Learning, Pass@k Optimization
- Data Domain: MATH, AIME
-
QuRL: Rubrics As Judge For Open-Ended Question Answering
- Xiyu Wei, Qingwei Zong, Xiaoguang Li, Eugene J. Yu, Sujian Li
- Key: rubrics, reinforcement-learning, open-ended qa, large language model, generation
- Data Domain: MT-Bench, AlpacaEval, open-ended QA benchmarks
-
Learning What Reinforcement Learning Can't: Interleaved Online Fine-Tuning for Hardest Questions
- Lu Ma, Hao Liang, Meiyi Qiang, Lexiang Tang, Xiaochen Ma, et al.
- Key: Large Language Models; Reasoning; Reinforcement Learning; Supervised Fine-Tuning
- Data Domain: MATH
-
- Xin Xu, Clive Bai, Kai Yang, Tianhao Chen, Yang Wang, et al.
- Key: Large Language Models, Reasoning, Reinforcement Learning with Verifiable Rewards, Long Chain-of-Thought
- Data Domain: LiveCodeBench, AIME24
-
Exploration vs Exploitation: Rethinking RLVR through Clipping, Entropy, and Spurious Reward
- Peter Chen, Xiaopeng Li, Ziniu Li, Wotao Yin, Xi Chen, et al.
- Key: Reinforcement Learning with Verifiable Rewards, Group Relative Policy Optimization, LLM Reasoning
- Data Domain: MATH, GSM8K
-
How Far Can Unsupervised RLVR Scale LLM Training?
- Bingxiang He, Yuxin Zuo, Zeyuan Liu, Shangziqi Zhao, Zixuan Fu, et al.
- Key: Large Language Models, Unsupervised Reward, Reinforcement Learning, Reasoning
- Data Domain: MATH, GSM8K, AIME
-
TraPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning
- Shenzhi Yang, Guangcheng Zhu, Haobo Wang, Xing Zheng, Yingfan MA, et al.
- Key: Reinforcement Learning with Verifiable Rewards, Semi-supervised Learning, Large Language Model
- Data Domain: MATH, AIME
-
Search Self-Play: Pushing the Frontier of Agent Capability without Supervision
- Hongliang Lu, Yuhang Wen, Pengyu Cheng, Ruijin Ding, Jiaqi Guo, et al.
- Key: Self-Play, Deep Search, LLM, Agent, RLVR
- Data Domain: WebShop, HotpotQA, agent benchmarks
- Code: Qwen-Applications/SSP
-
- Bo Liu, Simon Yu, Zichen Liu, Leon Guertler, Penghui Qi, et al.
- Key: Reinforcement Learning, Self-Play, Large Language Models, Reasoning, Multi-Agent Reinforcement Learning
- Data Domain: Game-based reasoning benchmarks
- Code: spiral-rl/spiral
-
- Yuxin Jiang, Yufei Wang, Qiyuan Zhang, Xingshan Zeng, Liangyou Li, et al.
- Key: reinforcement learning, verifiable reference-based rewards, open-ended generation
- Data Domain: MATH
-
A Simple "Motivation" Can Enhance Reinforcement Finetuning of Large Reasoning Models
- Junjie Zhang, Guozheng Ma, Shunyu Liu, Haoyu Wang, Jiaxing Huang, et al.
- Key: Reinforcement Finetuning, Large Language Models
- Data Domain: MATH, GSM8K
Click to expand / collapse
-
ViCrit: A Verifiable Reinforcement Learning Proxy Task for Visual Perception in VLMs
- Xiyao Wang, Zhengyuan Yang, Chao Feng, Yuhang Zhou, Xiaoyu Liu, Yongyuan Liang, Ming Li, Ziyi Zang, Linjie Li, Chung-Ching Lin, Kevin Lin, Furong Huang, Lijuan Wang
- Key: Visual reasoning, Vision-Language Model, Visual captioning, Reward Model, Visual Hallucination, fine-grained hallucination criticism as RL objective
- Data Domain: ViCrit-Bench, natural-image reasoning, abstract image reasoning, visual math
-
Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model?
- Yang Yue, Zhiqi Chen, Rui Lu, Andrew Zhao, Zhaokai Wang, Yang Yue, Shiji Song, Gao Huang
- Key: RLVR capability boundaries, pass@k analysis, base model vs RLVR-trained models, reasoning pattern emergence, distillation vs RL
- Data Domain: Math/coding/visual reasoning benchmarks, multiple model families and RL algorithms
-
Absolute Zero: Reinforced Self-play Reasoning with Zero Data
- Andrew Zhao, Yiran Wu, Yang Yue, Tong Wu, Quentin Xu, Yang Yue, Matthieu Lin, Shenzhi Wang, Qingyun Wu, Zilong Zheng, Gao Huang
- Key: Self-play reasoning, zero external data, self-proposed tasks, curriculum learning, code executor as unified feedback
- Data Domain: Coding and mathematical reasoning tasks, cross-model-scale experiments
-
CURE: Co-Evolving Coders and Unit Testers via Reinforcement Learning
- Yinjie Wang, Ling Yang, Ye Tian, Ke Shen, Mengdi Wang
- Key: Co-evolution of code generation and unit test generation, interaction-based rewards without ground-truth code, test-time scaling, agentic unit test generation
- Data Domain: SWE-bench Verified, unit test generation benchmarks, 4B model achieving 64.8% inference efficiency
-
Enigmata: Scaling Logical Reasoning in Large Language Models with Synthetic Verifiable Puzzles
- Jiangjie Chen, Qianyu He, Siyu Yuan, Aili Chen, Zhicheng Cai, Weinan Dai, Hongli Yu, Jiaze Chen, Xuefeng Li, Qiying Yu, Hao Zhou, Mingxuan Wang
- Key: Puzzle reasoning, generator-verifier design, 36 tasks across 7 categories, multi-task RLVR, 418K competition-level problems
- Data Domain: ENIGMATA-Eval, ARC-AGI (32.8%), ARC-AGI 2 (0.6%), AIME (2024-2025), BeyondAIME, GPQA (Diamond)
-
To Think or Not To Think: A Study of Thinking in Rule-Based Visual Reinforcement Fine-Tuning
- Ming Li, Jike Zhong, Shitian Zhao, Yuxiang Lai, Haoquan Zhang, Wang Bill Zhu, Kaipeng Zhang
- Key: Thinking vs No-Thinking RFT, visual perception tasks, overthinking in MLLMs, equality accuracy reward, Adaptive-Thinking method
- Data Domain: Six diverse visual tasks across different model sizes and types, image classification benchmarks
-
Trust, But Verify: A Self-Verification Approach to Reinforcement Learning with Verifiable Rewards
- Xiaoyuan Liu, Tian Liang, Zhiwei He, Jiahao Xu, Wenxuan Wang, Pinjia He, Zhaopeng Tu, Haitao Mi, Dong Yu
- Key: Self-verification in RLVR, RISE framework, simultaneous training of problem-solving and self-verification, online RL for both tasks
- Data Domain: Mathematical reasoning benchmarks, verification compute analysis
-
Beyond Verifiable Rewards: Scaling Reinforcement Learning in Language Models to Unverifiable Data
- Yunhao Tang, Sid Wang, Lovish Madaan, Remi Munos
- Key: JEPO algorithm, Jensen's evidence lower bound, unverifiable data, chain-of-thought as latent variable, extending RLVR to semi-verifiable data
- Data Domain: Math (verifiable), numina and numina-proof (semi-verifiable/unverifiable), test set likelihood evaluation
-
RLVR-World: Training World Models with Reinforcement Learning
- Jialong Wu, Shaofeng Yin, Ningya Feng, Mingsheng Long
- Key: World models with RLVR, task-specific optimization beyond MLE, transition prediction metrics as rewards, autoregressive tokenized sequences
- Data Domain: Text games, web navigation, robot manipulation, language-based and video-based world models
-
SeRL: Self-play Reinforcement Learning for Large Language Models with Limited Data
- Wenkai Fang, Shunyu Liu, Yang Zhou, Kongcheng Zhang, Tongya Zheng, Kaixuan Chen, Mingli Song, Dacheng Tao
- Key: Self-instruction generation, self-rewarding via majority-voting, bootstrapping with limited initial data, online filtering strategies
- Data Domain: Various reasoning benchmarks across different LLM backbones
-
Learning to Reason under Off-Policy Guidance
- Jianhao Yan, Yafu Li, Zican Hu, Zhi Wang, Ganqu Cui, Xiaoye Qu, Yu Cheng, Yue Zhang
- Key: LUFFY framework, off-policy reasoning traces, Mixed-Policy GRPO, policy shaping via regularized importance sampling, learning beyond initial capabilities
- Data Domain: Six math benchmarks, out-of-distribution tasks, weak model training scenarios
-
SWE-RL: Advancing LLM Reasoning via Reinforcement Learning on Open Software Evolution
- Yuxiang Wei, Olivier Duchenne, Jade Copet, Quentin Carbonneaux, Lingming Zhang, Daniel Fried, Gabriel Synnaeve, Rishabh Singh, Sida Wang
- Key: Software engineering with RL, lightweight rule-based reward, open-source software evolution data, Llama3-SWE-RL-70B achieving 41.0% on SWE-bench Verified
- Data Domain: SWE-bench Verified, function coding, library use, code reasoning, mathematics, general language understanding
-
rStar-Coder: Scaling Competitive Code Reasoning with a Large-Scale Verified Dataset
- Yifei Liu, Li Lyna Zhang, Yi Zhu, Bingcheng Dong, Xudong Zhou, Ning Shang, Fan Yang, Cheng Li, Mao Yang
- Key: 418K competition-level code problems, 580K long-reasoning solutions, input-output test case synthesis pipeline, mutual verification mechanism
- Data Domain: LiveCodeBench (57.3% for 7B), USA Computing Olympiad (16.15% avg for 7B, outperforming QWQ-32B)
-
SynLogic: Synthesizing Verifiable Reasoning Data at Scale for Learning Logical Reasoning and Beyond
- Junteng Liu, Yuanxiang Fan, Jiang Zhuo, Han Ding, Yongyi Hu, Chi Zhang, Yiqi Shi, Shitong Weng, Aili Chen, Shiqi Chen, Mozhi Zhang, Pengyu Zhao, Junxian He
- Key: Logical reasoning as foundation for general reasoning, 35 diverse logical reasoning tasks, controlled synthesis with adjustable difficulty, mixing with math/coding tasks
- Data Domain: BBEH (outperforming DeepSeek-R1-Distill-Qwen-32B by 6 points), state-of-the-art logical reasoning performance
-
SwS: Self-aware Weakness-driven Problem Synthesis in Reinforcement Learning for LLM Reasoning
- Xiao Liang, Zhong-Zhi Li, Yeyun Gong, Yang Wang, Hengyuan Zhang, Yelong Shen, Ying Nian Wu, Weizhu Chen
- Key: Self-aware weakness identification, problem synthesis targeting model deficiencies, core concept extraction from failure cases, weakness-driven augmentation
- Data Domain: Eight mainstream reasoning benchmarks, 10% gain on 7B models, 7.7% gain on 32B models
-
AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning
- Yang Chen, Zhuolin Yang, Zihan Liu, Chankyu Lee, Peng Xu, Mohammad Shoeybi, Bryan Catanzaro, Wei Ping
- Key: Math-only then code-only RL training sequence, curriculum learning with progressive response lengths, robust data curation for challenging prompts, on-policy parameter updates
- Data Domain: AIME 2025 (+14.6%/+17.2% for 7B/14B), LiveCodeBench (+6.8%/+5.8% for 7B/14B)
-
Agentic RL Scaling Law: Spontaneous Code Execution for Mathematical Problem Solving
- Xinji Mai, Haotian Xu, Xing W, Weinong Wang, Yingying Zhang, Wenqiang Zhang
- Key: ZeroTIR (Tool-Integrated Reasoning), spontaneous code execution without supervised tool-use examples, RL scaling laws for tool use, predictable metrics scaling
- Data Domain: Math benchmarks, standard RL algorithms comparison
-
Rethinking Verification for LLM Code Generation: From Generation to Testing
- Zihan Ma, Taolin Zhang, Maosongcao, Junnan Liu, Wenwei Zhang, Minnan Luo, Songyang Zhang, Kai Chen
- Key: Test-case generation (TCG) task, multi-dimensional thoroughness metrics, human-LLM collaborative method (SAGA), TCGBench benchmark
- Data Domain: TCGBench (90.62% detection rate), LiveCodeBench-v6 (10.78% higher Verifier Acc), test suite quality evaluation
-
ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models
- Mingjie Liu, Shizhe Diao, Ximing Lu, Jian Hu, Xin Dong, Yejin Choi, Jan Kautz, Yi Dong
- Key: Prolonged RL training, KL divergence control, reference policy resetting, diverse task suite, novel reasoning strategies inaccessible to base models
- Data Domain: Wide range of pass@k evaluations, base model competence vs training duration analysis
-
Scaling Code-Assisted Chain-of-Thoughts and Instructions for Model Reasoning
- Honglin Lin, Qizhi Pei, Zhuoshi Pan, Yu Li, Xin Gao, Juntao Li, Conghui He, Lijun Wu
- Key: Caco framework, code-assisted CoT, automated validation via code execution, reverse-engineering to natural language instructions, Caco-1.3M dataset
- Data Domain: Mathematical reasoning benchmarks, code-anchored verification, instruction diversity analysis
-
The Surprising Effectiveness of Negative Reinforcement in LLM Reasoning
- Xinyu Zhu, Mengzhou Xia, Zhepei Wei, Wei-Lin Chen, Danqi Chen, Yu Meng
- Key: Negative Sample Reinforcement (NSR), training with only negative samples, Pass@k across entire spectrum, gradient analysis, upweighting NSR
- Data Domain: MATH, AIME 2025, AMC23, Qwen2.5-Math-7B, Qwen3-4B, Llama-3.1-8B-Instruct
-
Solver-Informed RL: Grounding Large Language Models for Authentic Optimization Modeling
- Yitian Chen, Jingfan Xia, Siyu Shao, Dongdong Ge, Yinyu Ye
- Key: Optimization problem formulation, Solver-Informed RL (SIRL), executable code and .lp file assessment, instance-level mathematical model verification, instance-enhanced self-consistency
- Data Domain: Diverse public optimization benchmarks, surpassing DeepSeek-V3 and OpenAI-o3
-
ATLAS: Autoformalizing Theorems through Lifting, Augmentation, and Synthesis of Data
- Xiaoyang Liu, Kangjie Bao, Jiashuo Zhang, Yunqi Liu, Yu Chen, Yuntian Liu, Yang Jiao, Tao Luo
- Key: Autoformalization, Lean 4, expert iteration with knowledge distillation, structural augmentation strategies, 117k undergraduate-level theorem statements
- Data Domain: All benchmarks (p<0.05, two-sided t-test), outperforming Herald Translator and Kimina-Autoformalizer
-
QiMeng-CodeV-R1: Reasoning-Enhanced Verilog Generation
- Yaoyu Zhu, Di Huang, Hanqi Lyu, Xiaoyun Zhang, Chongxiao Li, Wenxuan Shi, Yutong Wu, Jianan Mu, Jinghua Wang, Yang zhao, Pengwei Jin, Shuyao Cheng, Shengwen Liang, Xishan Zhang, Rui Zhang, Zidong Du, Qi Guo, Xing Hu, Yunji Chen
- Key: Verilog generation with RLVR, rule-based testbench generator, round-trip data synthesis, distill-then-RL pipeline, adaptive DAPO algorithm
- Data Domain: VerilogEval v2 (68.6% pass@1), RTLLM v1.1 (72.9% pass@1), surpassing 671B DeepSeek-R1 on RTLLM
-
QiMeng-SALV: Signal-Aware Learning for Verilog Code Generation
- Yang Zhang, Rui Zhang, Jiaming Guo, Huang Lei, Di Huang, Yunpu Zhao, Shuyao Cheng, Pengwei Jin, Chongxiao Li, Zidong Du, Xing Hu, Qi Guo, Yunji Chen
- Key: Signal-level optimization, verified signal-aware implementations extraction, Abstract Syntax Tree (AST) for code segments, signal-aware DPO
- Data Domain: VerilogEval, RTLLM, 7B matching DeepSeek v3 671B performance
-
miniF2F-Lean Revisited: Reviewing Limitations and Charting a Path Forward
- Azim Ospanov, Farzan Farnia, Roozbeh Yousefzadeh
- Key: Formal reasoning, automated theorem proving, Lean prover, miniF2F benchmark analysis, discrepancy correction, miniF2F-v2 with verified statements
- Data Domain: miniF2F original vs miniF2F-v2, full theorem proving pipeline evaluation (70% on v2 vs 40% on original)
-
SWE-SQL: Illuminating LLM Pathways to Solve User SQL Issues in Real-World Applications
- Jinyang Li, Xiaolong Li, Ge Qu, Per Jacobsson, Bowen Qin, Binyuan Hui, Shuzheng Si, Nan Huo, Xiaohan Xu, Yue Zhang, Ziwei Tang, Yuanshuai Li, Florensia Widjaja, Xintong Zhu, Feige Zhou, Yongfeng Huang, Yannis Papakonstantinou, Fatma Ozcan, Chenhao Ma, Reynold Cheng
- Key: SQL issue debugging, BIRD-CRITIC benchmark (530 PostgreSQL + 570 multi-dialect tasks), SQL-Rewind strategy, f-Plan Boosting, BIRD-Fixer agent
- Data Domain: BIRD-CRITIC-PG (38.11% for 14B), BIRD-CRITIC-Multi (29.65% for 14B), surpassing Claude-3.7-Sonnet and GPT-4.1
ICML 2025
Click to expand / collapse
-
SFT Memorizes, RL Generalizes: A Comparative Study of Foundation Model Post-training
- Tianzhe Chu, Yuexiang Zhai, Jihan Yang, Shengbang Tong, Saining Xie, Dale Schuurmans, Quoc V. Le, Sergey Levine, Yi Ma
- Key: Reinforcement Learning, Supervised Fine-tuning, Generalization, Memorization
- Data Domain: GeneralPoints, V-IRL
-
VinePPO: Refining Credit Assignment in RL Training of LLMs
- Amirhossein Kazemnejad, Milad Aghajohari, Eva Portelance, Alessandro Sordoni, Siva Reddy, Aaron Courville, Nicolas Le Roux
- Key: reinforcement learning, large language models, credit assignment, PPO, Monte Carlo estimation
- Data Domain: MATH, GSM8K
-
Controlling Large Language Model with Latent Action
- Chengxing Jia, Ziniu Li, Pengyuan Wang, Yi-Chen Li, Zhenyu Hou, Yuxiao Dong, Yang Yu
- Key: reinforcement learning, latent action space, controllable language models, inverse dynamics, policy learning
- Data Domain: math500, Countdown Game, Alfworld, Scienceworld
-
Emergent Misalignment: Narrow Finetuning Can Produce Broadly Misaligned LLMs
- Jan Betley, Daniel Tan, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Nathan Labenz, Owain Evans
- Key: emergent misalignment, insecure code, deceptive behavior, alignment, dataset intent, finetuning impact
- Data Domain: GPT-4o, Qwen2.5-32B-Instruct, Mistral-Small-2409, HumanEval, TruthfulQA, StrongREJECT, Machiavelli
-
Reasoning Through Execution: Unifying Process and Outcome Rewards for Code Generation
- Zhuohao Yu, Weizheng Gu, Yidong Wang, Xingru Jiang, Zhengran Zeng, Jindong Wang, Wei Ye, Shikun Zhang
- Key: code generation, process supervision, outcome supervision, reasoning, execution verification
- Data Domain: HumanEval, MBPP, LBPP
-
Demystifying Long Chain-of-Thought Reasoning
- Shiming Yang, Yuxuan Tong, Xinyao Niu, Graham Neubig, Xiang Yue
- Key: long chain-of-thought, reinforcement learning, supervised fine-tuning, reward shaping, verifiable rewards
- Data Domain: MATH-500, AIME 2024, TheoremQA, MMLU-Pro-1k
-
- Ruida Wang, Rui Pan, Yuxin Li, Jipeng Zhang, Yizhen Jia, Shizhe Diao, Renjie Pi, Junjie Hu, Tong Zhang
- Key: theorem proving, formal verification, Lean4, large language models, model collaboration, chain-of-thought
- Data Domain: MiniF2F-Test
-
SHIELDAGENT: Shielding Agents via Verifiable Safety Policy Reasoning
- Zhaorun Chen, Mintong Kang, Bo Li
- Key: LLM agents, safety policy, guardrails, probabilistic reasoning, policy verification
- Data Domain: SHIELDAGENT-BENCH (6 web environments), ST-WebAgentBench, VWA-Adv, AgentHarm
-
TOPLOC: A Locality Sensitive Hashing Scheme for Trustless Verifiable Inference
- Jack Min Ong, Matthew Di Ferrante, Aaron Pazdera, Ryan Garner, Sami Jaghouar, Manveer Basra, Max Ryabinin, Johannes Hagemann
- Key: verifiable inference, locality-sensitive hashing, polynomial encoding, trustless AI, LLM verification
- Data Domain: Llama 3.1-8B-Instruct, Intellect-1-Instruct, Gemma-2-9b-it, UltraChat dataset
-
Brain Bandit: A Biologically Grounded Neural Network for Efficient Control of Exploration
- Chen Jiang, Jiahui An, Yating Liu, Ni Ji
- Key: explore-exploit, stochastic Hopfield net, Thompson sampling, brain-inspired RL
- Data Domain: MAB tasks, MDP tasks
Other 2025 Papers
Click to expand / collapse
-
AgentPRM: Process Reward Models for LLM Agents via Step-Wise Promise and Progress
- Zhiheng Xi, Chenyang Liao, Guanyu Li, Yajie Yang, Wenxiang Chen, Zhihao Zhang, Binghai Wang, Senjie Jin, Yuhao Zhou, Jian Guan, Wei Wu, Tao Ji, Tao Gui, Qi Zhang, Xuanjing Huang
- Key: Process Reward Models (PRM), Agentic Tasks, Generalized Advantage Estimation (GAE), Promise, Progress
- Data Domain: WebShop, HotpotQA (Agent setting), Interactive Environments
-
Towards Agentic Self-Learning LLMs in Search Environment
- Wangtao Sun, Xiang Cheng, Jialin Fan, Xing Yu, Yao Xu, Shizhu He, Jun Zhao, Kang Liu
- Key: Self-Learning, Co-Evolution, Generative Reward Model (GRM), Search Agents
- Data Domain: NQ, TriviaQA, HotpotQA, 2WikiMultiHopQA, Qwen-2.5-7B-Instruct
-
Reinforcement Learning with Verifiable yet Noisy Rewards under Imperfect Verifiers
- Xin-Qiang Cai, Wei Wang, Feng Liu, Tongliang Liu, Gang Niu, Masashi Sugiyama
- Key: Noisy Rewards, Verifier Hacking, Forward/Backward Correction, GRPO, Reference-Free RL
- Data Domain: GSM8K, MATH, Qwen2.5-Math-7B
-
Language Models that Think, Chat Better
- Adithya Bhaskar, Xi Ye, Danqi Chen
- Key: Long CoT Reasoning, Large Language Models, GRPO, SFT
- Data Domain: WildBench, AlpacaEval2, ArenaHardV2, CreativeWritingV3, IFBench, MMLU-Redux, PopQA
-
RLVE: Scaling Up Reinforcement Learning for Language Models with Adaptive Verifiable Environments
- Zhiyuan Zeng, Qinyuan Cheng, Zhangyue Yin, Yefei He, Jinpeng Wang, et al.
- Key: Adaptive Environments, Verifiable Rewards, Environment Scaling, Curriculum Learning
- Data Domain: RLVE-Gym
-
Game-RL: Synthesizing Multimodal Verifiable Game Data to Boost VLMs' General Reasoning
- Jingqi Tong, Jixin Tang, Hangcheng Li, Yurong Mou, Ming Zhang, Jun Zhao, Yanbo Wen, et al.
- Key: Vision Language Model, Reasoning, Data Synthesis, Game Playing, Visual Question Answering, Data Sets or Data Repositories, Benchmarks
- Data Domain: GameQA, CharXiv, MathVerse, MathVision, MathVista, MMBench, MMMU-Pro, MMMU
-
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
- Daya Guo, Dejian Yang, Haowei Zhang et al. (DeepSeek-AI)
- Key: GRPO, pure-RL reasoning, distillation to 1.5 B–70 B, open checkpoints
- Data Domain: AIME-2024, MATH-500, Codeforces, LiveCodeBench, GPQA-Diamond, SWE-Bench
-
Demystifying Long Chain-of-Thought Reasoning in LLMs
- IN.AI Research Team
- Key: cosine length-scaling reward, repetition penalty, stable long CoT
- Data Domain: GSM8K, MATH, mixed STEM sets
-
Exploring the Limit of Outcome Reward for Learning Mathematical Reasoning
- Shanghai AI Lab
- Key: outcome-only reward, sparse-signal RL, math-centric limits
- Data Domain: MATH-Benchmark, GSM8K, AIME, proof datasets
-
Kimi K 1.5: Scaling Reinforcement Learning with LLMs
- Moonshot AI
- Key: curriculum RL, large-batch PPO, scalable infra
- Data Domain: multi-domain reasoning, long-context writing, agent benchmarks
-
S²R: Teaching LLMs to Self-Verify and Self-Correct via Reinforcement Learning
- Tencent AI Lab
- Key: self-verification & correction loops, dual-reward, safety alignment
- Data Domain: math QA, code generation, natural-language inference
-
Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling
- Tsinghua University
- Key: compute-optimal scaling, small-vs-large model trade-offs
- Data Domain: reasoning benchmarks, test-time compute scaling
-
QLASS: Boosting Language Agent Inference via Q-Guided Stepwise Search
- UCLA (Yizhou Sun Lab)
- Key: Q-guided stepwise search, agent inference efficiency
- Data Domain: web-agent tasks, reasoning QA
-
Process Reward Models That Think
- University of Michigan
- Key: process reward modelling, reasoning guidance
- Data Domain: reasoning QA, code tasks
-
THINKPRUNE: Pruning Long Chain-of-Thought of LLMs via Reinforcement Learning
- Anonymous
- Key: CoT pruning through RL, latency reduction
- Data Domain: GSM8K, assorted reasoning sets
-
GPG: A Simple and Strong Reinforcement Learning Baseline for Model Reasoning
- TBD
- Key: lightweight RL baseline, strong reasoning gains
- Data Domain: diverse reasoning benchmarks
-
- Google DeepMind
- Key: dynamic solve-vs-verify decision, compute optimality
- Data Domain: math & code tasks
-
SWEET-RL: Training Multi-Turn LLM Agents on Collaborative Reasoning Tasks
- Meta, UC Berkeley
- Key: multi-turn agent RL, collaborative reasoning
- Data Domain: agent task suites
-
L1: Controlling How Long a Reasoning Model Thinks With Reinforcement Learning
- Carnegie Mellon University
- Key: explicit control of reasoning steps via RL
- Data Domain: GSM8K, MATH
-
Scaling Test-Time Compute Without Verification or RL is Suboptimal
- CMU, UC Berkeley
- Key: verifier-based vs verifier-free compute scaling
- Data Domain: reasoning benchmarks
-
DAST: Difficulty-Adaptive Slow-Thinking for Large Reasoning Models
- Unicom Data Intelligence
- Key: difficulty-adaptive thinking length
- Data Domain: reasoning sets
-
Reasoning with Reinforced Functional Token Tuning
- Zhejiang University, Alibaba Cloud Computing
- Key: functional token tuning, RL-aided reasoning
- Data Domain: reasoning QA, code
-
Provably Optimal Distributional RL for LLM Post-Training
- Cornell & Harvard
- Key: distributional RL theory for LLM post-training
- Data Domain: synthetic reasoning, math tasks
-
On the Emergence of Thinking in LLMs I: Searching for the Right Intuition
- MIT
- Key: self-play RL, emergent reasoning patterns
- Data Domain: reasoning games, maths puzzles
-
STP: Self-Play LLM Theorem Provers with Iterative Conjecturing and Proving
- Stanford (Tengyu Ma)
- Key: theorem proving via self-play, sparse-reward tackling
- Data Domain: proof assistant datasets
-
A Sober Look at Progress in Language Model Reasoning: Pitfalls and Paths to Reproducibility
- University of Cambridge, University of Tübingen
- Key: evaluation pitfalls, reproducibility guidelines
- Data Domain: multiple reasoning benchmarks
-
Recitation over Reasoning: How Cutting-Edge LMs Fail on Elementary Reasoning Problems
- ByteDance Seed
- Key: fragility to minor perturbations, arithmetic reasoning
- Data Domain: elementary school-level arithmetic tasks
-
Proof or Bluff? Evaluating LLMs on 2025 USA Math Olympiad
- ETH Zurich, INSAIT
- Key: Olympiad-level evaluation, zero-score phenomenon
- Data Domain: 2025 USAMO problems
-
(REINFORCE++) A Simple and Efficient Approach for Aligning Large Language Models
- Jian Hu et al.
- Key: REINFORCE++ algorithm, stability vs PPO/GRPO
- Data Domain: RLHF alignment suites
-
ReFT v3: Reasoning with Reinforced Fine-Tuning (ACL 2025)
- Trung Le, Jiaqi Zhang et al.
- Key: single-stage RLFT, low-cost math alignment
- Data Domain: GSM8K, MATH, SVAMP
-
DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models
- DeepSeek-AI
- Key: GRPO, math-only RL, verifier-guided sampling
- Data Domain: MATH-500, AIME-2024, CNMO-2024
-
SimPO: Simple Preference Optimization with a Reference-Free Reward
- Shanghai AI Lab
- Key: reference-free preference optimisation, KL-free objective
- Data Domain: AlpacaEval, helpful/harmless RLHF sets
-
DeepSeek-Prover v1.5: Harnessing Proof Assistant Feedback for RL and MCTS
- DeepSeek-AI
- Key: proof-assistant feedback, Monte-Carlo Tree Search
- Data Domain: Lean theorem-proving benchmarks
-
Tülu 3: Pushing Frontiers in Open Language Model Post-Training
- Nathan Lambert, Jacob Morrison, Valentina Pyatkin, Shengyi Huang, Hamish Ivison, Faeze Brahman, Lester James V. Miranda, Alisa Liu, Nouha Dziri, Xinxi Lyu, Yuling Gu, Saumya Malik, Victoria Graf, Jena D. Hwang, Jiangjiang Yang, Ronan Le Bras, Øyvind Tafjord, Chris Wilhelm, Luca Soldaini, Noah A. Smith, Yizhong Wang, Pradeep Dasigi, Hannaneh Hajishirzi
- Key: post-training, supervised finetuning (SFT), Direct Preference Optimization (DPO), RLVR, open LLMs
- Data Domain: multi-task language-model benchmarks (Tülu 3 Eval, decontaminated standard suites)
-
Kimi k1.5: Scaling Reinforcement Learning with LLMs
- Kimi Team – Angang Du, Bofei Gao, Bowei Xing, Changjiu Jiang, Cheng Chen, Cheng Li, … , Zongyu Lin
- Key: RL with LLMs, long-context scaling, policy optimization, long2short CoT, multi-modal reasoning
- Data Domain: AIME, MATH 500, Codeforces, MathVista, LiveCodeBench
-
Model Alignment as Prospect Theoretic Optimization
- Stanford University, Contextual AI
- Key: prospect-theoretic objective for alignment
- Data Domain: alignment evaluation suites
-
UI-R1: Enhancing Efficient Action Prediction of GUI Agents by Reinforcement Learning
- Zhengxi Lu, Yuxiang Chai, Yaxuan Guo, Xi Yin, Liang Liu, Hao Wang, Han Xiao, Shuai Ren, Guanjing Xiong, Hongsheng Li
- Key: rule-based rewards, GRPO, multimodal LLM, GUI grounding & action, data-efficient RFT (136 samples)
- Data Domain: ScreenSpot, ScreenSpot-Pro, AndroidControl
-
GUI-R1: A Generalist R1-Style Vision-Language Action Model for GUI Agents
- Run Luo, Lu Wang, Wanwei He, Xiaobo Xia
- Key: unified action space, GRPO, high-level GUI tasks, cross-platform (Win/Linux/Mac/Android/Web), data-efficient RFT (3 K samples)
- Data Domain: ScreenSpot, ScreenSpot-Pro, GUI-Act-Web, OmniAct-Web, OmniAct-Desktop, AndroidControl-Low/High, GUI-Odyssey
-
MT-R1-Zero: Advancing LLM-based Machine Translation via R1-Zero-like Reinforcement Learning
- Zhaopeng Feng, Shaosheng Cao, Jiahan Ren, Jiayuan Su, Ruizhe Chen, Yan Zhang, Jian Wu, Zuozhu Liu
- Key: Machine Translation, Rule-metric Mixed Reward
- Data Domain: BLEU, COMETKiwi, XCOMET
-
Smart-Searcher: Incentivizing the Dynamic Knowledge Acquisition of LLMs via Reinforcement Learning
- Huatong Song, Jinhao Jiang, Wenqing Tian, Zhipeng Chen, Yuhuan Wu, Jiahao Zhao, Yingqian Min, Xin Zhao, Lei Fang, Ji-Rong Wen
- Key: Retrieval-Augmented Generation (RAG), Reinforcement Learning, Internal vs External Knowledge, Dynamic Switching
- Data Domain: Multi-hop QA benchmarks, Retrieval tasks
2024 & Earlier
Click to expand / collapse
-
Direct Preference Optimization: Your Language Model is Secretly a Reward Model (ICLR 2024)
- Rafael Raffel et al.
- Key: preference optimisation without RL, DPO objective
- Data Domain: summarisation, dialogue alignment
-
Math-Shepherd: Verify and Reinforce LLMs Step-by-Step without Human Annotations (NeurIPS 2023)
- Peking University, DeepSeek-AI
- Key: step-checker, verifier RL, zero human labels
- Data Domain: GSM8K-Step, MATH-Step
-
Let’s Verify Step by Step (ICML 2023)
- OpenAI
- Key: verifier prompts, iterative self-improvement
- Data Domain: GSM8K, ProofWriter
-
Solving Olympiad Geometry without Human Demonstrations (Nature 2023)
- DeepMind
- Key: formal geometry solving, RL without human demos
- Data Domain: geometry proof tasks
-
Training Language Models to Follow Instructions with Human Feedback (NeurIPS 2022)
- OpenAI
- Key: PPO-based RLHF, instruction-following alignment
- Data Domain: broad instruction-following tasks (InstructGPT)
Other Awesome Lists
Contributing
- Fork this repo.
- Add a paper/tool entry under the correct section (keep reverse-chronological order, follow the three-line format).
- Open a Pull Request and briefly describe your changes.
License
Awesome-RLVR © 2025 OpenDILab & Contributors Apache 2.0 License
Significant stargazers

137 followers · starred Sep 2026
Similar repos


A curated list of reinforcement learning with verifiable rewards (continually updated)
328
10 commits
updated Jun 1, 2026
README
Awesome RLVR — Reinforcement Learning with Verifiable Rewards
A curated collection of surveys, tutorials, codebases and papers on
Reinforcement Learning with Verifiable Rewards (RLVR)—
a rapidly emerging paradigm that aligns both LLMs and other agents through
objective, externally verifiable signals.
An overview of how Reinforcement Learning with Verifiable Rewards (RLVR) works.
(Figure taken from
“Tülu 3: Pushing Frontiers in
Open Language Model Post-Training”)
Why RLVR?
RLVR couples reinforcement learning with objective, externally verifiable signals, yielding a training paradigm that is simultaneously powerful and trustworthy:
- Ground-truth rewards – unit tests, formal proofs, or fact-checkers provide binary, tamper-proof feedback.
- Intrinsic safety & auditability – every reward can be traced back to a transparent verifier run, simplifying debugging and compliance.
- Strong generalization – models trained on verifiable objectives tend to extrapolate to unseen tasks with minimal extra data.
- Emergent “aha-moments” – sparse, high-precision rewards encourage systematic exploration that often yields sudden surges in capability when the correct strategy is discovered.
- Self-bootstrapping improvement – the agent can iteratively refine or even generate new verifiers, compounding its own learning signal.
- Domain-agnostic applicability – the same recipe works for code generation, theorem proving, robotics, games, and more.
How does it work?
- Sampling. We draw one or more candidate completions ( {a}{1..k} ) from a policy model ( \pi\theta ) given a prompt ( s ).
- Verification. A deterministic function ( r(s,{a}) ) checks each completion for correctness.
- Rewarding.
• If a completion is verifiably correct, it receives a reward ( r = \gamma ).
• Otherwise the reward is ( r = 0 ). - Policy update. Using the rewards, we update the policy parameters via RL (e.g., PPO).
- (Optional) Verifier refinement. The verifier itself can be trained, hardened, or expanded to cover new edge cases.
Through repeated iterations of this loop, the policy learns to maximise the externally verifiable reward while maintaining a clear audit trail for every decision it makes.
Pull requests are welcome 🎉 — see Contributing for guidelines.
[2026-05-06] New! Added 135 papers from ICLR 2026 and ICML 2026 🎉
[2025-07-03] Initial public release of Awesome-RLVR
Table of Contents
format:
- [title](paper link) (presentation type)
  - main authors or main affiliations
  - Key: key problems and insights
  - Data Domain: experiment environments
Surveys & Tutorials
Click to expand / collapse
-
Inference-Time Techniques for LLM Reasoning (Berkeley Lecture 2025)
- DeepMind & UC Berkeley (Xinyun Chen)
- Key: decoding-time search, self-consistency, verifier pipelines
- Data Domain: code/math reasoning benchmarks
-
Learning to Self-Improve & Reason with LLMs (Berkeley Talk 2025)
- Meta AI & NYU (Jason Weston)
- Key: continual self-improvement loops, alignment interplay
- Data Domain: open-ended dialogue & retrieval tasks
-
LLM Reasoning: Key Ideas and Limitations (Tutorial Slides 2024)
- DeepMind (Denny Zhou)
- Key: theoretical foundations & failure modes of reasoning
- Data Domain: slide examples, classroom demos
-
Can LLMs Reason & Plan? (ICML Tutorial 2024)
- Arizona State University (Subbarao Kambhampati)
- Key: planning-oriented reasoning, agent integration
- Data Domain: symbolic + LLM planning tasks
-
Towards Reasoning in Large Language Models (ACL Tutorial 2023)
- UIUC (Jie Huang)
- Key: survey of reasoning techniques & benchmarks
- Data Domain: academic tutorial datasets
-
From System 1 to System 2: A Survey of Reasoning Large Language Models (arXiv 2025)
- CAS & MBZUAI
- Key: cognitive-style taxonomy (fast vs. deliberative reasoning)
- Data Domain: logical, mathematical, commonsense datasets
-
Harnessing the Reasoning Economy: A Survey of Efficient Reasoning for Large Language Models (arXiv 2025)
- Chinese Univ. of Hong Kong
- Key: efficient reasoning, test-time-compute scaling
- Data Domain: math & code reasoning benchmarks
-
What, How, Where, and How Well? A Survey on Test-Time Scaling in Large Language Models (arXiv 2025)
- City University of Hong Kong
- Key: methods for scaling inference-time compute (CoT, search, self-consistency)
- Data Domain: diverse reasoning datasets
-
A Survey of Efficient Reasoning for Large Reasoning Models: Language, Multimodality, and Beyond (arXiv 2025)
- Shanghai AI Lab et al.
- Key: lifecycle-wide efficiency (pre-training → inference) for LRMs
- Data Domain: language + vision reasoning tasks
-
Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models (arXiv 2025)
- Rice University
- Key: “overthinking” phenomenon, length-control techniques
- Data Domain: GSM8K, MATH-500, AIME-24
-
A Visual Guide to Reasoning LLMs (Newsletter 2025)
- Maarten Grootendorst
- Key: illustrated test-time-compute concepts, DeepSeek-R1 case study
- Data Domain: graphical explanations & code demos
-
Understanding Reasoning LLMs – Methods and Strategies for Building and Refining Reasoning Models (Blog 2025)
- Sebastian Raschka
- Key: practical tutorial on data, architectures, evaluation
- Data Domain: Jupyter notebooks & open-source models
-
An Illusion of Progress? Assessing the Current State of Web Agents (arXiv 2025)
- Ohio State & UC Berkeley
- Key: empirical audit of LLM-based web agents, evaluation protocols
- Data Domain: autonomous web-navigation tasks
-
Agentic Large Language Models, A Survey (arXiv 2025)
- Leiden University
- Key: taxonomy of agentic LLM architectures & planning mechanisms
- Data Domain: multi-step reasoning / tool-use agents
-
A Comprehensive Survey of LLM Alignment Techniques: RLHF, RLAIF, PPO, DPO and More (arXiv 2024)
- Salesforce AI
- Key: reward modeling & preference-optimization pipelines
- Data Domain: alignment benchmarks, safety tasks
-
Self-Improvement of LLM Agents through Reinforcement Learning at Scale (MIT Scale-ML Talk 2024)
- MIT CSAIL & collaborators
- Key: large-scale RL for autonomous agent refinement
- Data Domain: simulated dialogue & tool-use agents
-
Reinforcement Learning from Verifiable Rewards (Book 2026)
- Kian Kyars
- Key: verifier design, outcome and process rewards, GRPO training signals, reward hacking, search/test-time verification, frontier RLVR, and agentic RLVR
- ExpEnv: math, code, proof, long-context QA, multimodal, and agentic verification examples
-
Reinforcement Learning from Verifiable Rewards (Blog 2025)
- Key: Uses binary, verifiable reward functions to inject precise, unbiased learning signals into RL pipelines for math, code, and other accuracy-critical tasks.
- Data Domain: Easily reproducible in Jupyter notebooks or any RL setup by plugging in auto-grading tools such as compilers, unit tests, or schema validators.
Codebases
Click to expand / collapse
| Project | Stars | Description |
|---|---|---|
| open-r1 | | Fully open reproduction of the DeepSeek-R1 pipeline (SFT, distillation, GRPO, evaluation) |
| OpenRLHF | | An Easy-to-use, Scalable and High-performance RLHF Framework based on Ray (PPO & GRPO & REINFORCE++ & vLLM & Ray & Dynamic Sampling & Async Agentic RL)* |
| verl | | a flexible, efficient and production-ready RL training library for large language models |
| TinyZero | | Minimal reproduction of DeepSeek R1-Zero |
| AReaL | | Ant Reasoning Reinforcement Learning for LLMs |
| Open-Reasoner-Zero | | one open source implementation of large-scale reasoning-oriented RL training focusing on scalability, simplicity and accessibility |
| ROLL | | an Efficient and User-Friendly Scaling Library for Reinforcement Learning with Large Language Models |
| slime | | an LLM post-training framework for RL scaling with high-performance training and flexible data generation |
| RAGEN | | RAGEN (Reasoning AGENt, pronounced like "region") leverages reinforcement learning (RL) to train LLM reasoning agents in interactive, stochastic environments. |
| PRIME | | PRIME (Process Reinforcement through IMplicit REwards), an open-source solution for online RL with process rewards |
| rllm | | an open-source framework for post-training language agents via reinforcement learning |
| Nemo-Aligner | | Scalable toolkit for efficient model alignment |
| Trinity-RFT | | A unified RFT framework with plug-and-play modules (for algorithms, data pipelines, and synchronization) |
Papers
2026
ICML 2026
Click to expand / collapse
-
RuCL: Stratified Rubric-Based Curriculum Learning for Multimodal Large Language Model Reasoning
- Yukun Chen, Jiaming Li, Longze Chen, Ze Gong, Jingpeng Li, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MathVerse, MathVision, Geo3k, MMK12, We-Math
-
ResRL: Boosting LLM Reasoning via Negative Sample Projection Residual Reinforcement Learning
- Zihan Lin, Xiaohan Wang, Jie Cao, Jiajun Chai, Li Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, alignment
- Data Domain: Residual Reinforcement Learning, Calling
- Code: 1229095296/ResRL
-
- Zhengzhao Ma, Xueru Wen, Boxi Cao, Yaojie Lu, Hongyu Lin, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME, AMC, LiveCodeBench, HumanEval+
- Code: icip-cas/DCPO
-
See First, Reason Later: Mutual Information-Guided Reinforcement Learning for Vision-Language Models
- Junfeng Fang, Zonghan Wu, Yin Zhang, Jiaxuan Zhao, Zengxiang Li, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MathVerse, MathVision, MMMU
-
G$^2$RPO: Geometric GRPO; Escaping LLM's Reasoning Rut to Break Accuracy--Entropy Trade-off
- Ali Rad, Khashayar Filom, Darioush Keivan, Peyman Mohajerin Esfahani, Ehsan Kamalinejad
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, reasoning
- Data Domain: MATH, AIME
-
Rate or Fate? RLV$^{ arepsilon}$R: Reinforcement Learning with Verifiable Noisy Rewards
- Ali Rad, Khashayar Filom, Darioush Keivan, Peyman Mohajerin Esfahani, Ehsan Kamalinejad
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, grpo
- Data Domain: Python code tasks with synthetic noise
-
Anchored Policy Optimization: Mitigating Exploration Collapse via Support-Constrained Rectification
- Tianyi Wang, Long Li, Hongcan Guo, Yibiao Chen, Yixia Li, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, ppo
- Data Domain: MATH, AIME
-
Spurious Rewards: Rethinking Training Signals in RLVR
- Rulin Shao, Stella Li, Rui Xin, Scott Geng, Yiping Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH
-
- Johannes Ackermann, Michael Noukhovitch, Takashi Ishida, Masashi Sugiyama
- Key: verifiable reward, reinforcement learning, rlvr, language model, rlhf
- Data Domain: MATH
-
- Haechan Kim, Soohyun Ryu, Gyouk Chu, Doohyuk Jang, Eunho Yang
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Contextual Rollout Bandits for Reinforcement Learning with Verifiable Rewards
- Xiaodong Lu, Xiaohan Wang, Jiajun Chai, Guojun Yin, Wei Lin, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, ppo
- Data Domain: MATH, AIME
-
The Unlearnability Phenomenon in RLVR for Language Models
- Yulin Chen, He He, Chen Zhao
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Evaluating Parameter Efficient Methods for RLVR
- Qingyu Yin, Yulun Wu, Zhennan Shen, Sunbowen Lee, Zhilin Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, AIME
-
- Chuyi Tan, Peiwen Yuan, Xinglin Wang, Yiwei Li, Shaoxiong Feng, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Clipping Bottleneck: Stabilizing RLVR via Stochastic Recovery of Near-Boundary Signals
- Shuo Yang, Jinda Lu, Chiyu Ma, Kexin Huang, Haoming Meng, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, llm
- Data Domain: MATH, AIME
-
One-Way Policy Optimization for Self-Evolving LLMs
- Shuo Yang, Jinda Lu, Kexin Huang, Chiyu Ma, Shaohang Wei, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, AIME
-
Experience Augmented Policy Optimization for LLM Reasoning
- Jinda Lu, Kexin Huang, Junkang Wu, Shuo Yang, Jinghan Li, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH
-
- Yunjian Zhang, Sudong Wang, Yang Li, Peiran Xu, Conghao Zhou, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME
-
EchoRL: Reinforcement Learning via Rollout Echoing
- Jinhe Bi, Aniri -, Minglai Yang, Xingcheng Zhou, Wenke Huang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K
-
Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Jiaming Li, Longze Chen, Ze Gong, Yukun Chen, Lu Wang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME
- Code: ritzz-ai/PACS
-
ThoughtFold: Folding Reasoning Chains via Introspective Preference Learning
- Ziyan Liu, Xueda Shen, Yuzhe Gu, songyang gao, Kuikun Liu, et al.
- Key: verifiable reward, reinforcement learning, rlvr, preference learning, reasoning
- Data Domain: Chain-of-Thoughts
-
- Lecheng Yan, Ruizhe Li, Guanhua CHEN, Qing Li, Jiahui Geng, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, llm
- Data Domain: MATH, GSM8K
-
Noise-corrected GRPO: From Noisy Rewards to Unbiased Gradients
- Omar Elmansouri, Fathinah Izzati, Mohamed El Amine Seddik, Salem Lahlou
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, rlhf
- Data Domain: MATH
-
TGPO: Efficient Policy Optimization through Sequence Anchor and Information Gating
- Hang Ding, Dongqi Liu, Qiming Feng, Jian Li, Tong Lei, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, AIME
-
Provable Benefits of RLVR over SFT for Reasoning Models: Learning to Backtrack Efficiently
- Stanley Wei, Juno Kim
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH
-
Do We Need Adam? Surprisingly Strong and Sparse Reinforcement Learning with SGD in LLMs
- Sagnik Mukherjee, Lifan Yuan, Pavan Jayasinha, Dilek Hakkani-Tür, Hao Peng
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, GSM8K
-
Beyond Normalization: Rethinking the Partition Function as a Difficulty Scheduler for RLVR
- Dohyung Kim, Minbeom Kim, Jeonghye Kim, Lee Sangmook, Sojeong Rhee, et al.
- Key: reasoning, llm, grpo
- Data Domain: MATH, GSM8K
-
Learning Useful Supervision for Reinforcement Learning in Reasoning Models
- Liang CHEN, Xueting Han, Li Shen, Jing Bai, Kam-Fai Wong
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, AIME
-
The Obfuscation Atlas: Mapping Where Honesty Emerges in RLVR with Deception Probes
- Mohammad Taufeeque, Stefan Heimersheim, Adam Gleave, Chris Cundy
- Key: detector, training, deception, obfuscated, honest
- Data Domain: MATH, GSM8K
-
- Yi Ding, Ziliang Qiu, Bolian Li, Ruqi Zhang
- Key: reinforcement learning, rlvr, language model, reasoning
- Data Domain: MathVerse, MathVision
-
PLaID++: A Preference Aligned Language Model for Targeted Inorganic Materials Design
- Andy Xu, Rohan Desai, Larry Wang, Ethan Ritz, Gabriel Hope
- Key: verifiable reward, reinforcement learning, rlvr, llm, preference optimization
- Data Domain: Materials science domain data
-
Enhancing Multi-Modal LLMs Reasoning via Difficulty-Aware Group Normalization
- Jinghan Li, Junfeng Fang, Jinda Lu, Yuan Wang, Xiaoyan Guo, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MathVerse, MathVision, MMMU
-
Escaping the Mode: Multi-Answer Reinforcement Learning in LMs
- Isha Puri, Mehul Damani, Idan Shenfeld, Marzyeh Ghassemi, Jacob Andreas, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model
- Data Domain: MATH, GSM8K
-
Depth-Breadth Synergy in RLVR: Unlocking LLM Reasoning Gains with Adaptive Exploration
- Zhicheng Yang, Zhijiang Guo, Yinya Huang, Yongxin Wang, Dongchun Xie, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME
-
Reinforcement Learning via Self-Distillation
- Jonas Hübotter, Frederike Lübeck, Lejs Behric, Anton Baumann, Marco Bagatella, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, LiveCodeBench, Policy Optimization
- Code: lasgroup/SDPO
-
A Regret Minimization Framework on Preference Learning in Large Language Models
- Suhwan Kim, Taehyun Cho, Youngsoo Jang, Geon-Hyeong Kim, Yu Jin Kim, et al.
- Key: verifiable reward, reinforcement learning, rlvr, preference learning, language model
- Data Domain: MATH, GSM8K
-
Geometry-Preserving Orthonormal Initialization for Low-Rank Adaptation in Reinforcement Learning
- Ruijia Zhang, Jiacheng Zhu, Hanqing Zhu, Laixi Shi
- Key: verifiable reward, reinforcement learning, rlvr, language model, fine-tuning
- Data Domain: MATH, GSM8K
-
- Zichao Li, Jie Lou, Fangchen Dong, Zhiyuan Fan, Mengjie Ren, et al.
- Key: reinforcement learning, rlvr, rlhf, reasoning, llm
- Data Domain: MATH, AIME, GSM8K
-
Scaling the Scaling Logic: Agentic Meta-Synthesis of Logic Reasoning
- Bowen LIU, Zhi Wu, RunquanXie, Zhanhui Kang, Jia Li
- Key: verifiable reward, reinforcement learning, rlvr, reasoning
- Data Domain: Protocol, SSLogic-evolved
-
Single-Rollout Hidden-State Dynamics for Training-Free RLVR Data Selection
- Jianghao Wu, Daniel F Schmidt, Weiqiang Wang, Jin Ye, Jianfei Cai, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning
- Data Domain: MATH, GSM8K
-
SAGE: Shaping Anchors for Guided Exploration in RLVR of LLMs
- Chanuk Lee, Minki Kang, Sung Ju Hwang
- Key: verifiable reward, reinforcement learning, rlvr, language model, ppo
- Data Domain: MATH-500, AIME, AMC23, Minerva
- Code: tally0818/SAGE
-
Outcome-Based Rewards Do Not Guarantee Faithful and Verifiable Reasoning
- Qinan Yu, Alexa Tartaglini, Peter Hase, Carlos Guestrin, Christopher Potts
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GSM8K, HotpotQA
-
Reward and Guidance through Rubrics: Promoting Exploration to Improve Multi-Domain Reasoning
- Baolong Bi, Shenghua Liu, Yiwei Wang, Siqian Tong, Lingrui Mei, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, GPQA, MMLU
-
Advantage Collapse in Group Relative Policy Optimization: Diagnosis and Mitigation
- Xixiang He, Qiyao Sun, Ao Cheng, Xingming Li, Xuanyu Ji, et al.
- Key: verifiable reward, policy optimization, reinforcement learning, rlvr, language model
- Data Domain: MATH, AIME
-
Golden Goose: A Simple Trick to Synthesize Unlimited RLVR Tasks from Unverifiable Internet Text
- Ximing Lu, David Acuna, Jaehun Jung, Jian Hu, Di Zhang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: GooseReason-0.7M, MATH
-
Shrinking the Variance: Shrinkage Baselines for Reinforcement Learning with Verifiable Rewards
- Guanning Zeng, Zhaoyi Zhou, Daman Arora, Andrea Zanette
- Key: verifiable reward, reinforcement learning, rlvr, reasoning, grpo
- Data Domain: MATH, AIME, GSM8K
-
Rubric Curriculum RL: Exploiting the Generation-Verification Gap in Creative Writing
- Tejas Krishnan, Sumeet Motwani, Charles London, Suhaas Bhat, Huitian Jiao, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reward model
- Data Domain: MATH
-
On the Learning Dynamics of RLVR at the Edge of Competence
- Yu Huang, Zixin Wen, Yuejie Chi, Yuting Wei, Aarti Singh, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reasoning
- Data Domain: MATH, GSM8K
-
BroRL: Scaling Reinforcement Learning via Broadened Exploration
- Jian Hu, Mingjie Liu, Ximing Lu, Fang Wu, Zaid Harchaoui, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, reasoning
- Data Domain: MATH, AIME, LiveCodeBench
-
Probing RLVR Training Instability through the Lens of Objective-Level Hacking
- Yiming Dong, Kun Fu, Haoyu Li, Xinyuan Zhu, Yurou Liu, et al.
- Key: verifiable reward, reinforcement learning, rlvr, language model, alignment
- Data Domain: MATH, AIME
-
Monitorability as a Free Gift: How RLVR Spontaneously Aligns Reasoning
- Zidi Xiong, Shan Chen, Himabindu Lakkaraju
- Key: verifiable reward, reinforcement learning, safety, rlvr, reasoning
- Data Domain: MATH, GSM8K
-
PretrainZero: Reinforcement Active Pretraining
- Xingrun Xing, Zhiyuan Fan, Jie Lou, Guoqi Li, Jiajun Zhang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, fine-tuning, reward model
- Data Domain: MATH, MMLU, MMLU-Pro
-
- Ruicheng Ao, David Simchi-Levi, Xinshang Wang
- Key: rlvr, llm, models, through, solver
- Data Domain: MDP-based OR benchmarks
-
- Speed Zhu, Chuheng Zhang, Jianwei Cai, Guang Chen, Lulu Wu, et al.
- Key: verifiable reward, reinforcement learning, rlvr, fine-tuning, reasoning
- Data Domain: CodeForces
-
Reward Modeling from Natural Language Human Feedback
- Zongqi Wang, Rui Wang, Yuchuan Wu, Yiyao Yu, Pinyi Zhang, et al.
- Key: verifiable reward, reinforcement learning, rlvr, reward model, reward modeling
- Data Domain: MT-Bench, AlpacaEval, RewardBench
2025
NeurIPS 2025
ICLR 2026
Click to expand / collapse
-
RLVER: Reinforcement Learning with Verifiable Emotion Rewards for Empathetic Agents
- Peisong Wang, Ruotian Ma, Bang Zhang, Xingyu Chen, Zhiwei He, et al.
- Key: Large language models, Reinforcement Learning, Agent
- Data Domain: Empathetic dialogue benchmarks
- Code: Tencent/DigitalHuman/RLVER
-
Rectifying LLM Thought from Lens of Optimization
- Junnan Liu, Hongwei Liu, Songyang Zhang, Kai Chen
- Key: Large Lanugae Model, Large Lanugae Model Reasoning, Reinforcement Learning with Verifiable Rewards
- Data Domain: MATH, AIME, GSM8K
-
EEPO: Exploration-Enhanced Policy Optimization via Sample-Then-Forget
- Liang Chen, Xueting Han, Qizhou Wang, Bo Han, Jing Bai, et al.
- Key: large language models, reasoning models, reinforcement learning, RLVR, exploration, unlearning
- Data Domain: MATH, AIME, GSM8K
- Code: ChanLiang/EEPO
-
HiPO: Self-Hint Policy Optimization for RLVR
- Deng Qiyuan, Kehai Chen, Min Zhang, Zhongwen Xu
- Key: Reinforcement Learning, Large Language Models, Mathematical Reasoning
- Data Domain: AIME, CMIMC, BRUMO
-
Sparse but Critical: A Token-Level Analysis of Distributional Shifts in RLVR Fine-Tuning of LLMs
- Haoming Meng, Kexin Huang, Shaohang Wei, Chiyu Ma, Shuo Yang, et al.
- Key: LLM Reasoning, RLVR
- Data Domain: MATH, GSM8K
-
Supervised Reinforcement Learning: From Expert Trajectories to Step-wise Reasoning
- Yihe Deng, I-Hung Hsu, Jun Yan, Zifeng Wang, Rujun Han, et al.
- Key: Reinforcement learning, Reasoning, Large Language Model, Agent
- Data Domain: MATH, AIME, GSM8K
-
RLBFF: Binary Flexible Feedback to bridge between Human Feedback & Verifiable Rewards
- Zhilin Wang, Jiaqi Zeng, Olivier Delalleau, Ellie Evans, Daniel Egert, et al.
- Key: reward modeling, model alignment, inference-time control, customization, LLM post-training
- Data Domain: MT-Bench, WildBench, RM-Bench
-
The Markovian Thinker: Architecture-Agnostic Linear Scaling of Reasoning
- Milad Aghajohari, Kamran Chitsaz, Amirhossein Kazemnejad, Sarath Chandar, Alessandro Sordoni, et al.
- Key: LLM Reasoning, RL for LLMs, Reasoning Models, Scalable Reasoning, Test-Time Scaling
- Data Domain: DeepScaleR
-
Generalization of RLVR Using Causal Reasoning as a Testbed
- Brian Lu, Hongyu Zhao, Shuo Sun, Hao Peng, Rui Ding, et al.
- Key: Large Language Models, Reinforcement Learning with Verifiable Rewards, Generalization, Causal Reasoning
- Data Domain: Causal reasoning benchmarks, MATH
-
Rubrics as Rewards: Reinforcement Learning Beyond Verifiable Domains
- Anisha Gunjal, Anthony Wang, Elaine Lau, Vaskar Nath, Yunzhong He, et al.
- Key: representation learning for language, datasets and benchmarks, reward modeling, reinforcement learning, natural langauge processing, large language models, reasoning, alignment
- Data Domain: MATH, GPQA, HealthBench, GPQA-Diamond
-
References Improve LLM Alignment in Non-Verifiable Domains
- Kejian Shi, Yixin Liu, PeiFeng Wang, Alexander Fabbri, Shafiq Joty, et al.
- Key: LLM Alignment; LLM-as-a-Judge; Alignment Evaluation; Preference Optimization
- Data Domain: AlpacaEval, Arena-Hard
-
Parameter-Efficient Reinforcement Learning using Prefix Optimization
- Itamar Rocha Filho, Rosie Zhao, Sham M. Kakade, Eran Malach, Samy Jelassi
- Key: reinforcement learning with verifiable rewards, parameter efficient tuning
- Data Domain: MATH
-
HARDTESTGEN: A High-Quality RL Verifier Generation Pipeline for LLM Algorithmic Coding
- Zhongmou He, Yee Man Choi, Kexun Zhang, Ivan Bercovich, Jiabao Ji, et al.
- Key: LLMs, RLVR, code generation
- Data Domain: LiveCodeBench, CodeForces
-
- Aleksander Boruch-Gruszecki, Yangtian Zi, Zixuan Wu, Tejas Oberoi, Carolyn Jane Anderson, et al.
- Key: large language models, program synthesis, code generation, reinforcement learning, low-resource programming languages
- Data Domain: MBPP, LiveCodeBench, CodeForces, MultiPL-E
-
- Zhiheng Xi, Xin Guo, Yang Nan, Enyu Zhou, Junrui Shen, et al.
- Key: RLVR, LLM Reasoning
- Data Domain: AIME
- Code: WooooDyy/BAPO
-
Learning to Reason as Action Abstractions with Scalable Mid-Training RL
- Shenao Zhang, Donghan Yu, Yihao Feng, Bowen Jin, Zhaoran Wang, et al.
- Key: reinforcement learning, large language model
- Data Domain: HumanEval, MBPP, LiveCodeBench, CodeForces
-
Diversity-Enhanced Reasoning for Subjective Questions
- Yumeng Wang, Zhiyuan Fan, Jiayu Liu, Jen-tse Huang, Yi R. Fung
- Key: LLM, subjective reasoning, diversity-enhanced training
- Data Domain: MATH, AIME
-
PROS: Towards Compute-Efficient RLVR via Rollout Prefix Reuse
- Baizhou Huang, Xiaojun Wan
- Key: RLVR, reasoning
- Data Domain: MATH, GSM8K
-
LongRLVR: Long-Context Reinforcement Learning Requires Verifiable Context Rewards
- Guanzheng Chen, Michael Qizhe Shieh, Lidong Bing
- Key: Large Language Models, Long Context, Reinforcement Learning with Verifiable Rewards
- Data Domain: RULER-QA, LongBench
- Code: real-absolute-AI/LongRLVR
-
Selective Expert Guidance for Effective and Diverse Exploration in Reinforcement Learning of LLMs
- Zishang Jiang, Jinyi Han, tingyun li, Xinyi Wang, Sihang Jiang, et al.
- Key: Large Language Models, Group Relative Policy Optimization
- Data Domain: MATH, AIME, GSM8K
-
- Shangyu Xing, Siyuan Wang, Chenyuan Yang, Xinyu Dai, Xiang Ren
- Key: RLVR, GRPO, rollout, LLM, reasoning
- Data Domain: MATH, AIME, GSM8K
-
Controllable Exploration in Hybrid-Policy RLVR for Multi-Modal Reasoning
- Zhuoxu Huang, Mengxi Jia, Hao Sun, Xuelong Li, Jungong Han
- Key: Multi-Modal Reasoning, Reinforcement Learning from Verifiable Rewards
- Data Domain: MathVerse, MathVision, MMMU
-
Group Verification-based Policy Optimization for Interactive Coding Agents
- Silong Dai, Changzhi Sun, Haolun Wu, Huanran Zheng, Tao Ji, et al.
- Key: Large language model, Tool Learning, Reinforcement Learning
- Data Domain: AppWorld
-
Beyond Magnitude: Leveraging Direction of RLVR Updates for LLM Reasoning
- Kexin Huang, Haoming Meng, Junkang Wu, Jinda Lu, Chiyu Ma, et al.
- Key: RLVR, LLM reasoning
- Data Domain: MATH, AIME, DeepScaleR
-
Curriculum Reinforcement Learning from Easy to Hard Tasks Improves LLM Reasoning
- Shubham Parashar, Shurui Gui, Xiner Li, Hongyi Ling, Sushil Vemuri, et al.
- Key: LLM, Reinforcement Learning, Post Training
- Data Domain: MATH, AIME, GSM8K
-
ReVeal: Self-Evolving Code Agents via Reliable Self-Verification
- Yiyang Jin, Kunzhao Xu, Hang Li, Xueting Han, Yanmin Zhou, et al.
- Key: Large Language Model, Reinforcement Learning, Code LLM, multi-turn RL
- Data Domain: LiveCodeBench
-
Process-Verified Reinforcement Learning for Theorem Proving via Lean
- Minsu Kim, Se-Young Yun
- Key: Formal Reasoning, Large Language Models, Theorem Proving with LLMs, Lean4
- Data Domain: MiniF2F, ProofNet
-
RL Squeezes, SFT Expands: A Comparative Study of Reasoning LLMs
- Kohsei Matsutani, Shota Takashiro, Gouki Minegishi, Takeshi Kojima, Yusuke Iwasawa, et al.
- Key: LLMs, Reasoning, RLVR, Interpretability
- Data Domain: MATH, AIME, GSM8K
-
- Xingwu Chen, Tianle Li, Difan Zou
- Key: Reinforcement Learning, Language Models, Reasoning Patterns, Training Dynamics
- Data Domain: MATH, GSM8K
-
Evaluating and Improving Cultural Awareness of Reward Models for LLM Alignment
- Hongbin Zhang, Kehai Chen, Xuefeng Bai, Yang Xiang, Min Zhang
- Key: cultural awareness, reward model, LLM Alignment, RLHF, RL, Dataset, Benchmark, Multilingual Evaluation
- Data Domain: CARB, GlobalOpinionQA
-
Breaking Barriers: Do Reinforcement Post Training Gains Transfer To Unseen Domains?
- Chuxuan Hu, Yuxuan Zhu, Antony Kellermann, Caleb Biddulph, Suppakit Waiwitlikhit, et al.
- Key: large language models, reinforcement learning, supervised fine-tuning, generalizability
- Data Domain: MATH, GSM8K, MMLU
-
Tina: Tiny Reasoning Models via LoRA
- Shangshang Wang, Julian Asilis, Ömer Faruk Akgül, Enes Burak Bilgin, Ollie Liu, et al.
- Key: Reasoning models, efficient reasoning, LoRA, RLVR
- Data Domain: AIME24
-
Learning to Reason without External Rewards
- Xuandong Zhao, Zhewei Kang, Aosong Feng, Sergey Levine, Dawn Song
- Key: RL, Reasoning, LLM
- Data Domain: MATH, GSM8K
- Code: sunblaze-ucb/Intuitor
-
$ extbf{Re}^{2}$: Unlocking LLM Reasoning via Reinforcement Learning with Re-solving
- Pinzheng Wang, ShuliXu, Juntao Li, Yu Luo, Dong Li, et al.
- Key: LLM Reasoning, Reinforcement learning, Re-solving Mechanism, Test-time Scaling
- Data Domain: MATH, AIME, GSM8K
-
Co-rewarding: Stable Self-supervised RL for Eliciting Reasoning in Large Language Models
- Zizhuo Zhang, Jianing Zhu, Xinmu Ge, Zihua Zhao, Zhanke Zhou, et al.
- Key: Large language model reasoning, self-supervised RL
- Data Domain: GSM8K
-
MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent
- Hongli Yu, Tinghong Chen, Jiangtao Feng, Jiangjie Chen, Weinan Dai, et al.
- Key: LLM, memory, agent, RLVR
- Data Domain: ViCrit-Bench, visual reasoning benchmarks
-
Diversity-Incentivized Exploration for Versatile Reasoning
- Zican Hu, Shilin Zhang, Yafu Li, Jianhao Yan, Xuyang Hu, et al.
- Key: LLM reasoning, Reinforcement learning with verifiable rewards, efficient exploration, diversity
- Data Domain: MATH, AIME, GSM8K
-
- Zijun Gao, Zhikun Xu, Xiao Ye, Ben Zhou
- Key: large language models, mathematical reasoning, conceptual understanding, fine-tuning, robustness
- Data Domain: MATH
-
Random Policy Valuation is Enough for LLM Reasoning with Verifiable Rewards
- Haoran He, Yuxiao Ye, Qingpeng Cai, Chen Hu, Binxing Jiao, et al.
- Key: Large Language Models (LLMs), Reinforcement Learning, RLVR, Math Reasoning, Diversity
- Data Domain: MATH, Markov Decision Process
-
ExGRPO: Learning to Reason from Experience
- Runzhe Zhan, Yafu Li, Zhi Wang, Xiaoye Qu, Dongrui Liu, et al.
- Key: Reinforcement Learning, Large Reasoning Model, Reinforcement Learning with Verifiable Rewards
- Data Domain: MATH, AIME, GSM8K
- Code: ElliottYan/LUFFY
-
MATH-Beyond: A Benchmark for RL to Expand Beyond the Base Model
- Prasanna Mayilvahanan, Ricardo Olmedo, Thaddäus Wiedemer, Wieland Brendel
- Key: RLVR, RL, Reasoning, Math, LLM Evaluation
- Data Domain: MATH, AIME, DeepScaleR, DAPO-Math, MATH-B
-
CDE: Curiosity-Driven Exploration for Efficient Reinforcement Learning in Large Language Models
- Runpeng Dai, Linfeng Song, Haolin Liu, Zhenwen Liang, Dian Yu, et al.
- Key: Large language models, Reasoning, Exploration
- Data Domain: AIME
-
LaSeR: Reinforcement Learning with Last-Token Self-Rewarding
- Wenkai Yang, Weijie Liu, Ruobing Xie, Yiju Guo, Lulu Wu, et al.
- Key: Reinforcement Learning, LLM Reasoning, Self-Rewarding
- Data Domain: MATH, GSM8K
- Code: RUCBM/LaSeR
-
Learn More with Less: Uncertainty Consistency Guided Query Selection for RLVR
- Hao Yi, Yulan Hu, Xin Li, Sheng Ouyang, Lizhong Ding, et al.
- Key: Reinforcement learning; Large Language Model; Active Learning; Reasoning
- Data Domain: MATH, GSM8K
-
- Xumeng Wen, Zihan Liu, Shun Zheng, Shengyu Ye, Zhirong Wu, et al.
- Key: large language models, reasoning, reinforcement learning
- Data Domain: MATH, GSM8K
-
Spotlight on Token Perception for Multimodal Reinforcement Learning
- Siyuan Huang, Xiaoye Qu, Yafu Li, Yun Luo, Zefeng He, et al.
- Key: Multimodal Reasoning, LVLM, Reinforcement Learning
- Data Domain: MathVerse, DynaMath, Geo3k, MathVision, MMK12, We-Math, LogicVista, MMMU-Pro
-
SPECS: Decoupling Multimodal Learning via Self-distilled Preference-based Cold Start
- Kun Chen, Peng Shi, Haibo Qiu, Zhixiong Zeng, Siqi Yang, et al.
- Key: Vision Language Models, Reinforcement Learning, Reasoning, Cold-Start, Preference Optimization, Direct Preference Optimization (DPO), Self-Distillation
- Data Domain: MathVista, MEGA-Bench
-
Quagmires in SFT-RL Post-Training: When High SFT Scores Mislead and What to Use Instead
- Feiyang Kang, Michael Kuchnik, Karthik Padthe, Marin Vlastelica, Ruoxi Jia, et al.
- Key: Post-Training, Large Reasoning Models, Large Language Models, Performance Prediction, Reinforcement Learning with Verifiable Rewards
- Data Domain: MATH
-
- Fang Wu, Weihao Xuan, Heli Qi, Aaron Tu, Ximing Lu, et al.
- Key: MCTS, RLVR
- Data Domain: LiveCodeBench, AIME24
- Code: smiles724/DeepSearch
-
- Thanh-Long V. Le, Myeongho Jeon, Kim Vu, Viet Dac Lai, Eunho Yang
- Key: large language models, reinforcement learning with verifiable rewards, llm reasoning
- Data Domain: MATH
-
R-Horizon: How Far Can Your Large Reasoning Model Really Go in Breadth and Depth?
- Yi Lu, Jianing Wang, Linsen Guo, Wei He, Hongyin Tang, et al.
- Key: Large Reasoning Models, Long Horizon Reasoning
- Data Domain: R-HORIZON, AIME2024
- Code: meituan-longcat/R-HORIZON
-
DuPO: Enabling Reliable Self-Verification via Dual Preference Optimization
- Shuaijie She, Yu Bao, Yu Lu, Lu Xu, Tao Li, et al.
- Key: Self-Verification, Dual Learning, Preference Optimization, Large Language Model
- Data Domain: MATH, GSM8K, AIME
-
FAPO: Flawed-Aware Policy Optimization for Efficient and Reliable Reasoning
- Yuyang Ding, Chi Zhang, Juntao Li, Haibin Lin, Xin Liu, et al.
- Key: LLM Reasoning, Reinforcement Learning, Robust Learning
- Data Domain: MATH, AIME
- Code: volcengine/verl/recipe/fapo
-
Conditional Advantage Estimation for Reinforcement Learning in Large Reasoning Models
- Guanxu Chen, Yafu Li, Yuxian Jiang, Chen Qian, Qihan Ren, et al.
- Key: language models, reinforcement learning
- Data Domain: MATH
-
Quantile Advantage Estimation: Stabilizing RLVR for LLM Reasoning
- Junkang Wu, Kexin Huang, Jiancan Wu, An Zhang, Xiang Wang, et al.
- Key: RLVR, LLM reasoning, entropy explosion, advantage estimation
- Data Domain: AIME, AMC, MATH
-
Agentic Reinforced Policy Optimization
- Guanting Dong, Hangyu Mao, Kai Ma, Licheng Bao, Yifei Chen, et al.
- Key: Agentic Reinforcement Learning, Large Language Model, Agentic Reasoning, Tool-use Alignment
- Data Domain: GAIA, HLE, agent benchmarks
- Code: RUC-NLPIR/ARPO
-
Beyond Pass@ 1: Self-Play with Variational Problem Synthesis Sustains RLVR
- Xiao Liang, Zhong-Zhi Li, Yeyun Gong, yelong shen, Ying Nian Wu, et al.
- Key: LLM Reasoning; Reinforcement Learning; Self-envolving
- Data Domain: MATH, LiveCodeBench
- Code: MasterVito/SvS
-
AnesSuite: A Comprehensive Benchmark and Dataset Suite for Anesthesiology Reasoning in LLMs
- Xiang Feng, Wentao Jiang, Zengmao Wang, Yong Luo, Pingbo Xu, et al.
- Key: Large language model, Reasoning, Anesthesiology, Medicine
- Data Domain: AnesSuite, medical QA benchmarks
-
Native Reasoning Models: Training Language Models to Reason on Unverifiable Data
- Yuanfu Wang, Zhixuan Liu, Li xiangtian, Chaochao Lu, Chao Yang
- Key: LLM, Reinforcement Learning
- Data Domain: MATH, GSM8K
-
- Long Li, Zhijian Zhou, JIARAN HAO, Jason Klein Liu, Yanting Miao, et al.
- Key: Large Language Model, Reinforcement Learning with Verifiable Reward, f divergence
- Data Domain: MATH
-
Overthinking Reduction with Decoupled Rewards and Curriculum Data Scheduling
- Shuyang Jiang, Yusheng Liao, Ya Zhang, Yanfeng Wang, Yu Wang
- Key: efficient reasoning; curriculum sampling with decoupled reward
- Data Domain: MATH, AIME, GSM8K
-
- Yanqi Dai, Yuxiang Ji, Xiao Zhang, Yong Wang, Xiangxiang Chu, et al.
- Key: Mathematical Reasoning, Group Relative Policy Optimization, Question Reformulation
- Data Domain: MATH, AIME
-
Perception-R1: Advancing Multimodal Reasoning Capabilities of MLLMs via Visual Perception Reward
- Tong Xiao, Xin Xu, Zhenya Huang, Hongyu Gao, Quan Liu, et al.
- Key: Multimodal Large Language Models, Multimodal Reasoning, Reinforcement Learning
- Data Domain: MATH
-
- Xu Wan, Yansheng Wang, Wenqi Huang, Mingyang Sun
- Key: LLM post-training; off-policy RLVR
- Data Domain: MathVerse, MathVision, MMMU
-
QuRL: Low-Precision Reinforcement Learning for Efficient Reasoning
- Yuhang Li, Reena Elangovan, Xin Dong, Priyadarshini Panda, Brucek Khailany
- Key: Reinforcement Learning, Quantization
- Data Domain: DeepScaleR
-
Towards High Data Efficiency in Reinforcement Learning with Verifiable Reward
- Xinyu Tang, Zhenduo Zhang, Yurou Liu, Xin Zhao, zujie wen, et al.
- Key: Data Efficiency, Reinforcement Learning with Verifiable Reward
- Data Domain: AIME24, AIME25
-
Perception-Aware Policy Optimization for Multimodal Reasoning
- Zhenhailong Wang, Xuehang Guo, Sofia Stoica, Haiyang Xu, Hongru WANG, et al.
- Key: multimodal reasoning, reinforcement learning, policy optimization, large language models, visual perception, GRPO, DAPO
- Data Domain: MathVerse, MathVision, MMMU-Pro
-
Sample Lottery: Unsupervised Discovery of Critical Instances for LLM Reasoning
- Zhiping Xiao, Yusheng Zhao, Qixin Zhang, Jiaye Xie, Wanjia Zhao, et al.
- Key: Large Language Model, Reinforcement Learning with Verifiable Reward
- Data Domain: MATH, GSM8K
-
Scheduling Your LLM Reinforcement Learning with Reasoning Trees
- Hong Wang, Zhezheng Hao, Jian Luo, Chenxing Wei, Yao Shu, et al.
- Key: large language model, RLVR, Data Scheduling
- Data Domain: MATH
-
Risk-Sensitive Reinforcement Learning for Alleviating Exploration Dilemmas in Large Language Models
- Yuhua Jiang, Jiawei Huang, Yufeng Yuan, Xin Mao, YuYue, et al.
- Key: RLVR, Large Language Model, Reinforcement Learning, Pass@k Optimization
- Data Domain: MATH, AIME
-
QuRL: Rubrics As Judge For Open-Ended Question Answering
- Xiyu Wei, Qingwei Zong, Xiaoguang Li, Eugene J. Yu, Sujian Li
- Key: rubrics, reinforcement-learning, open-ended qa, large language model, generation
- Data Domain: MT-Bench, AlpacaEval, open-ended QA benchmarks
-
Learning What Reinforcement Learning Can't: Interleaved Online Fine-Tuning for Hardest Questions
- Lu Ma, Hao Liang, Meiyi Qiang, Lexiang Tang, Xiaochen Ma, et al.
- Key: Large Language Models; Reasoning; Reinforcement Learning; Supervised Fine-Tuning
- Data Domain: MATH
-
- Xin Xu, Clive Bai, Kai Yang, Tianhao Chen, Yang Wang, et al.
- Key: Large Language Models, Reasoning, Reinforcement Learning with Verifiable Rewards, Long Chain-of-Thought
- Data Domain: LiveCodeBench, AIME24
-
Exploration vs Exploitation: Rethinking RLVR through Clipping, Entropy, and Spurious Reward
- Peter Chen, Xiaopeng Li, Ziniu Li, Wotao Yin, Xi Chen, et al.
- Key: Reinforcement Learning with Verifiable Rewards, Group Relative Policy Optimization, LLM Reasoning
- Data Domain: MATH, GSM8K
-
How Far Can Unsupervised RLVR Scale LLM Training?
- Bingxiang He, Yuxin Zuo, Zeyuan Liu, Shangziqi Zhao, Zixuan Fu, et al.
- Key: Large Language Models, Unsupervised Reward, Reinforcement Learning, Reasoning
- Data Domain: MATH, GSM8K, AIME
-
TraPO: A Semi-Supervised Reinforcement Learning Framework for Boosting LLM Reasoning
- Shenzhi Yang, Guangcheng Zhu, Haobo Wang, Xing Zheng, Yingfan MA, et al.
- Key: Reinforcement Learning with Verifiable Rewards, Semi-supervised Learning, Large Language Model
- Data Domain: MATH, AIME
-
Search Self-Play: Pushing the Frontier of Agent Capability without Supervision
- Hongliang Lu, Yuhang Wen, Pengyu Cheng, Ruijin Ding, Jiaqi Guo, et al.
- Key: Self-Play, Deep Search, LLM, Agent, RLVR
- Data Domain: WebShop, HotpotQA, agent benchmarks
- Code: Qwen-Applications/SSP
-
- Bo Liu, Simon Yu, Zichen Liu, Leon Guertler, Penghui Qi, et al.
- Key: Reinforcement Learning, Self-Play, Large Language Models, Reasoning, Multi-Agent Reinforcement Learning
- Data Domain: Game-based reasoning benchmarks
- Code: spiral-rl/spiral
-
- Yuxin Jiang, Yufei Wang, Qiyuan Zhang, Xingshan Zeng, Liangyou Li, et al.
- Key: reinforcement learning, verifiable reference-based rewards, open-ended generation
- Data Domain: MATH
-
A Simple "Motivation" Can Enhance Reinforcement Finetuning of Large Reasoning Models
- Junjie Zhang, Guozheng Ma, Shunyu Liu, Haoyu Wang, Jiaxing Huang, et al.
- Key: Reinforcement Finetuning, Large Language Models
- Data Domain: MATH, GSM8K
Click to expand / collapse
-
ViCrit: A Verifiable Reinforcement Learning Proxy Task for Visual Perception in VLMs
- Xiyao Wang, Zhengyuan Yang, Chao Feng, Yuhang Zhou, Xiaoyu Liu, Yongyuan Liang, Ming Li, Ziyi Zang, Linjie Li, Chung-Ching Lin, Kevin Lin, Furong Huang, Lijuan Wang
- Key: Visual reasoning, Vision-Language Model, Visual captioning, Reward Model, Visual Hallucination, fine-grained hallucination criticism as RL objective
- Data Domain: ViCrit-Bench, natural-image reasoning, abstract image reasoning, visual math
-
Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model?
- Yang Yue, Zhiqi Chen, Rui Lu, Andrew Zhao, Zhaokai Wang, Yang Yue, Shiji Song, Gao Huang
- Key: RLVR capability boundaries, pass@k analysis, base model vs RLVR-trained models, reasoning pattern emergence, distillation vs RL
- Data Domain: Math/coding/visual reasoning benchmarks, multiple model families and RL algorithms
-
Absolute Zero: Reinforced Self-play Reasoning with Zero Data
- Andrew Zhao, Yiran Wu, Yang Yue, Tong Wu, Quentin Xu, Yang Yue, Matthieu Lin, Shenzhi Wang, Qingyun Wu, Zilong Zheng, Gao Huang
- Key: Self-play reasoning, zero external data, self-proposed tasks, curriculum learning, code executor as unified feedback
- Data Domain: Coding and mathematical reasoning tasks, cross-model-scale experiments
-
CURE: Co-Evolving Coders and Unit Testers via Reinforcement Learning
- Yinjie Wang, Ling Yang, Ye Tian, Ke Shen, Mengdi Wang
- Key: Co-evolution of code generation and unit test generation, interaction-based rewards without ground-truth code, test-time scaling, agentic unit test generation
- Data Domain: SWE-bench Verified, unit test generation benchmarks, 4B model achieving 64.8% inference efficiency
-
Enigmata: Scaling Logical Reasoning in Large Language Models with Synthetic Verifiable Puzzles
- Jiangjie Chen, Qianyu He, Siyu Yuan, Aili Chen, Zhicheng Cai, Weinan Dai, Hongli Yu, Jiaze Chen, Xuefeng Li, Qiying Yu, Hao Zhou, Mingxuan Wang
- Key: Puzzle reasoning, generator-verifier design, 36 tasks across 7 categories, multi-task RLVR, 418K competition-level problems
- Data Domain: ENIGMATA-Eval, ARC-AGI (32.8%), ARC-AGI 2 (0.6%), AIME (2024-2025), BeyondAIME, GPQA (Diamond)
-
To Think or Not To Think: A Study of Thinking in Rule-Based Visual Reinforcement Fine-Tuning
- Ming Li, Jike Zhong, Shitian Zhao, Yuxiang Lai, Haoquan Zhang, Wang Bill Zhu, Kaipeng Zhang
- Key: Thinking vs No-Thinking RFT, visual perception tasks, overthinking in MLLMs, equality accuracy reward, Adaptive-Thinking method
- Data Domain: Six diverse visual tasks across different model sizes and types, image classification benchmarks
-
Trust, But Verify: A Self-Verification Approach to Reinforcement Learning with Verifiable Rewards
- Xiaoyuan Liu, Tian Liang, Zhiwei He, Jiahao Xu, Wenxuan Wang, Pinjia He, Zhaopeng Tu, Haitao Mi, Dong Yu
- Key: Self-verification in RLVR, RISE framework, simultaneous training of problem-solving and self-verification, online RL for both tasks
- Data Domain: Mathematical reasoning benchmarks, verification compute analysis
-
Beyond Verifiable Rewards: Scaling Reinforcement Learning in Language Models to Unverifiable Data
- Yunhao Tang, Sid Wang, Lovish Madaan, Remi Munos
- Key: JEPO algorithm, Jensen's evidence lower bound, unverifiable data, chain-of-thought as latent variable, extending RLVR to semi-verifiable data
- Data Domain: Math (verifiable), numina and numina-proof (semi-verifiable/unverifiable), test set likelihood evaluation
-
RLVR-World: Training World Models with Reinforcement Learning
- Jialong Wu, Shaofeng Yin, Ningya Feng, Mingsheng Long
- Key: World models with RLVR, task-specific optimization beyond MLE, transition prediction metrics as rewards, autoregressive tokenized sequences
- Data Domain: Text games, web navigation, robot manipulation, language-based and video-based world models
-
SeRL: Self-play Reinforcement Learning for Large Language Models with Limited Data
- Wenkai Fang, Shunyu Liu, Yang Zhou, Kongcheng Zhang, Tongya Zheng, Kaixuan Chen, Mingli Song, Dacheng Tao
- Key: Self-instruction generation, self-rewarding via majority-voting, bootstrapping with limited initial data, online filtering strategies
- Data Domain: Various reasoning benchmarks across different LLM backbones
-
Learning to Reason under Off-Policy Guidance
- Jianhao Yan, Yafu Li, Zican Hu, Zhi Wang, Ganqu Cui, Xiaoye Qu, Yu Cheng, Yue Zhang
- Key: LUFFY framework, off-policy reasoning traces, Mixed-Policy GRPO, policy shaping via regularized importance sampling, learning beyond initial capabilities
- Data Domain: Six math benchmarks, out-of-distribution tasks, weak model training scenarios
-
SWE-RL: Advancing LLM Reasoning via Reinforcement Learning on Open Software Evolution
- Yuxiang Wei, Olivier Duchenne, Jade Copet, Quentin Carbonneaux, Lingming Zhang, Daniel Fried, Gabriel Synnaeve, Rishabh Singh, Sida Wang
- Key: Software engineering with RL, lightweight rule-based reward, open-source software evolution data, Llama3-SWE-RL-70B achieving 41.0% on SWE-bench Verified
- Data Domain: SWE-bench Verified, function coding, library use, code reasoning, mathematics, general language understanding
-
rStar-Coder: Scaling Competitive Code Reasoning with a Large-Scale Verified Dataset
- Yifei Liu, Li Lyna Zhang, Yi Zhu, Bingcheng Dong, Xudong Zhou, Ning Shang, Fan Yang, Cheng Li, Mao Yang
- Key: 418K competition-level code problems, 580K long-reasoning solutions, input-output test case synthesis pipeline, mutual verification mechanism
- Data Domain: LiveCodeBench (57.3% for 7B), USA Computing Olympiad (16.15% avg for 7B, outperforming QWQ-32B)
-
SynLogic: Synthesizing Verifiable Reasoning Data at Scale for Learning Logical Reasoning and Beyond
- Junteng Liu, Yuanxiang Fan, Jiang Zhuo, Han Ding, Yongyi Hu, Chi Zhang, Yiqi Shi, Shitong Weng, Aili Chen, Shiqi Chen, Mozhi Zhang, Pengyu Zhao, Junxian He
- Key: Logical reasoning as foundation for general reasoning, 35 diverse logical reasoning tasks, controlled synthesis with adjustable difficulty, mixing with math/coding tasks
- Data Domain: BBEH (outperforming DeepSeek-R1-Distill-Qwen-32B by 6 points), state-of-the-art logical reasoning performance
-
SwS: Self-aware Weakness-driven Problem Synthesis in Reinforcement Learning for LLM Reasoning
- Xiao Liang, Zhong-Zhi Li, Yeyun Gong, Yang Wang, Hengyuan Zhang, Yelong Shen, Ying Nian Wu, Weizhu Chen
- Key: Self-aware weakness identification, problem synthesis targeting model deficiencies, core concept extraction from failure cases, weakness-driven augmentation
- Data Domain: Eight mainstream reasoning benchmarks, 10% gain on 7B models, 7.7% gain on 32B models
-
AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning
- Yang Chen, Zhuolin Yang, Zihan Liu, Chankyu Lee, Peng Xu, Mohammad Shoeybi, Bryan Catanzaro, Wei Ping
- Key: Math-only then code-only RL training sequence, curriculum learning with progressive response lengths, robust data curation for challenging prompts, on-policy parameter updates
- Data Domain: AIME 2025 (+14.6%/+17.2% for 7B/14B), LiveCodeBench (+6.8%/+5.8% for 7B/14B)
-
Agentic RL Scaling Law: Spontaneous Code Execution for Mathematical Problem Solving
- Xinji Mai, Haotian Xu, Xing W, Weinong Wang, Yingying Zhang, Wenqiang Zhang
- Key: ZeroTIR (Tool-Integrated Reasoning), spontaneous code execution without supervised tool-use examples, RL scaling laws for tool use, predictable metrics scaling
- Data Domain: Math benchmarks, standard RL algorithms comparison
-
Rethinking Verification for LLM Code Generation: From Generation to Testing
- Zihan Ma, Taolin Zhang, Maosongcao, Junnan Liu, Wenwei Zhang, Minnan Luo, Songyang Zhang, Kai Chen
- Key: Test-case generation (TCG) task, multi-dimensional thoroughness metrics, human-LLM collaborative method (SAGA), TCGBench benchmark
- Data Domain: TCGBench (90.62% detection rate), LiveCodeBench-v6 (10.78% higher Verifier Acc), test suite quality evaluation
-
ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models
- Mingjie Liu, Shizhe Diao, Ximing Lu, Jian Hu, Xin Dong, Yejin Choi, Jan Kautz, Yi Dong
- Key: Prolonged RL training, KL divergence control, reference policy resetting, diverse task suite, novel reasoning strategies inaccessible to base models
- Data Domain: Wide range of pass@k evaluations, base model competence vs training duration analysis
-
Scaling Code-Assisted Chain-of-Thoughts and Instructions for Model Reasoning
- Honglin Lin, Qizhi Pei, Zhuoshi Pan, Yu Li, Xin Gao, Juntao Li, Conghui He, Lijun Wu
- Key: Caco framework, code-assisted CoT, automated validation via code execution, reverse-engineering to natural language instructions, Caco-1.3M dataset
- Data Domain: Mathematical reasoning benchmarks, code-anchored verification, instruction diversity analysis
-
The Surprising Effectiveness of Negative Reinforcement in LLM Reasoning
- Xinyu Zhu, Mengzhou Xia, Zhepei Wei, Wei-Lin Chen, Danqi Chen, Yu Meng
- Key: Negative Sample Reinforcement (NSR), training with only negative samples, Pass@k across entire spectrum, gradient analysis, upweighting NSR
- Data Domain: MATH, AIME 2025, AMC23, Qwen2.5-Math-7B, Qwen3-4B, Llama-3.1-8B-Instruct
-
Solver-Informed RL: Grounding Large Language Models for Authentic Optimization Modeling
- Yitian Chen, Jingfan Xia, Siyu Shao, Dongdong Ge, Yinyu Ye
- Key: Optimization problem formulation, Solver-Informed RL (SIRL), executable code and .lp file assessment, instance-level mathematical model verification, instance-enhanced self-consistency
- Data Domain: Diverse public optimization benchmarks, surpassing DeepSeek-V3 and OpenAI-o3
-
ATLAS: Autoformalizing Theorems through Lifting, Augmentation, and Synthesis of Data
- Xiaoyang Liu, Kangjie Bao, Jiashuo Zhang, Yunqi Liu, Yu Chen, Yuntian Liu, Yang Jiao, Tao Luo
- Key: Autoformalization, Lean 4, expert iteration with knowledge distillation, structural augmentation strategies, 117k undergraduate-level theorem statements
- Data Domain: All benchmarks (p<0.05, two-sided t-test), outperforming Herald Translator and Kimina-Autoformalizer
-
QiMeng-CodeV-R1: Reasoning-Enhanced Verilog Generation
- Yaoyu Zhu, Di Huang, Hanqi Lyu, Xiaoyun Zhang, Chongxiao Li, Wenxuan Shi, Yutong Wu, Jianan Mu, Jinghua Wang, Yang zhao, Pengwei Jin, Shuyao Cheng, Shengwen Liang, Xishan Zhang, Rui Zhang, Zidong Du, Qi Guo, Xing Hu, Yunji Chen
- Key: Verilog generation with RLVR, rule-based testbench generator, round-trip data synthesis, distill-then-RL pipeline, adaptive DAPO algorithm
- Data Domain: VerilogEval v2 (68.6% pass@1), RTLLM v1.1 (72.9% pass@1), surpassing 671B DeepSeek-R1 on RTLLM
-
QiMeng-SALV: Signal-Aware Learning for Verilog Code Generation
- Yang Zhang, Rui Zhang, Jiaming Guo, Huang Lei, Di Huang, Yunpu Zhao, Shuyao Cheng, Pengwei Jin, Chongxiao Li, Zidong Du, Xing Hu, Qi Guo, Yunji Chen
- Key: Signal-level optimization, verified signal-aware implementations extraction, Abstract Syntax Tree (AST) for code segments, signal-aware DPO
- Data Domain: VerilogEval, RTLLM, 7B matching DeepSeek v3 671B performance
-
miniF2F-Lean Revisited: Reviewing Limitations and Charting a Path Forward
- Azim Ospanov, Farzan Farnia, Roozbeh Yousefzadeh
- Key: Formal reasoning, automated theorem proving, Lean prover, miniF2F benchmark analysis, discrepancy correction, miniF2F-v2 with verified statements
- Data Domain: miniF2F original vs miniF2F-v2, full theorem proving pipeline evaluation (70% on v2 vs 40% on original)
-
SWE-SQL: Illuminating LLM Pathways to Solve User SQL Issues in Real-World Applications
- Jinyang Li, Xiaolong Li, Ge Qu, Per Jacobsson, Bowen Qin, Binyuan Hui, Shuzheng Si, Nan Huo, Xiaohan Xu, Yue Zhang, Ziwei Tang, Yuanshuai Li, Florensia Widjaja, Xintong Zhu, Feige Zhou, Yongfeng Huang, Yannis Papakonstantinou, Fatma Ozcan, Chenhao Ma, Reynold Cheng
- Key: SQL issue debugging, BIRD-CRITIC benchmark (530 PostgreSQL + 570 multi-dialect tasks), SQL-Rewind strategy, f-Plan Boosting, BIRD-Fixer agent
- Data Domain: BIRD-CRITIC-PG (38.11% for 14B), BIRD-CRITIC-Multi (29.65% for 14B), surpassing Claude-3.7-Sonnet and GPT-4.1
ICML 2025
Click to expand / collapse
-
SFT Memorizes, RL Generalizes: A Comparative Study of Foundation Model Post-training
- Tianzhe Chu, Yuexiang Zhai, Jihan Yang, Shengbang Tong, Saining Xie, Dale Schuurmans, Quoc V. Le, Sergey Levine, Yi Ma
- Key: Reinforcement Learning, Supervised Fine-tuning, Generalization, Memorization
- Data Domain: GeneralPoints, V-IRL
-
VinePPO: Refining Credit Assignment in RL Training of LLMs
- Amirhossein Kazemnejad, Milad Aghajohari, Eva Portelance, Alessandro Sordoni, Siva Reddy, Aaron Courville, Nicolas Le Roux
- Key: reinforcement learning, large language models, credit assignment, PPO, Monte Carlo estimation
- Data Domain: MATH, GSM8K
-
Controlling Large Language Model with Latent Action
- Chengxing Jia, Ziniu Li, Pengyuan Wang, Yi-Chen Li, Zhenyu Hou, Yuxiao Dong, Yang Yu
- Key: reinforcement learning, latent action space, controllable language models, inverse dynamics, policy learning
- Data Domain: math500, Countdown Game, Alfworld, Scienceworld
-
Emergent Misalignment: Narrow Finetuning Can Produce Broadly Misaligned LLMs
- Jan Betley, Daniel Tan, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Nathan Labenz, Owain Evans
- Key: emergent misalignment, insecure code, deceptive behavior, alignment, dataset intent, finetuning impact
- Data Domain: GPT-4o, Qwen2.5-32B-Instruct, Mistral-Small-2409, HumanEval, TruthfulQA, StrongREJECT, Machiavelli
-
Reasoning Through Execution: Unifying Process and Outcome Rewards for Code Generation
- Zhuohao Yu, Weizheng Gu, Yidong Wang, Xingru Jiang, Zhengran Zeng, Jindong Wang, Wei Ye, Shikun Zhang
- Key: code generation, process supervision, outcome supervision, reasoning, execution verification
- Data Domain: HumanEval, MBPP, LBPP
-
Demystifying Long Chain-of-Thought Reasoning
- Shiming Yang, Yuxuan Tong, Xinyao Niu, Graham Neubig, Xiang Yue
- Key: long chain-of-thought, reinforcement learning, supervised fine-tuning, reward shaping, verifiable rewards
- Data Domain: MATH-500, AIME 2024, TheoremQA, MMLU-Pro-1k
-
- Ruida Wang, Rui Pan, Yuxin Li, Jipeng Zhang, Yizhen Jia, Shizhe Diao, Renjie Pi, Junjie Hu, Tong Zhang
- Key: theorem proving, formal verification, Lean4, large language models, model collaboration, chain-of-thought
- Data Domain: MiniF2F-Test
-
SHIELDAGENT: Shielding Agents via Verifiable Safety Policy Reasoning
- Zhaorun Chen, Mintong Kang, Bo Li
- Key: LLM agents, safety policy, guardrails, probabilistic reasoning, policy verification
- Data Domain: SHIELDAGENT-BENCH (6 web environments), ST-WebAgentBench, VWA-Adv, AgentHarm
-
TOPLOC: A Locality Sensitive Hashing Scheme for Trustless Verifiable Inference
- Jack Min Ong, Matthew Di Ferrante, Aaron Pazdera, Ryan Garner, Sami Jaghouar, Manveer Basra, Max Ryabinin, Johannes Hagemann
- Key: verifiable inference, locality-sensitive hashing, polynomial encoding, trustless AI, LLM verification
- Data Domain: Llama 3.1-8B-Instruct, Intellect-1-Instruct, Gemma-2-9b-it, UltraChat dataset
-
Brain Bandit: A Biologically Grounded Neural Network for Efficient Control of Exploration
- Chen Jiang, Jiahui An, Yating Liu, Ni Ji
- Key: explore-exploit, stochastic Hopfield net, Thompson sampling, brain-inspired RL
- Data Domain: MAB tasks, MDP tasks
Other 2025 Papers
Click to expand / collapse
-
AgentPRM: Process Reward Models for LLM Agents via Step-Wise Promise and Progress
- Zhiheng Xi, Chenyang Liao, Guanyu Li, Yajie Yang, Wenxiang Chen, Zhihao Zhang, Binghai Wang, Senjie Jin, Yuhao Zhou, Jian Guan, Wei Wu, Tao Ji, Tao Gui, Qi Zhang, Xuanjing Huang
- Key: Process Reward Models (PRM), Agentic Tasks, Generalized Advantage Estimation (GAE), Promise, Progress
- Data Domain: WebShop, HotpotQA (Agent setting), Interactive Environments
-
Towards Agentic Self-Learning LLMs in Search Environment
- Wangtao Sun, Xiang Cheng, Jialin Fan, Xing Yu, Yao Xu, Shizhu He, Jun Zhao, Kang Liu
- Key: Self-Learning, Co-Evolution, Generative Reward Model (GRM), Search Agents
- Data Domain: NQ, TriviaQA, HotpotQA, 2WikiMultiHopQA, Qwen-2.5-7B-Instruct
-
Reinforcement Learning with Verifiable yet Noisy Rewards under Imperfect Verifiers
- Xin-Qiang Cai, Wei Wang, Feng Liu, Tongliang Liu, Gang Niu, Masashi Sugiyama
- Key: Noisy Rewards, Verifier Hacking, Forward/Backward Correction, GRPO, Reference-Free RL
- Data Domain: GSM8K, MATH, Qwen2.5-Math-7B
-
Language Models that Think, Chat Better
- Adithya Bhaskar, Xi Ye, Danqi Chen
- Key: Long CoT Reasoning, Large Language Models, GRPO, SFT
- Data Domain: WildBench, AlpacaEval2, ArenaHardV2, CreativeWritingV3, IFBench, MMLU-Redux, PopQA
-
RLVE: Scaling Up Reinforcement Learning for Language Models with Adaptive Verifiable Environments
- Zhiyuan Zeng, Qinyuan Cheng, Zhangyue Yin, Yefei He, Jinpeng Wang, et al.
- Key: Adaptive Environments, Verifiable Rewards, Environment Scaling, Curriculum Learning
- Data Domain: RLVE-Gym
-
Game-RL: Synthesizing Multimodal Verifiable Game Data to Boost VLMs' General Reasoning
- Jingqi Tong, Jixin Tang, Hangcheng Li, Yurong Mou, Ming Zhang, Jun Zhao, Yanbo Wen, et al.
- Key: Vision Language Model, Reasoning, Data Synthesis, Game Playing, Visual Question Answering, Data Sets or Data Repositories, Benchmarks
- Data Domain: GameQA, CharXiv, MathVerse, MathVision, MathVista, MMBench, MMMU-Pro, MMMU
-
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
- Daya Guo, Dejian Yang, Haowei Zhang et al. (DeepSeek-AI)
- Key: GRPO, pure-RL reasoning, distillation to 1.5 B–70 B, open checkpoints
- Data Domain: AIME-2024, MATH-500, Codeforces, LiveCodeBench, GPQA-Diamond, SWE-Bench
-
Demystifying Long Chain-of-Thought Reasoning in LLMs
- IN.AI Research Team
- Key: cosine length-scaling reward, repetition penalty, stable long CoT
- Data Domain: GSM8K, MATH, mixed STEM sets
-
Exploring the Limit of Outcome Reward for Learning Mathematical Reasoning
- Shanghai AI Lab
- Key: outcome-only reward, sparse-signal RL, math-centric limits
- Data Domain: MATH-Benchmark, GSM8K, AIME, proof datasets
-
Kimi K 1.5: Scaling Reinforcement Learning with LLMs
- Moonshot AI
- Key: curriculum RL, large-batch PPO, scalable infra
- Data Domain: multi-domain reasoning, long-context writing, agent benchmarks
-
S²R: Teaching LLMs to Self-Verify and Self-Correct via Reinforcement Learning
- Tencent AI Lab
- Key: self-verification & correction loops, dual-reward, safety alignment
- Data Domain: math QA, code generation, natural-language inference
-
Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling
- Tsinghua University
- Key: compute-optimal scaling, small-vs-large model trade-offs
- Data Domain: reasoning benchmarks, test-time compute scaling
-
QLASS: Boosting Language Agent Inference via Q-Guided Stepwise Search
- UCLA (Yizhou Sun Lab)
- Key: Q-guided stepwise search, agent inference efficiency
- Data Domain: web-agent tasks, reasoning QA
-
Process Reward Models That Think
- University of Michigan
- Key: process reward modelling, reasoning guidance
- Data Domain: reasoning QA, code tasks
-
THINKPRUNE: Pruning Long Chain-of-Thought of LLMs via Reinforcement Learning
- Anonymous
- Key: CoT pruning through RL, latency reduction
- Data Domain: GSM8K, assorted reasoning sets
-
GPG: A Simple and Strong Reinforcement Learning Baseline for Model Reasoning
- TBD
- Key: lightweight RL baseline, strong reasoning gains
- Data Domain: diverse reasoning benchmarks
-
- Google DeepMind
- Key: dynamic solve-vs-verify decision, compute optimality
- Data Domain: math & code tasks
-
SWEET-RL: Training Multi-Turn LLM Agents on Collaborative Reasoning Tasks
- Meta, UC Berkeley
- Key: multi-turn agent RL, collaborative reasoning
- Data Domain: agent task suites
-
L1: Controlling How Long a Reasoning Model Thinks With Reinforcement Learning
- Carnegie Mellon University
- Key: explicit control of reasoning steps via RL
- Data Domain: GSM8K, MATH
-
Scaling Test-Time Compute Without Verification or RL is Suboptimal
- CMU, UC Berkeley
- Key: verifier-based vs verifier-free compute scaling
- Data Domain: reasoning benchmarks
-
DAST: Difficulty-Adaptive Slow-Thinking for Large Reasoning Models
- Unicom Data Intelligence
- Key: difficulty-adaptive thinking length
- Data Domain: reasoning sets
-
Reasoning with Reinforced Functional Token Tuning
- Zhejiang University, Alibaba Cloud Computing
- Key: functional token tuning, RL-aided reasoning
- Data Domain: reasoning QA, code
-
Provably Optimal Distributional RL for LLM Post-Training
- Cornell & Harvard
- Key: distributional RL theory for LLM post-training
- Data Domain: synthetic reasoning, math tasks
-
On the Emergence of Thinking in LLMs I: Searching for the Right Intuition
- MIT
- Key: self-play RL, emergent reasoning patterns
- Data Domain: reasoning games, maths puzzles
-
STP: Self-Play LLM Theorem Provers with Iterative Conjecturing and Proving
- Stanford (Tengyu Ma)
- Key: theorem proving via self-play, sparse-reward tackling
- Data Domain: proof assistant datasets
-
A Sober Look at Progress in Language Model Reasoning: Pitfalls and Paths to Reproducibility
- University of Cambridge, University of Tübingen
- Key: evaluation pitfalls, reproducibility guidelines
- Data Domain: multiple reasoning benchmarks
-
Recitation over Reasoning: How Cutting-Edge LMs Fail on Elementary Reasoning Problems
- ByteDance Seed
- Key: fragility to minor perturbations, arithmetic reasoning
- Data Domain: elementary school-level arithmetic tasks
-
Proof or Bluff? Evaluating LLMs on 2025 USA Math Olympiad
- ETH Zurich, INSAIT
- Key: Olympiad-level evaluation, zero-score phenomenon
- Data Domain: 2025 USAMO problems
-
(REINFORCE++) A Simple and Efficient Approach for Aligning Large Language Models
- Jian Hu et al.
- Key: REINFORCE++ algorithm, stability vs PPO/GRPO
- Data Domain: RLHF alignment suites
-
ReFT v3: Reasoning with Reinforced Fine-Tuning (ACL 2025)
- Trung Le, Jiaqi Zhang et al.
- Key: single-stage RLFT, low-cost math alignment
- Data Domain: GSM8K, MATH, SVAMP
-
DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models
- DeepSeek-AI
- Key: GRPO, math-only RL, verifier-guided sampling
- Data Domain: MATH-500, AIME-2024, CNMO-2024
-
SimPO: Simple Preference Optimization with a Reference-Free Reward
- Shanghai AI Lab
- Key: reference-free preference optimisation, KL-free objective
- Data Domain: AlpacaEval, helpful/harmless RLHF sets
-
DeepSeek-Prover v1.5: Harnessing Proof Assistant Feedback for RL and MCTS
- DeepSeek-AI
- Key: proof-assistant feedback, Monte-Carlo Tree Search
- Data Domain: Lean theorem-proving benchmarks
-
Tülu 3: Pushing Frontiers in Open Language Model Post-Training
- Nathan Lambert, Jacob Morrison, Valentina Pyatkin, Shengyi Huang, Hamish Ivison, Faeze Brahman, Lester James V. Miranda, Alisa Liu, Nouha Dziri, Xinxi Lyu, Yuling Gu, Saumya Malik, Victoria Graf, Jena D. Hwang, Jiangjiang Yang, Ronan Le Bras, Øyvind Tafjord, Chris Wilhelm, Luca Soldaini, Noah A. Smith, Yizhong Wang, Pradeep Dasigi, Hannaneh Hajishirzi
- Key: post-training, supervised finetuning (SFT), Direct Preference Optimization (DPO), RLVR, open LLMs
- Data Domain: multi-task language-model benchmarks (Tülu 3 Eval, decontaminated standard suites)
-
Kimi k1.5: Scaling Reinforcement Learning with LLMs
- Kimi Team – Angang Du, Bofei Gao, Bowei Xing, Changjiu Jiang, Cheng Chen, Cheng Li, … , Zongyu Lin
- Key: RL with LLMs, long-context scaling, policy optimization, long2short CoT, multi-modal reasoning
- Data Domain: AIME, MATH 500, Codeforces, MathVista, LiveCodeBench
-
Model Alignment as Prospect Theoretic Optimization
- Stanford University, Contextual AI
- Key: prospect-theoretic objective for alignment
- Data Domain: alignment evaluation suites
-
UI-R1: Enhancing Efficient Action Prediction of GUI Agents by Reinforcement Learning
- Zhengxi Lu, Yuxiang Chai, Yaxuan Guo, Xi Yin, Liang Liu, Hao Wang, Han Xiao, Shuai Ren, Guanjing Xiong, Hongsheng Li
- Key: rule-based rewards, GRPO, multimodal LLM, GUI grounding & action, data-efficient RFT (136 samples)
- Data Domain: ScreenSpot, ScreenSpot-Pro, AndroidControl
-
GUI-R1: A Generalist R1-Style Vision-Language Action Model for GUI Agents
- Run Luo, Lu Wang, Wanwei He, Xiaobo Xia
- Key: unified action space, GRPO, high-level GUI tasks, cross-platform (Win/Linux/Mac/Android/Web), data-efficient RFT (3 K samples)
- Data Domain: ScreenSpot, ScreenSpot-Pro, GUI-Act-Web, OmniAct-Web, OmniAct-Desktop, AndroidControl-Low/High, GUI-Odyssey
-
MT-R1-Zero: Advancing LLM-based Machine Translation via R1-Zero-like Reinforcement Learning
- Zhaopeng Feng, Shaosheng Cao, Jiahan Ren, Jiayuan Su, Ruizhe Chen, Yan Zhang, Jian Wu, Zuozhu Liu
- Key: Machine Translation, Rule-metric Mixed Reward
- Data Domain: BLEU, COMETKiwi, XCOMET
-
Smart-Searcher: Incentivizing the Dynamic Knowledge Acquisition of LLMs via Reinforcement Learning
- Huatong Song, Jinhao Jiang, Wenqing Tian, Zhipeng Chen, Yuhuan Wu, Jiahao Zhao, Yingqian Min, Xin Zhao, Lei Fang, Ji-Rong Wen
- Key: Retrieval-Augmented Generation (RAG), Reinforcement Learning, Internal vs External Knowledge, Dynamic Switching
- Data Domain: Multi-hop QA benchmarks, Retrieval tasks
2024 & Earlier
Click to expand / collapse
-
Direct Preference Optimization: Your Language Model is Secretly a Reward Model (ICLR 2024)
- Rafael Raffel et al.
- Key: preference optimisation without RL, DPO objective
- Data Domain: summarisation, dialogue alignment
-
Math-Shepherd: Verify and Reinforce LLMs Step-by-Step without Human Annotations (NeurIPS 2023)
- Peking University, DeepSeek-AI
- Key: step-checker, verifier RL, zero human labels
- Data Domain: GSM8K-Step, MATH-Step
-
Let’s Verify Step by Step (ICML 2023)
- OpenAI
- Key: verifier prompts, iterative self-improvement
- Data Domain: GSM8K, ProofWriter
-
Solving Olympiad Geometry without Human Demonstrations (Nature 2023)
- DeepMind
- Key: formal geometry solving, RL without human demos
- Data Domain: geometry proof tasks
-
Training Language Models to Follow Instructions with Human Feedback (NeurIPS 2022)
- OpenAI
- Key: PPO-based RLHF, instruction-following alignment
- Data Domain: broad instruction-following tasks (InstructGPT)
Other Awesome Lists
Contributing
- Fork this repo.
- Add a paper/tool entry under the correct section (keep reverse-chronological order, follow the three-line format).
- Open a Pull Request and briefly describe your changes.
License
Awesome-RLVR © 2025 OpenDILab & Contributors Apache 2.0 License
Similar repos
Significant stargazers
137 followers · starred Sep 2026