
README
angelX
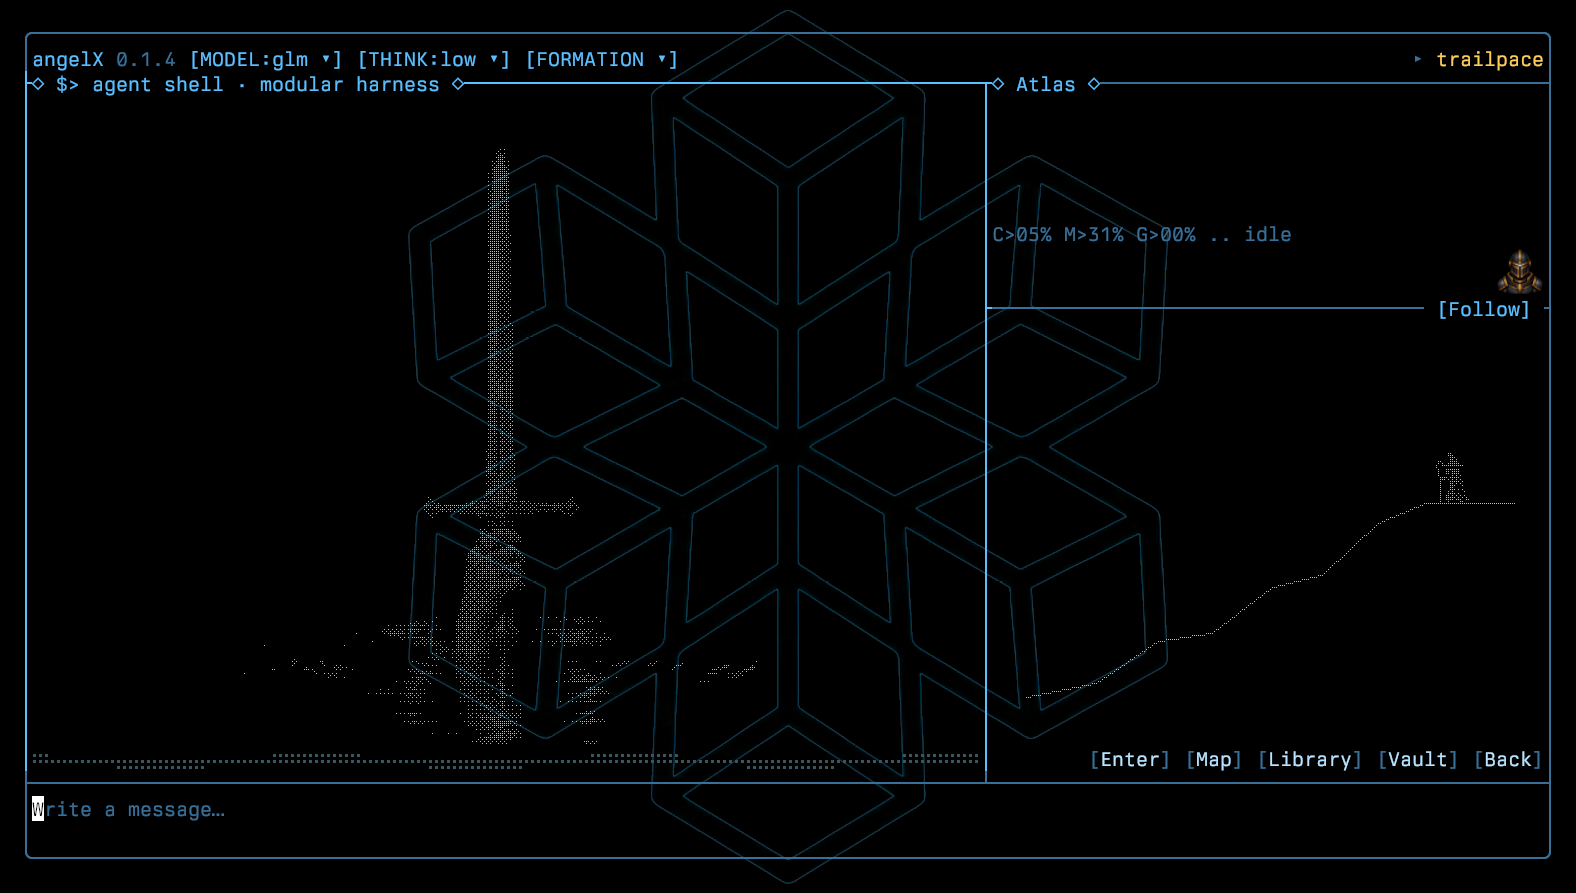
angelX is a terminal coding agent. It works inside your repository with the models you choose, asks before it runs a command or edits a file, checks its work before it reports done, and keeps what it learns about your project.
Field proven in kernel and cryptography work: GPU MODE Cholesky · 2nd · 100+ records on Yukon
# Requires Linux x86_64, Rust/Cargo, C/C++ tools, Bash, Node.js and Python 3.
# The first launch builds from source.
git clone https://github.com/newjordan/angelX.git
cd angelX
./bin/angelX
Model setup · /commands · Feature evidence · Attributions · MIT
How it works
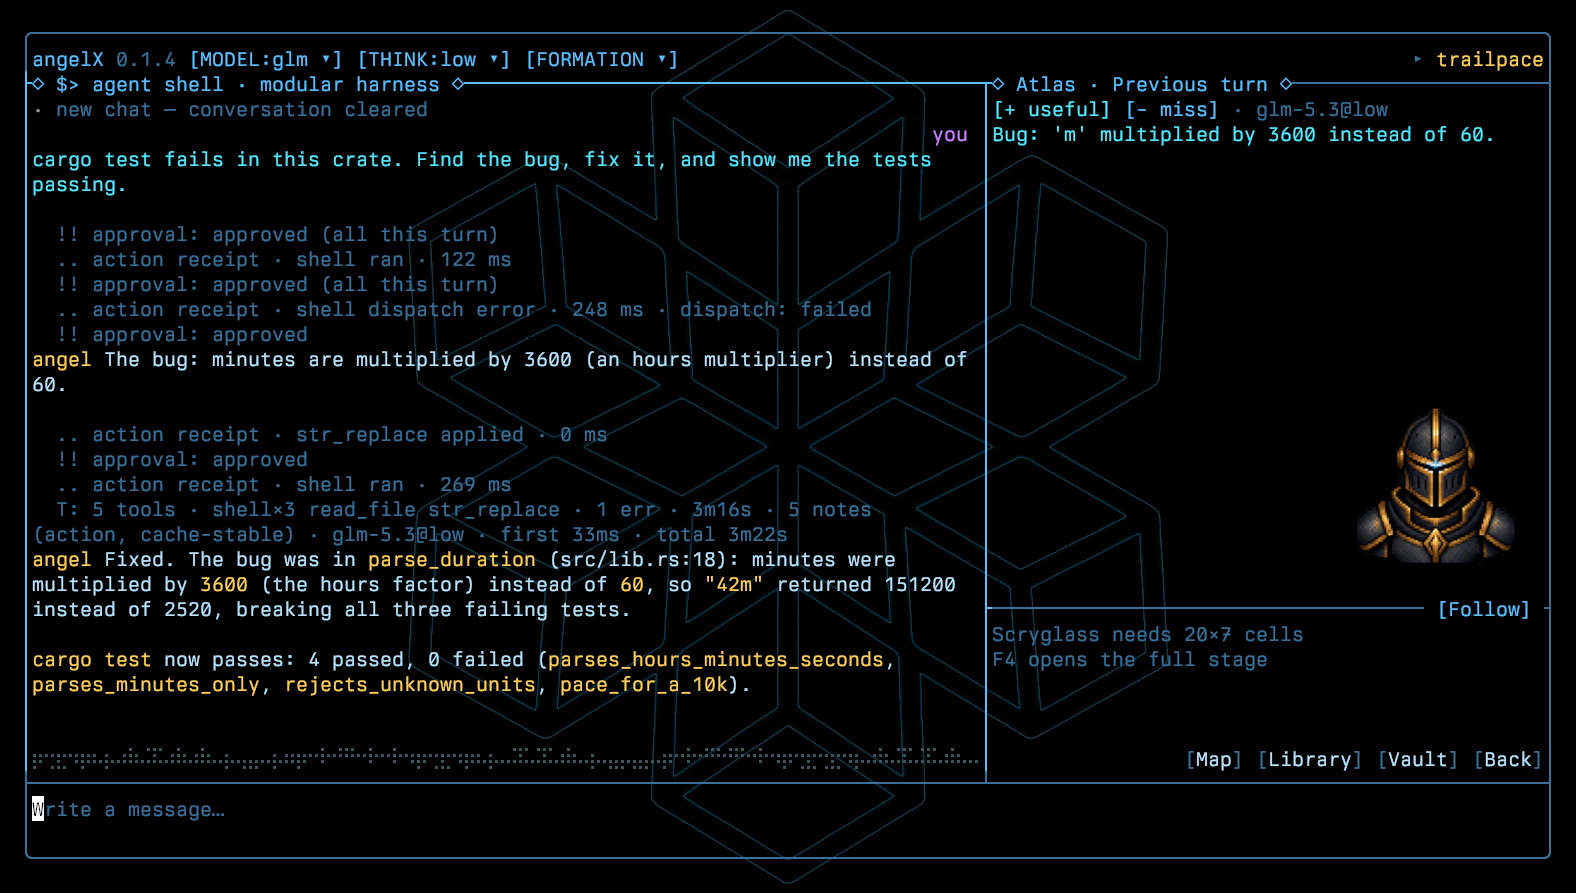
1 · Choose a model. /model lists every connected route with its thinking level; /think changes the level.
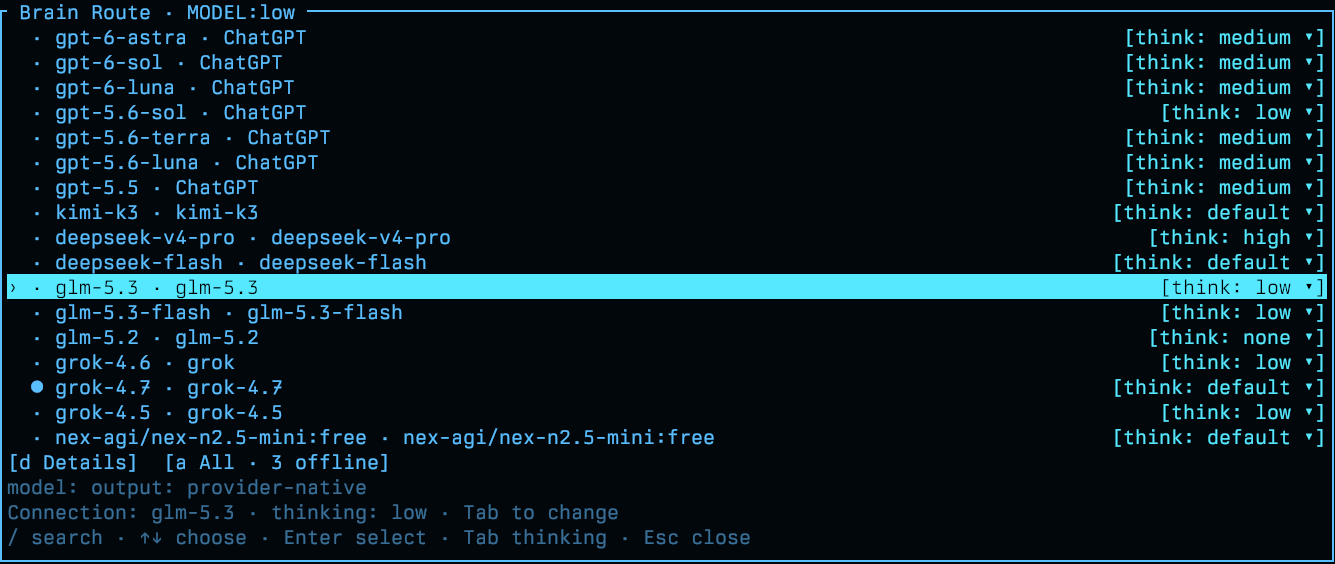
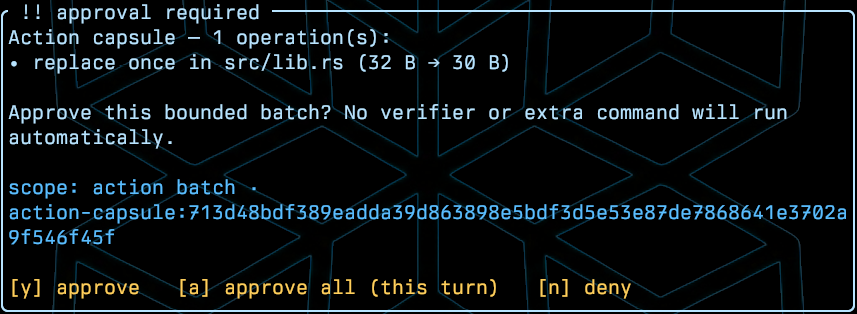
2 · Approve what it does. Commands and edits arrive as action capsules: approve one (y), approve the rest of the turn (a), or deny (n).
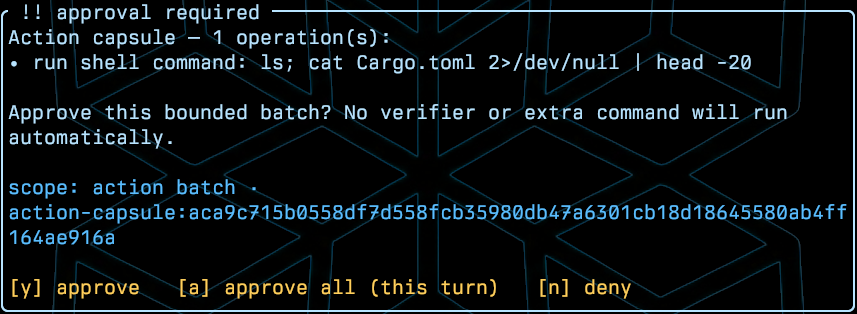
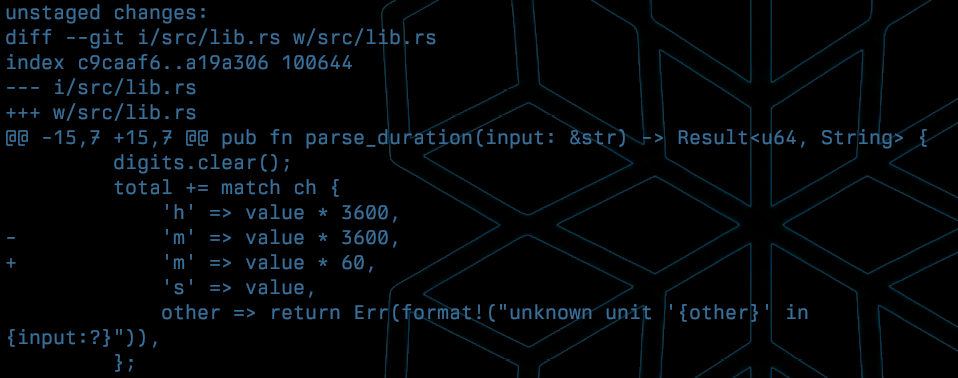
3 · Content-checked edits. Each edit is anchored to the file's current content and shows its byte change before it lands. /diff shows the result.
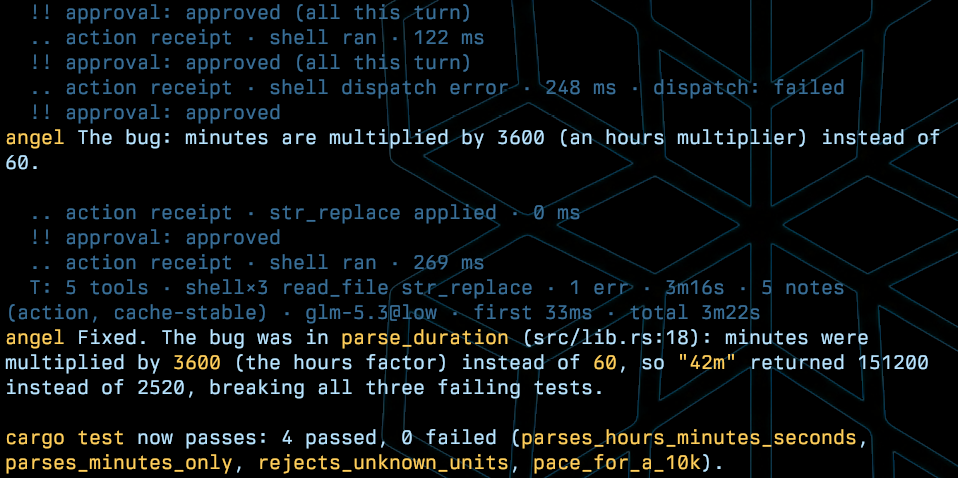
4 · Checked before done. The agent runs the checks and reports with receipts: every tool call, its time and the model route.
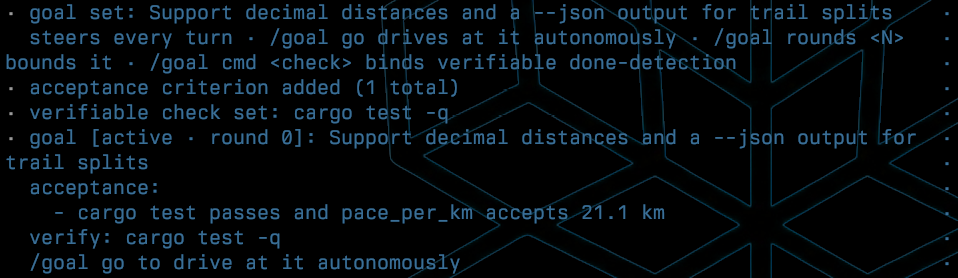
5 · Longer work. /goal sets a durable objective with acceptance criteria and a check. /loop runs it within time, iteration and token limits.
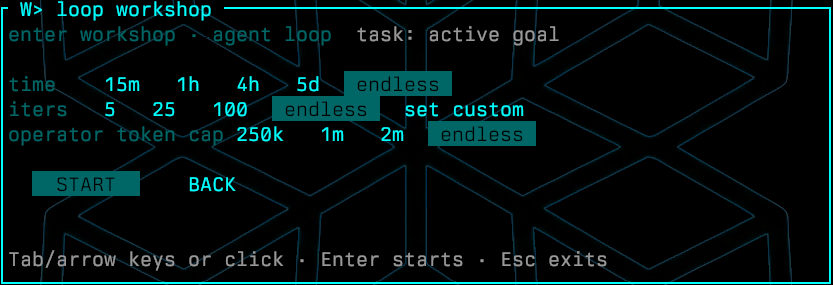
In the cockpit
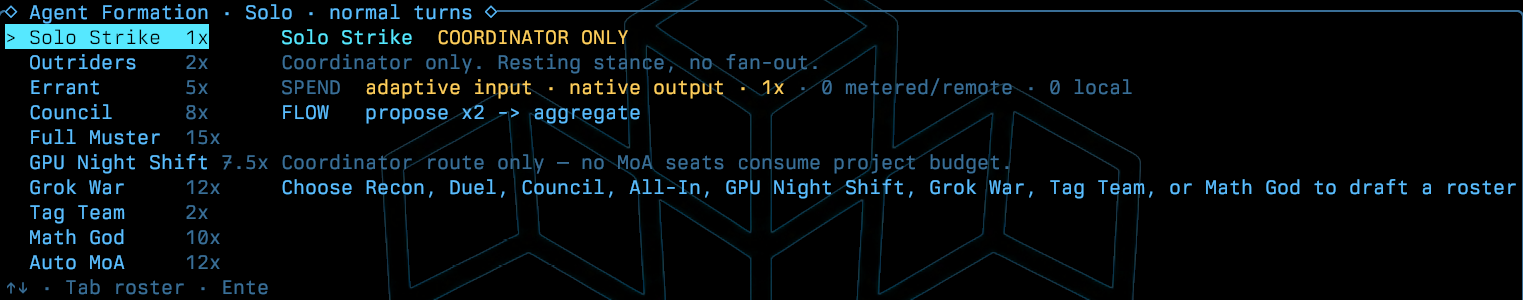 Formations · model teams, from a lone coordinator to a full roster. | 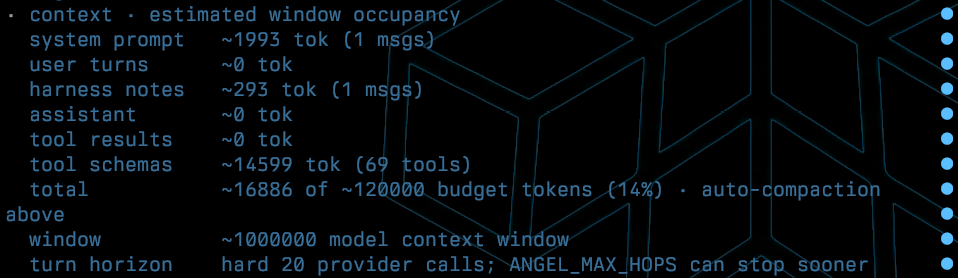 Context budget · where the window goes; compaction runs automatically. |
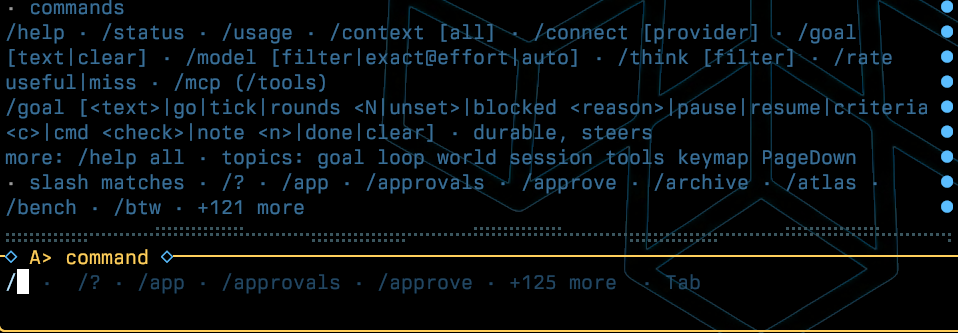 Commands · /help and Tab completion for every command. | 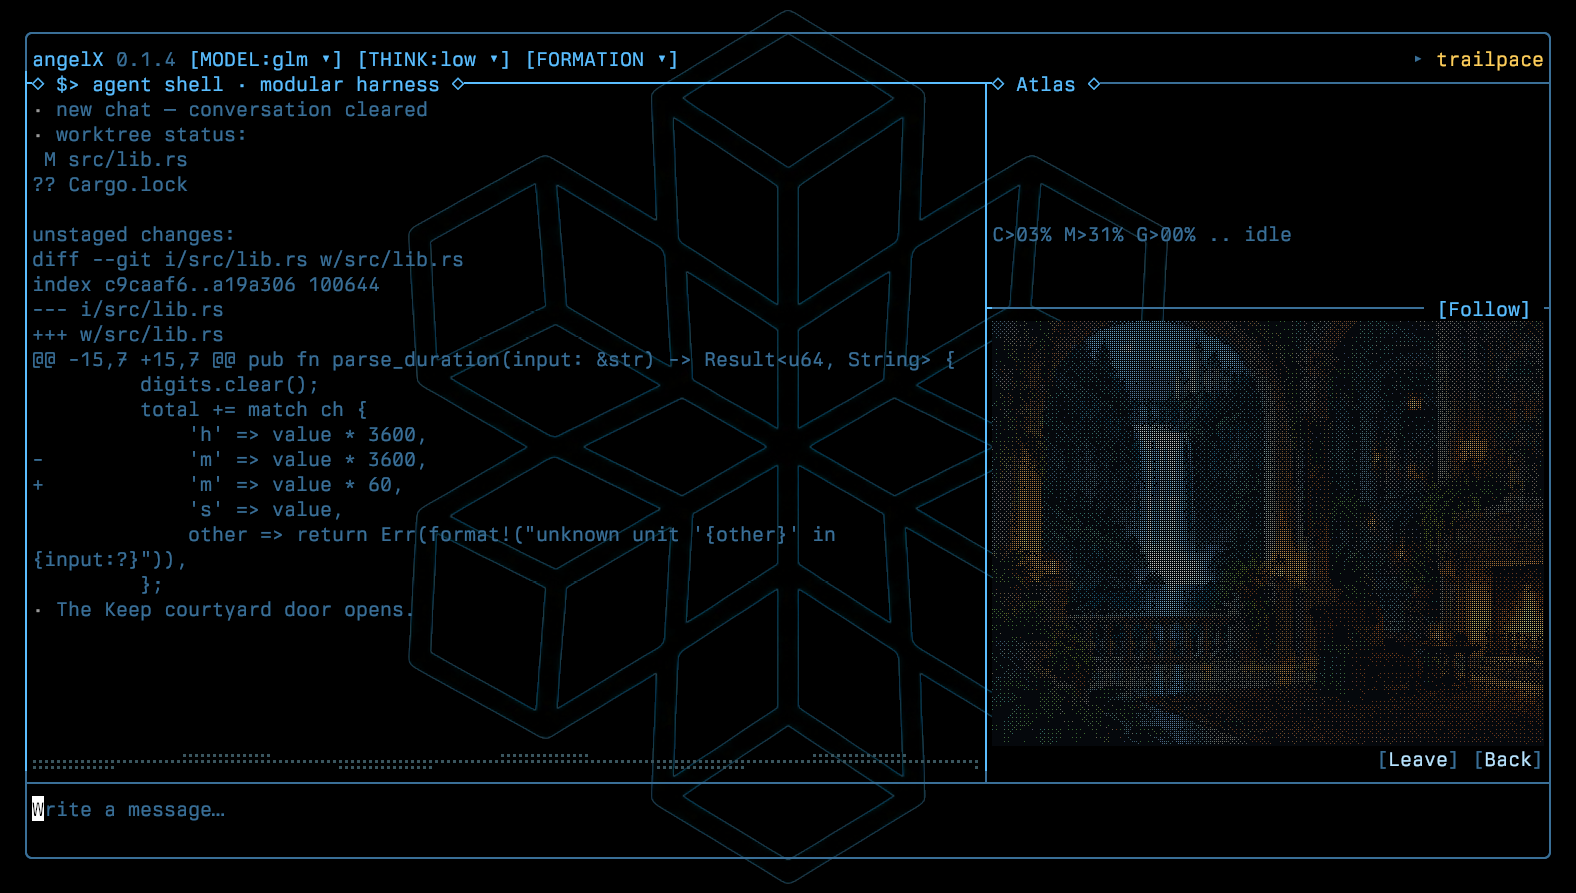 World view · Watch model behavior as an adventure in information. |
Features
- Models and formations — Choose models and thinking levels, configure teams, and run agent graphs.
- Repository tools — Search files, inspect symbols, follow definitions, and review diffs.
- Content-checked edits — Hashline editing checks file content before applying anchored changes.
- Programmable tools — Run tool calls, loops, and filters locally in JavaScript with
code_mode. - Long-session context — Compact, deduplicate, and age retained context as work continues.
- Project memory — Review source-linked knowledge in Atlas and reuse it in later tasks.
- Persistent goals — Resume sessions and autonomous work with configurable run limits.
- Headless runs — Record task settings, source identity, tool activity, and acceptance evidence.
- Measured campaigns — Evaluate isolated attempts with verifiers and independent review.
- Research loops — Use Sloptomizer suggestions, Deli deliberation, and paired experiments.
- Measured benchmarks — Calculate measured changes from paired benchmark samples.
- Adventure world model TUI — Introducing the early stages of Cyberdynamic world tui for reviewing work, presenting data graphs, adventure, and model behavior.
Benchmarks
polyglot-v1 · 136 tasks · 2026-09-21
136 repository-repair tasks (48 JS, 34 Python, 30 Rust, 24 C++) from the Aider polyglot set. One attempt per task, 600 s limit, graded by each task's tests. Wall: median agent time per attempt. Tokens: totals per cell.
| model | harness | solved | wall (median) | calls / task | input tokens | cache hit | output tokens |
|---|---|---|---|---|---|---|---|
| DeepSeek V4.1 Flash, thinking off | angelX | 133 / 136 | 9.9 s | 7.5 | 11.5 M | 88% | 257 k |
| OpenCode 1.18.31 | 132 / 136 | 8.6 s | 12.5 | 67.7 M | 97% | 349 k | |
| oh-my-pi 18.2.4 | 86 / 93 * | 15.3 s | 35.5 | 200.1 M | 99% | 866 k | |
| GLM-5.3-Flash, thinking low | angelX | 135 / 136 | 50.7 s | 8.9 | 10.9 M | 84% | 256 k |
| OpenCode 1.18.31 | 133 / 136 | 38.9 s | 7.4 | 10.1 M | 85% | 179 k | |
| oh-my-pi 18.2.4 | 133 / 136 | 37.7 s | 8.9 | 24.1 M | 90% | 203 k |
- oh-my-pi on DeepSeek reached its 200M-token budget cap after 93 tasks.
angelX runs a verification step before reporting a task done. That step accounts for its extra wall time on GLM; higher thinking levels add more.


Evaluator: Prime Intellect Verifiers v0.3.1 · angelX 98d7340 · OpenCode 1.18.31 · oh-my-pi 18.2.4 · DeepSeek V4.1 Flash, thinking off · GLM-5.3-Flash, thinking low (lowest available) · temperature 0 · 8,192-token output cap · 600 s per attempt · fresh environment per attempt · 2026-09-21
Research and credits
Research and public work that informed Angel:
- A Programming Paradigm for Spatiotemporal Composability — Yifan Shi, Wei Zhang and Tianyi Cui (2026); component lifecycle, reactive dependencies and reversible registration.
- GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning — Lakshya A. Agrawal and collaborators (2025); reflection and Pareto selection.
- Learning, Fast and Slow: Towards LLMs That Adapt Continually — Rishabh Tiwari and collaborators (2026); Sloptomizer's fast-context and slow-learner design.
- Finite-time Analysis of the Multiarmed Bandit Problem — Peter Auer, Nicolò Cesa-Bianchi and Paul Fischer (2002); UCB1 exploration.
- Prime Agent: A Self-Improving RLM Harness — Seth Karten and collaborators (2026); editable, persistent harness state.
- Geoffrey Huntley's Ralph loop — an agent put on a loop with a simple prime directive: read the issues, pick one, write the patch, run the tests, repeat. The measured campaign and autonomous loop work here is a direct descendant of that idea.
- RL Systems Mind the Gap: Matching Trainer and Generator Throughput — Kimbo Chen, Cheang Kang Wen and Dylan Patel / SemiAnalysis (2026); rollout staleness, pruning and reward-variance guards.
- Deli_AutoResearch — Deli Chen; retained findings, fresh-context deliberation and stall recovery.
- OpenScience — Synthetic Sciences; literature-search design. Search metadata comes from OpenAlex, Crossref, Semantic Scholar and Europe PMC.
Code and tooling credits include OpenAI Codex, Grok CLI, oh-my-pi, DeepSeek-Reasonix, Hermes Agent, Prime Agent, Dotmax, ureq, Ratatui, Crossterm, rusty_v8 and V8. Early inspiration: DotAgents and SpeakMCP by aj47. File-tool interface references include Claude Code, aider and OpenHands. Attributions records implementation links, authors and retained licenses; research inspiration and incorporated code are identified separately.
Field results
Field proven: 100+ records on public research leaderboards, with first-place results in kernel optimization, LLM inference and cryptography research, and 2nd place on the GPU MODE Cholesky leaderboard. Yukon field results
Special thanks
Yukon, the platform for open frontier research, where angelX set its leaderboard records.
Contributors

115 commits
Similar repos


Languages
Rust
93.9%
JavaScript
3.1%
Python
2.8%
README
angelX
angelX is a terminal coding agent. It works inside your repository with the models you choose, asks before it runs a command or edits a file, checks its work before it reports done, and keeps what it learns about your project.
Field proven in kernel and cryptography work: GPU MODE Cholesky · 2nd · 100+ records on Yukon
# Requires Linux x86_64, Rust/Cargo, C/C++ tools, Bash, Node.js and Python 3.
# The first launch builds from source.
git clone https://github.com/newjordan/angelX.git
cd angelX
./bin/angelX
Model setup · /commands · Feature evidence · Attributions · MIT
How it works
1 · Choose a model. /model lists every connected route with its thinking level; /think changes the level.
2 · Approve what it does. Commands and edits arrive as action capsules: approve one (y), approve the rest of the turn (a), or deny (n).
3 · Content-checked edits. Each edit is anchored to the file's current content and shows its byte change before it lands. /diff shows the result.
4 · Checked before done. The agent runs the checks and reports with receipts: every tool call, its time and the model route.
5 · Longer work. /goal sets a durable objective with acceptance criteria and a check. /loop runs it within time, iteration and token limits.
In the cockpit
Formations · model teams, from a lone coordinator to a full roster. | Context budget · where the window goes; compaction runs automatically. |
Commands · /help and Tab completion for every command. | World view · Watch model behavior as an adventure in information. |
Features
- Models and formations — Choose models and thinking levels, configure teams, and run agent graphs.
- Repository tools — Search files, inspect symbols, follow definitions, and review diffs.
- Content-checked edits — Hashline editing checks file content before applying anchored changes.
- Programmable tools — Run tool calls, loops, and filters locally in JavaScript with
code_mode. - Long-session context — Compact, deduplicate, and age retained context as work continues.
- Project memory — Review source-linked knowledge in Atlas and reuse it in later tasks.
- Persistent goals — Resume sessions and autonomous work with configurable run limits.
- Headless runs — Record task settings, source identity, tool activity, and acceptance evidence.
- Measured campaigns — Evaluate isolated attempts with verifiers and independent review.
- Research loops — Use Sloptomizer suggestions, Deli deliberation, and paired experiments.
- Measured benchmarks — Calculate measured changes from paired benchmark samples.
- Adventure world model TUI — Introducing the early stages of Cyberdynamic world tui for reviewing work, presenting data graphs, adventure, and model behavior.
Benchmarks
polyglot-v1 · 136 tasks · 2026-09-21
136 repository-repair tasks (48 JS, 34 Python, 30 Rust, 24 C++) from the Aider polyglot set. One attempt per task, 600 s limit, graded by each task's tests. Wall: median agent time per attempt. Tokens: totals per cell.
| model | harness | solved | wall (median) | calls / task | input tokens | cache hit | output tokens |
|---|---|---|---|---|---|---|---|
| DeepSeek V4.1 Flash, thinking off | angelX | 133 / 136 | 9.9 s | 7.5 | 11.5 M | 88% | 257 k |
| OpenCode 1.18.31 | 132 / 136 | 8.6 s | 12.5 | 67.7 M | 97% | 349 k | |
| oh-my-pi 18.2.4 | 86 / 93 * | 15.3 s | 35.5 | 200.1 M | 99% | 866 k | |
| GLM-5.3-Flash, thinking low | angelX | 135 / 136 | 50.7 s | 8.9 | 10.9 M | 84% | 256 k |
| OpenCode 1.18.31 | 133 / 136 | 38.9 s | 7.4 | 10.1 M | 85% | 179 k | |
| oh-my-pi 18.2.4 | 133 / 136 | 37.7 s | 8.9 | 24.1 M | 90% | 203 k |
- oh-my-pi on DeepSeek reached its 200M-token budget cap after 93 tasks.
angelX runs a verification step before reporting a task done. That step accounts for its extra wall time on GLM; higher thinking levels add more.
Evaluator: Prime Intellect Verifiers v0.3.1 · angelX 98d7340 · OpenCode 1.18.31 · oh-my-pi 18.2.4 · DeepSeek V4.1 Flash, thinking off · GLM-5.3-Flash, thinking low (lowest available) · temperature 0 · 8,192-token output cap · 600 s per attempt · fresh environment per attempt · 2026-09-21
Research and credits
Research and public work that informed Angel:
- A Programming Paradigm for Spatiotemporal Composability — Yifan Shi, Wei Zhang and Tianyi Cui (2026); component lifecycle, reactive dependencies and reversible registration.
- GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning — Lakshya A. Agrawal and collaborators (2025); reflection and Pareto selection.
- Learning, Fast and Slow: Towards LLMs That Adapt Continually — Rishabh Tiwari and collaborators (2026); Sloptomizer's fast-context and slow-learner design.
- Finite-time Analysis of the Multiarmed Bandit Problem — Peter Auer, Nicolò Cesa-Bianchi and Paul Fischer (2002); UCB1 exploration.
- Prime Agent: A Self-Improving RLM Harness — Seth Karten and collaborators (2026); editable, persistent harness state.
- Geoffrey Huntley's Ralph loop — an agent put on a loop with a simple prime directive: read the issues, pick one, write the patch, run the tests, repeat. The measured campaign and autonomous loop work here is a direct descendant of that idea.
- RL Systems Mind the Gap: Matching Trainer and Generator Throughput — Kimbo Chen, Cheang Kang Wen and Dylan Patel / SemiAnalysis (2026); rollout staleness, pruning and reward-variance guards.
- Deli_AutoResearch — Deli Chen; retained findings, fresh-context deliberation and stall recovery.
- OpenScience — Synthetic Sciences; literature-search design. Search metadata comes from OpenAlex, Crossref, Semantic Scholar and Europe PMC.
Code and tooling credits include OpenAI Codex, Grok CLI, oh-my-pi, DeepSeek-Reasonix, Hermes Agent, Prime Agent, Dotmax, ureq, Ratatui, Crossterm, rusty_v8 and V8. Early inspiration: DotAgents and SpeakMCP by aj47. File-tool interface references include Claude Code, aider and OpenHands. Attributions records implementation links, authors and retained licenses; research inspiration and incorporated code are identified separately.
Field results
Field proven: 100+ records on public research leaderboards, with first-place results in kernel optimization, LLM inference and cryptography research, and 2nd place on the GPU MODE Cholesky leaderboard. Yukon field results
Special thanks
Yukon, the platform for open frontier research, where angelX set its leaderboard records.
Similar repos
Contributors
115 commits
Languages
Rust
93.9%
JavaScript
3.1%
Python
2.8%