
A Curated List of Awesome Works in World Modeling, Aiming to Serve as a One-stop Resource for Researchers, Practitioners, and Enthusiasts Interested in World Modeling.
3,441
170 commits
updated Sep 23, 2026
README
🌍 Awesome World Models


📜 A Curated List of Amazing Works in World Modeling, spanning applications in Embodied AI, Autonomous Driving, Natural Language Processing and Agents.
Based on Awesome-World-Model-for-Autonomous-Driving and Awesome-World-Model-for-Robotics.
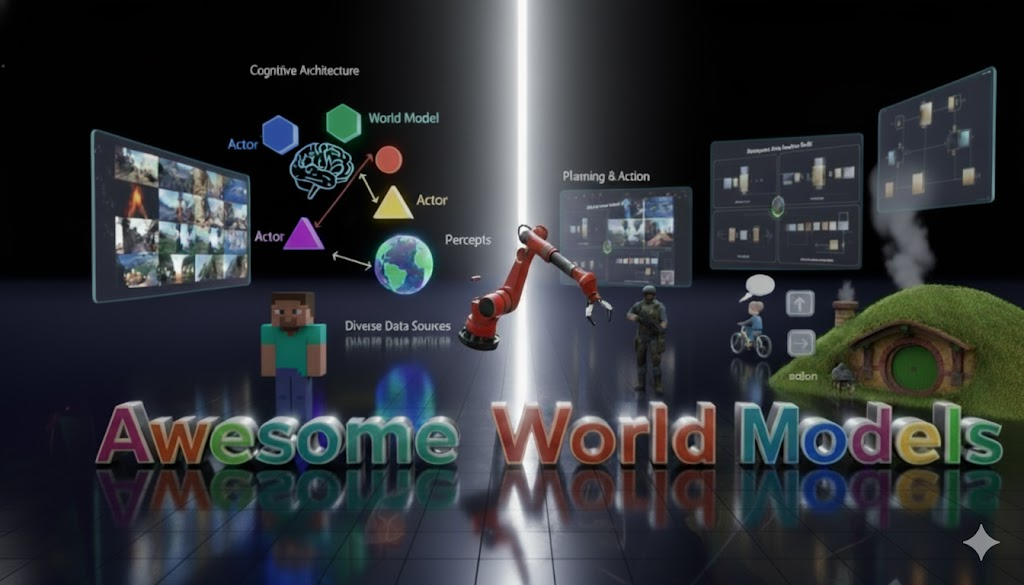
Photo Credit: Gemini-Nano-Banana🍌.
🚩 News & Updates
Major updates and announcements are shown below. Scroll for full timeline.
🚀 [2025-11] 1k+ Stars ⭐️ Under 30 Days — 🌍 Awesome World Models reached 1k github stars within 30 days of initial release, let's go!!!
🗺️ [2025-10] Enhanced Visual Navigation — Introduced badge system for papers! All entries now display 


🔥 [2025-10] Repository Launch — Awesome World Models is now live! We're building a comprehensive collection spanning Embodied AI, Autonomous Driving, NLP, and more. See CONTRIBUTING.md for how to contribute.
💡 [Ongoing] Community Contributions Welcome — Help us maintain the most up-to-date world models resource! Submit papers via PR or contact us at email.
⭐ [Ongoing] Support This Project — If you find this useful, please cite our work and give us a star. Share with your research community!
Overview
- 🎯 Aim of the project
- 📚 Definition of World Models
- 🧭 Tutorials & Starter Resources
- 📖 Surveys of World Models
- 🎮 World Models for Game Simulation
- 🚗 World Models for Autonomous Driving
- 🤖 World Models for Embodied AI
- 🔬 World Models for Science
- 💭 Positions on World Models
- 📐 Theory & World Models Explainability
- 🛠️ General Approaches to World Models
- 📊 Evaluating World Models
- 🙏 Acknowledgements
- 📝 Citation
Aim of the Project
World Models have become a hot topic in both research and industry, attracting unprecedented attention from the AI community and beyond. However, due to the interdisciplinary nature of the field (and because the term "world model" simply sounds amazing), the concept has been used with varying definitions across different domains.
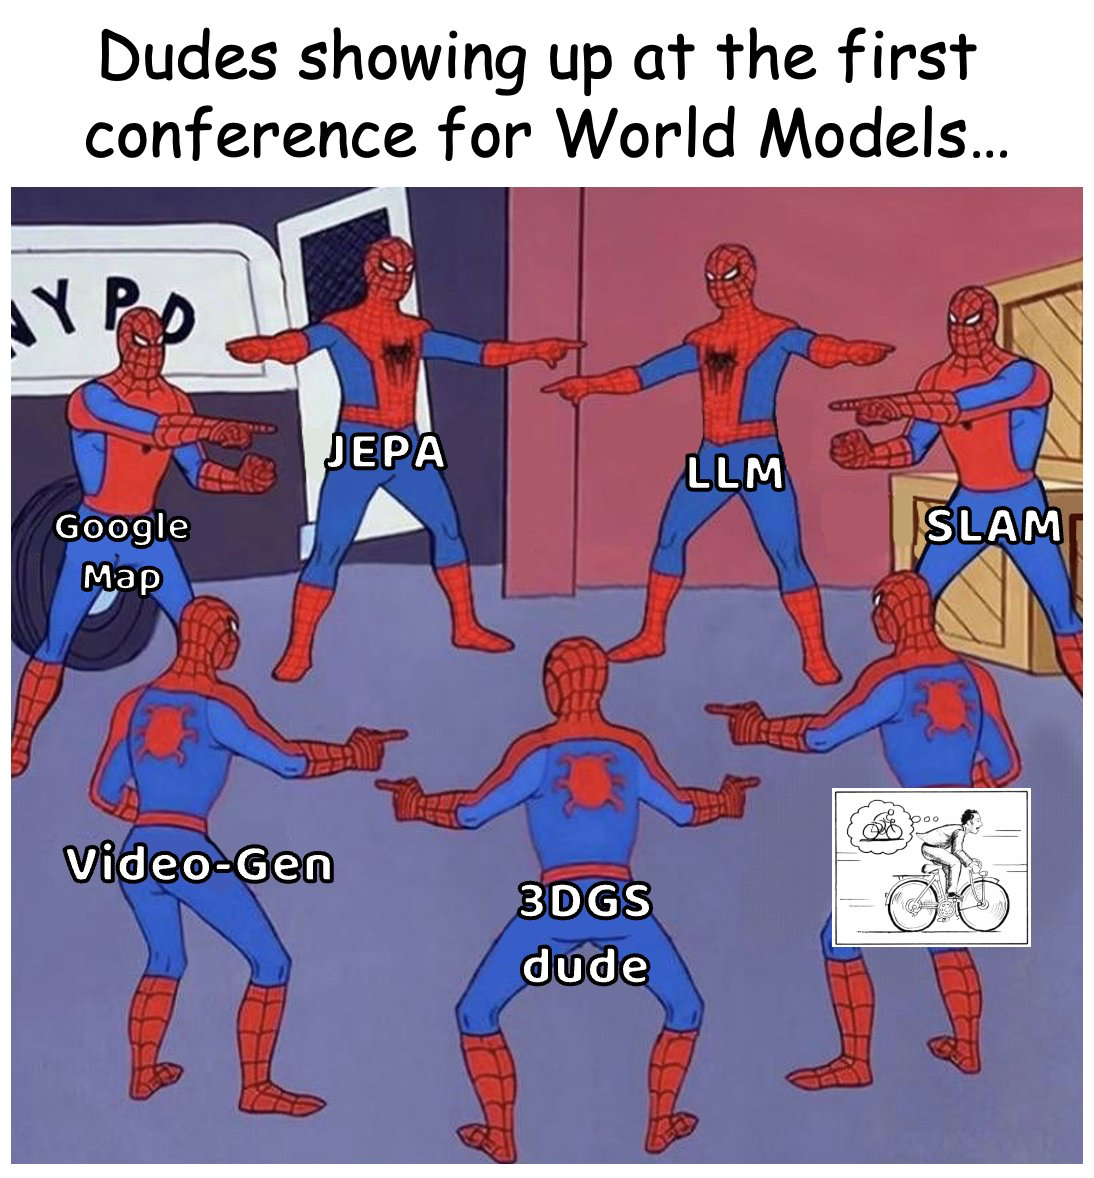
This repository aims to:
- 🔍 Organize the rapidly growing body of world model research across multiple application domains
- 🗺️ Provide a minimalist map of how world models are utilized in different fields (Embodied AI, Autonomous Driving, NLP, etc.)
- 🤝 Bridge the gap between different communities working on world models with varying perspectives
- 📚 Serve as a one-stop resource for researchers, practitioners, and enthusiasts interested in world modeling
- 🚀 Track the latest developments and breakthroughs in this exciting field
Whether you're a researcher looking for related work, a practitioner seeking implementation references, or simply curious about world models, we hope this curated list helps you navigate the landscape!
Definition of World Models
While world models' outreach has been expanded again and again, it is widely adopted that the original sources of world models come from these two papers:
- [⭐️] World Models, World Models.

- [⭐️] Yann Lecun's Speech, "A Path Towards Autonomous Machine Intelligence".

Some other great blogposts on world models include:
- [⭐️] Towards Video World Models, "Towards Video World Models".
- Status of World Models in 2025, "Beyond the Hype: How I See World Models Evolving in 2025".
- [⭐️] Jim Fan's tweet.
- [⭐️] World Model Workshop at Montreal, "Keynote: Yoshua Bengio, Yann Lecun, Jurgen Schmidhuber, Sherry Yang, Shirley Ho, etc. (Youtube Streamning included)".

Tutorials & Starter Resources
- [⭐️] Nano World Models, "Nano World Models: A Minimalist Implementation of Future Video Prediction".

- [⭐️] minWM, "minWM: A Full-Stack Open-Source Framework for Real-Time Interactive Video World Models".

- StableWM, "stable-worldmodel: A Platform for Reproducible World Modeling Research and Evaluation".

- WorldFoundry, "WorldFoundry: Unified World Model Inference & Evaluation Infrastructure".
- world-models.io, "A structured knowledge platform for discovering and comparing AI world models across robotics, model-based reinforcement learning, simulation engines, embodied AI, and autonomous systems, with model profiles, comparisons, research, benchmarks, and a practical taxonomy."
Surveys of World Models
1. World Models and Video Generation:
- [⭐️] Is Sora a World Simulator, "Is Sora a World Simulator? A Comprehensive Survey on General World Models and Beyond".

- Physics Cognition in Video Generation, "Exploring the Evolution of Physics Cognition in Video Generation: A Survey".

- From Generation to Simulation, "From Generation to Simulation: How Far Are World Models from Being True Simulators?".
2. World Models and 3D Generation:
- [⭐️] 3D and 4D World Modeling: A Survey, "3D and 4D World Modeling: A Survey".

- [⭐️] Understanding World or Predicting Future?, "Understanding World or Predicting Future? A Comprehensive Survey of World Models".

- From 2D to 3D Cognition, "From 2D to 3D Cognition: A Brief Survey of General World Models".

3. World Models and Embodied Artificial Intelligence:
- [⭐️] World Models for Embodied AI, "A Comprehensive Survey on World Models for Embodied AI".

- World Models and Physical Simulation, "A Survey: Learning Embodied Intelligence from Physical Simulators and World Models".

- Embodied AI Agents: Modeling the World, "Embodied AI Agents: Modeling the World".

- Aligning Cyber Space with Physical World, "Aligning Cyber Space with Physical World: A Comprehensive Survey on Embodied AI".

- Physical Grounding in World Models, "From Generative Engines to Actionable Simulators: The Imperative of Physical Grounding in World Models".

- [⭐️] World Action Models v.s. VLA, "Do World Action Models Generalize Better than VLAs? A Robustness Study".

- WorldScape, "WorldScape: A Unified Real-time World Model Integrating Locomotion And Manipulation".
- [⭐️] World Model for Robot Learning: "World Model for Robot Learning: A Comprehensive Survey".

4. World Models for Autonomous Driving:
- [⭐️] A Survey of World Models for Autonomous Driving, "A Survey of World Models for Autonomous Driving".

- World Models for Autonomous Driving: An Initial Survey, "World Models for Autonomous Driving: An Initial Survey".

- Interplay Between Video Generation and World Models in Autonomous Driving, "Exploring the Interplay Between Video Generation and World Models in Autonomous Driving: A Survey".

- Progressive Robustness-Aware World Models in Autonomous Driving: A Survey, "Progressive Robustness-Aware World Models in Autonomous Driving: A Survey".


5. Other Good Surveys:
- From Masks to Worlds, "From Masks to Worlds: A Hitchhiker's Guide to World Models".

- The Safety Challenge of World Models, "The Safety Challenge of World Models for Embodied AI Agents: A Review".

- World Models in AI: Like a Child, "World Models in Artificial Intelligence: Sensing, Learning, and Reasoning Like a Child".

- World Model Safety, "World Models: The Safety Perspective".

- Model-based reinforcement learning: "A survey on model-based reinforcement learning".
- On Memory: A comparison of memory mechanisms in world models: "On Memory: A comparison of memory mechanisms in world models".

World Models for Game Simulation
Pixel Space:
- [⭐️] GameNGen, "Diffusion Models Are Real-Time Game Engines".

- [⭐️] DIAMOND, "Diffusion for World Modeling: Visual Details Matter in Atari".

- MineWorld, "MineWorld: a Real-Time and Open-Source Interactive World Model on Minecraft".

- Oasis, "Oasis: A Universe in a Transformer".
- AnimeGamer, "AnimeGamer: Infinite Anime Life Simulation with Next Game State Prediction".

- [⭐️] Matrix-Game, "Matrix-Game: Interactive World Foundation Model."

- [⭐️] Matrix-Game 2.0, Matrix-Game 2.0: An Open-Source, Real-Time, and Streaming Interactive World Model.

- [⭐️] Matrix-Game 3.0, "Matrix-Game 3.0: Real-Time and Streaming Interactive World Model with Long-Horizon Memory".

- Matrix-Game 3.5, "Matrix-Game 3.5: Enhancing Real-Time Streaming Interactive World Models with Patch Memory".
- RealPlay, "From Virtual Games to Real-World Play".

- GameFactory, "GameFactory: Creating New Games with Generative Interactive Videos".

- WORLDMEM, "Worldmem: Long-term Consistent World Simulation with Memory".

- Waypoint-1, "The Path to Real-Time Worlds and Why It Matters".
- SCOPE, "SCOPE: Simulating Cross-game Operations in Playable Environments for FPS World Models".

- MIRA, "Multiplayer Interactive World Models with Representation Autoencoders".

- Solaris, "Solaris: Building a Multiplayer Video World Model in Minecraft".

- ABot-World-0: "ABot-World-0: Infinite Interactive World Rollout on a Single Desktop GPU".
- ForgeWM: "ForgeWM: Progressive Causal Training for Few-Step Action-Conditioned Video World Models".
- Programmable World Model: "Programmable World Model".
3D Mesh Space:
- [⭐️] HunyuanWorld 1.0, HunyuanWorld 1.0: Generating Immersive, Explorable, and Interactive 3D Worlds from Words or Pixels.

- [⭐️] Matrix-3D, Matrix-3D: Omnidirectional Explorable 3D World Generation.

World Models for Autonomous Driving
Refer to https://github.com/LMD0311/Awesome-World-Model for full list.
[!NOTE] 📢 [Call for Maintenance] The repo creator is no expert of autonomous driving, so this is a more-than-concise list of works without classification. We anticipate community effort on turning this section cleaner and more well-sorted.
- [⭐️] Cosmos-Drive-Dreams, "Cosmos-Drive-Dreams: Scalable Synthetic Driving Data Generation with World Foundation Models".

- [⭐️] OmniDreams, "NVIDIA OmniDreams: Real-Time Generative World Model for Closed-Loop Autonomous Vehicle Simulation".

- [⭐️] GAIA-2, "GAIA-2: A Controllable Multi-View Generative World Model for Autonomous Driving".

- WorldLens, "WorldLens: Full-Spectrum Evaluations of Driving World Models in Real World".

- Copilot4D, "Copilot4D: Learning Unsupervised World Models for Autonomous Driving via Discrete Diffusion".

- OmniNWM: "OmniNWM: Omniscient Driving Navigation World Models".

- GAIA-1, "Introducing GAIA-1: A Cutting-Edge Generative AI Model for Autonomy".

-
PWM, "From Forecasting to Planning: Policy World Model for Collaborative State-Action Prediction".

-
Dream4Drive, "Rethinking Driving World Model as Synthetic Data Generator for Perception Tasks".

-
SparseWorld, "SparseWorld: A Flexible, Adaptive, and Efficient 4D Occupancy World Model Powered by Sparse and Dynamic Queries".

-
DriveVLA-W0: "DriveVLA-W0: World Models Amplify Data Scaling Law in Autonomous Driving".

-
"Enhancing Physical Consistency in Lightweight World Models".

-
IRL-VLA: "IRL-VLA: Training an Vision-Language-Action Policy via Reward World Model".

-
LiDARCrafter: "LiDARCrafter: Dynamic 4D World Modeling from LiDAR Sequences".

-
FASTopoWM: "FASTopoWM: Fast-Slow Lane Segment Topology Reasoning with Latent World Models".

-
Orbis: "Orbis: Overcoming Challenges of Long-Horizon Prediction in Driving World Models".

-
"World Model-Based End-to-End Scene Generation for Accident Anticipation in Autonomous Driving".

-
NRSeg: "NRSeg: Noise-Resilient Learning for BEV Semantic Segmentation via Driving World Models"

-
World4Drive: "World4Drive: End-to-End Autonomous Driving via Intention-aware Physical Latent World Model".

-
Epona: "Epona: Autoregressive Diffusion World Model for Autonomous Driving".

-
"Towards foundational LiDAR world models with efficient latent flow matching".

-
SceneDiffuser++: "SceneDiffuser++: City-Scale Traffic Simulation via a Generative World Model".

-
COME: "COME: Adding Scene-Centric Forecasting Control to Occupancy World Model"

-
STAGE: "STAGE: A Stream-Centric Generative World Model for Long-Horizon Driving-Scene Simulation".

-
ReSim: "ReSim: Reliable World Simulation for Autonomous Driving".

-
"Ego-centric Learning of Communicative World Models for Autonomous Driving".

-
V2XCrafter: "V2XCrafter: Learning to Generate Driving Scene Across Agents".

-
Dreamland: "Dreamland: Controllable World Creation with Simulator and Generative Models".

-
LongDWM: "LongDWM: Cross-Granularity Distillation for Building a Long-Term Driving World Model".

-
GeoDrive: "GeoDrive: 3D Geometry-Informed Driving World Model with Precise Action Control".

-
FutureSightDrive: "FutureSightDrive: Thinking Visually with Spatio-Temporal CoT for Autonomous Driving".

-
Raw2Drive: "Raw2Drive: Reinforcement Learning with Aligned World Models for End-to-End Autonomous Driving (in CARLA v2)".

-
VL-SAFE: "VL-SAFE: Vision-Language Guided Safety-Aware Reinforcement Learning with World Models for Autonomous Driving".

-
PosePilot: "PosePilot: Steering Camera Pose for Generative World Models with Self-supervised Depth".

-
"World Model-Based Learning for Long-Term Age of Information Minimization in Vehicular Networks".

-
"Learning to Drive from a World Model".

-
DriVerse: "DriVerse: Navigation World Model for Driving Simulation via Multimodal Trajectory Prompting and Motion Alignment".

-
"End-to-End Driving with Online Trajectory Evaluation via BEV World Model".

-
"Knowledge Graphs as World Models for Semantic Material-Aware Obstacle Handling in Autonomous Vehicles".

-
MiLA: "MiLA: Multi-view Intensive-fidelity Long-term Video Generation World Model for Autonomous Driving".

-
SimWorld: "SimWorld: A Unified Benchmark for Simulator-Conditioned Scene Generation via World Model".

-
UniFuture: "Seeing the Future, Perceiving the Future: A Unified Driving World Model for Future Generation and Perception".

-
EOT-WM: "Other Vehicle Trajectories Are Also Needed: A Driving World Model Unifies Ego-Other Vehicle Trajectories in Video Latent Space".

-
"Temporal Triplane Transformers as Occupancy World Models".

-
InDRiVE: "InDRiVE: Intrinsic Disagreement based Reinforcement for Vehicle Exploration through Curiosity Driven Generalized World Model".

-
MaskGWM: "MaskGWM: A Generalizable Driving World Model with Video Mask Reconstruction".

-
Dream to Drive: "Dream to Drive: Model-Based Vehicle Control Using Analytic World Models".

-
"Semi-Supervised Vision-Centric 3D Occupancy World Model for Autonomous Driving".

-
"Dream to Drive with Predictive Individual World Model".

-
HERMES: "HERMES: A Unified Self-Driving World Model for Simultaneous 3D Scene Understanding and Generation".

-
AdaWM: "AdaWM: Adaptive World Model based Planning for Autonomous Driving".

-
AD-L-JEPA: "AD-L-JEPA: Self-Supervised Spatial World Models with Joint Embedding Predictive Architecture for Autonomous Driving with LiDAR Data".

-
DrivingWorld: "DrivingWorld: Constructing World Model for Autonomous Driving via Video GPT".

-
DrivingGPT: "DrivingGPT: Unifying Driving World Modeling and Planning with Multi-modal Autoregressive Transformers".

-
"An Efficient Occupancy World Model via Decoupled Dynamic Flow and Image-assisted Training".

-
GEM: "GEM: A Generalizable Ego-Vision Multimodal World Model for Fine-Grained Ego-Motion, Object Dynamics, and Scene Composition Control".

-
GaussianWorld: "GaussianWorld: Gaussian World Model for Streaming 3D Occupancy Prediction".

-
Doe-1: "Doe-1: Closed-Loop Autonomous Driving with Large World Model".

-
"Physical Informed Driving World Model".

-
InfiniCube: "InfiniCube: Unbounded and Controllable Dynamic 3D Driving Scene Generation with World-Guided Video Models".

-
InfinityDrive: "InfinityDrive: Breaking Time Limits in Driving World Models".

-
ReconDreamer: "ReconDreamer: Crafting World Models for Driving Scene Reconstruction via Online Restoration".

-
Imagine-2-Drive: "Imagine-2-Drive: High-Fidelity World Modeling in CARLA for Autonomous Vehicles".

-
DynamicCity: "DynamicCity: Large-Scale 4D Occupancy Generation from Dynamic Scenes".

-
DriveDreamer4D: "World Models Are Effective Data Machines for 4D Driving Scene Representation".

-
DOME: "Taming Diffusion Model into High-Fidelity Controllable Occupancy World Model".

-
SSR: "Does End-to-End Autonomous Driving Really Need Perception Tasks?".

-
"Mitigating Covariate Shift in Imitation Learning for Autonomous Vehicles Using Latent Space Generative World Models".

-
LatentDriver: "Learning Multiple Probabilistic Decisions from Latent World Model in Autonomous Driving".

-
RenderWorld: "World Model with Self-Supervised 3D Label".

-
OccLLaMA: "An Occupancy-Language-Action Generative World Model for Autonomous Driving".

-
DriveGenVLM: "Real-world Video Generation for Vision Language Model based Autonomous Driving".

-
Drive-OccWorld: "Driving in the Occupancy World: Vision-Centric 4D Occupancy Forecasting and Planning via World Models for Autonomous Driving".

-
CarFormer: "Self-Driving with Learned Object-Centric Representations".

-
BEVWorld: "A Multimodal World Model for Autonomous Driving via Unified BEV Latent Space".

-
TOKEN: "Tokenize the World into Object-level Knowledge to Address Long-tail Events in Autonomous Driving".

-
UMAD: "Unsupervised Mask-Level Anomaly Detection for Autonomous Driving".

-
SimGen: "Simulator-conditioned Driving Scene Generation".

-
AdaptiveDriver: "Planning with Adaptive World Models for Autonomous Driving".

-
UnO: "Unsupervised Occupancy Fields for Perception and Forecasting".

-
LAW: "Enhancing End-to-End Autonomous Driving with Latent World Model".

-
Delphi: "Unleashing Generalization of End-to-End Autonomous Driving with Controllable Long Video Generation".

-
OccSora: "4D Occupancy Generation Models as World Simulators for Autonomous Driving".

-
MagicDrive3D: "Controllable 3D Generation for Any-View Rendering in Street Scenes".

-
Vista: "A Generalizable Driving World Model with High Fidelity and Versatile Controllability".

-
CarDreamer: "Open-Source Learning Platform for World Model based Autonomous Driving".

-
DriveSim: "Probing Multimodal LLMs as World Models for Driving".

-
DriveWorld: "4D Pre-trained Scene Understanding via World Models for Autonomous Driving".

-
LidarDM: "Generative LiDAR Simulation in a Generated World".

-
SubjectDrive: "Scaling Generative Data in Autonomous Driving via Subject Control".

-
DriveDreamer-2: "LLM-Enhanced World Models for Diverse Driving Video Generation".

-
Think2Drive: "Efficient Reinforcement Learning by Thinking in Latent World Model for Quasi-Realistic Autonomous Driving".

-
MARL-CCE: "Modelling Competitive Behaviors in Autonomous Driving Under Generative World Model".
-
GenAD: "Generalized Predictive Model for Autonomous Driving".

-
GenAD: "Generative End-to-End Autonomous Driving".

-
NeMo: "Neural Volumetric World Models for Autonomous Driving".
-
MARL-CCE: "Modelling-Competitive-Behaviors-in-Autonomous-Driving-Under-Generative-World-Model".
-
ViDAR: "Visual Point Cloud Forecasting enables Scalable Autonomous Driving".

-
Drive-WM: "Driving into the Future: Multiview Visual Forecasting and Planning with World Model for Autonomous Driving".

-
Cam4DOCC: "Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications".

-
Panacea: "Panoramic and Controllable Video Generation for Autonomous Driving".

-
OccWorld: "Learning a 3D Occupancy World Model for Autonomous Driving".

-
DrivingDiffusion: "Layout-Guided multi-view driving scene video generation with latent diffusion model".

-
SafeDreamer: "Safe Reinforcement Learning with World Models".
-
MagicDrive: "Street View Generation with Diverse 3D Geometry Control".

-
DriveDreamer: "Towards Real-world-driven World Models for Autonomous Driving".

-
SEM2: "Enhance Sample Efficiency and Robustness of End-to-end Urban Autonomous Driving via Semantic Masked World Model".
- COMPARATIVE STUDY OF WORLD MODELS: "COMPARATIVE STUDY OF WORLD MODELS, NVAE- BASED HIERARCHICAL MODELS, AND NOISYNET- AUGMENTED MODELS IN CARRACING-V2".
- Knowledge Graphs as World Models: "Knowledge Graphs as World Models for Material-Aware Obstacle Handling in Autonomous Vehicles".
- Uncertainty Modeling: "Uncertainty Modeling in Autonomous Vehicle Trajectory Prediction: A Comprehensive Survey".
- Divide and Merge: "Divide and Merge: Motion and Semantic Learning in End-to-End Autonomous Driving".
- RDAR: "RDAR: Reward-Driven Agent Relevance Estimation for Autonomous Driving".
World Models for Embodied AI
1. Foundation Embodied World Models
- [⭐️] Genie Envisioner: "Genie Envisioner: A Unified World Foundation Platform for Robotic Manipulation".

- [⭐️] WoW, "WoW: Towards a World omniscient World model Through Embodied Interaction".

- UnifoLM-WMA-0, "UnifoLM-WMA-0: A World-Model-Action (WMA) Framework under UnifoLM Family".
- [⭐️] iVideoGPT, "iVideoGPT: Interactive VideoGPTs are Scalable World Models".

- Direct Robot Configuration Space Construction: "Direct Robot Configuration Space Construction using Convolutional Encoder-Decoders".
- ViPRA: "ViPRA: Video Prediction for Robot Actions".
- ROPES: "ROPES: Robotic Pose Estimation via Score-based Causal Representation Learning".
- [⭐️] Qwen-RobotWorld, "Qwen-RobotWorld Technical Report: Unifying Embodied World Modeling through Language-Conditioned Video Generation".

- [⭐️] Xiaomi-Robotics-U0: "Xiaomi-Robotics-U0: Unified Embodied Synthesis with World Foundation Model".

- Masked Visual Actions: "Masked Visual Actions for Unified World Modeling".
- Hydra-0: "Hydra-0: Action Flow for Generalist World Modeling and Control".
- Zero-WAM: "Zero-WAM: In-Context World-Action Modeling from Human Videos for Open-Ended Task Generalization".
- WALL-SS: "WALL-SS: Scaling Long-horizon World Models via Next-Scale Autoregression".
- Riemann-1.0: "Riemann-1.0: An Embodied World Action Model for Physical AI".
- ZimaBlue: "ZimaBlue: Evolving Generalizable World Action Models through Scalable Video Pre-training".

- [⭐️] OpenWAM: "OpenWAM: An Open, Modular Exploration Towards Systematic World-Action Model Pretraining".
- SyncWorld: "SyncWorld: Visual Calibration Enables World Models as Zero-Shot Simulators".
2. World Models for Manipulation
- [⭐️] PointWorld,

- [⭐️] Dex-WM, "".

- [⭐️] FLARE, "FLARE: Robot Learning with Implicit World Modeling".

- [⭐️] Enerverse, "EnerVerse: Envisioning Embodied Future Space for Robotics Manipulation".

- [⭐️] AgiBot-World, "AgiBot World Colosseo: A Large-scale Manipulation Platform for Scalable and Intelligent Embodied Systems".

- [⭐️] DyWA: "DyWA: Dynamics-adaptive World Action Model for Generalizable Non-prehensile Manipulation"

- [⭐️] TesserAct, "TesserAct: Learning 4D Embodied World Models".

- [⭐️] DreamGen: "DreamGen: Unlocking Generalization in Robot Learning through Video World Models".

- [⭐️] HiP, "Compositional Foundation Models for Hierarchical Planning".

- [⭐️] VLA-JEPA, "VLA-JEPA: Enhancing Vision-Language-Action Model with Latent World Model".

- PAR: "Physical Autoregressive Model for Robotic Manipulation without Action Pretraining".

- iMoWM: "iMoWM: Taming Interactive Multi-Modal World Model for Robotic Manipulation".

- WristWorld: "WristWorld: Generating Wrist-Views via 4D World Models for Robotic Manipulation".
- "A Recipe for Efficient Sim-to-Real Transfer in Manipulation with Online Imitation-Pretrained World Models".

- EMMA: "EMMA: Generalizing Real-World Robot Manipulation via Generative Visual Transfer".

- PhysTwin, "PhysTwin: Physics-Informed Reconstruction and Simulation of Deformable Objects from Videos".

- [⭐️] KeyWorld: "KeyWorld: Key Frame Reasoning Enables Effective and Efficient World Models".

- World4RL: "World4RL: Diffusion World Models for Policy Refinement with Reinforcement Learning for Robotic Manipulation".

- [⭐️] SAMPO: "SAMPO:Scale-wise Autoregression with Motion PrOmpt for generative world models".

- PhysicalAgent: "PhysicalAgent: Towards General Cognitive Robotics with Foundation World Models".

- "Empowering Multi-Robot Cooperation via Sequential World Models".

- [⭐️] "Learning Primitive Embodied World Models: Towards Scalable Robotic Learning".

- [⭐️] GWM: "GWM: Towards Scalable Gaussian World Models for Robotic Manipulation".

- [⭐️] Flow-as-Action, "Latent Policy Steering with Embodiment-Agnostic Pretrained World Models".

- EmbodieDreamer: "EmbodieDreamer: Advancing Real2Sim2Real Transfer for Policy Training via Embodied World Modeling".

- WEAVER: "WEAVER, Better, Faster, Longer: An Effective World Model for Robotic Manipulation".

- PhysisForcing: "PhysisForcing: Physics Reinforced World Simulator for Robotic Manipulation".

- RynnWorld-4D: "RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation".

- RynnWorld-Teleop: "RynnWorld-Teleop: An Action-Conditioned World Model for Digital Teleoperation".

- RoboScape: "RoboScape: Physics-informed Embodied World Model".

- FWM, "Factored World Models for Zero-Shot Generalization in Robotic Manipulation".

- [⭐️] ParticleFormer: "ParticleFormer: A 3D Point Cloud World Model for Multi-Object, Multi-Material Robotic Manipulation".

- ManiGaussian++: "ManiGaussian++: General Robotic Bimanual Manipulation with Hierarchical Gaussian World Model".

- ReOI: "Reimagination with Test-time Observation Interventions: Distractor-Robust World Model Predictions for Visual Model Predictive Control".

- GAF: "GAF: Gaussian Action Field as a Dynamic World Model for Robotic Manipulation".

- "Prompting with the Future: Open-World Model Predictive Control with Interactive Digital Twins".

- "Time-Aware World Model for Adaptive Prediction and Control".

- [⭐️] 3DFlowAction: "3DFlowAction: Learning Cross-Embodiment Manipulation from 3D Flow World Model".

- [⭐️] ORV: "ORV: 4D Occupancy-centric Robot Video Generation".

- [⭐️] WoMAP: "WoMAP: World Models For Embodied Open-Vocabulary Object Localization".

- "Sparse Imagination for Efficient Visual World Model Planning".

- [⭐️] OSVI-WM: "OSVI-WM: One-Shot Visual Imitation for Unseen Tasks using World-Model-Guided Trajectory Generation".

- [⭐️] LaDi-WM: "LaDi-WM: A Latent Diffusion-based World Model for Predictive Manipulation".

- FlowDreamer: "FlowDreamer: A RGB-D World Model with Flow-based Motion Representations for Robot Manipulation".

- PIN-WM: "PIN-WM: Learning Physics-INformed World Models for Non-Prehensile Manipulation".

- RoboMaster, "Learning Video Generation for Robotic Manipulation with Collaborative Trajectory Control".

- ManipDreamer: "ManipDreamer: Boosting Robotic Manipulation World Model with Action Tree and Visual Guidance".

- [⭐️] AdaWorld: "AdaWorld: Learning Adaptable World Models with Latent Actions"

- "Towards Suturing World Models: Learning Predictive Models for Robotic Surgical Tasks"

- [⭐️] EVA: "EVA: An Embodied World Model for Future Video Anticipation".

- "Representing Positional Information in Generative World Models for Object Manipulation".

- DexSim2Real$^2$: "DexSim2Real$^2: Building Explicit World Model for Precise Articulated Object Dexterous Manipulation".

- "Physically Embodied Gaussian Splatting: A Realtime Correctable World Model for Robotics".

- [⭐️] LUMOS: "LUMOS: Language-Conditioned Imitation Learning with World Models".

- [⭐️] "Object-Centric World Model for Language-Guided Manipulation"

- [⭐️] DEMO^3: "Multi-Stage Manipulation with Demonstration-Augmented Reward, Policy, and World Model Learning"

- "Strengthening Generative Robot Policies through Predictive World Modeling".

- RoboHorizon: "RoboHorizon: An LLM-Assisted Multi-View World Model for Long-Horizon Robotic Manipulation.

- Dream to Manipulate: "Dream to Manipulate: Compositional World Models Empowering Robot Imitation Learning with Imagination".

- [⭐️] RoboDreamer: "RoboDreamer: Learning Compositional World Models for Robot Imagination".

- [⭐️] Vidar: "Vidar: Embodied Video Diffusion Model for Generalist Manipulation".
- ManiGaussian: "ManiGaussian: Dynamic Gaussian Splatting for Multi-task Robotic Manipulation".

- [⭐️] WHALE: "WHALE: Towards Generalizable and Scalable World Models for Embodied Decision-making".

- [⭐️] VisualPredicator: "VisualPredicator: Learning Abstract World Models with Neuro-Symbolic Predicates for Robot Planning".

- [⭐️] "Multi-Task Interactive Robot Fleet Learning with Visual World Models".

- PIVOT-R: "PIVOT-R: Primitive-Driven Waypoint-Aware World Model for Robotic Manipulation".

- Video2Action, "Grounding Video Models to Actions through Goal Conditioned Exploration".

- Diffuser, "Planning with Diffusion for Flexible Behavior Synthesis".

- Decision Diffuser, "Is Conditional Generative Modeling all you need for Decision-Making?".

- Potential Based Diffusion Motion Planning, "Potential Based Diffusion Motion Planning".

- GRIM: "GRIM: Task-Oriented Grasping with Conditioning on Generative Examples".
- World4Omni: "World4Omni: A Zero-Shot Framework from Image Generation World Model to Robotic Manipulation".
- In-Context Policy Iteration: "In-Context Policy Iteration for Dynamic Manipulation".
- HDFlow: "HDFlow: Hierarchical Diffusion-Flow Planning for Long-horizon Robotic Assembly".
- Mobile Manipulation with Active Inference: "Mobile Manipulation with Active Inference for Long-Horizon Rearrangement Tasks".
- [⭐️] Hierarchical World Model, "H-WM: Robotic Task and Motion Planning Guided by Hierarchical World Model".

- Cosmos Policy: "Cosmos Policy: Fine-Tuning Video Models for Visuomotor Control and Planning".

- DiT4DiT: "DiT4DiT: Jointly Modeling Video Dynamics and Actions for Generalizable Robot Control".

- GEM-4D, "GEM-4D: Geometry-Enhanced Video World Models for Robot Manipulation".

- GaussianDream, "GaussianDream: A Feed-Forward 3D Gaussian World Model for Robotic Manipulation".

- Demo-JEPA, "Demo-JEPA: Joint-Embedding Predictive Architecture for One-shot Cross-Embodiment Imitation".

- Action-State Consistency, "Is the Future Compatible? Diagnosing Dynamic Consistency in World Action Models".

- DriftWorld: "DriftWorld: Fast World Modeling through Drifting".

- Robot-Factored World Models: "Robot-Factored World Models via Robot Rendering".
- DreamX-Phi 1.0: "DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation".
- EgoGenesis: "EgoGenesis: Egocentric World-Action Modeling with Online Anchored Projective Memory and Action-3D RoPE".
- N0-TWAM, "N_0-TWAM: Scaling Tactile-Native World-Action Model for Contact-Rich Manipulation".
3. World Models for Navigation
- [⭐️] NWM, "Navigation World Models".

- EfficientNWM, "An Efficient and Multi-Modal Navigation System with One-Step World Model".

- [⭐️] MindJourney: "MindJourney: Test-Time Scaling with World Models for Spatial Reasoning".

- Test-Time Scaling: "Test-Time Scaling with World Models for Spatial Reasoning".
- Scaling Inference-Time Search: "Scaling Inference-Time Search with Vision Value Model for Improved Visual Comprehension".
- FalconWing: "FalconWing: An Ultra-Light Fixed-Wing Platform for Indoor Aerial Applications".
- Foundation Models as World Models: "Foundation Models as World Models: A Foundational Study in Text-Based GridWorlds".
- Geosteering Through the Lens of Decision Transformers: "Geosteering Through the Lens of Decision Transformers: Toward Embodied Sequence Decision-Making".
- Latent Weight Diffusion: "Latent Weight Diffusion: Generating reactive policies instead of trajectories".
- Abstract Sim2Real: "Abstract Sim2Real through Approximate Information States".
- FLAM: "FLAM: Scaling Latent Action Models with Factorization".
- NavMorph: "NavMorph: A Self-Evolving World Model for Vision-and-Language Navigation in Continuous Environments".

- Unified World Models: "Unified World Models: Memory-Augmented Planning and Foresight for Visual Navigation".
 [code]
- RECON, "Rapid Exploration for Open-World Navigation with Latent Goal Models".

- WMNav: "WMNav: Integrating Vision-Language Models into World Models for Object Goal Navigation".

- NavCoT, "NavCoT: Boosting LLM-Based Vision-and-Language Navigation via Learning Disentangled Reasoning".

- NaVi-WM, "Deductive Chain-of-Thought Augmented Socially-aware Robot Navigation World Model".

- AIF, "Deep Active Inference with Diffusion Policy and Multiple Timescale World Model for Real-World Exploration and Navigation".

- "Kinodynamic Motion Planning for Mobile Robot Navigation across Inconsistent World Models".

- "World Model Implanting for Test-time Adaptation of Embodied Agents".

- "Imaginative World Modeling with Scene Graphs for Embodied Agent Navigation".

- [⭐️] Persistent Embodied World Models, "Learning 3D Persistent Embodied World Models".

- "Perspective-Shifted Neuro-Symbolic World Models: A Framework for Socially-Aware Robot Navigation"

- X-MOBILITY: "X-MOBILITY: End-To-End Generalizable Navigation via World Modeling".

- MWM, "Masked World Models for Visual Control".

4. World Models for Locomotion
Locomotion:
- [⭐️] Ego-VCP, "Ego-Vision World Model for Humanoid Contact Planning".

- [⭐️] RWM-O, "Offline Robotic World Model: Learning Robotic Policies without a Physics Simulator".

- [⭐️] DWL: "Advancing Humanoid Locomotion: Mastering Challenging Terrains with Denoising World Model Learning".

- HRSSM: "Learning Latent Dynamic Robust Representations for World Models".

- WMP: "World Model-based Perception for Visual Legged Locomotion".

- TrajWorld, "Trajectory World Models for Heterogeneous Environments".

- Puppeteer: "Hierarchical World Models as Visual Whole-Body Humanoid Controllers".

- ProTerrain: "ProTerrain: Probabilistic Physics-Informed Rough Terrain World Modeling".

- Occupancy World Model, "Occupancy World Model for Robots".

- [⭐️] "Accelerating Model-Based Reinforcement Learning with State-Space World Models".

- [⭐️] "Learning Humanoid Locomotion with World Model Reconstruction".

- [⭐️] Robotic World Model: "Robotic World Model: A Neural Network Simulator for Robust Policy Optimization in Robotics.

Loco-Manipulation:
- [⭐️] 1X World Model, 1X World Model.
- [⭐️] GROOT-Dreams, "Dream Come True — NVIDIA Isaac GR00T-Dreams Advances Robot Training With Synthetic Data and Neural Simulation".
- Humanoid World Models: "Humanoid World Models: Open World Foundation Models for Humanoid Robotics".

- Ego-Agent, "EgoAgent: A Joint Predictive Agent Model in Egocentric Worlds".

- D^2PO, "World Modeling Makes a Better Planner: Dual Preference Optimization for Embodied Task Planning"

- COMBO: "COMBO: Compositional World Models for Embodied Multi-Agent Cooperation.

- Scalable Humanoid Whole-Body Control: "Scalable Humanoid Whole-Body Control via Differentiable Neural Network Dynamics".
- HuWo: "HuWo: Building Physical Interaction World Models for Humanoid Robot Locomotion".
- Bridging the Sim-to-Real Gap: "Bridging the Sim-to-Real Gap in Humanoid Dynamics via Learned Nonlinear Operators".
- GigaBrain-WBC-0.5: "GigaBrain-WBC-0.5: A Behavior World Model for Robust Whole-Body Control with Environment Interaction".
5. World Models x VLAs
Unifying World Models and VLAs in one model:
- [⭐️] CoT-VLA: "CoT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models".

- [⭐️] UP-VLA, "UP-VLA: A Unified Understanding and Prediction Model for Embodied Agent".

- [⭐️] VPP, "Video Prediction Policy: A Generalist Robot Policy with Predictive Visual Representations".

- [⭐️] FLARE: "FLARE: Robot Learning with Implicit World Modeling".
- [⭐️] MinD: "MinD: Unified Visual Imagination and Control via Hierarchical World Models".

- [⭐️] DreamVLA, "DreamVLA: A Vision-Language-Action Model Dreamed with Comprehensive World Knowledge".

- [⭐️] WorldVLA: "WorldVLA: Towards Autoregressive Action World Model".

- 3D-VLA: "3D-VLA: A 3D Vision-Language-Action Generative World Model".

- LAWM: "Latent Action Pretraining Through World Modeling".

- [⭐️] UniVLA: "UniVLA: Unified Vision-Language-Action Model".

- [⭐️] dVLA, "dVLA: Diffusion Vision-Language-Action Model with Multimodal Chain-of-Thought".

- [⭐️] Vidar, "Vidar: Embodied Video Diffusion Model for Generalist Manipulation".

- [⭐️] UD-VLA, "Unified Diffusion VLA: Vision-Language-Action Model via Joint Discrete Denoising Diffusion Process".

- Goal-VLA: "Goal-VLA: Image-Generative VLMs as Object-Centric World Models Empowering Zero-shot Robot Manipulation".

- Vidarc: "Vidarc: Embodied Video Diffusion Model for Closed-loop Control".

- [⭐️] VideoVLA: "VideoVLA: Video Generators Can Be Generalizable Robot Manipulators".

- [⭐️] Motus: "Motus: A Unified Latent Action World Model".

- [⭐️] mimic-video: "mimic-video: Video-Action Models for Generalizable Robot Control Beyond VLAs".

- InternVLA-A1.5, "InternVLA-A1.5: Unifying Understanding, Latent Foresight, and Action for Compositional Generalization".

Combining World Models and VLAs:
- [⭐️] Ctrl-World: "Ctrl-World: A Controllable Generative World Model for Robot Manipulation".

- VLA-RFT: "VLA-RFT: Vision-Language-Action Reinforcement Fine-tuning with Verified Rewards in World Simulators".

- World-Env: "World-Env: Leveraging World Model as a Virtual Environment for VLA Post-Training".

- [⭐️] Self-Improving Embodied Foundation Models, "Self-Improving Embodied Foundation Models".

- GigaBrain-0.5M*, GigaBrain-0.5M*: a VLA That Learns From World Model-Based Reinforcement Learning.

- RISE: "RISE: Self-Improving Robot Policy with Compositional World Model".

- GigaBrain-0, GigaBrain-0: A World Model-Powered Vision-Language-Action Model.

- NinA: "NinA: Normalizing Flows in Action. Training VLA Models with Normalizing Flows".
- Ada-Diffuser: "Ada-Diffuser: Latent-Aware Adaptive Diffusion for Decision-Making".
- Steering Diffusion Policies: "Steering Diffusion Policies with Value-Guided Denoising".
- SPUR: "SPUR: Scaling Reward Learning from Human Demonstrations".
- A Smooth Sea Never Made a Skilled SAILOR: "A Smooth Sea Never Made a Skilled SAILOR: Robust Imitation via Learning to Search".
- RADI: "RADI: LLMs as World Models for Robotic Action Decomposition and Imagination".
- WMPO: "WMPO: World Model-based Policy Optimization for Vision-Language-Action Models".

- Motus2: "Motus2: A Self-Evolving General World Model for Dexterous Manipulation".
6. World Models x Policy Learning
This subsection focuses on general policy learning methods in embodied intelligence via leveraging world models.
- [⭐️] LingBot-VA, "LingBot-VA: Causal video-action world model for generalist robot control".

- [⭐️] LingBot-VA 2.0, "Native Video-Action Pretraining for Generalizable Robot Control".

- [⭐️] UWM, "Unified World Models: Coupling Video and Action Diffusion for Pretraining on Large Robotic Datasets".

- [⭐️] UVA, Unified Video Action Model.

- DiWA, "DiWA: Diffusion Policy Adaptation with World Models".

- [⭐️] Dreamerv4, "Training Agents Inside of Scalable World Models".

- LVP, "Large Video Planner Enables Generalizable Robot Control".

- [⭐️] LDA-1B, "LDA-1B: Scaling Latent Dynamics Action Model via Universal Embodied Data Ingestion".

- ABot-M0.5, "ABot-M0.5: Unified Mobility-and-Manipulation World Action Model".

- EgoWAM: "EgoWAM: World Action Models Beyond Pixels with In-the-Wild Egocentric Human Data".

- WAM-TTT: "WAM-TTT: Steering World-Action Models by Watching Human Play at Test Time".

- FlowWAM: "FlowWAM: Optical Flow as a Unified Action Representation for World Action Models".

- GigaWorld-Policy-0.5: "GigaWorld-Policy-0.5: A Faster and Stronger WAM Empowered by AutoResearch".

- WorldScape Policy 2.0: "WorldScape Policy 2.0: Empowering Steerable World Action Modeling with Reasoning-Augmented Memory".
- [⭐️] Dyna-2: "Dyna-2: A 1-Million-Hour Scaling Law for World-Action Models".
- Latent Action Learning Requires Supervision: "Latent Action Learning Requires Supervision in the Presence of Distractors".
- Beyond Experience: "Beyond Experience: Fictive Learning as an Inherent Advantage of World Models".
- Robotic World Model: "Robotic World Model: A Neural Network Simulator for Robust Policy Optimization in Robotics".
- Sim-to-Real Contact-Rich Pivoting: "Sim-to-Real Contact-Rich Pivoting via Optimization-Guided RL with Vision and Touch".
- Hierarchical Task Environments: "Hierarchical Task Environments as the Next Frontier for Embodied World Models in Robot Soccer".
7. World Models for Policy evaluation
Real-world policy evaluation is expensive and noisy. The promise of world models is by accurately capturing environment dynamics, it can serve as a surrogate evaluation environment with high correlation to the policy performance in the real world. Before world models, the role for that was simulators:
- [⭐️] Simpler, "Evaluating Real-World Robot Manipulation Policies in Simulation".

For World Model Evaluation:
- [⭐️] WorldGym, "WorldGym: Evaluating Robot Policies in a World Model".

- [⭐️] WorldEval: "WorldEval: World Model as Real-World Robot Policies Evaluator".

- [⭐️] WoW!: "WOW!: World Models in a Closed-Loop World".
- Cosmos-Surg-dVRK: "Cosmos-Surg-dVRK: World Foundation Model-based Automated Online Evaluation of Surgical Robot Policy Learning".

- [⭐️] SC3-Eval, "SC3-Eval: Evaluating Robot Foundation Models via Self-Consistent Video Generation".

- [⭐️] GigaWorld-1, "GigaWorld-1: A Roadmap to Build World Models for Robot Policy Evaluation".

- StressDream: "StressDream: Steering Video World Models for Robust Policy Evaluation and Improvement".

World Models for Science
Related resource:
- World Models for Healthcare - Medical world models, patient digital twins, and counterfactual simulators for clinical planning.
Natural Science:
- [⭐️] CellFlux, "CellFlux: Simulating Cellular Morphology Changes via Flow Matching".

- CheXWorld, "CheXWorld: Exploring Image World Modeling for Radiograph Representation Learning".

- EchoWorld: "EchoWorld: Learning Motion-Aware World Models for Echocardiography Probe Guidance".

- ODesign, "ODesign: A World Model for Biomolecular Interaction Design."

- [⭐️] SFP, "Spatiotemporal Forecasting as Planning: A Model-Based Reinforcement Learning Approach with Generative World Models".

- Xray2Xray, "Xray2Xray: World Model from Chest X-rays with Volumetric Context".

- [⭐️] Medical World Model: "Medical World Model: Generative Simulation of Tumor Evolution for Treatment Planning".

- Surgical Vision World Model, "Surgical Vision World Model".

- MicroVerse: "MicroVerse: A Preliminary Exploration Toward a Micro-World Simulation".

Social Science:
- Social World Models, "Social World Models".

- "Social World Model-Augmented Mechanism Design Policy Learning".

- SocioVerse, "SocioVerse: A World Model for Social Simulation Powered by LLM Agents and A Pool of 10 Million Real-World Users".

- Effectively Designing 2-Dimensional Sequence Models: "Effectively Designing 2-Dimensional Sequence Models for Multivariate Time Series".
- A Virtual Reality-Integrated System: "A Virtual Reality-Integrated System for Behavioral Analysis in Neurological Decline".
- TwinMarket: "TwinMarket: A Scalable Behavioral and Social Simulation for Financial Markets".
- Latent Representation Encoding: "Latent Representation Encoding and Multimodal Biomarkers for Post-Stroke Speech Assessment".
- Reconstructing Dynamics: "Reconstructing Dynamics from Steady Spatial Patterns with Partial Observations".
- SP: Learning Physics from Sparse Observations: "SP: Learning Physics from Sparse Observations — Three Pitfalls of PDE-Constrained Diffusion Models".
- SP: Continuous Autoregressive Generation: "SP: Continuous Autoregressive Generation with Mixture of Gaussians".
- EquiReg: "EquiReg: Symmetry-Driven Regularization for Physically Grounded Diffusion-based Inverse Solvers".
- Neural Modular World Model: "Neural Modular World Model".
- Bidding for Influence: "Bidding for Influence: Auction-Driven Diffusion Image Generation".
- PINT: "PINT: Physics-Informed Neural Time Series Models with Applications to Long-term Inference on WeatherBench 2m-Temperature Data".
- HEP-JEPA: "HEP-JEPA: A foundation model for collider physics".
Positions on World Models
- [⭐️] Video as the New Language for Real-World Decision Making, "Video as the New Language for Real-World Decision Making".

- [⭐️] Critiques of World Models, "Critiques of World Models".

- LAW, "Language Models, Agent Models, and World Models: The LAW for Machine Reasoning and Planning".

- [⭐️] Compositional Generative Modeling: A Single Model is Not All You Need, "Compositional Generative Modeling: A Single Model is Not All You Need".

- Interactive Generative Video as Next-Generation Game Engine, "Position: Interactive Generative Video as Next-Generation Game Engine".

- Quo Vadis, World Modeling?, "Quo Vadis, World Modeling?".
- A Proposal for Networks Capable of Continual Learning: "A Proposal for Networks Capable of Continual Learning".
- Towards Unified Expressive Policy Optimization: "Opinion: Towards Unified Expressive Policy Optimization for Robust Robot Learning".
- Learning Intuitive Physics: "Opinion: Learning Intuitive Physics Requires More Than Visual Data".
- A Unified World Model: "Opinion: A Unified World Model is the cornerstone for integrating perception, reasoning, and decision-making in embodied AI".
- Small VLAs: "Opinion: Small VLAs Self-Learn Consistency".
- How Can Causal AI Benefit World Models?: "Opinion: How Can Causal AI Benefit World Models?".
Theory & World Models Explainability
- [⭐️] General agents Contain World Models, "General agents contain world models".

- [⭐️] When Do Neural Networks Learn World Models? "When Do Neural Networks Learn World Models?"

- [⭐️] Reconstruction or Semantics? What Makes a Latent Space Useful for Robotic World Models

- What Does it Mean for a Neural Network to Learn a 'World Model'?, "What Does it Mean for a Neural Network to Learn a 'World Model'?".

- Transformer cannot learn HMMs (sometimes) "On Limitation of Transformer for Learning HMMs".

- Identifiable latent space world models through contrastive learning, "Self-supervised contrastive learning performs non-linear system identification".
- [⭐️] Inductive Bias Probe, "What Has a Foundation Model Found? Using Inductive Bias to Probe for World Models".

- [⭐️] Dynamical Systems Learning for World Models, "When do World Models Successfully Learn Dynamical Systems?".

- How Hard is it to Confuse a World Model?, "How Hard is it to Confuse a World Model?".

- Partially Observable Safety: "How Well Do Latent World Models Understand Partially Observable Safety Constraints?".

- ICL Emergence, "Context and Diversity Matter: The Emergence of In-Context Learning in World Models".

- [⭐️] Scaling Law,"Scaling Laws for Pre-training Agents and World Models".

- LLM World Model, "Linear Spatial World Models Emerge in Large Language Models".

- Revisiting Othello, "Revisiting the Othello World Model Hypothesis".

- [⭐️] Transformers Use Causal World Models, "Transformers Use Causal World Models in Maze-Solving Tasks".

- [⭐️] Causal World Model inside NTP, "A Causal World Model Underlying Next Token Prediction: Exploring GPT in a Controlled Environment".

- When do neural networks learn world models?: "When do neural networks learn world models?".
- Utilizing World Models: "Utilizing World Models for Adaptively Covariate Acquisition Under Limited Budget for Causal Decision Making Problem".
General Approaches to World Models
1. Foundation World Models
SOTA Models:
Interactive Video Generation:
- [⭐️] Genie 3, "Genie 3: A new frontier for world models".
- [⭐️] V-JEPA 2, "V-JEPA 2: Self-Supervised Video Models Enable Understanding, Prediction and Planning".

- [⭐️] V-JEPA 2.1, "V-JEPA 2.1: Unlocking Dense Features in Video Self-Supervised Learning".

- [⭐️] Cosmos Predict 2.5 & Cosmos Transfer 2.5, "Cosmos Predict 2.5 & Transfer 2.5: Evolving the World Foundation Models for Physical AI".
- [⭐️] Cosmos 3, "Cosmos 3: Omnimodal World Models for Physical AI".

- [⭐️] FlashDreams, "FlashDreams: High-performance inference and serving for interactive autoregressive video and world models".
- [⭐️] HY-World 1.5, "HY-World 1.5: A Systematic Framework for Interactive World Modeling with Real-Time Latency and Geometric Consistency".
- [⭐️] PAN, "PAN: A World Model for General, Interactable, and Long-Horizon World Simulation".

- [⭐️] LingBot-World, "Advancing Open-source World Models".

- LingBot-World 2.0, "Infinite Worlds with Versatile Interactions".

- [⭐️] DreamZero, "DreamZero: World Action Models are Zero-shot Policies".

- SANA-WM: "SANA-WM: Efficient Minute-Scale World Modeling with Hybrid Linear Diffusion Transformer".

- [⭐️] Kairos, "Kairos: A Native World Model Stack for Physical AI".

- [⭐️] DreamX-World 1.0, "DreamX-World 1.0: A General-Purpose Interactive World Model".

- Orca: "Orca: The World is in Your Mind".

- AlayaWorld v1.1: "AlayaWorld: Interactive Long-Horizon World Modeling - Full Technical Report (v1.1)".
- Alaya-EVOKE: "Alaya-EVOKE: From Linear-Scaling Supervision to Endless World".

- [⭐️] EchoWM, "EchoWM: Open and Enterable Omnimodal World Models".
- [⭐️] JoyAI-Echo-1.5, "Long-Horizon Audio-Visual Generation for Persistent Stories and Interactive Worlds".
- SolarWM: "SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models".

- WorldCrafter: "WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory".
3D Scene Generation:
- [⭐️] RTFM, "RTFM: A Real-Time Frame Model".
- [⭐️] Marble, "Generating Bigger and Better Worlds".
- [⭐️] WorldGen, "WorldGen: From Text to Traversable and Interactive 3D Worlds".

Classics:
Genie Series:
- [⭐️] Genie 2, "Genie 2: A Large-Scale Foundation World Model".
- [⭐️] Genie, "Genie: Generative Interactive Environments".

V-JEPA Series:
- [⭐️] V-JEPA: "V-JEPA: Video Joint Embedding Predictive Architecture".
- LeWM: "LeWorldModel: Stable End-to-End Joint-Embedding Predictive Architecture from Pixels".
- Interpreting JEPA: "Interpreting Physics in Video World Models".

Cosmos Series:
- [⭐️] Cosmos, "Cosmos World Foundation Model Platform for Physical AI".

World-Lab Projects:
- Generating Worlds, "Generating Worlds".
Other Awesome Models:
- [⭐️] Pandora, "Pandora: Towards General World Model with Natural Language Actions and Video States".

- [⭐️] UniSim, "UniSim: Learning Interactive Real-World Simulators".

- Masked Generative Priors: "Masked Generative Priors Improve World Models Sequence Modelling Capabilities".
- Recurrent world model: "Recurrent world model with tokenized latent states".
- Mixture-of-Transformers: "Mixture-of-Transformers: A Sparse and Scalable Architecture for Multi-Modal Foundation Models".
- Mixture-of-Mamba: "Mixture-of-Mamba: Enhancing Multi-Modal State-Space Models with Modality-Aware Sparsity".
- Improving World Models: "Improving World Models using Supervision with Co-Evolving Linear Probes".
- MS-SSM: "MS-SSM: A Multi-Scale State Space Model for Enhanced Sequence Modeling".
- Fixed-Point RNNs: "Fixed-Point RNNs: From Diagonal to Dense in a Few Iterations".
- ACDiT: "ACDiT: Interpolating Autoregressive Conditional Modeling and Diffusion Transformer".
- FPAN: "FPAN: Mitigating Replication in Diffusion Models through the Fine-Grained Probabilistic Addition of Noise to Token Embeddings".
- SPARTAN: "SPARTAN: A Sparse Transformer World Model Attending to What Matters".

2. Building World Models from 2D Vision Priors
The represents a "bottom-up" approach to achieving intelligence, sensorimotor before abstraction. In the 2D pixel space, world models often build upon pre-existing image/video generation approaches.
To what extent does Vision Intelligence exist in Video Generation Models:
- [⭐️] Sora, "Video generation models as world simulators". [Technical report]
- [⭐️] Veo-3 are zero-shot Learners and Reasoners, "Video models are zero-shot learners and reasoners".

- [⭐️] PhyWorld, "How Far is Video Generation from World Model: A Physical Law Perspective".

- Emergent Few-Shot Learning in Video Diffusion Models, "From Generation to Generalization: Emergent Few-Shot Learning in Video Diffusion Models".

- VideoVerse: "VideoVerse: How Far is Your T2V Generator from a World Model?".

- [⭐️] Emu 3.5, "Emu3.5: Native Multimodal Models are World Learners".

- [⭐️] Emu 3, "Emu3: Next-Token Prediction is All You Need".

Useful Approaches in Video Generation:
- [⭐️] Diffusion Forcing, "Diffusion Forcing: Next-token Prediction Meets Full-Sequence Diffusion".

- [⭐️] DFoT, "History-Guided Video Diffusion".

- [⭐️] Self-Forcing, "Self Forcing: Bridging the Train-Test Gap in Autoregressive Video Diffusion".

- CausVid, "From Slow Bidirectional to Fast Causal Video Generators".

- Longlive, "LongLive: Real-time Interactive Long Video Generation".

- ControlNet, "Adding Conditional Control to Text-to-Image Diffusion Models".

- ReCamMaster, "ReCamMaster: Camera-Controlled Generative Rendering from A Single Video".

- SpaceTimePilot, “SpaceTimePilot: Generative Rendering of Dynamic Scenes Across Space and Time”.

- NeoVerse, "NeoVerse: Enhancing 4D World Model with in-the-wild Monocular Videos".

- [⭐️] Causal Forcing, "Causal Forcing: Autoregressive Diffusion Distillation Done Right for High-Quality Real-Time Interactive Video Generation".

- [⭐️] Next Forcing, "Next Forcing: Causal World Modeling with Multi-Chunk Prediction".

- [⭐️] Helios, "Helios: Real Real-Time Long Video Generation Model".

From Video Generation Models to World Models:
- [⭐️] Vid2World: "Vid2World: Crafting Video Diffusion Models to Interactive World Models".

- AVID, "AVID: Adapting Video Diffusion Models to World Models".

- IRASim, "IRASim: A Fine-Grained World Model for Robot Manipulation".

- DWS, "Pre-Trained Video Generative Models as World Simulators".

- Video Adapter, "Probabilistic Adaptation of Black-Box Text-to-Video Models".
- Video Agent, "VideoAgent: Self-Improving Video Generation".

- WISA, "WISA: World Simulator Assistant for Physics-Aware Text-to-Video Generation".

- Force Prompting, "Force Prompting: Video Generation Models Can Learn and Generalize Physics-based Control Signals".

Pixel Space World Models:
- [⭐️] Owl-1: "Owl-1: Omni World Model for Consistent Long Video Generation".

- [⭐️] Long-Context State-Space Video World Models, "Long-Context State-Space Video World Models".

- [⭐️] StateSpaceDiffuser: "StateSpaceDiffuser: Bringing Long Context to Diffusion World Models".

- [⭐️] Geometry Forcing: "Geometry Forcing: Marrying Video Diffusion and 3D Representation for Consistent World Modeling".

- Yume: "Yume: An Interactive World Generation Model".

- PSI, "World Modeling with Probabilistic Structure Integration".

- Martian World Models, "Martian World Models: Controllable Video Synthesis with Physically Accurate 3D Reconstructions".

- WorldDreamer: "WorldDreamer: Towards General World Models for Video Generation via Predicting Masked Tokens".

- EBWM: "Cognitively Inspired Energy-Based World Models".

- "Video World Models with Long-term Spatial Memory".

- VRAG, "Learning World Models for Interactive Video Generation".

- DRAW, "Adapting World Models with Latent-State Dynamics Residuals".

- ForeDiff, "Consistent World Models via Foresight Diffusion".

- Distribution Recovery: "Distribution Recovery in Compact Diffusion World Models via Conditioned Frame Interpolation".
- EmbodiedScene: "EmbodiedScene: Towards Automated Generation of Diverse and Realistic Scenes for Embodied AI".
- BEYOND SINGLE-STEP: "BEYOND SINGLE-STEP: MULTI-FRAME ACTION- CONDITIONED VIDEO GENERATION FOR REINFORCE- MENT LEARNING ENVIRONMENTS".
- Adaptive Attention-Guided Masking: "Adaptive Attention-Guided Masking in Vision Transformers for Self-Supervised Hyperspectral Feature Learning".
- Implicit State Estimation: "Implicit State Estimation via Video Replanning".
- Enhancing Long Video Generation Consistency: "Enhancing Long Video Generation Consistency without Tuning: Time-Frequency Analysis, Prompt Alignment, and Theory".
- Can Image-To-Video Models Simulate Pedestrian Dynamics?: "Can Image-To-Video Models Simulate Pedestrian Dynamics?".
- Eyes of the DINO: "Eyes of the DINO: Learning Physical World Models from Uncurated Web Videos".
- Video Self-Distillation: "Video Self-Distillation for Single-Image Encoders: A Step Toward Physically Plausible Perception".
- Learning Skill Abstraction: "Learning Skill Abstraction from Action-Free Videos via Optical Flow".
- CRISP: "CRISP: Contact-guided Real2Sim from Monocular Video with Planar Scene Primitives".
- Whole-Body Conditioned Egocentric Video Prediction: "Whole-Body Conditioned Egocentric Video Prediction".

- Hand2World: "Hand2World: Autoregressive Egocentric Interaction Generation via Free-Space Hand Gestures".

- Taming generative world models: "Taming generative world models for zero-shot optical flow extraction".

3. Building World Models from 3D Vision Priors
3D Mesh is also a useful representaiton of the physical world, including benefits such as spatial consistency.
- [⭐️] WorldGrow: "WorldGrow: Generating Infinite 3D World".

- TRELLISWorld: "TRELLISWorld: Training-Free World Generation from Object Generators".

- Terra: "Terra: Explorable Native 3D World Model with Point Latents".

- MorphoSim: "MorphoSim: An Interactive, Controllable, and Editable Language-guided 4D World Simulator".
 [code]
- EvoWorld: "EvoWorld: Evolving Panoramic World Generation with Explicit 3D Memory".

- [⭐️] FantasyWorld: "FantasyWorld: Geometry-Consistent World Modeling via Unified Video and 3D Prediction".

- [⭐️] Aether: "Aether: Geometric-Aware Unified World Modeling".

- HERO: "HERO: Hierarchical Extrapolation and Refresh for Efficient World Models".

- UrbanWorld: "UrbanWorld: An Urban World Model for 3D City Generation".

- DeepVerse: "DeepVerse: 4D Autoregressive Video Generation as a World Model".

- ABot-3DWorld 0: "ABot-3DWorld 0: A Universal World Model to Explore Any 3D Space".

- EnerVerse-AC: "EnerVerse-AC: Envisioning Embodied Environments with Action Condition".
- Adapting a World Model: "Adapting a World Model for Trajectory Following in a 3D Game".
- SteerX: "SteerX: Creating Any Camera-Free 3D and 4D Scenes with Geometric Steering".
- SP- PhysicsNeRF: "SP- PhysicsNeRF: Physics-Guided 3D Reconstruction from Sparse Views".
4. Building World Models from Language Priors
The represents a "top-down" approach to achieving intelligence, abstraction before sensorimotor.
Aiming to Advance LLM/VLM skills:
- [⭐️] VLWM, "Planning with Reasoning using Vision Language World Model".

- [⭐️] Agent Learning via Early Experience, "Agent Learning via Early Experience".

- [⭐️] CWM, "CWM: An Open-Weights LLM for Research on Code Generation with World Models".

- [⭐️] RAP, "Reasoning with language model is planning with world model".

- SURGE, "SURGE: On the Potential of Large Language Models as General-Purpose Surrogate Code Executors".

- LLM-Sim: "Can Language Models Serve as Text-Based World Simulators?".

- WorldLLM, "WorldLLM: Improving LLMs' world modeling using curiosity-driven theory-making".

- LLMs as World Models, "LLMs as World Models: Data-Driven and Human-Centered Pre-Event Simulation for Disaster Impact Assessment".

- [⭐️] LWM: "World Model on Million-Length Video And Language With RingAttention".

- "Evaluating World Models with LLM for Decision Making".

- LLMPhy: "LLMPhy: Complex Physical Reasoning Using Large Language Models and World Models".

- LLMCWM: "Language Agents Meet Causality -- Bridging LLMs and Causal World Models".

- "Making Large Language Models into World Models with Precondition and Effect Knowledge".

- CityBench: "CityBench: Evaluating the Capabilities of Large Language Model as World Model".

- [⭐️] Qwen-AgentWorld: "Qwen-AgentWorld: Language World Models for General Agents".

Aiming to enhance computer-use agent performance:
- [⭐️] Neural-OS, "NeuralOS: Towards Simulating Operating Systems via Neural Generative Models".

- R-WoM: "R-WoM: Retrieval-augmented World Model For Computer-use Agents".

- [⭐️] SimuRA: "SimuRA: Towards General Goal-Oriented Agent via Simulative Reasoning Architecture with LLM-Based World Model".

- WebSynthesis, "WebSynthesis: World-Model-Guided MCTS for Efficient WebUI-Trajectory Synthesis".

- WKM: "Agent Planning with World Knowledge Model".

- WebDreamer, "Is Your LLM Secretly a World Model of the Internet? Model-Based Planning for Web Agents".

- "Web Agents with World Models: Learning and Leveraging Environment Dynamics in Web Navigation".

- WebEvolver: "WebEvolver: Enhancing Web Agent Self-Improvement with Coevolving World Model".

- WALL-E 2.0: "WALL-E 2.0: World Alignment by NeuroSymbolic Learning improves World Model-based LLM Agents".

- ViMo: "ViMo: A Generative Visual GUI World Model for App Agent".

- [⭐️] Dyna-Think: "Dyna-Think: Synergizing Reasoning, Acting, and World Model Simulation in AI Agents".

- FPWC, "Unlocking Smarter Device Control: Foresighted Planning with a World Model-Driven Code Execution Approach".

Symbolic World Models:
- [⭐️] PoE-World, "PoE-World: Compositional World Modeling with Products of Programmatic Experts".

- "One Life to Learn: Inferring Symbolic World Models for Stochastic Environments from Unguided Exploration".

- "Finite Automata Extraction: Low-data World Model Learning as Programs from Gameplay Video".

- "Synthesizing world models for bilevel planning".

- "Generating Symbolic World Models via Test-time Scaling of Large Language Models".

- Neuro-Symbolic World Models: "Neuro-Symbolic World Models for Adapting to Open World Novelty".

LLM-in-the-loop World Generation:
- LatticeWorld, "LatticeWorld: A Multimodal Large Language Model-Empowered Framework for Interactive Complex World Generation".

- Text2World: "Text2World: Benchmarking Large Language Models for Symbolic World Model Generation".

5. Building World Models by Bridging Language and Vision Intelligence
A recent trend of work is bridging highly-compressed semantic tokens (e.g. language) with information-sparse cues in the observation space (e.g. vision). This results in World Models that combine high-level and low-level intelligence.
- [⭐️] VAGEN, "VAGEN: Reinforcing World Model Reasoning for Multi-Turn VLM Agents".

- [⭐️] Semantic World Models, "Semantic World Models".

- DyVA: "Can World Models Benefit VLMs for World Dynamics?".

- From Foresight to Forethought: "From Foresight to Forethought: VLM-In-the-Loop Policy Steering via Latent Alignment".
- SEAL: "SEAL: SEmantic-Augmented Imitation Learning via Language Model".
- Programmatic Video Prediction: "Programmatic Video Prediction Using Large Language Models".
- Emergent Stack Representations: "Emergent Stack Representations in Modeling Counter Languages Using Transformers".
- DIALOGUES BETWEEN ADAM AND EVE: "DIALOGUES BETWEEN ADAM AND EVE: EXPLORATION OF UNKNOWN CIVILIZATION LANGUAGE BY LLM".
- Memory Helps, but Confabulation Misleads: "Memory Helps, but Confabulation Misleads: Understanding Streaming Events in Videos with MLLMs".
- Reframing LLM Finetuning: "Reframing LLM Finetuning Through the Lens of Bayesian Optimization".
- TrajEvo: "TrajEvo: Designing Trajectory Prediction Heuristics via LLM-driven Evolution".
- CCC: "CCC: Enhancing Video Generation via Structured MLLM Feedback".
- VLA-OS: "VLA-OS: Structuring and Dissecting Planning Representations and Paradigms in Vision-Language-Action Models".
- LLM-Guided Probabilistic Program Induction: "LLM-Guided Probabilistic Program Induction for POMDP Model Estimation".
- Decoupled Planning and Execution: "Decoupled Planning and Execution with LLM-Driven World Models for Efficient Task Planning".
- The Physical Basis of Prediction: "The Physical Basis of Prediction: World Model Formation in Neural Organoids via an LLM-Generated Curriculum".
- Avi: "Avi: A 3D Vision-Language Action Model Architecture generating Action from Volumetric Inference".
- Plan Verification: "Plan Verification for LLM-Based Embodied Task Completion Agents".
- SpatialThinker: "SpatialThinker: Reinforcing 3D Reasoning in Multimodal LLMs via Spatial Rewards".
- How Foundational Skills Influence VLM-based Embodied Agents: "How Foundational Skills Influence VLM-based Embodied Agents: A Native Perspective".
- Towards Fine-tuning a Small Vision-Language Model: "Towards Fine-tuning a Small Vision-Language Model for Aerial Navigation".
- Improvisational Reasoning: "Improvisational Reasoning with Vision-Language Models for Grounded Procedural Planning".
- Vision-Language Reasoning for Burn Depth Assessment: "Vision-Language Reasoning for Burn Depth Assessment with Structured Diagnostic Hypotheses".
- WALL-E: "WALL-E: World Alignment by NeuroSymbolic Learning improves World Model-based LLM Agents".
- Puffin: "Thinking with Camera: A Unified Multimodal Model for Camera-Centric Understanding and Generation".

- IVT: "Beyond Visual CoT: Internalized Visual Thinking for Proactive Video Reasoning".
- Code World Model: "Code World Model: Coding Agent as World Brain".
- Code as Worlds: "Code as Worlds: Agentic Discovery of Executable World Representations for Physical Reasoning".
6. Latent Space World Models
While learning in the observation space (pixel, 3D mesh, language, etc.) is a common approach, for many applications (planning, policy evaluation, etc.) learning in latent space is sufficient or is believed to lead to even better performace.
- [⭐️] DINO-WM, "DINO-WM: World Models on Pre-trained Visual Features enable Zero-shot Planning".

- [⭐️] DINO-World, "Back to the Features: DINO as a Foundation for Video World Models".

- [⭐️] DINO-Foresight, "DINO-Foresight: Looking into the Future with DINO
".

- AWM, "Learning Abstract World Models with a Group-Structured Latent Space".

JEPA is a special kind of learning in latent space, where the loss is put on the latent space, and the encoder & predictor are co-trained. However, the usage of JEPA is not only in world models (e.g. V-JEPA2-AC), but also representation learning (e.g. I-JEPA, V-JEPA), we provide representative works from both perspectives below.
- [⭐️] I-JEPA,"Self-Supervised Learning from Images with a Joint-Embedding Predictive Architecture". [


Similar repos


A Curated List of Awesome Works in World Modeling, Aiming to Serve as a One-stop Resource for Researchers, Practitioners, and Enthusiasts Interested in World Modeling.
3,441
170 commits
updated Sep 23, 2026
README
🌍 Awesome World Models
📜 A Curated List of Amazing Works in World Modeling, spanning applications in Embodied AI, Autonomous Driving, Natural Language Processing and Agents.
Based on Awesome-World-Model-for-Autonomous-Driving and Awesome-World-Model-for-Robotics.
Photo Credit: Gemini-Nano-Banana🍌.
🚩 News & Updates
Major updates and announcements are shown below. Scroll for full timeline.
🚀 [2025-11] 1k+ Stars ⭐️ Under 30 Days — 🌍 Awesome World Models reached 1k github stars within 30 days of initial release, let's go!!!
🗺️ [2025-10] Enhanced Visual Navigation — Introduced badge system for papers! All entries now display
🔥 [2025-10] Repository Launch — Awesome World Models is now live! We're building a comprehensive collection spanning Embodied AI, Autonomous Driving, NLP, and more. See CONTRIBUTING.md for how to contribute.
💡 [Ongoing] Community Contributions Welcome — Help us maintain the most up-to-date world models resource! Submit papers via PR or contact us at email.
⭐ [Ongoing] Support This Project — If you find this useful, please cite our work and give us a star. Share with your research community!
Overview
- 🎯 Aim of the project
- 📚 Definition of World Models
- 🧭 Tutorials & Starter Resources
- 📖 Surveys of World Models
- 🎮 World Models for Game Simulation
- 🚗 World Models for Autonomous Driving
- 🤖 World Models for Embodied AI
- 🔬 World Models for Science
- 💭 Positions on World Models
- 📐 Theory & World Models Explainability
- 🛠️ General Approaches to World Models
- 📊 Evaluating World Models
- 🙏 Acknowledgements
- 📝 Citation
Aim of the Project
World Models have become a hot topic in both research and industry, attracting unprecedented attention from the AI community and beyond. However, due to the interdisciplinary nature of the field (and because the term "world model" simply sounds amazing), the concept has been used with varying definitions across different domains.
This repository aims to:
- 🔍 Organize the rapidly growing body of world model research across multiple application domains
- 🗺️ Provide a minimalist map of how world models are utilized in different fields (Embodied AI, Autonomous Driving, NLP, etc.)
- 🤝 Bridge the gap between different communities working on world models with varying perspectives
- 📚 Serve as a one-stop resource for researchers, practitioners, and enthusiasts interested in world modeling
- 🚀 Track the latest developments and breakthroughs in this exciting field
Whether you're a researcher looking for related work, a practitioner seeking implementation references, or simply curious about world models, we hope this curated list helps you navigate the landscape!
Definition of World Models
While world models' outreach has been expanded again and again, it is widely adopted that the original sources of world models come from these two papers:
- [⭐️] World Models, World Models.
- [⭐️] Yann Lecun's Speech, "A Path Towards Autonomous Machine Intelligence".
Some other great blogposts on world models include:
- [⭐️] Towards Video World Models, "Towards Video World Models".
- Status of World Models in 2025, "Beyond the Hype: How I See World Models Evolving in 2025".
- [⭐️] Jim Fan's tweet.
- [⭐️] World Model Workshop at Montreal, "Keynote: Yoshua Bengio, Yann Lecun, Jurgen Schmidhuber, Sherry Yang, Shirley Ho, etc. (Youtube Streamning included)".
Tutorials & Starter Resources
- [⭐️] Nano World Models, "Nano World Models: A Minimalist Implementation of Future Video Prediction".
- [⭐️] minWM, "minWM: A Full-Stack Open-Source Framework for Real-Time Interactive Video World Models".
- StableWM, "stable-worldmodel: A Platform for Reproducible World Modeling Research and Evaluation".
- WorldFoundry, "WorldFoundry: Unified World Model Inference & Evaluation Infrastructure".
- world-models.io, "A structured knowledge platform for discovering and comparing AI world models across robotics, model-based reinforcement learning, simulation engines, embodied AI, and autonomous systems, with model profiles, comparisons, research, benchmarks, and a practical taxonomy."
Surveys of World Models
1. World Models and Video Generation:
- [⭐️] Is Sora a World Simulator, "Is Sora a World Simulator? A Comprehensive Survey on General World Models and Beyond".
- Physics Cognition in Video Generation, "Exploring the Evolution of Physics Cognition in Video Generation: A Survey".
- From Generation to Simulation, "From Generation to Simulation: How Far Are World Models from Being True Simulators?".
2. World Models and 3D Generation:
- [⭐️] 3D and 4D World Modeling: A Survey, "3D and 4D World Modeling: A Survey".
- [⭐️] Understanding World or Predicting Future?, "Understanding World or Predicting Future? A Comprehensive Survey of World Models".
- From 2D to 3D Cognition, "From 2D to 3D Cognition: A Brief Survey of General World Models".
3. World Models and Embodied Artificial Intelligence:
- [⭐️] World Models for Embodied AI, "A Comprehensive Survey on World Models for Embodied AI".
- World Models and Physical Simulation, "A Survey: Learning Embodied Intelligence from Physical Simulators and World Models".
- Embodied AI Agents: Modeling the World, "Embodied AI Agents: Modeling the World".
- Aligning Cyber Space with Physical World, "Aligning Cyber Space with Physical World: A Comprehensive Survey on Embodied AI".
- Physical Grounding in World Models, "From Generative Engines to Actionable Simulators: The Imperative of Physical Grounding in World Models".
- [⭐️] World Action Models v.s. VLA, "Do World Action Models Generalize Better than VLAs? A Robustness Study".
- WorldScape, "WorldScape: A Unified Real-time World Model Integrating Locomotion And Manipulation".
- [⭐️] World Model for Robot Learning: "World Model for Robot Learning: A Comprehensive Survey".
4. World Models for Autonomous Driving:
- [⭐️] A Survey of World Models for Autonomous Driving, "A Survey of World Models for Autonomous Driving".
- World Models for Autonomous Driving: An Initial Survey, "World Models for Autonomous Driving: An Initial Survey".
- Interplay Between Video Generation and World Models in Autonomous Driving, "Exploring the Interplay Between Video Generation and World Models in Autonomous Driving: A Survey".
- Progressive Robustness-Aware World Models in Autonomous Driving: A Survey, "Progressive Robustness-Aware World Models in Autonomous Driving: A Survey".
5. Other Good Surveys:
- From Masks to Worlds, "From Masks to Worlds: A Hitchhiker's Guide to World Models".
- The Safety Challenge of World Models, "The Safety Challenge of World Models for Embodied AI Agents: A Review".
- World Models in AI: Like a Child, "World Models in Artificial Intelligence: Sensing, Learning, and Reasoning Like a Child".
- World Model Safety, "World Models: The Safety Perspective".
- Model-based reinforcement learning: "A survey on model-based reinforcement learning".
- On Memory: A comparison of memory mechanisms in world models: "On Memory: A comparison of memory mechanisms in world models".
World Models for Game Simulation
Pixel Space:
- [⭐️] GameNGen, "Diffusion Models Are Real-Time Game Engines".
- [⭐️] DIAMOND, "Diffusion for World Modeling: Visual Details Matter in Atari".
- MineWorld, "MineWorld: a Real-Time and Open-Source Interactive World Model on Minecraft".
- Oasis, "Oasis: A Universe in a Transformer".
- AnimeGamer, "AnimeGamer: Infinite Anime Life Simulation with Next Game State Prediction".
- [⭐️] Matrix-Game, "Matrix-Game: Interactive World Foundation Model."
- [⭐️] Matrix-Game 2.0, Matrix-Game 2.0: An Open-Source, Real-Time, and Streaming Interactive World Model.
- [⭐️] Matrix-Game 3.0, "Matrix-Game 3.0: Real-Time and Streaming Interactive World Model with Long-Horizon Memory".
- Matrix-Game 3.5, "Matrix-Game 3.5: Enhancing Real-Time Streaming Interactive World Models with Patch Memory".
- RealPlay, "From Virtual Games to Real-World Play".
- GameFactory, "GameFactory: Creating New Games with Generative Interactive Videos".
- WORLDMEM, "Worldmem: Long-term Consistent World Simulation with Memory".
- Waypoint-1, "The Path to Real-Time Worlds and Why It Matters".
- SCOPE, "SCOPE: Simulating Cross-game Operations in Playable Environments for FPS World Models".
- MIRA, "Multiplayer Interactive World Models with Representation Autoencoders".
- Solaris, "Solaris: Building a Multiplayer Video World Model in Minecraft".
- ABot-World-0: "ABot-World-0: Infinite Interactive World Rollout on a Single Desktop GPU".
- ForgeWM: "ForgeWM: Progressive Causal Training for Few-Step Action-Conditioned Video World Models".
- Programmable World Model: "Programmable World Model".
3D Mesh Space:
- [⭐️] HunyuanWorld 1.0, HunyuanWorld 1.0: Generating Immersive, Explorable, and Interactive 3D Worlds from Words or Pixels.
- [⭐️] Matrix-3D, Matrix-3D: Omnidirectional Explorable 3D World Generation.
World Models for Autonomous Driving
Refer to https://github.com/LMD0311/Awesome-World-Model for full list.
[!NOTE] 📢 [Call for Maintenance] The repo creator is no expert of autonomous driving, so this is a more-than-concise list of works without classification. We anticipate community effort on turning this section cleaner and more well-sorted.
- [⭐️] Cosmos-Drive-Dreams, "Cosmos-Drive-Dreams: Scalable Synthetic Driving Data Generation with World Foundation Models".
- [⭐️] OmniDreams, "NVIDIA OmniDreams: Real-Time Generative World Model for Closed-Loop Autonomous Vehicle Simulation".
- [⭐️] GAIA-2, "GAIA-2: A Controllable Multi-View Generative World Model for Autonomous Driving".
- WorldLens, "WorldLens: Full-Spectrum Evaluations of Driving World Models in Real World".
- Copilot4D, "Copilot4D: Learning Unsupervised World Models for Autonomous Driving via Discrete Diffusion".
- OmniNWM: "OmniNWM: Omniscient Driving Navigation World Models".
- GAIA-1, "Introducing GAIA-1: A Cutting-Edge Generative AI Model for Autonomy".
-
PWM, "From Forecasting to Planning: Policy World Model for Collaborative State-Action Prediction".
-
Dream4Drive, "Rethinking Driving World Model as Synthetic Data Generator for Perception Tasks".
-
SparseWorld, "SparseWorld: A Flexible, Adaptive, and Efficient 4D Occupancy World Model Powered by Sparse and Dynamic Queries".
-
DriveVLA-W0: "DriveVLA-W0: World Models Amplify Data Scaling Law in Autonomous Driving".
-
"Enhancing Physical Consistency in Lightweight World Models".
-
IRL-VLA: "IRL-VLA: Training an Vision-Language-Action Policy via Reward World Model".
-
LiDARCrafter: "LiDARCrafter: Dynamic 4D World Modeling from LiDAR Sequences".
-
FASTopoWM: "FASTopoWM: Fast-Slow Lane Segment Topology Reasoning with Latent World Models".
-
Orbis: "Orbis: Overcoming Challenges of Long-Horizon Prediction in Driving World Models".
-
"World Model-Based End-to-End Scene Generation for Accident Anticipation in Autonomous Driving".
-
NRSeg: "NRSeg: Noise-Resilient Learning for BEV Semantic Segmentation via Driving World Models"
-
World4Drive: "World4Drive: End-to-End Autonomous Driving via Intention-aware Physical Latent World Model".
-
Epona: "Epona: Autoregressive Diffusion World Model for Autonomous Driving".
-
"Towards foundational LiDAR world models with efficient latent flow matching".
-
SceneDiffuser++: "SceneDiffuser++: City-Scale Traffic Simulation via a Generative World Model".
-
COME: "COME: Adding Scene-Centric Forecasting Control to Occupancy World Model"
-
STAGE: "STAGE: A Stream-Centric Generative World Model for Long-Horizon Driving-Scene Simulation".
-
ReSim: "ReSim: Reliable World Simulation for Autonomous Driving".
-
"Ego-centric Learning of Communicative World Models for Autonomous Driving".
-
V2XCrafter: "V2XCrafter: Learning to Generate Driving Scene Across Agents".
-
Dreamland: "Dreamland: Controllable World Creation with Simulator and Generative Models".
-
LongDWM: "LongDWM: Cross-Granularity Distillation for Building a Long-Term Driving World Model".
-
GeoDrive: "GeoDrive: 3D Geometry-Informed Driving World Model with Precise Action Control".
-
FutureSightDrive: "FutureSightDrive: Thinking Visually with Spatio-Temporal CoT for Autonomous Driving".
-
Raw2Drive: "Raw2Drive: Reinforcement Learning with Aligned World Models for End-to-End Autonomous Driving (in CARLA v2)".
-
VL-SAFE: "VL-SAFE: Vision-Language Guided Safety-Aware Reinforcement Learning with World Models for Autonomous Driving".
-
PosePilot: "PosePilot: Steering Camera Pose for Generative World Models with Self-supervised Depth".
-
"World Model-Based Learning for Long-Term Age of Information Minimization in Vehicular Networks".
-
"Learning to Drive from a World Model".
-
DriVerse: "DriVerse: Navigation World Model for Driving Simulation via Multimodal Trajectory Prompting and Motion Alignment".
-
"End-to-End Driving with Online Trajectory Evaluation via BEV World Model".
-
"Knowledge Graphs as World Models for Semantic Material-Aware Obstacle Handling in Autonomous Vehicles".
-
MiLA: "MiLA: Multi-view Intensive-fidelity Long-term Video Generation World Model for Autonomous Driving".
-
SimWorld: "SimWorld: A Unified Benchmark for Simulator-Conditioned Scene Generation via World Model".
-
UniFuture: "Seeing the Future, Perceiving the Future: A Unified Driving World Model for Future Generation and Perception".
-
EOT-WM: "Other Vehicle Trajectories Are Also Needed: A Driving World Model Unifies Ego-Other Vehicle Trajectories in Video Latent Space".
-
"Temporal Triplane Transformers as Occupancy World Models".
-
InDRiVE: "InDRiVE: Intrinsic Disagreement based Reinforcement for Vehicle Exploration through Curiosity Driven Generalized World Model".
-
MaskGWM: "MaskGWM: A Generalizable Driving World Model with Video Mask Reconstruction".
-
Dream to Drive: "Dream to Drive: Model-Based Vehicle Control Using Analytic World Models".
-
"Semi-Supervised Vision-Centric 3D Occupancy World Model for Autonomous Driving".
-
"Dream to Drive with Predictive Individual World Model".
-
HERMES: "HERMES: A Unified Self-Driving World Model for Simultaneous 3D Scene Understanding and Generation".
-
AdaWM: "AdaWM: Adaptive World Model based Planning for Autonomous Driving".
-
AD-L-JEPA: "AD-L-JEPA: Self-Supervised Spatial World Models with Joint Embedding Predictive Architecture for Autonomous Driving with LiDAR Data".
-
DrivingWorld: "DrivingWorld: Constructing World Model for Autonomous Driving via Video GPT".
-
DrivingGPT: "DrivingGPT: Unifying Driving World Modeling and Planning with Multi-modal Autoregressive Transformers".
-
"An Efficient Occupancy World Model via Decoupled Dynamic Flow and Image-assisted Training".
-
GEM: "GEM: A Generalizable Ego-Vision Multimodal World Model for Fine-Grained Ego-Motion, Object Dynamics, and Scene Composition Control".
-
GaussianWorld: "GaussianWorld: Gaussian World Model for Streaming 3D Occupancy Prediction".
-
Doe-1: "Doe-1: Closed-Loop Autonomous Driving with Large World Model".
-
"Physical Informed Driving World Model".
-
InfiniCube: "InfiniCube: Unbounded and Controllable Dynamic 3D Driving Scene Generation with World-Guided Video Models".
-
InfinityDrive: "InfinityDrive: Breaking Time Limits in Driving World Models".
-
ReconDreamer: "ReconDreamer: Crafting World Models for Driving Scene Reconstruction via Online Restoration".
-
Imagine-2-Drive: "Imagine-2-Drive: High-Fidelity World Modeling in CARLA for Autonomous Vehicles".
-
DynamicCity: "DynamicCity: Large-Scale 4D Occupancy Generation from Dynamic Scenes".
-
DriveDreamer4D: "World Models Are Effective Data Machines for 4D Driving Scene Representation".
-
DOME: "Taming Diffusion Model into High-Fidelity Controllable Occupancy World Model".
-
SSR: "Does End-to-End Autonomous Driving Really Need Perception Tasks?".
-
"Mitigating Covariate Shift in Imitation Learning for Autonomous Vehicles Using Latent Space Generative World Models".
-
LatentDriver: "Learning Multiple Probabilistic Decisions from Latent World Model in Autonomous Driving".
-
RenderWorld: "World Model with Self-Supervised 3D Label".
-
OccLLaMA: "An Occupancy-Language-Action Generative World Model for Autonomous Driving".
-
DriveGenVLM: "Real-world Video Generation for Vision Language Model based Autonomous Driving".
-
Drive-OccWorld: "Driving in the Occupancy World: Vision-Centric 4D Occupancy Forecasting and Planning via World Models for Autonomous Driving".
-
CarFormer: "Self-Driving with Learned Object-Centric Representations".
-
BEVWorld: "A Multimodal World Model for Autonomous Driving via Unified BEV Latent Space".
-
TOKEN: "Tokenize the World into Object-level Knowledge to Address Long-tail Events in Autonomous Driving".
-
UMAD: "Unsupervised Mask-Level Anomaly Detection for Autonomous Driving".
-
SimGen: "Simulator-conditioned Driving Scene Generation".
-
AdaptiveDriver: "Planning with Adaptive World Models for Autonomous Driving".
-
UnO: "Unsupervised Occupancy Fields for Perception and Forecasting".
-
LAW: "Enhancing End-to-End Autonomous Driving with Latent World Model".
-
Delphi: "Unleashing Generalization of End-to-End Autonomous Driving with Controllable Long Video Generation".
-
OccSora: "4D Occupancy Generation Models as World Simulators for Autonomous Driving".
-
MagicDrive3D: "Controllable 3D Generation for Any-View Rendering in Street Scenes".
-
Vista: "A Generalizable Driving World Model with High Fidelity and Versatile Controllability".
-
CarDreamer: "Open-Source Learning Platform for World Model based Autonomous Driving".
-
DriveSim: "Probing Multimodal LLMs as World Models for Driving".
-
DriveWorld: "4D Pre-trained Scene Understanding via World Models for Autonomous Driving".
-
LidarDM: "Generative LiDAR Simulation in a Generated World".
-
SubjectDrive: "Scaling Generative Data in Autonomous Driving via Subject Control".
-
DriveDreamer-2: "LLM-Enhanced World Models for Diverse Driving Video Generation".
-
Think2Drive: "Efficient Reinforcement Learning by Thinking in Latent World Model for Quasi-Realistic Autonomous Driving".
-
MARL-CCE: "Modelling Competitive Behaviors in Autonomous Driving Under Generative World Model".
-
GenAD: "Generalized Predictive Model for Autonomous Driving".
-
GenAD: "Generative End-to-End Autonomous Driving".
-
NeMo: "Neural Volumetric World Models for Autonomous Driving".
-
MARL-CCE: "Modelling-Competitive-Behaviors-in-Autonomous-Driving-Under-Generative-World-Model".
-
ViDAR: "Visual Point Cloud Forecasting enables Scalable Autonomous Driving".
-
Drive-WM: "Driving into the Future: Multiview Visual Forecasting and Planning with World Model for Autonomous Driving".
-
Cam4DOCC: "Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications".
-
Panacea: "Panoramic and Controllable Video Generation for Autonomous Driving".
-
OccWorld: "Learning a 3D Occupancy World Model for Autonomous Driving".
-
DrivingDiffusion: "Layout-Guided multi-view driving scene video generation with latent diffusion model".
-
SafeDreamer: "Safe Reinforcement Learning with World Models".
-
MagicDrive: "Street View Generation with Diverse 3D Geometry Control".
-
DriveDreamer: "Towards Real-world-driven World Models for Autonomous Driving".
-
SEM2: "Enhance Sample Efficiency and Robustness of End-to-end Urban Autonomous Driving via Semantic Masked World Model".
- COMPARATIVE STUDY OF WORLD MODELS: "COMPARATIVE STUDY OF WORLD MODELS, NVAE- BASED HIERARCHICAL MODELS, AND NOISYNET- AUGMENTED MODELS IN CARRACING-V2".
- Knowledge Graphs as World Models: "Knowledge Graphs as World Models for Material-Aware Obstacle Handling in Autonomous Vehicles".
- Uncertainty Modeling: "Uncertainty Modeling in Autonomous Vehicle Trajectory Prediction: A Comprehensive Survey".
- Divide and Merge: "Divide and Merge: Motion and Semantic Learning in End-to-End Autonomous Driving".
- RDAR: "RDAR: Reward-Driven Agent Relevance Estimation for Autonomous Driving".
World Models for Embodied AI
1. Foundation Embodied World Models
- [⭐️] Genie Envisioner: "Genie Envisioner: A Unified World Foundation Platform for Robotic Manipulation".
- [⭐️] WoW, "WoW: Towards a World omniscient World model Through Embodied Interaction".
- UnifoLM-WMA-0, "UnifoLM-WMA-0: A World-Model-Action (WMA) Framework under UnifoLM Family".
- [⭐️] iVideoGPT, "iVideoGPT: Interactive VideoGPTs are Scalable World Models".
- Direct Robot Configuration Space Construction: "Direct Robot Configuration Space Construction using Convolutional Encoder-Decoders".
- ViPRA: "ViPRA: Video Prediction for Robot Actions".
- ROPES: "ROPES: Robotic Pose Estimation via Score-based Causal Representation Learning".
- [⭐️] Qwen-RobotWorld, "Qwen-RobotWorld Technical Report: Unifying Embodied World Modeling through Language-Conditioned Video Generation".
- [⭐️] Xiaomi-Robotics-U0: "Xiaomi-Robotics-U0: Unified Embodied Synthesis with World Foundation Model".
- Masked Visual Actions: "Masked Visual Actions for Unified World Modeling".
- Hydra-0: "Hydra-0: Action Flow for Generalist World Modeling and Control".
- Zero-WAM: "Zero-WAM: In-Context World-Action Modeling from Human Videos for Open-Ended Task Generalization".
- WALL-SS: "WALL-SS: Scaling Long-horizon World Models via Next-Scale Autoregression".
- Riemann-1.0: "Riemann-1.0: An Embodied World Action Model for Physical AI".
- ZimaBlue: "ZimaBlue: Evolving Generalizable World Action Models through Scalable Video Pre-training".
- [⭐️] OpenWAM: "OpenWAM: An Open, Modular Exploration Towards Systematic World-Action Model Pretraining".
- SyncWorld: "SyncWorld: Visual Calibration Enables World Models as Zero-Shot Simulators".
2. World Models for Manipulation
- [⭐️] PointWorld,
- [⭐️] Dex-WM, "".
- [⭐️] FLARE, "FLARE: Robot Learning with Implicit World Modeling".
- [⭐️] Enerverse, "EnerVerse: Envisioning Embodied Future Space for Robotics Manipulation".
- [⭐️] AgiBot-World, "AgiBot World Colosseo: A Large-scale Manipulation Platform for Scalable and Intelligent Embodied Systems".
- [⭐️] DyWA: "DyWA: Dynamics-adaptive World Action Model for Generalizable Non-prehensile Manipulation"
- [⭐️] TesserAct, "TesserAct: Learning 4D Embodied World Models".
- [⭐️] DreamGen: "DreamGen: Unlocking Generalization in Robot Learning through Video World Models".
- [⭐️] HiP, "Compositional Foundation Models for Hierarchical Planning".
- [⭐️] VLA-JEPA, "VLA-JEPA: Enhancing Vision-Language-Action Model with Latent World Model".
- PAR: "Physical Autoregressive Model for Robotic Manipulation without Action Pretraining".
- iMoWM: "iMoWM: Taming Interactive Multi-Modal World Model for Robotic Manipulation".
- WristWorld: "WristWorld: Generating Wrist-Views via 4D World Models for Robotic Manipulation".
- "A Recipe for Efficient Sim-to-Real Transfer in Manipulation with Online Imitation-Pretrained World Models".
- EMMA: "EMMA: Generalizing Real-World Robot Manipulation via Generative Visual Transfer".
- PhysTwin, "PhysTwin: Physics-Informed Reconstruction and Simulation of Deformable Objects from Videos".
- [⭐️] KeyWorld: "KeyWorld: Key Frame Reasoning Enables Effective and Efficient World Models".
- World4RL: "World4RL: Diffusion World Models for Policy Refinement with Reinforcement Learning for Robotic Manipulation".
- [⭐️] SAMPO: "SAMPO:Scale-wise Autoregression with Motion PrOmpt for generative world models".
- PhysicalAgent: "PhysicalAgent: Towards General Cognitive Robotics with Foundation World Models".
- "Empowering Multi-Robot Cooperation via Sequential World Models".
- [⭐️] "Learning Primitive Embodied World Models: Towards Scalable Robotic Learning".
- [⭐️] GWM: "GWM: Towards Scalable Gaussian World Models for Robotic Manipulation".
- [⭐️] Flow-as-Action, "Latent Policy Steering with Embodiment-Agnostic Pretrained World Models".
- EmbodieDreamer: "EmbodieDreamer: Advancing Real2Sim2Real Transfer for Policy Training via Embodied World Modeling".
- WEAVER: "WEAVER, Better, Faster, Longer: An Effective World Model for Robotic Manipulation".
- PhysisForcing: "PhysisForcing: Physics Reinforced World Simulator for Robotic Manipulation".
- RynnWorld-4D: "RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation".
- RynnWorld-Teleop: "RynnWorld-Teleop: An Action-Conditioned World Model for Digital Teleoperation".
- RoboScape: "RoboScape: Physics-informed Embodied World Model".
- FWM, "Factored World Models for Zero-Shot Generalization in Robotic Manipulation".
- [⭐️] ParticleFormer: "ParticleFormer: A 3D Point Cloud World Model for Multi-Object, Multi-Material Robotic Manipulation".
- ManiGaussian++: "ManiGaussian++: General Robotic Bimanual Manipulation with Hierarchical Gaussian World Model".
- ReOI: "Reimagination with Test-time Observation Interventions: Distractor-Robust World Model Predictions for Visual Model Predictive Control".
- GAF: "GAF: Gaussian Action Field as a Dynamic World Model for Robotic Manipulation".
- "Prompting with the Future: Open-World Model Predictive Control with Interactive Digital Twins".
- "Time-Aware World Model for Adaptive Prediction and Control".
- [⭐️] 3DFlowAction: "3DFlowAction: Learning Cross-Embodiment Manipulation from 3D Flow World Model".
- [⭐️] ORV: "ORV: 4D Occupancy-centric Robot Video Generation".
- [⭐️] WoMAP: "WoMAP: World Models For Embodied Open-Vocabulary Object Localization".
- "Sparse Imagination for Efficient Visual World Model Planning".
- [⭐️] OSVI-WM: "OSVI-WM: One-Shot Visual Imitation for Unseen Tasks using World-Model-Guided Trajectory Generation".
- [⭐️] LaDi-WM: "LaDi-WM: A Latent Diffusion-based World Model for Predictive Manipulation".
- FlowDreamer: "FlowDreamer: A RGB-D World Model with Flow-based Motion Representations for Robot Manipulation".
- PIN-WM: "PIN-WM: Learning Physics-INformed World Models for Non-Prehensile Manipulation".
- RoboMaster, "Learning Video Generation for Robotic Manipulation with Collaborative Trajectory Control".
- ManipDreamer: "ManipDreamer: Boosting Robotic Manipulation World Model with Action Tree and Visual Guidance".
- [⭐️] AdaWorld: "AdaWorld: Learning Adaptable World Models with Latent Actions"
- "Towards Suturing World Models: Learning Predictive Models for Robotic Surgical Tasks"
- [⭐️] EVA: "EVA: An Embodied World Model for Future Video Anticipation".
- "Representing Positional Information in Generative World Models for Object Manipulation".
- DexSim2Real$^2$: "DexSim2Real$^2: Building Explicit World Model for Precise Articulated Object Dexterous Manipulation".
- "Physically Embodied Gaussian Splatting: A Realtime Correctable World Model for Robotics".
- [⭐️] LUMOS: "LUMOS: Language-Conditioned Imitation Learning with World Models".
- [⭐️] "Object-Centric World Model for Language-Guided Manipulation"
- [⭐️] DEMO^3: "Multi-Stage Manipulation with Demonstration-Augmented Reward, Policy, and World Model Learning"
- "Strengthening Generative Robot Policies through Predictive World Modeling".
- RoboHorizon: "RoboHorizon: An LLM-Assisted Multi-View World Model for Long-Horizon Robotic Manipulation.
- Dream to Manipulate: "Dream to Manipulate: Compositional World Models Empowering Robot Imitation Learning with Imagination".
- [⭐️] RoboDreamer: "RoboDreamer: Learning Compositional World Models for Robot Imagination".
- [⭐️] Vidar: "Vidar: Embodied Video Diffusion Model for Generalist Manipulation".
- ManiGaussian: "ManiGaussian: Dynamic Gaussian Splatting for Multi-task Robotic Manipulation".
- [⭐️] WHALE: "WHALE: Towards Generalizable and Scalable World Models for Embodied Decision-making".
- [⭐️] VisualPredicator: "VisualPredicator: Learning Abstract World Models with Neuro-Symbolic Predicates for Robot Planning".
- [⭐️] "Multi-Task Interactive Robot Fleet Learning with Visual World Models".
- PIVOT-R: "PIVOT-R: Primitive-Driven Waypoint-Aware World Model for Robotic Manipulation".
- Video2Action, "Grounding Video Models to Actions through Goal Conditioned Exploration".
- Diffuser, "Planning with Diffusion for Flexible Behavior Synthesis".
- Decision Diffuser, "Is Conditional Generative Modeling all you need for Decision-Making?".
- Potential Based Diffusion Motion Planning, "Potential Based Diffusion Motion Planning".
- GRIM: "GRIM: Task-Oriented Grasping with Conditioning on Generative Examples".
- World4Omni: "World4Omni: A Zero-Shot Framework from Image Generation World Model to Robotic Manipulation".
- In-Context Policy Iteration: "In-Context Policy Iteration for Dynamic Manipulation".
- HDFlow: "HDFlow: Hierarchical Diffusion-Flow Planning for Long-horizon Robotic Assembly".
- Mobile Manipulation with Active Inference: "Mobile Manipulation with Active Inference for Long-Horizon Rearrangement Tasks".
- [⭐️] Hierarchical World Model, "H-WM: Robotic Task and Motion Planning Guided by Hierarchical World Model".
- Cosmos Policy: "Cosmos Policy: Fine-Tuning Video Models for Visuomotor Control and Planning".
- DiT4DiT: "DiT4DiT: Jointly Modeling Video Dynamics and Actions for Generalizable Robot Control".
- GEM-4D, "GEM-4D: Geometry-Enhanced Video World Models for Robot Manipulation".
- GaussianDream, "GaussianDream: A Feed-Forward 3D Gaussian World Model for Robotic Manipulation".
- Demo-JEPA, "Demo-JEPA: Joint-Embedding Predictive Architecture for One-shot Cross-Embodiment Imitation".
- Action-State Consistency, "Is the Future Compatible? Diagnosing Dynamic Consistency in World Action Models".
- DriftWorld: "DriftWorld: Fast World Modeling through Drifting".
- Robot-Factored World Models: "Robot-Factored World Models via Robot Rendering".
- DreamX-Phi 1.0: "DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation".
- EgoGenesis: "EgoGenesis: Egocentric World-Action Modeling with Online Anchored Projective Memory and Action-3D RoPE".
- N0-TWAM, "N_0-TWAM: Scaling Tactile-Native World-Action Model for Contact-Rich Manipulation".
3. World Models for Navigation
- [⭐️] NWM, "Navigation World Models".
- EfficientNWM, "An Efficient and Multi-Modal Navigation System with One-Step World Model".
- [⭐️] MindJourney: "MindJourney: Test-Time Scaling with World Models for Spatial Reasoning".
- Test-Time Scaling: "Test-Time Scaling with World Models for Spatial Reasoning".
- Scaling Inference-Time Search: "Scaling Inference-Time Search with Vision Value Model for Improved Visual Comprehension".
- FalconWing: "FalconWing: An Ultra-Light Fixed-Wing Platform for Indoor Aerial Applications".
- Foundation Models as World Models: "Foundation Models as World Models: A Foundational Study in Text-Based GridWorlds".
- Geosteering Through the Lens of Decision Transformers: "Geosteering Through the Lens of Decision Transformers: Toward Embodied Sequence Decision-Making".
- Latent Weight Diffusion: "Latent Weight Diffusion: Generating reactive policies instead of trajectories".
- Abstract Sim2Real: "Abstract Sim2Real through Approximate Information States".
- FLAM: "FLAM: Scaling Latent Action Models with Factorization".
- NavMorph: "NavMorph: A Self-Evolving World Model for Vision-and-Language Navigation in Continuous Environments".
- Unified World Models: "Unified World Models: Memory-Augmented Planning and Foresight for Visual Navigation". [code]
- RECON, "Rapid Exploration for Open-World Navigation with Latent Goal Models".
- WMNav: "WMNav: Integrating Vision-Language Models into World Models for Object Goal Navigation".
- NavCoT, "NavCoT: Boosting LLM-Based Vision-and-Language Navigation via Learning Disentangled Reasoning".
- NaVi-WM, "Deductive Chain-of-Thought Augmented Socially-aware Robot Navigation World Model".
- AIF, "Deep Active Inference with Diffusion Policy and Multiple Timescale World Model for Real-World Exploration and Navigation".
- "Kinodynamic Motion Planning for Mobile Robot Navigation across Inconsistent World Models".
- "World Model Implanting for Test-time Adaptation of Embodied Agents".
- "Imaginative World Modeling with Scene Graphs for Embodied Agent Navigation".
- [⭐️] Persistent Embodied World Models, "Learning 3D Persistent Embodied World Models".
- "Perspective-Shifted Neuro-Symbolic World Models: A Framework for Socially-Aware Robot Navigation"
- X-MOBILITY: "X-MOBILITY: End-To-End Generalizable Navigation via World Modeling".
- MWM, "Masked World Models for Visual Control".
4. World Models for Locomotion
Locomotion:
- [⭐️] Ego-VCP, "Ego-Vision World Model for Humanoid Contact Planning".
- [⭐️] RWM-O, "Offline Robotic World Model: Learning Robotic Policies without a Physics Simulator".
- [⭐️] DWL: "Advancing Humanoid Locomotion: Mastering Challenging Terrains with Denoising World Model Learning".
- HRSSM: "Learning Latent Dynamic Robust Representations for World Models".
- WMP: "World Model-based Perception for Visual Legged Locomotion".
- TrajWorld, "Trajectory World Models for Heterogeneous Environments".
- Puppeteer: "Hierarchical World Models as Visual Whole-Body Humanoid Controllers".
- ProTerrain: "ProTerrain: Probabilistic Physics-Informed Rough Terrain World Modeling".
- Occupancy World Model, "Occupancy World Model for Robots".
- [⭐️] "Accelerating Model-Based Reinforcement Learning with State-Space World Models".
- [⭐️] "Learning Humanoid Locomotion with World Model Reconstruction".
- [⭐️] Robotic World Model: "Robotic World Model: A Neural Network Simulator for Robust Policy Optimization in Robotics.
Loco-Manipulation:
- [⭐️] 1X World Model, 1X World Model.
- [⭐️] GROOT-Dreams, "Dream Come True — NVIDIA Isaac GR00T-Dreams Advances Robot Training With Synthetic Data and Neural Simulation".
- Humanoid World Models: "Humanoid World Models: Open World Foundation Models for Humanoid Robotics".
- Ego-Agent, "EgoAgent: A Joint Predictive Agent Model in Egocentric Worlds".
- D^2PO, "World Modeling Makes a Better Planner: Dual Preference Optimization for Embodied Task Planning"
- COMBO: "COMBO: Compositional World Models for Embodied Multi-Agent Cooperation.
- Scalable Humanoid Whole-Body Control: "Scalable Humanoid Whole-Body Control via Differentiable Neural Network Dynamics".
- HuWo: "HuWo: Building Physical Interaction World Models for Humanoid Robot Locomotion".
- Bridging the Sim-to-Real Gap: "Bridging the Sim-to-Real Gap in Humanoid Dynamics via Learned Nonlinear Operators".
- GigaBrain-WBC-0.5: "GigaBrain-WBC-0.5: A Behavior World Model for Robust Whole-Body Control with Environment Interaction".
5. World Models x VLAs
Unifying World Models and VLAs in one model:
- [⭐️] CoT-VLA: "CoT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models".
- [⭐️] UP-VLA, "UP-VLA: A Unified Understanding and Prediction Model for Embodied Agent".
- [⭐️] VPP, "Video Prediction Policy: A Generalist Robot Policy with Predictive Visual Representations".
- [⭐️] FLARE: "FLARE: Robot Learning with Implicit World Modeling".
- [⭐️] MinD: "MinD: Unified Visual Imagination and Control via Hierarchical World Models".
- [⭐️] DreamVLA, "DreamVLA: A Vision-Language-Action Model Dreamed with Comprehensive World Knowledge".
- [⭐️] WorldVLA: "WorldVLA: Towards Autoregressive Action World Model".
- 3D-VLA: "3D-VLA: A 3D Vision-Language-Action Generative World Model".
- LAWM: "Latent Action Pretraining Through World Modeling".
- [⭐️] UniVLA: "UniVLA: Unified Vision-Language-Action Model".
- [⭐️] dVLA, "dVLA: Diffusion Vision-Language-Action Model with Multimodal Chain-of-Thought".
- [⭐️] Vidar, "Vidar: Embodied Video Diffusion Model for Generalist Manipulation".
- [⭐️] UD-VLA, "Unified Diffusion VLA: Vision-Language-Action Model via Joint Discrete Denoising Diffusion Process".
- Goal-VLA: "Goal-VLA: Image-Generative VLMs as Object-Centric World Models Empowering Zero-shot Robot Manipulation".
- Vidarc: "Vidarc: Embodied Video Diffusion Model for Closed-loop Control".
- [⭐️] VideoVLA: "VideoVLA: Video Generators Can Be Generalizable Robot Manipulators".
- [⭐️] Motus: "Motus: A Unified Latent Action World Model".
- [⭐️] mimic-video: "mimic-video: Video-Action Models for Generalizable Robot Control Beyond VLAs".
- InternVLA-A1.5, "InternVLA-A1.5: Unifying Understanding, Latent Foresight, and Action for Compositional Generalization".
Combining World Models and VLAs:
- [⭐️] Ctrl-World: "Ctrl-World: A Controllable Generative World Model for Robot Manipulation".
- VLA-RFT: "VLA-RFT: Vision-Language-Action Reinforcement Fine-tuning with Verified Rewards in World Simulators".
- World-Env: "World-Env: Leveraging World Model as a Virtual Environment for VLA Post-Training".
- [⭐️] Self-Improving Embodied Foundation Models, "Self-Improving Embodied Foundation Models".
- GigaBrain-0.5M*, GigaBrain-0.5M*: a VLA That Learns From World Model-Based Reinforcement Learning.
- RISE: "RISE: Self-Improving Robot Policy with Compositional World Model".
- GigaBrain-0, GigaBrain-0: A World Model-Powered Vision-Language-Action Model.
- NinA: "NinA: Normalizing Flows in Action. Training VLA Models with Normalizing Flows".
- Ada-Diffuser: "Ada-Diffuser: Latent-Aware Adaptive Diffusion for Decision-Making".
- Steering Diffusion Policies: "Steering Diffusion Policies with Value-Guided Denoising".
- SPUR: "SPUR: Scaling Reward Learning from Human Demonstrations".
- A Smooth Sea Never Made a Skilled SAILOR: "A Smooth Sea Never Made a Skilled SAILOR: Robust Imitation via Learning to Search".
- RADI: "RADI: LLMs as World Models for Robotic Action Decomposition and Imagination".
- WMPO: "WMPO: World Model-based Policy Optimization for Vision-Language-Action Models".
- Motus2: "Motus2: A Self-Evolving General World Model for Dexterous Manipulation".
6. World Models x Policy Learning
This subsection focuses on general policy learning methods in embodied intelligence via leveraging world models.
- [⭐️] LingBot-VA, "LingBot-VA: Causal video-action world model for generalist robot control".
- [⭐️] LingBot-VA 2.0, "Native Video-Action Pretraining for Generalizable Robot Control".
- [⭐️] UWM, "Unified World Models: Coupling Video and Action Diffusion for Pretraining on Large Robotic Datasets".
- [⭐️] UVA, Unified Video Action Model.
- DiWA, "DiWA: Diffusion Policy Adaptation with World Models".
- [⭐️] Dreamerv4, "Training Agents Inside of Scalable World Models".
- LVP, "Large Video Planner Enables Generalizable Robot Control".
- [⭐️] LDA-1B, "LDA-1B: Scaling Latent Dynamics Action Model via Universal Embodied Data Ingestion".
- ABot-M0.5, "ABot-M0.5: Unified Mobility-and-Manipulation World Action Model".
- EgoWAM: "EgoWAM: World Action Models Beyond Pixels with In-the-Wild Egocentric Human Data".
- WAM-TTT: "WAM-TTT: Steering World-Action Models by Watching Human Play at Test Time".
- FlowWAM: "FlowWAM: Optical Flow as a Unified Action Representation for World Action Models".
- GigaWorld-Policy-0.5: "GigaWorld-Policy-0.5: A Faster and Stronger WAM Empowered by AutoResearch".
- WorldScape Policy 2.0: "WorldScape Policy 2.0: Empowering Steerable World Action Modeling with Reasoning-Augmented Memory".
- [⭐️] Dyna-2: "Dyna-2: A 1-Million-Hour Scaling Law for World-Action Models".
- Latent Action Learning Requires Supervision: "Latent Action Learning Requires Supervision in the Presence of Distractors".
- Beyond Experience: "Beyond Experience: Fictive Learning as an Inherent Advantage of World Models".
- Robotic World Model: "Robotic World Model: A Neural Network Simulator for Robust Policy Optimization in Robotics".
- Sim-to-Real Contact-Rich Pivoting: "Sim-to-Real Contact-Rich Pivoting via Optimization-Guided RL with Vision and Touch".
- Hierarchical Task Environments: "Hierarchical Task Environments as the Next Frontier for Embodied World Models in Robot Soccer".
7. World Models for Policy evaluation
Real-world policy evaluation is expensive and noisy. The promise of world models is by accurately capturing environment dynamics, it can serve as a surrogate evaluation environment with high correlation to the policy performance in the real world. Before world models, the role for that was simulators:
- [⭐️] Simpler, "Evaluating Real-World Robot Manipulation Policies in Simulation".
For World Model Evaluation:
- [⭐️] WorldGym, "WorldGym: Evaluating Robot Policies in a World Model".
- [⭐️] WorldEval: "WorldEval: World Model as Real-World Robot Policies Evaluator".
- [⭐️] WoW!: "WOW!: World Models in a Closed-Loop World".
- Cosmos-Surg-dVRK: "Cosmos-Surg-dVRK: World Foundation Model-based Automated Online Evaluation of Surgical Robot Policy Learning".
- [⭐️] SC3-Eval, "SC3-Eval: Evaluating Robot Foundation Models via Self-Consistent Video Generation".
- [⭐️] GigaWorld-1, "GigaWorld-1: A Roadmap to Build World Models for Robot Policy Evaluation".
- StressDream: "StressDream: Steering Video World Models for Robust Policy Evaluation and Improvement".
World Models for Science
Related resource:
- World Models for Healthcare - Medical world models, patient digital twins, and counterfactual simulators for clinical planning.
Natural Science:
- [⭐️] CellFlux, "CellFlux: Simulating Cellular Morphology Changes via Flow Matching".
- CheXWorld, "CheXWorld: Exploring Image World Modeling for Radiograph Representation Learning".
- EchoWorld: "EchoWorld: Learning Motion-Aware World Models for Echocardiography Probe Guidance".
- ODesign, "ODesign: A World Model for Biomolecular Interaction Design."
- [⭐️] SFP, "Spatiotemporal Forecasting as Planning: A Model-Based Reinforcement Learning Approach with Generative World Models".
- Xray2Xray, "Xray2Xray: World Model from Chest X-rays with Volumetric Context".
- [⭐️] Medical World Model: "Medical World Model: Generative Simulation of Tumor Evolution for Treatment Planning".
- Surgical Vision World Model, "Surgical Vision World Model".
- MicroVerse: "MicroVerse: A Preliminary Exploration Toward a Micro-World Simulation".
Social Science:
- Social World Models, "Social World Models".
- "Social World Model-Augmented Mechanism Design Policy Learning".
- SocioVerse, "SocioVerse: A World Model for Social Simulation Powered by LLM Agents and A Pool of 10 Million Real-World Users".
- Effectively Designing 2-Dimensional Sequence Models: "Effectively Designing 2-Dimensional Sequence Models for Multivariate Time Series".
- A Virtual Reality-Integrated System: "A Virtual Reality-Integrated System for Behavioral Analysis in Neurological Decline".
- TwinMarket: "TwinMarket: A Scalable Behavioral and Social Simulation for Financial Markets".
- Latent Representation Encoding: "Latent Representation Encoding and Multimodal Biomarkers for Post-Stroke Speech Assessment".
- Reconstructing Dynamics: "Reconstructing Dynamics from Steady Spatial Patterns with Partial Observations".
- SP: Learning Physics from Sparse Observations: "SP: Learning Physics from Sparse Observations — Three Pitfalls of PDE-Constrained Diffusion Models".
- SP: Continuous Autoregressive Generation: "SP: Continuous Autoregressive Generation with Mixture of Gaussians".
- EquiReg: "EquiReg: Symmetry-Driven Regularization for Physically Grounded Diffusion-based Inverse Solvers".
- Neural Modular World Model: "Neural Modular World Model".
- Bidding for Influence: "Bidding for Influence: Auction-Driven Diffusion Image Generation".
- PINT: "PINT: Physics-Informed Neural Time Series Models with Applications to Long-term Inference on WeatherBench 2m-Temperature Data".
- HEP-JEPA: "HEP-JEPA: A foundation model for collider physics".
Positions on World Models
- [⭐️] Video as the New Language for Real-World Decision Making, "Video as the New Language for Real-World Decision Making".
- [⭐️] Critiques of World Models, "Critiques of World Models".
- LAW, "Language Models, Agent Models, and World Models: The LAW for Machine Reasoning and Planning".
- [⭐️] Compositional Generative Modeling: A Single Model is Not All You Need, "Compositional Generative Modeling: A Single Model is Not All You Need".
- Interactive Generative Video as Next-Generation Game Engine, "Position: Interactive Generative Video as Next-Generation Game Engine".
- Quo Vadis, World Modeling?, "Quo Vadis, World Modeling?".
- A Proposal for Networks Capable of Continual Learning: "A Proposal for Networks Capable of Continual Learning".
- Towards Unified Expressive Policy Optimization: "Opinion: Towards Unified Expressive Policy Optimization for Robust Robot Learning".
- Learning Intuitive Physics: "Opinion: Learning Intuitive Physics Requires More Than Visual Data".
- A Unified World Model: "Opinion: A Unified World Model is the cornerstone for integrating perception, reasoning, and decision-making in embodied AI".
- Small VLAs: "Opinion: Small VLAs Self-Learn Consistency".
- How Can Causal AI Benefit World Models?: "Opinion: How Can Causal AI Benefit World Models?".
Theory & World Models Explainability
- [⭐️] General agents Contain World Models, "General agents contain world models".
- [⭐️] When Do Neural Networks Learn World Models? "When Do Neural Networks Learn World Models?"
- [⭐️] Reconstruction or Semantics? What Makes a Latent Space Useful for Robotic World Models
- What Does it Mean for a Neural Network to Learn a 'World Model'?, "What Does it Mean for a Neural Network to Learn a 'World Model'?".
- Transformer cannot learn HMMs (sometimes) "On Limitation of Transformer for Learning HMMs".
- Identifiable latent space world models through contrastive learning, "Self-supervised contrastive learning performs non-linear system identification".
- [⭐️] Inductive Bias Probe, "What Has a Foundation Model Found? Using Inductive Bias to Probe for World Models".
- [⭐️] Dynamical Systems Learning for World Models, "When do World Models Successfully Learn Dynamical Systems?".
- How Hard is it to Confuse a World Model?, "How Hard is it to Confuse a World Model?".
- Partially Observable Safety: "How Well Do Latent World Models Understand Partially Observable Safety Constraints?".
- ICL Emergence, "Context and Diversity Matter: The Emergence of In-Context Learning in World Models".
- [⭐️] Scaling Law,"Scaling Laws for Pre-training Agents and World Models".
- LLM World Model, "Linear Spatial World Models Emerge in Large Language Models".
- Revisiting Othello, "Revisiting the Othello World Model Hypothesis".
- [⭐️] Transformers Use Causal World Models, "Transformers Use Causal World Models in Maze-Solving Tasks".
- [⭐️] Causal World Model inside NTP, "A Causal World Model Underlying Next Token Prediction: Exploring GPT in a Controlled Environment".
- When do neural networks learn world models?: "When do neural networks learn world models?".
- Utilizing World Models: "Utilizing World Models for Adaptively Covariate Acquisition Under Limited Budget for Causal Decision Making Problem".
General Approaches to World Models
1. Foundation World Models
SOTA Models:
Interactive Video Generation:
- [⭐️] Genie 3, "Genie 3: A new frontier for world models".
- [⭐️] V-JEPA 2, "V-JEPA 2: Self-Supervised Video Models Enable Understanding, Prediction and Planning".
- [⭐️] V-JEPA 2.1, "V-JEPA 2.1: Unlocking Dense Features in Video Self-Supervised Learning".
- [⭐️] Cosmos Predict 2.5 & Cosmos Transfer 2.5, "Cosmos Predict 2.5 & Transfer 2.5: Evolving the World Foundation Models for Physical AI".
- [⭐️] Cosmos 3, "Cosmos 3: Omnimodal World Models for Physical AI".
- [⭐️] FlashDreams, "FlashDreams: High-performance inference and serving for interactive autoregressive video and world models".
- [⭐️] HY-World 1.5, "HY-World 1.5: A Systematic Framework for Interactive World Modeling with Real-Time Latency and Geometric Consistency".
- [⭐️] PAN, "PAN: A World Model for General, Interactable, and Long-Horizon World Simulation".
- [⭐️] LingBot-World, "Advancing Open-source World Models".
- LingBot-World 2.0, "Infinite Worlds with Versatile Interactions".
- [⭐️] DreamZero, "DreamZero: World Action Models are Zero-shot Policies".
- SANA-WM: "SANA-WM: Efficient Minute-Scale World Modeling with Hybrid Linear Diffusion Transformer".
- [⭐️] Kairos, "Kairos: A Native World Model Stack for Physical AI".
- [⭐️] DreamX-World 1.0, "DreamX-World 1.0: A General-Purpose Interactive World Model".
- Orca: "Orca: The World is in Your Mind".
- AlayaWorld v1.1: "AlayaWorld: Interactive Long-Horizon World Modeling - Full Technical Report (v1.1)".
- Alaya-EVOKE: "Alaya-EVOKE: From Linear-Scaling Supervision to Endless World".
- [⭐️] EchoWM, "EchoWM: Open and Enterable Omnimodal World Models".
- [⭐️] JoyAI-Echo-1.5, "Long-Horizon Audio-Visual Generation for Persistent Stories and Interactive Worlds".
- SolarWM: "SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models".
- WorldCrafter: "WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory".
3D Scene Generation:
- [⭐️] RTFM, "RTFM: A Real-Time Frame Model".
- [⭐️] Marble, "Generating Bigger and Better Worlds".
- [⭐️] WorldGen, "WorldGen: From Text to Traversable and Interactive 3D Worlds".
Classics:
Genie Series:
- [⭐️] Genie 2, "Genie 2: A Large-Scale Foundation World Model".
- [⭐️] Genie, "Genie: Generative Interactive Environments".
V-JEPA Series:
- [⭐️] V-JEPA: "V-JEPA: Video Joint Embedding Predictive Architecture".
- LeWM: "LeWorldModel: Stable End-to-End Joint-Embedding Predictive Architecture from Pixels".
- Interpreting JEPA: "Interpreting Physics in Video World Models".
Cosmos Series:
- [⭐️] Cosmos, "Cosmos World Foundation Model Platform for Physical AI".
World-Lab Projects:
- Generating Worlds, "Generating Worlds".
Other Awesome Models:
- [⭐️] Pandora, "Pandora: Towards General World Model with Natural Language Actions and Video States".
- [⭐️] UniSim, "UniSim: Learning Interactive Real-World Simulators".
- Masked Generative Priors: "Masked Generative Priors Improve World Models Sequence Modelling Capabilities".
- Recurrent world model: "Recurrent world model with tokenized latent states".
- Mixture-of-Transformers: "Mixture-of-Transformers: A Sparse and Scalable Architecture for Multi-Modal Foundation Models".
- Mixture-of-Mamba: "Mixture-of-Mamba: Enhancing Multi-Modal State-Space Models with Modality-Aware Sparsity".
- Improving World Models: "Improving World Models using Supervision with Co-Evolving Linear Probes".
- MS-SSM: "MS-SSM: A Multi-Scale State Space Model for Enhanced Sequence Modeling".
- Fixed-Point RNNs: "Fixed-Point RNNs: From Diagonal to Dense in a Few Iterations".
- ACDiT: "ACDiT: Interpolating Autoregressive Conditional Modeling and Diffusion Transformer".
- FPAN: "FPAN: Mitigating Replication in Diffusion Models through the Fine-Grained Probabilistic Addition of Noise to Token Embeddings".
- SPARTAN: "SPARTAN: A Sparse Transformer World Model Attending to What Matters".
2. Building World Models from 2D Vision Priors
The represents a "bottom-up" approach to achieving intelligence, sensorimotor before abstraction. In the 2D pixel space, world models often build upon pre-existing image/video generation approaches.
To what extent does Vision Intelligence exist in Video Generation Models:
- [⭐️] Sora, "Video generation models as world simulators". [Technical report]
- [⭐️] Veo-3 are zero-shot Learners and Reasoners, "Video models are zero-shot learners and reasoners".
- [⭐️] PhyWorld, "How Far is Video Generation from World Model: A Physical Law Perspective".
- Emergent Few-Shot Learning in Video Diffusion Models, "From Generation to Generalization: Emergent Few-Shot Learning in Video Diffusion Models".
- VideoVerse: "VideoVerse: How Far is Your T2V Generator from a World Model?".
- [⭐️] Emu 3.5, "Emu3.5: Native Multimodal Models are World Learners".
- [⭐️] Emu 3, "Emu3: Next-Token Prediction is All You Need".
Useful Approaches in Video Generation:
- [⭐️] Diffusion Forcing, "Diffusion Forcing: Next-token Prediction Meets Full-Sequence Diffusion".
- [⭐️] DFoT, "History-Guided Video Diffusion".
- [⭐️] Self-Forcing, "Self Forcing: Bridging the Train-Test Gap in Autoregressive Video Diffusion".
- CausVid, "From Slow Bidirectional to Fast Causal Video Generators".
- Longlive, "LongLive: Real-time Interactive Long Video Generation".
- ControlNet, "Adding Conditional Control to Text-to-Image Diffusion Models".
- ReCamMaster, "ReCamMaster: Camera-Controlled Generative Rendering from A Single Video".
- SpaceTimePilot, “SpaceTimePilot: Generative Rendering of Dynamic Scenes Across Space and Time”.
- NeoVerse, "NeoVerse: Enhancing 4D World Model with in-the-wild Monocular Videos".
- [⭐️] Causal Forcing, "Causal Forcing: Autoregressive Diffusion Distillation Done Right for High-Quality Real-Time Interactive Video Generation".
- [⭐️] Next Forcing, "Next Forcing: Causal World Modeling with Multi-Chunk Prediction".
- [⭐️] Helios, "Helios: Real Real-Time Long Video Generation Model".
From Video Generation Models to World Models:
- [⭐️] Vid2World: "Vid2World: Crafting Video Diffusion Models to Interactive World Models".
- AVID, "AVID: Adapting Video Diffusion Models to World Models".
- IRASim, "IRASim: A Fine-Grained World Model for Robot Manipulation".
- DWS, "Pre-Trained Video Generative Models as World Simulators".
- Video Adapter, "Probabilistic Adaptation of Black-Box Text-to-Video Models".
- Video Agent, "VideoAgent: Self-Improving Video Generation".
- WISA, "WISA: World Simulator Assistant for Physics-Aware Text-to-Video Generation".
- Force Prompting, "Force Prompting: Video Generation Models Can Learn and Generalize Physics-based Control Signals".
Pixel Space World Models:
- [⭐️] Owl-1: "Owl-1: Omni World Model for Consistent Long Video Generation".
- [⭐️] Long-Context State-Space Video World Models, "Long-Context State-Space Video World Models".
- [⭐️] StateSpaceDiffuser: "StateSpaceDiffuser: Bringing Long Context to Diffusion World Models".
- [⭐️] Geometry Forcing: "Geometry Forcing: Marrying Video Diffusion and 3D Representation for Consistent World Modeling".
- Yume: "Yume: An Interactive World Generation Model".
- PSI, "World Modeling with Probabilistic Structure Integration".
- Martian World Models, "Martian World Models: Controllable Video Synthesis with Physically Accurate 3D Reconstructions".
- WorldDreamer: "WorldDreamer: Towards General World Models for Video Generation via Predicting Masked Tokens".
- EBWM: "Cognitively Inspired Energy-Based World Models".
- "Video World Models with Long-term Spatial Memory".
- VRAG, "Learning World Models for Interactive Video Generation".
- DRAW, "Adapting World Models with Latent-State Dynamics Residuals".
- ForeDiff, "Consistent World Models via Foresight Diffusion".
- Distribution Recovery: "Distribution Recovery in Compact Diffusion World Models via Conditioned Frame Interpolation".
- EmbodiedScene: "EmbodiedScene: Towards Automated Generation of Diverse and Realistic Scenes for Embodied AI".
- BEYOND SINGLE-STEP: "BEYOND SINGLE-STEP: MULTI-FRAME ACTION- CONDITIONED VIDEO GENERATION FOR REINFORCE- MENT LEARNING ENVIRONMENTS".
- Adaptive Attention-Guided Masking: "Adaptive Attention-Guided Masking in Vision Transformers for Self-Supervised Hyperspectral Feature Learning".
- Implicit State Estimation: "Implicit State Estimation via Video Replanning".
- Enhancing Long Video Generation Consistency: "Enhancing Long Video Generation Consistency without Tuning: Time-Frequency Analysis, Prompt Alignment, and Theory".
- Can Image-To-Video Models Simulate Pedestrian Dynamics?: "Can Image-To-Video Models Simulate Pedestrian Dynamics?".
- Eyes of the DINO: "Eyes of the DINO: Learning Physical World Models from Uncurated Web Videos".
- Video Self-Distillation: "Video Self-Distillation for Single-Image Encoders: A Step Toward Physically Plausible Perception".
- Learning Skill Abstraction: "Learning Skill Abstraction from Action-Free Videos via Optical Flow".
- CRISP: "CRISP: Contact-guided Real2Sim from Monocular Video with Planar Scene Primitives".
- Whole-Body Conditioned Egocentric Video Prediction: "Whole-Body Conditioned Egocentric Video Prediction".
- Hand2World: "Hand2World: Autoregressive Egocentric Interaction Generation via Free-Space Hand Gestures".
- Taming generative world models: "Taming generative world models for zero-shot optical flow extraction".
3. Building World Models from 3D Vision Priors
3D Mesh is also a useful representaiton of the physical world, including benefits such as spatial consistency.
- [⭐️] WorldGrow: "WorldGrow: Generating Infinite 3D World".
- TRELLISWorld: "TRELLISWorld: Training-Free World Generation from Object Generators".
- Terra: "Terra: Explorable Native 3D World Model with Point Latents".
- MorphoSim: "MorphoSim: An Interactive, Controllable, and Editable Language-guided 4D World Simulator". [code]
- EvoWorld: "EvoWorld: Evolving Panoramic World Generation with Explicit 3D Memory".
- [⭐️] FantasyWorld: "FantasyWorld: Geometry-Consistent World Modeling via Unified Video and 3D Prediction".
- [⭐️] Aether: "Aether: Geometric-Aware Unified World Modeling".
- HERO: "HERO: Hierarchical Extrapolation and Refresh for Efficient World Models".
- UrbanWorld: "UrbanWorld: An Urban World Model for 3D City Generation".
- DeepVerse: "DeepVerse: 4D Autoregressive Video Generation as a World Model".
- ABot-3DWorld 0: "ABot-3DWorld 0: A Universal World Model to Explore Any 3D Space".
- EnerVerse-AC: "EnerVerse-AC: Envisioning Embodied Environments with Action Condition".
- Adapting a World Model: "Adapting a World Model for Trajectory Following in a 3D Game".
- SteerX: "SteerX: Creating Any Camera-Free 3D and 4D Scenes with Geometric Steering".
- SP- PhysicsNeRF: "SP- PhysicsNeRF: Physics-Guided 3D Reconstruction from Sparse Views".
4. Building World Models from Language Priors
The represents a "top-down" approach to achieving intelligence, abstraction before sensorimotor.
Aiming to Advance LLM/VLM skills:
- [⭐️] VLWM, "Planning with Reasoning using Vision Language World Model".
- [⭐️] Agent Learning via Early Experience, "Agent Learning via Early Experience".
- [⭐️] CWM, "CWM: An Open-Weights LLM for Research on Code Generation with World Models".
- [⭐️] RAP, "Reasoning with language model is planning with world model".
- SURGE, "SURGE: On the Potential of Large Language Models as General-Purpose Surrogate Code Executors".
- LLM-Sim: "Can Language Models Serve as Text-Based World Simulators?".
- WorldLLM, "WorldLLM: Improving LLMs' world modeling using curiosity-driven theory-making".
- LLMs as World Models, "LLMs as World Models: Data-Driven and Human-Centered Pre-Event Simulation for Disaster Impact Assessment".
- [⭐️] LWM: "World Model on Million-Length Video And Language With RingAttention".
- "Evaluating World Models with LLM for Decision Making".
- LLMPhy: "LLMPhy: Complex Physical Reasoning Using Large Language Models and World Models".
- LLMCWM: "Language Agents Meet Causality -- Bridging LLMs and Causal World Models".
- "Making Large Language Models into World Models with Precondition and Effect Knowledge".
- CityBench: "CityBench: Evaluating the Capabilities of Large Language Model as World Model".
- [⭐️] Qwen-AgentWorld: "Qwen-AgentWorld: Language World Models for General Agents".
Aiming to enhance computer-use agent performance:
- [⭐️] Neural-OS, "NeuralOS: Towards Simulating Operating Systems via Neural Generative Models".
- R-WoM: "R-WoM: Retrieval-augmented World Model For Computer-use Agents".
- [⭐️] SimuRA: "SimuRA: Towards General Goal-Oriented Agent via Simulative Reasoning Architecture with LLM-Based World Model".
- WebSynthesis, "WebSynthesis: World-Model-Guided MCTS for Efficient WebUI-Trajectory Synthesis".
- WKM: "Agent Planning with World Knowledge Model".
- WebDreamer, "Is Your LLM Secretly a World Model of the Internet? Model-Based Planning for Web Agents".
- "Web Agents with World Models: Learning and Leveraging Environment Dynamics in Web Navigation".
- WebEvolver: "WebEvolver: Enhancing Web Agent Self-Improvement with Coevolving World Model".
- WALL-E 2.0: "WALL-E 2.0: World Alignment by NeuroSymbolic Learning improves World Model-based LLM Agents".
- ViMo: "ViMo: A Generative Visual GUI World Model for App Agent".
- [⭐️] Dyna-Think: "Dyna-Think: Synergizing Reasoning, Acting, and World Model Simulation in AI Agents".
- FPWC, "Unlocking Smarter Device Control: Foresighted Planning with a World Model-Driven Code Execution Approach".
Symbolic World Models:
- [⭐️] PoE-World, "PoE-World: Compositional World Modeling with Products of Programmatic Experts".
- "One Life to Learn: Inferring Symbolic World Models for Stochastic Environments from Unguided Exploration".
- "Finite Automata Extraction: Low-data World Model Learning as Programs from Gameplay Video".
- "Synthesizing world models for bilevel planning".
- "Generating Symbolic World Models via Test-time Scaling of Large Language Models".
- Neuro-Symbolic World Models: "Neuro-Symbolic World Models for Adapting to Open World Novelty".
LLM-in-the-loop World Generation:
- LatticeWorld, "LatticeWorld: A Multimodal Large Language Model-Empowered Framework for Interactive Complex World Generation".
- Text2World: "Text2World: Benchmarking Large Language Models for Symbolic World Model Generation".
5. Building World Models by Bridging Language and Vision Intelligence
A recent trend of work is bridging highly-compressed semantic tokens (e.g. language) with information-sparse cues in the observation space (e.g. vision). This results in World Models that combine high-level and low-level intelligence.
- [⭐️] VAGEN, "VAGEN: Reinforcing World Model Reasoning for Multi-Turn VLM Agents".
- [⭐️] Semantic World Models, "Semantic World Models".
- DyVA: "Can World Models Benefit VLMs for World Dynamics?".
- From Foresight to Forethought: "From Foresight to Forethought: VLM-In-the-Loop Policy Steering via Latent Alignment".
- SEAL: "SEAL: SEmantic-Augmented Imitation Learning via Language Model".
- Programmatic Video Prediction: "Programmatic Video Prediction Using Large Language Models".
- Emergent Stack Representations: "Emergent Stack Representations in Modeling Counter Languages Using Transformers".
- DIALOGUES BETWEEN ADAM AND EVE: "DIALOGUES BETWEEN ADAM AND EVE: EXPLORATION OF UNKNOWN CIVILIZATION LANGUAGE BY LLM".
- Memory Helps, but Confabulation Misleads: "Memory Helps, but Confabulation Misleads: Understanding Streaming Events in Videos with MLLMs".
- Reframing LLM Finetuning: "Reframing LLM Finetuning Through the Lens of Bayesian Optimization".
- TrajEvo: "TrajEvo: Designing Trajectory Prediction Heuristics via LLM-driven Evolution".
- CCC: "CCC: Enhancing Video Generation via Structured MLLM Feedback".
- VLA-OS: "VLA-OS: Structuring and Dissecting Planning Representations and Paradigms in Vision-Language-Action Models".
- LLM-Guided Probabilistic Program Induction: "LLM-Guided Probabilistic Program Induction for POMDP Model Estimation".
- Decoupled Planning and Execution: "Decoupled Planning and Execution with LLM-Driven World Models for Efficient Task Planning".
- The Physical Basis of Prediction: "The Physical Basis of Prediction: World Model Formation in Neural Organoids via an LLM-Generated Curriculum".
- Avi: "Avi: A 3D Vision-Language Action Model Architecture generating Action from Volumetric Inference".
- Plan Verification: "Plan Verification for LLM-Based Embodied Task Completion Agents".
- SpatialThinker: "SpatialThinker: Reinforcing 3D Reasoning in Multimodal LLMs via Spatial Rewards".
- How Foundational Skills Influence VLM-based Embodied Agents: "How Foundational Skills Influence VLM-based Embodied Agents: A Native Perspective".
- Towards Fine-tuning a Small Vision-Language Model: "Towards Fine-tuning a Small Vision-Language Model for Aerial Navigation".
- Improvisational Reasoning: "Improvisational Reasoning with Vision-Language Models for Grounded Procedural Planning".
- Vision-Language Reasoning for Burn Depth Assessment: "Vision-Language Reasoning for Burn Depth Assessment with Structured Diagnostic Hypotheses".
- WALL-E: "WALL-E: World Alignment by NeuroSymbolic Learning improves World Model-based LLM Agents".
- Puffin: "Thinking with Camera: A Unified Multimodal Model for Camera-Centric Understanding and Generation".
- IVT: "Beyond Visual CoT: Internalized Visual Thinking for Proactive Video Reasoning".
- Code World Model: "Code World Model: Coding Agent as World Brain".
- Code as Worlds: "Code as Worlds: Agentic Discovery of Executable World Representations for Physical Reasoning".
6. Latent Space World Models
While learning in the observation space (pixel, 3D mesh, language, etc.) is a common approach, for many applications (planning, policy evaluation, etc.) learning in latent space is sufficient or is believed to lead to even better performace.
- [⭐️] DINO-WM, "DINO-WM: World Models on Pre-trained Visual Features enable Zero-shot Planning".
- [⭐️] DINO-World, "Back to the Features: DINO as a Foundation for Video World Models".
- [⭐️] DINO-Foresight, "DINO-Foresight: Looking into the Future with DINO
".
- AWM, "Learning Abstract World Models with a Group-Structured Latent Space".
JEPA is a special kind of learning in latent space, where the loss is put on the latent space, and the encoder & predictor are co-trained. However, the usage of JEPA is not only in world models (e.g. V-JEPA2-AC), but also representation learning (e.g. I-JEPA, V-JEPA), we provide representative works from both perspectives below.
- [⭐️] I-JEPA,"Self-Supervised Learning from Images with a Joint-Embedding Predictive Architecture". [