
[IEEE TPAMI 2026] Simulating the Real World: Survey & Resources, which contains our survey "Simulating the Real World: A Unified Survey of Multimodal Generative Models" (IEEE TPAMI, 2026) and Awesome-Text2X-Resources. Watch this repository for the latest updates! 🔥
See the codeREADME
Simulating the Real World: Survey & Resources


This repository is divided into two main sections:
Our Survey Paper Collection - This section presents our survey, "Simulating the Real World: A Unified Survey of Multimodal Generative Models" (IEEE TPAMI, 2026), which systematically unify the study of 2D, video, 3D and 4D generation within a single framework.
Text2X Resources – This section continues the original Awesome-Text2X-Resources, an open collection of state-of-the-art (SOTA) and novel Text-to-X (X can be everything) methods, including papers, codes, and datasets. The goal is to track the rapid progress in this field and provide researchers with up-to-date references.
⭐ If you find this repository useful for your research or work, a star is highly appreciated!
💗 This repository is continuously updated. If you find relevant papers, blog posts, videos, or other resources that should be included, feel free to submit a pull request (PR) or open an issue. Community contributions are always welcome!
🔔 News
- 🎉 [25 Apr 2026] Our survey is accepted by IEEE TPAMI 2026!
- ✨ [16 Feb 2026] Updated our survey (Version 3, 25 pages) on arXiv.
- ✨ [13 Aug 2025] Updated our survey (Version 2, 25 pages) on arXiv.
- ✨ [6 Mar 2025] Updated our survey (Version 1) on arXiv.
Table of Contents
- Our Survey Paper Collection
- Text2X Resources
📜 Our Survey Paper Collection
𝐒𝐢𝐦𝐮𝐥𝐚𝐭𝐢𝐧𝐠 𝐭𝐡𝐞 𝐑𝐞𝐚𝐥 𝐖𝐨𝐫𝐥𝐝: 𝐀 𝐔𝐧𝐢𝐟𝐢𝐞𝐝 𝐒𝐮𝐫𝐯𝐞𝐲 𝐨𝐟 𝐌𝐮𝐥𝐭𝐢𝐦𝐨𝐝𝐚𝐥 𝐆𝐞𝐧𝐞𝐫𝐚𝐭𝐢𝐯𝐞 𝐌𝐨𝐝𝐞𝐥𝐬
𝑰𝑬𝑬𝑬 𝑻𝑷𝑨𝑴𝑰, 𝟐𝟎𝟐𝟔


Abstract
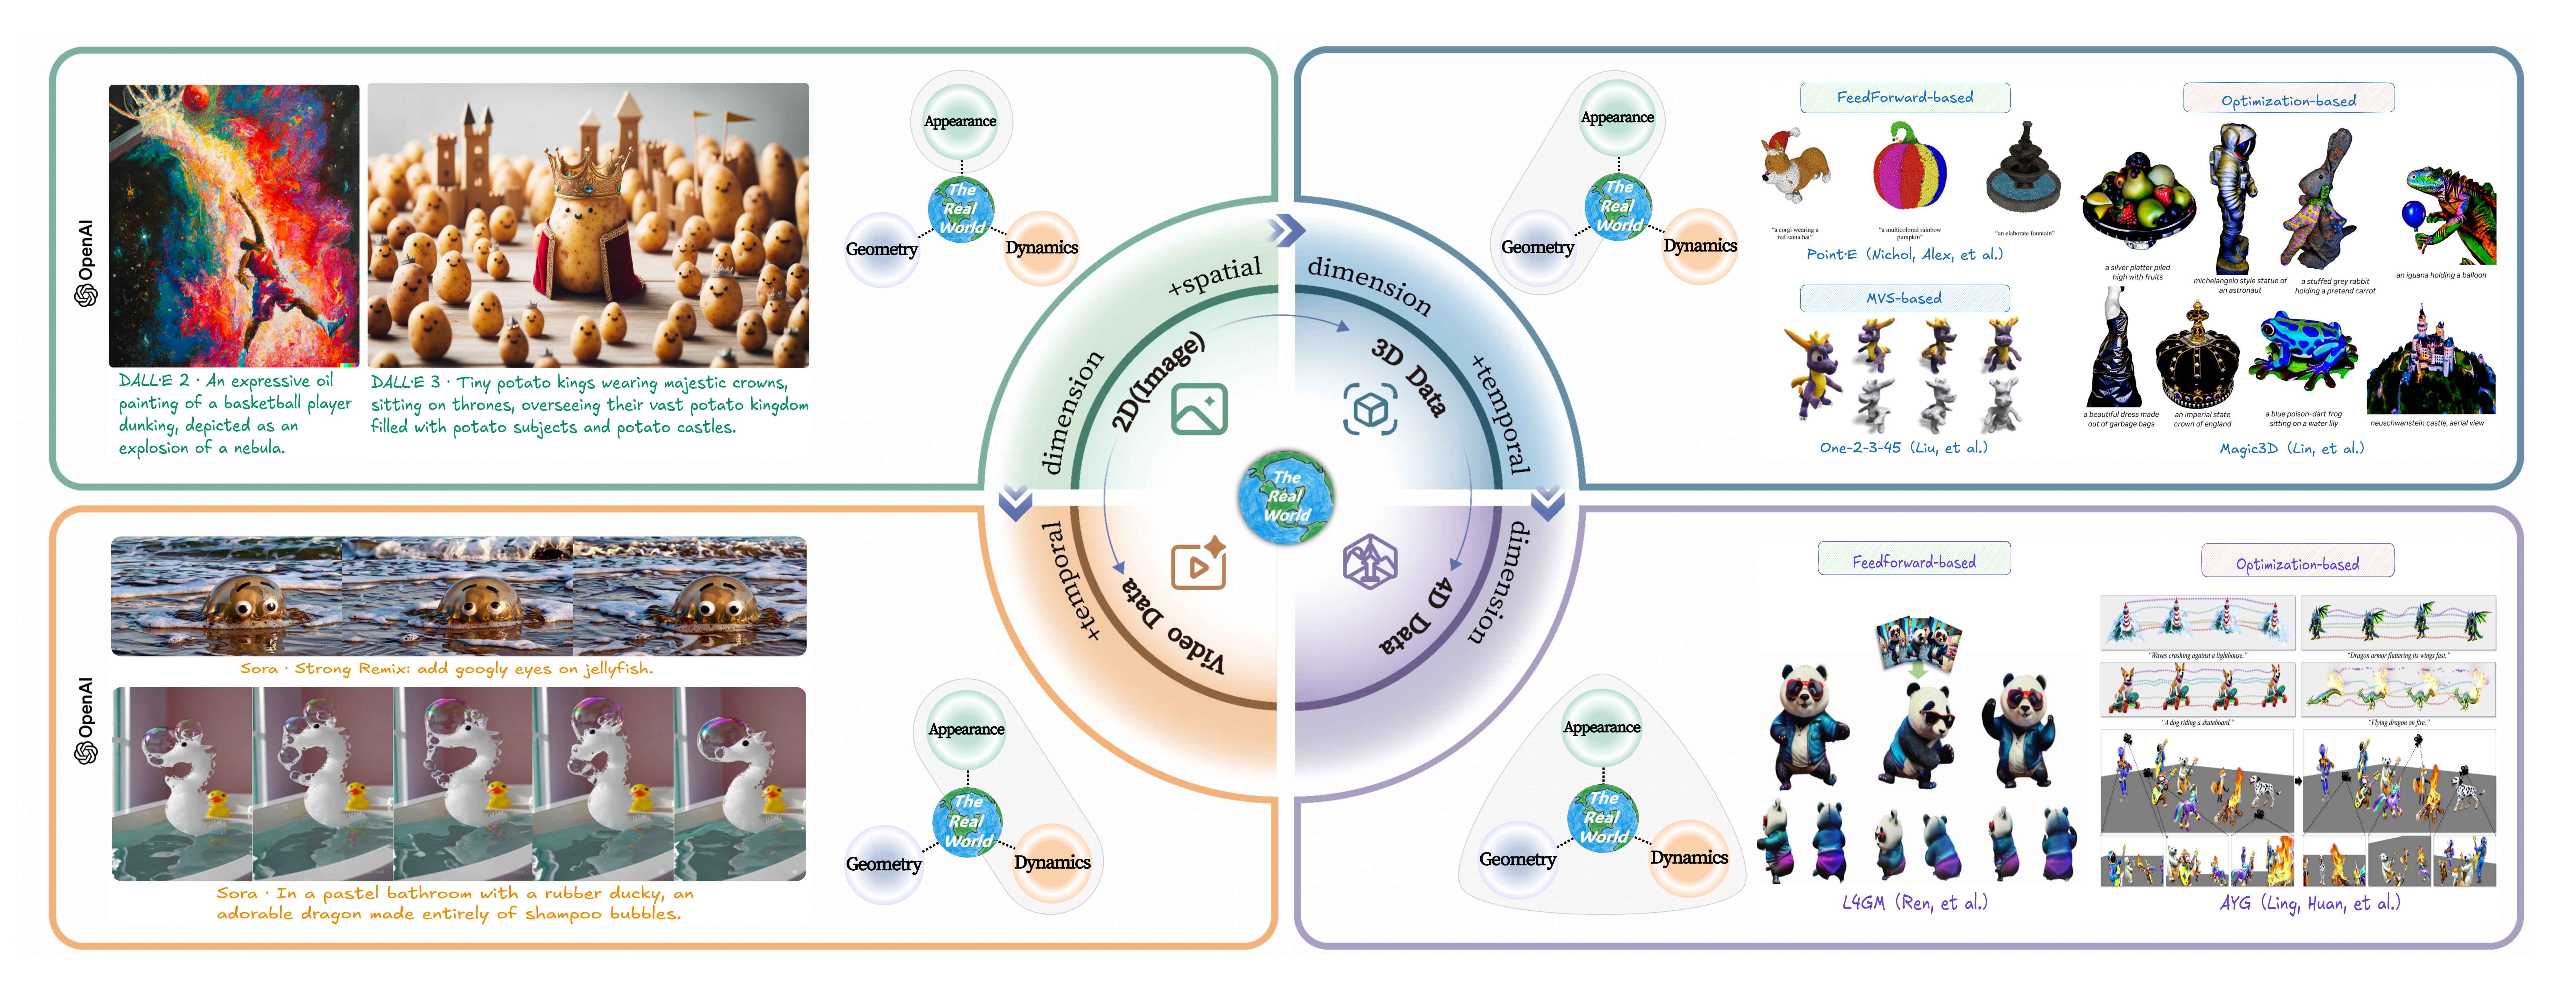
Understanding and replicating the real world is a critical challenge in Artificial General Intelligence (AGI) research. To achieve this, many existing approaches, such as world models, aim to capture the fundamental principles governing the physical world, enabling more accurate simulations and meaningful interactions. However, current methods often treat different modalities, including 2D (images), videos, 3D, and 4D representations, as independent domains, overlooking their interdependencies. Additionally, these methods typically focus on isolated dimensions of reality without systematically integrating their connections. In this survey, we present a unified survey for multimodal generative models that investigate the progression of data dimensionality in real-world simulation. Specifically, this survey starts from 2D generation (appearance), then moves to video (appearance+dynamics) and 3D generation (appearance+geometry), and finally culminates in 4D generation that integrate all dimensions. To the best of our knowledge, this is the first attempt to systematically unify the study of 2D, video, 3D and 4D generation within a single framework. To guide future research, we provide a comprehensive review of datasets, evaluation metrics and future directions, and fostering insights for newcomers. This survey serves as a bridge to advance the study of multimodal generative models and real-world simulation within a unified framework.
⭐ Citation
If you find this paper and repo helpful for your research, please cite it below:
@article{hu2026simulating,
  title={Simulating the real world: A unified survey of multimodal generative models},
  author={Hu, Yuqi and Wang, Longguang and Liu, Xian and Chen, Ling-Hao and Guo, Yuwei and Shi, Yukai and Liu, Ce and Rao, Anyi and Wang, Zeyu and Xiong, Hui},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  year={2026},
  publisher={IEEE}
}
🧭 Getting Started with Key Concepts
[!Note] If you are new to this field, you can find clear and concise definitions of essential technical terms and concepts, such as NeRF, 3DGS, SDS, and Diffusion Models in our Glossary.
[!TIP] Feel free to pull requests or contact us if you find any related papers that are not included here. The process to submit a pull request is as follows:
- a. Fork the project into your own repository.
- b. Add the Title, Paper link, Conference, Project/GitHub link in
README.mdusing the following format:
[Origin] **Paper Title** [[Paper](Paper Link)] [[GitHub](GitHub Link)] [[Project Page](Project Page Link)]
- c. Submit the pull request to this branch.
The Dimensional Evolution of Generative AI
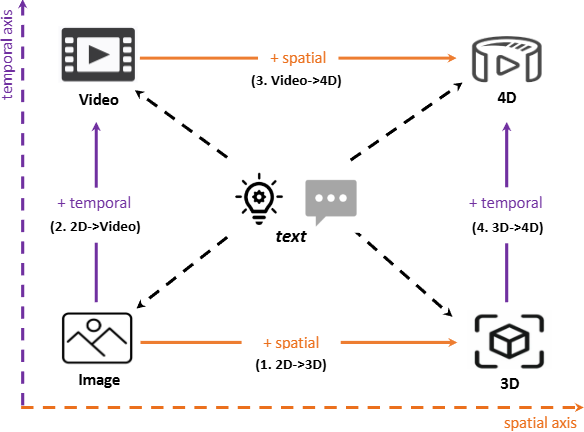
We present a unified framework connecting 2D, Video, 3D, and 4D generation through text-guided synthesis. This paradigm illustrates how higher-dimensional content is synthesized by extending foundational modalities along spatial and temporal axes. (1)2D->3D: Spatial lifting of 2D priors to achieve geometric consistency; (2)2D->Video: Temporal inflation of static features to capture motion dynamics; (3)Video->4D: Spatial reconstruction and stabilization of dynamic sequences; (4)3D->4D: Temporal animation and deformation of static geometry. This perspective underscores that higher-dimensional generation methodologies are derivatives of foundational lower-dimensional generative priors, adapted through specialized architectural extensions.
Paradigms
2D Generation
Text-to-Image Generation.
Here are some seminal papers and models.
- Imagen: [NeurIPS 2022] Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding [Paper] [Project Page]
- DALL-E: [ICML 2021] Zero-shot text-to-image generation [Paper] [GitHub]
- DALL-E 2: [arXiv 2022] Hierarchical Text-Conditional Image Generation with CLIP Latents [Paper]
- DALL-E 3: [Platform Link]
- DeepFloyd IF: [GitHub]
- Stable Diffusion: [CVPR 2022] High-Resolution Image Synthesis with Latent Diffusion Models [Paper] [GitHub]
- SDXL: [ICLR 2024 spotlight] SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis [Paper] [GitHub]
- FLUX.1: [Platform Link]
Video Generation
Overview of text-to-video generation technologies categorized by three main approaches.
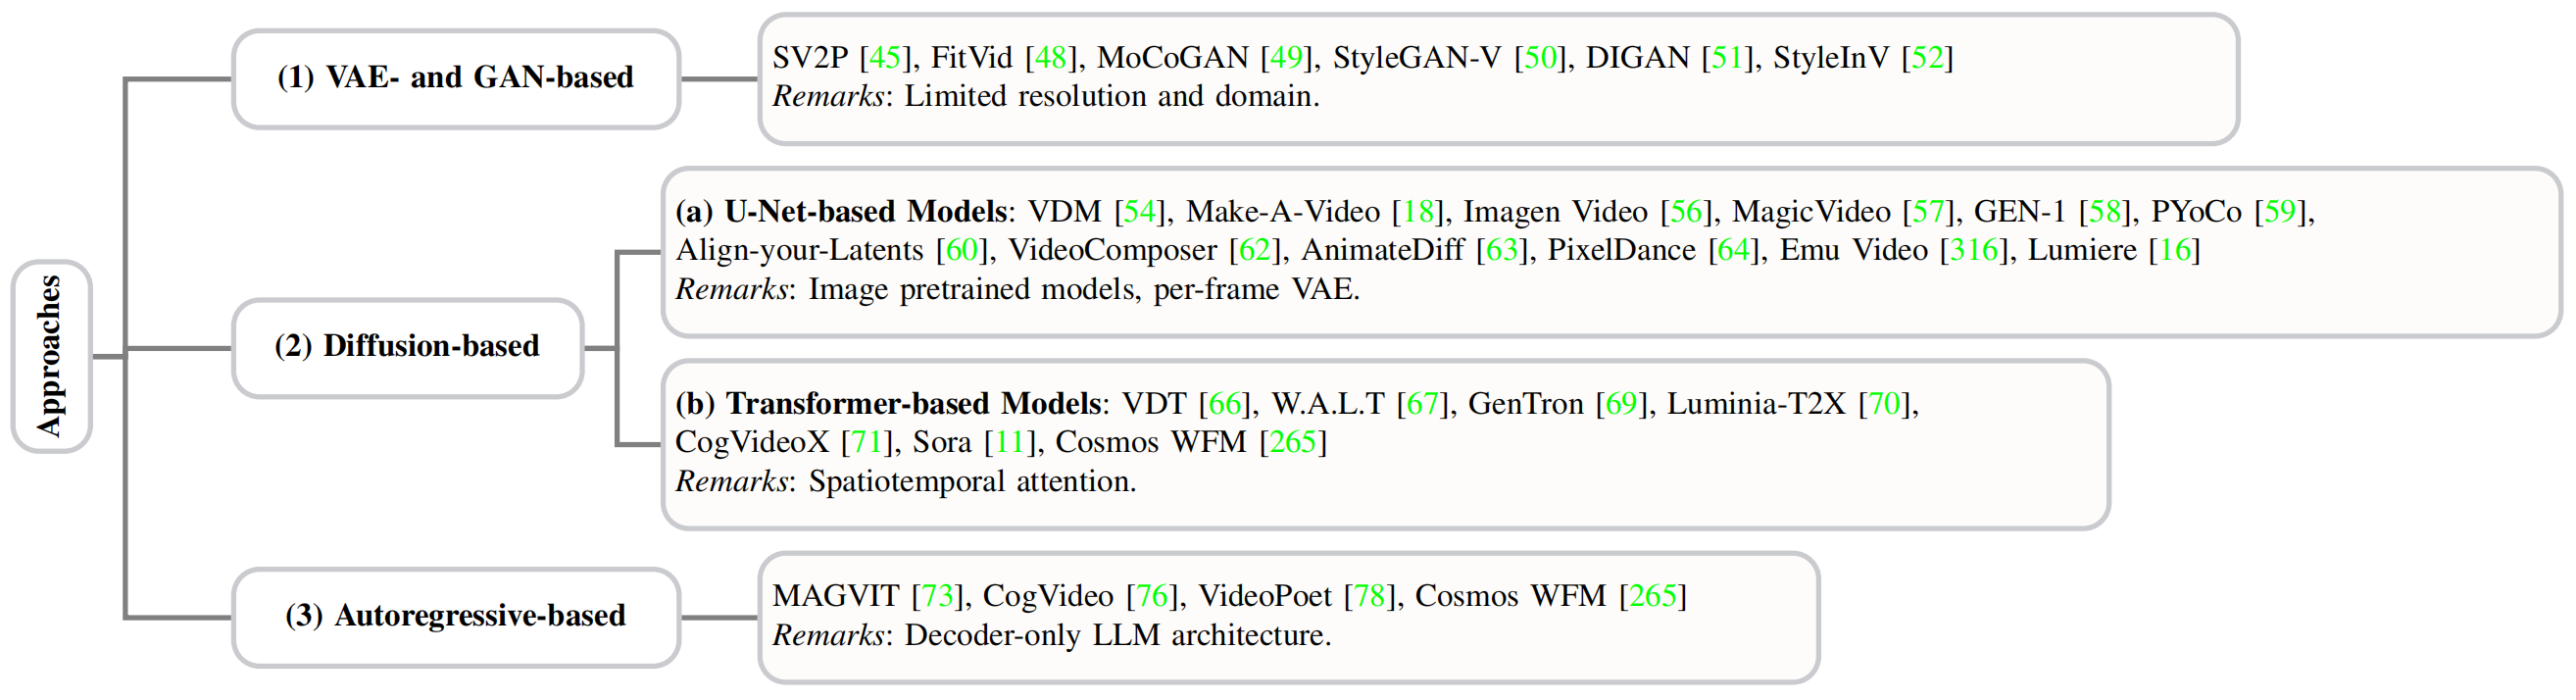
Text-to-video generation models adapt text-to-image frameworks to handle the additional dimension of dynamics in the real world. We classify these models into three categories based on different generative machine learning architectures.
Survey
- [AIRC 2023] A Survey of AI Text-to-Image and AI Text-to-Video Generators [Paper]
- [arXiv 2024] Sora as an AGI World Model? A Complete Survey on Text-to-Video Generation [Paper]
Video Algorithms
(1) VAE- and GAN-based Approaches.
VAE-based Approaches.
- SV2P: [ICLR 2018 Poster] Stochastic Variational Video Prediction [Paper] [Project Page]
- [arXiv 2021] VideoGPT: Video Generation using VQ-VAE and Transformers [Paper] [GitHub] [Project Page]
- [arXiv 2021] FitVid: Overfitting in Pixel-Level Video Prediction [Paper] [GitHub] [Project Page]
GAN-based Approaches.
- [CVPR 2018] MoCoGAN: Decomposing Motion and Content for Video Generation [Paper] [GitHub]
- [CVPR 2022] StyleGAN-V: A Continuous Video Generator with the Price, Image Quality and Perks of StyleGAN2 [Paper] [GitHub] [Project Page]
- DIGAN: [ICLR 2022] Generating Videos with Dynamics-aware Implicit Generative Adversarial Networks [Paper] [GitHub] [Project Page]
- [ICCV 2023] StyleInV: A Temporal Style Modulated Inversion Network for Unconditional Video Generation [Paper] [GitHub] [Project Page]
(2) Diffusion-based Approaches.
U-Net-based Architectures.
- [NeurIPS 2022] Video Diffusion Models [Paper] [Project Page]
- [arXiv 2025] UniVerse-1: Unified Audio-Video Generation via Stitching of Experts [Paper] [GitHub] [Project Page]
- [arXiv 2022] Imagen Video: High Definition Video Generation with Diffusion Models [Paper] [Project Page]
- [arXiv 2022] MagicVideo: Efficient Video Generation With Latent Diffusion Models [Paper] [Project Page]
- [ICLR 2023 Poster] Make-A-Video: Text-to-Video Generation without Text-Video Data [Paper] [Project Page]
- GEN-1: [ICCV 2023] Structure and Content-Guided Video Synthesis with Diffusion Models [Paper] [Project Page]
- PYoCo: [ICCV 2023] Preserve Your Own Correlation: A Noise Prior for Video Diffusion Models [Paper] [Project Page]
- [CVPR 2023] Align your Latents: High-Resolution Video Synthesis with Latent Diffusion Models [Paper] [Project Page]
- [IJCV 2024] Show-1: Marrying Pixel and Latent Diffusion Models for Text-to-Video Generation [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] VideoComposer: Compositional Video Synthesis with Motion Controllability [Paper] [GitHub] [Project Page]
- [ICLR 2024 Spotlight] AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning [Paper] [GitHub] [Project Page]
- [CVPR 2024] Make Pixels Dance: High-Dynamic Video Generation [Paper] [Project Page]
- [ECCV 2024] Emu Video: Factorizing Text-to-Video Generation by Explicit Image Conditioning [Paper] [Project Page]
- [SIGGRAPH Asia 2024] Lumiere: A Space-Time Diffusion Model for Video Generation [Paper] [Project Page]
Transformer-based Architectures.
- [ICLR 2024 Poster] VDT: General-purpose Video Diffusion Transformers via Mask Modeling [Paper] [GitHub] [Project Page]
- W.A.L.T: [ECCV 2024] Photorealistic Video Generation with Diffusion Models [Paper] [Project Page]
- [CVPR 2024] Snap Video: Scaled Spatiotemporal Transformers for Text-to-Video Synthesis [Paper] [Project Page]
- [CVPR 2024] GenTron: Diffusion Transformers for Image and Video Generation [Paper] [Project Page]
- [Seminal Work 2024] Sora: Video generation models as world simulators, OpenAI Blog, vol. 1, no. 8, p. 1, 2024. [Project Page]
- [ICLR 2025 Poster] CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer [Paper] [GitHub]
- [ICLR 2025 Spotlight] Lumina-T2X: Transforming Text into Any Modality, Resolution, and Duration via Flow-based Large Diffusion Transformers [Paper] [GitHub]
(3) Autoregressive-based Approaches.
- VQ-GAN: [CVPR 2021 Oral] Taming Transformers for High-Resolution Image Synthesis [Paper] [GitHub]
- [NeurIPS 2021] Cogview: Mastering text-to-image generation via transformers [[Paper][https://arxiv.org/abs/2105.13290]]
- [CVPR 2023 Highlight] MAGVIT: Masked Generative Video Transformer [Paper] [GitHub] [Project Page]
- [ICLR 2023 Poster] CogVideo: Large-scale Pretraining for Text-to-Video Generation via Transformers [Paper] [GitHub]
- [ICML 2024] VideoPoet: A Large Language Model for Zero-Shot Video Generation [Paper] [Project Page]
- [ICLR 2024 Poster] Language Model Beats Diffusion - Tokenizer is key to visual generation [Paper]
- [arXiv 2024] Open-MAGVIT2: An Open-Source Project Toward Democratizing Auto-regressive Visual Generation [Paper] [GitHub]
- [arXiv 2024] Emu3: Next-Token Prediction is All You Need [Paper] [GitHub] [Project Page]
- [ICLR 2025 Poster] Accelerating Auto-regressive Text-to-Image Generation with Training-free Speculative Jacobi Decoding [Paper] [GitHub]
- [arXiv 2025] Cosmos World Foundation Model Platform for Physical AI [Paper] [GitHub]
Video Applications
Video Editing.
- [ICCV 2023] Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation [Paper] [GitHub] [Project Page]
- [ICCV 2023] Pix2Video: Video Editing using Image Diffusion [Paper] [GitHub] [Project Page]
- [NeurIPS 2023] Towards consistent video editing with text-to-image diffusion models [[Paper][https://arxiv.org/abs/2305.17431]]
- [CVPR 2024] VidToMe: Video Token Merging for Zero-Shot Video Editing [Paper] [GitHub] [Project Page]
- [CVPR 2024] Video-P2P: Video Editing with Cross-attention Control [Paper] [GitHub] [Project Page]
- [CVPR 2024 Highlight] CoDeF: Content Deformation Fields for Temporally Consistent Video Processing [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Towards Consistent Video Editing with Text-to-Image Diffusion Models [Paper]
- [ICLR 2024 Poster] Ground-A-Video: Zero-shot Grounded Video Editing using Text-to-image Diffusion Models [Paper] [GitHub] [Project Page]
- [arXiv 2024] UniEdit: A Unified Tuning-Free Framework for Video Motion and Appearance Editing [Paper] [GitHub] [Project Page]
- [TMLR 2024] AnyV2V: A Tuning-Free Framework For Any Video-to-Video Editing Tasks [Paper] [GitHub] [Project Page]
Novel View Synthesis.
- [TPAMI 2025] ViewCrafter: Taming Video Diffusion Models for High-fidelity Novel View Synthesis [Paper] [GitHub] [Project Page]
- [CVPR 2024 Highlight] ViVid-1-to-3: Novel View Synthesis with Video Diffusion Models [Paper] [GitHub] [Project Page]
- [ICLR 2025 Poster] CameraCtrl: Enabling Camera Control for Video Diffusion Models [Paper] [GitHub] [Project Page]
- [ICLR 2025 Poster] NVS-Solver: Video Diffusion Model as Zero-Shot Novel View Synthesizer [Paper] [GitHub]
Human Animation in Videos.
- [CVPR 2018] MoCoGAN: Decomposing Motion and Content for Video Generation [Paper] [GitHub]]
- [ICCV 2019] Everybody Dance Now [Paper] [GitHub] [Project Page]
- [ICCV 2019] Liquid Warping GAN: A Unified Framework for Human Motion Imitation, Appearance Transfer and Novel View Synthesis [Paper] [GitHub] [Project Page] [Dataset]
- [NeurIPS 2019] First Order Motion Model for Image Animation [Paper] [GitHub] [Project Page]
- [ICCV 2023] Adding Conditional Control to Text-to-Image Diffusion Models [Paper] [GitHub]
- [ICCV 2023] HumanSD: A Native Skeleton-Guided Diffusion Model for Human Image Generation [Paper] [GitHub] [Project Page]
- [CVPR 2023] Learning Locally Editable Virtual Humans [Paper] [GitHub] [Project Page] [Dataset]
- [CVPR 2023] Animate Anyone: Consistent and Controllable Image-to-Video Synthesis for Character Animation [Paper] [GitHub] [Project Page]
- [CVPRW 2024] LatentMan: Generating Consistent Animated Characters using Image Diffusion Models [Paper] [GitHub] [Project Page]
- [IJCAI 2024] Zero-shot High-fidelity and Pose-controllable Character Animation [Paper]
- [SCIS-2025] UniAnimate: Taming Unified Video Diffusion Models for Consistent Human Image Animation [Paper] [GitHub] [Project Page]
- [CVPR 2025] MIMO: Controllable Character Video Synthesis with Spatial Decomposed Modeling [Paper] [GitHub] [Project Page]
3D Generation
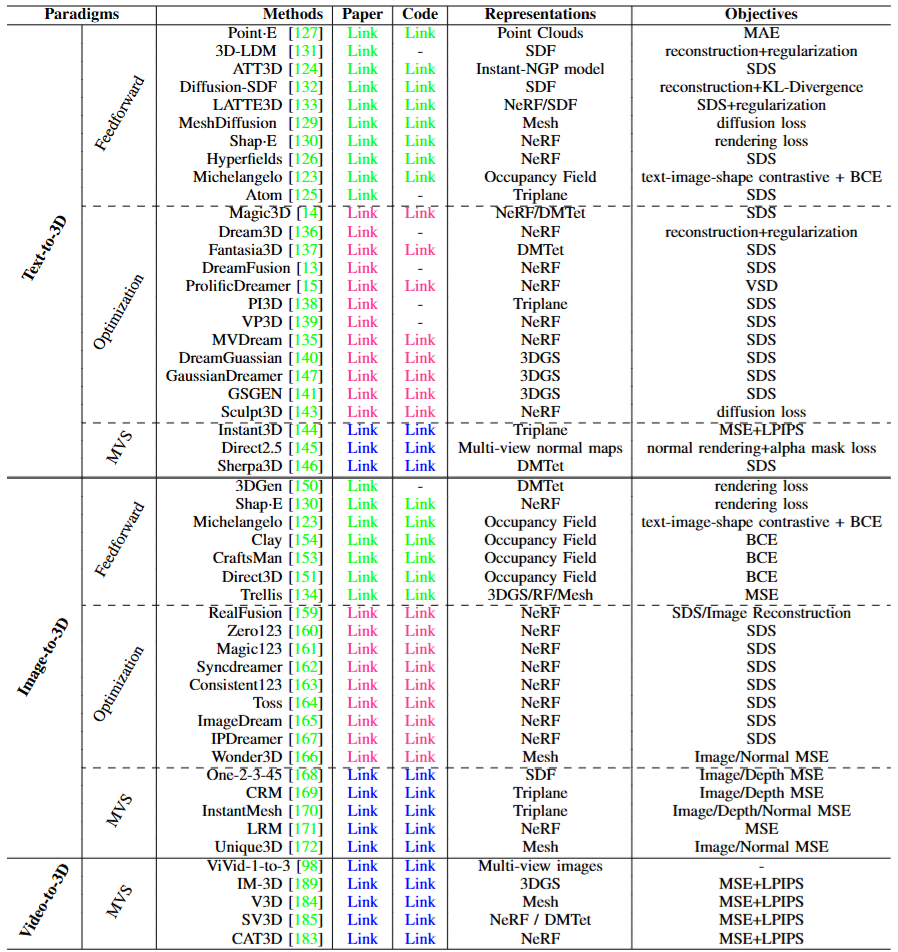
Recent text-to-3D, image-to-3D and video-to-3D generation methods.
3D Algorithms
Text-to-3D Generation.
Survey
- [arXiv 2023] Generative AI meets 3D: A Survey on Text-to-3D in AIGC Era [Paper]
- [arXiv 2024] Advances in 3D Generation: A Survey [Paper]
- [arXiv 2024] A Survey On Text-to-3D Contents Generation In The Wild [Paper]
Feedforward Approaches.
- [arXiv 2022] 3D-LDM: Neural Implicit 3D Shape Generation with Latent Diffusion Models [Paper] [GitHub]
- [arXiv 2022] Point-E: A System for Generating 3D Point Clouds from Complex Prompts [Paper] [GitHub]
- [arXiv 2023] Shap-E: Generating Conditional 3D Implicit Functions [Paper] [GitHub]
- [NeurIPS 2023] Michelangelo: Conditional 3d shape generation based on shape-image-text aligned latent representation [Paper] [GitHub] [Project Page]
- [ICCV 2023] ATT3D: Amortized Text-to-3D Object Synthesis [Paper] [Project Page]
- [ICLR 2023 Spotlight] MeshDiffusion: Score-based Generative 3D Mesh Modeling [Paper] [GitHub] [Project Page]
- [CVPR 2023] Diffusion-SDF: Text-to-Shape via Voxelized Diffusion [Paper] [GitHub] [Project Page]
- [ICML 2024] HyperFields:Towards Zero-Shot Generation of NeRFs from Text [Paper] [GitHub] [Project Page]
- [ECCV 2024] LATTE3D: Large-scale Amortized Text-To-Enhanced3D Synthesis [Paper] [Project Page]
- [arXiv 2024] AToM: Amortized Text-to-Mesh using 2D Diffusion [Paper] [GitHub] [Project Page]
Optimization-based Approaches.
- [ICLR 2023 notable top 5%] DreamFusion: Text-to-3D using 2D Diffusion [Paper] [Project Page]
- [CVPR 2023 Highlight] Magic3D: High-Resolution Text-to-3D Content Creation [Paper] [Project Page]
- [CVPR 2023] Dream3D: Zero-Shot Text-to-3D Synthesis Using 3D Shape Prior and Text-to-Image Diffusion Models [Paper] [Project Page]
- [ICCV 2023] Fantasia3D: Disentangling Geometry and Appearance for High-quality Text-to-3D Content Creation [Paper] [GitHub] [Project Page]
- [NeurIPS 2023 Spotlight] ProlificDreamer: High-Fidelity and Diverse Text-to-3D Generation with Variational Score Distillation [Paper] [GitHub] [Project Page]
- [ICLR 2024 Poster] MVDream: Multi-view Diffusion for 3D Generation [Paper] [GitHub] [Project Page]
- [ICLR 2024 Oral] DreamGaussian: Generative Gaussian Splatting for Efficient 3D Content Creation [Paper] [GitHub] [Project Page]
- [CVPR 2024] PI3D: Efficient Text-to-3D Generation with Pseudo-Image Diffusion [Paper]
- [CVPR 2024] VP3D: Unleashing 2D Visual Prompt for Text-to-3D Generation [Paper] [Project Page]
- [CVPR 2024] GSGEN: Text-to-3D using Gaussian Splatting [Paper] [GitHub] [Project Page]
- [CVPR 2024] GaussianDreamer: Fast Generation from Text to 3D Gaussians by Bridging 2D and 3D Diffusion Models [Paper] [GitHub] [Project Page]
- [CVPR 2024] Sculpt3D: Multi-View Consistent Text-to-3D Generation with Sparse 3D Prior [Paper] [GitHub] [Project Page]
MVS-based Approaches.
- [ICLR 2024 Poster] Instant3D: Fast Text-to-3D with Sparse-view Generation and Large Reconstruction Model [Paper] [Project Page]
- [CVPR 2024] Direct2.5: Diverse Text-to-3D Generation via Multi-view 2.5D Diffusion [Paper] [GitHub] [Project Page]
- [CVPR 2024] Sherpa3D: Boosting High-Fidelity Text-to-3D Generation via Coarse 3D Prior [Paper] [GitHub] [Project Page]
Image-to-3D Generation.
Feedforward Approaches.
- [arXiv 2023] 3DGen: Triplane Latent Diffusion for Textured Mesh Generation [Paper]
- [NeurIPS 2023] Michelangelo: Conditional 3d shape generation based on shape-image-text aligned latent representation [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Direct3D: Scalable Image-to-3D Generation via 3D Latent Diffusion Transformer [Paper] [GitHub] [Project Page]
- [SIGGRAPH 2024 Best Paper Honorable Mention] CLAY: A Controllable Large-scale Generative Model for Creating High-quality 3D Assets [Paper] [GitHub] [Project Page]
- [arXiv 2024] CraftsMan: High-fidelity Mesh Generation with 3D Native Generation and Interactive Geometry Refiner [Paper] [GitHub] [Project Page]
- [CVPR 2025] Structured 3D Latents for Scalable and Versatile 3D Generation [Paper] [GitHub] [Project Page]
Optimization-based Approaches.
- [arXiv 2023] Consistent123: Improve Consistency for One Image to 3D Object Synthesis [Paper] [Project Page]
- [arXiv 2023] ImageDream: Image-Prompt Multi-view Diffusion for 3D Generation [Paper] [GitHub] [Project Page]
- [CVPR 2023] RealFusion: 360° Reconstruction of Any Object from a Single Image [Paper] [GitHub] [Project Page]
- [ICCV 2023] Zero-1-to-3: Zero-shot One Image to 3D Object [Paper] [GitHub] [Project Page]
- [ICLR 2024 Poster] Magic123: One Image to High-Quality 3D Object Generation Using Both 2D and 3D Diffusion Priors [Paper] [GitHub] [Project Page]
- [ICLR 2024 Poster] TOSS: High-quality Text-guided Novel View Synthesis from a Single Image [Paper] [GitHub] [Project Page]
- [ICLR 2024 Spotlight] SyncDreamer: Generating Multiview-consistent Images from a Single-view Image [Paper] [GitHub] [Project Page]
- [CVPR 2024] Wonder3D: Single Image to 3D using Cross-Domain Diffusion [Paper] [GitHub] [Project Page]
- [ICLR 2025] IPDreamer: Appearance-Controllable 3D Object Generation with Complex Image Prompts [Paper] [GitHub]
MVS-based Approaches.
- [NeurIPS 2023] One-2-3-45: Any Single Image to 3D Mesh in 45 Seconds without Per-Shape Optimization [Paper] [GitHub] [Project Page]
- [ECCV 2024] CRM: Single Image to 3D Textured Mesh with Convolutional Reconstruction Model [Paper] [GitHub] [Project Page]
- [arXiv 2024] InstantMesh: Efficient 3D Mesh Generation from a Single Image with Sparse-view Large Reconstruction Models [Paper] [GitHub]
- [ICLR 2024 Oral] LRM: Large Reconstruction Model for Single Image to 3D [Paper] [Project Page]
- [NeurIPS 2024] Unique3D: High-Quality and Efficient 3D Mesh Generation from a Single Image [Paper] [GitHub] [Project Page]
Video-to-3D Generation.
- [CVPR 2024 Highlight] ViVid-1-to-3: Novel View Synthesis with Video Diffusion Models [Paper] [GitHub] [Project Page]
- [ICML 2024] IM-3D: Iterative Multiview Diffusion and Reconstruction for High-Quality 3D Generation [Paper] [Project Page]
- [TPAMI 2025] V3D: Video Diffusion Models are Effective 3D Generators [Paper] [GitHub] [Project Page]
- [ECCV 2024 Oral] SV3D: Novel Multi-view Synthesis and 3D Generation from a Single Image Using Latent Video Diffusion [Paper] [Project Page]
- [NeurIPS 2024 Oral] CAT3D: Create Anything in 3D with Multi-View Diffusion Models [Paper] [Project Page]
3D Applications
Avatar Generation.
- [CVPR 2023] Zero-Shot Text-to-Parameter Translation for Game Character Auto-Creation [Paper]
- [SIGGRAPH 2023] DreamFace: Progressive Generation of Animatable 3D Faces under Text Guidance [Paper] [Project Page]
- [NeurIPS 2023] Headsculpt: Crafting 3d head avatars with text [Paper] [GitHub] [Project Page]
- [NeurIPS 2023] DreamWaltz: Make a Scene with Complex 3D Animatable Avatars [Paper] [GitHub] [Project Page]
- [NeurIPS 2023 Spotlight] DreamHuman: Animatable 3D Avatars from Text [Paper] [Project Page]
Scene Generation.
- [ACM MM 2023] RoomDreamer: Text-Driven 3D Indoor Scene Synthesis with Coherent Geometry and Texture [Paper]
- [TVCG 2024] Text2NeRF: Text-Driven 3D Scene Generation with Neural Radiance Fields [Paper] [GitHub] [Project Page]
- [ECCV 2024] DreamScene: 3D Gaussian-based Text-to-3D Scene Generation via Formation Pattern Sampling [Paper] [GitHub] [Project Page]
- [ECCV 2024] DreamScene360: Unconstrained Text-to-3D Scene Generation with Panoramic Gaussian Splatting [Paper] [GitHub] [Project Page]
- [arXiv 2024] Urban Architect: Steerable 3D Urban Scene Generation with Layout Prior [Paper] [GitHub] [Project Page]
- [arXiv 2024] CityCraft: A Real Crafter for 3D City Generation [Paper] [GitHub]
3D Editing.
- [ECCV 2022] Unified Implicit Neural Stylization [Paper] [GitHub] [Project Page]
- [ECCV 2022] ARF: Artistic Radiance Fields [Paper] [GitHub] [Project Page]
- [SIGGRAPH Asia 2022] FDNeRF: Few-shot Dynamic Neural Radiance Fields for Face Reconstruction and Expression Editing [Paper] [GitHub] [Project Page]
- [CVPR 2022] FENeRF: Face Editing in Neural Radiance Fields [Paper] [GitHub] [Project Page]
- [SIGGRAPH 2023] TextDeformer: Geometry Manipulation using Text Guidance [Paper] [GitHub] [Project Page]
- [ICCV 2023] ObjectSDF++: Improved Object-Compositional Neural Implicit Surfaces [Paper] [GitHub] [Project Page]
- [ICCV 2023 Oral] Instruct-NeRF2NeRF: Editing 3D Scenes with Instructions [Paper] [GitHub] [Project Page]
4D Generation
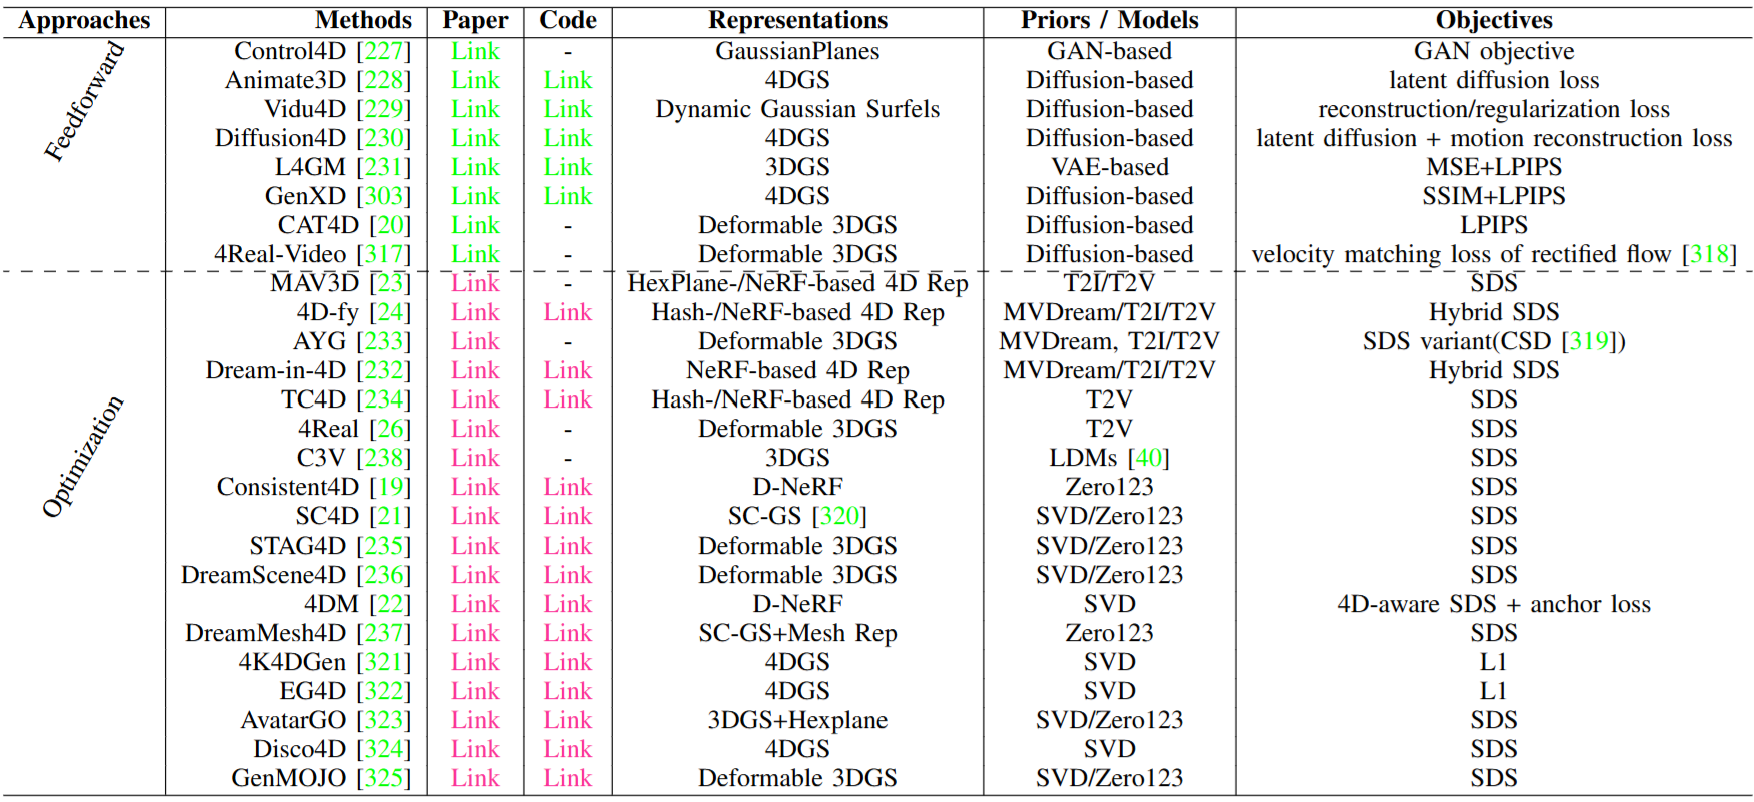
Representative works of 4D generation methods. ''Rep'' stands for representations.
4D Algorithms
Feedforward Approaches.
- [CVPR 2024] Control4D: Efficient 4D Portrait Editing with Text [Paper] [Project Page]
- [NeurIPS 2024] Animate3D: Animating Any 3D Model with Multi-view Video Diffusion [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Vidu4D: Single Generated Video to High-Fidelity 4D Reconstruction with Dynamic Gaussian Surfels [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models [Paper] [GitHub] [Project Page] [Dataset]
- [NeurIPS 2024] L4GM: Large 4D Gaussian Reconstruction Model [Paper] [GitHub] [Project Page]
Optimization-based Approaches.
- [ICML 2023] Text-To-4D Dynamic Scene Generation [Paper] [Project Page]
- [CVPR 2024] 4D-fy: Text-to-4D Generation Using Hybrid Score Distillation Sampling [Paper] [GitHub] [Project Page]
- [CVPR 2024] A Unified Approach for Text- and Image-guided 4D Scene Generation [Paper] [GitHub] [Project Page]
- [CVPR 2024] Align Your Gaussians: Text-to-4D with Dynamic 3D Gaussians and Composed Diffusion Models [Paper] [Project Page]
- [ECCV 2024] TC4D: Trajectory-Conditioned Text-to-4D Generation [Paper] [GitHub] [Project Page]
- [ECCV 2024] SC4D: Sparse-Controlled Video-to-4D Generation and Motion Transfer [Paper] [GitHub] [Project Page]
- [ECCV 2024] STAG4D: Spatial-Temporal Anchored Generative 4D Gaussians [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] 4Real: Towards Photorealistic 4D Scene Generation via Video Diffusion Models [Paper] [Project Page]
- [NeurIPS 2024] Compositional 3D-aware Video Generation with LLM Director [Paper] [Project Page]
- [NeurIPS 2024] DreamScene4D: Dynamic Multi-Object Scene Generation from Monocular Videos [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] DreamMesh4D: Video-to-4D Generation with Sparse-Controlled Gaussian-Mesh Hybrid Representation [Paper] [GitHub] [Project Page]
- [arXiv 2024] Trans4D: Realistic Geometry-Aware Transition for Compositional Text-to-4D Synthesis [Paper] [GitHub]
4D Applications
4D Editing.
- [CVPR 2024] Control4D: Efficient 4D Portrait Editing with Text [Paper] [Project Page]
- [CVPR 2024] Instruct 4D-to-4D: Editing 4D Scenes as Pseudo-3D Scenes Using 2D Diffusion [Paper] [GitHub] [Project Page]
Human Animation.
- [SIGGRAPH 2020] Robust Motion In-betweening [Paper]
- [CVPR 2022] Generating Diverse and Natural 3D Human Motions from Text [Paper] [GitHub] [Project Page]
- [SCA 2023] Motion In-Betweening with Phase Manifolds [Paper] [GitHub]
- [CVPR 2023] T2M-GPT: Generating Human Motion from Textual Descriptions with Discrete Representations [Paper] [GitHub] [Project Page]
- [ICLR 2023 notable top 25%] Human Motion Diffusion Model [Paper] [GitHub] [Project Page]
- [NeurIPS 2023] MotionGPT: Human Motion as a Foreign Language [Paper] [GitHub] [Project Page]
- [ICML 2024] HumanTOMATO: Text-aligned Whole-body Motion Generation [Paper] [GitHub] [Project Page]
- [CVPR 2024] MoMask: Generative Masked Modeling of 3D Human Motions [Paper] [GitHub] [Project Page]
- [CVPR 2024] Lodge: A Coarse to Fine Diffusion Network for Long Dance Generation Guided by the Characteristic Dance Primitives [Paper] [GitHub] [Project Page]
Datasets and Evaluations
Datasets
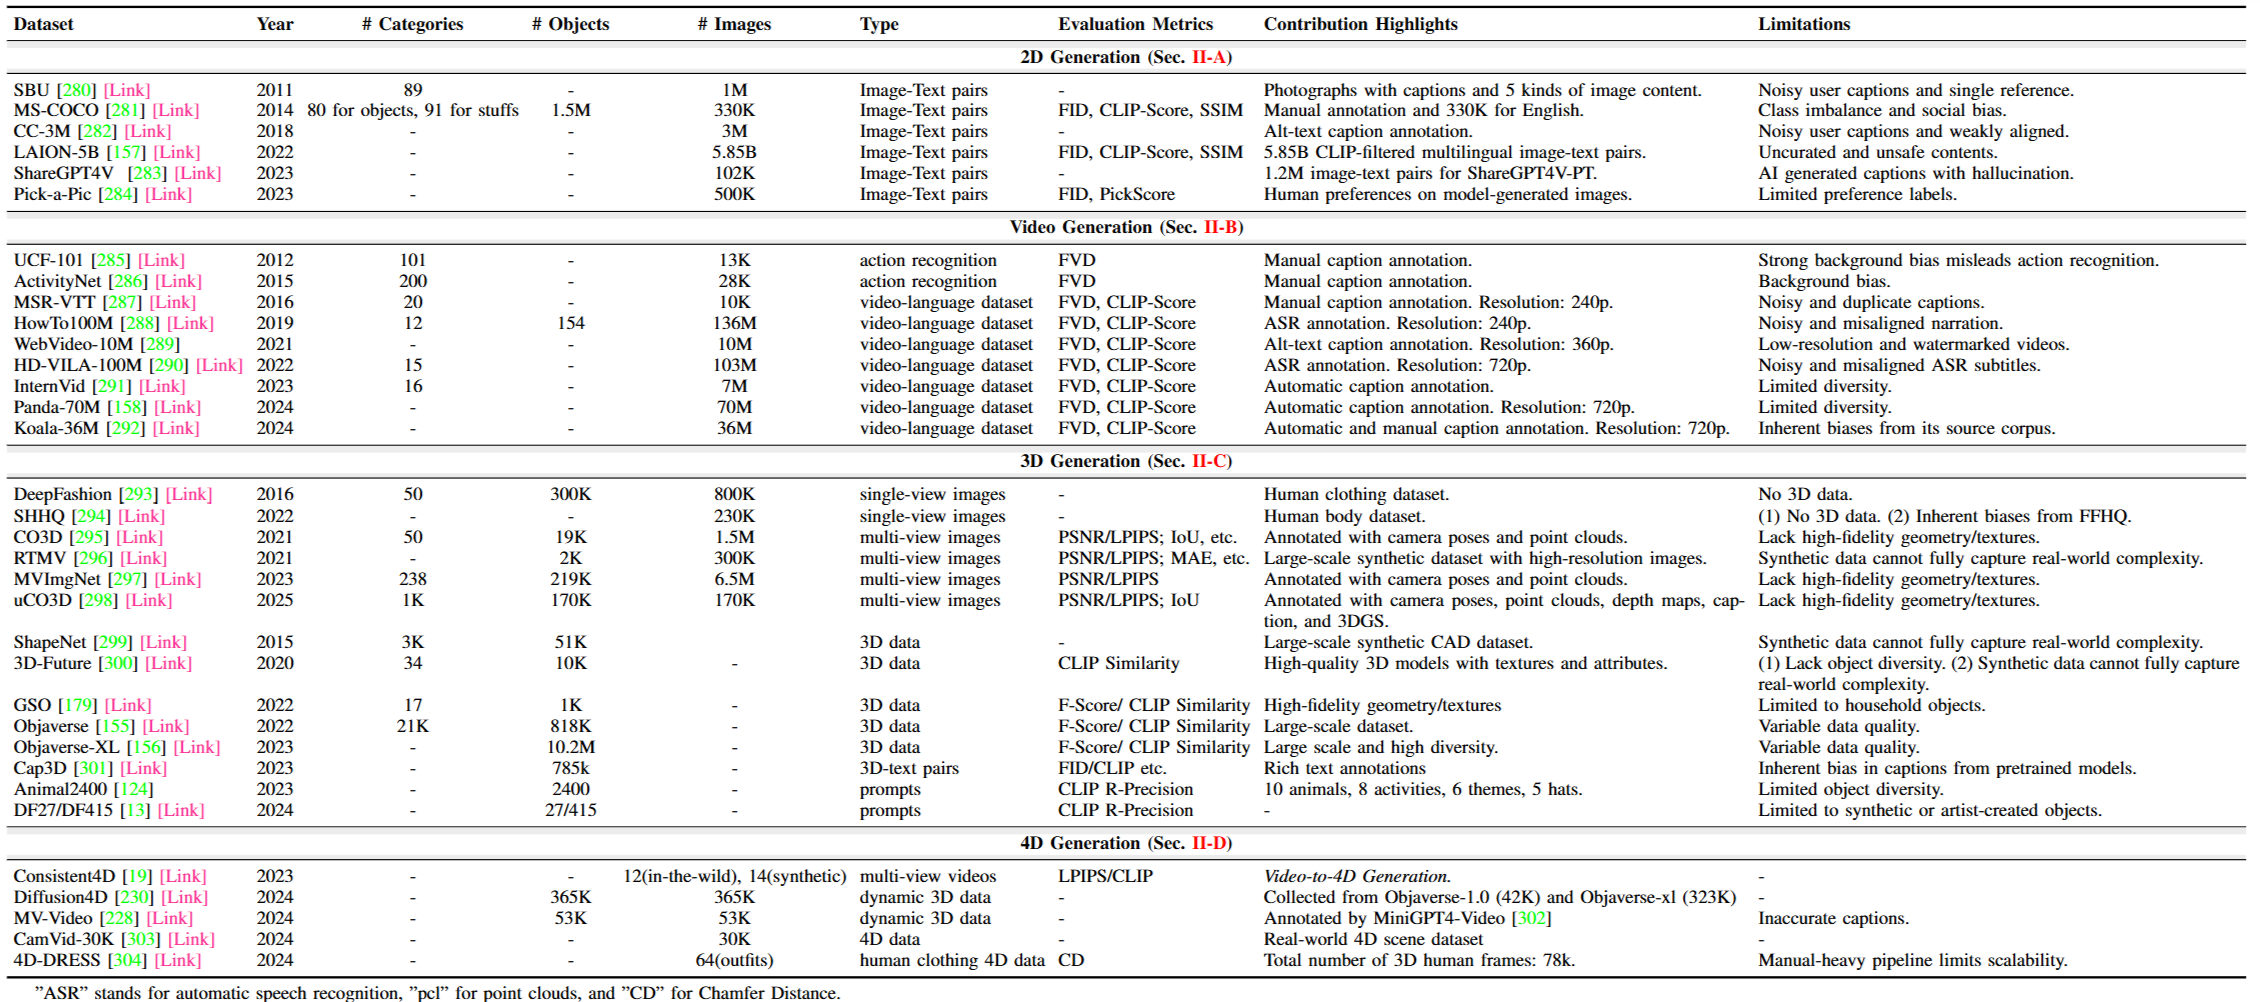
Summary of the widely-used 2D, video, 3D and 4D generation datasets. [Link] directs to dataset websites.
- [arXiv 2026] Sekai2: From World Exploration to Interactive World Modeling [Sekai2 dataset technical report] [Project Page]
Evaluation Metrics
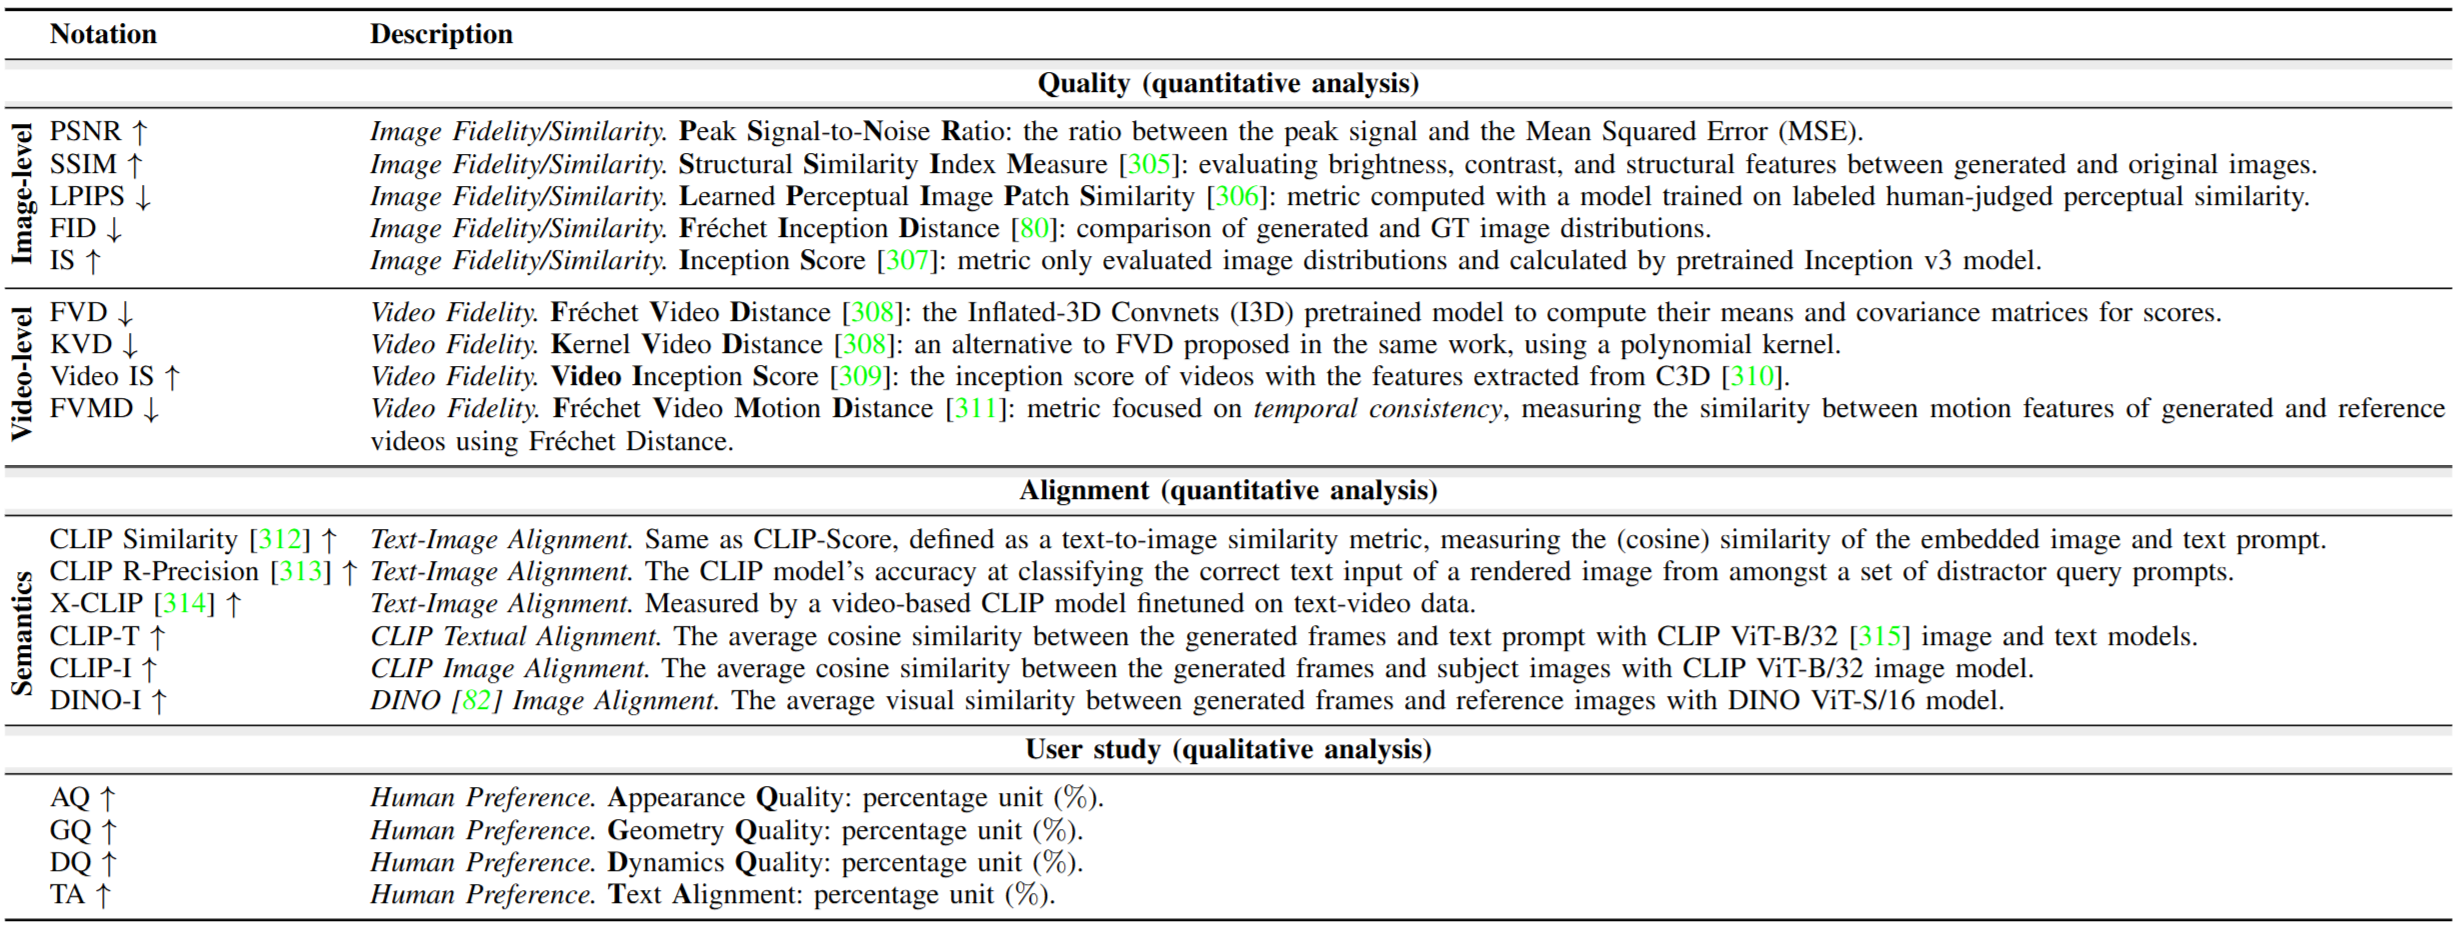
Summary of common evaluation metrics.
Other Related Resources
World Model Benchmark
- [NeurIPS 2026] WorldModelBench: Judging Video Generation Models As World Models [Paper] [GitHub] [Project Page]
- [arXiv 2026] PlayWorld: Benchmarking World Models with Agent Players over Long-Horizon Objectives [Paper] [GitHub] [Project Page]
World Foundation Model Platform
-
Atlas: the world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D, World Labs, Sept 1st, 2026.
-
WorldFoundry([GitHub]): an open-source infrastructure for world models.
-
NVIDIA Cosmos ([GitHub] [Paper]): NVIDIA Cosmos is a world foundation model platform for accelerating the development of physical AI systems.
- Cosmos-Transfer1:a world-to-world transfer model designed to bridge the perceptual divide between simulated and real-world environments.
- Cosmos-Predict1: a collection of general-purpose world foundation models for Physical AI that can be fine-tuned into customized world models for downstream applications.
- Cosmos-Reason1: a model that understands the physical common sense and generate appropriate embodied decisions in natural language through long chain-of-thought reasoning processes.
-
Genie3, Google Deepmind, August 5th, 2025.
🎯Back to Top - Our Survey Paper Collection
🔥 Awesome Text2X Resources
An open collection of state-of-the-art (SOTA), novel Text to X (X can be everything) methods (papers, codes and datasets), intended to keep pace with the anticipated surge of research.
Update Logs
2026.09.04- rename previousT2V SubsectiontoVideo Generation Subsection.2026.01.07- update 2025 papers collection into docs.
2025 Update Logs:
2025.12.03- update several papers accepted by NeurIPS 2025, congrats to all 🎉2025.05.08- update new layout.2025.04.18- update layout on section Related Resources.2025.03.10- CVPR 2025 Accepted Papers🎉2025.02.28- update several papers status "CVPR 2025" to accepted papers, congrats to all 🎉2025.01.23- update several papers status "ICLR 2025" to accepted papers, congrats to all 🎉2025.01.09- update layout.
2024 Update Logs:
2024.12.21adjusted the layouts of several sections and Happy Winter Solstice ⚪🥣.2024.09.26- update several papers status "NeurIPS 2024" to accepted papers, congrats to all 🎉2024.09.03- add one new section 'text to model'.2024.06.30- add one new section 'text to video'.2024.07.02- update several papers status "ECCV 2024" to accepted papers, congrats to all 🎉2024.06.21- add one hot Topic about AIGC 4D Generation on the section of Suvery and Awesome Repos.2024.06.17- an awesome repo for CVPR2024 Link 👍🏻2024.04.05adjusted the layout and added accepted lists and ArXiv lists to each section.2024.04.05- an awesome repo for CVPR2024 on 3DGS and NeRF Link 👍🏻2024.03.25- add one new survey paper of 3D GS into the section of "Survey and Awesome Repos--Topic 1: 3D Gaussian Splatting".2024.03.12- add a new section "Dynamic Gaussian Splatting", including Neural Deformable 3D Gaussians, 4D Gaussians, Dynamic 3D Gaussians.2024.03.11- CVPR 2024 Accpeted Papers Link- update some papers accepted by CVPR 2024! Congratulations🎉
4D Subsection
🎉 4D Accepted Papers
| Year | Title | Venue | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2026 | Geometry-aware 4D Video Generation for Robot Manipulation | ICLR 2026 | Link | Link | Link |
| 2026 | Turbo4DGen: Ultra-Fast Acceleration for 4D Generation | ICML 2026 | Link | Link | Link |
| 2026 | Code2Worlds: Empowering Coding LLMs for 4D World Generation | ICML 2026 | Link | Link | Link |
| 2026 | PerpetualWonder: Long-Horizon Action-Conditioned 4D Scene Generation | CVPR 2026 | Link | Link | Link |
| 2026 | AvatarPointillist: Autoregressive 4D Gaussian Avatarization | CVPR 2026 | Link | Link | Link |
| 2026 | Vista4D: Video Reshooting with 4D Point Clouds | CVPR 2026 | Link | Link | Link |
| 2026 | Motion 3-to-4: 3D Motion Reconstruction for 4D Synthesis | CVPR 2026 | Link | Link | Link |
| 2026 | NeuROK: Generative 4D Neural Object Kinematics | CVPR 2026 | Link | Coming Soon! | Link |
| 2026 | Choreographing a World of Dynamic Objects | CVPR 2026 | Link | Link | Link |
| 2026 | ActionMesh: Animated 3D Mesh Generation with Temporal 3D Diffusion | CVPR 2026 | Link | Link | Link |
| 2026 | MV-Forcing: Long Multi-View Video Generation via 4D-Grounded Spatio-Temporal Self-Forcing | ECCV 2026 | Link | Coming Soon! | Link |
| 2026 | VGGRPO: Towards World-Consistent Video Generation with 4D Latent Reward | ECCV 2026 | Link | -- | Link |
| 2026 | LivingWorld: Interactive 4D World Generation with Environmental Dynamics | ECCV 2026 | Link | Link | Link |
| 2026 | InterPet4D: A Multimodal 4D Human-Pet Interaction Dataset for Pet Motion Generation | ECCV 2026 | Link | Datasets | Link |
| 2026 | MoGe4D: Geometry-Aware Single-Image 4D Synthesis via Dense Trajectory Generation | ECCV 2026 | Link | Link | Link |
| 2026 | Alignment Is All You Need For X-to-4D Generation | IEEE Transactions on Multimedia (TMM) 2026 | Link | -- | Link |
| 2026 | Lift4D: Harmonizing Single-View 3D Estimation for 4D Reconstruction In-the-Wild | SIGGRAPH Asia 2026 | Link | Link | Link |
| 2026 | 4DAnyone: Create Anyone in 4D from a Casual Monocular Video | SIGGRAPH Asia 2026 | Link | Link | Link |
| 2026 | Streaming4D: Accelerate 4D World Models via Block-wise Video Generation and Incremental Reconstruction | CVPR 2026 4DV Workshop | Link | -- | -- |
Accepted Papers References
%accepted papers

@article{liu2025geometry,
  title={Geometry-aware 4D Video Generation for Robot Manipulation},
  author={Liu, Zeyi and Li, Shuang and Cousineau, Eric and Feng, Siyuan and Burchfiel, Benjamin and Song, Shuran},
  journal={arXiv preprint arXiv:2507.01099},
  year={2025}
}

@article{man2026turbo4dgen,
  title={Turbo4DGen: Ultra-Fast Acceleration for 4D Generation},
  author={Man, Yuanbin and Huang, Ying and Ren, Zhile and Yin, Miao},
  journal={arXiv preprint arXiv:2603.29572},
  year={2026}
}

@article{zhang2026code2worlds,
  title={Code2worlds: Empowering coding llms for 4d world generation},
  author={Zhang, Yi and Wang, Yunshuang and Zhang, Zeyu and Tang, Hao},
  journal={arXiv preprint arXiv:2602.11757},
  year={2026}
}

@article{zhan2026perpetualwonder,
  title={PerpetualWonder: Long-Horizon Action-Conditioned 4D Scene Generation},
  author={Zhan, Jiahao and Li, Zizhang and Yu, Hong-Xing and Wu, Jiajun},
  journal={arXiv preprint arXiv:2602.04876},
  year={2026}
}

@inproceedings{liu2026avatarpointillist,
  title     = {AvatarPointillist: Autoregressive 4D Gaussian Avatarization},
  author    = {Hongyu Liu and Xuan Wang and Yating Wang and Zijian Wu and Ziyu Wan and Yue Ma and Runtao Liu and Boyao Zhou and Yujun Shen and Qifeng Chen},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  year      = {2026}
}

@misc{lin2026vista4dvideoreshooting4d,
      title={Vista4D: Video Reshooting with 4D Point Clouds},
      author={Kuan Heng Lin and Zhizheng Liu and Pablo Salamanca and Yash Kant and Ryan Burgert and Yuancheng Xu and Koichi Namekata and Yiwei Zhao and Bolei Zhou and Micah Goldblum and Paul Debevec and Ning Yu},
      year={2026},
      eprint={2604.21915},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2604.21915},
}

@inproceedings{chen2026motion,
  title={Motion 3-to-4: 3d motion reconstruction for 4d synthesis},
  author={Chen, Hongyuan and Chen, Xingyu and Xu, Zexiang and Chen, Anpei},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={28947--28958},
  year={2026}
}

@inproceedings{geng2026neurok,
  title={NeuROK: Generative 4D Neural Object Kinematics},
  author={Geng, Chen and He, Guangzhao and Gao, Yue and Zhang, Yunzhi and Wu, Shangzhe and Wu, Jiajun},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={39239--39251},
  year={2026}
}

@article{lyu2026choreographing,
  title={Choreographing a World of Dynamic Objects},
  author={Lyu, Yanzhe and Geng, Chen and Dharmarajan, Karthik and Zhang, Yunzhi and Alzayer, Hadi and Wu, Shangzhe and Wu, Jiajun},
  journal={arXiv preprint arXiv:2601.04194},
  year={2026}
}

@article{sabathier2026actionmesh,
  title={Actionmesh: Animated 3d mesh generation with temporal 3d diffusion},
  author={Sabathier, Remy and Novotny, David and Mitra, Niloy J and Monnier, Tom},
  journal={arXiv preprint arXiv:2601.16148},
  year={2026}
}

@article{fiebelman2026mv,
  title={MV-Forcing: Long Multi-View Video Generation via 4D-Grounded Spatio-Temporal Self-Forcing},
  author={Fiebelman, Gal and Averbuch-Elor, Hadar and Benaim, Sagie},
  journal={arXiv preprint arXiv:2607.05376},
  year={2026}
}

@article{an2026vggrpo,
  title={Vggrpo: Towards world-consistent video generation with 4d latent reward},
  author={An, Zhaochong and Kupyn, Orest and Uscidda, Th{\'e}o and Colaco, Andrea and Ahuja, Karan and Belongie, Serge and Gonzalez-Franco, Mar and Gazulla, Marta Tintore},
  journal={arXiv preprint arXiv:2603.26599},
  year={2026}
}

@article{mun2026livingworld,
  title={LivingWorld: Interactive 4D World Generation with Environmental Dynamics},
  author={Mun, Hyeongju and Jin, In-Hwan and Kim, Sohyeong and Kong, Kyeongbo},
  journal={arXiv preprint arXiv:2604.01641},
  year={2026}
}

@article{peng2026interpet4d,
  title={InterPet4D: A Multimodal 4D Human-Pet Interaction Dataset for Pet Motion Generation},
  author={Peng, Yichen and Song, Jyun-Ting and Liao, Chen-Chieh and Kitani, Kris and Koike, Hideki and Wu, Erwin},
  journal={arXiv preprint arXiv:2607.10287},
  year={2026}
}

@misc{zhang2026geometryawaresingleimage4dsynthesis,
      title={Geometry-Aware Single-Image 4D Synthesis via Dense Trajectory Generation},
      author={Yanran Zhang and Ziyi Wang and Wenzhao Zheng and Zheng Zhu and Jie Zhou and Jiwen Lu},
      year={2026},
      eprint={2512.05044},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2512.05044},
}

@article{miao2026alignment,
  title={Alignment Is All You Need For X-to-4D Generation},
  author={Miao, Qiaowei and Li, Kehan and Luo, Yawei and Yang, Yi},
  journal={arXiv preprint arXiv:2607.02516},
  year={2026}
}

@article{litman2026lift4d,
  title={Lift4D: Harmonizing Single-View 3D Estimation for 4D Reconstruction In-the-Wild},
  author={Litman, Yehonathan and Ma, Xiaoxuan and Shah, Manan and Ugrinovic, Nicolas and Kitani, Kris and De la Torre, Fernando and Tulsiani, Shubham},
  journal={arXiv preprint arXiv:2606.23688},
  year={2026}
}

@article{jin2026fdanyone,
  title={4DAnyone: Create Anyone in 4D from a Casual Monocular Video},
  author={Jin, Yudong and Xie, Tao and Zhang, Qihang and Shen, Zehong and Xu, Zhen and Shen, Yujun and Bao, Hujun and Zhou, Xiaowei and Xu, Yinghao},
  journal={arXiv preprint arXiv:2608.20335},
  year={2026},
  url={https://arxiv.org/abs/2608.20335}
}

@article{liu2026streaming4d,
  title={Streaming4D: Accelerate 4D World Models via Block-wise Video Generation and Incremental Reconstruction},
  author={Liu, Xiaoyan and Liu, Jiaxin and Li, Kangrui and Zhou, Sifan},
  journal={arXiv preprint arXiv:2609.00610},
  year={2026}
}
💡 4D ArXiv Papers
1. Pixel-to-4D: Camera-Controlled Image-to-Video Generation with Dynamic 3D Gaussians
Melonie de Almeida, Daniela Ivanova, Tong Shi, John H. Williamson, Paul Henderson (University of Glasgow)
Abstract
Humans excel at forecasting the future dynamics of a scene given just a single image. Video generation models that can mimic this ability are an essential component for intelligent systems. Recent approaches have improved temporal coherence and 3D consistency in single-image-conditioned video generation. However, these methods often lack robust user controllability, such as modifying the camera path, limiting their applicability in real-world applications. Most existing camera-controlled image-to-video models struggle with accurately modeling camera motion, maintaining temporal consistency, and preserving geometric integrity. Leveraging explicit intermediate 3D representations offers a promising solution by enabling coherent video generation aligned with a given camera trajectory. Although these methods often use 3D point clouds to render scenes and introduce object motion in a later stage, this two-step process still falls short in achieving full temporal consistency, despite allowing precise control over camera movement. We propose a novel framework that constructs a 3D Gaussian scene representation and samples plausible object motion, given a single image in a single forward pass. This enables fast, camera-guided video generation without the need for iterative denoising to inject object motion into render frames. Extensive experiments on the KITTI, Waymo, RealEstate10K and DL3DV-10K datasets demonstrate that our method achieves state-of-the-art video quality and inference efficiency.2. ST-Gen4D: Embedding 4D Spatiotemporal Cognition into World Model for 4D Generation
Haonan Wang, Hanyu Zhou, Tao Gu, Luxin Yan
(Huazhong University of Science and Technology, National University of Singapore, Macquarie University)
Abstract
Generative models have achieved success in producing apparently coherent 2D videos, but remain challenging in the physical world due to lack of 4D spatiotemporal scale. Typically, existing 4D generative models directly embed macro scale constraints to enhance overall spatiotemporal consistency. However, these methods only ensure global appearance coherence and fail to reveal the local dynamics of the physical world. Our insight is that global appearance structure and local dynamic topology empower 4D spatiotemporal cognition, thereby enabling 4D generation with spatiotemporal regularities. In this work, we propose ST-Gen4D, a 4D generation framework with 4D spatiotemporal cognition-based world model. Our model is guided by four key designs: 1) Spatiotemporal representation. We encode various modalities into multiple representations as a feature basis. 2) Spatiotemporal cognition. We sculpture these representations into global appearance graph and local dynamic graph, and fuse them via semantic-bridged spatiotemporal fusion to obtain a 4D cognition graph. 3) Spatiotemporal reasoning. We utilize a world model to derive future state based on the 4D cognition. 4) Spatiotemporal generation. We leverage the derived cognition as condition to guide latent diffusion for 4D Gaussian generation. By deeply integrating 4D intrinsic cognition with generative priors, our model guarantees the structural rationality and topological consistency of 4D generation. Moreover, we propose ST-4D datasets by aggregating public 4D datasets and self-built subset. Extensive experiments demonstrate the superiority of our ST-Gen4D across 3D and 4D generation tasks.3. Geometric 4D Stitching for Grounded 4D Generation
Sunwoo Park, Taesung Kwon, Jong Chul Ye (KAIST AI)
Abstract
Recent 4D generation methods complete scene-level missing information using generative models and reconstruct the scene into radiance-based representations. However, these pipelines often present geometric inconsistencies in the generated content, and the radiance-based reconstruction requires expensive optimization. Furthermore, radiance-based representations often absorb these geometric inconsistencies into their view-dependent nature, failing to enforce the grounded geometric consistency. To address these issues, we propose Geometric 4D Stitching, an efficient framework that explicitly identifies missing geometric regions and complements them with geometrically grounded 4D stitches. As a result, our method constructs 4D scene representations in under 10 minutes on a single NVIDIA RTX 5090 GPU per one-step scene expansion, while improving geometric consistency. Moreover, we demonstrate that our explicit 4D stitching supports interative expansion of 4D mesh as well as 4D scene editing.4. Fast 4D Mesh Generation by Spatio-Temporal Attention Chains
Dvir Samuel, Yuval Atzmon, Gal Chechik, Yoni Kasten (NVIDIA Research, Bar-Ilan University)
Abstract
4D mesh generation has recently emerged as a powerful paradigm for recovering dynamic 3D structure from videos, but existing methods remain slow, computationally expensive, and difficult to scale to longer sequences. We introduce a training-free approach that accelerates 4D mesh generation while improving temporal correspondence quality. Our key observation is that temporal correspondences emerge inside a 4D backbone long before its generated meshes become visually accurate. We exploit this with a general framework we call Spatio-Temporal Attention Chain which propagates information across space and time. Starting from vertices on an anchor mesh, the chain maps vertices to latent tokens. It then follows temporal correspondences in latent space, and recovers frame-specific vertices through latent-to-vertex attention. This design avoids expensive explicit matching while preserving anchor mesh details and thereby improving dynamic mesh geometry and temporal consistency. Compared to state-of-the-art, our method generates a 4D mesh in 9 seconds, achieving a speedup while producing higher-quality results. Moreover, our approach scales to videos up to longer without degrading mesh quality. Beyond generation, the improved correspondences enable competitive zero-shot performance on two downstream tasks: 2D object tracking and 4D tracking. We further show that our framework enables reliable camera estimation, a capability not supported by prior 4D mesh generation methods.5. Helix4D: Complex 4D Mesh Generation
Jiraphon Yenphraphai, Jianqi Chen, Jian Wang, Gordon Qian, Sergey Tulyakov, Rameen Abdal, Raymond A. Yeh, Peter Wonka, Chaoyang Wang
(Snap, Purdue University, KAUST)
Abstract
Current video-to-4D methods struggle with complex topology changes, transparent materials, thin structures, and inner surfaces. We present Helix4D, a dynamic mesh generation framework by inheriting the expressive representation of Trellis2, adapting it from image-to-3D to video-conditioned 4D generation. Our design arises from two key questions: (a) how to enable Trellis2's frame-local attention to share information across frames while preserving its pretrained quality on rare cases such as transparent objects and inner surfaces, and (b) how to inject temporal information into a purely 3D positional encoding without breaking pretrained capabilities. We address (a) with a sliding-window cross-frame attention and anchor on the first frame. The first frame is generated by the base Trellis2 model and injected into our model, letting it inherit Trellis2's quality in rare cases through cross-frame attention. We address (b) with a 4D temporal encoding that repurposes redundant low-frequency spatial RoPE bands for time, extending the encoding from 3D with no additional parameters. Extensive experiments show the effectiveness of Helix4D for high-quality dynamic mesh generation on ActionBench and our own challenging complex dynamics set.6. SpatialAvatar-0: High-Quality 4D Head Avatar with Multi-Stage Reconstruction
Yiran Wang, Zeyu Zhang, Yuanming Li, Ziming Wang, Yang Zhao
(USYD, SpatialReal, ZJU, La Trobe)
Abstract
High-quality 4D head avatars from one or a few source portraits are central to telepresence, AR/VR, and digital-human interaction. 3D Gaussian Splatting (3DGS) has emerged as the dominant representation, with two complementary regimes (generalizable feed-forward predictors and per-subject refiners) maturing in parallel. However, existing feed-forward predictors are trained on a single dataset family with a hard-coded source count, inheriting the corresponding domain bias. Per-subject refiners require 300K--600K iterations and rely on adaptive densification that destroys upstream Gaussian layouts, preventing the two regimes from sharing a representation end-to-end. To bridge both regimes we propose SpatialAvatar-0 on a shared FLAME-mesh-bound Gaussian representation: a feed-forward generator with a parameter-free K-source mean-pool and a monocular-temporal to multi-view-spatial two-phase schedule that anchors against identity-prior collapse onto the smaller multi-view set. We further introduce a 10K-iter layout-preserving per-subject refinement loop that freezes the FLAME-binding and Gaussian count and replaces densification with a three-component anti-spike regularization. On VFHQ/HDTF cross-domain zero-shot we surpass the in-domain leader GAGAvatar by +1.5 dB PSNR despite never training on either test domain, and on the SplattingAvatar monocular benchmark we lead every reported metric, surpassing the 300K-iter GeoAvatar by +1.3 dB PSNR at up to 60x shorter per-subject schedule than common SOTA baselines.7. IMAGIN-4D: Image-Guided Controllable Interaction Generation
Sai Kumar Dwivedi, Federica Bogo, Buğra Tekin, Chenhongyi Yang, Nadine Bertsch, Tomas Hodan, Michael J. Black, Dimitrios Tzionas, Shreyas Hampali
(Meta, Max Planck Institute for Intelligent Systems, University of Amsterdam, Aristotle University of Thessaloniki)
Abstract
Generating human-object interactions (HOI) is central to character animation, robotics, AR/VR, and embodied AI. Recent HOI generation methods synthesize motion from text, object geometry, and sparse waypoints, controlling action semantics and object trajectories. However, these signals underspecify interaction: the same prompt and trajectory can produce different grasps, approach directions, body poses, object poses, contacts, and body-object layouts. We address this ambiguity with a reference image as a visual specification of the desired interaction snapshot. However, a single global image representation conflates distinct cues and conditions all frames on identical visual evidence. We therefore introduce IMAGIN-4D, a diffusion-based HOI generator that decomposes image conditioning spatio-temporally. For spatial conditioning, IMAGIN-4D extracts supervised interaction-state tokens for body pose, object pose, body-object contact, and spatial relationships at the depicted frame. For temporal conditioning, it computes frame-aware tokens by querying image patches per generated frame, allowing sequence segments to attend to different visual cues from the same image. To balance image, text, and waypoint cues, IMAGIN-4D uses role-aware conditioning: text, waypoints, and interaction-state tokens use separate AdaLN streams, while frame-aware visual tokens cross-attend with motion tokens. Since HOI motion datasets lack paired images, we build a synthetic motion-to-image rendering pipeline from FullBodyManipulation (FBM) and introduce an image-adherence metric to evaluate whether generated motions match the reference snapshot. Experiments on FBM and BEHAVE show that IMAGIN-4D improves fine-grained interaction control over single-token and uniformly image-conditioned baselines while preserving waypoint-following and motion quality.8. MVTrack4Gen: Multi-View Point Tracking as Geometric Supervision for 4D Video Generation
JoungBin Lee, Jaewoo Jung, Jongmin Lee, Tongmin Kim, Hyunsung Kim, Takuya Narihira, Kazumi Fukuda, Jahyeok Koo, Jisang Han, Yuki Mitsufuji, Seungryong Kim
(KAIST AI, Sony AI, Sony Group Corporation)
Abstract
Synthesizing a novel-view video from a monocular reference video along a target camera trajectory requires both geometric consistency and motion fidelity with respect to the reference video. Existing methods based on explicit 3D representations are limited by the accuracy of off-the-shelf reconstruction modules, which often produce inaccurate geometry for dynamic objects in monocular videos. In contrast, camera-conditioning-only methods can achieve high visual quality but often struggle to preserve geometric and motion consistency. In this work, we introduce MVTrack4Gen (Multi-View point Tracking for Novel-View Generation), a motion-aware training framework that leverages multi-view point tracking as an additional geometric and motion supervision signal for camera-conditioning-only novel-view video diffusion models. Our key finding is that specific attention layers encode strong correspondence cues, where query features attend to key features at geometrically corresponding locations across views and over time, and the misalignment of these correspondences causes motion inconsistency. Based on this observation, we route these features into an auxiliary multi-view tracking head and jointly train the diffusion model with a point-tracking objective. By explicitly strengthening these motion-aware correspondences, MVTrack4Gen improves existing models to better follow the motion in the reference view and maintain cross-view geometric consistency. Across diverse benchmarks, our method achieves state-of-the-art geometric consistency and competitive camera accuracy.9. RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation
Haoyu Zhao, Xingyue Zhao, Siteng Huang, Xin Li, Deli Zhao, Zhongyu Li
(DAMO Academy Alibaba Group, Hong Kong Embodied AI Lab, CUHK, Hupan Lab)
Abstract
Robotic manipulation in the open world requires not only recognizing what a scene looks like, but also anticipating how its 3D structure moves under interaction. We argue that synchronized RGB, depth, and optical flow, namely RGB-DF, provide a physically grounded representation that captures the underlying 4D dynamics of a scene. Compared to 2D pixel videos, this multi-modal synergy aligns visual appearance with geometric structure and temporal motion, creating a representation space significantly closer to the low-level end-effector actions demanded by robotic systems, thereby narrowing the gap between world prediction and policy learning. Building on this insight, we introduce RynnWorld-4D, a generative model that co-produces future RGB frames, depth maps, and optical flow from a single RGB-D image and a language instruction within one unified diffusion process. This 4D world model features a tri-branch architecture that integrates cross-modal attention with frame-wise 3D RoPE, ensuring that appearance, geometry, and motion evolve consistently. To supply training data at scale, we curate Rynn4DDataset 1.0, a massive dataset of over 254.4 million frames across egocentric human and robotic manipulation videos with high-quality pseudo-labels for depth and optical flow. We further propose RynnWorld-4D-Policy, an inverse dynamics head that consumes the internal 4D representations of RynnWorld-4D in a single forward pass, bypassing expensive multi-step denoising, to output robot actions in a closed-loop manner. Experiments show that RynnWorld-4D produces temporally and spatially coherent 4D predictions, and that RynnWorld-4D-Policy achieves state-of-the-art performance on real-world dexterous bimanual manipulation tasks, particularly excelling in tasks demanding spatial precision and temporal coordination.10. SkelGen4D: Weakly-Supervised Skeleton-Based 4D Generation for Text-Driven Mesh Animation
Hao Feng, Zhi Zuo, Jia-Hui Pan, Ka-Hei Hui, Zhengzhe Liu, Dian Zhang, Haoran Xie, Bin Sheng, Jingyu Hu
(Lingnan University, Chinese University of Hong Kong, Autodesk Research, Shanghai Jiao Tong University)
Abstract
We study 4D generation to synthesize temporally coherent sequences of 3D geometry for animation and content creation. In contrast to existing SDS-based optimization methods and video-driven animation approaches, we adopt a skeleton-driven animation framework aligned with standard industrial pipelines, which enables explicit control and editing. To this end, we propose SkelGen4D, a weakly supervised feed-forward framework for text-driven mesh animation that generates explicit skeleton motions without requiring per-frame skeleton annotations. SkelGen4D first recovers temporally consistent pseudo-skeletons from animated meshes via differentiable fitting, and then generates text-conditioned skeleton motion sequences in a feed-forward manner, further refined with Motion-GRPO to ensure temporally coherent, physically plausible, and articulated animation. We evaluate our method on two large-scale benchmarks, Truebones Zoo and Diffusion4D. Our results show that our weakly supervised skeleton modeling matches or surpasses fully supervised baselines while scaling to diverse object categories for high-quality text-driven mesh animation. Further, our method supports flexible motion editing and is aligned with standard animation production pipelines.11. Hallo4D: Multi-Modal Hallucination Mitigation for Consistent Spatio-Temporal Generation
Hongbo Wang, Huaibo Huang, Jie Cao, Jin Liu, Haoyang Tong, Ran He
(CASIA, UCAS, ShanghaiTech)
Abstract
While recent advances in 3D generation have enabled impressive visual synthesis, existing methods often rely on 2D diffusion supervision without explicit mechanisms for geometric consistency, leading to spatial hallucinations such as duplicated structures and misaligned geometry. These issues become more severe in 4D generation, where maintaining consistency across viewpoints and temporal evolution introduces additional challenges, including jitter, identity flicker, and structural drift. We present \textbf{Hallo4D}, a unified and model-agnostic framework for mitigating spatiotemporal hallucinations in 3D and 4D content generation. Hallo4D introduces a generation-detection-correction paradigm that leverages large multimodal language models (LMMs) to identify and summarize spatial and temporal inconsistencies from multi-view and multi-frame renderings. These insights guide a consensus-driven image-space consistency optimization, where an LMM-based selector evaluates candidate corrections through multi-model voting, without requiring retraining or architectural modifications. To further improve temporal consistency and optimization efficiency, Hallo4D incorporates motion-aware keyframe sampling, LMM-guided initialization, and appearance alignment. We additionally introduce exposure-aware optimization and visibility pruning to enhance robustness under challenging viewpoints. Extensive experiments demonstrate that Hallo4D consistently outperforms strong baselines across diverse 3D and 4D generation settings, providing a scalable and generalizable solution for consistency-aware content generation.12. PE-Field 4D: Video Generation Models as Canvas
Yunpeng Bai, Haoxiang Li, Qixing Huang (UT Austin, Pixocial Technology)
Abstract
Diffusion Transformers have recently achieved strong performance in video generation, yet controlling scene geometry under viewpoint changes and camera motion remains challenging. In this work, we revisit the role of positional encoding in video diffusion transformers and show that it provides a useful spatial bias for geometry-aware control. Specifically, if reference tokens are encoded according to their projected locations in the target view, the denoising model is encouraged to retrieve content from position aligned regions of the input video. Building on this observation, we introduce a geometry-aware cross-attention mechanism that enables target video latent tokens to attend to structured context tokens derived from reference images or frames. To establish correspondence between the reference content and the target camera trajectory, we equip the context tokens with a projected positional encoding scheme that combines target-view 2D reprojection with depth-aware disambiguation. At the same time, we preserve the original spatiotemporal positional encoding of the generated video latent, allowing geometric guidance to be injected while maintaining consistency with the video model's native latent structure. The resulting framework provides a simple and effective approach for controllable video generation. It improves spatial controllability in viewpoint-dependent editing tasks, including camera re-trajectory, novel-view video synthesis, and geometry-aware video editing, while preserving the generative prior of the underlying video diffusion model.13. Beyond Pixels: From Video Priors to 4D Worlds
Zihao Liu, Xiaolong Shen, Zhenglin Zhou, Ruijie Quan, Yi Yang (Zhejiang University)
Abstract
4D generation synthesizes dynamic 3D scenes from conditions such as text or images. Existing methods either reconstruct generated RGB videos with a separate 4D model or adapt a particular video generator to predict geometry directly. The former suffers from distribution mismatch and error propagation, whereas the latter ties 4D prediction to a specific generator and may require retraining when the generator or conditioning regime changes. We ask whether the final denoised latents of video models that share a variational autoencoder (VAE) can instead provide a reusable interface to explicit 4D prediction. Building on this insight, we introduce direct latent-to-4D generation and instantiate it as Latent-to-4D, which bypasses RGB by aligning a video latent with the token grid of a pretrained 4D decoder and refining it through frame-wise and global spatiotemporal attention. Trained on roughly 1K existing reconstruction clips, a single checkpoint transfers unchanged across multiple video diffusion transformers within the same VAE family. On Text4D-200 and I4D-200, Latent-to-4D surpasses matched same-latent Wan+4RC cascades in projection-based DINO-F1 by 2.88--3.45 and 5.81 points, respectively, while also being preferred by human raters for geometry, temporal stability, and overall quality.14. Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models
Yuanhao Ban, Jiaqi Feng, Hengguang Zhou, Xiaohuan Pei, Justin Cui, Cho-Jui Hsieh
(UCLA, Tsinghua University)
Abstract
Streaming autoregressive diffusion models enable real-time, long-horizon video generation, but their training objectives optimize local frame prediction rather than the geometry and dynamics of a coherent world: long rollouts accumulate geometric drift and degrade into static or unnatural motion. Recent bidirectional approaches address this problem using rewards signals built upon 3D Gaussian-Splatting reconstruction. However, a single rigid 3d reconstruction cannot model a dynamic scene, so this critic penalizes genuine object motion as reconstruction error and is maximized by freezing the video. This shortcut is especially detrimental in the AR setting, where each chunk can propagate an already-static configuration. In this work, we propose Stream4D, which replaces the static critic with a feed-forward 4D reconstruction reward that explicitly models scene dynamics, allowing coherent motion to receive high consistency rewards. To further guide motion magnitude and quality, we add a motion prior that rewards natural scene-flow magnitude while penalizing jitter and non-rigid artifacts. Our final recipe combines these two terms with a lightweight perceptual anchor. Across various autoregressive video backbones and various generation horizons, Stream4D improves 4D reconstruction quality, preserves motion more effectively, and achieves higher human-aligned preference.15. 4DStreamCtrl: Interactive Video Generation with Online 4D Control
Shiqian Li, Chenguo Lin, Zhiguang Liu, Yu Tang, Jiarong Ou, Rui Chen, Yixin Zhu
(Peking University, Tencent Hunyuan)
Abstract
Generative video models now synthesize footage nearly indistinguishable from reality. Their promise as interactive tools hinges on fine-grained control of how objects and the camera move over time, yet each existing approach captures only part of this: camera-parameter methods steer the viewpoint but cannot move objects, 2D-trajectory methods act in the image plane and ignore depth and occlusion, and recent 3D methods add geometry but run only offline at a fixed length. In particular, none combines 3D-consistent control of both camera and objects with real-time, streaming generation. Here we show that camera motion, object trajectories, and depth can be unified into a single 3D point-track representation, from which one model performs joint camera and object control, depth editing, and motion transfer in a single forward pass. To learn this interface at scale, we mine in-the-wild video for 3D motion supervision, yielding OpenVidHD-Motion3D, and encode it with a lightweight Geometric Motion Head that plugs into a pretrained video diffusion model. Because this encoder is temporally separable, we distill the model into a causal streaming student that generates arbitrarily long video in four denoising steps at memory independent of length. This unified design surpasses prior camera-only, 2D, and offline-3D methods in motion-control precision while covering modalities they address only in isolation. 4DStreamCtrl runs at 20 FPS on a single high-end GPU for 480p video and stays temporally coherent over hundreds of frames, enabling, to our knowledge, interactive 4D-controllable streaming generation for the first time. More broadly, grounding generation in explicit 3D geometry with efficient causal inference points toward interactive world models with closed-loop spatiotemporal control, from controllable simulators to real-time visual imagination for embodied agents.16. GAE: Learning a Geometry-Native Latent Space for 3D-Consistent World Generation
Jiahao Lu, Minghao Yin, Wenbo Hu, Hengyu Liu, Wang Zhao, Sai-Kit Yeung, Ying Shan, Yuan Liu
(The Hong Kong University of Science and Technology, ARC Lab Tencent IEG, The University of Hong Kong, The University of Texas at Austin)
Abstract
We present a compact geometry-native latent space as a shared foundation for perception and generation. Visual generators can produce photorealistic frames without preserving a consistent 3D scene. We argue that this is not only a modeling problem but also a representation problem: generators typically evolve appearance-centric latents, while perception models recover geometry in a semantically rich space that encodes cross-view structure. Rather than adding geometry as another output, we reparameterize a geometry foundation model's features into a compact latent space for generation. We realize this shift with the geometry-native autoencoder (GAE), whose latent is jointly decodable to appearance, depth, cameras, and point maps. With this state, a standard conditional flow supports diverse generation tasks. In controlled comparisons that hold the generator and training protocol fixed, replacing the latent with GAE improves both visual quality and independently measured 3D coherence: FVD falls by 12.7% and 23.1% on RealEstate10K and DL3DV, and camera-trajectory error is halved on RealEstate10K. Together, these results show that the latent space is central to geometry-consistent generation and can serve as a shared interface between perception and generation.| Year | Title | ArXiv Time | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2026 | Pixel-to-4D: Camera-Controlled Image-to-Video Generation with Dynamic 3D Gaussians | 2 Jan 2026 | Link | -- | Link |
| 2026 | InSpatio-World | 20 Mar 2026 | Live Demo | Link | Link |
| 2026 | ST-Gen4D: Embedding 4D Spatiotemporal Cognition into World Model for 4D Generation | 8 May 2026 | Link | -- | -- |
| 2026 | Geometric 4D Stitching for Grounded 4D Generation | 11 May 2026 | Link | -- | -- |
| 2026 | Fast 4D Mesh Generation by Spatio-Temporal Attention Chains | 19 May 2026 | Link | -- | Link |
| 2026 | Helix4D: Complex 4D Mesh Generation | 25 May 2026 | Link | -- | Link |
| 2026 | SpatialAvatar-0: High-Quality 4D Head Avatar with Multi-Stage Reconstruction | 14 Jun 2026 | Link | -- | Link |
| 2026 | IMAGIN-4D: Image-Guided Controllable Interaction Generation | 22 Jun 2026 | Link | -- | Link |
| 2026 | MVTrack4Gen: Multi-View Point Tracking as Geometric Supervision for 4D Video Generation | 24 Jun 2026 | Link | Link | Link |
| 2026 | RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation | 7 Jul 2026 | Link | Link | Link |
| 2026 | SkelGen4D: Weakly-Supervised Skeleton-Based 4D Generation for Text-Driven Mesh Animation | 9 Jul 2026 | Link | -- | -- |
| 2026 | Hallo4D: Multi-Modal Hallucination Mitigation for Consistent Spatio-Temporal Generation | 15 Jul 2026 | Link | Link | Link |
| 2026 | PE-Field 4D: Video Generation Models as Canvas | 17 Jul 2026 | Link | -- | -- |
| 2026 | Beyond Pixels: From Video Priors to 4D Worlds | 11 Aug 2026 | Link | Link | Link |
| 2026 | Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models | 20 Aug 2026 | Link | -- | Link |
| 2026 | 4DStreamCtrl: Interactive Video Generation with Online 4D Control | 27 Aug 2026 | Link | -- | Link |
| 2026 | GAE: Learning a Geometry-Native Latent Space for 3D-Consistent World Generation | 21 Sep 2026 | Link | Link | Link |
ArXiv Papers References
%axiv papers

@article{de2026pixel,
  title={Pixel-to-4D: Camera-Controlled Image-to-Video Generation with Dynamic 3D Gaussians},
  author={de Almeida, Melonie and Ivanova, Daniela and Shi, Tong and Williamson, John H and Henderson, Paul},
  journal={arXiv preprint arXiv:2601.00678},
  year={2026}
}

@misc{inspatio-world,
    title={InSpatio-World},
    author={InSpatio-World Contributors},
    howpublished={\url{https://github.com/inspatio/inspatio-world}},
    year={2025}
}

@article{wang2026st,
  title={ST-Gen4D: Embedding 4D Spatiotemporal Cognition into World Model for 4D Generation},
  author={Wang, Haonan and Zhou, Hanyu and Gu, Tao and Yan, Luxin},
  journal={arXiv preprint arXiv:2605.07390},
  year={2026}
}

@article{park2026geometric,
  title={Geometric 4D Stitching for Grounded 4D Generation},
  author={Park, Sunwoo and Kwon, Taesung and Ye, Jong Chul},
  journal={arXiv preprint arXiv:2605.09984},
  year={2026}
}

@article{samuel2026fast,
  title={Fast 4D Mesh Generation by Spatio-Temporal Attention Chains},
  author={Samuel, Dvir and Atzmon, Yuval and Chechik, Gal and Kasten, Yoni},
  journal={arXiv preprint arXiv:2605.19786},
  year={2026}
}

@article{yenphraphai2026helix4d,
  title={Helix4D: Complex 4D Mesh Generation},
  author={Yenphraphai, Jiraphon and Chen, Jianqi and Wang, Jian and Qian, Gordon and Tulyakov, Sergey and Abdal, Rameen and Yeh, Raymond A and Wonka, Peter and Wang, Chaoyang},
  journal={arXiv preprint arXiv:2605.26109},
  year={2026}
}

@article{wang2026spatialavatar,
  title={SpatialAvatar-0: High-Quality 4D Head Avatar with Multi-Stage Reconstruction},
  author={Wang, Yiran and Zhang, Zeyu and Li, Yuanming and Wang, Ziming and Zhao, Yang},
  journal={arXiv preprint arXiv:2606.15659},
  year={2026}
}

@misc{dwivedi2026imagin4dimageguidedcontrollableinteraction,
      title={IMAGIN-4D: Image-Guided Controllable Interaction Generation},
      author={Sai Kumar Dwivedi and Federica Bogo and Buğra Tekin and Chenhongyi Yang and Nadine Bertsch and Tomas Hodan and Michael J. Black and Dimitrios Tzionas and Shreyas Hampali},
      year={2026},
      eprint={2606.23675},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2606.23675},
}

@misc{lee2026mvtrack4genmultiviewpointtracking,
      title={MVTrack4Gen: Multi-View Point Tracking as Geometric Supervision for 4D Video Generation},
      author={JoungBin Lee and Jaewoo Jung and Jongmin Lee and Tongmin Kim and Hyunsung Kim and Takuya Narihira and Kazumi Fukuda and Jahyeok Koo and Jisang Han and Yuki Mitsufuji and Seungryong Kim},
      year={2026},
      eprint={2606.26087},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2606.26087},
}

@article{zhao2026rynnworld,
  title={RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation},
  author={Zhao, Haoyu and Zhao, Xingyue and Huang, Siteng and Li, Xin and Zhao, Deli and Li, Zhongyu},
  journal={arXiv preprint arXiv:2607.06559},
  year={2026}
}

@article{feng2026skelgen4d,
  title={SkelGen4D: Weakly-Supervised Skeleton-Based 4D Generation for Text-Driven Mesh Animation},
  author={Feng, Hao and Zuo, Zhi and Pan, Jia-Hui and Hui, Ka-Hei and Liu, Zhengzhe and Zhang, Dian and Xie, Haoran and Sheng, Bin and Hu, Jingyu},
  journal={arXiv preprint arXiv:2607.08246},
  year={2026}
}

@article{wang2026hallo4d,
  title={Hallo4D: Multi-Modal Hallucination Mitigation for Consistent Spatio-Temporal Generation},
  author={Wang, Hongbo and Huang, Huaibo and Cao, Jie and Liu, Jin and Tong, Haoyang and He, Ran},
  journal={arXiv preprint arXiv:2607.12752},
  year={2026}
}

@article{bai2026pe,
  title={PE-Field 4D: Video Generation Models as Canvas},
  author={Bai, Yunpeng and Li, Haoxiang and Huang, Qixing},
  journal={arXiv preprint arXiv:2607.15667},
  year={2026}
}

@misc{liu2026pixelsvideopriors4d,
      title={Beyond Pixels: From Video Priors to 4D Worlds},
      author={Zihao Liu and Xiaolong Shen and Zhenglin Zhou and Ruijie Quan and Yi Yang},
      year={2026},
      eprint={2608.10744},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2608.10744},
}

@misc{ban2026stream4d4dconsistencystreamingautoregressive,
      title={Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models},
      author={Yuanhao Ban and Jiaqi Feng and Hengguang Zhou and Xiaohuan Pei and Justin Cui and Cho-Jui Hsieh},
      year={2026},
      eprint={2608.19556},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2608.19556},
}

@article{li20264dstreamctrl,
  title={4DStreamCtrl: Interactive Video Generation with Online 4D Control},
  author={Li, Shiqian and Lin, Chenguo and Liu, Zhiguang and Tang, Yu and Ou, Jiarong and Chen, Rui and Zhu, Yixin},
  journal={arXiv preprint arXiv:2608.25479},
  year={2026}
}

@misc{lu2026gaelearninggeometrynativelatent,
      title={GAE: Learning a Geometry-Native Latent Space for 3D-Consistent World Generation},
      author={Jiahao Lu and Minghao Yin and Wenbo Hu and Hengyu Liu and Wang Zhao and Sai-Kit Yeung and Ying Shan and Yuan Liu},
      year={2026},
      eprint={2609.24981},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.24981},
}
Previous Papers and Other Awesome Repos
Year 2025
For more details, please check the 2025 4D Papers, including 35 accepted papers, 6 arXiv papers and 2 arXiv surveys.
Year 2024
For more details, please check the 2024 4D Papers, including 27 accepted papers and 7 arXiv papers.
Year 2023
In 2023, tasks classified as text/Image to 4D and video to 4D generally involve producing four-dimensional data from text/Image or video input. For more details, please check the 2023 4D Papers, including 6 accepted papers and 3 arXiv papers.
Video Generation Subsection
🎉 Video Accepted Papers
💡 Video ArXiv Papers
1. SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models
Junchao Huang, Guian Fang, Shengju Qian, Xianghao Kong, Zhuoran Zhao, Wei Huang, Yihua Du, Zixin Zhang, Justin Cui, Yuchao Gu, Yukang Chen, Xinting Hu, Tianyu He, Shaoshuai Shi, Zhuotao Tian, Xin Wang, Mike Zheng Shou, Li Jiang
(CUHK-SZ, SLAI, NUS, CUHK, HKUST, HKUST-GZ, NVIDIA, UCLA, MSRA)
Abstract
We introduce SolarWM, a fully open foundation for building interactive video world models from data preparation through long-horizon inference. Training across heterogeneous data sources and video backbones is challenging: datasets differ in temporal scale, camera geometry, visual quality, motion, and captioning styles, while video generators use distinct representations and architectures. Naive data mixing and model-specific implementations therefore produce inconsistent supervision and make results difficult to reproduce and compare. SolarWM addresses this coupling with a reconfigurable multi-source data engine and a backbone-native adaptation framework. The engine converts 1.43 million canonical clips from 10 datasets into a unified, frame-aligned contract covering visual observations, metric camera geometry, captions, quality metadata, selection decisions, and provenance, while decoupling source processing from mixture construction. Under shared camera-conditioning, training, and inference interfaces, we instantiate four 5B--33B models based on Wan2.2, LTX-2.5, and MiniMax-H3 while preserving their native representations and objectives. A unified three-stage recipe combines bidirectional adaptation, teacher-forced autoregressive initialization, and distribution matching distillation. The resulting causal models enable real-time interaction over rollouts ranging from minutes to hours after being trained on only 5s sequences. By releasing the resulting data, pipeline, recipes, weights, and framework, SolarWM provides a reproducible and extensible foundation for interactive world-model research.| Year | Title | ArXiv Time | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2026 | SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models | 2 Sept 2026 | Link | Link | Link |
ArXiv Papers References
%axiv papers

@misc{huang2026solarwmopendatascalable,
      title={SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models},
      author={Junchao Huang and Guian Fang and Shengju Qian and Xianghao Kong and Zhuoran Zhao and Wei Huang and Yihua Du and Zixin Zhang and Justin Cui and Yuchao Gu and Yukang Chen and Xinting Hu and Tianyu He and Shaoshuai Shi and Zhuotao Tian and Xin Wang and Mike Zheng Shou and Li Jiang},
      year={2026},
      eprint={2609.02886},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.02886},
}
Video Other Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 T2V Papers, including 16 accepted papers and 11 arXiv papers.
Year 2024
For more details, please check the 2024 T2V Papers, including 25 accepted papers and 3 arXiv papers.
- OSS video generation models: Mochi 1 preview is an open state-of-the-art video generation model with high-fidelity motion and strong prompt adherence.
- Survey: The Dawn of Video Generation: Preliminary Explorations with SORA-like Models, arXiv, Project Page, GitHub Repo
3D Scene Subsection
🎉 3D Scene Accepted Papers
| Year | Title | Venue | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2025 | PanoDreamer: Optimization-Based Single Image to 360 3D Scene With Diffusion | SIGGRAPH Asia 2025 | Link | Link | Link |
Accepted Papers References
%accepted papers

@inproceedings{paliwal2025panodreamer,
  title={PanoDreamer: Optimization-Based Single Image to 360 3D Scene With Diffusion},
  author={Paliwal, Avinash and Zhou, Xilong and Tsarov, Andrii and Kalantari, Nima},
  booktitle={Proceedings of the SIGGRAPH Asia 2025 Conference Papers},
  pages={1--10},
  year={2025}
}
Scene Other Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 3D Scene Papers, including 15 accepted papers, 10 arXiv papers and 2 arXiv surveys.
Year 2023-2024
For more details, please check the 2023-2024 3D Scene Papers, including 25 accepted papers and 6 arXiv papers.
Awesome Repos
Awesome Repos
- Resource1: WorldGen: Generate Any 3D Scene in Seconds
- Resource2: RTFM: A Real-Time Frame Model Blog Demo Try-on
Human Motion Subsection
Motion Other Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 Human Motion Papers, including 18 accepted papers and 4 arXiv papers.
Year 2023-2024
For more details, please check the 2023-2024 Text to Human Motion Papers, including 37 accepted papers and 5 arXiv papers.
Datasets
| Motion | Info | URL | Others |
|---|---|---|---|
| AIST | AIST Dance Motion Dataset | Link | -- |
| AIST++ | AIST++ Dance Motion Dataset | Link | dance video database with SMPL annotations |
| AMASS | optical marker-based motion capture datasets | Link | -- |
Additional Info
AMASS
AMASS is a large database of human motion unifying different optical marker-based motion capture datasets by representing them within a common framework and parameterization. AMASS is readily useful for animation, visualization, and generating training data for deep learning.
Awesome Repos
Survey
3D Human Subsection
3D Human Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 3D Human Papers, including 12 accepted papers and 1 arXiv papers.
Year 2023-2024
For more details, please check the 2023-2024 3D Human Papers, including 22 accepted papers and 1 arXiv papers.
Pretrained Models
| Pretrained Models (human body) | Info | URL |
|---|---|---|
| SMPL | smpl model (smpl weights) | Link |
| SMPL-X | smpl model (smpl weights) | Link |
| human_body_prior | vposer model (smpl weights) | Link |
SMPL
SMPL is an easy-to-use, realistic, model of the of the human body that is useful for animation and computer vision.
- version 1.0.0 for Python 2.7 (female/male, 10 shape PCs)
- version 1.1.0 for Python 2.7 (female/male/neutral, 300 shape PCs)
- UV map in OBJ format
SMPL-X
SMPL-X, that extends SMPL with fully articulated hands and facial expressions (55 joints, 10475 vertices)
🎯Back to Top - Text2X Resources
Related Resources
Text to 'other tasks'
Here, other tasks refer to CAD, 3D modeling, music generation, and so on.
Text to CAD
- [arXiv 7 Nov 2024] CAD-MLLM: Unifying Multimodality-Conditioned CAD Generation With MLLM [Paper] [GitHub] [Project Page]
- [NeurIPS 2024 Spotlight] Text2CAD: Generating Sequential CAD Designs from Beginner-to-Expert Level Text Prompts [Paper] [GitHub] [Project Page] [Dataset]
- [CVPR 2025] CAD-Llama: Leveraging Large Language Models for Computer-Aided Design Parametric 3D Model Generation [Paper]
Text to Music
- [arXiv 1 Sep 2024] FLUX that Plays Music [Paper] [GitHub]
- [International Society for Music Information Retrieval(ISMIR) 2025] Video-Guided Text-to-Music Generation Using Public Domain Movie Collections [Paper] [Code] [Project Page]
Text to Model
- [ICLR Workshop on Neural Network Weights as a New Data Modality 2025] Text-to-Model: Text-Conditioned Neural Network Diffusion for Train-Once-for-All Personalization [Paper]
Survey and Awesome Repos
🔥 Topic 1: 3D Gaussian Splatting
Survey
- [arXiv 6 May 2024] Gaussian Splatting: 3D Reconstruction and Novel View Synthesis, a Review [Paper]
- [arXiv 17 Mar 2024] Recent Advances in 3D Gaussian Splatting [Paper]
- [IEEE TVCG 2024] 3D Gaussian as a New Vision Era: A Survey [Paper]
- [arXiv 8 Jan 2024] A Survey on 3D Gaussian Splatting [Paper] [GitHub] [Benchmark]
Awesome Repos
- Resource1: Awesome 3D Gaussian Splatting Resources
- Resource2: 3D Gaussian Splatting Papers
- Resource3: 3DGS and Beyond Docs
🔥 Topic 2: AIGC 3D
Survey
- [arXiv 15 May 2024] A Survey On Text-to-3D Contents Generation In The Wild [Paper]
- [arXiv 2 Feb 2024] A Comprehensive Survey on 3D Content Generation [Paper] [GitHub]
- [arXiv 31 Jan 2024] Advances in 3D Generation: A Survey [Paper]
Awesome Repos
- Resource1: Awesome 3D AIGC Resources
- Resource2: Awesome-Text/Image-to-3D
- Resource3: Awesome Text-to-3D
Benchmark
- [CVPR 2024] GPT-4V(ision) is a Human-Aligned Evaluator for Text-to-3D Generation [Paper] [GitHub] [Project Page]
Foundation Model
🔥 Topic 3: 3D Human & LLM 3D
Survey
- [arXiv 6 June 2024] A Survey on 3D Human Avatar Modeling -- From Reconstruction to Generation [Paper]
- [arXiv 5 Jan 2024] Progress and Prospects in 3D Generative AI: A Technical Overview including 3D human [Paper]
Awesome Repos
- Resource1: Awesome LLM 3D
- Resource2: Awesome Digital Human
- Resource3: Awesome-Avatars
🔥 Topic 5: Physics-based AIGC
Survey
Dynamic Gaussian Splatting
Neural Deformable 3D Gaussians
- [CVPR 2024] Deformable 3D Gaussians for High-Fidelity Monocular Dynamic Scene Reconstruction [Paper] [GitHub] [Project Page]
- [CVPR 2024] 4D Gaussian Splatting for Real-Time Dynamic Scene Rendering [Paper] [GitHub] [Project Page]
- [CVPR 2024] SC-GS: Sparse-Controlled Gaussian Splatting for Editable Dynamic Scenes [Paper] [GitHub] [Project Page]
- [CVPR 2024 Highlight] 3DGStream: On-the-Fly Training of 3D Gaussians for Efficient Streaming of Photo-Realistic Free-Viewpoint Videos [Paper] [GitHub] [Project Page]
4D Gaussians
- [SIGGRAPH 2024] 4D-Rotor Gaussian Splatting: Towards Efficient Novel View Synthesis for Dynamic Scenes [Paper]
- [ICLR 2024] Real-time Photorealistic Dynamic Scene Representation and Rendering with 4D Gaussian Splatting [Paper] [GitHub] [Project Page]
Dynamic 3D Gaussians
- [CVPR 2024 Highlight] Gaussian-Flow: 4D Reconstruction with Dynamic 3D Gaussian Particle [Paper] [GitHub] [Project Page]
- [3DV 2024] Dynamic 3D Gaussians: Tracking by Persistent Dynamic View Synthesis [Paper] [GitHub] [Project Page]
🎯Back to Top - Table of Contents
License
This repo is released under the MIT license.
✉️ Any additions or suggestions, feel free to contact us.
Contributors


Similar repos


[IEEE TPAMI 2026] Simulating the Real World: Survey & Resources, which contains our survey "Simulating the Real World: A Unified Survey of Multimodal Generative Models" (IEEE TPAMI, 2026) and Awesome-Text2X-Resources. Watch this repository for the latest updates! 🔥
See the codeREADME
Simulating the Real World: Survey & Resources
This repository is divided into two main sections:
Our Survey Paper Collection - This section presents our survey, "Simulating the Real World: A Unified Survey of Multimodal Generative Models" (IEEE TPAMI, 2026), which systematically unify the study of 2D, video, 3D and 4D generation within a single framework.
Text2X Resources – This section continues the original Awesome-Text2X-Resources, an open collection of state-of-the-art (SOTA) and novel Text-to-X (X can be everything) methods, including papers, codes, and datasets. The goal is to track the rapid progress in this field and provide researchers with up-to-date references.
⭐ If you find this repository useful for your research or work, a star is highly appreciated!
💗 This repository is continuously updated. If you find relevant papers, blog posts, videos, or other resources that should be included, feel free to submit a pull request (PR) or open an issue. Community contributions are always welcome!
🔔 News
- 🎉 [25 Apr 2026] Our survey is accepted by IEEE TPAMI 2026!
- ✨ [16 Feb 2026] Updated our survey (Version 3, 25 pages) on arXiv.
- ✨ [13 Aug 2025] Updated our survey (Version 2, 25 pages) on arXiv.
- ✨ [6 Mar 2025] Updated our survey (Version 1) on arXiv.
Table of Contents
- Our Survey Paper Collection
- Text2X Resources
📜 Our Survey Paper Collection
𝐒𝐢𝐦𝐮𝐥𝐚𝐭𝐢𝐧𝐠 𝐭𝐡𝐞 𝐑𝐞𝐚𝐥 𝐖𝐨𝐫𝐥𝐝: 𝐀 𝐔𝐧𝐢𝐟𝐢𝐞𝐝 𝐒𝐮𝐫𝐯𝐞𝐲 𝐨𝐟 𝐌𝐮𝐥𝐭𝐢𝐦𝐨𝐝𝐚𝐥 𝐆𝐞𝐧𝐞𝐫𝐚𝐭𝐢𝐯𝐞 𝐌𝐨𝐝𝐞𝐥𝐬
𝑰𝑬𝑬𝑬 𝑻𝑷𝑨𝑴𝑰, 𝟐𝟎𝟐𝟔
Abstract
Understanding and replicating the real world is a critical challenge in Artificial General Intelligence (AGI) research. To achieve this, many existing approaches, such as world models, aim to capture the fundamental principles governing the physical world, enabling more accurate simulations and meaningful interactions. However, current methods often treat different modalities, including 2D (images), videos, 3D, and 4D representations, as independent domains, overlooking their interdependencies. Additionally, these methods typically focus on isolated dimensions of reality without systematically integrating their connections. In this survey, we present a unified survey for multimodal generative models that investigate the progression of data dimensionality in real-world simulation. Specifically, this survey starts from 2D generation (appearance), then moves to video (appearance+dynamics) and 3D generation (appearance+geometry), and finally culminates in 4D generation that integrate all dimensions. To the best of our knowledge, this is the first attempt to systematically unify the study of 2D, video, 3D and 4D generation within a single framework. To guide future research, we provide a comprehensive review of datasets, evaluation metrics and future directions, and fostering insights for newcomers. This survey serves as a bridge to advance the study of multimodal generative models and real-world simulation within a unified framework.
⭐ Citation
If you find this paper and repo helpful for your research, please cite it below:
@article{hu2026simulating,
  title={Simulating the real world: A unified survey of multimodal generative models},
  author={Hu, Yuqi and Wang, Longguang and Liu, Xian and Chen, Ling-Hao and Guo, Yuwei and Shi, Yukai and Liu, Ce and Rao, Anyi and Wang, Zeyu and Xiong, Hui},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  year={2026},
  publisher={IEEE}
}
🧭 Getting Started with Key Concepts
[!Note] If you are new to this field, you can find clear and concise definitions of essential technical terms and concepts, such as NeRF, 3DGS, SDS, and Diffusion Models in our Glossary.
[!TIP] Feel free to pull requests or contact us if you find any related papers that are not included here. The process to submit a pull request is as follows:
- a. Fork the project into your own repository.
- b. Add the Title, Paper link, Conference, Project/GitHub link in
README.mdusing the following format:
[Origin] **Paper Title** [[Paper](Paper Link)] [[GitHub](GitHub Link)] [[Project Page](Project Page Link)]
- c. Submit the pull request to this branch.
The Dimensional Evolution of Generative AI
We present a unified framework connecting 2D, Video, 3D, and 4D generation through text-guided synthesis. This paradigm illustrates how higher-dimensional content is synthesized by extending foundational modalities along spatial and temporal axes. (1)2D->3D: Spatial lifting of 2D priors to achieve geometric consistency; (2)2D->Video: Temporal inflation of static features to capture motion dynamics; (3)Video->4D: Spatial reconstruction and stabilization of dynamic sequences; (4)3D->4D: Temporal animation and deformation of static geometry. This perspective underscores that higher-dimensional generation methodologies are derivatives of foundational lower-dimensional generative priors, adapted through specialized architectural extensions.
Paradigms
2D Generation
Text-to-Image Generation.
Here are some seminal papers and models.
- Imagen: [NeurIPS 2022] Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding [Paper] [Project Page]
- DALL-E: [ICML 2021] Zero-shot text-to-image generation [Paper] [GitHub]
- DALL-E 2: [arXiv 2022] Hierarchical Text-Conditional Image Generation with CLIP Latents [Paper]
- DALL-E 3: [Platform Link]
- DeepFloyd IF: [GitHub]
- Stable Diffusion: [CVPR 2022] High-Resolution Image Synthesis with Latent Diffusion Models [Paper] [GitHub]
- SDXL: [ICLR 2024 spotlight] SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis [Paper] [GitHub]
- FLUX.1: [Platform Link]
Video Generation
Overview of text-to-video generation technologies categorized by three main approaches.
Text-to-video generation models adapt text-to-image frameworks to handle the additional dimension of dynamics in the real world. We classify these models into three categories based on different generative machine learning architectures.
Survey
- [AIRC 2023] A Survey of AI Text-to-Image and AI Text-to-Video Generators [Paper]
- [arXiv 2024] Sora as an AGI World Model? A Complete Survey on Text-to-Video Generation [Paper]
Video Algorithms
(1) VAE- and GAN-based Approaches.
VAE-based Approaches.
- SV2P: [ICLR 2018 Poster] Stochastic Variational Video Prediction [Paper] [Project Page]
- [arXiv 2021] VideoGPT: Video Generation using VQ-VAE and Transformers [Paper] [GitHub] [Project Page]
- [arXiv 2021] FitVid: Overfitting in Pixel-Level Video Prediction [Paper] [GitHub] [Project Page]
GAN-based Approaches.
- [CVPR 2018] MoCoGAN: Decomposing Motion and Content for Video Generation [Paper] [GitHub]
- [CVPR 2022] StyleGAN-V: A Continuous Video Generator with the Price, Image Quality and Perks of StyleGAN2 [Paper] [GitHub] [Project Page]
- DIGAN: [ICLR 2022] Generating Videos with Dynamics-aware Implicit Generative Adversarial Networks [Paper] [GitHub] [Project Page]
- [ICCV 2023] StyleInV: A Temporal Style Modulated Inversion Network for Unconditional Video Generation [Paper] [GitHub] [Project Page]
(2) Diffusion-based Approaches.
U-Net-based Architectures.
- [NeurIPS 2022] Video Diffusion Models [Paper] [Project Page]
- [arXiv 2025] UniVerse-1: Unified Audio-Video Generation via Stitching of Experts [Paper] [GitHub] [Project Page]
- [arXiv 2022] Imagen Video: High Definition Video Generation with Diffusion Models [Paper] [Project Page]
- [arXiv 2022] MagicVideo: Efficient Video Generation With Latent Diffusion Models [Paper] [Project Page]
- [ICLR 2023 Poster] Make-A-Video: Text-to-Video Generation without Text-Video Data [Paper] [Project Page]
- GEN-1: [ICCV 2023] Structure and Content-Guided Video Synthesis with Diffusion Models [Paper] [Project Page]
- PYoCo: [ICCV 2023] Preserve Your Own Correlation: A Noise Prior for Video Diffusion Models [Paper] [Project Page]
- [CVPR 2023] Align your Latents: High-Resolution Video Synthesis with Latent Diffusion Models [Paper] [Project Page]
- [IJCV 2024] Show-1: Marrying Pixel and Latent Diffusion Models for Text-to-Video Generation [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] VideoComposer: Compositional Video Synthesis with Motion Controllability [Paper] [GitHub] [Project Page]
- [ICLR 2024 Spotlight] AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning [Paper] [GitHub] [Project Page]
- [CVPR 2024] Make Pixels Dance: High-Dynamic Video Generation [Paper] [Project Page]
- [ECCV 2024] Emu Video: Factorizing Text-to-Video Generation by Explicit Image Conditioning [Paper] [Project Page]
- [SIGGRAPH Asia 2024] Lumiere: A Space-Time Diffusion Model for Video Generation [Paper] [Project Page]
Transformer-based Architectures.
- [ICLR 2024 Poster] VDT: General-purpose Video Diffusion Transformers via Mask Modeling [Paper] [GitHub] [Project Page]
- W.A.L.T: [ECCV 2024] Photorealistic Video Generation with Diffusion Models [Paper] [Project Page]
- [CVPR 2024] Snap Video: Scaled Spatiotemporal Transformers for Text-to-Video Synthesis [Paper] [Project Page]
- [CVPR 2024] GenTron: Diffusion Transformers for Image and Video Generation [Paper] [Project Page]
- [Seminal Work 2024] Sora: Video generation models as world simulators, OpenAI Blog, vol. 1, no. 8, p. 1, 2024. [Project Page]
- [ICLR 2025 Poster] CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer [Paper] [GitHub]
- [ICLR 2025 Spotlight] Lumina-T2X: Transforming Text into Any Modality, Resolution, and Duration via Flow-based Large Diffusion Transformers [Paper] [GitHub]
(3) Autoregressive-based Approaches.
- VQ-GAN: [CVPR 2021 Oral] Taming Transformers for High-Resolution Image Synthesis [Paper] [GitHub]
- [NeurIPS 2021] Cogview: Mastering text-to-image generation via transformers [[Paper][https://arxiv.org/abs/2105.13290]]
- [CVPR 2023 Highlight] MAGVIT: Masked Generative Video Transformer [Paper] [GitHub] [Project Page]
- [ICLR 2023 Poster] CogVideo: Large-scale Pretraining for Text-to-Video Generation via Transformers [Paper] [GitHub]
- [ICML 2024] VideoPoet: A Large Language Model for Zero-Shot Video Generation [Paper] [Project Page]
- [ICLR 2024 Poster] Language Model Beats Diffusion - Tokenizer is key to visual generation [Paper]
- [arXiv 2024] Open-MAGVIT2: An Open-Source Project Toward Democratizing Auto-regressive Visual Generation [Paper] [GitHub]
- [arXiv 2024] Emu3: Next-Token Prediction is All You Need [Paper] [GitHub] [Project Page]
- [ICLR 2025 Poster] Accelerating Auto-regressive Text-to-Image Generation with Training-free Speculative Jacobi Decoding [Paper] [GitHub]
- [arXiv 2025] Cosmos World Foundation Model Platform for Physical AI [Paper] [GitHub]
Video Applications
Video Editing.
- [ICCV 2023] Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation [Paper] [GitHub] [Project Page]
- [ICCV 2023] Pix2Video: Video Editing using Image Diffusion [Paper] [GitHub] [Project Page]
- [NeurIPS 2023] Towards consistent video editing with text-to-image diffusion models [[Paper][https://arxiv.org/abs/2305.17431]]
- [CVPR 2024] VidToMe: Video Token Merging for Zero-Shot Video Editing [Paper] [GitHub] [Project Page]
- [CVPR 2024] Video-P2P: Video Editing with Cross-attention Control [Paper] [GitHub] [Project Page]
- [CVPR 2024 Highlight] CoDeF: Content Deformation Fields for Temporally Consistent Video Processing [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Towards Consistent Video Editing with Text-to-Image Diffusion Models [Paper]
- [ICLR 2024 Poster] Ground-A-Video: Zero-shot Grounded Video Editing using Text-to-image Diffusion Models [Paper] [GitHub] [Project Page]
- [arXiv 2024] UniEdit: A Unified Tuning-Free Framework for Video Motion and Appearance Editing [Paper] [GitHub] [Project Page]
- [TMLR 2024] AnyV2V: A Tuning-Free Framework For Any Video-to-Video Editing Tasks [Paper] [GitHub] [Project Page]
Novel View Synthesis.
- [TPAMI 2025] ViewCrafter: Taming Video Diffusion Models for High-fidelity Novel View Synthesis [Paper] [GitHub] [Project Page]
- [CVPR 2024 Highlight] ViVid-1-to-3: Novel View Synthesis with Video Diffusion Models [Paper] [GitHub] [Project Page]
- [ICLR 2025 Poster] CameraCtrl: Enabling Camera Control for Video Diffusion Models [Paper] [GitHub] [Project Page]
- [ICLR 2025 Poster] NVS-Solver: Video Diffusion Model as Zero-Shot Novel View Synthesizer [Paper] [GitHub]
Human Animation in Videos.
- [CVPR 2018] MoCoGAN: Decomposing Motion and Content for Video Generation [Paper] [GitHub]]
- [ICCV 2019] Everybody Dance Now [Paper] [GitHub] [Project Page]
- [ICCV 2019] Liquid Warping GAN: A Unified Framework for Human Motion Imitation, Appearance Transfer and Novel View Synthesis [Paper] [GitHub] [Project Page] [Dataset]
- [NeurIPS 2019] First Order Motion Model for Image Animation [Paper] [GitHub] [Project Page]
- [ICCV 2023] Adding Conditional Control to Text-to-Image Diffusion Models [Paper] [GitHub]
- [ICCV 2023] HumanSD: A Native Skeleton-Guided Diffusion Model for Human Image Generation [Paper] [GitHub] [Project Page]
- [CVPR 2023] Learning Locally Editable Virtual Humans [Paper] [GitHub] [Project Page] [Dataset]
- [CVPR 2023] Animate Anyone: Consistent and Controllable Image-to-Video Synthesis for Character Animation [Paper] [GitHub] [Project Page]
- [CVPRW 2024] LatentMan: Generating Consistent Animated Characters using Image Diffusion Models [Paper] [GitHub] [Project Page]
- [IJCAI 2024] Zero-shot High-fidelity and Pose-controllable Character Animation [Paper]
- [SCIS-2025] UniAnimate: Taming Unified Video Diffusion Models for Consistent Human Image Animation [Paper] [GitHub] [Project Page]
- [CVPR 2025] MIMO: Controllable Character Video Synthesis with Spatial Decomposed Modeling [Paper] [GitHub] [Project Page]
3D Generation
Recent text-to-3D, image-to-3D and video-to-3D generation methods.
3D Algorithms
Text-to-3D Generation.
Survey
- [arXiv 2023] Generative AI meets 3D: A Survey on Text-to-3D in AIGC Era [Paper]
- [arXiv 2024] Advances in 3D Generation: A Survey [Paper]
- [arXiv 2024] A Survey On Text-to-3D Contents Generation In The Wild [Paper]
Feedforward Approaches.
- [arXiv 2022] 3D-LDM: Neural Implicit 3D Shape Generation with Latent Diffusion Models [Paper] [GitHub]
- [arXiv 2022] Point-E: A System for Generating 3D Point Clouds from Complex Prompts [Paper] [GitHub]
- [arXiv 2023] Shap-E: Generating Conditional 3D Implicit Functions [Paper] [GitHub]
- [NeurIPS 2023] Michelangelo: Conditional 3d shape generation based on shape-image-text aligned latent representation [Paper] [GitHub] [Project Page]
- [ICCV 2023] ATT3D: Amortized Text-to-3D Object Synthesis [Paper] [Project Page]
- [ICLR 2023 Spotlight] MeshDiffusion: Score-based Generative 3D Mesh Modeling [Paper] [GitHub] [Project Page]
- [CVPR 2023] Diffusion-SDF: Text-to-Shape via Voxelized Diffusion [Paper] [GitHub] [Project Page]
- [ICML 2024] HyperFields:Towards Zero-Shot Generation of NeRFs from Text [Paper] [GitHub] [Project Page]
- [ECCV 2024] LATTE3D: Large-scale Amortized Text-To-Enhanced3D Synthesis [Paper] [Project Page]
- [arXiv 2024] AToM: Amortized Text-to-Mesh using 2D Diffusion [Paper] [GitHub] [Project Page]
Optimization-based Approaches.
- [ICLR 2023 notable top 5%] DreamFusion: Text-to-3D using 2D Diffusion [Paper] [Project Page]
- [CVPR 2023 Highlight] Magic3D: High-Resolution Text-to-3D Content Creation [Paper] [Project Page]
- [CVPR 2023] Dream3D: Zero-Shot Text-to-3D Synthesis Using 3D Shape Prior and Text-to-Image Diffusion Models [Paper] [Project Page]
- [ICCV 2023] Fantasia3D: Disentangling Geometry and Appearance for High-quality Text-to-3D Content Creation [Paper] [GitHub] [Project Page]
- [NeurIPS 2023 Spotlight] ProlificDreamer: High-Fidelity and Diverse Text-to-3D Generation with Variational Score Distillation [Paper] [GitHub] [Project Page]
- [ICLR 2024 Poster] MVDream: Multi-view Diffusion for 3D Generation [Paper] [GitHub] [Project Page]
- [ICLR 2024 Oral] DreamGaussian: Generative Gaussian Splatting for Efficient 3D Content Creation [Paper] [GitHub] [Project Page]
- [CVPR 2024] PI3D: Efficient Text-to-3D Generation with Pseudo-Image Diffusion [Paper]
- [CVPR 2024] VP3D: Unleashing 2D Visual Prompt for Text-to-3D Generation [Paper] [Project Page]
- [CVPR 2024] GSGEN: Text-to-3D using Gaussian Splatting [Paper] [GitHub] [Project Page]
- [CVPR 2024] GaussianDreamer: Fast Generation from Text to 3D Gaussians by Bridging 2D and 3D Diffusion Models [Paper] [GitHub] [Project Page]
- [CVPR 2024] Sculpt3D: Multi-View Consistent Text-to-3D Generation with Sparse 3D Prior [Paper] [GitHub] [Project Page]
MVS-based Approaches.
- [ICLR 2024 Poster] Instant3D: Fast Text-to-3D with Sparse-view Generation and Large Reconstruction Model [Paper] [Project Page]
- [CVPR 2024] Direct2.5: Diverse Text-to-3D Generation via Multi-view 2.5D Diffusion [Paper] [GitHub] [Project Page]
- [CVPR 2024] Sherpa3D: Boosting High-Fidelity Text-to-3D Generation via Coarse 3D Prior [Paper] [GitHub] [Project Page]
Image-to-3D Generation.
Feedforward Approaches.
- [arXiv 2023] 3DGen: Triplane Latent Diffusion for Textured Mesh Generation [Paper]
- [NeurIPS 2023] Michelangelo: Conditional 3d shape generation based on shape-image-text aligned latent representation [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Direct3D: Scalable Image-to-3D Generation via 3D Latent Diffusion Transformer [Paper] [GitHub] [Project Page]
- [SIGGRAPH 2024 Best Paper Honorable Mention] CLAY: A Controllable Large-scale Generative Model for Creating High-quality 3D Assets [Paper] [GitHub] [Project Page]
- [arXiv 2024] CraftsMan: High-fidelity Mesh Generation with 3D Native Generation and Interactive Geometry Refiner [Paper] [GitHub] [Project Page]
- [CVPR 2025] Structured 3D Latents for Scalable and Versatile 3D Generation [Paper] [GitHub] [Project Page]
Optimization-based Approaches.
- [arXiv 2023] Consistent123: Improve Consistency for One Image to 3D Object Synthesis [Paper] [Project Page]
- [arXiv 2023] ImageDream: Image-Prompt Multi-view Diffusion for 3D Generation [Paper] [GitHub] [Project Page]
- [CVPR 2023] RealFusion: 360° Reconstruction of Any Object from a Single Image [Paper] [GitHub] [Project Page]
- [ICCV 2023] Zero-1-to-3: Zero-shot One Image to 3D Object [Paper] [GitHub] [Project Page]
- [ICLR 2024 Poster] Magic123: One Image to High-Quality 3D Object Generation Using Both 2D and 3D Diffusion Priors [Paper] [GitHub] [Project Page]
- [ICLR 2024 Poster] TOSS: High-quality Text-guided Novel View Synthesis from a Single Image [Paper] [GitHub] [Project Page]
- [ICLR 2024 Spotlight] SyncDreamer: Generating Multiview-consistent Images from a Single-view Image [Paper] [GitHub] [Project Page]
- [CVPR 2024] Wonder3D: Single Image to 3D using Cross-Domain Diffusion [Paper] [GitHub] [Project Page]
- [ICLR 2025] IPDreamer: Appearance-Controllable 3D Object Generation with Complex Image Prompts [Paper] [GitHub]
MVS-based Approaches.
- [NeurIPS 2023] One-2-3-45: Any Single Image to 3D Mesh in 45 Seconds without Per-Shape Optimization [Paper] [GitHub] [Project Page]
- [ECCV 2024] CRM: Single Image to 3D Textured Mesh with Convolutional Reconstruction Model [Paper] [GitHub] [Project Page]
- [arXiv 2024] InstantMesh: Efficient 3D Mesh Generation from a Single Image with Sparse-view Large Reconstruction Models [Paper] [GitHub]
- [ICLR 2024 Oral] LRM: Large Reconstruction Model for Single Image to 3D [Paper] [Project Page]
- [NeurIPS 2024] Unique3D: High-Quality and Efficient 3D Mesh Generation from a Single Image [Paper] [GitHub] [Project Page]
Video-to-3D Generation.
- [CVPR 2024 Highlight] ViVid-1-to-3: Novel View Synthesis with Video Diffusion Models [Paper] [GitHub] [Project Page]
- [ICML 2024] IM-3D: Iterative Multiview Diffusion and Reconstruction for High-Quality 3D Generation [Paper] [Project Page]
- [TPAMI 2025] V3D: Video Diffusion Models are Effective 3D Generators [Paper] [GitHub] [Project Page]
- [ECCV 2024 Oral] SV3D: Novel Multi-view Synthesis and 3D Generation from a Single Image Using Latent Video Diffusion [Paper] [Project Page]
- [NeurIPS 2024 Oral] CAT3D: Create Anything in 3D with Multi-View Diffusion Models [Paper] [Project Page]
3D Applications
Avatar Generation.
- [CVPR 2023] Zero-Shot Text-to-Parameter Translation for Game Character Auto-Creation [Paper]
- [SIGGRAPH 2023] DreamFace: Progressive Generation of Animatable 3D Faces under Text Guidance [Paper] [Project Page]
- [NeurIPS 2023] Headsculpt: Crafting 3d head avatars with text [Paper] [GitHub] [Project Page]
- [NeurIPS 2023] DreamWaltz: Make a Scene with Complex 3D Animatable Avatars [Paper] [GitHub] [Project Page]
- [NeurIPS 2023 Spotlight] DreamHuman: Animatable 3D Avatars from Text [Paper] [Project Page]
Scene Generation.
- [ACM MM 2023] RoomDreamer: Text-Driven 3D Indoor Scene Synthesis with Coherent Geometry and Texture [Paper]
- [TVCG 2024] Text2NeRF: Text-Driven 3D Scene Generation with Neural Radiance Fields [Paper] [GitHub] [Project Page]
- [ECCV 2024] DreamScene: 3D Gaussian-based Text-to-3D Scene Generation via Formation Pattern Sampling [Paper] [GitHub] [Project Page]
- [ECCV 2024] DreamScene360: Unconstrained Text-to-3D Scene Generation with Panoramic Gaussian Splatting [Paper] [GitHub] [Project Page]
- [arXiv 2024] Urban Architect: Steerable 3D Urban Scene Generation with Layout Prior [Paper] [GitHub] [Project Page]
- [arXiv 2024] CityCraft: A Real Crafter for 3D City Generation [Paper] [GitHub]
3D Editing.
- [ECCV 2022] Unified Implicit Neural Stylization [Paper] [GitHub] [Project Page]
- [ECCV 2022] ARF: Artistic Radiance Fields [Paper] [GitHub] [Project Page]
- [SIGGRAPH Asia 2022] FDNeRF: Few-shot Dynamic Neural Radiance Fields for Face Reconstruction and Expression Editing [Paper] [GitHub] [Project Page]
- [CVPR 2022] FENeRF: Face Editing in Neural Radiance Fields [Paper] [GitHub] [Project Page]
- [SIGGRAPH 2023] TextDeformer: Geometry Manipulation using Text Guidance [Paper] [GitHub] [Project Page]
- [ICCV 2023] ObjectSDF++: Improved Object-Compositional Neural Implicit Surfaces [Paper] [GitHub] [Project Page]
- [ICCV 2023 Oral] Instruct-NeRF2NeRF: Editing 3D Scenes with Instructions [Paper] [GitHub] [Project Page]
4D Generation
Representative works of 4D generation methods. ''Rep'' stands for representations.
4D Algorithms
Feedforward Approaches.
- [CVPR 2024] Control4D: Efficient 4D Portrait Editing with Text [Paper] [Project Page]
- [NeurIPS 2024] Animate3D: Animating Any 3D Model with Multi-view Video Diffusion [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Vidu4D: Single Generated Video to High-Fidelity 4D Reconstruction with Dynamic Gaussian Surfels [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models [Paper] [GitHub] [Project Page] [Dataset]
- [NeurIPS 2024] L4GM: Large 4D Gaussian Reconstruction Model [Paper] [GitHub] [Project Page]
Optimization-based Approaches.
- [ICML 2023] Text-To-4D Dynamic Scene Generation [Paper] [Project Page]
- [CVPR 2024] 4D-fy: Text-to-4D Generation Using Hybrid Score Distillation Sampling [Paper] [GitHub] [Project Page]
- [CVPR 2024] A Unified Approach for Text- and Image-guided 4D Scene Generation [Paper] [GitHub] [Project Page]
- [CVPR 2024] Align Your Gaussians: Text-to-4D with Dynamic 3D Gaussians and Composed Diffusion Models [Paper] [Project Page]
- [ECCV 2024] TC4D: Trajectory-Conditioned Text-to-4D Generation [Paper] [GitHub] [Project Page]
- [ECCV 2024] SC4D: Sparse-Controlled Video-to-4D Generation and Motion Transfer [Paper] [GitHub] [Project Page]
- [ECCV 2024] STAG4D: Spatial-Temporal Anchored Generative 4D Gaussians [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] 4Real: Towards Photorealistic 4D Scene Generation via Video Diffusion Models [Paper] [Project Page]
- [NeurIPS 2024] Compositional 3D-aware Video Generation with LLM Director [Paper] [Project Page]
- [NeurIPS 2024] DreamScene4D: Dynamic Multi-Object Scene Generation from Monocular Videos [Paper] [GitHub] [Project Page]
- [NeurIPS 2024] DreamMesh4D: Video-to-4D Generation with Sparse-Controlled Gaussian-Mesh Hybrid Representation [Paper] [GitHub] [Project Page]
- [arXiv 2024] Trans4D: Realistic Geometry-Aware Transition for Compositional Text-to-4D Synthesis [Paper] [GitHub]
4D Applications
4D Editing.
- [CVPR 2024] Control4D: Efficient 4D Portrait Editing with Text [Paper] [Project Page]
- [CVPR 2024] Instruct 4D-to-4D: Editing 4D Scenes as Pseudo-3D Scenes Using 2D Diffusion [Paper] [GitHub] [Project Page]
Human Animation.
- [SIGGRAPH 2020] Robust Motion In-betweening [Paper]
- [CVPR 2022] Generating Diverse and Natural 3D Human Motions from Text [Paper] [GitHub] [Project Page]
- [SCA 2023] Motion In-Betweening with Phase Manifolds [Paper] [GitHub]
- [CVPR 2023] T2M-GPT: Generating Human Motion from Textual Descriptions with Discrete Representations [Paper] [GitHub] [Project Page]
- [ICLR 2023 notable top 25%] Human Motion Diffusion Model [Paper] [GitHub] [Project Page]
- [NeurIPS 2023] MotionGPT: Human Motion as a Foreign Language [Paper] [GitHub] [Project Page]
- [ICML 2024] HumanTOMATO: Text-aligned Whole-body Motion Generation [Paper] [GitHub] [Project Page]
- [CVPR 2024] MoMask: Generative Masked Modeling of 3D Human Motions [Paper] [GitHub] [Project Page]
- [CVPR 2024] Lodge: A Coarse to Fine Diffusion Network for Long Dance Generation Guided by the Characteristic Dance Primitives [Paper] [GitHub] [Project Page]
Datasets and Evaluations
Datasets
Summary of the widely-used 2D, video, 3D and 4D generation datasets. [Link] directs to dataset websites.
- [arXiv 2026] Sekai2: From World Exploration to Interactive World Modeling [Sekai2 dataset technical report] [Project Page]
Evaluation Metrics
Summary of common evaluation metrics.
Other Related Resources
World Model Benchmark
- [NeurIPS 2026] WorldModelBench: Judging Video Generation Models As World Models [Paper] [GitHub] [Project Page]
- [arXiv 2026] PlayWorld: Benchmarking World Models with Agent Players over Long-Horizon Objectives [Paper] [GitHub] [Project Page]
World Foundation Model Platform
-
Atlas: the world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D, World Labs, Sept 1st, 2026.
-
WorldFoundry([GitHub]): an open-source infrastructure for world models.
-
NVIDIA Cosmos ([GitHub] [Paper]): NVIDIA Cosmos is a world foundation model platform for accelerating the development of physical AI systems.
- Cosmos-Transfer1:a world-to-world transfer model designed to bridge the perceptual divide between simulated and real-world environments.
- Cosmos-Predict1: a collection of general-purpose world foundation models for Physical AI that can be fine-tuned into customized world models for downstream applications.
- Cosmos-Reason1: a model that understands the physical common sense and generate appropriate embodied decisions in natural language through long chain-of-thought reasoning processes.
-
Genie3, Google Deepmind, August 5th, 2025.
🎯Back to Top - Our Survey Paper Collection
🔥 Awesome Text2X Resources
An open collection of state-of-the-art (SOTA), novel Text to X (X can be everything) methods (papers, codes and datasets), intended to keep pace with the anticipated surge of research.
Update Logs
2026.09.04- rename previousT2V SubsectiontoVideo Generation Subsection.2026.01.07- update 2025 papers collection into docs.
2025 Update Logs:
2025.12.03- update several papers accepted by NeurIPS 2025, congrats to all 🎉2025.05.08- update new layout.2025.04.18- update layout on section Related Resources.2025.03.10- CVPR 2025 Accepted Papers🎉2025.02.28- update several papers status "CVPR 2025" to accepted papers, congrats to all 🎉2025.01.23- update several papers status "ICLR 2025" to accepted papers, congrats to all 🎉2025.01.09- update layout.
2024 Update Logs:
2024.12.21adjusted the layouts of several sections and Happy Winter Solstice ⚪🥣.2024.09.26- update several papers status "NeurIPS 2024" to accepted papers, congrats to all 🎉2024.09.03- add one new section 'text to model'.2024.06.30- add one new section 'text to video'.2024.07.02- update several papers status "ECCV 2024" to accepted papers, congrats to all 🎉2024.06.21- add one hot Topic about AIGC 4D Generation on the section of Suvery and Awesome Repos.2024.06.17- an awesome repo for CVPR2024 Link 👍🏻2024.04.05adjusted the layout and added accepted lists and ArXiv lists to each section.2024.04.05- an awesome repo for CVPR2024 on 3DGS and NeRF Link 👍🏻2024.03.25- add one new survey paper of 3D GS into the section of "Survey and Awesome Repos--Topic 1: 3D Gaussian Splatting".2024.03.12- add a new section "Dynamic Gaussian Splatting", including Neural Deformable 3D Gaussians, 4D Gaussians, Dynamic 3D Gaussians.2024.03.11- CVPR 2024 Accpeted Papers Link- update some papers accepted by CVPR 2024! Congratulations🎉
4D Subsection
🎉 4D Accepted Papers
| Year | Title | Venue | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2026 | Geometry-aware 4D Video Generation for Robot Manipulation | ICLR 2026 | Link | Link | Link |
| 2026 | Turbo4DGen: Ultra-Fast Acceleration for 4D Generation | ICML 2026 | Link | Link | Link |
| 2026 | Code2Worlds: Empowering Coding LLMs for 4D World Generation | ICML 2026 | Link | Link | Link |
| 2026 | PerpetualWonder: Long-Horizon Action-Conditioned 4D Scene Generation | CVPR 2026 | Link | Link | Link |
| 2026 | AvatarPointillist: Autoregressive 4D Gaussian Avatarization | CVPR 2026 | Link | Link | Link |
| 2026 | Vista4D: Video Reshooting with 4D Point Clouds | CVPR 2026 | Link | Link | Link |
| 2026 | Motion 3-to-4: 3D Motion Reconstruction for 4D Synthesis | CVPR 2026 | Link | Link | Link |
| 2026 | NeuROK: Generative 4D Neural Object Kinematics | CVPR 2026 | Link | Coming Soon! | Link |
| 2026 | Choreographing a World of Dynamic Objects | CVPR 2026 | Link | Link | Link |
| 2026 | ActionMesh: Animated 3D Mesh Generation with Temporal 3D Diffusion | CVPR 2026 | Link | Link | Link |
| 2026 | MV-Forcing: Long Multi-View Video Generation via 4D-Grounded Spatio-Temporal Self-Forcing | ECCV 2026 | Link | Coming Soon! | Link |
| 2026 | VGGRPO: Towards World-Consistent Video Generation with 4D Latent Reward | ECCV 2026 | Link | -- | Link |
| 2026 | LivingWorld: Interactive 4D World Generation with Environmental Dynamics | ECCV 2026 | Link | Link | Link |
| 2026 | InterPet4D: A Multimodal 4D Human-Pet Interaction Dataset for Pet Motion Generation | ECCV 2026 | Link | Datasets | Link |
| 2026 | MoGe4D: Geometry-Aware Single-Image 4D Synthesis via Dense Trajectory Generation | ECCV 2026 | Link | Link | Link |
| 2026 | Alignment Is All You Need For X-to-4D Generation | IEEE Transactions on Multimedia (TMM) 2026 | Link | -- | Link |
| 2026 | Lift4D: Harmonizing Single-View 3D Estimation for 4D Reconstruction In-the-Wild | SIGGRAPH Asia 2026 | Link | Link | Link |
| 2026 | 4DAnyone: Create Anyone in 4D from a Casual Monocular Video | SIGGRAPH Asia 2026 | Link | Link | Link |
| 2026 | Streaming4D: Accelerate 4D World Models via Block-wise Video Generation and Incremental Reconstruction | CVPR 2026 4DV Workshop | Link | -- | -- |
Accepted Papers References
%accepted papers

@article{liu2025geometry,
  title={Geometry-aware 4D Video Generation for Robot Manipulation},
  author={Liu, Zeyi and Li, Shuang and Cousineau, Eric and Feng, Siyuan and Burchfiel, Benjamin and Song, Shuran},
  journal={arXiv preprint arXiv:2507.01099},
  year={2025}
}

@article{man2026turbo4dgen,
  title={Turbo4DGen: Ultra-Fast Acceleration for 4D Generation},
  author={Man, Yuanbin and Huang, Ying and Ren, Zhile and Yin, Miao},
  journal={arXiv preprint arXiv:2603.29572},
  year={2026}
}

@article{zhang2026code2worlds,
  title={Code2worlds: Empowering coding llms for 4d world generation},
  author={Zhang, Yi and Wang, Yunshuang and Zhang, Zeyu and Tang, Hao},
  journal={arXiv preprint arXiv:2602.11757},
  year={2026}
}

@article{zhan2026perpetualwonder,
  title={PerpetualWonder: Long-Horizon Action-Conditioned 4D Scene Generation},
  author={Zhan, Jiahao and Li, Zizhang and Yu, Hong-Xing and Wu, Jiajun},
  journal={arXiv preprint arXiv:2602.04876},
  year={2026}
}

@inproceedings{liu2026avatarpointillist,
  title     = {AvatarPointillist: Autoregressive 4D Gaussian Avatarization},
  author    = {Hongyu Liu and Xuan Wang and Yating Wang and Zijian Wu and Ziyu Wan and Yue Ma and Runtao Liu and Boyao Zhou and Yujun Shen and Qifeng Chen},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  year      = {2026}
}

@misc{lin2026vista4dvideoreshooting4d,
      title={Vista4D: Video Reshooting with 4D Point Clouds},
      author={Kuan Heng Lin and Zhizheng Liu and Pablo Salamanca and Yash Kant and Ryan Burgert and Yuancheng Xu and Koichi Namekata and Yiwei Zhao and Bolei Zhou and Micah Goldblum and Paul Debevec and Ning Yu},
      year={2026},
      eprint={2604.21915},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2604.21915},
}

@inproceedings{chen2026motion,
  title={Motion 3-to-4: 3d motion reconstruction for 4d synthesis},
  author={Chen, Hongyuan and Chen, Xingyu and Xu, Zexiang and Chen, Anpei},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={28947--28958},
  year={2026}
}

@inproceedings{geng2026neurok,
  title={NeuROK: Generative 4D Neural Object Kinematics},
  author={Geng, Chen and He, Guangzhao and Gao, Yue and Zhang, Yunzhi and Wu, Shangzhe and Wu, Jiajun},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={39239--39251},
  year={2026}
}

@article{lyu2026choreographing,
  title={Choreographing a World of Dynamic Objects},
  author={Lyu, Yanzhe and Geng, Chen and Dharmarajan, Karthik and Zhang, Yunzhi and Alzayer, Hadi and Wu, Shangzhe and Wu, Jiajun},
  journal={arXiv preprint arXiv:2601.04194},
  year={2026}
}

@article{sabathier2026actionmesh,
  title={Actionmesh: Animated 3d mesh generation with temporal 3d diffusion},
  author={Sabathier, Remy and Novotny, David and Mitra, Niloy J and Monnier, Tom},
  journal={arXiv preprint arXiv:2601.16148},
  year={2026}
}

@article{fiebelman2026mv,
  title={MV-Forcing: Long Multi-View Video Generation via 4D-Grounded Spatio-Temporal Self-Forcing},
  author={Fiebelman, Gal and Averbuch-Elor, Hadar and Benaim, Sagie},
  journal={arXiv preprint arXiv:2607.05376},
  year={2026}
}

@article{an2026vggrpo,
  title={Vggrpo: Towards world-consistent video generation with 4d latent reward},
  author={An, Zhaochong and Kupyn, Orest and Uscidda, Th{\'e}o and Colaco, Andrea and Ahuja, Karan and Belongie, Serge and Gonzalez-Franco, Mar and Gazulla, Marta Tintore},
  journal={arXiv preprint arXiv:2603.26599},
  year={2026}
}

@article{mun2026livingworld,
  title={LivingWorld: Interactive 4D World Generation with Environmental Dynamics},
  author={Mun, Hyeongju and Jin, In-Hwan and Kim, Sohyeong and Kong, Kyeongbo},
  journal={arXiv preprint arXiv:2604.01641},
  year={2026}
}

@article{peng2026interpet4d,
  title={InterPet4D: A Multimodal 4D Human-Pet Interaction Dataset for Pet Motion Generation},
  author={Peng, Yichen and Song, Jyun-Ting and Liao, Chen-Chieh and Kitani, Kris and Koike, Hideki and Wu, Erwin},
  journal={arXiv preprint arXiv:2607.10287},
  year={2026}
}

@misc{zhang2026geometryawaresingleimage4dsynthesis,
      title={Geometry-Aware Single-Image 4D Synthesis via Dense Trajectory Generation},
      author={Yanran Zhang and Ziyi Wang and Wenzhao Zheng and Zheng Zhu and Jie Zhou and Jiwen Lu},
      year={2026},
      eprint={2512.05044},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2512.05044},
}

@article{miao2026alignment,
  title={Alignment Is All You Need For X-to-4D Generation},
  author={Miao, Qiaowei and Li, Kehan and Luo, Yawei and Yang, Yi},
  journal={arXiv preprint arXiv:2607.02516},
  year={2026}
}

@article{litman2026lift4d,
  title={Lift4D: Harmonizing Single-View 3D Estimation for 4D Reconstruction In-the-Wild},
  author={Litman, Yehonathan and Ma, Xiaoxuan and Shah, Manan and Ugrinovic, Nicolas and Kitani, Kris and De la Torre, Fernando and Tulsiani, Shubham},
  journal={arXiv preprint arXiv:2606.23688},
  year={2026}
}

@article{jin2026fdanyone,
  title={4DAnyone: Create Anyone in 4D from a Casual Monocular Video},
  author={Jin, Yudong and Xie, Tao and Zhang, Qihang and Shen, Zehong and Xu, Zhen and Shen, Yujun and Bao, Hujun and Zhou, Xiaowei and Xu, Yinghao},
  journal={arXiv preprint arXiv:2608.20335},
  year={2026},
  url={https://arxiv.org/abs/2608.20335}
}

@article{liu2026streaming4d,
  title={Streaming4D: Accelerate 4D World Models via Block-wise Video Generation and Incremental Reconstruction},
  author={Liu, Xiaoyan and Liu, Jiaxin and Li, Kangrui and Zhou, Sifan},
  journal={arXiv preprint arXiv:2609.00610},
  year={2026}
}
💡 4D ArXiv Papers
1. Pixel-to-4D: Camera-Controlled Image-to-Video Generation with Dynamic 3D Gaussians
Melonie de Almeida, Daniela Ivanova, Tong Shi, John H. Williamson, Paul Henderson (University of Glasgow)
Abstract
Humans excel at forecasting the future dynamics of a scene given just a single image. Video generation models that can mimic this ability are an essential component for intelligent systems. Recent approaches have improved temporal coherence and 3D consistency in single-image-conditioned video generation. However, these methods often lack robust user controllability, such as modifying the camera path, limiting their applicability in real-world applications. Most existing camera-controlled image-to-video models struggle with accurately modeling camera motion, maintaining temporal consistency, and preserving geometric integrity. Leveraging explicit intermediate 3D representations offers a promising solution by enabling coherent video generation aligned with a given camera trajectory. Although these methods often use 3D point clouds to render scenes and introduce object motion in a later stage, this two-step process still falls short in achieving full temporal consistency, despite allowing precise control over camera movement. We propose a novel framework that constructs a 3D Gaussian scene representation and samples plausible object motion, given a single image in a single forward pass. This enables fast, camera-guided video generation without the need for iterative denoising to inject object motion into render frames. Extensive experiments on the KITTI, Waymo, RealEstate10K and DL3DV-10K datasets demonstrate that our method achieves state-of-the-art video quality and inference efficiency.2. ST-Gen4D: Embedding 4D Spatiotemporal Cognition into World Model for 4D Generation
Haonan Wang, Hanyu Zhou, Tao Gu, Luxin Yan
(Huazhong University of Science and Technology, National University of Singapore, Macquarie University)
Abstract
Generative models have achieved success in producing apparently coherent 2D videos, but remain challenging in the physical world due to lack of 4D spatiotemporal scale. Typically, existing 4D generative models directly embed macro scale constraints to enhance overall spatiotemporal consistency. However, these methods only ensure global appearance coherence and fail to reveal the local dynamics of the physical world. Our insight is that global appearance structure and local dynamic topology empower 4D spatiotemporal cognition, thereby enabling 4D generation with spatiotemporal regularities. In this work, we propose ST-Gen4D, a 4D generation framework with 4D spatiotemporal cognition-based world model. Our model is guided by four key designs: 1) Spatiotemporal representation. We encode various modalities into multiple representations as a feature basis. 2) Spatiotemporal cognition. We sculpture these representations into global appearance graph and local dynamic graph, and fuse them via semantic-bridged spatiotemporal fusion to obtain a 4D cognition graph. 3) Spatiotemporal reasoning. We utilize a world model to derive future state based on the 4D cognition. 4) Spatiotemporal generation. We leverage the derived cognition as condition to guide latent diffusion for 4D Gaussian generation. By deeply integrating 4D intrinsic cognition with generative priors, our model guarantees the structural rationality and topological consistency of 4D generation. Moreover, we propose ST-4D datasets by aggregating public 4D datasets and self-built subset. Extensive experiments demonstrate the superiority of our ST-Gen4D across 3D and 4D generation tasks.3. Geometric 4D Stitching for Grounded 4D Generation
Sunwoo Park, Taesung Kwon, Jong Chul Ye (KAIST AI)
Abstract
Recent 4D generation methods complete scene-level missing information using generative models and reconstruct the scene into radiance-based representations. However, these pipelines often present geometric inconsistencies in the generated content, and the radiance-based reconstruction requires expensive optimization. Furthermore, radiance-based representations often absorb these geometric inconsistencies into their view-dependent nature, failing to enforce the grounded geometric consistency. To address these issues, we propose Geometric 4D Stitching, an efficient framework that explicitly identifies missing geometric regions and complements them with geometrically grounded 4D stitches. As a result, our method constructs 4D scene representations in under 10 minutes on a single NVIDIA RTX 5090 GPU per one-step scene expansion, while improving geometric consistency. Moreover, we demonstrate that our explicit 4D stitching supports interative expansion of 4D mesh as well as 4D scene editing.4. Fast 4D Mesh Generation by Spatio-Temporal Attention Chains
Dvir Samuel, Yuval Atzmon, Gal Chechik, Yoni Kasten (NVIDIA Research, Bar-Ilan University)
Abstract
4D mesh generation has recently emerged as a powerful paradigm for recovering dynamic 3D structure from videos, but existing methods remain slow, computationally expensive, and difficult to scale to longer sequences. We introduce a training-free approach that accelerates 4D mesh generation while improving temporal correspondence quality. Our key observation is that temporal correspondences emerge inside a 4D backbone long before its generated meshes become visually accurate. We exploit this with a general framework we call Spatio-Temporal Attention Chain which propagates information across space and time. Starting from vertices on an anchor mesh, the chain maps vertices to latent tokens. It then follows temporal correspondences in latent space, and recovers frame-specific vertices through latent-to-vertex attention. This design avoids expensive explicit matching while preserving anchor mesh details and thereby improving dynamic mesh geometry and temporal consistency. Compared to state-of-the-art, our method generates a 4D mesh in 9 seconds, achieving a speedup while producing higher-quality results. Moreover, our approach scales to videos up to longer without degrading mesh quality. Beyond generation, the improved correspondences enable competitive zero-shot performance on two downstream tasks: 2D object tracking and 4D tracking. We further show that our framework enables reliable camera estimation, a capability not supported by prior 4D mesh generation methods.5. Helix4D: Complex 4D Mesh Generation
Jiraphon Yenphraphai, Jianqi Chen, Jian Wang, Gordon Qian, Sergey Tulyakov, Rameen Abdal, Raymond A. Yeh, Peter Wonka, Chaoyang Wang
(Snap, Purdue University, KAUST)
Abstract
Current video-to-4D methods struggle with complex topology changes, transparent materials, thin structures, and inner surfaces. We present Helix4D, a dynamic mesh generation framework by inheriting the expressive representation of Trellis2, adapting it from image-to-3D to video-conditioned 4D generation. Our design arises from two key questions: (a) how to enable Trellis2's frame-local attention to share information across frames while preserving its pretrained quality on rare cases such as transparent objects and inner surfaces, and (b) how to inject temporal information into a purely 3D positional encoding without breaking pretrained capabilities. We address (a) with a sliding-window cross-frame attention and anchor on the first frame. The first frame is generated by the base Trellis2 model and injected into our model, letting it inherit Trellis2's quality in rare cases through cross-frame attention. We address (b) with a 4D temporal encoding that repurposes redundant low-frequency spatial RoPE bands for time, extending the encoding from 3D with no additional parameters. Extensive experiments show the effectiveness of Helix4D for high-quality dynamic mesh generation on ActionBench and our own challenging complex dynamics set.6. SpatialAvatar-0: High-Quality 4D Head Avatar with Multi-Stage Reconstruction
Yiran Wang, Zeyu Zhang, Yuanming Li, Ziming Wang, Yang Zhao
(USYD, SpatialReal, ZJU, La Trobe)
Abstract
High-quality 4D head avatars from one or a few source portraits are central to telepresence, AR/VR, and digital-human interaction. 3D Gaussian Splatting (3DGS) has emerged as the dominant representation, with two complementary regimes (generalizable feed-forward predictors and per-subject refiners) maturing in parallel. However, existing feed-forward predictors are trained on a single dataset family with a hard-coded source count, inheriting the corresponding domain bias. Per-subject refiners require 300K--600K iterations and rely on adaptive densification that destroys upstream Gaussian layouts, preventing the two regimes from sharing a representation end-to-end. To bridge both regimes we propose SpatialAvatar-0 on a shared FLAME-mesh-bound Gaussian representation: a feed-forward generator with a parameter-free K-source mean-pool and a monocular-temporal to multi-view-spatial two-phase schedule that anchors against identity-prior collapse onto the smaller multi-view set. We further introduce a 10K-iter layout-preserving per-subject refinement loop that freezes the FLAME-binding and Gaussian count and replaces densification with a three-component anti-spike regularization. On VFHQ/HDTF cross-domain zero-shot we surpass the in-domain leader GAGAvatar by +1.5 dB PSNR despite never training on either test domain, and on the SplattingAvatar monocular benchmark we lead every reported metric, surpassing the 300K-iter GeoAvatar by +1.3 dB PSNR at up to 60x shorter per-subject schedule than common SOTA baselines.7. IMAGIN-4D: Image-Guided Controllable Interaction Generation
Sai Kumar Dwivedi, Federica Bogo, Buğra Tekin, Chenhongyi Yang, Nadine Bertsch, Tomas Hodan, Michael J. Black, Dimitrios Tzionas, Shreyas Hampali
(Meta, Max Planck Institute for Intelligent Systems, University of Amsterdam, Aristotle University of Thessaloniki)
Abstract
Generating human-object interactions (HOI) is central to character animation, robotics, AR/VR, and embodied AI. Recent HOI generation methods synthesize motion from text, object geometry, and sparse waypoints, controlling action semantics and object trajectories. However, these signals underspecify interaction: the same prompt and trajectory can produce different grasps, approach directions, body poses, object poses, contacts, and body-object layouts. We address this ambiguity with a reference image as a visual specification of the desired interaction snapshot. However, a single global image representation conflates distinct cues and conditions all frames on identical visual evidence. We therefore introduce IMAGIN-4D, a diffusion-based HOI generator that decomposes image conditioning spatio-temporally. For spatial conditioning, IMAGIN-4D extracts supervised interaction-state tokens for body pose, object pose, body-object contact, and spatial relationships at the depicted frame. For temporal conditioning, it computes frame-aware tokens by querying image patches per generated frame, allowing sequence segments to attend to different visual cues from the same image. To balance image, text, and waypoint cues, IMAGIN-4D uses role-aware conditioning: text, waypoints, and interaction-state tokens use separate AdaLN streams, while frame-aware visual tokens cross-attend with motion tokens. Since HOI motion datasets lack paired images, we build a synthetic motion-to-image rendering pipeline from FullBodyManipulation (FBM) and introduce an image-adherence metric to evaluate whether generated motions match the reference snapshot. Experiments on FBM and BEHAVE show that IMAGIN-4D improves fine-grained interaction control over single-token and uniformly image-conditioned baselines while preserving waypoint-following and motion quality.8. MVTrack4Gen: Multi-View Point Tracking as Geometric Supervision for 4D Video Generation
JoungBin Lee, Jaewoo Jung, Jongmin Lee, Tongmin Kim, Hyunsung Kim, Takuya Narihira, Kazumi Fukuda, Jahyeok Koo, Jisang Han, Yuki Mitsufuji, Seungryong Kim
(KAIST AI, Sony AI, Sony Group Corporation)
Abstract
Synthesizing a novel-view video from a monocular reference video along a target camera trajectory requires both geometric consistency and motion fidelity with respect to the reference video. Existing methods based on explicit 3D representations are limited by the accuracy of off-the-shelf reconstruction modules, which often produce inaccurate geometry for dynamic objects in monocular videos. In contrast, camera-conditioning-only methods can achieve high visual quality but often struggle to preserve geometric and motion consistency. In this work, we introduce MVTrack4Gen (Multi-View point Tracking for Novel-View Generation), a motion-aware training framework that leverages multi-view point tracking as an additional geometric and motion supervision signal for camera-conditioning-only novel-view video diffusion models. Our key finding is that specific attention layers encode strong correspondence cues, where query features attend to key features at geometrically corresponding locations across views and over time, and the misalignment of these correspondences causes motion inconsistency. Based on this observation, we route these features into an auxiliary multi-view tracking head and jointly train the diffusion model with a point-tracking objective. By explicitly strengthening these motion-aware correspondences, MVTrack4Gen improves existing models to better follow the motion in the reference view and maintain cross-view geometric consistency. Across diverse benchmarks, our method achieves state-of-the-art geometric consistency and competitive camera accuracy.9. RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation
Haoyu Zhao, Xingyue Zhao, Siteng Huang, Xin Li, Deli Zhao, Zhongyu Li
(DAMO Academy Alibaba Group, Hong Kong Embodied AI Lab, CUHK, Hupan Lab)
Abstract
Robotic manipulation in the open world requires not only recognizing what a scene looks like, but also anticipating how its 3D structure moves under interaction. We argue that synchronized RGB, depth, and optical flow, namely RGB-DF, provide a physically grounded representation that captures the underlying 4D dynamics of a scene. Compared to 2D pixel videos, this multi-modal synergy aligns visual appearance with geometric structure and temporal motion, creating a representation space significantly closer to the low-level end-effector actions demanded by robotic systems, thereby narrowing the gap between world prediction and policy learning. Building on this insight, we introduce RynnWorld-4D, a generative model that co-produces future RGB frames, depth maps, and optical flow from a single RGB-D image and a language instruction within one unified diffusion process. This 4D world model features a tri-branch architecture that integrates cross-modal attention with frame-wise 3D RoPE, ensuring that appearance, geometry, and motion evolve consistently. To supply training data at scale, we curate Rynn4DDataset 1.0, a massive dataset of over 254.4 million frames across egocentric human and robotic manipulation videos with high-quality pseudo-labels for depth and optical flow. We further propose RynnWorld-4D-Policy, an inverse dynamics head that consumes the internal 4D representations of RynnWorld-4D in a single forward pass, bypassing expensive multi-step denoising, to output robot actions in a closed-loop manner. Experiments show that RynnWorld-4D produces temporally and spatially coherent 4D predictions, and that RynnWorld-4D-Policy achieves state-of-the-art performance on real-world dexterous bimanual manipulation tasks, particularly excelling in tasks demanding spatial precision and temporal coordination.10. SkelGen4D: Weakly-Supervised Skeleton-Based 4D Generation for Text-Driven Mesh Animation
Hao Feng, Zhi Zuo, Jia-Hui Pan, Ka-Hei Hui, Zhengzhe Liu, Dian Zhang, Haoran Xie, Bin Sheng, Jingyu Hu
(Lingnan University, Chinese University of Hong Kong, Autodesk Research, Shanghai Jiao Tong University)
Abstract
We study 4D generation to synthesize temporally coherent sequences of 3D geometry for animation and content creation. In contrast to existing SDS-based optimization methods and video-driven animation approaches, we adopt a skeleton-driven animation framework aligned with standard industrial pipelines, which enables explicit control and editing. To this end, we propose SkelGen4D, a weakly supervised feed-forward framework for text-driven mesh animation that generates explicit skeleton motions without requiring per-frame skeleton annotations. SkelGen4D first recovers temporally consistent pseudo-skeletons from animated meshes via differentiable fitting, and then generates text-conditioned skeleton motion sequences in a feed-forward manner, further refined with Motion-GRPO to ensure temporally coherent, physically plausible, and articulated animation. We evaluate our method on two large-scale benchmarks, Truebones Zoo and Diffusion4D. Our results show that our weakly supervised skeleton modeling matches or surpasses fully supervised baselines while scaling to diverse object categories for high-quality text-driven mesh animation. Further, our method supports flexible motion editing and is aligned with standard animation production pipelines.11. Hallo4D: Multi-Modal Hallucination Mitigation for Consistent Spatio-Temporal Generation
Hongbo Wang, Huaibo Huang, Jie Cao, Jin Liu, Haoyang Tong, Ran He
(CASIA, UCAS, ShanghaiTech)
Abstract
While recent advances in 3D generation have enabled impressive visual synthesis, existing methods often rely on 2D diffusion supervision without explicit mechanisms for geometric consistency, leading to spatial hallucinations such as duplicated structures and misaligned geometry. These issues become more severe in 4D generation, where maintaining consistency across viewpoints and temporal evolution introduces additional challenges, including jitter, identity flicker, and structural drift. We present \textbf{Hallo4D}, a unified and model-agnostic framework for mitigating spatiotemporal hallucinations in 3D and 4D content generation. Hallo4D introduces a generation-detection-correction paradigm that leverages large multimodal language models (LMMs) to identify and summarize spatial and temporal inconsistencies from multi-view and multi-frame renderings. These insights guide a consensus-driven image-space consistency optimization, where an LMM-based selector evaluates candidate corrections through multi-model voting, without requiring retraining or architectural modifications. To further improve temporal consistency and optimization efficiency, Hallo4D incorporates motion-aware keyframe sampling, LMM-guided initialization, and appearance alignment. We additionally introduce exposure-aware optimization and visibility pruning to enhance robustness under challenging viewpoints. Extensive experiments demonstrate that Hallo4D consistently outperforms strong baselines across diverse 3D and 4D generation settings, providing a scalable and generalizable solution for consistency-aware content generation.12. PE-Field 4D: Video Generation Models as Canvas
Yunpeng Bai, Haoxiang Li, Qixing Huang (UT Austin, Pixocial Technology)
Abstract
Diffusion Transformers have recently achieved strong performance in video generation, yet controlling scene geometry under viewpoint changes and camera motion remains challenging. In this work, we revisit the role of positional encoding in video diffusion transformers and show that it provides a useful spatial bias for geometry-aware control. Specifically, if reference tokens are encoded according to their projected locations in the target view, the denoising model is encouraged to retrieve content from position aligned regions of the input video. Building on this observation, we introduce a geometry-aware cross-attention mechanism that enables target video latent tokens to attend to structured context tokens derived from reference images or frames. To establish correspondence between the reference content and the target camera trajectory, we equip the context tokens with a projected positional encoding scheme that combines target-view 2D reprojection with depth-aware disambiguation. At the same time, we preserve the original spatiotemporal positional encoding of the generated video latent, allowing geometric guidance to be injected while maintaining consistency with the video model's native latent structure. The resulting framework provides a simple and effective approach for controllable video generation. It improves spatial controllability in viewpoint-dependent editing tasks, including camera re-trajectory, novel-view video synthesis, and geometry-aware video editing, while preserving the generative prior of the underlying video diffusion model.13. Beyond Pixels: From Video Priors to 4D Worlds
Zihao Liu, Xiaolong Shen, Zhenglin Zhou, Ruijie Quan, Yi Yang (Zhejiang University)
Abstract
4D generation synthesizes dynamic 3D scenes from conditions such as text or images. Existing methods either reconstruct generated RGB videos with a separate 4D model or adapt a particular video generator to predict geometry directly. The former suffers from distribution mismatch and error propagation, whereas the latter ties 4D prediction to a specific generator and may require retraining when the generator or conditioning regime changes. We ask whether the final denoised latents of video models that share a variational autoencoder (VAE) can instead provide a reusable interface to explicit 4D prediction. Building on this insight, we introduce direct latent-to-4D generation and instantiate it as Latent-to-4D, which bypasses RGB by aligning a video latent with the token grid of a pretrained 4D decoder and refining it through frame-wise and global spatiotemporal attention. Trained on roughly 1K existing reconstruction clips, a single checkpoint transfers unchanged across multiple video diffusion transformers within the same VAE family. On Text4D-200 and I4D-200, Latent-to-4D surpasses matched same-latent Wan+4RC cascades in projection-based DINO-F1 by 2.88--3.45 and 5.81 points, respectively, while also being preferred by human raters for geometry, temporal stability, and overall quality.14. Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models
Yuanhao Ban, Jiaqi Feng, Hengguang Zhou, Xiaohuan Pei, Justin Cui, Cho-Jui Hsieh
(UCLA, Tsinghua University)
Abstract
Streaming autoregressive diffusion models enable real-time, long-horizon video generation, but their training objectives optimize local frame prediction rather than the geometry and dynamics of a coherent world: long rollouts accumulate geometric drift and degrade into static or unnatural motion. Recent bidirectional approaches address this problem using rewards signals built upon 3D Gaussian-Splatting reconstruction. However, a single rigid 3d reconstruction cannot model a dynamic scene, so this critic penalizes genuine object motion as reconstruction error and is maximized by freezing the video. This shortcut is especially detrimental in the AR setting, where each chunk can propagate an already-static configuration. In this work, we propose Stream4D, which replaces the static critic with a feed-forward 4D reconstruction reward that explicitly models scene dynamics, allowing coherent motion to receive high consistency rewards. To further guide motion magnitude and quality, we add a motion prior that rewards natural scene-flow magnitude while penalizing jitter and non-rigid artifacts. Our final recipe combines these two terms with a lightweight perceptual anchor. Across various autoregressive video backbones and various generation horizons, Stream4D improves 4D reconstruction quality, preserves motion more effectively, and achieves higher human-aligned preference.15. 4DStreamCtrl: Interactive Video Generation with Online 4D Control
Shiqian Li, Chenguo Lin, Zhiguang Liu, Yu Tang, Jiarong Ou, Rui Chen, Yixin Zhu
(Peking University, Tencent Hunyuan)
Abstract
Generative video models now synthesize footage nearly indistinguishable from reality. Their promise as interactive tools hinges on fine-grained control of how objects and the camera move over time, yet each existing approach captures only part of this: camera-parameter methods steer the viewpoint but cannot move objects, 2D-trajectory methods act in the image plane and ignore depth and occlusion, and recent 3D methods add geometry but run only offline at a fixed length. In particular, none combines 3D-consistent control of both camera and objects with real-time, streaming generation. Here we show that camera motion, object trajectories, and depth can be unified into a single 3D point-track representation, from which one model performs joint camera and object control, depth editing, and motion transfer in a single forward pass. To learn this interface at scale, we mine in-the-wild video for 3D motion supervision, yielding OpenVidHD-Motion3D, and encode it with a lightweight Geometric Motion Head that plugs into a pretrained video diffusion model. Because this encoder is temporally separable, we distill the model into a causal streaming student that generates arbitrarily long video in four denoising steps at memory independent of length. This unified design surpasses prior camera-only, 2D, and offline-3D methods in motion-control precision while covering modalities they address only in isolation. 4DStreamCtrl runs at 20 FPS on a single high-end GPU for 480p video and stays temporally coherent over hundreds of frames, enabling, to our knowledge, interactive 4D-controllable streaming generation for the first time. More broadly, grounding generation in explicit 3D geometry with efficient causal inference points toward interactive world models with closed-loop spatiotemporal control, from controllable simulators to real-time visual imagination for embodied agents.16. GAE: Learning a Geometry-Native Latent Space for 3D-Consistent World Generation
Jiahao Lu, Minghao Yin, Wenbo Hu, Hengyu Liu, Wang Zhao, Sai-Kit Yeung, Ying Shan, Yuan Liu
(The Hong Kong University of Science and Technology, ARC Lab Tencent IEG, The University of Hong Kong, The University of Texas at Austin)
Abstract
We present a compact geometry-native latent space as a shared foundation for perception and generation. Visual generators can produce photorealistic frames without preserving a consistent 3D scene. We argue that this is not only a modeling problem but also a representation problem: generators typically evolve appearance-centric latents, while perception models recover geometry in a semantically rich space that encodes cross-view structure. Rather than adding geometry as another output, we reparameterize a geometry foundation model's features into a compact latent space for generation. We realize this shift with the geometry-native autoencoder (GAE), whose latent is jointly decodable to appearance, depth, cameras, and point maps. With this state, a standard conditional flow supports diverse generation tasks. In controlled comparisons that hold the generator and training protocol fixed, replacing the latent with GAE improves both visual quality and independently measured 3D coherence: FVD falls by 12.7% and 23.1% on RealEstate10K and DL3DV, and camera-trajectory error is halved on RealEstate10K. Together, these results show that the latent space is central to geometry-consistent generation and can serve as a shared interface between perception and generation.| Year | Title | ArXiv Time | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2026 | Pixel-to-4D: Camera-Controlled Image-to-Video Generation with Dynamic 3D Gaussians | 2 Jan 2026 | Link | -- | Link |
| 2026 | InSpatio-World | 20 Mar 2026 | Live Demo | Link | Link |
| 2026 | ST-Gen4D: Embedding 4D Spatiotemporal Cognition into World Model for 4D Generation | 8 May 2026 | Link | -- | -- |
| 2026 | Geometric 4D Stitching for Grounded 4D Generation | 11 May 2026 | Link | -- | -- |
| 2026 | Fast 4D Mesh Generation by Spatio-Temporal Attention Chains | 19 May 2026 | Link | -- | Link |
| 2026 | Helix4D: Complex 4D Mesh Generation | 25 May 2026 | Link | -- | Link |
| 2026 | SpatialAvatar-0: High-Quality 4D Head Avatar with Multi-Stage Reconstruction | 14 Jun 2026 | Link | -- | Link |
| 2026 | IMAGIN-4D: Image-Guided Controllable Interaction Generation | 22 Jun 2026 | Link | -- | Link |
| 2026 | MVTrack4Gen: Multi-View Point Tracking as Geometric Supervision for 4D Video Generation | 24 Jun 2026 | Link | Link | Link |
| 2026 | RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation | 7 Jul 2026 | Link | Link | Link |
| 2026 | SkelGen4D: Weakly-Supervised Skeleton-Based 4D Generation for Text-Driven Mesh Animation | 9 Jul 2026 | Link | -- | -- |
| 2026 | Hallo4D: Multi-Modal Hallucination Mitigation for Consistent Spatio-Temporal Generation | 15 Jul 2026 | Link | Link | Link |
| 2026 | PE-Field 4D: Video Generation Models as Canvas | 17 Jul 2026 | Link | -- | -- |
| 2026 | Beyond Pixels: From Video Priors to 4D Worlds | 11 Aug 2026 | Link | Link | Link |
| 2026 | Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models | 20 Aug 2026 | Link | -- | Link |
| 2026 | 4DStreamCtrl: Interactive Video Generation with Online 4D Control | 27 Aug 2026 | Link | -- | Link |
| 2026 | GAE: Learning a Geometry-Native Latent Space for 3D-Consistent World Generation | 21 Sep 2026 | Link | Link | Link |
ArXiv Papers References
%axiv papers

@article{de2026pixel,
  title={Pixel-to-4D: Camera-Controlled Image-to-Video Generation with Dynamic 3D Gaussians},
  author={de Almeida, Melonie and Ivanova, Daniela and Shi, Tong and Williamson, John H and Henderson, Paul},
  journal={arXiv preprint arXiv:2601.00678},
  year={2026}
}

@misc{inspatio-world,
    title={InSpatio-World},
    author={InSpatio-World Contributors},
    howpublished={\url{https://github.com/inspatio/inspatio-world}},
    year={2025}
}

@article{wang2026st,
  title={ST-Gen4D: Embedding 4D Spatiotemporal Cognition into World Model for 4D Generation},
  author={Wang, Haonan and Zhou, Hanyu and Gu, Tao and Yan, Luxin},
  journal={arXiv preprint arXiv:2605.07390},
  year={2026}
}

@article{park2026geometric,
  title={Geometric 4D Stitching for Grounded 4D Generation},
  author={Park, Sunwoo and Kwon, Taesung and Ye, Jong Chul},
  journal={arXiv preprint arXiv:2605.09984},
  year={2026}
}

@article{samuel2026fast,
  title={Fast 4D Mesh Generation by Spatio-Temporal Attention Chains},
  author={Samuel, Dvir and Atzmon, Yuval and Chechik, Gal and Kasten, Yoni},
  journal={arXiv preprint arXiv:2605.19786},
  year={2026}
}

@article{yenphraphai2026helix4d,
  title={Helix4D: Complex 4D Mesh Generation},
  author={Yenphraphai, Jiraphon and Chen, Jianqi and Wang, Jian and Qian, Gordon and Tulyakov, Sergey and Abdal, Rameen and Yeh, Raymond A and Wonka, Peter and Wang, Chaoyang},
  journal={arXiv preprint arXiv:2605.26109},
  year={2026}
}

@article{wang2026spatialavatar,
  title={SpatialAvatar-0: High-Quality 4D Head Avatar with Multi-Stage Reconstruction},
  author={Wang, Yiran and Zhang, Zeyu and Li, Yuanming and Wang, Ziming and Zhao, Yang},
  journal={arXiv preprint arXiv:2606.15659},
  year={2026}
}

@misc{dwivedi2026imagin4dimageguidedcontrollableinteraction,
      title={IMAGIN-4D: Image-Guided Controllable Interaction Generation},
      author={Sai Kumar Dwivedi and Federica Bogo and Buğra Tekin and Chenhongyi Yang and Nadine Bertsch and Tomas Hodan and Michael J. Black and Dimitrios Tzionas and Shreyas Hampali},
      year={2026},
      eprint={2606.23675},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2606.23675},
}

@misc{lee2026mvtrack4genmultiviewpointtracking,
      title={MVTrack4Gen: Multi-View Point Tracking as Geometric Supervision for 4D Video Generation},
      author={JoungBin Lee and Jaewoo Jung and Jongmin Lee and Tongmin Kim and Hyunsung Kim and Takuya Narihira and Kazumi Fukuda and Jahyeok Koo and Jisang Han and Yuki Mitsufuji and Seungryong Kim},
      year={2026},
      eprint={2606.26087},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2606.26087},
}

@article{zhao2026rynnworld,
  title={RynnWorld-4D: 4D Embodied World Models for Robotic Manipulation},
  author={Zhao, Haoyu and Zhao, Xingyue and Huang, Siteng and Li, Xin and Zhao, Deli and Li, Zhongyu},
  journal={arXiv preprint arXiv:2607.06559},
  year={2026}
}

@article{feng2026skelgen4d,
  title={SkelGen4D: Weakly-Supervised Skeleton-Based 4D Generation for Text-Driven Mesh Animation},
  author={Feng, Hao and Zuo, Zhi and Pan, Jia-Hui and Hui, Ka-Hei and Liu, Zhengzhe and Zhang, Dian and Xie, Haoran and Sheng, Bin and Hu, Jingyu},
  journal={arXiv preprint arXiv:2607.08246},
  year={2026}
}

@article{wang2026hallo4d,
  title={Hallo4D: Multi-Modal Hallucination Mitigation for Consistent Spatio-Temporal Generation},
  author={Wang, Hongbo and Huang, Huaibo and Cao, Jie and Liu, Jin and Tong, Haoyang and He, Ran},
  journal={arXiv preprint arXiv:2607.12752},
  year={2026}
}

@article{bai2026pe,
  title={PE-Field 4D: Video Generation Models as Canvas},
  author={Bai, Yunpeng and Li, Haoxiang and Huang, Qixing},
  journal={arXiv preprint arXiv:2607.15667},
  year={2026}
}

@misc{liu2026pixelsvideopriors4d,
      title={Beyond Pixels: From Video Priors to 4D Worlds},
      author={Zihao Liu and Xiaolong Shen and Zhenglin Zhou and Ruijie Quan and Yi Yang},
      year={2026},
      eprint={2608.10744},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2608.10744},
}

@misc{ban2026stream4d4dconsistencystreamingautoregressive,
      title={Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models},
      author={Yuanhao Ban and Jiaqi Feng and Hengguang Zhou and Xiaohuan Pei and Justin Cui and Cho-Jui Hsieh},
      year={2026},
      eprint={2608.19556},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2608.19556},
}

@article{li20264dstreamctrl,
  title={4DStreamCtrl: Interactive Video Generation with Online 4D Control},
  author={Li, Shiqian and Lin, Chenguo and Liu, Zhiguang and Tang, Yu and Ou, Jiarong and Chen, Rui and Zhu, Yixin},
  journal={arXiv preprint arXiv:2608.25479},
  year={2026}
}

@misc{lu2026gaelearninggeometrynativelatent,
      title={GAE: Learning a Geometry-Native Latent Space for 3D-Consistent World Generation},
      author={Jiahao Lu and Minghao Yin and Wenbo Hu and Hengyu Liu and Wang Zhao and Sai-Kit Yeung and Ying Shan and Yuan Liu},
      year={2026},
      eprint={2609.24981},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.24981},
}
Previous Papers and Other Awesome Repos
Year 2025
For more details, please check the 2025 4D Papers, including 35 accepted papers, 6 arXiv papers and 2 arXiv surveys.
Year 2024
For more details, please check the 2024 4D Papers, including 27 accepted papers and 7 arXiv papers.
Year 2023
In 2023, tasks classified as text/Image to 4D and video to 4D generally involve producing four-dimensional data from text/Image or video input. For more details, please check the 2023 4D Papers, including 6 accepted papers and 3 arXiv papers.
Video Generation Subsection
🎉 Video Accepted Papers
💡 Video ArXiv Papers
1. SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models
Junchao Huang, Guian Fang, Shengju Qian, Xianghao Kong, Zhuoran Zhao, Wei Huang, Yihua Du, Zixin Zhang, Justin Cui, Yuchao Gu, Yukang Chen, Xinting Hu, Tianyu He, Shaoshuai Shi, Zhuotao Tian, Xin Wang, Mike Zheng Shou, Li Jiang
(CUHK-SZ, SLAI, NUS, CUHK, HKUST, HKUST-GZ, NVIDIA, UCLA, MSRA)
Abstract
We introduce SolarWM, a fully open foundation for building interactive video world models from data preparation through long-horizon inference. Training across heterogeneous data sources and video backbones is challenging: datasets differ in temporal scale, camera geometry, visual quality, motion, and captioning styles, while video generators use distinct representations and architectures. Naive data mixing and model-specific implementations therefore produce inconsistent supervision and make results difficult to reproduce and compare. SolarWM addresses this coupling with a reconfigurable multi-source data engine and a backbone-native adaptation framework. The engine converts 1.43 million canonical clips from 10 datasets into a unified, frame-aligned contract covering visual observations, metric camera geometry, captions, quality metadata, selection decisions, and provenance, while decoupling source processing from mixture construction. Under shared camera-conditioning, training, and inference interfaces, we instantiate four 5B--33B models based on Wan2.2, LTX-2.5, and MiniMax-H3 while preserving their native representations and objectives. A unified three-stage recipe combines bidirectional adaptation, teacher-forced autoregressive initialization, and distribution matching distillation. The resulting causal models enable real-time interaction over rollouts ranging from minutes to hours after being trained on only 5s sequences. By releasing the resulting data, pipeline, recipes, weights, and framework, SolarWM provides a reproducible and extensible foundation for interactive world-model research.| Year | Title | ArXiv Time | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2026 | SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models | 2 Sept 2026 | Link | Link | Link |
ArXiv Papers References
%axiv papers

@misc{huang2026solarwmopendatascalable,
      title={SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models},
      author={Junchao Huang and Guian Fang and Shengju Qian and Xianghao Kong and Zhuoran Zhao and Wei Huang and Yihua Du and Zixin Zhang and Justin Cui and Yuchao Gu and Yukang Chen and Xinting Hu and Tianyu He and Shaoshuai Shi and Zhuotao Tian and Xin Wang and Mike Zheng Shou and Li Jiang},
      year={2026},
      eprint={2609.02886},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.02886},
}
Video Other Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 T2V Papers, including 16 accepted papers and 11 arXiv papers.
Year 2024
For more details, please check the 2024 T2V Papers, including 25 accepted papers and 3 arXiv papers.
- OSS video generation models: Mochi 1 preview is an open state-of-the-art video generation model with high-fidelity motion and strong prompt adherence.
- Survey: The Dawn of Video Generation: Preliminary Explorations with SORA-like Models, arXiv, Project Page, GitHub Repo
3D Scene Subsection
🎉 3D Scene Accepted Papers
| Year | Title | Venue | Paper | Code | Project Page |
|---|---|---|---|---|---|
| 2025 | PanoDreamer: Optimization-Based Single Image to 360 3D Scene With Diffusion | SIGGRAPH Asia 2025 | Link | Link | Link |
Accepted Papers References
%accepted papers

@inproceedings{paliwal2025panodreamer,
  title={PanoDreamer: Optimization-Based Single Image to 360 3D Scene With Diffusion},
  author={Paliwal, Avinash and Zhou, Xilong and Tsarov, Andrii and Kalantari, Nima},
  booktitle={Proceedings of the SIGGRAPH Asia 2025 Conference Papers},
  pages={1--10},
  year={2025}
}
Scene Other Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 3D Scene Papers, including 15 accepted papers, 10 arXiv papers and 2 arXiv surveys.
Year 2023-2024
For more details, please check the 2023-2024 3D Scene Papers, including 25 accepted papers and 6 arXiv papers.
Awesome Repos
Awesome Repos
- Resource1: WorldGen: Generate Any 3D Scene in Seconds
- Resource2: RTFM: A Real-Time Frame Model Blog Demo Try-on
Human Motion Subsection
Motion Other Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 Human Motion Papers, including 18 accepted papers and 4 arXiv papers.
Year 2023-2024
For more details, please check the 2023-2024 Text to Human Motion Papers, including 37 accepted papers and 5 arXiv papers.
Datasets
| Motion | Info | URL | Others |
|---|---|---|---|
| AIST | AIST Dance Motion Dataset | Link | -- |
| AIST++ | AIST++ Dance Motion Dataset | Link | dance video database with SMPL annotations |
| AMASS | optical marker-based motion capture datasets | Link | -- |
Additional Info
AMASS
AMASS is a large database of human motion unifying different optical marker-based motion capture datasets by representing them within a common framework and parameterization. AMASS is readily useful for animation, visualization, and generating training data for deep learning.
Awesome Repos
Survey
3D Human Subsection
3D Human Additional Info
Previous Papers
Year 2025
For more details, please check the 2025 3D Human Papers, including 12 accepted papers and 1 arXiv papers.
Year 2023-2024
For more details, please check the 2023-2024 3D Human Papers, including 22 accepted papers and 1 arXiv papers.
Pretrained Models
| Pretrained Models (human body) | Info | URL |
|---|---|---|
| SMPL | smpl model (smpl weights) | Link |
| SMPL-X | smpl model (smpl weights) | Link |
| human_body_prior | vposer model (smpl weights) | Link |
SMPL
SMPL is an easy-to-use, realistic, model of the of the human body that is useful for animation and computer vision.
- version 1.0.0 for Python 2.7 (female/male, 10 shape PCs)
- version 1.1.0 for Python 2.7 (female/male/neutral, 300 shape PCs)
- UV map in OBJ format
SMPL-X
SMPL-X, that extends SMPL with fully articulated hands and facial expressions (55 joints, 10475 vertices)
🎯Back to Top - Text2X Resources
Related Resources
Text to 'other tasks'
Here, other tasks refer to CAD, 3D modeling, music generation, and so on.
Text to CAD
- [arXiv 7 Nov 2024] CAD-MLLM: Unifying Multimodality-Conditioned CAD Generation With MLLM [Paper] [GitHub] [Project Page]
- [NeurIPS 2024 Spotlight] Text2CAD: Generating Sequential CAD Designs from Beginner-to-Expert Level Text Prompts [Paper] [GitHub] [Project Page] [Dataset]
- [CVPR 2025] CAD-Llama: Leveraging Large Language Models for Computer-Aided Design Parametric 3D Model Generation [Paper]
Text to Music
- [arXiv 1 Sep 2024] FLUX that Plays Music [Paper] [GitHub]
- [International Society for Music Information Retrieval(ISMIR) 2025] Video-Guided Text-to-Music Generation Using Public Domain Movie Collections [Paper] [Code] [Project Page]
Text to Model
- [ICLR Workshop on Neural Network Weights as a New Data Modality 2025] Text-to-Model: Text-Conditioned Neural Network Diffusion for Train-Once-for-All Personalization [Paper]
Survey and Awesome Repos
🔥 Topic 1: 3D Gaussian Splatting
Survey
- [arXiv 6 May 2024] Gaussian Splatting: 3D Reconstruction and Novel View Synthesis, a Review [Paper]
- [arXiv 17 Mar 2024] Recent Advances in 3D Gaussian Splatting [Paper]
- [IEEE TVCG 2024] 3D Gaussian as a New Vision Era: A Survey [Paper]
- [arXiv 8 Jan 2024] A Survey on 3D Gaussian Splatting [Paper] [GitHub] [Benchmark]
Awesome Repos
- Resource1: Awesome 3D Gaussian Splatting Resources
- Resource2: 3D Gaussian Splatting Papers
- Resource3: 3DGS and Beyond Docs
🔥 Topic 2: AIGC 3D
Survey
- [arXiv 15 May 2024] A Survey On Text-to-3D Contents Generation In The Wild [Paper]
- [arXiv 2 Feb 2024] A Comprehensive Survey on 3D Content Generation [Paper] [GitHub]
- [arXiv 31 Jan 2024] Advances in 3D Generation: A Survey [Paper]
Awesome Repos
- Resource1: Awesome 3D AIGC Resources
- Resource2: Awesome-Text/Image-to-3D
- Resource3: Awesome Text-to-3D
Benchmark
- [CVPR 2024] GPT-4V(ision) is a Human-Aligned Evaluator for Text-to-3D Generation [Paper] [GitHub] [Project Page]
Foundation Model
🔥 Topic 3: 3D Human & LLM 3D
Survey
- [arXiv 6 June 2024] A Survey on 3D Human Avatar Modeling -- From Reconstruction to Generation [Paper]
- [arXiv 5 Jan 2024] Progress and Prospects in 3D Generative AI: A Technical Overview including 3D human [Paper]
Awesome Repos
- Resource1: Awesome LLM 3D
- Resource2: Awesome Digital Human
- Resource3: Awesome-Avatars
🔥 Topic 5: Physics-based AIGC
Survey
Dynamic Gaussian Splatting
Neural Deformable 3D Gaussians
- [CVPR 2024] Deformable 3D Gaussians for High-Fidelity Monocular Dynamic Scene Reconstruction [Paper] [GitHub] [Project Page]
- [CVPR 2024] 4D Gaussian Splatting for Real-Time Dynamic Scene Rendering [Paper] [GitHub] [Project Page]
- [CVPR 2024] SC-GS: Sparse-Controlled Gaussian Splatting for Editable Dynamic Scenes [Paper] [GitHub] [Project Page]
- [CVPR 2024 Highlight] 3DGStream: On-the-Fly Training of 3D Gaussians for Efficient Streaming of Photo-Realistic Free-Viewpoint Videos [Paper] [GitHub] [Project Page]
4D Gaussians
- [SIGGRAPH 2024] 4D-Rotor Gaussian Splatting: Towards Efficient Novel View Synthesis for Dynamic Scenes [Paper]
- [ICLR 2024] Real-time Photorealistic Dynamic Scene Representation and Rendering with 4D Gaussian Splatting [Paper] [GitHub] [Project Page]
Dynamic 3D Gaussians
- [CVPR 2024 Highlight] Gaussian-Flow: 4D Reconstruction with Dynamic 3D Gaussian Particle [Paper] [GitHub] [Project Page]
- [3DV 2024] Dynamic 3D Gaussians: Tracking by Persistent Dynamic View Synthesis [Paper] [GitHub] [Project Page]
🎯Back to Top - Table of Contents
License
This repo is released under the MIT license.
✉️ Any additions or suggestions, feel free to contact us.