
README
A Survey on Video Diffusion Models 

Zhen Xing, Qijun Feng, Haoran Chen, Qi Dai, Han Hu, Hang Xu, Zuxuan Wu, Yu-Gang Jiang
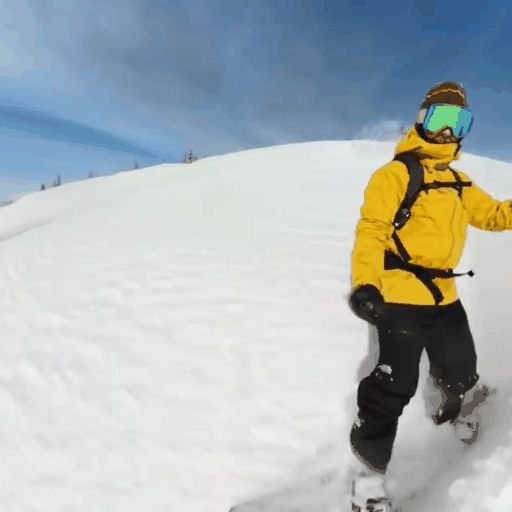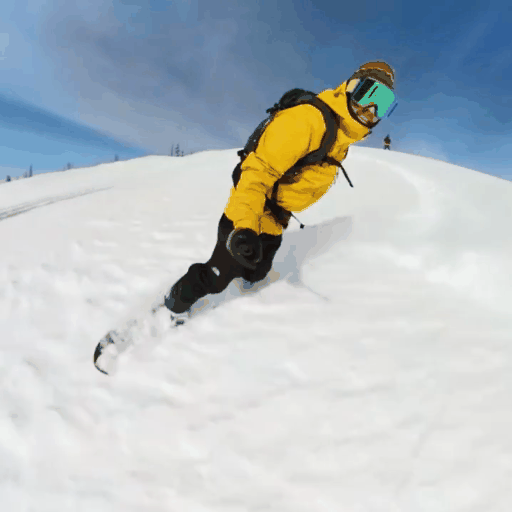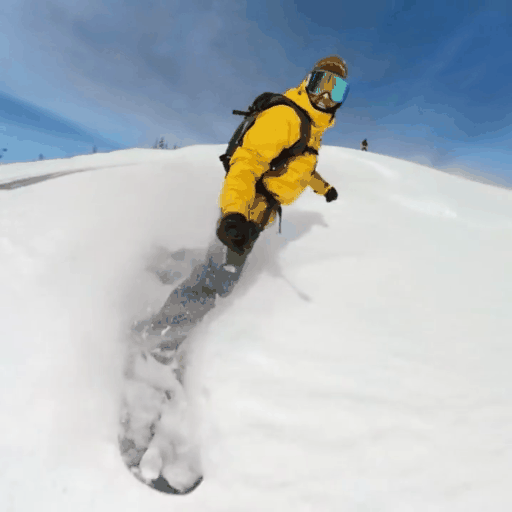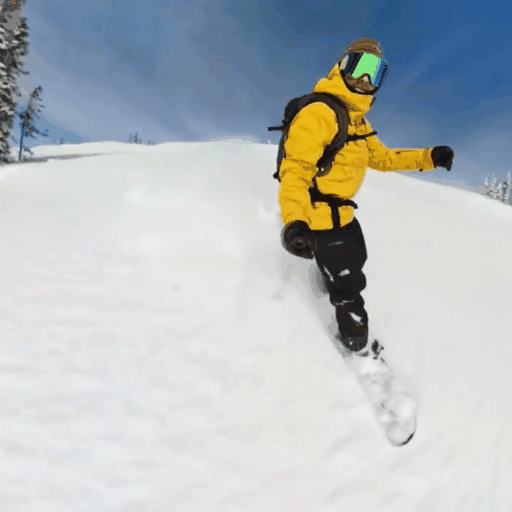
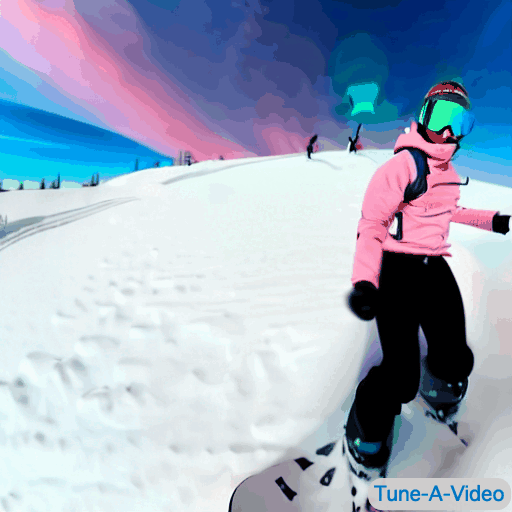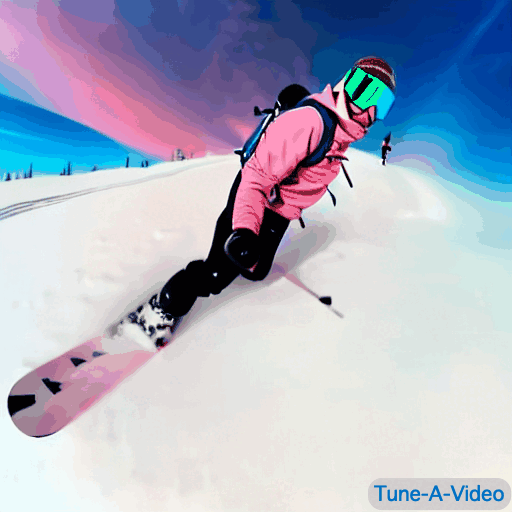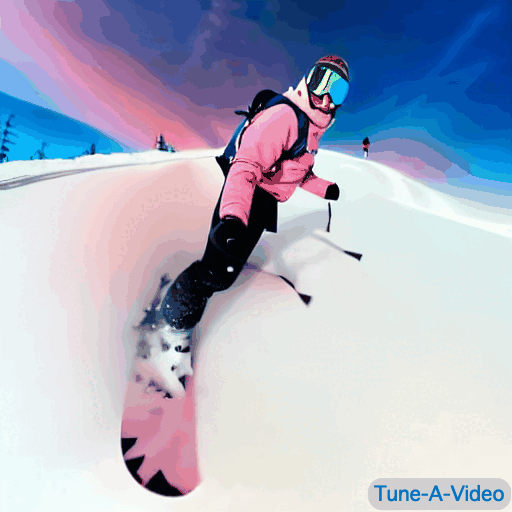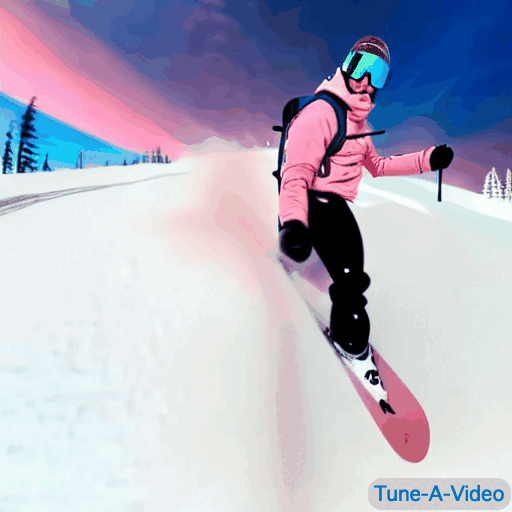
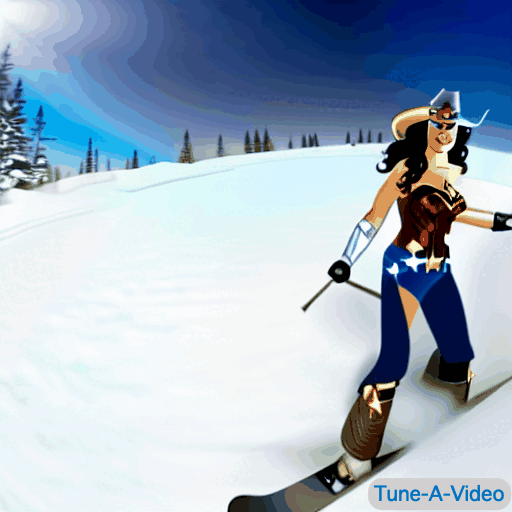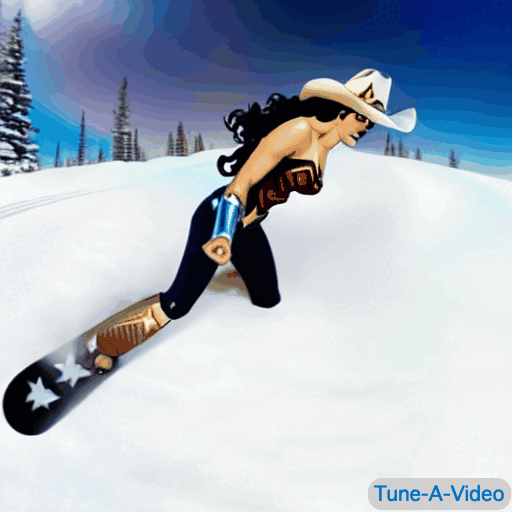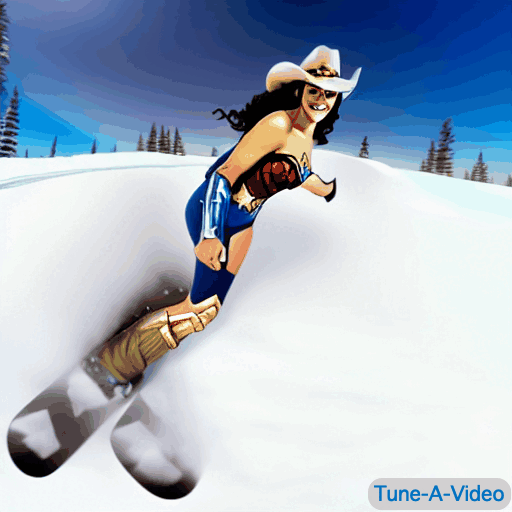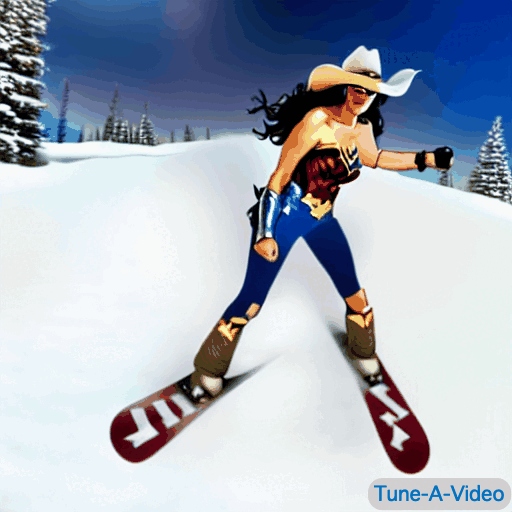
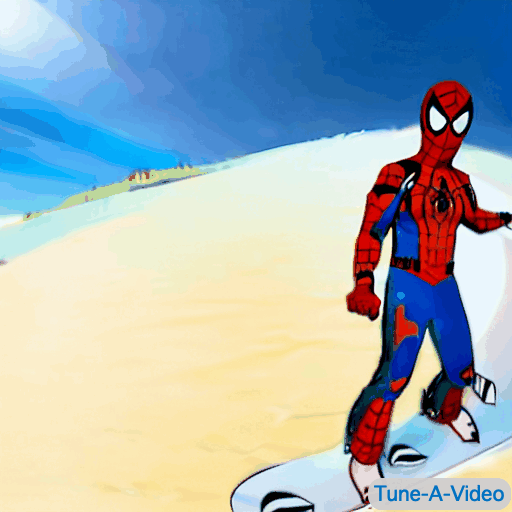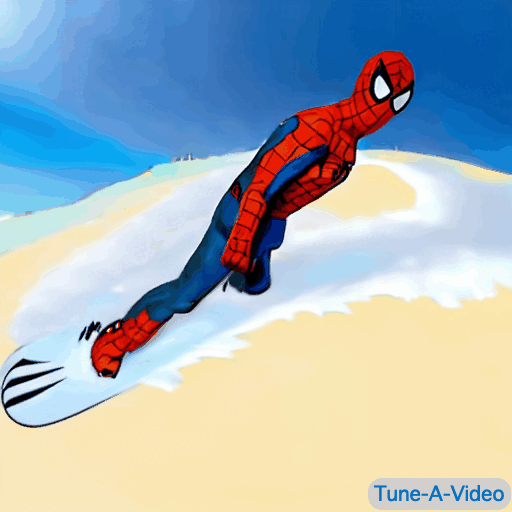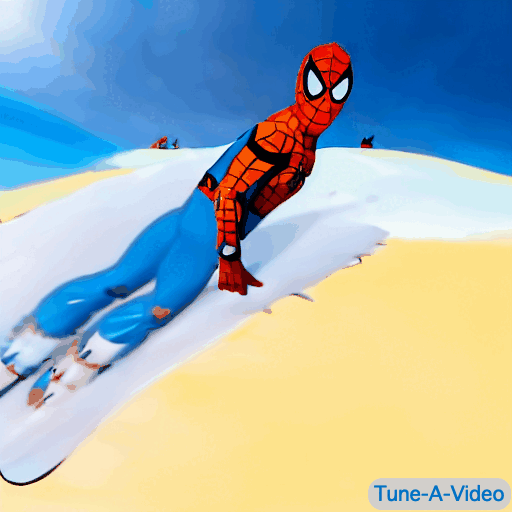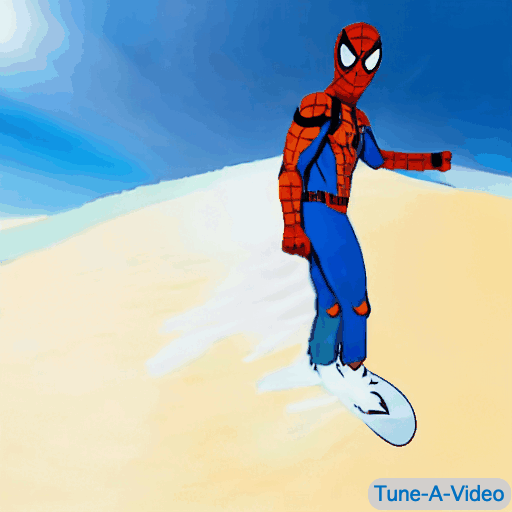
(Source: Make-A-Video, SimDA, PYoCo, SVD , Video LDM and Tune-A-Video)
- [News] The updated version is available on arXiv.
- [News] Our survey is accepted by ACM Computing Surveys (CSUR).
- [News] The Chinese translation is available on Zhihu. Special thanks to Dai-Wenxun for this.
Contact
If you have any suggestions or find our work helpful, feel free to contact us
Homepage: Zhen Xing
Email: zhenxingfd@gmail.com
If you find our survey is useful in your research or applications, please consider giving us a star 🌟 and citing it by the following BibTeX entry.
@article{xing2023survey,
  title={A survey on video diffusion models},
  author={Xing, Zhen and Feng, Qijun and Chen, Haoran and Dai, Qi and Hu, Han and Xu, Hang and Wu, Zuxuan and Jiang, Yu-Gang},
  journal={ACM Computing Surveys},
  year={2023},
  publisher={ACM New York, NY}
}
Open-source Toolboxes and Foundation Models
| Methods | Task | Github |
|---|---|---|
| Helios | T2V Generation |  |
| Movie Gen | T2V Generation | - |
| CogVideoX | T2V Generation |  |
| Open-Sora-Plan | T2V Generation |  |
| Open-Sora | T2V Generation |  |
| Morph Studio | T2V Generation | - |
| Genie | T2V Generation | - |
| Sora | T2V Generation & Editing | - |
| VideoPoet | T2V Generation & Editing | - |
| Stable Video Diffusion | T2V Generation |  |
| NeverEnds | T2V Generation | - |
| Pika | T2V Generation | - |
| EMU-Video | T2V Generation | - |
| GEN-2 | T2V Generation & Editing | - |
| ModelScope | T2V Generation |  |
| ZeroScope | T2V Generation | - |
| T2V Synthesis Colab | T2V Genetation |  |
| VideoCraft | T2V Genetation & Editing |  |
| Diffusers (T2V synthesis) | T2V Genetation | - |
| AnimateDiff | Personalized T2V Genetation |  |
| Text2Video-Zero | T2V Genetation |  |
| HotShot-XL | T2V Genetation |  |
| Genmo | T2V Genetation | - |
| Fliki | T2V Generation | - |
| Seedream AI Studio | Image Generation + I2V Animation | - |
| Omni-Rewriter | Prompt Expansion (Video/Image PE) |  |
Table of Contents
Video Generation
Data
Caption-level


| MiniMax H3 1K Prompt Dataset | 
 |

Category-level
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| UCF101: A Dataset of 101 Human Actions Classes From Videos in The Wild | | - | - | Dec., 2012 |
| First Order Motion Model for Image Animation | | - | - | May, 2023 |
| Learning to Generate Time-Lapse Videos Using Multi-Stage Dynamic Generative Adversarial Networks | | - | - | CVPR,2018 |
Metric and BenchMark


Text-to-Video Generation
Training-based


Training-free


Video Generation with other conditions
Pose-guided Video Generation


Motion-guided Video Generation


Sound-guided Video Generation


Image-guided Video Generation


Brain-guided Video Generation
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| NeuroCine: Decoding Vivid Video Sequences from Human Brain Activties | | - | - | Feb., 2024 |
| Cinematic Mindscapes: High-quality Video Reconstruction from Brain Activity | |  | | NeurIPS, 2023 |
Depth-guided Video Generation
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| StableV2V: Stablizing Shape Consistency in Video-to-Video Editing | |  | | Nov., 2024 |
| Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation | |  | | Jul., 2023 |
| Make-Your-Video: Customized Video Generation Using Textual and Structural Guidance | |  | | Jun., 2023 |
Multi-modal guided Video Generation


Unconditional Video Generation
U-Net based
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| Hybrid Video Diffusion Models with 2D Triplane and 3D Wavelet Representation | |  | | Feb. 2024 |
| Video Probabilistic Diffusion Models in Projected Latent Space | |  | | CVPR 2023 |
| VIDM: Video Implicit Diffusion Models | |  | | AAAI 2023 |
| GD-VDM: Generated Depth for better Diffusion-based Video Generation | |  | - | Jun., 2023 |
| LEO: Generative Latent Image Animator for Human Video Synthesis | |  | | May., 2023 |
Transformer based


Video Completion
Video Enhancement and Restoration


Video Prediction


Video Editing
General Editing Model


Training-free Editing Model


One-shot Editing Model


Instruct-guided Video Editing

Motion-guided Video Editing


Sound-guided Video Editing
| Title | arXiv | Github | Website | Pub. Date |
|---|---|---|---|---|
| Speech Driven Video Editing via an Audio-Conditioned Diffusion Model | | - | - | May., 2023 |
| Soundini: Sound-Guided Diffusion for Natural Video Editing | |  | | Apr., 2023 |
Multi-modal Control Editing Model


Domain-specific Editing Model


Non-diffusion Editing model
| Title | arXiv | Github | Website | Pub. Date |
|---|---|---|---|---|
| DynVideo-E: Harnessing Dynamic NeRF for Large-Scale Motion- and View-Change Human-Centric Video Editing | | - | | Oct., 2023 |
| INVE: Interactive Neural Video Editing | | - | | Jul., 2023 |
| Shape-Aware Text-Driven Layered Video Editing | | - | | Jan., 2023 |
Video Understanding


Contributors
(top 30 of 35)


Similar repos



README
A Survey on Video Diffusion Models
Zhen Xing, Qijun Feng, Haoran Chen, Qi Dai, Han Hu, Hang Xu, Zuxuan Wu, Yu-Gang Jiang
(Source: Make-A-Video, SimDA, PYoCo, SVD , Video LDM and Tune-A-Video)
- [News] The updated version is available on arXiv.
- [News] Our survey is accepted by ACM Computing Surveys (CSUR).
- [News] The Chinese translation is available on Zhihu. Special thanks to Dai-Wenxun for this.
Contact
If you have any suggestions or find our work helpful, feel free to contact us
Homepage: Zhen Xing
Email: zhenxingfd@gmail.com
If you find our survey is useful in your research or applications, please consider giving us a star 🌟 and citing it by the following BibTeX entry.
@article{xing2023survey,
  title={A survey on video diffusion models},
  author={Xing, Zhen and Feng, Qijun and Chen, Haoran and Dai, Qi and Hu, Han and Xu, Hang and Wu, Zuxuan and Jiang, Yu-Gang},
  journal={ACM Computing Surveys},
  year={2023},
  publisher={ACM New York, NY}
}
Open-source Toolboxes and Foundation Models
| Methods | Task | Github |
|---|---|---|
| Helios | T2V Generation | |
| Movie Gen | T2V Generation | - |
| CogVideoX | T2V Generation | |
| Open-Sora-Plan | T2V Generation | |
| Open-Sora | T2V Generation | |
| Morph Studio | T2V Generation | - |
| Genie | T2V Generation | - |
| Sora | T2V Generation & Editing | - |
| VideoPoet | T2V Generation & Editing | - |
| Stable Video Diffusion | T2V Generation | |
| NeverEnds | T2V Generation | - |
| Pika | T2V Generation | - |
| EMU-Video | T2V Generation | - |
| GEN-2 | T2V Generation & Editing | - |
| ModelScope | T2V Generation | |
| ZeroScope | T2V Generation | - |
| T2V Synthesis Colab | T2V Genetation | |
| VideoCraft | T2V Genetation & Editing | |
| Diffusers (T2V synthesis) | T2V Genetation | - |
| AnimateDiff | Personalized T2V Genetation | |
| Text2Video-Zero | T2V Genetation | |
| HotShot-XL | T2V Genetation | |
| Genmo | T2V Genetation | - |
| Fliki | T2V Generation | - |
| Seedream AI Studio | Image Generation + I2V Animation | - |
| Omni-Rewriter | Prompt Expansion (Video/Image PE) | |
Table of Contents
Video Generation
Data
Caption-level
| MiniMax H3 1K Prompt Dataset | |
Category-level
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| UCF101: A Dataset of 101 Human Actions Classes From Videos in The Wild | | - | - | Dec., 2012 |
| First Order Motion Model for Image Animation | | - | - | May, 2023 |
| Learning to Generate Time-Lapse Videos Using Multi-Stage Dynamic Generative Adversarial Networks | | - | - | CVPR,2018 |
Metric and BenchMark
Text-to-Video Generation
Training-based
Training-free
Video Generation with other conditions
Pose-guided Video Generation
Motion-guided Video Generation
Sound-guided Video Generation
Image-guided Video Generation
Brain-guided Video Generation
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| NeuroCine: Decoding Vivid Video Sequences from Human Brain Activties | | - | - | Feb., 2024 |
| Cinematic Mindscapes: High-quality Video Reconstruction from Brain Activity | | | | NeurIPS, 2023 |
Depth-guided Video Generation
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| StableV2V: Stablizing Shape Consistency in Video-to-Video Editing | | | | Nov., 2024 |
| Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation | | | | Jul., 2023 |
| Make-Your-Video: Customized Video Generation Using Textual and Structural Guidance | | | | Jun., 2023 |
Multi-modal guided Video Generation
Unconditional Video Generation
U-Net based
| Title | arXiv | Github | WebSite | Pub. & Date |
|---|---|---|---|---|
| Hybrid Video Diffusion Models with 2D Triplane and 3D Wavelet Representation | | | | Feb. 2024 |
| Video Probabilistic Diffusion Models in Projected Latent Space | | | | CVPR 2023 |
| VIDM: Video Implicit Diffusion Models | | | | AAAI 2023 |
| GD-VDM: Generated Depth for better Diffusion-based Video Generation | | | - | Jun., 2023 |
| LEO: Generative Latent Image Animator for Human Video Synthesis | | | | May., 2023 |
Transformer based
Video Completion
Video Enhancement and Restoration
Video Prediction
Video Editing
General Editing Model
Training-free Editing Model
One-shot Editing Model
Instruct-guided Video Editing
Motion-guided Video Editing
Sound-guided Video Editing
| Title | arXiv | Github | Website | Pub. Date |
|---|---|---|---|---|
| Speech Driven Video Editing via an Audio-Conditioned Diffusion Model | | - | - | May., 2023 |
| Soundini: Sound-Guided Diffusion for Natural Video Editing | | | | Apr., 2023 |
Multi-modal Control Editing Model
Domain-specific Editing Model
Non-diffusion Editing model
| Title | arXiv | Github | Website | Pub. Date |
|---|---|---|---|---|
| DynVideo-E: Harnessing Dynamic NeRF for Large-Scale Motion- and View-Change Human-Centric Video Editing | | - | | Oct., 2023 |
| INVE: Interactive Neural Video Editing | | - | | Jul., 2023 |
| Shape-Aware Text-Driven Layered Video Editing | | - | | Jan., 2023 |
Video Understanding
Similar repos
Contributors
(top 30 of 35)