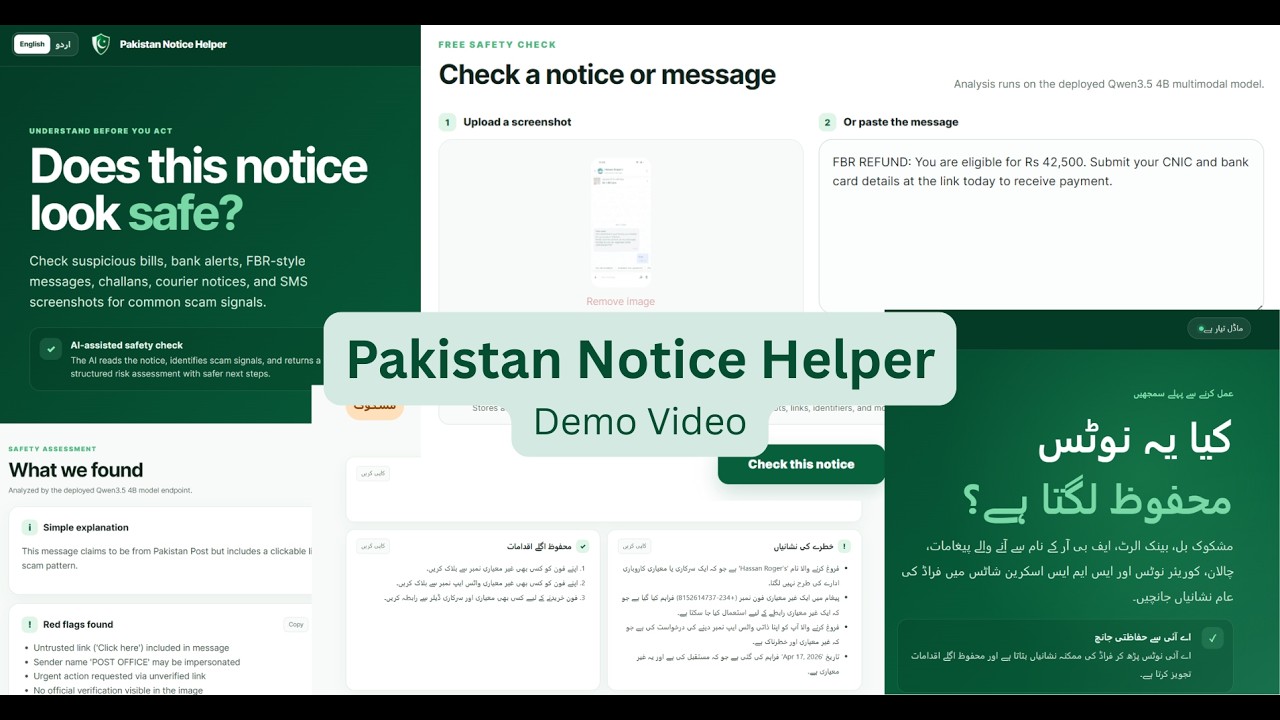
A bilingual, multimodal safety assistant for notices, bills, SMS messages, bank alerts, challans, courier updates, and customs messages.
See the code
Check suspicious Pakistani messages before you trust, pay, or reply.
A bilingual, multimodal safety assistant for notices, bills, SMS messages,
bank alerts, challans, courier updates, and customs messages.


Paste text or upload a screenshot to receive:
| Result | What you get |
|---|---|
| Risk assessment | Looks normal, Verify first, Suspicious, or Likely scam |
| Clear explanation | A simple response in English or Urdu |
| Red flags | The suspicious details that influenced the assessment |
| Safe next steps | Practical actions that avoid risky links and contacts |
| Reply draft | A polite response that does not expose personal information |
The mobile-first interface has a persistent English/Urdu switch. Urdu mode uses a right-to-left layout and asks the live model to answer in Urdu. Roman Urdu and mixed-language inputs are also supported.
[!IMPORTANT]
Pakistan Notice Helper checks common scam signals, but it does not provide official verification, legal advice, or financial advice. Always verify through an official website or helpline before paying or sharing personal information.
This is a Backyard AI submission for the Build Small. Play Big. Hackathon. It applies a small model to a practical regional safety problem.
| Area | Project evidence |
|---|---|
| Core constraints | Public Gradio Space using Qwen3.5-4B, below the 32B limit |
| Backyard AI | A real user tested the phone workflow and plans to use it for future suspicious messages |
| Modal | Qwen3.5-4B is hosted on a Modal L4 GPU endpoint |
| Tiny Titan | The 4B Q8 model passed the final 10-case internal regression suite |
| Llama Champion | Qwen3.5-4B runs through a CUDA-enabled llama.cpp server using its OpenAI-compatible API |
| Off-Brand | Custom mobile-first HTML, CSS, and JavaScript interface served through gradio.Server instead of the default Gradio UI |
| Sharing is Caring | Privacy-safe workflow traces are published as a Hugging Face dataset |
| Field Notes | Published a blog in the Build Small Hackathon organization sharing my opinions, development experience, model experiments, and lessons learned |
The demo includes a real user testing the app on a phone, taking screenshots of messages, and checking them with Pakistan Notice Helper.
The user especially liked the app's speed and the accuracy of its responses. They said they plan to use it in the future to check different scam or suspicious messages.
Text or screenshot
        |
        v
Custom bilingual frontend on gradio.Server
        |
        v
Image preprocessing and structured safety prompt
        |
        v
Qwen3.5-4B Q8_0 MTP on llama.cpp
        |
        v
Modal L4 endpoint
        |
        v
Risk label, explanation, red flags, and safe next steps
Gradio provides queueing, API routes, and Hugging Face Spaces hosting without exposing a default Gradio UI. Live analyses always use the configured model endpoint. There is no heuristic fallback, and endpoint failures are shown explicitly. Bundled English examples are cached; Urdu analyses are generated live.
unsloth/Qwen3.5-4B-MTP-GGUF using Qwen3.5-4B-Q8_0.ggufllama.cpp OpenAI-compatible serverbase_urlThe focused test set covers banking notices, authority impersonation, prize scams, service messages, Urdu text, and screenshots. It is not a claim of general fraud-detection accuracy.
The web app requires the Qwen model endpoint to be deployed and available before it starts.
git clone https://github.com/kingabzpro/pakistan-notice-helper.git
cd pakistan-notice-helper

python -m venv .venv
.\.venv\Scripts\Activate.ps1
pip install -r requirements.txt

modal setup
modal setup opens a browser to authenticate your Modal account and configures
the CLI. This account token is used only to run and deploy Modal code.
modal run model_server.py::download_model
modal deploy model_server.py
The first command downloads Qwen3.5-4B Q8 and its vision projector to a
persistent Modal Volume. The second command deploys the private
OpenAI-compatible llama.cpp server and prints its .modal.run endpoint URL.
The model server uses Modal Proxy Auth. In the Modal Dashboard, open Settings > Proxy Auth Tokens, create a new token, and copy both values:
wk-ws-The secret is shown only once. These proxy credentials are different from the
account token created by modal setup.
Set the credentials in the same terminal that will run the app:
$env:MODAL_PROXY_KEY = "wk-..."
$env:MODAL_PROXY_SECRET = "ws-..."

# Only required if your deployment printed a different endpoint URL:
$env:MODEL_BASE_URL = "https://your-workspace--pakistan-scam-checker-qwen35-4b-q8-serve.modal.run"
$env:MODEL_NAME = "qwen3.5-4b-q8"

python app.py --test-endpoint
python app.py
The endpoint test sends a synthetic notice to the deployed model and verifies the response contract before the UI starts. Never commit proxy credentials.
To use your own OpenAI-compatible llama.cpp server instead of Modal, set
MODEL_BASE_URL, MODEL_NAME, and optionally MODEL_API_KEY. Image analysis
also requires the Qwen vision projector (mmproj-F16.gguf) to be loaded by the
server.
Users can explicitly consent to sharing a minimized workflow trace. Traces may include language, input type, risk label, latency, response length, and a coarse error category.
They do not include raw notice text, OCR text, screenshots, names, phone
numbers, credentials, or full model responses. See
the trace dataset card.
Never rely on a verification link contained inside a suspicious message.
A bilingual, multimodal safety assistant for notices, bills, SMS messages, bank alerts, challans, courier updates, and customs messages.
See the code
Check suspicious Pakistani messages before you trust, pay, or reply.
A bilingual, multimodal safety assistant for notices, bills, SMS messages,
bank alerts, challans, courier updates, and customs messages.
Paste text or upload a screenshot to receive:
| Result | What you get |
|---|---|
| Risk assessment | Looks normal, Verify first, Suspicious, or Likely scam |
| Clear explanation | A simple response in English or Urdu |
| Red flags | The suspicious details that influenced the assessment |
| Safe next steps | Practical actions that avoid risky links and contacts |
| Reply draft | A polite response that does not expose personal information |
The mobile-first interface has a persistent English/Urdu switch. Urdu mode uses a right-to-left layout and asks the live model to answer in Urdu. Roman Urdu and mixed-language inputs are also supported.
[!IMPORTANT]
Pakistan Notice Helper checks common scam signals, but it does not provide official verification, legal advice, or financial advice. Always verify through an official website or helpline before paying or sharing personal information.
This is a Backyard AI submission for the Build Small. Play Big. Hackathon. It applies a small model to a practical regional safety problem.
| Area | Project evidence |
|---|---|
| Core constraints | Public Gradio Space using Qwen3.5-4B, below the 32B limit |
| Backyard AI | A real user tested the phone workflow and plans to use it for future suspicious messages |
| Modal | Qwen3.5-4B is hosted on a Modal L4 GPU endpoint |
| Tiny Titan | The 4B Q8 model passed the final 10-case internal regression suite |
| Llama Champion | Qwen3.5-4B runs through a CUDA-enabled llama.cpp server using its OpenAI-compatible API |
| Off-Brand | Custom mobile-first HTML, CSS, and JavaScript interface served through gradio.Server instead of the default Gradio UI |
| Sharing is Caring | Privacy-safe workflow traces are published as a Hugging Face dataset |
| Field Notes | Published a blog in the Build Small Hackathon organization sharing my opinions, development experience, model experiments, and lessons learned |
The demo includes a real user testing the app on a phone, taking screenshots of messages, and checking them with Pakistan Notice Helper.
The user especially liked the app's speed and the accuracy of its responses. They said they plan to use it in the future to check different scam or suspicious messages.
Text or screenshot
        |
        v
Custom bilingual frontend on gradio.Server
        |
        v
Image preprocessing and structured safety prompt
        |
        v
Qwen3.5-4B Q8_0 MTP on llama.cpp
        |
        v
Modal L4 endpoint
        |
        v
Risk label, explanation, red flags, and safe next steps
Gradio provides queueing, API routes, and Hugging Face Spaces hosting without exposing a default Gradio UI. Live analyses always use the configured model endpoint. There is no heuristic fallback, and endpoint failures are shown explicitly. Bundled English examples are cached; Urdu analyses are generated live.
unsloth/Qwen3.5-4B-MTP-GGUF using Qwen3.5-4B-Q8_0.ggufllama.cpp OpenAI-compatible serverbase_urlThe focused test set covers banking notices, authority impersonation, prize scams, service messages, Urdu text, and screenshots. It is not a claim of general fraud-detection accuracy.
The web app requires the Qwen model endpoint to be deployed and available before it starts.
git clone https://github.com/kingabzpro/pakistan-notice-helper.git
cd pakistan-notice-helper

python -m venv .venv
.\.venv\Scripts\Activate.ps1
pip install -r requirements.txt

modal setup
modal setup opens a browser to authenticate your Modal account and configures
the CLI. This account token is used only to run and deploy Modal code.
modal run model_server.py::download_model
modal deploy model_server.py
The first command downloads Qwen3.5-4B Q8 and its vision projector to a
persistent Modal Volume. The second command deploys the private
OpenAI-compatible llama.cpp server and prints its .modal.run endpoint URL.
The model server uses Modal Proxy Auth. In the Modal Dashboard, open Settings > Proxy Auth Tokens, create a new token, and copy both values:
wk-ws-The secret is shown only once. These proxy credentials are different from the
account token created by modal setup.
Set the credentials in the same terminal that will run the app:
$env:MODAL_PROXY_KEY = "wk-..."
$env:MODAL_PROXY_SECRET = "ws-..."

# Only required if your deployment printed a different endpoint URL:
$env:MODEL_BASE_URL = "https://your-workspace--pakistan-scam-checker-qwen35-4b-q8-serve.modal.run"
$env:MODEL_NAME = "qwen3.5-4b-q8"

python app.py --test-endpoint
python app.py
The endpoint test sends a synthetic notice to the deployed model and verifies the response contract before the UI starts. Never commit proxy credentials.
To use your own OpenAI-compatible llama.cpp server instead of Modal, set
MODEL_BASE_URL, MODEL_NAME, and optionally MODEL_API_KEY. Image analysis
also requires the Qwen vision projector (mmproj-F16.gguf) to be loaded by the
server.
Users can explicitly consent to sharing a minimized workflow trace. Traces may include language, input type, risk label, latency, response length, and a coarse error category.
They do not include raw notice text, OCR text, screenshots, names, phone
numbers, credentials, or full model responses. See
the trace dataset card.
Never rely on a verification link contained inside a suspicious message.