
Visual catalog of omni, speech and audio language models with public code and weights, short descriptions, architecture figures, license labels and VoiceBench coverage.
Python
14
9 commits
updated Sep 13, 2026
README
Awesome Omni Architectures 
A visual catalog of omni, speech and audio language models with public code and weights. Every entry has a short description, a diagram, code and checkpoint links.
140 models + 4 cascaded systems · Reviewed 2026-09-13
Model list · All diagrams · VoiceBench coverage · Research · Timeline · Scope
Licenses: 68 open · 48 custom/restricted · 28 unclear. Downloadable weights do not always mean an unrestricted open-source license; each card shows the applicable terms.
| Collection | Entries |
|---|---|
| Omni and audio-visual models | 44 |
| Speech dialogue models | 42 |
| Audio understanding models | 45 |
| Speech recognition language models | 9 |
| VoiceBench cascaded systems | 4 |
Models
T: text · I: image · V: video · A: audio · S: speech · M: music · X: other. Scope and labels.
Alphabetical model list · 144 entries
| Model | Group | Input → output | Release |
|---|---|---|---|
| AnyGPT | Omni | T, I, S, M → T, I, S, M | License unclear |
| Audio Flamingo | Audio | T, A → T | Custom / restricted |
| Audio Flamingo 2 | Audio | T, A → T | Custom / restricted |
| Audio Flamingo 3 Chat | Speech | T, A → T, S | Custom / restricted |
| Audio Flamingo Next | Audio | T, A → T | Custom / restricted |
| Audio-Interaction | Audio | T, A → T | License unclear |
| Audio-Reasoner | Audio | T, A → T | Open license |
| Audio-Visual Flamingo | Omni | T, I, V, A → T | Custom / restricted |
| AzeroS | Audio | T, S → T | Open license |
| Baichuan-Audio | Speech | T, A → T, S | Open license |
| Baichuan-Omni 1.5 | Omni | T, I, V, A → T, S | Custom / restricted |
| BLSP-Emo | Audio | T, S → T | Custom / restricted |
| BR-Voice-Reasoner | Omni | T, I, V, A → T | Open license |
| Canary-Qwen | LLM-ASR | T, S → T | Open license |
| Covo-Audio Chat | Speech | T, S → T, S | Custom / restricted |
| DeSTA2 | Audio | T, A → T | License unclear |
| DeSTA2.5-Audio | Audio | T, A → T | License unclear |
| DialectS2S | Speech | T, S → T, S | Open license |
| DIFFA | Audio | T, A → T | License unclear |
| DIFFA-2 | Audio | T, A → T | License unclear |
| DiVA | Audio | T, S → T | Custom / restricted |
| DuplexCascade | Speech | T, S → T, S | Open license |
| DuplexMamba | Audio | T, S → T | Open license |
| EMOVA (Qwen2.5-7B) | Omni | T, I, S → T, S | Open license |
| Freeze-Omni | Speech | T, S → T, S | Custom / restricted |
| Fun-Audio-Chat | Speech | T, S → T, S | Open license |
| Gemma 3n E4B | Omni | T, I, V, A → T | Custom / restricted |
| Gemma 4 E4B | Omni | T, I, V, A → T | Open license |
| GLM-4-Voice | Speech | T, S → T, S | Custom / restricted |
| GLM-ASR Nano | LLM-ASR | S → T | Open license |
| Granite Speech 3.3 | LLM-ASR | T, S → T | Open license |
| Granite Speech 4.0 | LLM-ASR | T, S → T | Open license |
| Granite Speech 4.1 | LLM-ASR | T, S → T | Open license |
| Hibiki | Speech | T, S → T, S | Open license |
| HumanOmni | Omni | T, V, A → T | License unclear |
| HumanOmniV2 | Omni | T, V, A → T | Open license |
| Ichigo | Audio | T, S → T | License unclear |
| Kimi-Audio | Speech | T, A → T, S | Open license |
| LFG-1 | Omni | T, I, S → T | Open license |
| LFG-2 | Audio | T, S → T | License unclear |
| LFG-3 | Audio | T, S → T | License unclear |
| LFM2-Audio-1.5B | Speech | T, S → T, S | Custom / restricted |
| LFM2.5-Audio-1.5B | Speech | T, S → T, S | Custom / restricted |
| LFM2.5-Audio-1.5B-JP | Speech | T, S → T, S | Custom / restricted |
| LLaMA-Omni | Speech | T, S → T, S | Custom / restricted |
| LLaMA-Omni 2 | Speech | T, S → T, S | Custom / restricted |
| LLaSM | Audio | T, S → T | Custom / restricted |
| LongCat-Flash-Omni | Omni | T, I, V, A → T, S | Open license |
| LongCat-Next | Omni | T, I, A → T, I, A | Open license |
| Lychee-FD | Speech | T, S → T, S | Open license |
| Lyra-Base | Omni | T, I, V, A → T, S | Custom / restricted |
| Lyra-Mini | Omni | T, I, V, A → T, S | Custom / restricted |
| Mair-hub-0.5B-Omni | Speech | T, S → T, S | License unclear |
| Megrez-Omni | Omni | T, I, A → T | Open license |
| Mellow | Audio | T, A → T | Open license |
| MERaLiON 2 | Audio | T, A → T | Custom / restricted |
| MERaLiON 3 | Audio | T, S → T | Custom / restricted |
| MERaLiON 3 ASR | LLM-ASR | S → T | Custom / restricted |
| MERaLiON-AudioLLM | Audio | T, A → T | Custom / restricted |
| MiDashengLM | Audio | T, A → T | License unclear |
| MiMo-Audio | Speech | T, A → T, S | Open license |
| MiMo-V2.5 | Omni | T, I, V, A → T | Open license |
| Ming-Flash-Omni | Omni | T, I, V, A → T, I, A | Open license |
| Ming-Flash-Omni 2.0 | Omni | T, I, V, A → T, I, A | Open license |
| Ming-Lite-Omni | Omni | T, I, V, A → T, I, S | Open license |
| Mini-Omni | Speech | T, S → T, S | Open license |
| Mini-Omni2 | Omni | T, I, S → T, S | Open license |
| MiniCPM-o 2.6 | Omni | T, I, V, A → T, S | Open license |
| MiniCPM-o 4.5 | Omni | T, I, V, A → T, S | Open license |
| MiniMind-O | Omni | T, I, S → T, S | Open license |
| MIO | Omni | T, I, V, A → T, I, S | License unclear |
| Moshi | Speech | T, S → T, S | Open license |
| MOSS-Audio Instruct | Audio | T, A → T | License unclear |
| MOSS-Audio Thinking | Audio | T, A → T | License unclear |
| MOSS-Speech | Speech | S → S | License unclear |
| Music Flamingo | Audio | T, M → T | Custom / restricted |
| Nemotron 3 Nano Omni | Omni | T, I, V, A → T | Custom / restricted |
| Nemotron-Labs-Audex 2B | Speech | T, A → T, A | License unclear |
| Nemotron-Labs-Audex 30B-A3B | Speech | T, A → T, A | License unclear |
| NemotronLabs VoiceChat 11B | Speech | T, S → T, S | Open license |
| NExT-GPT | Omni | T, I, V, A → T, I, V, A | Custom / restricted |
| Nexus-O | Omni | T, I, V, A → T, S | Custom / restricted |
| Ola | Omni | T, I, V, A → T | Open license |
| Omni-AutoThink | Omni | T, I, V, A → T | Open license |
| Omni-R1 (audio reasoning) | Audio | T, A → T | License unclear |
| Omni-R1 (two-system collaboration) | Omni | T, I, V, A → T | License unclear |
| OmniVinci | Omni | T, I, V, A → T | Custom / restricted |
| OneLLM | Omni | T, I, V, A → T | Custom / restricted |
| OpenOmni | Omni | T, I, V, A → T, S | License unclear |
| OpenS2S | Speech | T, S → T, S | Open license |
| OpenS2S 1.5 | Speech | T, S → T, S | Open license |
| OSUM | Audio | T, S → T | Open license |
| OSUM-EChat | Speech | T, S → T, S | Open license |
| ParaBridge | Audio | T, A → T | Open license |
| Parakeet-TDT-v2 + Qwen3-8B | Cascade | S → T | Open license |
| PersonaPlex | Speech | T, S → T, S | Custom / restricted |
| Phi-4-multimodal | Omni | T, I, A → T | Open license |
| Qwen-Audio | Audio | T, A → T | Custom / restricted |
| Qwen2-Audio | Audio | T, A → T | Open license |
| Qwen2.5-Omni | Omni | T, I, V, A → T, S | Open license |
| Qwen3-ASR | LLM-ASR | T, S → T | Open license |
| Qwen3-Omni Instruct | Omni | T, I, V, A → T, S | Open license |
| Qwen3-Omni Thinking | Omni | T, I, V, A → T | Open license |
| R1-Omni | Omni | T, V, A → T | License unclear |
| SALMONN | Audio | T, A → T | Custom / restricted |
| SALMONN-2 | Audio | T, A → T | Open license |
| SLAM-Omni | Speech | T, S → T, S | Open license |
| SoulX-Duplug | Audio | T, S → T | Open license |
| SpeechGPT | Speech | T, S → T, S | License unclear |
| SpeechGPT 2.0 Preview | Speech | T, S → T, S | License unclear |
| Step-Audio | Speech | T, A → T, S | Open license |
| Step-Audio 2 Mini | Speech | T, A → T, S | Open license |
| Step-Audio 2 Mini Think | Audio | T, A → T | Open license |
| Step-Audio-AQAA | Speech | T, A → T, S | Open license |
| Step-Audio-R1 | Audio | T, A → T | Open license |
| Step-Audio-R1.1 | Speech | T, A → T, S | Open license |
| Stream-Omni | Omni | T, I, S → T, S | Custom / restricted |
| Sympatheia | Speech | T, S → T, S | License unclear |
| TurnGuide | Speech | T, S → T, S | License unclear |
| Ultravox 0.4.1 Llama-3.1-8B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.5 Llama-3.1-8B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.5 Llama-3.2-1B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Gemma-3-27B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Llama-3.1-8B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Llama-3.3-70B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Qwen3-32B | Audio | T, S → T | Open license |
| Ultravox 0.7 GLM-4.6 | Audio | T, S → T | Open license |
| Uni-MoE 2.0 Omni | Omni | T, I, V, A → T, I, A | License unclear |
| VibeVoice-ASR | LLM-ASR | T, S → T | Open license |
| video-SALMONN 2+ (7B) | Omni | T, V, A → T | Open license |
| VideoLLaMA 2.1 AV | Omni | T, I, V, A → T | Custom / restricted |
| VITA 1.0 | Omni | T, I, V, A → T | Custom / restricted |
| VITA 1.5 | Omni | T, I, V, A → T, S | Custom / restricted |
| VITA-Audio | Speech | T, S → T, S | Custom / restricted |
| VITA-Audio Plus | Speech | T, S → T, S | Custom / restricted |
| Voila Autonomous | Speech | T, S → T, S | Open license |
| Voila Chat | Speech | T, S → T, S | Open license |
| VoxMind | Speech | T, S → T, S | License unclear |
| Voxtral Mini | Audio | T, A → T | Open license |
| Voxtral Realtime | LLM-ASR | S → T | Open license |
| Voxtral Small | Audio | T, A → T | Open license |
| Whisper-v3-large + Llama-3.1-8B | Cascade | S → T | Custom / restricted |
| Whisper-v3-turbo + Llama-3.1-8B | Cascade | S → T | Custom / restricted |
| Whisper-v3-turbo + Llama-3.2-3B | Cascade | S → T | Custom / restricted |
Model figures
Figures are credited to their sources. Editorial input/output diagrams are labeled. Credits.
AnyGPT
Understands and generates text, images, speech and music using a shared token vocabulary.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 + Llama 2 terms — Base-model community terms also apply; repository-wide code licensing is not stated.
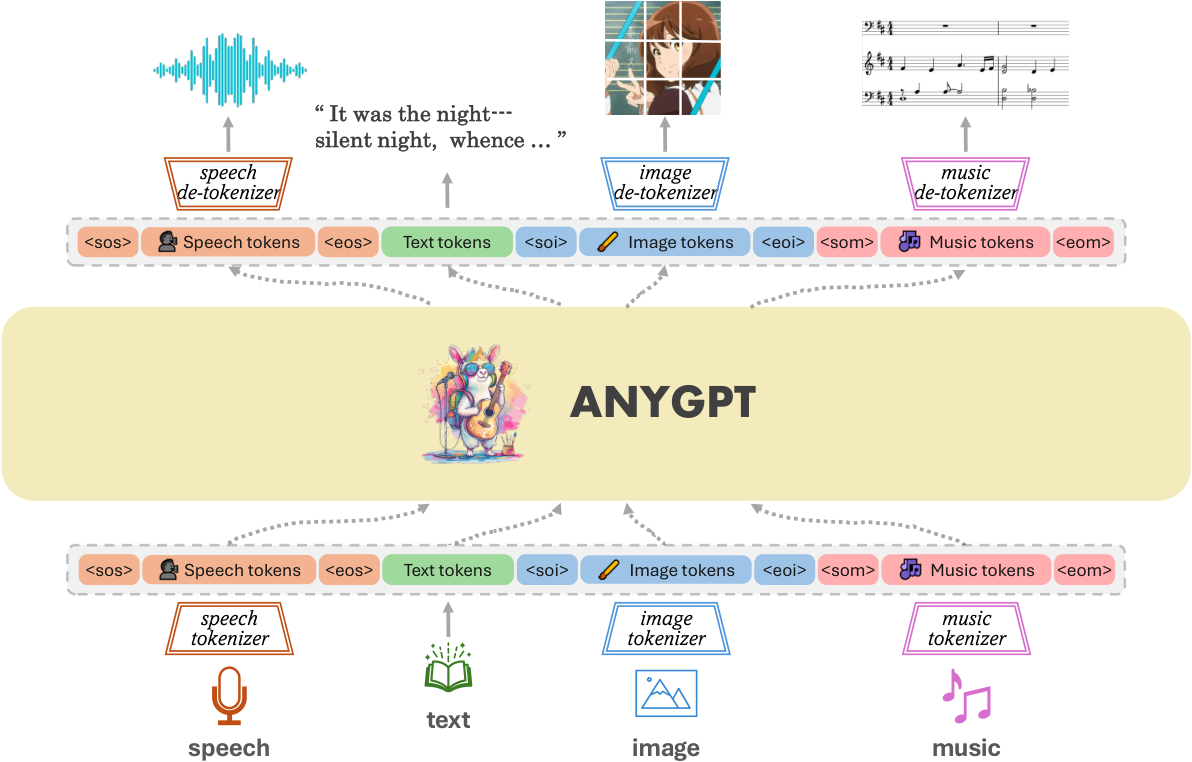
Figure 1 · Source
Audio Flamingo
Answers questions about sounds and music and supports audio-grounded dialogue and examples.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights OPT-IML noncommercial license — Noncommercial terms apply to model weights and relevant bundled components.
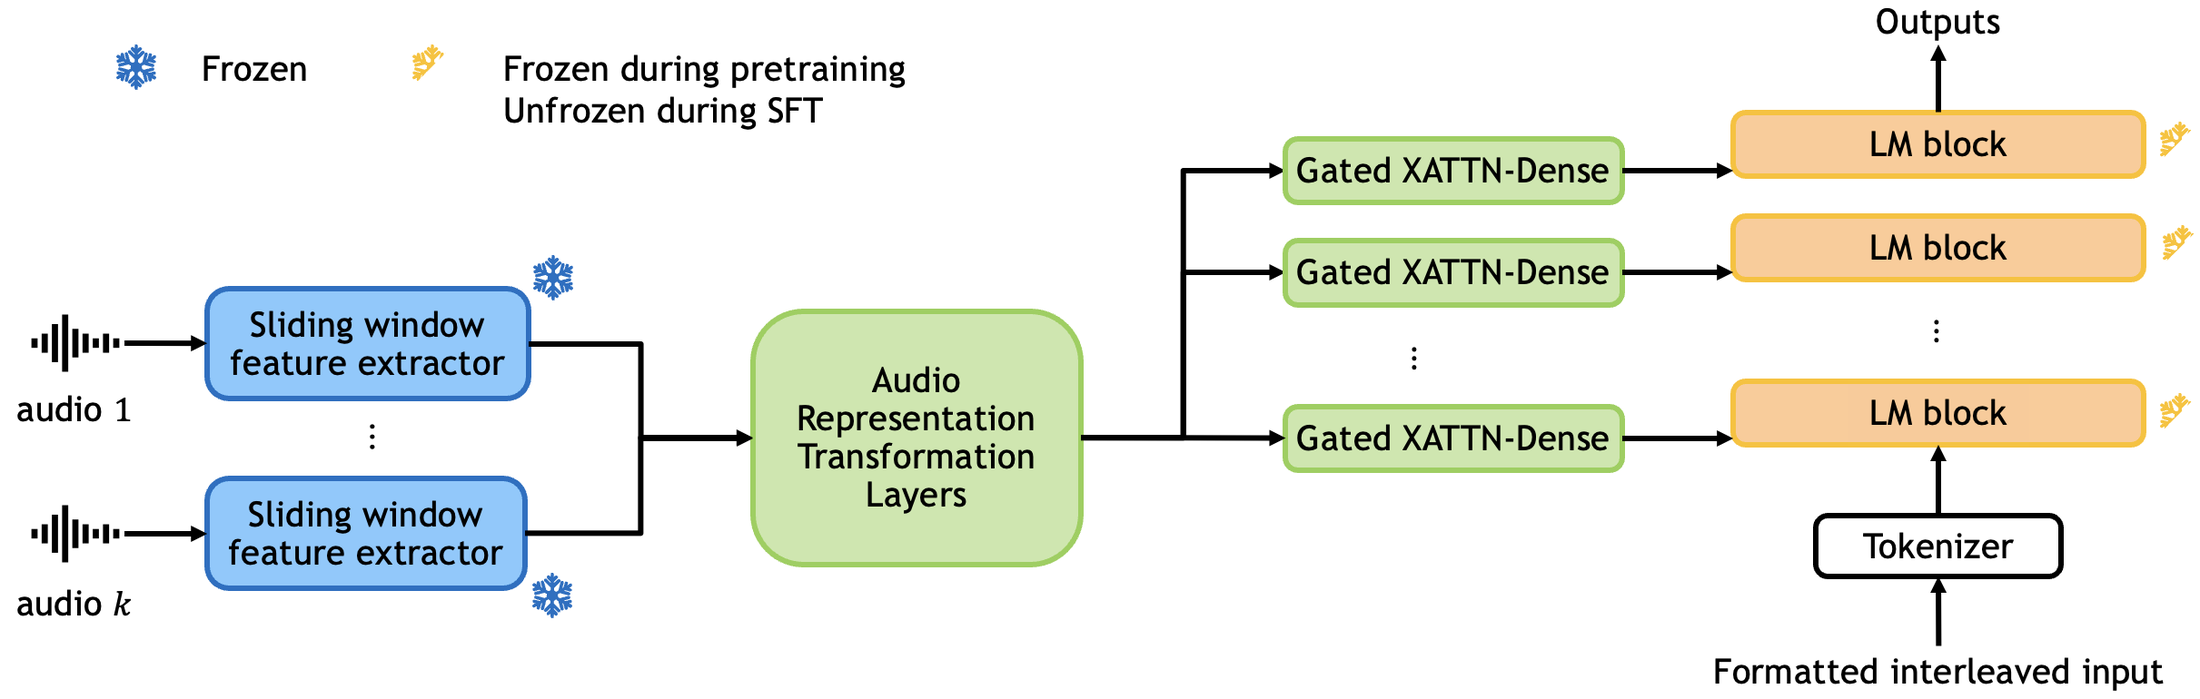
Figure 2 · Source
Audio Flamingo 2
Reasons about environmental sounds and music, including long recordings.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
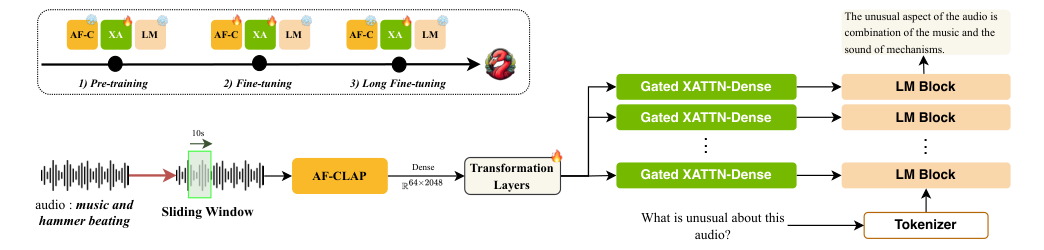
Figure 2 · Source
Audio Flamingo 3 Chat
Discusses speech, sounds and music across multiple recordings and can reply with streaming speech.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
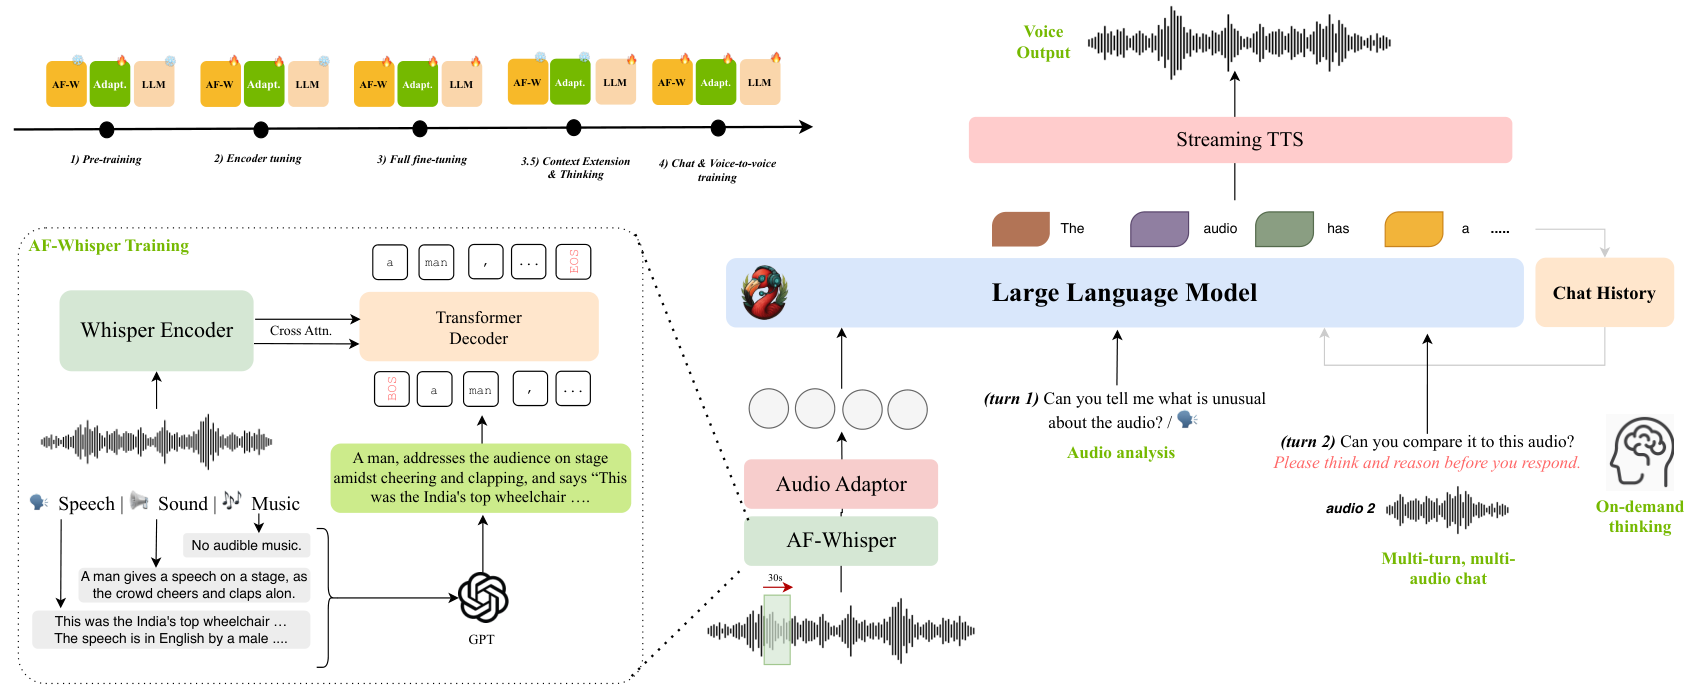
Figure 2 · Source
Audio Flamingo Next
Analyzes long audio recordings and reasons about speech, sounds and music.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
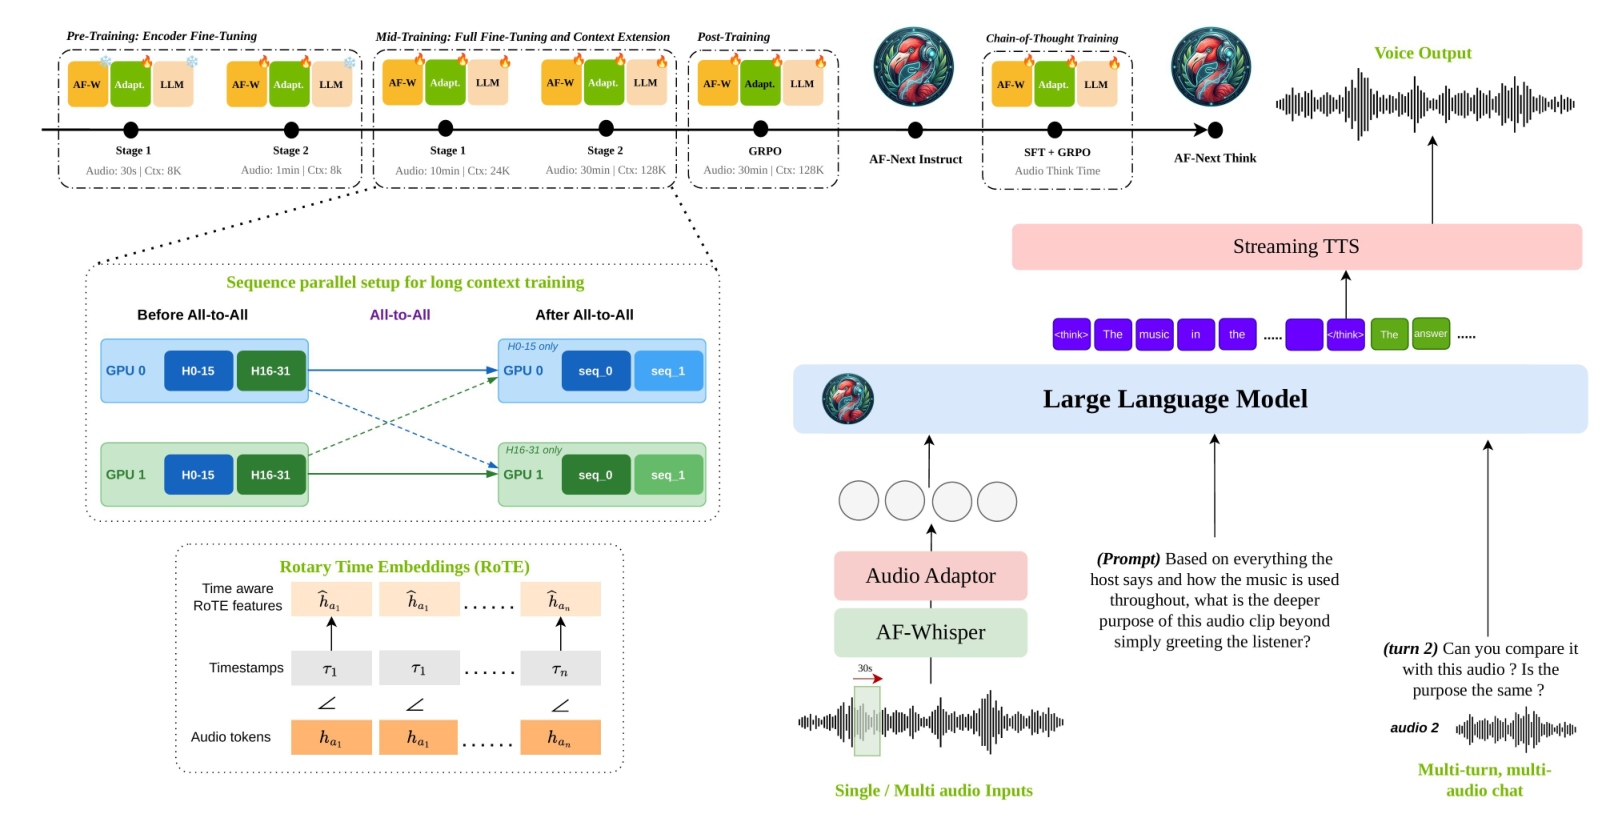
Figure 3 · Source
Audio-Interaction
Monitors an ongoing audio stream and decides when a text response or proactive intervention is useful.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
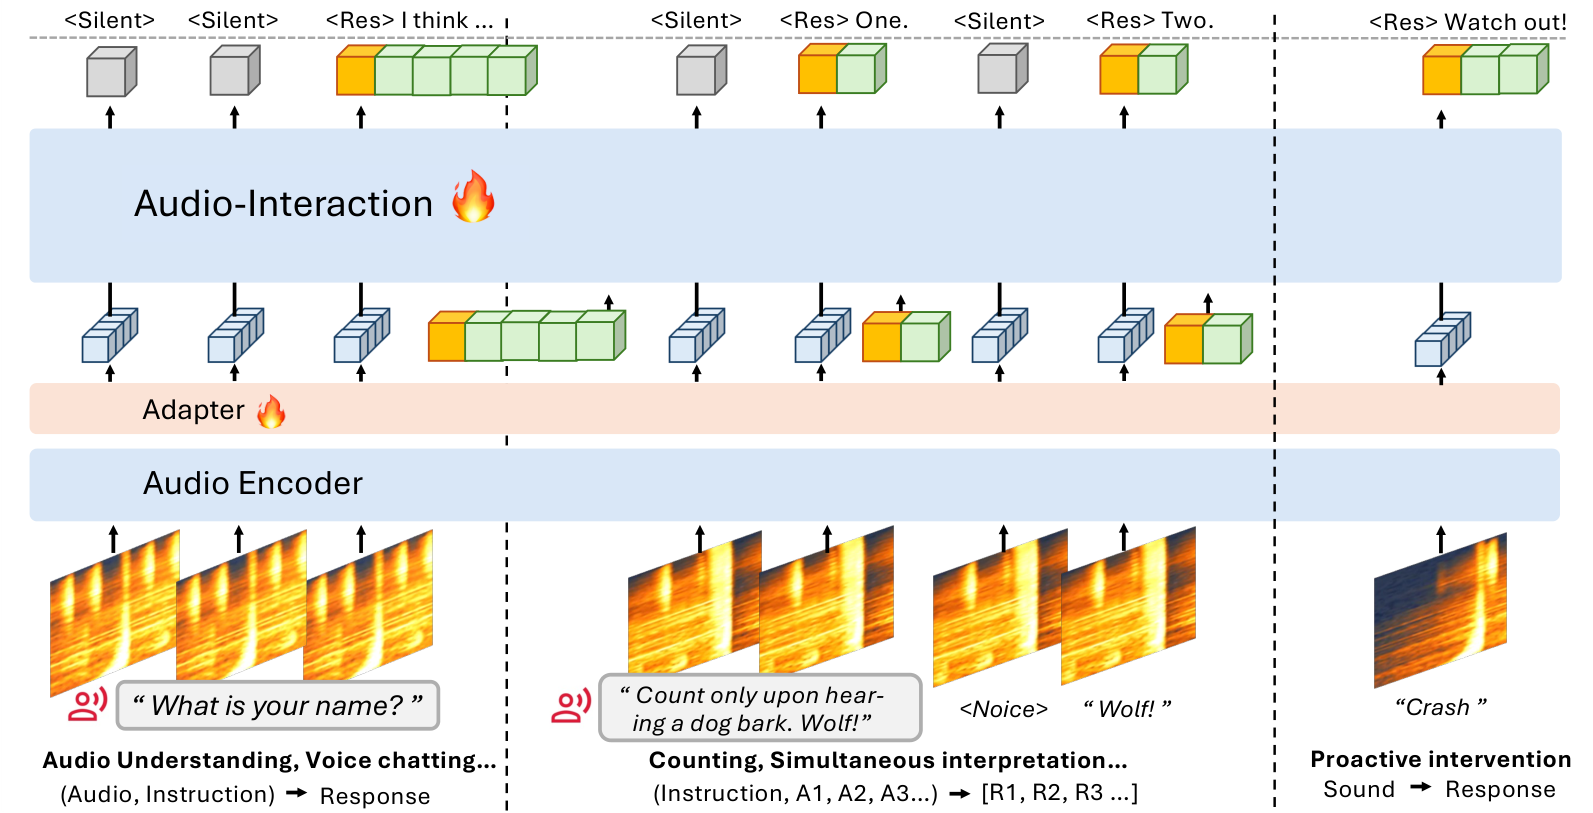
Figure 3 · Source
Audio-Reasoner
Reasons about speech, music and environmental sounds to answer complex audio questions.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
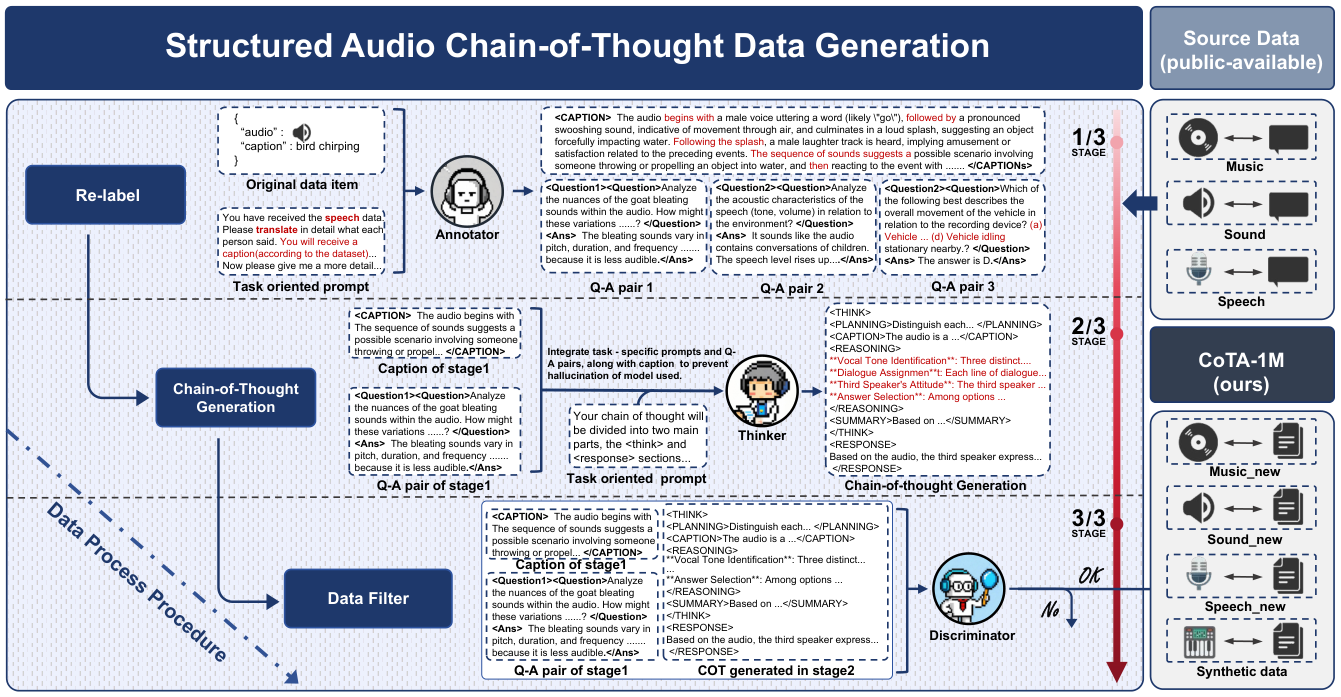
Figure 3 · Source
Audio-Visual Flamingo
Explains long videos by reasoning jointly about visual events and their soundtracks.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
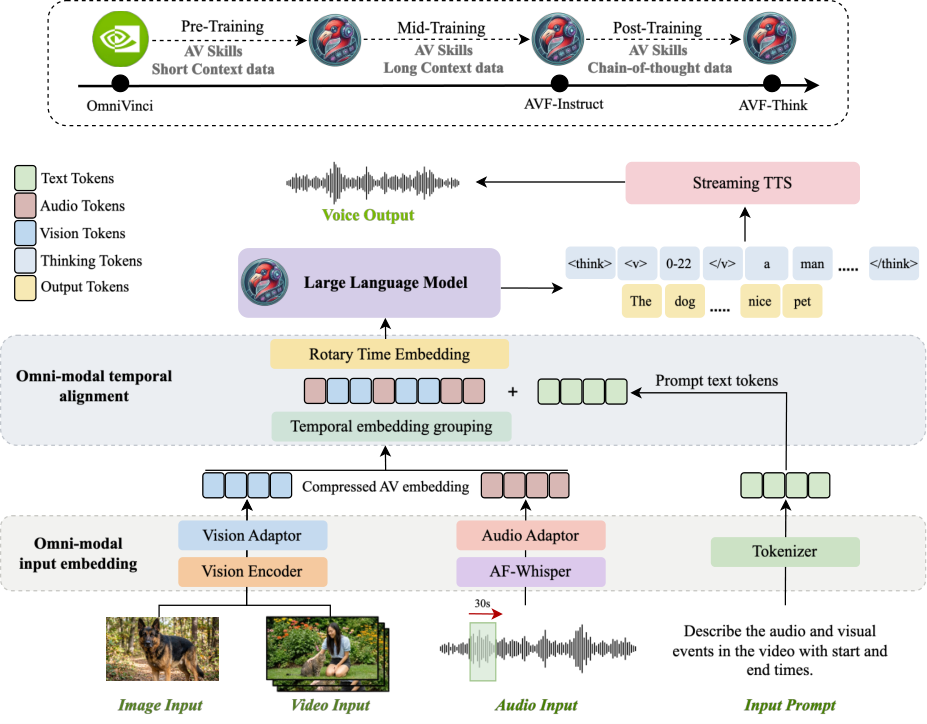
Figure 2 · Source
AzeroS
Follows spoken instructions using speech adaptation learned without curated instruction-answer pairs.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
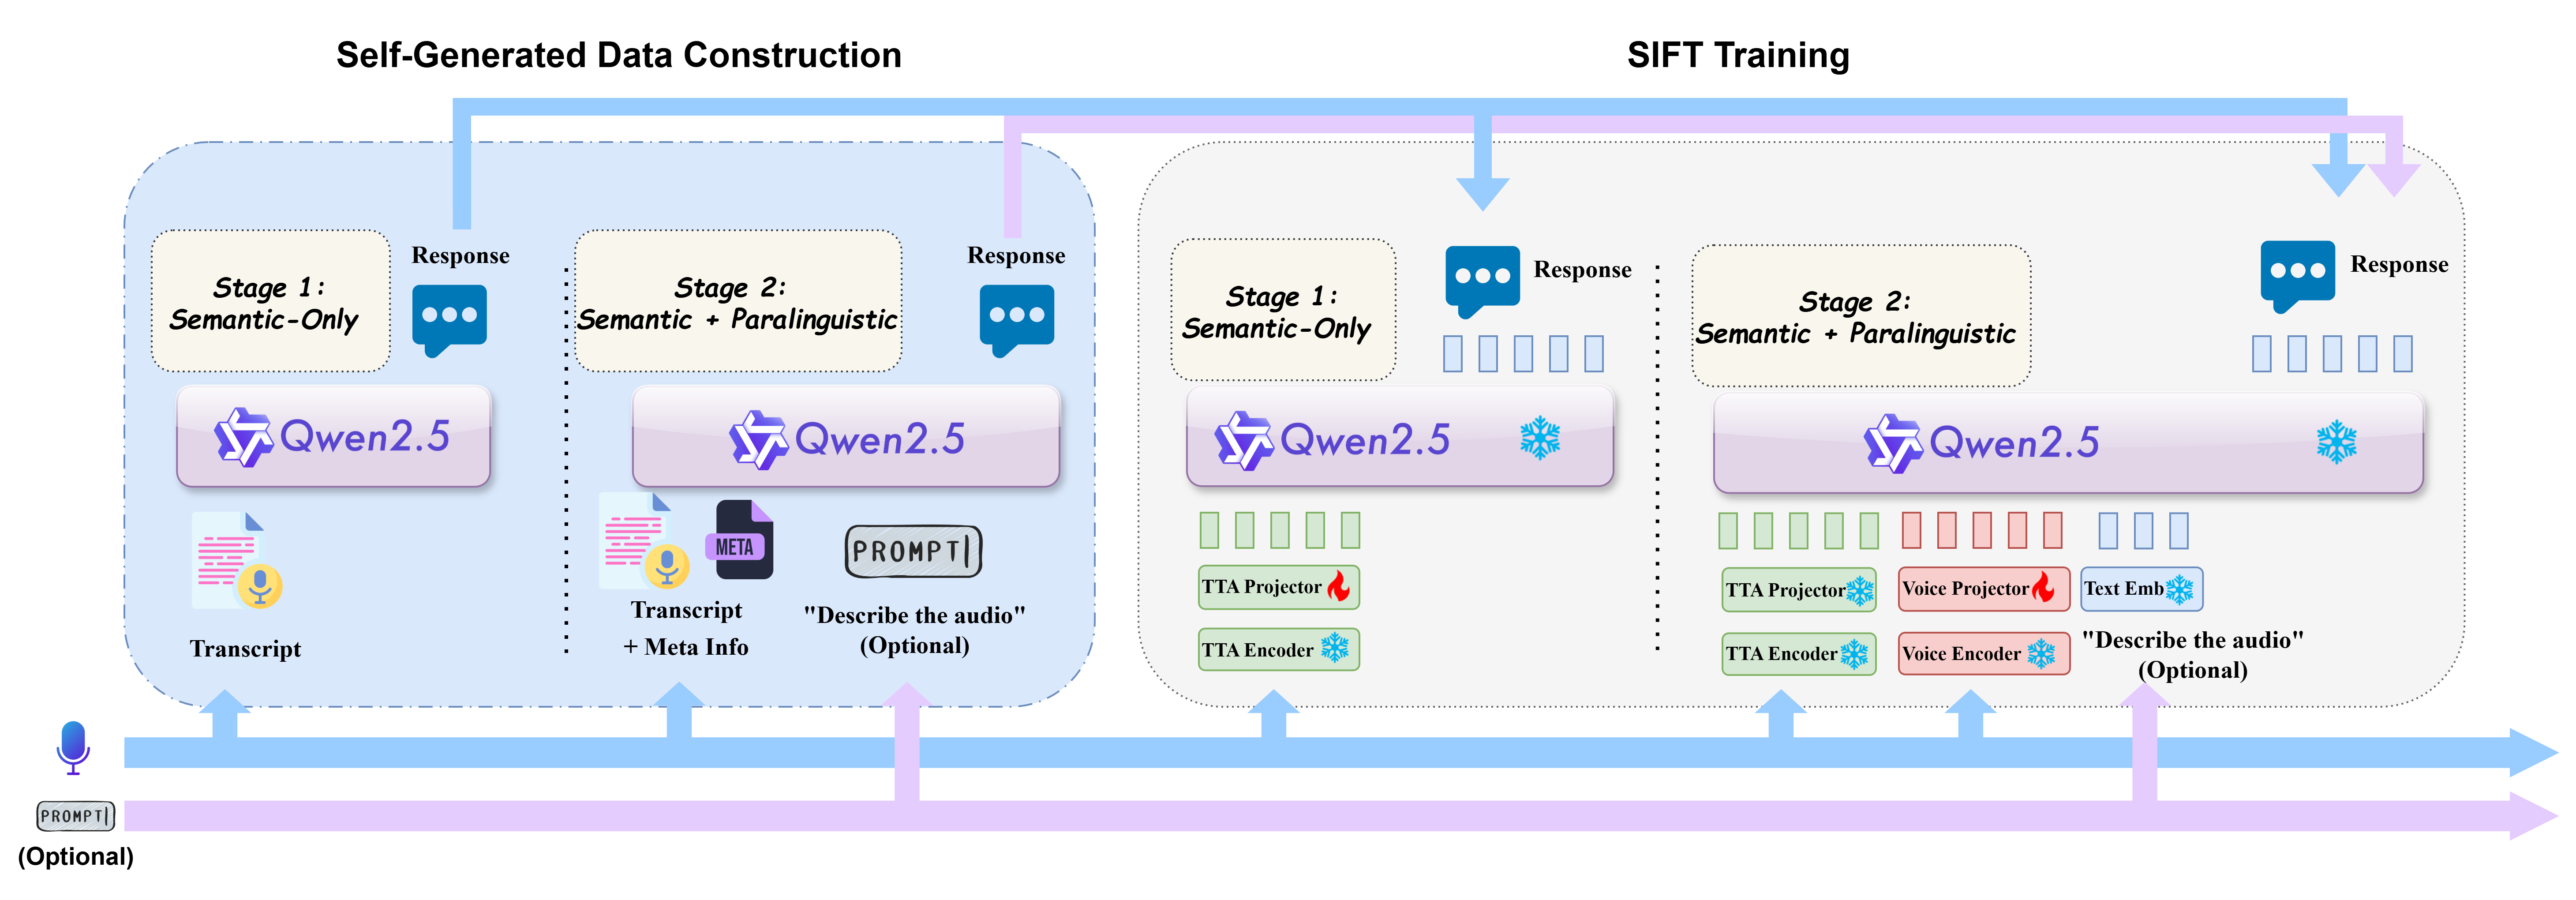
Figure 1 · Source
Baichuan-Audio
Follows spoken instructions and generates text and expressive speech responses.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
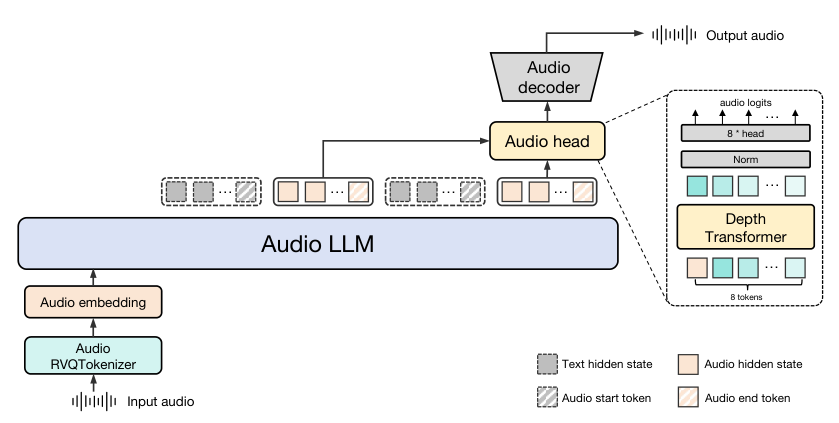
Figure 1 · Source
Baichuan-Omni 1.5
Understands images, video and sound and answers through text or speech.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Baichuan model terms — The model card adds commercial-use conditions beyond its Apache metadata.
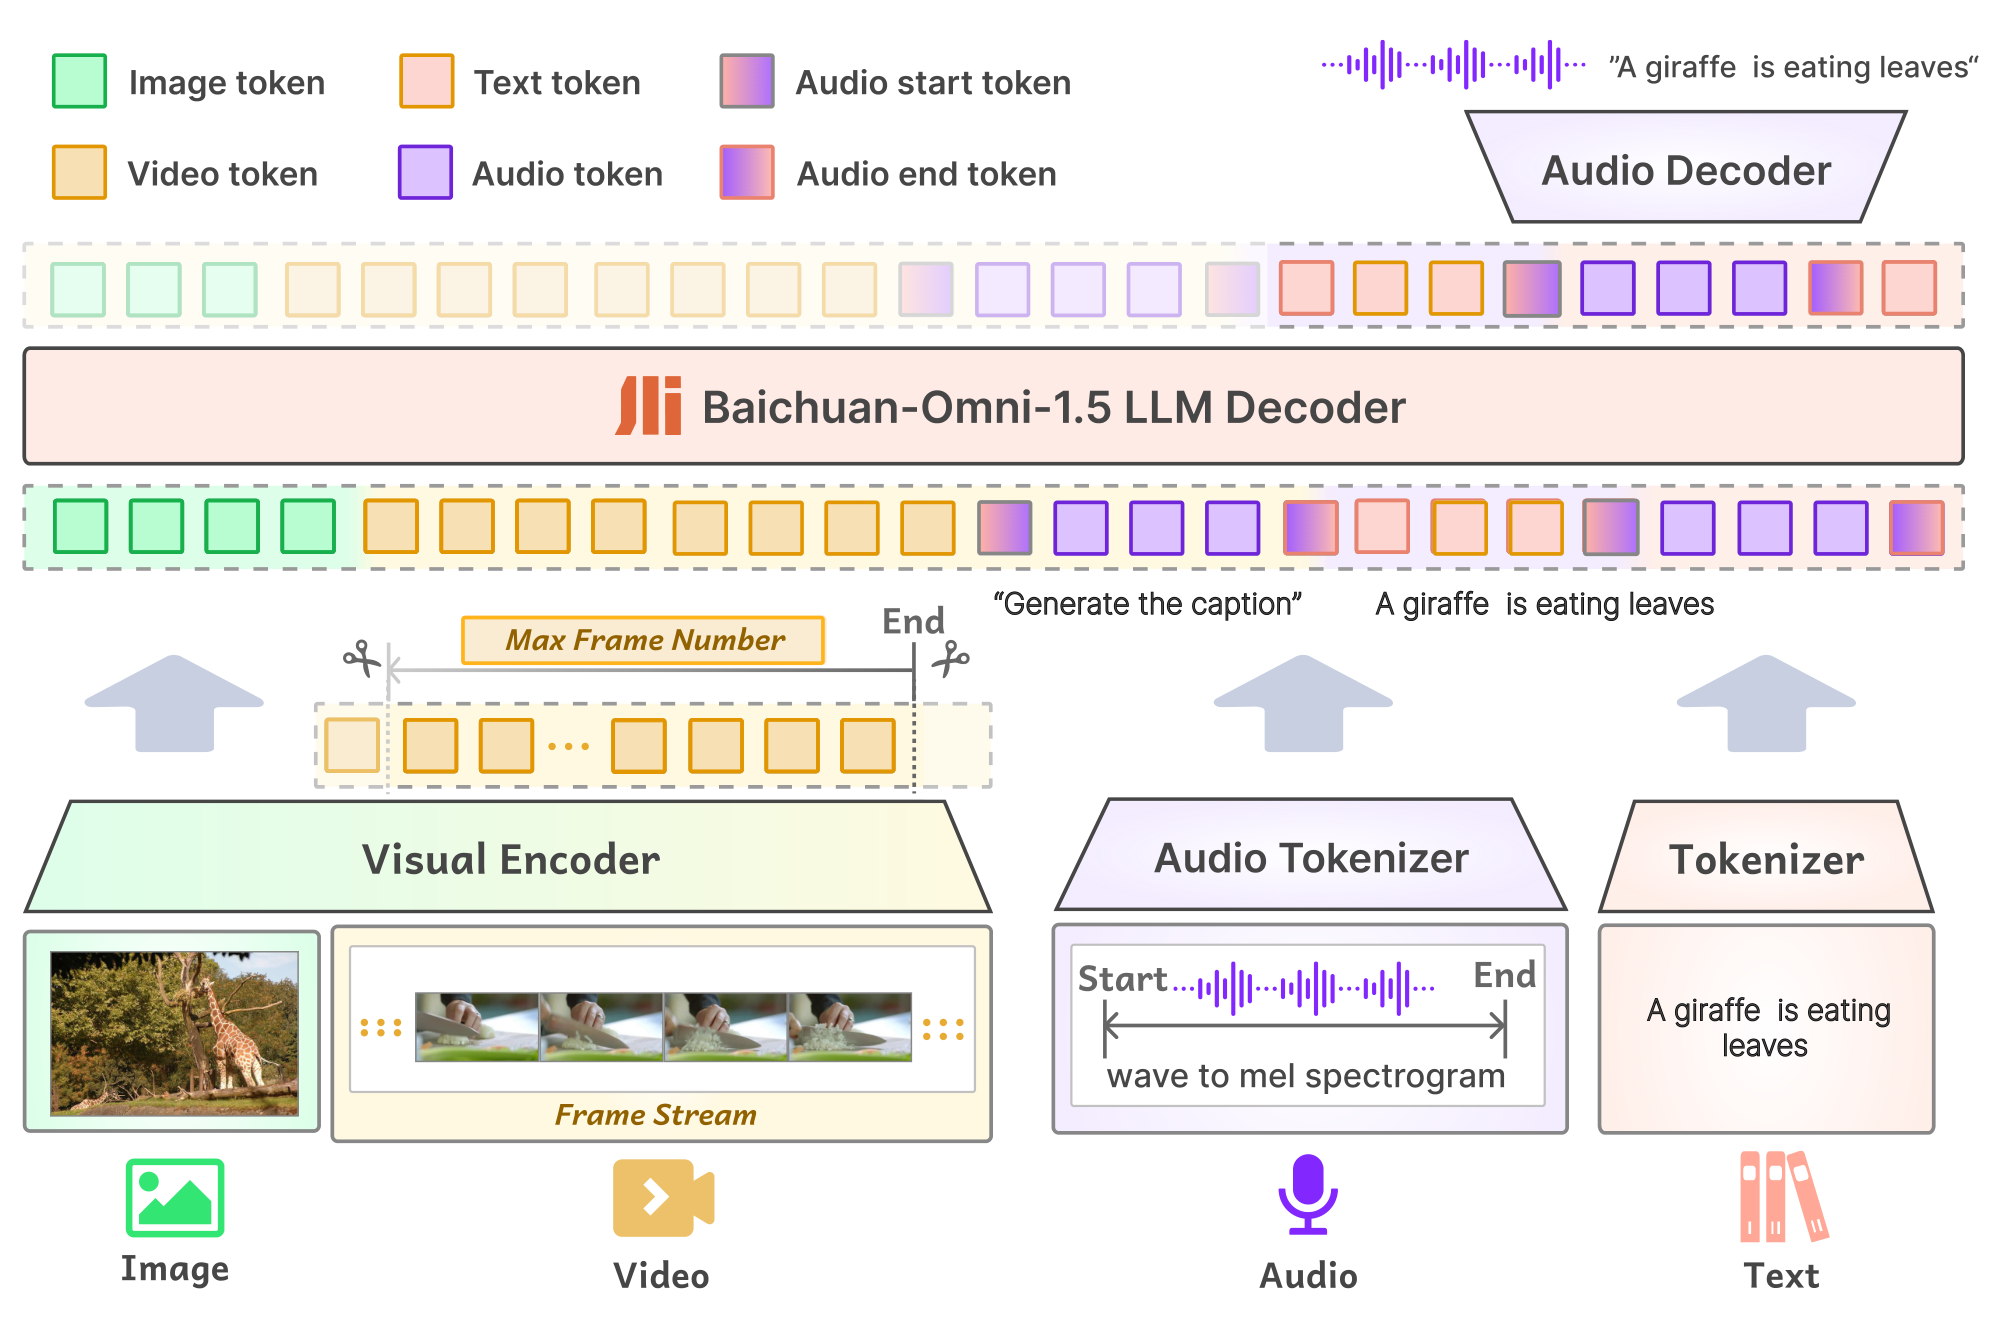
Figure 2 · Source
BLSP-Emo
Understands vocal emotion and writes empathetic responses to spoken requests.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Apache-2.0 + Qwen terms — The Qwen-7B-Chat backbone retains its custom license.
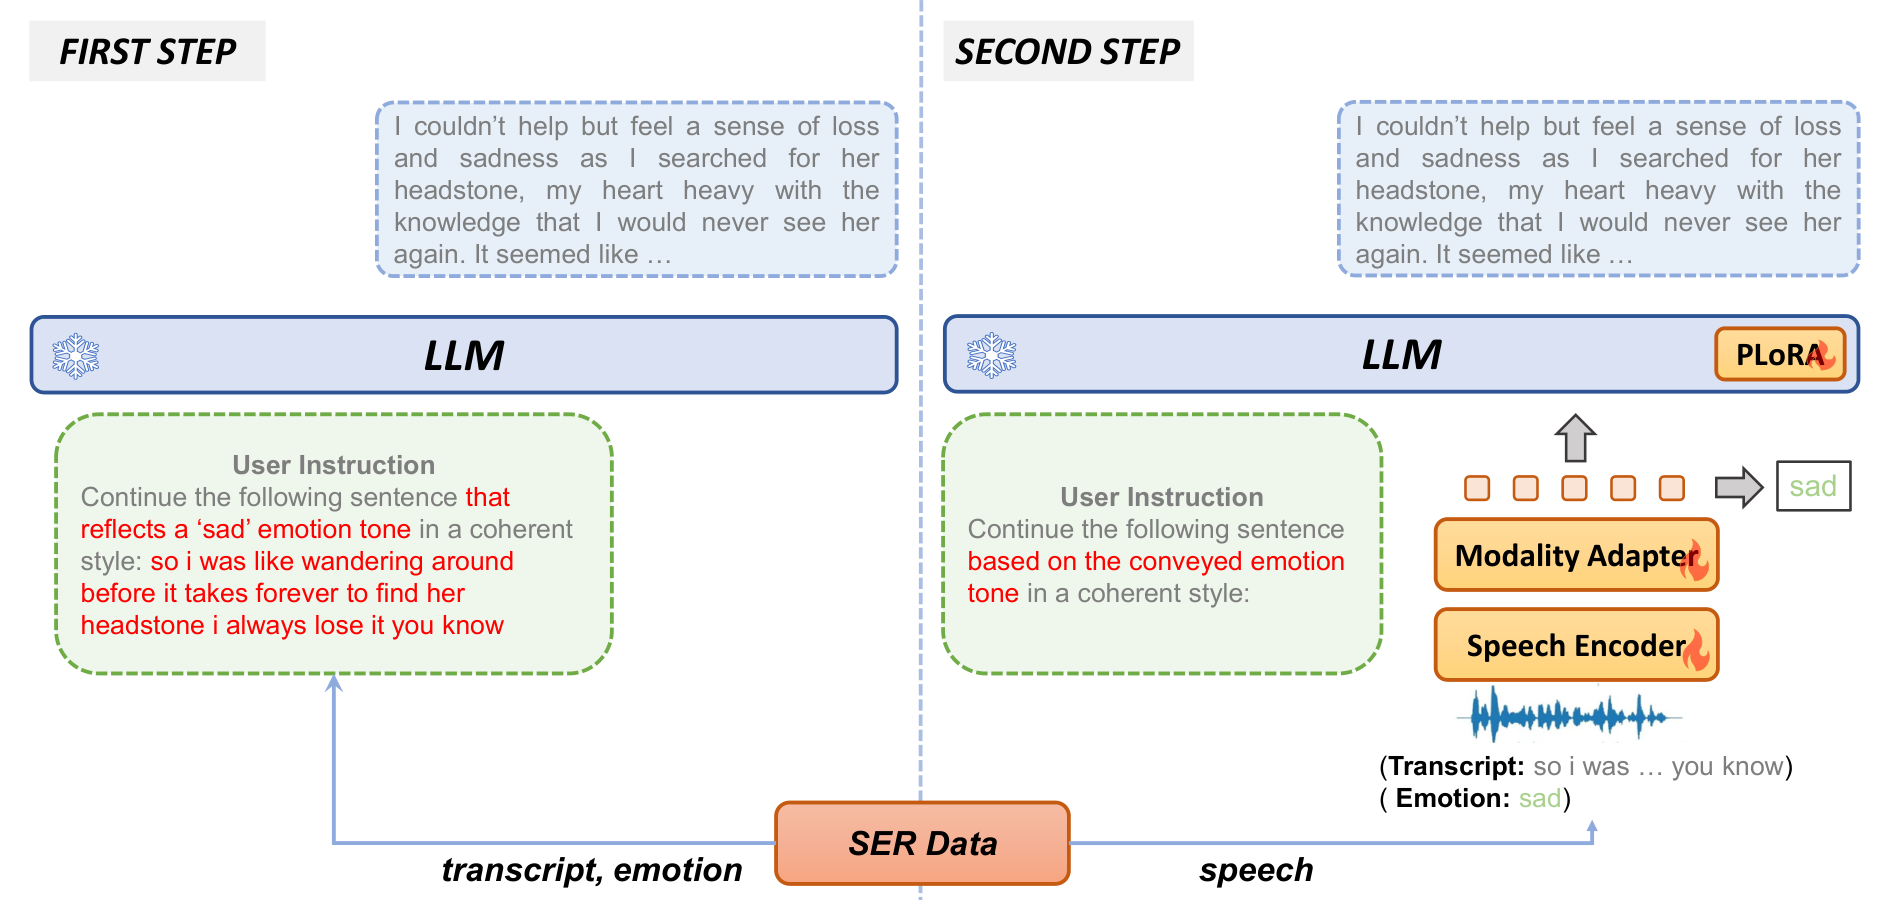
Figure 2 · Source
BR-Voice-Reasoner
Answers spoken knowledge and reasoning questions using a speech-adapted Qwen3-Omni Thinker.
Open license: code Apache-2.0 · weights Apache-2.0
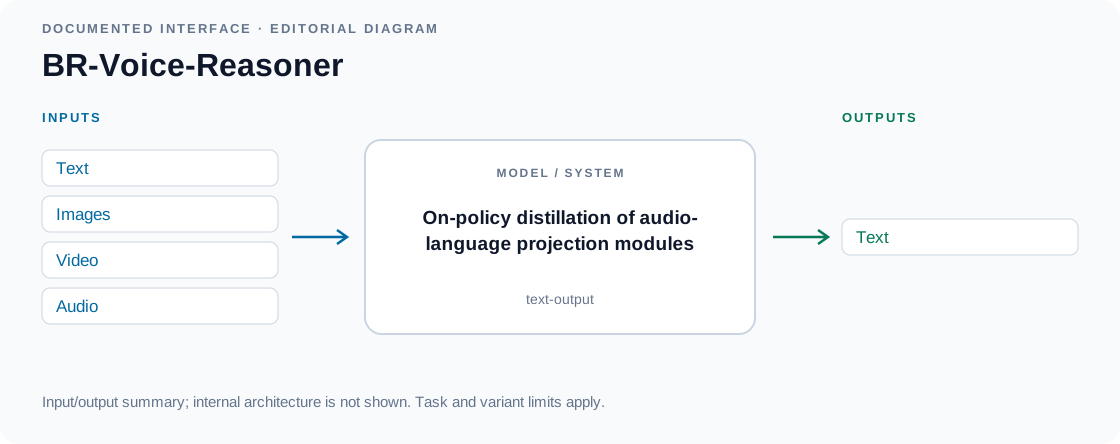
Input/output diagram · Source
Canary-Qwen
Transcribes English speech and offers a separate text-language mode for follow-up processing.
Open license: code Apache-2.0 · weights CC-BY-4.0
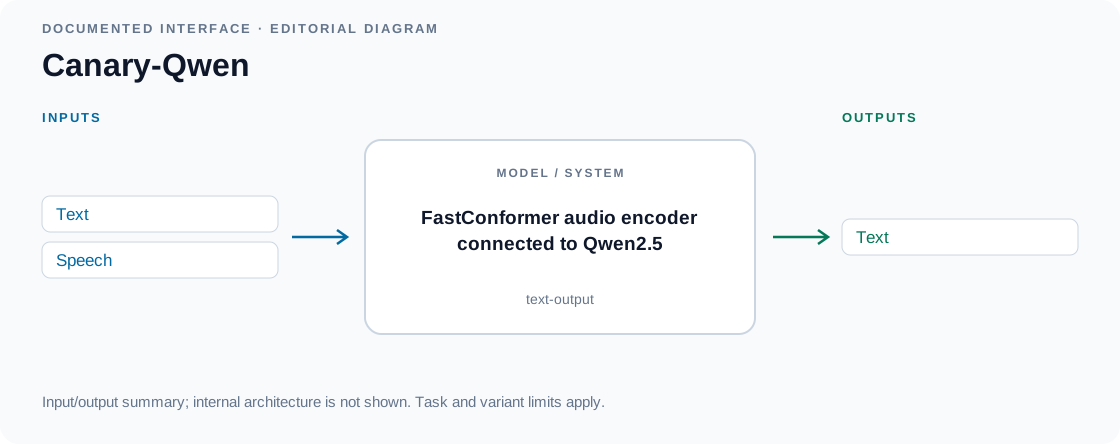
Input/output diagram · Source
Covo-Audio Chat
Understands spoken requests and generates context-aware, expressive voice responses.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
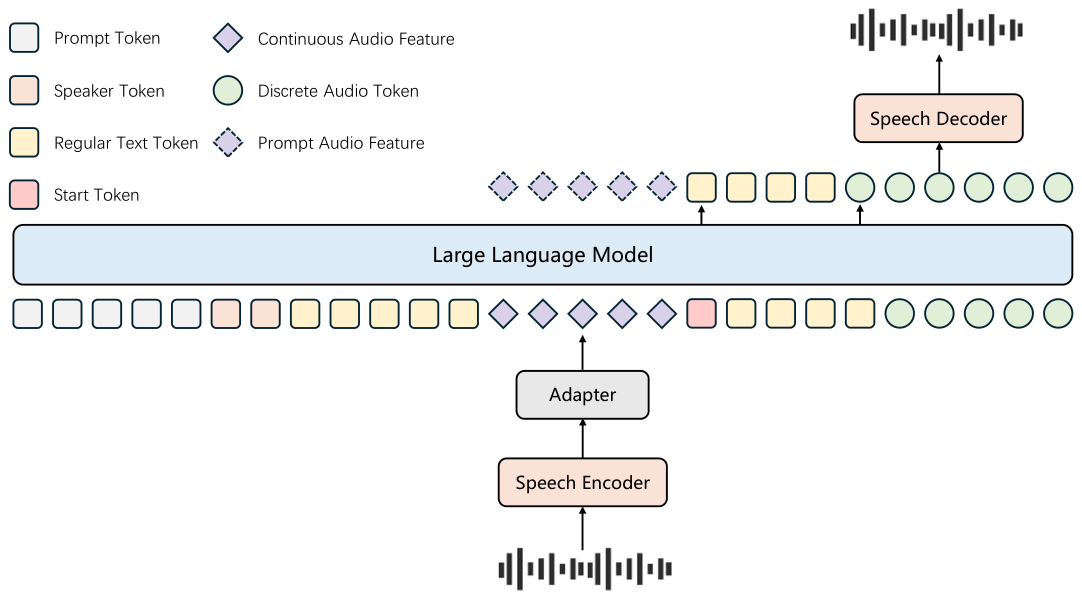
Figure 2, PDF p. 4 · Source
DeSTA2
Describes and answers questions about audio using a language model aligned with speech representations.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Llama community / component terms — Base-model and dataset terms apply; no unrestricted standalone weight license is stated.
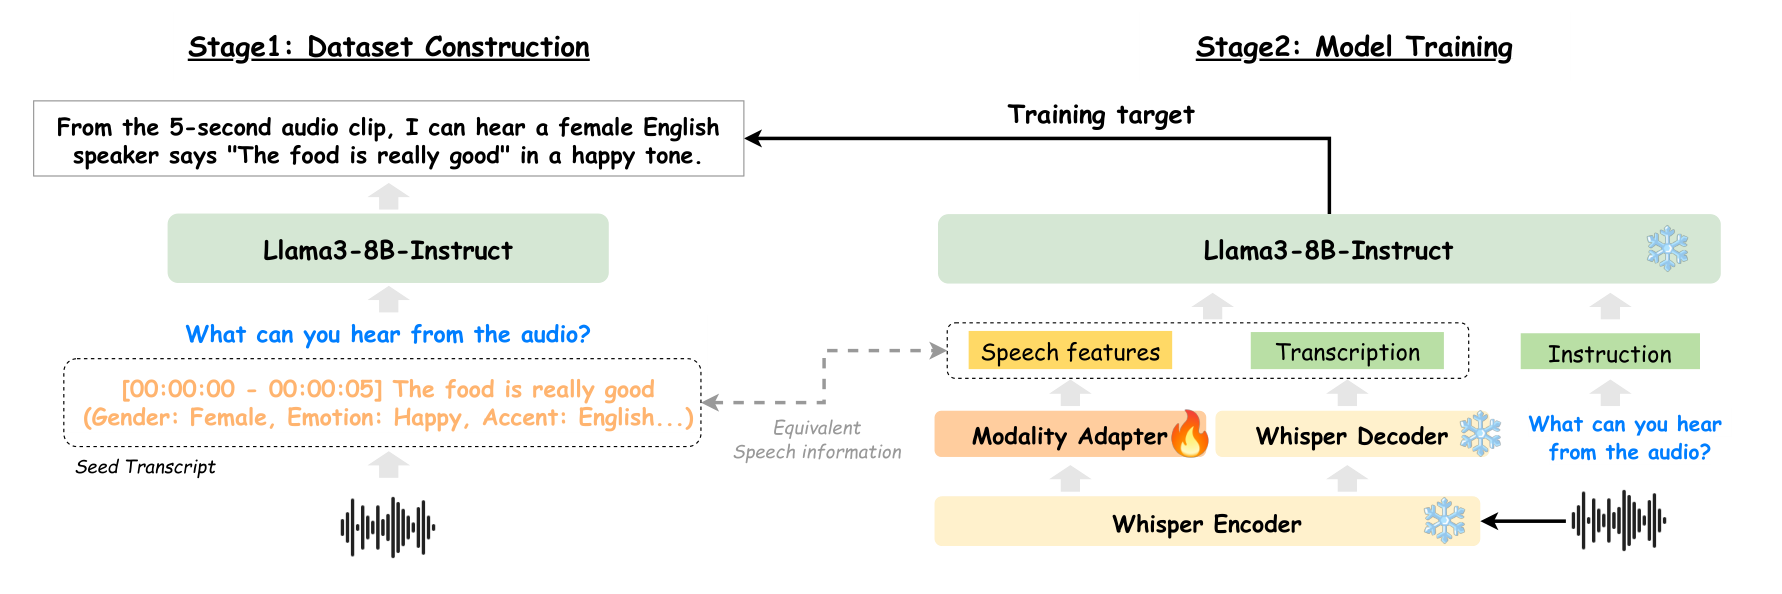
Figure 1 · Source
DeSTA2.5-Audio
Performs general audio understanding and follows spoken instructions without an external transcript pipeline.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Llama community / component terms — Base-model and dataset terms apply; no unrestricted standalone weight license is stated.
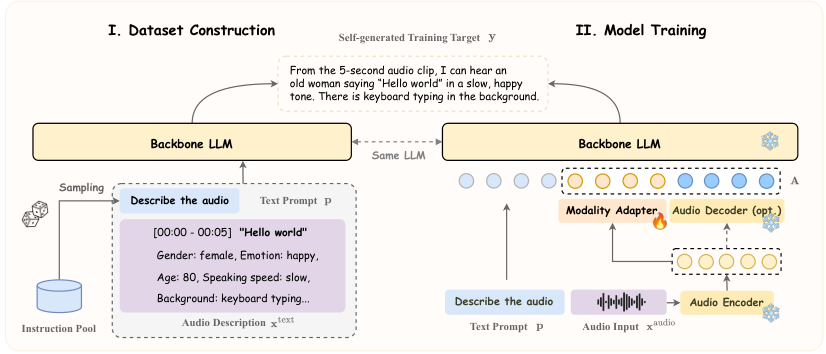
Figure 2 · Source
DialectS2S
Understands and speaks low-resource Chinese dialects in end-to-end voice conversations.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights MIT
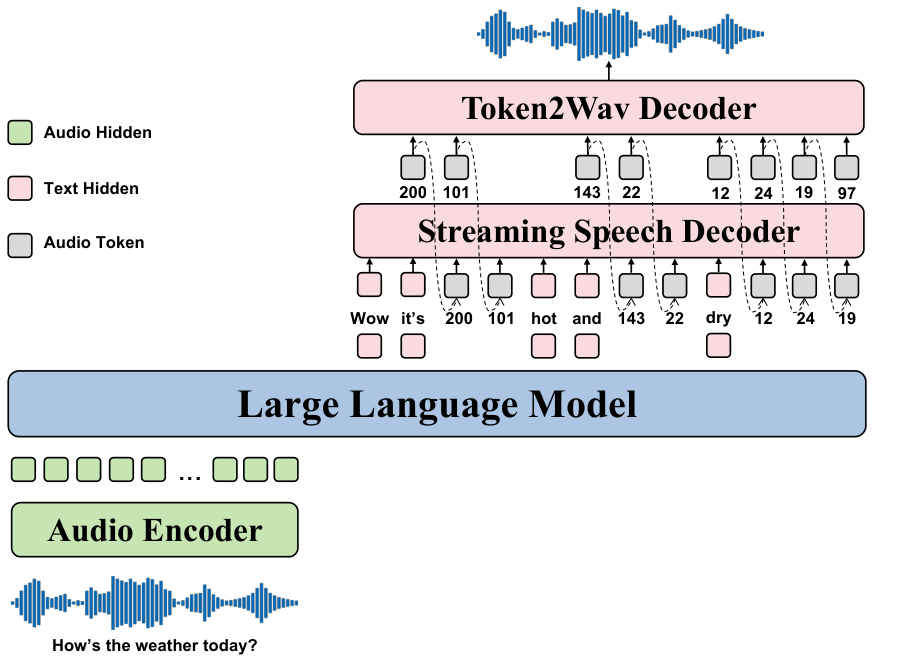
Family figure — Figure 1 · Source
DIFFA
Answers audio questions using diffusion-based text generation instead of left-to-right decoding.
Paper · Code · Weights · Details
License unclear: code Not stated · weights CC-BY-NC-SA-4.0 — The checkpoint uses a noncommercial share-alike license; repository code terms are not stated.
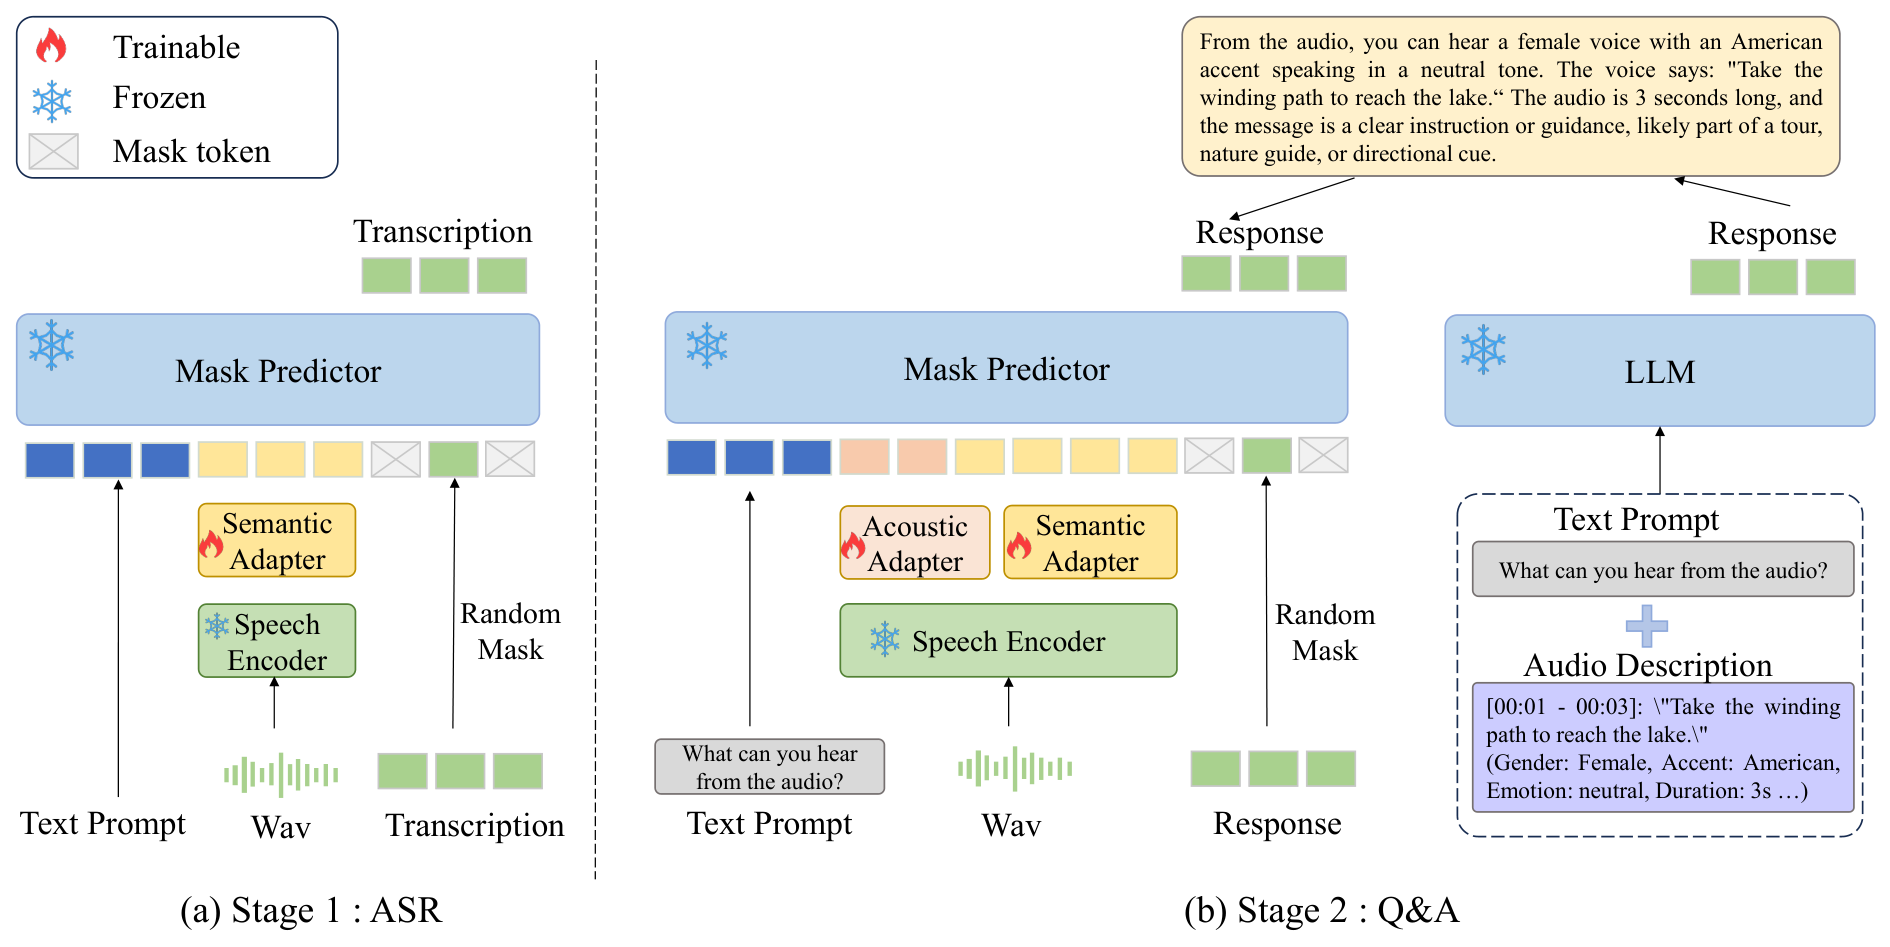
Figure 2 · Source
DIFFA-2
Understands speech, sound and music with a diffusion language model and richer acoustic representations.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Not stated — No release-specific code or weight license was located; do not assume DIFFA 1 terms apply.
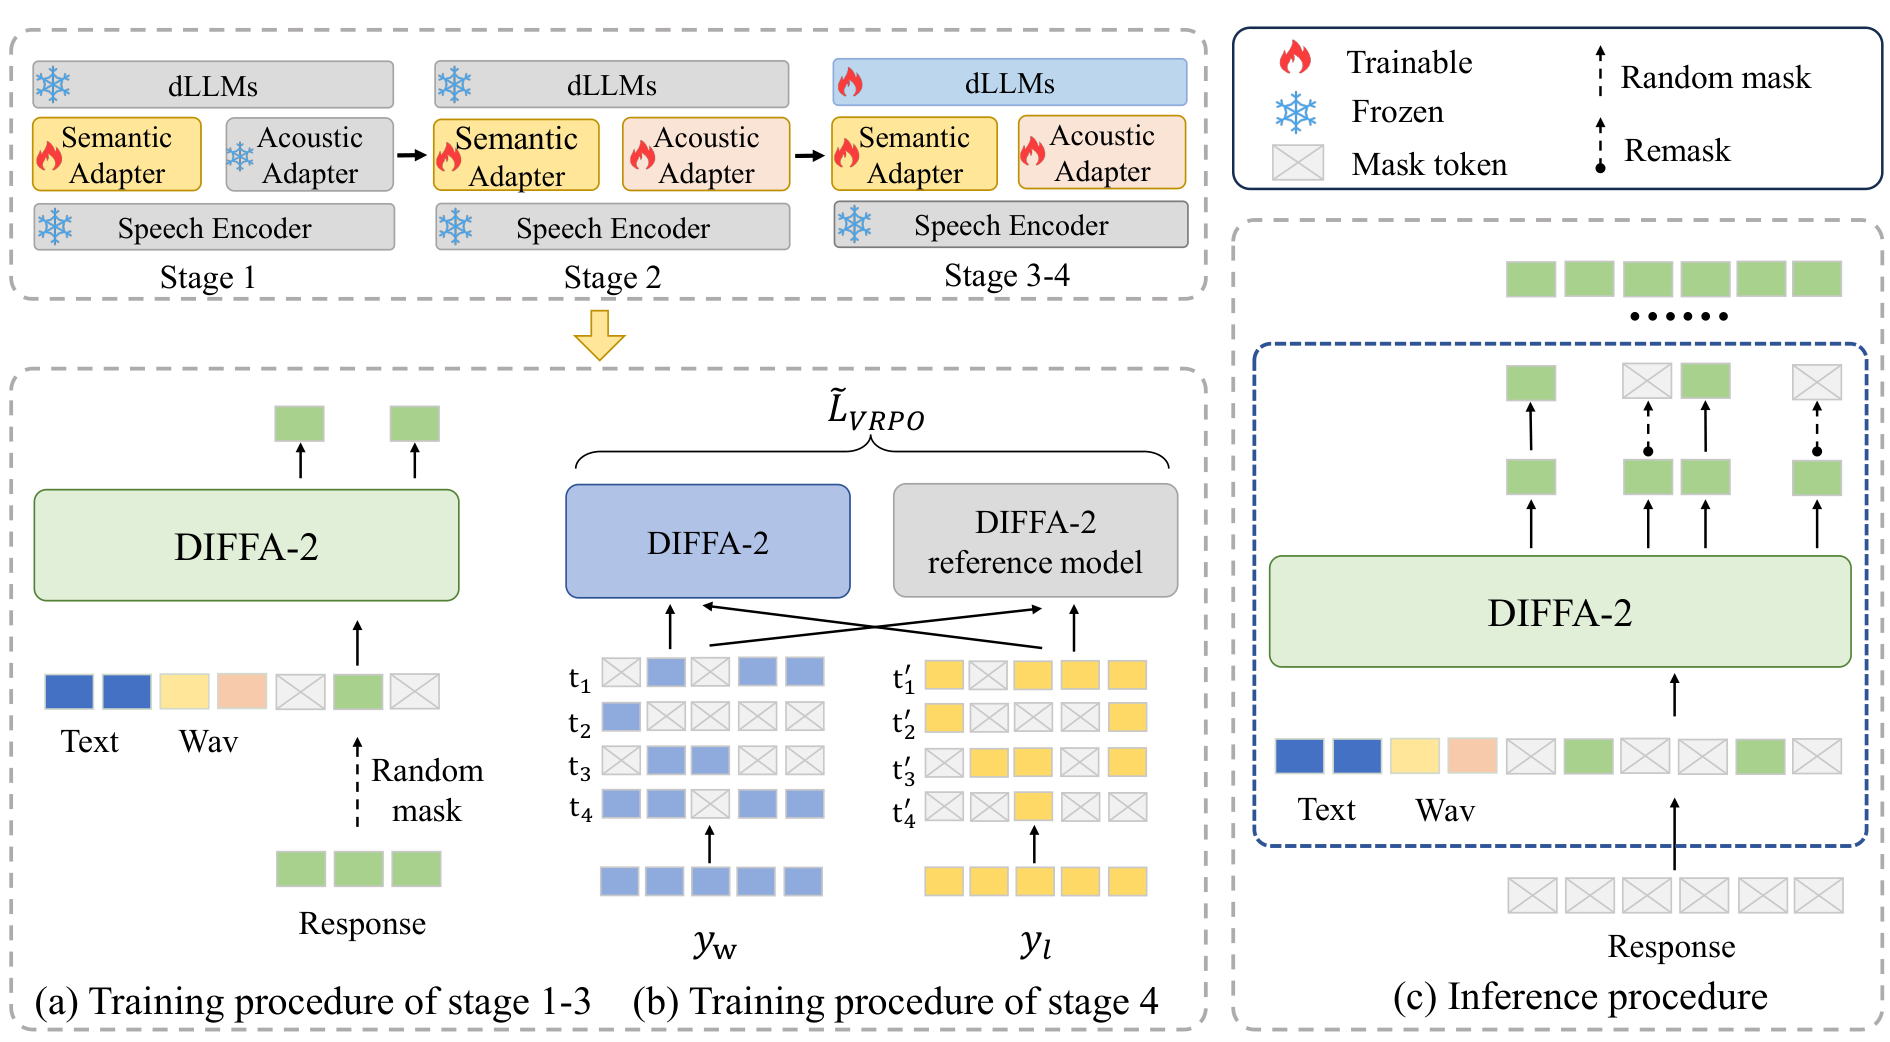
Figure 1 · Source
DiVA
Answers spoken questions by transferring a text assistant's behavior into an audio-input model.
Custom / restricted: code MPL-2.0 · weights MPL-2.0 + Llama 3 terms — The Llama 3 backbone retains its community license.
Input/output diagram · Source
DuplexCascade
Coordinates streaming transcription, language generation and speech synthesis for interruptible voice conversations.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
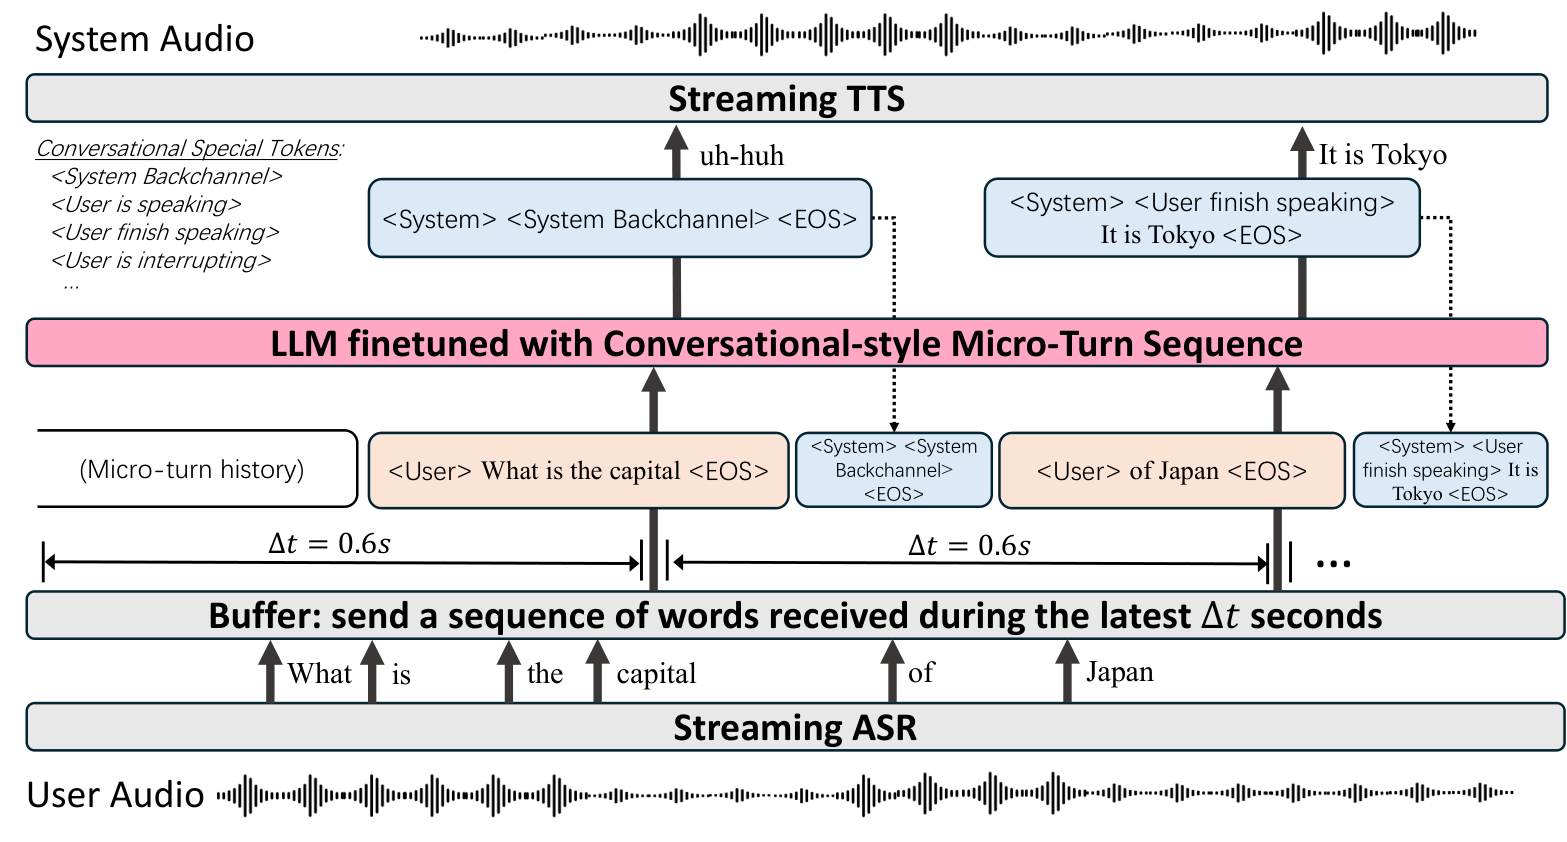
Figure 1 · Source
DuplexMamba
Reads incoming speech incrementally and supports responsive text generation during speech interaction.
Paper · Code · Weights · Details
Open license: code GPL-3.0 · weights Apache-2.0
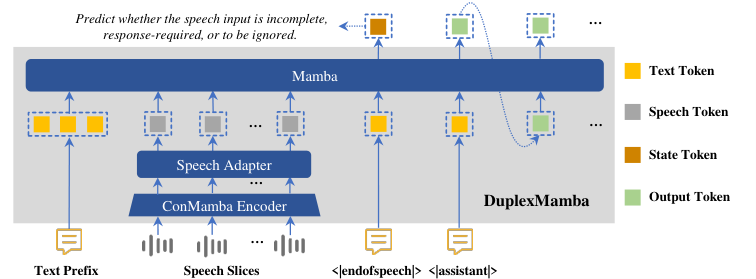
Figure 1 · Source
EMOVA (Qwen2.5-7B)
Discusses images and spoken requests, replying with text and expressive speech.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
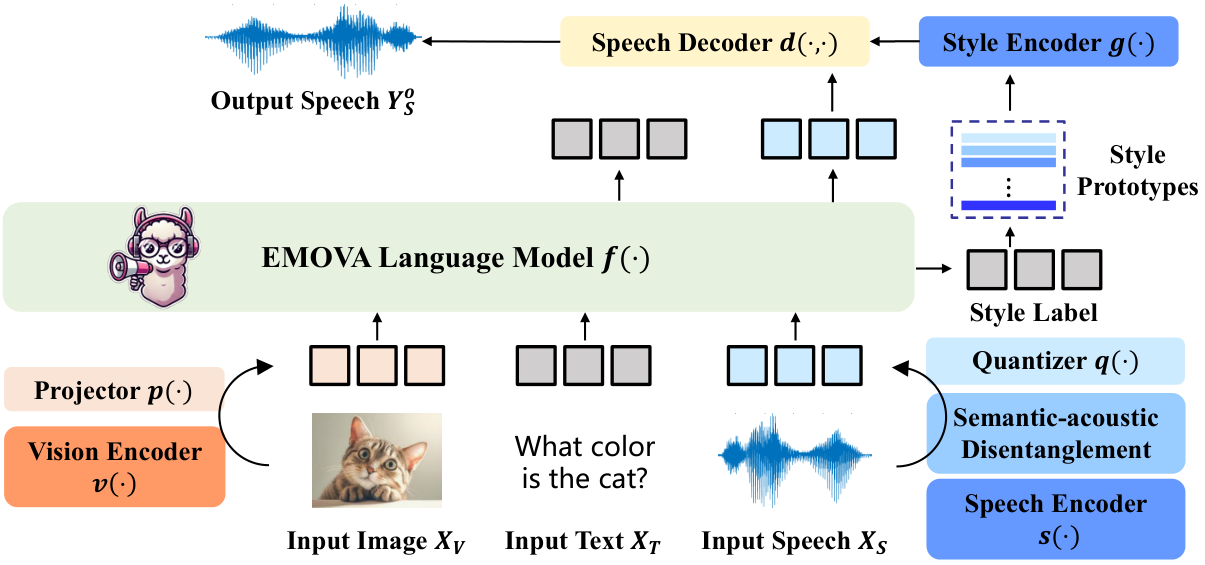
Family figure · Figure 2 · Source
Freeze-Omni
Enables streaming spoken dialogue while retaining a frozen text model's language abilities.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
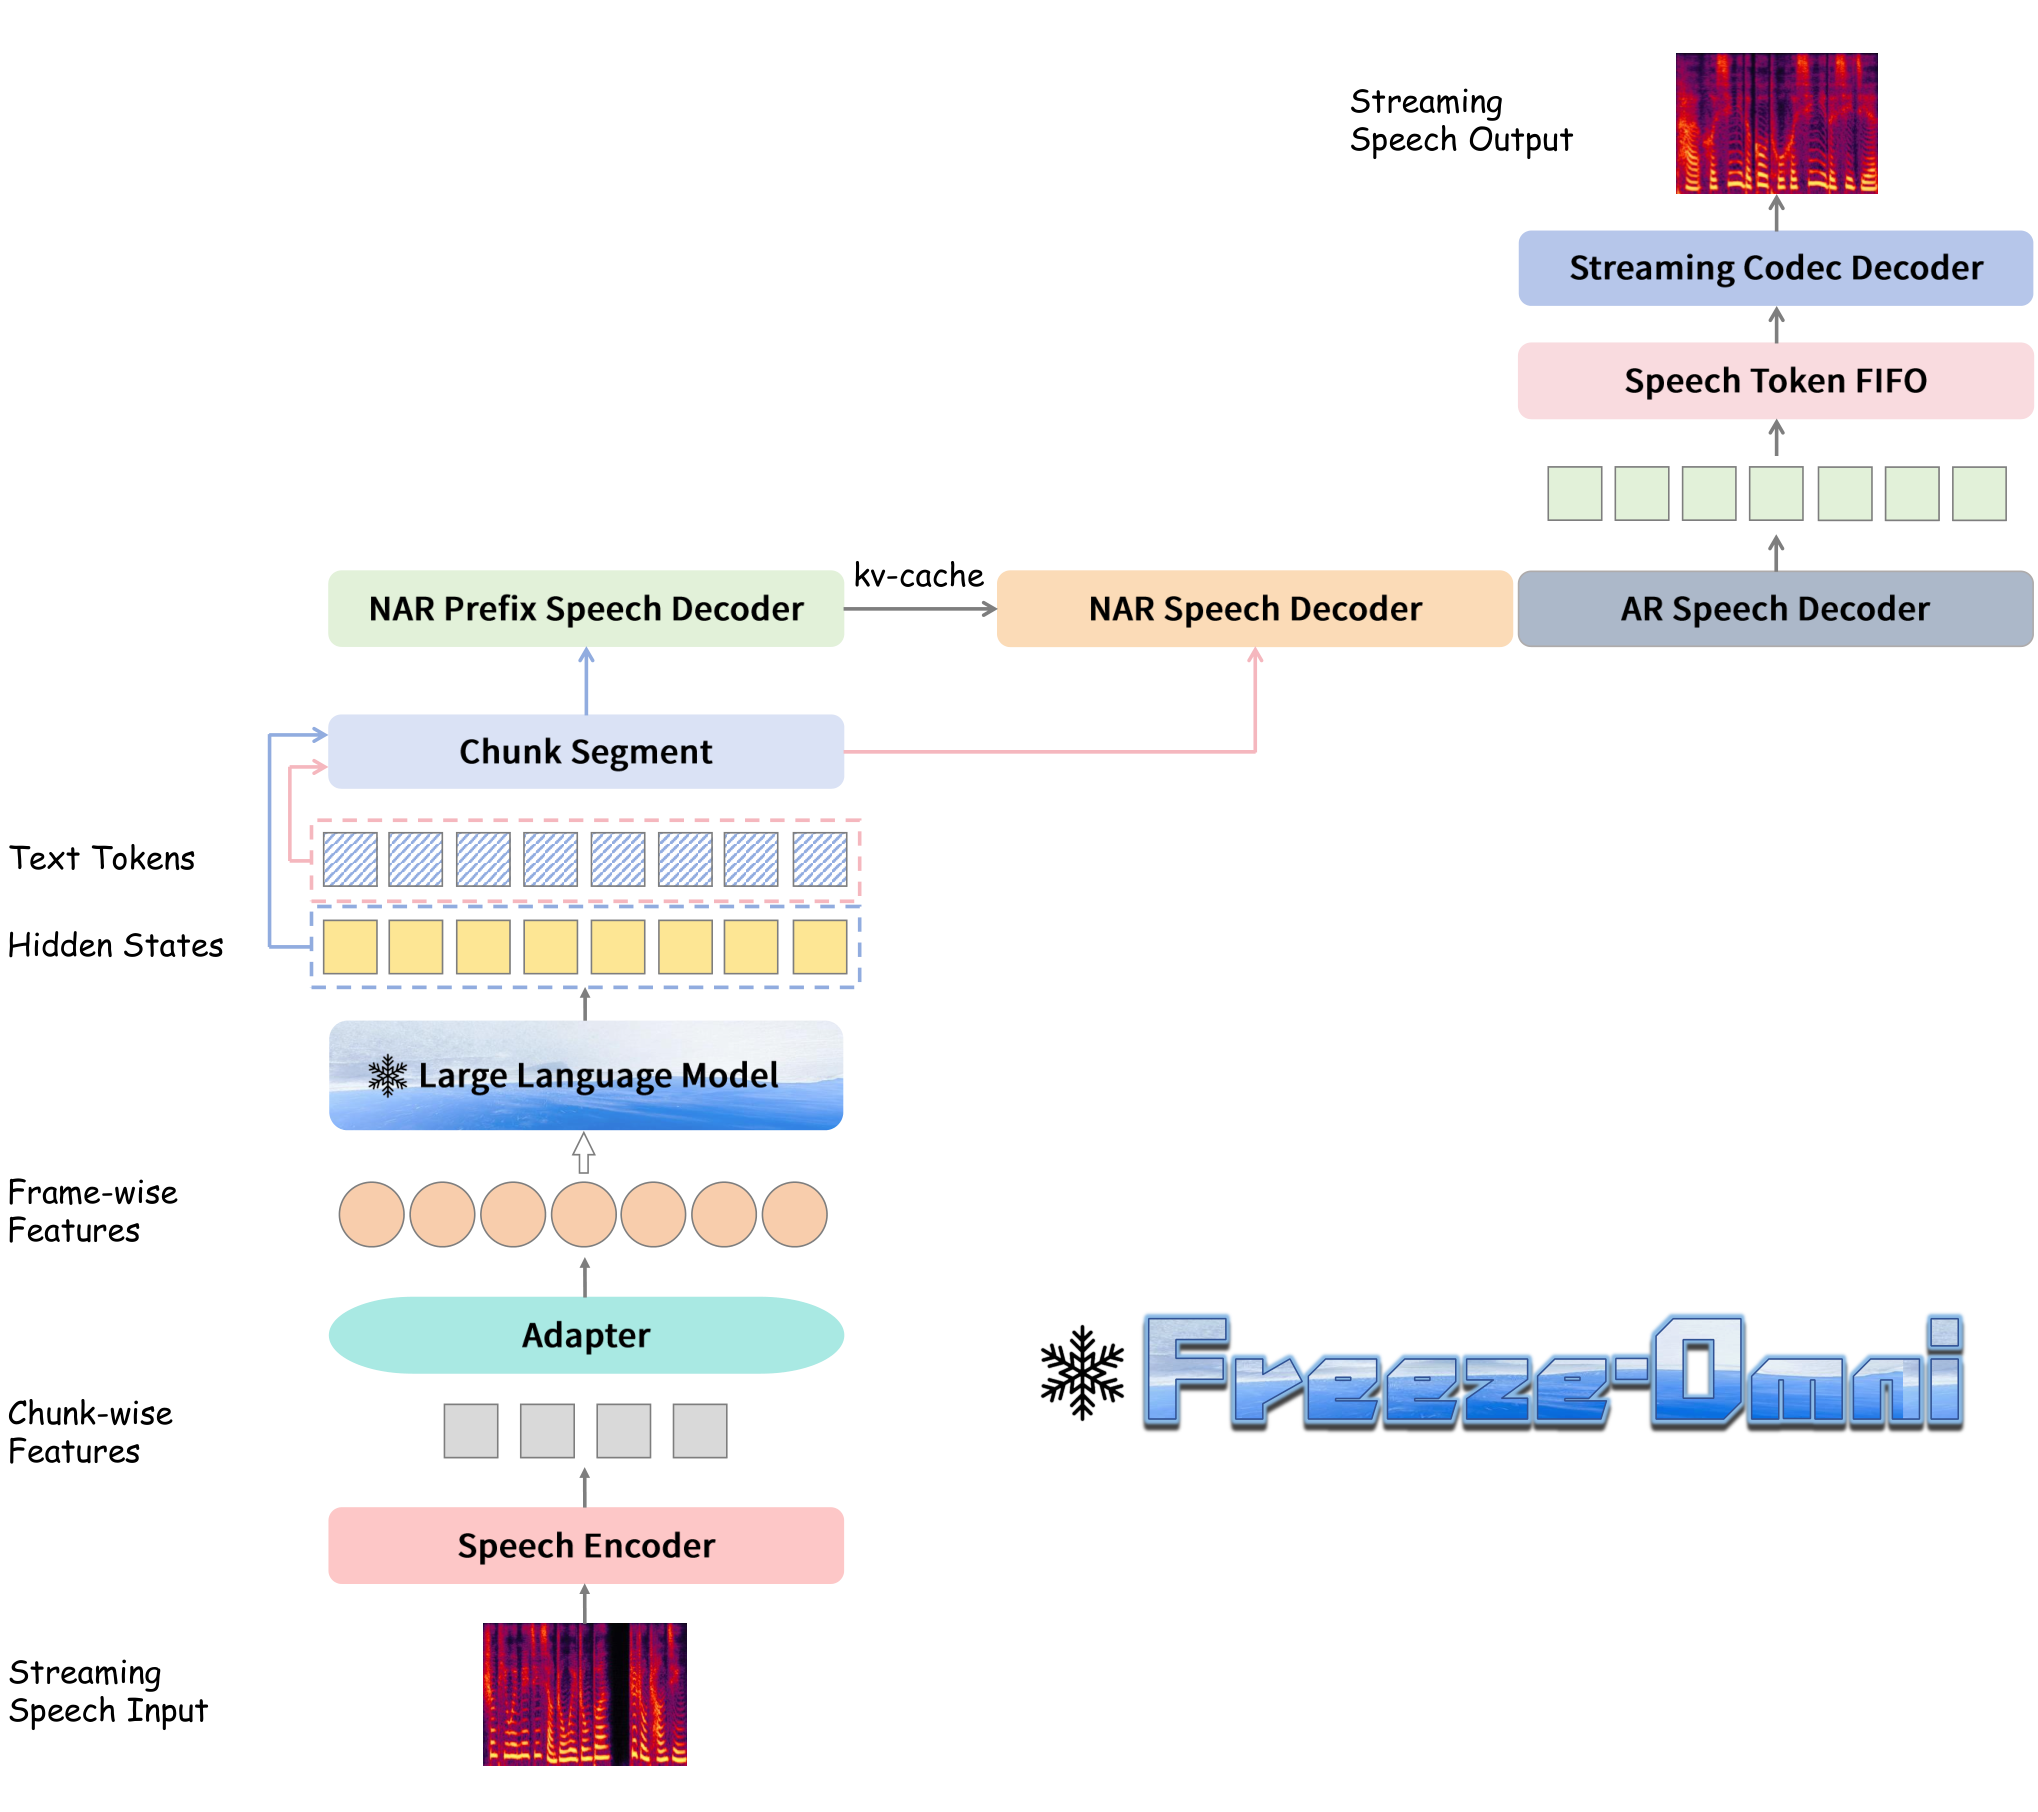
Figure 1 · Source
Fun-Audio-Chat
Holds low-latency spoken conversations while responding to vocal style and emotion.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
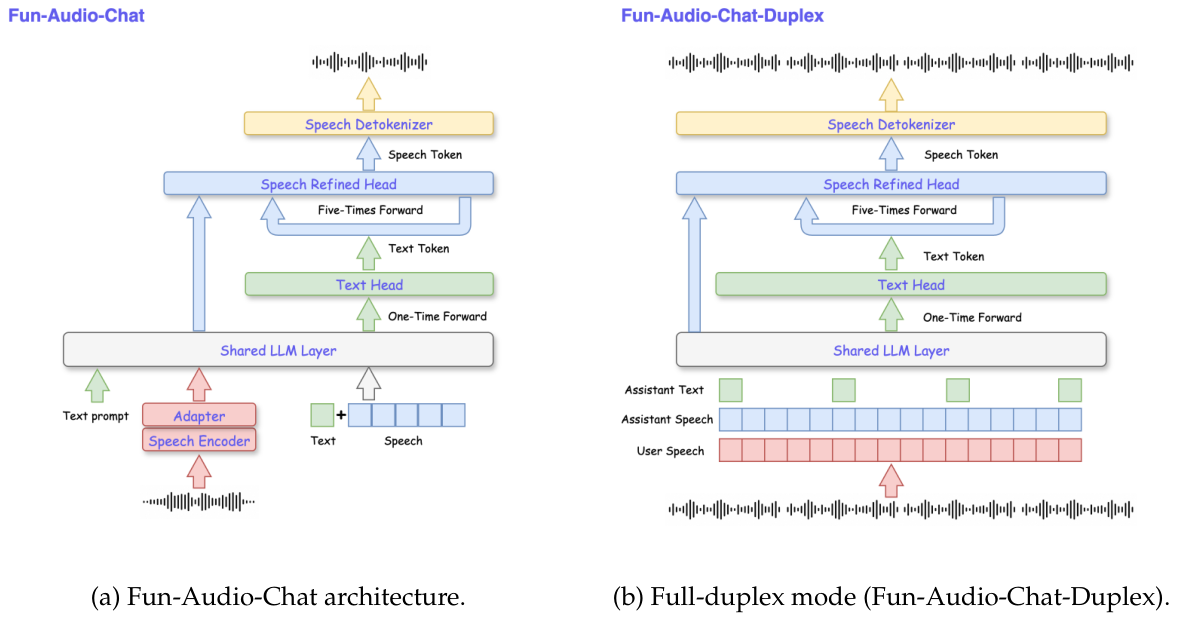
Figure 2, PDF p. 4 · Source
Gemma 3n E4B
Understands text, images, video and audio in a model designed for mobile devices.
Custom / restricted: code Apache-2.0 · weights Gemma terms — The weights use custom Gemma terms.
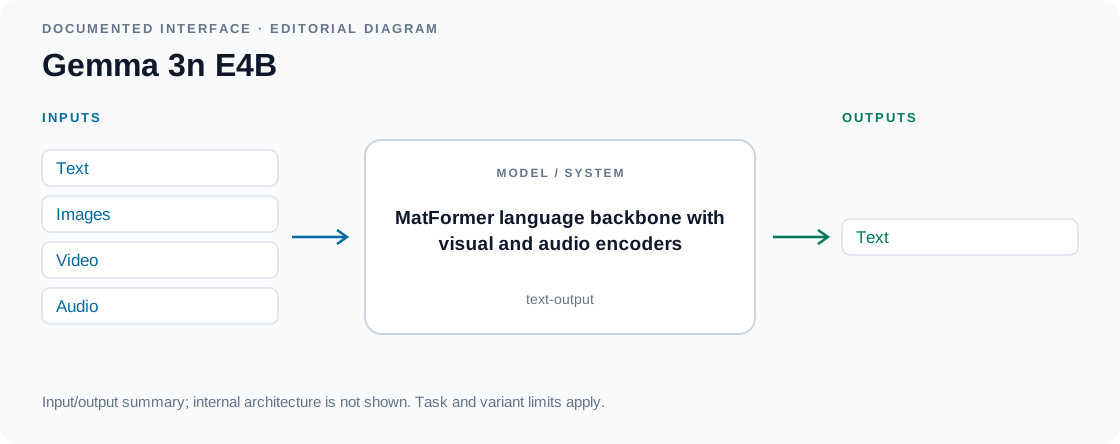
Input/output diagram · Source
Gemma 4 E4B
Answers questions about images, video and audio in a compact model designed for local use.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
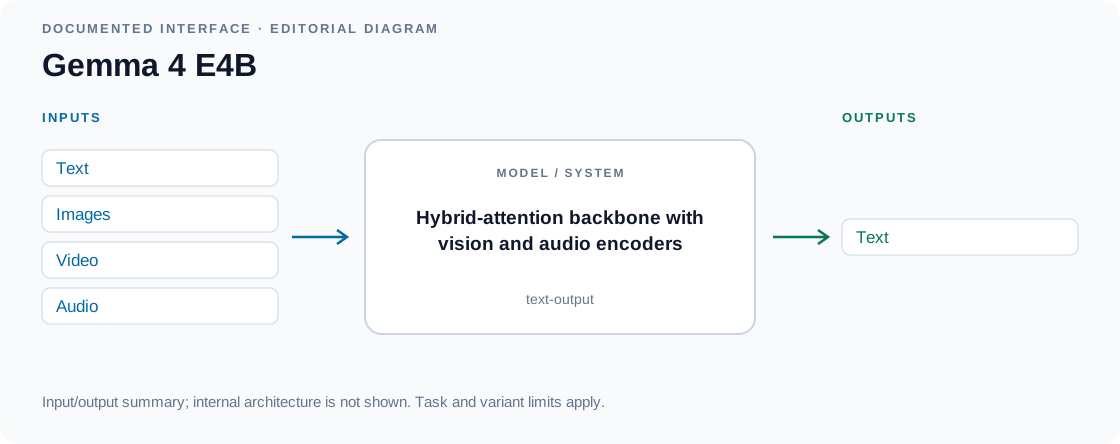
Input/output diagram · Source
GLM-4-Voice
Converses in Chinese and English with controllable emotion, speaking rate and vocal style.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights GLM-4 model license — Custom GLM model terms apply to the speech checkpoint.
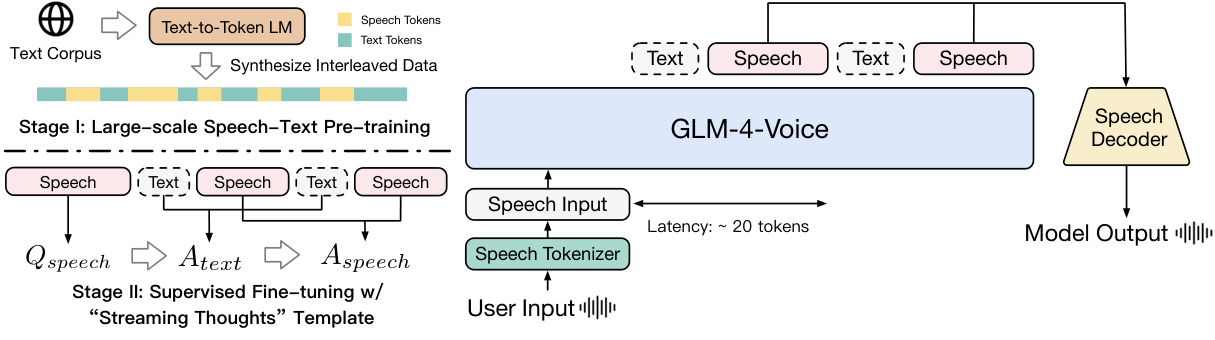
Figure 2 · Source
GLM-ASR Nano
Transcribes speech in English, Mandarin and Chinese dialects, including noisy recordings.
Open license: code MIT · weights MIT
Input/output diagram · Source
Granite Speech 3.3
Transcribes and translates speech while retaining a text language-model interface.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
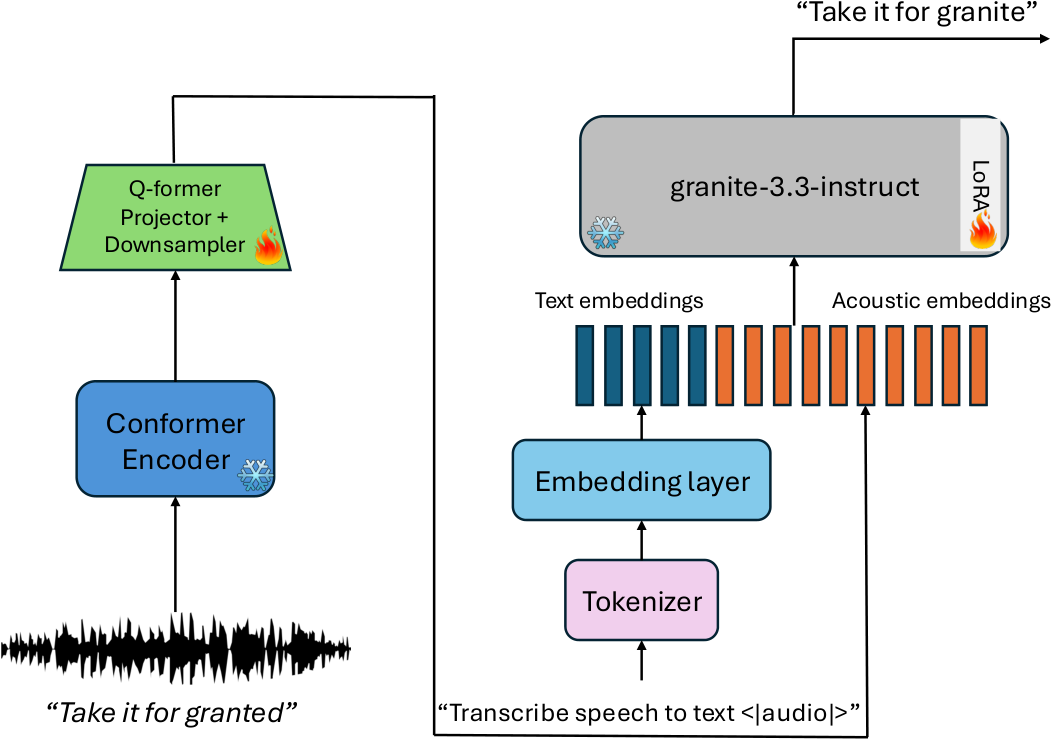
Figure 1 · Source
Granite Speech 4.0
Provides compact speech transcription and translation with a 1B language backbone.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Granite Speech 4.1
Transcribes and translates multilingual speech using an updated speech-language architecture.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Hibiki
Translates French speech into English as it arrives while preserving the speaker's voice.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights CC-BY-4.0
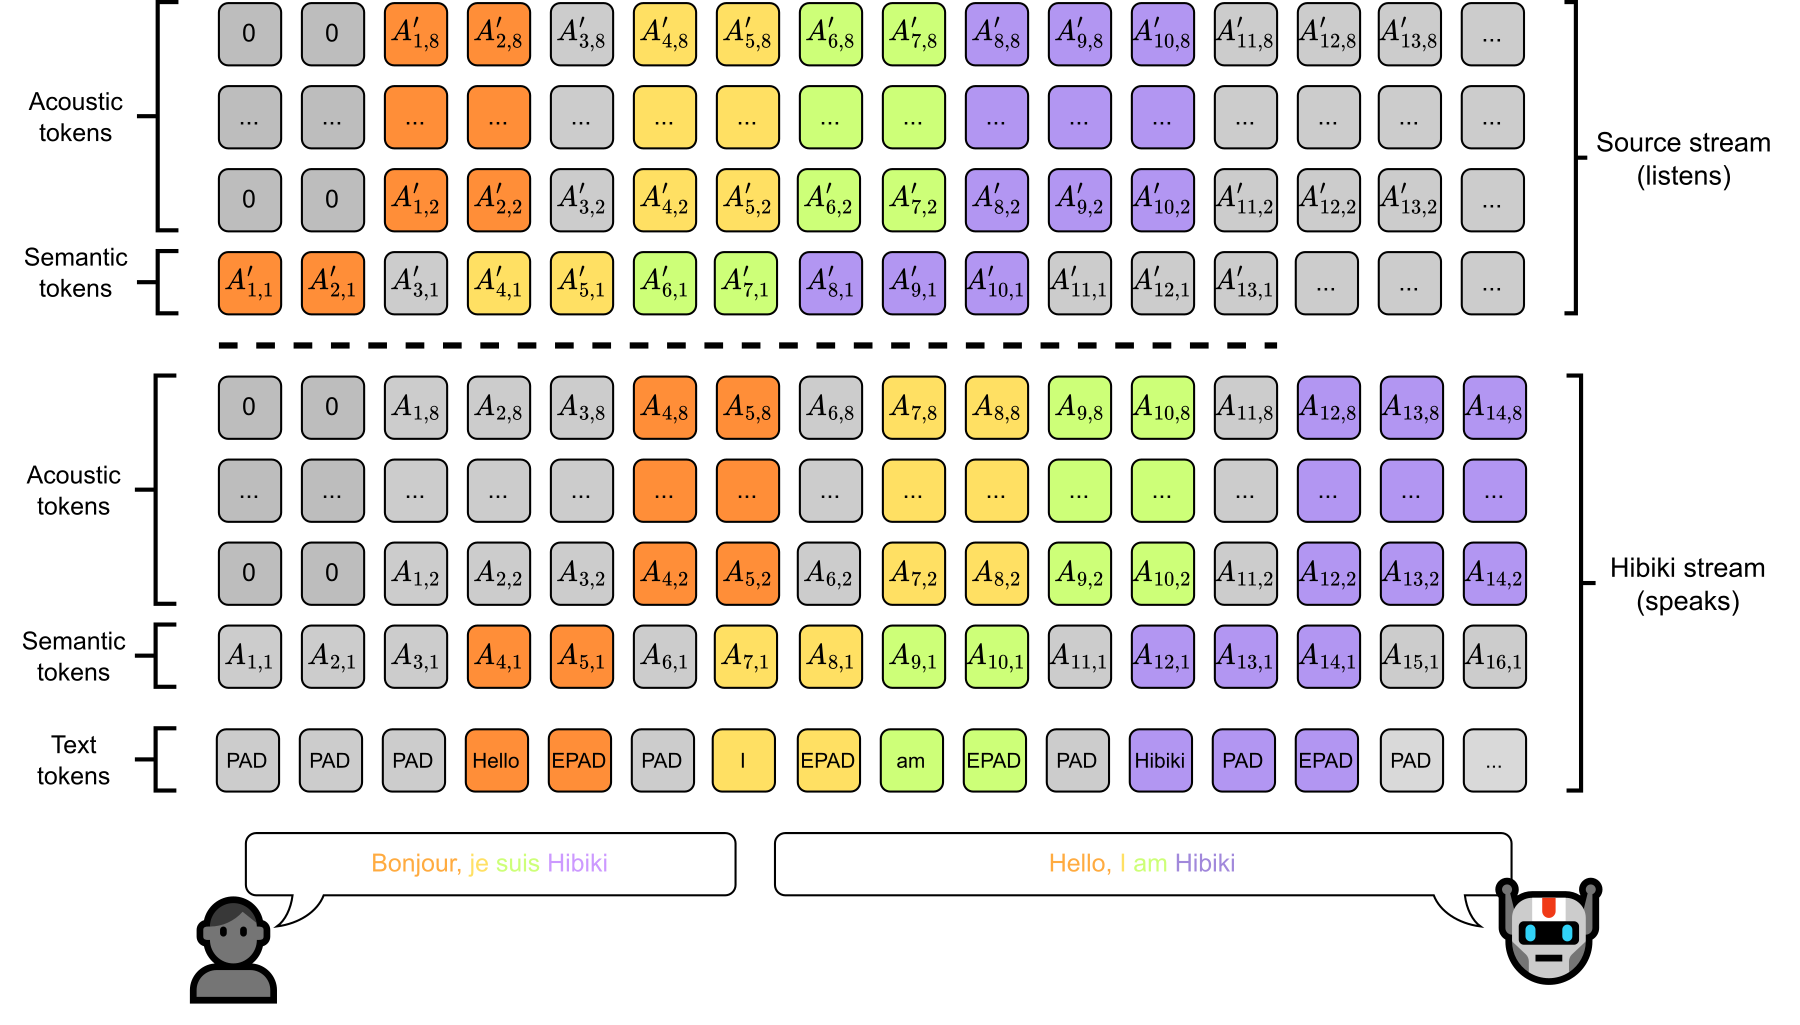
Figure 2 · Source
HumanOmni
Interprets human behavior, expressions and interactions from video and audio.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Not stated — Public code and weights were located, but a complete release license was not stated.
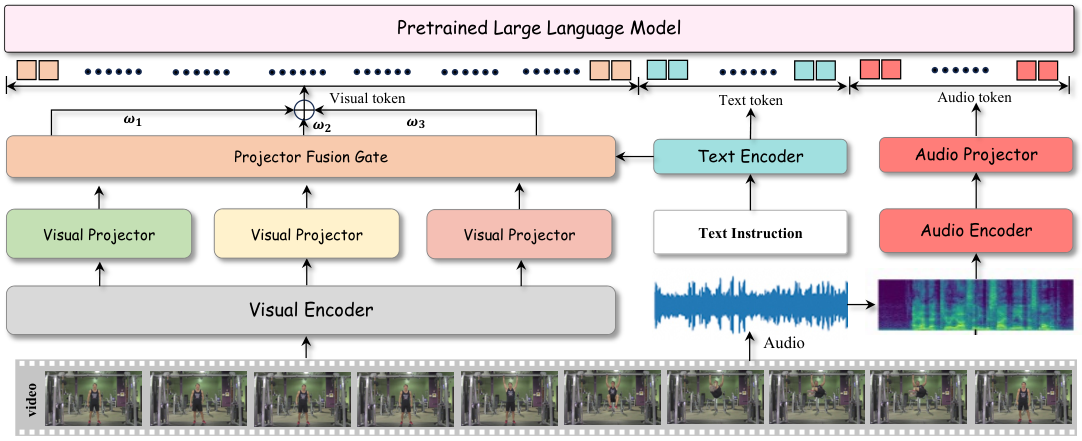
Figure 1 · Source
HumanOmniV2
Interprets people's actions, emotions and social interactions from video and audio.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
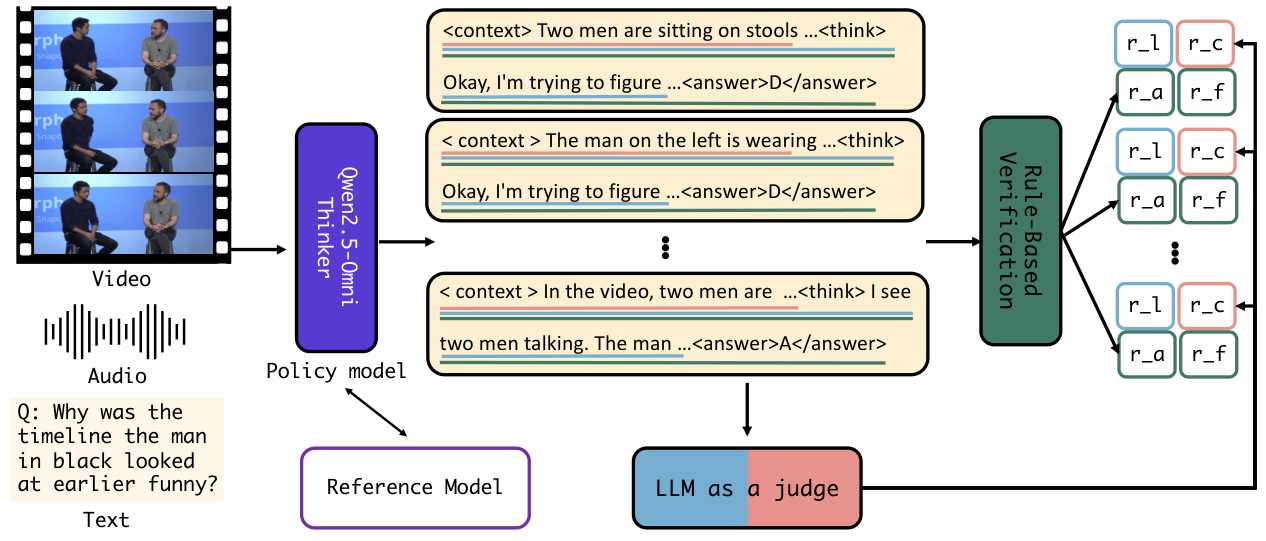
Figure 4 · Source
Ichigo
Answers spoken questions using audio tokens embedded directly into a Llama conversation.
License unclear: code Not stated · weights Apache-2.0 + Llama 3.1 terms — The Llama 3.1 backbone retains its community license; no standalone repository license was located.
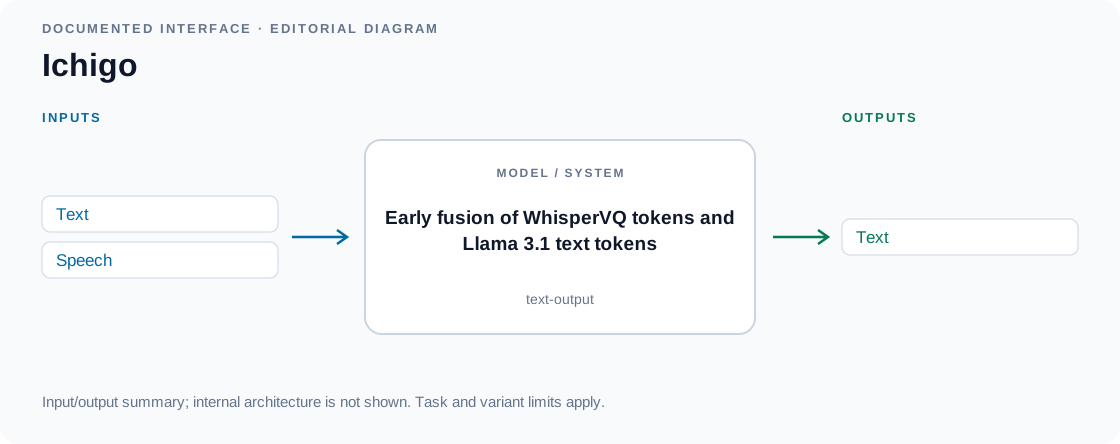
Input/output diagram · Source
Kimi-Audio
Understands speech, sound and music and supports natural voice conversations.
Paper · Code · Weights · Details
Open license: code MIT / Apache-2.0 · weights MIT
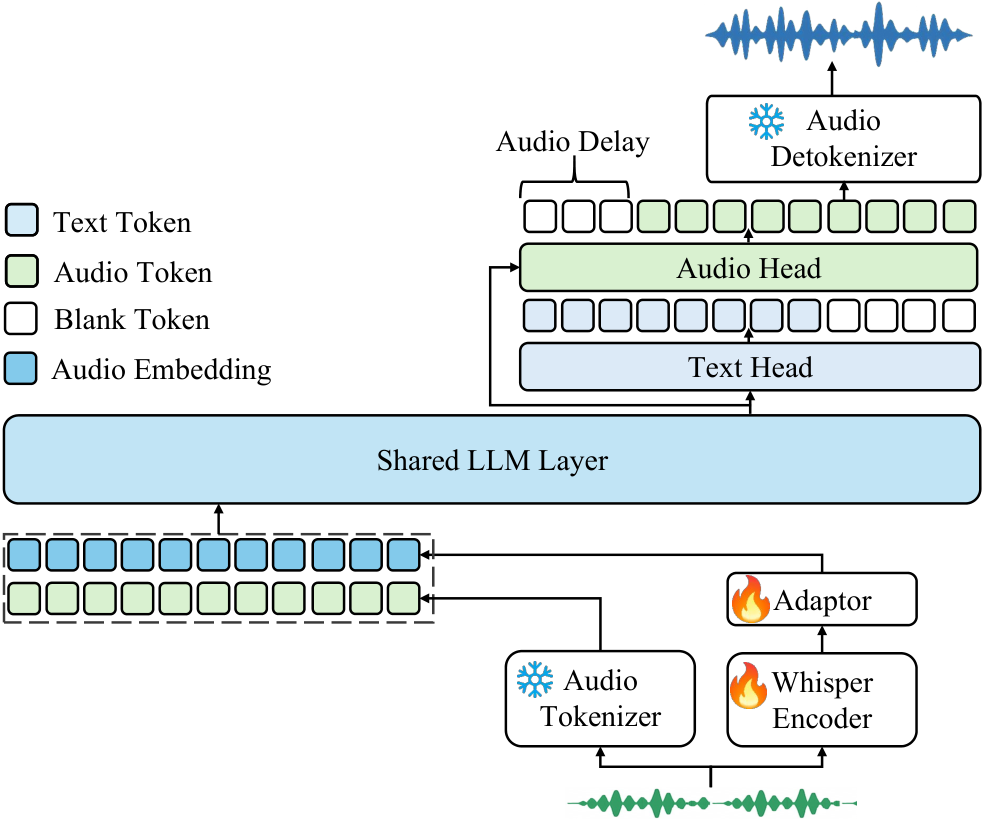
Figure 2 · Source
LFG-1
Answers English spoken questions locally on Apple Silicon and also accepts images.
Open license: code Apache-2.0 · weights Apache-2.0
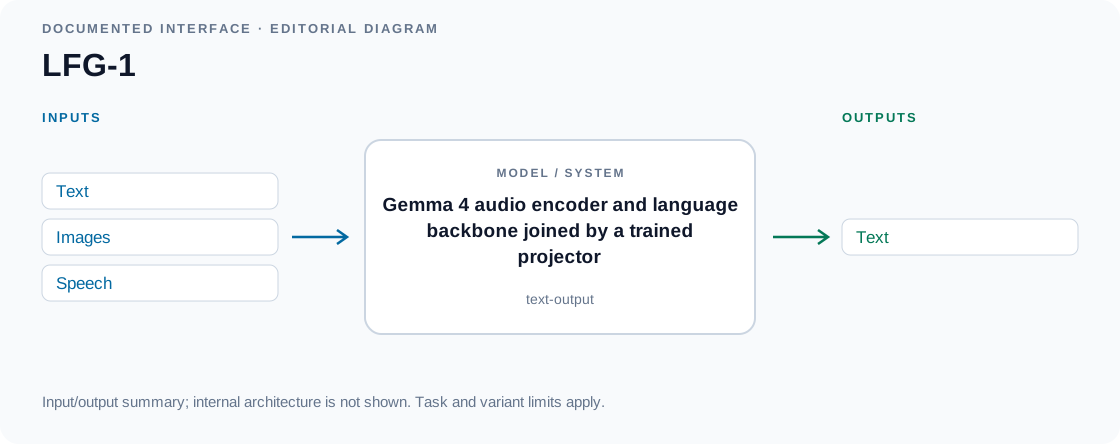
Input/output diagram · Source
LFG-2
Reasons about English spoken instructions and returns a text answer with an optional thought channel.
License unclear: code Not stated · weights Not stated — Code and weights are downloadable, but this release does not state a license.
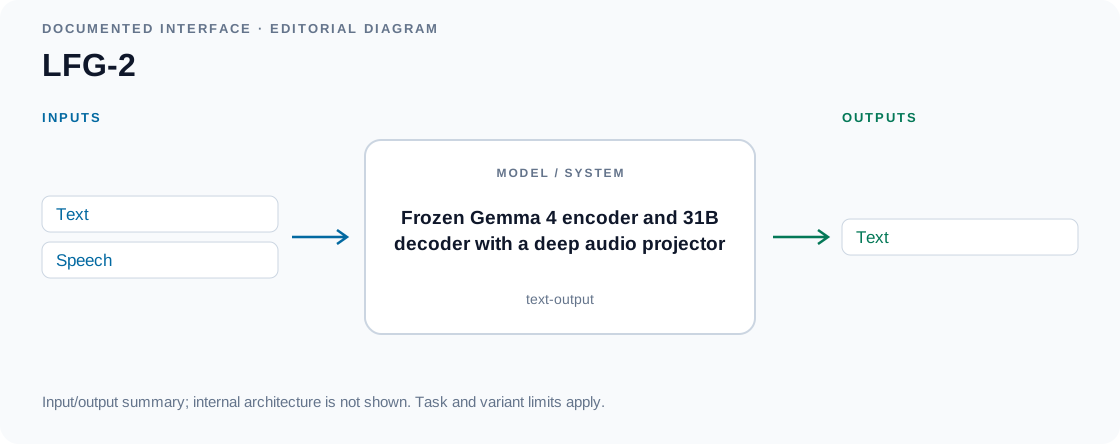
Input/output diagram · Source
LFG-3
Answers English spoken questions using acoustic features instead of an intermediate transcript.
License unclear: code Not stated · weights Not stated — Code and weights are downloadable, but this release does not state a license.
Input/output diagram · Source
LFM2-Audio-1.5B
Transcribes speech, synthesizes speech and supports interleaved voice conversations on local devices.
Paper · Code · Weights · Details
Custom / restricted: code LFM Open License v1.0 · weights LFM Open License v1.0 — Revenue-based commercial-use limit; see the LFM license.
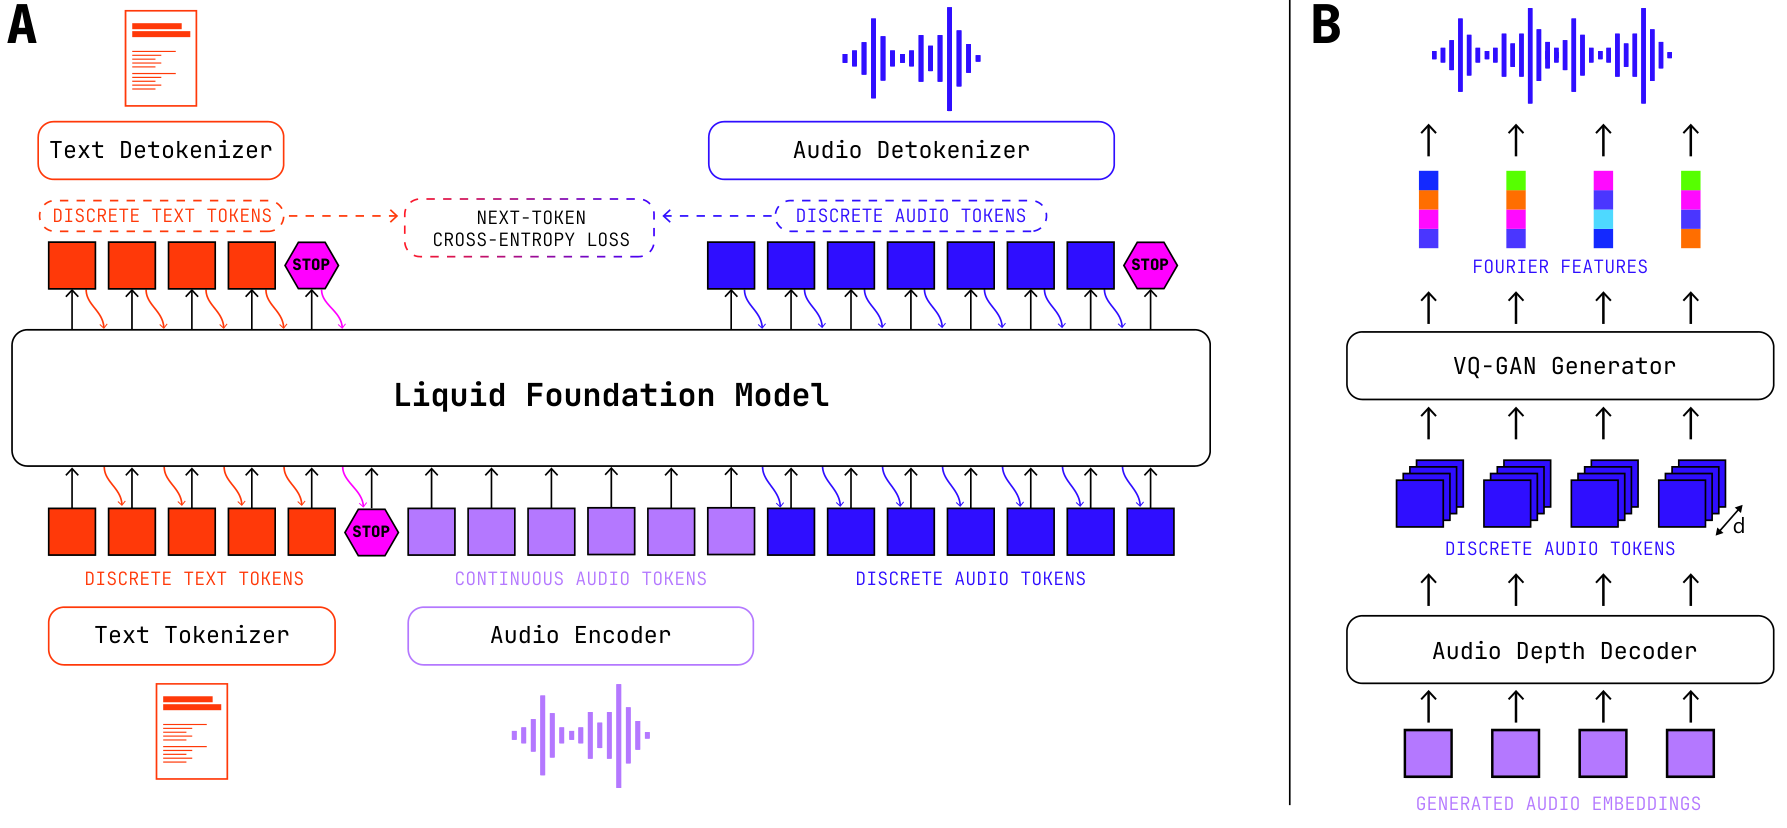
Figure 7 · Source
LFM2.5-Audio-1.5B
Handles transcription, speech synthesis and voice chat with a faster audio decoder for local inference.
Paper · Code · Weights · Details
Custom / restricted: code LFM Open License v1.0 · weights LFM Open License v1.0 — Revenue-based commercial-use limit; see the LFM license.
Input/output diagram · Source
LFM2.5-Audio-1.5B-JP
Brings Japanese transcription, speech synthesis and spoken conversation to the LFM2.5 audio family.
Paper · Code · Weights · Details
Custom / restricted: code LFM Open License v1.0 · weights LFM Open License v1.0 — Revenue-based commercial-use limit; see the LFM license.
Input/output diagram · Source
LLaMA-Omni
Answers spoken requests with synchronized text and streaming speech.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Research-only — The model card excludes commercial use of the weights.
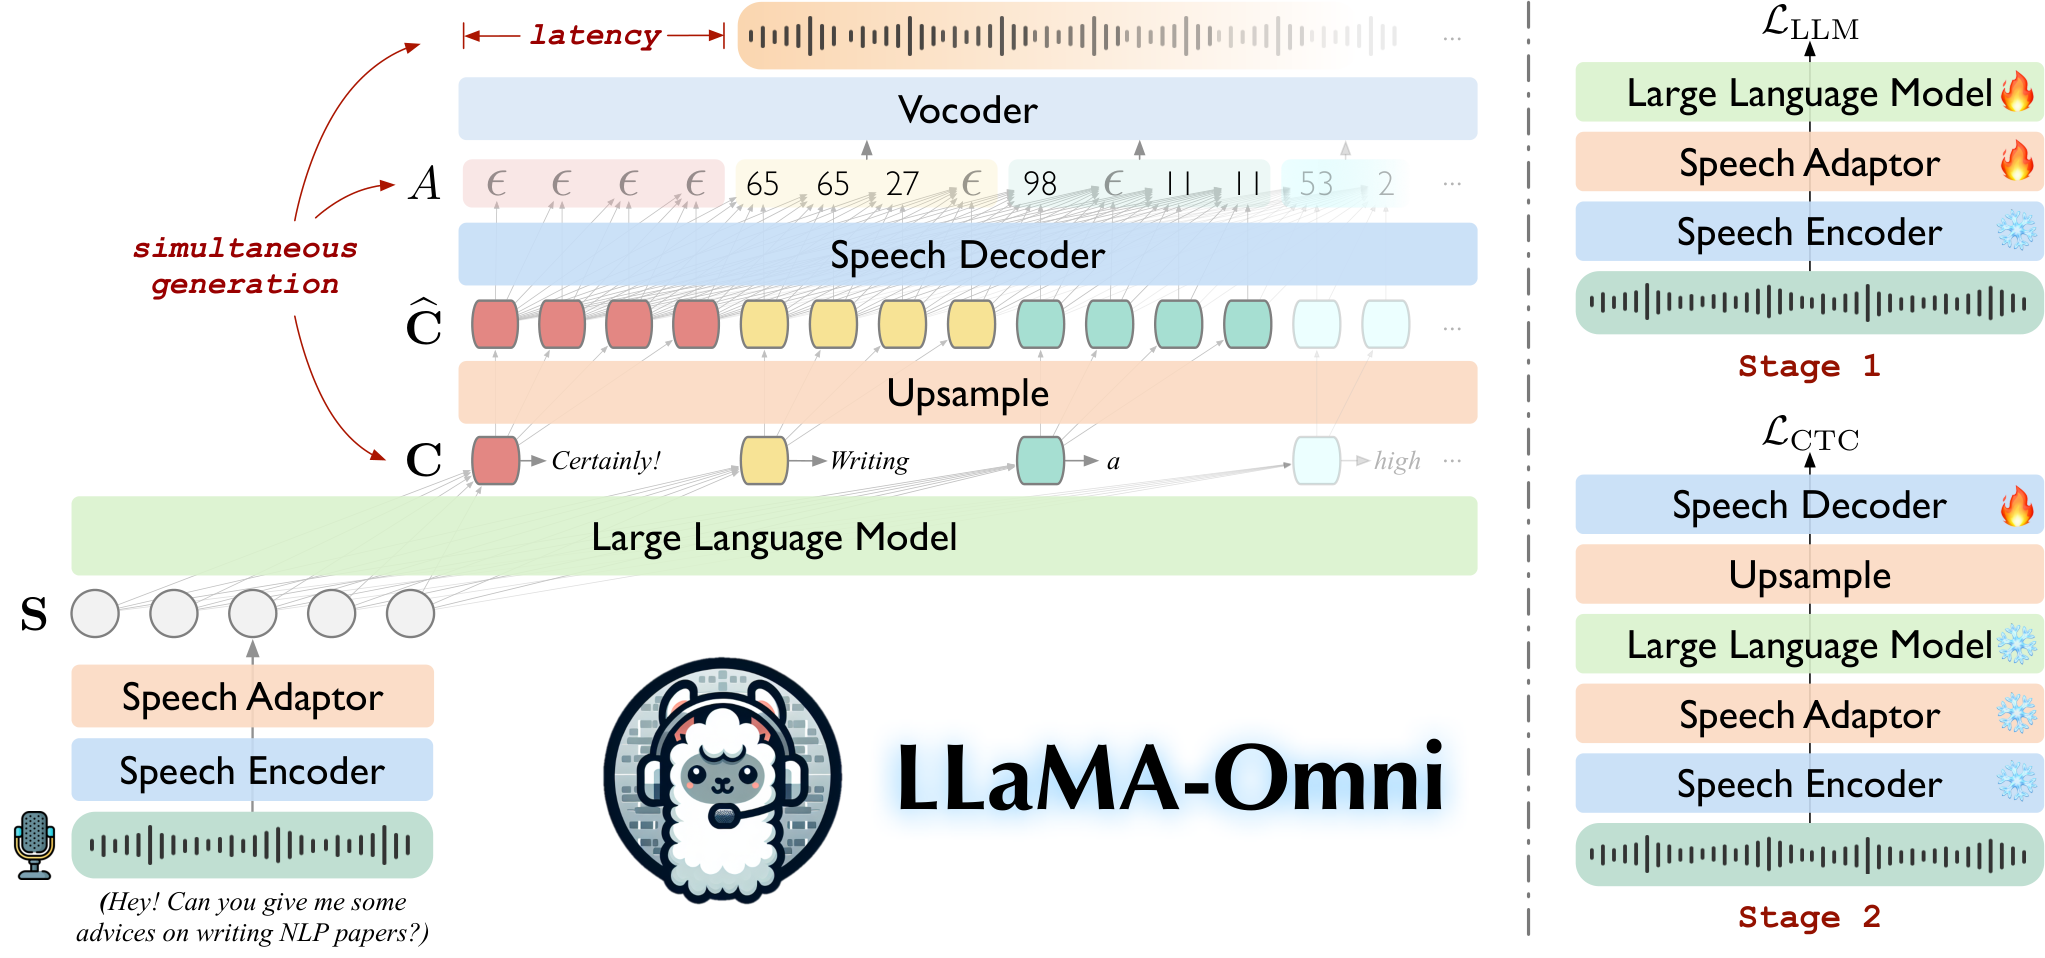
Figure 2 · Source
LLaMA-Omni 2
Supports multi-turn spoken chat with streaming speech generation.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Research-only — The model card excludes commercial use of the weights.
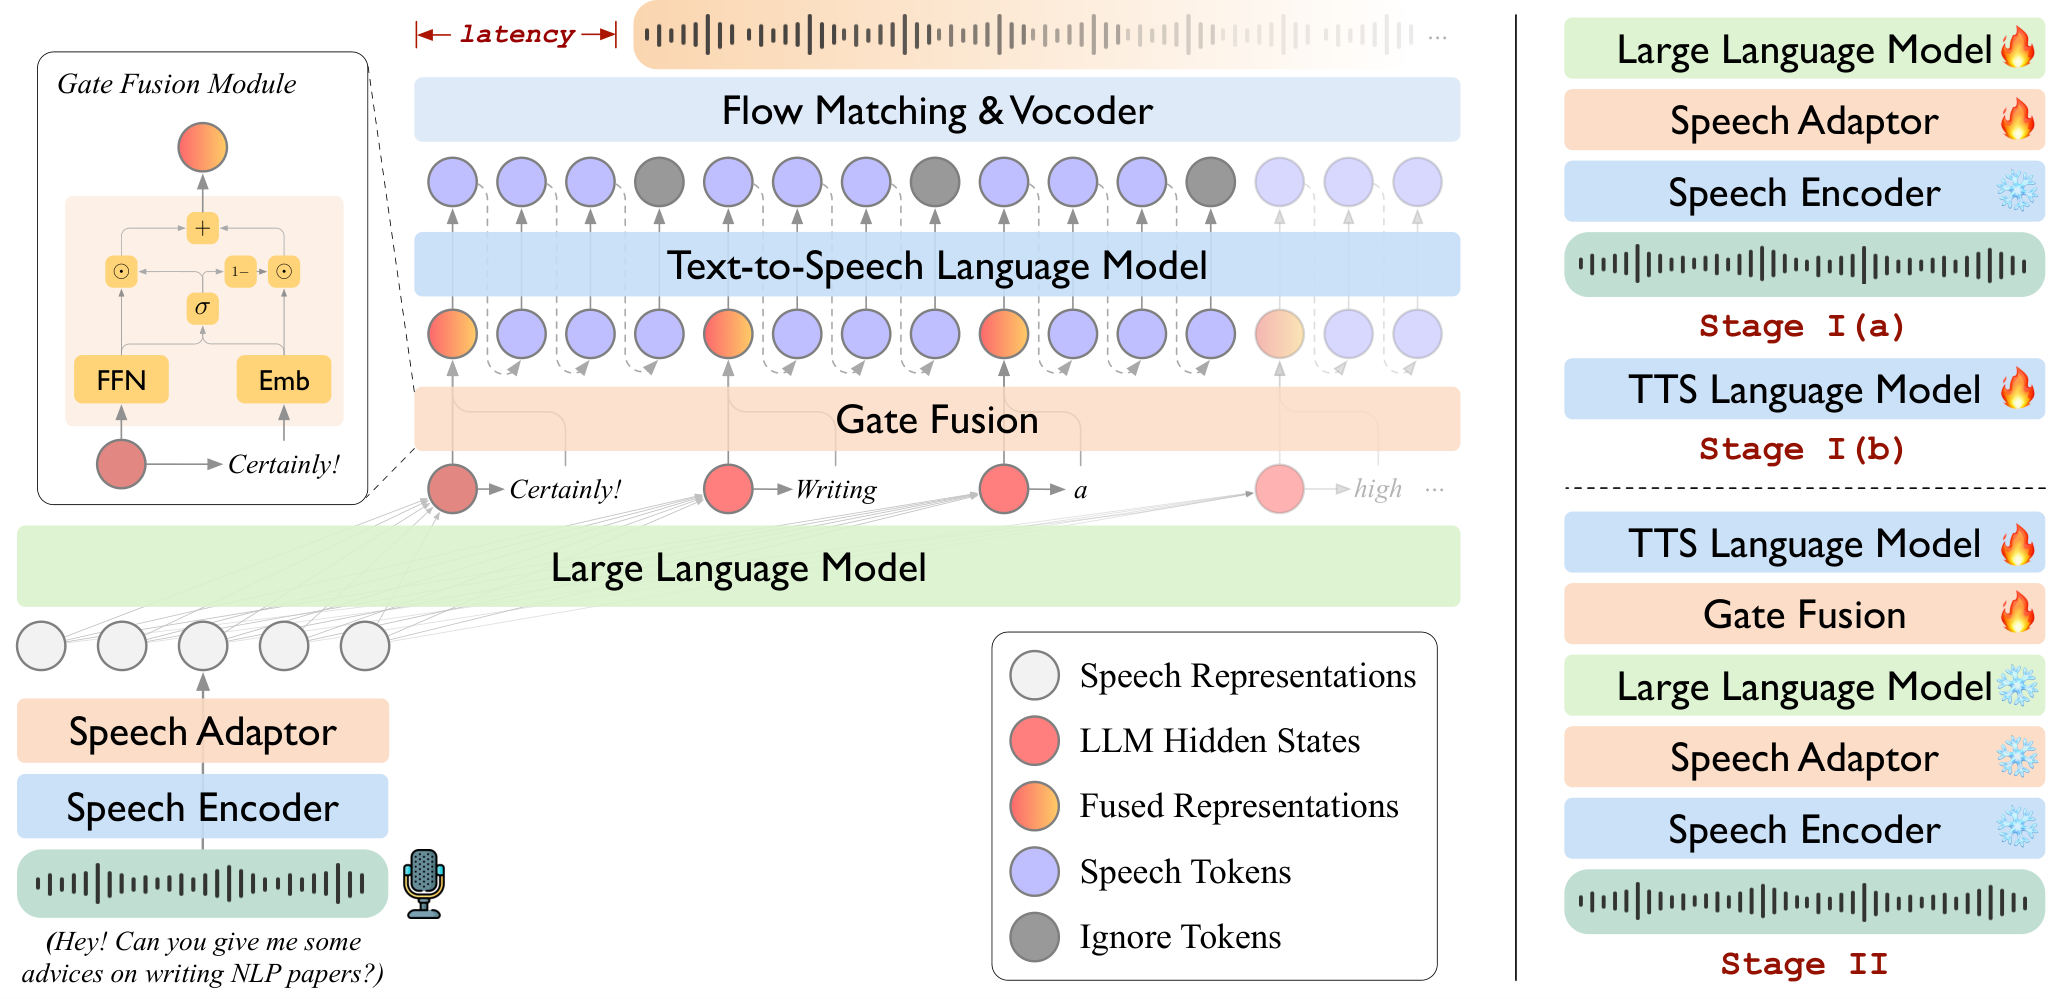
Figure 1 · Source
LLaSM
Answers spoken questions and supports instruction following across speech and text.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights OpenRAIL — Custom release or component terms apply; consult the linked license evidence.
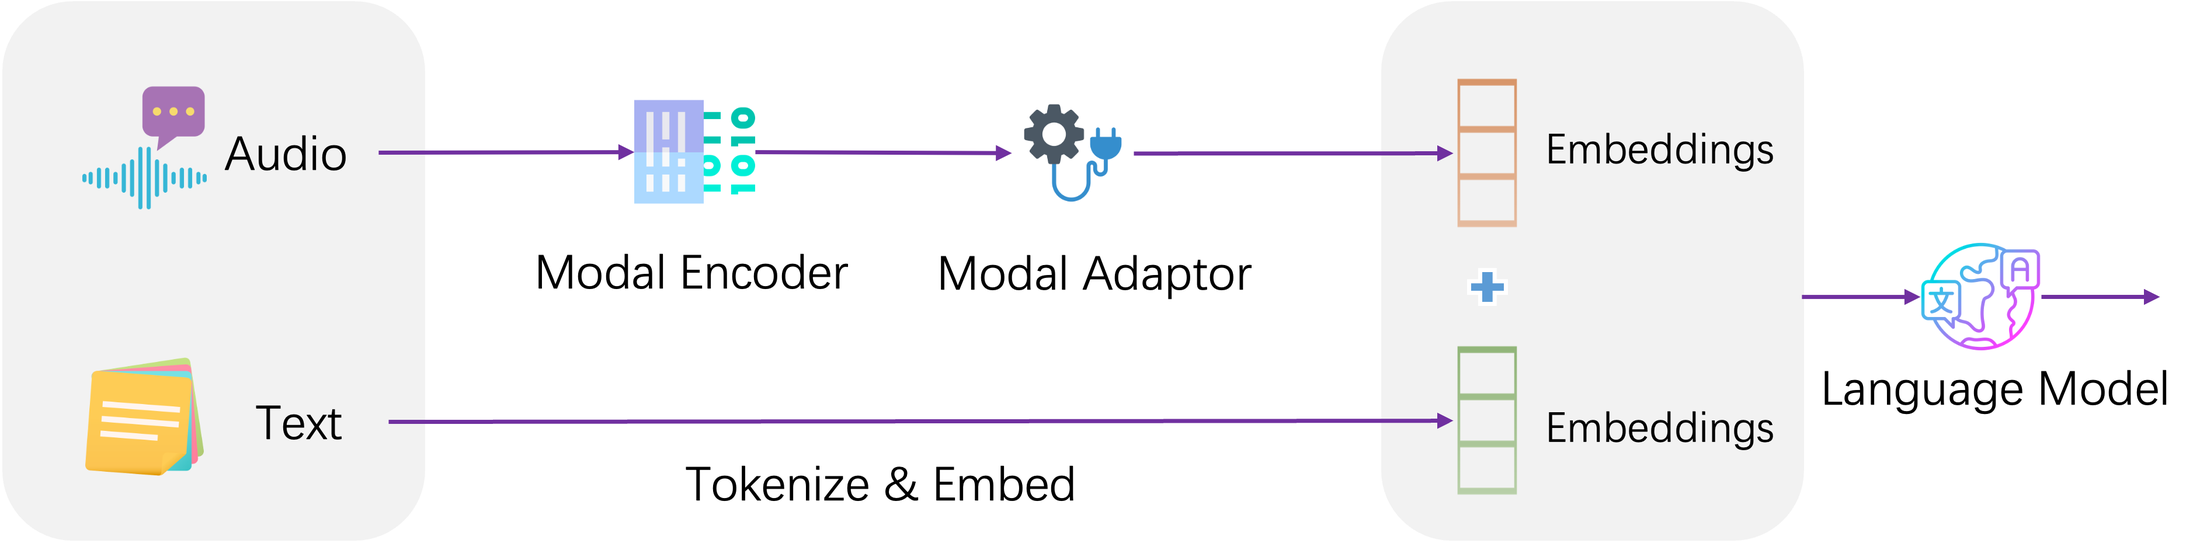
Figure 1 · Source
LongCat-Flash-Omni
Understands text, images, video and audio and produces text or spoken responses.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
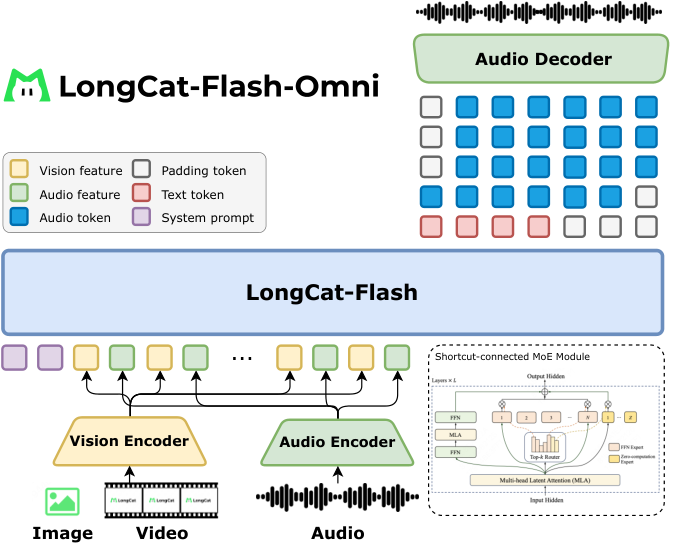
Figure 2 · Source
LongCat-Next
Understands and generates text, images and audio within one multimodal model.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
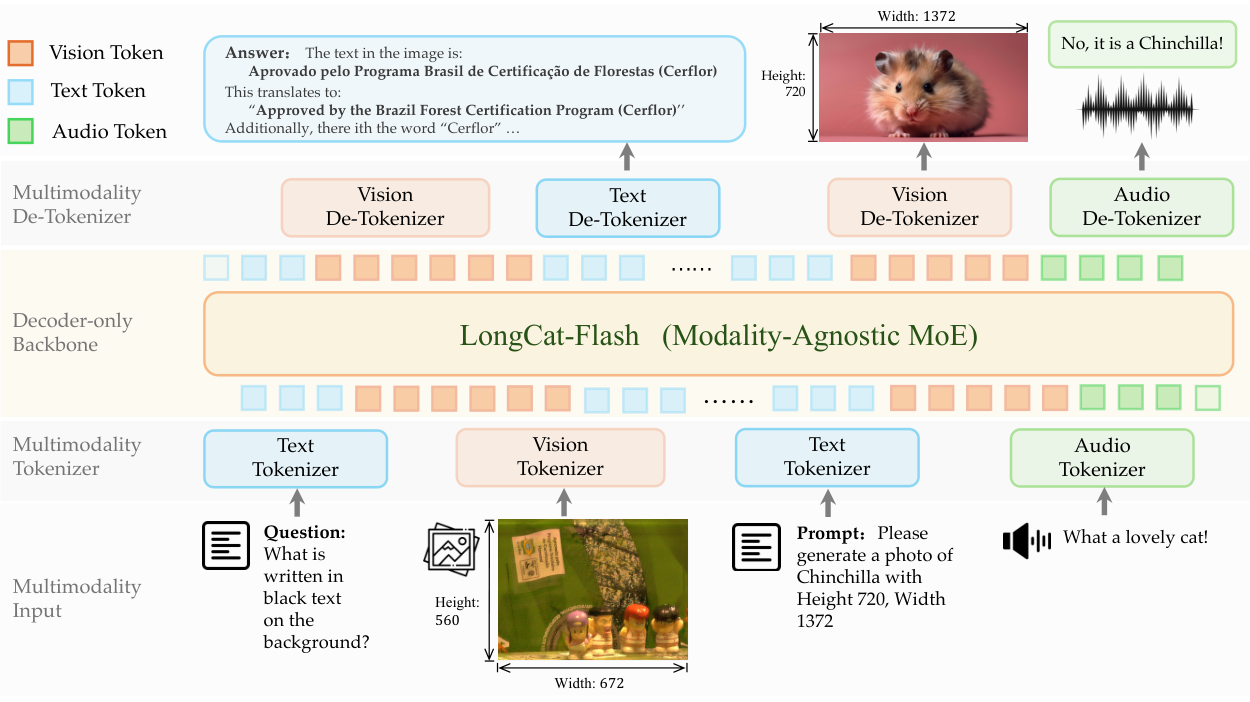
Figure 2 · Source
Lychee-FD
Listens and speaks continuously while deciding when to respond, stop or handle interruptions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
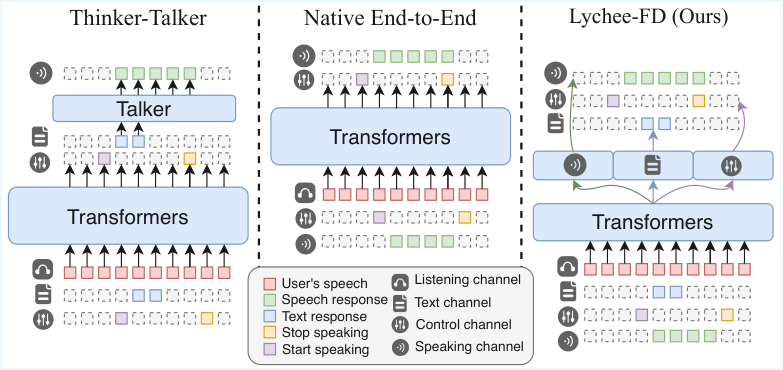
Figure 3 · Source
Lyra-Base
Handles long speech, audiovisual questions and spoken dialogue with a 9B configuration.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-4.0 — The repository limits model weights to noncommercial research despite the model-card badge.
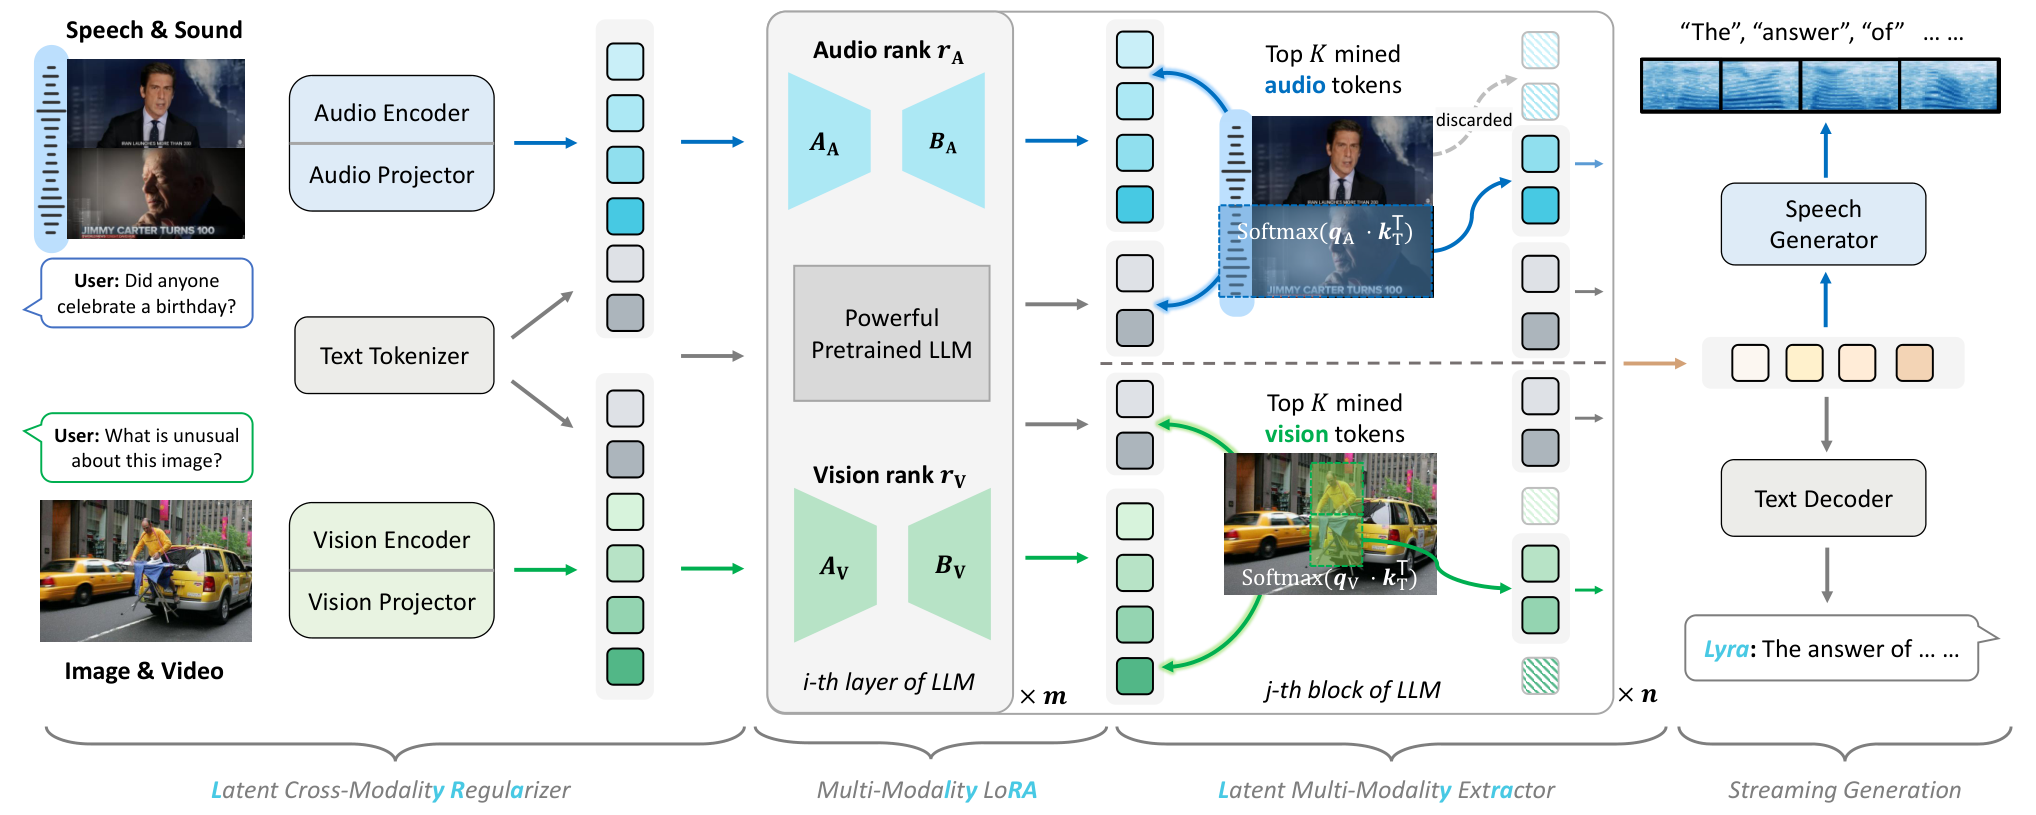
Figure 2 · Source
Lyra-Mini
Offers audiovisual understanding and spoken interaction in Lyra's smaller 3B configuration.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-4.0 — The repository limits model weights to noncommercial research despite the model-card badge.
Family figure — Figure 2 · Source
Mair-hub-0.5B-Omni
Provides a small speech-to-speech assistant trained with a reproducible Qwen-Omni-like recipe.
License unclear: code Apache-2.0 · weights Not stated — The training recipe is Apache-2.0; the published checkpoint does not state a weight license.
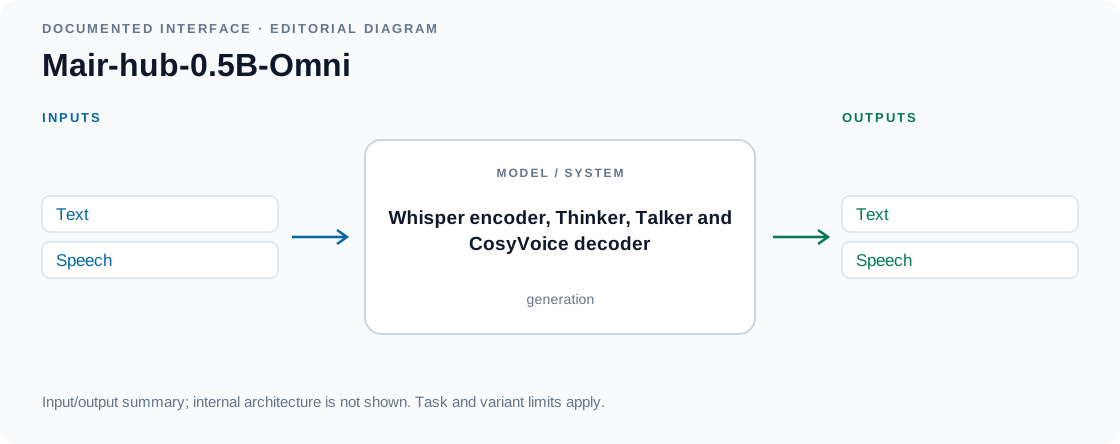
Input/output diagram · Source
Megrez-Omni
Answers questions about pictures and audio using a compact 3B language backbone.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
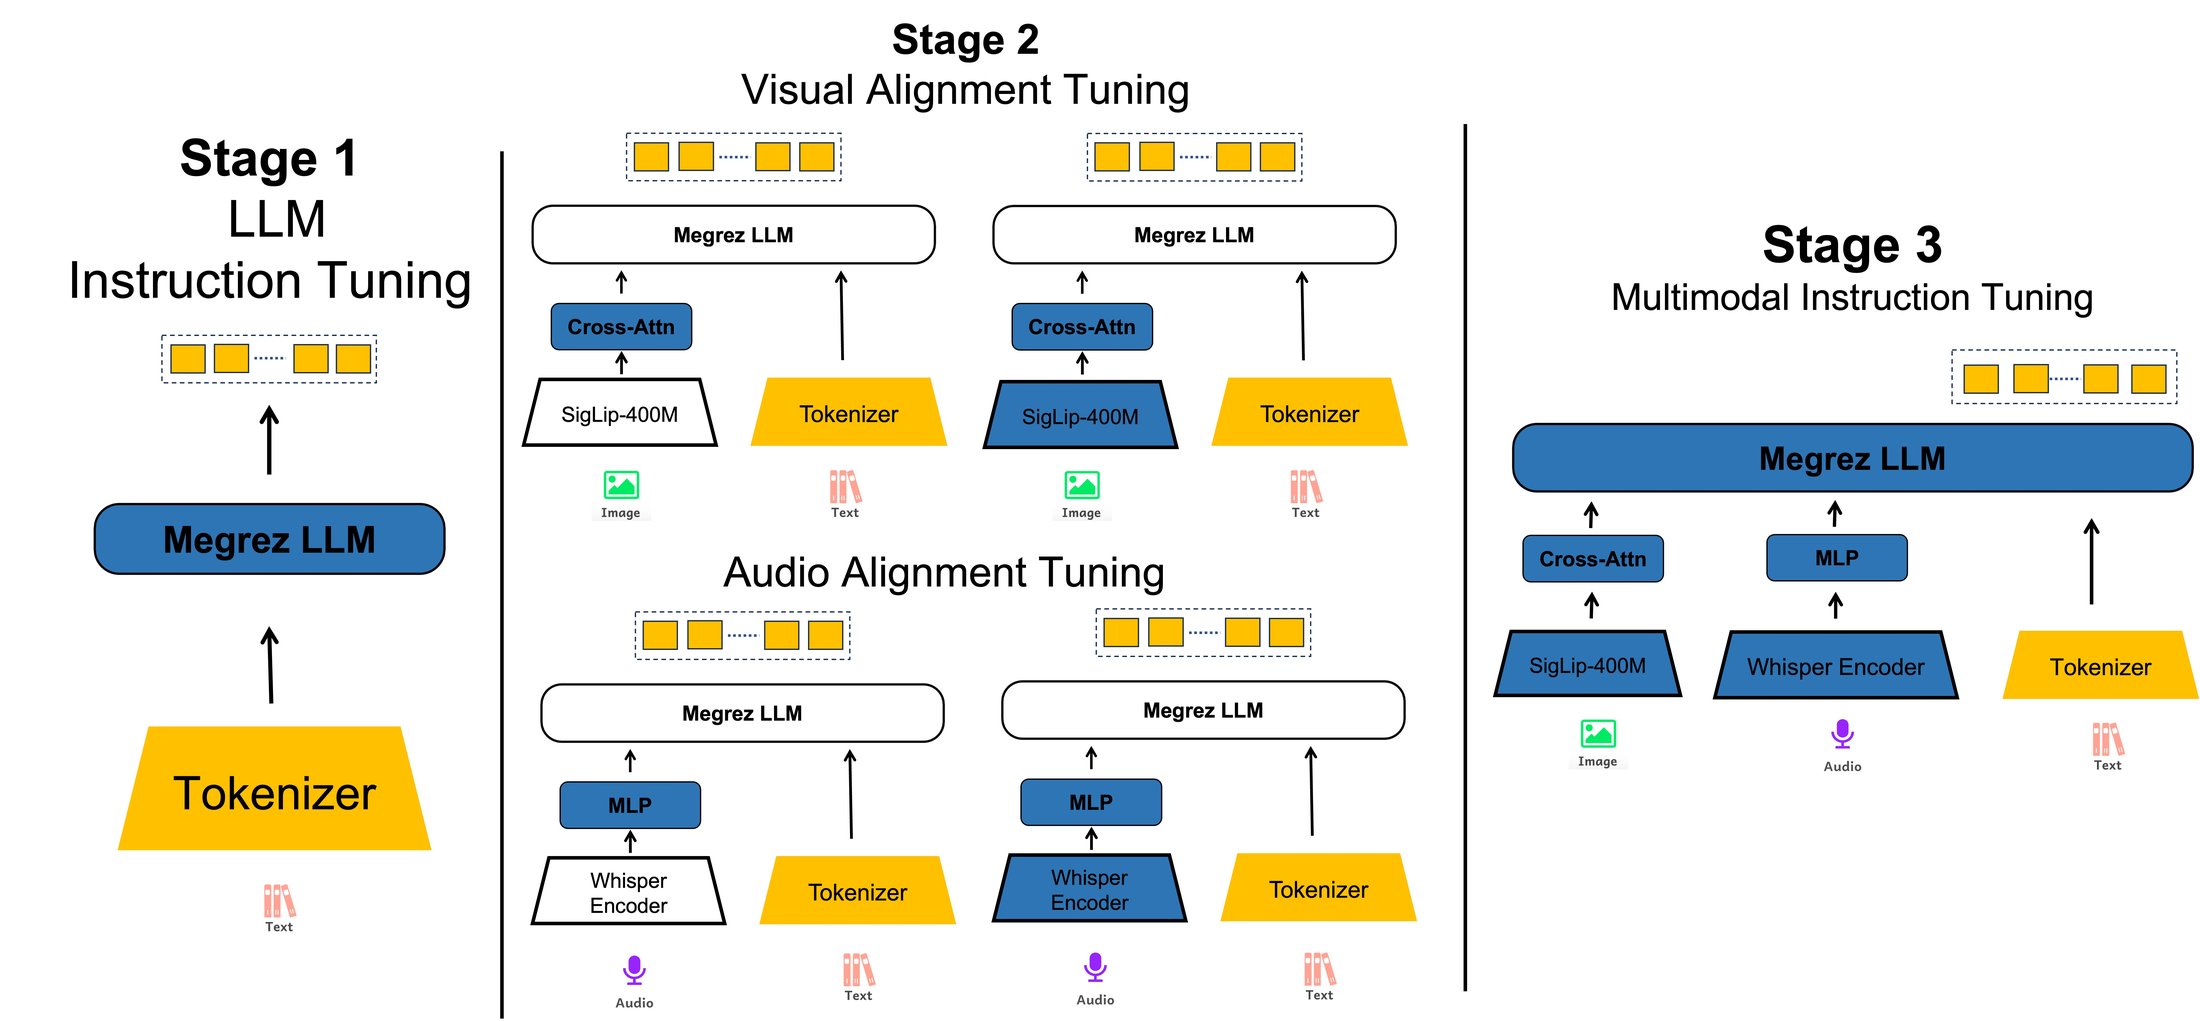
Figure 2 · Source
Mellow
Uses reasoning over audio to answer questions that require more than recognizing a sound.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
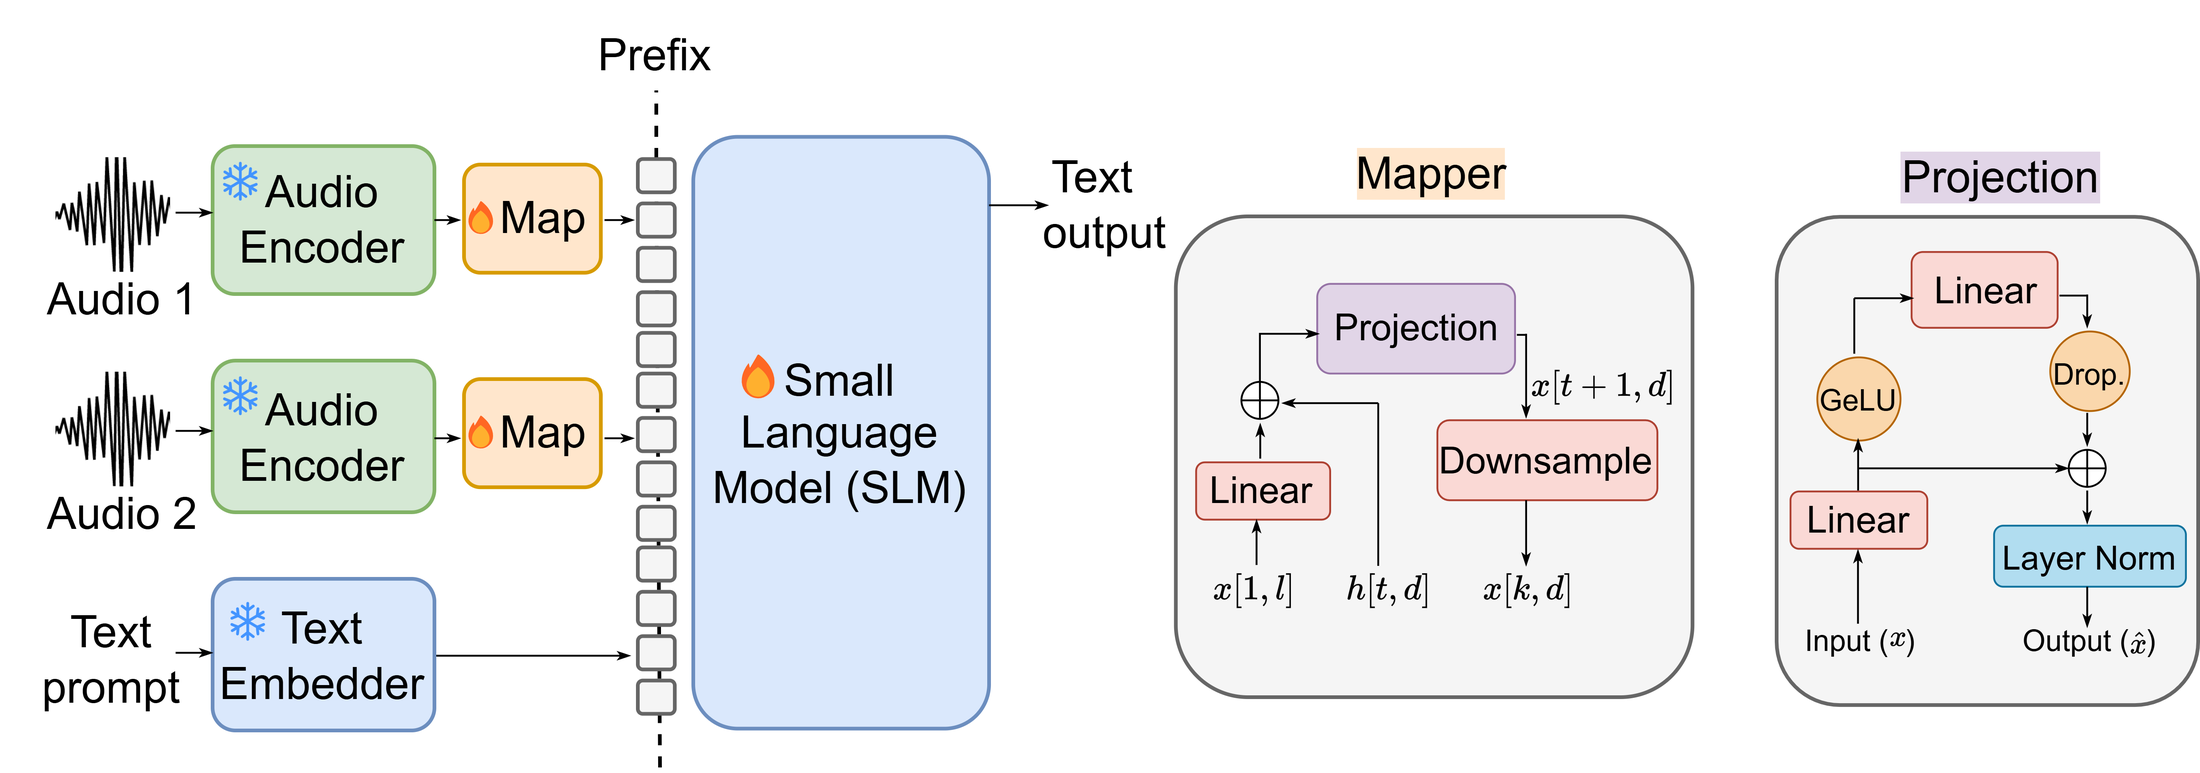
Figure 2 · Source
MERaLiON 2
Understands multilingual Southeast Asian speech, code-switching, emotion and audio scenes.
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
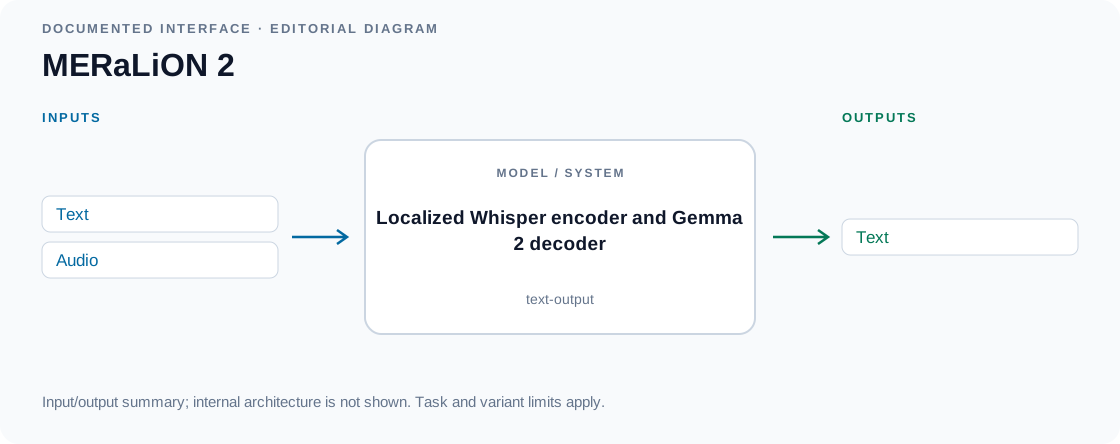
Input/output diagram · Source
MERaLiON 3
Understands multilingual Southeast Asian speech, including local dialects and conversational code-switching.
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
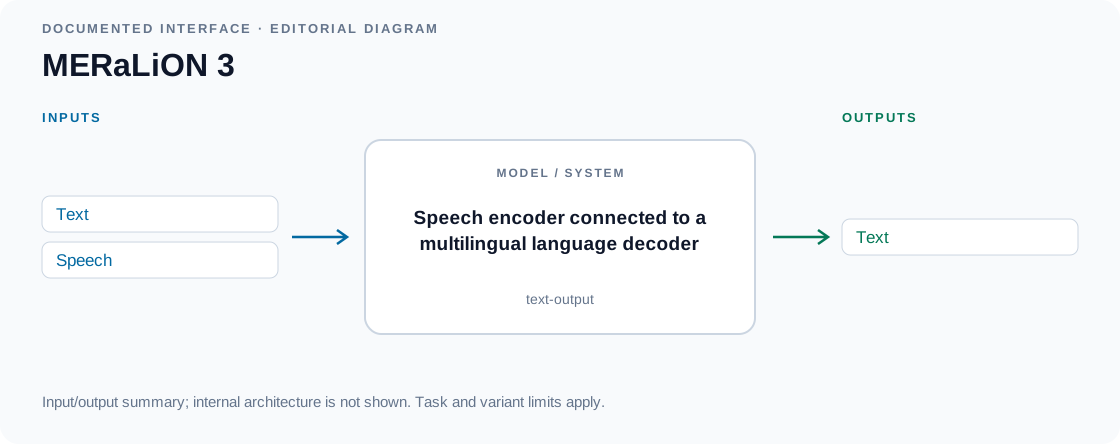
Input/output diagram · Source
MERaLiON 3 ASR
Transcribes Southeast Asian languages, regional dialects and code-switched speech.
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
Input/output diagram · Source
MERaLiON-AudioLLM
Transcribes, translates and explains audio, including Singaporean speech and local language usage.
Paper · Code · Weights · Details
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
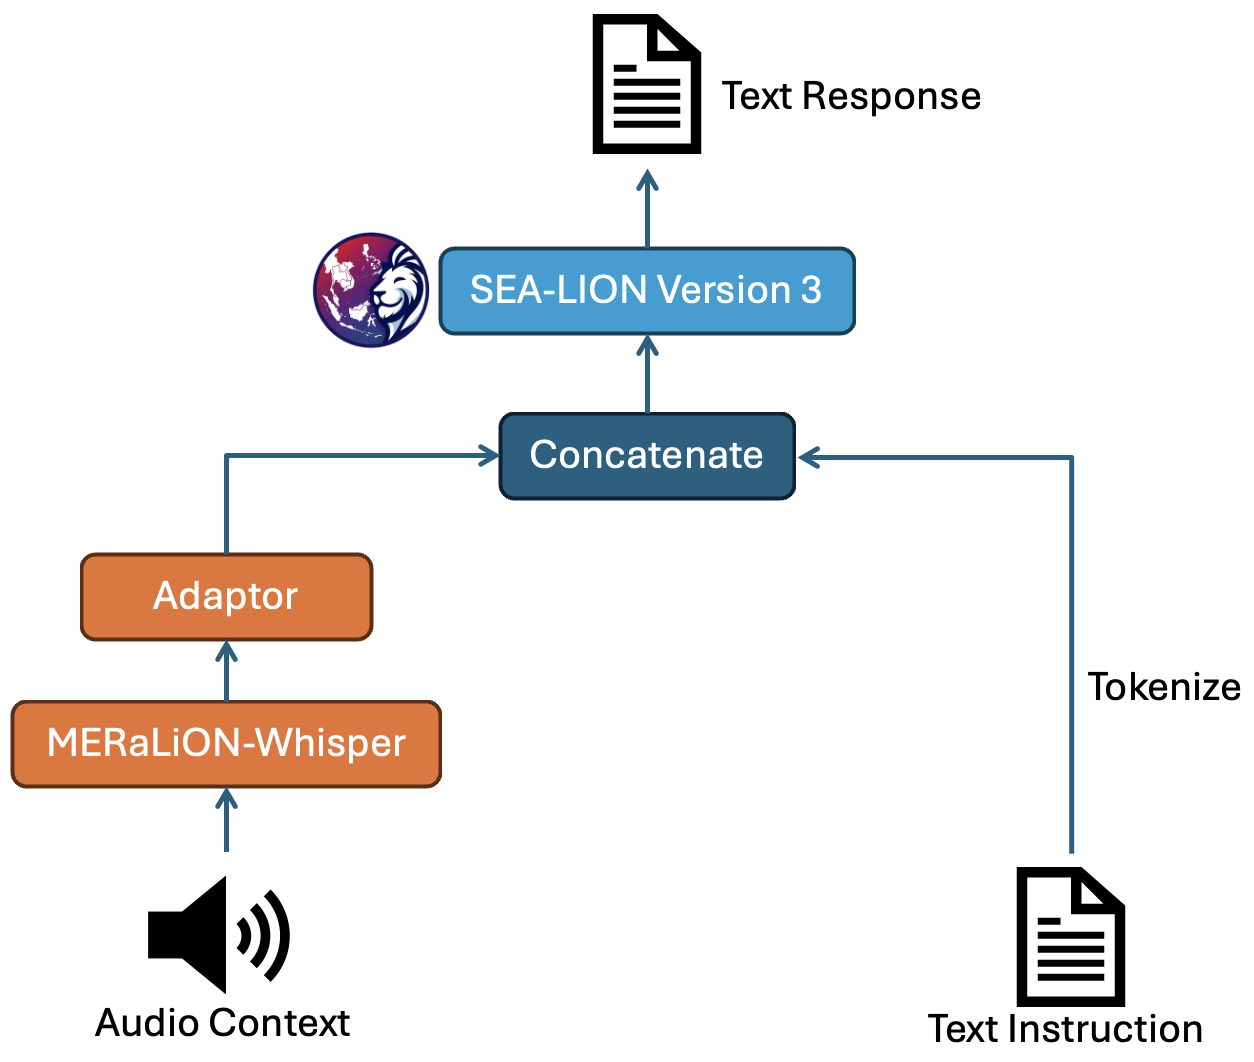
Figure 1 · Source
MiDashengLM
Describes speech, environmental sounds and music and answers questions about recordings.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
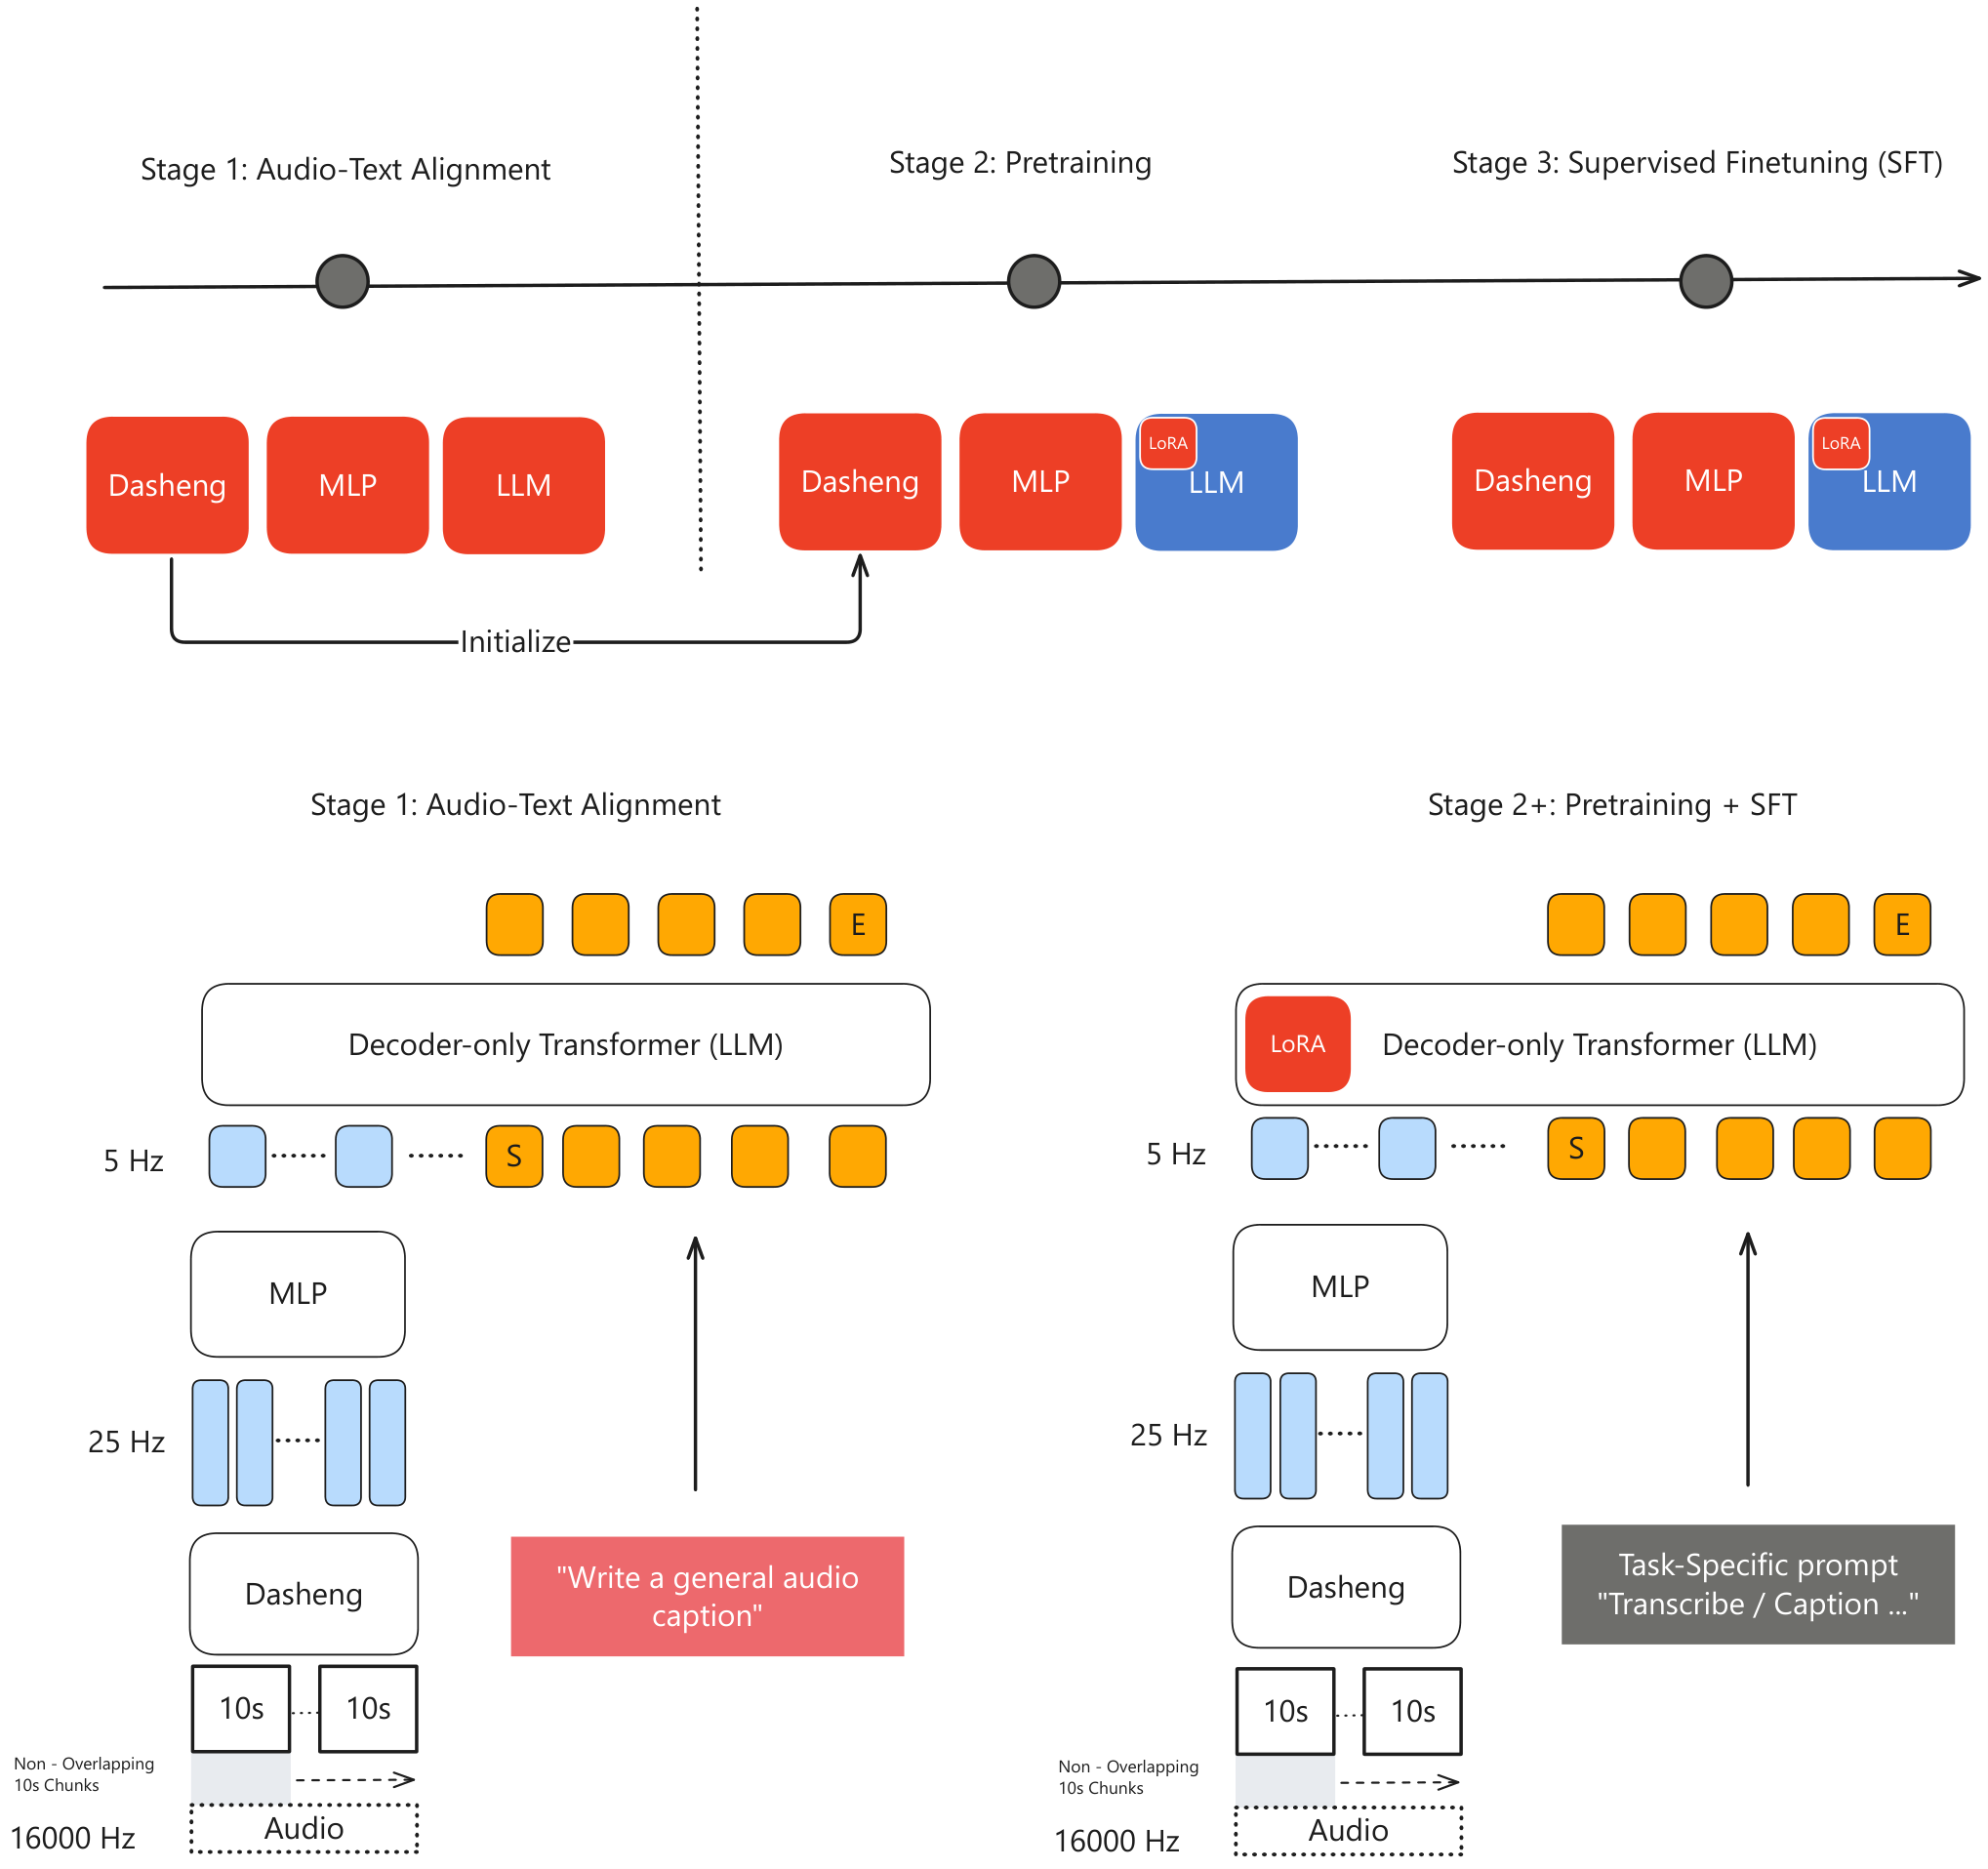
Figure 2 · Source
MiMo-Audio
Understands recordings and conducts spoken conversations using instructions and audio examples.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights MIT
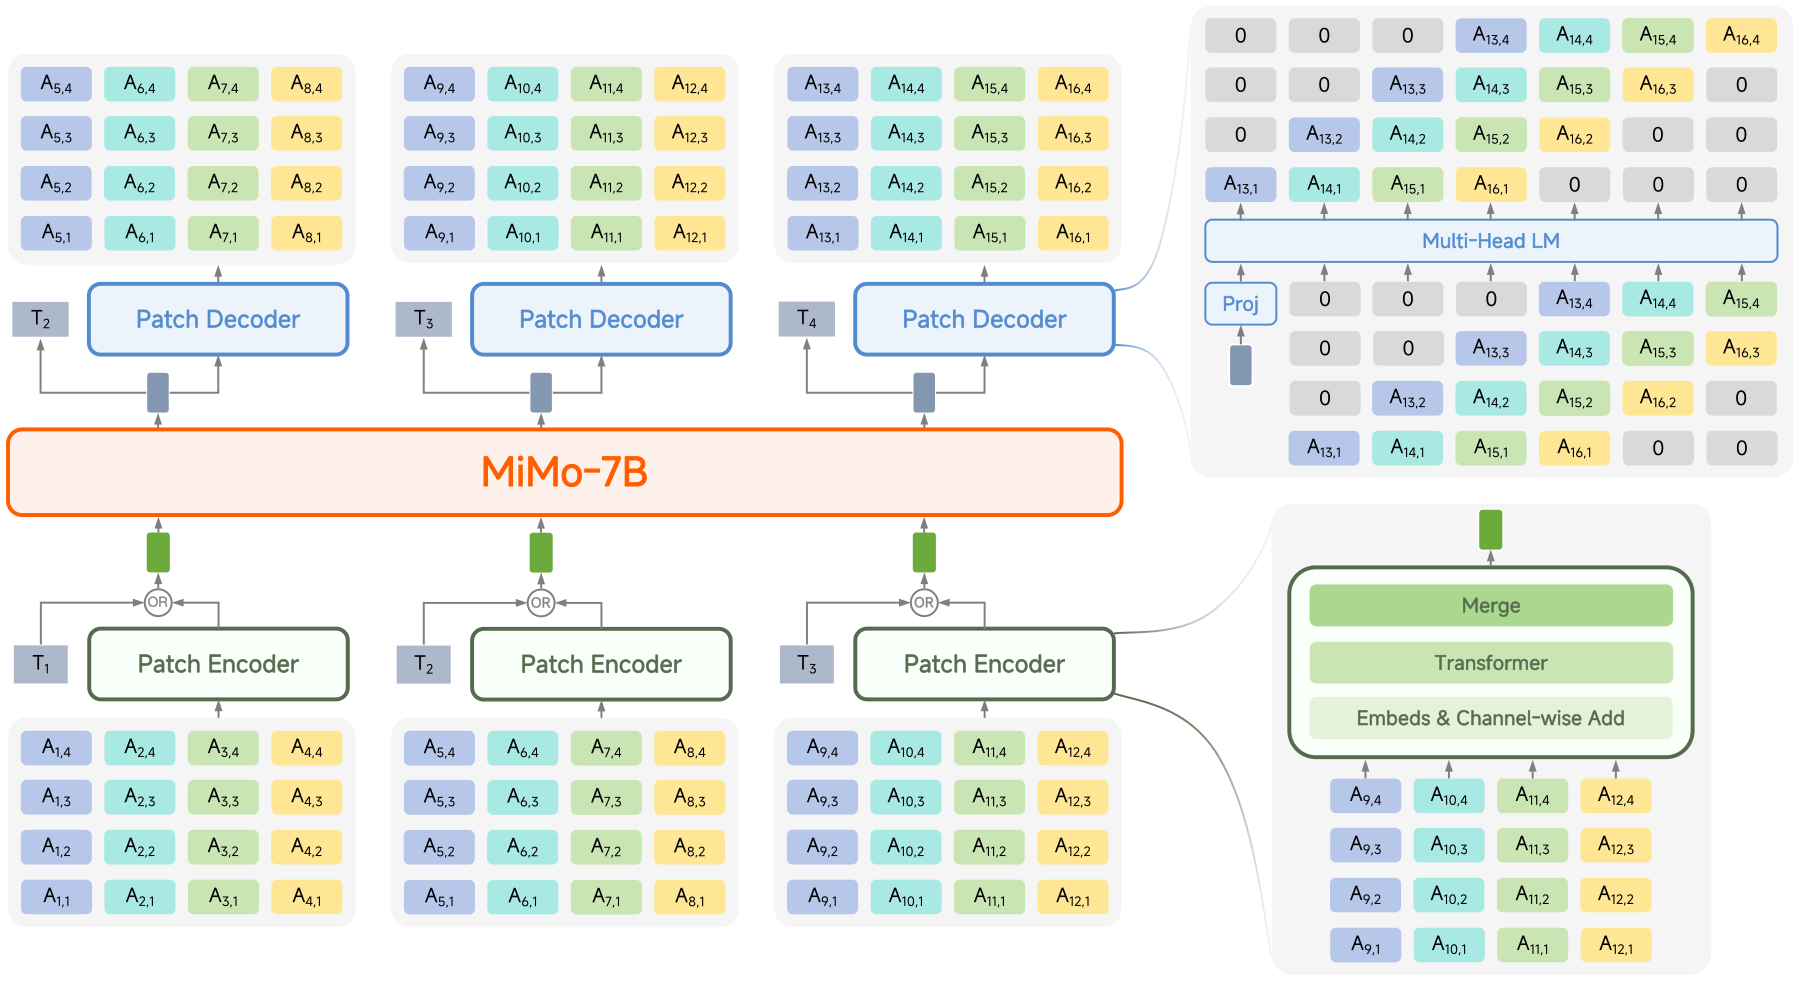
Figure 3 · Source
MiMo-V2.5
Answers questions and follows instructions involving text, images, videos and audio.
Open license: code Apache-2.0 · weights MIT
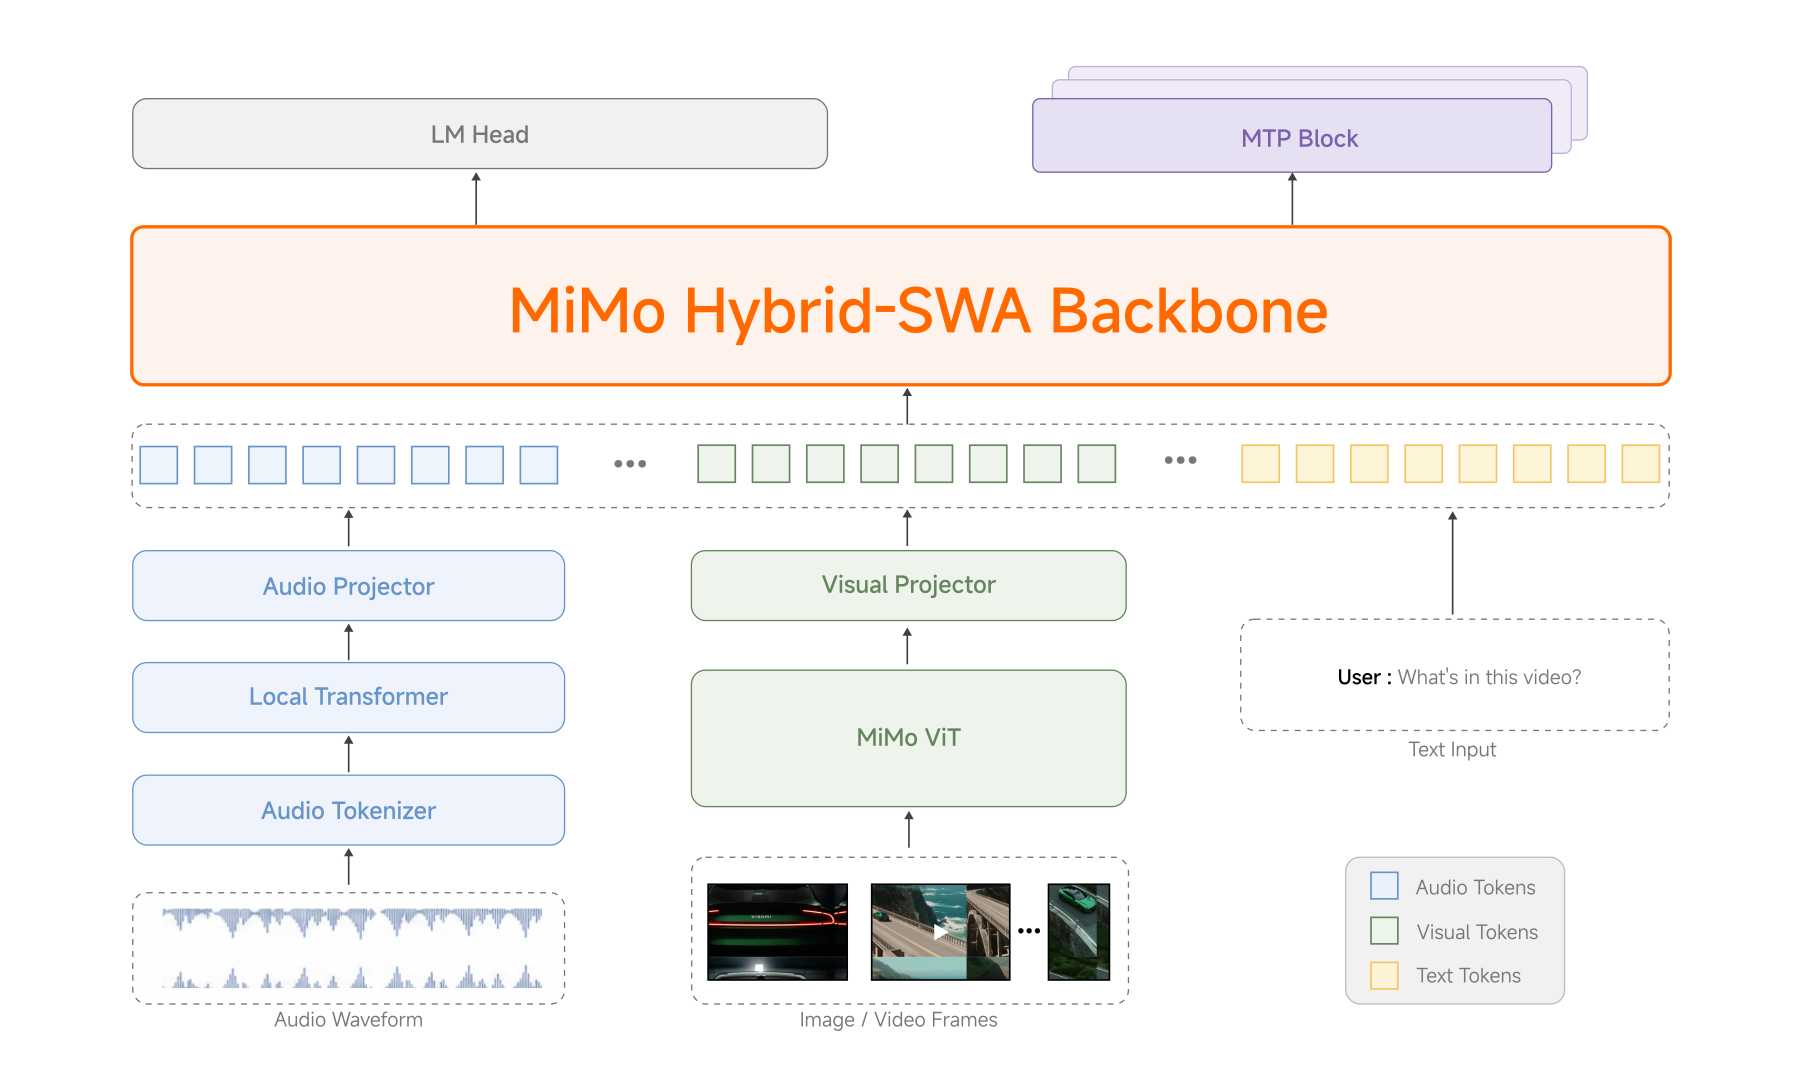
Official architecture diagram · Source
Ming-Flash-Omni
Combines audiovisual understanding with text, image and audio generation.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
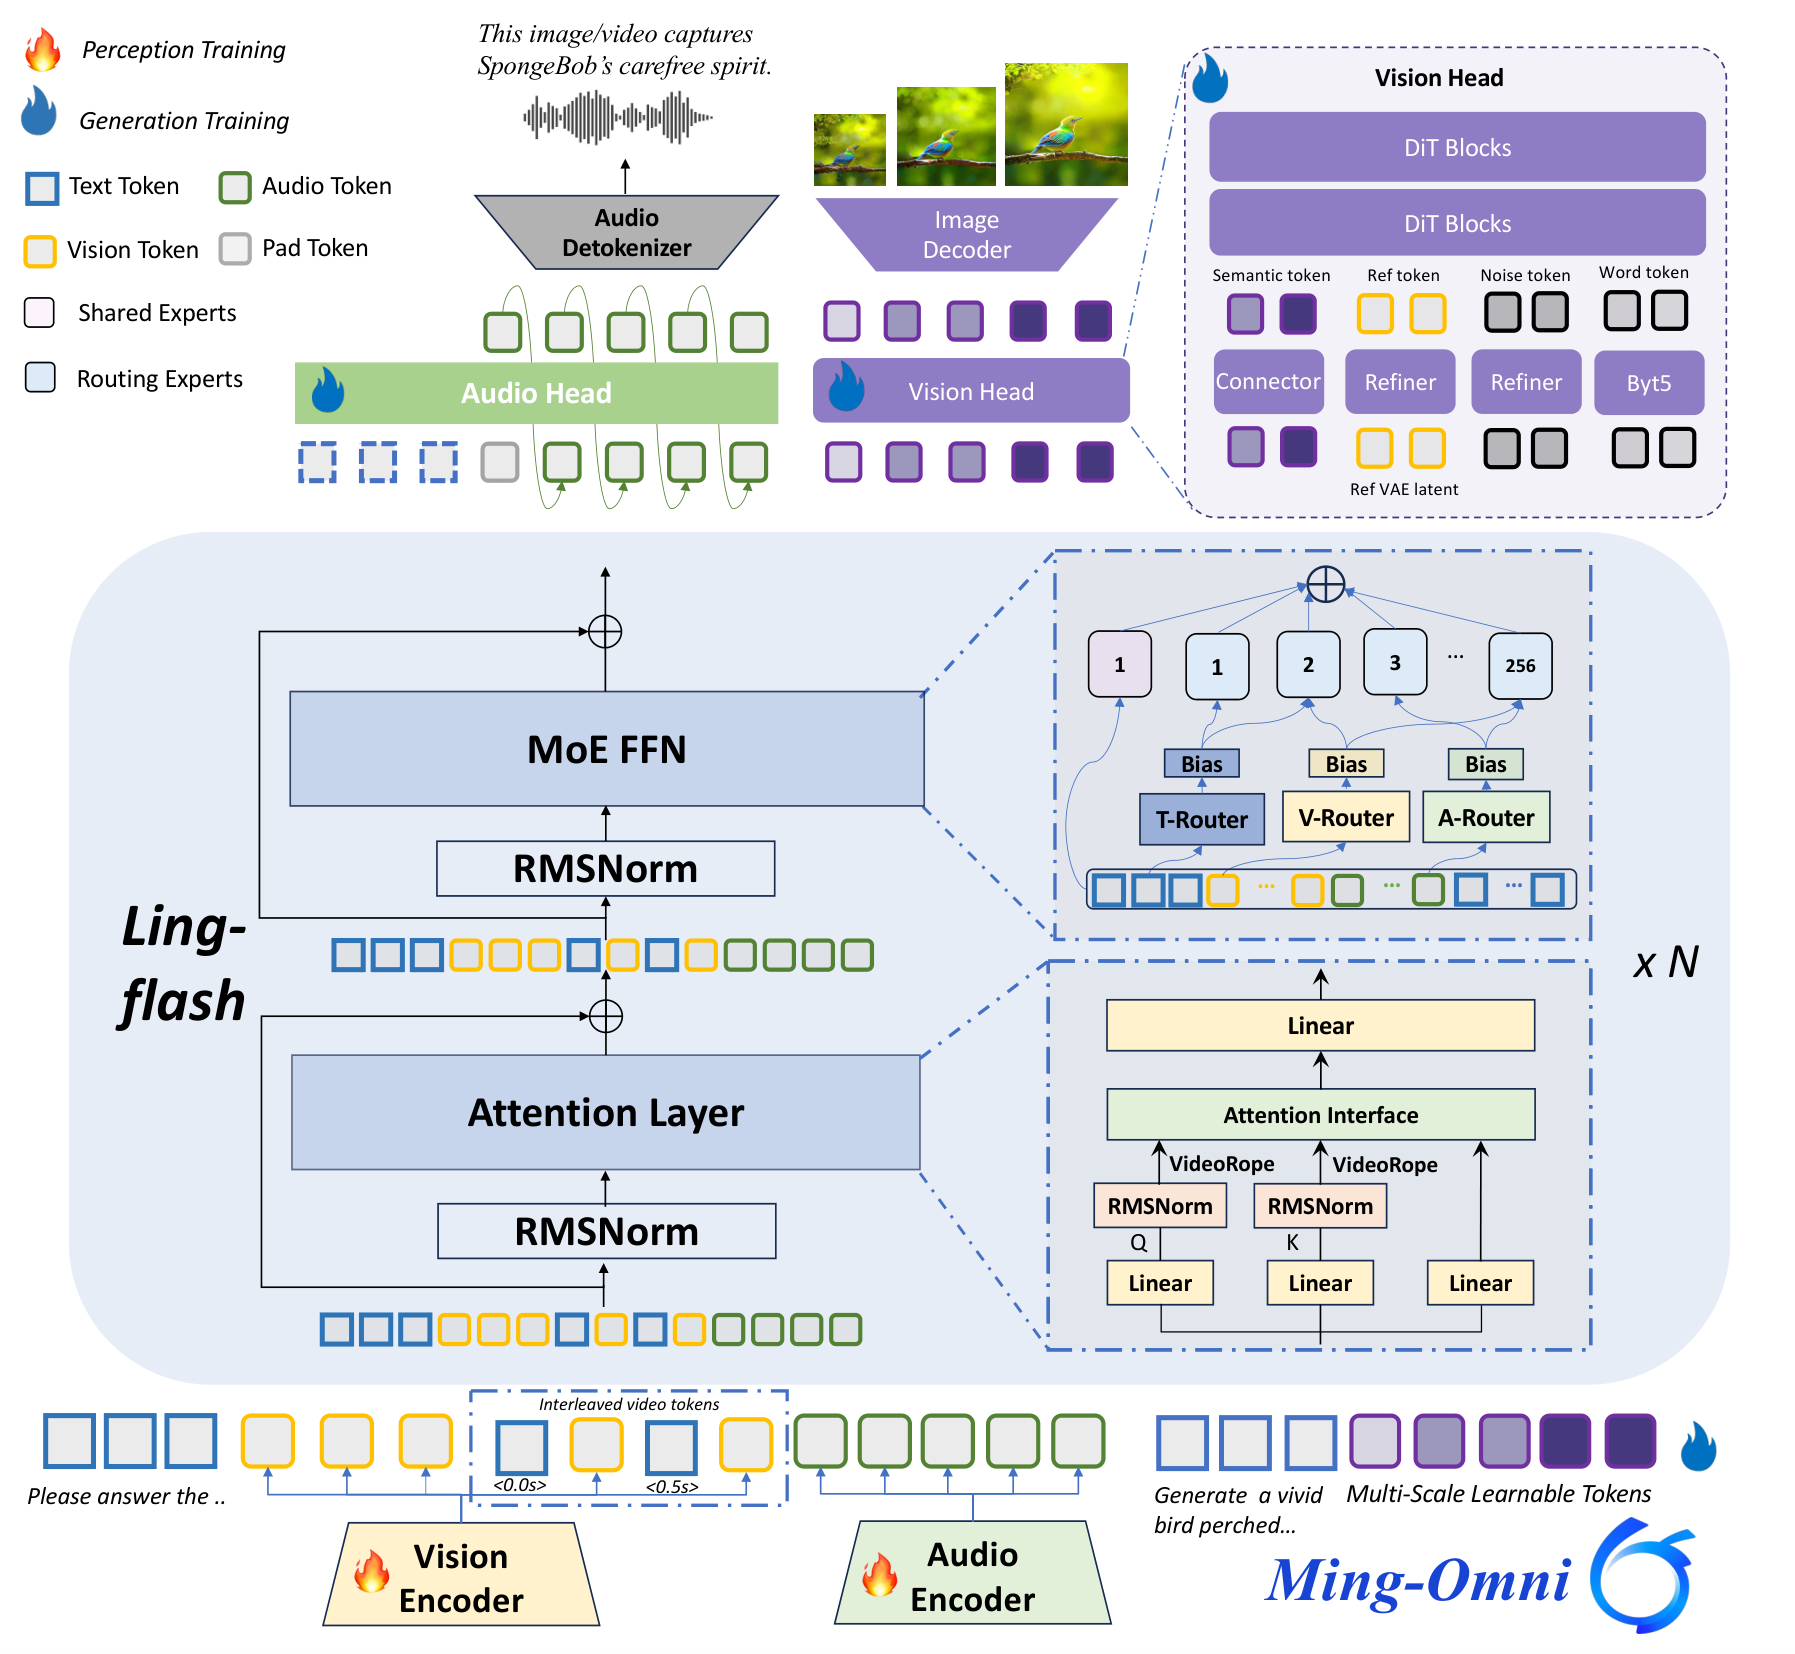
Figure 2 · Source
Ming-Flash-Omni 2.0
Interprets mixed audiovisual inputs and generates text, images or expressive audio.
Open license: code MIT · weights MIT
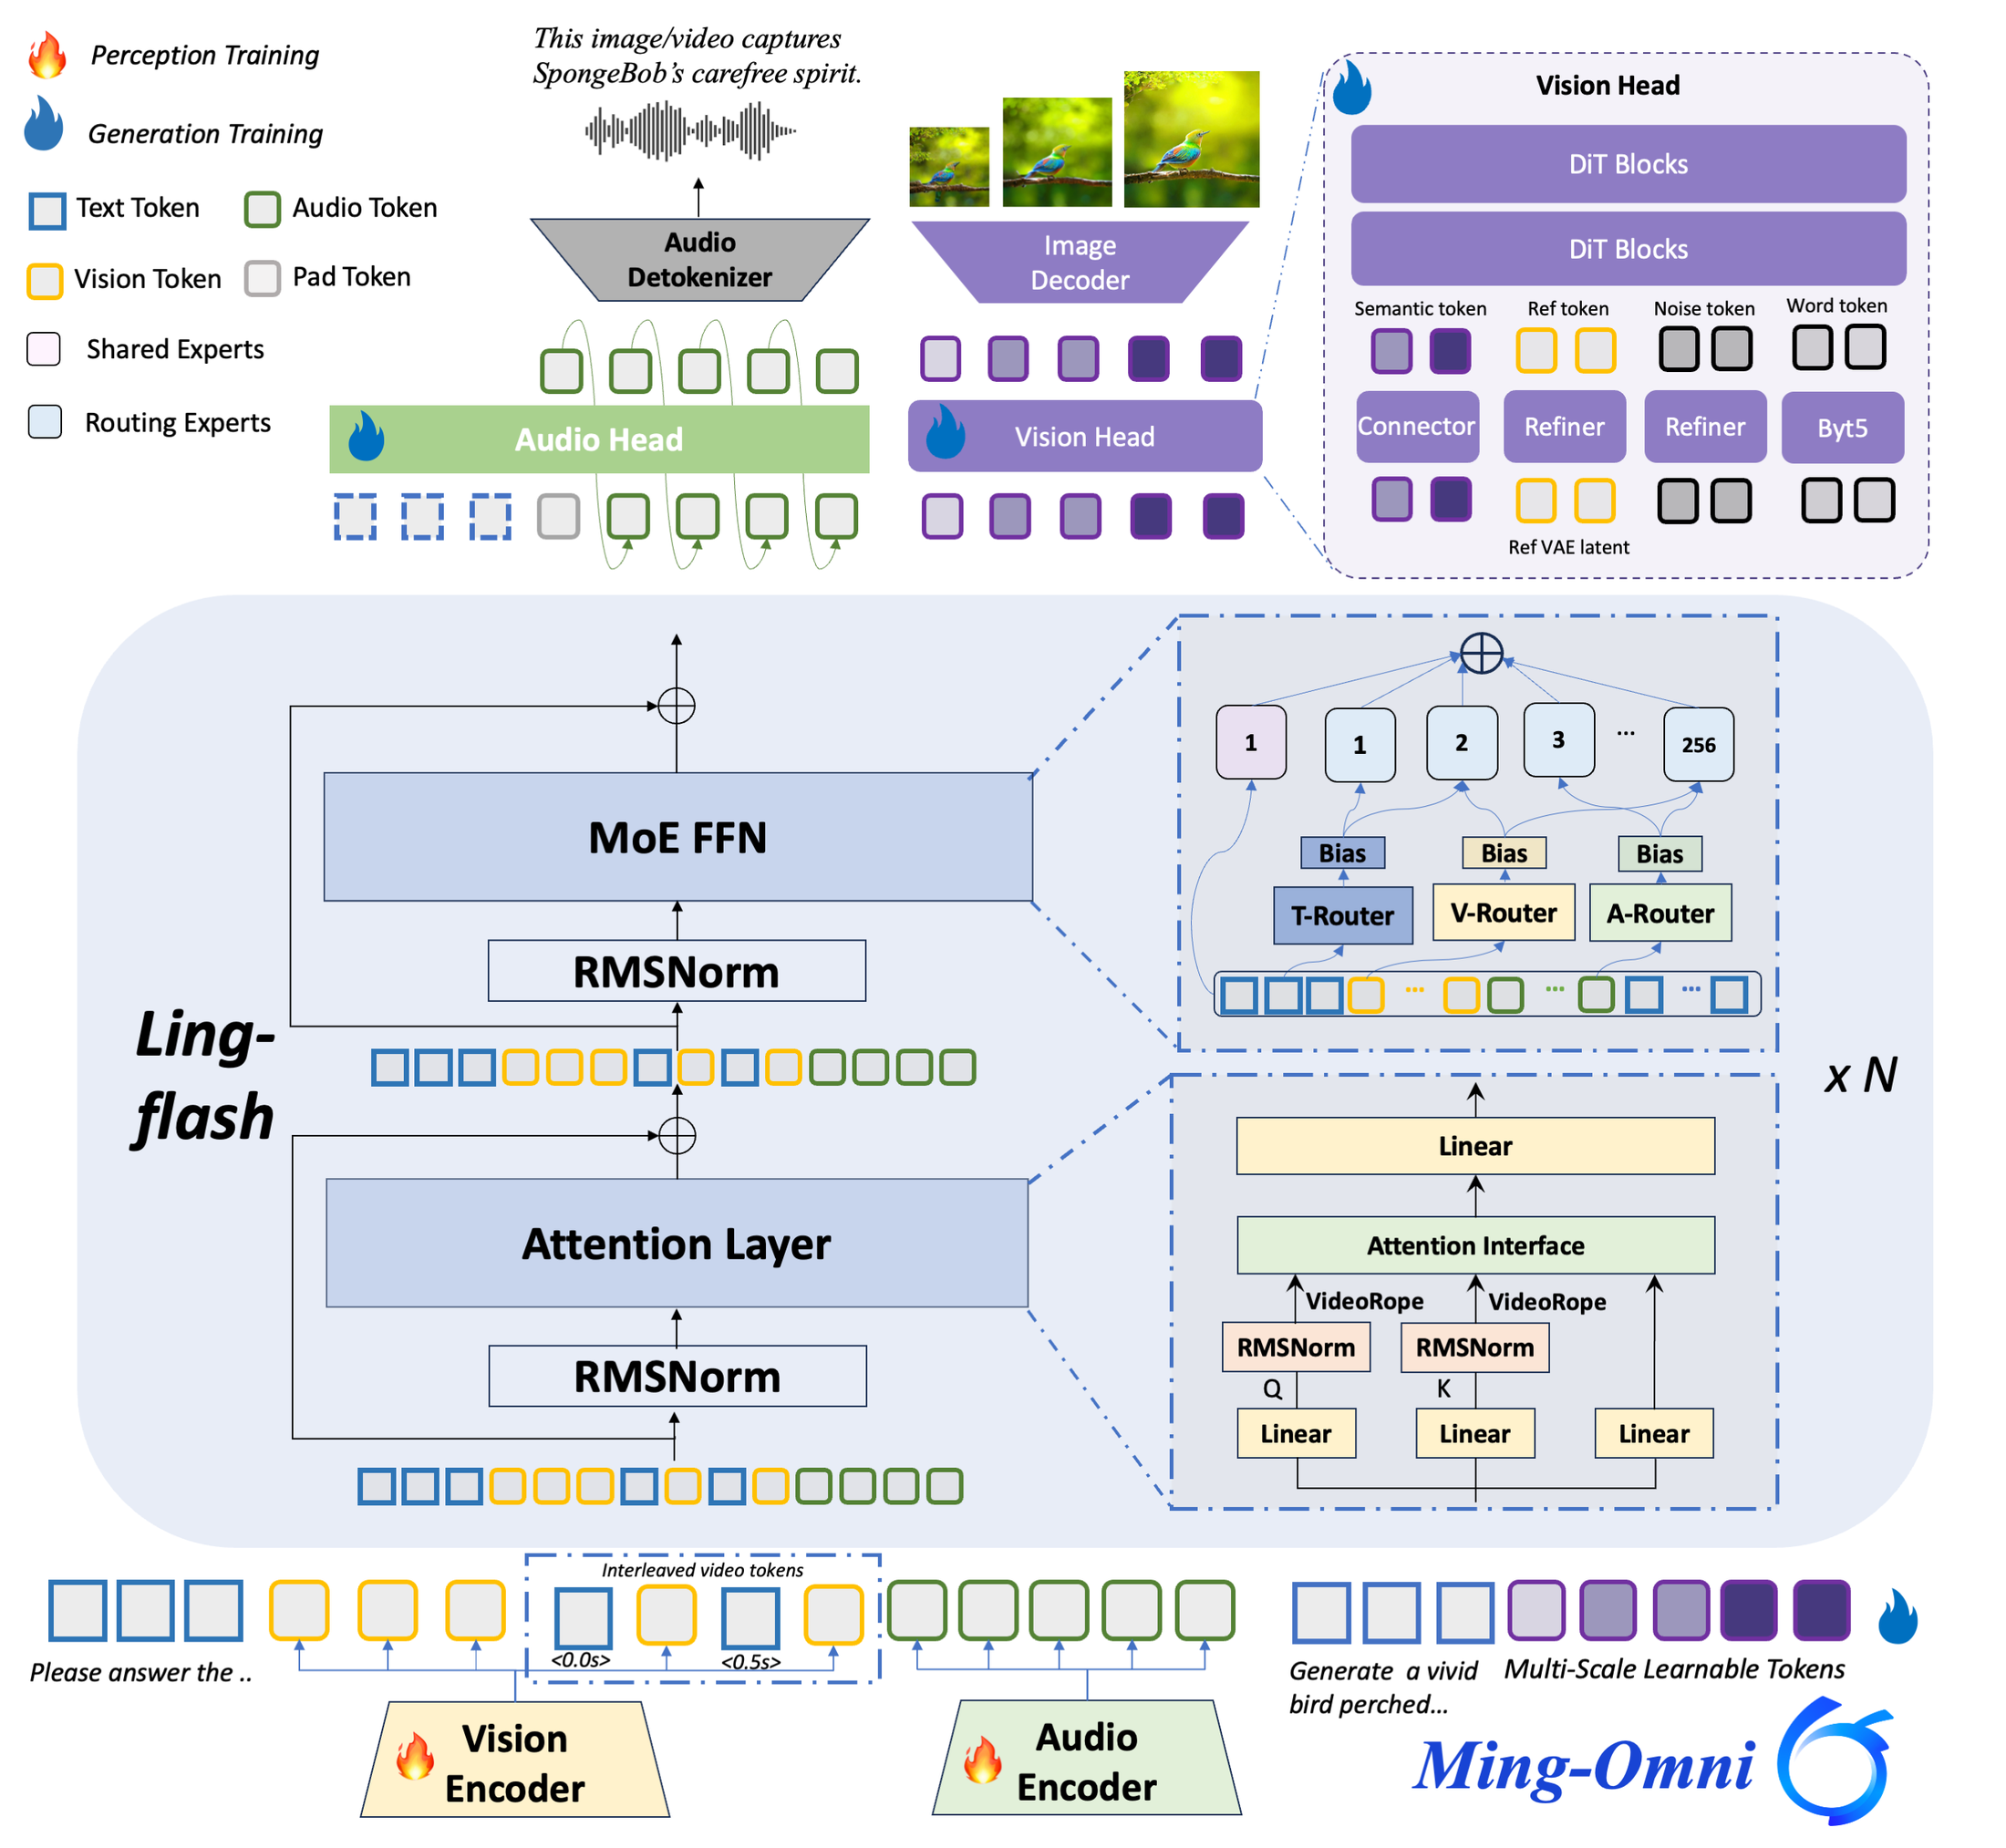
Official architecture diagram · Source
Ming-Lite-Omni
Handles audiovisual questions and creates text, images and spoken responses.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
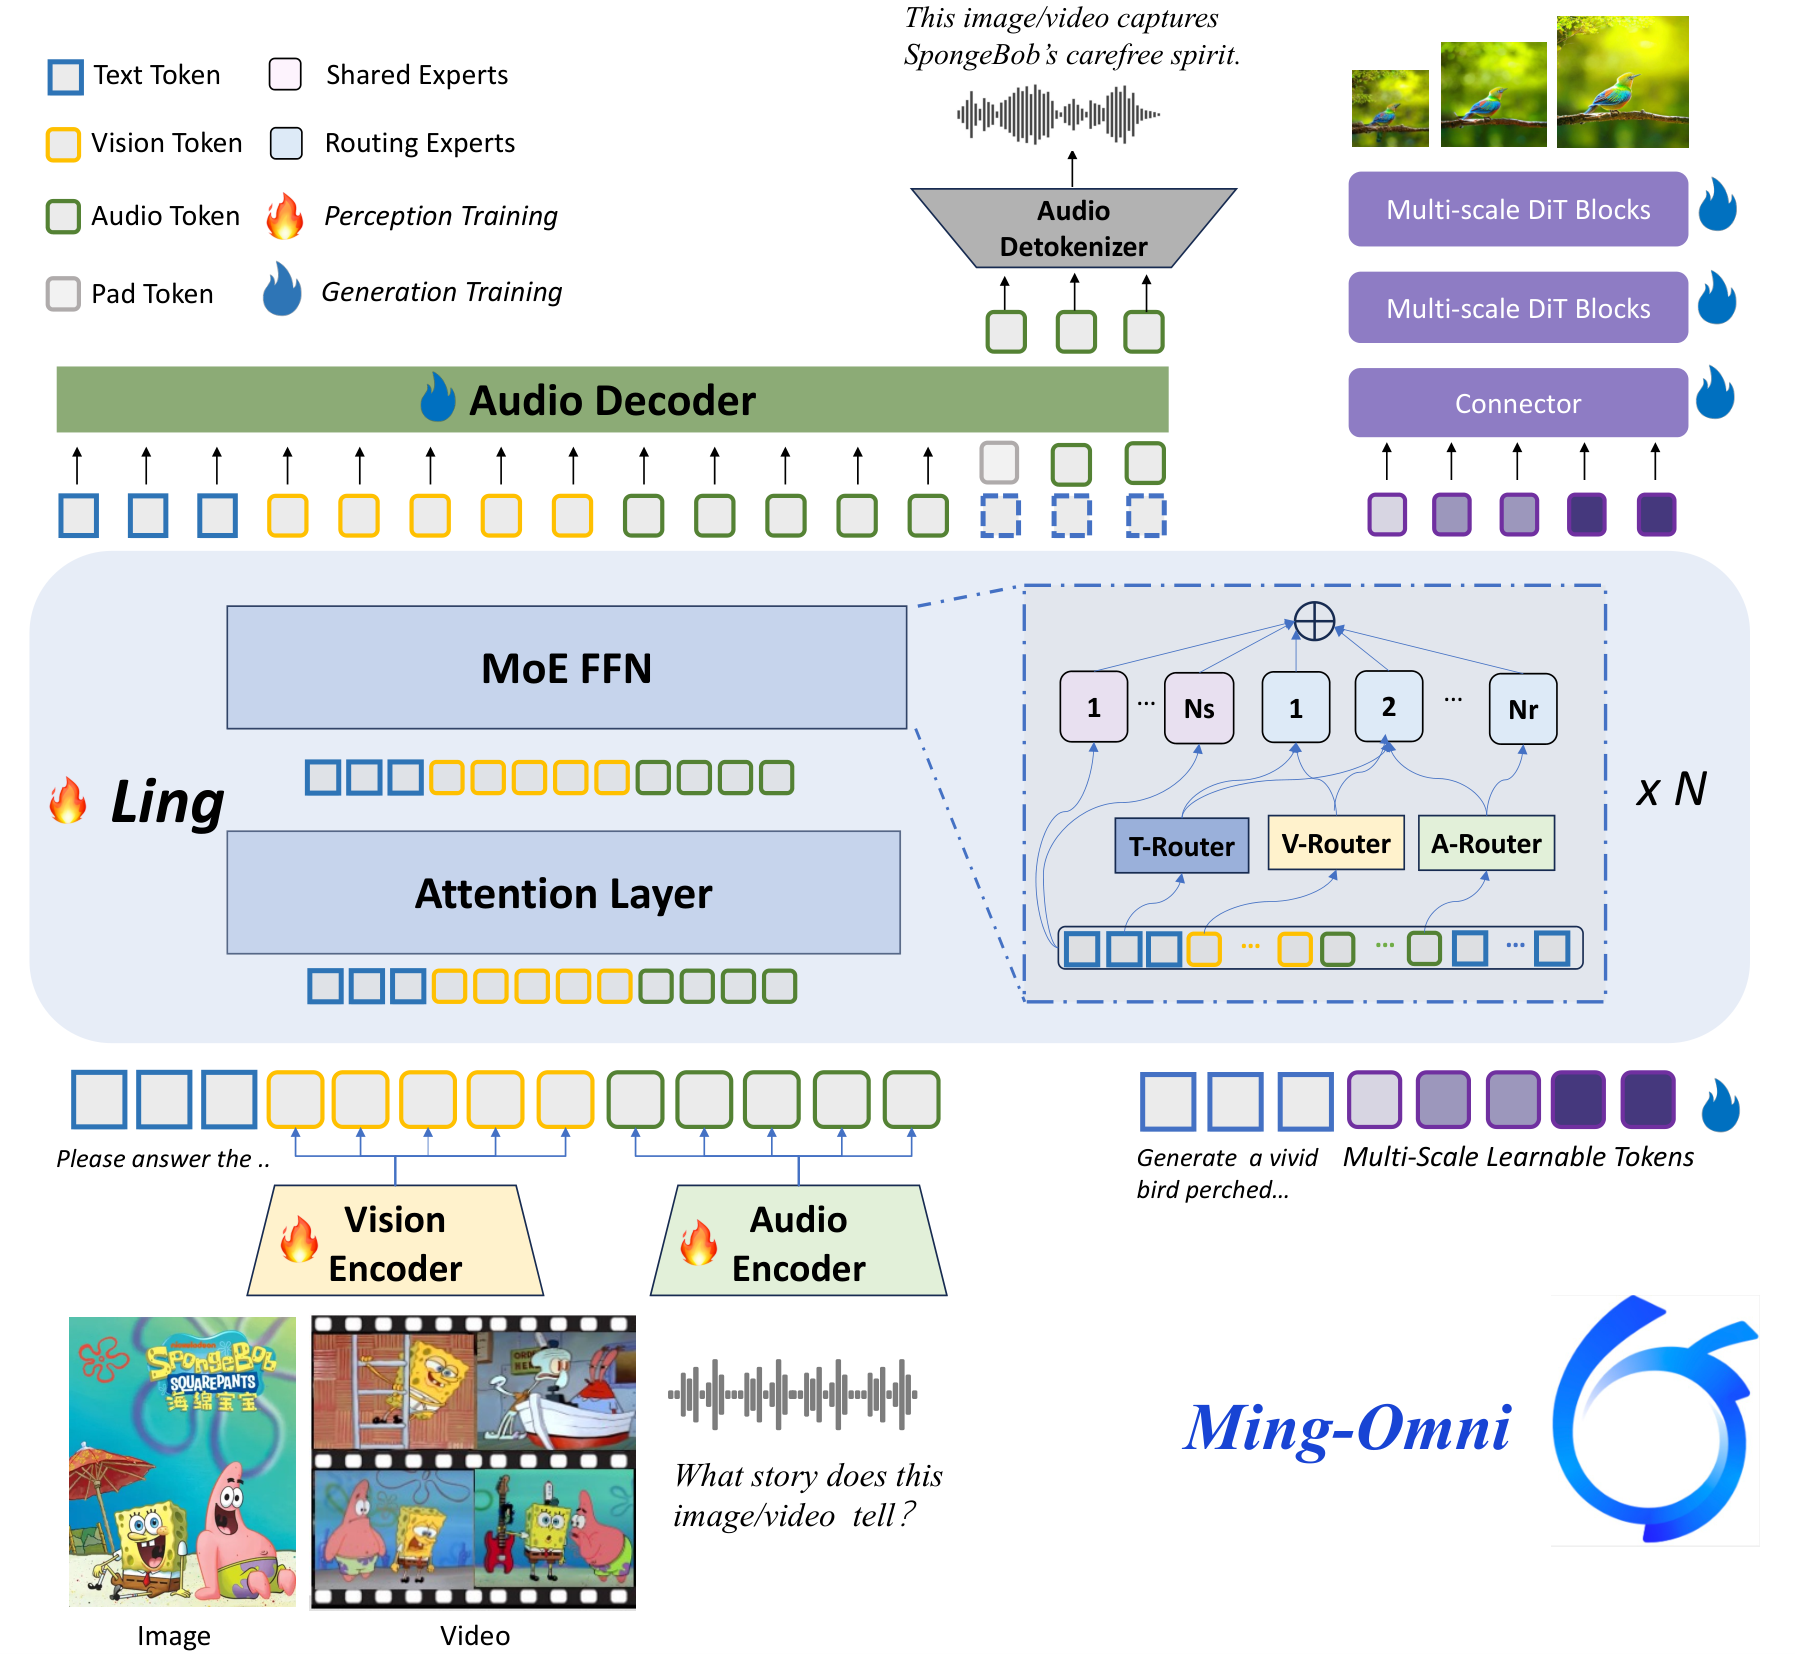
Family figure · Figure 2 · Source
Mini-Omni
Listens to spoken questions and streams text and speech answers together.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
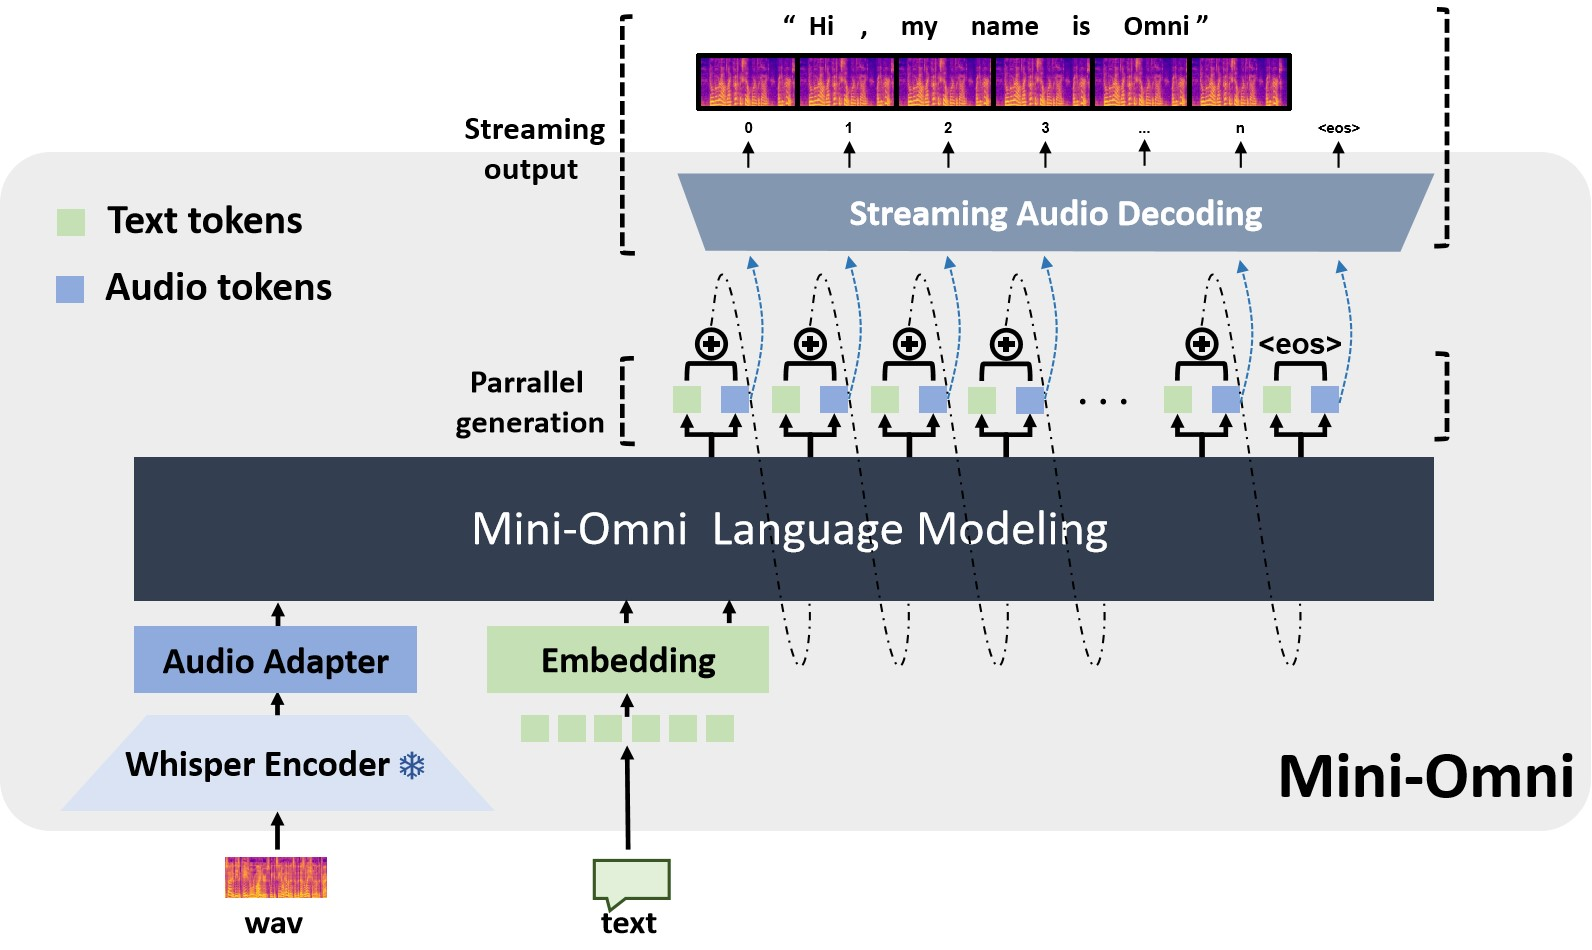
Figure 1 · Source
Mini-Omni2
Sees images, follows spoken instructions and streams spoken replies with interruption handling.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
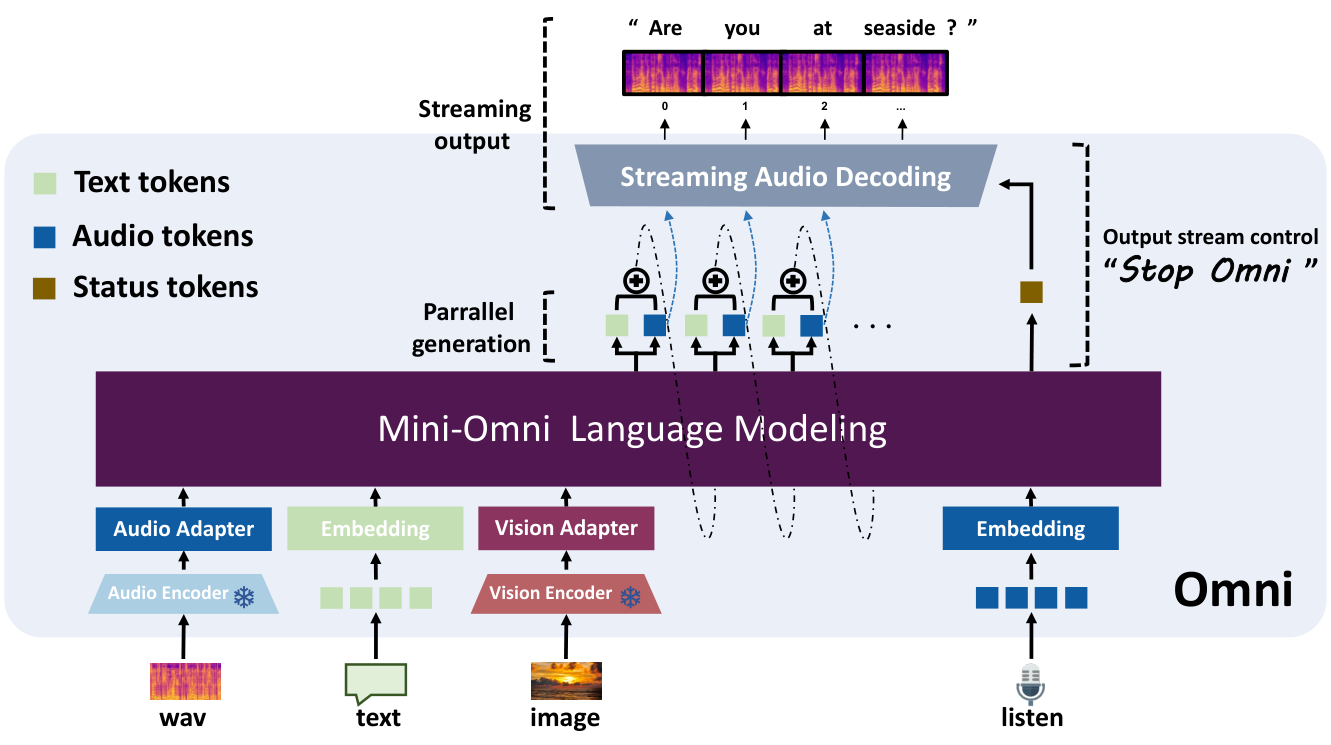
Figure 1 · Source
MiniCPM-o 2.6
Chats about images, video and audio, with speech output and voice imitation.
Open license: code Apache-2.0 · weights Apache-2.0
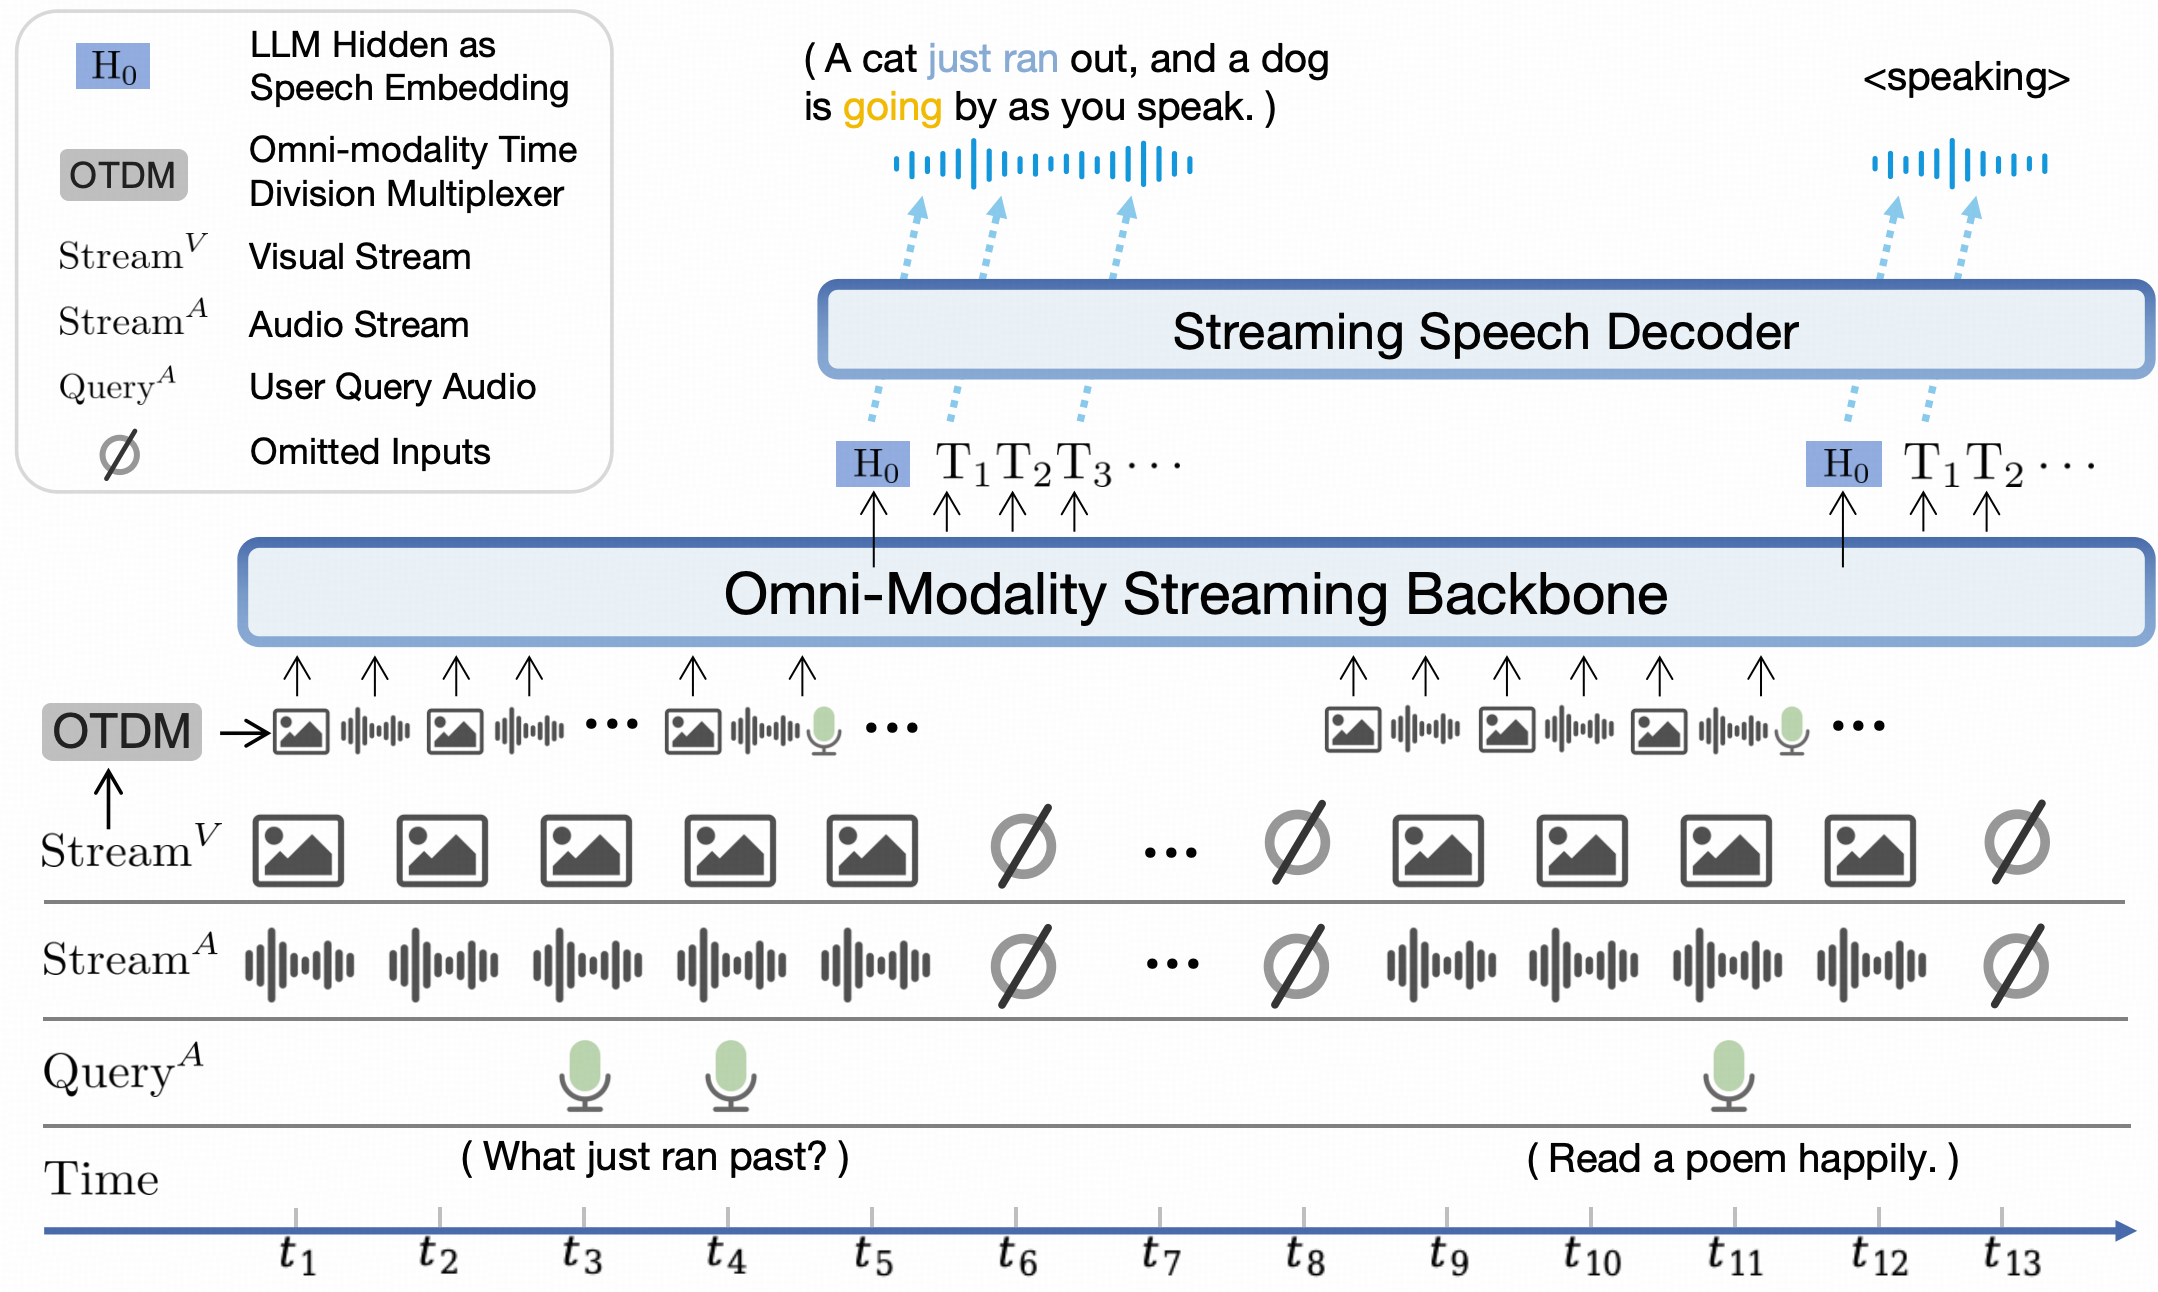
Official architecture diagram · Source
MiniCPM-o 4.5
Supports live audiovisual conversations while listening and speaking at the same time.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
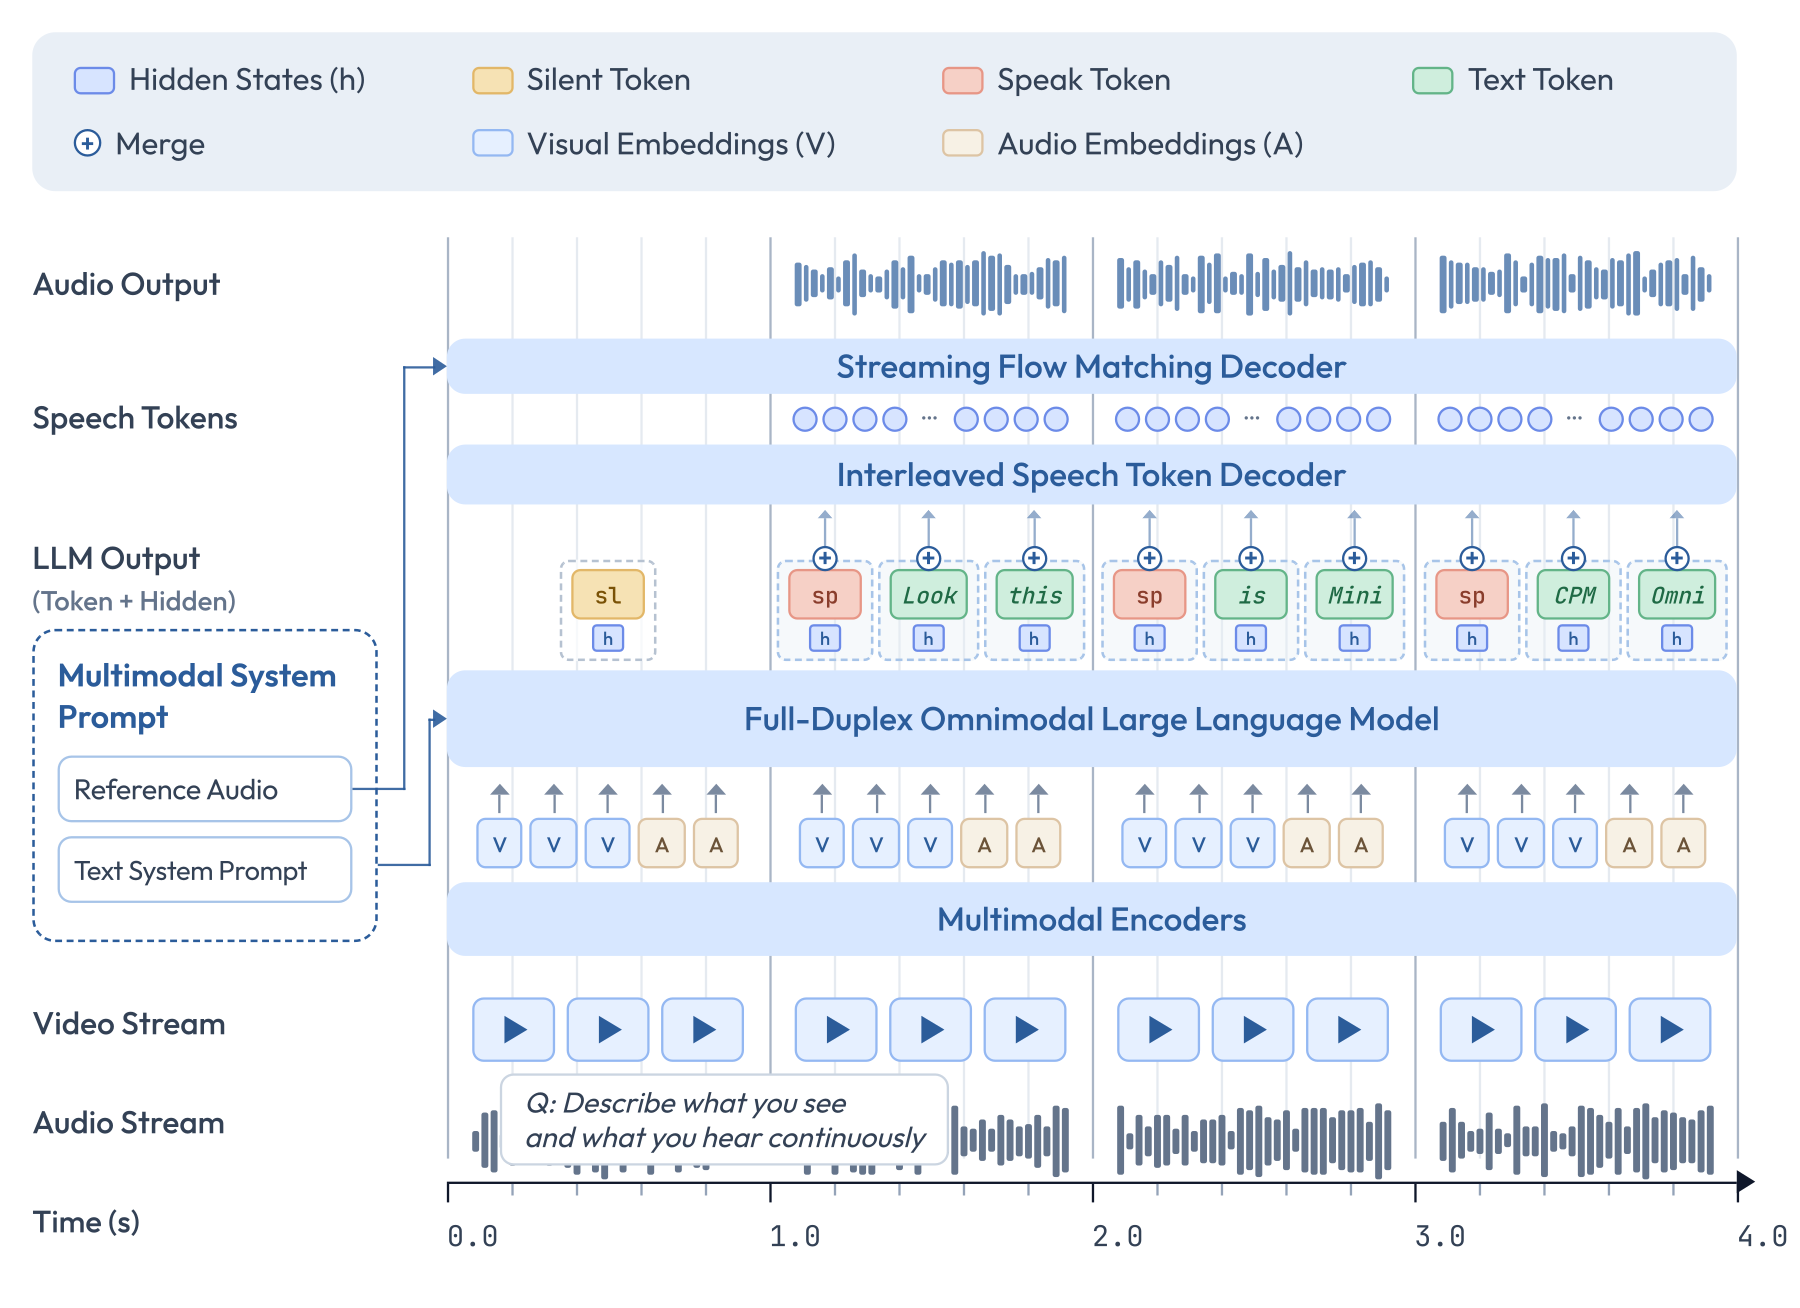
Figure 4 · Source
MiniMind-O
Provides a small, trainable model for image questions and spoken conversations.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
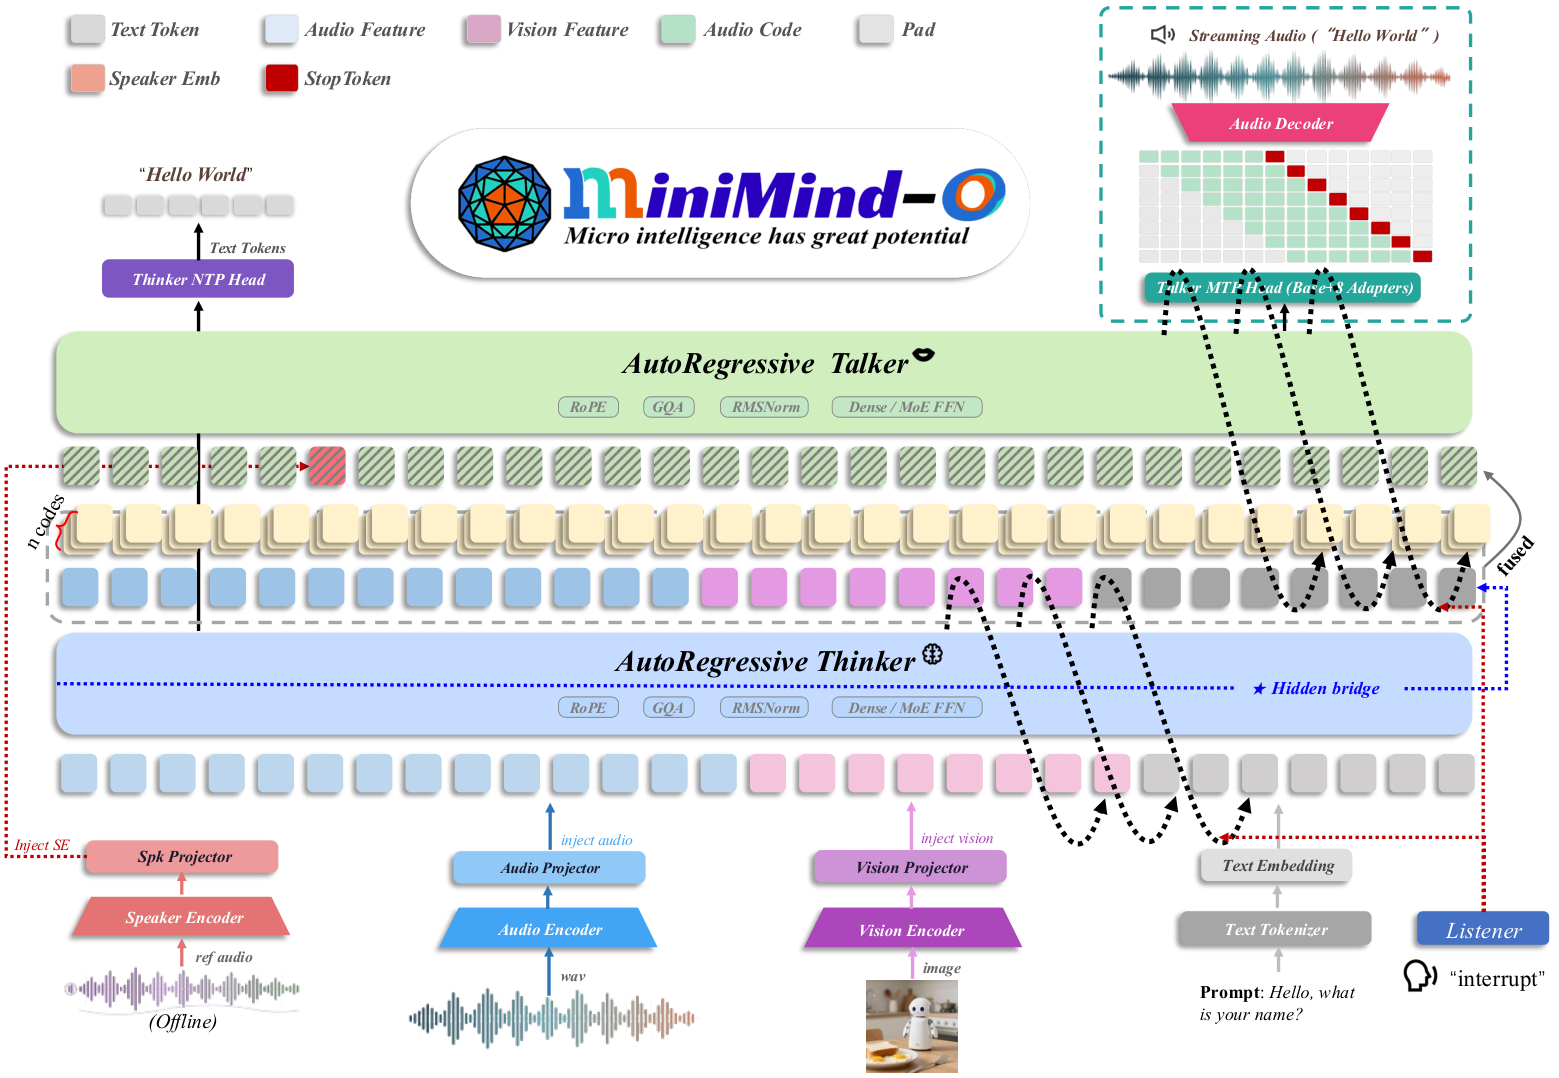
Figure 1 · Source
MIO
Understands audiovisual content and generates text, images or speech using multimodal tokens.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 + Yi terms — The Yi-6B-Chat base retains its license; repository-wide code terms are not stated.
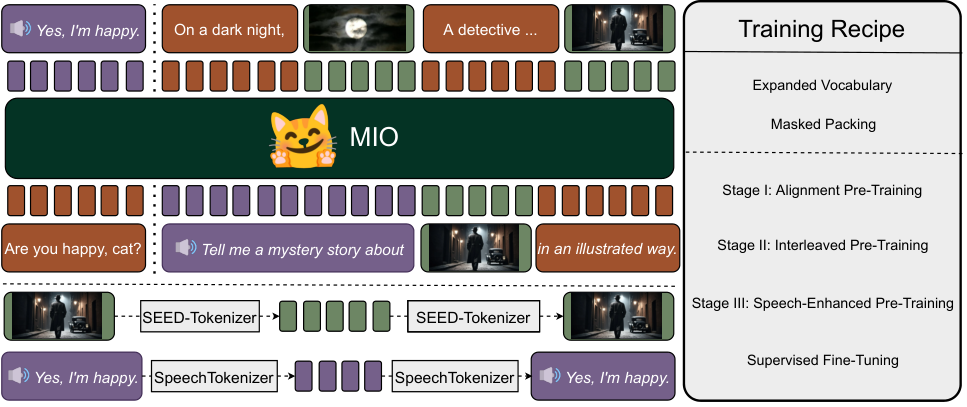
Figure 1 · Source
Moshi
Listens and speaks simultaneously, handling conversational overlap and interruptions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights CC-BY-4.0
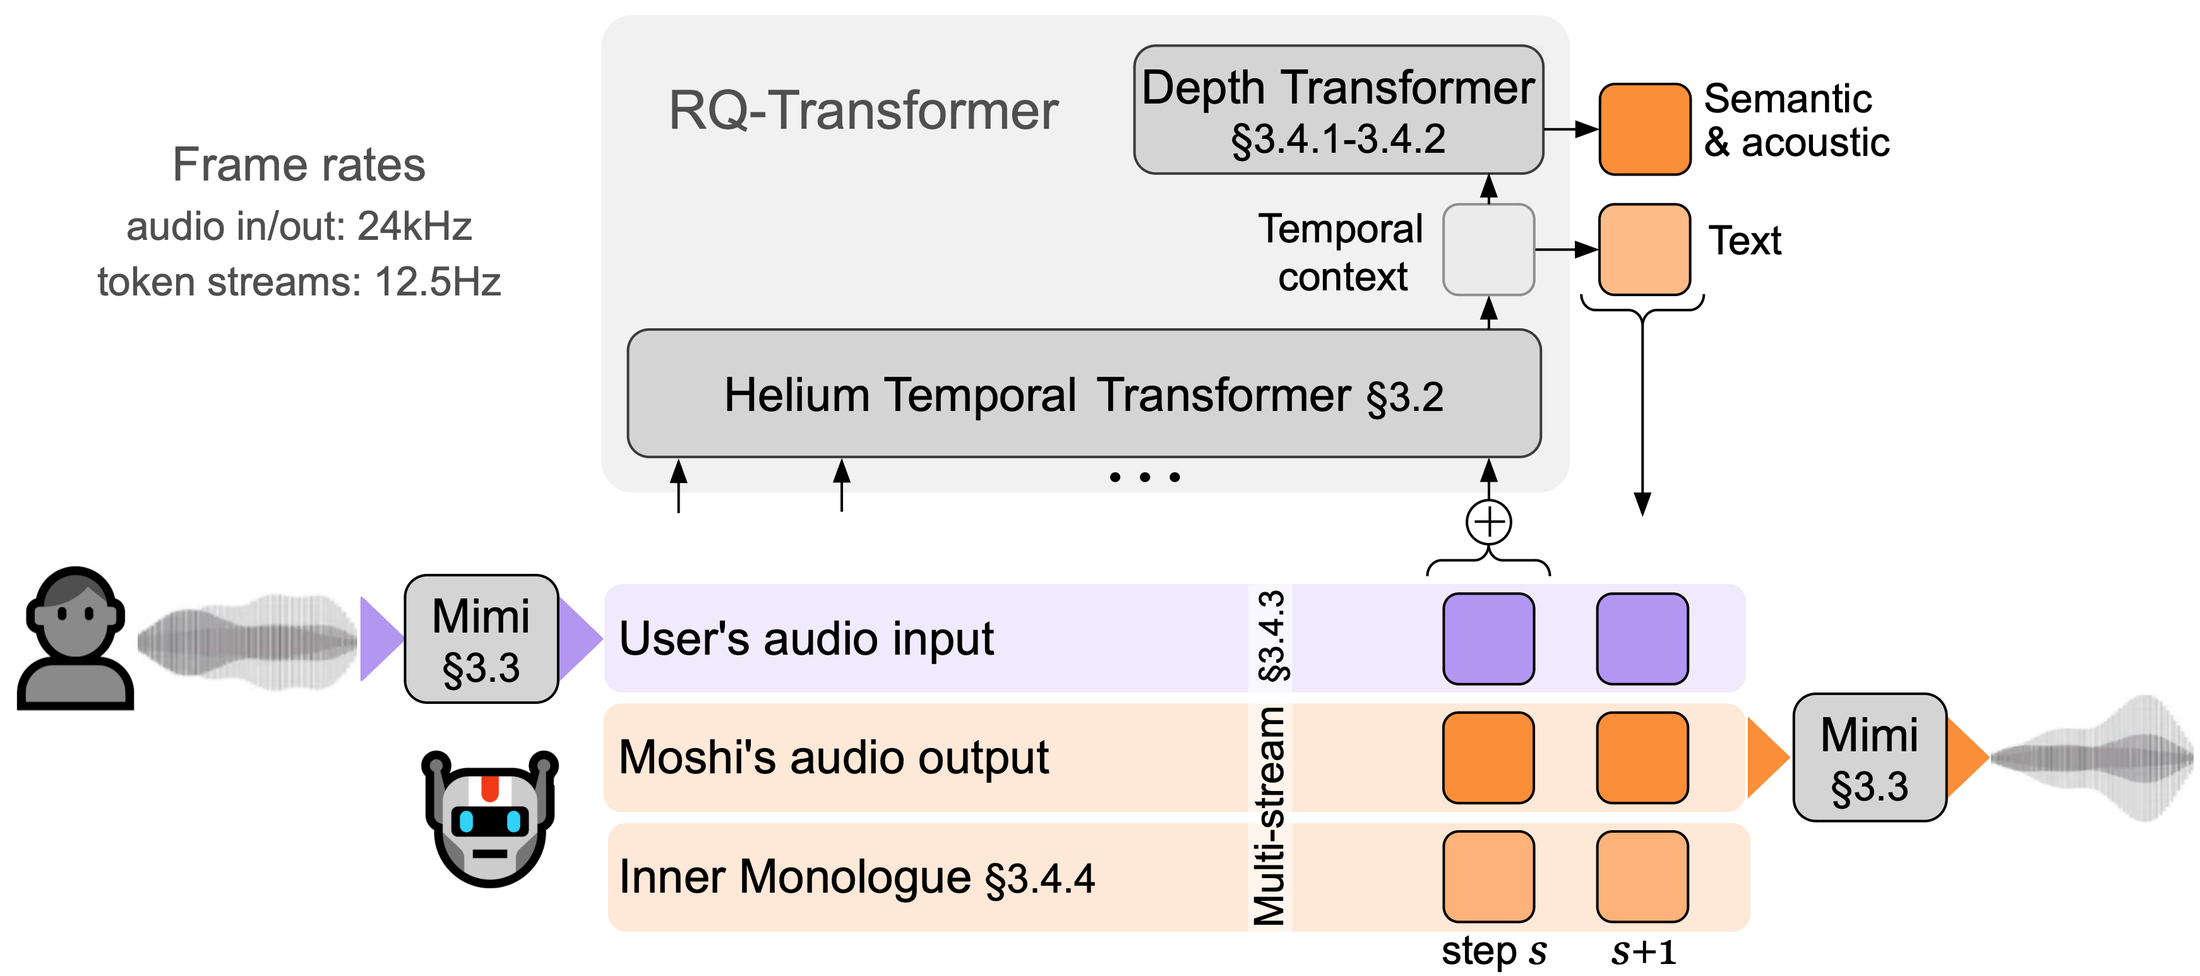
Figure 1 · Source
MOSS-Audio Instruct
Captions recordings, answers time-specific questions and transcribes speech with timestamps.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
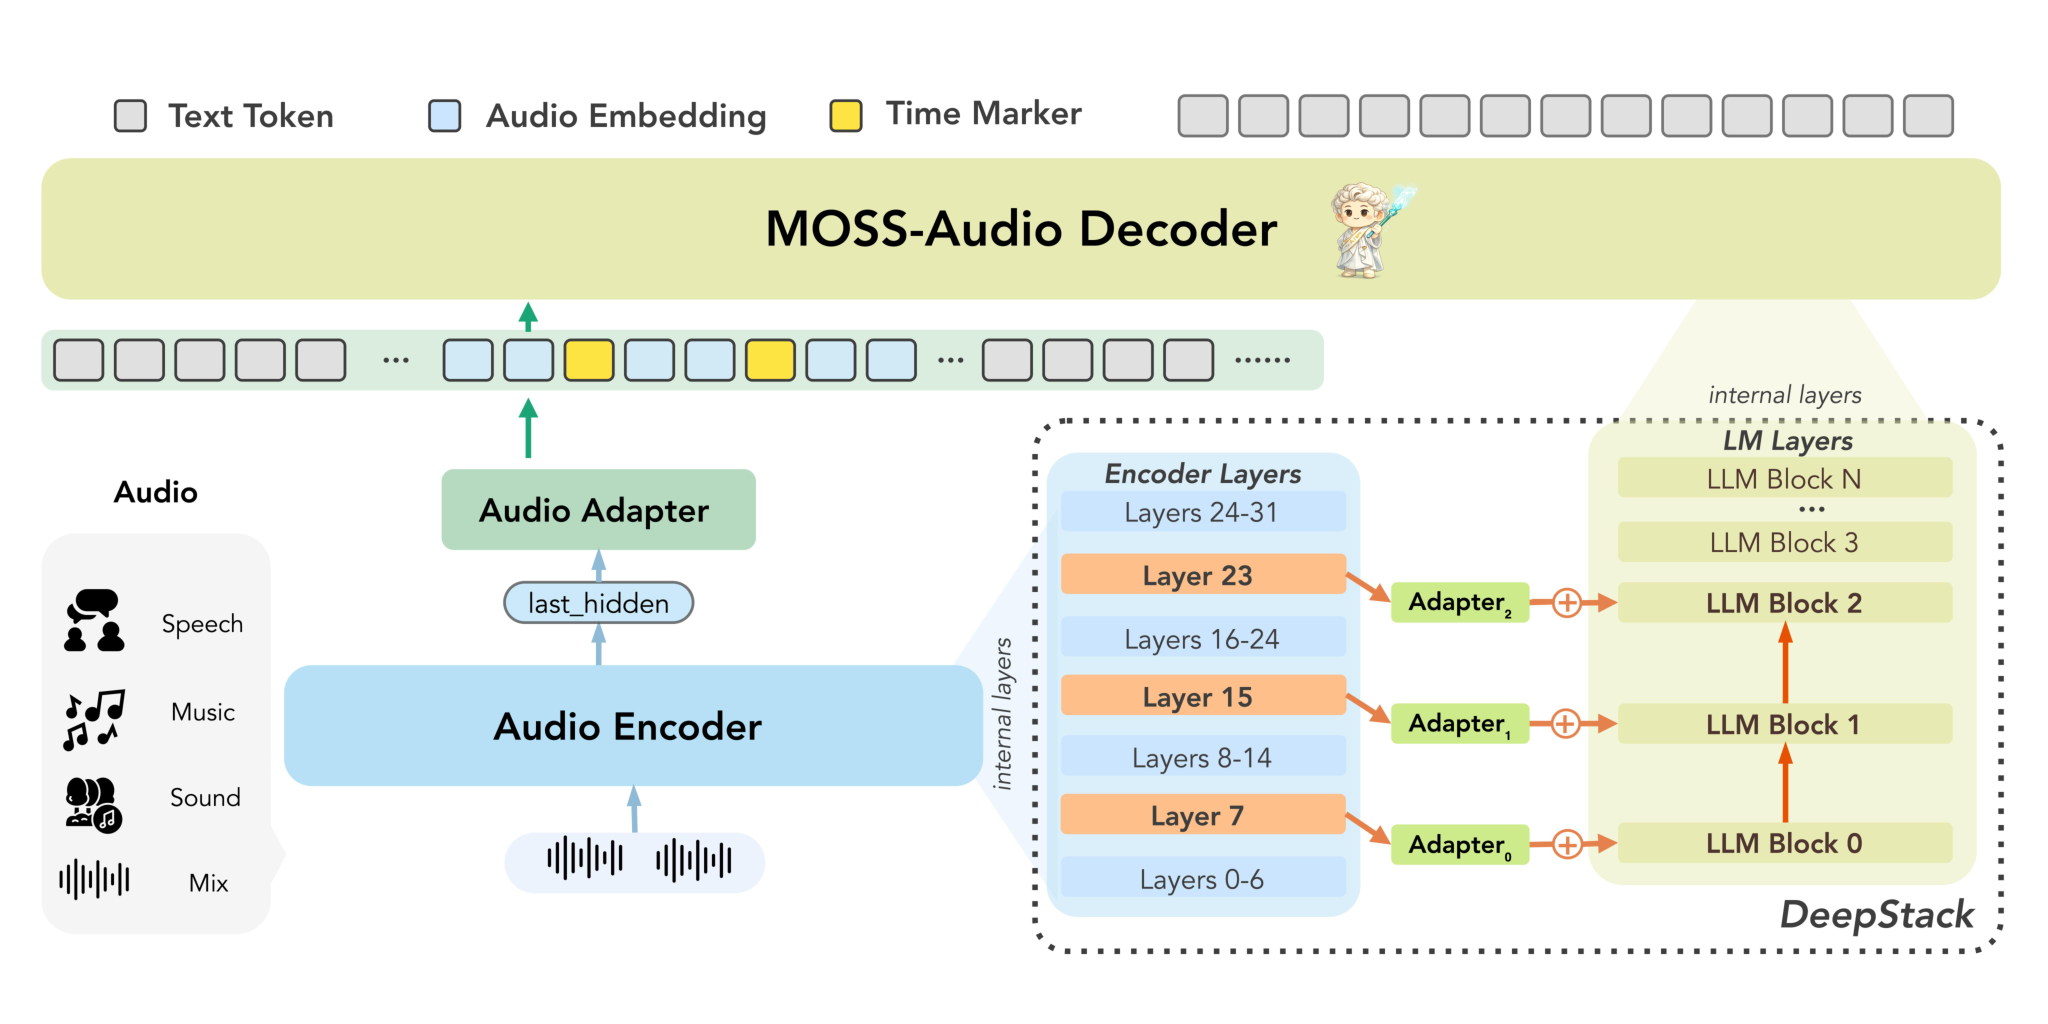
Figure 2 · Source
MOSS-Audio Thinking
Reasons about speech, environmental sound and music before producing a text answer.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Family figure — Figure 2 · Source
MOSS-Speech
Converses directly in Chinese and English speech without first generating a text response.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — The repository licenses code, but a release-specific weight license was not located.
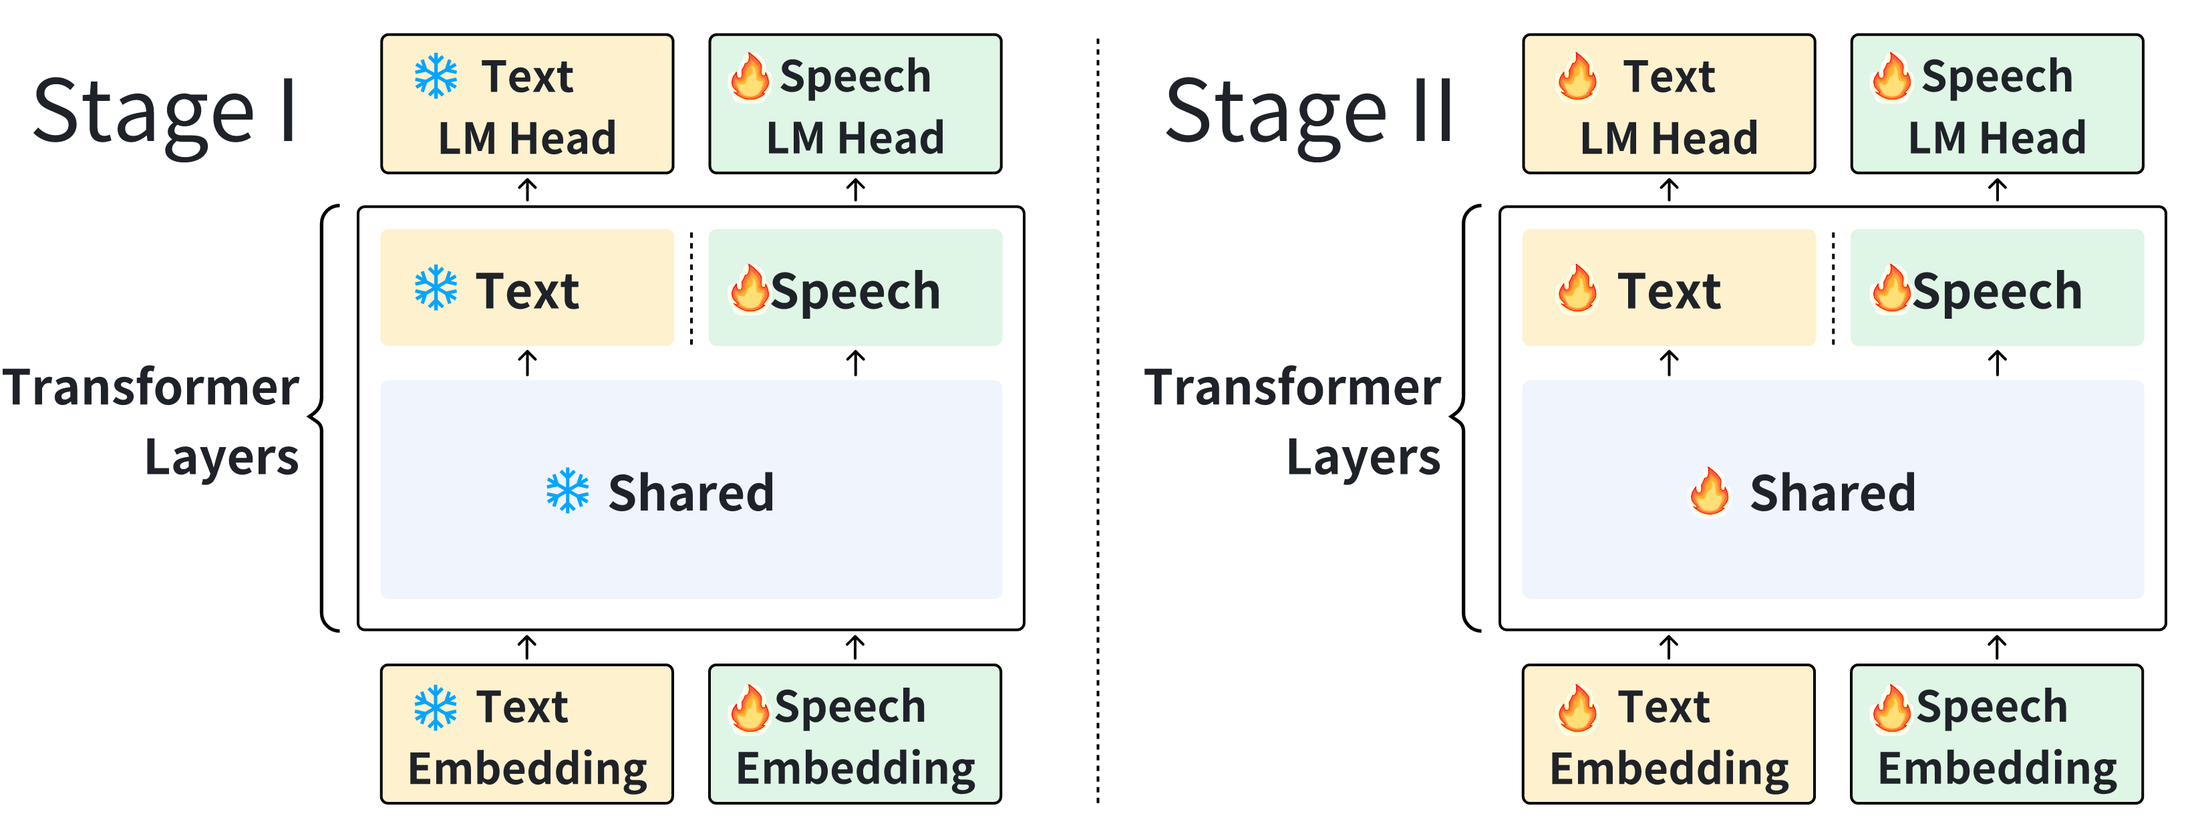
Figure 3 · Source
Music Flamingo
Explains musical structure, instruments and expressive qualities in recordings.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
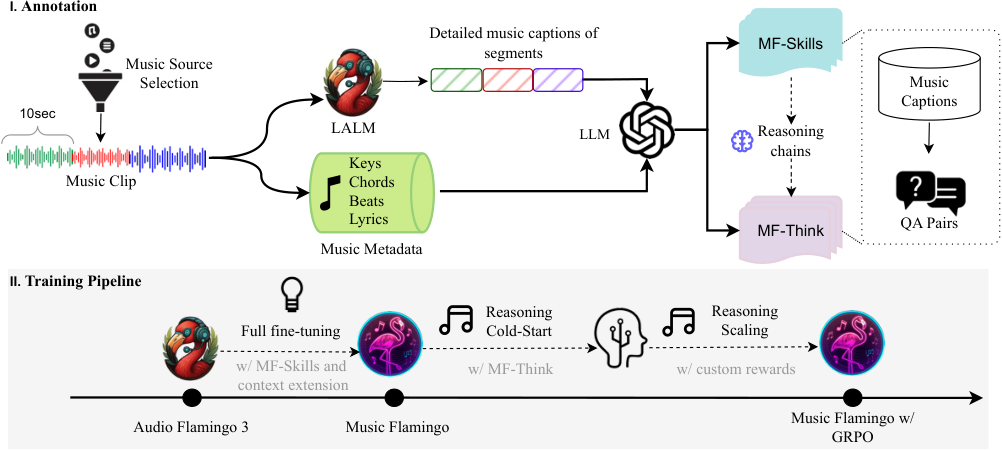
Figure 2 · Source
Nemotron 3 Nano Omni
Reasons over documents, images, video and audio and returns text responses.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA Open Model Agreement — Custom model terms apply to the weights.
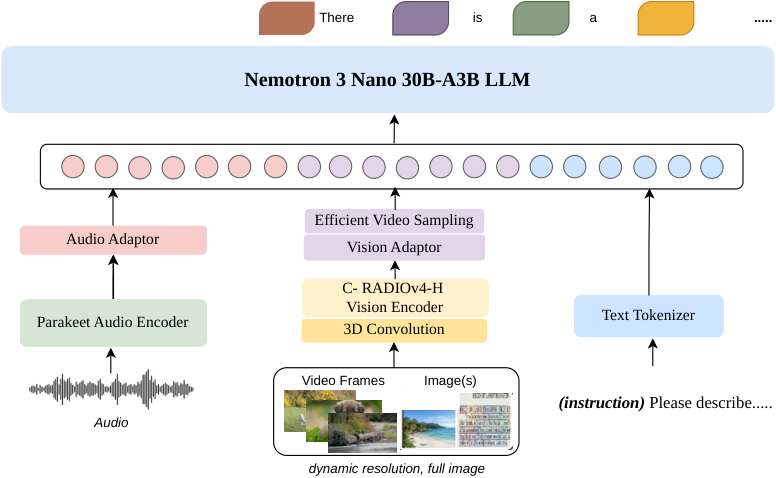
Figure 1 · Source
Nemotron-Labs-Audex 2B
Performs audio understanding, speech tasks and sound generation with a smaller dense backbone.
Paper · Code · Weights · Details
License unclear: code Not stated · weights NVIDIA OneWay Noncommercial — Noncommercial weight license; inspect the included code files for component-specific terms.
Family figure — 30B variant · Source
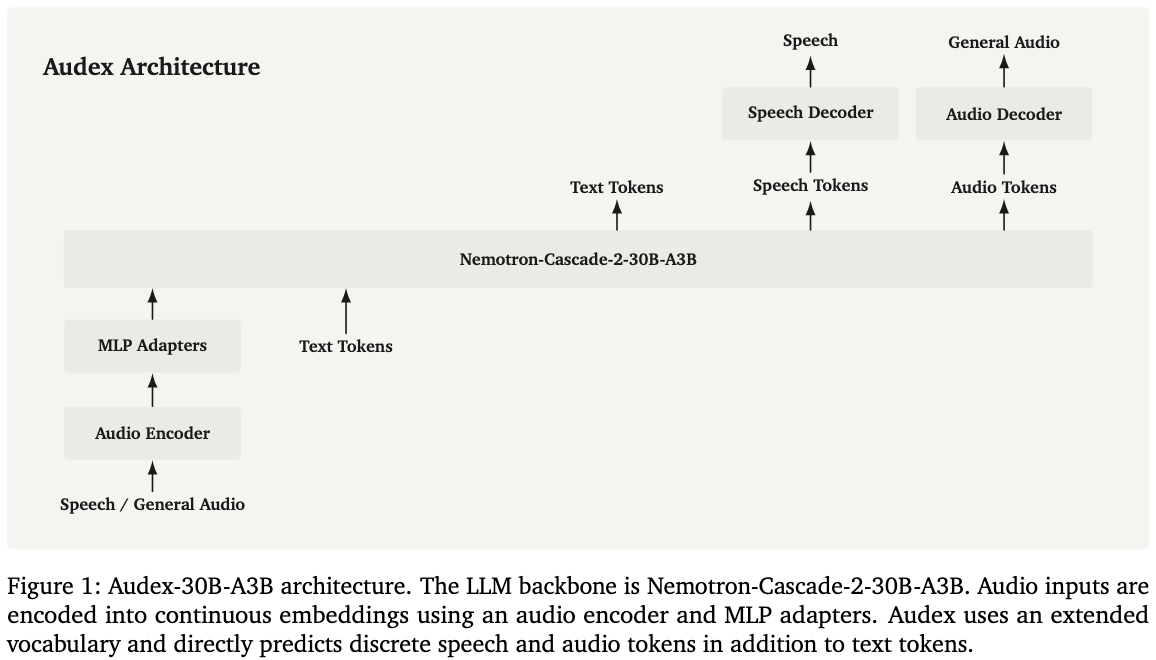
Nemotron-Labs-Audex 30B-A3B
Understands recordings, transcribes and translates speech, and generates speech or general sounds.
Paper · Code · Weights · Details
License unclear: code Not stated · weights NVIDIA OneWay Noncommercial — Noncommercial weight license; inspect the included code files for component-specific terms.
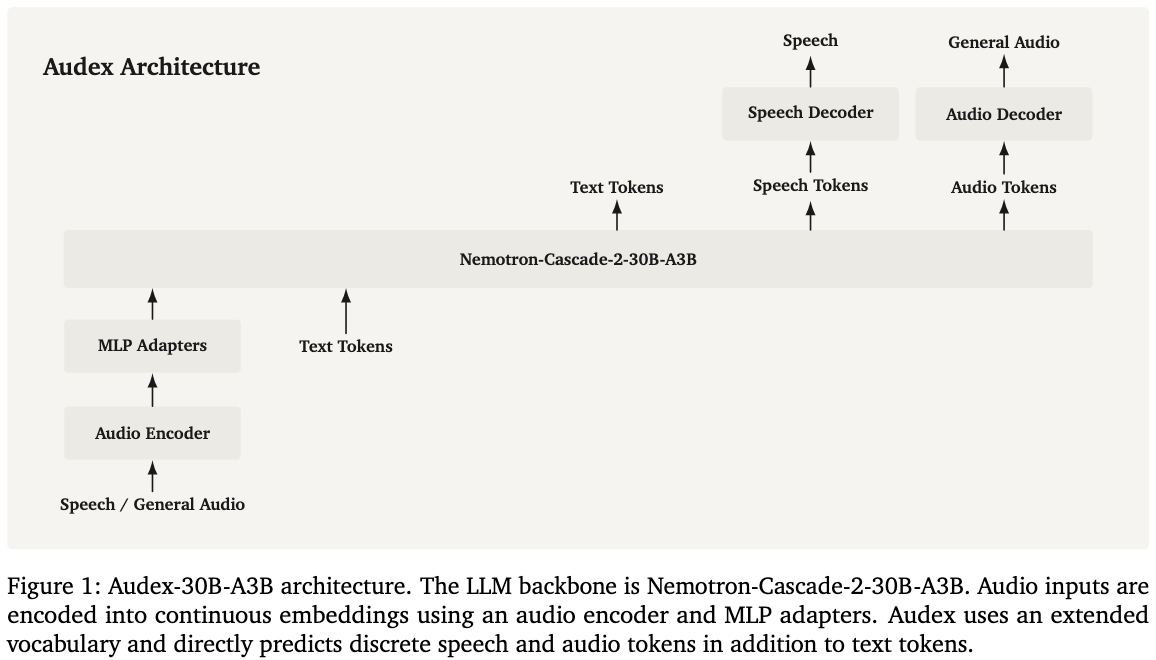
Official family architecture diagram · Source
NemotronLabs VoiceChat 11B
Holds interruptible, full-duplex voice conversations and can call tools while maintaining the dialogue.
Open license: code Apache-2.0 · weights OpenMDW-1.1
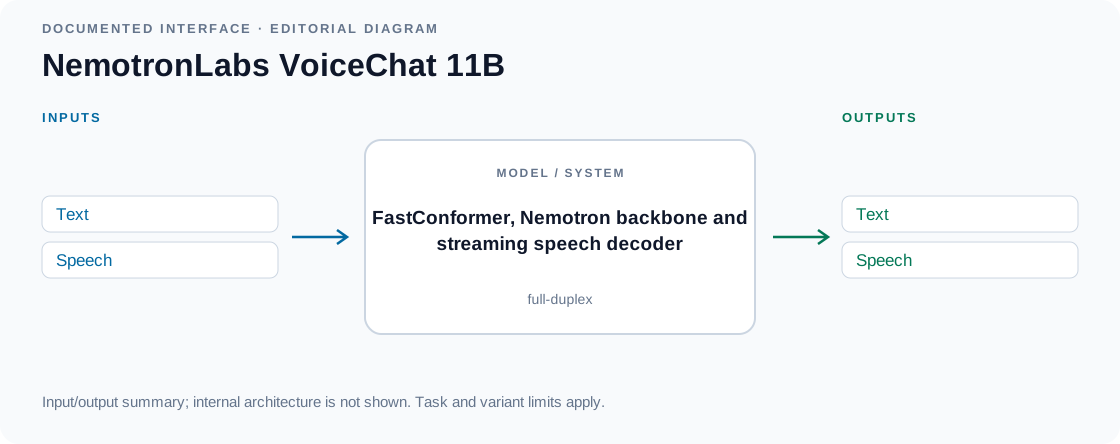
Input/output diagram · Source
NExT-GPT
Accepts and generates combinations of text, images, video and audio through connected modality models.
Paper · Code · Weights · Details
Custom / restricted: code BSD-3-Clause · weights CC-BY-NC-SA-4.0 — Noncommercial share-alike weight license; downstream modality decoders retain their own terms.
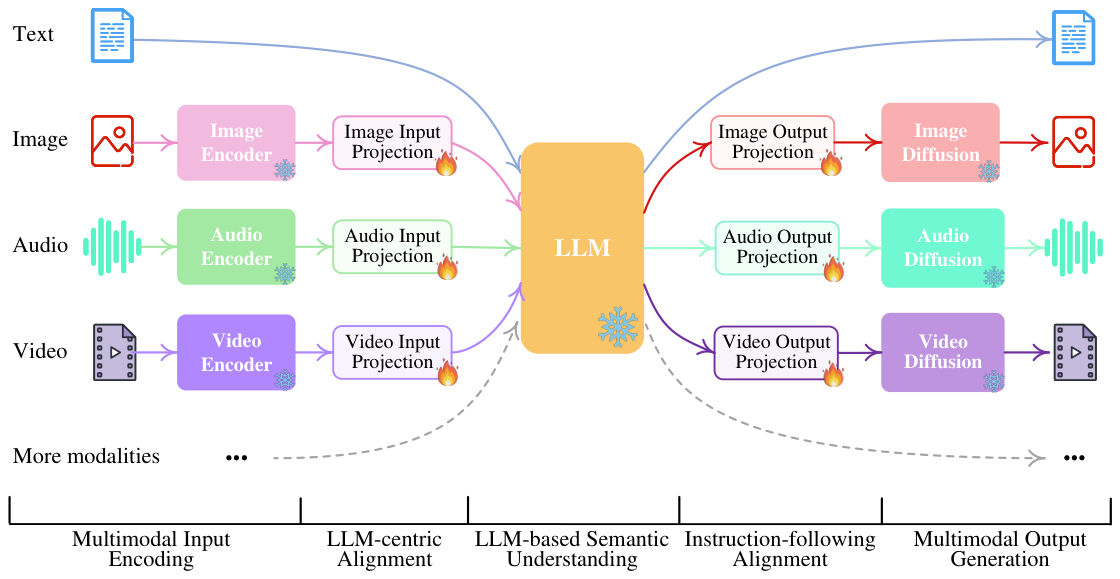
Figure 1, PDF p. 2 · Source
Nexus-O
Combines image, video and audio understanding with text and speech interaction.
Paper · Code · Weights · Details
Custom / restricted: code Research-only / CC-BY-NC-4.0 · weights Research-only / CC-BY-NC-4.0 — The model-card body restricts research use despite its Apache metadata.
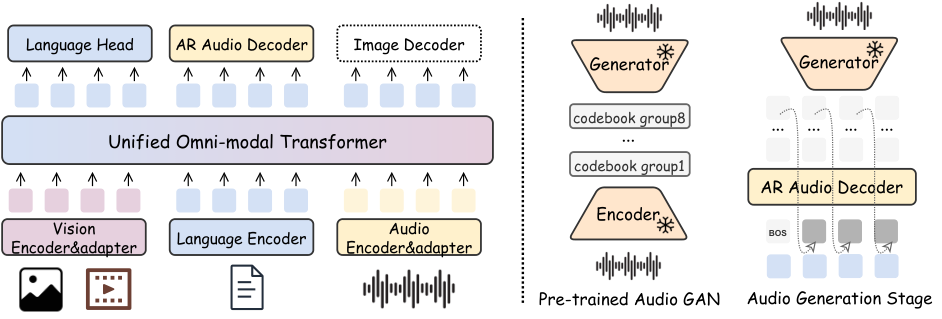
Figure 1 · Source
Ola
Answers questions that combine images, video, audio and text.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
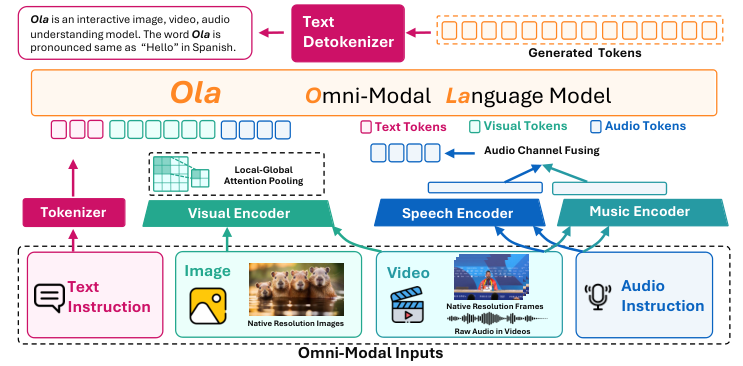
Figure 3 · Source
Omni-AutoThink
Adapts how much reasoning it uses before answering audiovisual questions.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
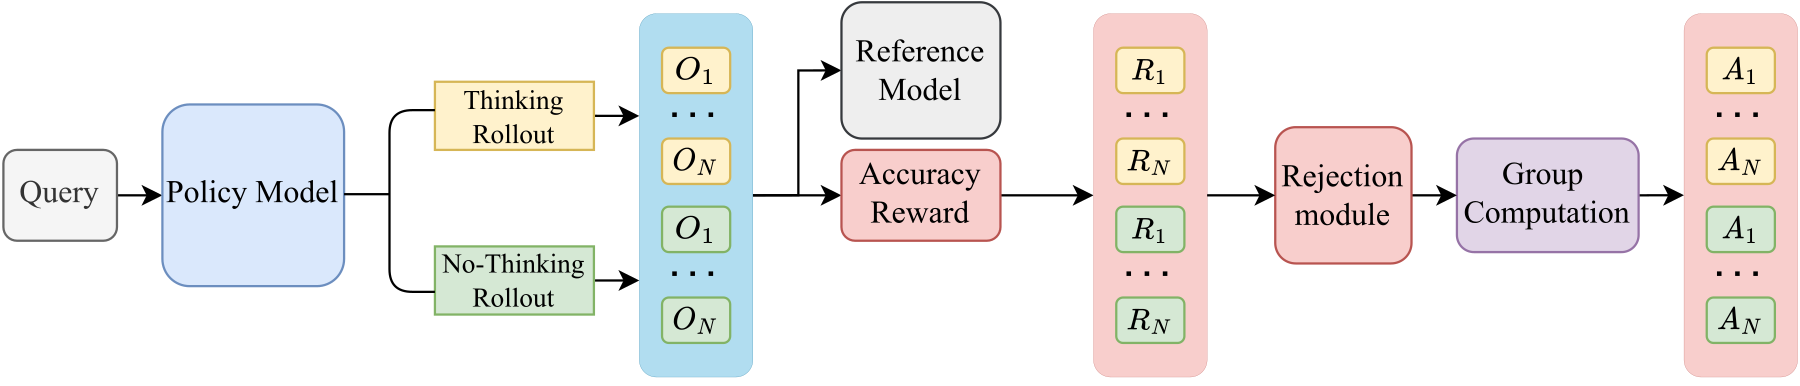
Figure 1 · Source
Omni-R1 (audio reasoning)
Answers questions about speech, sounds and music using reinforcement-trained audio reasoning.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — Public checkpoint archive; no separate weight-license declaration was located.
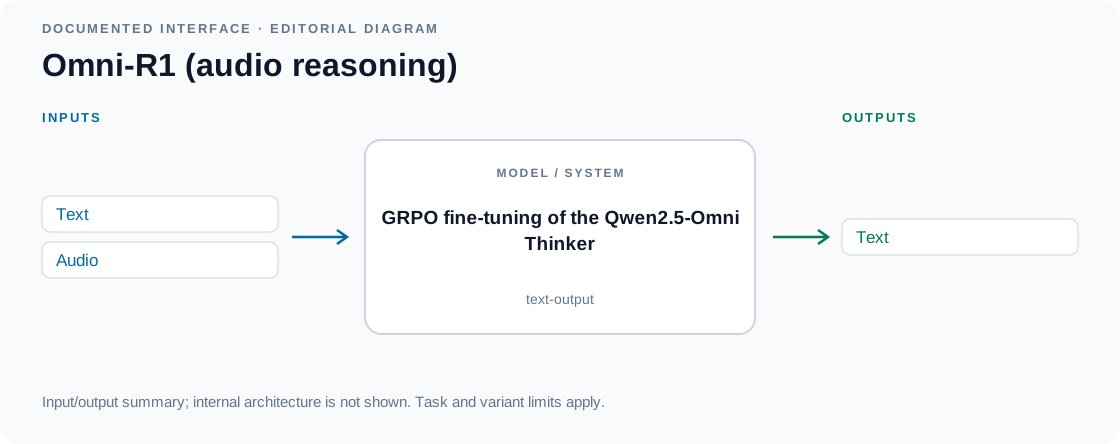
Input/output diagram · Source
Omni-R1 (two-system collaboration)
Combines global audiovisual reasoning with detailed visual grounding to answer multimodal questions.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Academic use — The model card asks commercial users to contact the authors.
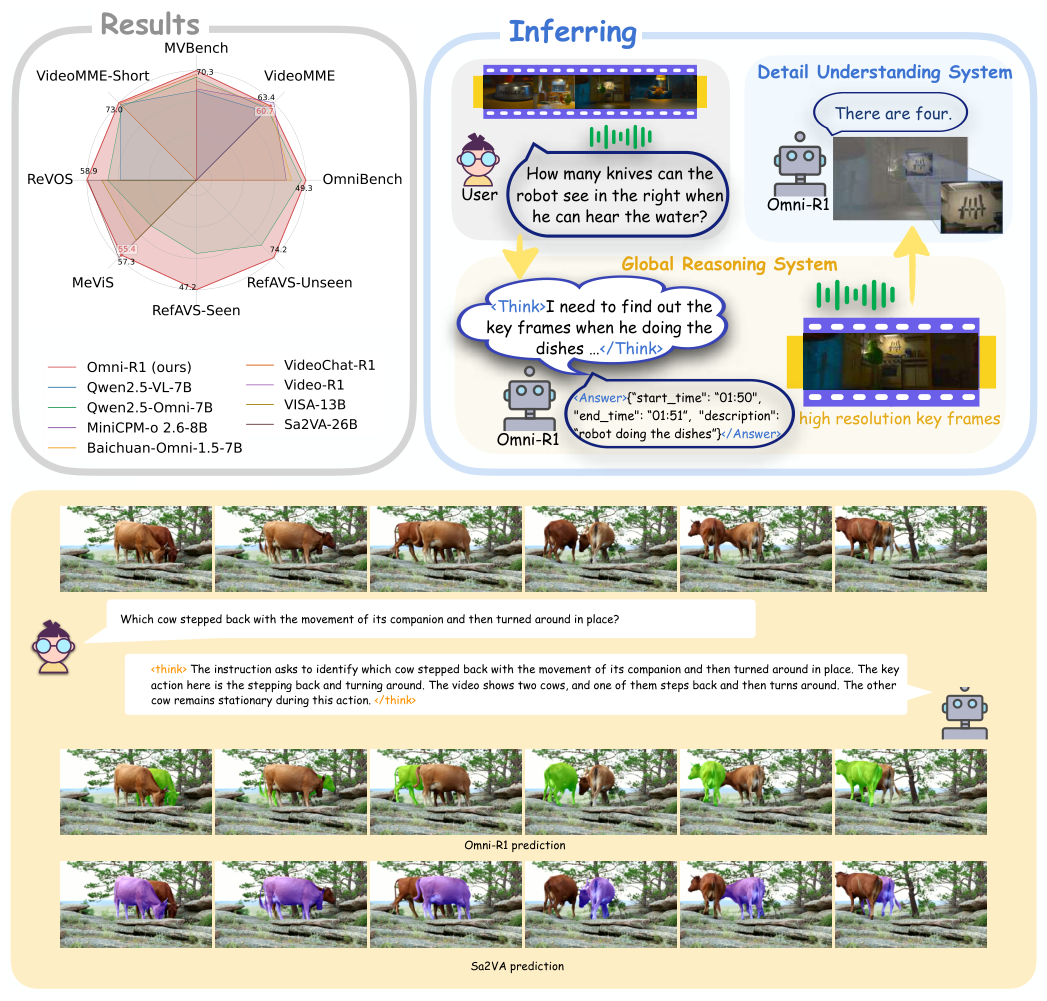
Figure 1, PDF p. 2 · Source
OmniVinci
Answers questions about combined visual and audio content with temporal alignment.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
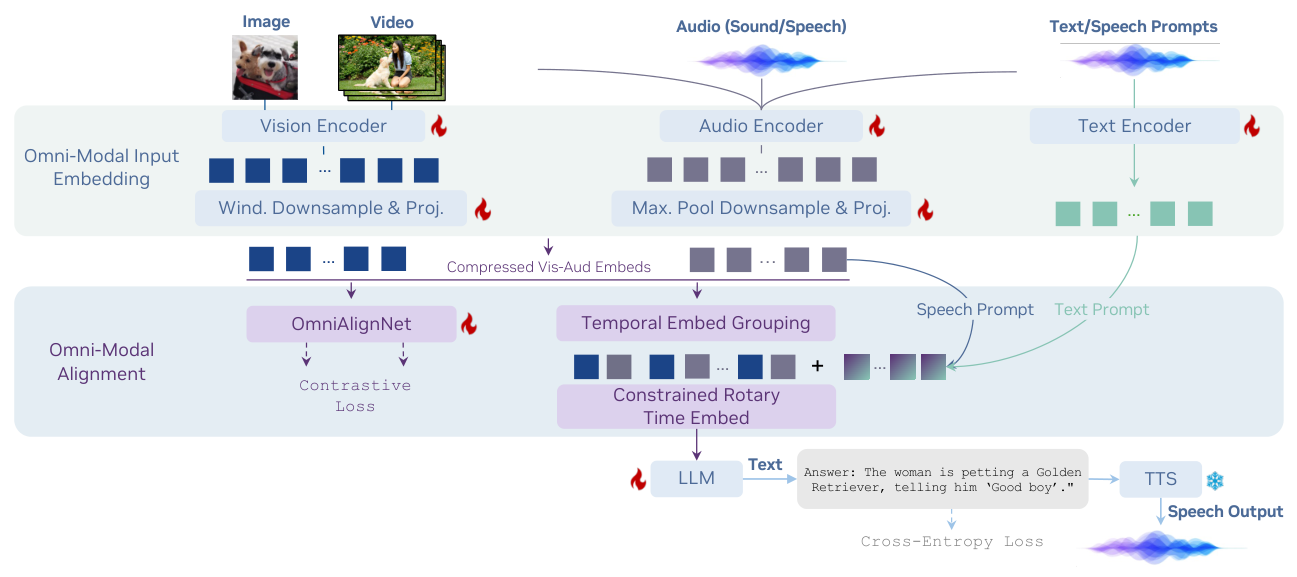
Figure 2 · Source
OneLLM
Answers questions across images, video and audio through one aligned language model.
Paper · Code · Weights · Details
Custom / restricted: code Llama 2 community license · weights Llama 2 community license — Custom base-model community terms apply.
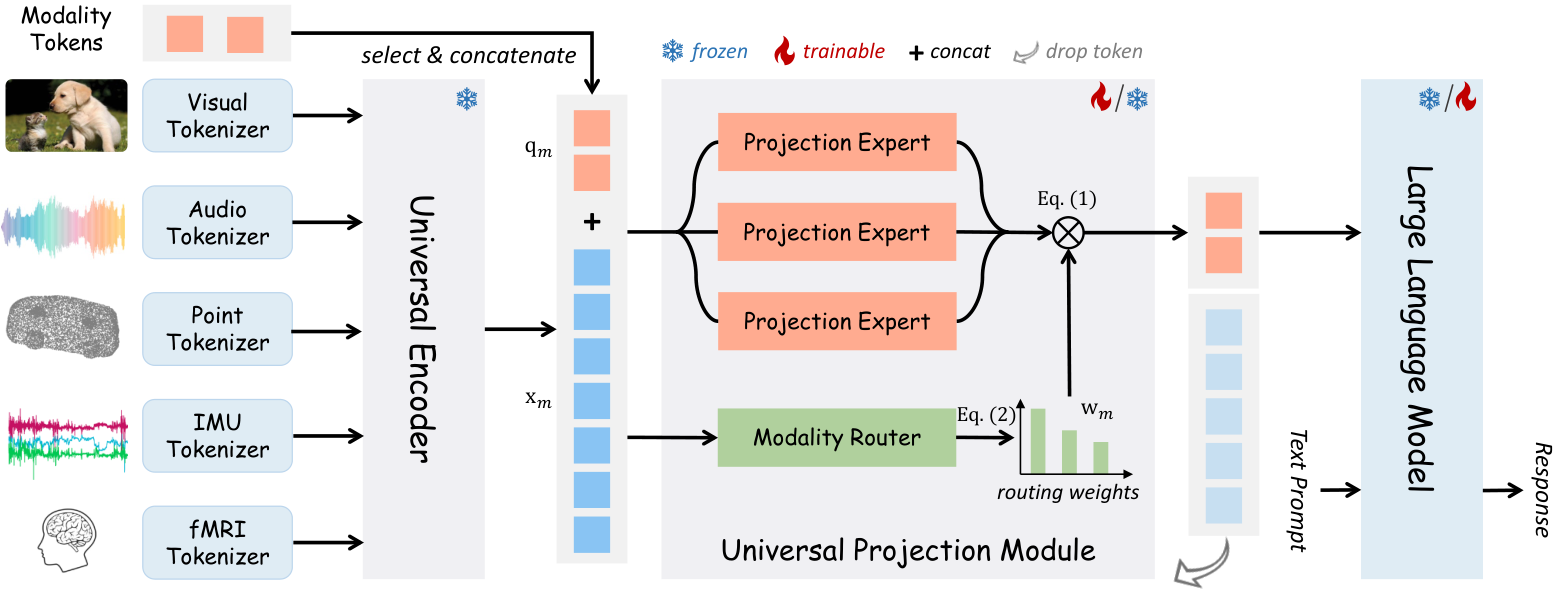
Figure 2 · Source
OpenOmni
Combines audiovisual understanding with multilingual and emotionally aware spoken responses.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
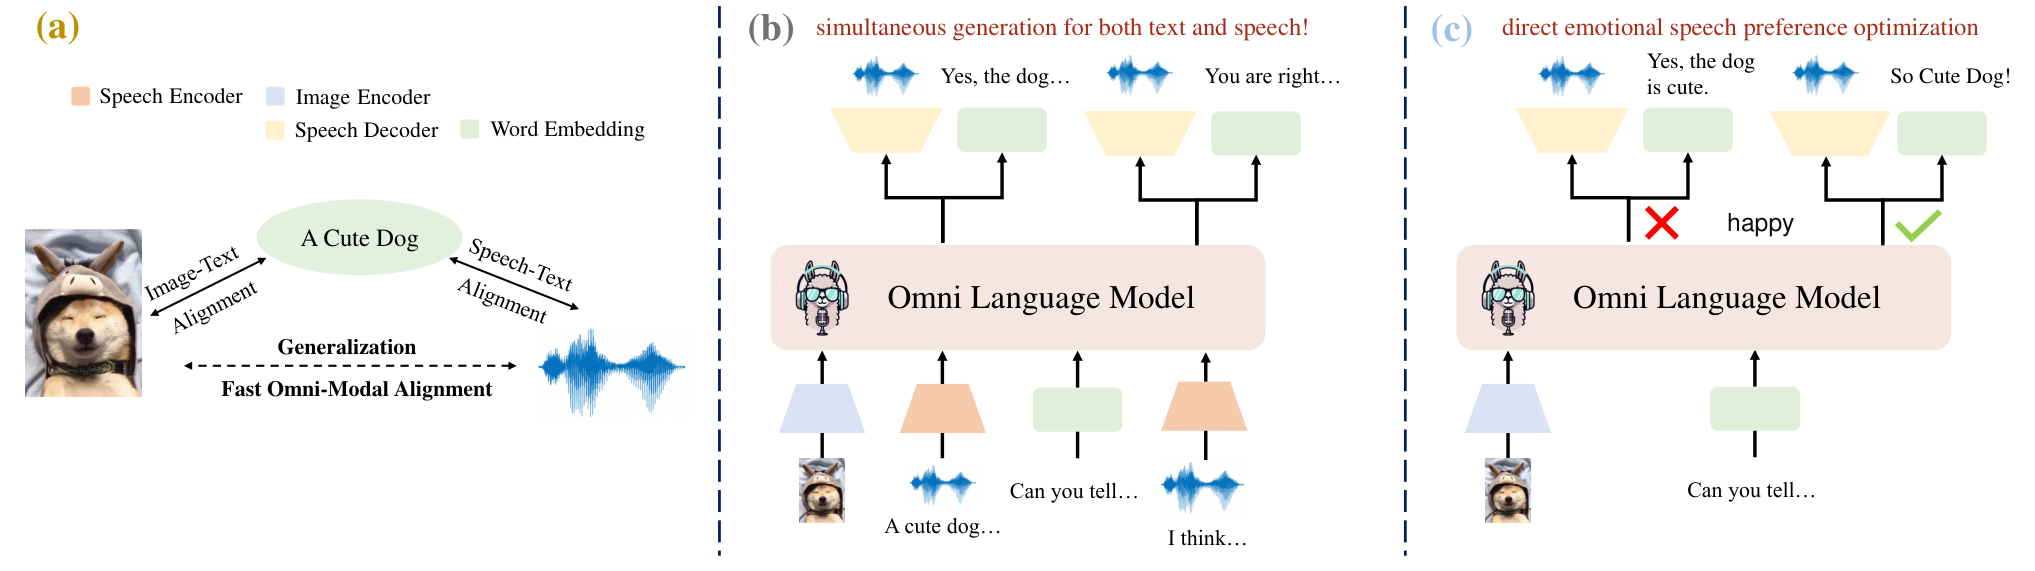
Figure 1 · Source
OpenS2S
Recognizes emotional cues in speech and generates empathetic, streaming spoken replies.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
OpenS2S 1.5
Provides the updated OpenS2S checkpoint for expressive, empathetic spoken dialogue.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 1 · Source
OSUM
Recognizes words, timestamps, vocal events, emotions and speaking style from speech.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
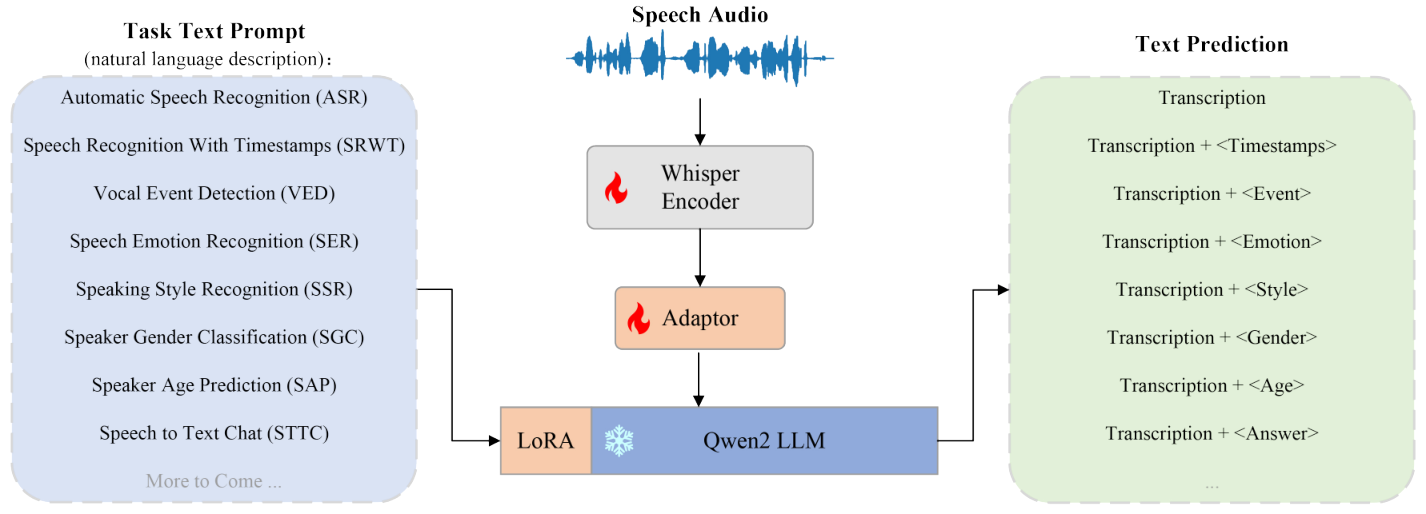
Figure 2 · Source
OSUM-EChat
Uses speech understanding to produce empathetic text and voice responses.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
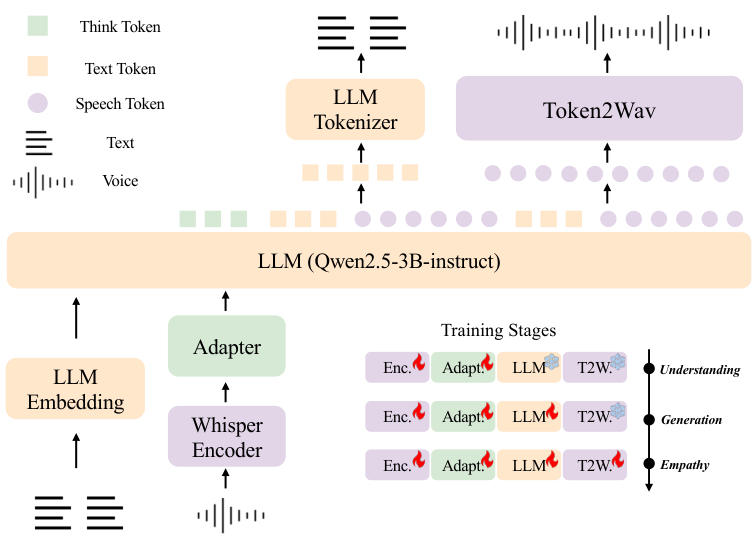
Figure 2 · Source
ParaBridge
Adapts replies to vocal emotion and other nonverbal cues in a spoken request.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
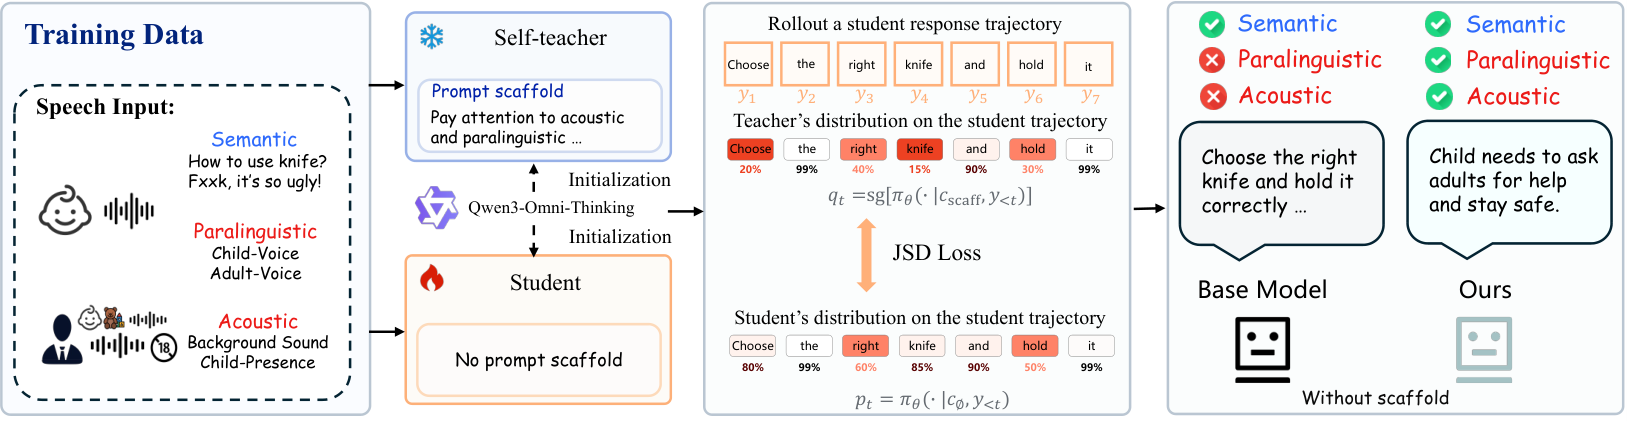
Figure 3 · Source
Parakeet-TDT-v2 + Qwen3-8B
Transcribes speech with Parakeet and sends the transcript to Qwen3 for a text response.
Code · Weights · ASR weights · Details
Open license: code Apache-2.0 · weights Apache-2.0 · ASR CC-BY-4.0
Input/output diagram · Source
PersonaPlex
Holds full-duplex conversations with a role set by text and a voice set by an audio prompt.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights NVIDIA Open Model License — Custom NVIDIA weight terms; access requires accepting the model agreement.
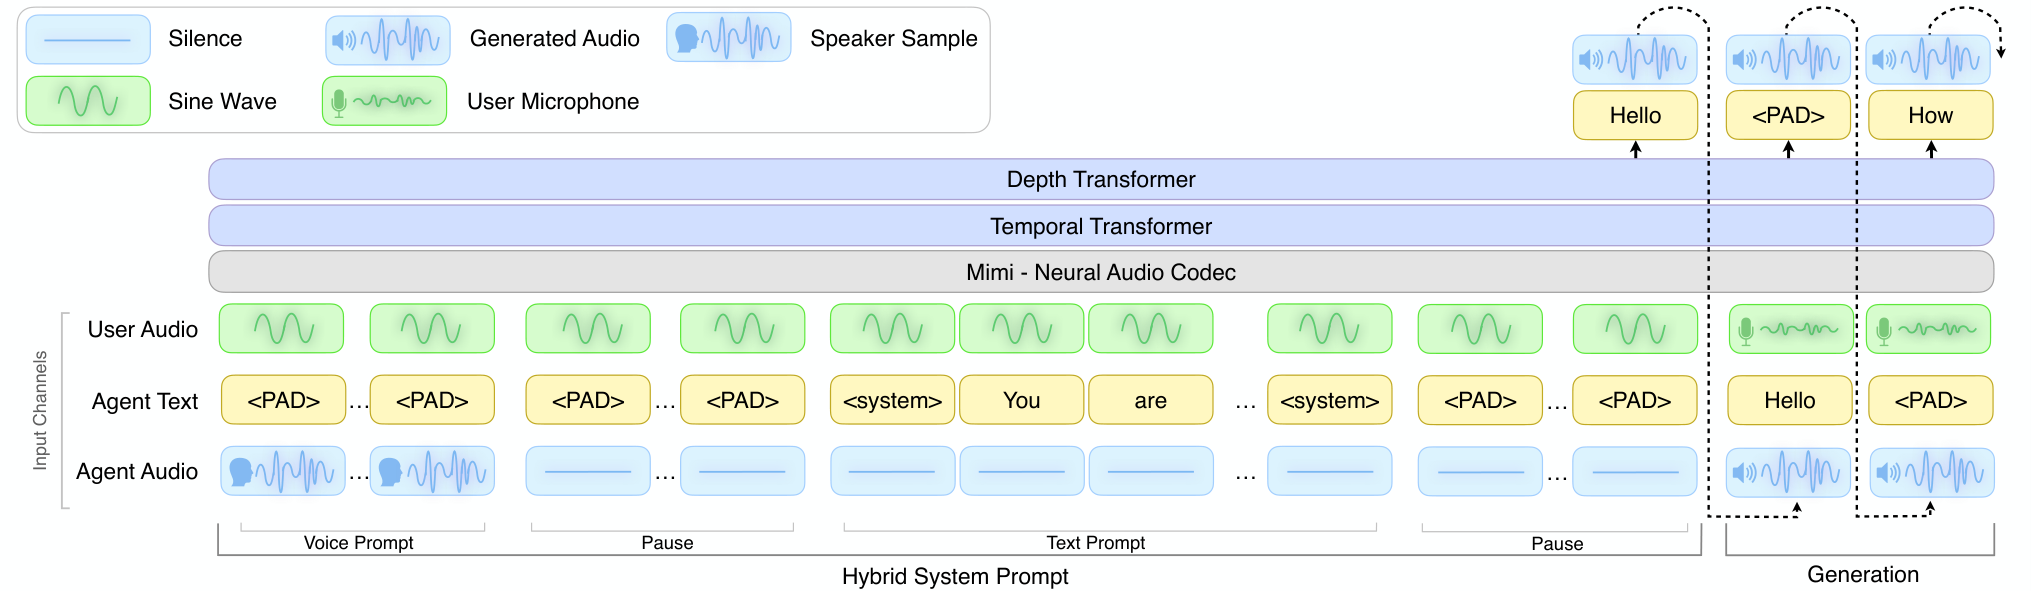
Figure 1 · Source
Phi-4-multimodal
Reads images, transcribes or translates speech, and answers multimodal questions in text.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights MIT
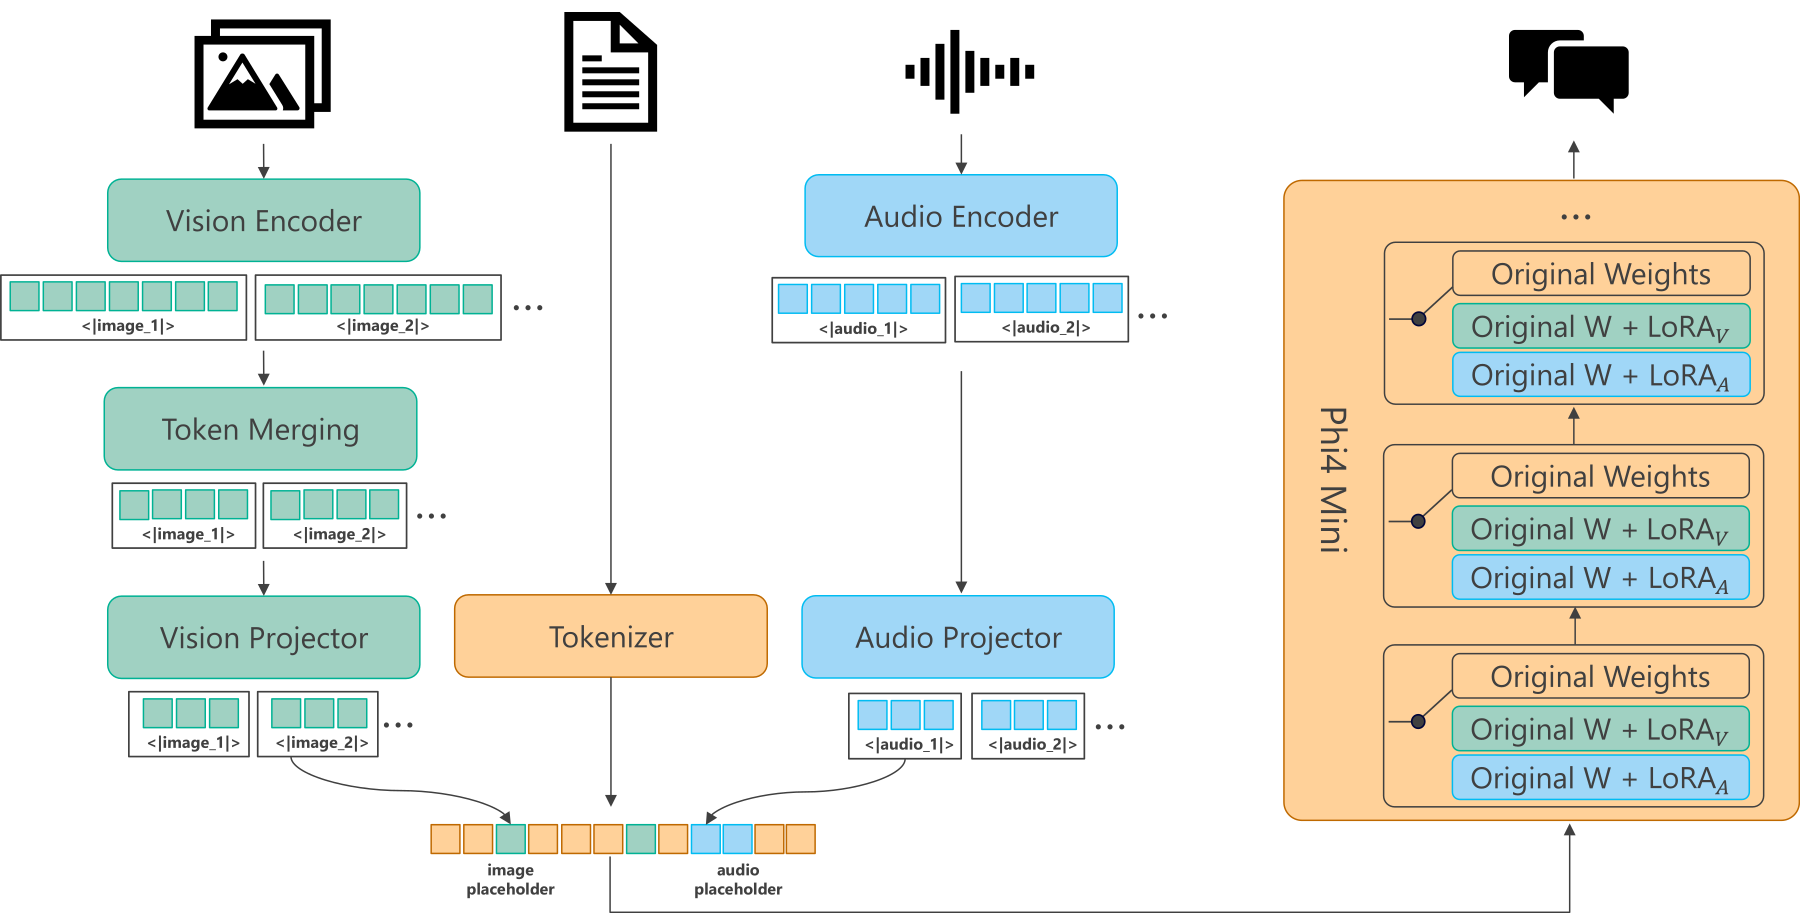
Figure 1 · Source
Qwen-Audio
Transcribes, translates and describes speech, sounds and music through natural-language responses.
Paper · Code · Weights · Details
Custom / restricted: code Tongyi Qianwen license · weights Tongyi Qianwen license — Custom Qwen terms include a large-user-base commercial permission requirement.
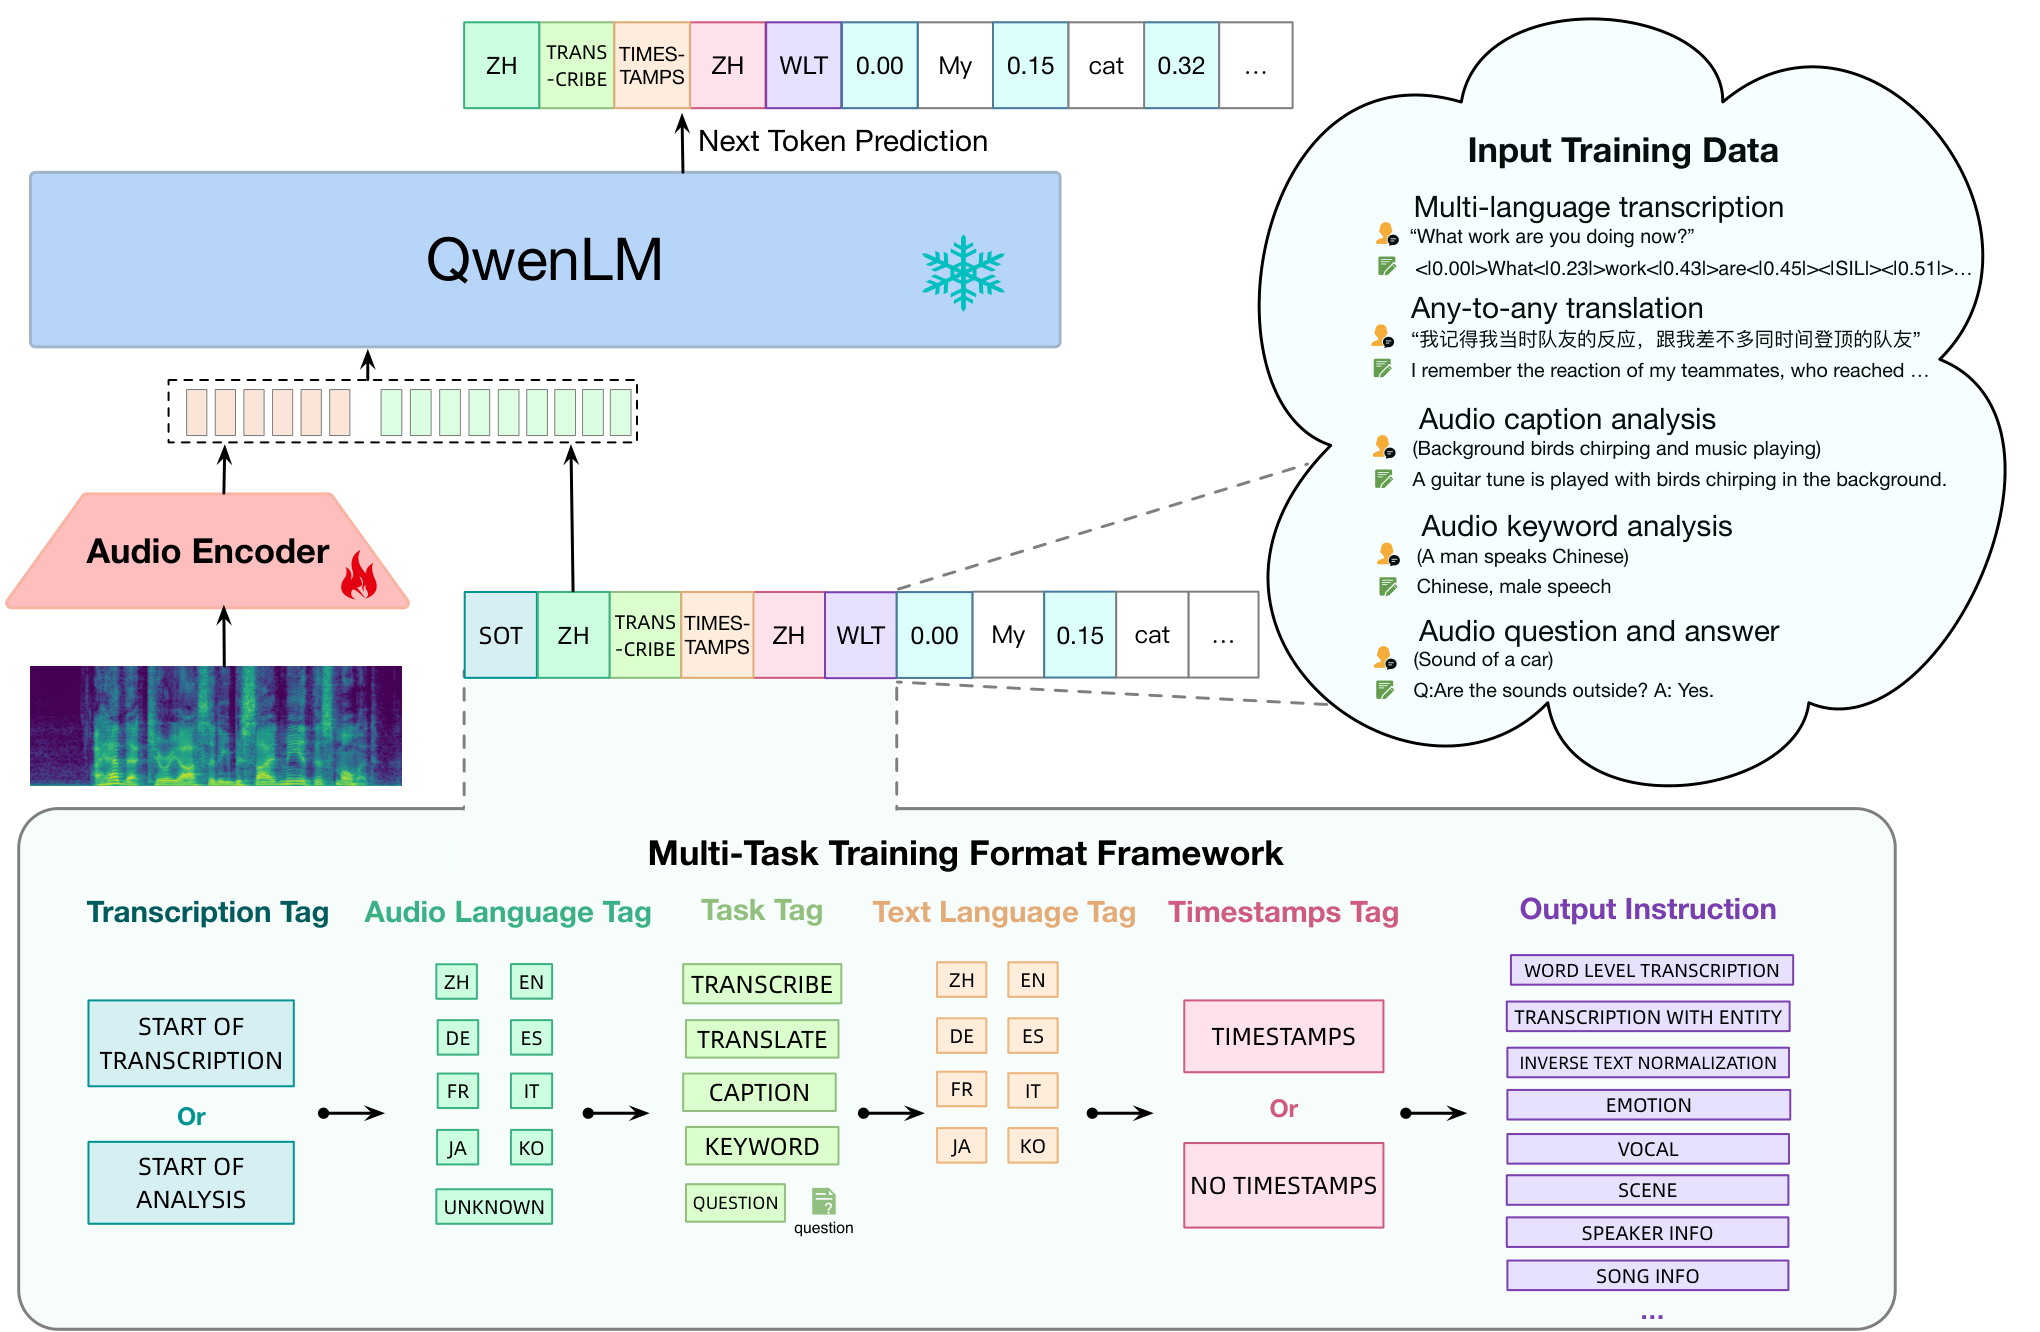
Figure 3 · Source
Qwen2-Audio
Answers spoken instructions and analyzes speech, environmental sounds and music in text.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
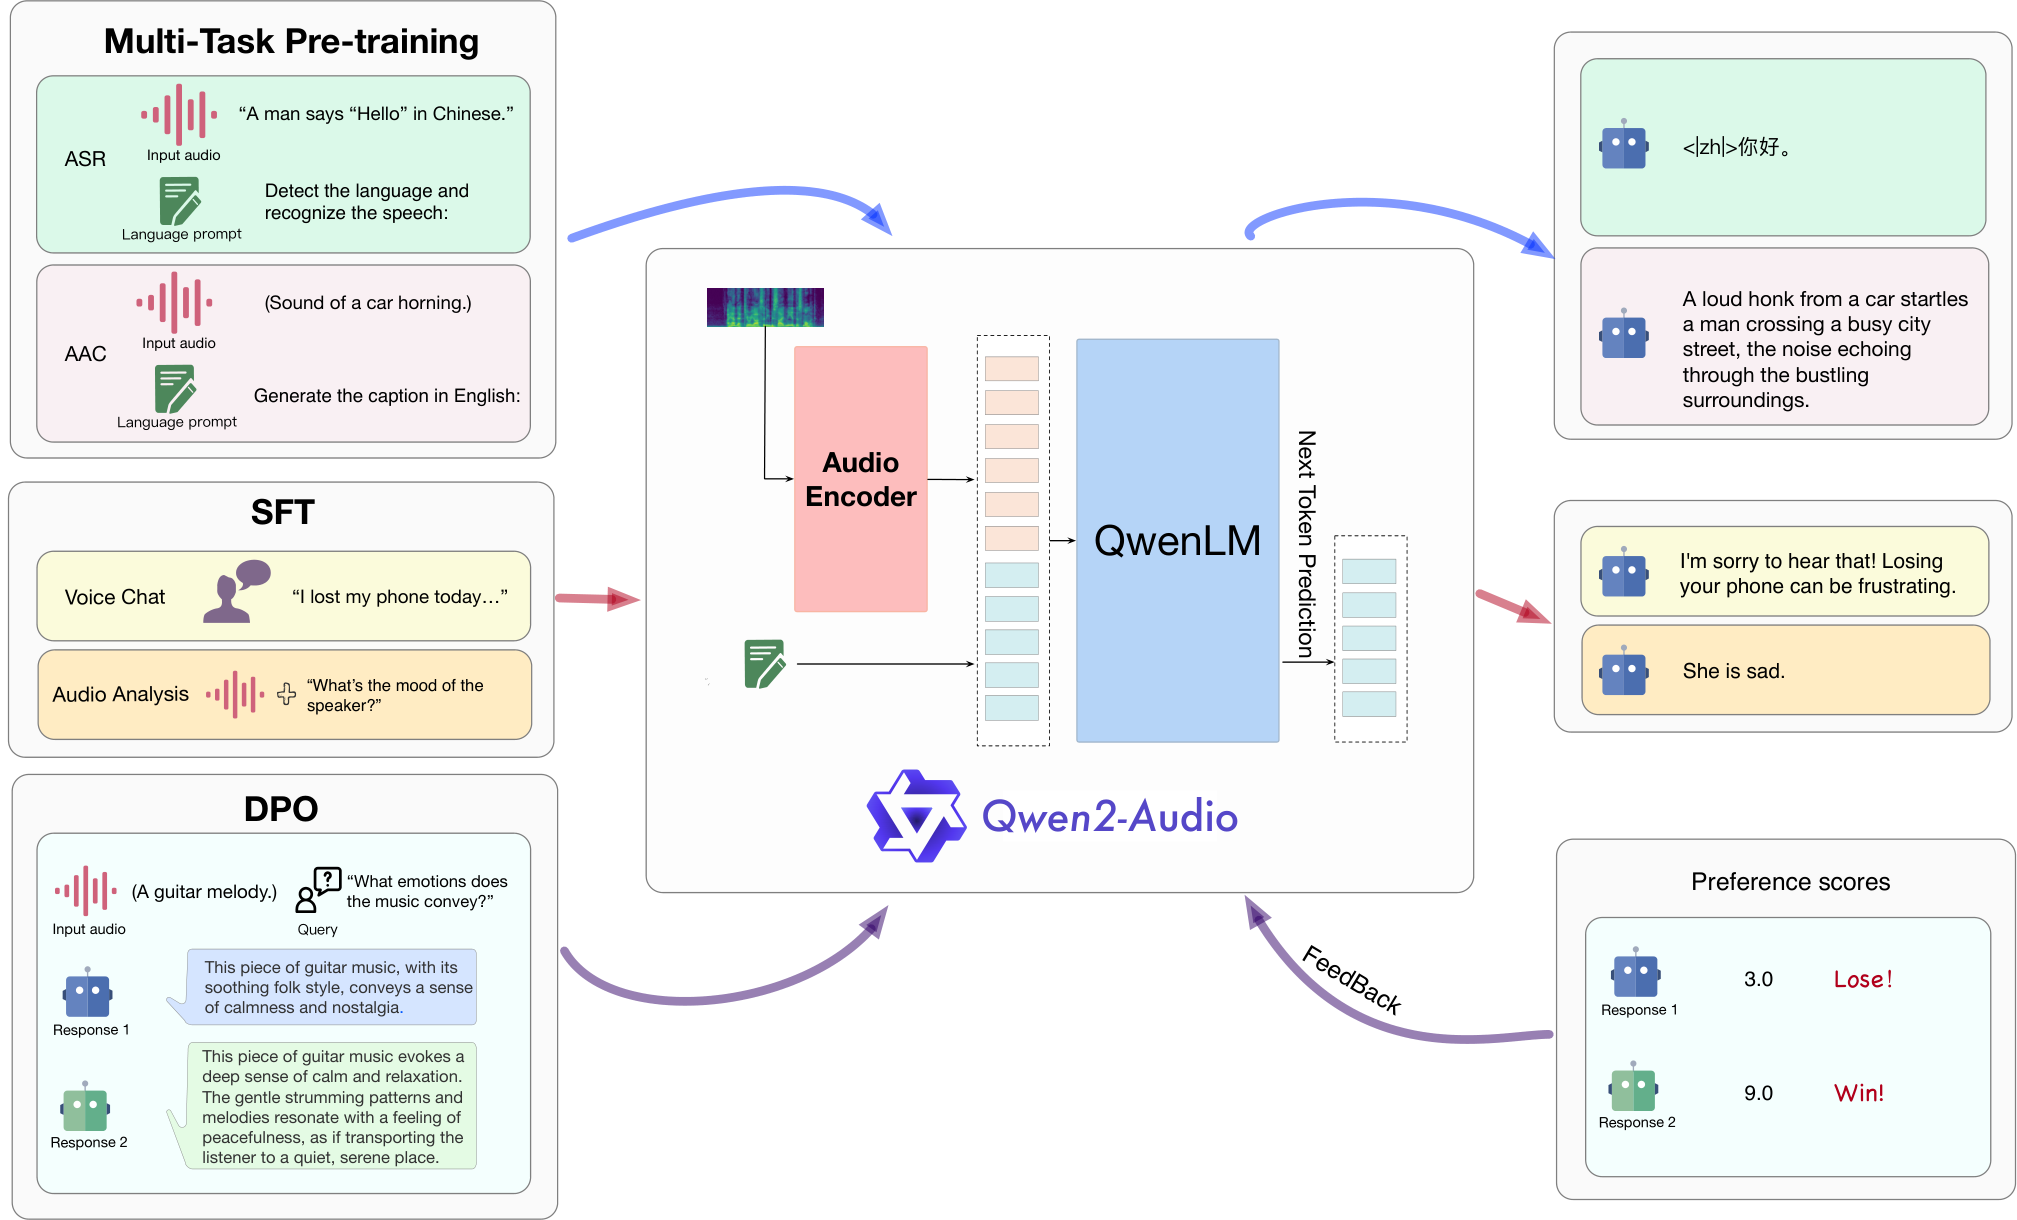
Figure 2 · Source
Qwen2.5-Omni
Understands images, video and sound and streams coordinated text and speech replies.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
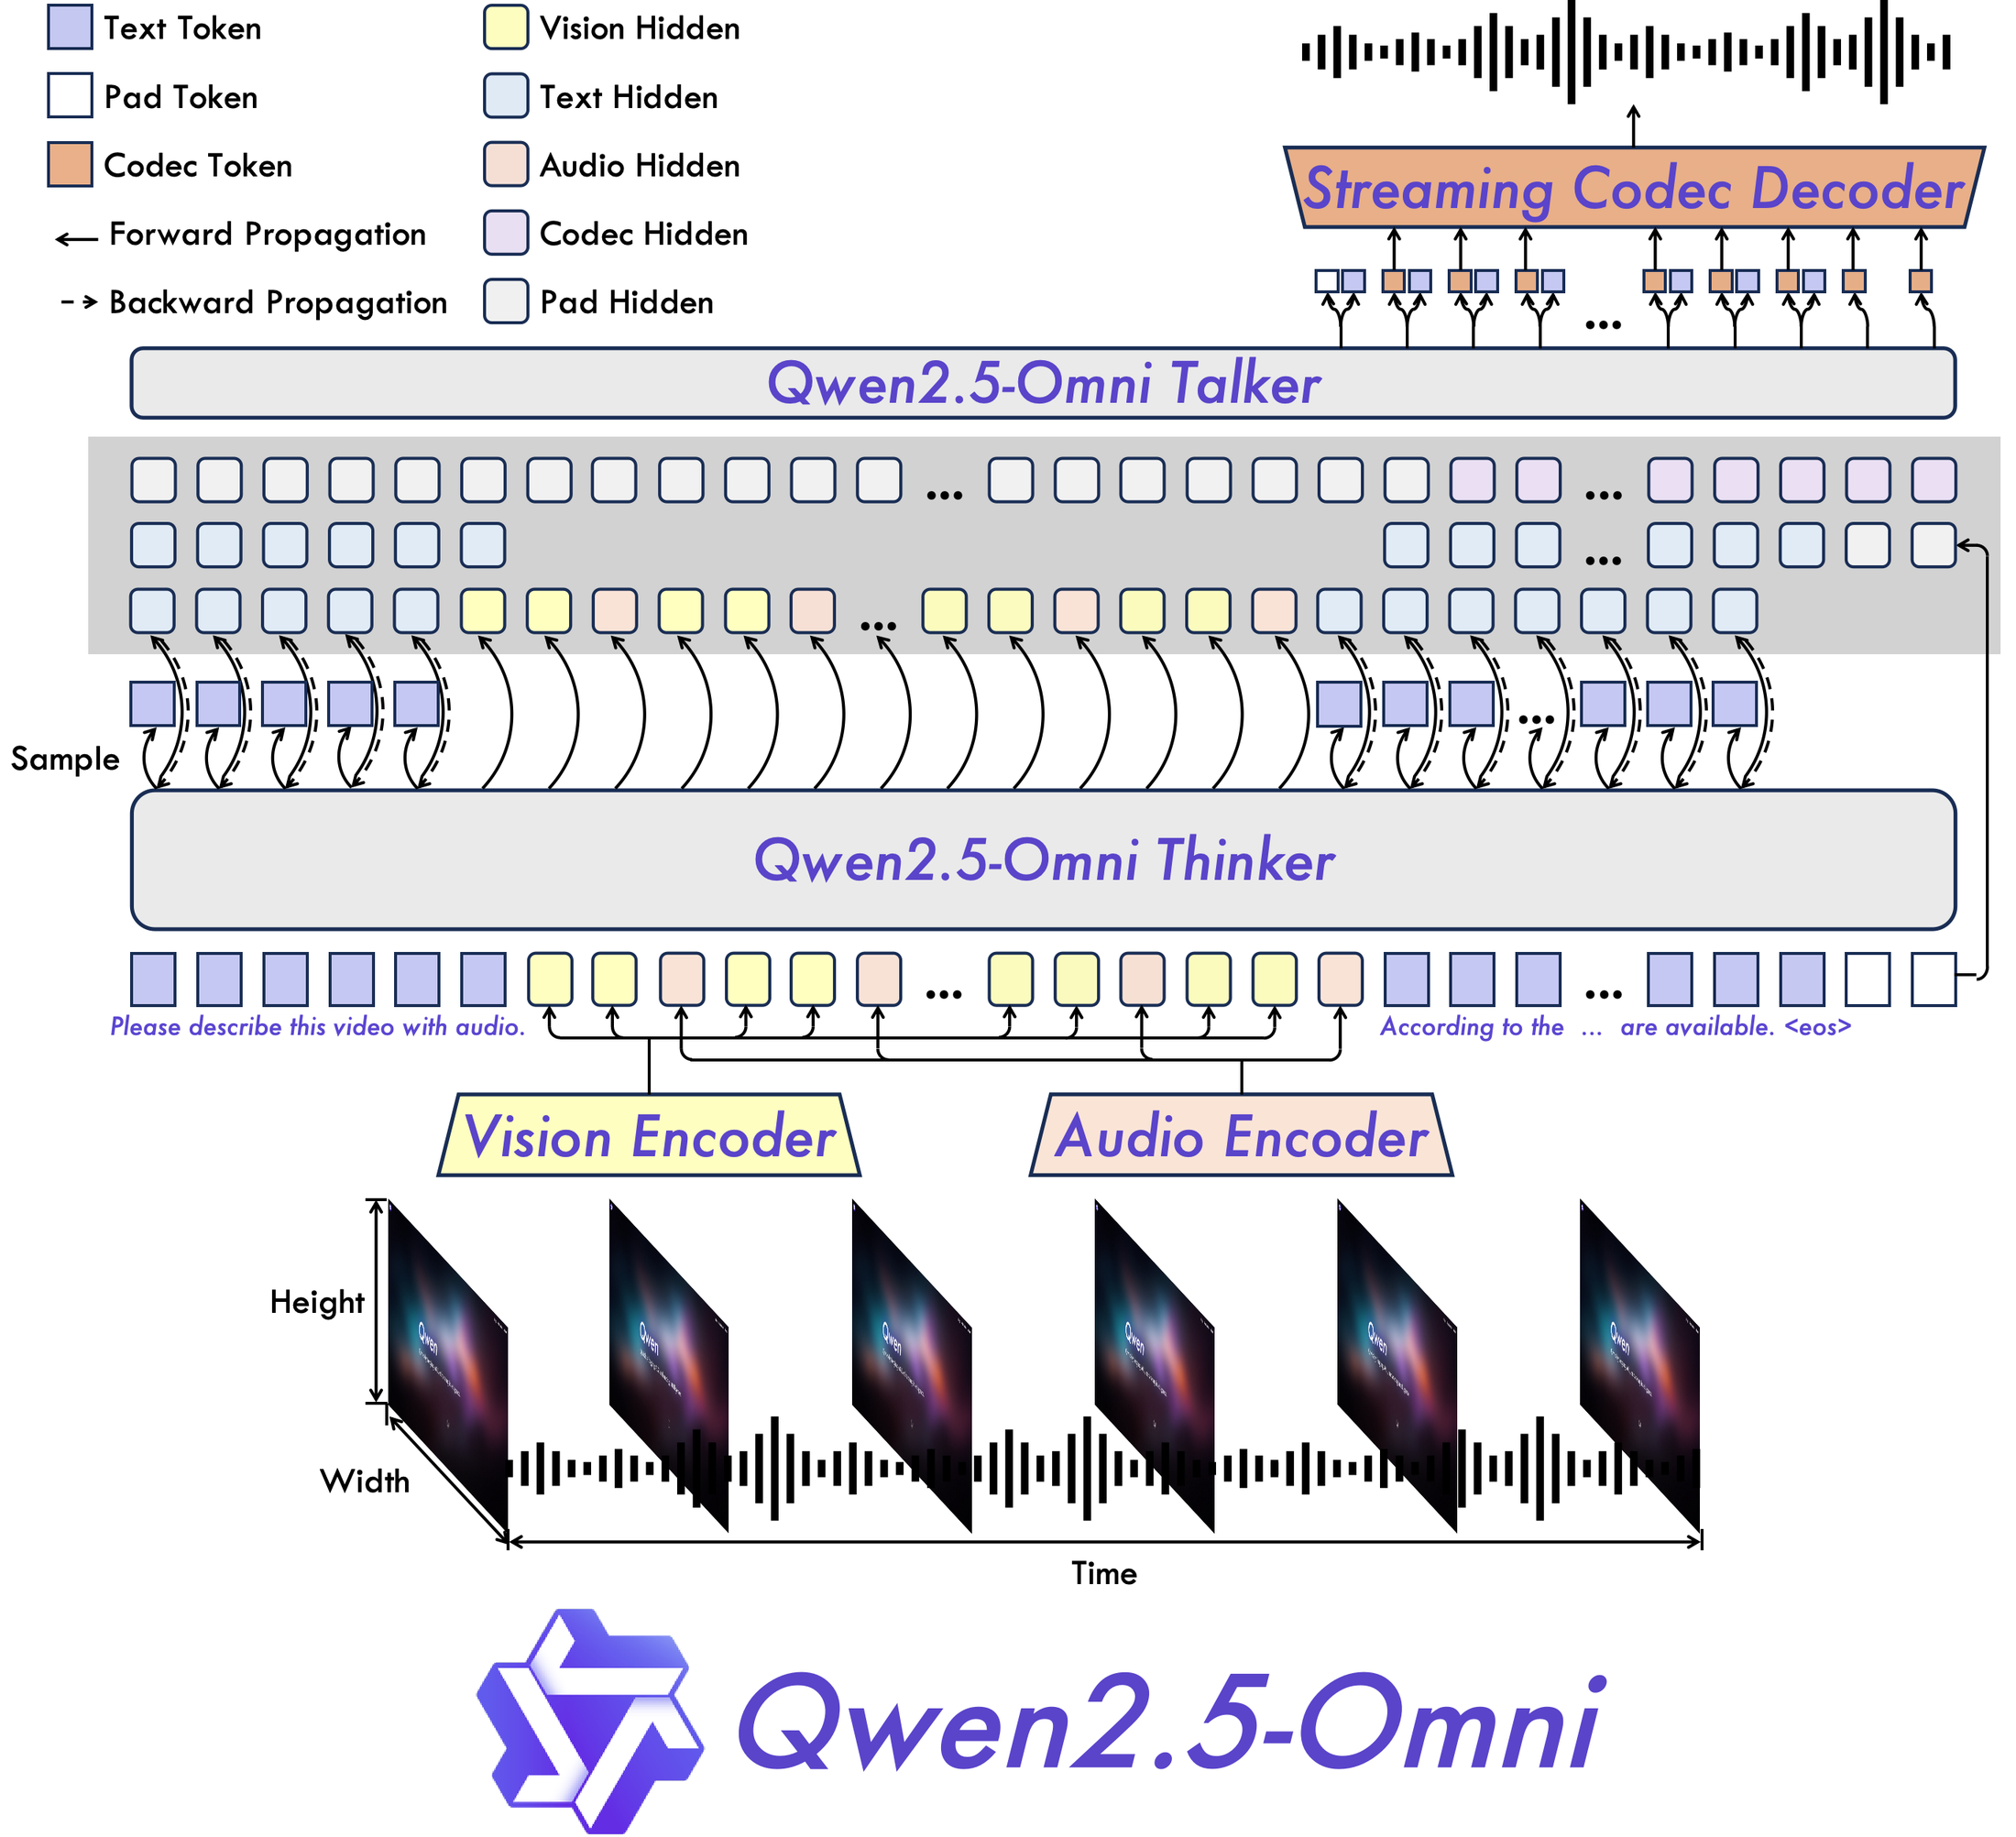
Figure 2 · Source
Qwen3-ASR
Identifies languages and transcribes speech across languages and dialects.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
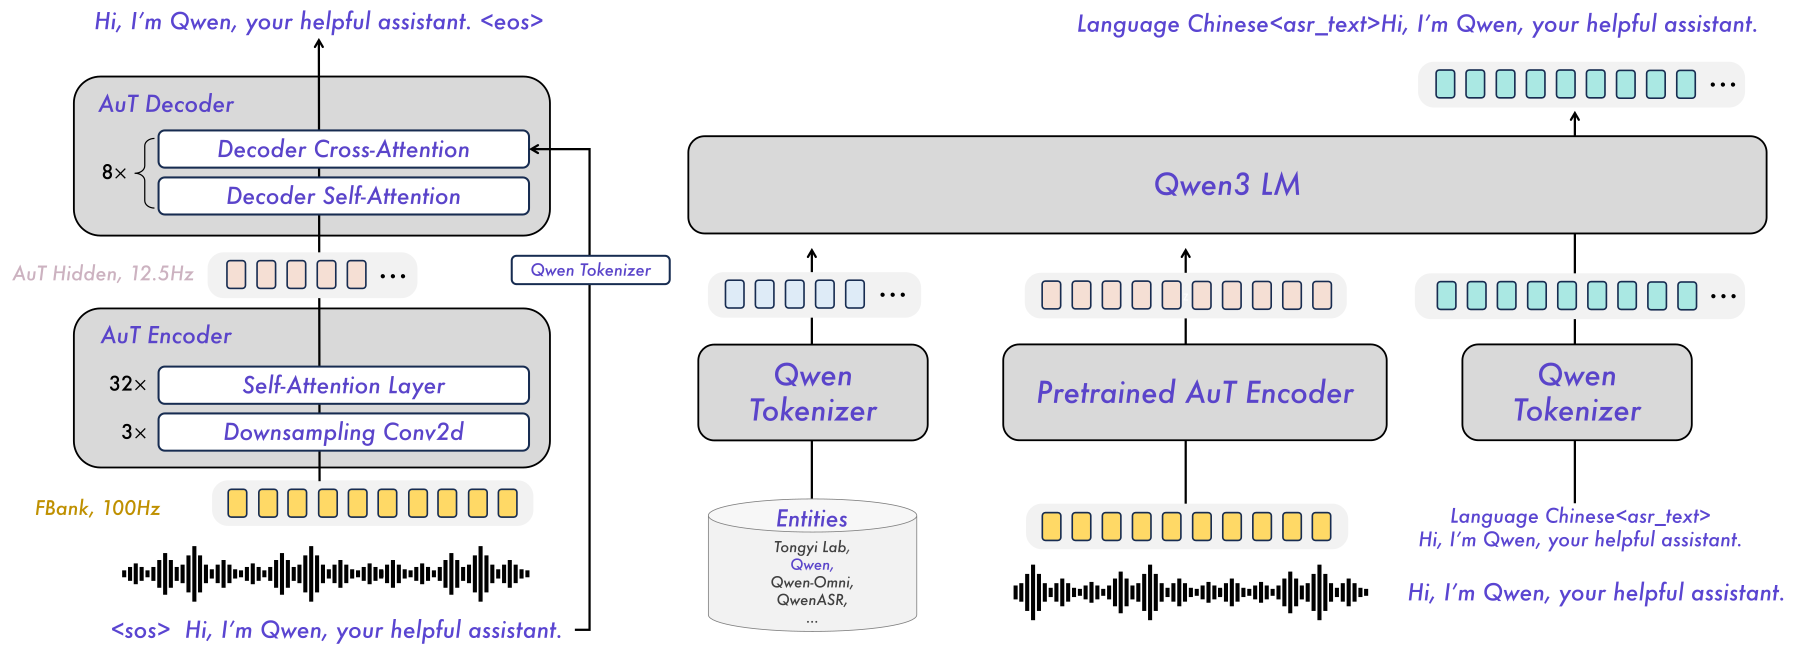
Figure 2 · Source
Qwen3-Omni Instruct
Converses about text, images, video and audio and generates streaming speech.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
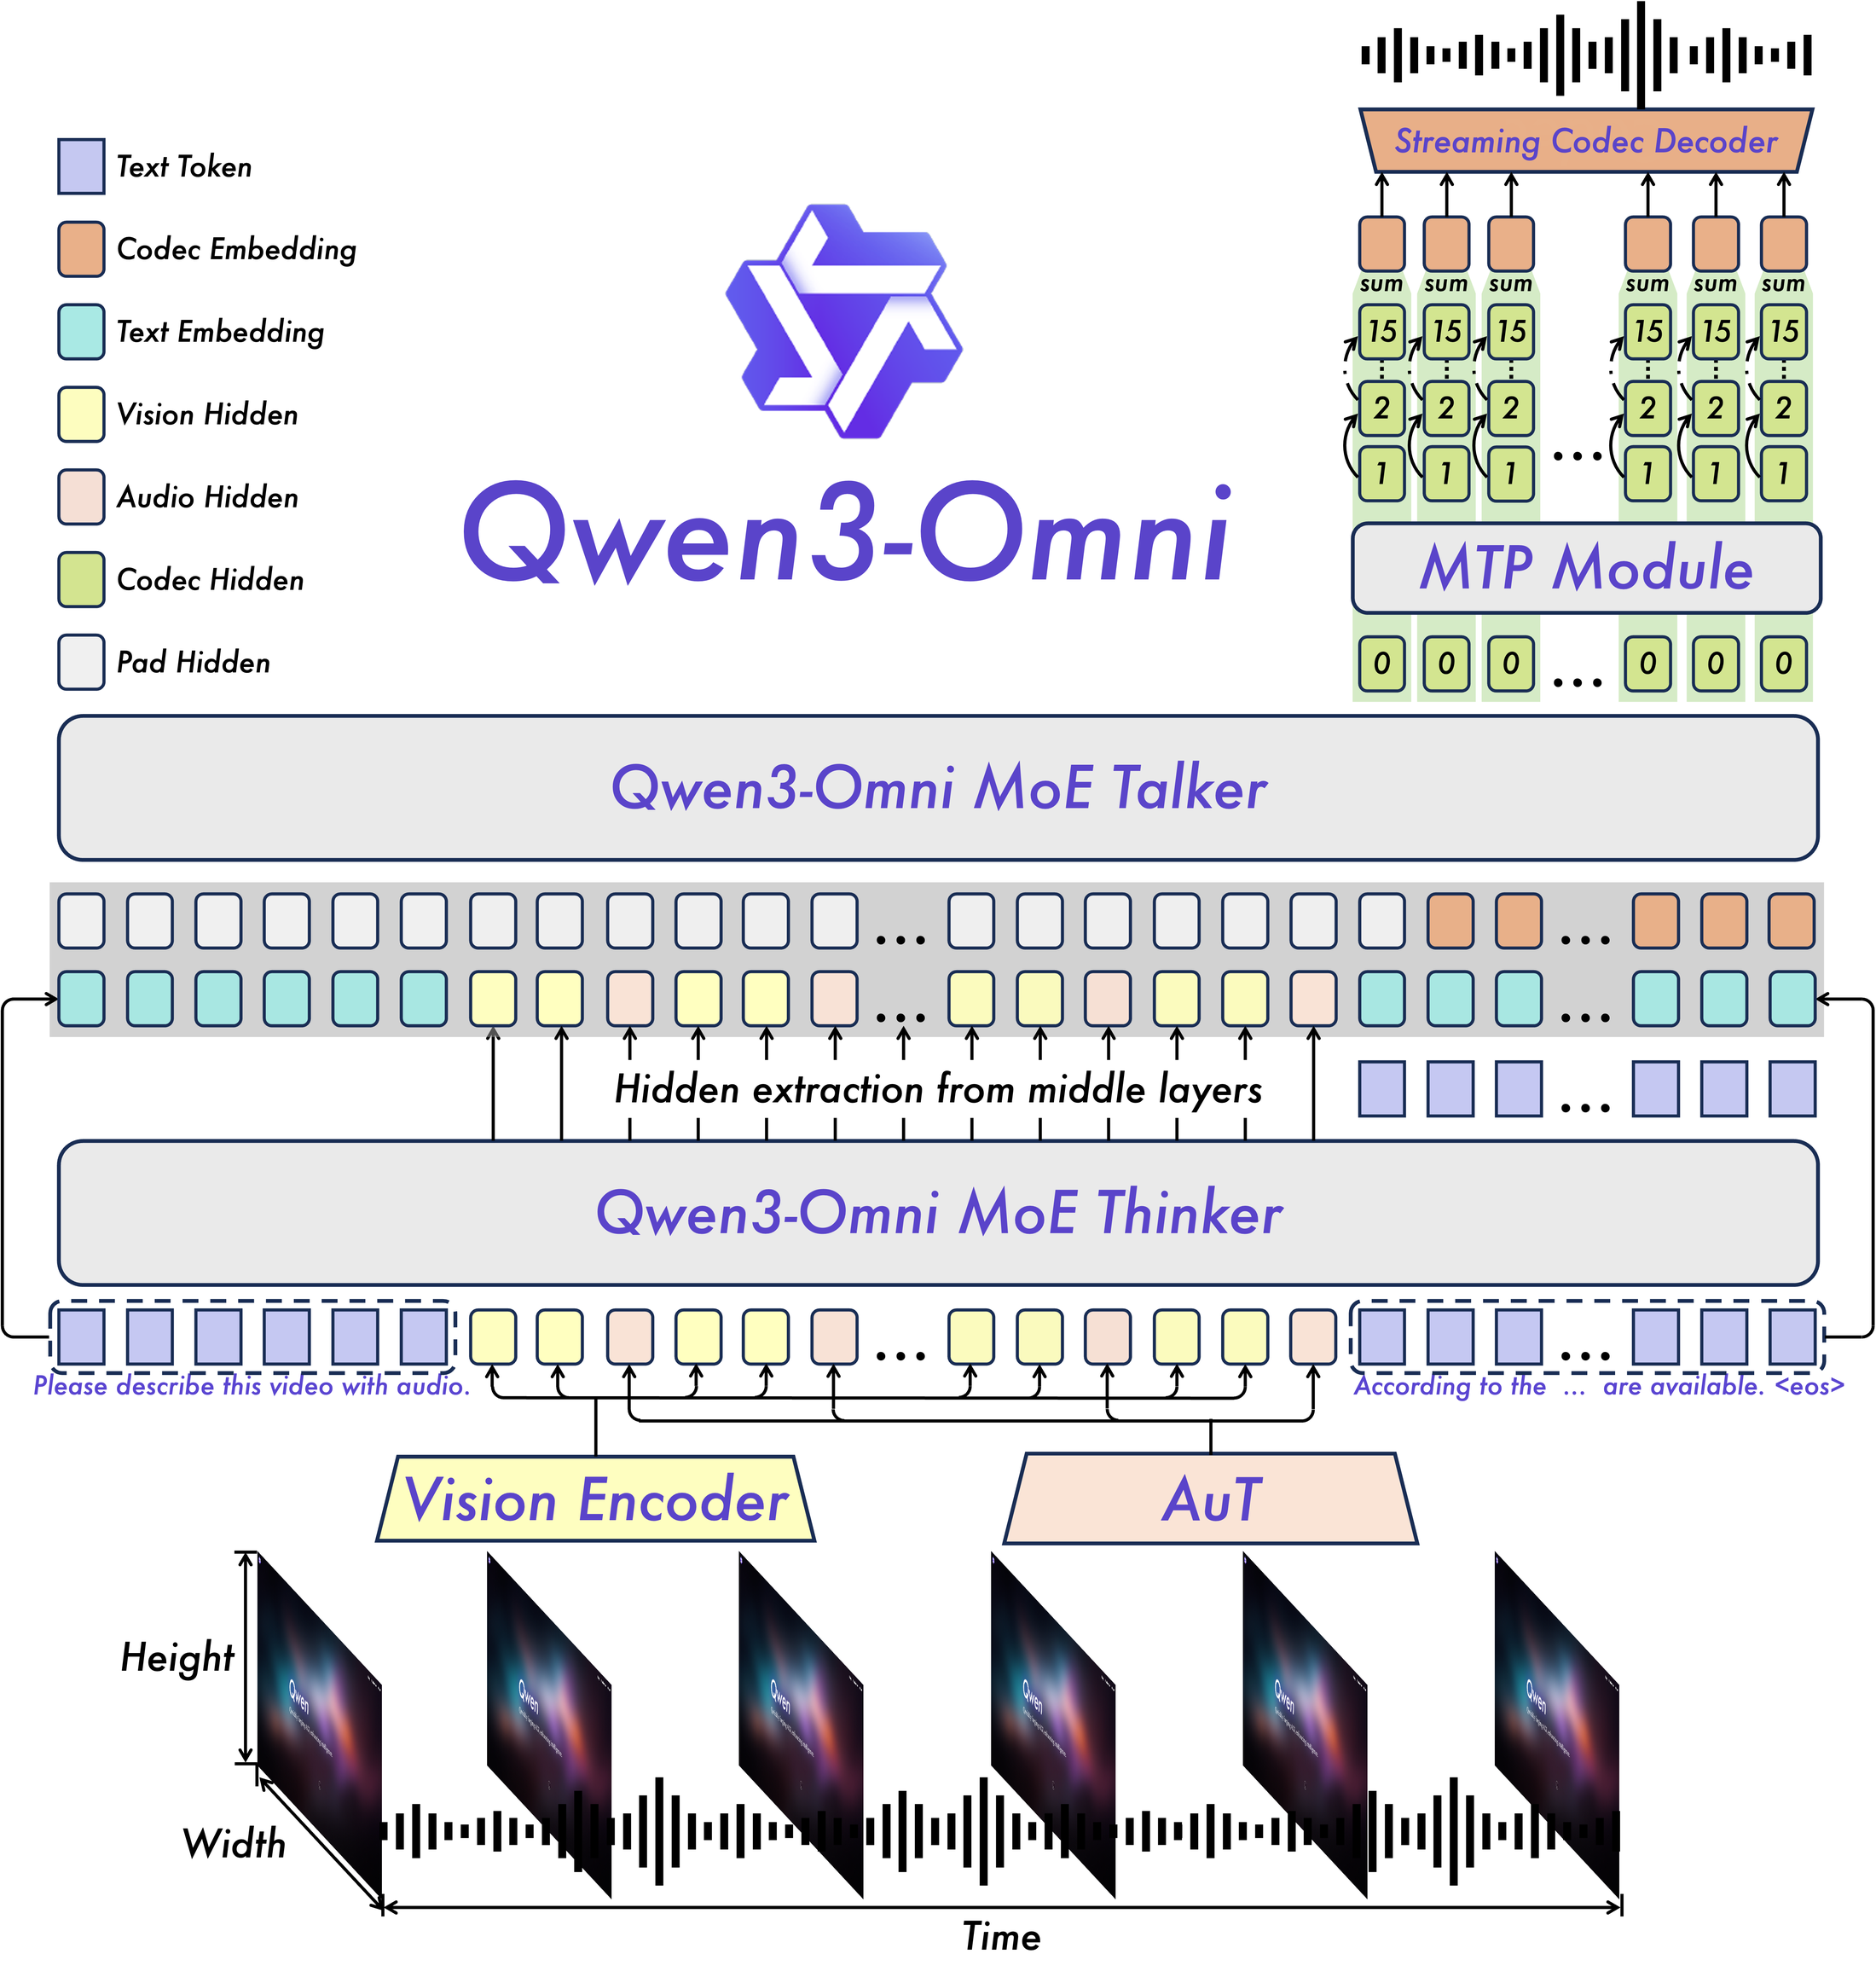
Figure 2 · Source
Qwen3-Omni Thinking
Uses explicit reasoning to answer questions about text, images, video and audio.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 2 · Source
R1-Omni
Reasons about emotion using facial, vocal and contextual cues in videos.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
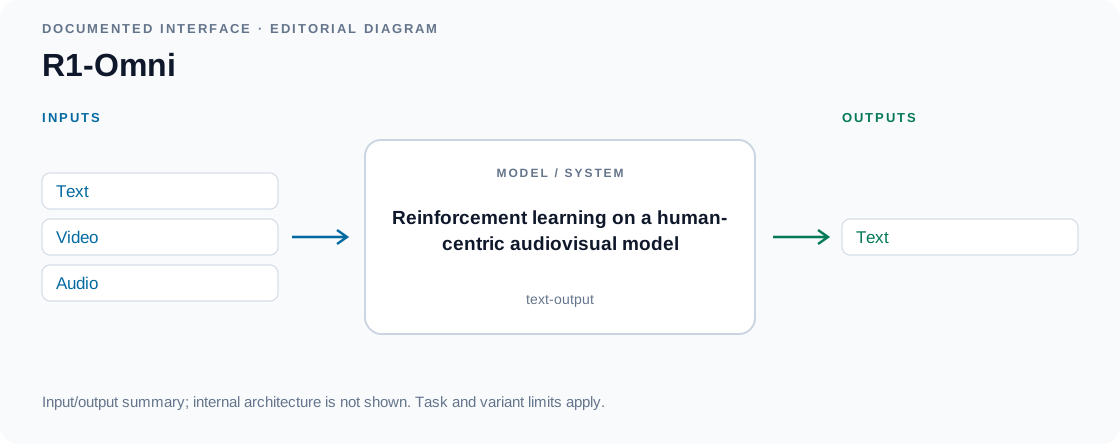
Input/output diagram · Source
SALMONN
Transcribes speech, captions sound and music, and answers audio-grounded questions.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Apache-2.0 + Llama 2 terms — The Vicuna/Llama 2 language backbone retains its community license.
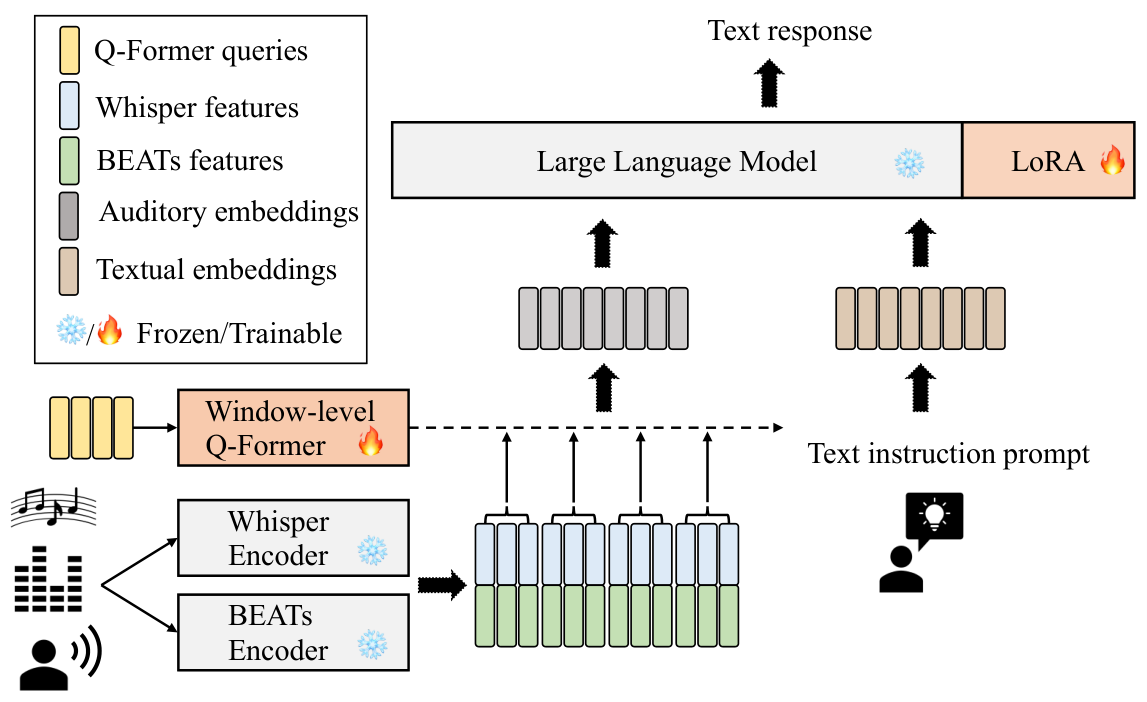
Figure 1 · Source
SALMONN-2
Understands speech, sounds and music and supports context-aware transcription and audio questions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
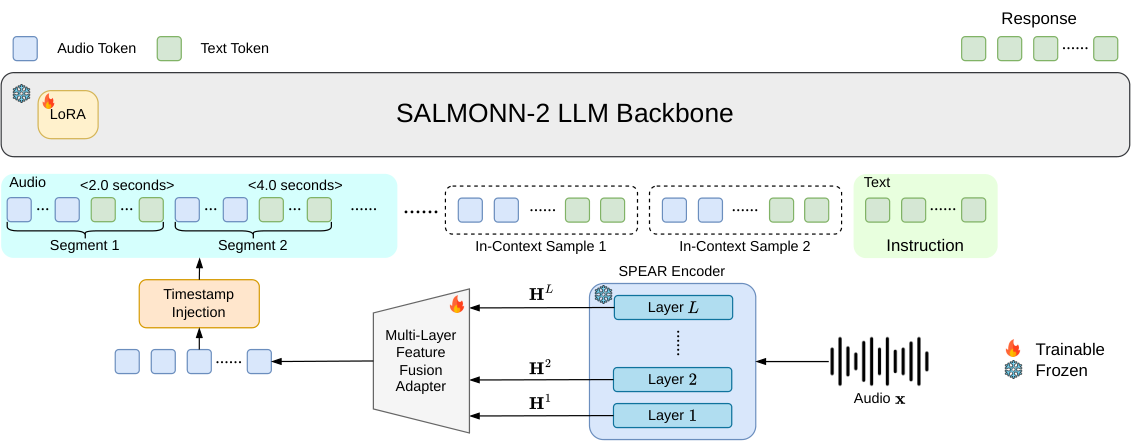
Figure 2 · Source
SLAM-Omni
Conducts multi-turn voice conversations while allowing the output speaker's timbre to be changed.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
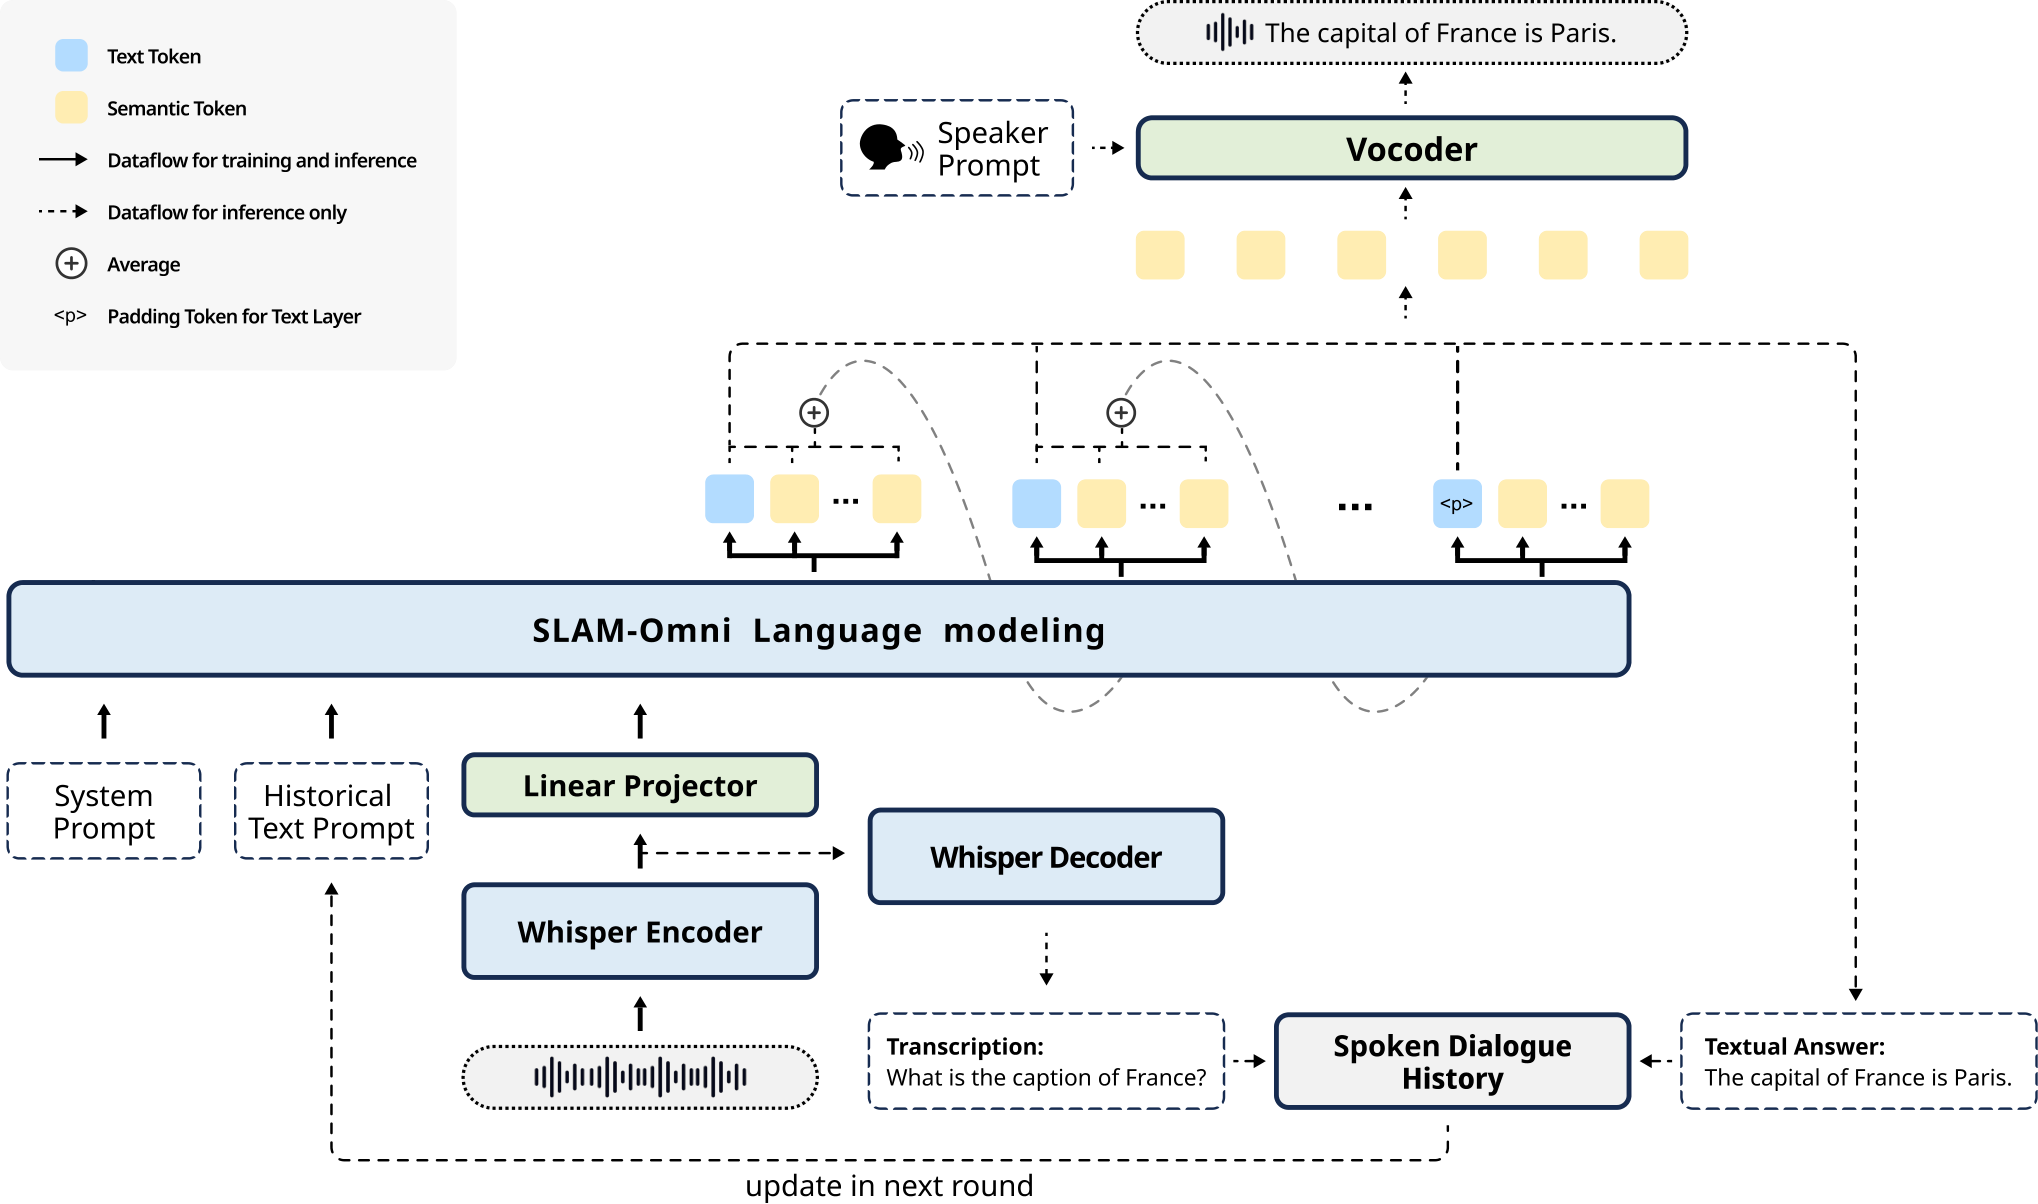
Figure 2 · Source
SoulX-Duplug
Predicts when a voice assistant should keep listening, respond or handle an interruption.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
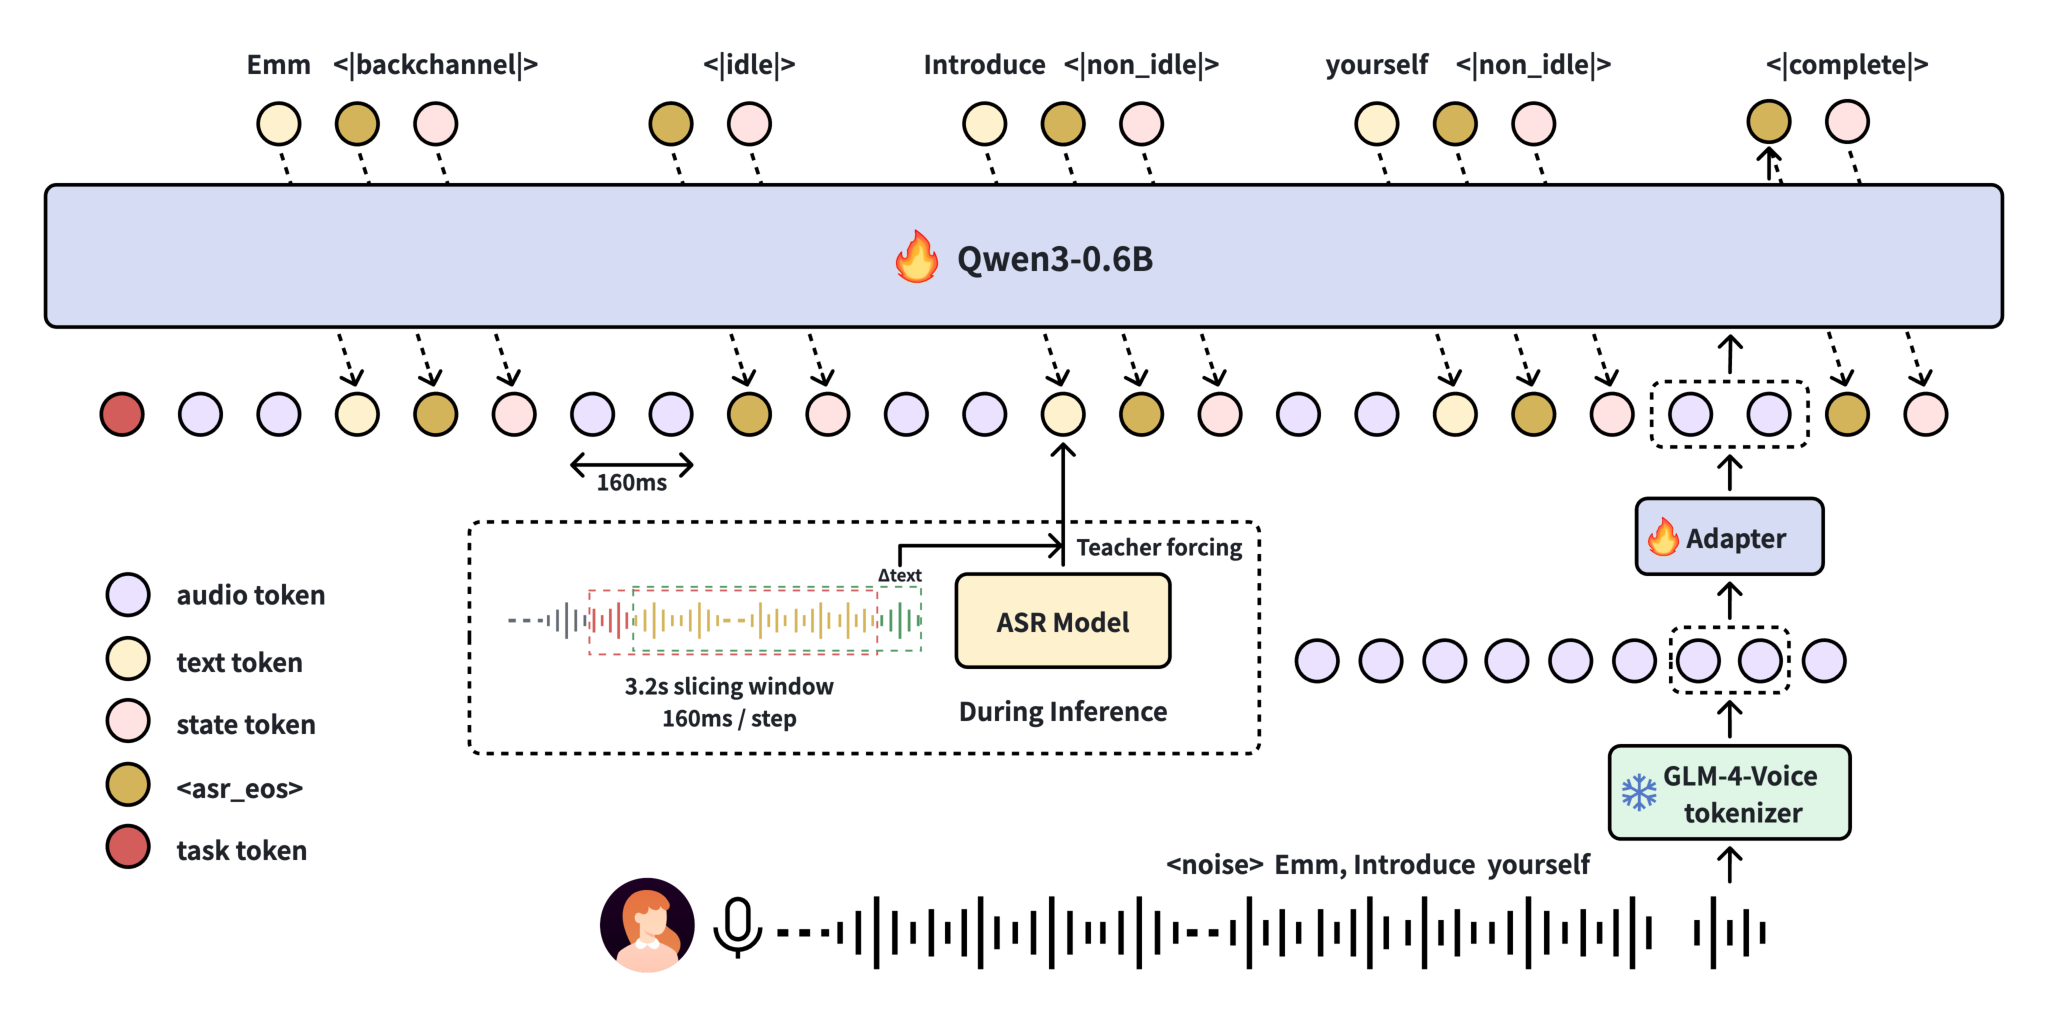
Figure 4 · Source
SpeechGPT
Follows spoken instructions and generates speech using discrete speech units in a language model.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — The repository licenses code, but a release-specific weight license was not located.
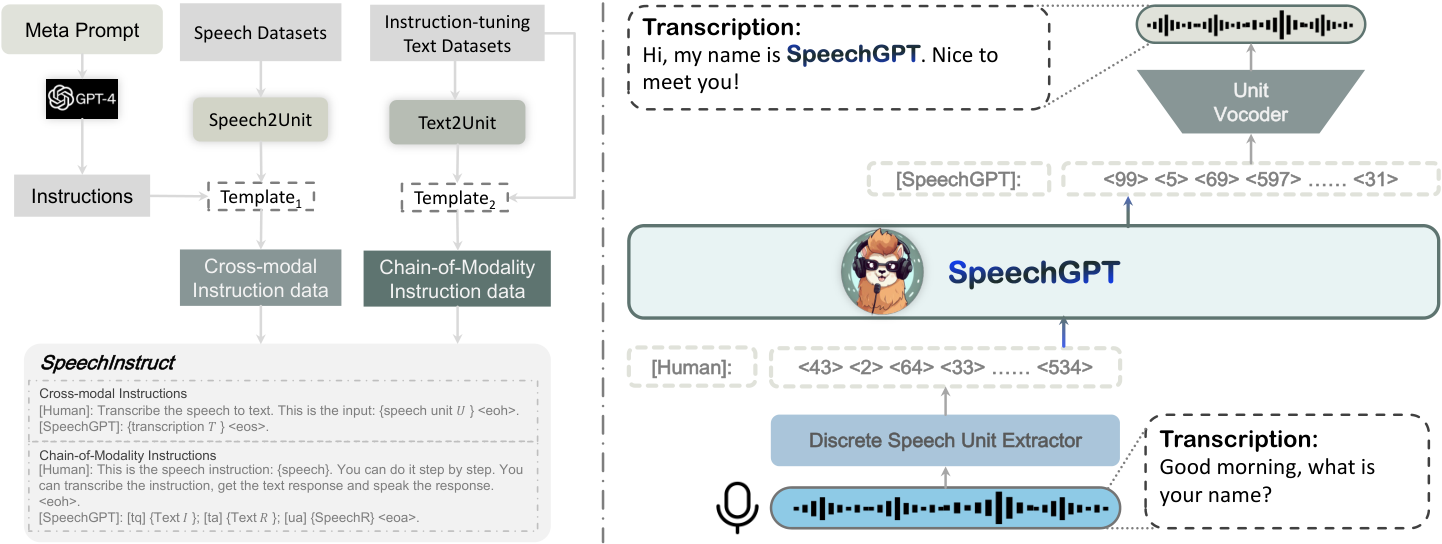
Figure 2 · Source
SpeechGPT 2.0 Preview
Understands spoken requests and produces natural spoken responses through a speech-native language model.
License unclear: code Apache-2.0 · weights Not stated — The repository licenses code, but a release-specific weight license was not located.
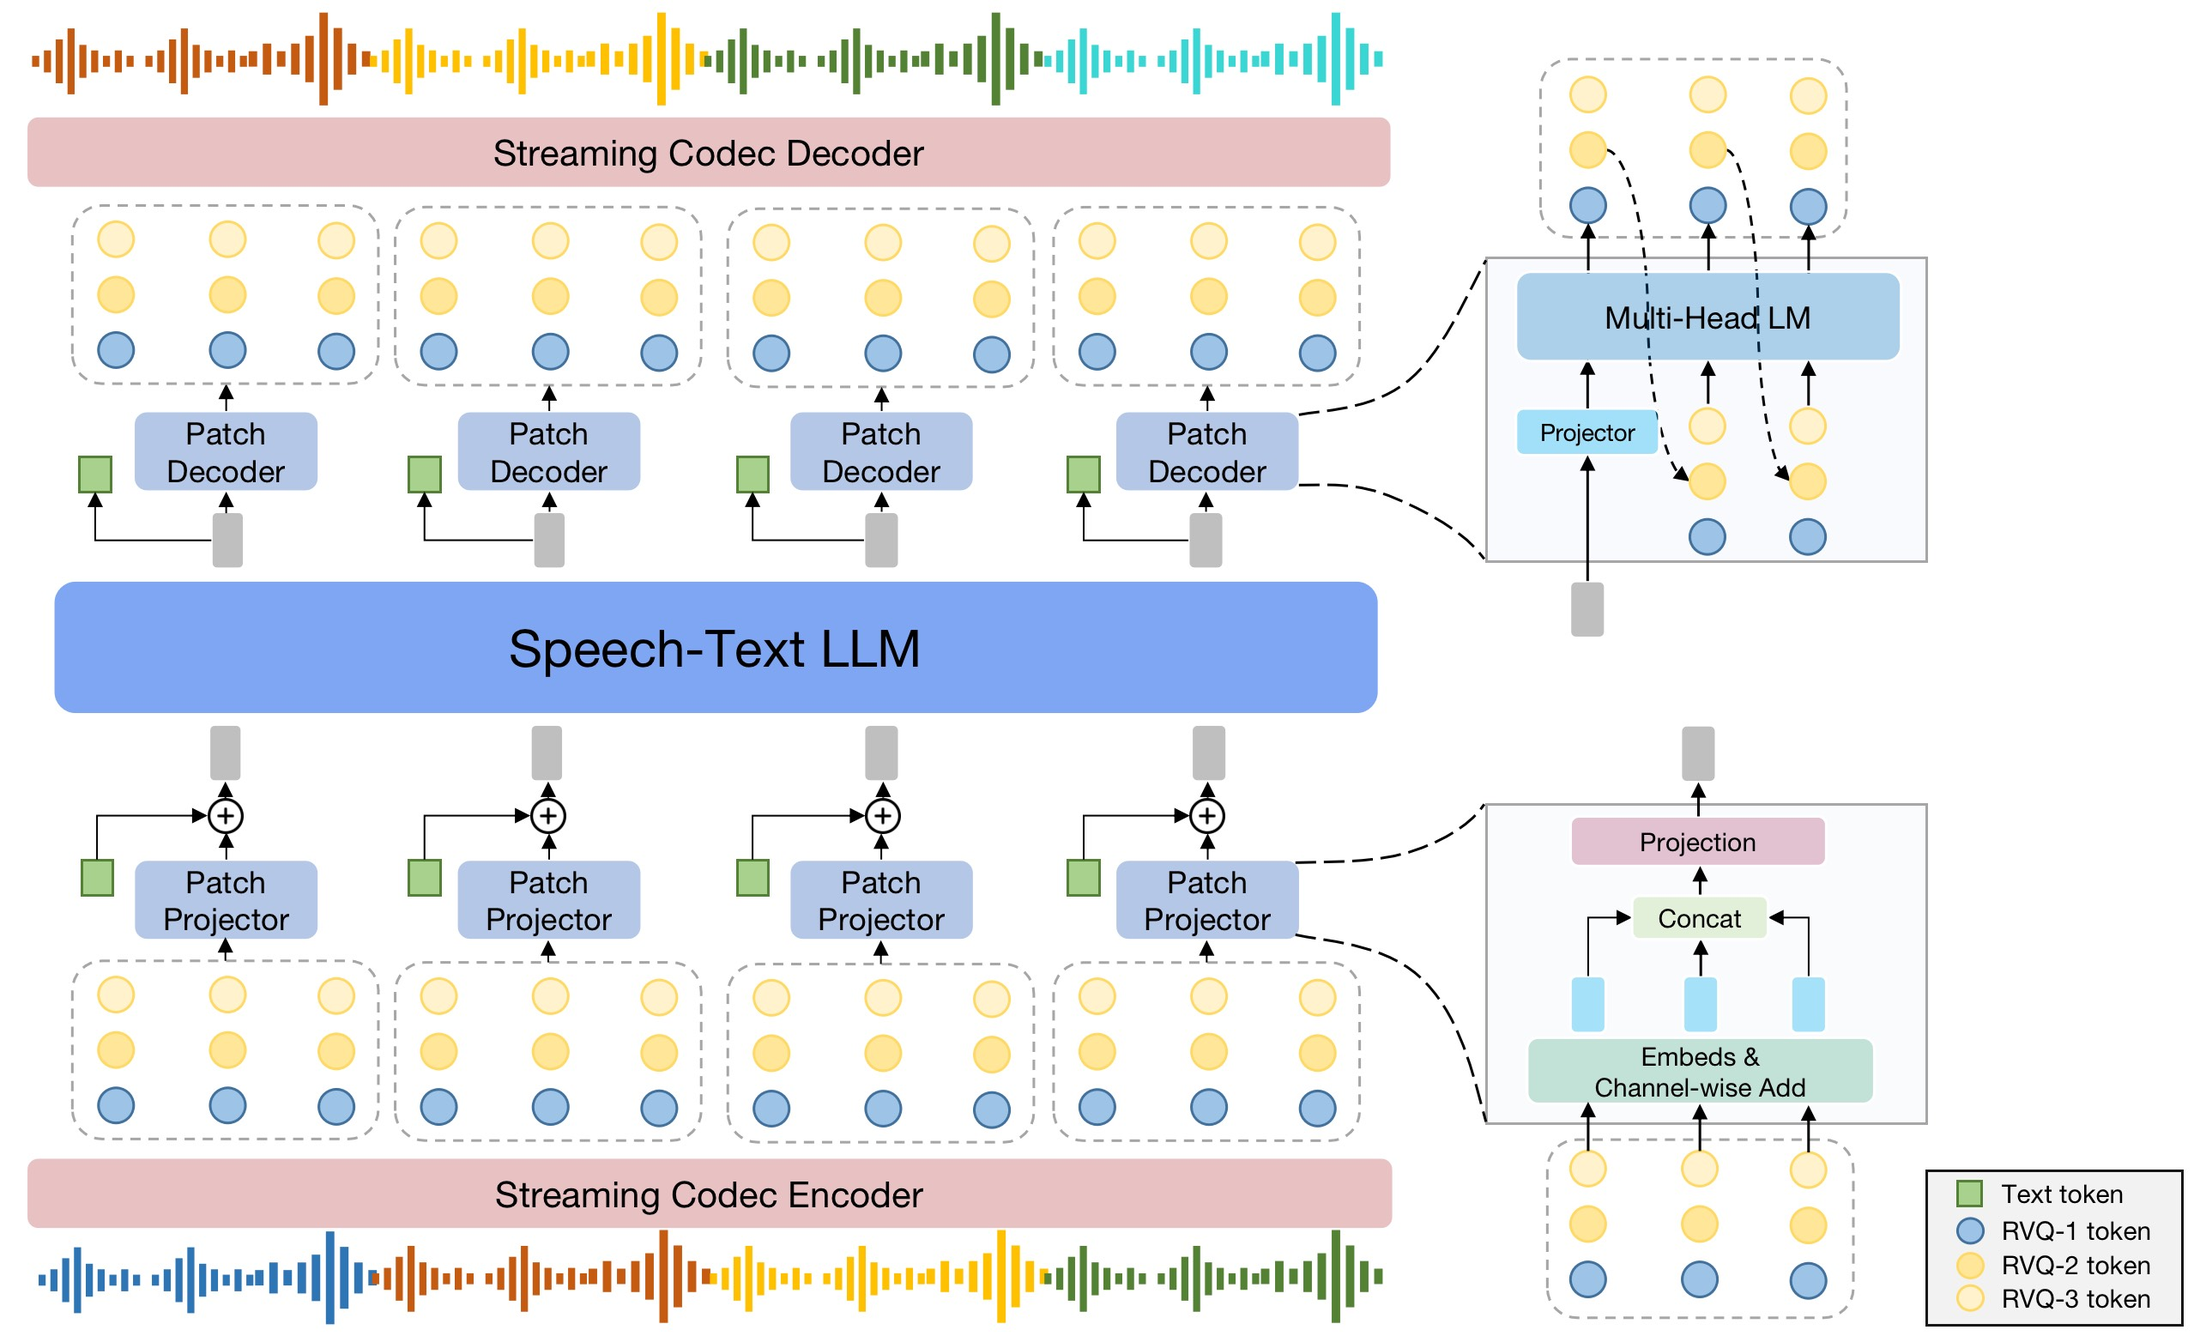
Official architecture diagram · Source
Step-Audio
Supports voice conversations with expressive speech, role-play and spoken tool requests.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
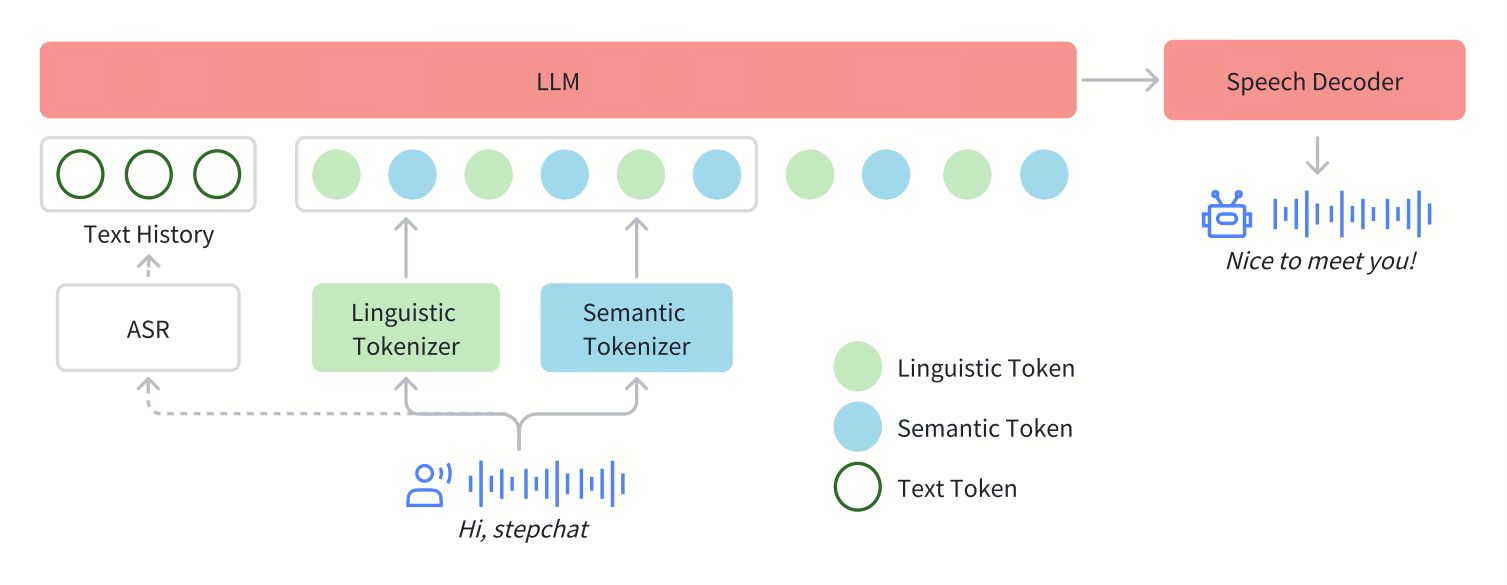
Figure 2 · Source
Step-Audio 2 Mini
Understands audio and produces expressive spoken replies, with support for tool-assisted conversations.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
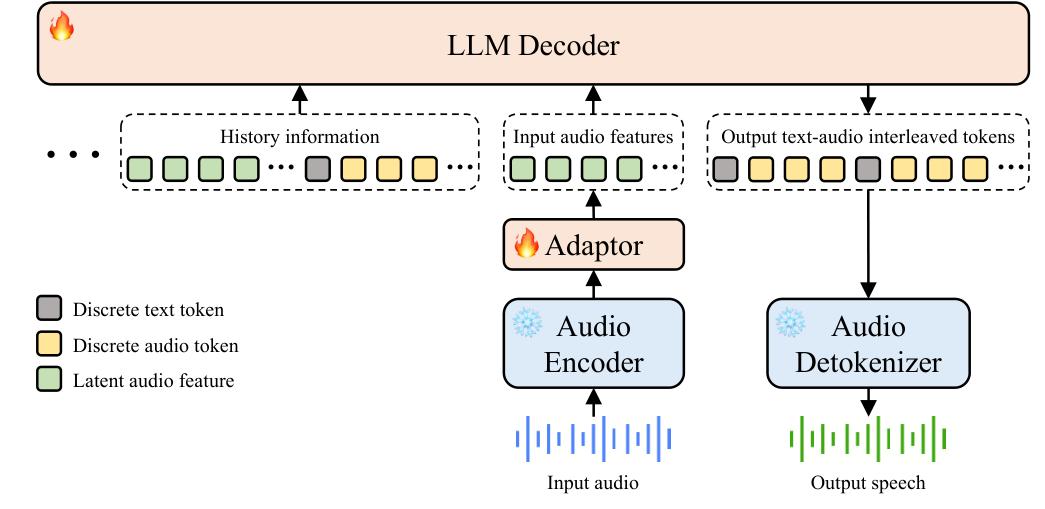
Figure 3 · Source
Step-Audio 2 Mini Think
Reasons before answering spoken questions and complex audio-understanding tasks.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 3 · Source
Step-Audio-AQAA
Produces expressive spoken answers directly from audio questions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
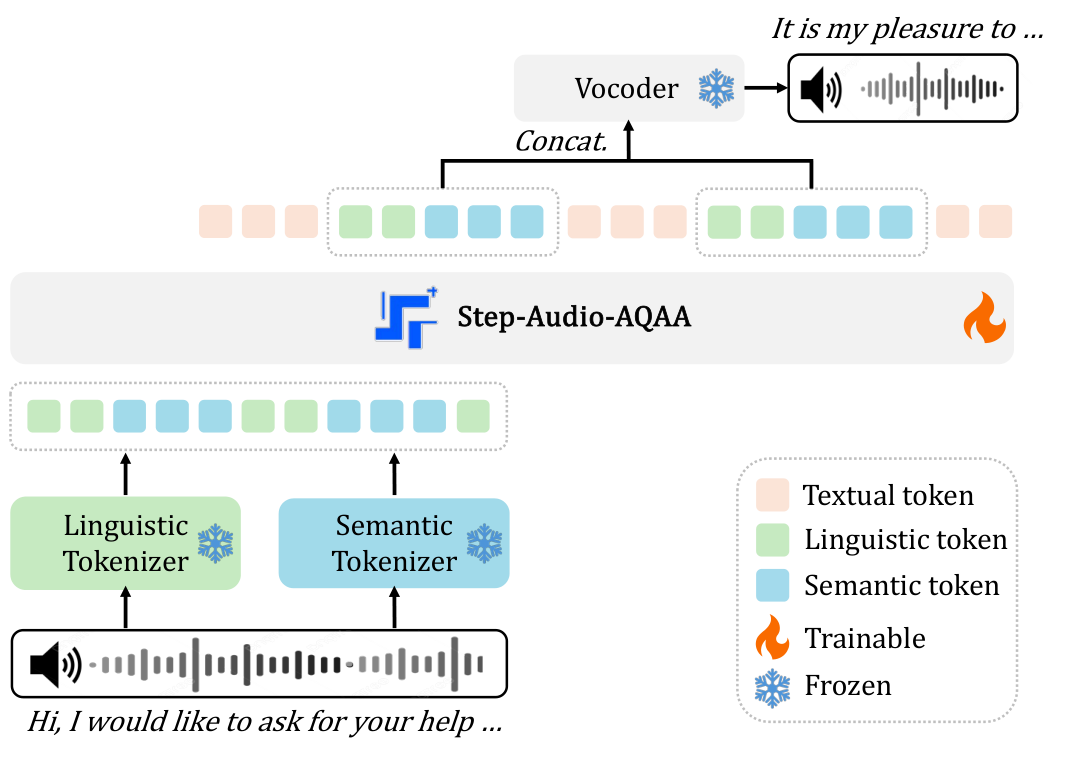
Figure 1 · Source
Step-Audio-R1
Uses reinforcement-learned reasoning to answer questions about speech, sound and music.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
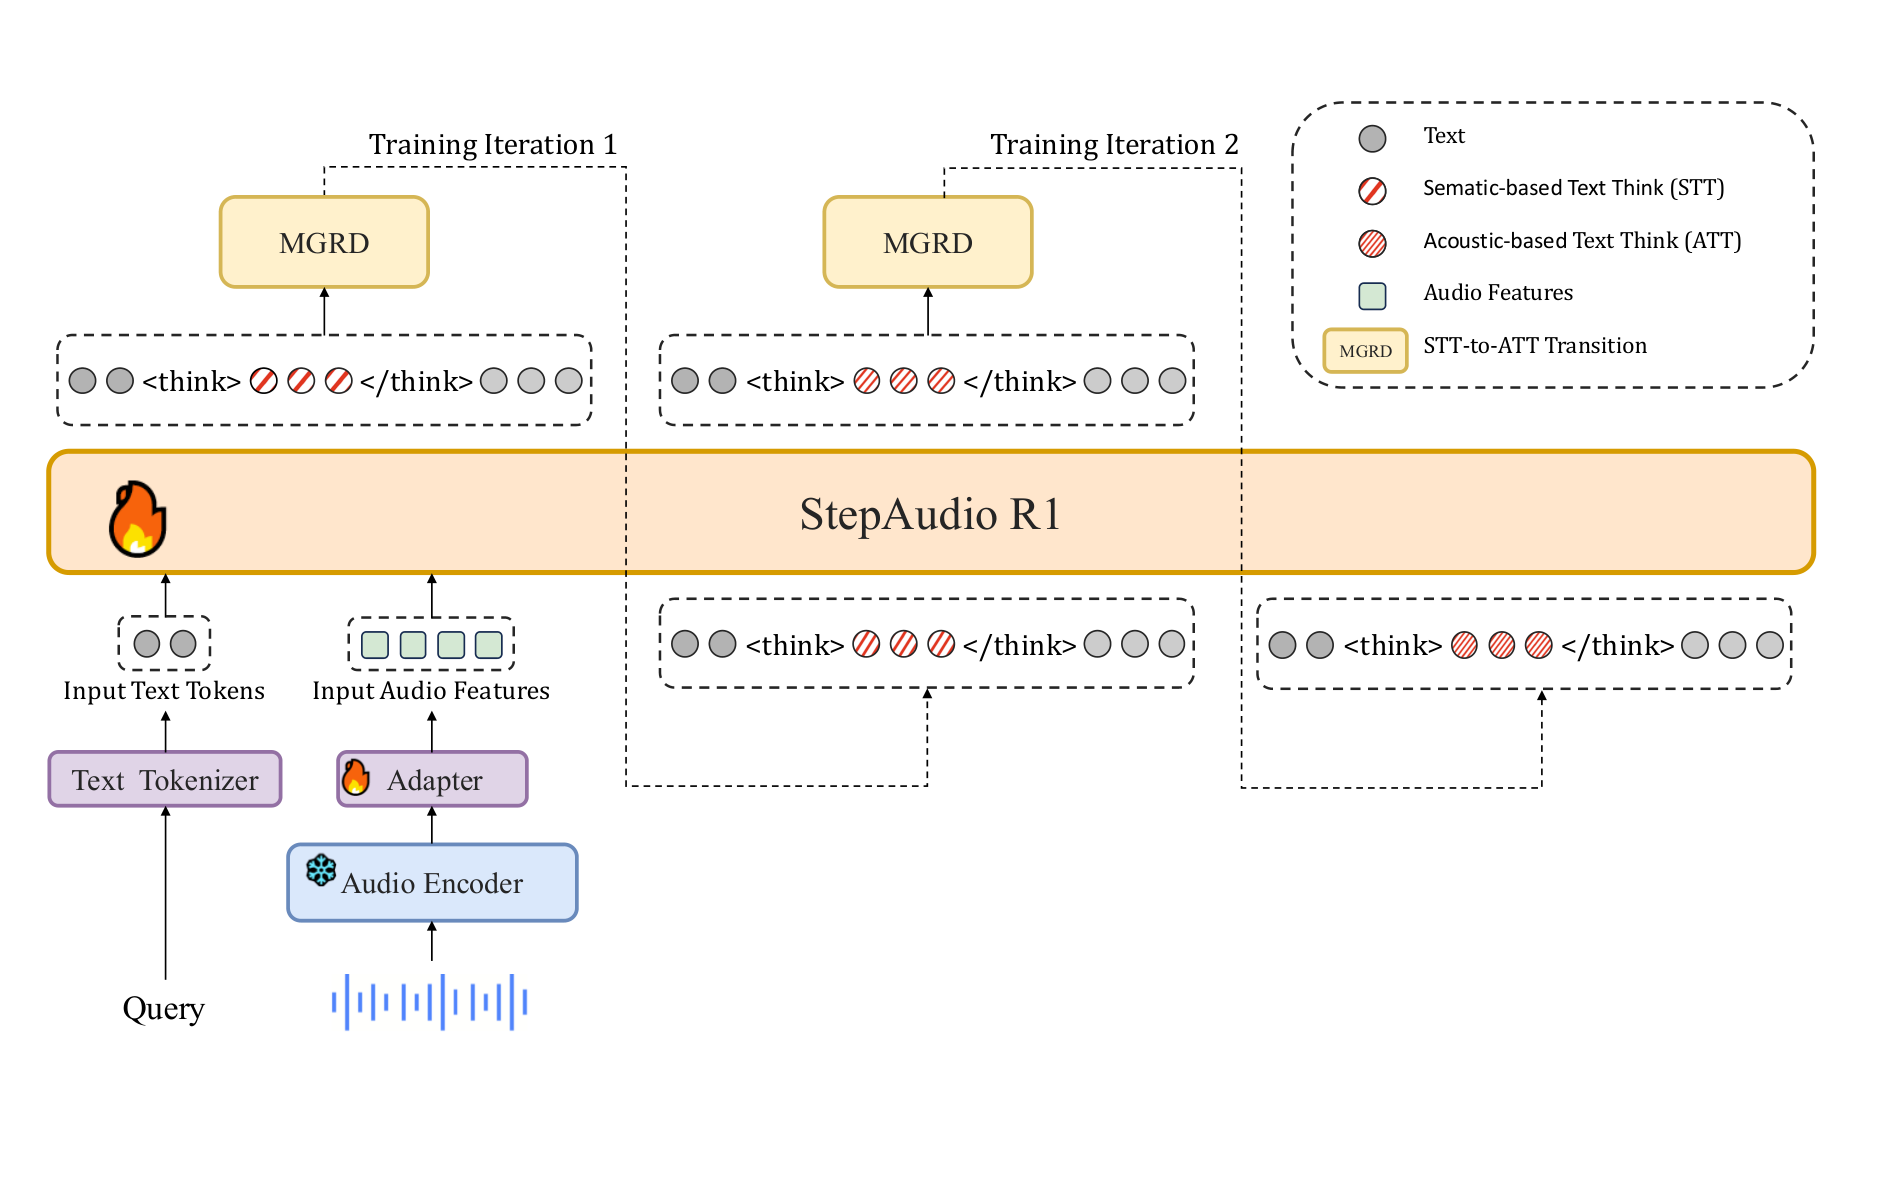
Figure 2 · Source
Step-Audio-R1.1
Extends audio reasoning into responsive spoken dialogue and voice interaction.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
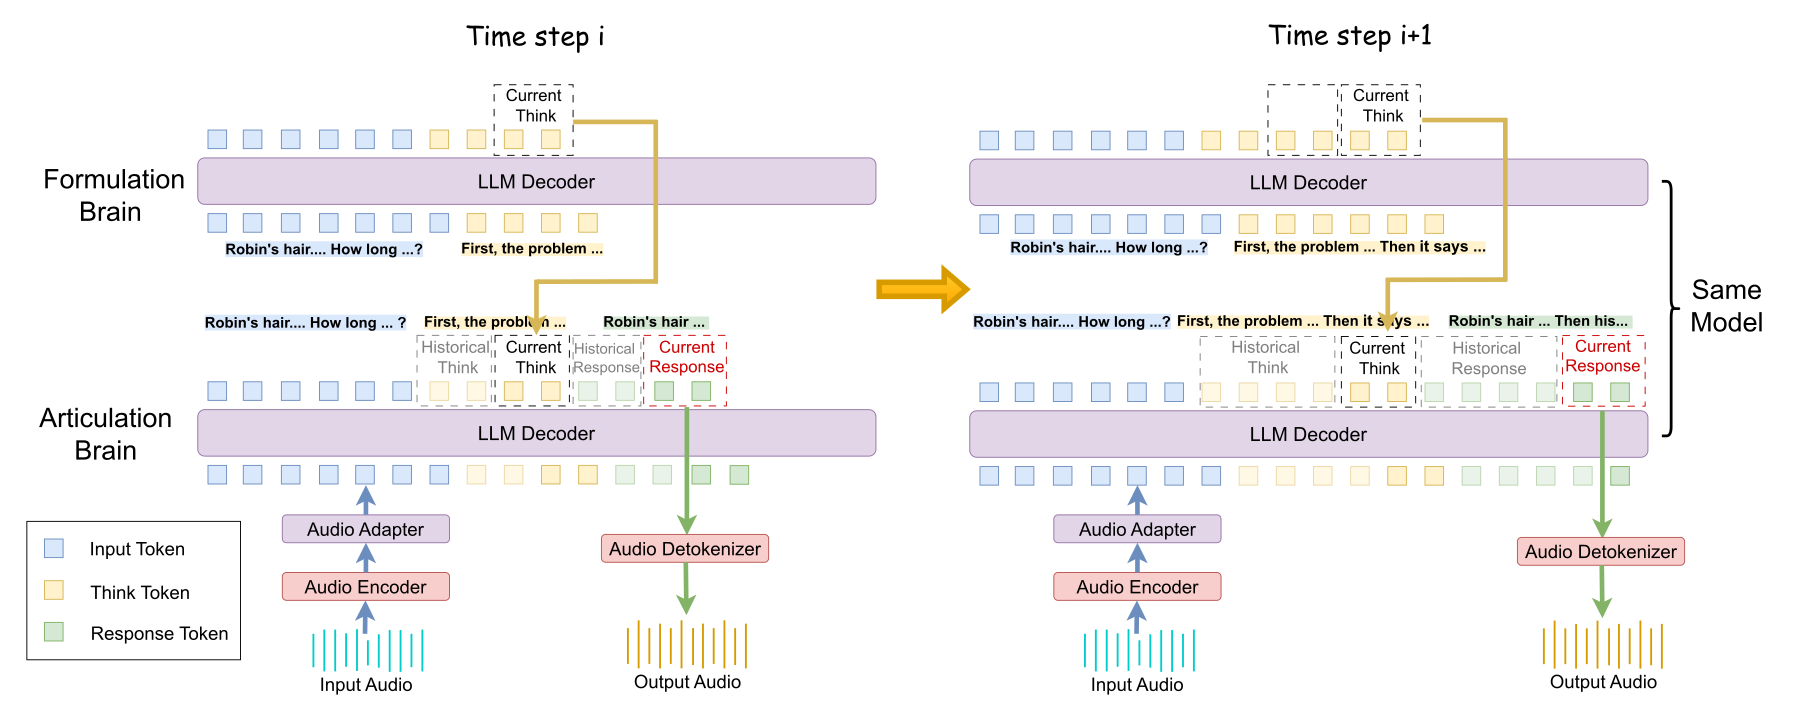
Related method — Mind-Paced Speaking, Figure 3 · Source
Stream-Omni
Supports simultaneous text, image and spoken interaction while aligning text and speech outputs.
Paper · Code · Weights · Details
Custom / restricted: code GPL-3.0 · weights GPL-3.0 + Llama 3.1 terms — The included Llama 3.1 backbone retains its community license.
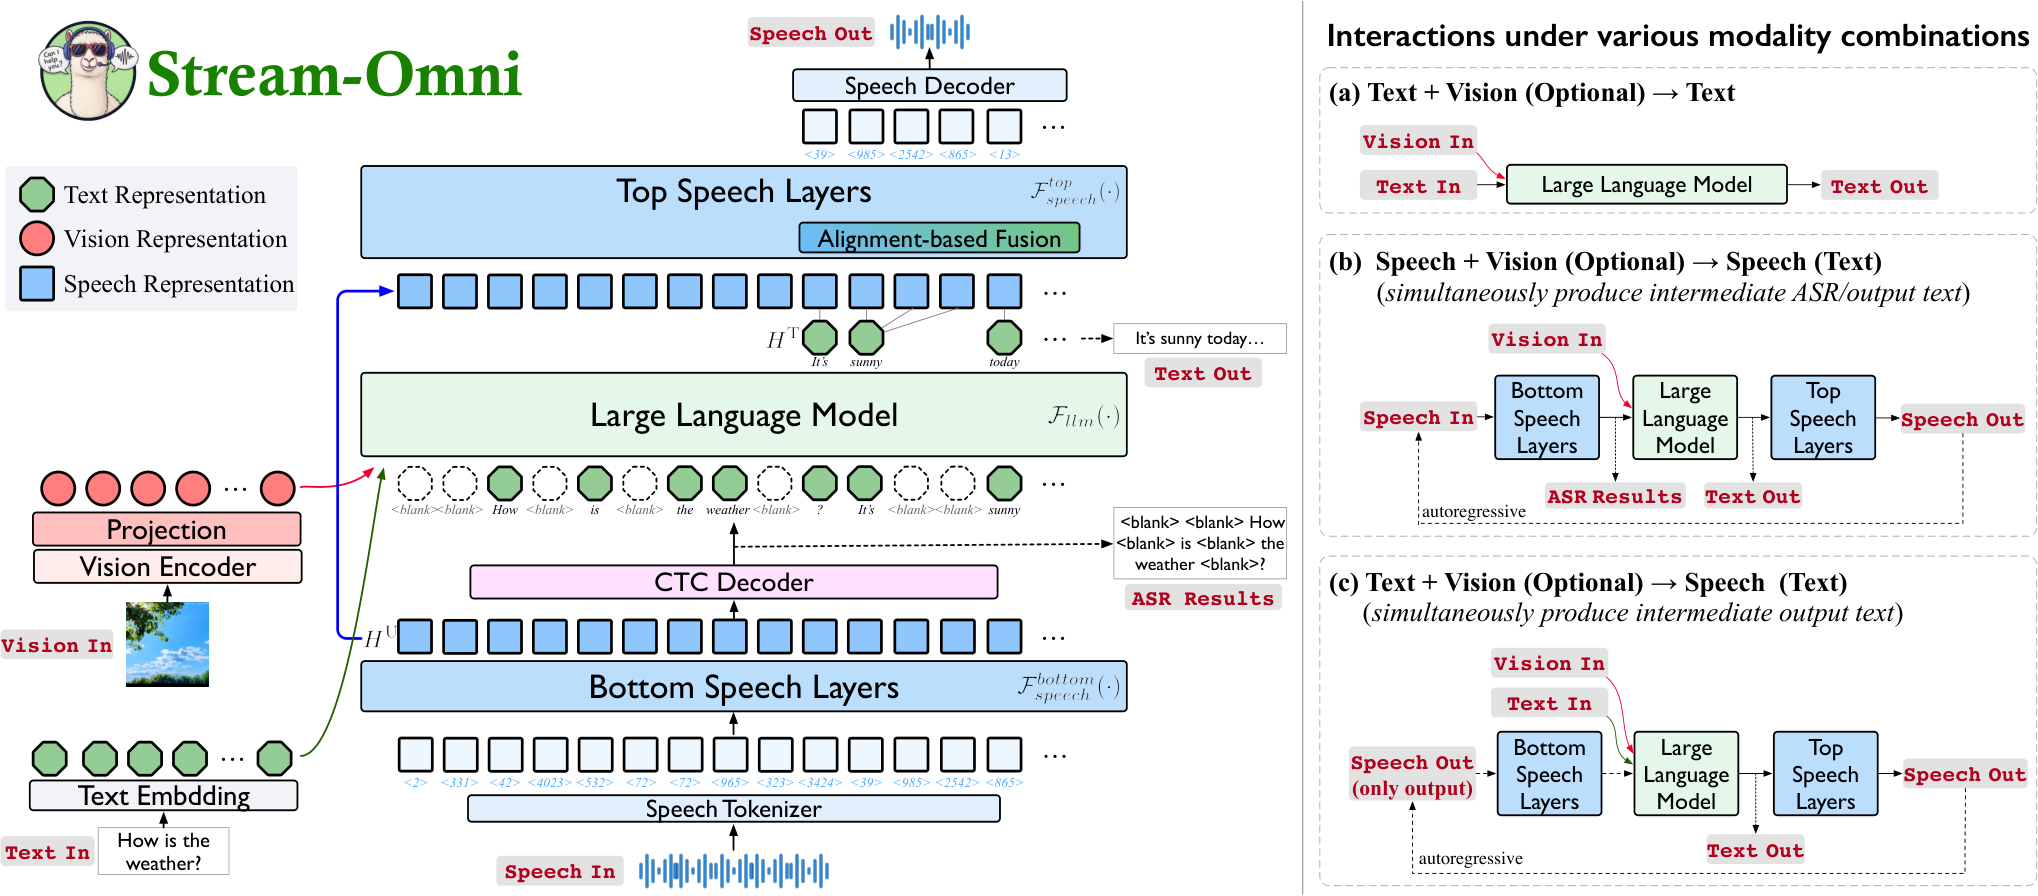
Figure 2 · Source
Sympatheia
Adjusts spoken replies to a speaker's changing emotional state.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 + GLM-4 terms — GLM-4-Voice base-model conditions also apply; repository code licensing is not stated.
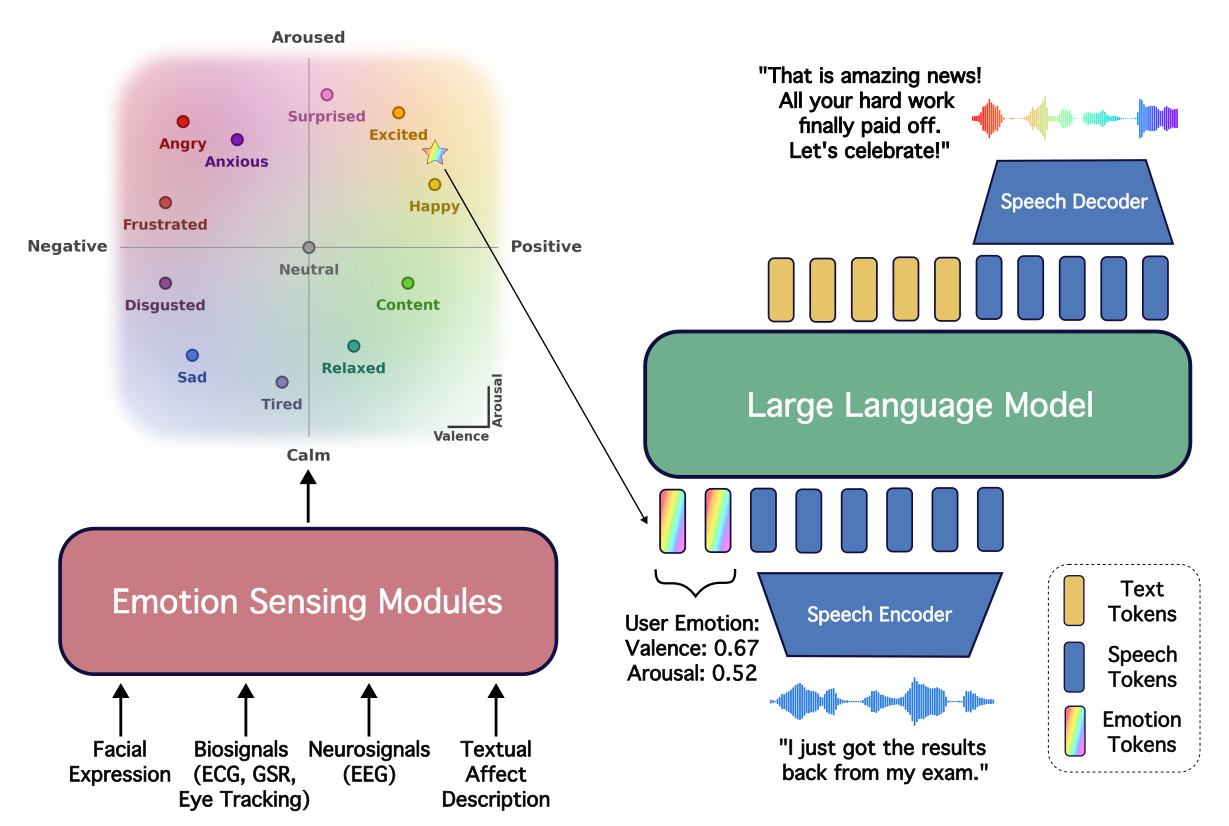
Figure 3 · Source
TurnGuide
Maintains coherent spoken conversations while managing overlaps and turn changes.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — No release-specific weight license is stated; the GLM-4-Voice base has custom terms.
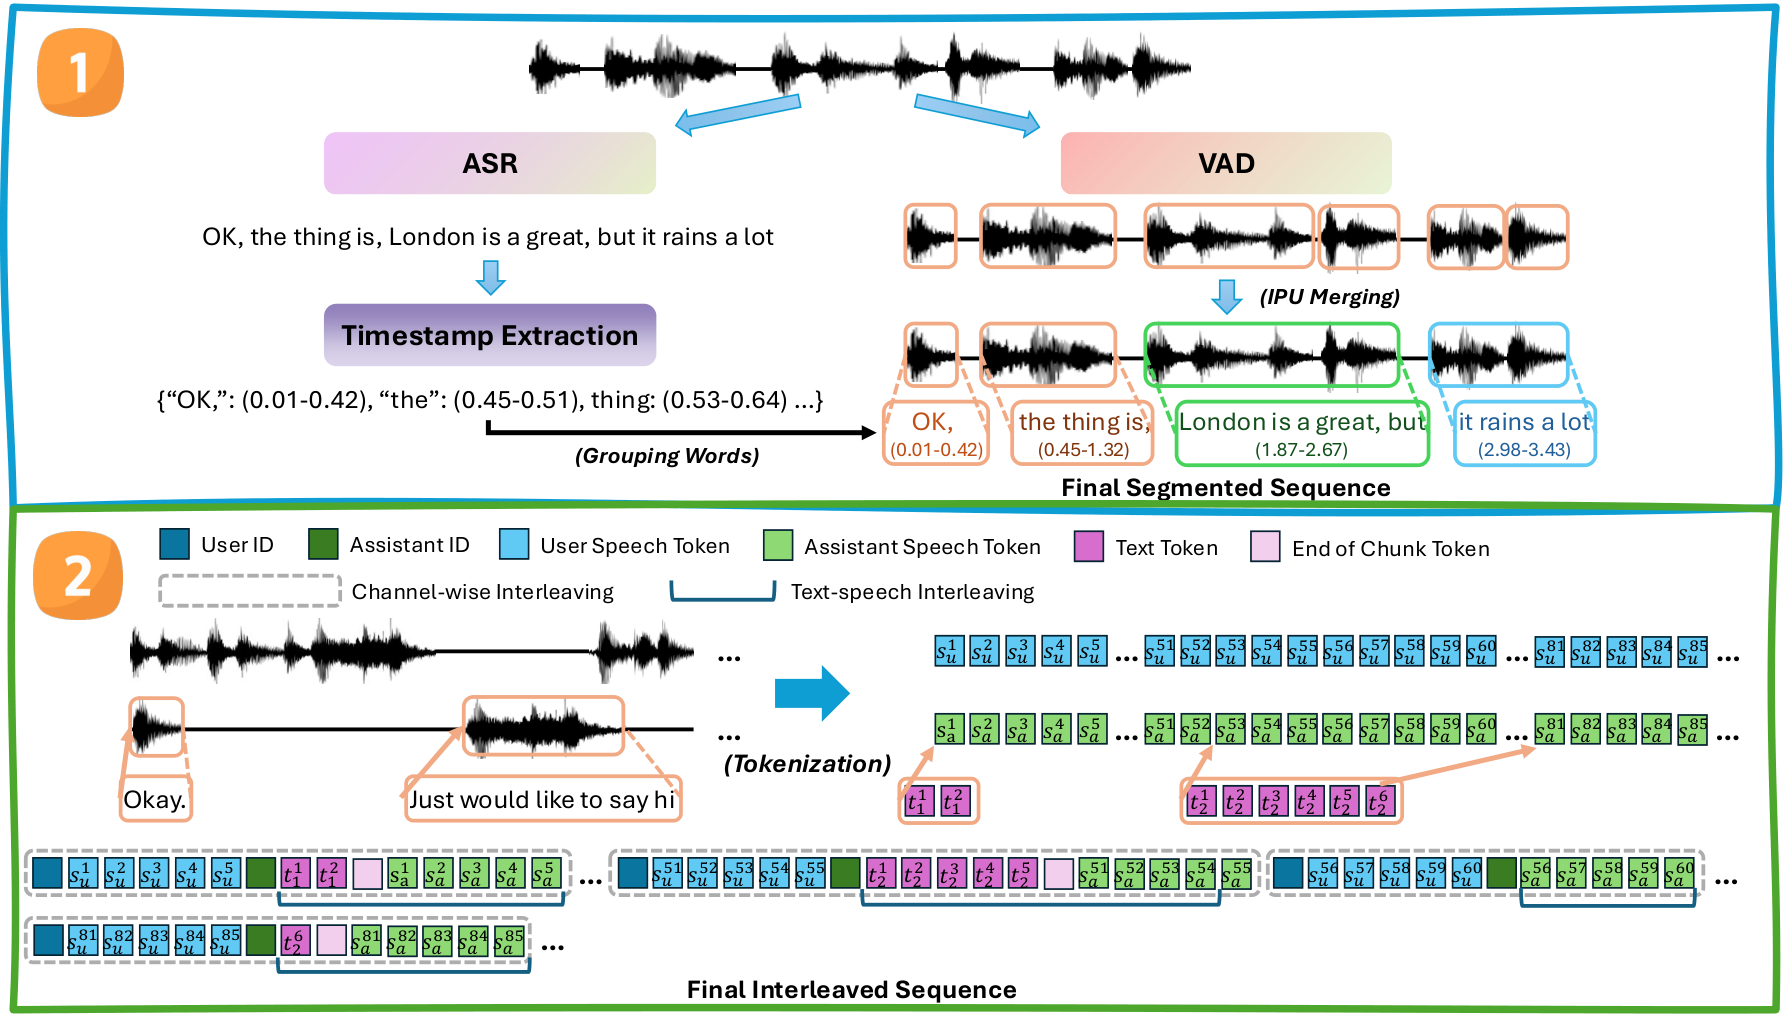
Figure 2 · Source
Ultravox 0.4.1 Llama-3.1-8B
Provides an earlier Ultravox speech-understanding checkpoint for text-based voice responses.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
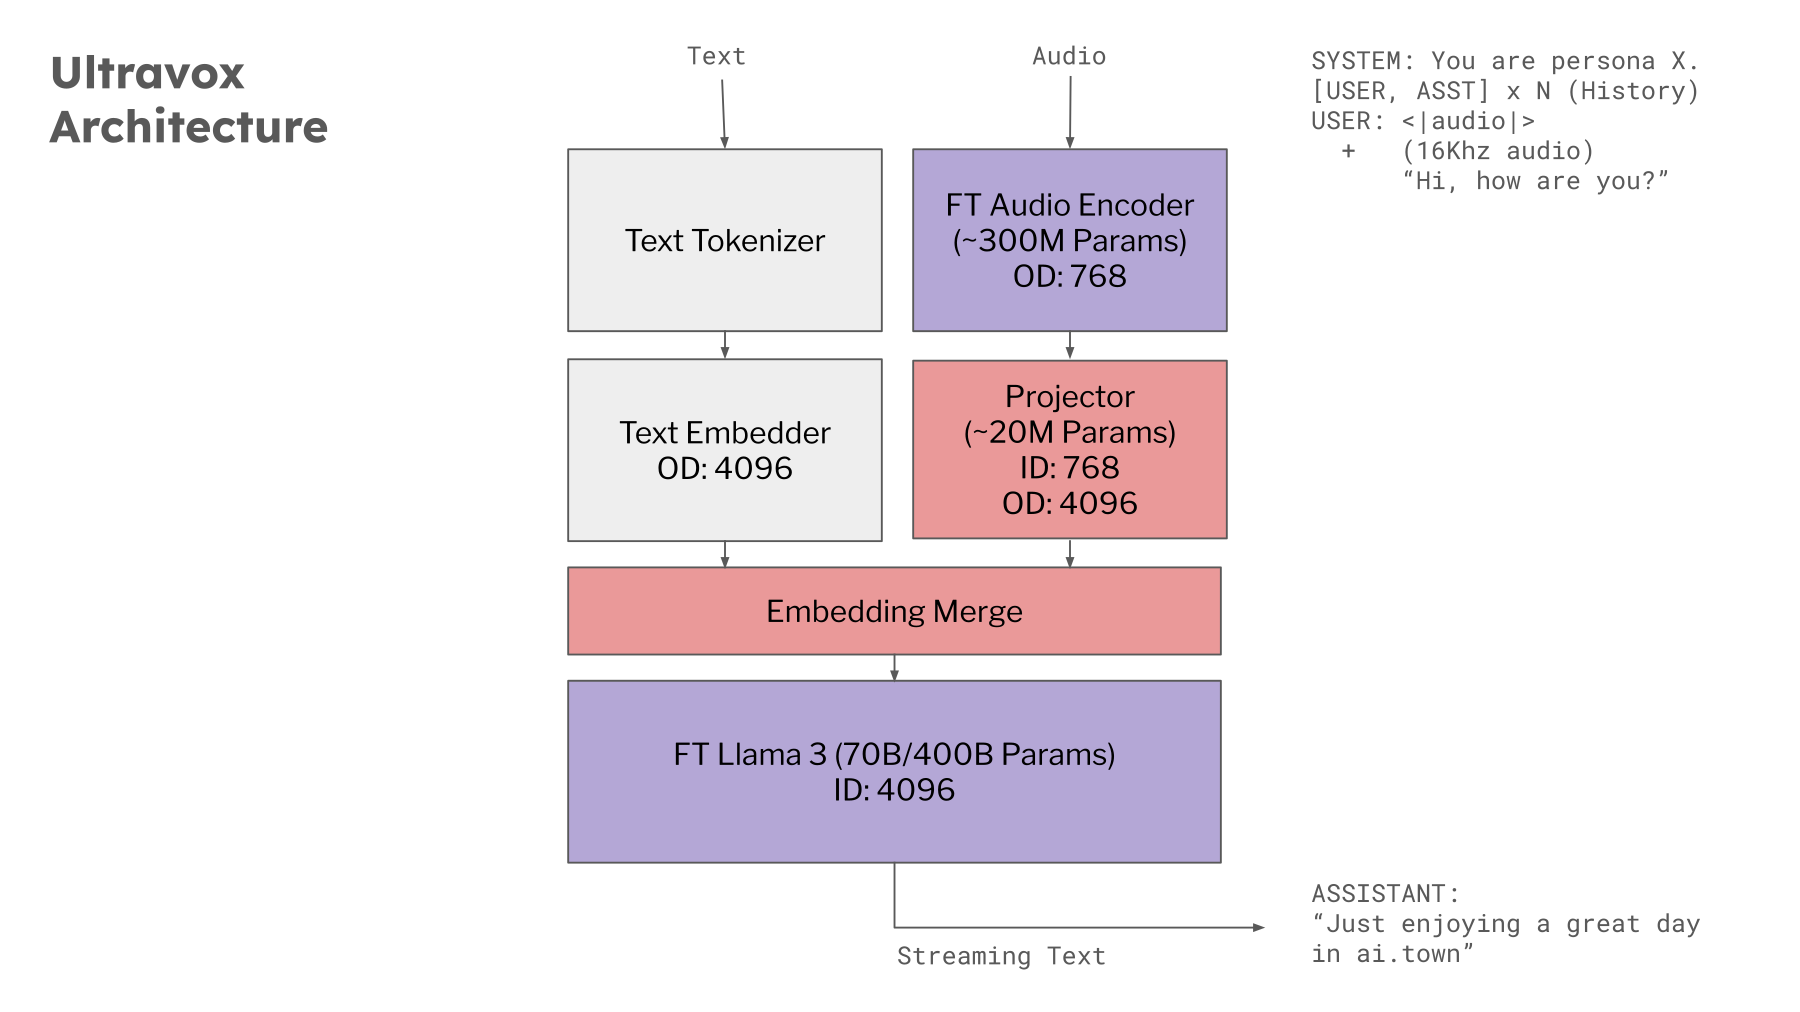
Family figure — Llama-based example · Source
Ultravox 0.5 Llama-3.1-8B
Handles spoken questions and instruction following with text output.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.5 Llama-3.2-1B
Provides speech-to-text-answer interaction with a small 1B language backbone.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.6 Gemma-3-27B
Answers voice requests using Gemma 3's language capabilities.
Custom / restricted: code MIT · weights MIT + Gemma terms — The included Gemma backbone retains its custom usage terms.
Family figure — Llama-based example · Source
Ultravox 0.6 Llama-3.1-8B
Responds to spoken instructions in text using the 8B Ultravox 0.6 release.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.6 Llama-3.3-70B
Turns spoken questions into text answers using a large Llama 3.3 backbone.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.6 Qwen3-32B
Adds spoken-instruction understanding and text responses to Qwen3-32B.
Open license: code MIT · weights MIT
Family figure — Llama-based example · Source
Ultravox 0.7 GLM-4.6
Answers spoken questions and follows voice instructions using a GLM-4.6 language backbone.
Open license: code MIT · weights MIT
Family figure — Llama-based example · Source
Uni-MoE 2.0 Omni
Understands audiovisual requests and supports text, image and speech generation.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Weights are Apache-2.0; no license for this implementation directory was located.
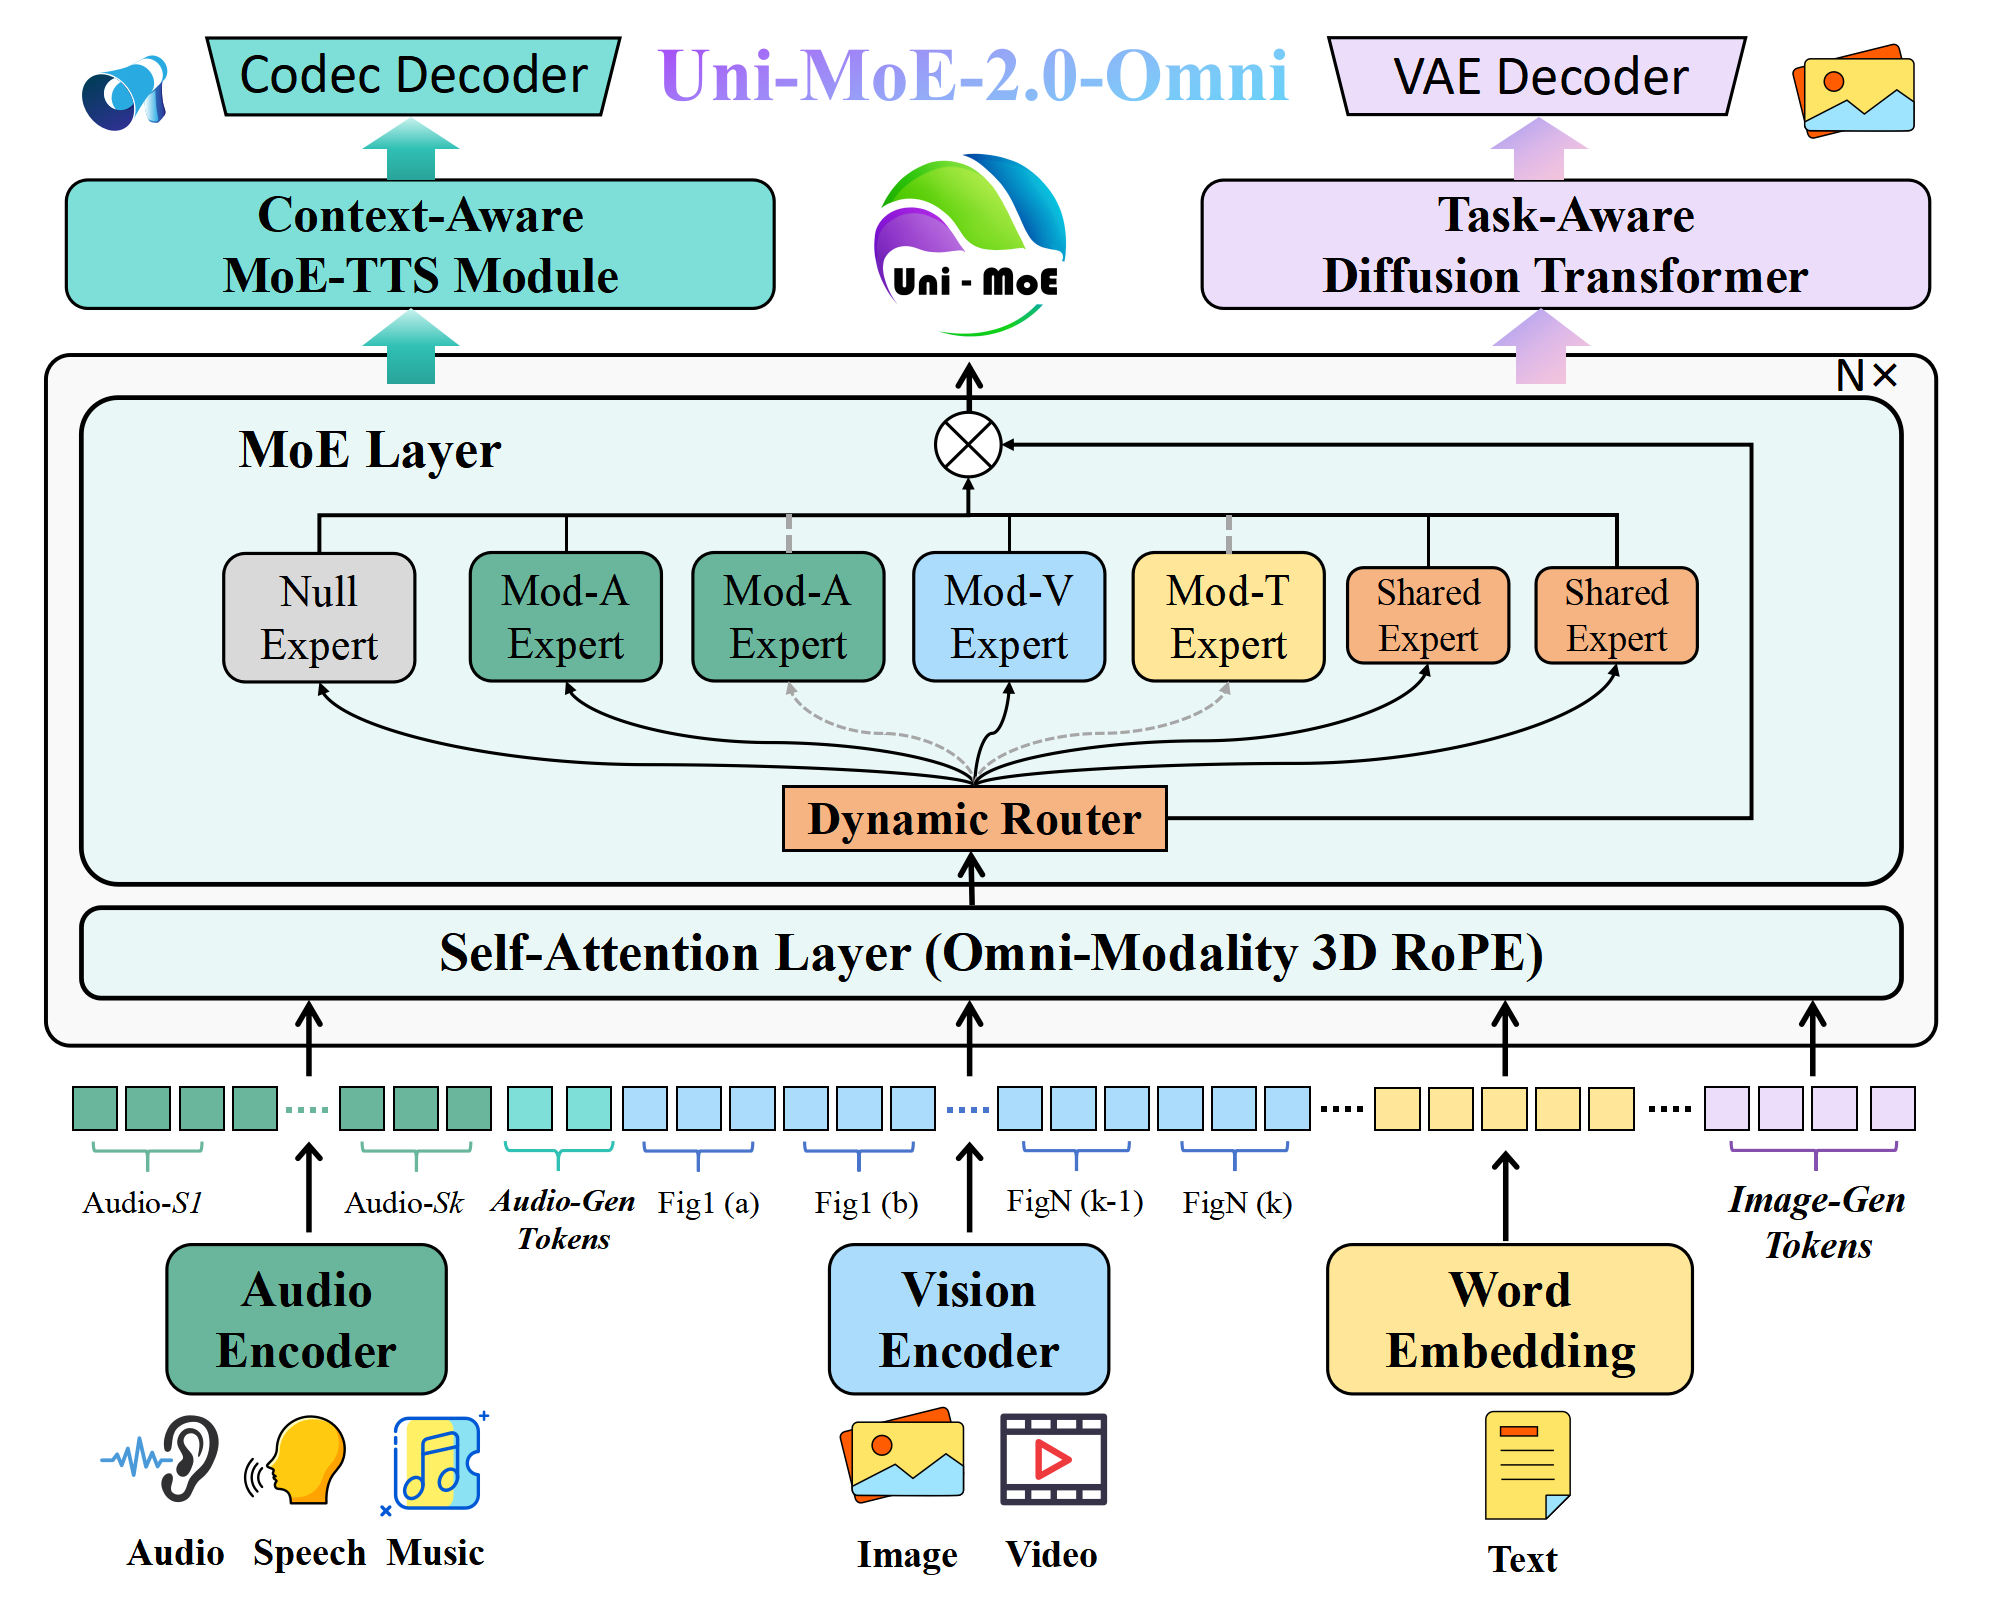
Figure 2 · Source
VibeVoice-ASR
Transcribes long recordings with speaker labels and timestamps in one pass.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
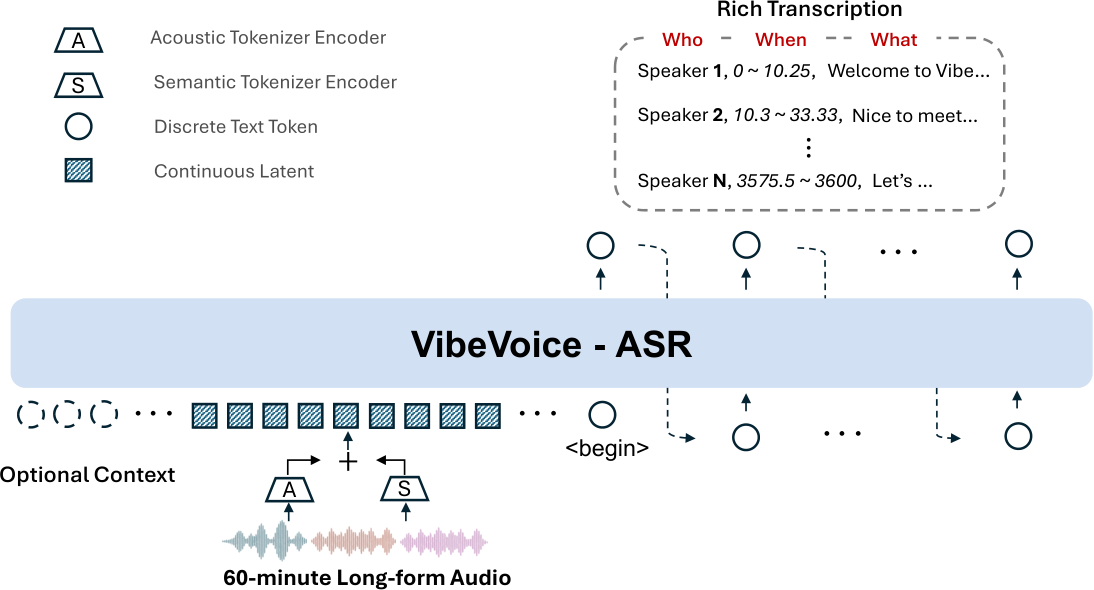
Figure 2 · Source
video-SALMONN 2+ (7B)
Captions videos and answers questions using both what is seen and heard.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
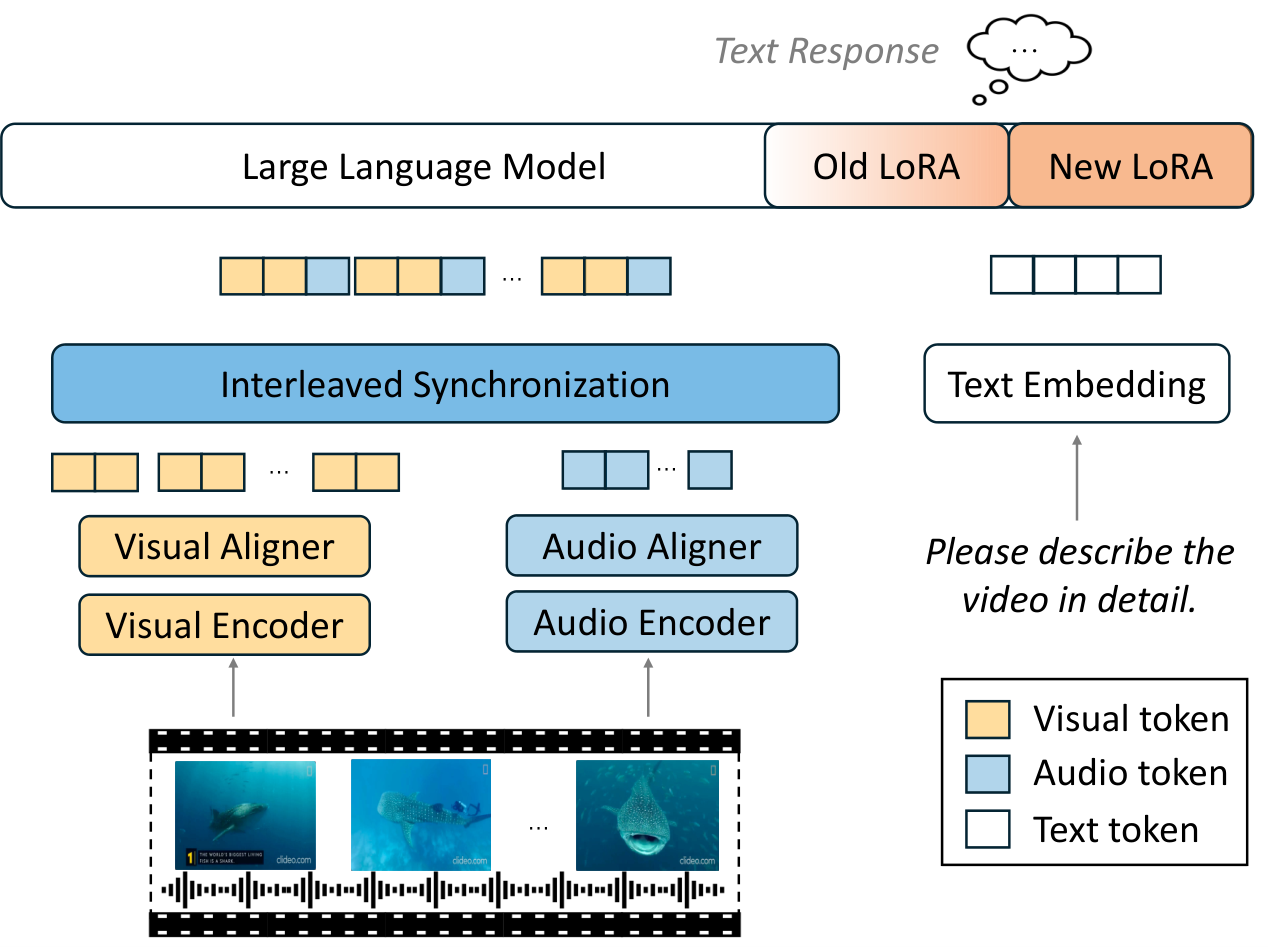
Family figure · Figure 1 · Source
VideoLLaMA 2.1 AV
Answers questions about videos using synchronized visual and audio information.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Research-only — The repository restricts use to noncommercial research despite the checkpoint badge.
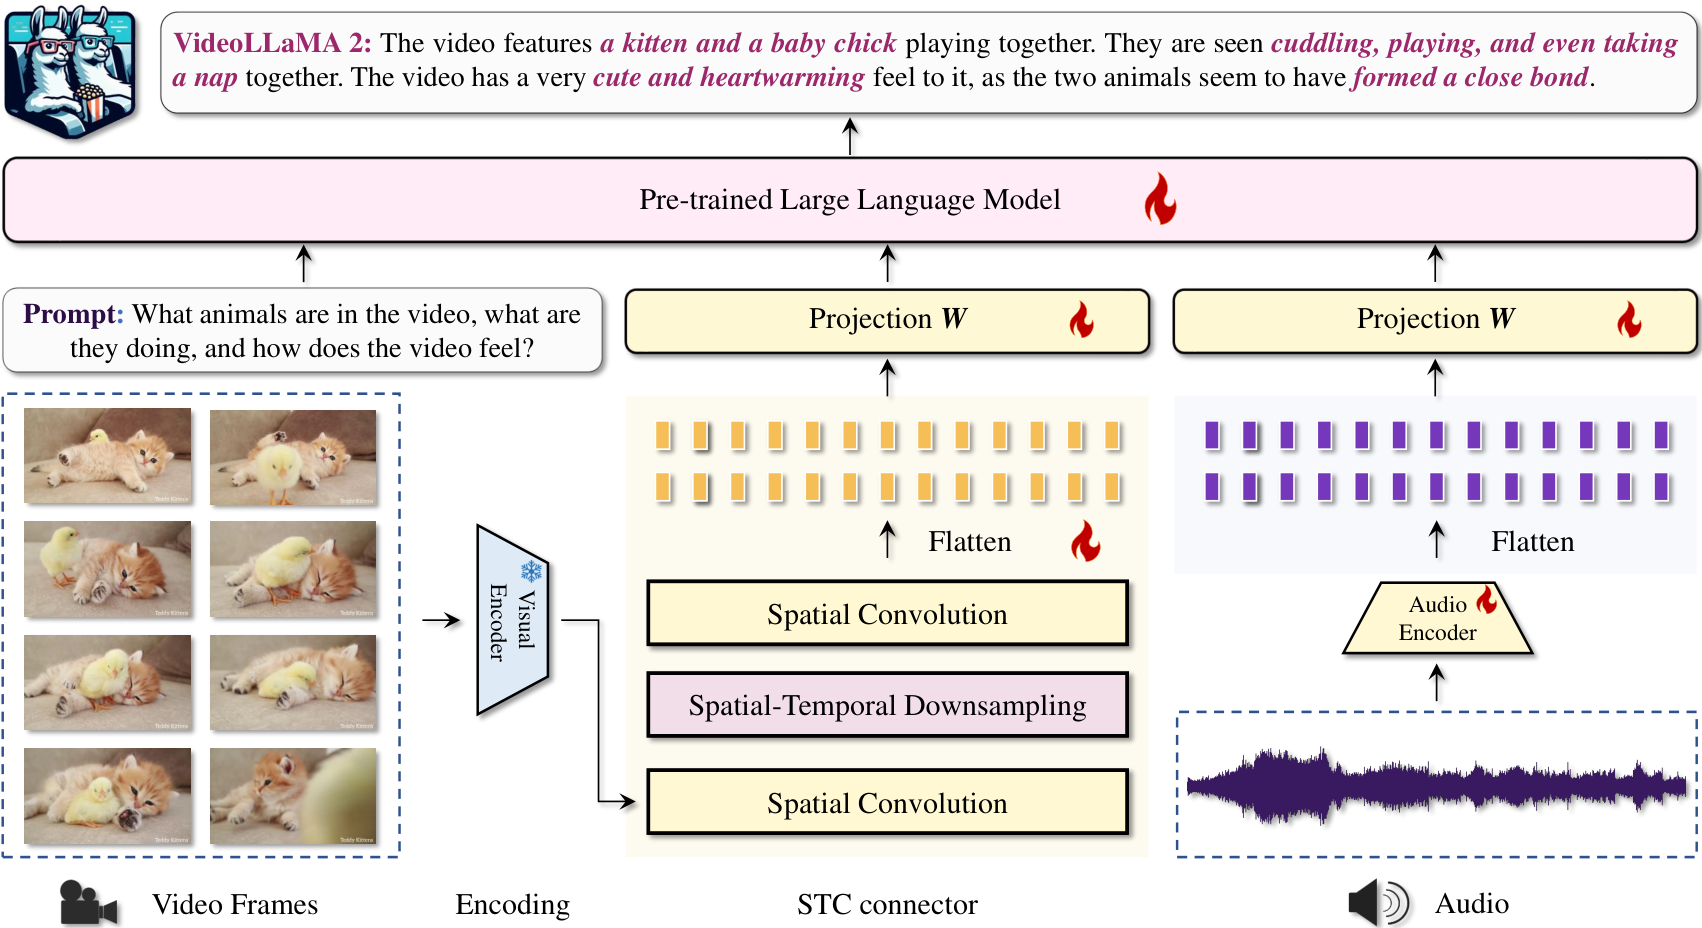
Figure 1 · Source
VITA 1.0
Understands images, video and speech in a multimodal assistant with interruptible interaction.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
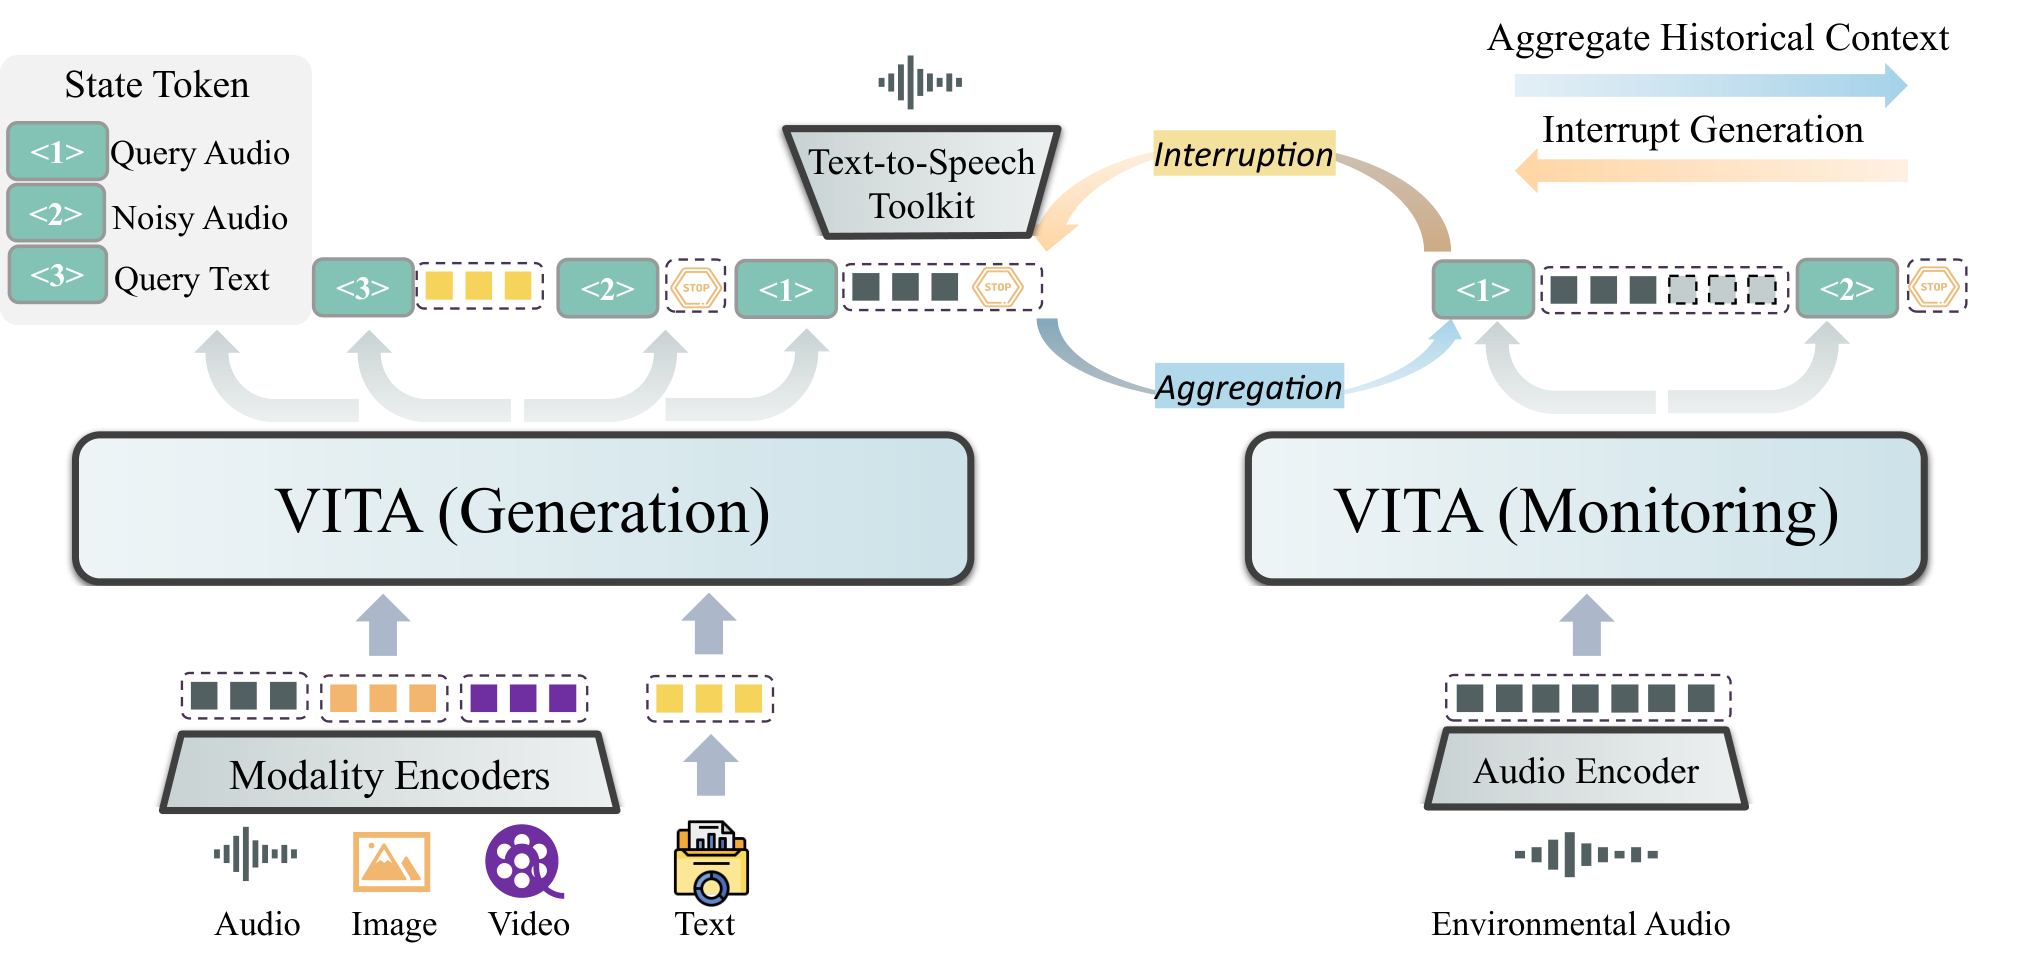
Figure 2 · Source
VITA 1.5
Provides visual and spoken interaction with streaming speech responses.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
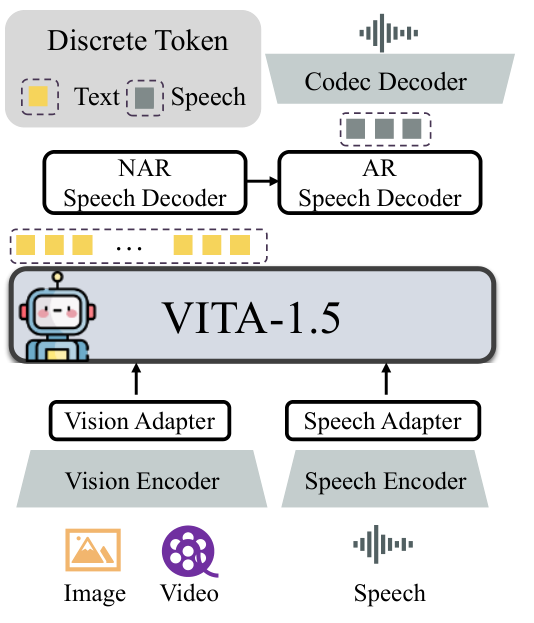
Figure 2 · Source
VITA-Audio
Streams spoken responses quickly by generating multiple audio tokens per language-model step.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
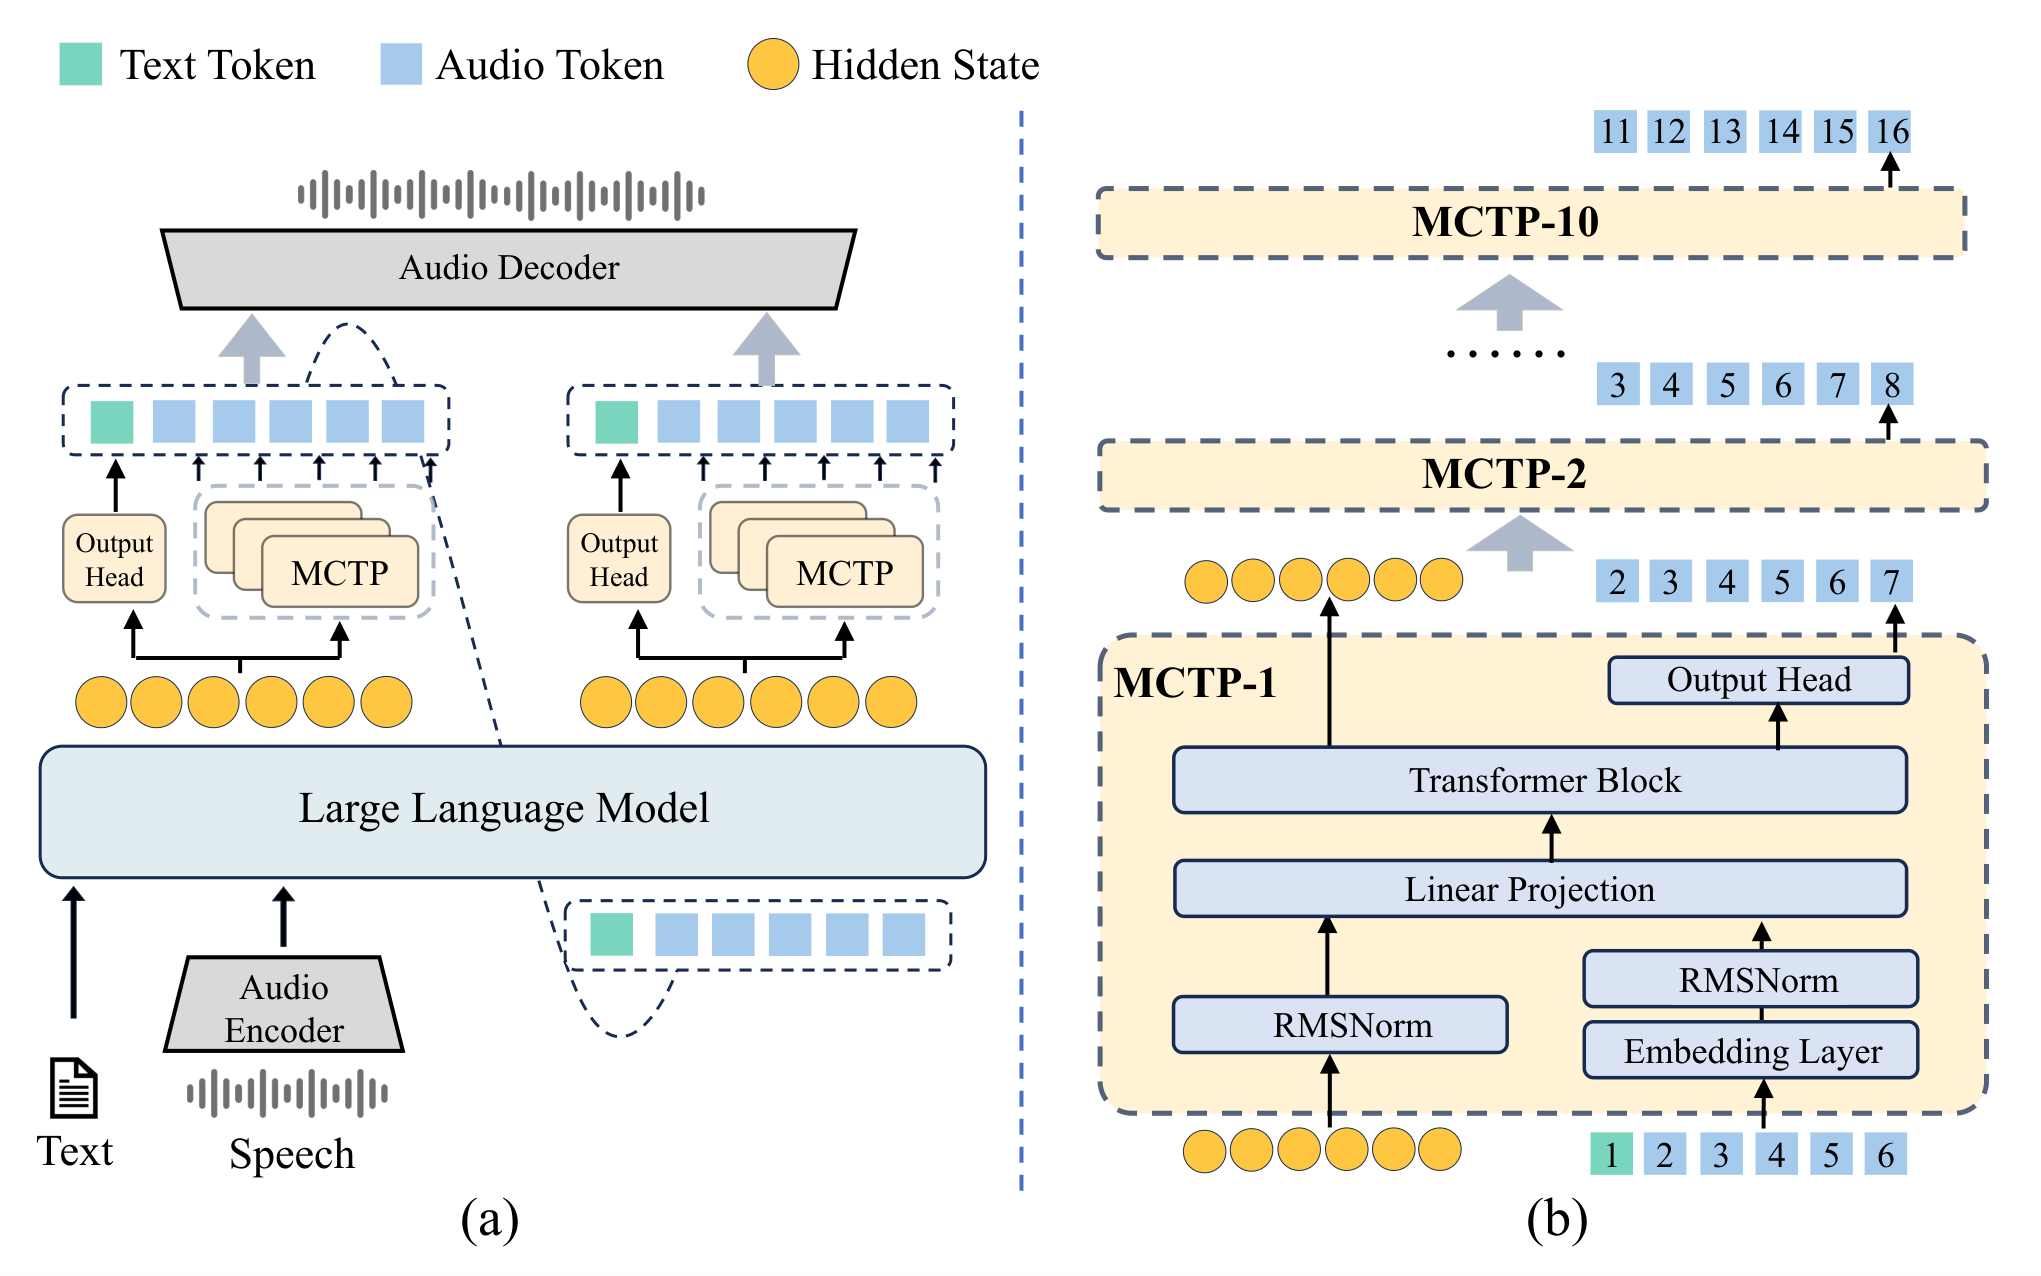
Figure 2 · Source
VITA-Audio Plus
Provides the later VITA-Audio release with accelerated interleaved speech and text generation.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Family figure — Figure 2 · Source
Voila Autonomous
Supports autonomous voice interaction with simultaneous listening and speaking.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
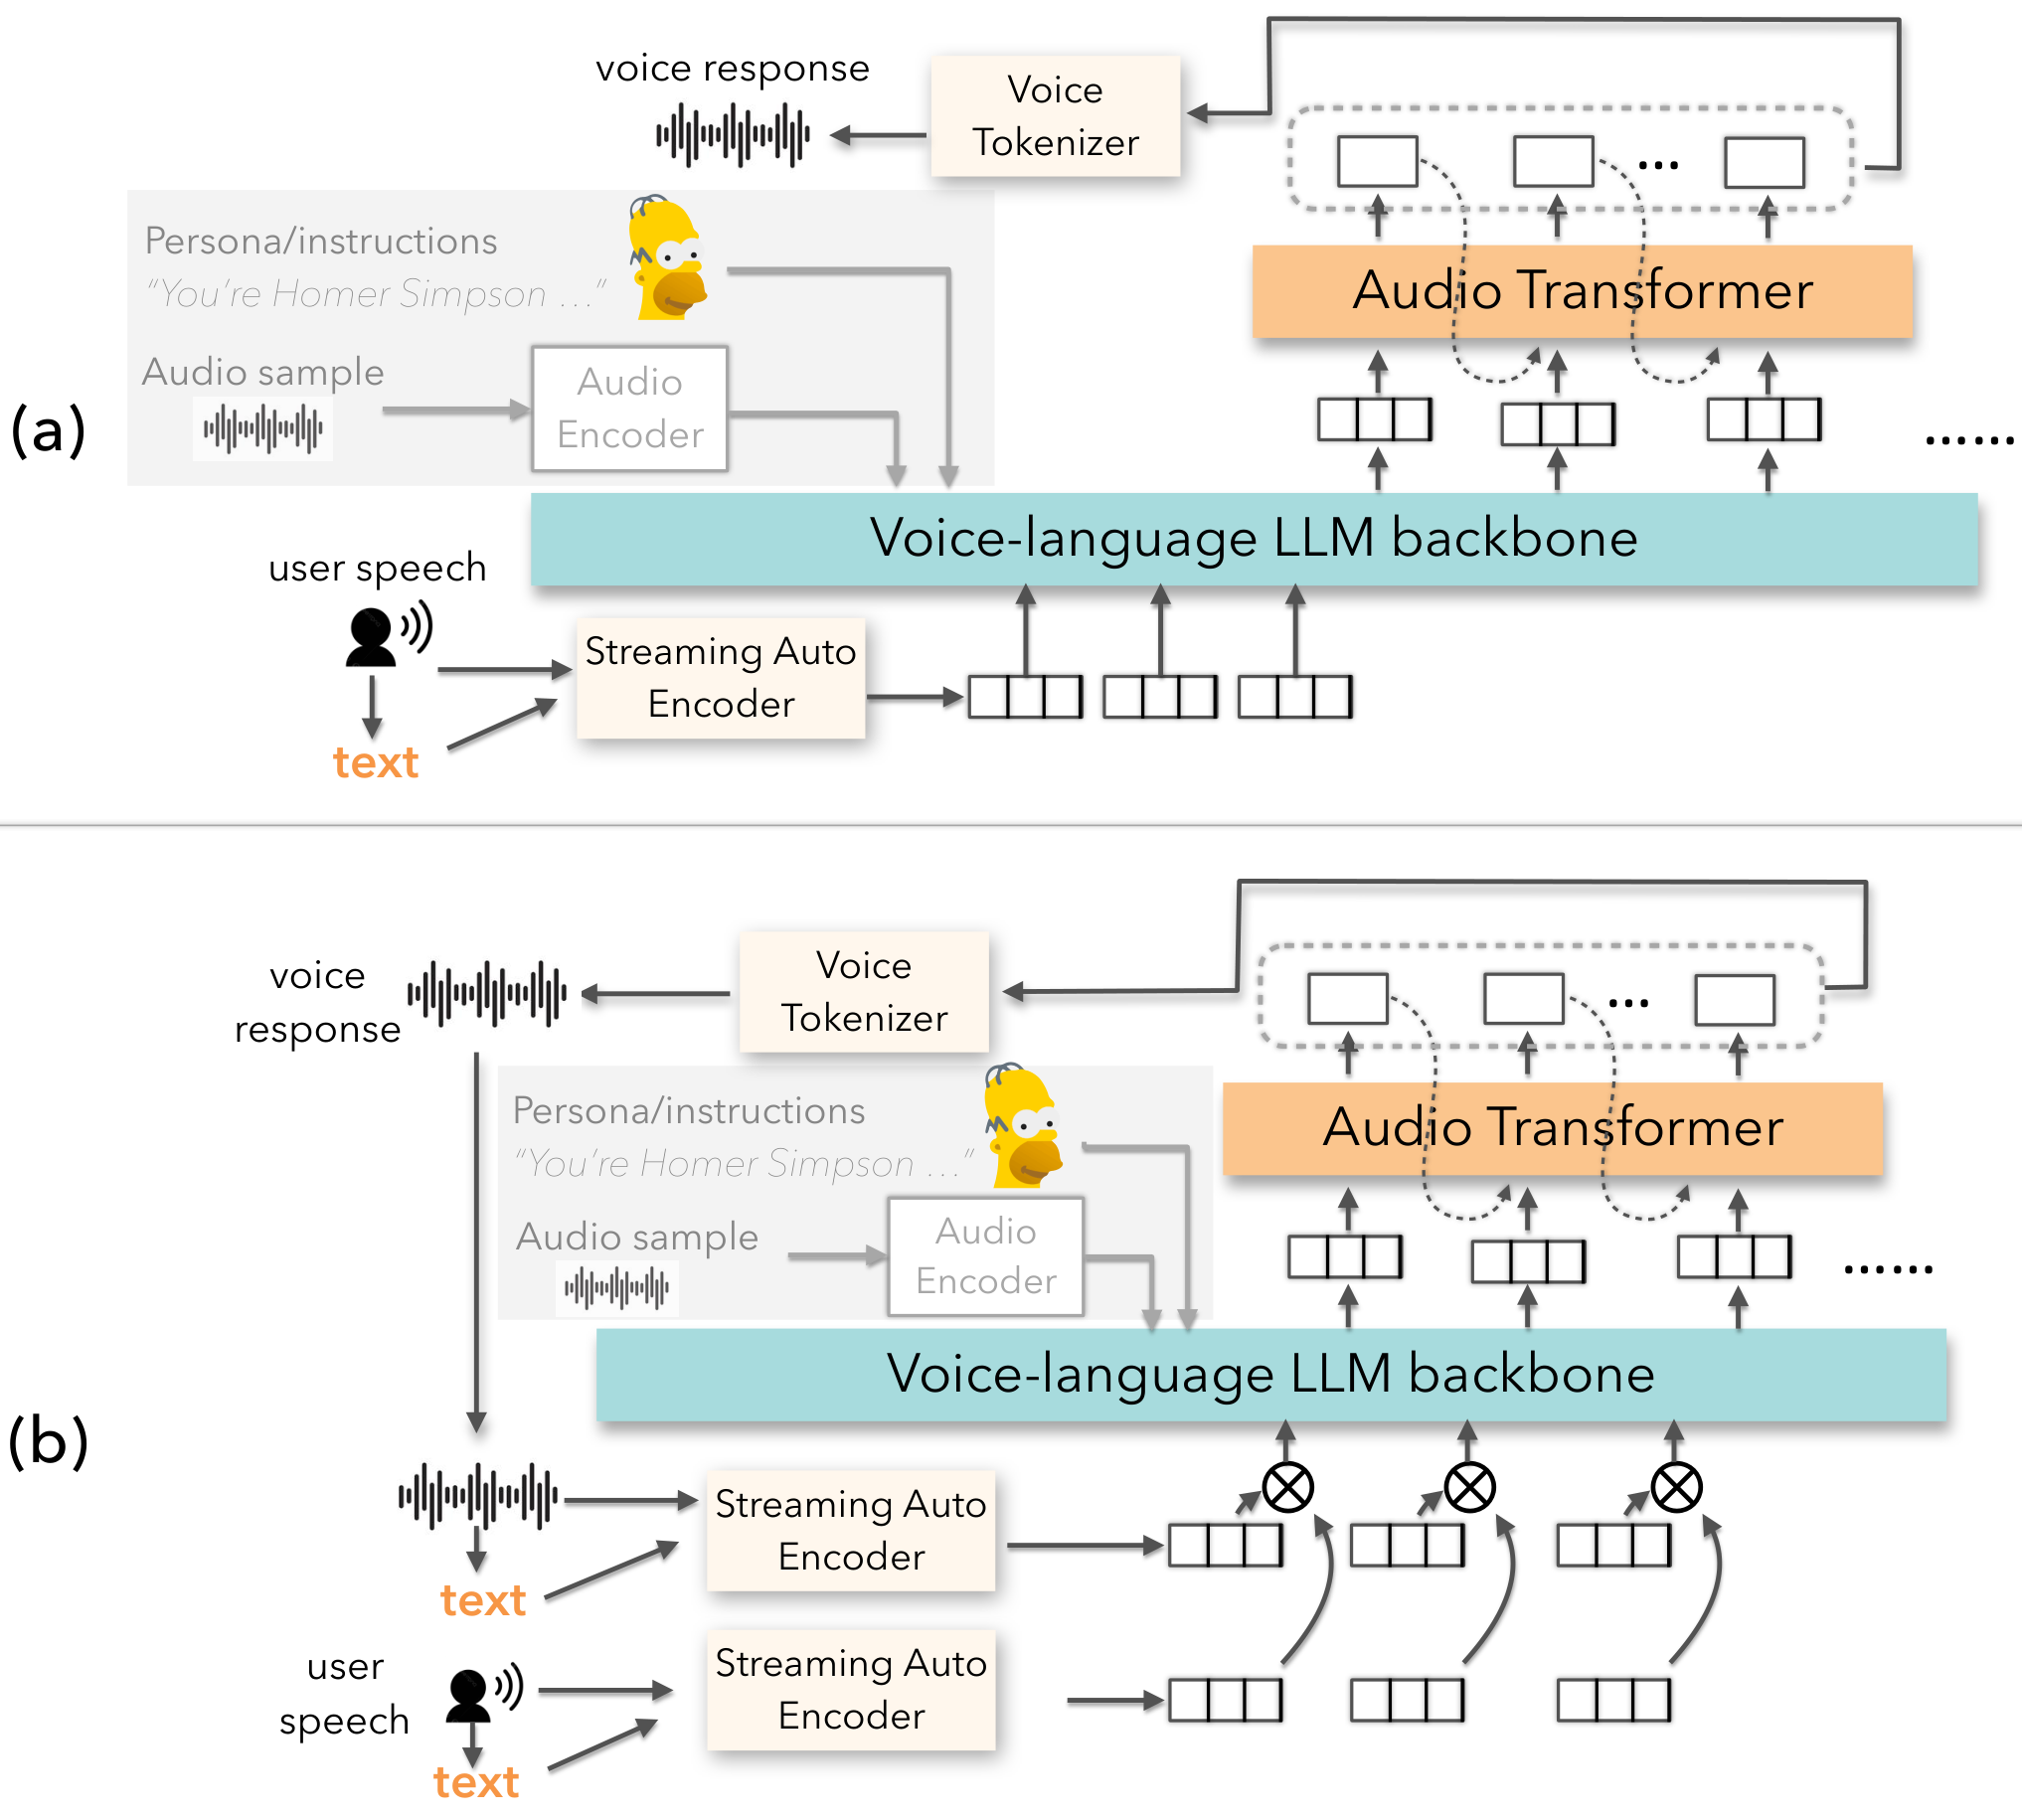
Family figure — Figure 2 · Source
Voila Chat
Holds voice conversations with speaker identity and speaking style controlled by prompts.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
VoxMind
Handles spoken requests that require reasoning, planning and external tool use.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Not stated — Public code and weights were located, but a complete release license was not stated.
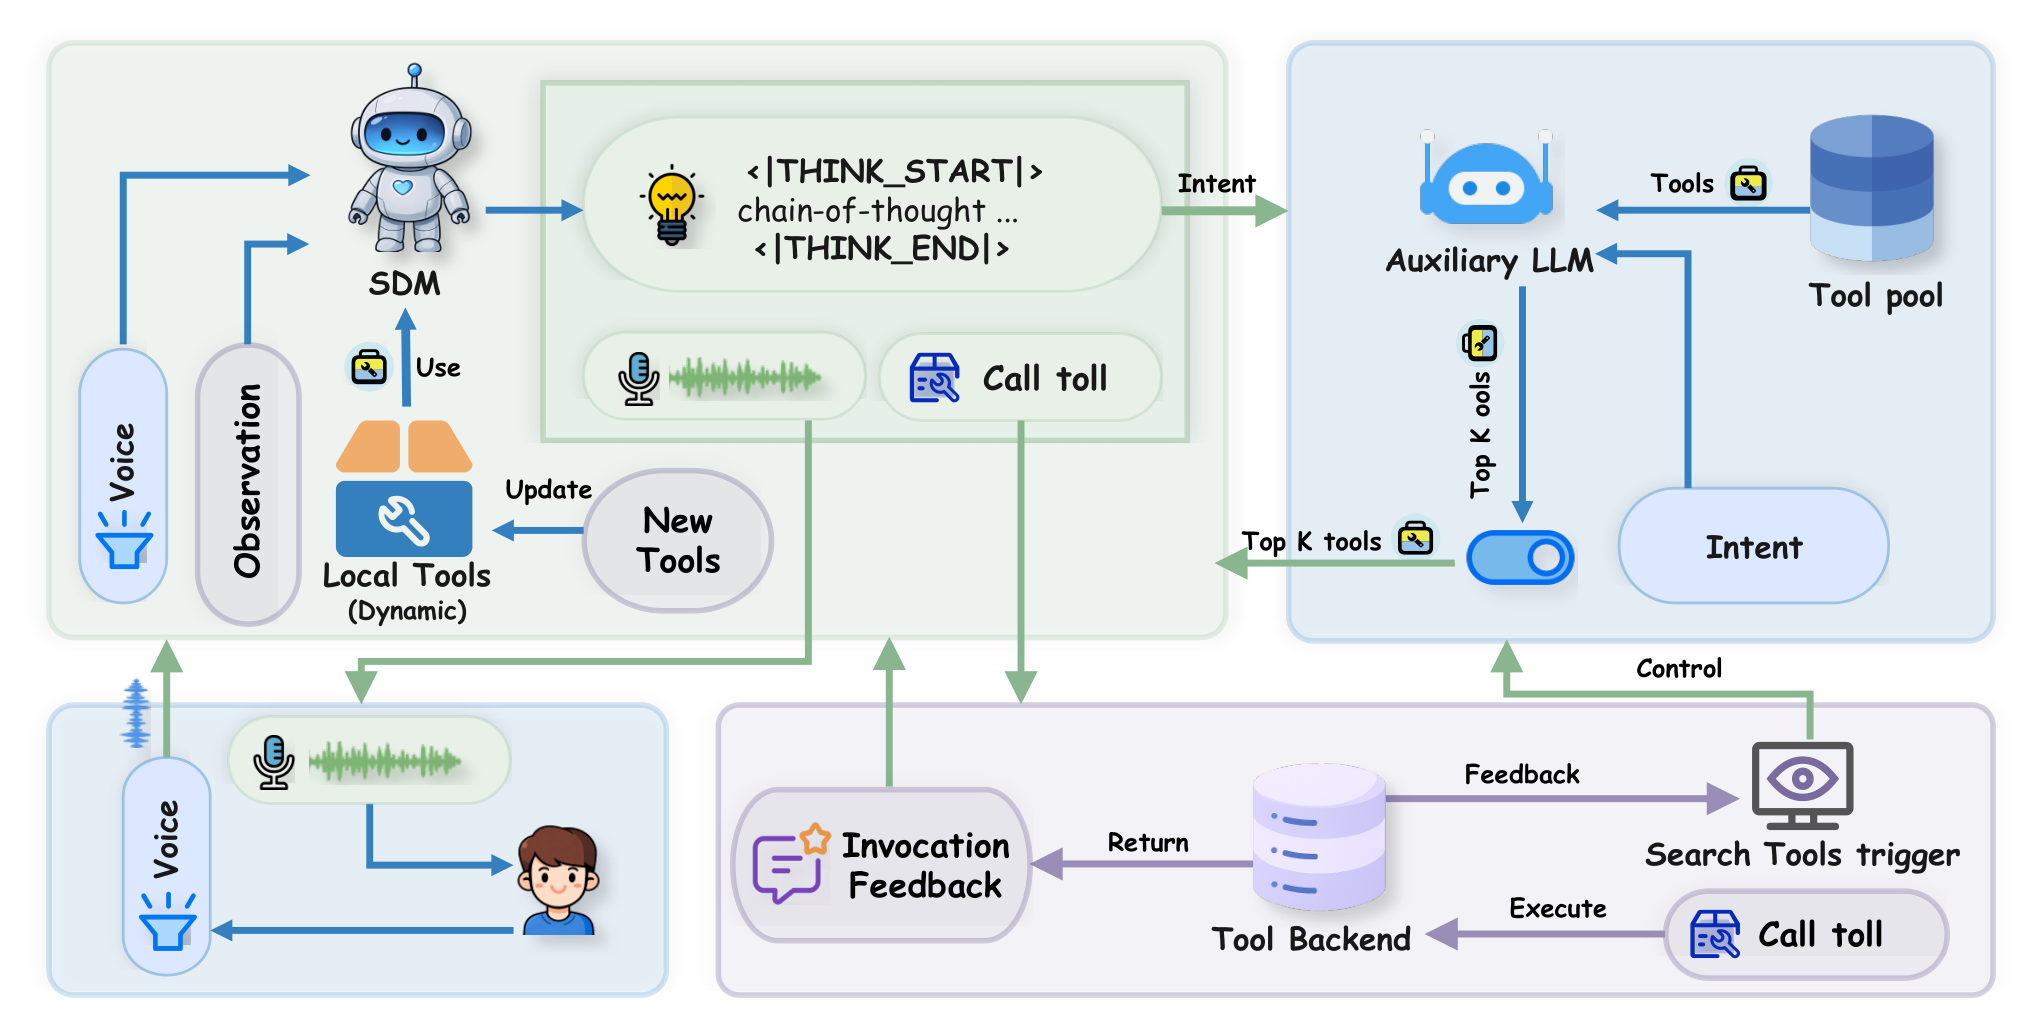
Figure 2 · Source
Voxtral Mini
Provides transcription and audio question answering in a smaller 3B configuration.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
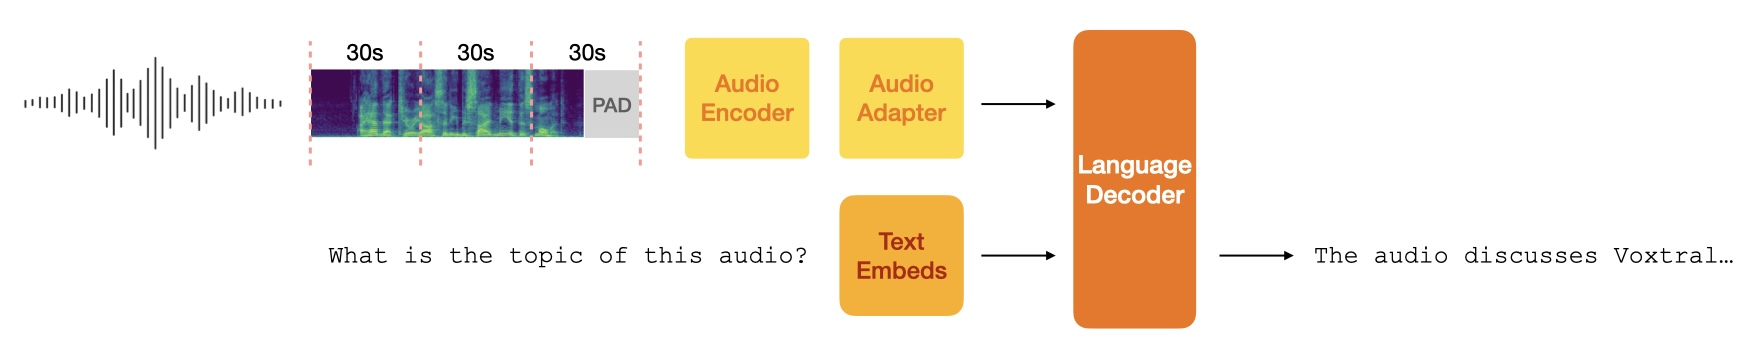
Family figure — Figure 1 · Source
Voxtral Realtime
Transcribes live audio incrementally for low-latency applications.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Voxtral Small
Transcribes and translates speech and answers questions about long audio recordings.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
Whisper-v3-large + Llama-3.1-8B
Uses Whisper to transcribe a spoken request and Llama 3.1 to answer it.
Code · Weights · ASR weights · Details
Custom / restricted: code Apache-2.0 · weights Llama community license · ASR Apache-2.0 — The text backbone uses the Llama community license.
Input/output diagram · Source
Whisper-v3-turbo + Llama-3.1-8B
Pairs faster Whisper transcription with Llama 3.1 text responses.
Code · Weights · ASR weights · Details
Custom / restricted: code Apache-2.0 · weights Llama community license · ASR MIT — The text backbone uses the Llama community license.
Input/output diagram · Source
Whisper-v3-turbo + Llama-3.2-3B
Combines Whisper Turbo with a smaller Llama 3.2 model for spoken question answering.
Code · Weights · ASR weights · Details
Custom / restricted: code Apache-2.0 · weights Llama community license · ASR MIT — The text backbone uses the Llama community license.
Input/output diagram · Source
Contributors

9 commits
Similar repos


Languages
Python
100.0%
Visual catalog of omni, speech and audio language models with public code and weights, short descriptions, architecture figures, license labels and VoiceBench coverage.
Python
14
9 commits
updated Sep 13, 2026
README
Awesome Omni Architectures
A visual catalog of omni, speech and audio language models with public code and weights. Every entry has a short description, a diagram, code and checkpoint links.
140 models + 4 cascaded systems · Reviewed 2026-09-13
Model list · All diagrams · VoiceBench coverage · Research · Timeline · Scope
Licenses: 68 open · 48 custom/restricted · 28 unclear. Downloadable weights do not always mean an unrestricted open-source license; each card shows the applicable terms.
| Collection | Entries |
|---|---|
| Omni and audio-visual models | 44 |
| Speech dialogue models | 42 |
| Audio understanding models | 45 |
| Speech recognition language models | 9 |
| VoiceBench cascaded systems | 4 |
Models
T: text · I: image · V: video · A: audio · S: speech · M: music · X: other. Scope and labels.
Alphabetical model list · 144 entries
| Model | Group | Input → output | Release |
|---|---|---|---|
| AnyGPT | Omni | T, I, S, M → T, I, S, M | License unclear |
| Audio Flamingo | Audio | T, A → T | Custom / restricted |
| Audio Flamingo 2 | Audio | T, A → T | Custom / restricted |
| Audio Flamingo 3 Chat | Speech | T, A → T, S | Custom / restricted |
| Audio Flamingo Next | Audio | T, A → T | Custom / restricted |
| Audio-Interaction | Audio | T, A → T | License unclear |
| Audio-Reasoner | Audio | T, A → T | Open license |
| Audio-Visual Flamingo | Omni | T, I, V, A → T | Custom / restricted |
| AzeroS | Audio | T, S → T | Open license |
| Baichuan-Audio | Speech | T, A → T, S | Open license |
| Baichuan-Omni 1.5 | Omni | T, I, V, A → T, S | Custom / restricted |
| BLSP-Emo | Audio | T, S → T | Custom / restricted |
| BR-Voice-Reasoner | Omni | T, I, V, A → T | Open license |
| Canary-Qwen | LLM-ASR | T, S → T | Open license |
| Covo-Audio Chat | Speech | T, S → T, S | Custom / restricted |
| DeSTA2 | Audio | T, A → T | License unclear |
| DeSTA2.5-Audio | Audio | T, A → T | License unclear |
| DialectS2S | Speech | T, S → T, S | Open license |
| DIFFA | Audio | T, A → T | License unclear |
| DIFFA-2 | Audio | T, A → T | License unclear |
| DiVA | Audio | T, S → T | Custom / restricted |
| DuplexCascade | Speech | T, S → T, S | Open license |
| DuplexMamba | Audio | T, S → T | Open license |
| EMOVA (Qwen2.5-7B) | Omni | T, I, S → T, S | Open license |
| Freeze-Omni | Speech | T, S → T, S | Custom / restricted |
| Fun-Audio-Chat | Speech | T, S → T, S | Open license |
| Gemma 3n E4B | Omni | T, I, V, A → T | Custom / restricted |
| Gemma 4 E4B | Omni | T, I, V, A → T | Open license |
| GLM-4-Voice | Speech | T, S → T, S | Custom / restricted |
| GLM-ASR Nano | LLM-ASR | S → T | Open license |
| Granite Speech 3.3 | LLM-ASR | T, S → T | Open license |
| Granite Speech 4.0 | LLM-ASR | T, S → T | Open license |
| Granite Speech 4.1 | LLM-ASR | T, S → T | Open license |
| Hibiki | Speech | T, S → T, S | Open license |
| HumanOmni | Omni | T, V, A → T | License unclear |
| HumanOmniV2 | Omni | T, V, A → T | Open license |
| Ichigo | Audio | T, S → T | License unclear |
| Kimi-Audio | Speech | T, A → T, S | Open license |
| LFG-1 | Omni | T, I, S → T | Open license |
| LFG-2 | Audio | T, S → T | License unclear |
| LFG-3 | Audio | T, S → T | License unclear |
| LFM2-Audio-1.5B | Speech | T, S → T, S | Custom / restricted |
| LFM2.5-Audio-1.5B | Speech | T, S → T, S | Custom / restricted |
| LFM2.5-Audio-1.5B-JP | Speech | T, S → T, S | Custom / restricted |
| LLaMA-Omni | Speech | T, S → T, S | Custom / restricted |
| LLaMA-Omni 2 | Speech | T, S → T, S | Custom / restricted |
| LLaSM | Audio | T, S → T | Custom / restricted |
| LongCat-Flash-Omni | Omni | T, I, V, A → T, S | Open license |
| LongCat-Next | Omni | T, I, A → T, I, A | Open license |
| Lychee-FD | Speech | T, S → T, S | Open license |
| Lyra-Base | Omni | T, I, V, A → T, S | Custom / restricted |
| Lyra-Mini | Omni | T, I, V, A → T, S | Custom / restricted |
| Mair-hub-0.5B-Omni | Speech | T, S → T, S | License unclear |
| Megrez-Omni | Omni | T, I, A → T | Open license |
| Mellow | Audio | T, A → T | Open license |
| MERaLiON 2 | Audio | T, A → T | Custom / restricted |
| MERaLiON 3 | Audio | T, S → T | Custom / restricted |
| MERaLiON 3 ASR | LLM-ASR | S → T | Custom / restricted |
| MERaLiON-AudioLLM | Audio | T, A → T | Custom / restricted |
| MiDashengLM | Audio | T, A → T | License unclear |
| MiMo-Audio | Speech | T, A → T, S | Open license |
| MiMo-V2.5 | Omni | T, I, V, A → T | Open license |
| Ming-Flash-Omni | Omni | T, I, V, A → T, I, A | Open license |
| Ming-Flash-Omni 2.0 | Omni | T, I, V, A → T, I, A | Open license |
| Ming-Lite-Omni | Omni | T, I, V, A → T, I, S | Open license |
| Mini-Omni | Speech | T, S → T, S | Open license |
| Mini-Omni2 | Omni | T, I, S → T, S | Open license |
| MiniCPM-o 2.6 | Omni | T, I, V, A → T, S | Open license |
| MiniCPM-o 4.5 | Omni | T, I, V, A → T, S | Open license |
| MiniMind-O | Omni | T, I, S → T, S | Open license |
| MIO | Omni | T, I, V, A → T, I, S | License unclear |
| Moshi | Speech | T, S → T, S | Open license |
| MOSS-Audio Instruct | Audio | T, A → T | License unclear |
| MOSS-Audio Thinking | Audio | T, A → T | License unclear |
| MOSS-Speech | Speech | S → S | License unclear |
| Music Flamingo | Audio | T, M → T | Custom / restricted |
| Nemotron 3 Nano Omni | Omni | T, I, V, A → T | Custom / restricted |
| Nemotron-Labs-Audex 2B | Speech | T, A → T, A | License unclear |
| Nemotron-Labs-Audex 30B-A3B | Speech | T, A → T, A | License unclear |
| NemotronLabs VoiceChat 11B | Speech | T, S → T, S | Open license |
| NExT-GPT | Omni | T, I, V, A → T, I, V, A | Custom / restricted |
| Nexus-O | Omni | T, I, V, A → T, S | Custom / restricted |
| Ola | Omni | T, I, V, A → T | Open license |
| Omni-AutoThink | Omni | T, I, V, A → T | Open license |
| Omni-R1 (audio reasoning) | Audio | T, A → T | License unclear |
| Omni-R1 (two-system collaboration) | Omni | T, I, V, A → T | License unclear |
| OmniVinci | Omni | T, I, V, A → T | Custom / restricted |
| OneLLM | Omni | T, I, V, A → T | Custom / restricted |
| OpenOmni | Omni | T, I, V, A → T, S | License unclear |
| OpenS2S | Speech | T, S → T, S | Open license |
| OpenS2S 1.5 | Speech | T, S → T, S | Open license |
| OSUM | Audio | T, S → T | Open license |
| OSUM-EChat | Speech | T, S → T, S | Open license |
| ParaBridge | Audio | T, A → T | Open license |
| Parakeet-TDT-v2 + Qwen3-8B | Cascade | S → T | Open license |
| PersonaPlex | Speech | T, S → T, S | Custom / restricted |
| Phi-4-multimodal | Omni | T, I, A → T | Open license |
| Qwen-Audio | Audio | T, A → T | Custom / restricted |
| Qwen2-Audio | Audio | T, A → T | Open license |
| Qwen2.5-Omni | Omni | T, I, V, A → T, S | Open license |
| Qwen3-ASR | LLM-ASR | T, S → T | Open license |
| Qwen3-Omni Instruct | Omni | T, I, V, A → T, S | Open license |
| Qwen3-Omni Thinking | Omni | T, I, V, A → T | Open license |
| R1-Omni | Omni | T, V, A → T | License unclear |
| SALMONN | Audio | T, A → T | Custom / restricted |
| SALMONN-2 | Audio | T, A → T | Open license |
| SLAM-Omni | Speech | T, S → T, S | Open license |
| SoulX-Duplug | Audio | T, S → T | Open license |
| SpeechGPT | Speech | T, S → T, S | License unclear |
| SpeechGPT 2.0 Preview | Speech | T, S → T, S | License unclear |
| Step-Audio | Speech | T, A → T, S | Open license |
| Step-Audio 2 Mini | Speech | T, A → T, S | Open license |
| Step-Audio 2 Mini Think | Audio | T, A → T | Open license |
| Step-Audio-AQAA | Speech | T, A → T, S | Open license |
| Step-Audio-R1 | Audio | T, A → T | Open license |
| Step-Audio-R1.1 | Speech | T, A → T, S | Open license |
| Stream-Omni | Omni | T, I, S → T, S | Custom / restricted |
| Sympatheia | Speech | T, S → T, S | License unclear |
| TurnGuide | Speech | T, S → T, S | License unclear |
| Ultravox 0.4.1 Llama-3.1-8B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.5 Llama-3.1-8B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.5 Llama-3.2-1B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Gemma-3-27B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Llama-3.1-8B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Llama-3.3-70B | Audio | T, S → T | Custom / restricted |
| Ultravox 0.6 Qwen3-32B | Audio | T, S → T | Open license |
| Ultravox 0.7 GLM-4.6 | Audio | T, S → T | Open license |
| Uni-MoE 2.0 Omni | Omni | T, I, V, A → T, I, A | License unclear |
| VibeVoice-ASR | LLM-ASR | T, S → T | Open license |
| video-SALMONN 2+ (7B) | Omni | T, V, A → T | Open license |
| VideoLLaMA 2.1 AV | Omni | T, I, V, A → T | Custom / restricted |
| VITA 1.0 | Omni | T, I, V, A → T | Custom / restricted |
| VITA 1.5 | Omni | T, I, V, A → T, S | Custom / restricted |
| VITA-Audio | Speech | T, S → T, S | Custom / restricted |
| VITA-Audio Plus | Speech | T, S → T, S | Custom / restricted |
| Voila Autonomous | Speech | T, S → T, S | Open license |
| Voila Chat | Speech | T, S → T, S | Open license |
| VoxMind | Speech | T, S → T, S | License unclear |
| Voxtral Mini | Audio | T, A → T | Open license |
| Voxtral Realtime | LLM-ASR | S → T | Open license |
| Voxtral Small | Audio | T, A → T | Open license |
| Whisper-v3-large + Llama-3.1-8B | Cascade | S → T | Custom / restricted |
| Whisper-v3-turbo + Llama-3.1-8B | Cascade | S → T | Custom / restricted |
| Whisper-v3-turbo + Llama-3.2-3B | Cascade | S → T | Custom / restricted |
Model figures
Figures are credited to their sources. Editorial input/output diagrams are labeled. Credits.
AnyGPT
Understands and generates text, images, speech and music using a shared token vocabulary.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 + Llama 2 terms — Base-model community terms also apply; repository-wide code licensing is not stated.
Figure 1 · Source
Audio Flamingo
Answers questions about sounds and music and supports audio-grounded dialogue and examples.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights OPT-IML noncommercial license — Noncommercial terms apply to model weights and relevant bundled components.
Figure 2 · Source
Audio Flamingo 2
Reasons about environmental sounds and music, including long recordings.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
Figure 2 · Source
Audio Flamingo 3 Chat
Discusses speech, sounds and music across multiple recordings and can reply with streaming speech.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
Figure 2 · Source
Audio Flamingo Next
Analyzes long audio recordings and reasons about speech, sounds and music.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
Figure 3 · Source
Audio-Interaction
Monitors an ongoing audio stream and decides when a text response or proactive intervention is useful.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Figure 3 · Source
Audio-Reasoner
Reasons about speech, music and environmental sounds to answer complex audio questions.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 3 · Source
Audio-Visual Flamingo
Explains long videos by reasoning jointly about visual events and their soundtracks.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
Figure 2 · Source
AzeroS
Follows spoken instructions using speech adaptation learned without curated instruction-answer pairs.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
Baichuan-Audio
Follows spoken instructions and generates text and expressive speech responses.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
Baichuan-Omni 1.5
Understands images, video and sound and answers through text or speech.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Baichuan model terms — The model card adds commercial-use conditions beyond its Apache metadata.
Figure 2 · Source
BLSP-Emo
Understands vocal emotion and writes empathetic responses to spoken requests.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Apache-2.0 + Qwen terms — The Qwen-7B-Chat backbone retains its custom license.
Figure 2 · Source
BR-Voice-Reasoner
Answers spoken knowledge and reasoning questions using a speech-adapted Qwen3-Omni Thinker.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Canary-Qwen
Transcribes English speech and offers a separate text-language mode for follow-up processing.
Open license: code Apache-2.0 · weights CC-BY-4.0
Input/output diagram · Source
Covo-Audio Chat
Understands spoken requests and generates context-aware, expressive voice responses.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Figure 2, PDF p. 4 · Source
DeSTA2
Describes and answers questions about audio using a language model aligned with speech representations.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Llama community / component terms — Base-model and dataset terms apply; no unrestricted standalone weight license is stated.
Figure 1 · Source
DeSTA2.5-Audio
Performs general audio understanding and follows spoken instructions without an external transcript pipeline.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Llama community / component terms — Base-model and dataset terms apply; no unrestricted standalone weight license is stated.
Figure 2 · Source
DialectS2S
Understands and speaks low-resource Chinese dialects in end-to-end voice conversations.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights MIT
Family figure — Figure 1 · Source
DIFFA
Answers audio questions using diffusion-based text generation instead of left-to-right decoding.
Paper · Code · Weights · Details
License unclear: code Not stated · weights CC-BY-NC-SA-4.0 — The checkpoint uses a noncommercial share-alike license; repository code terms are not stated.
Figure 2 · Source
DIFFA-2
Understands speech, sound and music with a diffusion language model and richer acoustic representations.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Not stated — No release-specific code or weight license was located; do not assume DIFFA 1 terms apply.
Figure 1 · Source
DiVA
Answers spoken questions by transferring a text assistant's behavior into an audio-input model.
Custom / restricted: code MPL-2.0 · weights MPL-2.0 + Llama 3 terms — The Llama 3 backbone retains its community license.
Input/output diagram · Source
DuplexCascade
Coordinates streaming transcription, language generation and speech synthesis for interruptible voice conversations.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 1 · Source
DuplexMamba
Reads incoming speech incrementally and supports responsive text generation during speech interaction.
Paper · Code · Weights · Details
Open license: code GPL-3.0 · weights Apache-2.0
Figure 1 · Source
EMOVA (Qwen2.5-7B)
Discusses images and spoken requests, replying with text and expressive speech.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure · Figure 2 · Source
Freeze-Omni
Enables streaming spoken dialogue while retaining a frozen text model's language abilities.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Figure 1 · Source
Fun-Audio-Chat
Holds low-latency spoken conversations while responding to vocal style and emotion.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2, PDF p. 4 · Source
Gemma 3n E4B
Understands text, images, video and audio in a model designed for mobile devices.
Custom / restricted: code Apache-2.0 · weights Gemma terms — The weights use custom Gemma terms.
Input/output diagram · Source
Gemma 4 E4B
Answers questions about images, video and audio in a compact model designed for local use.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
GLM-4-Voice
Converses in Chinese and English with controllable emotion, speaking rate and vocal style.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights GLM-4 model license — Custom GLM model terms apply to the speech checkpoint.
Figure 2 · Source
GLM-ASR Nano
Transcribes speech in English, Mandarin and Chinese dialects, including noisy recordings.
Open license: code MIT · weights MIT
Input/output diagram · Source
Granite Speech 3.3
Transcribes and translates speech while retaining a text language-model interface.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
Granite Speech 4.0
Provides compact speech transcription and translation with a 1B language backbone.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Granite Speech 4.1
Transcribes and translates multilingual speech using an updated speech-language architecture.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Hibiki
Translates French speech into English as it arrives while preserving the speaker's voice.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights CC-BY-4.0
Figure 2 · Source
HumanOmni
Interprets human behavior, expressions and interactions from video and audio.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Not stated — Public code and weights were located, but a complete release license was not stated.
Figure 1 · Source
HumanOmniV2
Interprets people's actions, emotions and social interactions from video and audio.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 4 · Source
Ichigo
Answers spoken questions using audio tokens embedded directly into a Llama conversation.
License unclear: code Not stated · weights Apache-2.0 + Llama 3.1 terms — The Llama 3.1 backbone retains its community license; no standalone repository license was located.
Input/output diagram · Source
Kimi-Audio
Understands speech, sound and music and supports natural voice conversations.
Paper · Code · Weights · Details
Open license: code MIT / Apache-2.0 · weights MIT
Figure 2 · Source
LFG-1
Answers English spoken questions locally on Apple Silicon and also accepts images.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
LFG-2
Reasons about English spoken instructions and returns a text answer with an optional thought channel.
License unclear: code Not stated · weights Not stated — Code and weights are downloadable, but this release does not state a license.
Input/output diagram · Source
LFG-3
Answers English spoken questions using acoustic features instead of an intermediate transcript.
License unclear: code Not stated · weights Not stated — Code and weights are downloadable, but this release does not state a license.
Input/output diagram · Source
LFM2-Audio-1.5B
Transcribes speech, synthesizes speech and supports interleaved voice conversations on local devices.
Paper · Code · Weights · Details
Custom / restricted: code LFM Open License v1.0 · weights LFM Open License v1.0 — Revenue-based commercial-use limit; see the LFM license.
Figure 7 · Source
LFM2.5-Audio-1.5B
Handles transcription, speech synthesis and voice chat with a faster audio decoder for local inference.
Paper · Code · Weights · Details
Custom / restricted: code LFM Open License v1.0 · weights LFM Open License v1.0 — Revenue-based commercial-use limit; see the LFM license.
Input/output diagram · Source
LFM2.5-Audio-1.5B-JP
Brings Japanese transcription, speech synthesis and spoken conversation to the LFM2.5 audio family.
Paper · Code · Weights · Details
Custom / restricted: code LFM Open License v1.0 · weights LFM Open License v1.0 — Revenue-based commercial-use limit; see the LFM license.
Input/output diagram · Source
LLaMA-Omni
Answers spoken requests with synchronized text and streaming speech.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Research-only — The model card excludes commercial use of the weights.
Figure 2 · Source
LLaMA-Omni 2
Supports multi-turn spoken chat with streaming speech generation.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Research-only — The model card excludes commercial use of the weights.
Figure 1 · Source
LLaSM
Answers spoken questions and supports instruction following across speech and text.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights OpenRAIL — Custom release or component terms apply; consult the linked license evidence.
Figure 1 · Source
LongCat-Flash-Omni
Understands text, images, video and audio and produces text or spoken responses.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
LongCat-Next
Understands and generates text, images and audio within one multimodal model.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
Lychee-FD
Listens and speaks continuously while deciding when to respond, stop or handle interruptions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 3 · Source
Lyra-Base
Handles long speech, audiovisual questions and spoken dialogue with a 9B configuration.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-4.0 — The repository limits model weights to noncommercial research despite the model-card badge.
Figure 2 · Source
Lyra-Mini
Offers audiovisual understanding and spoken interaction in Lyra's smaller 3B configuration.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-4.0 — The repository limits model weights to noncommercial research despite the model-card badge.
Family figure — Figure 2 · Source
Mair-hub-0.5B-Omni
Provides a small speech-to-speech assistant trained with a reproducible Qwen-Omni-like recipe.
License unclear: code Apache-2.0 · weights Not stated — The training recipe is Apache-2.0; the published checkpoint does not state a weight license.
Input/output diagram · Source
Megrez-Omni
Answers questions about pictures and audio using a compact 3B language backbone.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Mellow
Uses reasoning over audio to answer questions that require more than recognizing a sound.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
MERaLiON 2
Understands multilingual Southeast Asian speech, code-switching, emotion and audio scenes.
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
Input/output diagram · Source
MERaLiON 3
Understands multilingual Southeast Asian speech, including local dialects and conversational code-switching.
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
Input/output diagram · Source
MERaLiON 3 ASR
Transcribes Southeast Asian languages, regional dialects and code-switched speech.
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
Input/output diagram · Source
MERaLiON-AudioLLM
Transcribes, translates and explains audio, including Singaporean speech and local language usage.
Paper · Code · Weights · Details
Custom / restricted: code MERaLiON public license · weights MERaLiON public license — Custom MERaLiON terms and incorporated base-model licenses apply.
Figure 1 · Source
MiDashengLM
Describes speech, environmental sounds and music and answers questions about recordings.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Figure 2 · Source
MiMo-Audio
Understands recordings and conducts spoken conversations using instructions and audio examples.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights MIT
Figure 3 · Source
MiMo-V2.5
Answers questions and follows instructions involving text, images, videos and audio.
Open license: code Apache-2.0 · weights MIT
Official architecture diagram · Source
Ming-Flash-Omni
Combines audiovisual understanding with text, image and audio generation.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
Ming-Flash-Omni 2.0
Interprets mixed audiovisual inputs and generates text, images or expressive audio.
Open license: code MIT · weights MIT
Official architecture diagram · Source
Ming-Lite-Omni
Handles audiovisual questions and creates text, images and spoken responses.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Family figure · Figure 2 · Source
Mini-Omni
Listens to spoken questions and streams text and speech answers together.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 1 · Source
Mini-Omni2
Sees images, follows spoken instructions and streams spoken replies with interruption handling.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 1 · Source
MiniCPM-o 2.6
Chats about images, video and audio, with speech output and voice imitation.
Open license: code Apache-2.0 · weights Apache-2.0
Official architecture diagram · Source
MiniCPM-o 4.5
Supports live audiovisual conversations while listening and speaking at the same time.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 4 · Source
MiniMind-O
Provides a small, trainable model for image questions and spoken conversations.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
MIO
Understands audiovisual content and generates text, images or speech using multimodal tokens.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 + Yi terms — The Yi-6B-Chat base retains its license; repository-wide code terms are not stated.
Figure 1 · Source
Moshi
Listens and speaks simultaneously, handling conversational overlap and interruptions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights CC-BY-4.0
Figure 1 · Source
MOSS-Audio Instruct
Captions recordings, answers time-specific questions and transcribes speech with timestamps.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Figure 2 · Source
MOSS-Audio Thinking
Reasons about speech, environmental sound and music before producing a text answer.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Family figure — Figure 2 · Source
MOSS-Speech
Converses directly in Chinese and English speech without first generating a text response.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — The repository licenses code, but a release-specific weight license was not located.
Figure 3 · Source
Music Flamingo
Explains musical structure, instruments and expressive qualities in recordings.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
Figure 2 · Source
Nemotron 3 Nano Omni
Reasons over documents, images, video and audio and returns text responses.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA Open Model Agreement — Custom model terms apply to the weights.
Figure 1 · Source
Nemotron-Labs-Audex 2B
Performs audio understanding, speech tasks and sound generation with a smaller dense backbone.
Paper · Code · Weights · Details
License unclear: code Not stated · weights NVIDIA OneWay Noncommercial — Noncommercial weight license; inspect the included code files for component-specific terms.
Family figure — 30B variant · Source
Nemotron-Labs-Audex 30B-A3B
Understands recordings, transcribes and translates speech, and generates speech or general sounds.
Paper · Code · Weights · Details
License unclear: code Not stated · weights NVIDIA OneWay Noncommercial — Noncommercial weight license; inspect the included code files for component-specific terms.
Official family architecture diagram · Source
NemotronLabs VoiceChat 11B
Holds interruptible, full-duplex voice conversations and can call tools while maintaining the dialogue.
Open license: code Apache-2.0 · weights OpenMDW-1.1
Input/output diagram · Source
NExT-GPT
Accepts and generates combinations of text, images, video and audio through connected modality models.
Paper · Code · Weights · Details
Custom / restricted: code BSD-3-Clause · weights CC-BY-NC-SA-4.0 — Noncommercial share-alike weight license; downstream modality decoders retain their own terms.
Figure 1, PDF p. 2 · Source
Nexus-O
Combines image, video and audio understanding with text and speech interaction.
Paper · Code · Weights · Details
Custom / restricted: code Research-only / CC-BY-NC-4.0 · weights Research-only / CC-BY-NC-4.0 — The model-card body restricts research use despite its Apache metadata.
Figure 1 · Source
Ola
Answers questions that combine images, video, audio and text.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 3 · Source
Omni-AutoThink
Adapts how much reasoning it uses before answering audiovisual questions.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 1 · Source
Omni-R1 (audio reasoning)
Answers questions about speech, sounds and music using reinforcement-trained audio reasoning.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — Public checkpoint archive; no separate weight-license declaration was located.
Input/output diagram · Source
Omni-R1 (two-system collaboration)
Combines global audiovisual reasoning with detailed visual grounding to answer multimodal questions.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Academic use — The model card asks commercial users to contact the authors.
Figure 1, PDF p. 2 · Source
OmniVinci
Answers questions about combined visual and audio content with temporal alignment.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights NVIDIA OneWay Noncommercial — Noncommercial terms apply to model weights and relevant bundled components.
Figure 2 · Source
OneLLM
Answers questions across images, video and audio through one aligned language model.
Paper · Code · Weights · Details
Custom / restricted: code Llama 2 community license · weights Llama 2 community license — Custom base-model community terms apply.
Figure 2 · Source
OpenOmni
Combines audiovisual understanding with multilingual and emotionally aware spoken responses.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Figure 1 · Source
OpenS2S
Recognizes emotional cues in speech and generates empathetic, streaming spoken replies.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
OpenS2S 1.5
Provides the updated OpenS2S checkpoint for expressive, empathetic spoken dialogue.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 1 · Source
OSUM
Recognizes words, timestamps, vocal events, emotions and speaking style from speech.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
OSUM-EChat
Uses speech understanding to produce empathetic text and voice responses.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
ParaBridge
Adapts replies to vocal emotion and other nonverbal cues in a spoken request.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 3 · Source
Parakeet-TDT-v2 + Qwen3-8B
Transcribes speech with Parakeet and sends the transcript to Qwen3 for a text response.
Code · Weights · ASR weights · Details
Open license: code Apache-2.0 · weights Apache-2.0 · ASR CC-BY-4.0
Input/output diagram · Source
PersonaPlex
Holds full-duplex conversations with a role set by text and a voice set by an audio prompt.
Paper · Code · Weights · Details
Custom / restricted: code MIT · weights NVIDIA Open Model License — Custom NVIDIA weight terms; access requires accepting the model agreement.
Figure 1 · Source
Phi-4-multimodal
Reads images, transcribes or translates speech, and answers multimodal questions in text.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights MIT
Figure 1 · Source
Qwen-Audio
Transcribes, translates and describes speech, sounds and music through natural-language responses.
Paper · Code · Weights · Details
Custom / restricted: code Tongyi Qianwen license · weights Tongyi Qianwen license — Custom Qwen terms include a large-user-base commercial permission requirement.
Figure 3 · Source
Qwen2-Audio
Answers spoken instructions and analyzes speech, environmental sounds and music in text.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Qwen2.5-Omni
Understands images, video and sound and streams coordinated text and speech replies.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Qwen3-ASR
Identifies languages and transcribes speech across languages and dialects.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Qwen3-Omni Instruct
Converses about text, images, video and audio and generates streaming speech.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Qwen3-Omni Thinking
Uses explicit reasoning to answer questions about text, images, video and audio.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 2 · Source
R1-Omni
Reasons about emotion using facial, vocal and contextual cues in videos.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Public code and weights were located, but a complete release license was not stated.
Input/output diagram · Source
SALMONN
Transcribes speech, captions sound and music, and answers audio-grounded questions.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Apache-2.0 + Llama 2 terms — The Vicuna/Llama 2 language backbone retains its community license.
Figure 1 · Source
SALMONN-2
Understands speech, sounds and music and supports context-aware transcription and audio questions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
SLAM-Omni
Conducts multi-turn voice conversations while allowing the output speaker's timbre to be changed.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
SoulX-Duplug
Predicts when a voice assistant should keep listening, respond or handle an interruption.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 4 · Source
SpeechGPT
Follows spoken instructions and generates speech using discrete speech units in a language model.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — The repository licenses code, but a release-specific weight license was not located.
Figure 2 · Source
SpeechGPT 2.0 Preview
Understands spoken requests and produces natural spoken responses through a speech-native language model.
License unclear: code Apache-2.0 · weights Not stated — The repository licenses code, but a release-specific weight license was not located.
Official architecture diagram · Source
Step-Audio
Supports voice conversations with expressive speech, role-play and spoken tool requests.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Step-Audio 2 Mini
Understands audio and produces expressive spoken replies, with support for tool-assisted conversations.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 3 · Source
Step-Audio 2 Mini Think
Reasons before answering spoken questions and complex audio-understanding tasks.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 3 · Source
Step-Audio-AQAA
Produces expressive spoken answers directly from audio questions.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
Step-Audio-R1
Uses reinforcement-learned reasoning to answer questions about speech, sound and music.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
Step-Audio-R1.1
Extends audio reasoning into responsive spoken dialogue and voice interaction.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Related method — Mind-Paced Speaking, Figure 3 · Source
Stream-Omni
Supports simultaneous text, image and spoken interaction while aligning text and speech outputs.
Paper · Code · Weights · Details
Custom / restricted: code GPL-3.0 · weights GPL-3.0 + Llama 3.1 terms — The included Llama 3.1 backbone retains its community license.
Figure 2 · Source
Sympatheia
Adjusts spoken replies to a speaker's changing emotional state.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 + GLM-4 terms — GLM-4-Voice base-model conditions also apply; repository code licensing is not stated.
Figure 3 · Source
TurnGuide
Maintains coherent spoken conversations while managing overlaps and turn changes.
Paper · Code · Weights · Details
License unclear: code Apache-2.0 · weights Not stated — No release-specific weight license is stated; the GLM-4-Voice base has custom terms.
Figure 2 · Source
Ultravox 0.4.1 Llama-3.1-8B
Provides an earlier Ultravox speech-understanding checkpoint for text-based voice responses.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.5 Llama-3.1-8B
Handles spoken questions and instruction following with text output.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.5 Llama-3.2-1B
Provides speech-to-text-answer interaction with a small 1B language backbone.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.6 Gemma-3-27B
Answers voice requests using Gemma 3's language capabilities.
Custom / restricted: code MIT · weights MIT + Gemma terms — The included Gemma backbone retains its custom usage terms.
Family figure — Llama-based example · Source
Ultravox 0.6 Llama-3.1-8B
Responds to spoken instructions in text using the 8B Ultravox 0.6 release.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.6 Llama-3.3-70B
Turns spoken questions into text answers using a large Llama 3.3 backbone.
Custom / restricted: code MIT · weights MIT + Llama community terms — Ultravox code is MIT; the included Llama backbone retains its community license.
Family figure — Llama-based example · Source
Ultravox 0.6 Qwen3-32B
Adds spoken-instruction understanding and text responses to Qwen3-32B.
Open license: code MIT · weights MIT
Family figure — Llama-based example · Source
Ultravox 0.7 GLM-4.6
Answers spoken questions and follows voice instructions using a GLM-4.6 language backbone.
Open license: code MIT · weights MIT
Family figure — Llama-based example · Source
Uni-MoE 2.0 Omni
Understands audiovisual requests and supports text, image and speech generation.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Apache-2.0 — Weights are Apache-2.0; no license for this implementation directory was located.
Figure 2 · Source
VibeVoice-ASR
Transcribes long recordings with speaker labels and timestamps in one pass.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
video-SALMONN 2+ (7B)
Captions videos and answers questions using both what is seen and heard.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure · Figure 1 · Source
VideoLLaMA 2.1 AV
Answers questions about videos using synchronized visual and audio information.
Paper · Code · Weights · Details
Custom / restricted: code Apache-2.0 · weights Research-only — The repository restricts use to noncommercial research despite the checkpoint badge.
Figure 1 · Source
VITA 1.0
Understands images, video and speech in a multimodal assistant with interruptible interaction.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Figure 2 · Source
VITA 1.5
Provides visual and spoken interaction with streaming speech responses.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Figure 2 · Source
VITA-Audio
Streams spoken responses quickly by generating multiple audio tokens per language-model step.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Figure 2 · Source
VITA-Audio Plus
Provides the later VITA-Audio release with accelerated interleaved speech and text generation.
Paper · Code · Weights · Details
Custom / restricted: code Tencent research license · weights Tencent research license — Academic/research use only; commercial and production use are excluded.
Family figure — Figure 2 · Source
Voila Autonomous
Supports autonomous voice interaction with simultaneous listening and speaking.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Family figure — Figure 2 · Source
Voila Chat
Holds voice conversations with speaker identity and speaking style controlled by prompts.
Paper · Code · Weights · Details
Open license: code MIT · weights MIT
Figure 2 · Source
VoxMind
Handles spoken requests that require reasoning, planning and external tool use.
Paper · Code · Weights · Details
License unclear: code Not stated · weights Not stated — Public code and weights were located, but a complete release license was not stated.
Figure 2 · Source
Voxtral Mini
Provides transcription and audio question answering in a smaller 3B configuration.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Family figure — Figure 1 · Source
Voxtral Realtime
Transcribes live audio incrementally for low-latency applications.
Open license: code Apache-2.0 · weights Apache-2.0
Input/output diagram · Source
Voxtral Small
Transcribes and translates speech and answers questions about long audio recordings.
Paper · Code · Weights · Details
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 · Source
Whisper-v3-large + Llama-3.1-8B
Uses Whisper to transcribe a spoken request and Llama 3.1 to answer it.
Code · Weights · ASR weights · Details
Custom / restricted: code Apache-2.0 · weights Llama community license · ASR Apache-2.0 — The text backbone uses the Llama community license.
Input/output diagram · Source
Whisper-v3-turbo + Llama-3.1-8B
Pairs faster Whisper transcription with Llama 3.1 text responses.
Code · Weights · ASR weights · Details
Custom / restricted: code Apache-2.0 · weights Llama community license · ASR MIT — The text backbone uses the Llama community license.
Input/output diagram · Source
Whisper-v3-turbo + Llama-3.2-3B
Combines Whisper Turbo with a smaller Llama 3.2 model for spoken question answering.
Code · Weights · ASR weights · Details
Custom / restricted: code Apache-2.0 · weights Llama community license · ASR MIT — The text backbone uses the Llama community license.
Input/output diagram · Source
Similar repos
Contributors
9 commits
Languages
Python
100.0%