
Github repository for ACL 2025 paper: Recent Advances in Speech Language Models: A Survey.
225
8 commits
updated Aug 21, 2026
README
Awesome-SpeechLM-Survey

🎉🎉🎉Our survey paper "Recent Advances in Speech Language Models: A Survey" has been accepted to ACL 2025 main conference!
This is the Github repository for paper: Recent Advances in Speech Language Models: A Survey. In this paper, we survey the field of Speech Language Models (SpeechLMs), which are capable of performing end-to-end speech interactions with humans and serve as autoregressive foundation models.
News
- The short version of our audio reasoning survey paper has been accepted to EMNLP 2026 Findings! 🎉
- Our paper SpeechSense: A Paralinguistic-Focused Dataset for Fine-Grained Speech Sentiment Analysis has been accepted to ACM Multimedia 2026 (Dataset Track)! 🎉
- We have released TextPro-SLM: Minimizing Modality Gap from the Input Side: Your Speech LLM Can Be a Prosody-Aware Text LLM on arXiv! 🎉
- We have released A Survey of Audio Reasoning in Multimodal Foundation Models on arXiv! 🎉
- Our paper TurnGuide: Enhancing Meaningful Full Duplex Spoken Interactions via Dynamic Turn-Level Text-Speech Interleaving has been accepted to Interspeech 2026 Long Paper Track as an Oral presentation! 🎉 Check it out on GitHub.
- Our paper MTR-DuplexBench: Towards a Comprehensive Evaluation of Multi-Round Conversations for Full-Duplex Speech Language Models has been accepted to Findings of ACL 2026! 🎉 Check it out on GitHub.
- We have released VoxEval: Benchmarking the Knowledge Understanding Capabilities of End-to-End Spoken Language Models on arXiv!🎉 Also check it out on Github.
Introduction
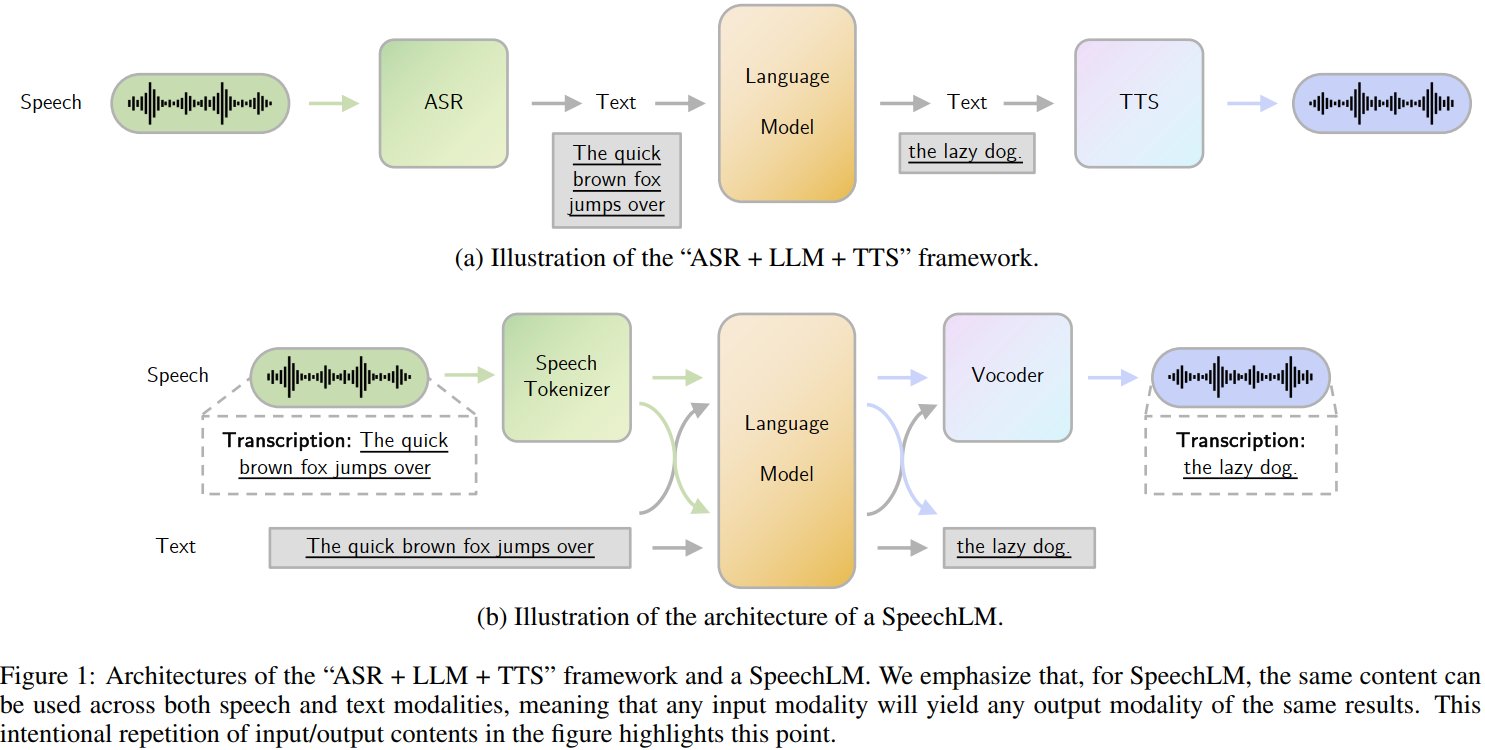
Why SpeechLMs? SpeechLMs are used for end-to-end speech-based interactions. Traditional ASR + LLM + TTS setups suffer from information loss and cumulative errors during conversion. SpeechLMs directly model speech data, capturing both semantic and paralinguistic information for richer interactions!
In this repository, we distinguish between two closely related model families:
- Speech Language Models (SpeechLMs) directly accept speech/audio and generate speech/audio. They may operate in turn-based, streaming, or full-duplex settings, but do not rely on an external ASR-LLM-TTS cascade as their core interaction mechanism.
- Large Audio Language Models (LALMs) use a generative language model to understand speech, environmental sound, or music and produce text. Speech-centric LLM-ASR models are included as a dedicated LALM category, while conventional encoder-only ASR models are outside the scope of this list.
Models supporting both text and speech output are listed under SpeechLMs to avoid duplication.
Taxonomy
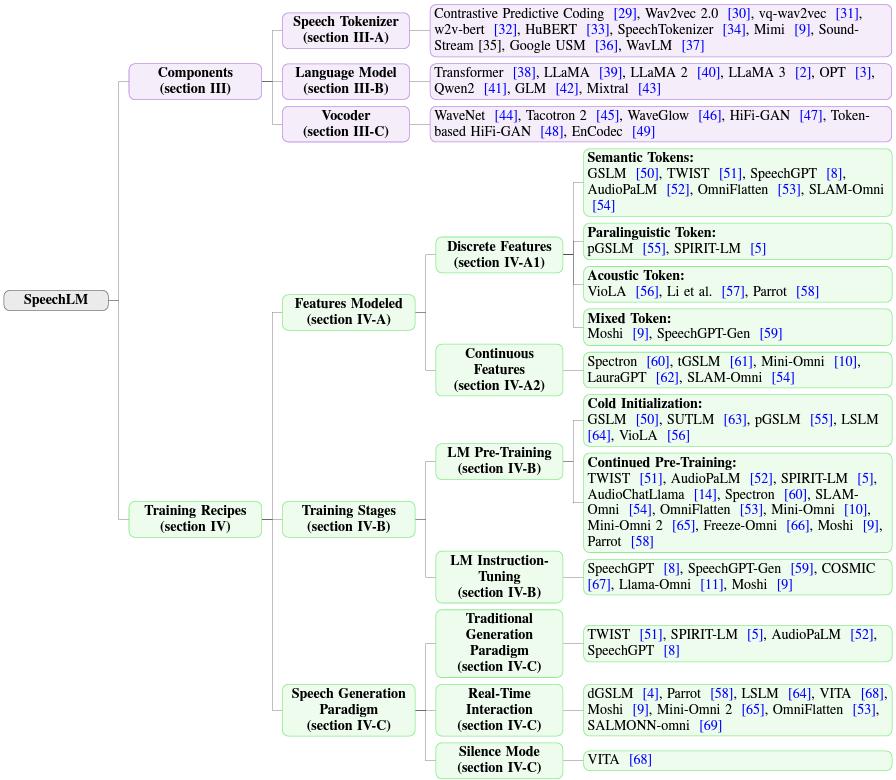
We introduce a novel taxonomy for SpeechLMs, categorizing them based on their architecture and training recipes.
Speech Language Models (SpeechLMs)
The models below support speech/audio input and speech/audio output within the model. The list covers turn-based, streaming, and full-duplex interaction.
Commercial and Closed Voice Systems
These entries are tracked separately because public information may describe a product or API rather than disclose a standalone end-to-end model architecture.
| System | Release | Year | Notes |
|---|---|---|---|
| OpenAI GPT-Live | Introducing GPT-Live | 2026 | Full-duplex voice model |
| OpenAI GPT-Realtime-2 | Advancing Voice Intelligence with New Models in the API | 2026 | Native audio input and output |
| OpenAI gpt-realtime | Introducing gpt-realtime | 2025 | Native audio input and output |
| Gemini Native Audio / Live API | Live API Capabilities | 2025 | Native real-time audio interaction |
| OpenAI Advanced Voice Mode | Advanced Voice Mode FAQ | 2024 | Commercial voice experience |
| Claude Voice Mode | Using Voice Mode on Claude Mobile Apps | 2025 | Product feature; native end-to-end architecture not publicly documented |
| MindGPT-4o-Audio | MindGPT-4o-Audio Release | 2025 | Commercial real-time voice model |
SpeechLM Training and Alignment
These papers improve the interaction behavior of full-duplex SpeechLMs rather than introducing a separate foundation-model family.
| Paper | Year | Focus |
|---|---|---|
| Aligning Spoken Dialogue Models from User Interactions | 2025 | Preference alignment from user interactions |
| Multi-Faceted Interactivity Alignment in Full-Duplex Speech Models | 2026 | Reinforcement learning for full-duplex interactivity |
Large Audio Language Models (LALMs)
LALMs accept speech, environmental sound, and/or music and generate text. Models that additionally generate speech are listed only in the SpeechLM section above.
General Audio Understanding
Audio Reasoning, Music, and Prosody
| Model | Paper | Year | Focus |
|---|---|---|---|
| TextPro-SLM | Minimizing Modality Gap from the Input Side: Your Speech LLM Can Be a Prosody-Aware Text LLM | 2026 | Speech and prosody understanding |
| Audio-Cogito | Audio-Cogito | 2026 | Deep audio reasoning |
| Step-Audio-R1 | Step-Audio-R1 | 2025 | Speech, sound, and music reasoning |
| Music Flamingo | Music Flamingo | 2025 | Music understanding and reasoning |
| Audio-Reasoner | Improving Reasoning Capability in Large Audio Language Models | 2025 | Chain-of-thought audio reasoning |
| LLark | A Multimodal Instruction-Following Language Model for Music | 2023 | Music understanding and reasoning |
| MusiLingo | Bridging Music and Text with Pre-trained Language Models for Music Captioning and Query Response | 2023 | Music captioning and QA |
| MU-LLaMA | Music Understanding Large Language Model | 2023 | Music understanding |
Speech-Centric LALMs and LLM-ASR
This category contains speech-conditioned generative language models whose primary output is text. Conventional encoder-only ASR systems are excluded.
| Model | Paper / Release | Year | Focus |
|---|---|---|---|
| FireRedASR2S | A Fully Open-Source Industrial-Grade All-in-One Speech Recognition System | 2026 | Multilingual ASR |
| Qwen3-ASR | Qwen3-ASR Technical Report | 2026 | Multilingual and multidialect ASR |
| VibeVoice-ASR | VibeVoice-ASR Technical Report | 2026 | Long-form ASR, diarization, and timestamps |
| GLM-ASR-Nano | GLM-ASR | 2025 | LLM-based ASR |
| Fun-ASR | Fun-ASR: A Large Language Model Based Speech Recognition System | 2025 | Multilingual speech-to-text |
| FireRedASR | Open-Source Industrial-Grade Speech Recognition Models from Encoder-Decoder to LLM Integration | 2025 | ASR and LLM integration |
| Seed-ASR | Understanding Diverse Speech and Contexts with LLM-based Speech Recognition | 2024 | Context-aware LLM-ASR |
Related Audio and Speech Generation Systems
The following works are closely related but are not included in the strict SpeechLM or LALM lists because they do not provide a unified speech-input/speech-output dialogue model or an audio-conditioned generative text LLM.
| Model / Family | Paper / Release | Scope |
|---|---|---|
| CSM | Conversational Speech Generation Model | Conversational speech generation / TTS |
| FunAudioLLM | Voice Understanding and Generation Foundation Models for Natural Interaction Between Humans and LLMs | SenseVoice and CosyVoice model family |
| UniAudio | An Audio Foundation Model Toward Universal Audio Generation | Universal audio generation |
| Voicebox | Text-Guided Multilingual Universal Speech Generation at Scale | Text-guided speech generation |
SpeechLM Tokenizers
Semantic Tokenizers
| Name | Title | Url |
|---|---|---|
| Whisper | Robust Speech Recognition via Large-Scale Weak Supervision | Link |
| CosyVoice | CosyVoice: A Scalable Multilingual Zero-shot Text-to-speech Synthesizer based on Supervised Semantic Tokens | Link |
| Google USM | Google USM: Scaling Automatic Speech Recognition Beyond 100 Languages | Link |
| WavLM | WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing | Link |
| HuBERT | HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units | Link |
| W2v-bert | W2v-BERT: Combining Contrastive Learning and Masked Language Modeling for Self-Supervised Speech Pre-Training | Link |
| Wav2vec 2.0 | wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations | Link |
Acoustic Tokenizers
| Name | Title | Url |
|---|---|---|
| WavTokenizer | WavTokenizer: an Efficient Acoustic Discrete Codec Tokenizer for Audio Language Modeling | Link |
| SNAC | SNAC: Multi-Scale Neural Audio Codec | Link |
| Encodec | High Fidelity Neural Audio Compression | Link |
| SoundStream | SoundStream: An End-to-End Neural Audio Codec | Link |
Mixed Tokenizers
| Name | Title | Url |
|---|---|---|
| SpeechTokenizer | SpeechTokenizer: Unified Speech Tokenizer for Speech Large Language Models | Link |
| Mimi | Moshi: a speech-text foundation model for real-time dialogue | Link |
Popular Training Datasets
| Dataset | Type | Phase | Hours | Year |
|---|---|---|---|---|
| LibriSpeech | ASR | Pre-Training | 1k | 2015 |
| Multilingual LibriSpeech | ASR | Pre-Training | 50.5k | 2020 |
| LibriLight | ASR | Pre-Training | 60k | 2019 |
| People dataset | ASR | Pre-Training | 30k | 2021 |
| VoxPopuli | ASR | Pre-Training | 1.6k | 2021 |
| Gigaspeech | ASR | Pre-Training | 40k | 2021 |
| Common Voice | ASR | Pre-Training | 2.5k | 2019 |
| VCTK | ASR | Pre-Training | 0.3k | 2017 |
| WenetSpeech | ASR | Pre-Training | 22k | 2022 |
| LibriTTS | TTS | Pre-Training | 0.6k | 2019 |
| CoVoST2 | S2TT | Pre-Training | 2.8k | 2020 |
| CVSS | S2ST | Pre-Training | 1.9k | 2022 |
| VoxCeleb | Speaker Identification | Pre-Training | 0.4k | 2017 |
| VoxCeleb2 | Speaker Identification | Pre-Training | 2.4k | 2018 |
| Spotify Podcasts | Podcast | Pre-Training | 47k | 2020 |
| Fisher | Telephone conversation | Pre-Training | 2k | 2004 |
| SpeechInstruct | Instruction-following | Instruction-Tuning | - | 2023 |
| InstructS2S-200K | Instruction-following | Instruction-Tuning | - | 2024 |
| VoiceAssistant-400K | Instruction-following | Instruction-Tuning | - | 2024 |
Evaluation Benchmarks
| Name | Eval Type | # Tasks | Audio Type | I/O |
|---|---|---|---|---|
| ABX | Representation | 1 | Speech | $A \rightarrow -$ |
| sWUGGY | Linguistic | 1 | Speech | $A \rightarrow -$ |
| sBLIMP | Linguistic | 1 | Speech | $A \rightarrow -$ |
| sStoryCloze | Linguistic | 1 | Speech | $A/T \rightarrow -$ |
| STSP | Paralinguistic | 1 | Speech | $A/T \rightarrow A/T$ |
| MMAU | Downstream | 27 | Speech, Sound, Music | $A \rightarrow T$ |
| Audiobench | Downstream | 8 | Speech, Sound | $A \rightarrow T$ |
| AIR-Bench | Downstream | 20 | Speech, Sound, Music | $A \rightarrow T$ |
| SD-Eval | Downstream | 4 | Speech | $A \rightarrow T$ |
| SUPERB | Downstream | 10 | Speech | $A \rightarrow T$ |
| Dynamic-SUPERB | Downstream | 180 | Speech, Sound, Music | $A \rightarrow T$ |
| SALMON | Downstream | 8 | Speech | $A \rightarrow -$ |
| VoiceBench | Downstream | 8 | Speech | $A \rightarrow A$ |
| VoxEval | Downstream | 56 | Speech | $A \rightarrow A$ |
Citation
@article{cui2024recent,
  title={Recent advances in speech language models: A survey},
  author={Cui, Wenqian and Yu, Dianzhi and Jiao, Xiaoqi and Meng, Ziqiao and Zhang, Guangyan and Wang, Qichao and Guo, Yiwen and King, Irwin},
  journal={arXiv preprint arXiv:2410.03751},
  year={2024}
}
Contributors

8 commits
Similar repos


Github repository for ACL 2025 paper: Recent Advances in Speech Language Models: A Survey.
225
8 commits
updated Aug 21, 2026
README
Awesome-SpeechLM-Survey
🎉🎉🎉Our survey paper "Recent Advances in Speech Language Models: A Survey" has been accepted to ACL 2025 main conference!
This is the Github repository for paper: Recent Advances in Speech Language Models: A Survey. In this paper, we survey the field of Speech Language Models (SpeechLMs), which are capable of performing end-to-end speech interactions with humans and serve as autoregressive foundation models.
News
- The short version of our audio reasoning survey paper has been accepted to EMNLP 2026 Findings! 🎉
- Our paper SpeechSense: A Paralinguistic-Focused Dataset for Fine-Grained Speech Sentiment Analysis has been accepted to ACM Multimedia 2026 (Dataset Track)! 🎉
- We have released TextPro-SLM: Minimizing Modality Gap from the Input Side: Your Speech LLM Can Be a Prosody-Aware Text LLM on arXiv! 🎉
- We have released A Survey of Audio Reasoning in Multimodal Foundation Models on arXiv! 🎉
- Our paper TurnGuide: Enhancing Meaningful Full Duplex Spoken Interactions via Dynamic Turn-Level Text-Speech Interleaving has been accepted to Interspeech 2026 Long Paper Track as an Oral presentation! 🎉 Check it out on GitHub.
- Our paper MTR-DuplexBench: Towards a Comprehensive Evaluation of Multi-Round Conversations for Full-Duplex Speech Language Models has been accepted to Findings of ACL 2026! 🎉 Check it out on GitHub.
- We have released VoxEval: Benchmarking the Knowledge Understanding Capabilities of End-to-End Spoken Language Models on arXiv!🎉 Also check it out on Github.
Introduction
Why SpeechLMs? SpeechLMs are used for end-to-end speech-based interactions. Traditional ASR + LLM + TTS setups suffer from information loss and cumulative errors during conversion. SpeechLMs directly model speech data, capturing both semantic and paralinguistic information for richer interactions!
In this repository, we distinguish between two closely related model families:
- Speech Language Models (SpeechLMs) directly accept speech/audio and generate speech/audio. They may operate in turn-based, streaming, or full-duplex settings, but do not rely on an external ASR-LLM-TTS cascade as their core interaction mechanism.
- Large Audio Language Models (LALMs) use a generative language model to understand speech, environmental sound, or music and produce text. Speech-centric LLM-ASR models are included as a dedicated LALM category, while conventional encoder-only ASR models are outside the scope of this list.
Models supporting both text and speech output are listed under SpeechLMs to avoid duplication.
Taxonomy
We introduce a novel taxonomy for SpeechLMs, categorizing them based on their architecture and training recipes.
Speech Language Models (SpeechLMs)
The models below support speech/audio input and speech/audio output within the model. The list covers turn-based, streaming, and full-duplex interaction.
Commercial and Closed Voice Systems
These entries are tracked separately because public information may describe a product or API rather than disclose a standalone end-to-end model architecture.
| System | Release | Year | Notes |
|---|---|---|---|
| OpenAI GPT-Live | Introducing GPT-Live | 2026 | Full-duplex voice model |
| OpenAI GPT-Realtime-2 | Advancing Voice Intelligence with New Models in the API | 2026 | Native audio input and output |
| OpenAI gpt-realtime | Introducing gpt-realtime | 2025 | Native audio input and output |
| Gemini Native Audio / Live API | Live API Capabilities | 2025 | Native real-time audio interaction |
| OpenAI Advanced Voice Mode | Advanced Voice Mode FAQ | 2024 | Commercial voice experience |
| Claude Voice Mode | Using Voice Mode on Claude Mobile Apps | 2025 | Product feature; native end-to-end architecture not publicly documented |
| MindGPT-4o-Audio | MindGPT-4o-Audio Release | 2025 | Commercial real-time voice model |
SpeechLM Training and Alignment
These papers improve the interaction behavior of full-duplex SpeechLMs rather than introducing a separate foundation-model family.
| Paper | Year | Focus |
|---|---|---|
| Aligning Spoken Dialogue Models from User Interactions | 2025 | Preference alignment from user interactions |
| Multi-Faceted Interactivity Alignment in Full-Duplex Speech Models | 2026 | Reinforcement learning for full-duplex interactivity |
Large Audio Language Models (LALMs)
LALMs accept speech, environmental sound, and/or music and generate text. Models that additionally generate speech are listed only in the SpeechLM section above.
General Audio Understanding
Audio Reasoning, Music, and Prosody
| Model | Paper | Year | Focus |
|---|---|---|---|
| TextPro-SLM | Minimizing Modality Gap from the Input Side: Your Speech LLM Can Be a Prosody-Aware Text LLM | 2026 | Speech and prosody understanding |
| Audio-Cogito | Audio-Cogito | 2026 | Deep audio reasoning |
| Step-Audio-R1 | Step-Audio-R1 | 2025 | Speech, sound, and music reasoning |
| Music Flamingo | Music Flamingo | 2025 | Music understanding and reasoning |
| Audio-Reasoner | Improving Reasoning Capability in Large Audio Language Models | 2025 | Chain-of-thought audio reasoning |
| LLark | A Multimodal Instruction-Following Language Model for Music | 2023 | Music understanding and reasoning |
| MusiLingo | Bridging Music and Text with Pre-trained Language Models for Music Captioning and Query Response | 2023 | Music captioning and QA |
| MU-LLaMA | Music Understanding Large Language Model | 2023 | Music understanding |
Speech-Centric LALMs and LLM-ASR
This category contains speech-conditioned generative language models whose primary output is text. Conventional encoder-only ASR systems are excluded.
| Model | Paper / Release | Year | Focus |
|---|---|---|---|
| FireRedASR2S | A Fully Open-Source Industrial-Grade All-in-One Speech Recognition System | 2026 | Multilingual ASR |
| Qwen3-ASR | Qwen3-ASR Technical Report | 2026 | Multilingual and multidialect ASR |
| VibeVoice-ASR | VibeVoice-ASR Technical Report | 2026 | Long-form ASR, diarization, and timestamps |
| GLM-ASR-Nano | GLM-ASR | 2025 | LLM-based ASR |
| Fun-ASR | Fun-ASR: A Large Language Model Based Speech Recognition System | 2025 | Multilingual speech-to-text |
| FireRedASR | Open-Source Industrial-Grade Speech Recognition Models from Encoder-Decoder to LLM Integration | 2025 | ASR and LLM integration |
| Seed-ASR | Understanding Diverse Speech and Contexts with LLM-based Speech Recognition | 2024 | Context-aware LLM-ASR |
Related Audio and Speech Generation Systems
The following works are closely related but are not included in the strict SpeechLM or LALM lists because they do not provide a unified speech-input/speech-output dialogue model or an audio-conditioned generative text LLM.
| Model / Family | Paper / Release | Scope |
|---|---|---|
| CSM | Conversational Speech Generation Model | Conversational speech generation / TTS |
| FunAudioLLM | Voice Understanding and Generation Foundation Models for Natural Interaction Between Humans and LLMs | SenseVoice and CosyVoice model family |
| UniAudio | An Audio Foundation Model Toward Universal Audio Generation | Universal audio generation |
| Voicebox | Text-Guided Multilingual Universal Speech Generation at Scale | Text-guided speech generation |
SpeechLM Tokenizers
Semantic Tokenizers
| Name | Title | Url |
|---|---|---|
| Whisper | Robust Speech Recognition via Large-Scale Weak Supervision | Link |
| CosyVoice | CosyVoice: A Scalable Multilingual Zero-shot Text-to-speech Synthesizer based on Supervised Semantic Tokens | Link |
| Google USM | Google USM: Scaling Automatic Speech Recognition Beyond 100 Languages | Link |
| WavLM | WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing | Link |
| HuBERT | HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units | Link |
| W2v-bert | W2v-BERT: Combining Contrastive Learning and Masked Language Modeling for Self-Supervised Speech Pre-Training | Link |
| Wav2vec 2.0 | wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations | Link |
Acoustic Tokenizers
| Name | Title | Url |
|---|---|---|
| WavTokenizer | WavTokenizer: an Efficient Acoustic Discrete Codec Tokenizer for Audio Language Modeling | Link |
| SNAC | SNAC: Multi-Scale Neural Audio Codec | Link |
| Encodec | High Fidelity Neural Audio Compression | Link |
| SoundStream | SoundStream: An End-to-End Neural Audio Codec | Link |
Mixed Tokenizers
| Name | Title | Url |
|---|---|---|
| SpeechTokenizer | SpeechTokenizer: Unified Speech Tokenizer for Speech Large Language Models | Link |
| Mimi | Moshi: a speech-text foundation model for real-time dialogue | Link |
Popular Training Datasets
| Dataset | Type | Phase | Hours | Year |
|---|---|---|---|---|
| LibriSpeech | ASR | Pre-Training | 1k | 2015 |
| Multilingual LibriSpeech | ASR | Pre-Training | 50.5k | 2020 |
| LibriLight | ASR | Pre-Training | 60k | 2019 |
| People dataset | ASR | Pre-Training | 30k | 2021 |
| VoxPopuli | ASR | Pre-Training | 1.6k | 2021 |
| Gigaspeech | ASR | Pre-Training | 40k | 2021 |
| Common Voice | ASR | Pre-Training | 2.5k | 2019 |
| VCTK | ASR | Pre-Training | 0.3k | 2017 |
| WenetSpeech | ASR | Pre-Training | 22k | 2022 |
| LibriTTS | TTS | Pre-Training | 0.6k | 2019 |
| CoVoST2 | S2TT | Pre-Training | 2.8k | 2020 |
| CVSS | S2ST | Pre-Training | 1.9k | 2022 |
| VoxCeleb | Speaker Identification | Pre-Training | 0.4k | 2017 |
| VoxCeleb2 | Speaker Identification | Pre-Training | 2.4k | 2018 |
| Spotify Podcasts | Podcast | Pre-Training | 47k | 2020 |
| Fisher | Telephone conversation | Pre-Training | 2k | 2004 |
| SpeechInstruct | Instruction-following | Instruction-Tuning | - | 2023 |
| InstructS2S-200K | Instruction-following | Instruction-Tuning | - | 2024 |
| VoiceAssistant-400K | Instruction-following | Instruction-Tuning | - | 2024 |
Evaluation Benchmarks
| Name | Eval Type | # Tasks | Audio Type | I/O |
|---|---|---|---|---|
| ABX | Representation | 1 | Speech | $A \rightarrow -$ |
| sWUGGY | Linguistic | 1 | Speech | $A \rightarrow -$ |
| sBLIMP | Linguistic | 1 | Speech | $A \rightarrow -$ |
| sStoryCloze | Linguistic | 1 | Speech | $A/T \rightarrow -$ |
| STSP | Paralinguistic | 1 | Speech | $A/T \rightarrow A/T$ |
| MMAU | Downstream | 27 | Speech, Sound, Music | $A \rightarrow T$ |
| Audiobench | Downstream | 8 | Speech, Sound | $A \rightarrow T$ |
| AIR-Bench | Downstream | 20 | Speech, Sound, Music | $A \rightarrow T$ |
| SD-Eval | Downstream | 4 | Speech | $A \rightarrow T$ |
| SUPERB | Downstream | 10 | Speech | $A \rightarrow T$ |
| Dynamic-SUPERB | Downstream | 180 | Speech, Sound, Music | $A \rightarrow T$ |
| SALMON | Downstream | 8 | Speech | $A \rightarrow -$ |
| VoiceBench | Downstream | 8 | Speech | $A \rightarrow A$ |
| VoxEval | Downstream | 56 | Speech | $A \rightarrow A$ |
Citation
@article{cui2024recent,
  title={Recent advances in speech language models: A survey},
  author={Cui, Wenqian and Yu, Dianzhi and Jiao, Xiaoqi and Meng, Ziqiao and Zhang, Guangyan and Wang, Qichao and Guo, Yiwen and King, Irwin},
  journal={arXiv preprint arXiv:2410.03751},
  year={2024}
}
Similar repos
Contributors
8 commits