
Visual catalog of neural audio and speech codec architectures, audio VAEs and continuous autoencoders, with code, checkpoints, figures and license evidence.
Python
5
3 commits
updated Sep 13, 2026
README
Awesome Codec Architectures 
A visual catalog of neural audio and speech codecs, audio VAEs and continuous autoencoders: architecture figures, concise descriptions, code, checkpoints and separately checked code/weight licenses.
59 codec entries + 33 audio VAEs / continuous codecs · 68 research entries · Reviewed 2026-09-13
Model list · Architecture gallery · Audio VAEs · Comparison · Timeline · Research · Tools and benchmarks · Scope
Licenses across released entries: 49 open · 25 custom/restricted · 18 unclear. Each card links the code and checkpoint terms.
| Collection | Entries |
|---|---|
| General audio codecs | 9 |
| Speech codecs | 18 |
| Semantic and acoustic codecs | 26 |
| Disentangled codecs | 4 |
| Music codecs | 2 |
| Audio VAEs and continuous codecs | 33 |
Models
Families group routine sample-rate and bitrate variants. The research list also records foundational and unreleased work. Coverage is a dated survey, and contributions are welcome.
Alphabetical index · 92 released entries
| Model | Collection | Sample rate | License |
|---|---|---|---|
| ACE-Step 1.5 VAE | Audio VAEs and continuous codecs | 48 kHz stereo | Open license |
| ACE-Step music DCAE | Audio VAEs and continuous codecs | 44.1 kHz (released vocoder config) | Open license |
| AudioDec | Speech codecs | 48 kHz (also 24 kHz) | Custom / restricted |
| AudioLDM / AudioLDM 2 VAE | Audio VAEs and continuous codecs | 16 kHz mono | Custom / restricted |
| Auffusion spectrogram VAE | Audio VAEs and continuous codecs | 16 kHz | Custom / restricted |
| AuK BigVGANFlowVAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| BiCodec | Disentangled codecs | 16 kHz | Custom / restricted |
| BigCodec | Speech codecs | 16 kHz | Open license |
| CodecSlime | Speech codecs | 16 kHz mono | Open license |
| CoDiCodec | General audio codecs | 44.1 / 48 kHz stereo | Custom / restricted |
| DACVAE (Movie Gen) | Audio VAEs and continuous codecs | 48 kHz mono (Movie Gen paper) | License unclear |
| Descript Audio Codec (DAC) | General audio codecs | 44.1 kHz (also 16 / 24 kHz) | Open license |
| Descript Audio VAE (community) | Audio VAEs and continuous codecs | 44.1 kHz | License unclear |
| DiffRhythm VAE | Audio VAEs and continuous codecs | 44.1 kHz stereo | Custom / restricted |
| dots.tts AudioVAE | Audio VAEs and continuous codecs | 48 kHz mono | Open license |
| DualCodec | Semantic and acoustic codecs | 24 kHz | License unclear |
| EnCodec | General audio codecs | 24 kHz mono; 48 kHz stereo | License unclear |
| EzAudio waveform VAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| FACodec | Disentangled codecs | 16 kHz | Open license |
| Firefly codec (Fish Speech 1.5) | Speech codecs | 44.1 kHz | Custom / restricted |
| FireRedTTS-2 speech tokenizer | Semantic and acoustic codecs | 16 kHz | Open license |
| Fish Audio codec (OpenAudio S1 / S2) | Speech codecs | 44.1 kHz | Custom / restricted |
| FlexiCodec | Semantic and acoustic codecs | 16 kHz | License unclear |
| FlowDec | General audio codecs | 48 kHz | Custom / restricted |
| FocalCodec | Speech codecs | 16 kHz | Open license |
| FocalCodec-Stream | Speech codecs | 16 kHz input → 24 kHz output | Open license |
| FunCodec | Speech codecs | 16 kHz | Open license |
| HARP | General audio codecs | Not specified | Open license |
| HeartCodec | Music codecs | 48 kHz stereo | Open license |
| HiFi-Codec | Speech codecs | 16 / 24 kHz | License unclear |
| Higgs Audio Tokenizer v2 | Semantic and acoustic codecs | 24 kHz | Custom / restricted |
| HILCodec | General audio codecs | 24 kHz | License unclear |
| HoliTok | Audio VAEs and continuous codecs | 48 kHz mono | Open license |
| HunyuanVideo-Foley audio VAE | Audio VAEs and continuous codecs | 48 kHz | Custom / restricted |
| JHCodec | Semantic and acoustic codecs | 16 kHz mono | Open license |
| KVAE-Audio | Audio VAEs and continuous codecs | 48 kHz | Open license |
| L3AC / SQCodec | Speech codecs | 16 kHz | License unclear |
| LILAC | Speech codecs | 24 kHz mono | Open license |
| LLM-Codec (LM objectives) | Semantic and acoustic codecs | Not specified | License unclear |
| LLM-Codec (UniAudio 1.5) | Semantic and acoustic codecs | Not specified | License unclear |
| LongCat Wav-VAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| LongCat-Audio-Codec | Semantic and acoustic codecs | 16 kHz input; 16 / 24 kHz output | Open license |
| Low Frame-rate Speech Codec (LFSC) | Speech codecs | 22.05 kHz | Custom / restricted |
| LTX-2 audio VAE | Audio VAEs and continuous codecs | 16 kHz analysis → 24 kHz stereo output | Custom / restricted |
| Lyra v2 (SoundStream-based) | Speech codecs | 16 kHz | License unclear |
| MagiCodec | Semantic and acoustic codecs | 16 kHz | Open license |
| Mimi | Semantic and acoustic codecs | 24 kHz mono | Open license |
| MiMo-Audio-Tokenizer | Semantic and acoustic codecs | 24 kHz | Open license |
| Ming-omni-tts continuous tokenizer | Audio VAEs and continuous codecs | 44.1 kHz | Open license |
| MingTok-Audio | Audio VAEs and continuous codecs | 16 kHz | Open license |
| MiniMax H3 AudioVAE | Audio VAEs and continuous codecs | 32 kHz mono; stereo channels processed separately | Custom / restricted |
| MMAudio VAE (16 / 44.1 kHz) | Audio VAEs and continuous codecs | 16 / 44.1 kHz | Custom / restricted |
| MOSS-Audio-Tokenizer | Semantic and acoustic codecs | 24 kHz mono | Open license |
| MOSS-Audio-Tokenizer Nano | Semantic and acoustic codecs | 48 kHz stereo | Open license |
| MOSS-Audio-Tokenizer v2 | Semantic and acoustic codecs | 48 kHz stereo | Open license |
| MuCodec | Music codecs | 48 kHz stereo | Custom / restricted |
| Music2Latent | Audio VAEs and continuous codecs | 44.1 kHz (also 48 kHz) | Custom / restricted |
| Musika autoencoder | Audio VAEs and continuous codecs | 44.1 kHz (released model card) | Open license |
| NanoCodec | Speech codecs | 22.05 kHz | Custom / restricted |
| NeuCodec | Semantic and acoustic codecs | 16 kHz input → 24 kHz output | Open license |
| Omni2Sound OOB/Wav VAE | Audio VAEs and continuous codecs | 16 kHz | Custom / restricted |
| OmniVAE audio-only | Audio VAEs and continuous codecs | 48 kHz | Open license |
| PAST | Semantic and acoustic codecs | Not specified | License unclear |
| Qwen3-TTS-Tokenizer-12Hz | Semantic and acoustic codecs | 24 kHz | Open license |
| RAVE (v1 / v2) | Audio VAEs and continuous codecs | Checkpoint-specific; not independently established | Custom / restricted |
| SAC | Semantic and acoustic codecs | 16 kHz | Open license |
| SAME (S / L) | Audio VAEs and continuous codecs | 44.1 kHz stereo | Custom / restricted |
| Semantic-VAE | Audio VAEs and continuous codecs | 16 kHz mono | License unclear |
| SemantiCodec | Semantic and acoustic codecs | 16 kHz | Open license |
| SimWhisper-Codec | Semantic and acoustic codecs | Not specified | Open license |
| SNAC | General audio codecs | 24 kHz speech; 32 / 44.1 kHz audio | Open license |
| SoCodec | Semantic and acoustic codecs | 16 kHz | Open license |
| SoviaMate-Codec | Disentangled codecs | Not specified | Custom / restricted |
| Speech DAC (IBM) | Speech codecs | 24 kHz | Open license |
| SpeechTokenizer | Semantic and acoustic codecs | 16 kHz mono | License unclear |
| Spine | Speech codecs | 24 kHz mono | Open license |
| Stable Audio Open autoencoder (Oobleck) | Audio VAEs and continuous codecs | 44.1 kHz stereo | Custom / restricted |
| Stable Codec | Speech codecs | 16 kHz | Custom / restricted |
| STFT-VAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| TaDiCodec | Semantic and acoustic codecs | 24 kHz | Open license |
| TiCodec | Disentangled codecs | Not specified | License unclear |
| U-Codec | Speech codecs | 16 kHz | License unclear |
| UniCodec (domain-adaptive) | General audio codecs | Not specified | License unclear |
| VibeVoice acoustic tokenizer | Audio VAEs and continuous codecs | 24 kHz | Open license |
| VoxCPM AudioVAE (1.0 / 1.5) | Audio VAEs and continuous codecs | 44.1 kHz (1.5); 16 kHz (1.0) | Open license |
| VoxCPM2 AudioVAE V2 | Audio VAEs and continuous codecs | 16 kHz input → 48 kHz output | Open license |
| WavTokenizer | General audio codecs | 24 kHz | Open license |
| X-Codec | Semantic and acoustic codecs | 16 kHz | License unclear |
| X-Codec 2 | Semantic and acoustic codecs | 16 kHz | Custom / restricted |
| XY-Tokenizer | Semantic and acoustic codecs | 16 kHz | Open license |
| εar-VAE | Audio VAEs and continuous codecs | 44.1 kHz stereo; 48 kHz variant | Open license |
| εar-VAE2 | Audio VAEs and continuous codecs | 48 kHz stereo | Open license |
Architecture gallery
Author figures and editorial overviews are labeled individually. See the figure credits. Technical numbers refer to the documented configuration, not every family variant.
ACE-Step 1.5 VAE
Encodes stereo music directly into continuous waveform latents for ACE-Step 1.5.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
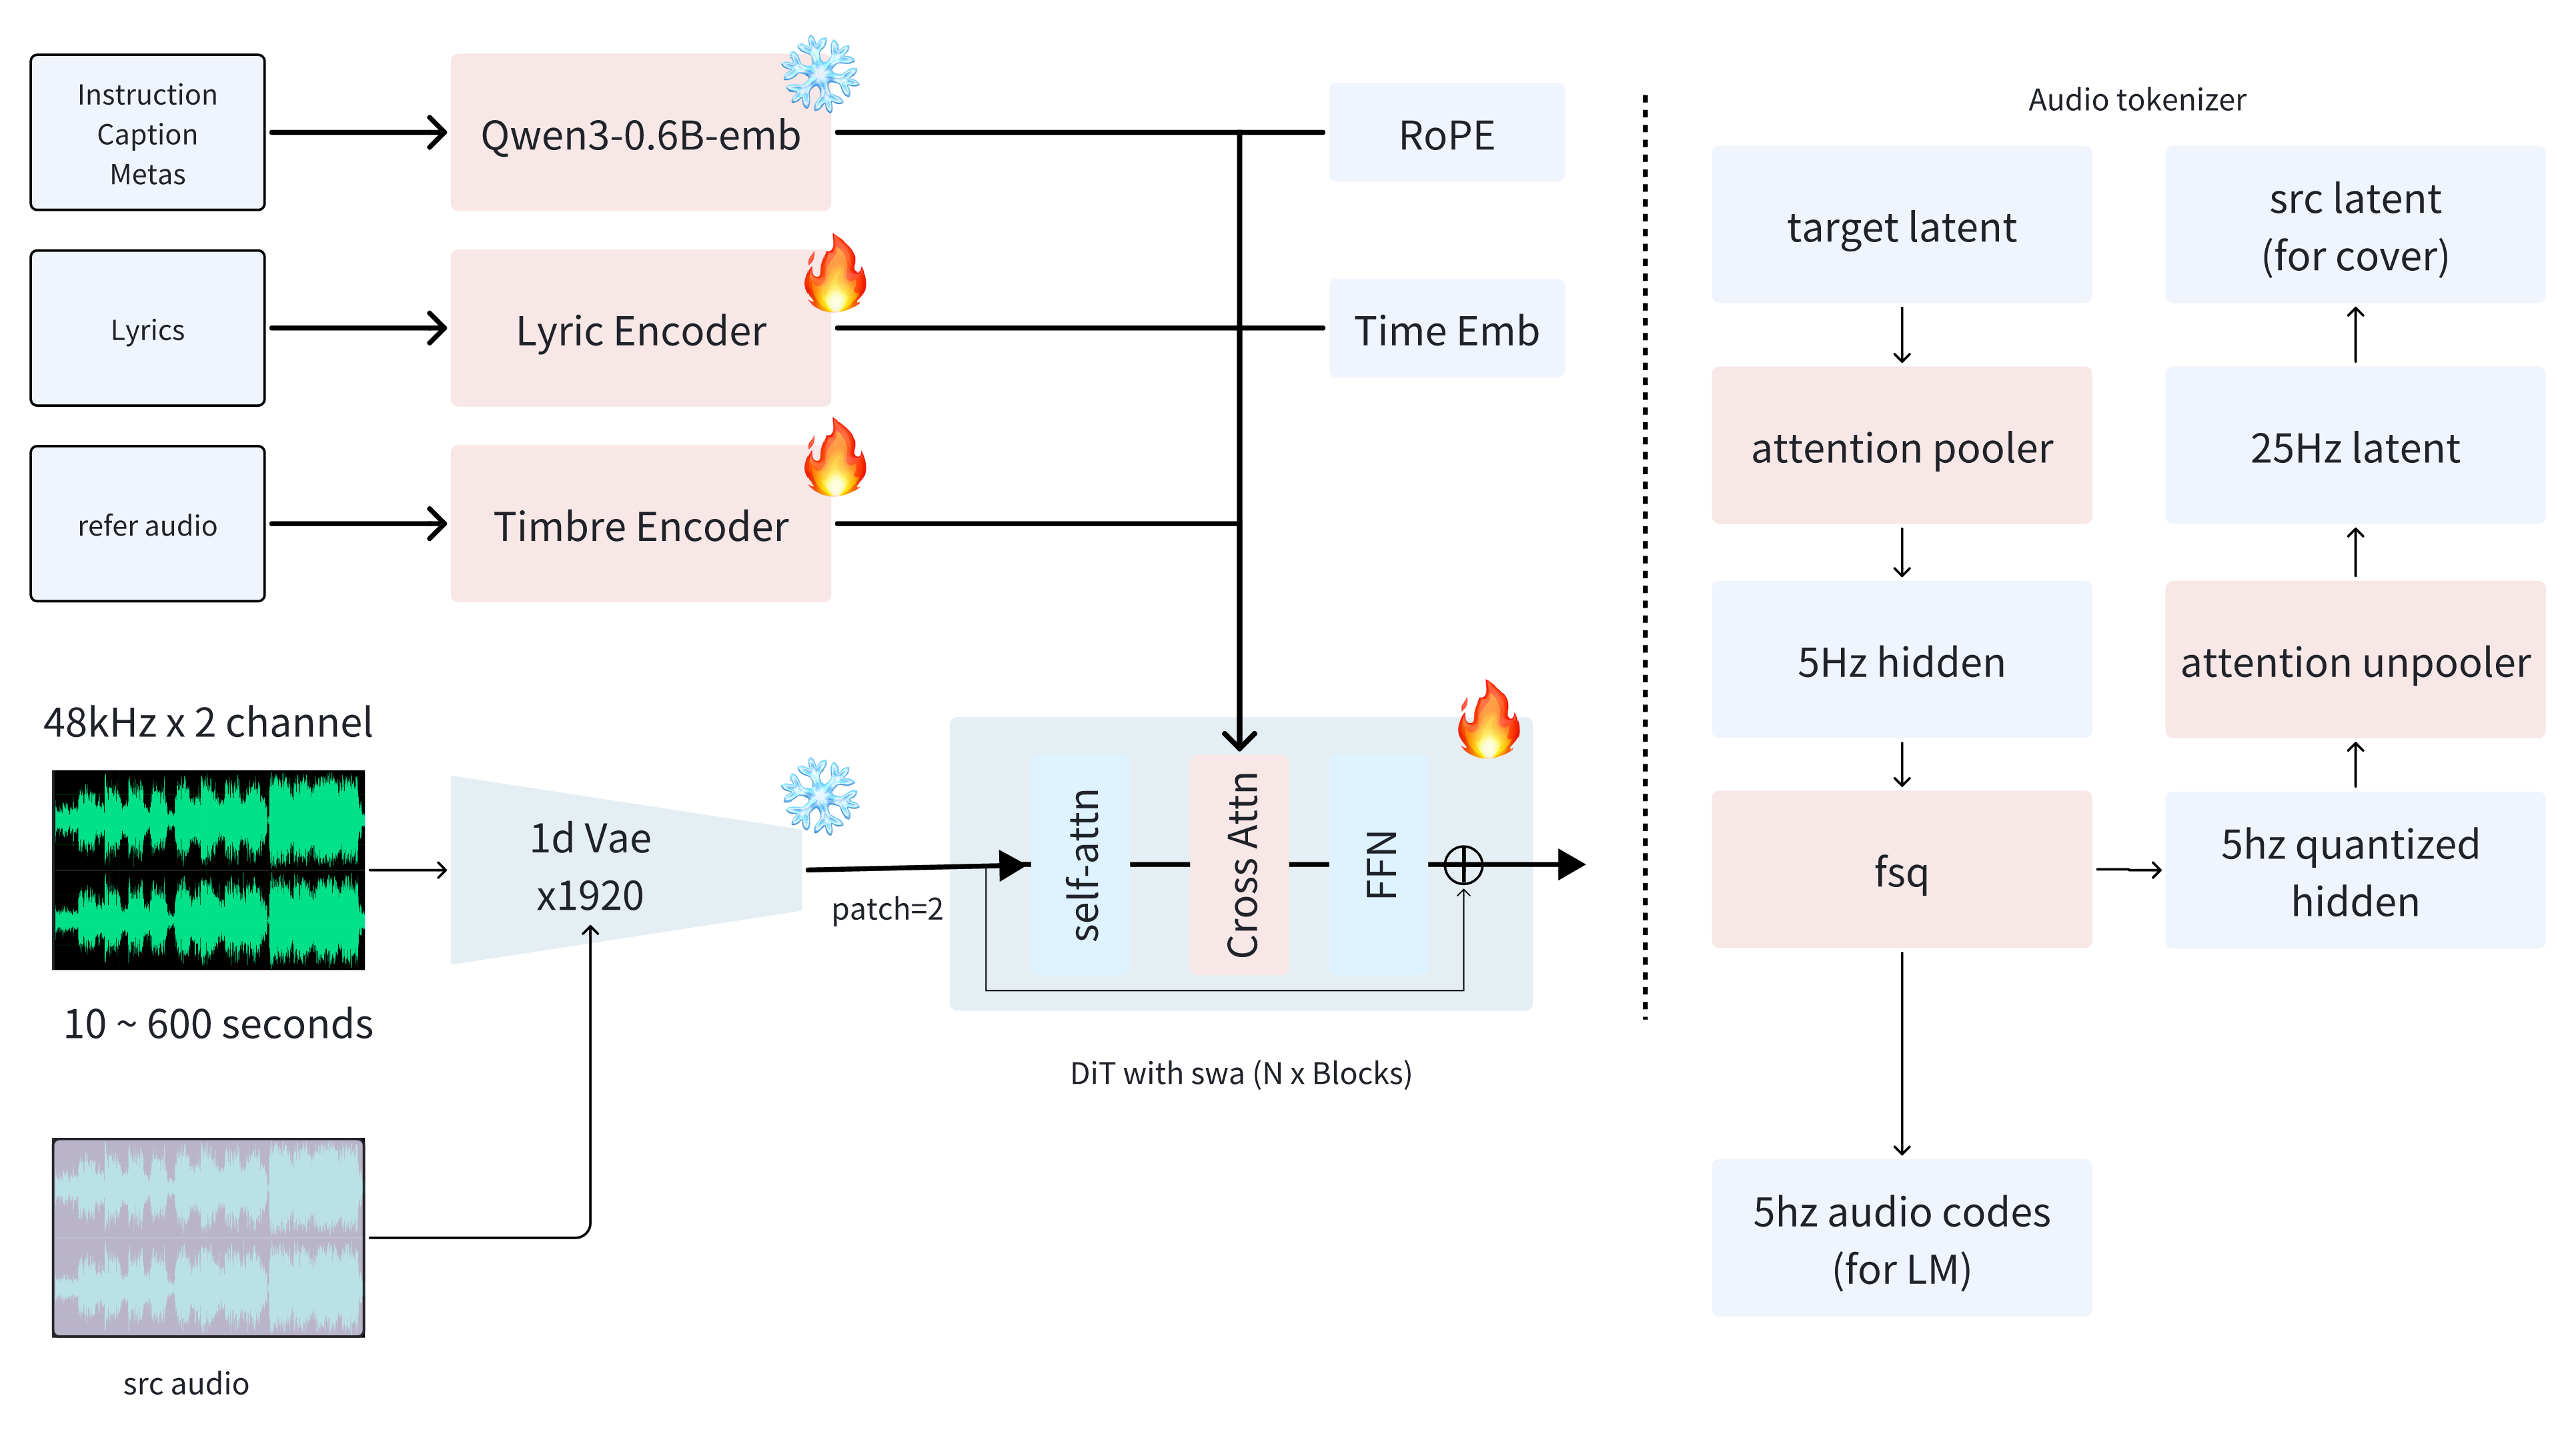
Figure 2 — parent ACE-Step 1.5 framework with VAE · Source
ACE-Step music DCAE
Compresses music spectrograms into continuous latents and reconstructs audio through a matching vocoder.
Paper · Code · Weights · Details
Audio: 44.1 kHz (released vocoder config) · Frame rate: ~10.77 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
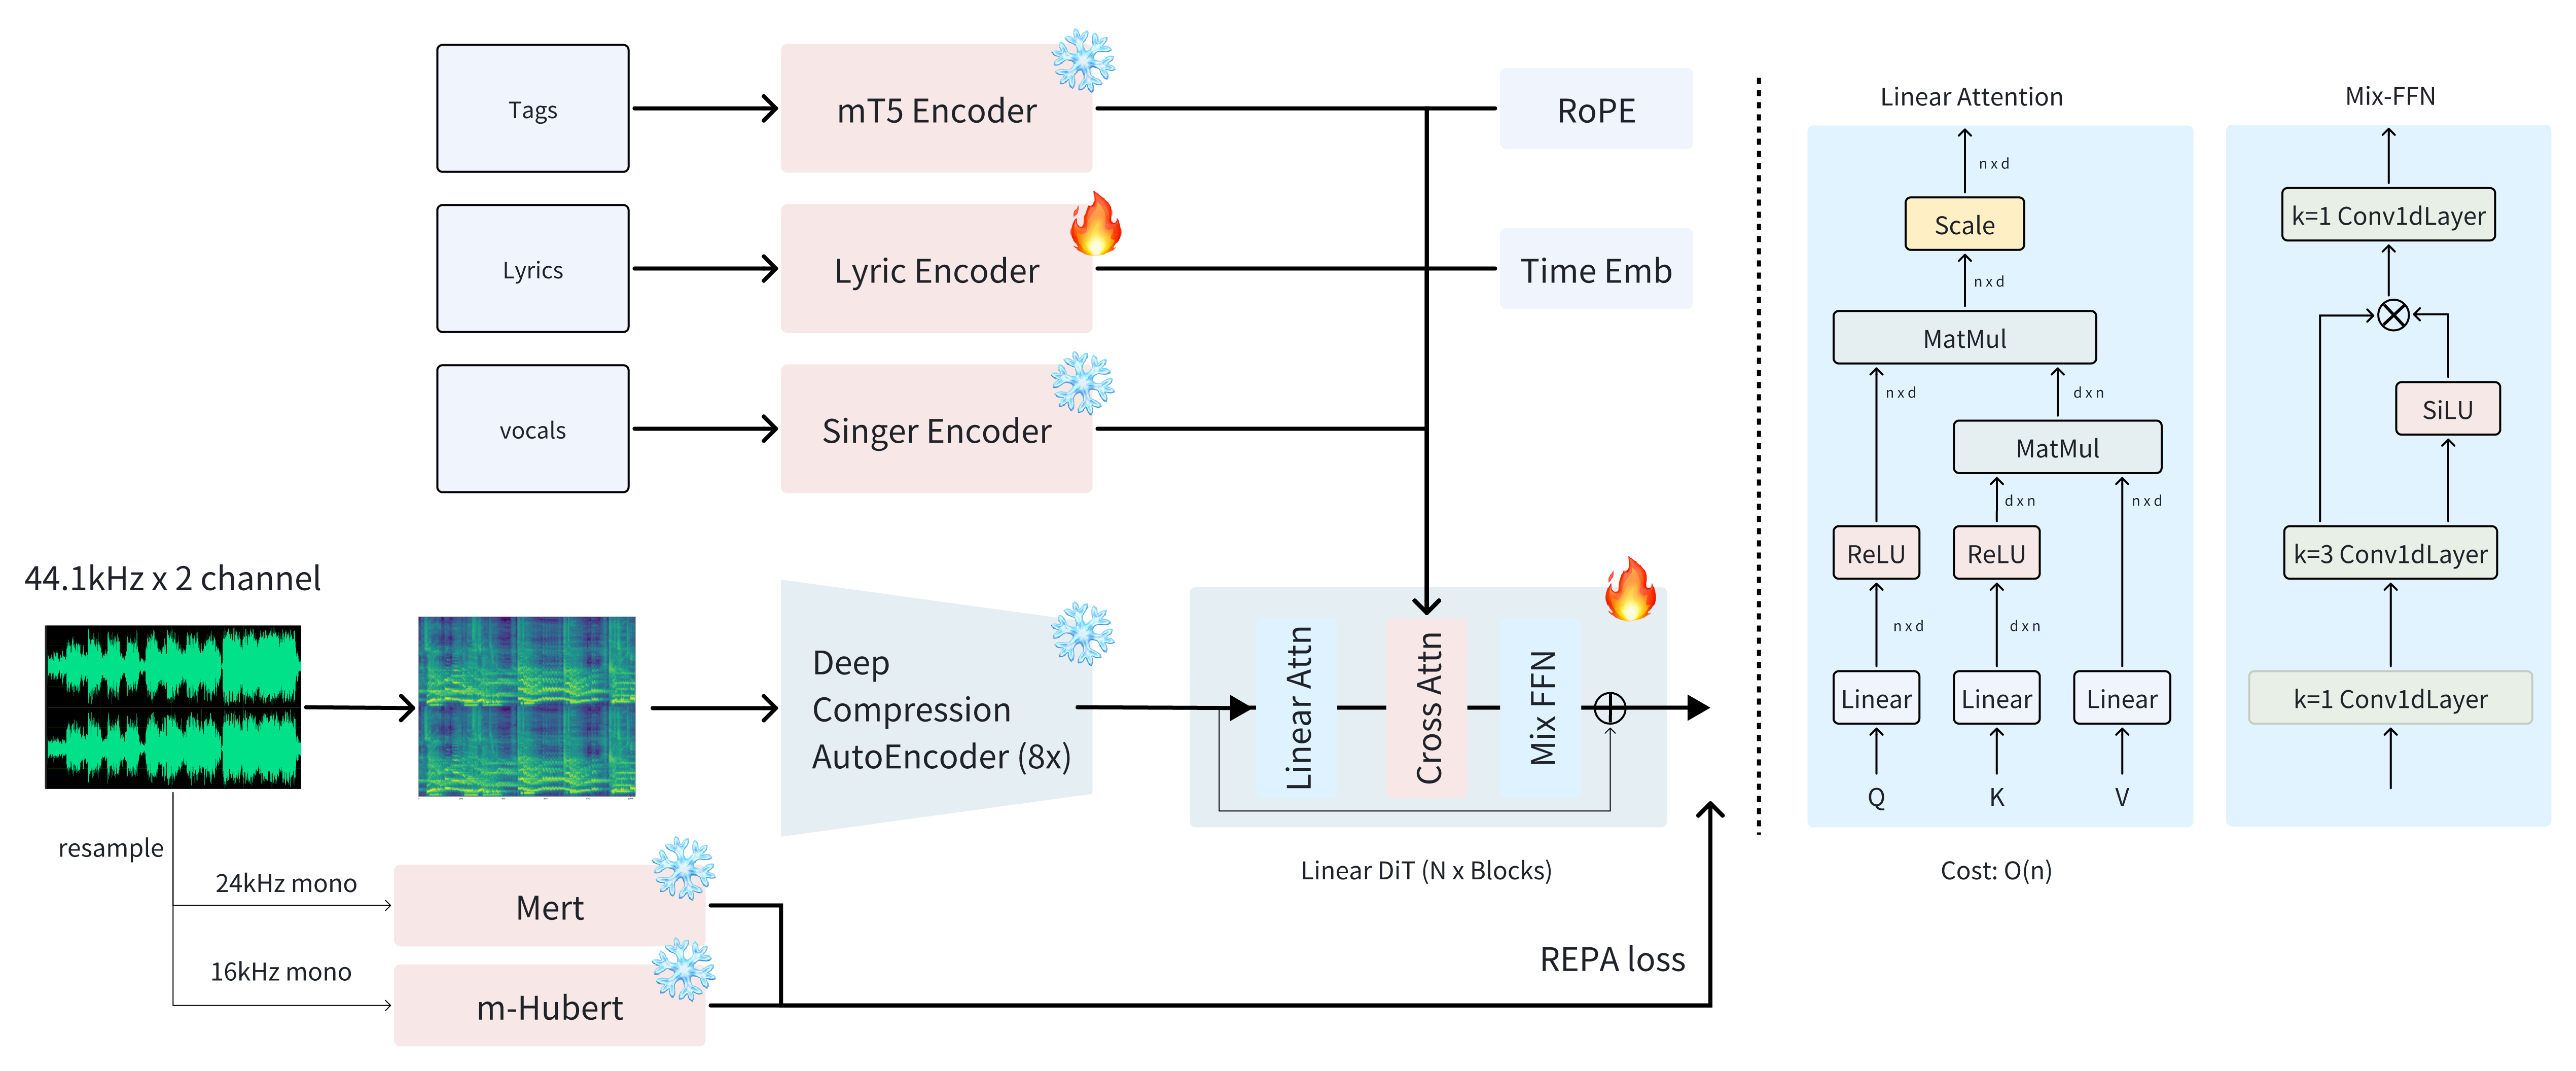
Figure 1 — parent ACE-Step system with DCAE and vocoder · Source
AudioDec
Reconstructs high-sample-rate speech with a streamable two-stage codec.
Paper · Code · Weights · Details
Audio: 48 kHz (also 24 kHz) · Frame rate: 160 (48 kHz / hop300) · Nominal bitrate: 12.8 kbps (selected 48 kHz model)
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
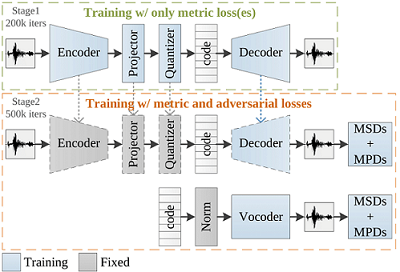
Author architecture (repository) · Source
AudioLDM / AudioLDM 2 VAE
Compresses mel spectrograms with a variational autoencoder and reconstructs audio using HiFi-GAN.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-SA-4.0 · weights CC-BY-NC-SA-4.0 — The linked noncommercial or custom terms apply to this release.
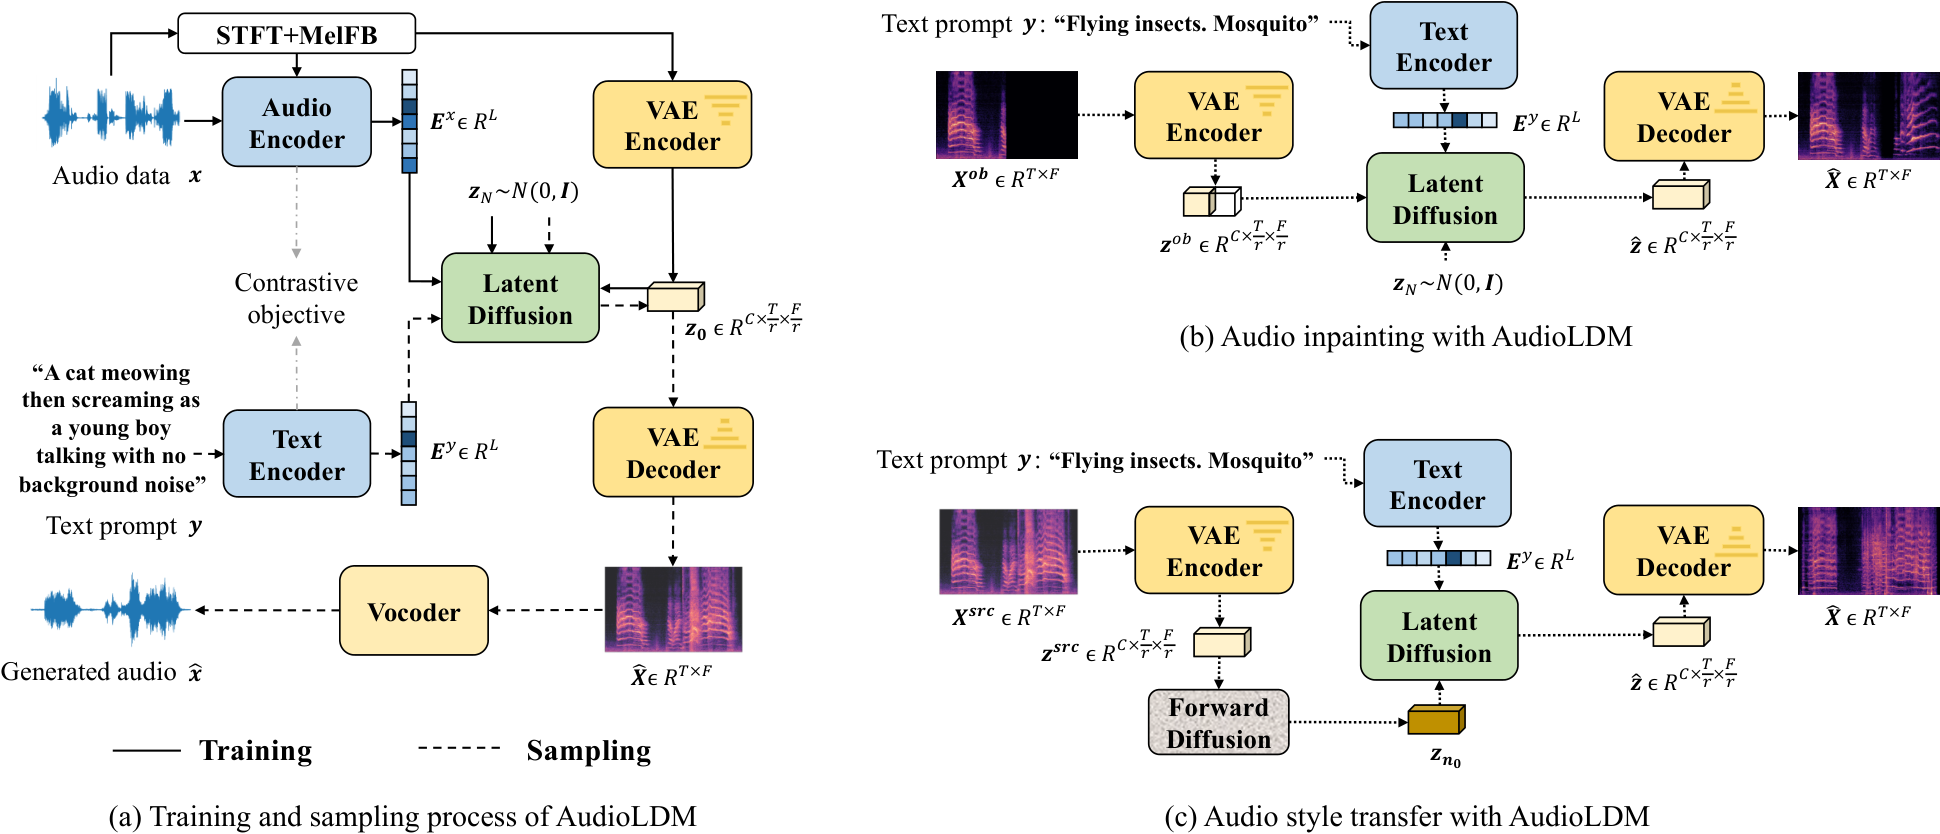
Figure 1 — parent AudioLDM system with VAE and vocoder · Source
Auffusion spectrogram VAE
Uses an image-style variational autoencoder on audio spectrograms with a released audio reconstruction path.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 (paper configuration) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-SA-4.0 · weights CC-BY-NC-SA-4.0 — The linked noncommercial or custom terms apply to this release.
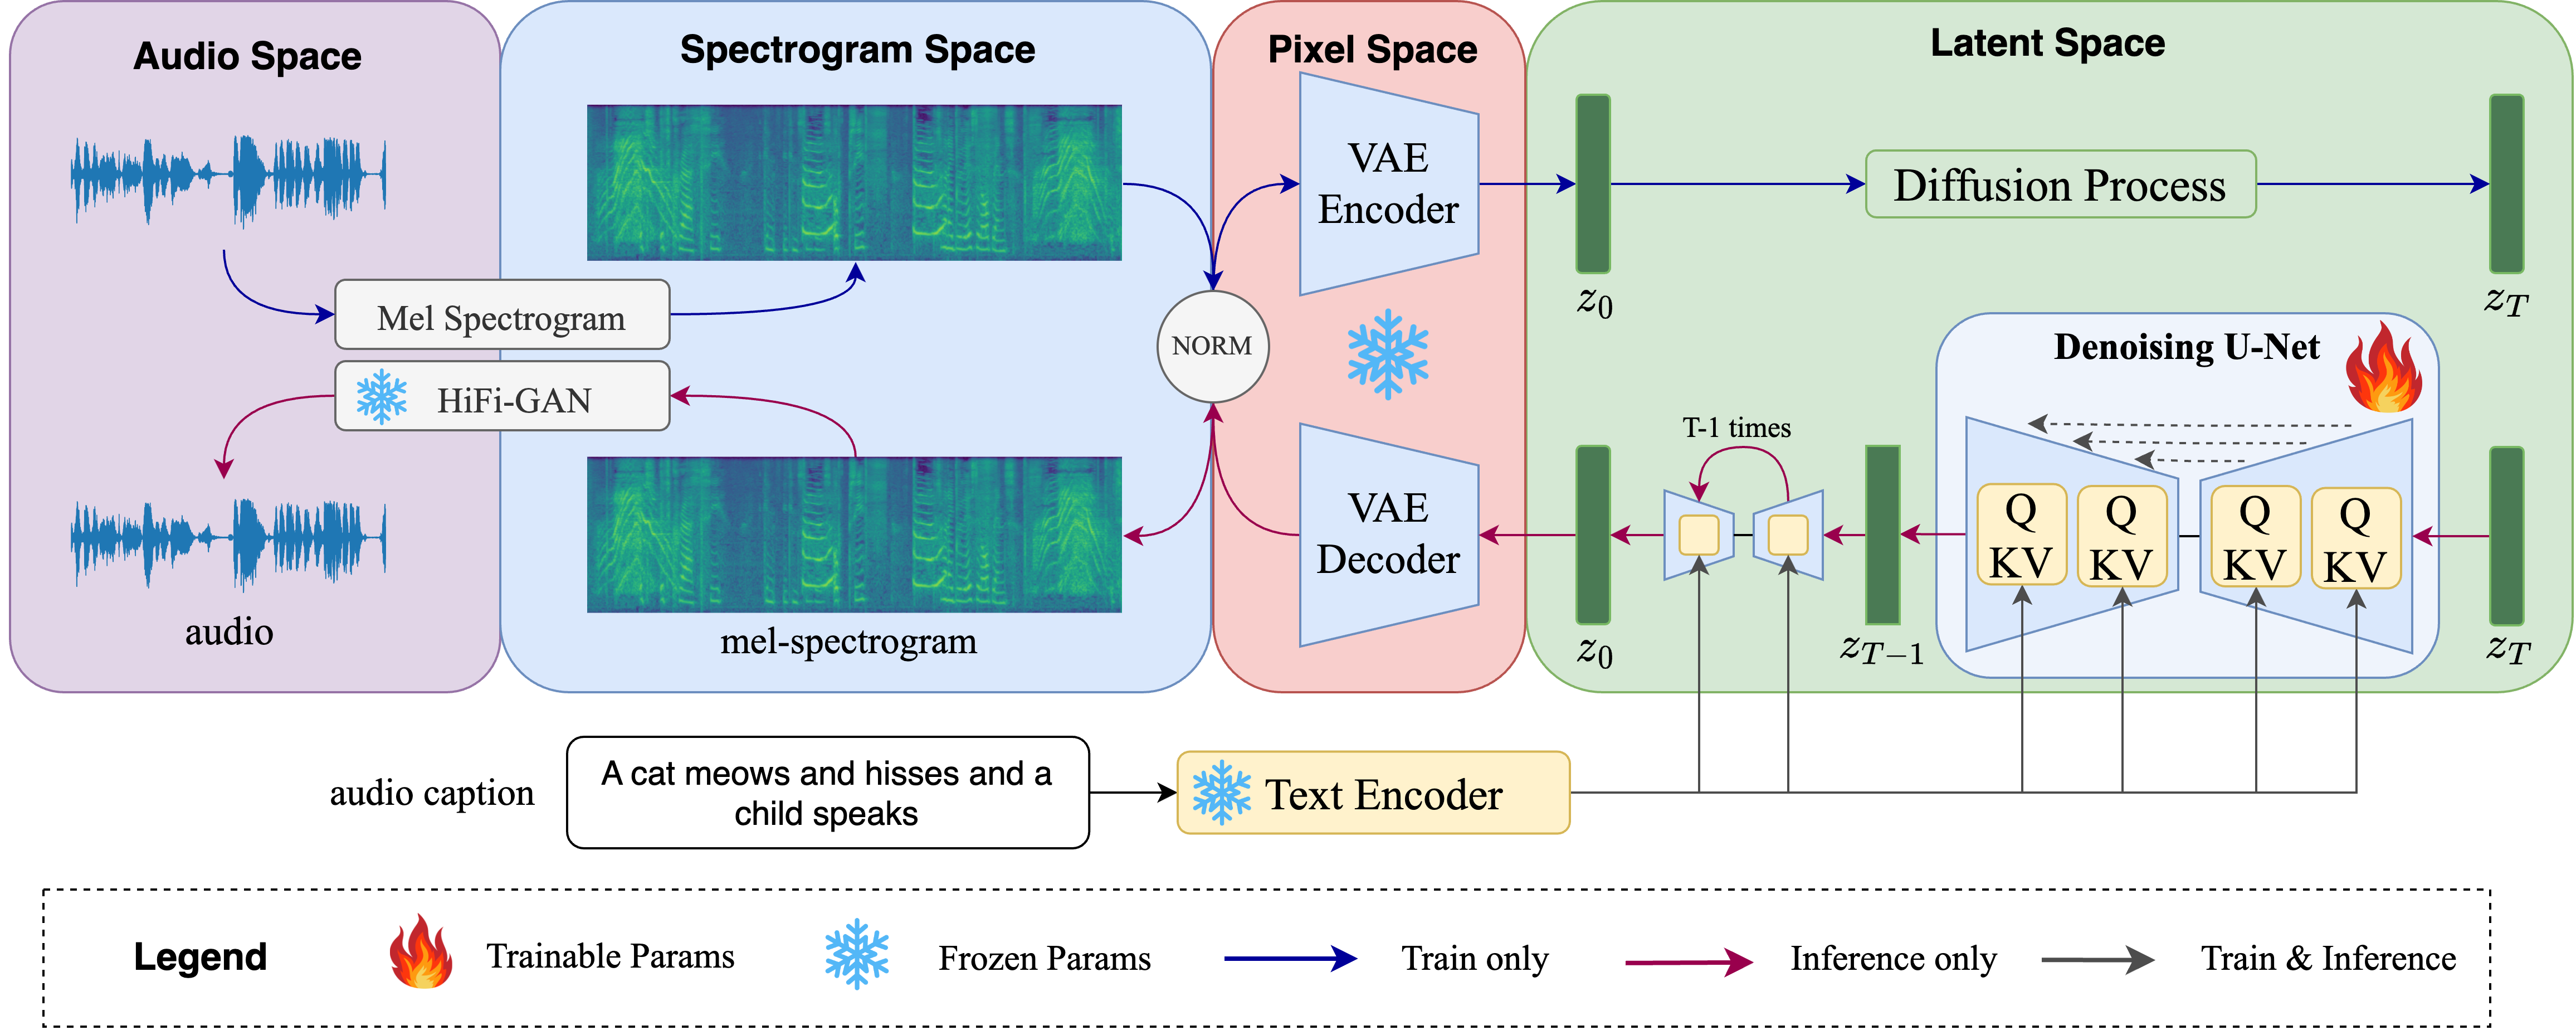
Figure 1 — spectrogram, VAE and waveform reconstruction path · Source
AuK BigVGANFlowVAE
Encodes speech into continuous variational latents for generation and audio editing.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
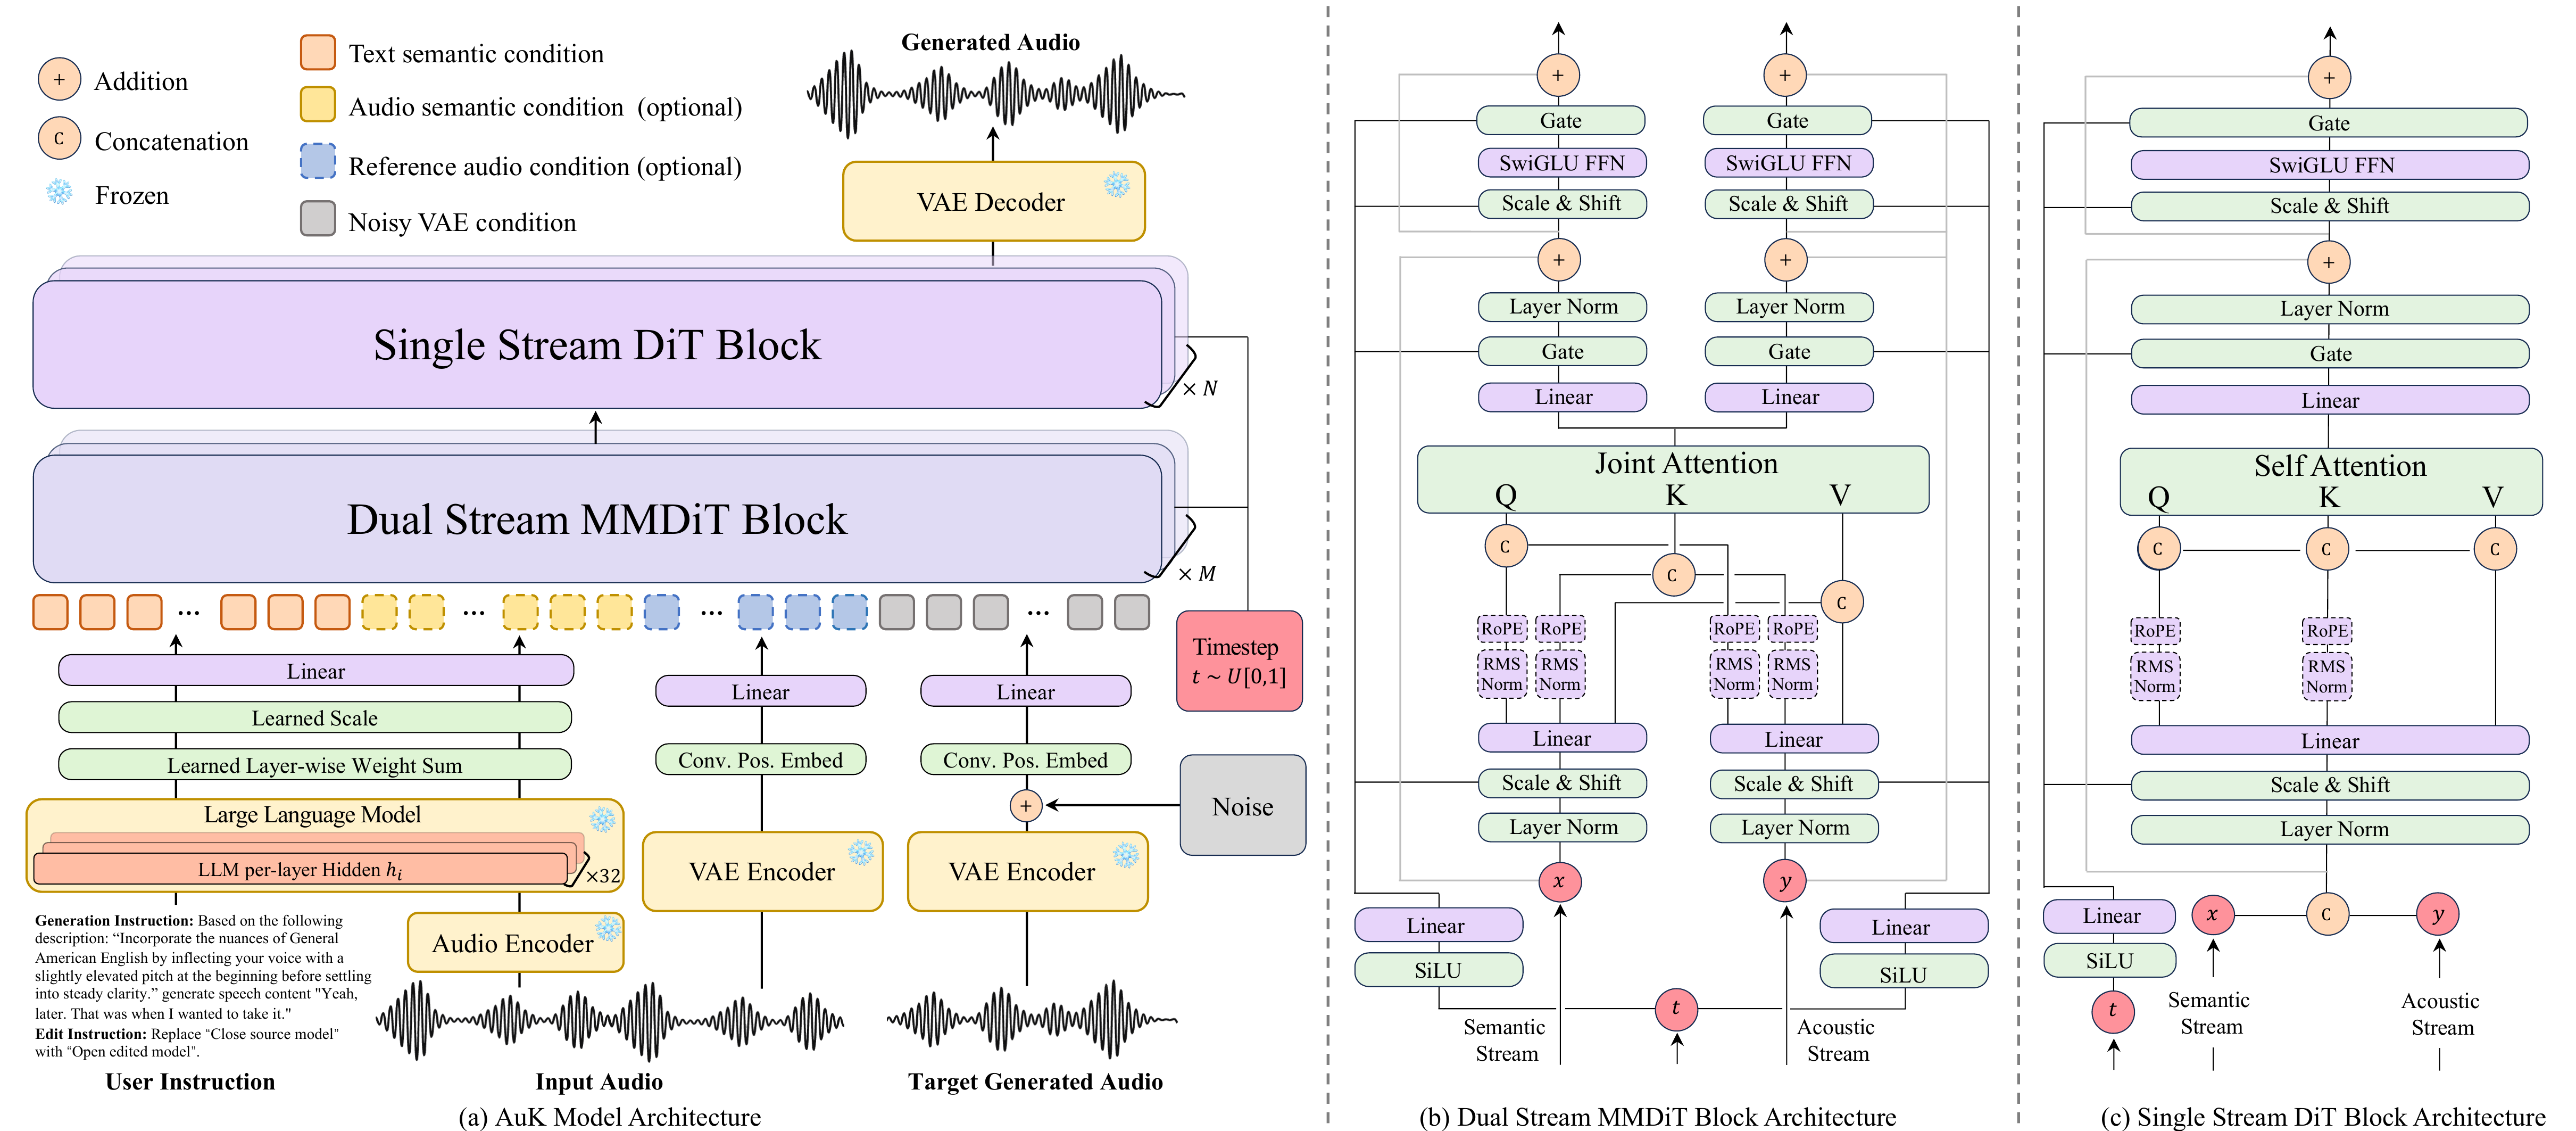
Parent AuK architecture with audio VAE · Source
BiCodec
Reconstructs speech from separate global speaker and time-varying semantic tokens.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 semantic frames/s · Nominal bitrate: 0.65 kbps semantic stream + global tokens
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-SA-4.0 — The linked custom or noncommercial terms apply to this release.
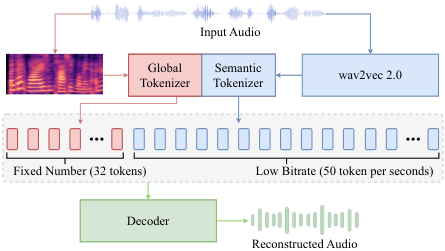
Figure 2 · Source
BigCodec
Scales a single-codebook speech codec to improve reconstruction at low bitrates.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 80 · Nominal bitrate: 1.04 kbps
Open license: code MIT · weights CC-BY-SA-4.0
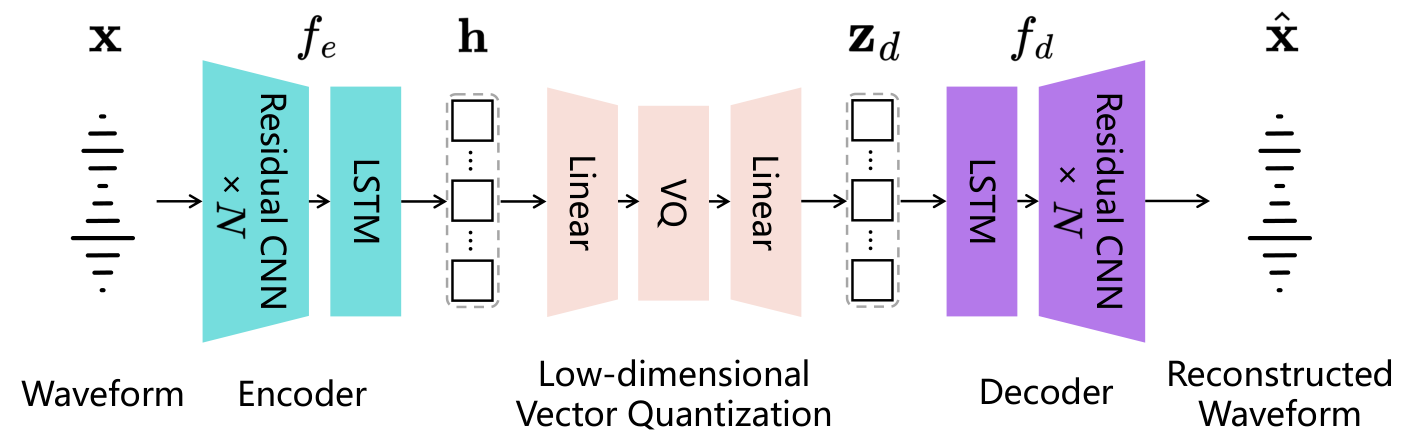
Fig. 1 · Source
CodecSlime
Removes redundant speech frames to support a controllable token rate.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 36–80 · Nominal bitrate: Not specified
Open license: code MIT · weights CC-BY-4.0
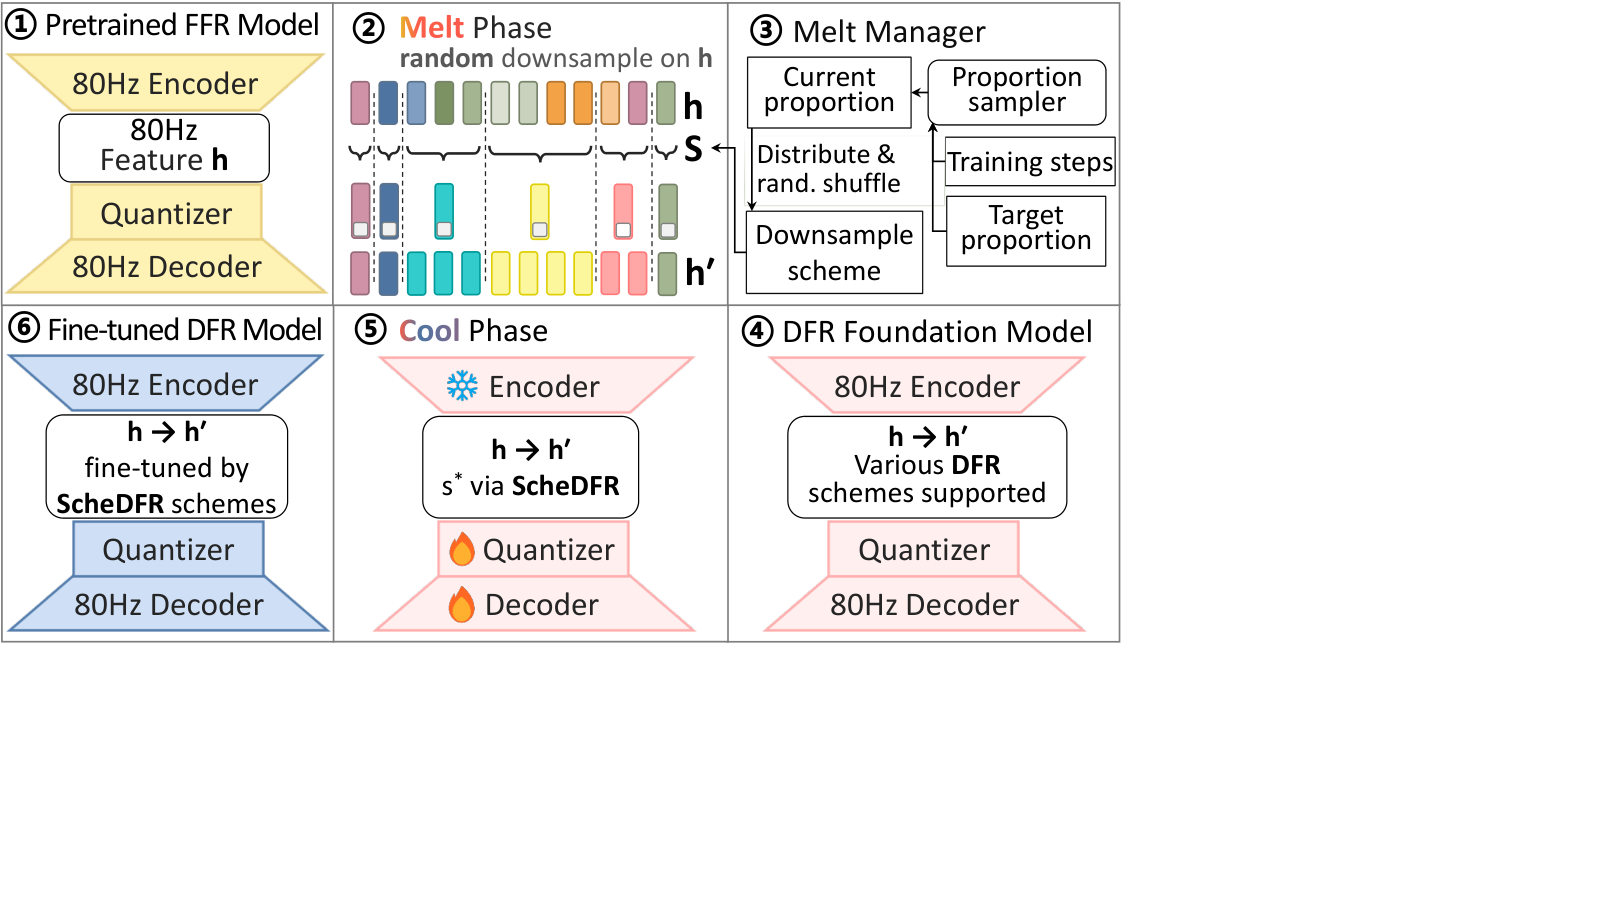
Figure 2 · Source
CoDiCodec
Offers continuous latents or discrete tokens through a shared stereo audio codec.
Paper · Code · Weights · Details
Audio: 44.1 / 48 kHz stereo · Frame rate: ~11 (continuous latent sequence) · Nominal bitrate: 2.38 kbps (discrete mode)
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
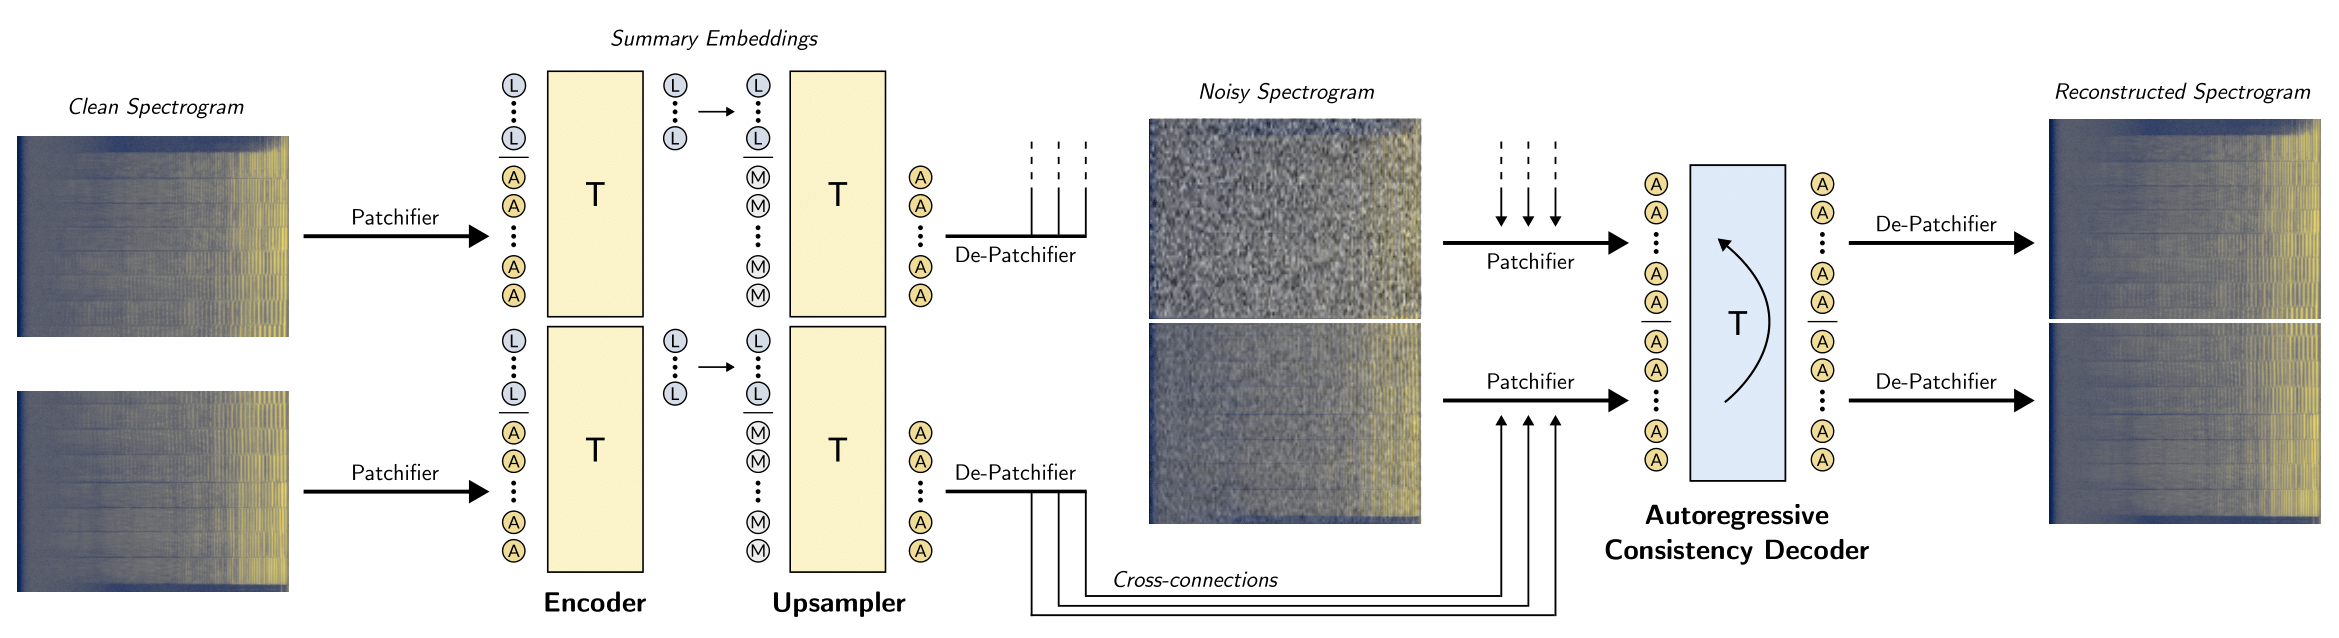
Author architecture (repository) · Source
DACVAE (Movie Gen)
Replaces DAC residual vector quantization with a continuous variational bottleneck for general-audio reconstruction.
Paper · Code · Weights · Details
Audio: 48 kHz mono (Movie Gen paper) · Frame rate: 25 (Movie Gen paper) · Nominal bitrate: Not applicable: continuous latents
License unclear: code Apache-2.0 · weights Conflicting: Apache-2.0 / SAM License — The GitHub code is Apache-2.0. Checkpoint-card metadata says Apache-2.0, but its license paragraph says SAM License and references a LICENSE file absent from the inspected checkpoint tree; the weight terms need clarification.
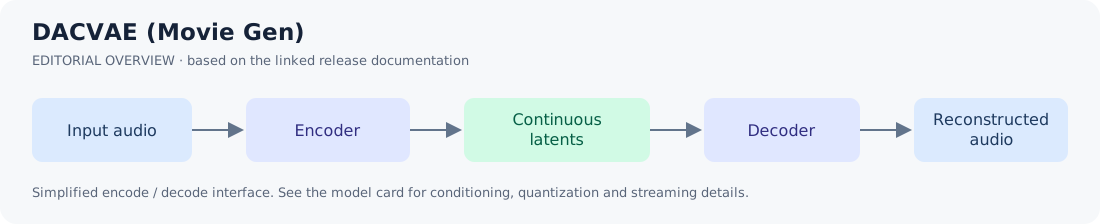
Editorial overview · Source
Descript Audio Codec (DAC)
Encodes speech, music and environmental audio into residual discrete codes.
Paper · Code · Weights · Details
Audio: 44.1 kHz (also 16 / 24 kHz) · Frame rate: ~86 (44.1 kHz) · Nominal bitrate: ~8 kbps (44.1 kHz)
Open license: code MIT · weights MIT
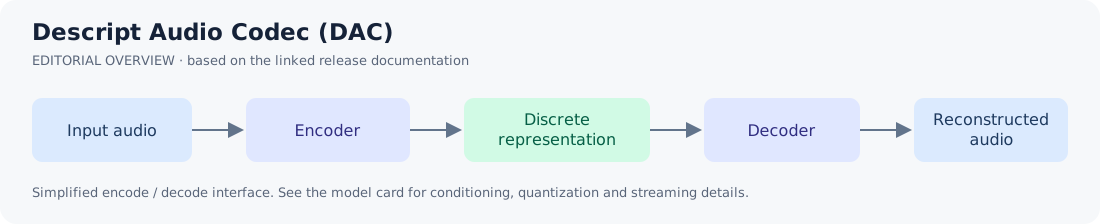
Editorial overview · Source
Descript Audio VAE (community)
Provides a community DAC-to-VAE adaptation for continuous audio latents.
Audio: 44.1 kHz · Frame rate: 87 (author release label) · Nominal bitrate: Not applicable: continuous latents
License unclear: code MIT · weights Not stated — The code is MIT. The checkpoint has no model-card license; generic MIT weight wording inherited in the DAC README is not treated as unambiguous evidence for the modified VAE checkpoint.
Editorial overview · Source
DiffRhythm VAE
Compresses stereo songs into continuous waveform latents for DiffRhythm.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo · Frame rate: ~21.53 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code Apache-2.0 · weights Stability AI Community License — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
dots.tts AudioVAE
Encodes and decodes the continuous speech representation used by dots.tts.
Paper · Code · Weights · Details
Audio: 48 kHz mono · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
DualCodec
Combines a semantic first codebook with acoustic residual streams at low frame rates.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 12.5 / 25 · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
EnCodec
Compresses general audio with selectable bandwidths and a separate stereo music variant.
Paper · Code · Weights · Details
Audio: 24 kHz mono; 48 kHz stereo · Frame rate: 75 (24 kHz); 150 (48 kHz) · Nominal bitrate: 1.5–24 kbps (24 kHz); 3–24 kbps (48 kHz)
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
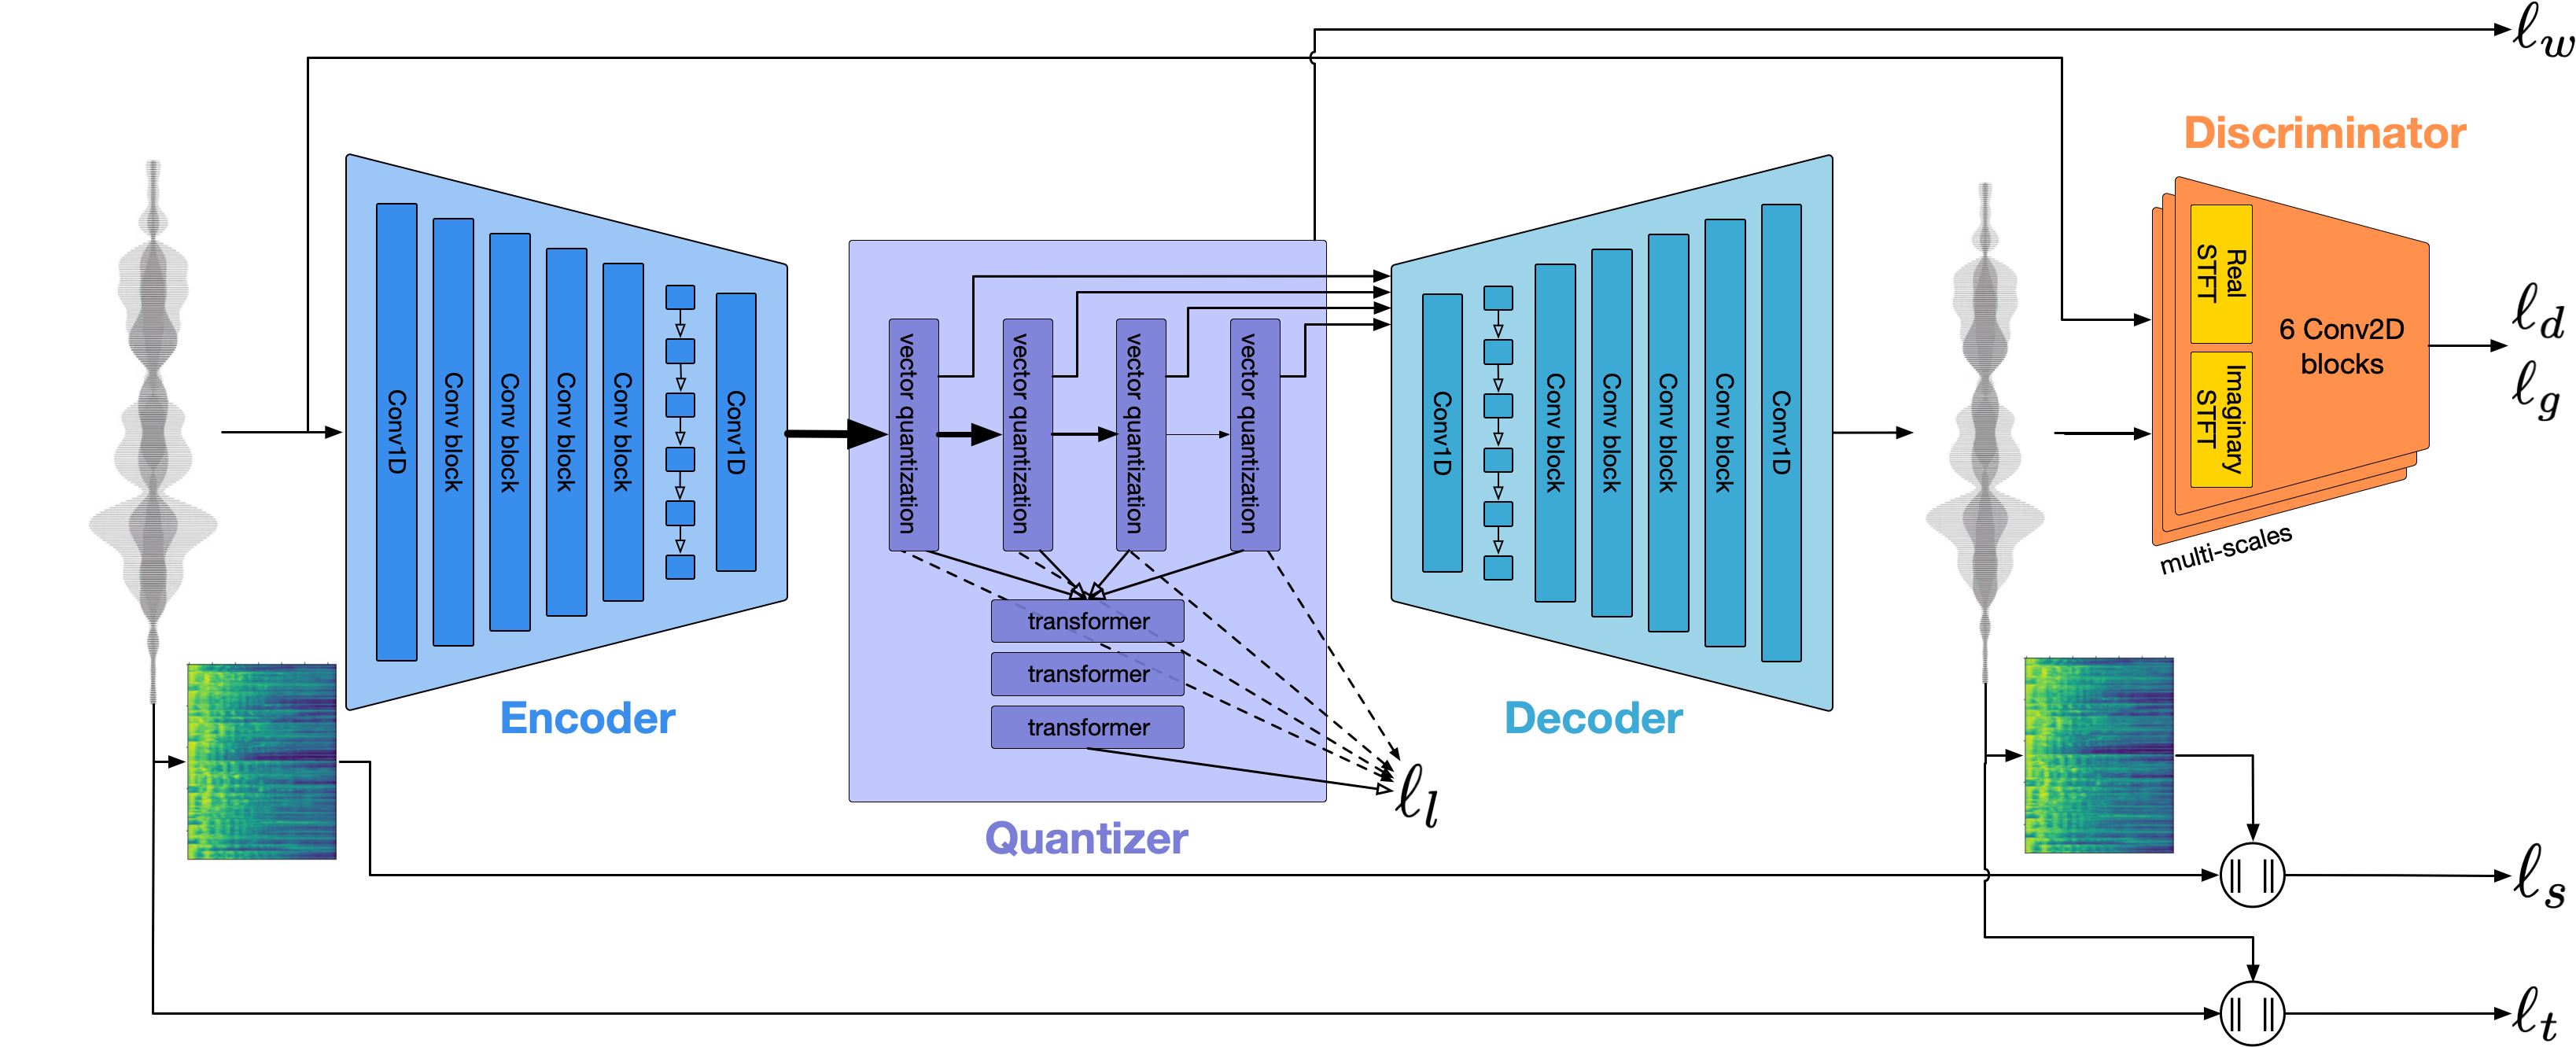
Author architecture (repository) · Source
EzAudio waveform VAE
Provides the waveform compression stage used by EzAudio text-to-audio models.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
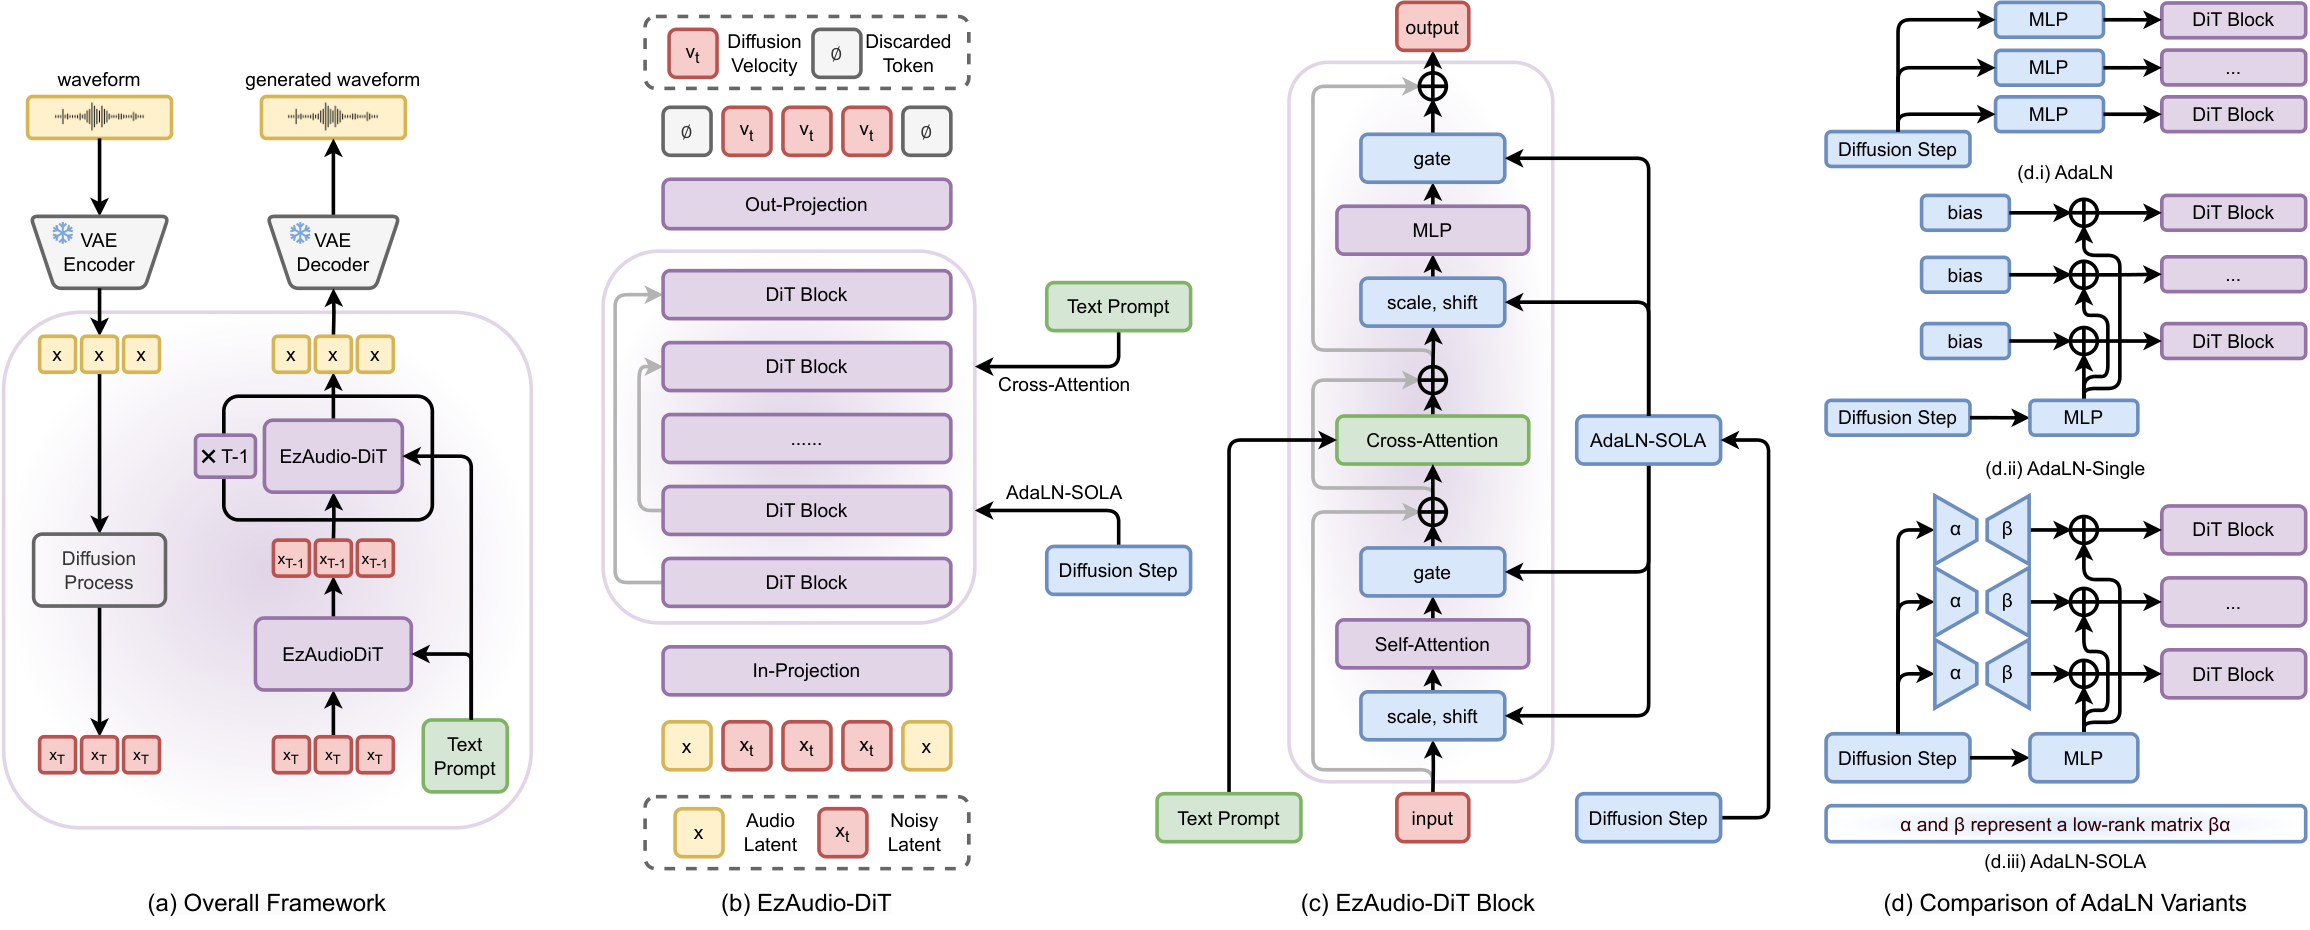
Figure 1 — parent EzAudio system with waveform VAE · Source
FACodec
Separates speech into content, prosody, timbre and acoustic-detail representations.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 80 · Nominal bitrate: Not specified
Open license: code MIT · weights Apache-2.0
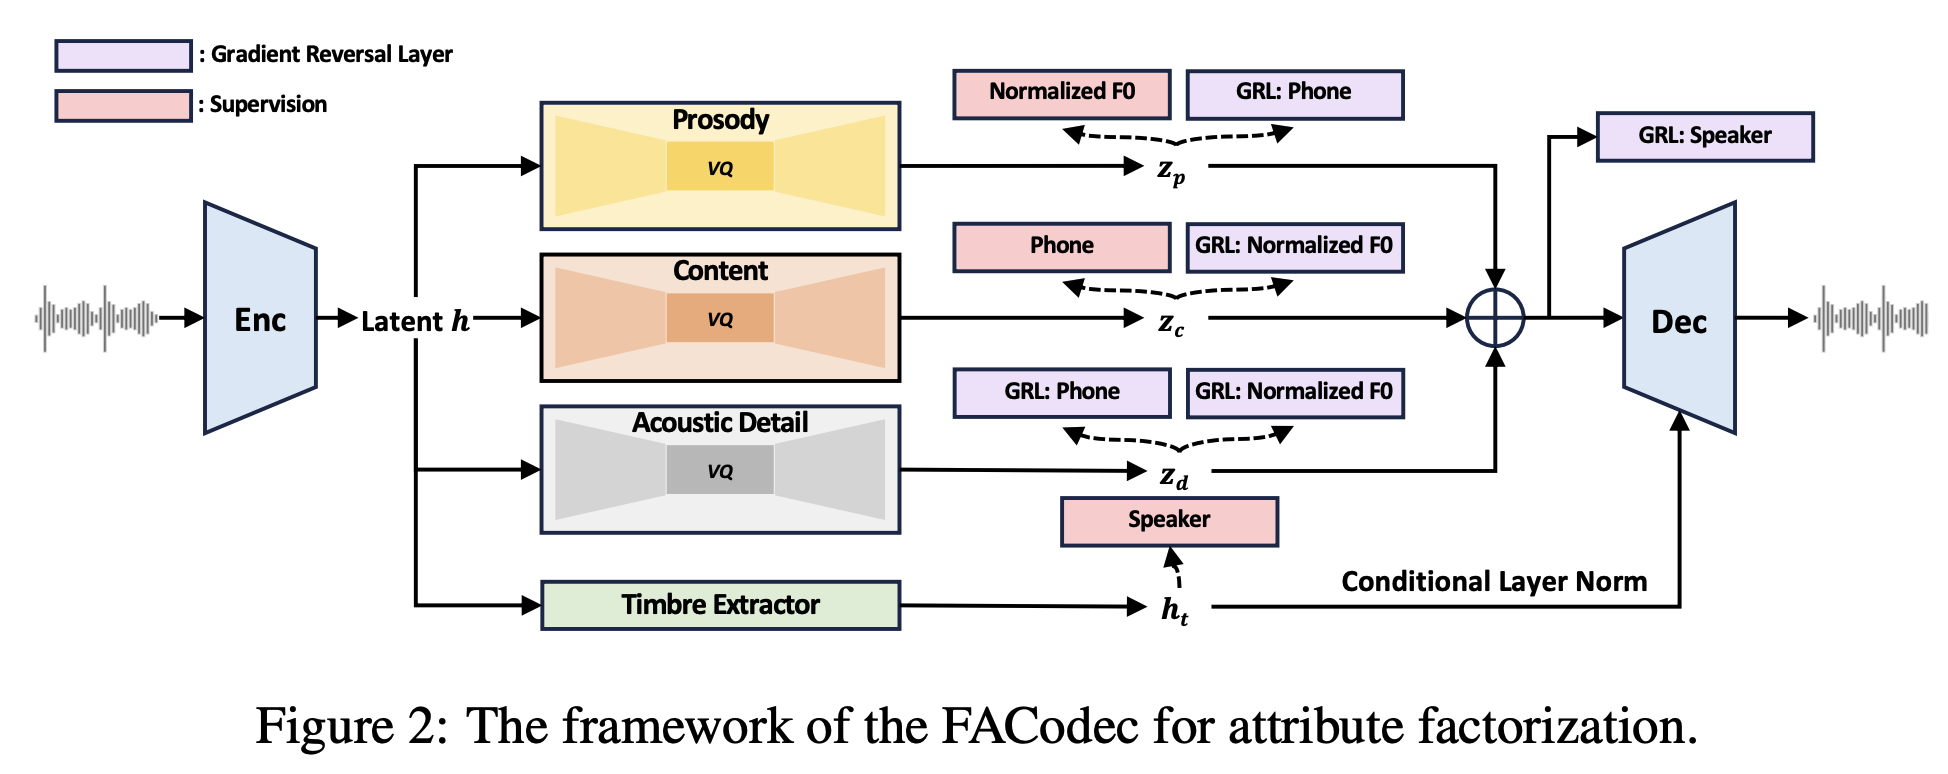
Author architecture (repository) · Source
Firefly codec (Fish Speech 1.5)
Encodes speech into grouped finite-scalar tokens for Fish Speech.
Audio: 44.1 kHz · Frame rate: ~21.5 · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-SA-4.0 — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
FireRedTTS-2 speech tokenizer
Provides streaming speech tokens for long conversational speech generation.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 · Nominal bitrate: 2.2 kbps (16 codebooks)
Open license: code Apache-2.0 · weights Apache-2.0
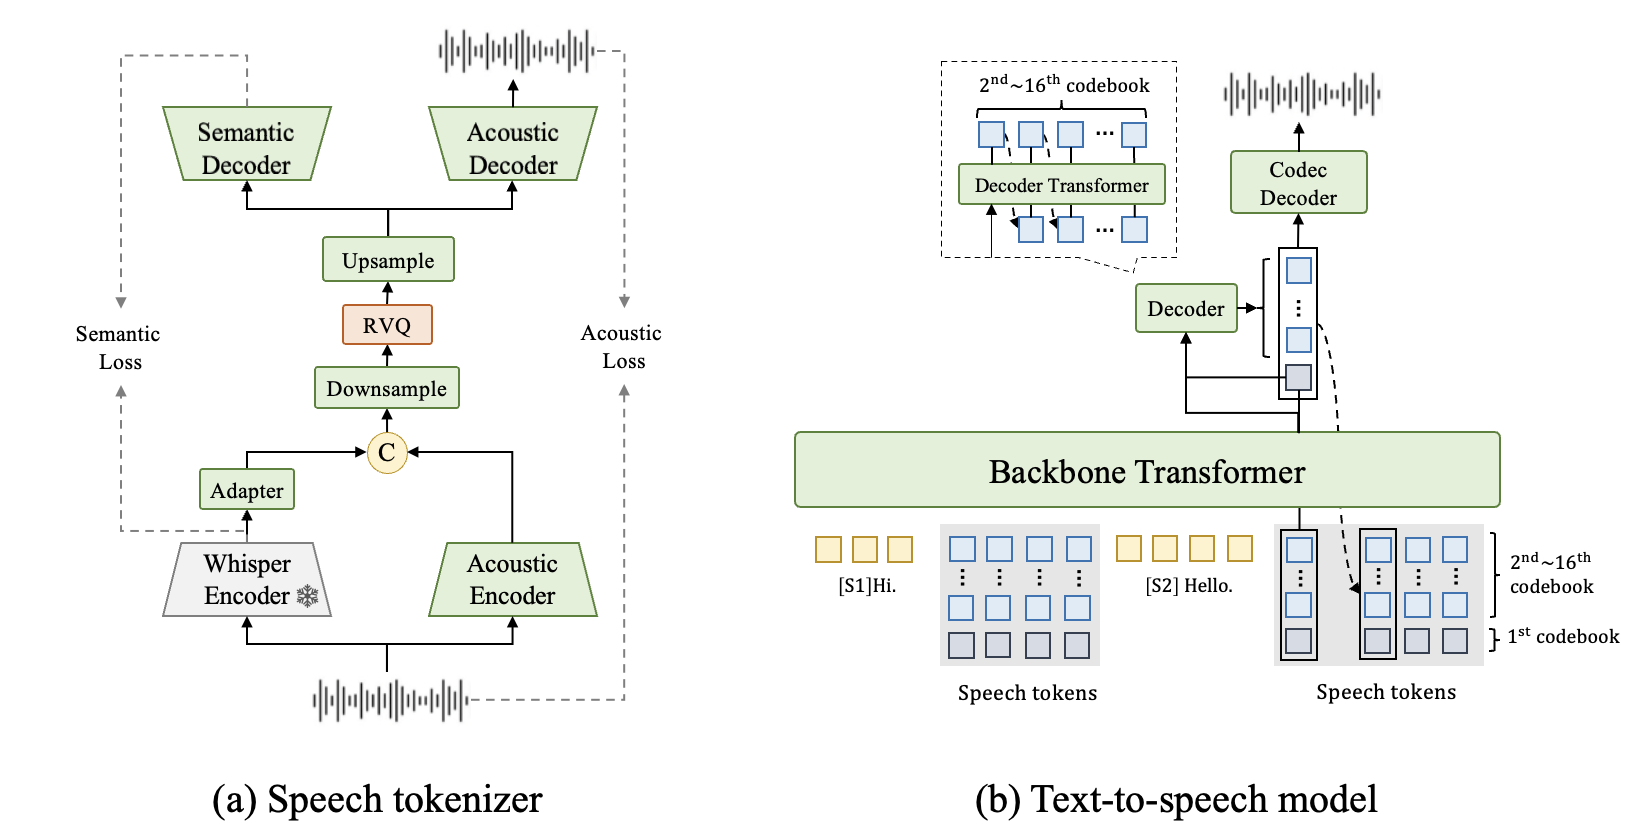
Figure 1 — system overview, including the tokenizer · Source
Fish Audio codec (OpenAudio S1 / S2)
Provides the audio tokenization and reconstruction component used by OpenAudio and Fish S2.
Audio: 44.1 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code Fish Audio Research License · weights Fish Audio Research License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
FlexiCodec
Adapts speech token duration by merging semantically similar frames.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: Dynamic: ~3–12.5 · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
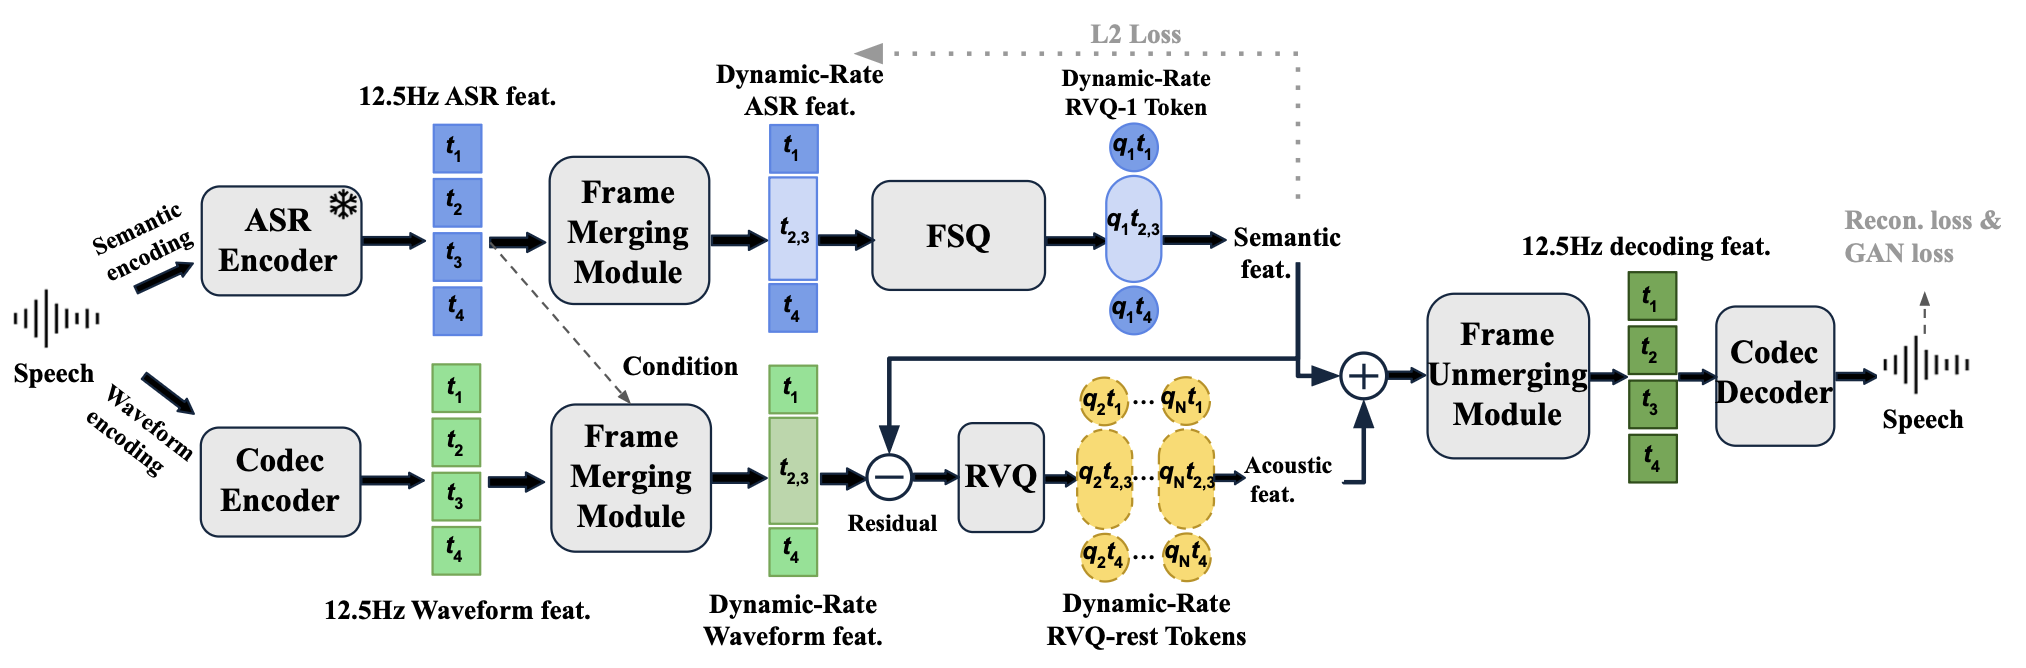
Author architecture (repository) · Source
FlowDec
Combines non-adversarial audio compression with a generative flow-matching postfilter.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
FocalCodec
Compresses speech into one codebook at several low token rates.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 / 25 / 50 · Nominal bitrate: ~0.16 / 0.33 / 0.65 kbps
Open license: code Apache-2.0 · weights Apache-2.0
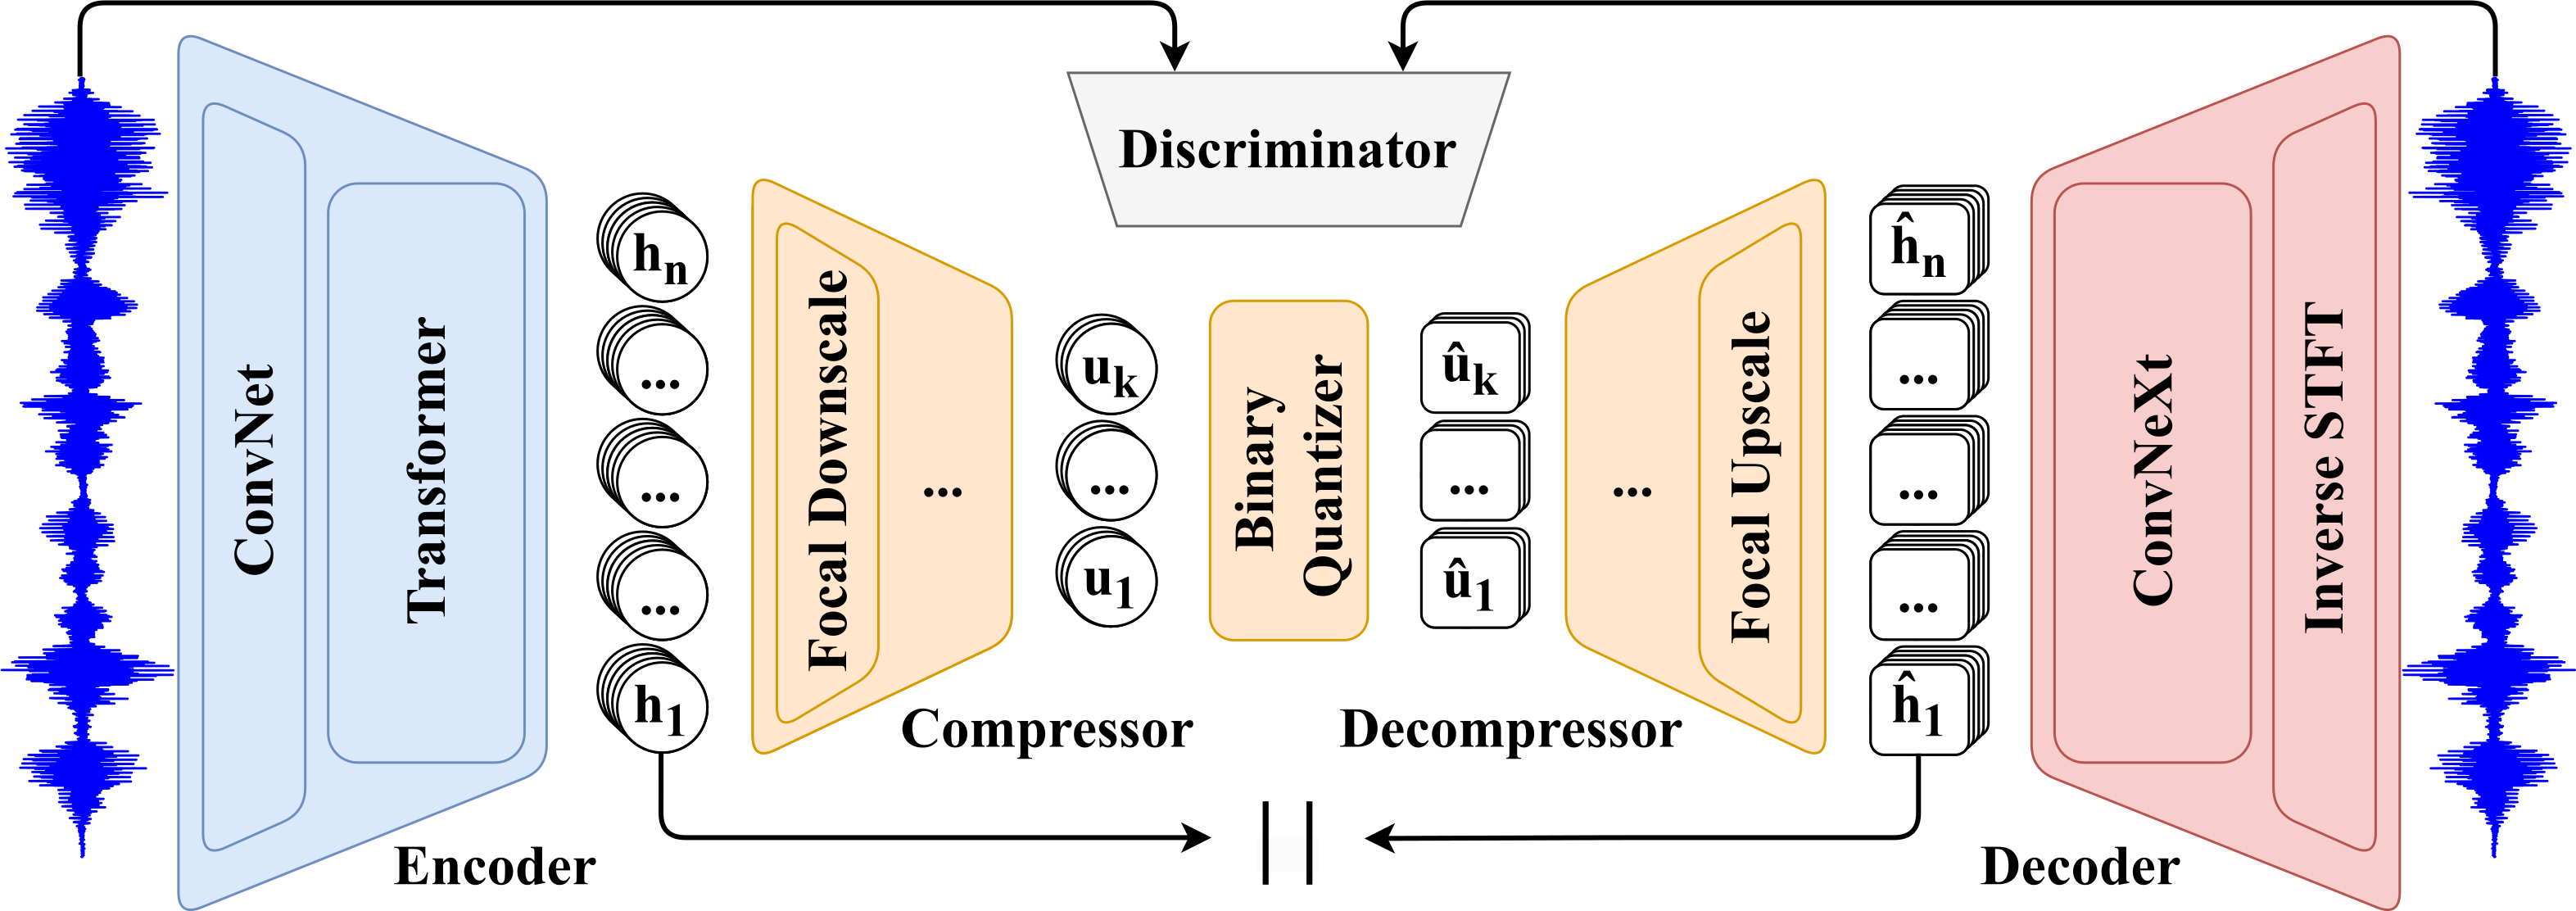
Author architecture (repository) · Source
FocalCodec-Stream
Adds causal, incremental speech coding with a single token stream.
Paper · Code · Weights · Details
Audio: 16 kHz input → 24 kHz output · Frame rate: 50 · Nominal bitrate: 0.55 / 0.60 / 0.80 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
FunCodec
Provides reproducible time-domain and frequency-domain neural speech coding recipes.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 (ds320); 25 (ds640) · Nominal bitrate: Not specified
Open license: code MIT · weights MIT
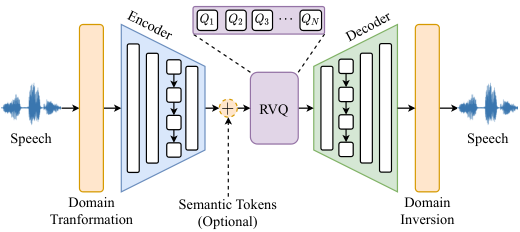
Figure 2 · Source
HARP
Allocates residual codebook capacity across harmonic frequency bands.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: ~86 · Nominal bitrate: ~2.6 / 4.3 / 6.0 / 7.7 kbps
Open license: code MIT · weights MIT
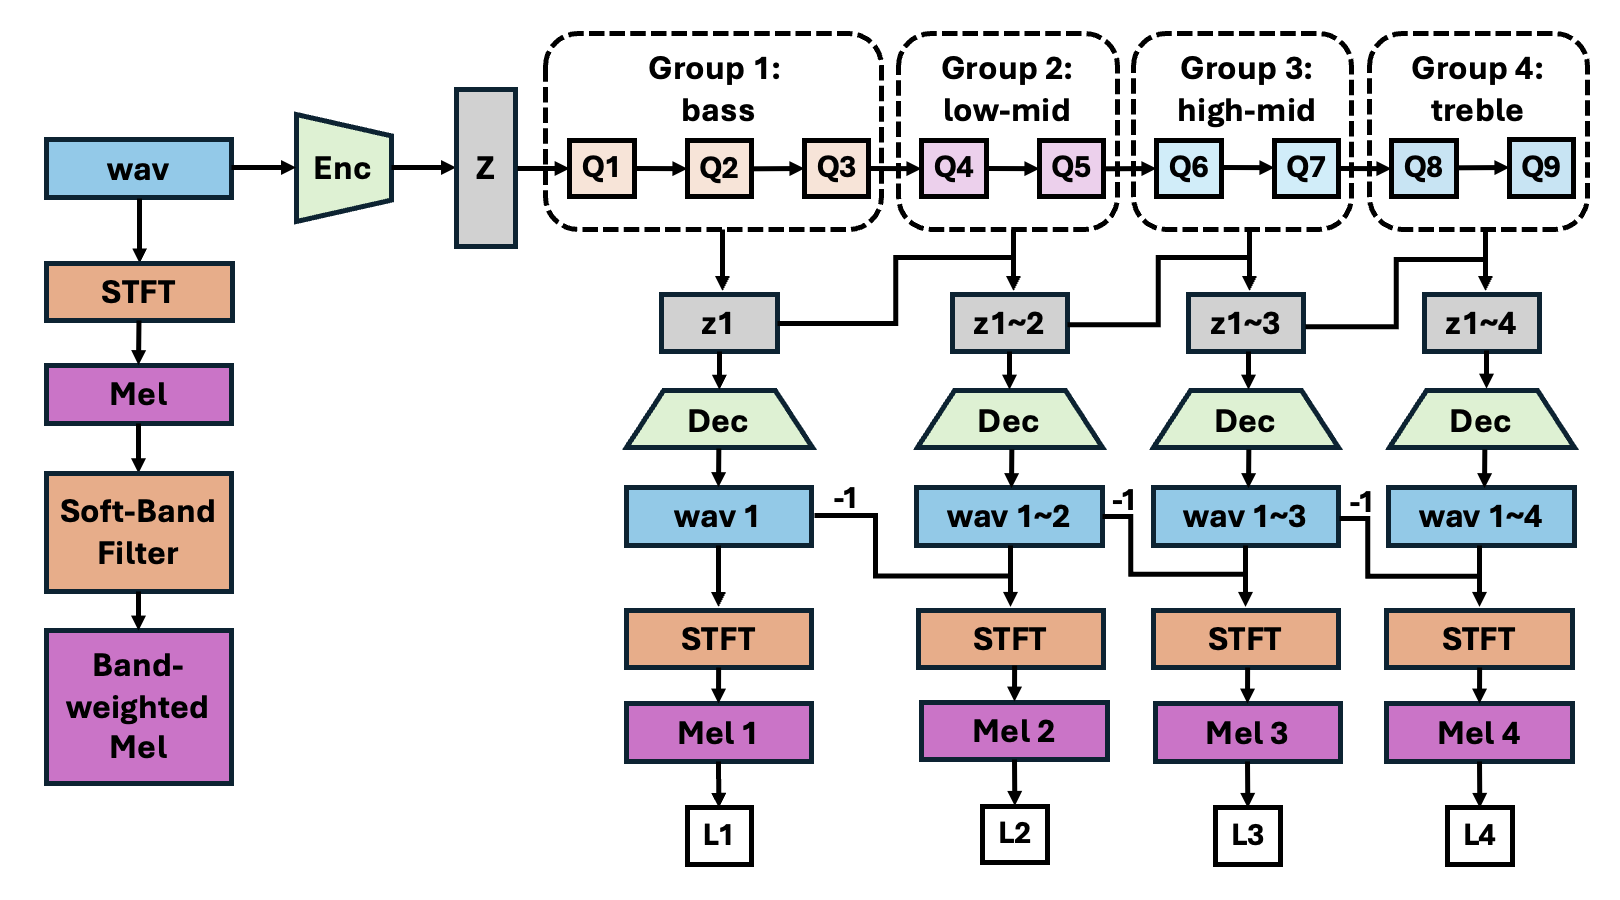
Figure 1 · Source
HeartCodec
Encodes music into tokens for the HeartMuLa music-generation family.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: Not specified · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
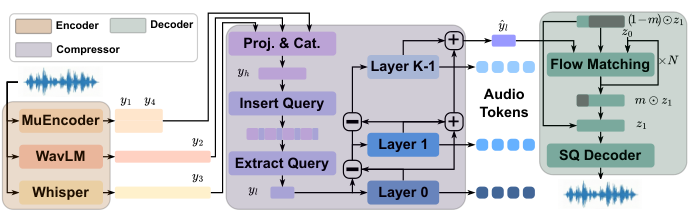
Figure 2 · Source
HiFi-Codec
Reconstructs speech using grouped residual quantization with few codebooks.
Paper · Code · Weights · Details
Audio: 16 / 24 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
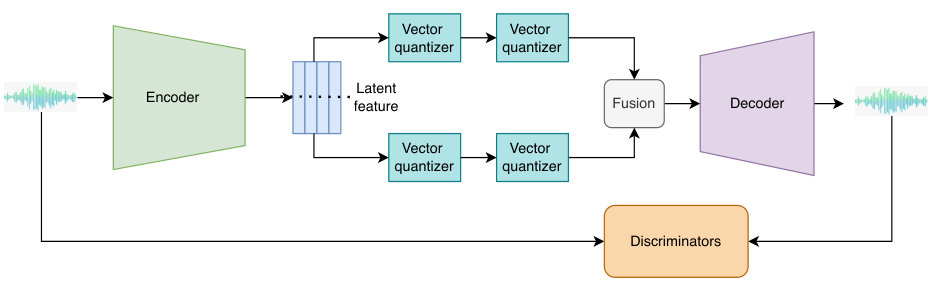
Figure 1 · Source
Higgs Audio Tokenizer v2
Compresses speech, music and sound events into low-frame-rate audio tokens.
Audio: 24 kHz · Frame rate: 25 · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights Boson Higgs Audio 2 Community License — The linked custom or noncommercial terms apply to this release.
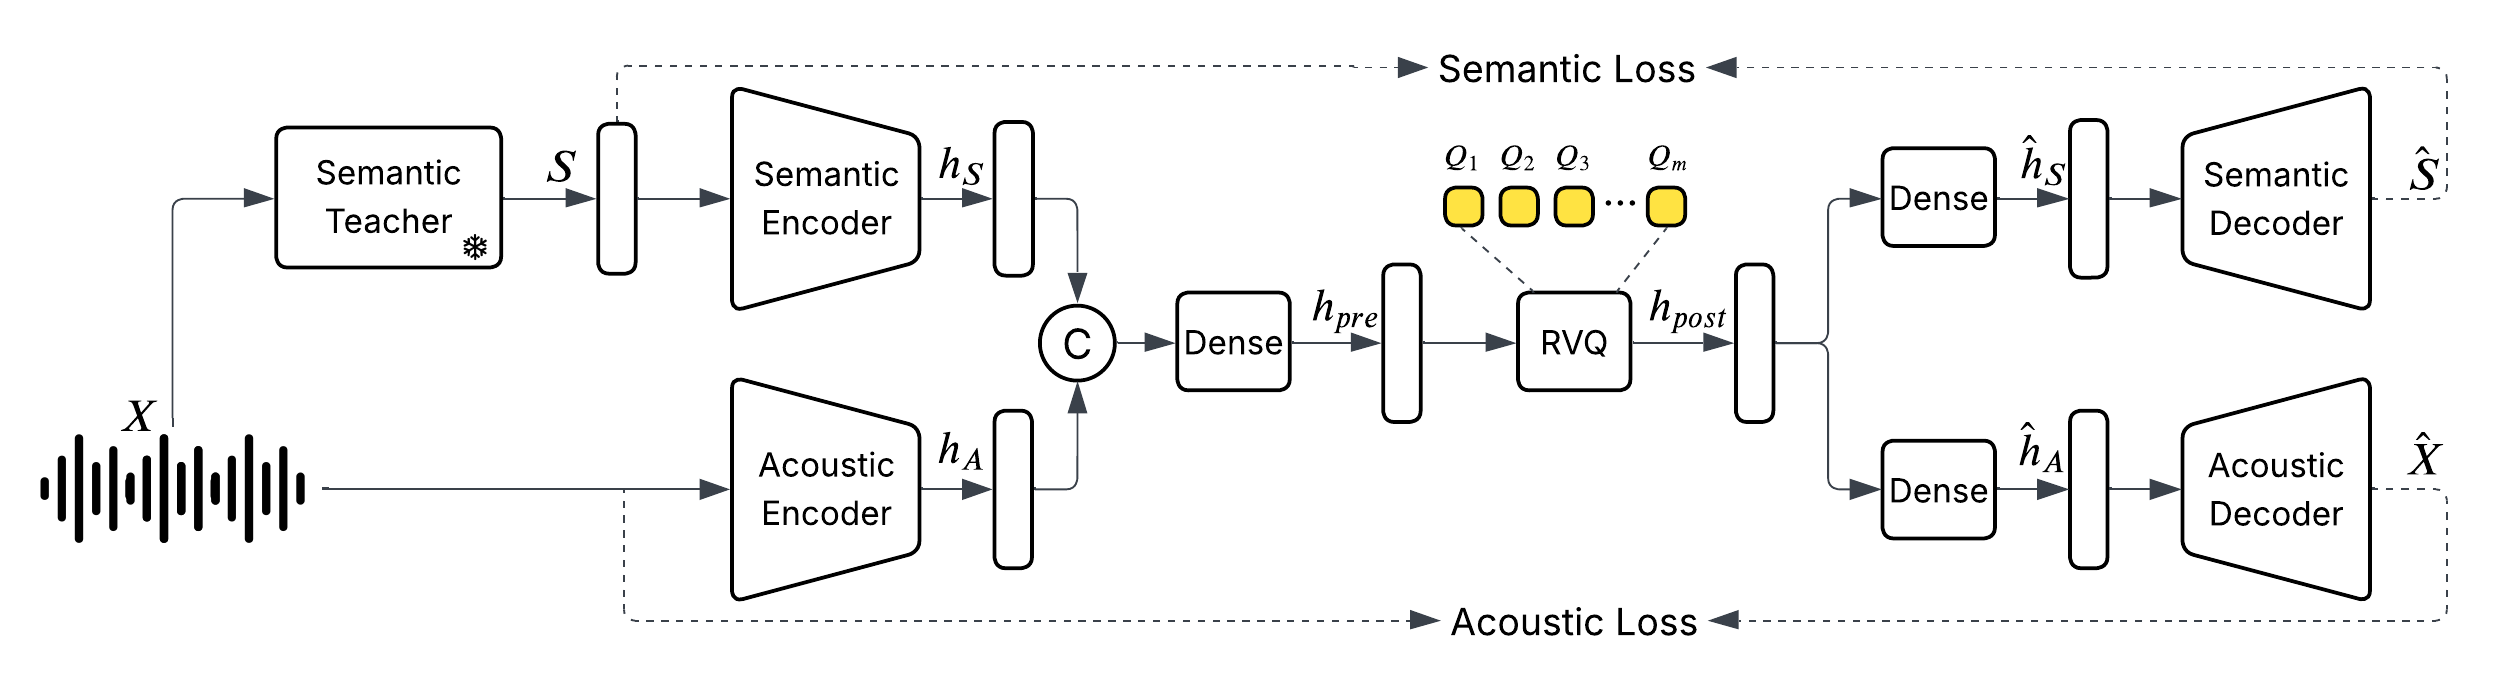
Author architecture (repository) · Source
HILCodec
Targets lightweight, high-fidelity neural audio coding with deployable inference graphs.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
HoliTok
Learns continuous speech latents that can support both audio reconstruction and semantic feature extraction.
Paper · Code · Weights · Details
Audio: 48 kHz mono · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
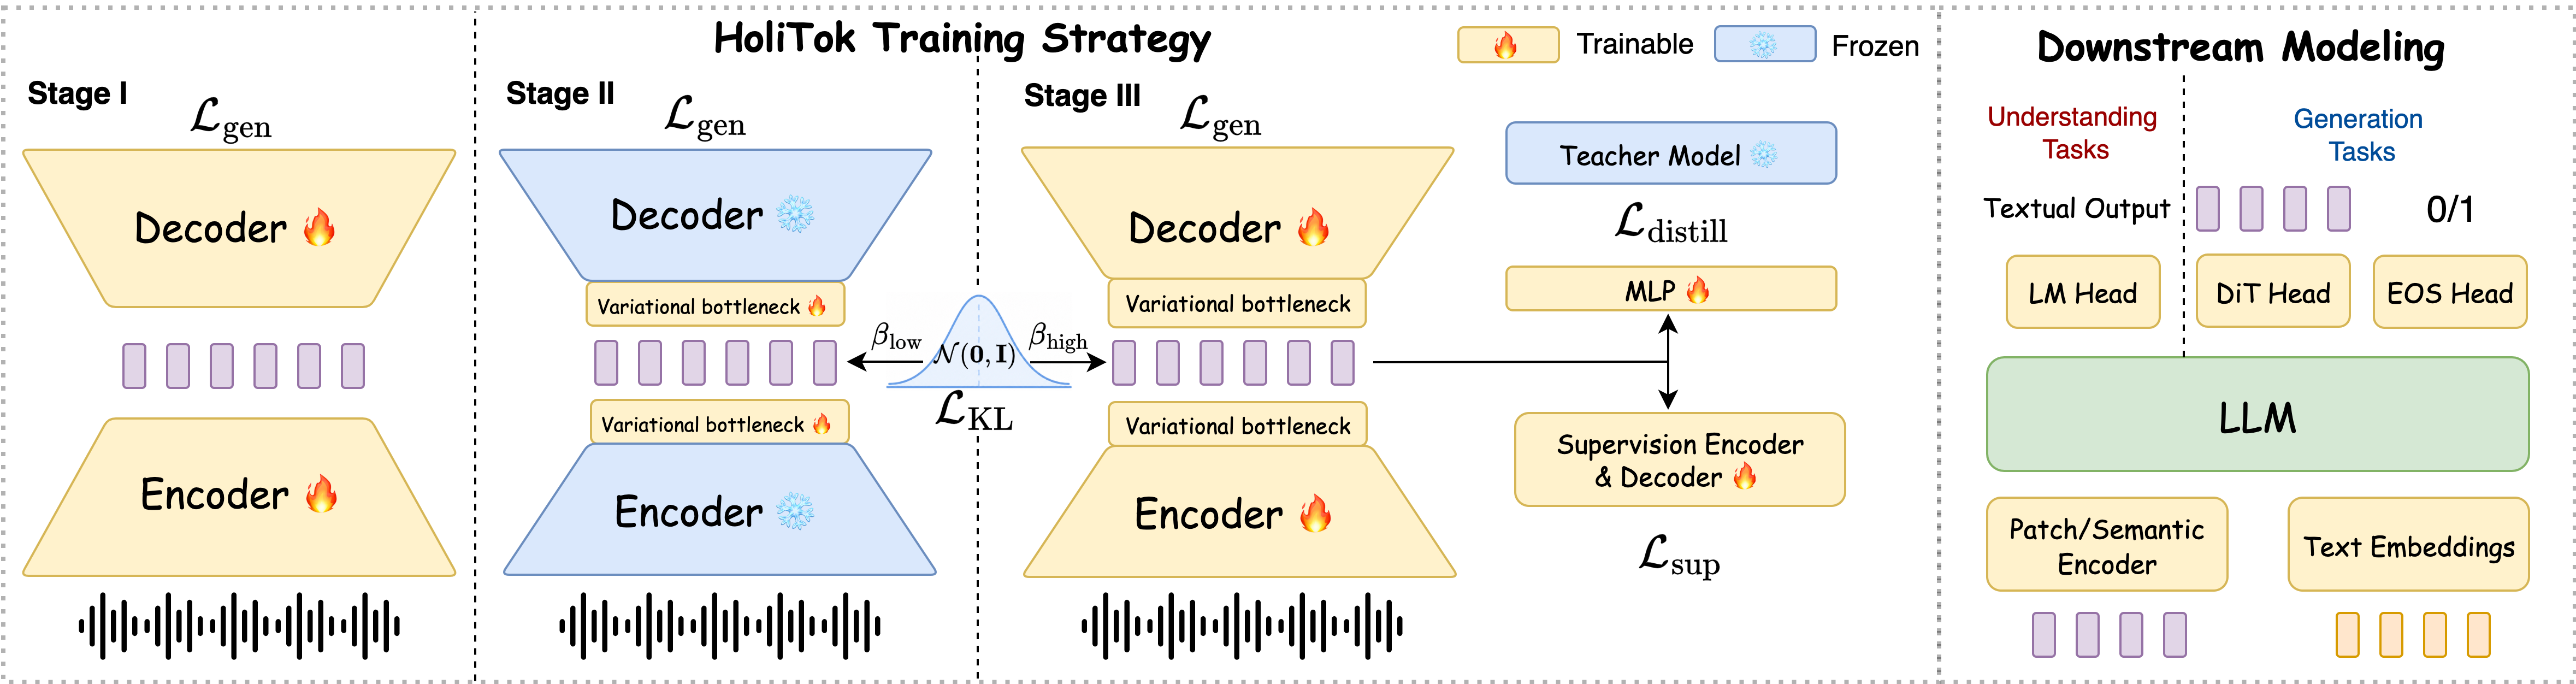
Figure 1 — HoliTok tokenizer and training framework · Source
HunyuanVideo-Foley audio VAE
Reconstructs general audio using the waveform VAE released with HunyuanVideo-Foley.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code Tencent Hunyuan Community License · weights Tencent Hunyuan Community License — The linked noncommercial or custom terms apply to this release.
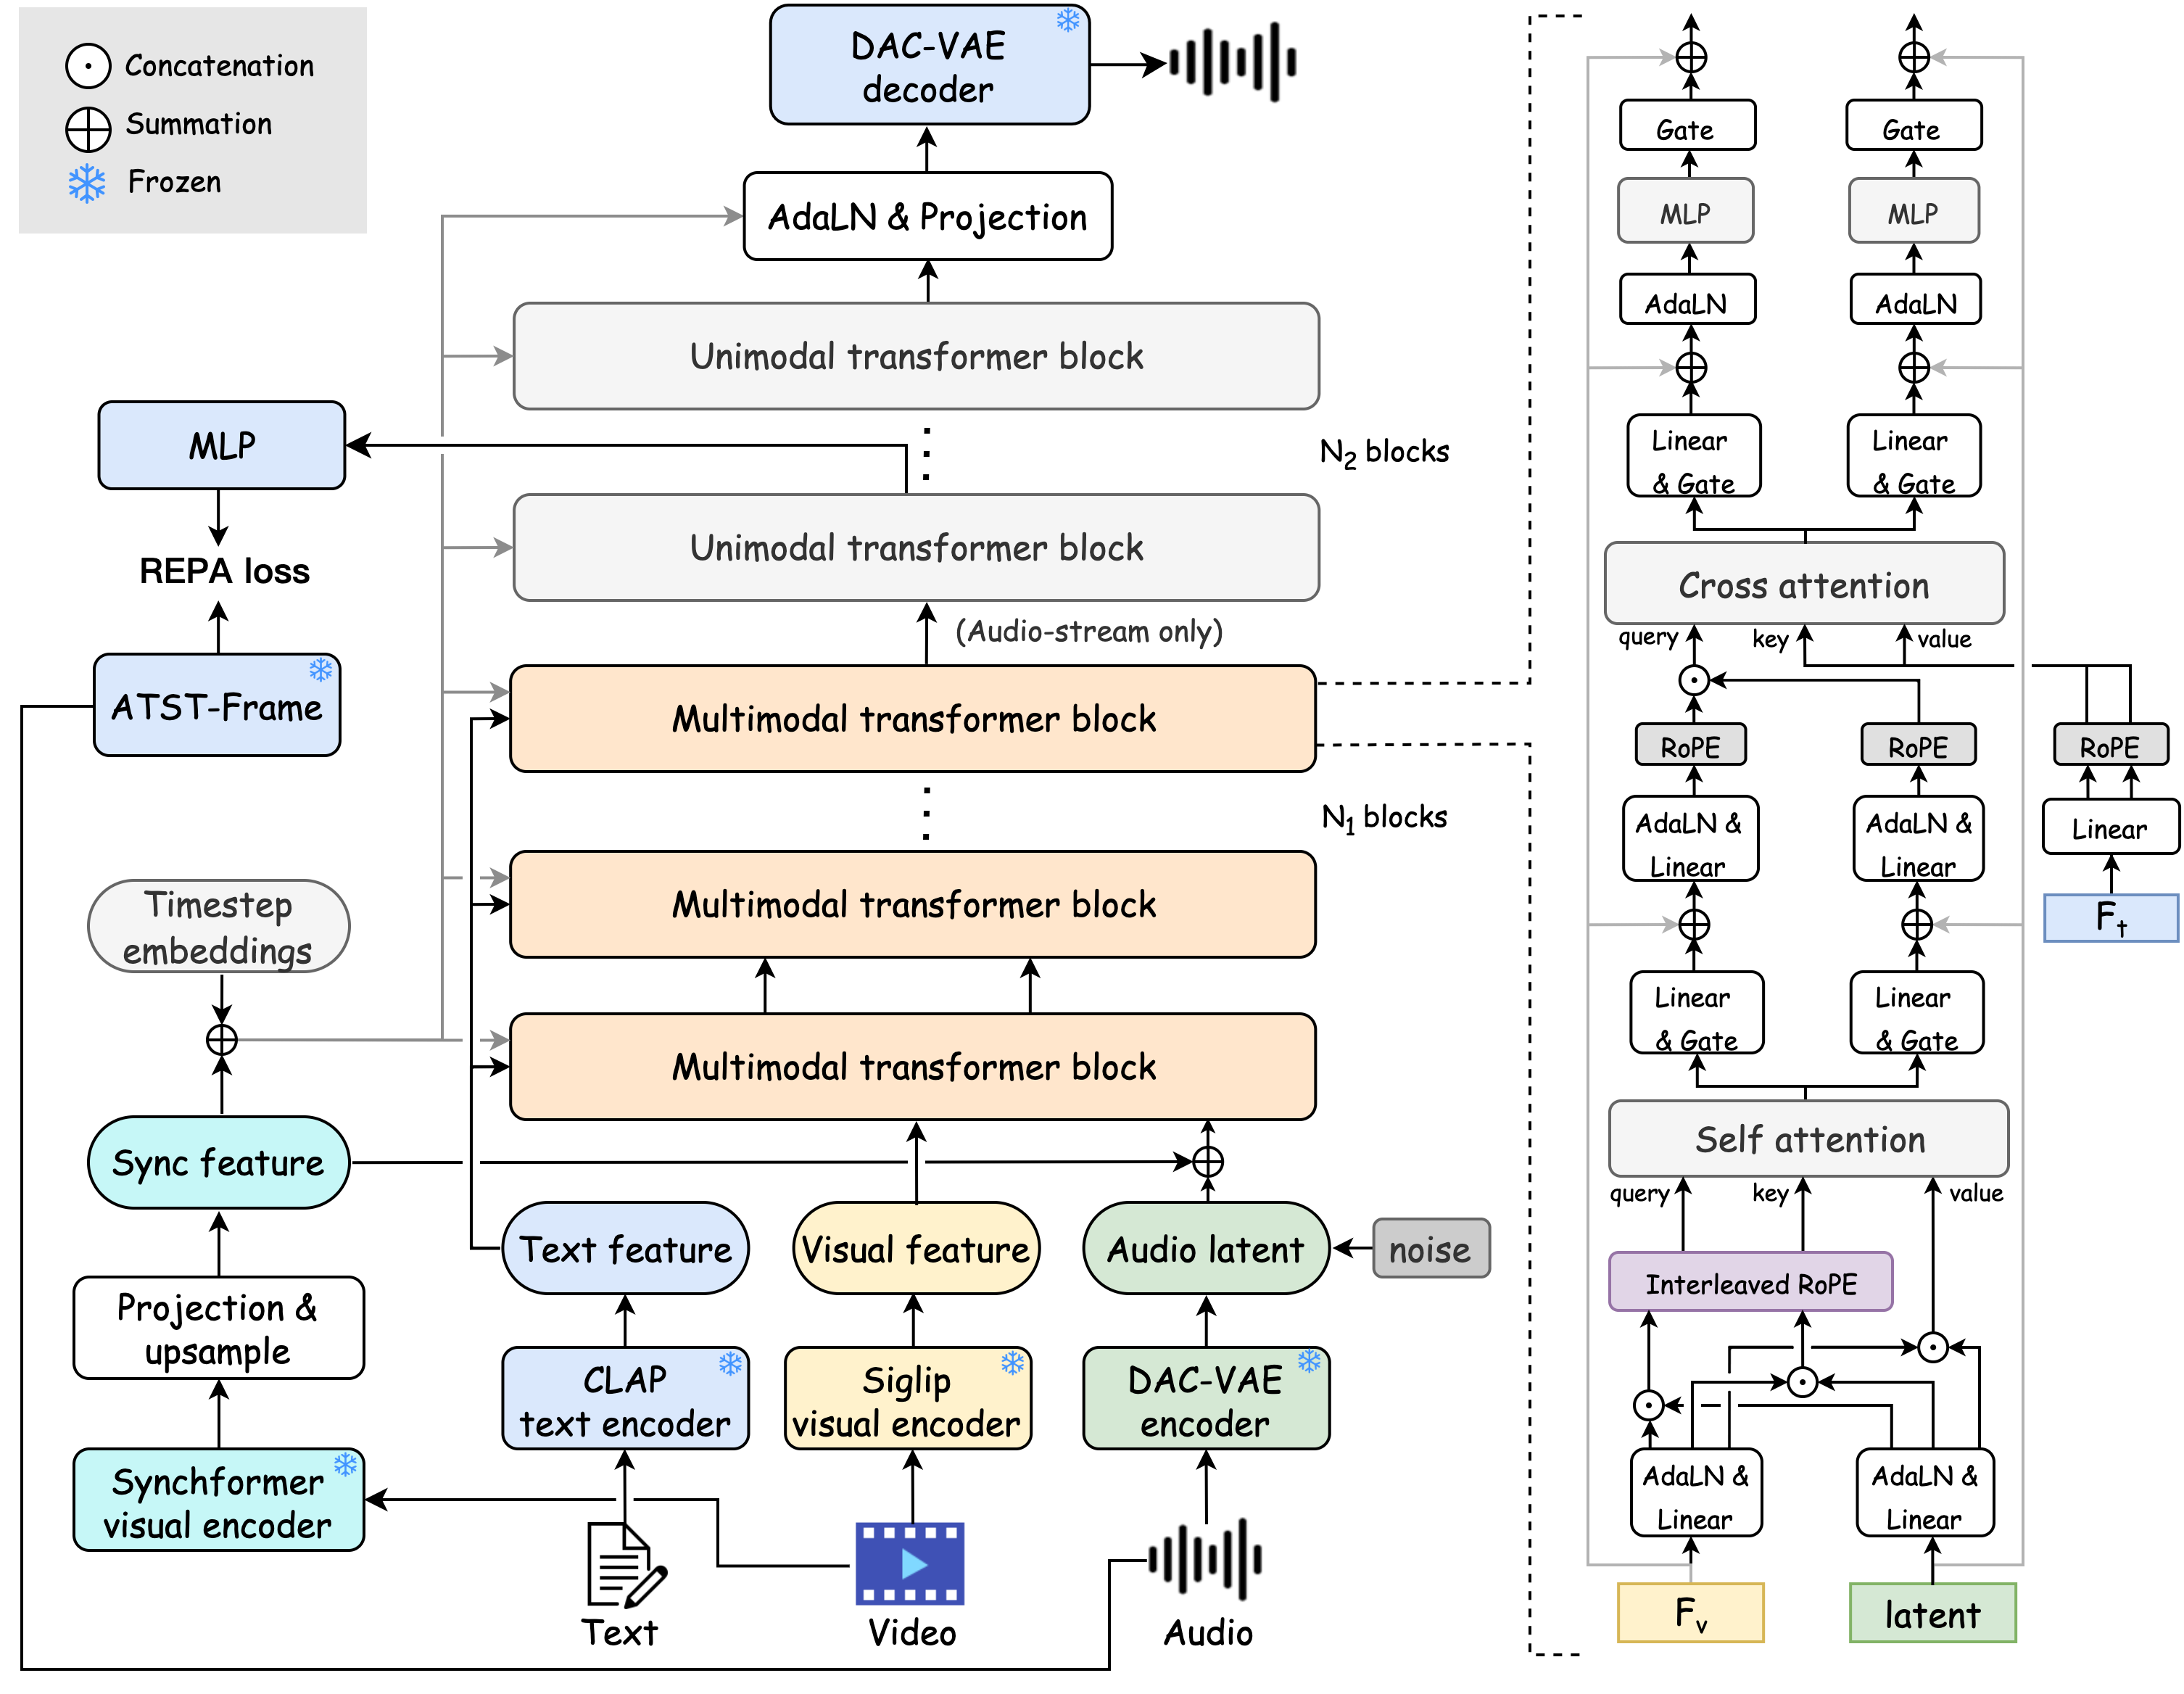
Figure 2 — parent HunyuanVideo-Foley system with DAC-VAE · Source
JHCodec
Uses self-supervised representation reconstruction to improve streaming speech tokens.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 50 · Nominal bitrate: 4 kbps (8 × 1,024 codes at 50 Hz)
Open license: code MIT · weights MIT
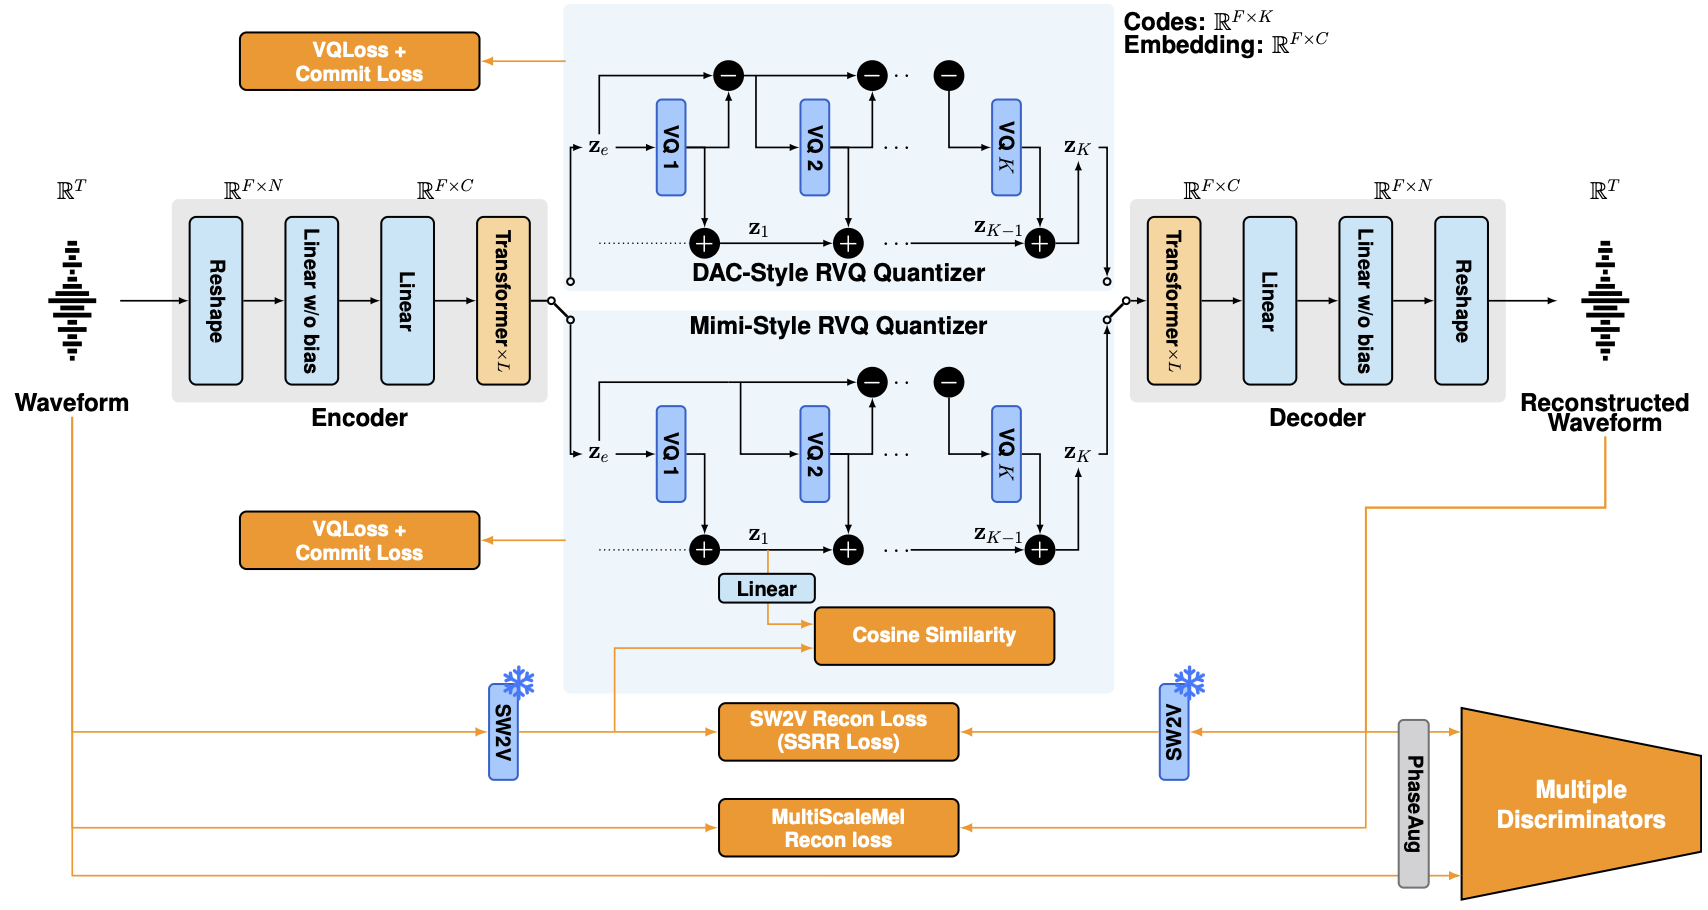
Author architecture (repository) · Source
KVAE-Audio
Encodes full-band speech, music and sound into continuous latents for reconstruction and generative modeling.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Editorial overview · Source
L3AC / SQCodec
Uses a single quantizer in a lightweight speech reconstruction model.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 44.44 / 59.26 / 88.89 / 166.67 · Nominal bitrate: ~0.75 / 1 / 1.5 / 3 kbps
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
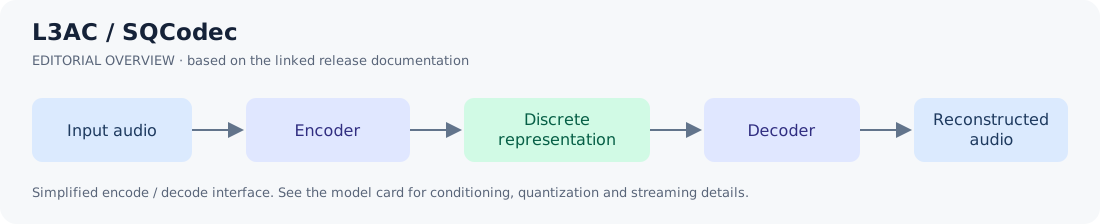
Editorial overview · Source
LILAC
Targets low-bitrate speech compression with stable codes under repeated decode/re-encode cycles.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 9.375 · Nominal bitrate: 0.75 kbps
Open license: code Apache-2.0 · weights Apache-2.0
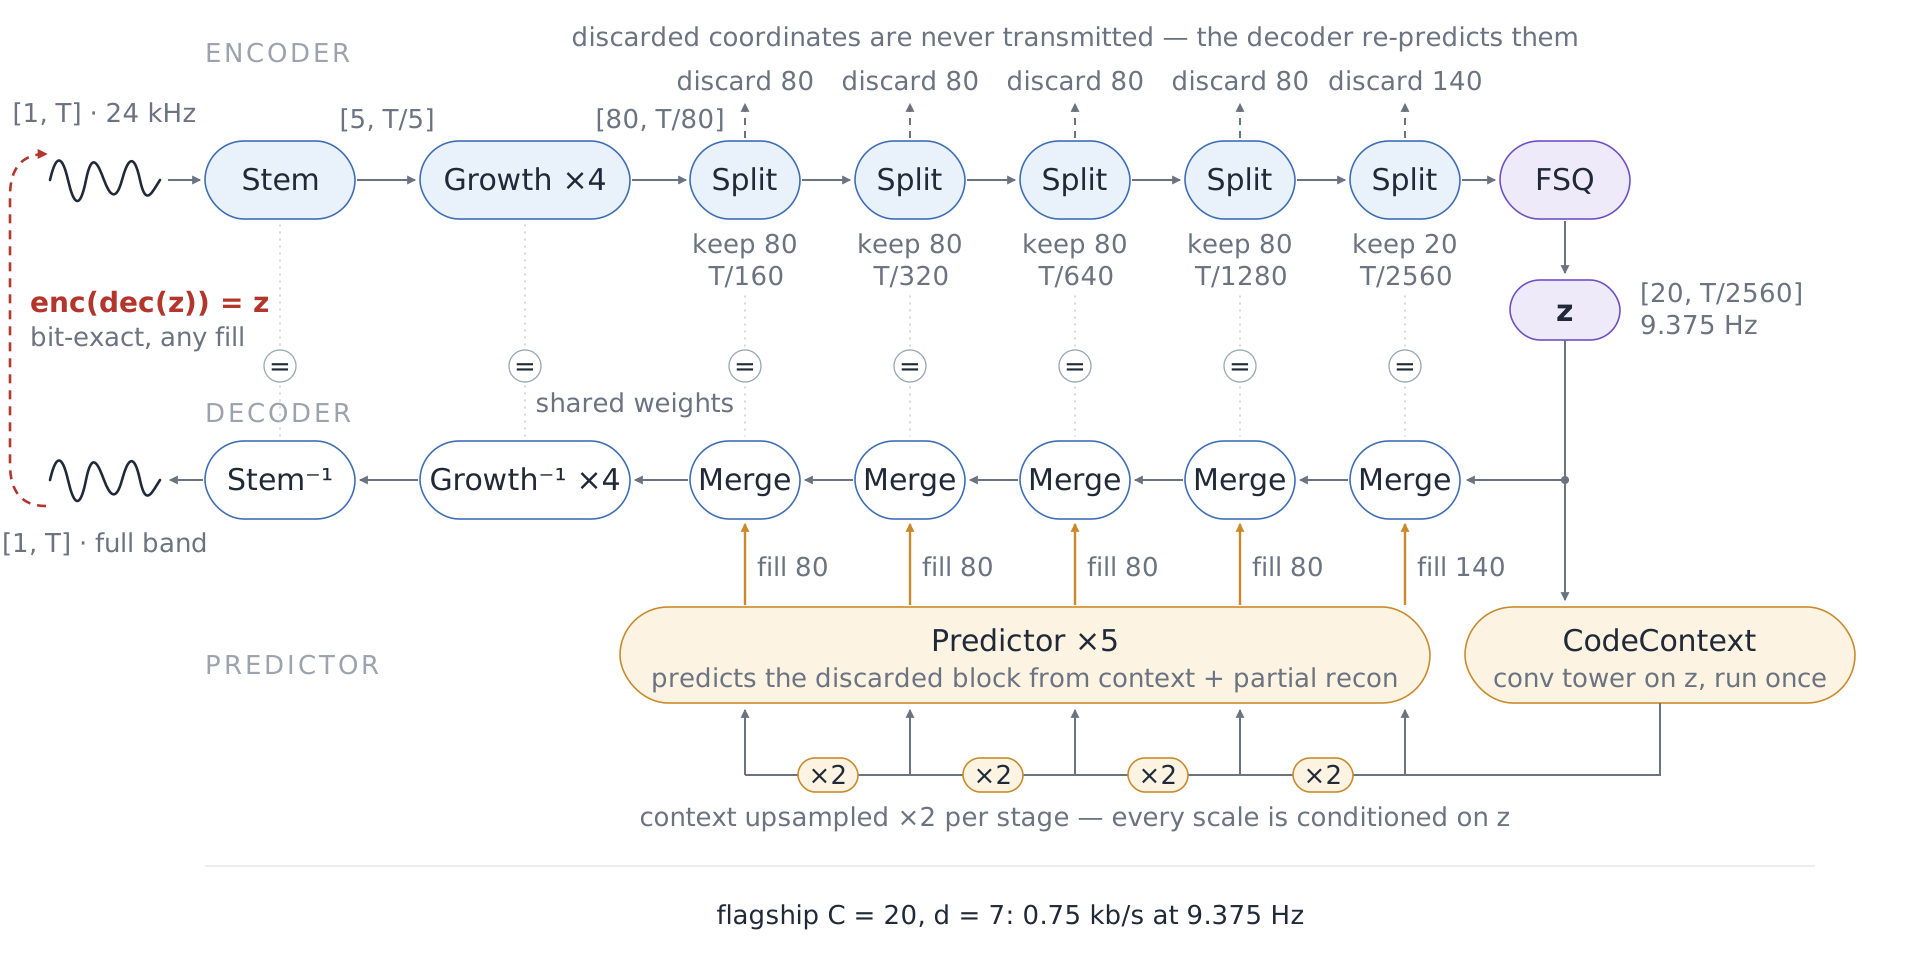
Author architecture (repository) · Source
LLM-Codec (LM objectives)
Adapts codec tokens to be easier for autoregressive language models to predict.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
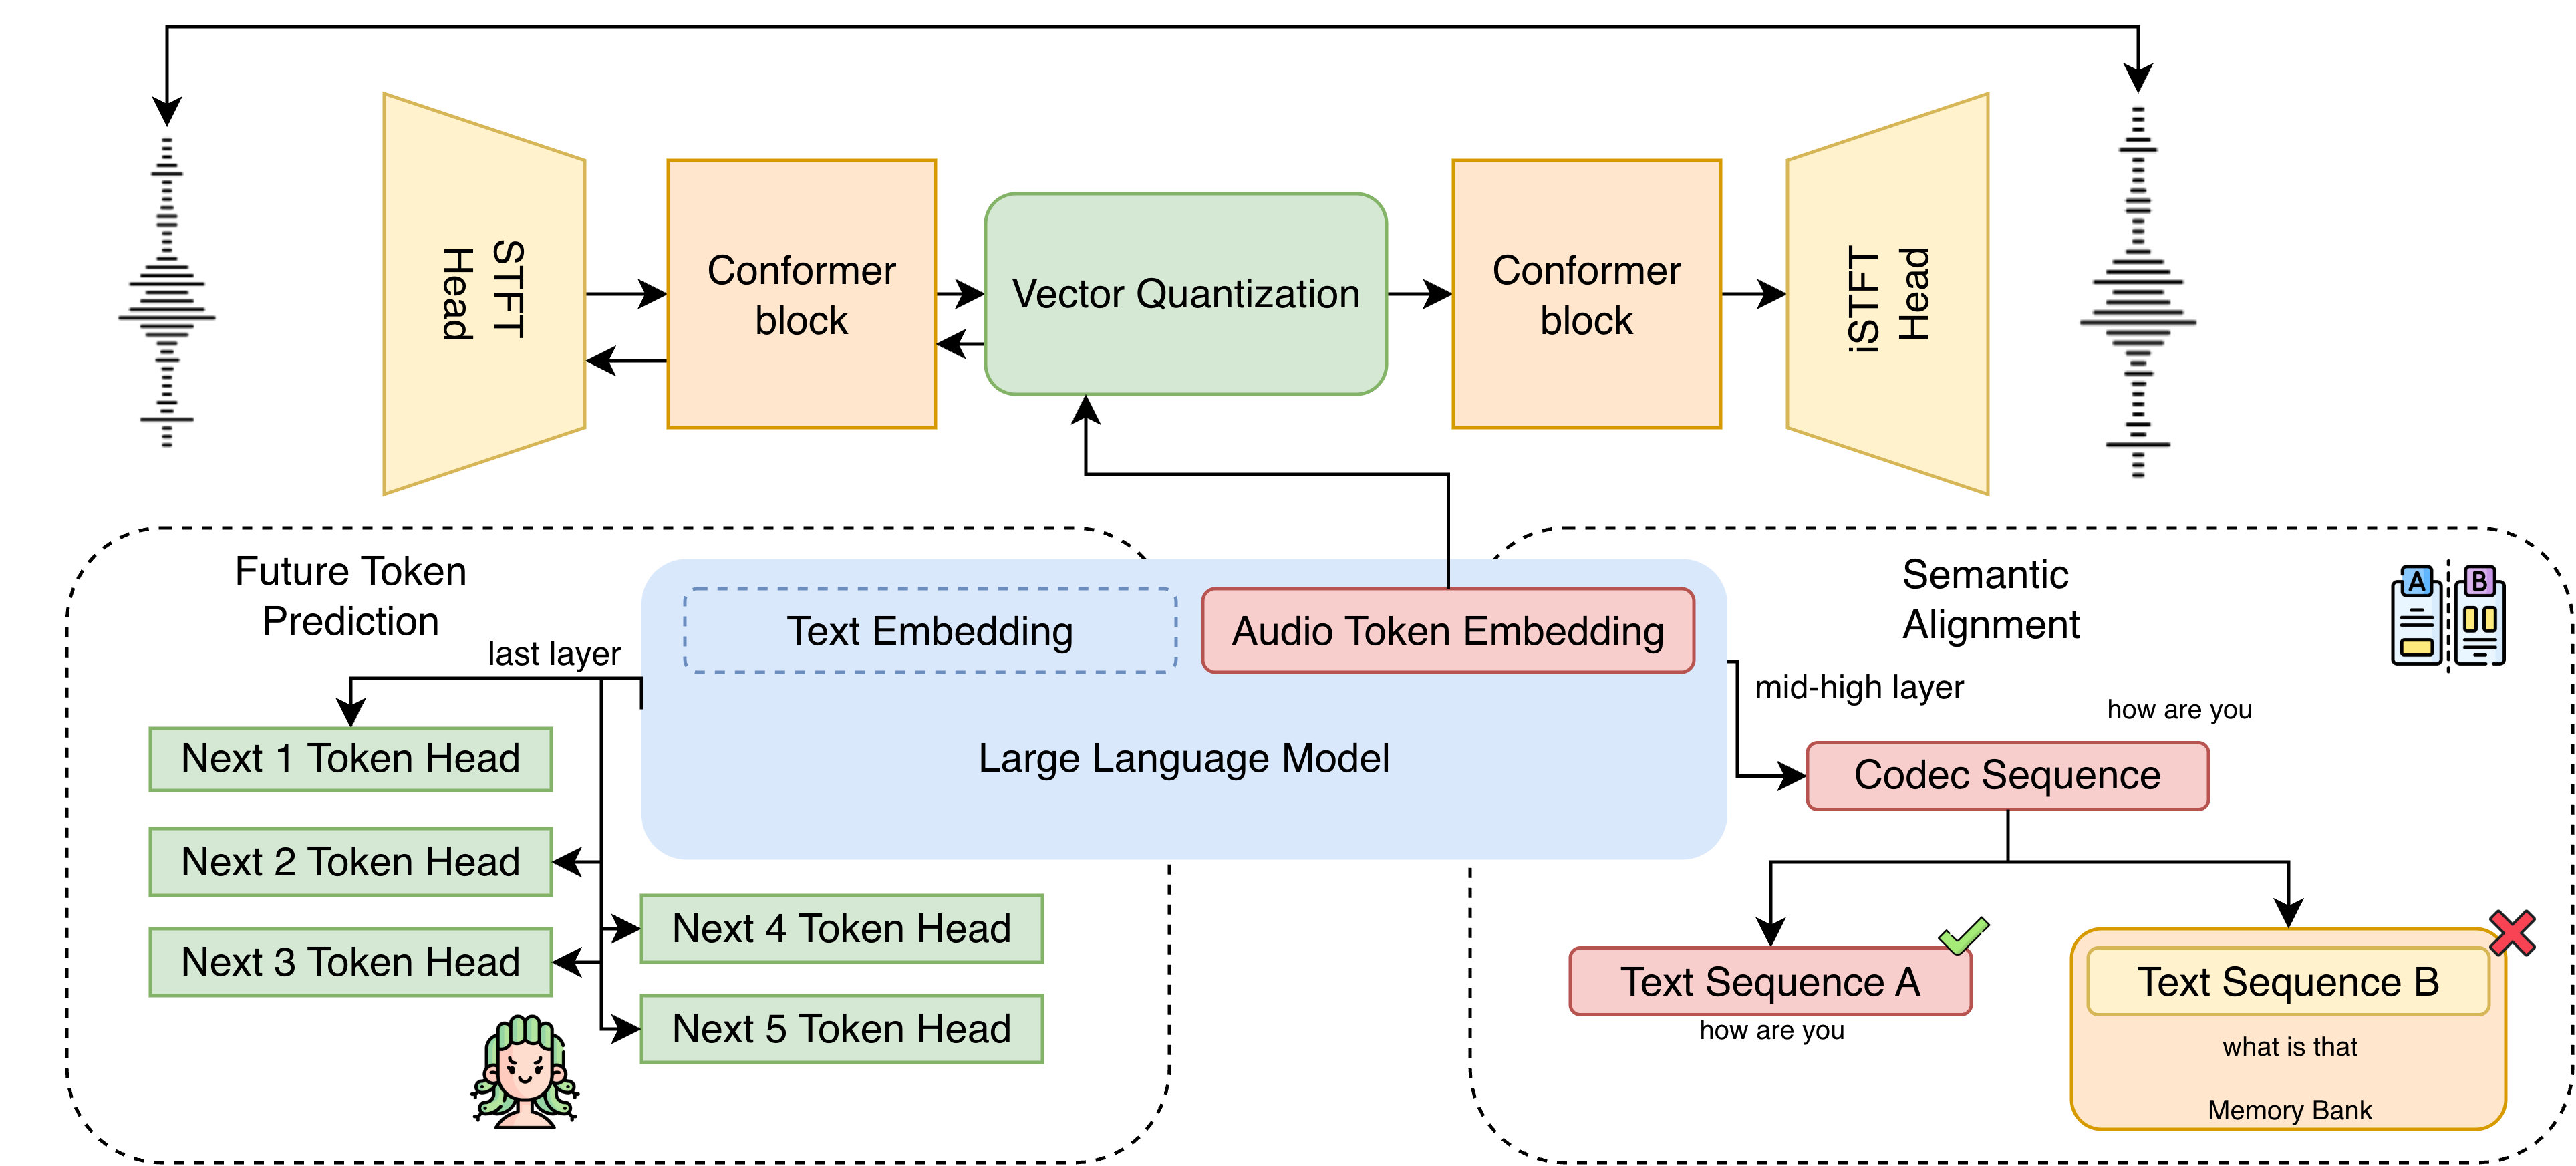
Author architecture (repository) · Source
LLM-Codec (UniAudio 1.5)
Maps audio into an existing language-model vocabulary while preserving reconstruction.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
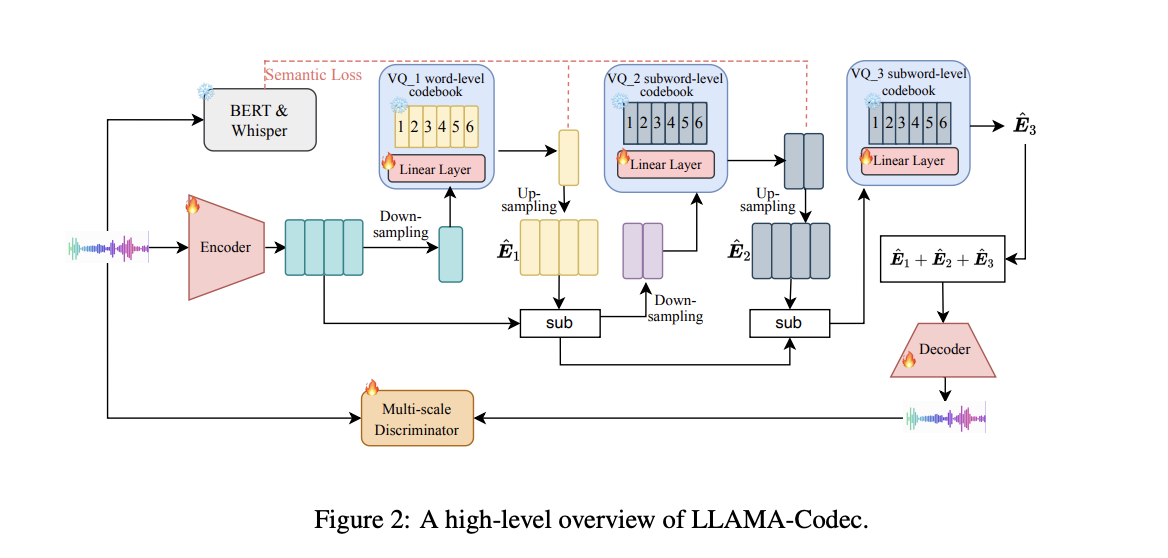
Author architecture (repository) · Source
LongCat Wav-VAE
Encodes speech directly into continuous waveform latents for LongCat-AudioDiT.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: ~11.72 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
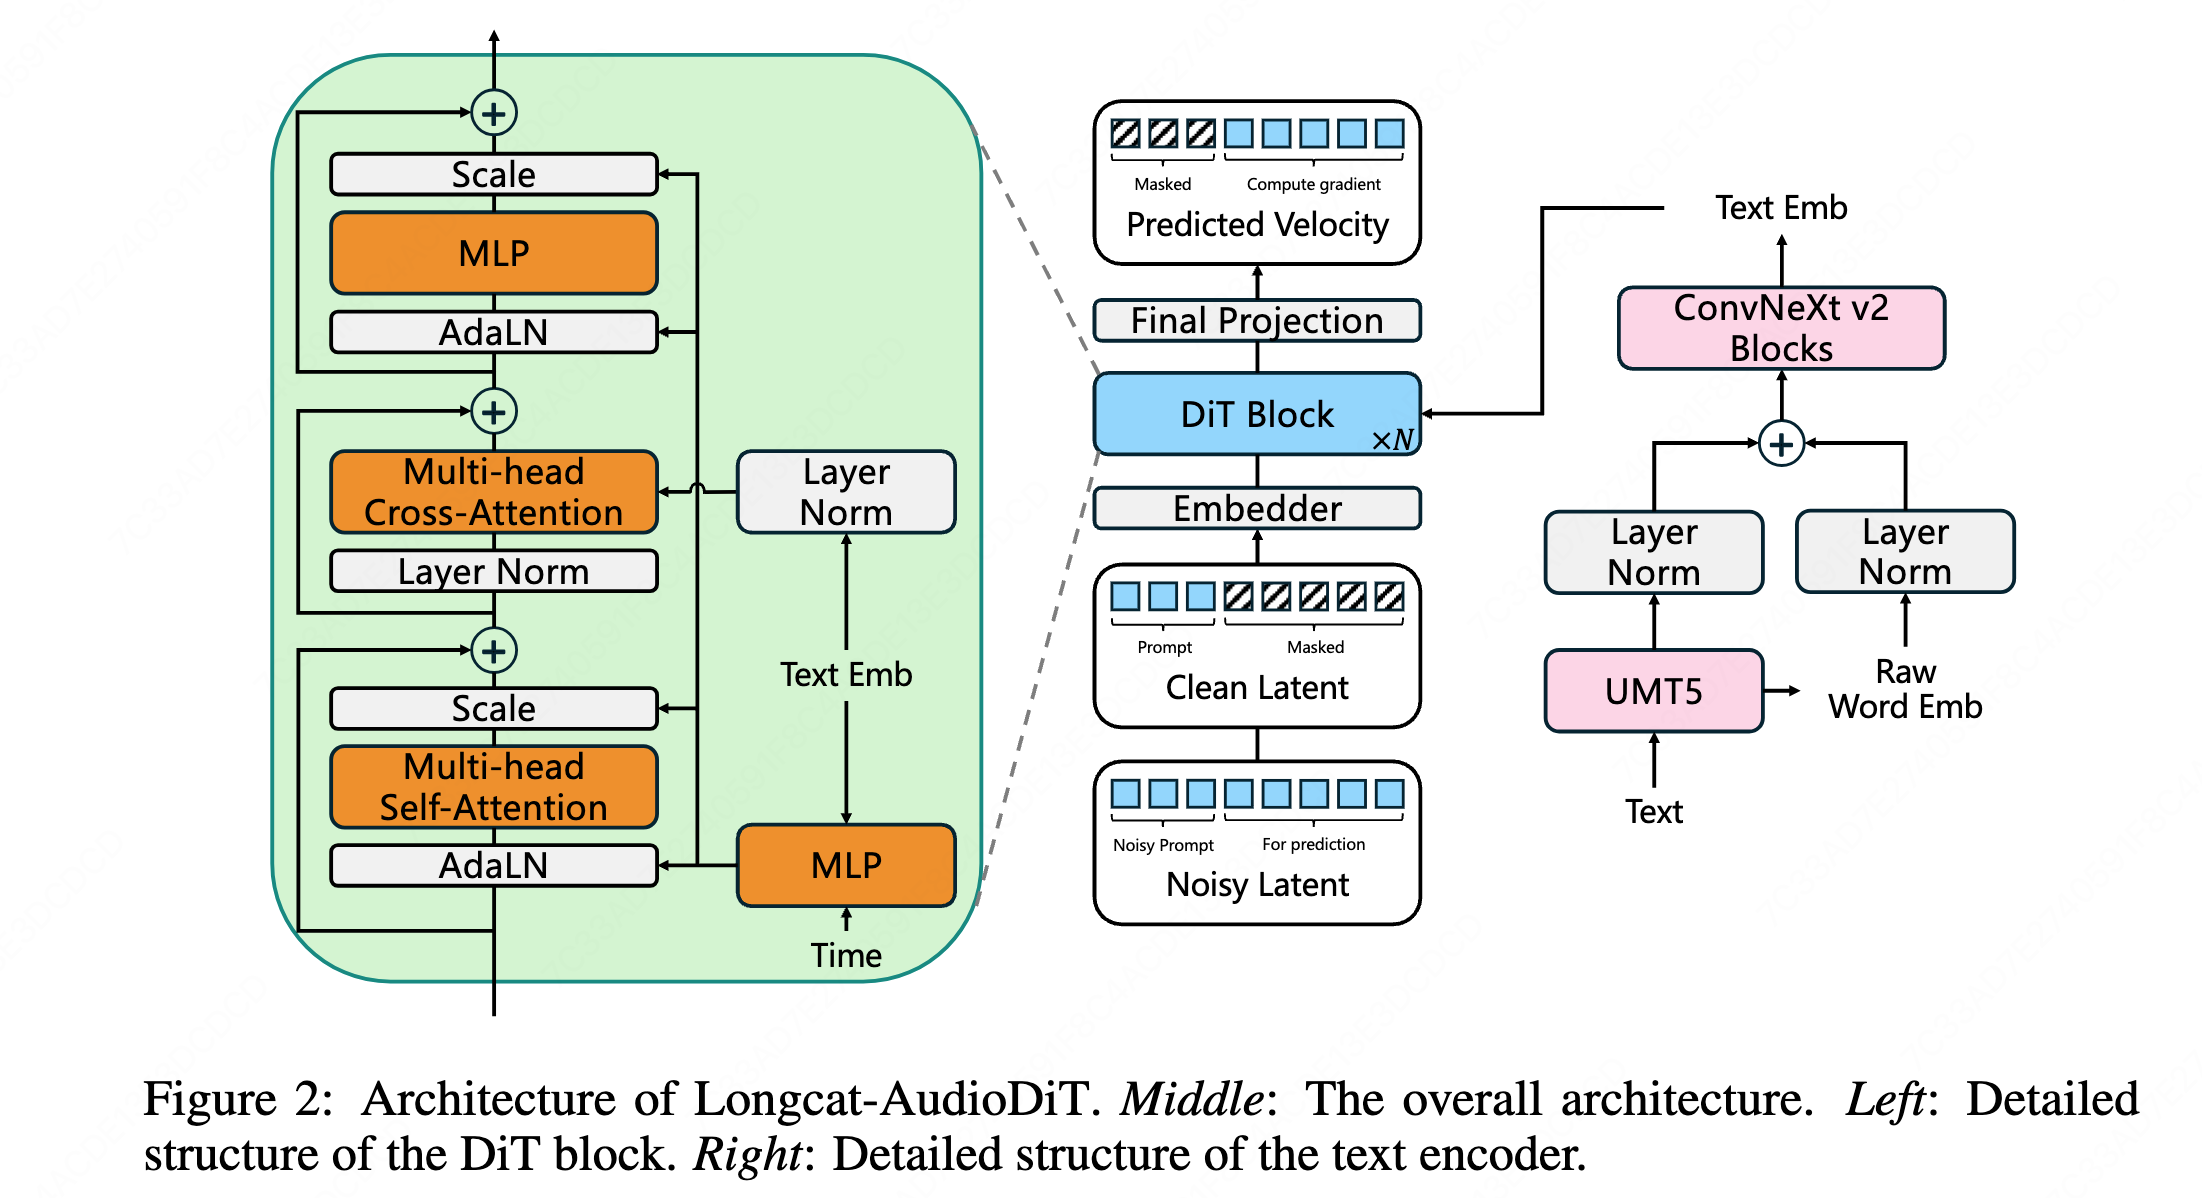
Parent LongCat-AudioDiT architecture with Wav-VAE · Source
LongCat-Audio-Codec
Extracts semantic and acoustic speech tokens in parallel with selectable decoders.
Paper · Code · Weights · Details
Audio: 16 kHz input; 16 / 24 kHz output · Frame rate: ~16.6 · Nominal bitrate: Not specified
Open license: code MIT · weights MIT
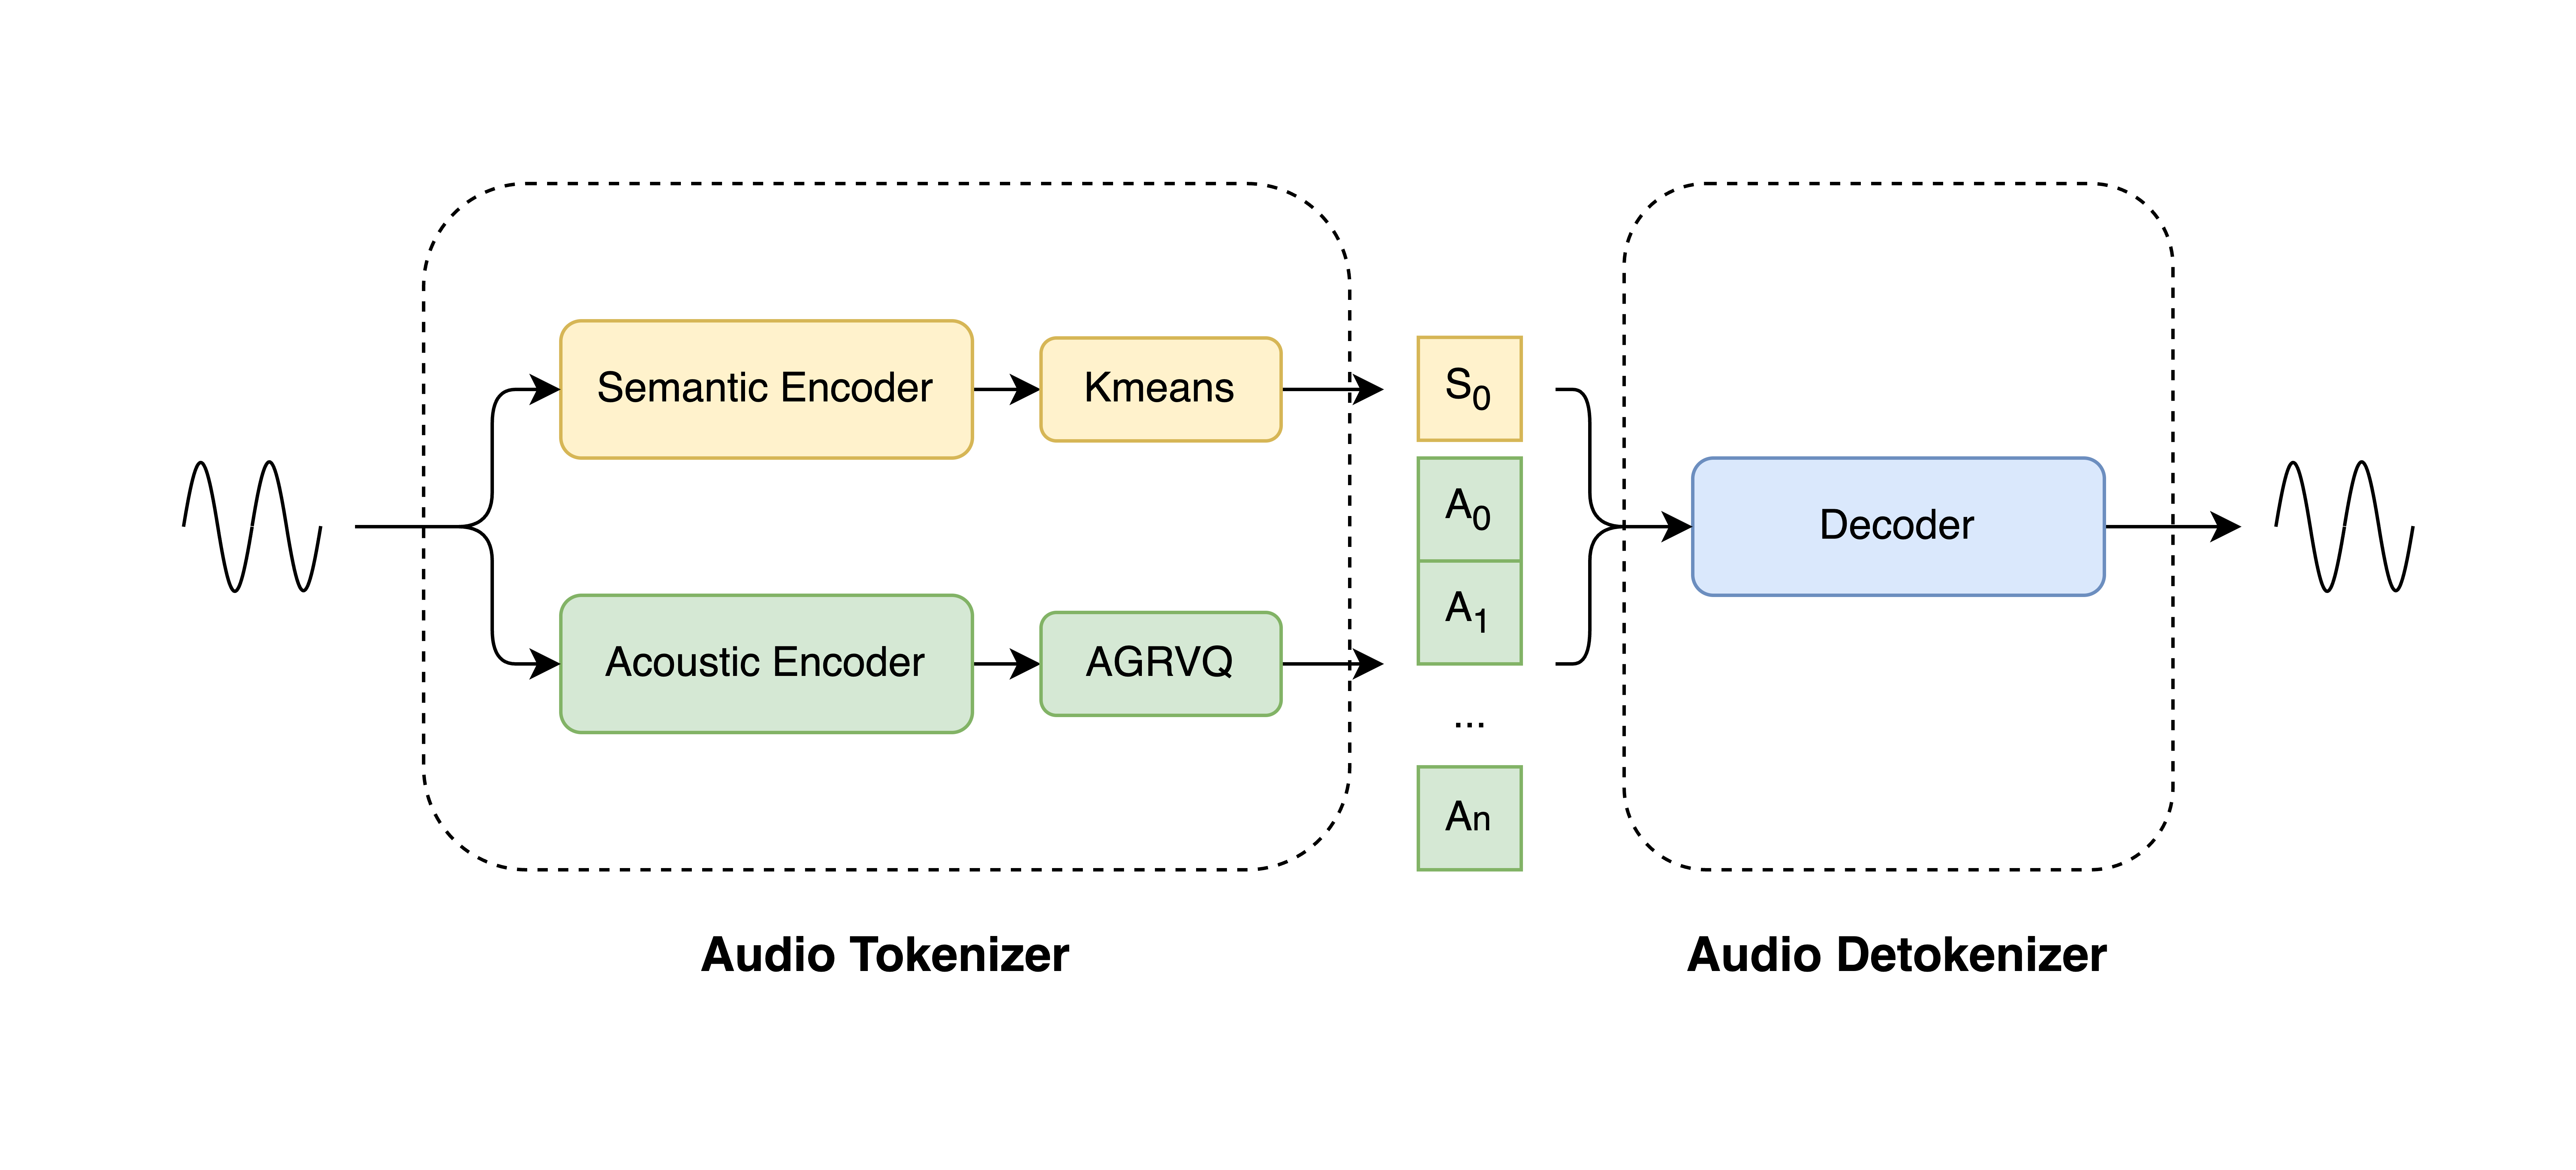
Author architecture (repository) · Source
Low Frame-rate Speech Codec (LFSC)
Reduces acoustic frame rate for speech language-model training and inference.
Paper · Code · Weights · Details
Audio: 22.05 kHz · Frame rate: 21.53 · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights NVIDIA Open Model License — The linked custom or noncommercial terms apply to this release.
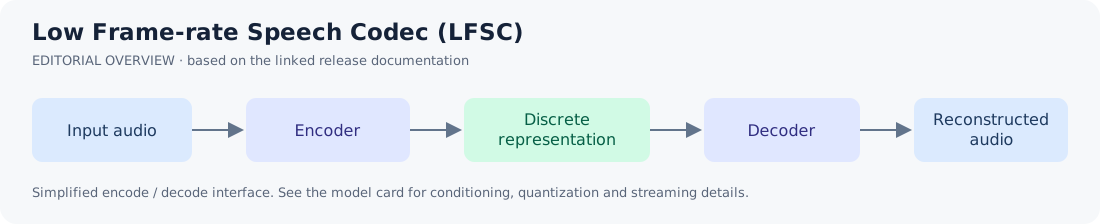
Editorial overview · Source
LTX-2 audio VAE
Encodes audio spectrograms into continuous latents and reconstructs stereo audio through the LTX-2 vocoder.
Audio: 16 kHz analysis → 24 kHz stereo output · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code LTX Community License (version-specific) · weights LTX-2 Community License — The linked noncommercial or custom terms apply to this release.
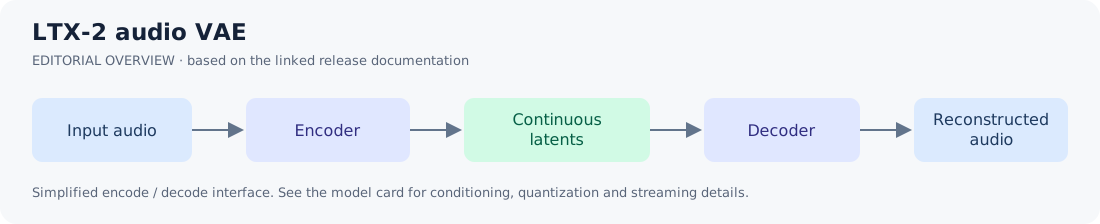
Editorial overview · Source
Lyra v2 (SoundStream-based)
Provides low-bitrate speech communication with bundled mobile inference models.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 (20 ms frames) · Nominal bitrate: 3.2 / 6 / 9.2 kbps
License unclear: code Apache-2.0 · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
MagiCodec
Produces low-rate speech tokens using masked Gaussian-injection training.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 · Nominal bitrate: ≤0.85 kbps
Open license: code MIT · weights MIT
Editorial overview · Source
Mimi
Provides streaming semantic and acoustic tokens for real-time spoken dialogue.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 12.5 · Nominal bitrate: 1.1 kbps (8 codebooks)
Open license: code MIT (Python); Apache-2.0 (Rust) · weights CC-BY-4.0
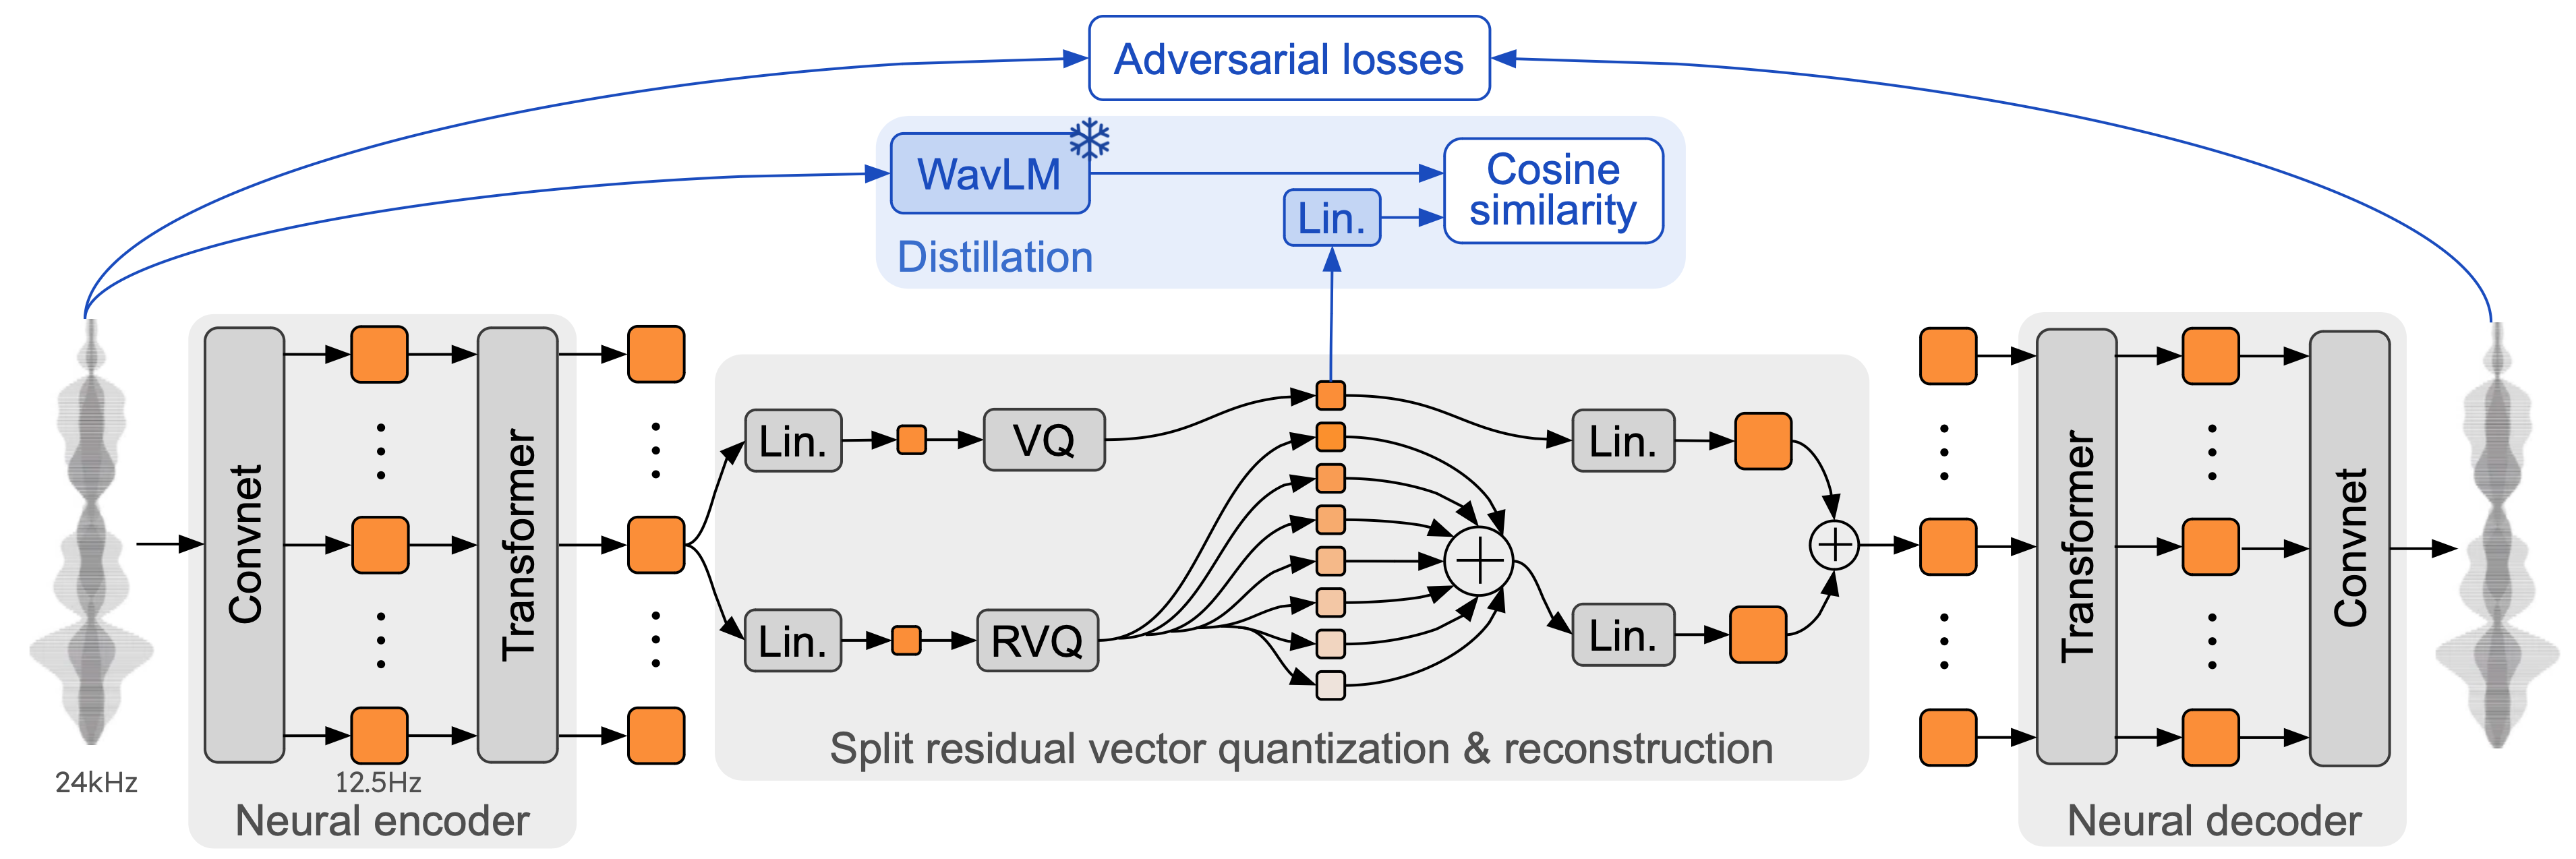
Author architecture (repository) · Source
MiMo-Audio-Tokenizer
Learns reconstructable audio tokens with joint semantic and acoustic objectives.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 25 · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights MIT
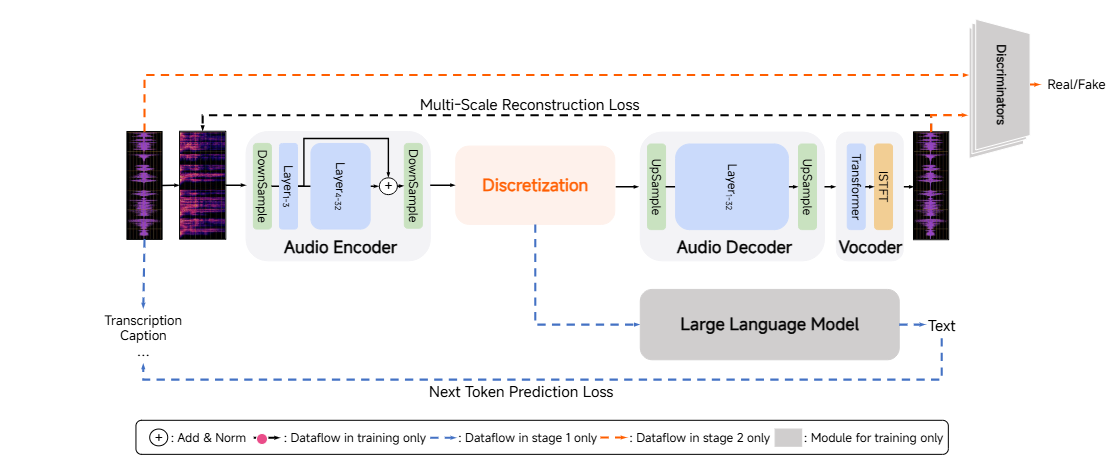
Author architecture (repository) · Source
Ming-omni-tts continuous tokenizer
Compresses speech, music and environmental audio into a shared continuous latent sequence.
Audio: 44.1 kHz · Frame rate: 12.5 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights Apache-2.0
Editorial overview · Source
MingTok-Audio
Provides continuous audio latents for joint speech understanding, generation and editing.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights Apache-2.0
Editorial overview · Source
MiniMax H3 AudioVAE
Compresses stereo audio into a continuous representation for MiniMax H3 audio generation.
Audio: 32 kHz mono; stereo channels processed separately · Frame rate: 40 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code Apache-2.0 · weights MiniMax H3 Community License — The reviewed Diffusers codec implementation is Apache-2.0; the publisher’s checkpoint uses the MiniMax H3 Community License.
Editorial overview · Source
MMAudio VAE (16 / 44.1 kHz)
Encodes mel spectrograms into continuous audio latents and reconstructs waveforms with BigVGAN.
Paper · Code · Weights · Details
Audio: 16 / 44.1 kHz · Frame rate: 31.25 (16 kHz); ~43.07 (44.1 kHz) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code MIT · weights CC-BY-NC-4.0 — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
MOSS-Audio-Tokenizer
Provides low-rate semantic/acoustic tokens across speech, music and sound effects.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 12.5 · Nominal bitrate: 0.125–4 kbps
Open license: code Apache-2.0 · weights Apache-2.0
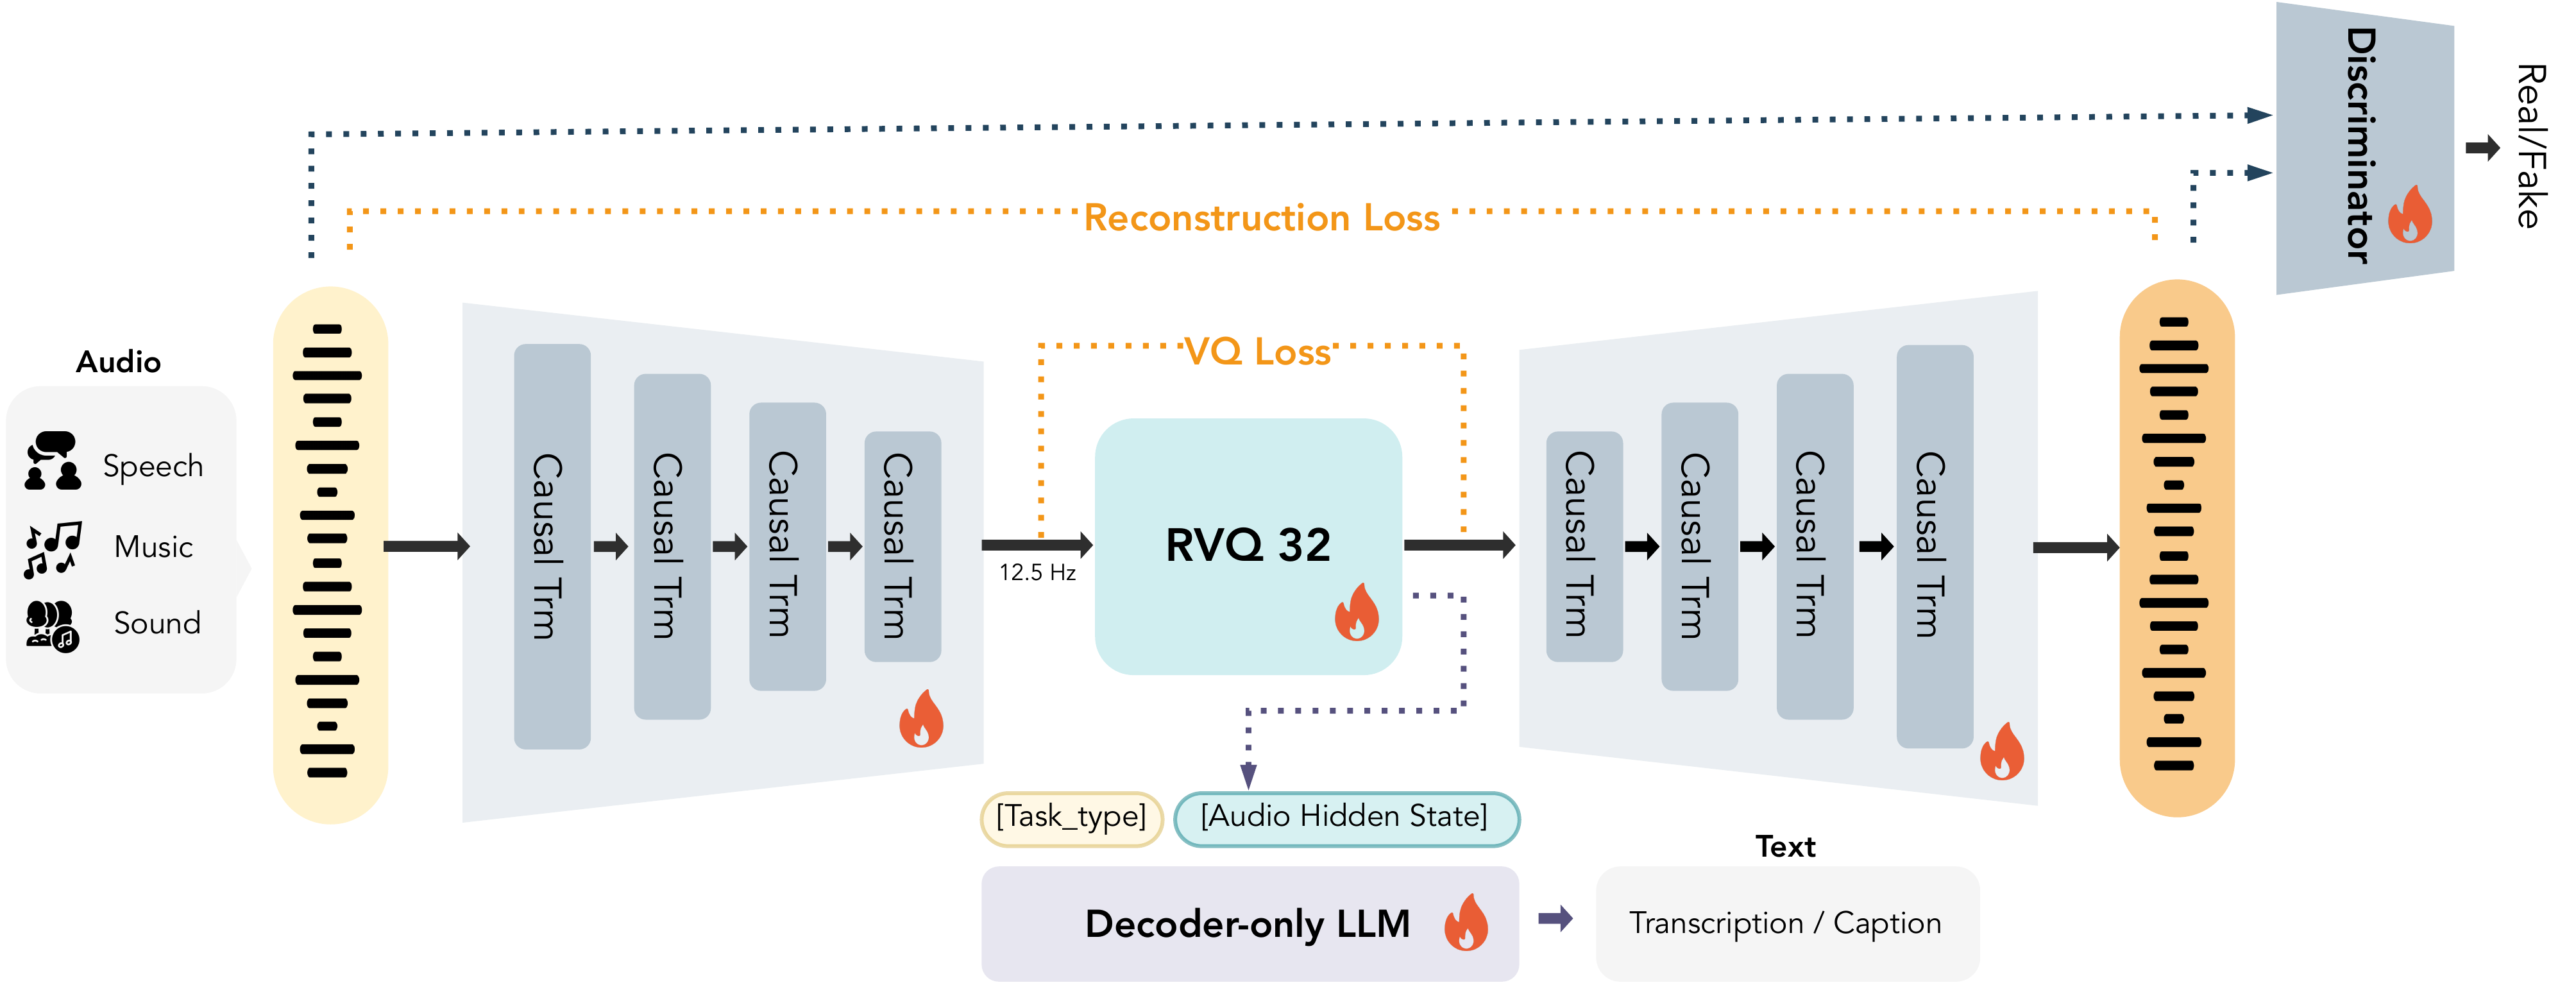
Author architecture (repository) · Source
MOSS-Audio-Tokenizer Nano
Provides a compact stereo audio codec for lower-cost deployment.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 12.5 · Nominal bitrate: 0.125–2 kbps
Open license: code Apache-2.0 · weights Apache-2.0
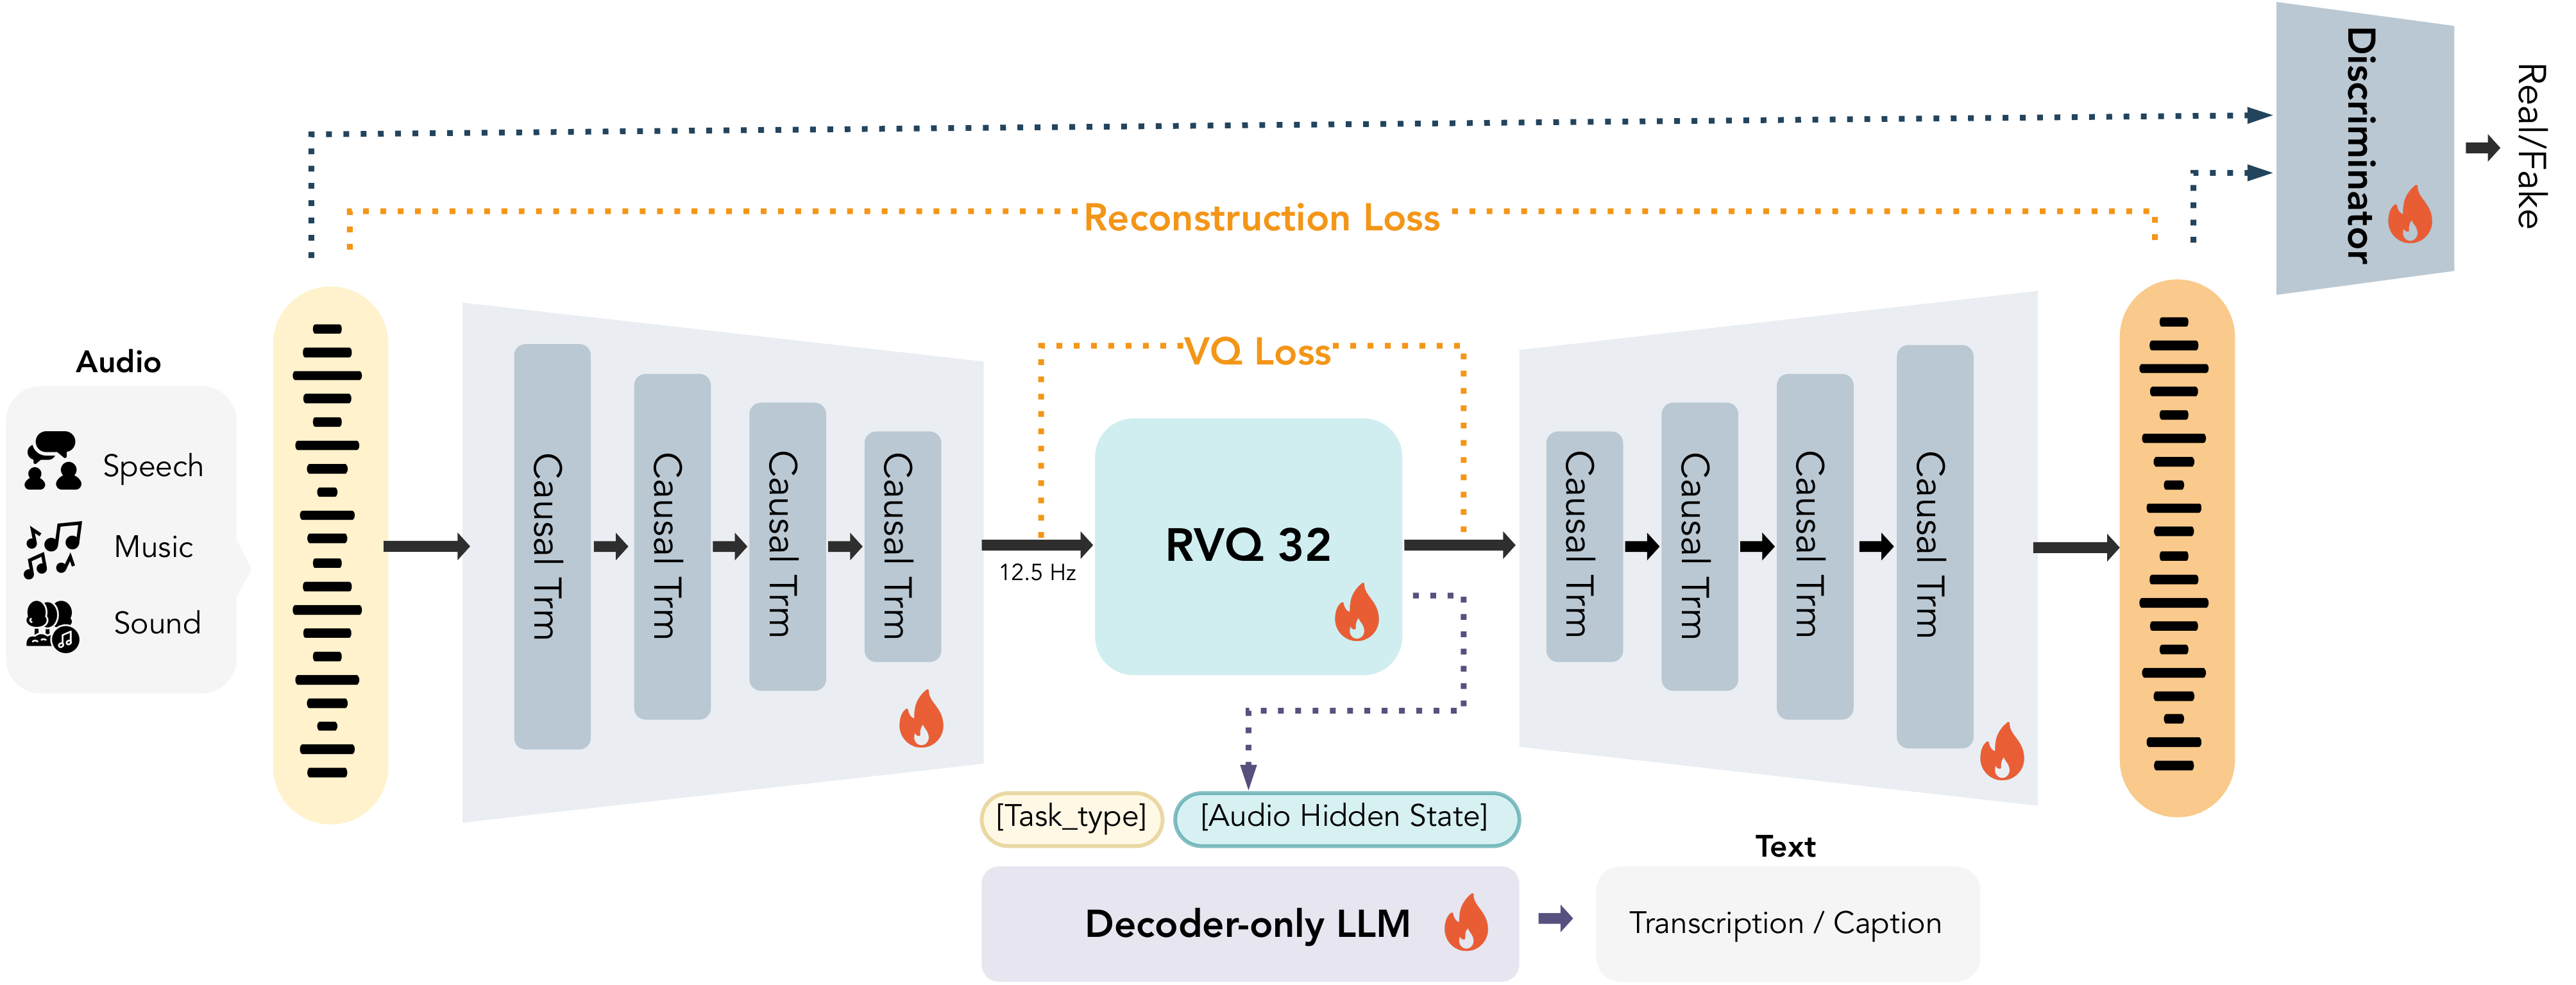
CAT family architecture (shared; variant details in model card) · Source
MOSS-Audio-Tokenizer v2
Extends the MOSS codec interface to native stereo audio at 48 kHz.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 12.5 · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
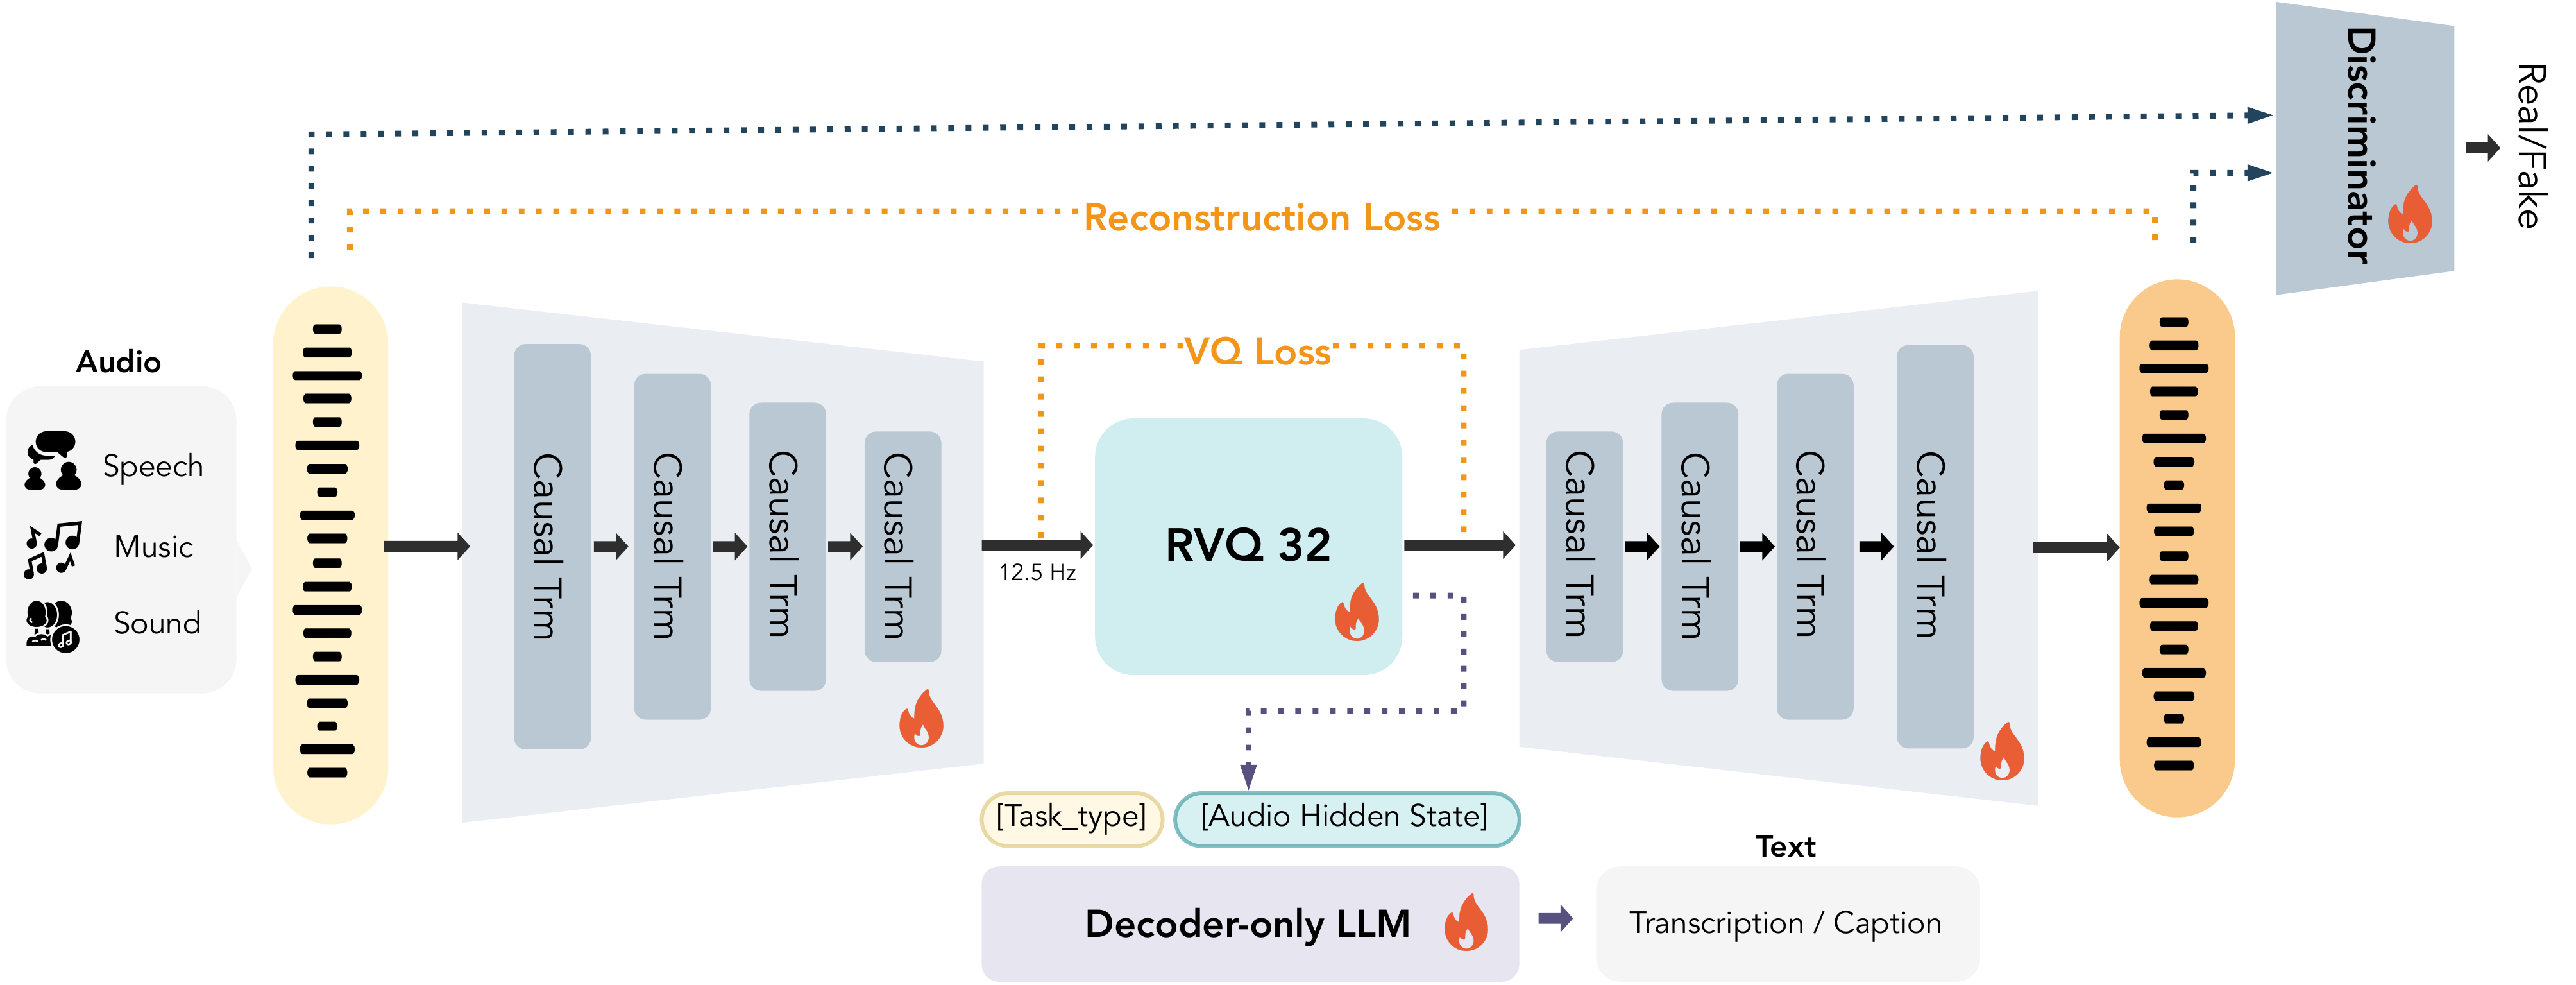
CAT family architecture (shared; variant details in model card) · Source
MuCodec
Reconstructs stereo music from an ultra-low-bitrate representation.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: Not specified · Nominal bitrate: 0.35 kbps (released configuration)
Custom / restricted: code MIT · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
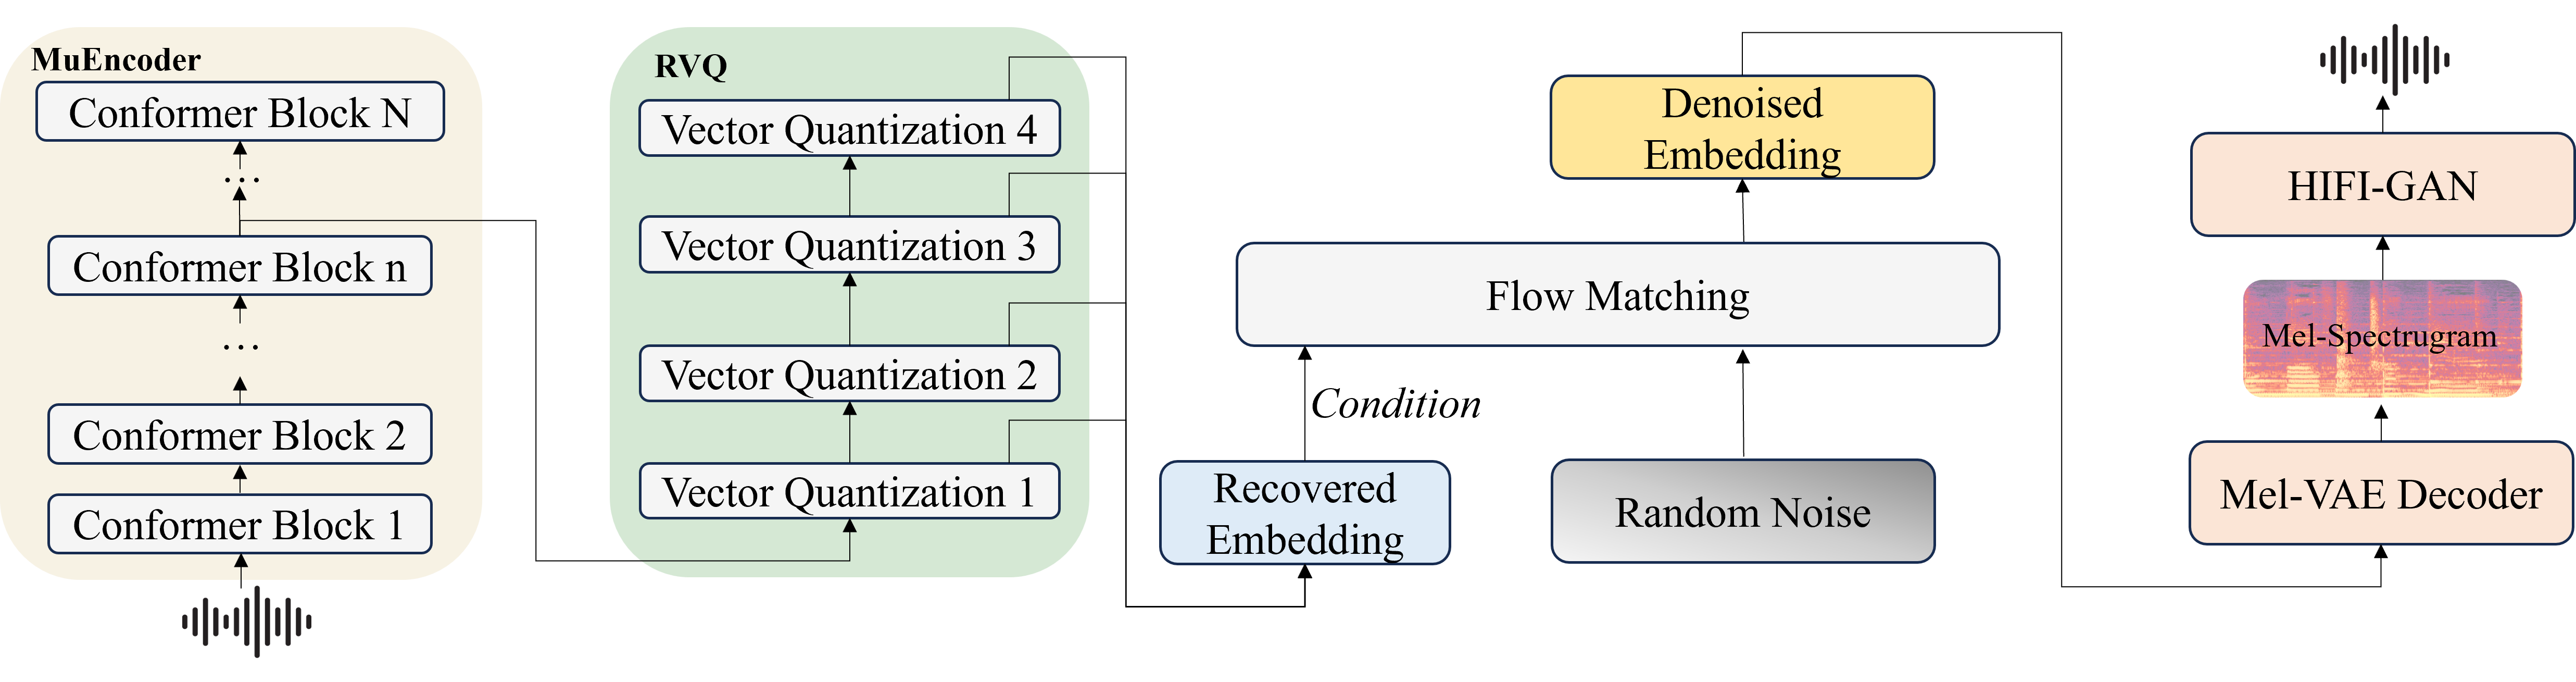
Fig. 1 · Source
Music2Latent
Encodes music and speech into compact continuous latents and reconstructs the waveform.
Paper · Code · Weights · Details
Audio: 44.1 kHz (also 48 kHz) · Frame rate: ~10 (44.1 kHz); ~12 (48 kHz) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
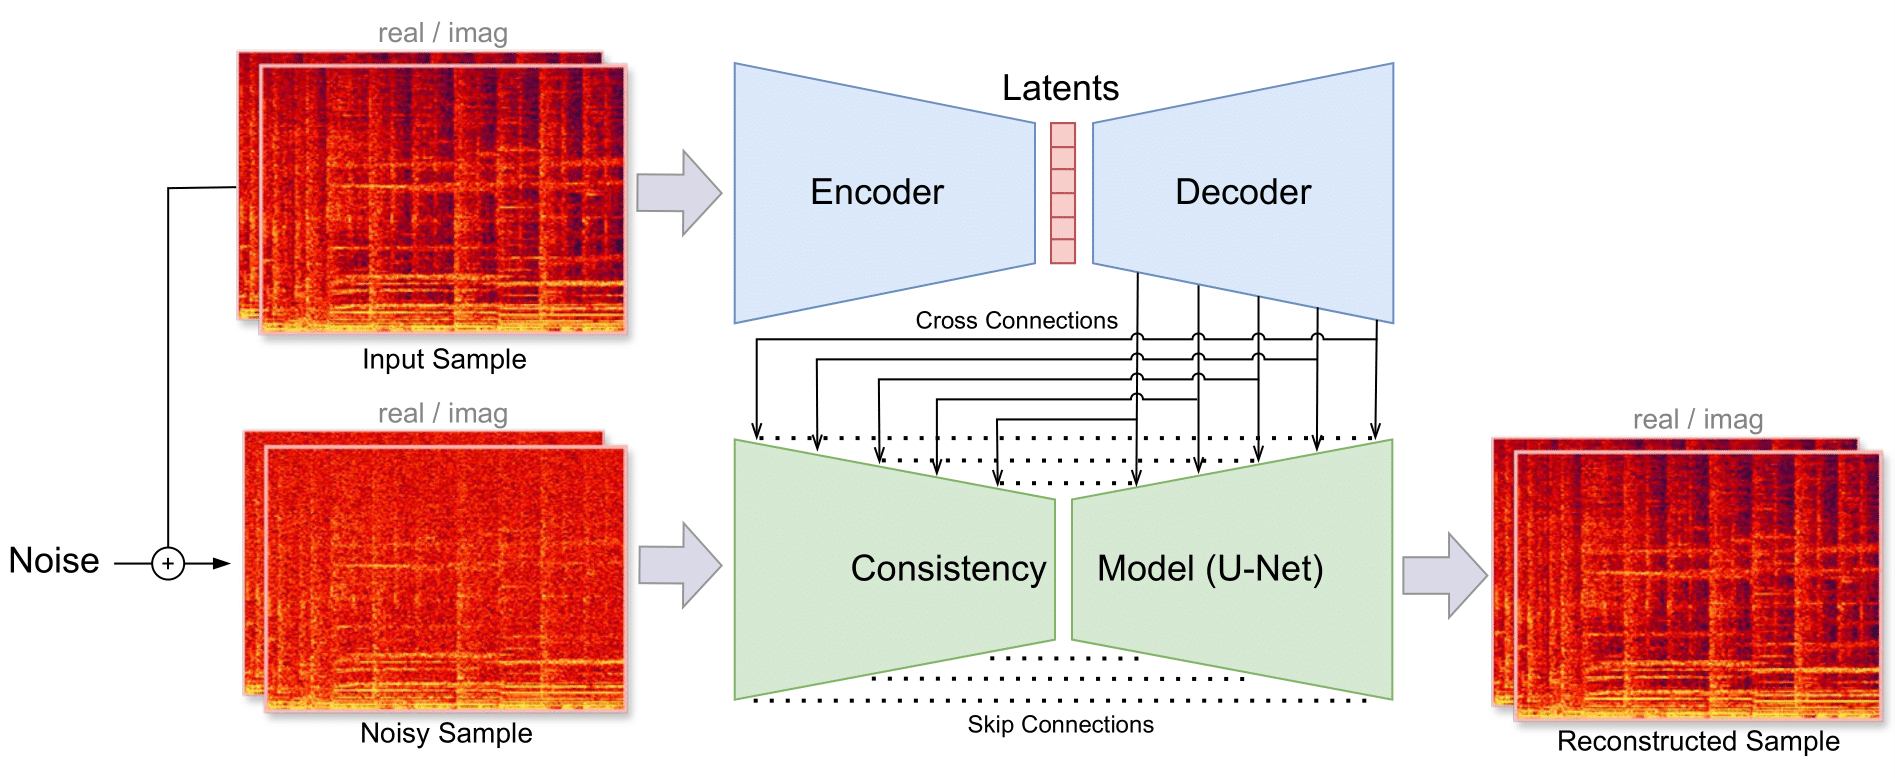
Author architecture (repository) · Source
Musika autoencoder
Builds a compact, hierarchical continuous representation for waveform music reconstruction.
Paper · Code · Weights · Details
Audio: 44.1 kHz (released model card) · Frame rate: ~10.77 (final stage) · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
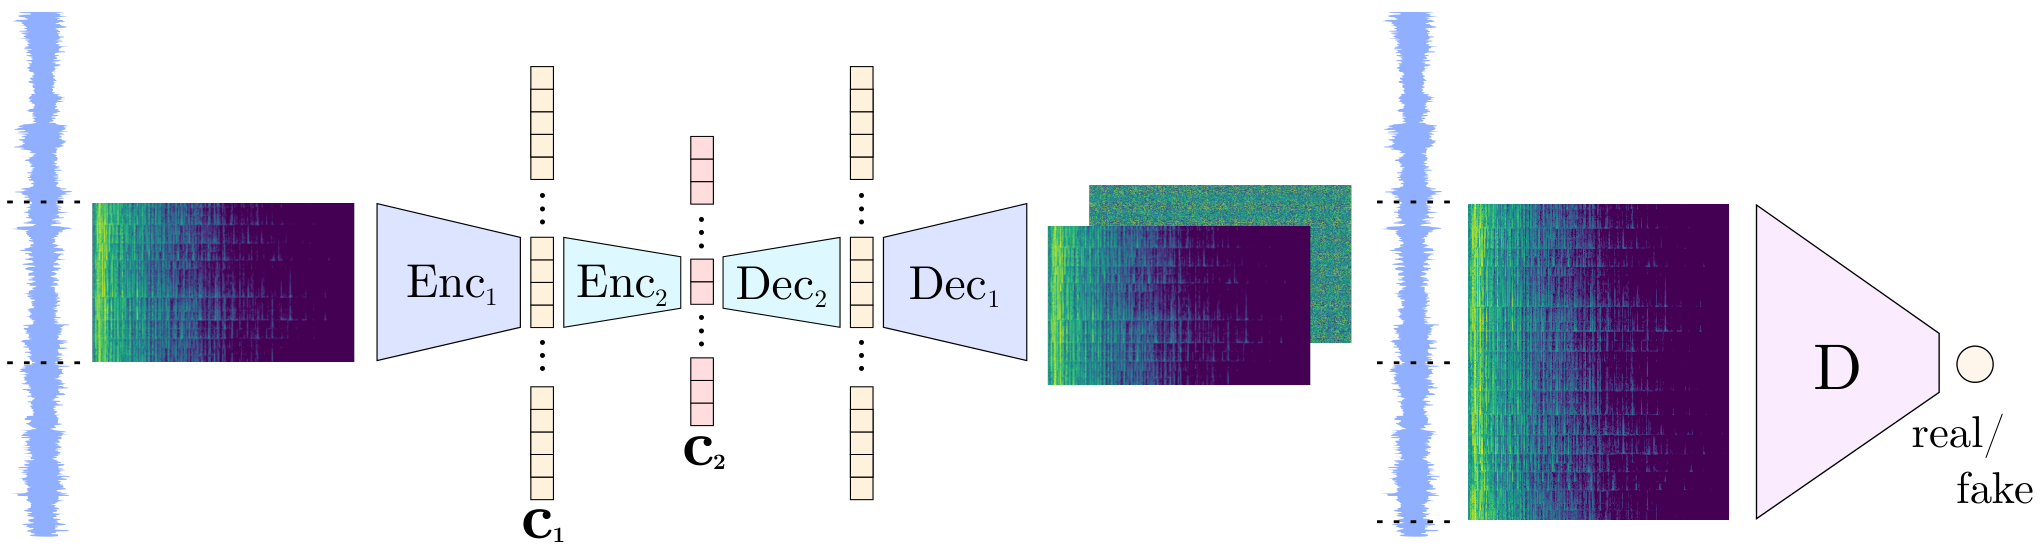
Figure 1 — two-stage audio autoencoder · Source
NanoCodec
Provides low-frame-rate speech tokens with a compact, fast decoder.
Paper · Code · Weights · Details
Audio: 22.05 kHz · Frame rate: 12.5 (also 21.5) · Nominal bitrate: 1.78 kbps (also 1.89)
Custom / restricted: code Apache-2.0 · weights NVIDIA Open Model License — The linked custom or noncommercial terms apply to this release.
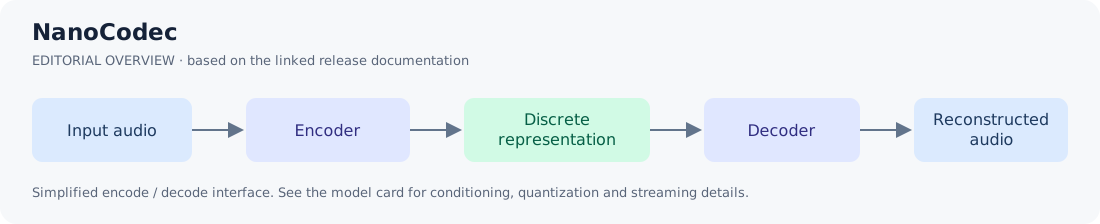
Editorial overview · Source
NeuCodec
Compresses speech into one token stream and reconstructs it at a higher sample rate.
Paper · Code · Weights · Details
Audio: 16 kHz input → 24 kHz output · Frame rate: 50 · Nominal bitrate: 0.8 kbps
Open license: code Apache-2.0 · weights Apache-2.0
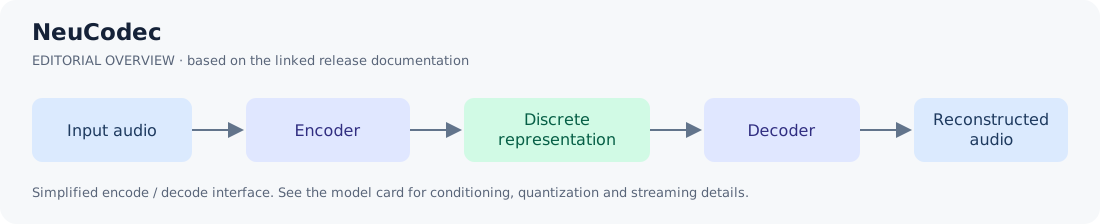
Editorial overview · Source
Omni2Sound OOB/Wav VAE
Provides a waveform latent representation for the audio path of Omni2Sound.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 25 (paper configuration) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
OmniVAE audio-only
Provides an independently usable audio VAE within the OmniVAE release.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
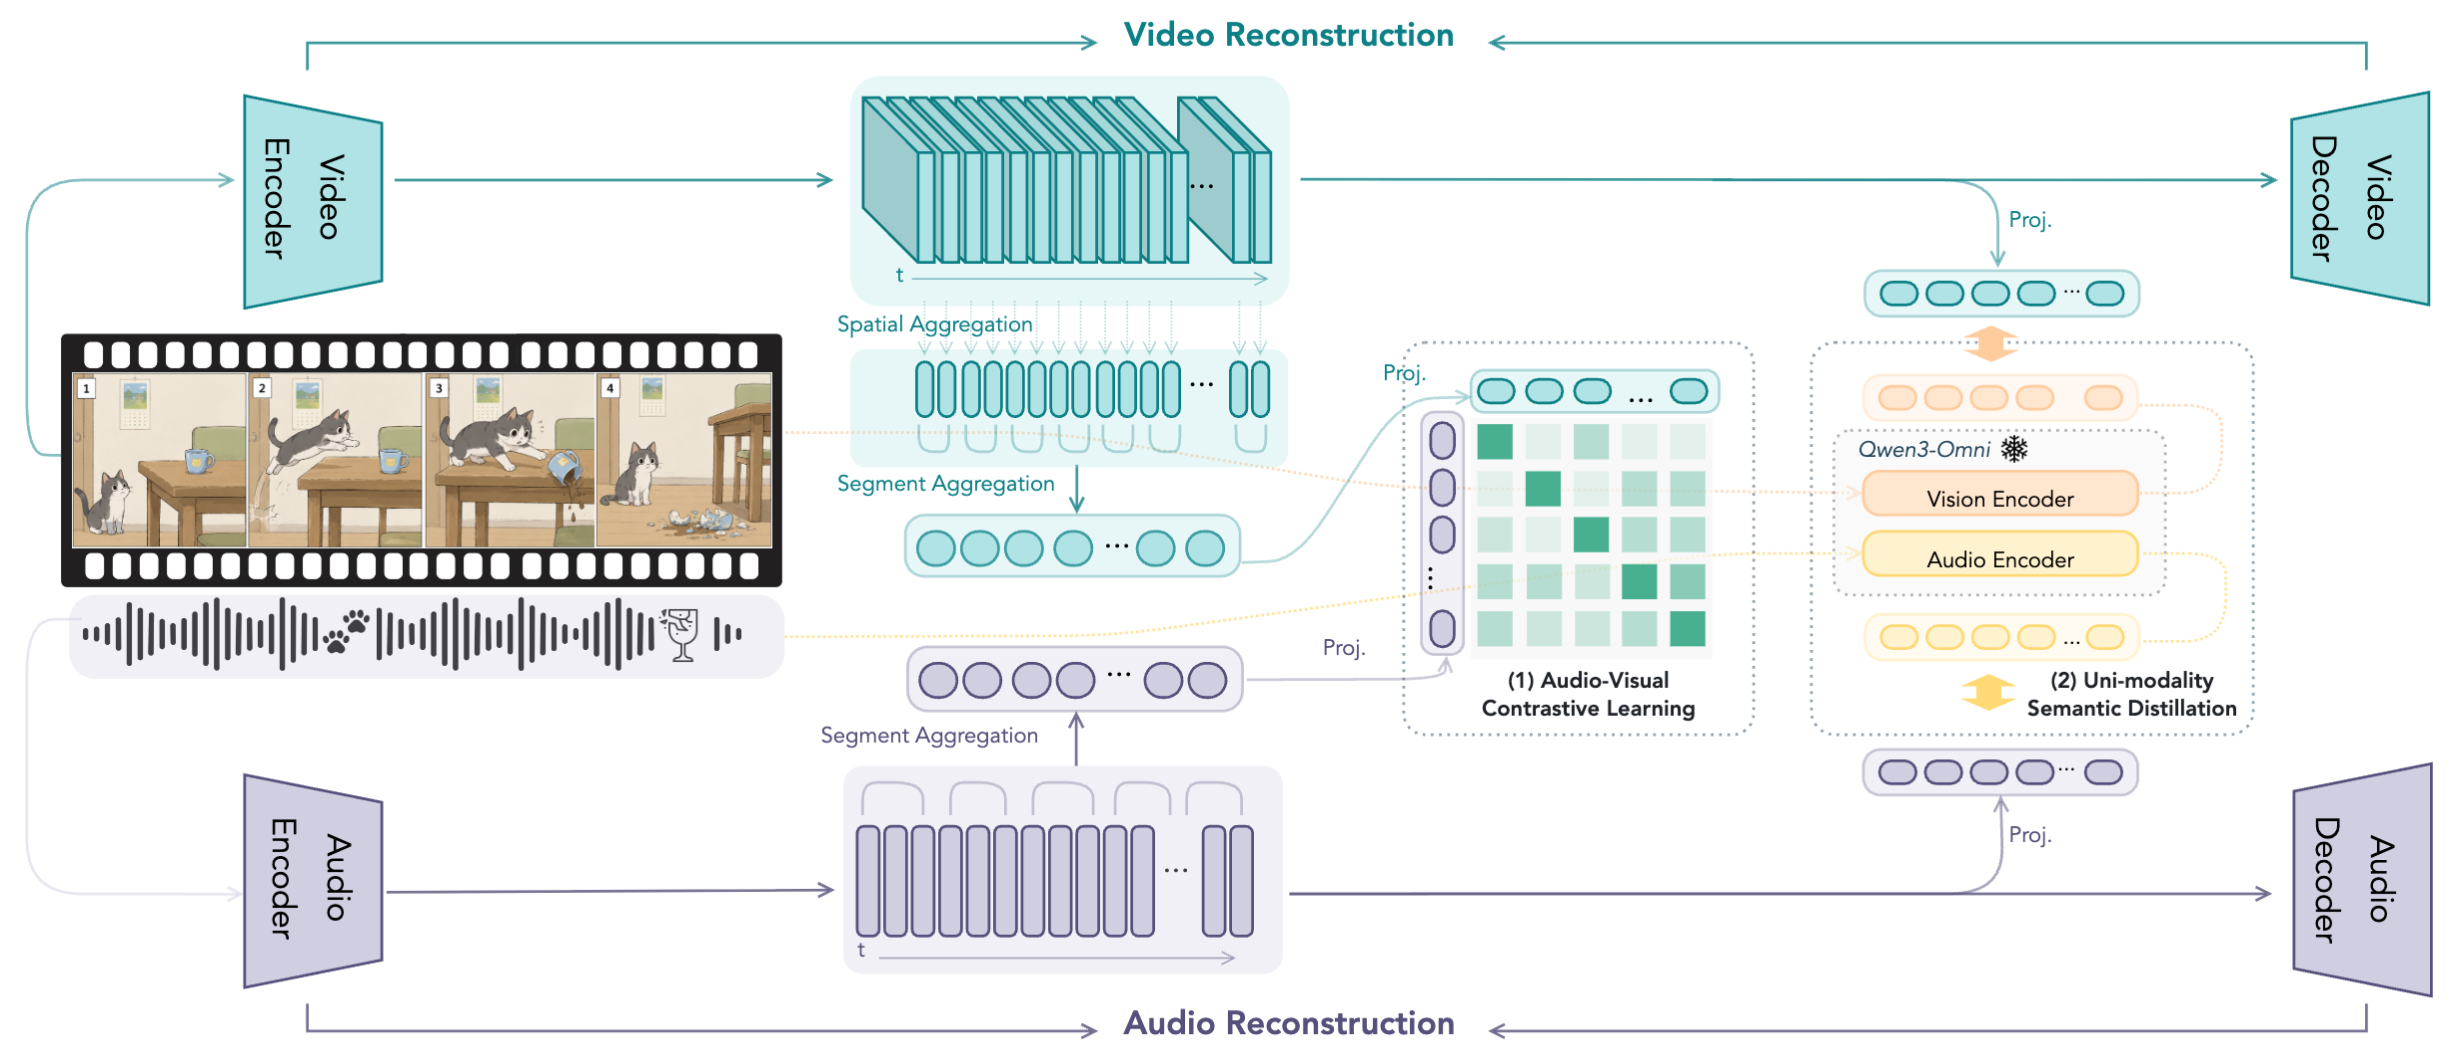
OmniVAE family architecture; this card covers the audio-only checkpoint · Source
PAST
Learns phonetic and acoustic speech tokens jointly with waveform reconstruction.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
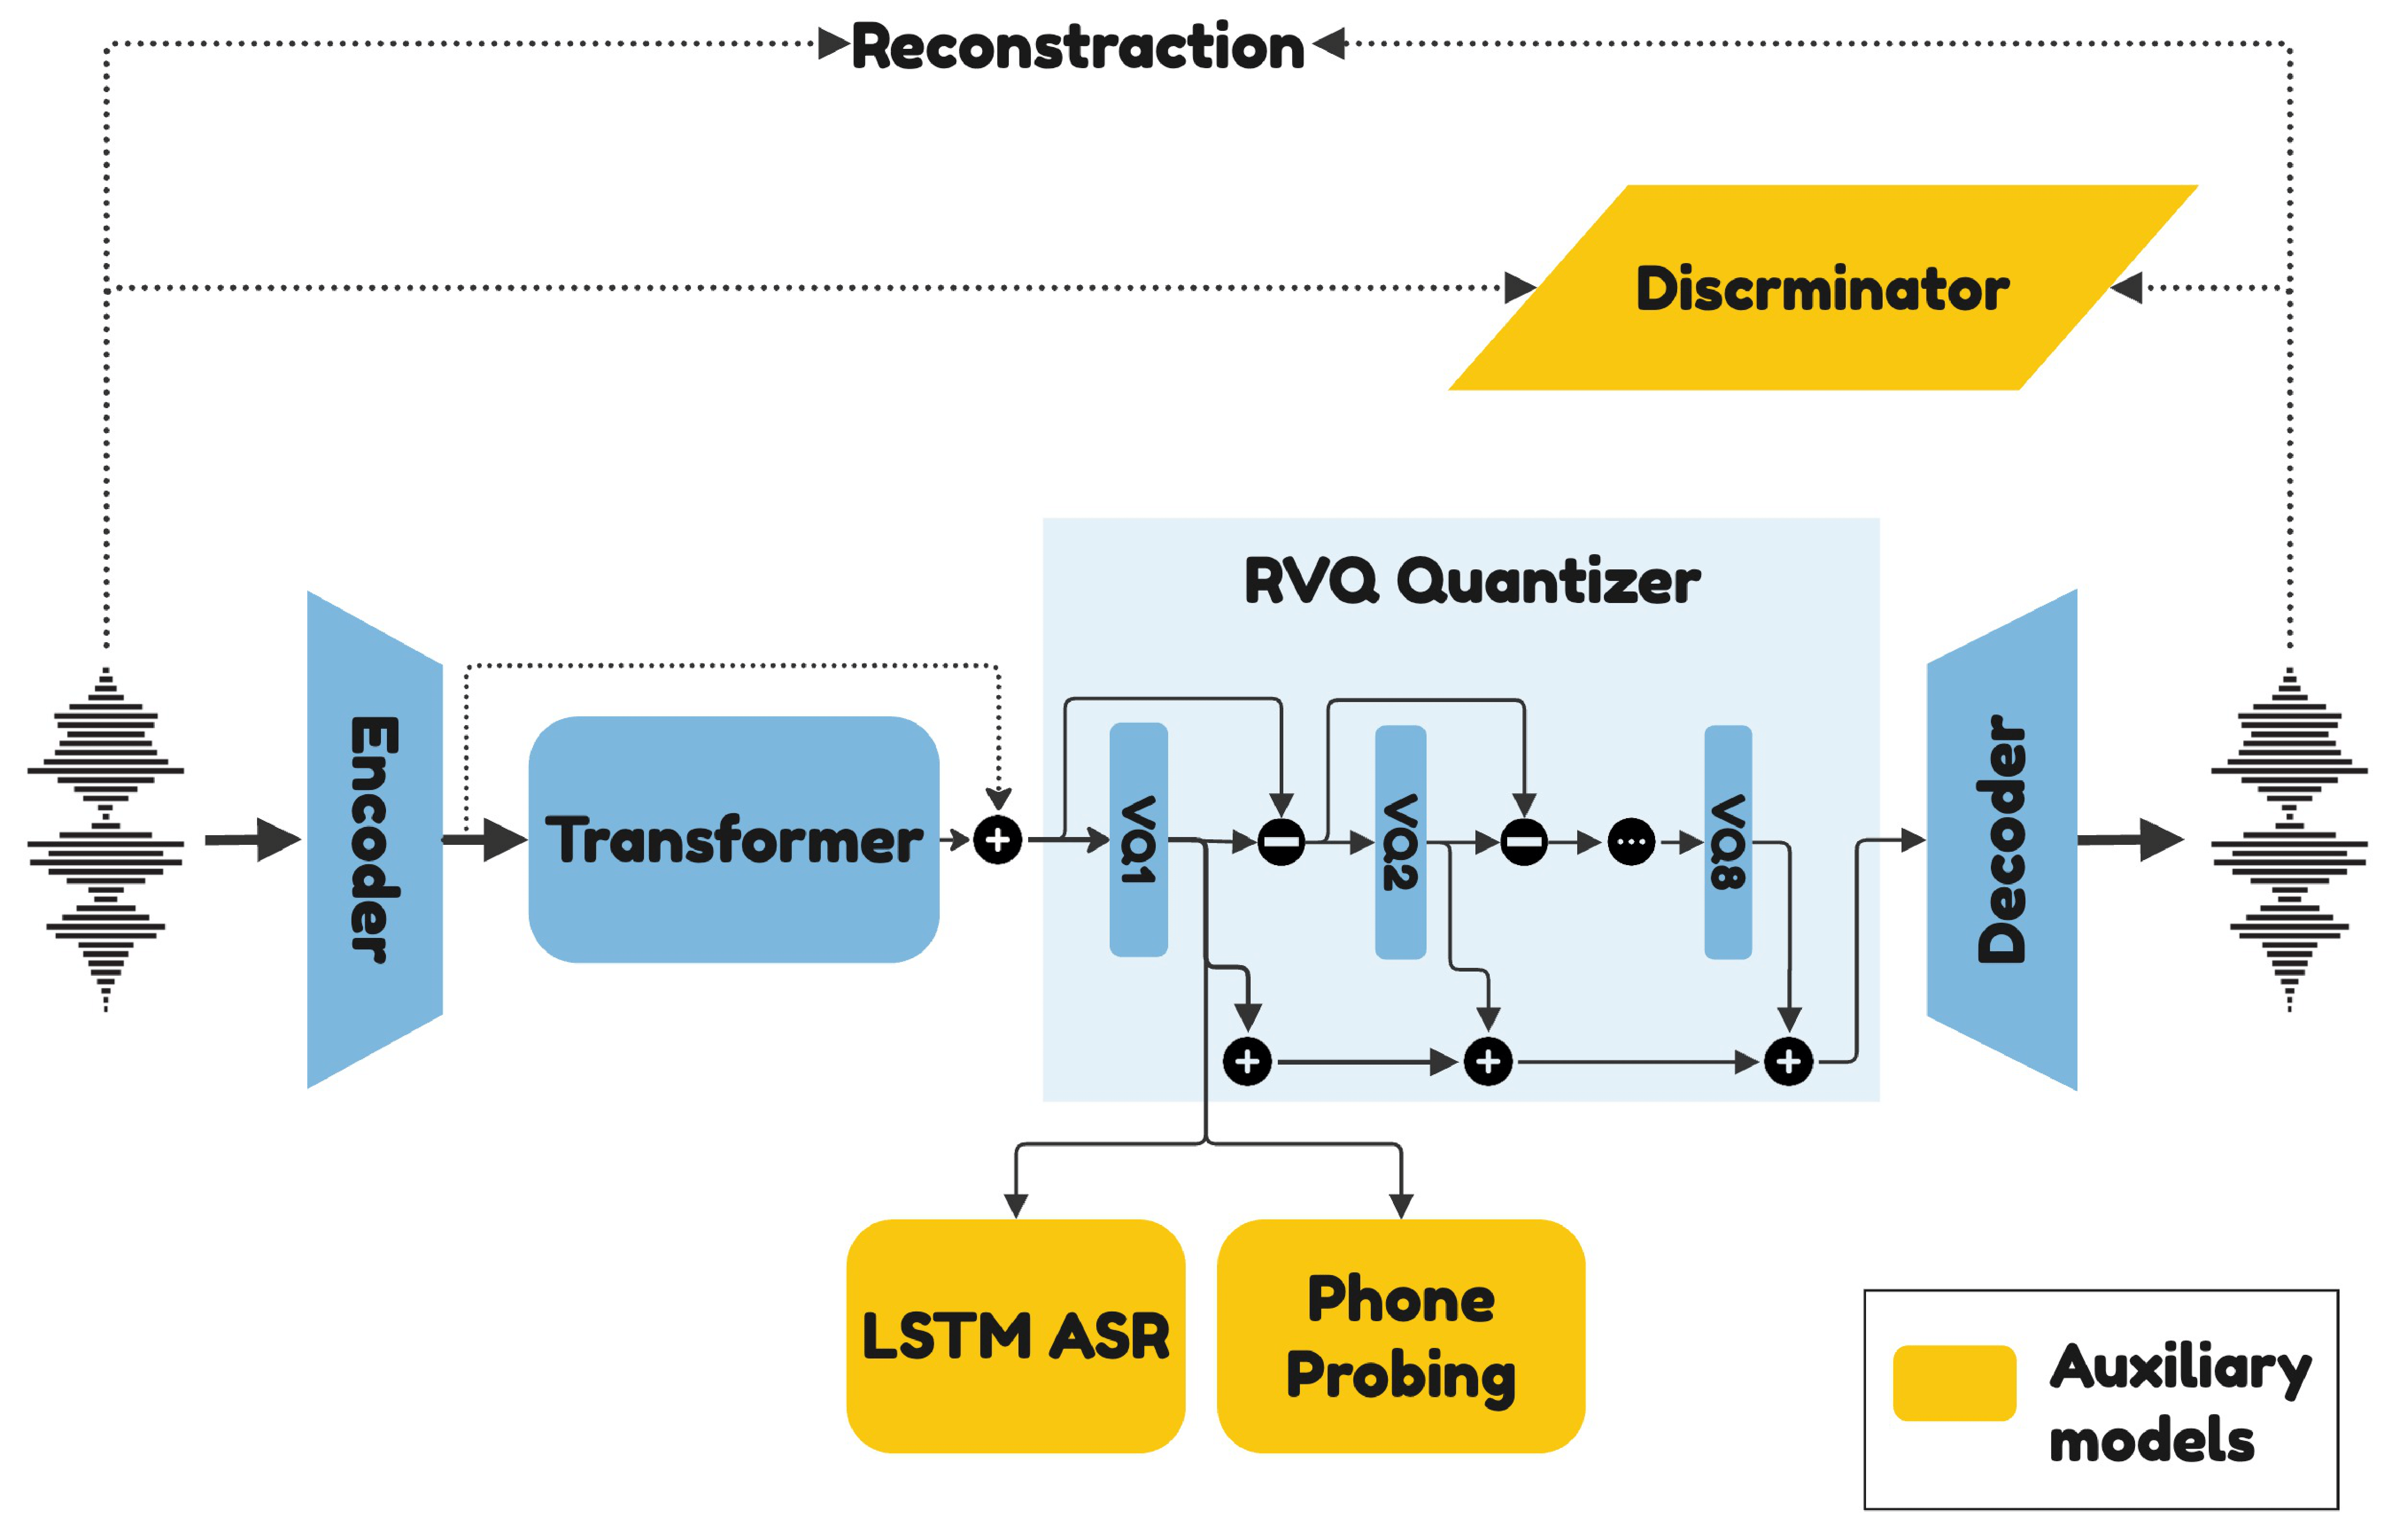
Author architecture (repository) · Source
Qwen3-TTS-Tokenizer-12Hz
Encodes and reconstructs speech using low-rate, multi-codebook tokens.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 12.5 · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
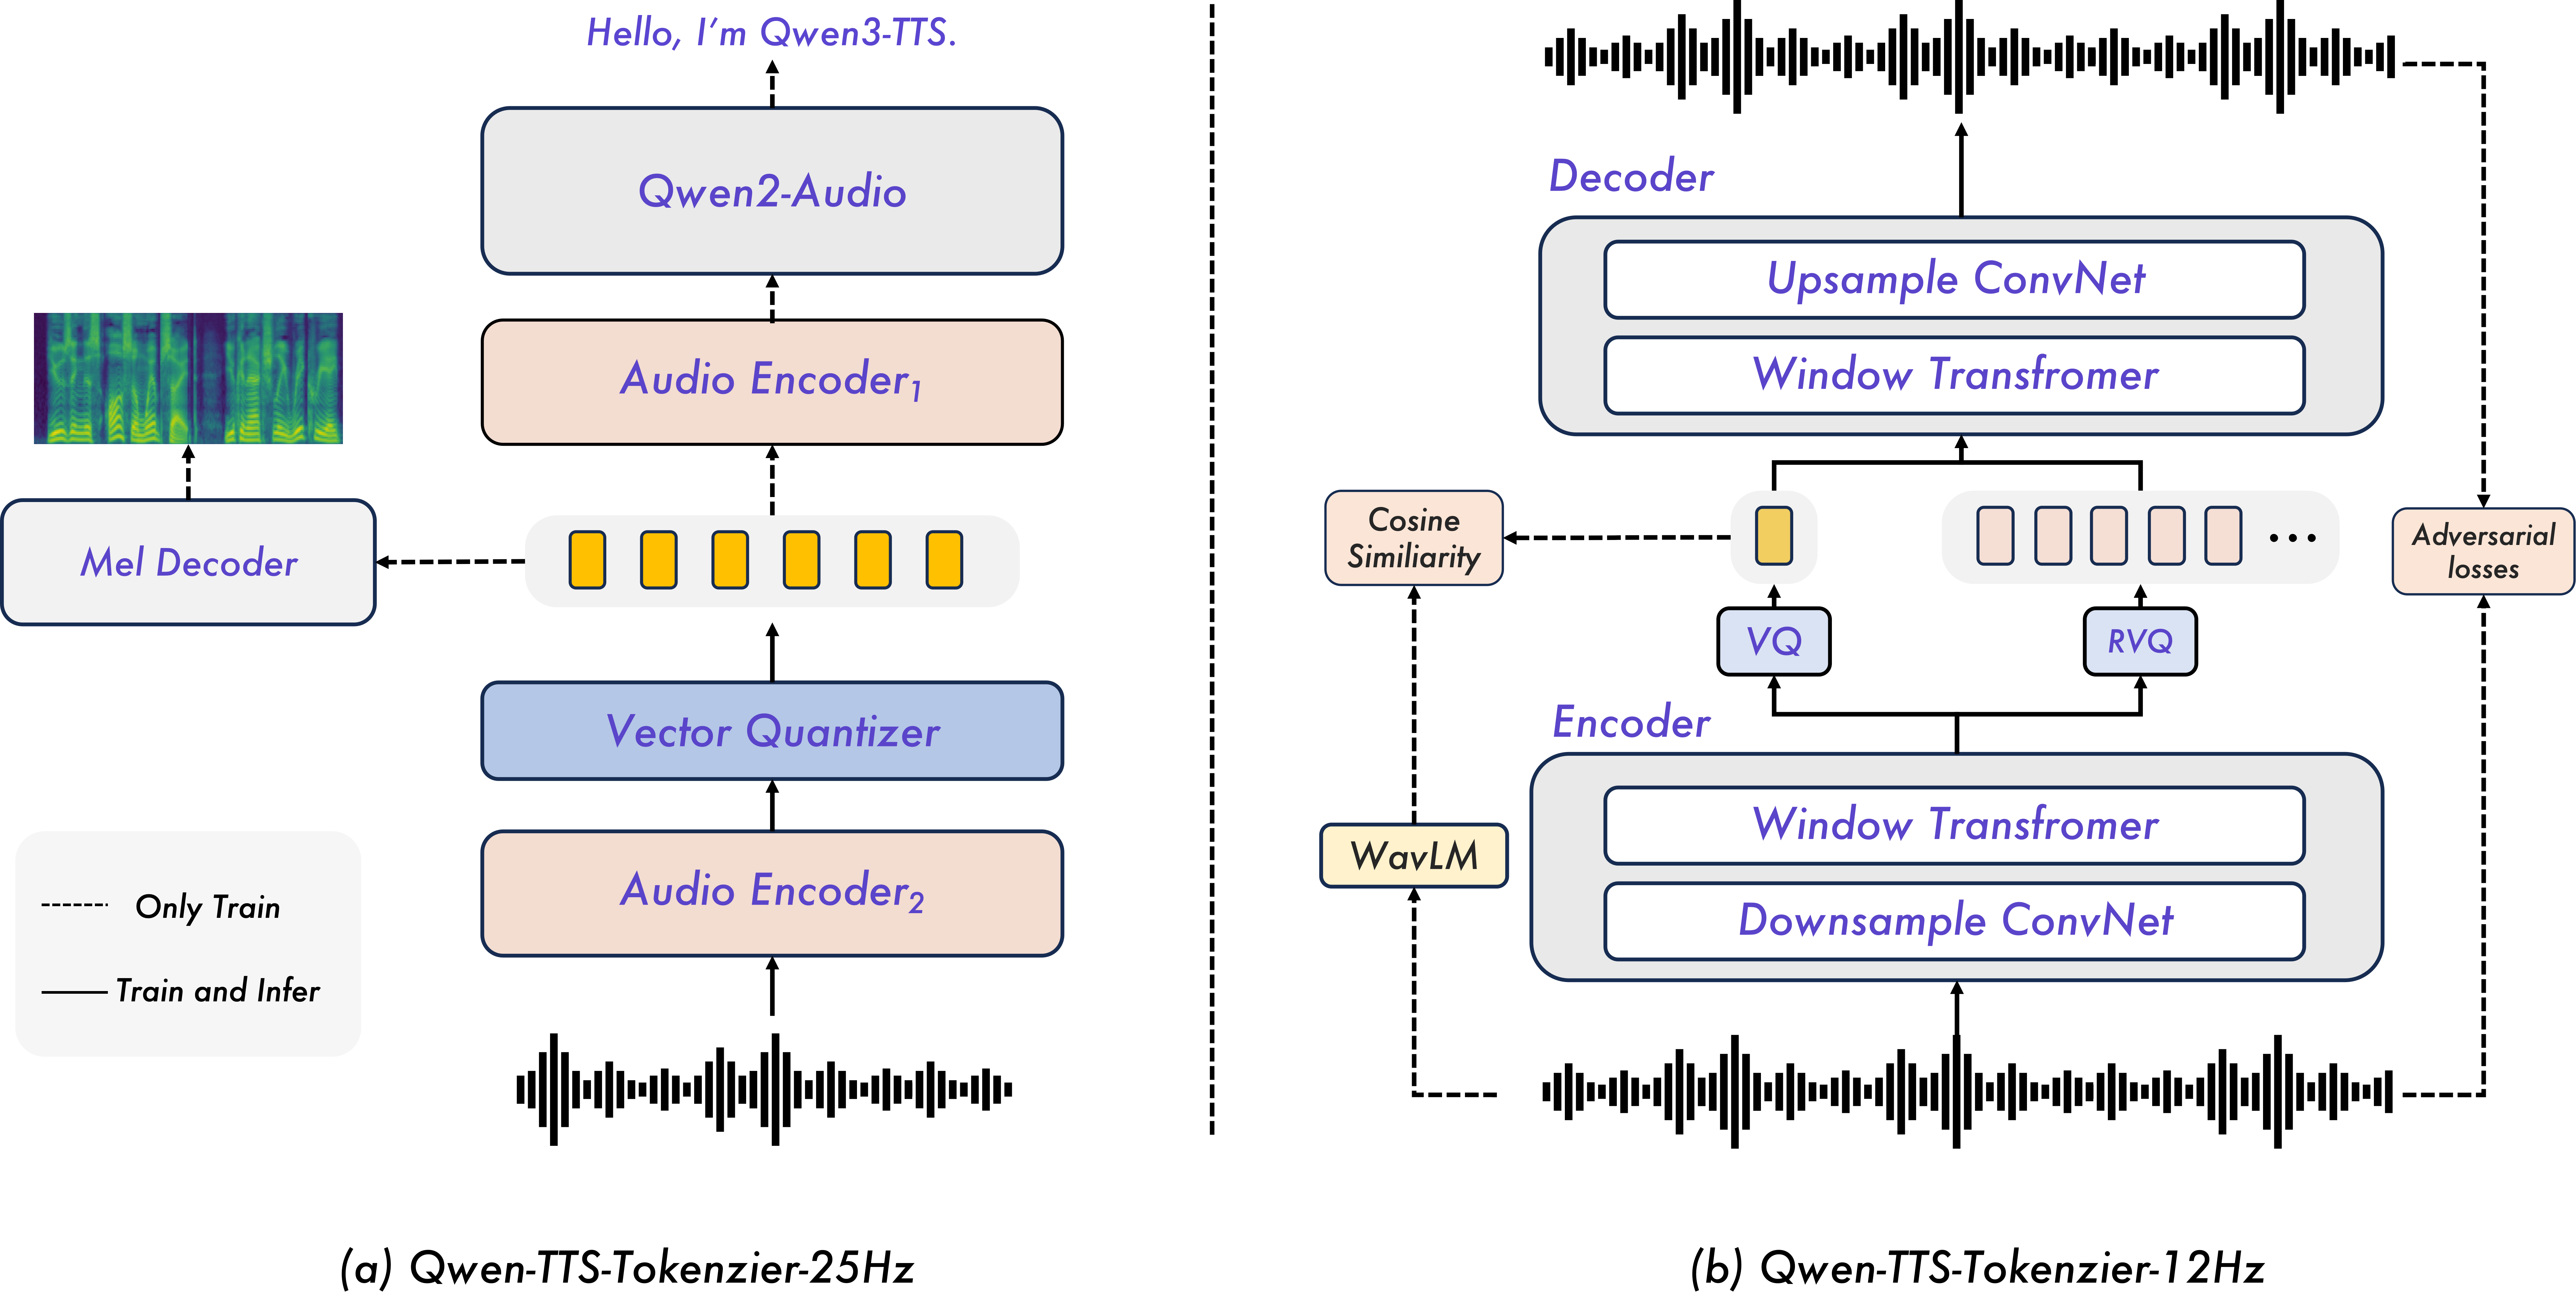
Figure 2 — tokenizer family overview; 12.5 Hz variant · Source
RAVE (v1 / v2)
Provides variational audio encoders and decoders for reconstruction, timbre transfer and real-time audio processing.
Paper · Code · Weights · Details
Audio: Checkpoint-specific; not independently established · Frame rate: Not specified · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-4.0 · weights Not stated on the inspected download catalog — The code has noncommercial terms. The inspected author download catalog does not separately state the MusicNet checkpoint license.
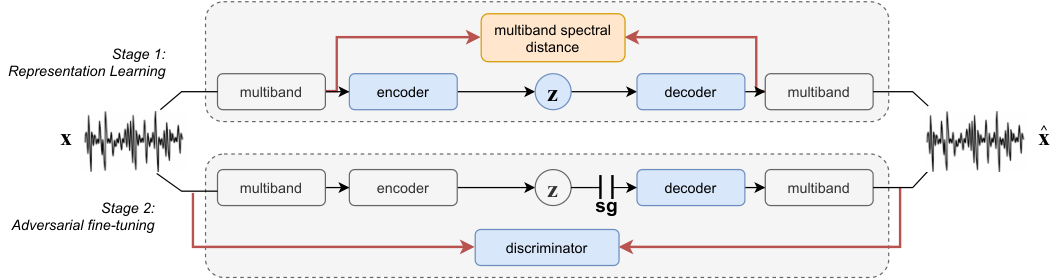
Figure 1 — original RAVE family architecture · Source
SAC
Uses separate semantic and acoustic quantization streams for speech reconstruction.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 37.5 / 62.5 · Nominal bitrate: 0.525 / 0.875 kbps
Open license: code Apache-2.0 · weights Apache-2.0
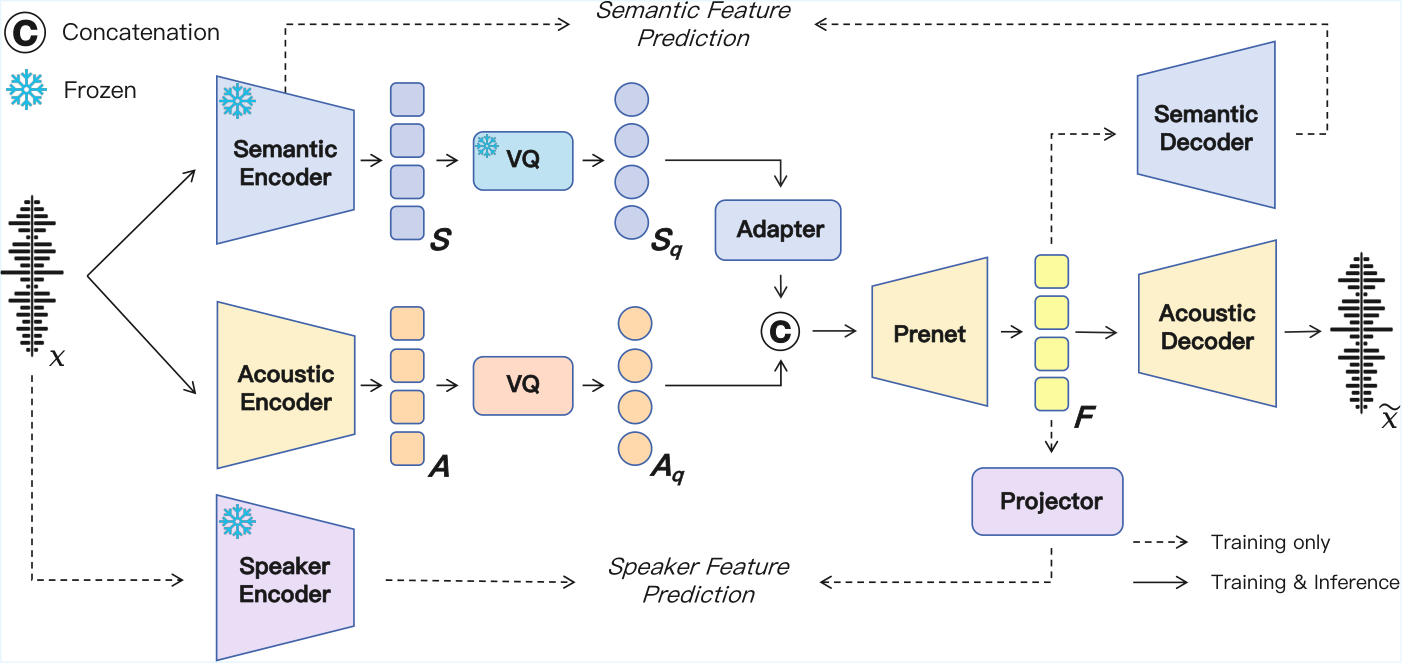
Figure 2 · Source
SAME (S / L)
Compresses stereo audio into semantically aligned continuous latents with transformer-based encoders and decoders.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo · Frame rate: ~10.77 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code MIT · weights Stability AI Community License — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
Semantic-VAE
Aligns continuous speech latents with semantic information for speech synthesis.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 40 · Nominal bitrate: Not applicable: continuous latents
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
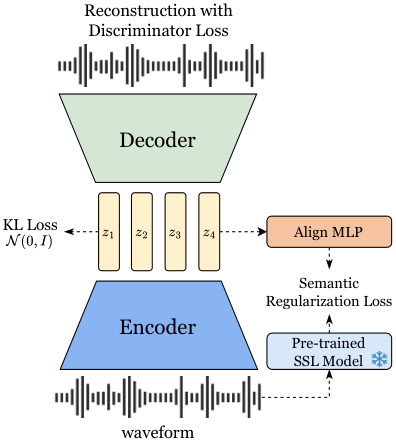
Figure 2 · Source
SemantiCodec
Compresses general audio into semantic and acoustic tokens with diffusion reconstruction.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: See total token-rate variants · Nominal bitrate: ~0.31–1.40 kbps
Open license: code MIT · weights MIT
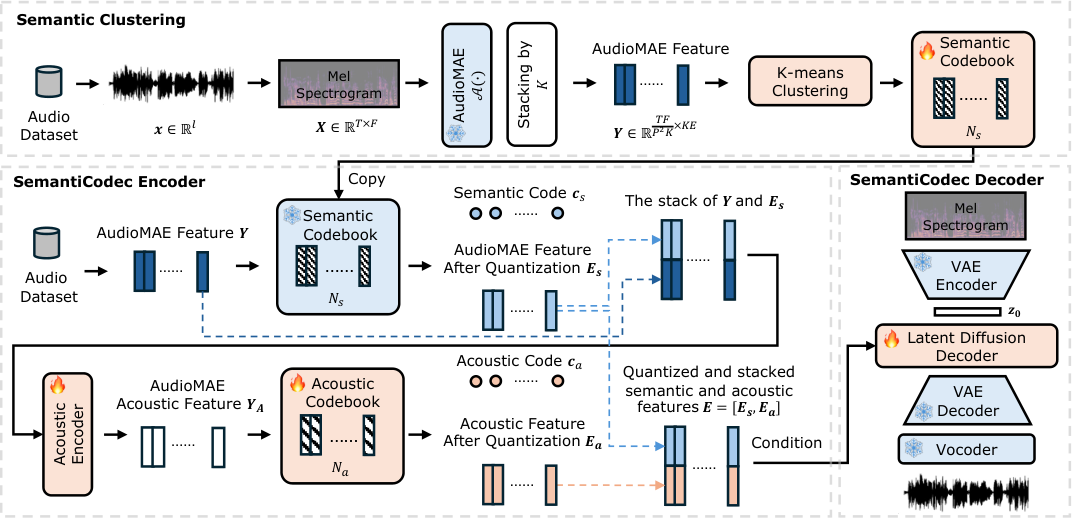
Fig. 2 · Source
SimWhisper-Codec
Uses a simplified Whisper-based representation for low-bitrate speech coding.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
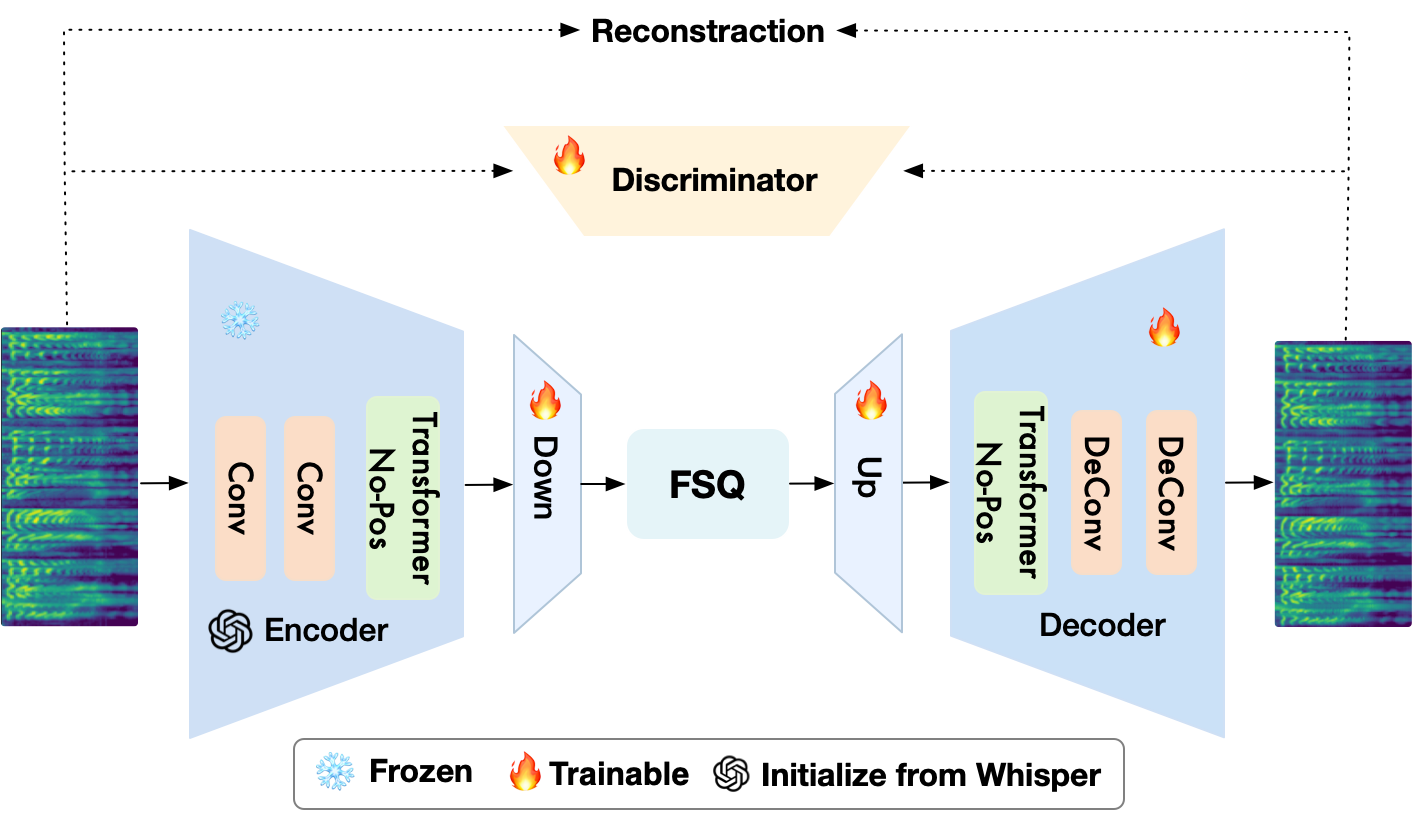
Author architecture (repository) · Source
SNAC
Uses coarse and fine token streams at different time scales to shorten audio token sequences.
Paper · Code · Weights · Details
Audio: 24 kHz speech; 32 / 44.1 kHz audio · Frame rate: Multiple temporal scales · Nominal bitrate: 0.98 / 1.9 / 2.6 kbps by variant
Open license: code MIT · weights MIT
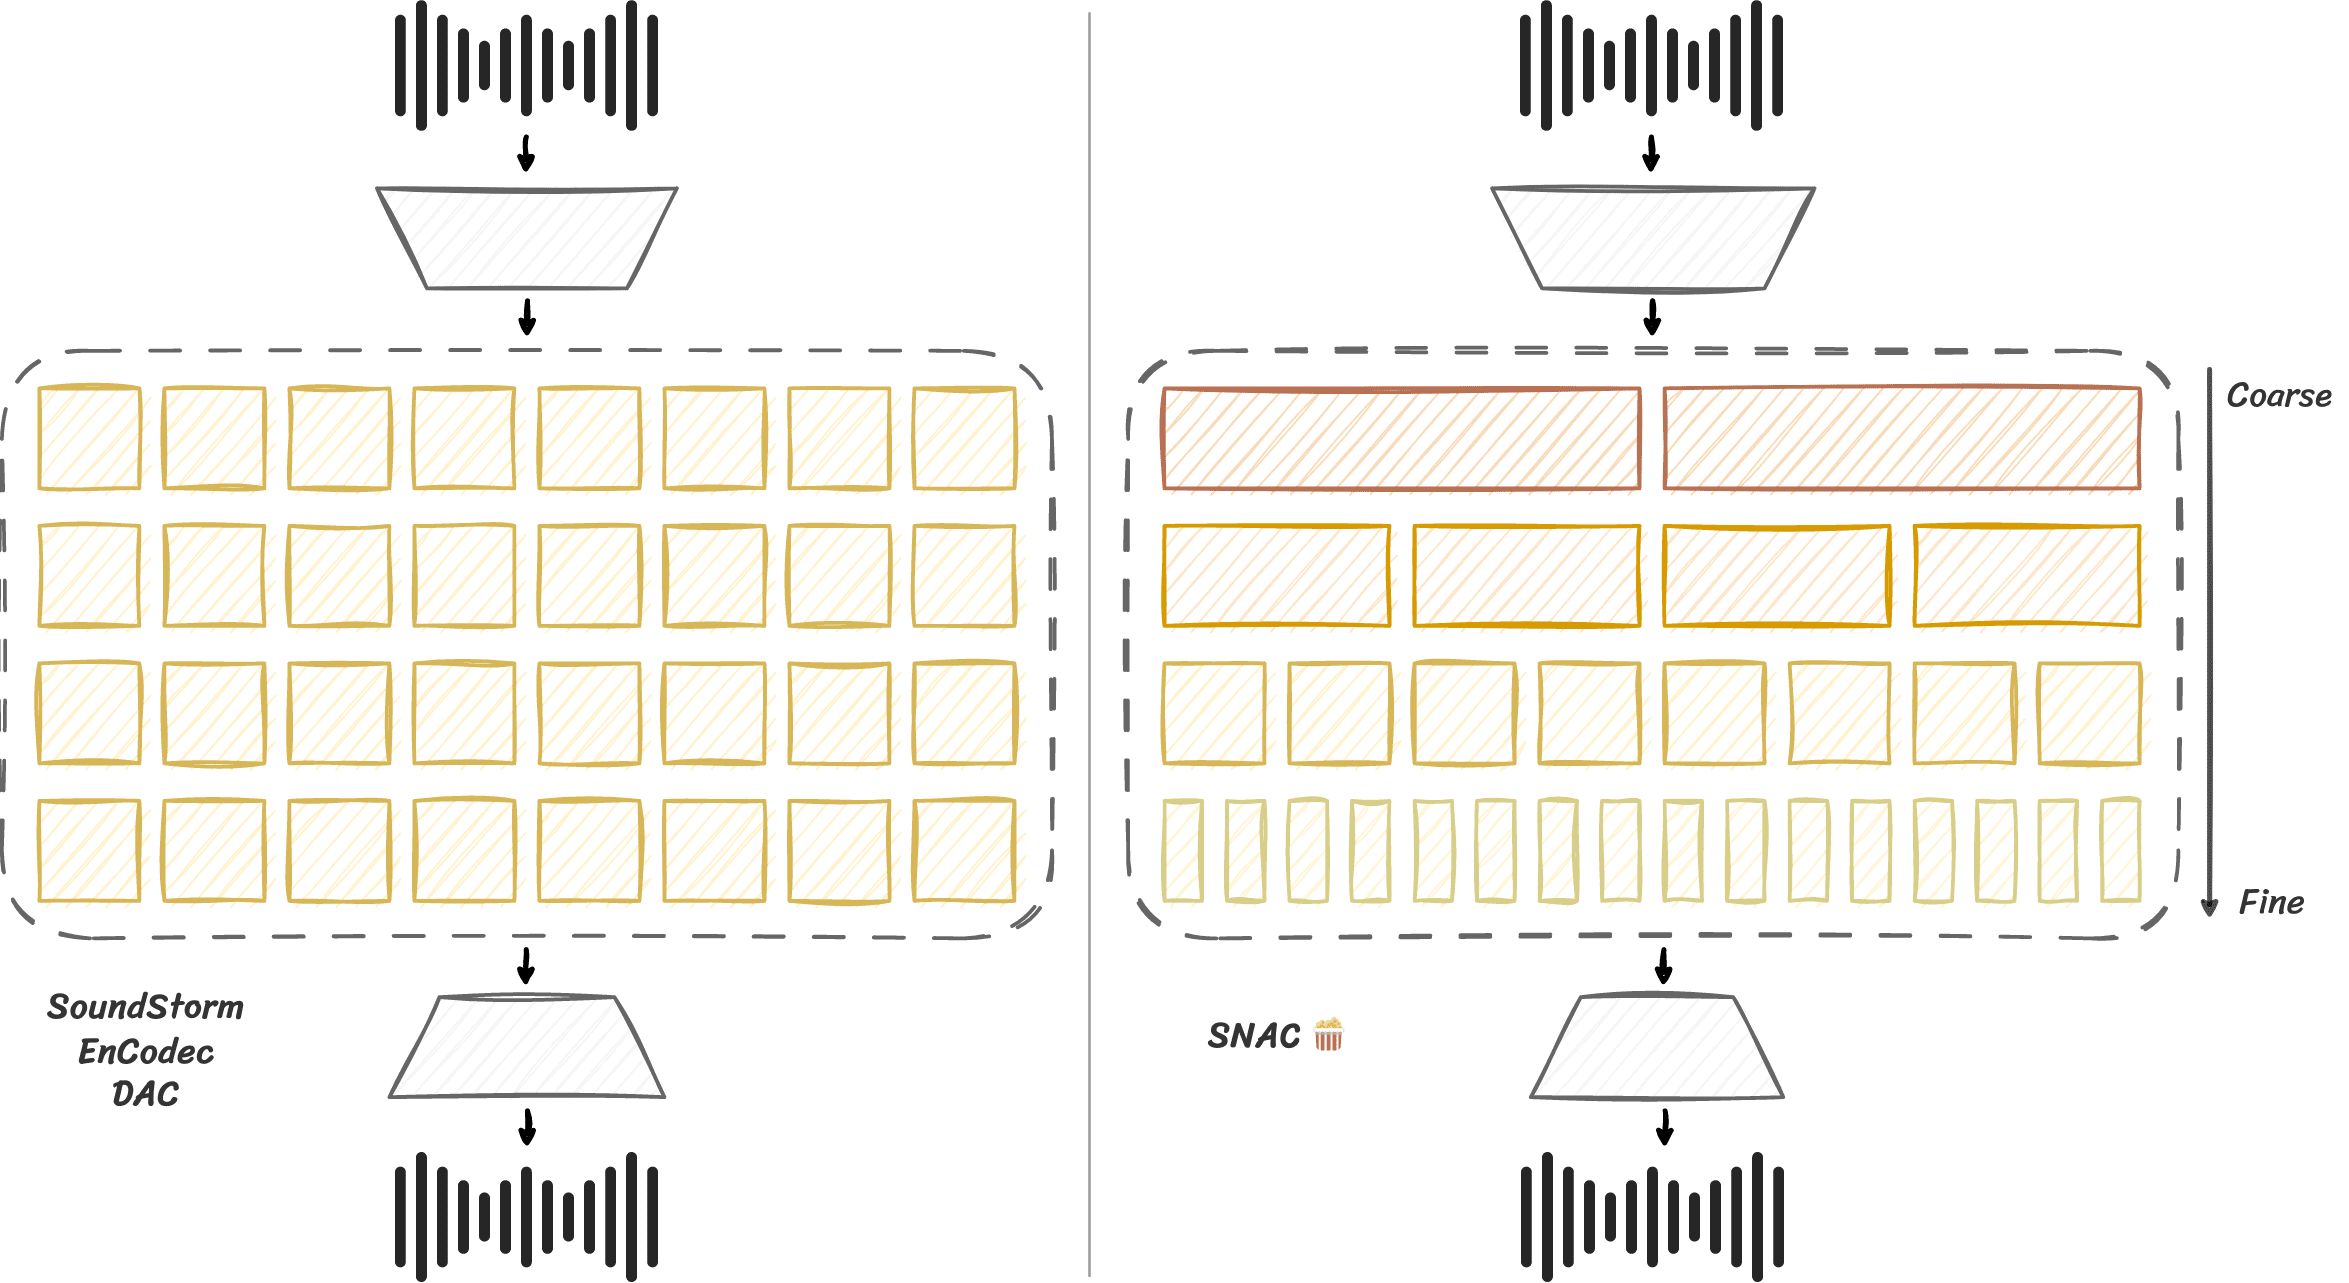
Author architecture (repository) · Source
SoCodec
Orders speech token streams by semantic content for efficient speech language modeling.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 8.33 (120 ms frames) · Nominal bitrate: ~0.47 kbps
Open license: code MIT · weights MIT
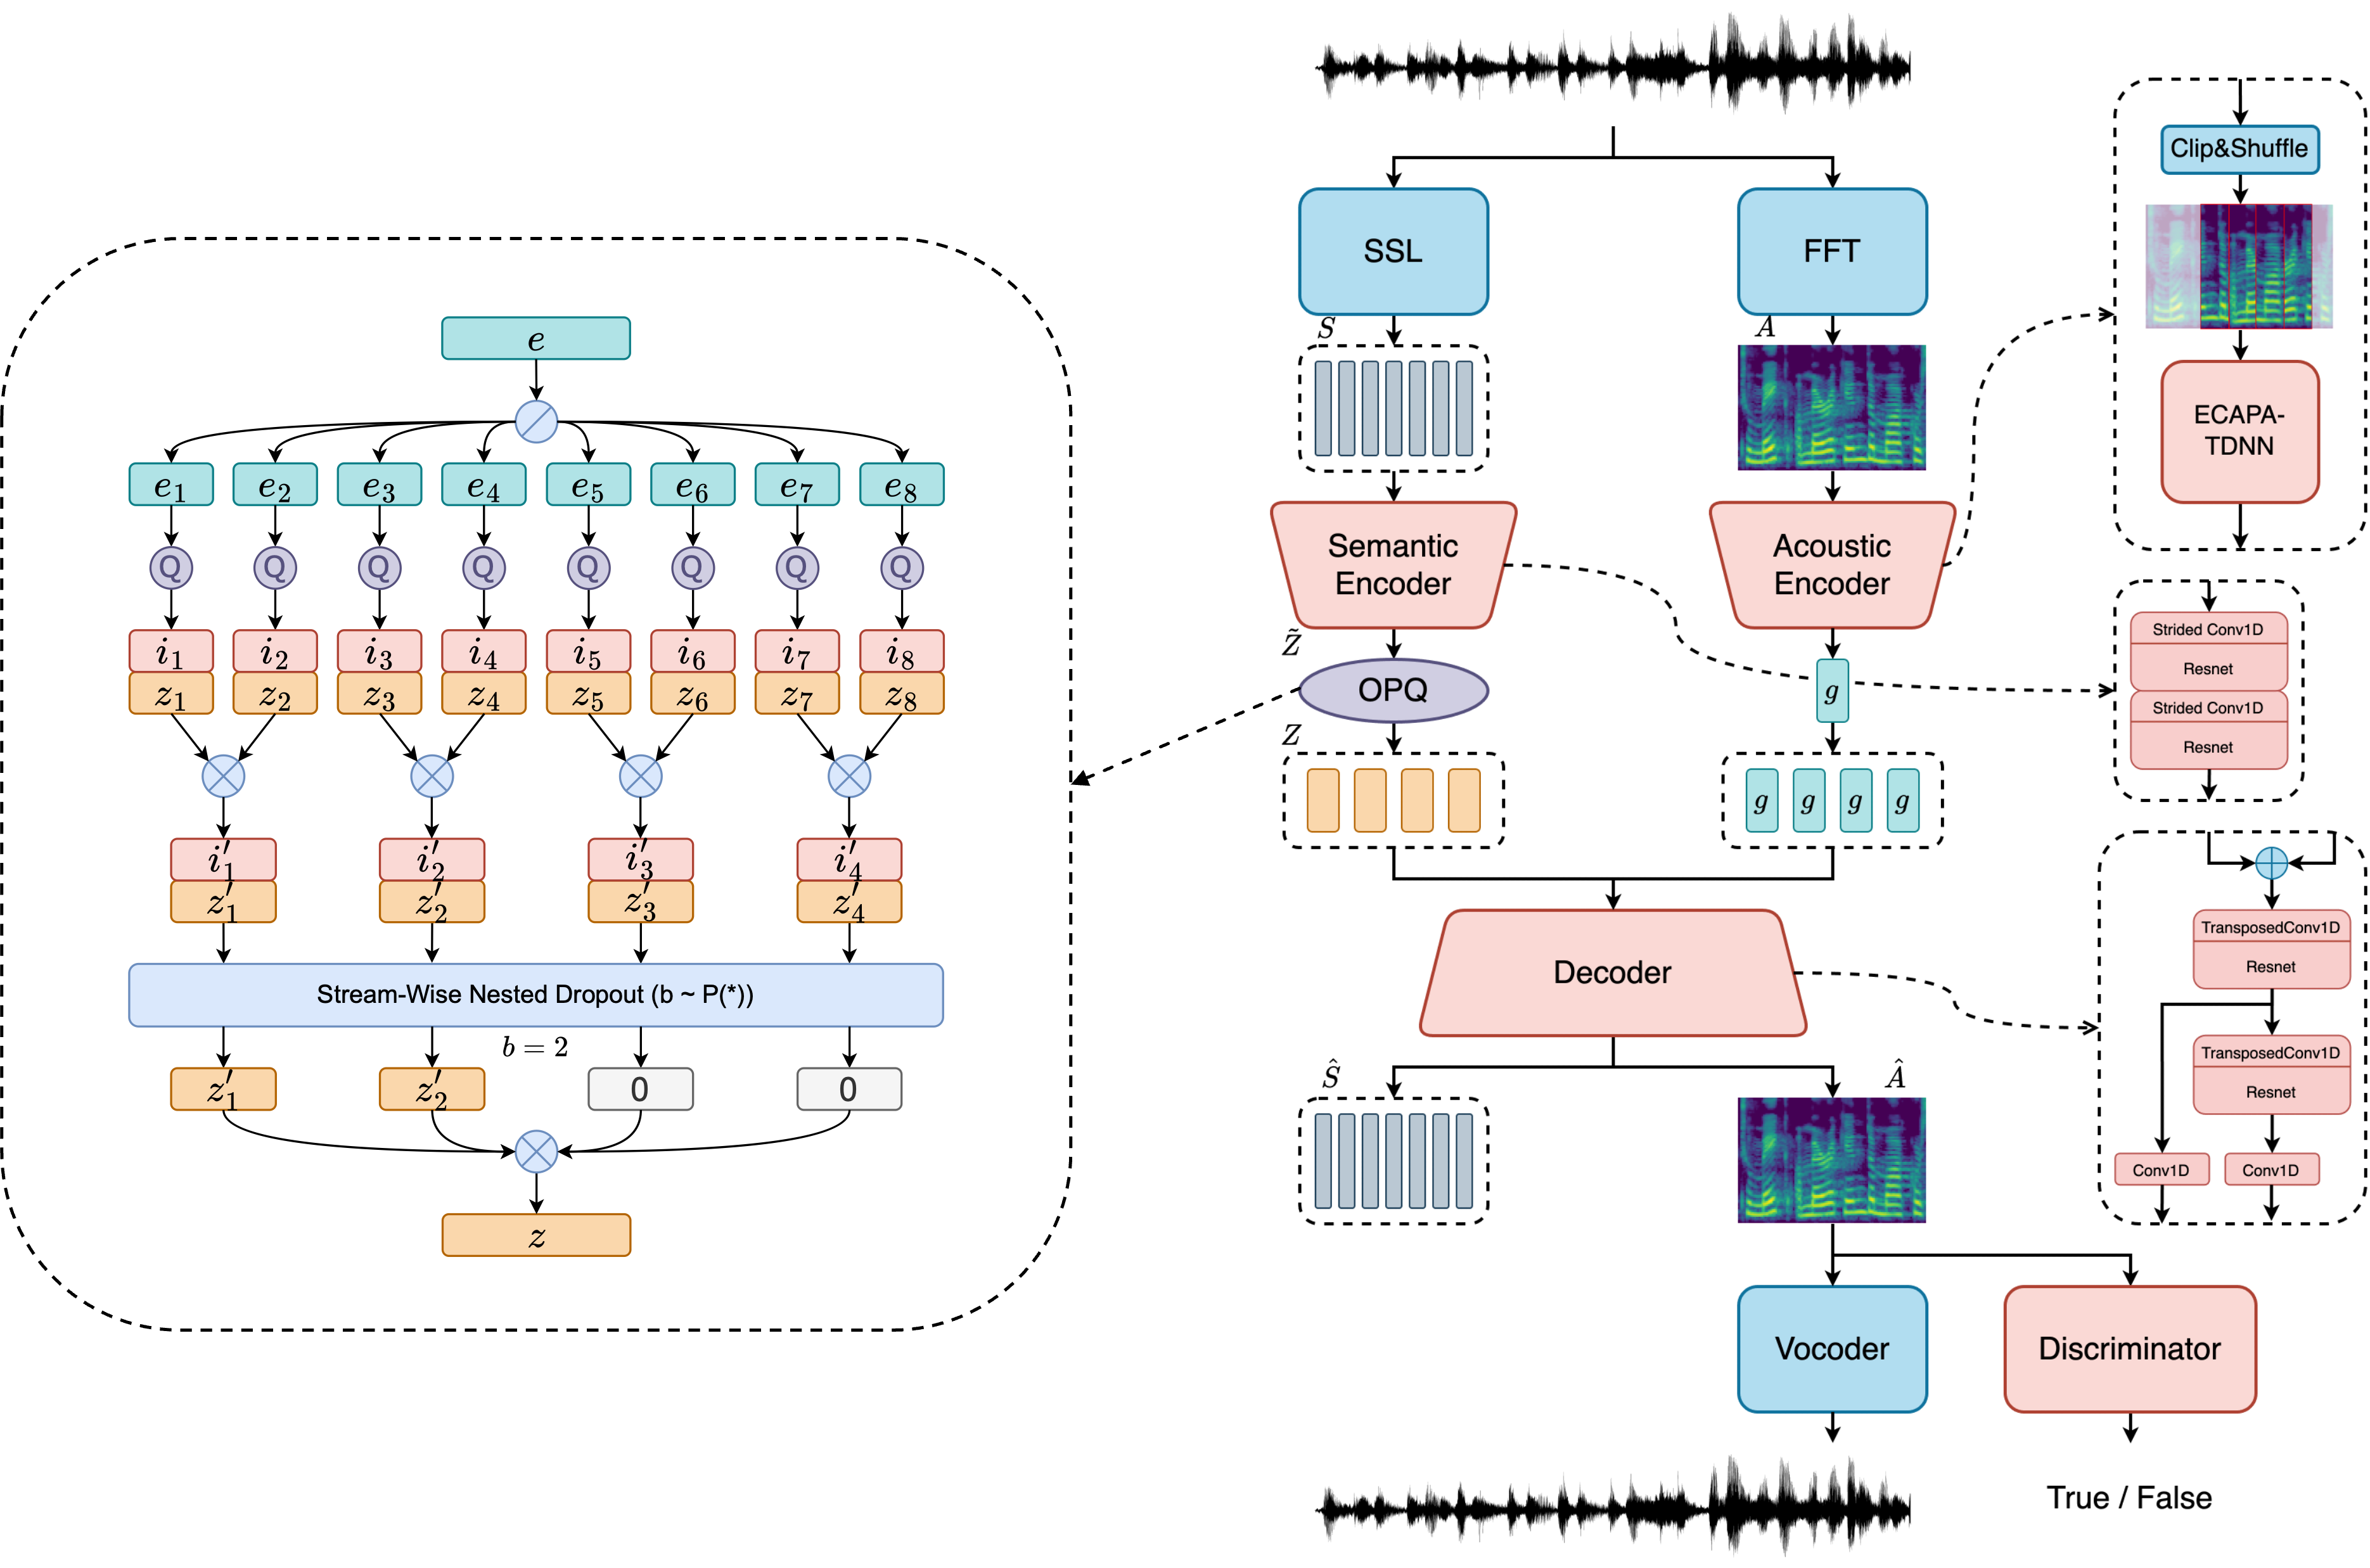
Author architecture (repository) · Source
SoviaMate-Codec
Provides reconstruction and speaker-conditioned codec checkpoints with enhancement training.
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights Apache-2.0 — The model card adds usage restrictions alongside its Apache-2.0 declaration.
Editorial overview · Source
Speech DAC (IBM)
Fine-tunes DAC for compact, high-quality speech representations.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 75 · Nominal bitrate: 1.5 / 3 kbps
Open license: code MIT · weights CDLA-Permissive-2.0
Editorial overview · Source
SpeechTokenizer
Separates a content-oriented first token stream from residual acoustic detail.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 50 · Nominal bitrate: 4 kbps (8 codebooks)
License unclear: code Apache-2.0 · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
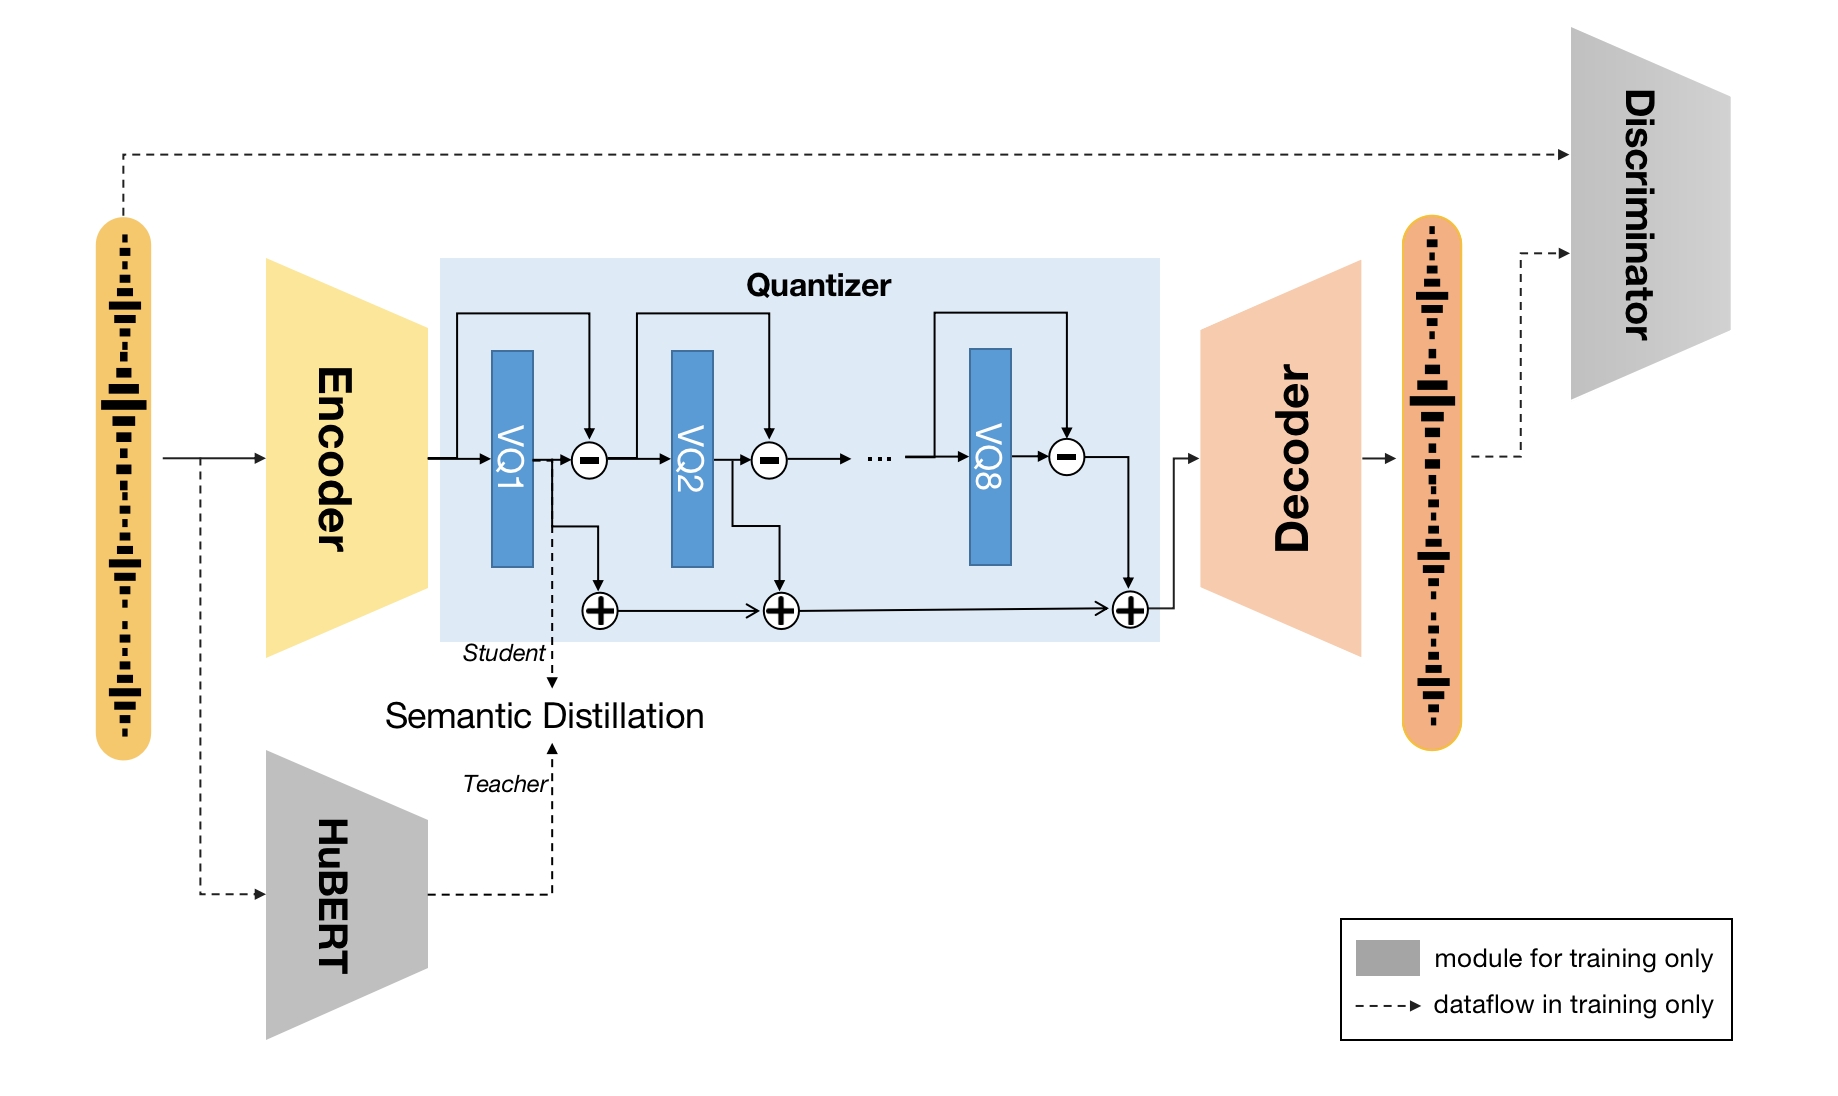
Author architecture (repository) · Source
Spine
Encodes expressive speech with token streams at several temporal scales.
Audio: 24 kHz mono · Frame rate: ~6 / 12 / 23 / 47 by scale · Nominal bitrate: 1.57 kbps
Open license: code Apache-2.0 · weights Apache-2.0
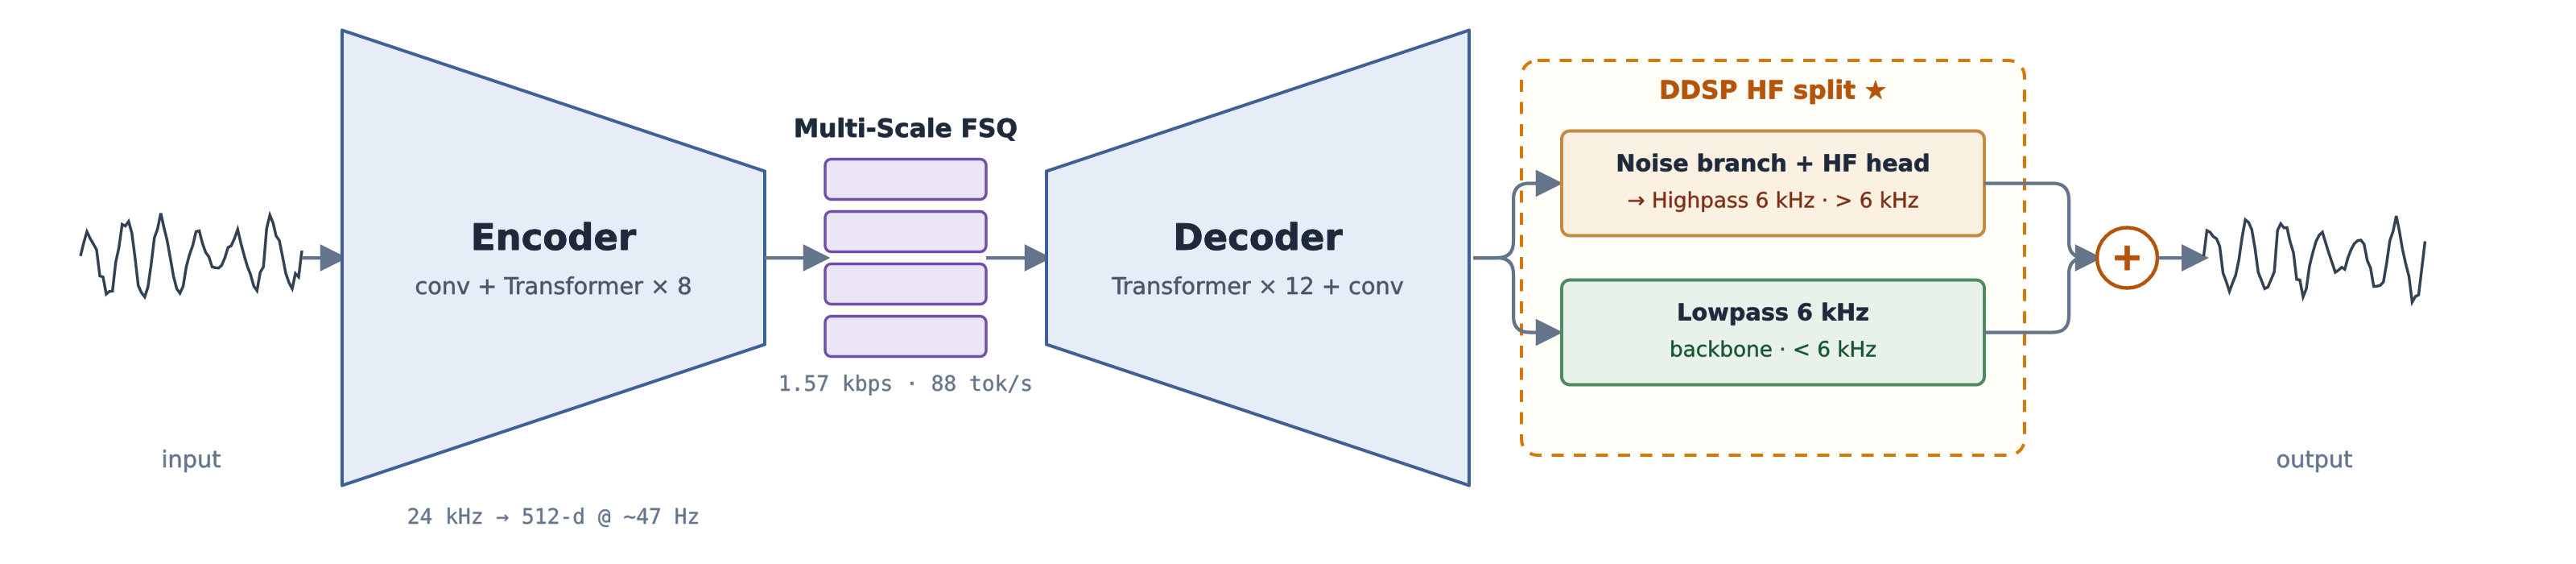
Author architecture (repository) · Source
Stable Audio Open autoencoder (Oobleck)
Compresses stereo waveforms into continuous latents for audio diffusion models.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo · Frame rate: Not specified · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code MIT · weights Stability AI Community License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
Stable Codec
Uses large Transformer autoencoders for low-bitrate speech coding.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code MIT · weights Stability AI Community License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
STFT-VAE
Compresses complex spectrograms into very low-rate continuous audio latents and reconstructs phase with an inverse STFT.
Audio: 24 kHz mono · Frame rate: 3.125 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Editorial overview · Source
TaDiCodec
Uses text-guided diffusion reconstruction to reduce the speech-token frame rate.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 6.25 · Nominal bitrate: 0.0875 kbps (tokens only)
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
TiCodec
Moves time-invariant speech information into a separate code to reduce frame-level tokens.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
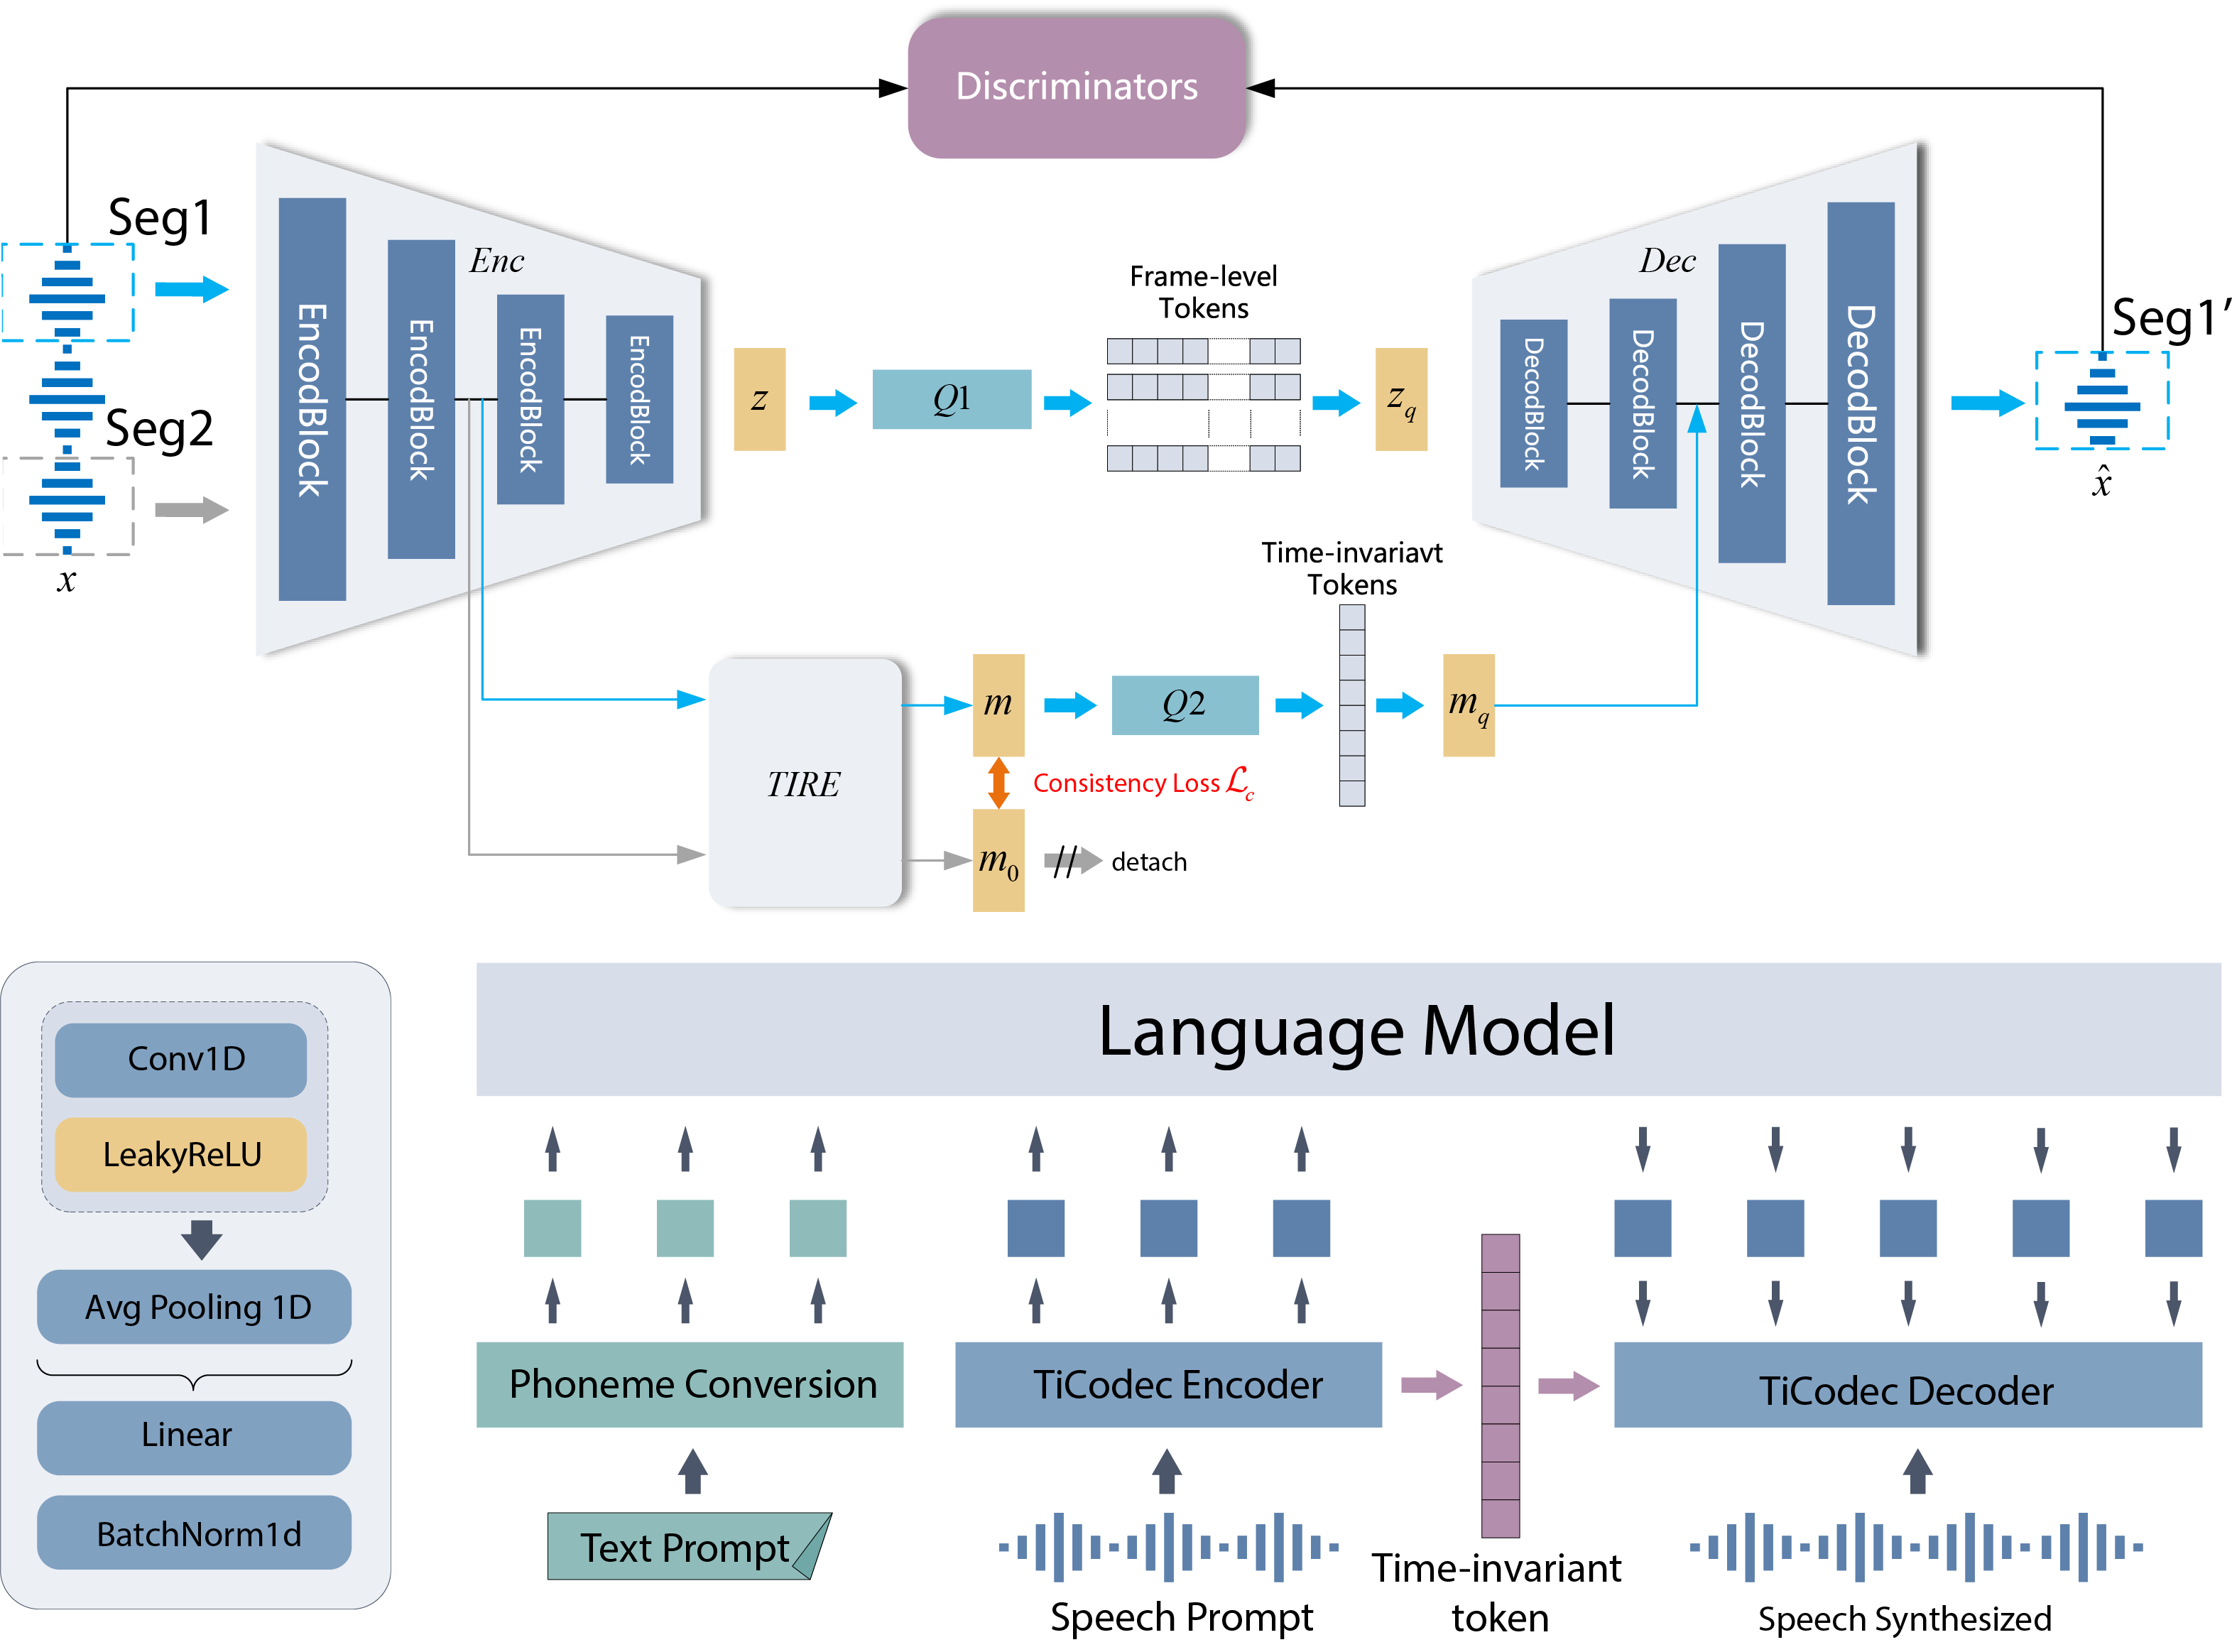
Author architecture (repository) · Source
U-Codec
Reduces the speech representation to an ultra-low frame rate for speech generation.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 5 · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
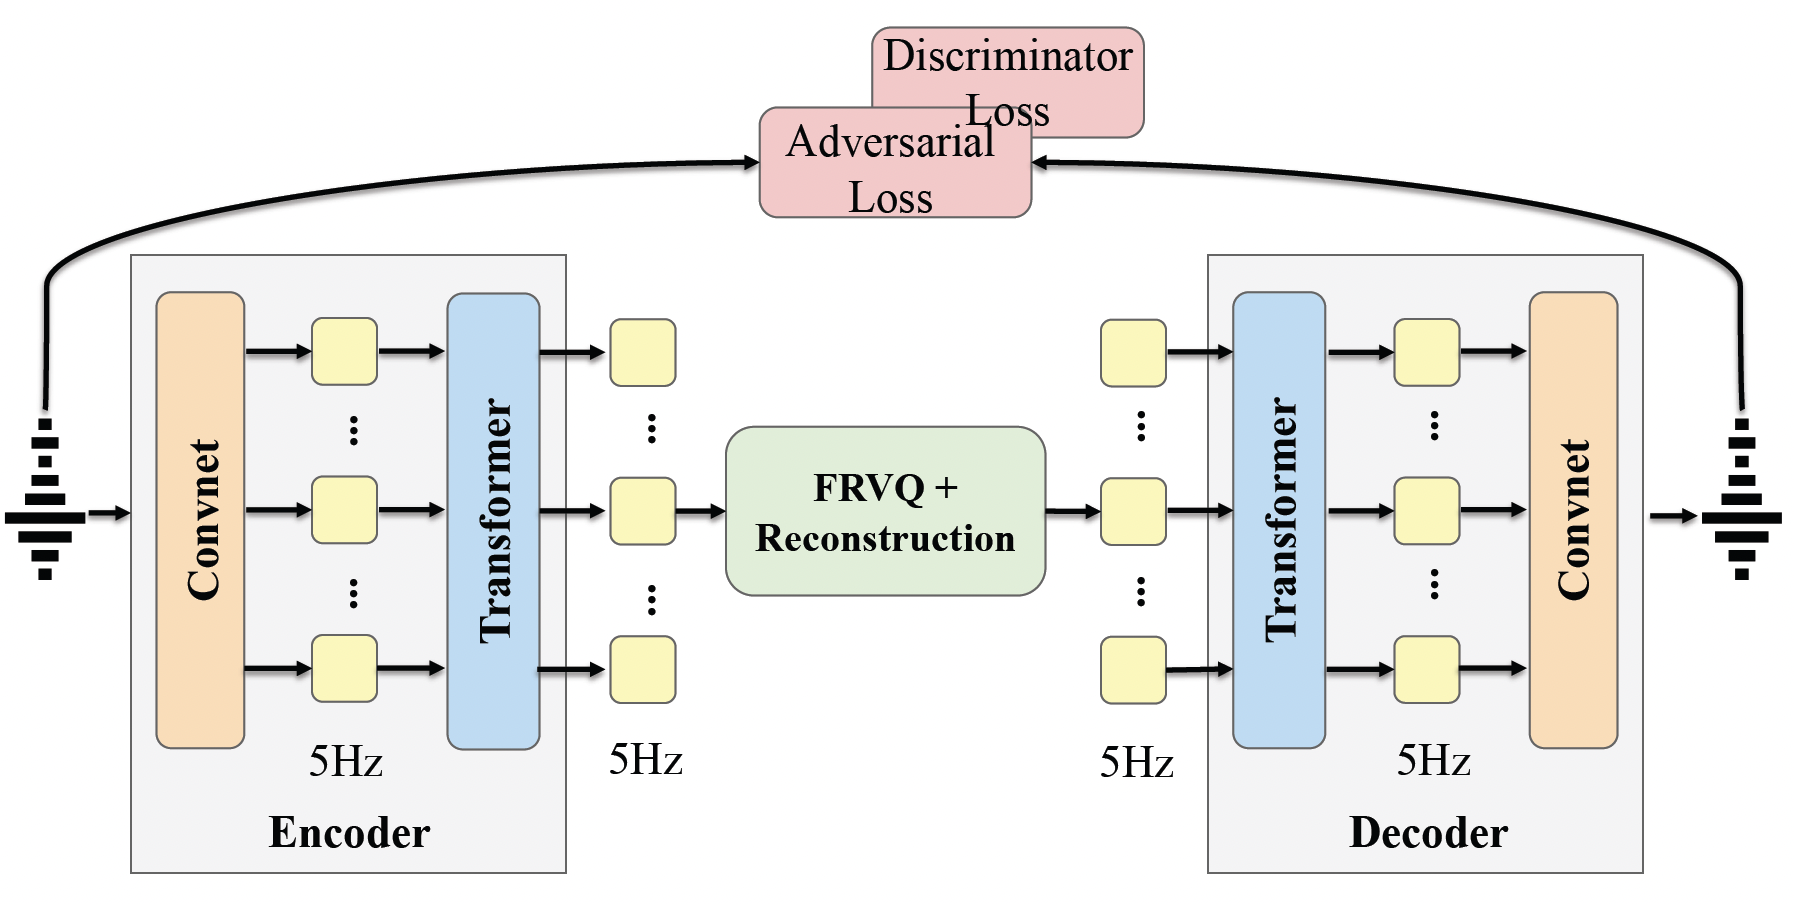
Author architecture (repository) · Source
UniCodec (domain-adaptive)
Uses one domain-adaptive codebook across speech, music and other sounds.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
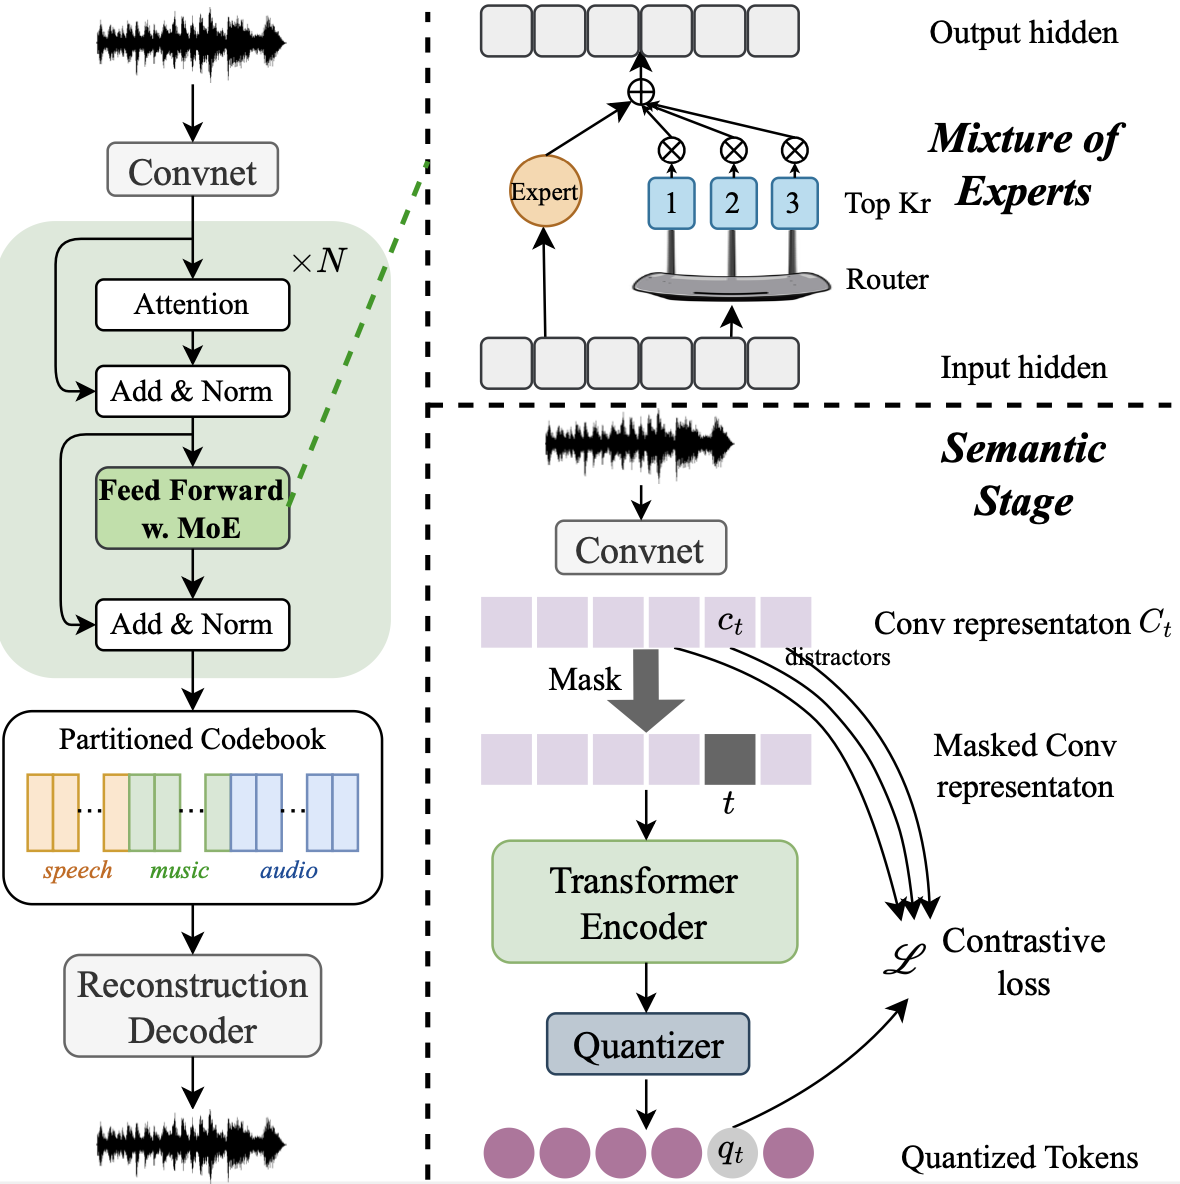
Author architecture (repository) · Source
VibeVoice acoustic tokenizer
Compresses speech into low-frame-rate continuous acoustic representations.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 7.5 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
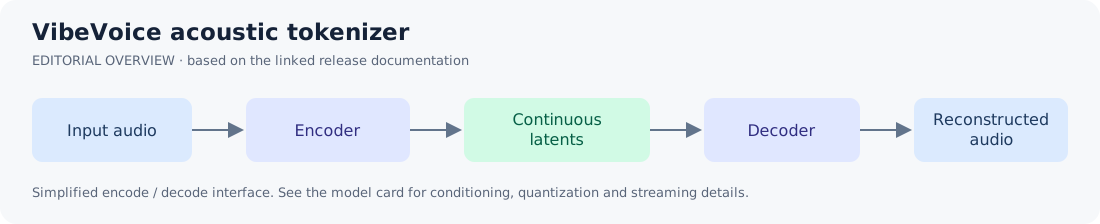
Editorial overview · Source
VoxCPM AudioVAE (1.0 / 1.5)
Reconstructs speech from continuous latents used by VoxCPM and VoxCPM1.5.
Paper · Code · Weights · Details
Audio: 44.1 kHz (1.5); 16 kHz (1.0) · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
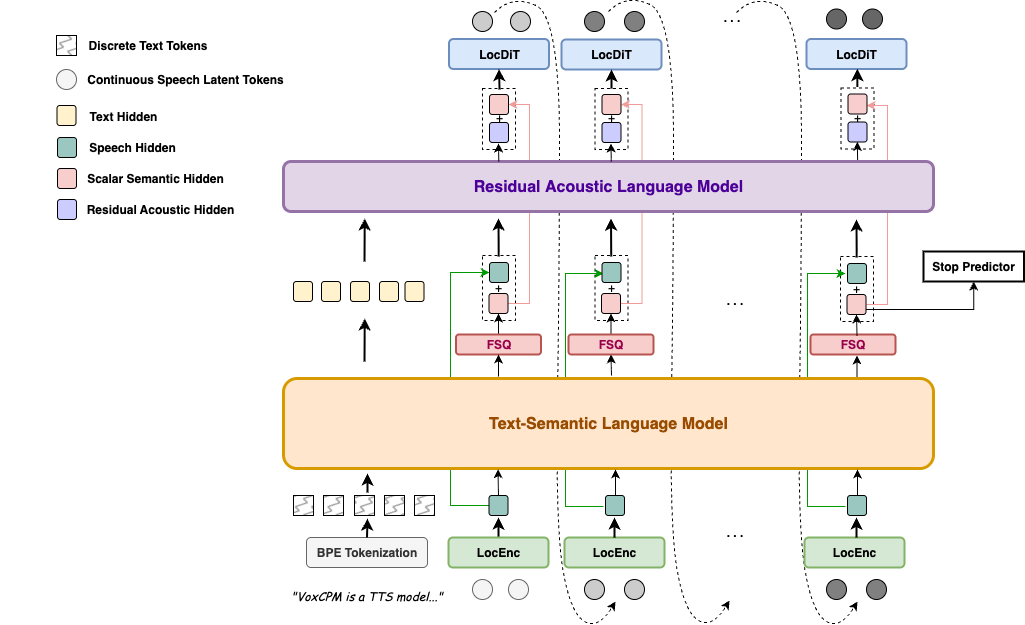
Parent VoxCPM architecture with AudioVAE · Source
VoxCPM2 AudioVAE V2
Encodes 16 kHz reference speech and decodes continuous latents into 48 kHz speech.
Paper · Code · Weights · Details
Audio: 16 kHz input → 48 kHz output · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
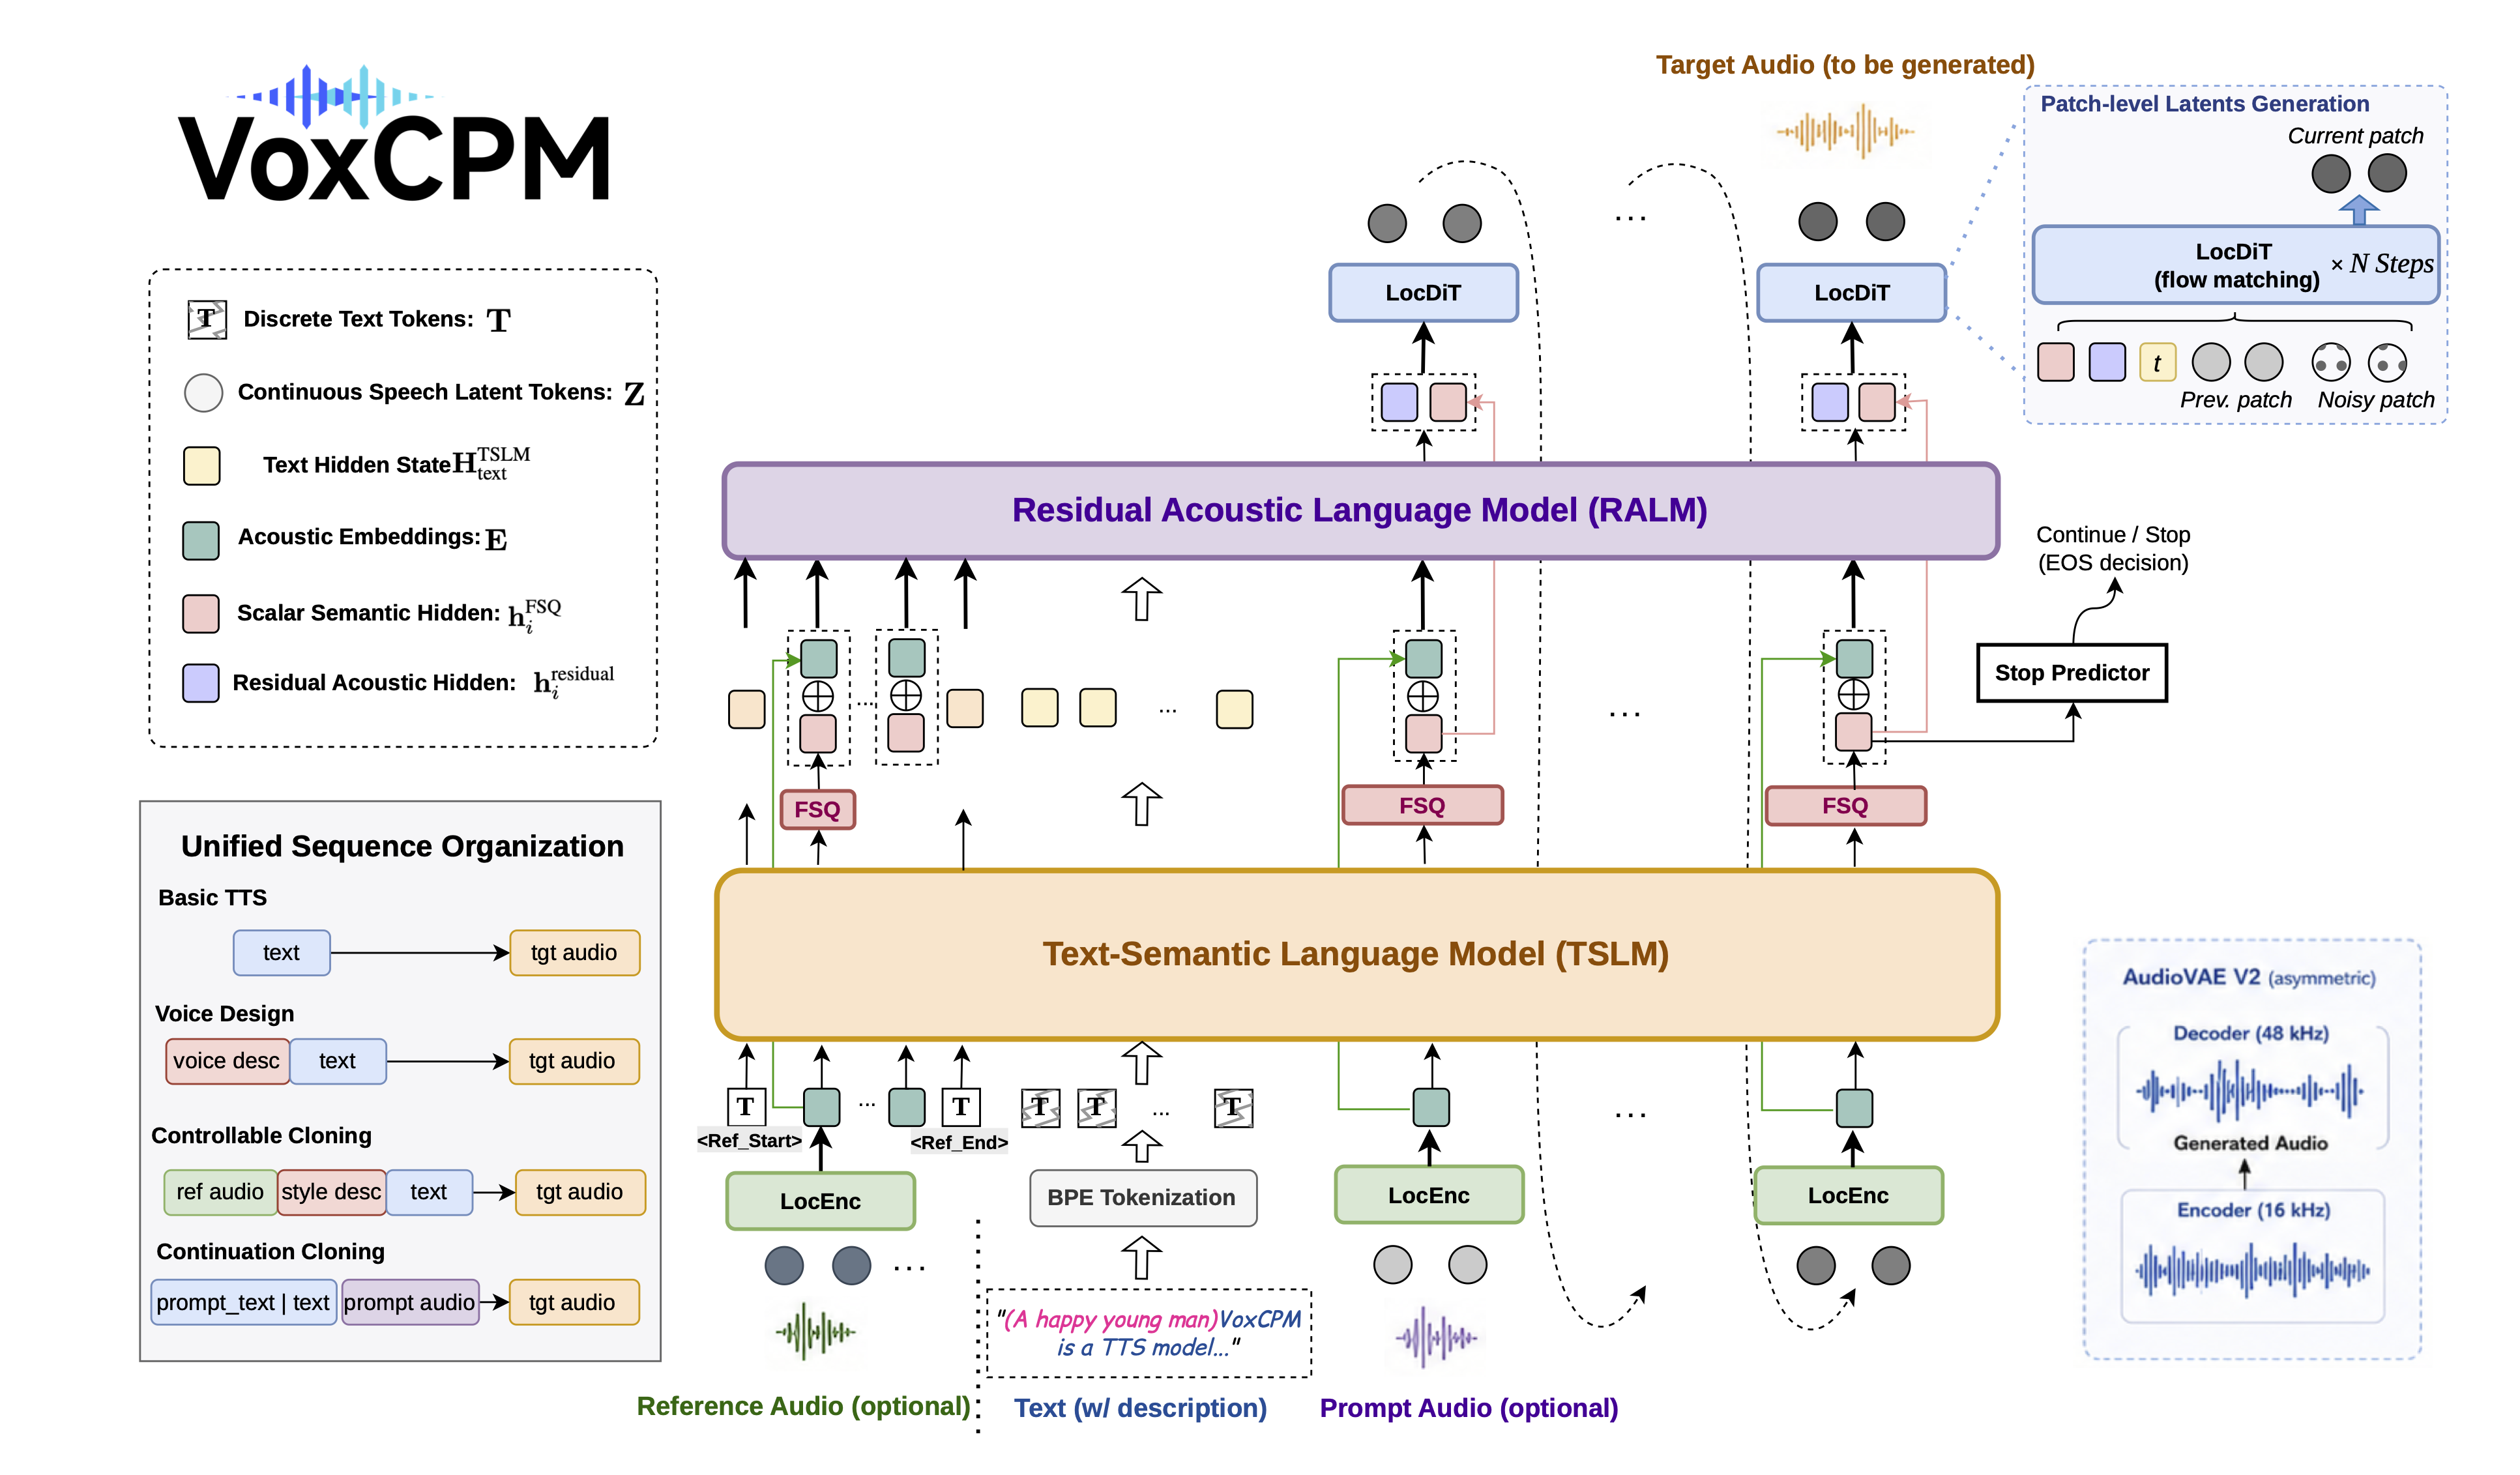
Parent VoxCPM2 architecture with AudioVAE V2 · Source
WavTokenizer
Represents speech, music and sounds with a single low-rate discrete stream.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 40 (also 75) · Nominal bitrate: 0.48 kbps (40 Hz × 12 bits)
Open license: code MIT · weights MIT
Editorial overview · Source
X-Codec
Combines pretrained semantic features with acoustic features before quantization.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
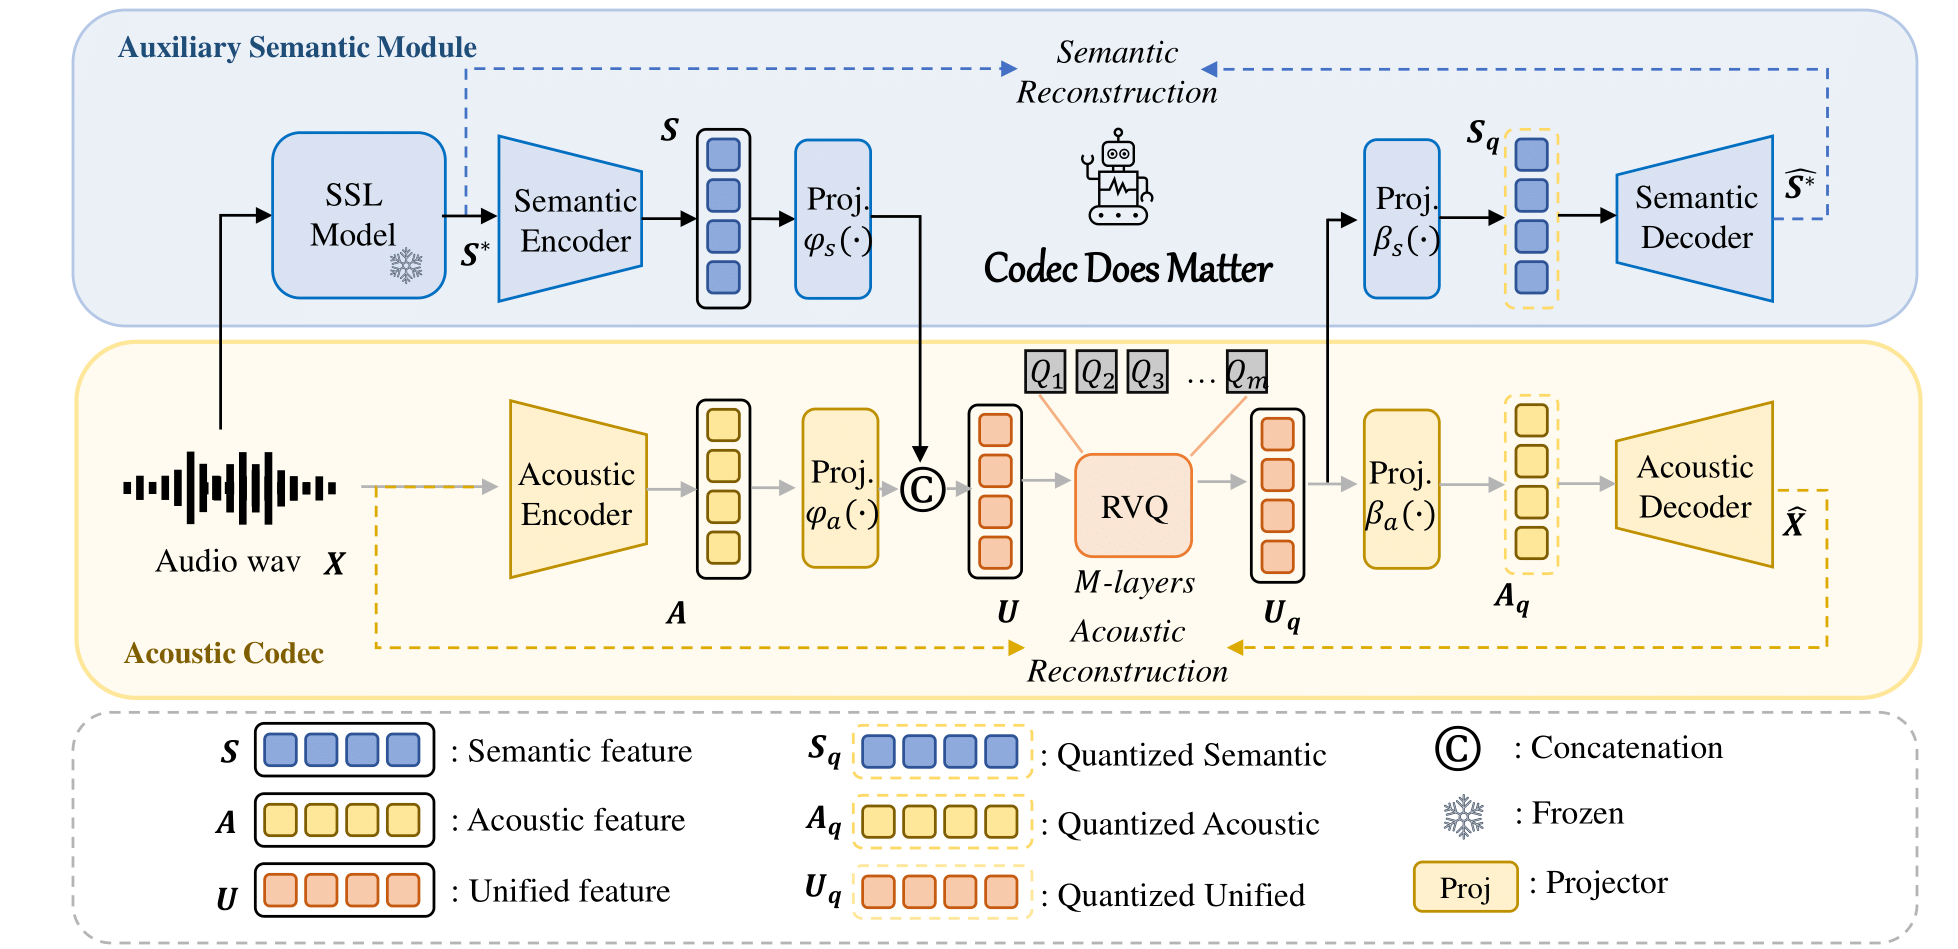
Author architecture (repository) · Source
X-Codec 2
Encodes multilingual speech into a single stream for speech language modeling.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 · Nominal bitrate: 0.8 kbps
Custom / restricted: code MIT · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
XY-Tokenizer
Aligns speech content and acoustics in low-frame-rate tokens.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 · Nominal bitrate: 1 kbps
Open license: code Apache-2.0 · weights Apache-2.0
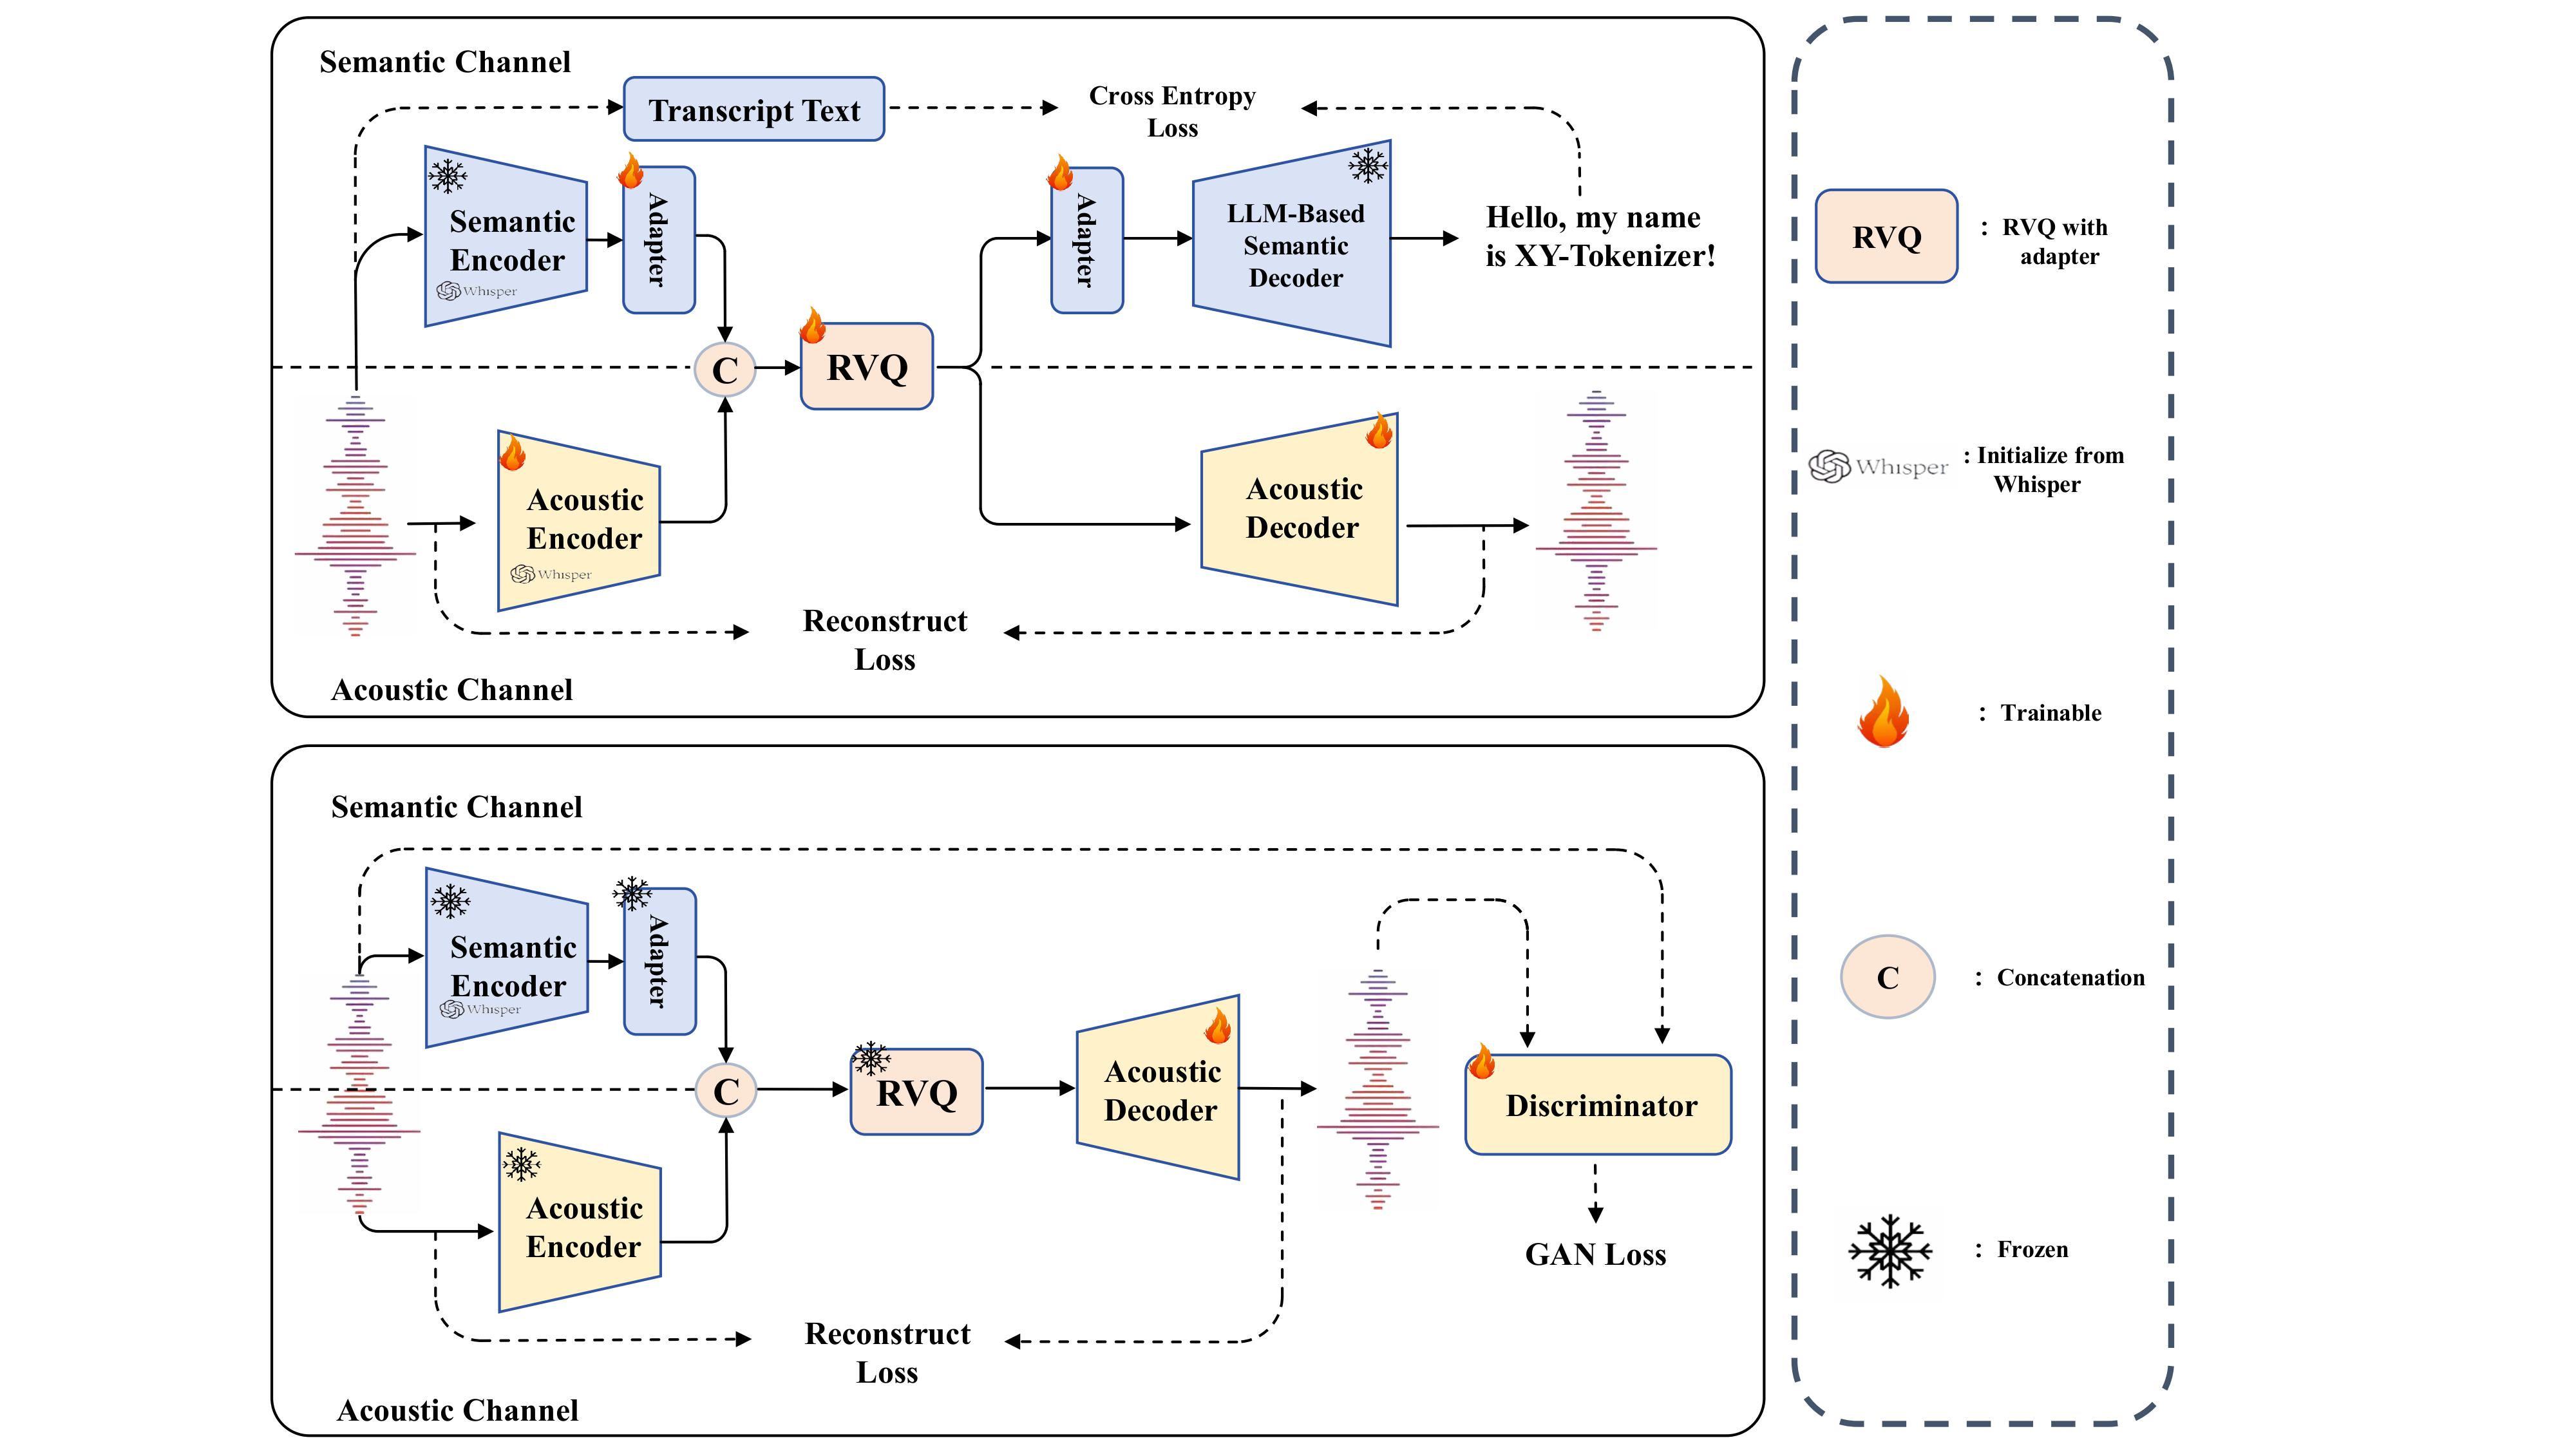
Author architecture (repository) · Source
εar-VAE
Learns stereo music latents with objectives that preserve phase and spatial structure.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo; 48 kHz variant · Frame rate: ~43.07 (44.1 kHz / 1024) · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
εar-VAE2
Reconstructs stereo music using a variational representation learned in the complex spectral domain.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
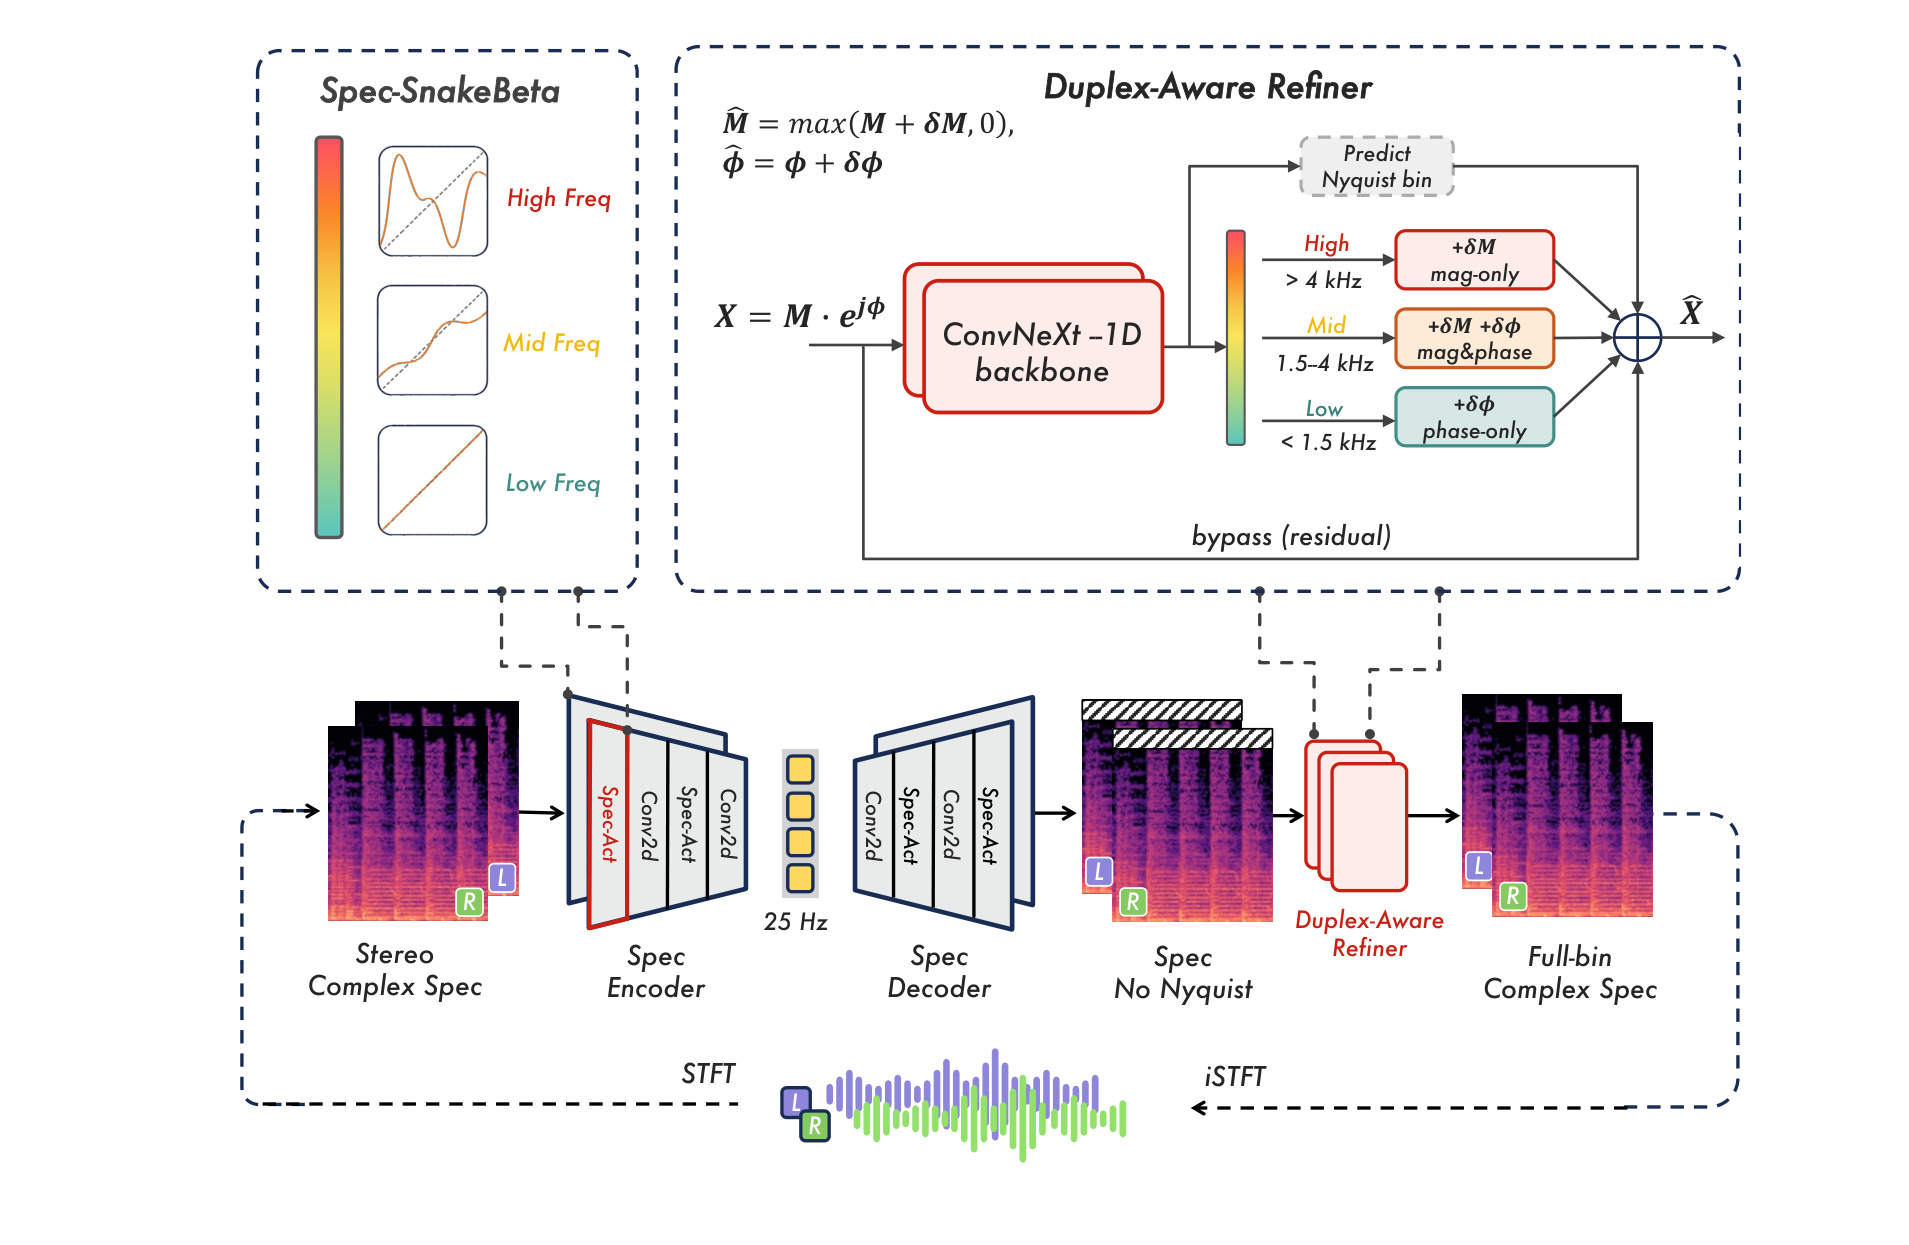
Figure 1 — spectral audio VAE architecture · Source
Contributing
See CONTRIBUTING.md to add a model or correct evidence. The catalog and gallery are generated from JSON with a dependency-free Python script.
Inspired by Awesome Omni Architectures and Awesome TTS Architectures.
License
Original catalog text, scripts and editorial diagrams: MIT. Author figures and listed models retain their own terms.
Contributors

3 commits
Similar repos




Languages
Python
100.0%
Visual catalog of neural audio and speech codec architectures, audio VAEs and continuous autoencoders, with code, checkpoints, figures and license evidence.
Python
5
3 commits
updated Sep 13, 2026
README
Awesome Codec Architectures
A visual catalog of neural audio and speech codecs, audio VAEs and continuous autoencoders: architecture figures, concise descriptions, code, checkpoints and separately checked code/weight licenses.
59 codec entries + 33 audio VAEs / continuous codecs · 68 research entries · Reviewed 2026-09-13
Model list · Architecture gallery · Audio VAEs · Comparison · Timeline · Research · Tools and benchmarks · Scope
Licenses across released entries: 49 open · 25 custom/restricted · 18 unclear. Each card links the code and checkpoint terms.
| Collection | Entries |
|---|---|
| General audio codecs | 9 |
| Speech codecs | 18 |
| Semantic and acoustic codecs | 26 |
| Disentangled codecs | 4 |
| Music codecs | 2 |
| Audio VAEs and continuous codecs | 33 |
Models
Families group routine sample-rate and bitrate variants. The research list also records foundational and unreleased work. Coverage is a dated survey, and contributions are welcome.
Alphabetical index · 92 released entries
| Model | Collection | Sample rate | License |
|---|---|---|---|
| ACE-Step 1.5 VAE | Audio VAEs and continuous codecs | 48 kHz stereo | Open license |
| ACE-Step music DCAE | Audio VAEs and continuous codecs | 44.1 kHz (released vocoder config) | Open license |
| AudioDec | Speech codecs | 48 kHz (also 24 kHz) | Custom / restricted |
| AudioLDM / AudioLDM 2 VAE | Audio VAEs and continuous codecs | 16 kHz mono | Custom / restricted |
| Auffusion spectrogram VAE | Audio VAEs and continuous codecs | 16 kHz | Custom / restricted |
| AuK BigVGANFlowVAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| BiCodec | Disentangled codecs | 16 kHz | Custom / restricted |
| BigCodec | Speech codecs | 16 kHz | Open license |
| CodecSlime | Speech codecs | 16 kHz mono | Open license |
| CoDiCodec | General audio codecs | 44.1 / 48 kHz stereo | Custom / restricted |
| DACVAE (Movie Gen) | Audio VAEs and continuous codecs | 48 kHz mono (Movie Gen paper) | License unclear |
| Descript Audio Codec (DAC) | General audio codecs | 44.1 kHz (also 16 / 24 kHz) | Open license |
| Descript Audio VAE (community) | Audio VAEs and continuous codecs | 44.1 kHz | License unclear |
| DiffRhythm VAE | Audio VAEs and continuous codecs | 44.1 kHz stereo | Custom / restricted |
| dots.tts AudioVAE | Audio VAEs and continuous codecs | 48 kHz mono | Open license |
| DualCodec | Semantic and acoustic codecs | 24 kHz | License unclear |
| EnCodec | General audio codecs | 24 kHz mono; 48 kHz stereo | License unclear |
| EzAudio waveform VAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| FACodec | Disentangled codecs | 16 kHz | Open license |
| Firefly codec (Fish Speech 1.5) | Speech codecs | 44.1 kHz | Custom / restricted |
| FireRedTTS-2 speech tokenizer | Semantic and acoustic codecs | 16 kHz | Open license |
| Fish Audio codec (OpenAudio S1 / S2) | Speech codecs | 44.1 kHz | Custom / restricted |
| FlexiCodec | Semantic and acoustic codecs | 16 kHz | License unclear |
| FlowDec | General audio codecs | 48 kHz | Custom / restricted |
| FocalCodec | Speech codecs | 16 kHz | Open license |
| FocalCodec-Stream | Speech codecs | 16 kHz input → 24 kHz output | Open license |
| FunCodec | Speech codecs | 16 kHz | Open license |
| HARP | General audio codecs | Not specified | Open license |
| HeartCodec | Music codecs | 48 kHz stereo | Open license |
| HiFi-Codec | Speech codecs | 16 / 24 kHz | License unclear |
| Higgs Audio Tokenizer v2 | Semantic and acoustic codecs | 24 kHz | Custom / restricted |
| HILCodec | General audio codecs | 24 kHz | License unclear |
| HoliTok | Audio VAEs and continuous codecs | 48 kHz mono | Open license |
| HunyuanVideo-Foley audio VAE | Audio VAEs and continuous codecs | 48 kHz | Custom / restricted |
| JHCodec | Semantic and acoustic codecs | 16 kHz mono | Open license |
| KVAE-Audio | Audio VAEs and continuous codecs | 48 kHz | Open license |
| L3AC / SQCodec | Speech codecs | 16 kHz | License unclear |
| LILAC | Speech codecs | 24 kHz mono | Open license |
| LLM-Codec (LM objectives) | Semantic and acoustic codecs | Not specified | License unclear |
| LLM-Codec (UniAudio 1.5) | Semantic and acoustic codecs | Not specified | License unclear |
| LongCat Wav-VAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| LongCat-Audio-Codec | Semantic and acoustic codecs | 16 kHz input; 16 / 24 kHz output | Open license |
| Low Frame-rate Speech Codec (LFSC) | Speech codecs | 22.05 kHz | Custom / restricted |
| LTX-2 audio VAE | Audio VAEs and continuous codecs | 16 kHz analysis → 24 kHz stereo output | Custom / restricted |
| Lyra v2 (SoundStream-based) | Speech codecs | 16 kHz | License unclear |
| MagiCodec | Semantic and acoustic codecs | 16 kHz | Open license |
| Mimi | Semantic and acoustic codecs | 24 kHz mono | Open license |
| MiMo-Audio-Tokenizer | Semantic and acoustic codecs | 24 kHz | Open license |
| Ming-omni-tts continuous tokenizer | Audio VAEs and continuous codecs | 44.1 kHz | Open license |
| MingTok-Audio | Audio VAEs and continuous codecs | 16 kHz | Open license |
| MiniMax H3 AudioVAE | Audio VAEs and continuous codecs | 32 kHz mono; stereo channels processed separately | Custom / restricted |
| MMAudio VAE (16 / 44.1 kHz) | Audio VAEs and continuous codecs | 16 / 44.1 kHz | Custom / restricted |
| MOSS-Audio-Tokenizer | Semantic and acoustic codecs | 24 kHz mono | Open license |
| MOSS-Audio-Tokenizer Nano | Semantic and acoustic codecs | 48 kHz stereo | Open license |
| MOSS-Audio-Tokenizer v2 | Semantic and acoustic codecs | 48 kHz stereo | Open license |
| MuCodec | Music codecs | 48 kHz stereo | Custom / restricted |
| Music2Latent | Audio VAEs and continuous codecs | 44.1 kHz (also 48 kHz) | Custom / restricted |
| Musika autoencoder | Audio VAEs and continuous codecs | 44.1 kHz (released model card) | Open license |
| NanoCodec | Speech codecs | 22.05 kHz | Custom / restricted |
| NeuCodec | Semantic and acoustic codecs | 16 kHz input → 24 kHz output | Open license |
| Omni2Sound OOB/Wav VAE | Audio VAEs and continuous codecs | 16 kHz | Custom / restricted |
| OmniVAE audio-only | Audio VAEs and continuous codecs | 48 kHz | Open license |
| PAST | Semantic and acoustic codecs | Not specified | License unclear |
| Qwen3-TTS-Tokenizer-12Hz | Semantic and acoustic codecs | 24 kHz | Open license |
| RAVE (v1 / v2) | Audio VAEs and continuous codecs | Checkpoint-specific; not independently established | Custom / restricted |
| SAC | Semantic and acoustic codecs | 16 kHz | Open license |
| SAME (S / L) | Audio VAEs and continuous codecs | 44.1 kHz stereo | Custom / restricted |
| Semantic-VAE | Audio VAEs and continuous codecs | 16 kHz mono | License unclear |
| SemantiCodec | Semantic and acoustic codecs | 16 kHz | Open license |
| SimWhisper-Codec | Semantic and acoustic codecs | Not specified | Open license |
| SNAC | General audio codecs | 24 kHz speech; 32 / 44.1 kHz audio | Open license |
| SoCodec | Semantic and acoustic codecs | 16 kHz | Open license |
| SoviaMate-Codec | Disentangled codecs | Not specified | Custom / restricted |
| Speech DAC (IBM) | Speech codecs | 24 kHz | Open license |
| SpeechTokenizer | Semantic and acoustic codecs | 16 kHz mono | License unclear |
| Spine | Speech codecs | 24 kHz mono | Open license |
| Stable Audio Open autoencoder (Oobleck) | Audio VAEs and continuous codecs | 44.1 kHz stereo | Custom / restricted |
| Stable Codec | Speech codecs | 16 kHz | Custom / restricted |
| STFT-VAE | Audio VAEs and continuous codecs | 24 kHz mono | Open license |
| TaDiCodec | Semantic and acoustic codecs | 24 kHz | Open license |
| TiCodec | Disentangled codecs | Not specified | License unclear |
| U-Codec | Speech codecs | 16 kHz | License unclear |
| UniCodec (domain-adaptive) | General audio codecs | Not specified | License unclear |
| VibeVoice acoustic tokenizer | Audio VAEs and continuous codecs | 24 kHz | Open license |
| VoxCPM AudioVAE (1.0 / 1.5) | Audio VAEs and continuous codecs | 44.1 kHz (1.5); 16 kHz (1.0) | Open license |
| VoxCPM2 AudioVAE V2 | Audio VAEs and continuous codecs | 16 kHz input → 48 kHz output | Open license |
| WavTokenizer | General audio codecs | 24 kHz | Open license |
| X-Codec | Semantic and acoustic codecs | 16 kHz | License unclear |
| X-Codec 2 | Semantic and acoustic codecs | 16 kHz | Custom / restricted |
| XY-Tokenizer | Semantic and acoustic codecs | 16 kHz | Open license |
| εar-VAE | Audio VAEs and continuous codecs | 44.1 kHz stereo; 48 kHz variant | Open license |
| εar-VAE2 | Audio VAEs and continuous codecs | 48 kHz stereo | Open license |
Architecture gallery
Author figures and editorial overviews are labeled individually. See the figure credits. Technical numbers refer to the documented configuration, not every family variant.
ACE-Step 1.5 VAE
Encodes stereo music directly into continuous waveform latents for ACE-Step 1.5.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Figure 2 — parent ACE-Step 1.5 framework with VAE · Source
ACE-Step music DCAE
Compresses music spectrograms into continuous latents and reconstructs audio through a matching vocoder.
Paper · Code · Weights · Details
Audio: 44.1 kHz (released vocoder config) · Frame rate: ~10.77 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 — parent ACE-Step system with DCAE and vocoder · Source
AudioDec
Reconstructs high-sample-rate speech with a streamable two-stage codec.
Paper · Code · Weights · Details
Audio: 48 kHz (also 24 kHz) · Frame rate: 160 (48 kHz / hop300) · Nominal bitrate: 12.8 kbps (selected 48 kHz model)
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Author architecture (repository) · Source
AudioLDM / AudioLDM 2 VAE
Compresses mel spectrograms with a variational autoencoder and reconstructs audio using HiFi-GAN.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-SA-4.0 · weights CC-BY-NC-SA-4.0 — The linked noncommercial or custom terms apply to this release.
Figure 1 — parent AudioLDM system with VAE and vocoder · Source
Auffusion spectrogram VAE
Uses an image-style variational autoencoder on audio spectrograms with a released audio reconstruction path.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 (paper configuration) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-SA-4.0 · weights CC-BY-NC-SA-4.0 — The linked noncommercial or custom terms apply to this release.
Figure 1 — spectrogram, VAE and waveform reconstruction path · Source
AuK BigVGANFlowVAE
Encodes speech into continuous variational latents for generation and audio editing.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Parent AuK architecture with audio VAE · Source
BiCodec
Reconstructs speech from separate global speaker and time-varying semantic tokens.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 semantic frames/s · Nominal bitrate: 0.65 kbps semantic stream + global tokens
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-SA-4.0 — The linked custom or noncommercial terms apply to this release.
Figure 2 · Source
BigCodec
Scales a single-codebook speech codec to improve reconstruction at low bitrates.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 80 · Nominal bitrate: 1.04 kbps
Open license: code MIT · weights CC-BY-SA-4.0
Fig. 1 · Source
CodecSlime
Removes redundant speech frames to support a controllable token rate.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 36–80 · Nominal bitrate: Not specified
Open license: code MIT · weights CC-BY-4.0
Figure 2 · Source
CoDiCodec
Offers continuous latents or discrete tokens through a shared stereo audio codec.
Paper · Code · Weights · Details
Audio: 44.1 / 48 kHz stereo · Frame rate: ~11 (continuous latent sequence) · Nominal bitrate: 2.38 kbps (discrete mode)
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Author architecture (repository) · Source
DACVAE (Movie Gen)
Replaces DAC residual vector quantization with a continuous variational bottleneck for general-audio reconstruction.
Paper · Code · Weights · Details
Audio: 48 kHz mono (Movie Gen paper) · Frame rate: 25 (Movie Gen paper) · Nominal bitrate: Not applicable: continuous latents
License unclear: code Apache-2.0 · weights Conflicting: Apache-2.0 / SAM License — The GitHub code is Apache-2.0. Checkpoint-card metadata says Apache-2.0, but its license paragraph says SAM License and references a LICENSE file absent from the inspected checkpoint tree; the weight terms need clarification.
Editorial overview · Source
Descript Audio Codec (DAC)
Encodes speech, music and environmental audio into residual discrete codes.
Paper · Code · Weights · Details
Audio: 44.1 kHz (also 16 / 24 kHz) · Frame rate: ~86 (44.1 kHz) · Nominal bitrate: ~8 kbps (44.1 kHz)
Open license: code MIT · weights MIT
Editorial overview · Source
Descript Audio VAE (community)
Provides a community DAC-to-VAE adaptation for continuous audio latents.
Audio: 44.1 kHz · Frame rate: 87 (author release label) · Nominal bitrate: Not applicable: continuous latents
License unclear: code MIT · weights Not stated — The code is MIT. The checkpoint has no model-card license; generic MIT weight wording inherited in the DAC README is not treated as unambiguous evidence for the modified VAE checkpoint.
Editorial overview · Source
DiffRhythm VAE
Compresses stereo songs into continuous waveform latents for DiffRhythm.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo · Frame rate: ~21.53 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code Apache-2.0 · weights Stability AI Community License — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
dots.tts AudioVAE
Encodes and decodes the continuous speech representation used by dots.tts.
Paper · Code · Weights · Details
Audio: 48 kHz mono · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
DualCodec
Combines a semantic first codebook with acoustic residual streams at low frame rates.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 12.5 / 25 · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
EnCodec
Compresses general audio with selectable bandwidths and a separate stereo music variant.
Paper · Code · Weights · Details
Audio: 24 kHz mono; 48 kHz stereo · Frame rate: 75 (24 kHz); 150 (48 kHz) · Nominal bitrate: 1.5–24 kbps (24 kHz); 3–24 kbps (48 kHz)
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
EzAudio waveform VAE
Provides the waveform compression stage used by EzAudio text-to-audio models.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Figure 1 — parent EzAudio system with waveform VAE · Source
FACodec
Separates speech into content, prosody, timbre and acoustic-detail representations.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 80 · Nominal bitrate: Not specified
Open license: code MIT · weights Apache-2.0
Author architecture (repository) · Source
Firefly codec (Fish Speech 1.5)
Encodes speech into grouped finite-scalar tokens for Fish Speech.
Audio: 44.1 kHz · Frame rate: ~21.5 · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights CC-BY-NC-SA-4.0 — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
FireRedTTS-2 speech tokenizer
Provides streaming speech tokens for long conversational speech generation.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 · Nominal bitrate: 2.2 kbps (16 codebooks)
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 — system overview, including the tokenizer · Source
Fish Audio codec (OpenAudio S1 / S2)
Provides the audio tokenization and reconstruction component used by OpenAudio and Fish S2.
Audio: 44.1 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code Fish Audio Research License · weights Fish Audio Research License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
FlexiCodec
Adapts speech token duration by merging semantically similar frames.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: Dynamic: ~3–12.5 · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
FlowDec
Combines non-adversarial audio compression with a generative flow-matching postfilter.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
FocalCodec
Compresses speech into one codebook at several low token rates.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 / 25 / 50 · Nominal bitrate: ~0.16 / 0.33 / 0.65 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Author architecture (repository) · Source
FocalCodec-Stream
Adds causal, incremental speech coding with a single token stream.
Paper · Code · Weights · Details
Audio: 16 kHz input → 24 kHz output · Frame rate: 50 · Nominal bitrate: 0.55 / 0.60 / 0.80 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
FunCodec
Provides reproducible time-domain and frequency-domain neural speech coding recipes.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 (ds320); 25 (ds640) · Nominal bitrate: Not specified
Open license: code MIT · weights MIT
Figure 2 · Source
HARP
Allocates residual codebook capacity across harmonic frequency bands.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: ~86 · Nominal bitrate: ~2.6 / 4.3 / 6.0 / 7.7 kbps
Open license: code MIT · weights MIT
Figure 1 · Source
HeartCodec
Encodes music into tokens for the HeartMuLa music-generation family.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: Not specified · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
HiFi-Codec
Reconstructs speech using grouped residual quantization with few codebooks.
Paper · Code · Weights · Details
Audio: 16 / 24 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Figure 1 · Source
Higgs Audio Tokenizer v2
Compresses speech, music and sound events into low-frame-rate audio tokens.
Audio: 24 kHz · Frame rate: 25 · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights Boson Higgs Audio 2 Community License — The linked custom or noncommercial terms apply to this release.
Author architecture (repository) · Source
HILCodec
Targets lightweight, high-fidelity neural audio coding with deployable inference graphs.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
HoliTok
Learns continuous speech latents that can support both audio reconstruction and semantic feature extraction.
Paper · Code · Weights · Details
Audio: 48 kHz mono · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 — HoliTok tokenizer and training framework · Source
HunyuanVideo-Foley audio VAE
Reconstructs general audio using the waveform VAE released with HunyuanVideo-Foley.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code Tencent Hunyuan Community License · weights Tencent Hunyuan Community License — The linked noncommercial or custom terms apply to this release.
Figure 2 — parent HunyuanVideo-Foley system with DAC-VAE · Source
JHCodec
Uses self-supervised representation reconstruction to improve streaming speech tokens.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 50 · Nominal bitrate: 4 kbps (8 × 1,024 codes at 50 Hz)
Open license: code MIT · weights MIT
Author architecture (repository) · Source
KVAE-Audio
Encodes full-band speech, music and sound into continuous latents for reconstruction and generative modeling.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Editorial overview · Source
L3AC / SQCodec
Uses a single quantizer in a lightweight speech reconstruction model.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 44.44 / 59.26 / 88.89 / 166.67 · Nominal bitrate: ~0.75 / 1 / 1.5 / 3 kbps
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
LILAC
Targets low-bitrate speech compression with stable codes under repeated decode/re-encode cycles.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 9.375 · Nominal bitrate: 0.75 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Author architecture (repository) · Source
LLM-Codec (LM objectives)
Adapts codec tokens to be easier for autoregressive language models to predict.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
LLM-Codec (UniAudio 1.5)
Maps audio into an existing language-model vocabulary while preserving reconstruction.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
LongCat Wav-VAE
Encodes speech directly into continuous waveform latents for LongCat-AudioDiT.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: ~11.72 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Parent LongCat-AudioDiT architecture with Wav-VAE · Source
LongCat-Audio-Codec
Extracts semantic and acoustic speech tokens in parallel with selectable decoders.
Paper · Code · Weights · Details
Audio: 16 kHz input; 16 / 24 kHz output · Frame rate: ~16.6 · Nominal bitrate: Not specified
Open license: code MIT · weights MIT
Author architecture (repository) · Source
Low Frame-rate Speech Codec (LFSC)
Reduces acoustic frame rate for speech language-model training and inference.
Paper · Code · Weights · Details
Audio: 22.05 kHz · Frame rate: 21.53 · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights NVIDIA Open Model License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
LTX-2 audio VAE
Encodes audio spectrograms into continuous latents and reconstructs stereo audio through the LTX-2 vocoder.
Audio: 16 kHz analysis → 24 kHz stereo output · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code LTX Community License (version-specific) · weights LTX-2 Community License — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
Lyra v2 (SoundStream-based)
Provides low-bitrate speech communication with bundled mobile inference models.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 (20 ms frames) · Nominal bitrate: 3.2 / 6 / 9.2 kbps
License unclear: code Apache-2.0 · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Editorial overview · Source
MagiCodec
Produces low-rate speech tokens using masked Gaussian-injection training.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 · Nominal bitrate: ≤0.85 kbps
Open license: code MIT · weights MIT
Editorial overview · Source
Mimi
Provides streaming semantic and acoustic tokens for real-time spoken dialogue.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 12.5 · Nominal bitrate: 1.1 kbps (8 codebooks)
Open license: code MIT (Python); Apache-2.0 (Rust) · weights CC-BY-4.0
Author architecture (repository) · Source
MiMo-Audio-Tokenizer
Learns reconstructable audio tokens with joint semantic and acoustic objectives.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 25 · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights MIT
Author architecture (repository) · Source
Ming-omni-tts continuous tokenizer
Compresses speech, music and environmental audio into a shared continuous latent sequence.
Audio: 44.1 kHz · Frame rate: 12.5 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights Apache-2.0
Editorial overview · Source
MingTok-Audio
Provides continuous audio latents for joint speech understanding, generation and editing.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights Apache-2.0
Editorial overview · Source
MiniMax H3 AudioVAE
Compresses stereo audio into a continuous representation for MiniMax H3 audio generation.
Audio: 32 kHz mono; stereo channels processed separately · Frame rate: 40 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code Apache-2.0 · weights MiniMax H3 Community License — The reviewed Diffusers codec implementation is Apache-2.0; the publisher’s checkpoint uses the MiniMax H3 Community License.
Editorial overview · Source
MMAudio VAE (16 / 44.1 kHz)
Encodes mel spectrograms into continuous audio latents and reconstructs waveforms with BigVGAN.
Paper · Code · Weights · Details
Audio: 16 / 44.1 kHz · Frame rate: 31.25 (16 kHz); ~43.07 (44.1 kHz) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code MIT · weights CC-BY-NC-4.0 — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
MOSS-Audio-Tokenizer
Provides low-rate semantic/acoustic tokens across speech, music and sound effects.
Paper · Code · Weights · Details
Audio: 24 kHz mono · Frame rate: 12.5 · Nominal bitrate: 0.125–4 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Author architecture (repository) · Source
MOSS-Audio-Tokenizer Nano
Provides a compact stereo audio codec for lower-cost deployment.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 12.5 · Nominal bitrate: 0.125–2 kbps
Open license: code Apache-2.0 · weights Apache-2.0
CAT family architecture (shared; variant details in model card) · Source
MOSS-Audio-Tokenizer v2
Extends the MOSS codec interface to native stereo audio at 48 kHz.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 12.5 · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
CAT family architecture (shared; variant details in model card) · Source
MuCodec
Reconstructs stereo music from an ultra-low-bitrate representation.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: Not specified · Nominal bitrate: 0.35 kbps (released configuration)
Custom / restricted: code MIT · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Fig. 1 · Source
Music2Latent
Encodes music and speech into compact continuous latents and reconstructs the waveform.
Paper · Code · Weights · Details
Audio: 44.1 kHz (also 48 kHz) · Frame rate: ~10 (44.1 kHz); ~12 (48 kHz) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Author architecture (repository) · Source
Musika autoencoder
Builds a compact, hierarchical continuous representation for waveform music reconstruction.
Paper · Code · Weights · Details
Audio: 44.1 kHz (released model card) · Frame rate: ~10.77 (final stage) · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Figure 1 — two-stage audio autoencoder · Source
NanoCodec
Provides low-frame-rate speech tokens with a compact, fast decoder.
Paper · Code · Weights · Details
Audio: 22.05 kHz · Frame rate: 12.5 (also 21.5) · Nominal bitrate: 1.78 kbps (also 1.89)
Custom / restricted: code Apache-2.0 · weights NVIDIA Open Model License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
NeuCodec
Compresses speech into one token stream and reconstructs it at a higher sample rate.
Paper · Code · Weights · Details
Audio: 16 kHz input → 24 kHz output · Frame rate: 50 · Nominal bitrate: 0.8 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
Omni2Sound OOB/Wav VAE
Provides a waveform latent representation for the audio path of Omni2Sound.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 25 (paper configuration) · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-4.0 · weights CC-BY-NC-4.0 — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
OmniVAE audio-only
Provides an independently usable audio VAE within the OmniVAE release.
Paper · Code · Weights · Details
Audio: 48 kHz · Frame rate: 50 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
OmniVAE family architecture; this card covers the audio-only checkpoint · Source
PAST
Learns phonetic and acoustic speech tokens jointly with waveform reconstruction.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
Qwen3-TTS-Tokenizer-12Hz
Encodes and reconstructs speech using low-rate, multi-codebook tokens.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 12.5 · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 — tokenizer family overview; 12.5 Hz variant · Source
RAVE (v1 / v2)
Provides variational audio encoders and decoders for reconstruction, timbre transfer and real-time audio processing.
Paper · Code · Weights · Details
Audio: Checkpoint-specific; not independently established · Frame rate: Not specified · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code CC-BY-NC-4.0 · weights Not stated on the inspected download catalog — The code has noncommercial terms. The inspected author download catalog does not separately state the MusicNet checkpoint license.
Figure 1 — original RAVE family architecture · Source
SAC
Uses separate semantic and acoustic quantization streams for speech reconstruction.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 37.5 / 62.5 · Nominal bitrate: 0.525 / 0.875 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Figure 2 · Source
SAME (S / L)
Compresses stereo audio into semantically aligned continuous latents with transformer-based encoders and decoders.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo · Frame rate: ~10.77 · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code MIT · weights Stability AI Community License — The linked noncommercial or custom terms apply to this release.
Editorial overview · Source
Semantic-VAE
Aligns continuous speech latents with semantic information for speech synthesis.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 40 · Nominal bitrate: Not applicable: continuous latents
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Figure 2 · Source
SemantiCodec
Compresses general audio into semantic and acoustic tokens with diffusion reconstruction.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: See total token-rate variants · Nominal bitrate: ~0.31–1.40 kbps
Open license: code MIT · weights MIT
Fig. 2 · Source
SimWhisper-Codec
Uses a simplified Whisper-based representation for low-bitrate speech coding.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
Open license: code Apache-2.0 · weights Apache-2.0
Author architecture (repository) · Source
SNAC
Uses coarse and fine token streams at different time scales to shorten audio token sequences.
Paper · Code · Weights · Details
Audio: 24 kHz speech; 32 / 44.1 kHz audio · Frame rate: Multiple temporal scales · Nominal bitrate: 0.98 / 1.9 / 2.6 kbps by variant
Open license: code MIT · weights MIT
Author architecture (repository) · Source
SoCodec
Orders speech token streams by semantic content for efficient speech language modeling.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 8.33 (120 ms frames) · Nominal bitrate: ~0.47 kbps
Open license: code MIT · weights MIT
Author architecture (repository) · Source
SoviaMate-Codec
Provides reconstruction and speaker-conditioned codec checkpoints with enhancement training.
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code Apache-2.0 · weights Apache-2.0 — The model card adds usage restrictions alongside its Apache-2.0 declaration.
Editorial overview · Source
Speech DAC (IBM)
Fine-tunes DAC for compact, high-quality speech representations.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 75 · Nominal bitrate: 1.5 / 3 kbps
Open license: code MIT · weights CDLA-Permissive-2.0
Editorial overview · Source
SpeechTokenizer
Separates a content-oriented first token stream from residual acoustic detail.
Paper · Code · Weights · Details
Audio: 16 kHz mono · Frame rate: 50 · Nominal bitrate: 4 kbps (8 codebooks)
License unclear: code Apache-2.0 · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
Spine
Encodes expressive speech with token streams at several temporal scales.
Audio: 24 kHz mono · Frame rate: ~6 / 12 / 23 / 47 by scale · Nominal bitrate: 1.57 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Author architecture (repository) · Source
Stable Audio Open autoencoder (Oobleck)
Compresses stereo waveforms into continuous latents for audio diffusion models.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo · Frame rate: Not specified · Nominal bitrate: Not applicable: continuous latents
Custom / restricted: code MIT · weights Stability AI Community License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
Stable Codec
Uses large Transformer autoencoders for low-bitrate speech coding.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
Custom / restricted: code MIT · weights Stability AI Community License — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
STFT-VAE
Compresses complex spectrograms into very low-rate continuous audio latents and reconstructs phase with an inverse STFT.
Audio: 24 kHz mono · Frame rate: 3.125 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Editorial overview · Source
TaDiCodec
Uses text-guided diffusion reconstruction to reduce the speech-token frame rate.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 6.25 · Nominal bitrate: 0.0875 kbps (tokens only)
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
TiCodec
Moves time-invariant speech information into a separate code to reduce frame-level tokens.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
U-Codec
Reduces the speech representation to an ultra-low frame rate for speech generation.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 5 · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
UniCodec (domain-adaptive)
Uses one domain-adaptive codebook across speech, music and other sounds.
Paper · Code · Weights · Details
Audio: Not specified · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code Not stated · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
VibeVoice acoustic tokenizer
Compresses speech into low-frame-rate continuous acoustic representations.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 7.5 · Nominal bitrate: Not applicable: continuous latents
Open license: code MIT · weights MIT
Editorial overview · Source
VoxCPM AudioVAE (1.0 / 1.5)
Reconstructs speech from continuous latents used by VoxCPM and VoxCPM1.5.
Paper · Code · Weights · Details
Audio: 44.1 kHz (1.5); 16 kHz (1.0) · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Parent VoxCPM architecture with AudioVAE · Source
VoxCPM2 AudioVAE V2
Encodes 16 kHz reference speech and decodes continuous latents into 48 kHz speech.
Paper · Code · Weights · Details
Audio: 16 kHz input → 48 kHz output · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Parent VoxCPM2 architecture with AudioVAE V2 · Source
WavTokenizer
Represents speech, music and sounds with a single low-rate discrete stream.
Paper · Code · Weights · Details
Audio: 24 kHz · Frame rate: 40 (also 75) · Nominal bitrate: 0.48 kbps (40 Hz × 12 bits)
Open license: code MIT · weights MIT
Editorial overview · Source
X-Codec
Combines pretrained semantic features with acoustic features before quantization.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: Not specified · Nominal bitrate: Not specified
License unclear: code MIT · weights Not stated — The reviewed sources do not state complete code and checkpoint terms.
Author architecture (repository) · Source
X-Codec 2
Encodes multilingual speech into a single stream for speech language modeling.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 50 · Nominal bitrate: 0.8 kbps
Custom / restricted: code MIT · weights CC-BY-NC-4.0 — The linked custom or noncommercial terms apply to this release.
Editorial overview · Source
XY-Tokenizer
Aligns speech content and acoustics in low-frame-rate tokens.
Paper · Code · Weights · Details
Audio: 16 kHz · Frame rate: 12.5 · Nominal bitrate: 1 kbps
Open license: code Apache-2.0 · weights Apache-2.0
Author architecture (repository) · Source
εar-VAE
Learns stereo music latents with objectives that preserve phase and spatial structure.
Paper · Code · Weights · Details
Audio: 44.1 kHz stereo; 48 kHz variant · Frame rate: ~43.07 (44.1 kHz / 1024) · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Editorial overview · Source
εar-VAE2
Reconstructs stereo music using a variational representation learned in the complex spectral domain.
Paper · Code · Weights · Details
Audio: 48 kHz stereo · Frame rate: 25 · Nominal bitrate: Not applicable: continuous latents
Open license: code Apache-2.0 · weights Apache-2.0
Figure 1 — spectral audio VAE architecture · Source
Contributing
See CONTRIBUTING.md to add a model or correct evidence. The catalog and gallery are generated from JSON with a dependency-free Python script.
Inspired by Awesome Omni Architectures and Awesome TTS Architectures.
License
Original catalog text, scripts and editorial diagrams: MIT. Author figures and listed models retain their own terms.
Similar repos
Contributors
3 commits
Languages
Python
100.0%