
(TPAMI 2024) A Survey on Open Vocabulary Learning
See the codeREADME


Towards Open Vocabulary Learning: A Survey
T-PAMI, 2024
Jianzong Wu *
.
Xiangtai Li *
·
Shilin Xu *
·
Haobo Yuan *
·
Henghui Ding
·
Yibo Yang
·
Xia Li
·
Jiangning Zhang
·
Yunhai Tong
·
Xudong Jiang
·
Bernard Ghanem
·
Dacheng Tao
·


This repo is used for recording, tracking, and benchmarking several recent open vocabulary methods to supplement our survey. If you find any work missing or have any suggestions (papers, implementations, and other resources), feel free to pull requests. We will add the missing papers to this repo as soon as possible.
🔥Add Your Paper in our Repo and Survey!!!!!
[-] You are welcome to give us an issue or PR for your open vocabulary learning work !!!!!
[-] Note that: Due to the huge paper in Arxiv, we are sorry to cover all in our survey. You can directly present a PR into this repo and we will record it for next version update of our survey.
[-] Our survey will be updated in 2024.3.
🔥New
[-] Our work is accepted by T-PAMI !!! 🔥🔥🔥
[-] We update GitHub to record the available paper by the end of 2024/1/10.
[-] We update GitHub to record the available paper by the end of 2023/7/20.
🔥Highlight!!
[1] The first survey for open vocabulary learning, including open vocabulary detection/segmentation/tracking.
[2] It also contains several related domains, including foundation model tuning and open-world detection.
[3] We list detailed results for the most representative works and give a fairer and clearer comparison of different approaches.
Introduction
This survey presents the first detailed survey on open vocabulary tasks, including open-vocabulary object detection, open-vocabulary segmentation, and 3D/video open-vocabulary tasks.
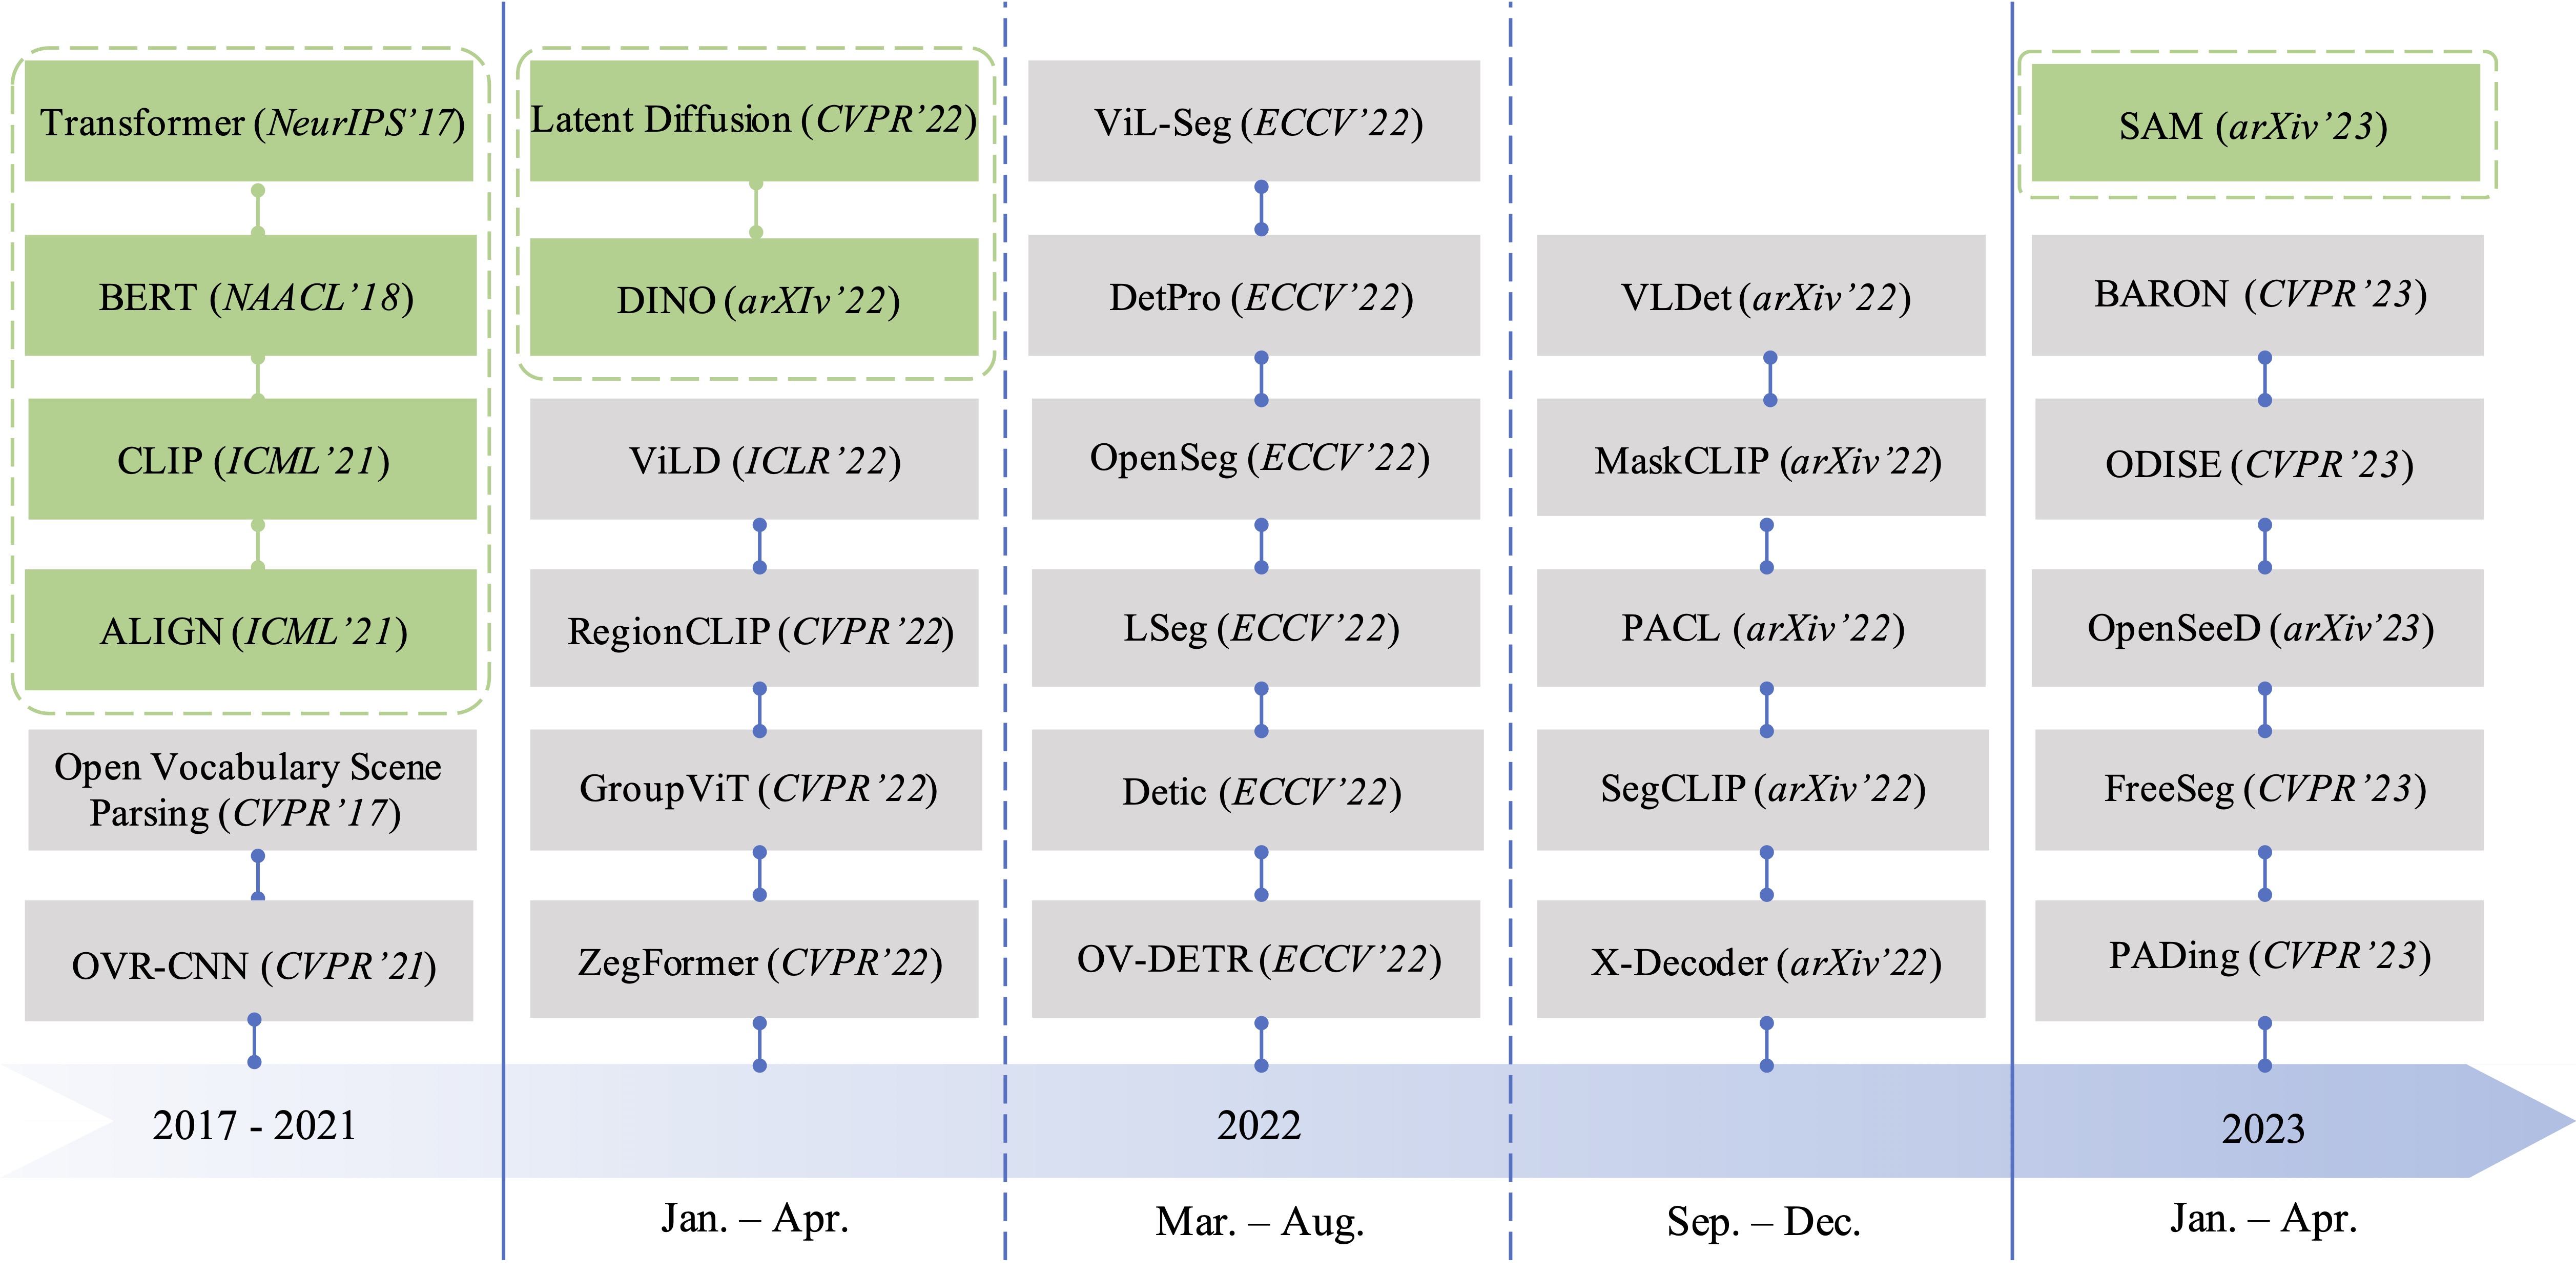
Summary of Contents
- Introduction
- Summary of Contents
- Methods: A Survey
- Related Domains and Beyond
- Acknowledgement
- Contact
Methods: A Survey
Keywords
cap.: Use caption as auxiliary training datavlm.: Use pretrained VLMs like CLIPpl.: Generate pseudo labelsw/o ps.: Training without pixel-level supervisionpre.: Vision-language pretrainingdiff.: Use diffusion modelsunify: Unify several tasks (semantic segmentation, instance segmentation, and panoptic segmentation)sam: Use SAM (Segment Anything Model)open.: Demonstrated with open-set capability. (only for Video Understanding)audio.: With audio modality.bench: Propose a benchmark.other: Other methods that cannot be grouped into above ones.no-train: Does not need training.
Open Vocabulary Object Detection
Open Vocabulary Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | unify., vlm. | Primitive Generation and Semantic-related Alignment for Universal Zero-Shot Segmentation | Code |
| 2023 | CVPR | unify., vlm. | FreeSeg: Unified, Universal and Open-Vocabulary Image Segmentation | Code |
| 2023 | arXiv | unify., vlm. | OpenSD: Unified Open-Vocabulary Segmentation and Detection | Code |
Semantic Segmentation
Instance Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | vlm. | Semantic-Promoted Debiasing and Background Disambiguation for Zero-Shot Instance Segmentation | Code |
| 2022 | CVPR | cap., pl., vlm. | Open-Vocabulary Instance Segmentation via Robust Cross-Modal Pseudo-Labeling | Code |
| 2023 | CVPR | vlm, cap, w/o ps. | Mask-free OVIS: Open-Vocabulary Instance Segmentation without Manual Mask Annotations | Code |
| 2023 | arXiv | cap. | Betrayed by Captions: Joint Caption Grounding and Generation for Open Vocabulary Instance Segmentation | Code |
| 2023 | arXiv | cap. | Leveraging Open-Vocabulary Diffusion to Camouflaged Instance Segmentation | N/A |
Panoptic Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | unify., vlm. | Primitive Generation and Semantic-related Alignment for Universal Zero-Shot Segmentation | Code |
| 2022 | arXiv | vlm | Open-Vocabulary Panoptic Segmentation with MaskCLIP | N/A |
| 2023 | CVPR | diff, vlm | Open-Vocabulary Panoptic Segmentation with Text-to-Image Diffusion Models | Code |
| 2023 | ICCV | vlm. | Open-vocabulary Panoptic Segmentation with Embedding Modulation | N/A |
| 2023 | NeurIPS | vlm., unify | Hierarchical Open-vocabulary Universal Image Segmentation | Code |
| 2024 | CVPR | vlm., unify, 'open' | OMG-Seg: Is One Model Good Enough For All Segmentation? | Code |
Open Vocabulary Video Understanding
Video Classification
Tracking
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | vlm.,open. | OVTrack: Open-Vocabulary Multiple Object Tracking | Project |
Video Instance Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | ICCV | vlm.,open. | Towards Open-Vocabulary Video Instance Segmentation | Code |
| 2023 | arXiv | vlm.,open. | OpenVIS: Open-vocabulary Video Instance Segmentation | N/A |
| 2023 | arXiv | vlm.,open. | DVIS++: Improved Decoupled Framework for Universal Video Segmentation | Code |
Open Vocabulary 3D Scene Understanding
3D Classification
3D Detection
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | arXiv | vlm. | Open-Vocabulary 3D Detection via Image-level Class and Debiased Cross-modal Contrastive Learning | N/A |
| 2023 | CVPR | vlm. | Open-Vocabulary Point-Cloud Object Detection without 3D Annotation | Code |
| 2023 | NeurIPS | vlm. | CoDA: Collaborative Novel Box Discovery and Cross-modal Alignment for Open-vocabulary 3D Object Detection | Project |
| 2023 | arXiv | vlm. | Object2Scene: Putting Objects in Context for Open-Vocabulary 3D Detection | N/A |
| 2023 | arXiv | vlm. | FM-OV3D: Foundation Model-based Cross-modal Knowledge Blending for Open-Vocabulary 3D Detection | N/A |
| 2023 | arXiv | vlm. | OpenSight: A Simple Open-Vocabulary Framework for LiDAR-Based Object Detection | N/A |
| 2024 | arXiv | vlm. | Open Vocabulary Monocular 3D Object Detection | Project |
3D segmentation
Related Domains and Beyond
Class-agnostic Detection and Segmentation
Open-World Object Detection
Open-Set Panoptic Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2021 | CVPR | - | Exemplar-Based Open-Set Panoptic Segmentation Network | Project |
| 2022 | BMVC | - | Dual Decision Improves Open-Set Panoptic Segmentation | Code |
Acknowledgement
If you find our survey and repository useful for your research project, please consider citing our paper:
@article{wu2023open,
      title={Towards Open Vocabulary Learning: A Survey},
      author={Jianzong Wu and Xiangtai Li and Shilin Xu and Haobo Yuan and Henghui Ding and Yibo Yang and Xia Li and Jiangning Zhang and Yunhai Tong and Xudong Jiang and Bernard Ghanem and Dacheng Tao},
      year={2024},
      journal={T-PAMI},
}
Contact
jzwu@stu.pku.edu.cn
lxtpku@pku.edu.cn or xiangtai94@gmail.com
Similar repos


(TPAMI 2024) A Survey on Open Vocabulary Learning
See the codeREADME
Towards Open Vocabulary Learning: A Survey
T-PAMI, 2024
Jianzong Wu *
.
Xiangtai Li *
·
Shilin Xu *
·
Haobo Yuan *
·
Henghui Ding
·
Yibo Yang
·
Xia Li
·
Jiangning Zhang
·
Yunhai Tong
·
Xudong Jiang
·
Bernard Ghanem
·
Dacheng Tao
·
This repo is used for recording, tracking, and benchmarking several recent open vocabulary methods to supplement our survey. If you find any work missing or have any suggestions (papers, implementations, and other resources), feel free to pull requests. We will add the missing papers to this repo as soon as possible.
🔥Add Your Paper in our Repo and Survey!!!!!
[-] You are welcome to give us an issue or PR for your open vocabulary learning work !!!!!
[-] Note that: Due to the huge paper in Arxiv, we are sorry to cover all in our survey. You can directly present a PR into this repo and we will record it for next version update of our survey.
[-] Our survey will be updated in 2024.3.
🔥New
[-] Our work is accepted by T-PAMI !!! 🔥🔥🔥
[-] We update GitHub to record the available paper by the end of 2024/1/10.
[-] We update GitHub to record the available paper by the end of 2023/7/20.
🔥Highlight!!
[1] The first survey for open vocabulary learning, including open vocabulary detection/segmentation/tracking.
[2] It also contains several related domains, including foundation model tuning and open-world detection.
[3] We list detailed results for the most representative works and give a fairer and clearer comparison of different approaches.
Introduction
This survey presents the first detailed survey on open vocabulary tasks, including open-vocabulary object detection, open-vocabulary segmentation, and 3D/video open-vocabulary tasks.
Summary of Contents
- Introduction
- Summary of Contents
- Methods: A Survey
- Related Domains and Beyond
- Acknowledgement
- Contact
Methods: A Survey
Keywords
cap.: Use caption as auxiliary training datavlm.: Use pretrained VLMs like CLIPpl.: Generate pseudo labelsw/o ps.: Training without pixel-level supervisionpre.: Vision-language pretrainingdiff.: Use diffusion modelsunify: Unify several tasks (semantic segmentation, instance segmentation, and panoptic segmentation)sam: Use SAM (Segment Anything Model)open.: Demonstrated with open-set capability. (only for Video Understanding)audio.: With audio modality.bench: Propose a benchmark.other: Other methods that cannot be grouped into above ones.no-train: Does not need training.
Open Vocabulary Object Detection
Open Vocabulary Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | unify., vlm. | Primitive Generation and Semantic-related Alignment for Universal Zero-Shot Segmentation | Code |
| 2023 | CVPR | unify., vlm. | FreeSeg: Unified, Universal and Open-Vocabulary Image Segmentation | Code |
| 2023 | arXiv | unify., vlm. | OpenSD: Unified Open-Vocabulary Segmentation and Detection | Code |
Semantic Segmentation
Instance Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | vlm. | Semantic-Promoted Debiasing and Background Disambiguation for Zero-Shot Instance Segmentation | Code |
| 2022 | CVPR | cap., pl., vlm. | Open-Vocabulary Instance Segmentation via Robust Cross-Modal Pseudo-Labeling | Code |
| 2023 | CVPR | vlm, cap, w/o ps. | Mask-free OVIS: Open-Vocabulary Instance Segmentation without Manual Mask Annotations | Code |
| 2023 | arXiv | cap. | Betrayed by Captions: Joint Caption Grounding and Generation for Open Vocabulary Instance Segmentation | Code |
| 2023 | arXiv | cap. | Leveraging Open-Vocabulary Diffusion to Camouflaged Instance Segmentation | N/A |
Panoptic Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | unify., vlm. | Primitive Generation and Semantic-related Alignment for Universal Zero-Shot Segmentation | Code |
| 2022 | arXiv | vlm | Open-Vocabulary Panoptic Segmentation with MaskCLIP | N/A |
| 2023 | CVPR | diff, vlm | Open-Vocabulary Panoptic Segmentation with Text-to-Image Diffusion Models | Code |
| 2023 | ICCV | vlm. | Open-vocabulary Panoptic Segmentation with Embedding Modulation | N/A |
| 2023 | NeurIPS | vlm., unify | Hierarchical Open-vocabulary Universal Image Segmentation | Code |
| 2024 | CVPR | vlm., unify, 'open' | OMG-Seg: Is One Model Good Enough For All Segmentation? | Code |
Open Vocabulary Video Understanding
Video Classification
Tracking
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | CVPR | vlm.,open. | OVTrack: Open-Vocabulary Multiple Object Tracking | Project |
Video Instance Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2023 | ICCV | vlm.,open. | Towards Open-Vocabulary Video Instance Segmentation | Code |
| 2023 | arXiv | vlm.,open. | OpenVIS: Open-vocabulary Video Instance Segmentation | N/A |
| 2023 | arXiv | vlm.,open. | DVIS++: Improved Decoupled Framework for Universal Video Segmentation | Code |
Open Vocabulary 3D Scene Understanding
3D Classification
3D Detection
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2022 | arXiv | vlm. | Open-Vocabulary 3D Detection via Image-level Class and Debiased Cross-modal Contrastive Learning | N/A |
| 2023 | CVPR | vlm. | Open-Vocabulary Point-Cloud Object Detection without 3D Annotation | Code |
| 2023 | NeurIPS | vlm. | CoDA: Collaborative Novel Box Discovery and Cross-modal Alignment for Open-vocabulary 3D Object Detection | Project |
| 2023 | arXiv | vlm. | Object2Scene: Putting Objects in Context for Open-Vocabulary 3D Detection | N/A |
| 2023 | arXiv | vlm. | FM-OV3D: Foundation Model-based Cross-modal Knowledge Blending for Open-Vocabulary 3D Detection | N/A |
| 2023 | arXiv | vlm. | OpenSight: A Simple Open-Vocabulary Framework for LiDAR-Based Object Detection | N/A |
| 2024 | arXiv | vlm. | Open Vocabulary Monocular 3D Object Detection | Project |
3D segmentation
Related Domains and Beyond
Class-agnostic Detection and Segmentation
Open-World Object Detection
Open-Set Panoptic Segmentation
| Year | Venue | Keywords | Paper Title | Code/Project |
|---|---|---|---|---|
| 2021 | CVPR | - | Exemplar-Based Open-Set Panoptic Segmentation Network | Project |
| 2022 | BMVC | - | Dual Decision Improves Open-Set Panoptic Segmentation | Code |
Acknowledgement
If you find our survey and repository useful for your research project, please consider citing our paper:
@article{wu2023open,
      title={Towards Open Vocabulary Learning: A Survey},
      author={Jianzong Wu and Xiangtai Li and Shilin Xu and Haobo Yuan and Henghui Ding and Yibo Yang and Xia Li and Jiangning Zhang and Yunhai Tong and Xudong Jiang and Bernard Ghanem and Dacheng Tao},
      year={2024},
      journal={T-PAMI},
}
Contact
jzwu@stu.pku.edu.cn
lxtpku@pku.edu.cn or xiangtai94@gmail.com