
Meta-Transformer for Unified Multimodal Learning
See the codeREADME
Hongsheng Li 1,2 Yu Qiao 2 Wanli Ouyang2 Xiangyu Yue1,†,‡
2 OpenGVLab,Shanghai AI Laboratory
* Equal Contribution † Corresponding Author ‡ Project Lead





Meta-Transformer with Large Language Models ✨✨✨
We're thrilled to present OneLLM, ensembling Meta-Transformer framework with Multimodal Large Language Models, which performs multimodal joint training🚀, supports more modalities including fMRI, Depth and Normal Maps 🚀, and demonstrates very impressive performances on 25 benchmarks🚀🚀🚀.
🔥🔥 The code, pretrained models, and datasets are publicly available at OneLLM.
🔥🔥 Project Website is at OneLLM.
🌟 Single Foundation Model Supports A Wide Range of Applications
As a foundation model, Meta-Transformer can handle data from 12 modalities, which determines that it can support a wide range of applications. As shown in this figure, Meta-Transformer can provide services for downstream tasks including stock analysis 📈, weather forecasting ☀️ ☔ ☁️ ❄️ ⛄ ⚡, remote sensing 📡, autonomous driving 🚗, social network 🌍, speech recognition 🔉, etc.
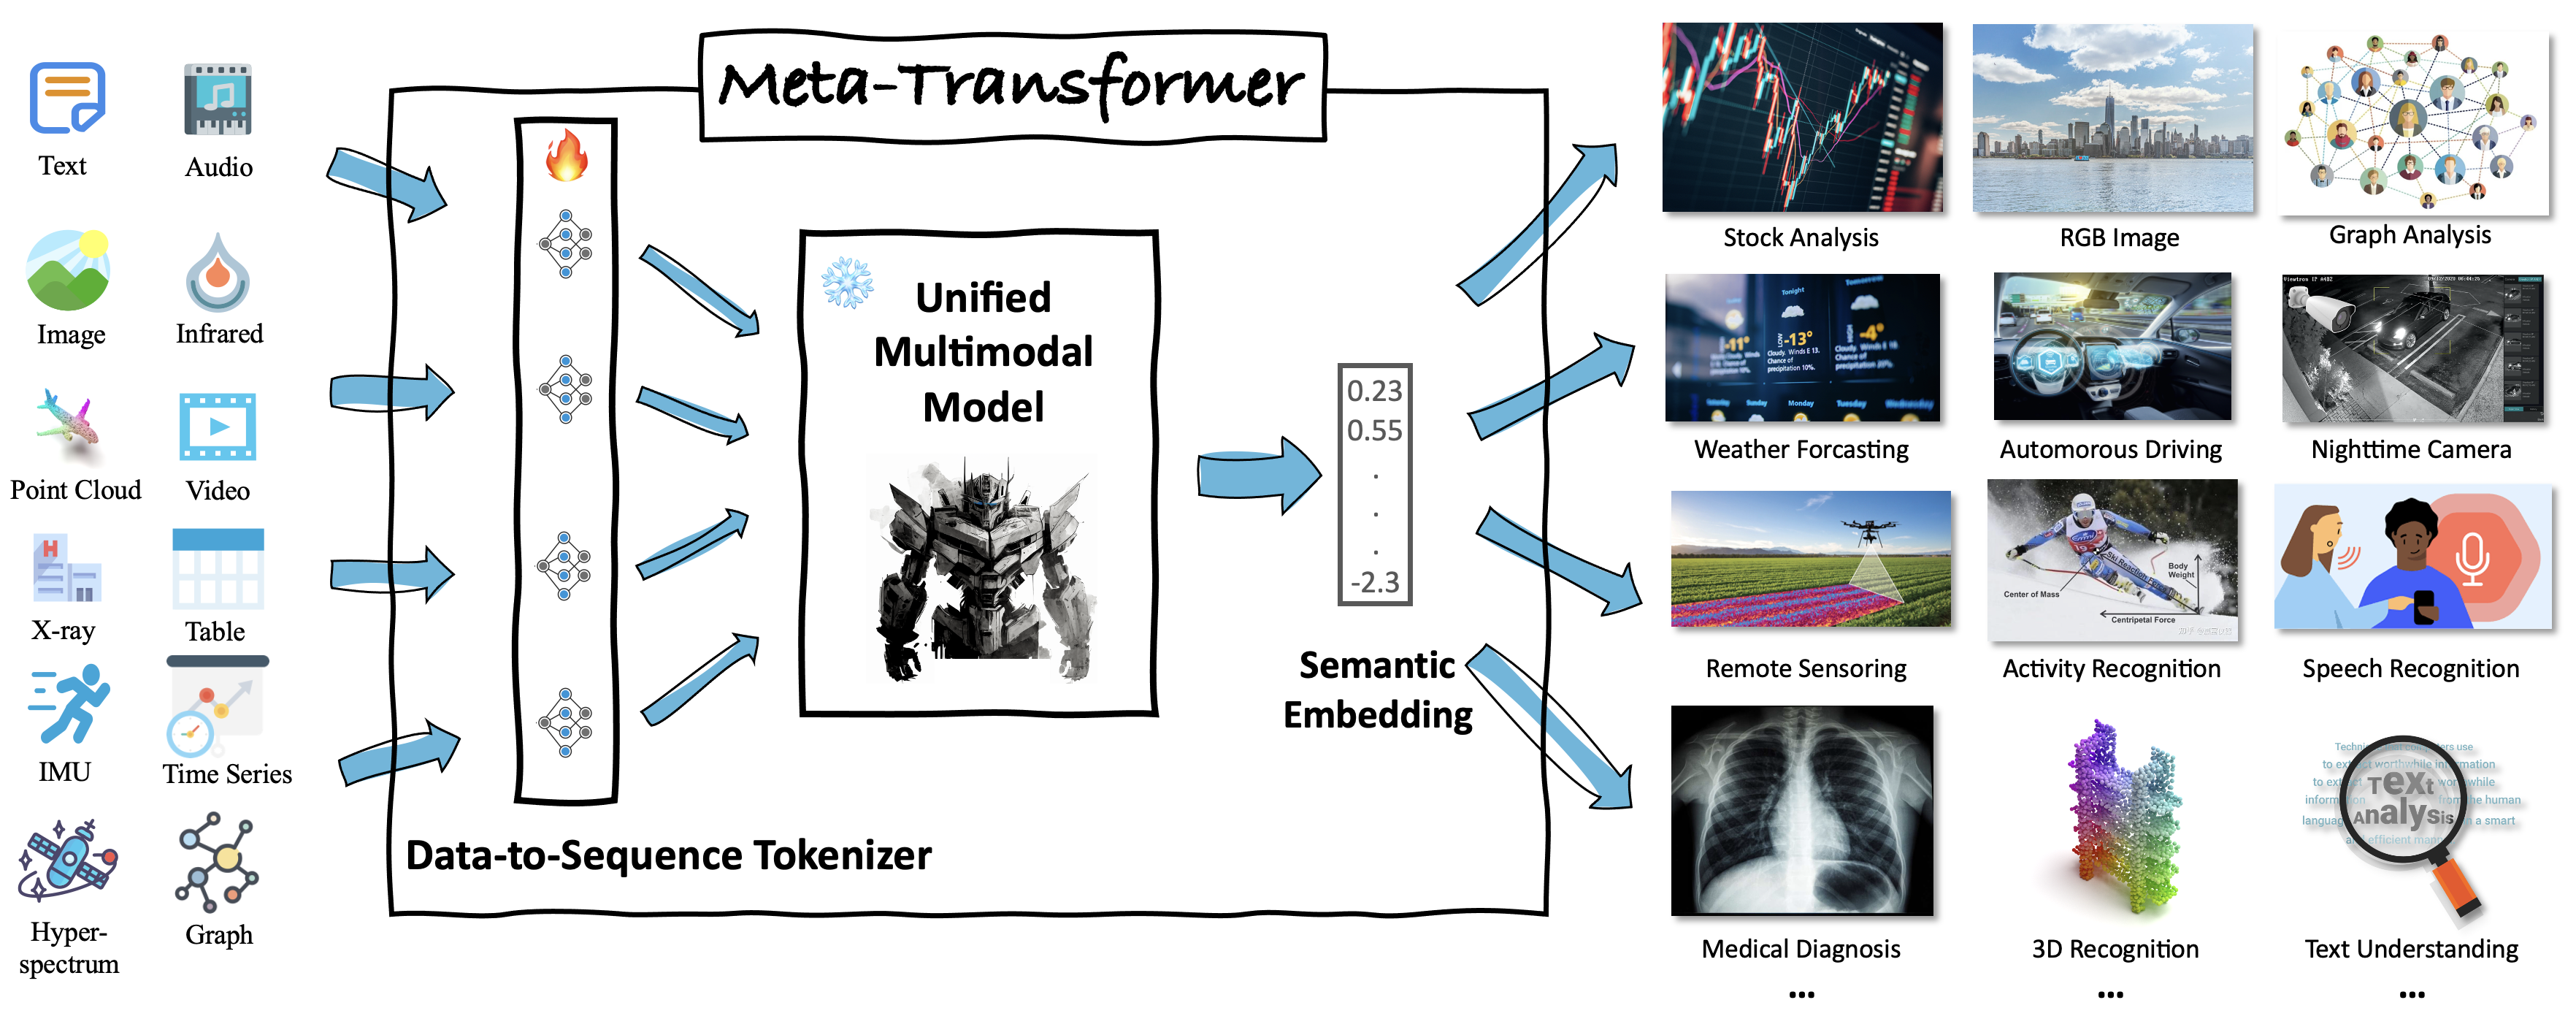
Table 1: Meta-Transformer is capable of handling up to 12 modalities, including natural language  , RGB images
 , point clouds
 , audios
 , videos
 , tabular data
 , graph
 , time series data
 , hyper-spectral images
 , IMU
 , medical images
 , and infrared images
 .
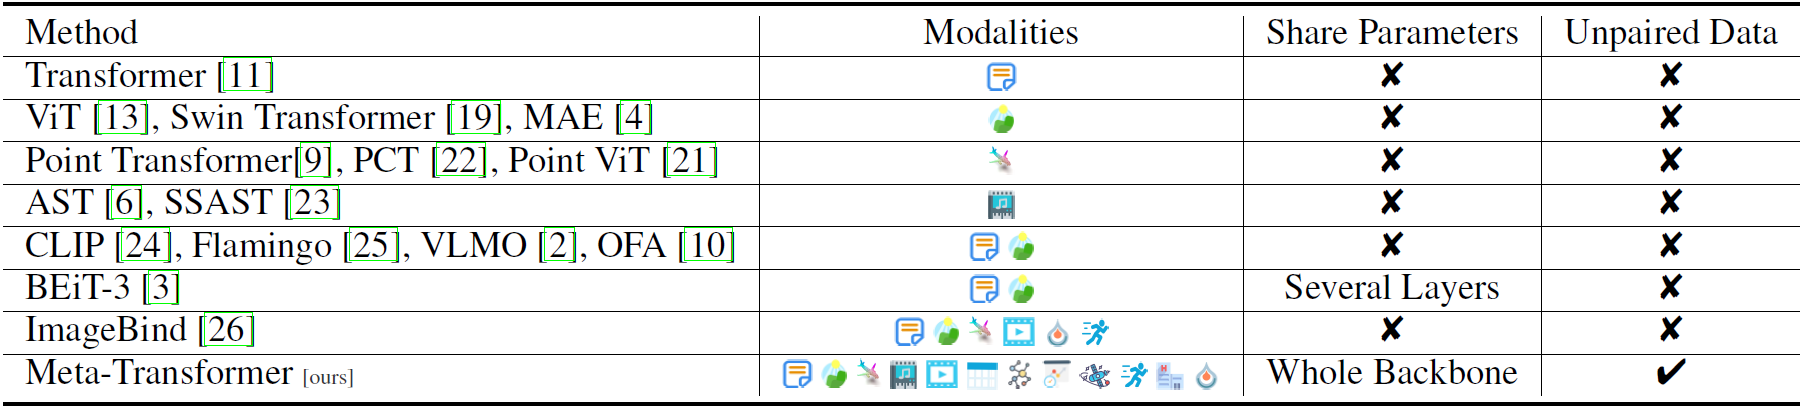
🚩🚩🚩 Shared-Encoder, Unpaired Data, More Modalities
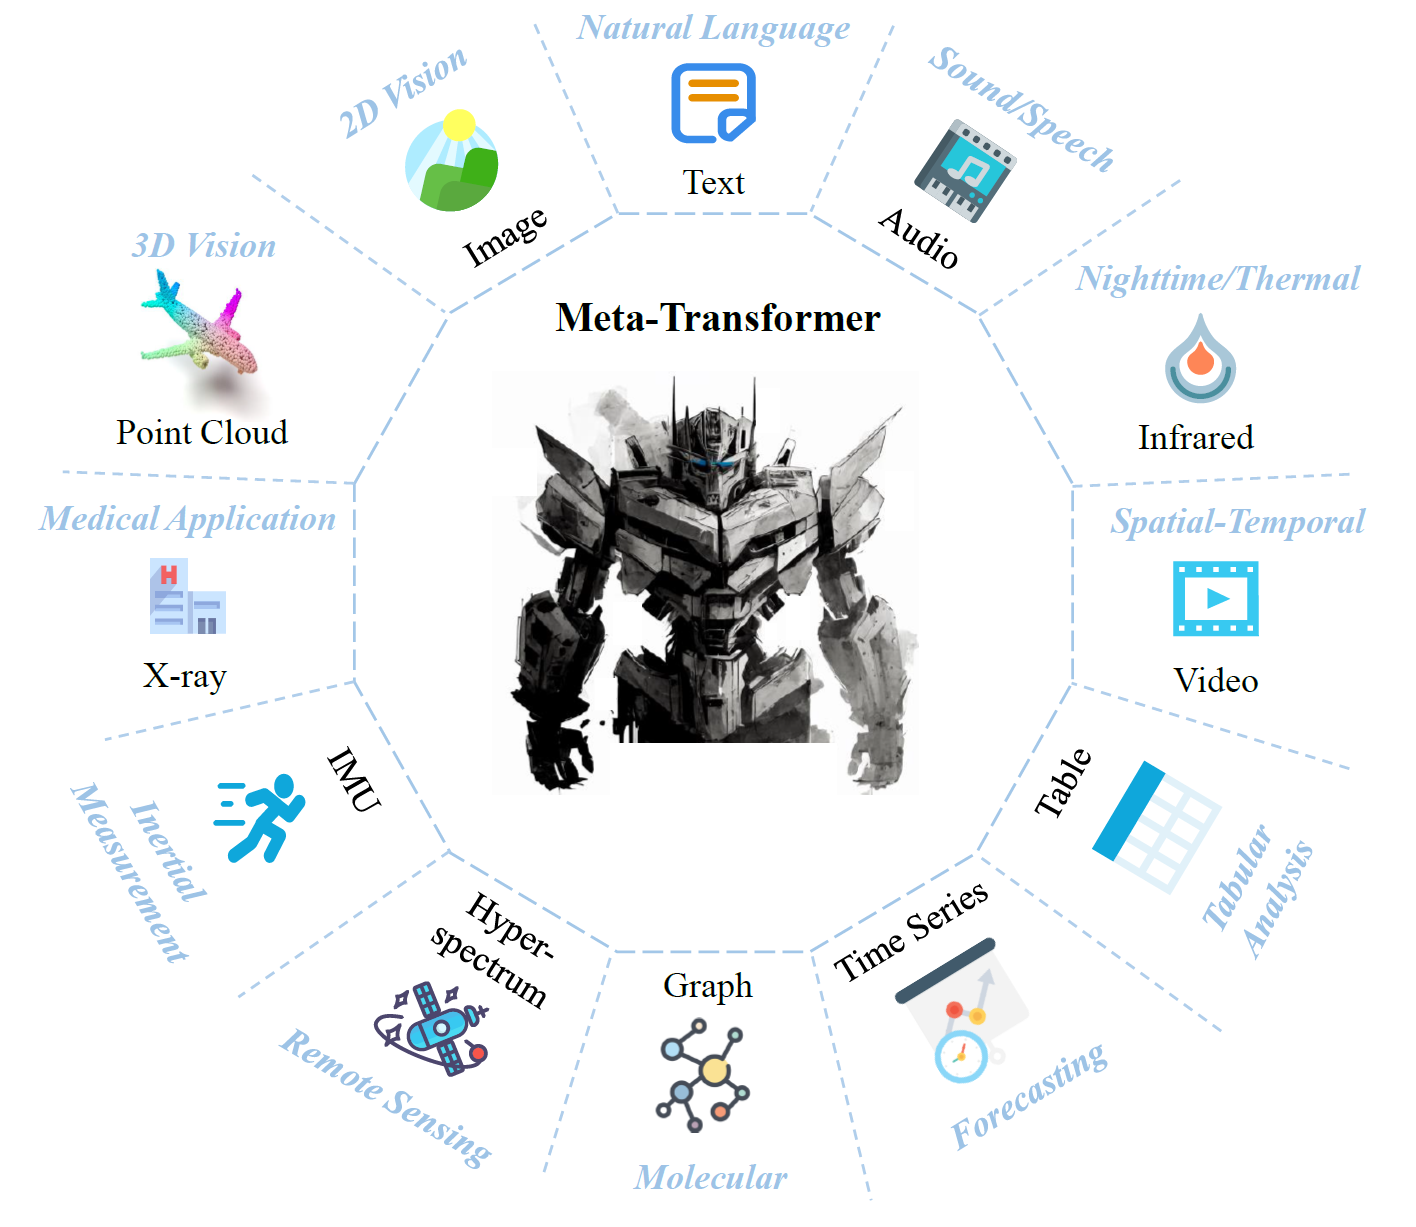
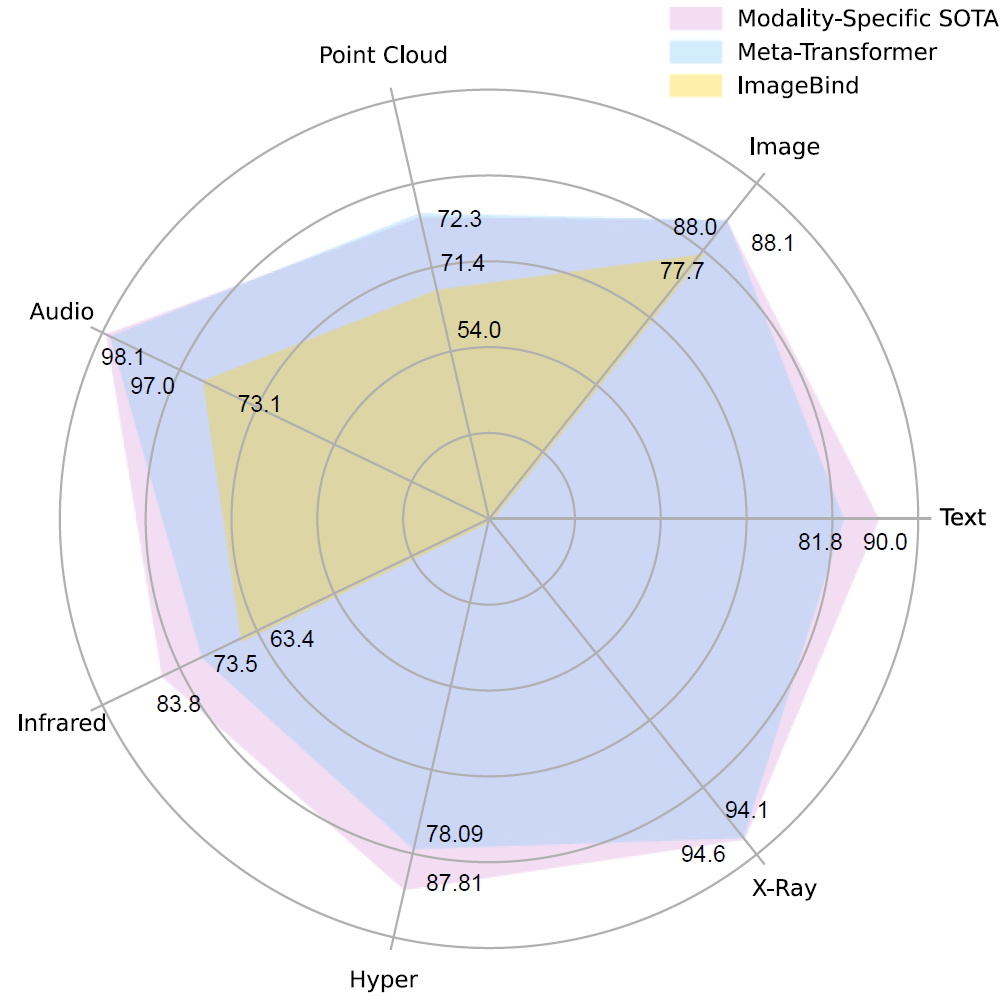
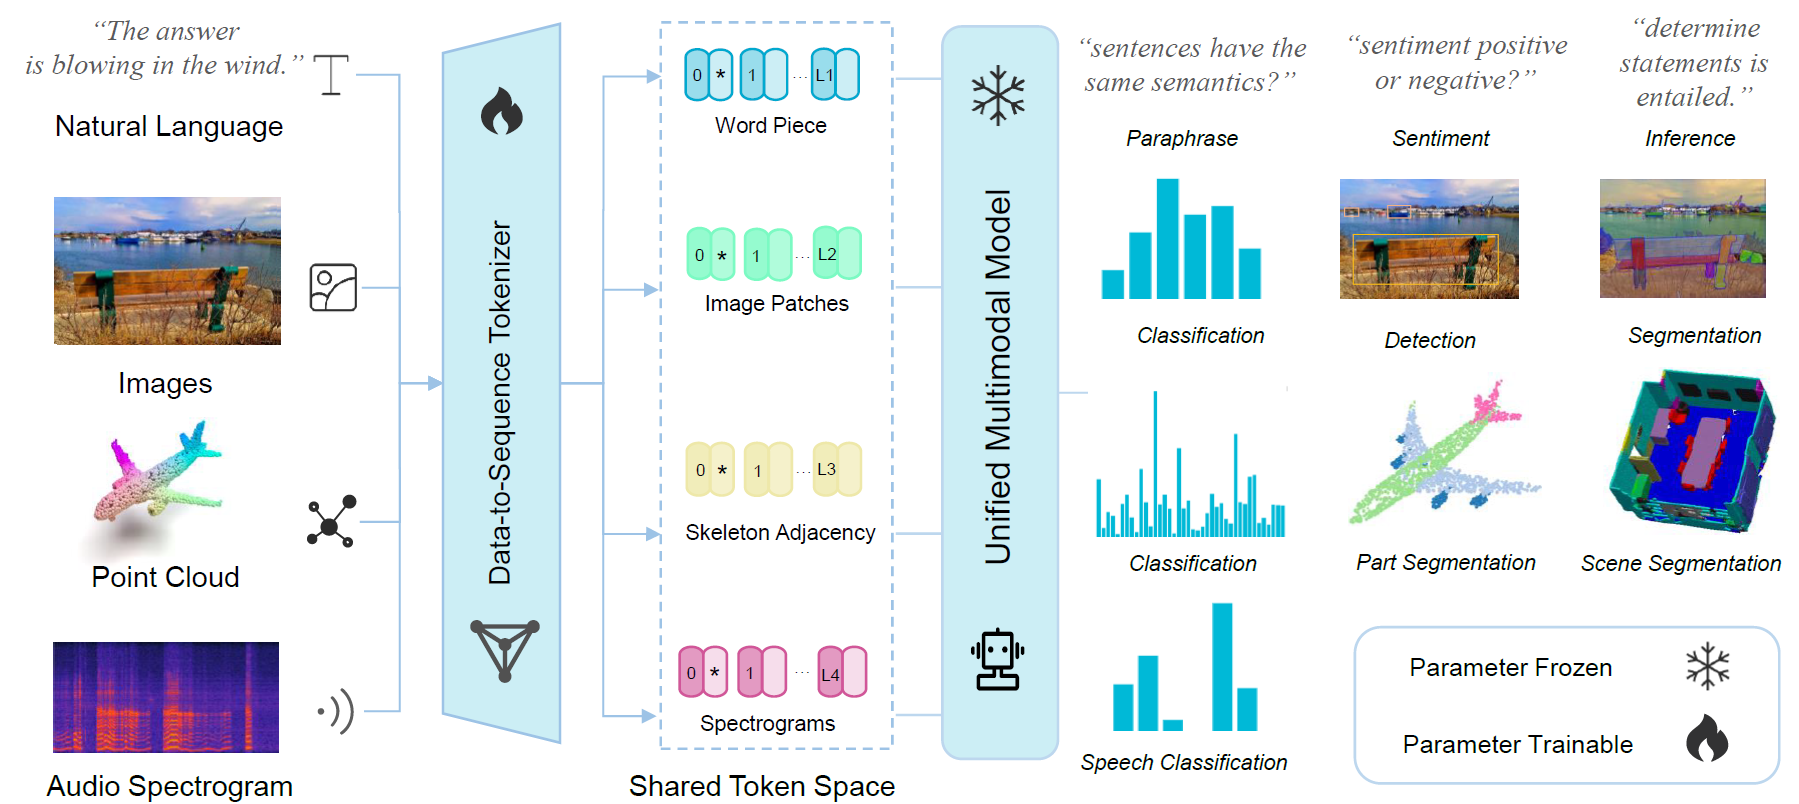
This repository is built to explore the potential and extensibility of transformers for multimodal learning. We utilize the advantages of Transformers to deal with length-variant sequences. Then we propose the Data-to-Sequence tokenization following a meta-scheme, then we apply it to 12 modalities including text, image, point cloud, audio, video, infrared, hyper-spectral, X-Ray, tabular, graph, time-series, and Inertial Measurement Unit (IMU) data.
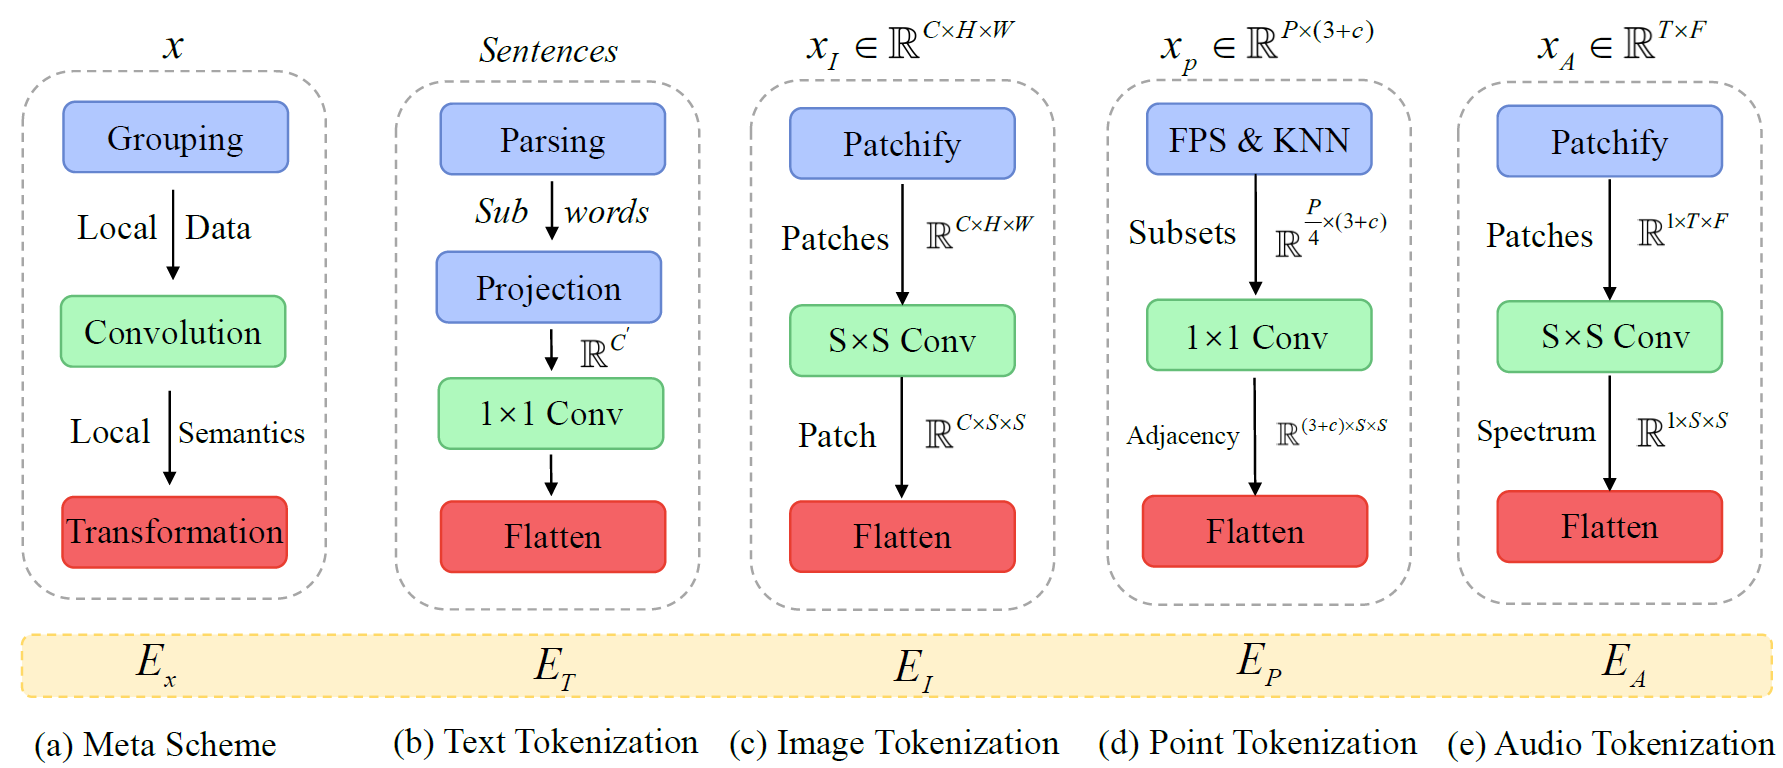
After obtaining the token sequence, we employ a modality-shared encoder to extract representation across different modalities. With task-specific heads, Meta-Transformer can handle various tasks on the different modalities, such as: classification, detection, and segmentation.
🌟 News
- 2023.8.17: Release code to directly get embeddings from multiple modalities. We will further release code on utilizing Meta-Transformer for Human-Centric vision tasks.
- 2023.8.2: 🎉🎉🎉 The implementation of Meta-Transformer for image, point cloud, graph, tabular, time-series, X-Ray, hyper-spectrum, LiDAR data has been released. We also release a very powerful foundation model for Autonomous Driving 🚀🚀🚀.
- 2023.7.22: Pretrained weights and a usage demo for our Meta-Transformer have been released. Comprehensive documentation and implementation of the image modality are underway and will be released soon. Stay tuned for more exciting updates!⌛⌛⌛
- 2023.7.21: Paper is released at arxiv, and code will be gradually released.
- 2023.7.8: Github Repository Initialization.
🔓 Model Zoo
- Demo of Use for Pretrained Encoder
import torch
import torch.nn as nn
from timm.models.vision_transformer import Block
from Data2Seq import Data2Seq
video_tokenier = Data2Seq(modality='video',dim=768)
audio_tokenier = Data2Seq(modality='audio',dim=768)
time_series_tokenier = Data2Seq(modality='time-series',dim=768)

features = torch.concat([video_tokenizer(video), audio_tokenizer(audio), time_series_tokenizer(time_data)],dim=1)
# For base-scale encoder:
ckpt = torch.load("Meta-Transformer_base_patch16_encoder.pth")
encoder = nn.Sequential(*[
            Block(
                dim=768,
                num_heads=12,
                mlp_ratio=4.,
                qkv_bias=True,
                norm_layer=nn.LayerNorm,
                act_layer=nn.GELU
            )
            for i in range(12)])
encoder.load_state_dict(ckpt,strict=True)
# For large-scale encoder:
ckpt = torch.load("Meta-Transformer_large_patch14_encoder.pth")
encoder = nn.Sequential(*[
            Block(
                dim=1024,
                num_heads=16,
                mlp_ratio=4.,
                qkv_bias=True,
                norm_layer=nn.LayerNorm,
                act_layer=nn.GELU
            )
            for i in range(24)])
encoder.load_state_dict(ckpt,strict=True)
encoded_features = encoder(features)
🕙 ToDo
- [ x ] Meta-Transformer with Large Language Models.
- [ x ] Multimodal Joint Training with Meta-Transformer.
- [ x ] Support More Modalities and More Tasks.
Contact
🚀🚀🚀 We aspire to shape this repository into a formidable foundation for mainstream AI perception tasks across diverse modalities. Your contributions can play a significant role in this endeavor, and we warmly welcome your participation in our project!
To contact us, never hestitate to send an email to yiyuanzhang.ai@gmail.com ,kaixionggong@gmail.com, zhangkaipeng@pjlab.org.cn, or xyyue@ie.cuhk.edu.hk!
Citation
If the code and paper help your research, please kindly cite:
@article{zhang2023meta,
  title={Meta-transformer: A unified framework for multimodal learning},
  author={Zhang, Yiyuan and Gong, Kaixiong and Zhang, Kaipeng and Li, Hongsheng and Qiao, Yu and Ouyang, Wanli and Yue, Xiangyu},
  journal={arXiv preprint arXiv:2307.10802},
  year={2023}
}
License
This project is released under the Apache 2.0 license.
Acknowledgement
This code is developed based on excellent open-sourced projects including MMClassification, MMDetection, MMsegmentation, OpenPoints, Time-Series-Library, Graphomer, SpectralFormer, and ViT-Adapter.
Significant stargazers

78 followers · starred Jul 2023

143 followers · starred Oct 2023

17 followers · starred Jul 2023

87 followers · starred Jul 2023
Similar repos




Meta-Transformer for Unified Multimodal Learning
See the codeREADME
Hongsheng Li 1,2 Yu Qiao 2 Wanli Ouyang2 Xiangyu Yue1,†,‡
2 OpenGVLab,Shanghai AI Laboratory
* Equal Contribution † Corresponding Author ‡ Project Lead
Meta-Transformer with Large Language Models ✨✨✨
We're thrilled to present OneLLM, ensembling Meta-Transformer framework with Multimodal Large Language Models, which performs multimodal joint training🚀, supports more modalities including fMRI, Depth and Normal Maps 🚀, and demonstrates very impressive performances on 25 benchmarks🚀🚀🚀.
🔥🔥 The code, pretrained models, and datasets are publicly available at OneLLM.
🔥🔥 Project Website is at OneLLM.
🌟 Single Foundation Model Supports A Wide Range of Applications
As a foundation model, Meta-Transformer can handle data from 12 modalities, which determines that it can support a wide range of applications. As shown in this figure, Meta-Transformer can provide services for downstream tasks including stock analysis 📈, weather forecasting ☀️ ☔ ☁️ ❄️ ⛄ ⚡, remote sensing 📡, autonomous driving 🚗, social network 🌍, speech recognition 🔉, etc.
Table 1: Meta-Transformer is capable of handling up to 12 modalities, including natural language , RGB images , point clouds , audios , videos , tabular data , graph , time series data , hyper-spectral images , IMU , medical images , and infrared images .
🚩🚩🚩 Shared-Encoder, Unpaired Data, More Modalities
This repository is built to explore the potential and extensibility of transformers for multimodal learning. We utilize the advantages of Transformers to deal with length-variant sequences. Then we propose the Data-to-Sequence tokenization following a meta-scheme, then we apply it to 12 modalities including text, image, point cloud, audio, video, infrared, hyper-spectral, X-Ray, tabular, graph, time-series, and Inertial Measurement Unit (IMU) data.
After obtaining the token sequence, we employ a modality-shared encoder to extract representation across different modalities. With task-specific heads, Meta-Transformer can handle various tasks on the different modalities, such as: classification, detection, and segmentation.
🌟 News
- 2023.8.17: Release code to directly get embeddings from multiple modalities. We will further release code on utilizing Meta-Transformer for Human-Centric vision tasks.
- 2023.8.2: 🎉🎉🎉 The implementation of Meta-Transformer for image, point cloud, graph, tabular, time-series, X-Ray, hyper-spectrum, LiDAR data has been released. We also release a very powerful foundation model for Autonomous Driving 🚀🚀🚀.
- 2023.7.22: Pretrained weights and a usage demo for our Meta-Transformer have been released. Comprehensive documentation and implementation of the image modality are underway and will be released soon. Stay tuned for more exciting updates!⌛⌛⌛
- 2023.7.21: Paper is released at arxiv, and code will be gradually released.
- 2023.7.8: Github Repository Initialization.
🔓 Model Zoo
- Demo of Use for Pretrained Encoder
import torch
import torch.nn as nn
from timm.models.vision_transformer import Block
from Data2Seq import Data2Seq
video_tokenier = Data2Seq(modality='video',dim=768)
audio_tokenier = Data2Seq(modality='audio',dim=768)
time_series_tokenier = Data2Seq(modality='time-series',dim=768)

features = torch.concat([video_tokenizer(video), audio_tokenizer(audio), time_series_tokenizer(time_data)],dim=1)
# For base-scale encoder:
ckpt = torch.load("Meta-Transformer_base_patch16_encoder.pth")
encoder = nn.Sequential(*[
            Block(
                dim=768,
                num_heads=12,
                mlp_ratio=4.,
                qkv_bias=True,
                norm_layer=nn.LayerNorm,
                act_layer=nn.GELU
            )
            for i in range(12)])
encoder.load_state_dict(ckpt,strict=True)
# For large-scale encoder:
ckpt = torch.load("Meta-Transformer_large_patch14_encoder.pth")
encoder = nn.Sequential(*[
            Block(
                dim=1024,
                num_heads=16,
                mlp_ratio=4.,
                qkv_bias=True,
                norm_layer=nn.LayerNorm,
                act_layer=nn.GELU
            )
            for i in range(24)])
encoder.load_state_dict(ckpt,strict=True)
encoded_features = encoder(features)
🕙 ToDo
- [ x ] Meta-Transformer with Large Language Models.
- [ x ] Multimodal Joint Training with Meta-Transformer.
- [ x ] Support More Modalities and More Tasks.
Contact
🚀🚀🚀 We aspire to shape this repository into a formidable foundation for mainstream AI perception tasks across diverse modalities. Your contributions can play a significant role in this endeavor, and we warmly welcome your participation in our project!
To contact us, never hestitate to send an email to yiyuanzhang.ai@gmail.com ,kaixionggong@gmail.com, zhangkaipeng@pjlab.org.cn, or xyyue@ie.cuhk.edu.hk!
Citation
If the code and paper help your research, please kindly cite:
@article{zhang2023meta,
  title={Meta-transformer: A unified framework for multimodal learning},
  author={Zhang, Yiyuan and Gong, Kaixiong and Zhang, Kaipeng and Li, Hongsheng and Qiao, Yu and Ouyang, Wanli and Yue, Xiangyu},
  journal={arXiv preprint arXiv:2307.10802},
  year={2023}
}
License
This project is released under the Apache 2.0 license.
Acknowledgement
This code is developed based on excellent open-sourced projects including MMClassification, MMDetection, MMsegmentation, OpenPoints, Time-Series-Library, Graphomer, SpectralFormer, and ViT-Adapter.
Significant stargazers
78 followers · starred Jul 2023
143 followers · starred Oct 2023
17 followers · starred Jul 2023
87 followers · starred Jul 2023