Local voice dictation for macOS on Apple Silicon. Tap a key, speak, and your words are typed into any app — 100% on-device with MLX, nothing leaves your machine.
Python
4
14 commits
updated Sep 10, 2026
Local voice dictation for macOS (Apple Silicon). Tap a key, speak, tap again — your words are typed into whatever window has focus. 100% on-device: audio never leaves your machine.


--language English) with no model reload.--language English.--polish runs a small local LLM that drops
contextual fillers ("you know", "yani"), stutters and false starts, and
fixes punctuation — guarded so it can only edit your words, never
answer them.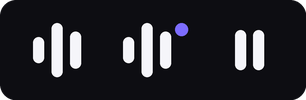 (idle · recording · paused) with start/stop, language
switcher, start-at-login, and a live status block: model download
progress, ready / recording / transcribing, and permission problems with
a one-click fix.
parlando --install-app creates Parlando.app
 so macOS asks for permissions in Parlando's name (not your terminal's) and
keeps them across upgrades.
uv installedparlando is on PyPI. With
uv (recommended):
uv tool install parlando     # puts the parlando command on your PATH
parlando --install-app       # creates ~/Applications/Parlando.app (see Permissions)
or try it without installing anything permanent:
uvx parlando
or with pipx / pip:
pipx install parlando        # isolated install, commands on PATH
pip install parlando         # into your current Python environment
# one-liner that also installs uv if you don't have it
curl -fsSL https://raw.githubusercontent.com/furkanc/parlando/main/install.sh | sh

# from source
git clone https://github.com/furkanc/parlando && cd parlando
uv run parlando              # run without installing
uv tool install .            # install commands from the checkout

# uninstall
uv tool uninstall parlando   # (or: pipx uninstall parlando / pip uninstall parlando)
parlando                 # menu bar app: icon top right, settings in its menu
parlando --terminal      # ...or dictate from this terminal window
After parlando --install-app, open Parlando from Spotlight or
~/Applications like any other app; permissions are then asked in
Parlando's name instead of your terminal's, and stay granted across
uv tool upgrade parlando.
macOS asks for two permissions and grants them to the responsible app:
Parlando when you use Parlando.app, otherwise the terminal you run
parlando from (Terminal, iTerm, VS Code, ...). This is why the app bundle is
recommended: the permission is asked once, in Parlando's name, and keeps
working whichever terminal you use.
| Permission | Why | Where |
|---|---|---|
| Microphone | hear you | Settings → Privacy & Security → Microphone |
| Accessibility | global hotkey and typing keystrokes | Settings → Privacy & Security → Accessibility |
parlando triggers the system prompts itself, detects missing permissions and
says so explicitly (in the terminal, or in a dialog from the menu bar app)
instead of failing silently. Without Accessibility the hotkey is not heard at
all. Once you grant it, parlando notices within a few seconds and enables
the hotkey by itself. macOS sometimes quits the app the moment the switch
is flipped; Parlando.app reopens itself in that case. This is a one-time
step: the launcher bundle does not change on upgrades, so macOS keeps the
permission.
Parlando.app is a thin launcher (Info.plist, icon, a Mach-O stub and a
script that runs the installed package) generated on your Mac and ad-hoc
signed, so nothing is downloaded and no developer certificate is needed.
Its contents do not change on upgrades, so macOS keeps the permissions.
Re-run --install-app only after moving the Python environment that owns
the package (that resets the permissions once).
parlando                      # menu bar app (default)
parlando --install-app        # create ~/Applications/Parlando.app (recommended)
parlando --uninstall-app      # remove it (and the login item)
parlando --install-login      # start the menu bar app at login
parlando --terminal           # dictate from the terminal; the options below need it
parlando -t --language English   # dictate in another language
parlando -t --polish             # LLM cleanup (fillers, false starts, punctuation)
parlando -t --enter              # press Enter after each utterance
parlando -t --mode stream        # live word-by-word streaming
parlando --pipe                  # print to stdout (scriptable; implies --terminal)
parlando -t --hotkey cmd_r       # tap right Command instead
parlando --list-devices          # list microphones
| Say (English) | Say (Turkish) | Result |
|---|---|---|
| period / comma | nokta / virgül | . , appended to previous word |
| question mark | soru işareti | ? appended |
| new line / new paragraph | yeni satır / yeni paragraf | line break |
| send | gönder | presses Enter |
Disable with --no-commands.
ASR models spell unknown technical terms phonetically ("MLX" can come out
as "Meleiks"). Give parlando your vocabulary and it biases recognition
toward the exact spellings — injected into the ASR context and honored by
--polish too.
Easiest way: menu bar → Vocabulary → Add Term… (active for the very next dictation) or Edit Vocabulary File… for bulk edits. Changes are picked up automatically — no restart. The same file by hand:
mkdir -p ~/.config/parlando
printf "MLX\nPyPI\nClaude Code\n" >> ~/.config/parlando/vocabulary.txt
(one term per line, # comments allowed), or ad hoc:
parlando -t --vocab "MLX, PyPI"
Speech recognition (--model, MLX Qwen3-ASR — 30 languages):
| Model | Size | Notes |
|---|---|---|
mlx-community/Qwen3-ASR-1.7B-8bit | ~2 GB | default — best accuracy, recommended |
mlx-community/Qwen3-ASR-0.6B-8bit | ~700 MB | good balance for low-RAM machines |
mlx-community/Qwen3-ASR-0.6B-4bit | ~400 MB | fastest, lowest accuracy |
mlx-community/Qwen3-ASR-0.6B-bf16 | ~1.3 GB | higher fidelity 0.6B, more RAM |
Polish LLM (--polish-model, used only with --polish; scores from
scripts/eval_polish.py, an 11-case cleanup benchmark):
| Model | Size | Eval | Latency | Notes |
|---|---|---|---|---|
mlx-community/Qwen3-1.7B-4bit | ~1 GB | 10/11 | ~0.4 s | default — fast, safe |
mlx-community/Qwen3-4B-4bit | ~2.3 GB | 11/11 | ~0.9 s | best quality; use on 16 GB+ Macs |
mlx-community/Qwen3-0.6B-4bit | ~350 MB | — | ~0.2 s | minimal RAM, weakest cleanup |
parlando -t --polish --polish-model mlx-community/Qwen3-4B-4bit
All models download once from Hugging Face and are cached in
~/.cache/huggingface; everything runs on-device.
record (default) — tap, speak freely (pauses are fine), tap again; the
whole recording is transcribed once and typed in one go. Recordings longer
than 28 s are split at natural silence points (2 min cap). This mode has no
VAD guessing, so it is the most robust.
stream — always listening; an energy VAD (hysteresis, adaptive noise
floor, optional --silero hybrid) segments utterances and words appear as
you speak. More "live", more sensitive to room noise.
| Symptom | Fix |
|---|---|
| "Microphone is silent" | Allow Parlando (or your terminal) under Microphone; parlando reopens the mic by itself |
| Hotkey does nothing / nothing typed | Grant Accessibility to Parlando (or your terminal); parlando enables the hotkey within seconds, no restart |
| Stalls after sleep | The watchdog reopens the stream within ~5 s automatically |
| Ghost text while silent (stream mode) | --energy-floor 0.008 or --silero |
| Missing soft speech (stream mode) | --energy-floor 0.002 |
| Wrong words | Move closer to the mic; prefer the built-in mic over AirPods (Bluetooth input drops to a low-quality codec) |
| Detailed trace | ~/Library/Logs/parlando.log |
Note: --device indices shift when devices connect/disconnect, and virtual
devices ("Microsoft Teams Audio", "ZoomAudioDevice") are not microphones.
Prefer the default device.
microphone ── 30 ms frames ──▶ hotkey-gated recorder (record mode)
                              or energy VAD w/ hysteresis + adaptive floor,
                              optional Silero hybrid, 300 ms pre-roll (stream)
                │ segment boundaries
                ▼
        segment audio only ──▶ Qwen3-ASR (MLX, on-device GPU)
                │ readings
                ▼
        LocalAgreement-2 ──▶ append-only word commits ──▶ CGEvent unicode
        (commit on 2-reading    (typed text is never        keyboard events
         agreement)              retracted)
Key decisions (each one earned by a real failure during development):
uvx --with numpy pytest tests -q   # unit tests; no model/mic needed
uv run scripts/eval_polish.py      # polish quality benchmark (real local LLM)
uv run scripts/make_icons.py       # regenerate icons, banner, Parlando.icns
scripts/build_launcher.sh          # rebuild the Parlando.app Mach-O stub
scripts/build_app.sh               # experimental: self-contained Parlando.app + .dmg
scripts/make_signing_cert.sh       # experimental: stable signing identity for that build
uv build                           # build the wheel/sdist
Package layout: src/parlando/ (engine, menubar, ASR engine, assets incl.
the prebuilt app launcher). Entry point parlando (menu bar app by default,
--terminal for the CLI); parlando-menubar is kept as an alias. CI runs
the test suite and a packaging build on macOS via GitHub Actions.
scripts/build_app.sh produces a self-contained Parlando.app + .dmg
(embedded Python and dependencies, ~250 MB; the speech model still
downloads on first run). It is not the supported distribution yet: a
downloaded app needs Developer ID signing and notarization to open without
a Gatekeeper detour, and a stable signing identity so permissions survive
updates (make_signing_cert.sh provides a self-signed one for local
experiments). Until then, install with uv.
install.sh) with parlando launcher commanduv tool install, entry points)uvx parlando works)brew install parlando)--vocab, vocabulary.txt)MIT. The Qwen3-ASR MLX engine (stt.py) is from
dictate.sh by Marc Puig (MIT), with
local modifications (partial streaming, energy gating, error hardening).
Turn-taking research: Whisper-Streaming /
LocalAgreement-2. VAD:
Silero VAD.
Local voice dictation for macOS on Apple Silicon. Tap a key, speak, and your words are typed into any app — 100% on-device with MLX, nothing leaves your machine.
Python
4
14 commits
updated Sep 10, 2026
Local voice dictation for macOS (Apple Silicon). Tap a key, speak, tap again — your words are typed into whatever window has focus. 100% on-device: audio never leaves your machine.
--language English) with no model reload.--language English.--polish runs a small local LLM that drops
contextual fillers ("you know", "yani"), stutters and false starts, and
fixes punctuation — guarded so it can only edit your words, never
answer them. (idle · recording · paused) with start/stop, language
switcher, start-at-login, and a live status block: model download
progress, ready / recording / transcribing, and permission problems with
a one-click fix.parlando --install-app creates Parlando.app
so macOS asks for permissions in Parlando's name (not your terminal's) and
keeps them across upgrades.uv installedparlando is on PyPI. With
uv (recommended):
uv tool install parlando     # puts the parlando command on your PATH
parlando --install-app       # creates ~/Applications/Parlando.app (see Permissions)
or try it without installing anything permanent:
uvx parlando
or with pipx / pip:
pipx install parlando        # isolated install, commands on PATH
pip install parlando         # into your current Python environment
# one-liner that also installs uv if you don't have it
curl -fsSL https://raw.githubusercontent.com/furkanc/parlando/main/install.sh | sh

# from source
git clone https://github.com/furkanc/parlando && cd parlando
uv run parlando              # run without installing
uv tool install .            # install commands from the checkout

# uninstall
uv tool uninstall parlando   # (or: pipx uninstall parlando / pip uninstall parlando)
parlando                 # menu bar app: icon top right, settings in its menu
parlando --terminal      # ...or dictate from this terminal window
After parlando --install-app, open Parlando from Spotlight or
~/Applications like any other app; permissions are then asked in
Parlando's name instead of your terminal's, and stay granted across
uv tool upgrade parlando.
macOS asks for two permissions and grants them to the responsible app:
Parlando when you use Parlando.app, otherwise the terminal you run
parlando from (Terminal, iTerm, VS Code, ...). This is why the app bundle is
recommended: the permission is asked once, in Parlando's name, and keeps
working whichever terminal you use.
| Permission | Why | Where |
|---|---|---|
| Microphone | hear you | Settings → Privacy & Security → Microphone |
| Accessibility | global hotkey and typing keystrokes | Settings → Privacy & Security → Accessibility |
parlando triggers the system prompts itself, detects missing permissions and
says so explicitly (in the terminal, or in a dialog from the menu bar app)
instead of failing silently. Without Accessibility the hotkey is not heard at
all. Once you grant it, parlando notices within a few seconds and enables
the hotkey by itself. macOS sometimes quits the app the moment the switch
is flipped; Parlando.app reopens itself in that case. This is a one-time
step: the launcher bundle does not change on upgrades, so macOS keeps the
permission.
Parlando.app is a thin launcher (Info.plist, icon, a Mach-O stub and a
script that runs the installed package) generated on your Mac and ad-hoc
signed, so nothing is downloaded and no developer certificate is needed.
Its contents do not change on upgrades, so macOS keeps the permissions.
Re-run --install-app only after moving the Python environment that owns
the package (that resets the permissions once).
parlando                      # menu bar app (default)
parlando --install-app        # create ~/Applications/Parlando.app (recommended)
parlando --uninstall-app      # remove it (and the login item)
parlando --install-login      # start the menu bar app at login
parlando --terminal           # dictate from the terminal; the options below need it
parlando -t --language English   # dictate in another language
parlando -t --polish             # LLM cleanup (fillers, false starts, punctuation)
parlando -t --enter              # press Enter after each utterance
parlando -t --mode stream        # live word-by-word streaming
parlando --pipe                  # print to stdout (scriptable; implies --terminal)
parlando -t --hotkey cmd_r       # tap right Command instead
parlando --list-devices          # list microphones
| Say (English) | Say (Turkish) | Result |
|---|---|---|
| period / comma | nokta / virgül | . , appended to previous word |
| question mark | soru işareti | ? appended |
| new line / new paragraph | yeni satır / yeni paragraf | line break |
| send | gönder | presses Enter |
Disable with --no-commands.
ASR models spell unknown technical terms phonetically ("MLX" can come out
as "Meleiks"). Give parlando your vocabulary and it biases recognition
toward the exact spellings — injected into the ASR context and honored by
--polish too.
Easiest way: menu bar → Vocabulary → Add Term… (active for the very next dictation) or Edit Vocabulary File… for bulk edits. Changes are picked up automatically — no restart. The same file by hand:
mkdir -p ~/.config/parlando
printf "MLX\nPyPI\nClaude Code\n" >> ~/.config/parlando/vocabulary.txt
(one term per line, # comments allowed), or ad hoc:
parlando -t --vocab "MLX, PyPI"
Speech recognition (--model, MLX Qwen3-ASR — 30 languages):
| Model | Size | Notes |
|---|---|---|
mlx-community/Qwen3-ASR-1.7B-8bit | ~2 GB | default — best accuracy, recommended |
mlx-community/Qwen3-ASR-0.6B-8bit | ~700 MB | good balance for low-RAM machines |
mlx-community/Qwen3-ASR-0.6B-4bit | ~400 MB | fastest, lowest accuracy |
mlx-community/Qwen3-ASR-0.6B-bf16 | ~1.3 GB | higher fidelity 0.6B, more RAM |
Polish LLM (--polish-model, used only with --polish; scores from
scripts/eval_polish.py, an 11-case cleanup benchmark):
| Model | Size | Eval | Latency | Notes |
|---|---|---|---|---|
mlx-community/Qwen3-1.7B-4bit | ~1 GB | 10/11 | ~0.4 s | default — fast, safe |
mlx-community/Qwen3-4B-4bit | ~2.3 GB | 11/11 | ~0.9 s | best quality; use on 16 GB+ Macs |
mlx-community/Qwen3-0.6B-4bit | ~350 MB | — | ~0.2 s | minimal RAM, weakest cleanup |
parlando -t --polish --polish-model mlx-community/Qwen3-4B-4bit
All models download once from Hugging Face and are cached in
~/.cache/huggingface; everything runs on-device.
record (default) — tap, speak freely (pauses are fine), tap again; the
whole recording is transcribed once and typed in one go. Recordings longer
than 28 s are split at natural silence points (2 min cap). This mode has no
VAD guessing, so it is the most robust.
stream — always listening; an energy VAD (hysteresis, adaptive noise
floor, optional --silero hybrid) segments utterances and words appear as
you speak. More "live", more sensitive to room noise.
| Symptom | Fix |
|---|---|
| "Microphone is silent" | Allow Parlando (or your terminal) under Microphone; parlando reopens the mic by itself |
| Hotkey does nothing / nothing typed | Grant Accessibility to Parlando (or your terminal); parlando enables the hotkey within seconds, no restart |
| Stalls after sleep | The watchdog reopens the stream within ~5 s automatically |
| Ghost text while silent (stream mode) | --energy-floor 0.008 or --silero |
| Missing soft speech (stream mode) | --energy-floor 0.002 |
| Wrong words | Move closer to the mic; prefer the built-in mic over AirPods (Bluetooth input drops to a low-quality codec) |
| Detailed trace | ~/Library/Logs/parlando.log |
Note: --device indices shift when devices connect/disconnect, and virtual
devices ("Microsoft Teams Audio", "ZoomAudioDevice") are not microphones.
Prefer the default device.
microphone ── 30 ms frames ──▶ hotkey-gated recorder (record mode)
                              or energy VAD w/ hysteresis + adaptive floor,
                              optional Silero hybrid, 300 ms pre-roll (stream)
                │ segment boundaries
                ▼
        segment audio only ──▶ Qwen3-ASR (MLX, on-device GPU)
                │ readings
                ▼
        LocalAgreement-2 ──▶ append-only word commits ──▶ CGEvent unicode
        (commit on 2-reading    (typed text is never        keyboard events
         agreement)              retracted)
Key decisions (each one earned by a real failure during development):
uvx --with numpy pytest tests -q   # unit tests; no model/mic needed
uv run scripts/eval_polish.py      # polish quality benchmark (real local LLM)
uv run scripts/make_icons.py       # regenerate icons, banner, Parlando.icns
scripts/build_launcher.sh          # rebuild the Parlando.app Mach-O stub
scripts/build_app.sh               # experimental: self-contained Parlando.app + .dmg
scripts/make_signing_cert.sh       # experimental: stable signing identity for that build
uv build                           # build the wheel/sdist
Package layout: src/parlando/ (engine, menubar, ASR engine, assets incl.
the prebuilt app launcher). Entry point parlando (menu bar app by default,
--terminal for the CLI); parlando-menubar is kept as an alias. CI runs
the test suite and a packaging build on macOS via GitHub Actions.
scripts/build_app.sh produces a self-contained Parlando.app + .dmg
(embedded Python and dependencies, ~250 MB; the speech model still
downloads on first run). It is not the supported distribution yet: a
downloaded app needs Developer ID signing and notarization to open without
a Gatekeeper detour, and a stable signing identity so permissions survive
updates (make_signing_cert.sh provides a self-signed one for local
experiments). Until then, install with uv.
install.sh) with parlando launcher commanduv tool install, entry points)uvx parlando works)brew install parlando)--vocab, vocabulary.txt)MIT. The Qwen3-ASR MLX engine (stt.py) is from
dictate.sh by Marc Puig (MIT), with
local modifications (partial streaming, energy gating, error hardening).
Turn-taking research: Whisper-Streaming /
LocalAgreement-2. VAD:
Silero VAD.



