cs-holder/Reasoning-Self-Evolution-Survey

54

6 commits

updated Mar 6, 2025

See the code

README

A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution

Tao He1∗, Hao Li1∗, Jingchang Chen1, Runxuan Liu1, Yixin Cao2, Lizi Liao3, Zihao Zheng1, Zheng Chu1, Jiafeng Liang1, Ming Liu1†, Bing Qin1,
1Harbin Institute of Technology, Harbin, China
2Fudan University, Shanghai, China
2Singpore Management University, Singapore

This repository contains the resources for survey paper A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution

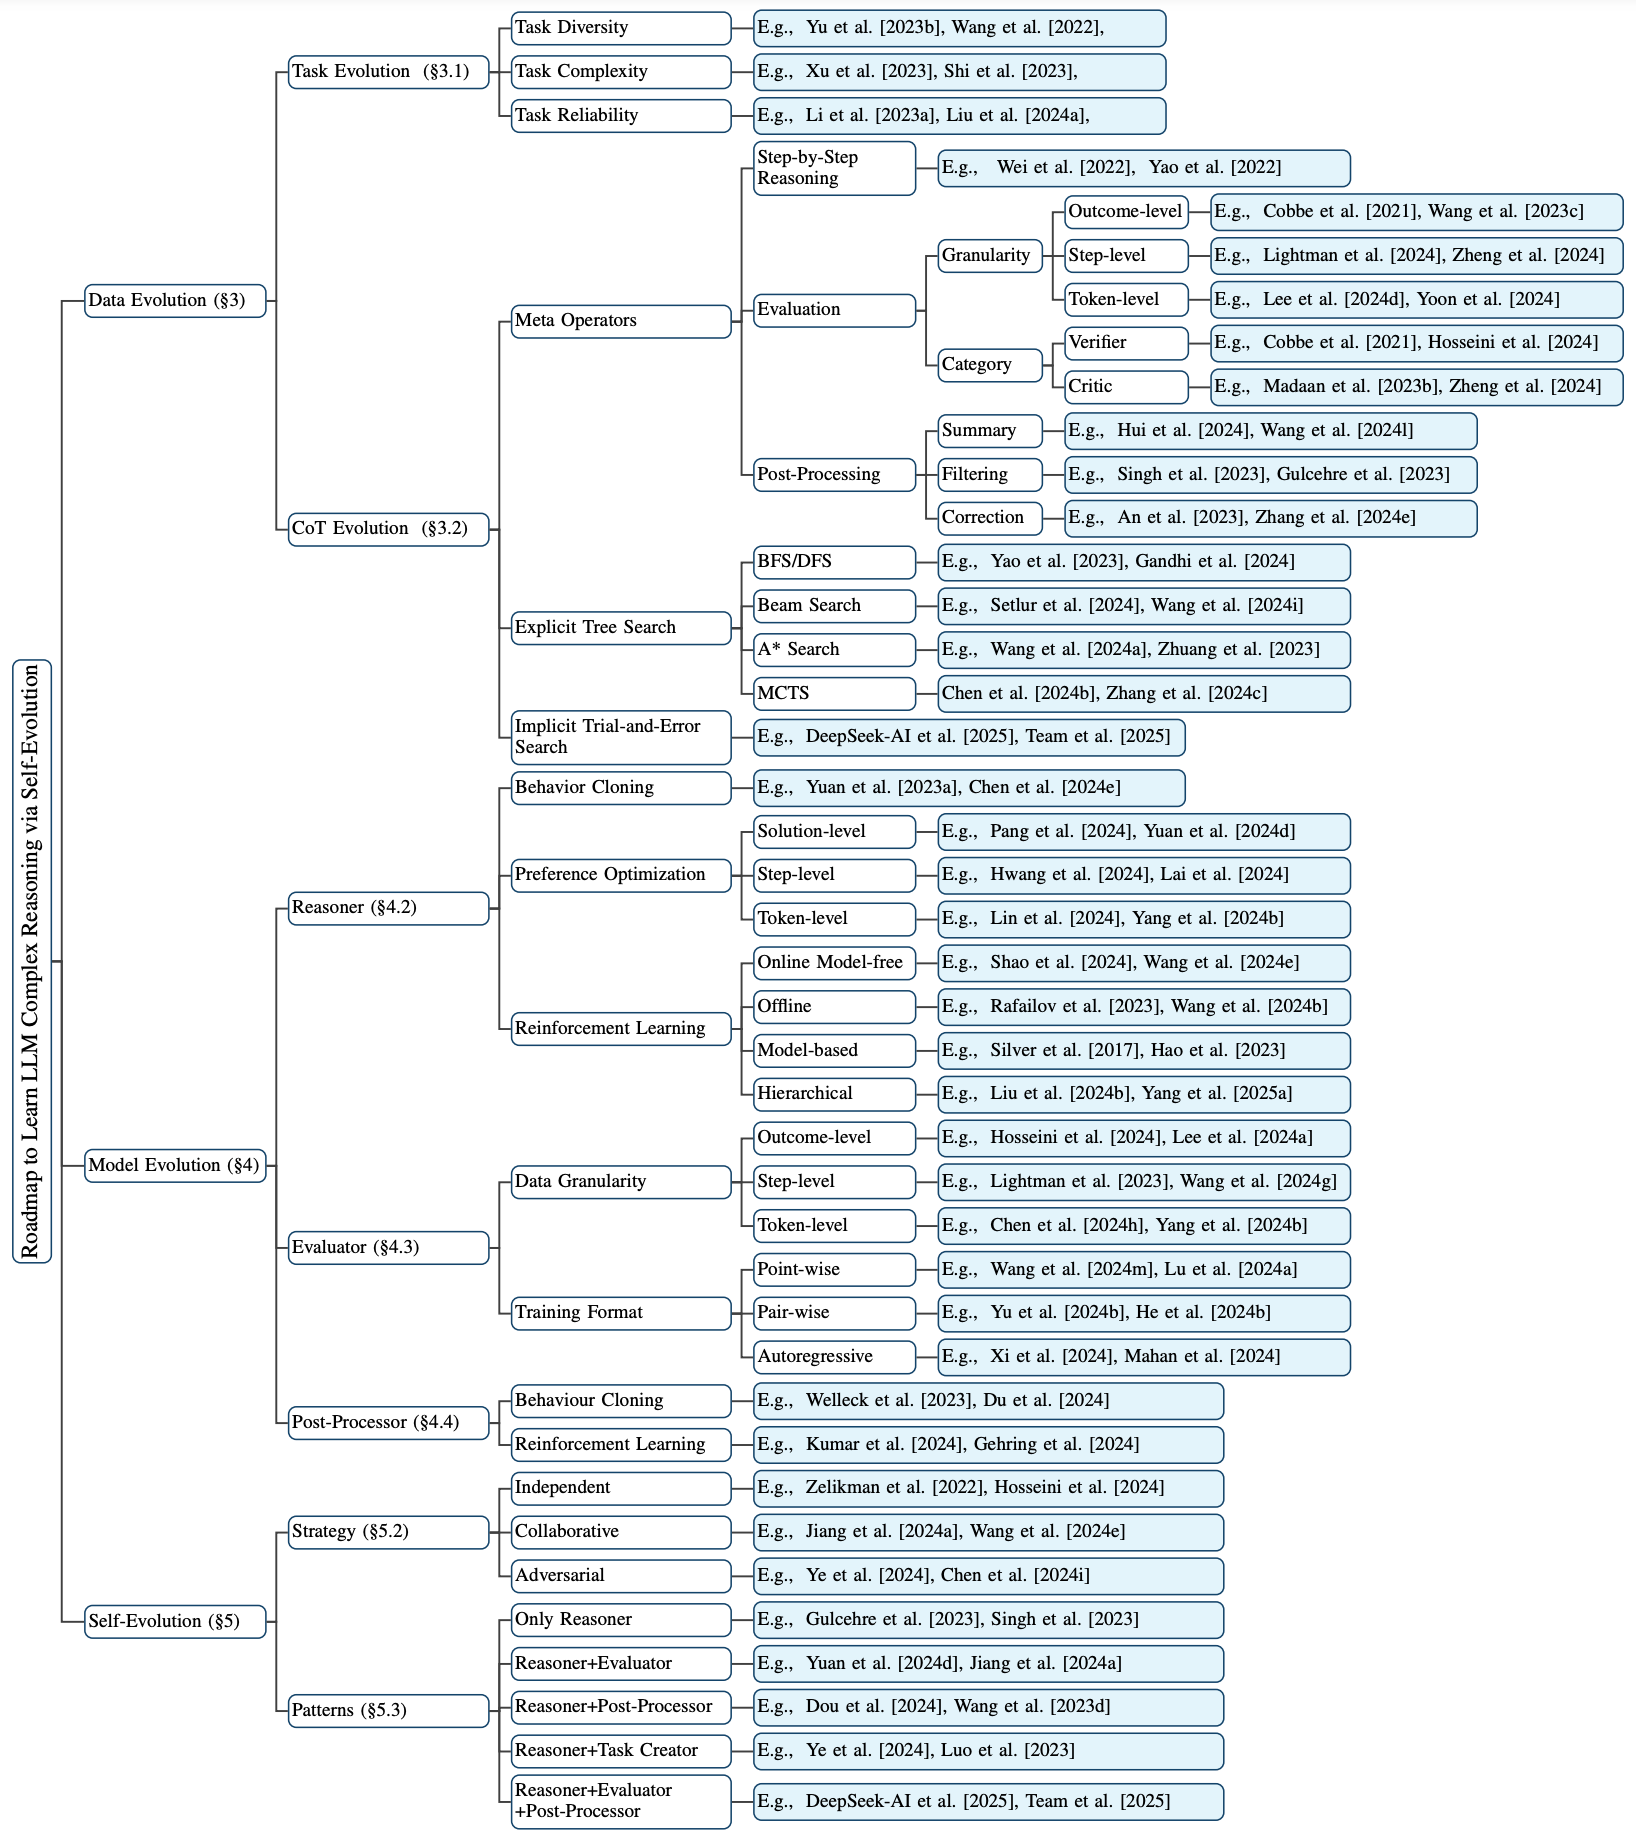
Self-Evolution Framework

taxonomy

For more details, please refer to the paper: A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution.

🎉 Updates

  • 2025/02/26 We updated the paper by replacing the terminology for the two search methods, adding a table to summarize the comparison between the two search approaches, and refining the content of theory in self-evolution.
  • 2025/02/24 We created this reading list repository.

We use the 💡 icon to identify articles that have been added since the last version of the paper.

This reading list will be updated periodically, and if you have any suggestions or find some we missed, feel free to contact us! You can submit an issue or send an email ([email protected] or [email protected]).

🎁 Resources

Surveys

  • Navigate through Enigmatic Labyrinth A Survey of Chain of Thought Reasoning: Advances, Frontiers and Future, ACL 2024 [paper]
  • A Survey on Self-Evolution of Large Language Models, arxiv.2404.14387 [paper]
  • A Survey on Data Synthesis and Augmentation for Large Language Models, arxiv.2410.12896 [paper]
  • Reinforcement learning enhanced LLMs: A survey, arxiv.2412.10400 [paper]
  • Automatically Correcting Large Language Models: Surveying the Landscape ofDiverse Automated Correction Strategies, TACL [paper]
  • When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs, TACL [paper]

Projects

  • HqWu-HITCS/Awesome-LLM-Survey, [project]
  • AGI-Edgerunners/LLM-Planning-Papers [project]
  • modelscope/awesome-deep-reasoning [project]
  • wasiahmad/Awesome-LLM-Synthetic-Data [project]
  • CSHaitao/Awesome-LLMs-as-Judges [project]

🚀 Data Evolution
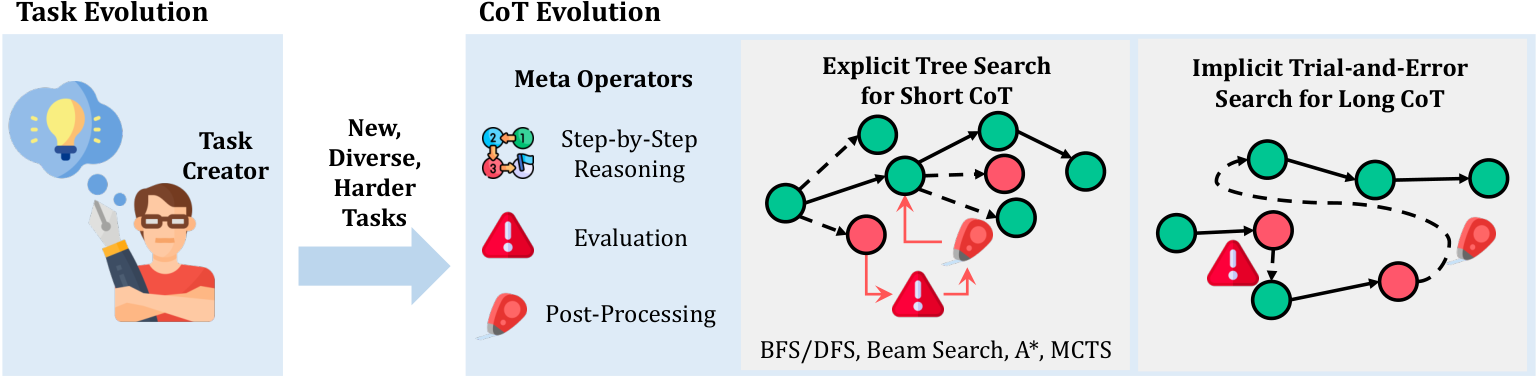
data evolution

Task Evolution

  • Common 7B Language Models Already Possess Strong Math Capabilities, arXiv.2403.04706 [paper]
  • Language Models Can Teach Themselves to Program Better, ICLR 2023 [paper]
  • Learning Performance-Improving Code Edits, ICLR 2024 [paper]
  • MetaMath: Bootstrap Your Own Mathematical Questions for Large Language Models, ICLR 2024 [paper]
  • TinyGSM: achieving >80% on GSM8k with small language models, arxiv.2312.09241 [paper]
  • WizardLM: Empowering Large Language Models to Follow Complex Instructions, ICLR 2024 [paper]
  • Self-Instruct: Aligning Language Models with Self-Generated Instructions, ACL 2023 [paper]
  • Large Language Models Can Be Easily Distracted by Irrelevant Context, ICML 2023 [paper]
  • Orca-Math: Unlocking the potential of SLMs in Grade School Math, arxiv.2402.14830 [paper]
  • Self-Alignment with Instruction Backtranslation, ICLR 2024 [paper]
  • Augmenting Math Word Problems via Iterative Question Composing, arXiv.2401.09003 [paper]
  • Generating Symbolic Reasoning Problems with Transformer GANs,arxiv.2110.10054 [paper]
  • Magicoder: Empowering Code Generation with OSS-Instruct, ICML 2024 [paper]
  • MathGenie: Generating Synthetic Data with Question Back-translation for Enhancing Mathematical Reasoning of LLMs, ACL 2024 [paper]

CoT Evolution

Step-by-Step Reasoning

  • Chain-of-Thought Prompting Elicits Reasoning in Large Language Models, NeurIPS 2022 [paper]
  • Plan-and-Solve Prompting: Improving Zero-Shot Chain-of-Thought Reasoning by Large Language Models, ACL 2023 [paper]
  • Least-to-Most Prompting Enables Complex Reasoning in Large Language Models, ICLR 2023 [paper]
  • Successive Prompting for Decomposing Complex Questions, EMNLP 2022 [paper]
  • ReAct: Synergizing Reasoning and Acting in Language Models, ICLR 2023 [paper]

Evaluation

  • Training Verifiers to Solve Math Word Problems, arxiv.2110.14168 [paper]
  • Self-Consistency Improves Chain of Thought Reasoning in Language Models, ICLR 2023 [paper]
  • RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback, ICML 2024 [paper]
  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]
  • Self-Refine: Iterative Refinement with Self-Feedback, NeurIPS 2023 [paper]
  • SciInstruct: a Self-Reflective Instruction Annotated Dataset for Training Scientific Language Models, arxiv.2401.07950 [paper]
  • Check Your Facts and Try Again: Improving Large Language Models with External Knowledge and Automated Feedback, arXiv.2302.12813 [paper]
  • Reflexion: language agents with verbal reinforcement learning, NeurIPS 2023 [paper]
  • CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing, ICLR 2024 [paper]
  • Critique-out-Loud Reward Models, arXiv.2408.11791 [paper]
  • Self-Generated Critiques Boost Reward Modeling for Language Models, arxiv.2411.16646 [paper]
  • Forward-Backward Reasoning in Large Language Models for Mathematical Verification, ACL 2024 [paper]
  • Large Language Models are Better Reasoners with Self-Verification, EMNLP 2023 [paper]
  • Let's Verify Step by Step, ICLR 2024 [paper]
  • Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations, ACL 2024 [paper]
  • Multi-step Problem Solving Through a Verifier: An Empirical Analysis on Model-induced Process Supervision, EMNLP 2024 [paper]
  • LLM Critics Help Catch Bugs in Mathematics: Towards a Better Mathematical Verifier with Natural Language Feedback, arXiv.2406.14024 [paper]
  • AutoPSV: Automated Process-Supervised Verifier, NeurIPS 2024 [paper]
  • Making Language Models Better Reasoners with Step-Aware Verifier, ACL 2023 [paper]
  • Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing, NeurIPS 2024 [paper]
  • Self-Evaluation Guided Beam Search for Reasoning, NeurIPS 2023 [paper]
  • Critic-CoT: Boosting the reasoning abilities of large language model via Chain-of-thoughts Critic, arXiv.2408.16326 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • TLCR: Token-Level Continuous Reward for Fine-grained Reinforcement Learning from Human Feedback, ACL 2024 [paper]
  • Improving Large Language Models via Fine-grained Reinforcement Learning with Minimum Editing Constraint, ACL 2024 [paper]
  • Token-Supervised Value Models for Enhancing Mathematical Reasoning Capabilities of Large Language Models, ICLR 2025 [paper]
  • Selective Preference Optimization via Token-Level Reward Function Estimation, arxiv.2408.13518 [paper]
  • MCTS-Judge: Test-Time Scaling in LLM-as-a-Judge for Code Correctness Evaluation, arxiv.2502.12468 [paper]
  • Reward Hacking in Reinforcement Learning, [blog]
  • On Designing Effective RL Reward at Training Time for LLM Reasoning, arxiv.2410.15115 [paper]
  • Process Reinforcement through Implicit Rewards, arxiv.2502.01456 [paper]

Post-Processing (Correction/Filtering/Summarization/...)

  • Learn Beyond The Answer: Training Language Models with Reflection for Mathematical Reasoning, EMNLP 2024 [paper]
  • Meta-Reflection: A Feedback-Free Reflection Learning Framework, arXiv.2412.13781 [paper]
  • RoT: Enhancing Large Language Models with Reflection on Search Trees, arXiv.2404.05449 [paper]
  • PRACT: Optimizing Principled Reasoning and Acting of LLM Agent, arXiv.2410.18528 [paper]
  • CoT-based Synthesizer: Enhancing LLM Performance through Answer Synthesis, arXiv.2501.01668 [paper]
  • Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models, TMLR 2024 [paper]
  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]
  • Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems, arxiv.2412.09413 [paper]
  • Self-Consistency Improves Chain of Thought Reasoning in Language Models, ICLR 2023 [paper]
  • Universal Self-Consistency for Large Language Model Generation, arXiv.2311.17311 [paper]
  • Forward-Backward Reasoning in Large Language Models for Mathematical Verification, ACL 2024 [paper]
  • Large Language Models are Better Reasoners with Self-Verification, EMNLP 2023 [paper]
  • Perplexed by Perplexity: Perplexity-Based Data Pruning With Small Reference Models, arxiv.2405.20541 [paper]
  • Self-Training Meets Consistency: Improving LLMs' Reasoning With Consistency-Driven Rationale Evaluation, arXiv.2411.06387 [paper]
  • Training Verifiers to Solve Math Word Problems, arxiv.2110.14168 [paper]
  • OVM, Outcome-supervised Value Models for Planning in Mathematical Reasoning, NAACL 2024 [paper]
  • Learning to summarize with human feedback, NeurIPS 2020 [paper]
  • Self-Refine: Iterative Refinement with Self-Feedback, NeurIPS 2023 [paper]
  • Self-Contrast: Better Reflection Through Inconsistent Solving Perspectives, ACL 2024 [paper]
  • LLM Self-Correction with DeCRIM: Decompose, Critique, and Refine for Enhanced Following of Instructions with Multiple Constraints, EMNLP 2024 [paper]
  • Large Language Models Can Self-Correct with Key Condition Verification, EMNLP 2024 [paper]
  • CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing, ICLR 2024 [paper]
  • DotaMath: Decomposition of Thought with Code Assistance and Self-correction for Mathematical Reasoning, arXiv.2407.04078 [paper]
  • Embedding Self-Correction as an Inherent Ability in Large Language Models for Enhanced Mathematical Reasoning, arXiv.2410.10735 [paper]
  • Teaching Large Language Models to Self-Debug, ICLR 2024 [paper]
  • Advancing LLM Reasoning Generalists with Preference Trees, arXiv.2404.02078 [paper]
  • Self-Refinement of Language Models from External Proxy Metrics Feedback, arXiv.2403.00827 [paper]
  • Enhancing Mathematical Reasoning in LLMs by Stepwise Correction, arXiv.2410.12934 [paper]
  • The ART of LLM Refinement: Ask, Refine, and Trust, NAACL 2024 [paper]
  • Critic-CoT: Boosting the reasoning abilities of large language model via Chain-of-thoughts Critic, arXiv.2408.16326 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • S3c-Math: Spontaneous Step-level Self-correction Makes Large Language Models Better Mathematical Reasoners, arXiv.2409.01524 [paper]
  • Small Language Models Need Strong Verifiers to Self-Correct Reasoning, ACL 2024 [paper]
  • LLaMA-Berry: Pairwise Optimization for O1-like Olympiad-Level Mathematical Reasoning, arXiv.2410.02884 [paper]
  • Accessing GPT-4 level Mathematical Olympiad Solutions via Monte Carlo Tree Self-refine with LLaMa-3 8B, arXiv.2406.07394 [paper]
  • O1 Replication Journey: A Strategic Progress Report - Part 1, arxiv.2410.18982 [paper]
  • Step Back to Leap Forward: Self-Backtracking for Boosting Reasoning of Language Models, arxiv.2502.04404 [paper]
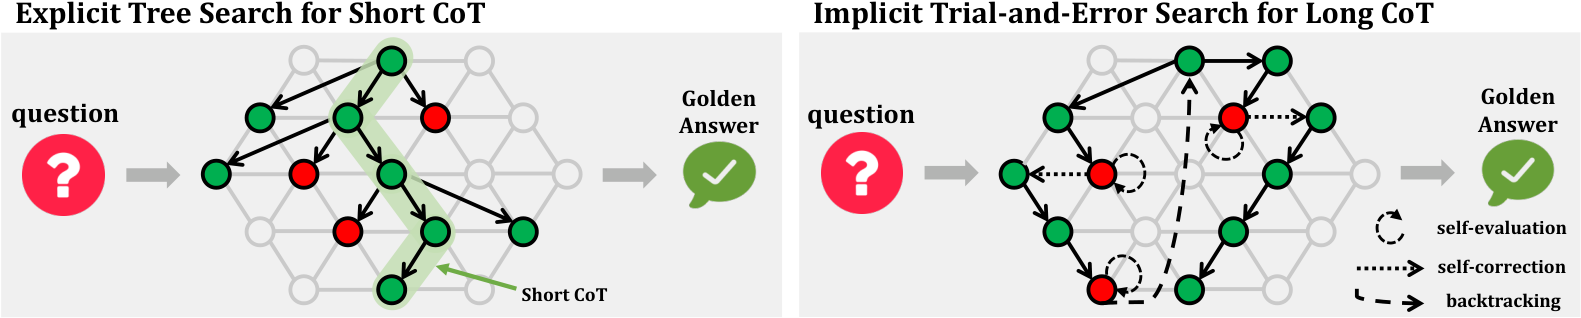
search difference

Explicit Tree Search For Short CoT

  • Tree of Thoughts: Deliberate Problem Solving with Large Language Models, NeurIPS 2023 [paper]
  • ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs, ICLR 2024 [paper]
  • Autonomous Tree-search Ability of Large Language Models, arxiv.2310.10686 [paper]
  • Algorithm of Thoughts: Enhancing Exploration of Ideas in Large Language Models, ICML 2024 [paper]
  • Token-Supervised Value Models for Enhancing Mathematical Reasoning Capabilities of Large Language Models, ICLR 2025 [paper]
  • Diverse Beam Search: Decoding Diverse Solutions from Neural Sequence Models, arxiv.1610.02424 [paper]
  • BPP-Search: Enhancing Tree of Thought Reasoning for Mathematical Modeling Problem Solving, arxiv.2411.17404 [paper]
  • AlphaMath Almost Zero: process Supervision without process, NeurIPS 2024 [paper]
  • OVM, Outcome-supervised Value Models for Planning in Mathematical Reasoning, NAACL 2024 [paper]
  • Rewarding Progress: Scaling Automated Process Verifiers for LLM Reasoning, arxiv.2410.08146 [paper]
  • Self-Evaluation Guided Beam Search for Reasoning, NeurIPS 2023 [paper]
  • Chain-of-Thought Reasoning Without Prompting, NeurIPS 2024 [paper]
  • ToolChain*: Efficient Action Space Navigation in Large Language Models with A* Search, ICLR 2024 [paper]
  • Q*: Improving Multi-step Reasoning for LLMs with Deliberative Planning, arxiv.2406.14283 [paper]
  • LLM-A*: Large Language Model Enhanced Incremental Heuristic Search on Path Planning, EMNLP 2024 [paper]
  • A Training Data Recipe to Accelerate A* Search with Language Models, EMNLP 2024 [paper]
  • Beyond A*: Better Planning with Transformers via Search Dynamics Bootstrapping, arxiv.2402.14083 [paper]
  • Dualformer: Controllable Fast and Slow Thinking by Learning with Randomized Reasoning Traces, arxiv.2410.09918 [paper]
  • Mastering the game of Go without human knowledge, Nature 2017 [paper]
  • Multi-armed bandits with episode context, Ann. Math. Artif. Intell. 2011 [paper]
  • Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning, arxiv.2405.00451 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions, arxiv.2411.14405 [paper]
  • Enhancing LLM Reasoning with Reward-guided Tree Search, arxiv.2411.11694 [paper]
  • Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing, NeurIPS 2024 [paper]
  • Reasoning with Language Model is Planning with World Model, EMNLP 2023 [paper]
  • Solving Math Word Problems via Cooperative Reasoning induced Language Models, ACL 2023 [paper]
  • Self-Consistency Improves Chain of Thought Reasoning in Language Models, ICLR 2023 [paper]
  • Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models, ICML 2024 [paper]
  • Alphazero-like Tree-Search can Guide Large Language Model Decoding and Training, ICML 2024 [paper]
  • Mutual Reasoning Makes Smaller LLMs Stronger Problem-Solvers, arxiv.2408.06195 [paper]
  • DeepSeek-Prover-V1.5: Harnessing Proof Assistant Feedback for Reinforcement Learning and Monte-Carlo Tree Search, arxiv.2408.08152 [paper]
  • Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning, arxiv.2410.06508 [paper]

Implicit Trial-and-Error Search For Long CoT

  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]
  • O1 Replication Journey - Part 2: Surpassing O1-preview through Simple Distillation, Big Progress or Bitter Lesson?, arxiv.2411.16489 [paper]
  • Back to Basics: Revisiting REINFORCE-Style Optimization for Learning from Human Feedback in LLMs, ACL 2024 [paper]
  • Do not think that much for 2+3=? on the overthinking of o1-like llms, arxiv.2412.21187 [paper] 💡
  • Thoughts are all over the place: On the underthinking of o1-like llms, arxiv.2501.18585 [paper] 💡
  • When more is less: Understanding chain-of-thought length in llms, arxiv.2502.07266 [paper] 💡
  • Logic-rl: Unleashing llm reasoning with rule-based reinforcement learning, arxiv.2502.14768 [paper] 💡
  • Demystifying long chain-of-thought reasoning in llms, arxiv.2502.03373 [paper] 💡
  • O1-pruner: Length-harmonizing fine-tuning for o1-like reasoning pruning, arxiv.2501.12570 [paper] 💡
  • Leveraging Constrained Monte Carlo Tree Search to Generate Reliable Long Chain-of-Thought for Mathematical Reasoning, arxiv.2502.11169 [paper] 💡

🔭 Model Evolution

  • Training language models to follow instructions with human feedback, NeurIPS 2022 [paper]
  • Learning to reason with llms, [blog]
  • Reinforcement Learning Enhanced LLMs: A Survey, arxiv.2412.10400 [paper]
  • Proximal Policy Optimization Algorithms, arxiv.1707.06347 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Hindsight Experience Replay, NeurIPS 2017 [paper]
  • DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models, arxiv.2402.03300 [paper]
  • Direct Preference Optimization: Your Language Model is Secretly a Reward Model, NeurIPS 2023 [paper]
  • Policy Gradient Methods for Reinforcement Learning with Function Approximation, NeurIPS 1999 [paper]
  • ReMax: A Simple, Effective, and Efficient Reinforcement Learning Method for Aligning Large Language Models, ICML 2024 [paper]
  • Back to Basics: Revisiting REINFORCE-Style Optimization for Learning from Human Feedback in LLMs, ACL 2024 [paper]
  • Approximating kl divergence, [blog]
  • Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement, arxiv.2409.12122 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • Bootstrapping Language Models with DPO Implicit Rewards, arxiv.2406.09760 [paper]
  • A General Theoretical Paradigm to Understand Learning from Human Preferences, AISTATS 2024 [paper]
  • iREPO: implicit Reward Pairwise Difference based Empirical Preference Optimization, arxiv.2405.15230 [paper]
  • Offline Reinforcement Learning for LLM Multi-Step Reasoning, arxiv.2412.16145 [paper]
  • Policy Optimization in RLHF: The Impact of Out-of-preference Data, arxiv.2312.10584 [paper]
  • Advancing LLM Reasoning Generalists with Preference Trees, arXiv.2404.02078 [paper]
  • Noise Contrastive Alignment of Language Models with Explicit Rewards, NeurIPS 2024 [paper]
  • Beyond Reverse KL: Generalizing Direct Preference Optimization with Diverse Divergence Constraints, ICLR 2024 [paper]
  • Provably Robust DPO: Aligning Language Models with Noisy Feedback, ICML 2024 [paper]
  • KTO: Model Alignment as Prospect Theoretic Optimization, arxiv.2402.01306 [paper]
  • Generalized Preference Optimization: A Unified Approach to Offline Alignment, ICML 2024 [paper]
  • ORPO: Monolithic Preference Optimization without Reference Model, EMNLP 2024 [paper]
  • From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function, arxiv.2404.12358 [paper]
  • Free Process Rewards without Process Labels, arxiv.2412.01981 [paper]
  • Process Reinforcement through Implicit Rewards, arxiv.2502.01456 [paper]

Optimizing Reasoner

Behavior Cloning

  • Scaling Relationship on Learning Mathematical Reasoning with Large Language Models, arxiv.2308.01825 [paper]
  • DART-Math: Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving, NeurIPS 2024 [paper]
  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • The Wisdom of Hindsight Makes Language Models Better Instruction Followers, ICML 2023 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning, arxiv.2410.06508 [paper]
  • Reverse Thinking Makes LLMs Stronger Reasoners, arxiv.2411.19865 [paper]

Preference Learning

  • RRHF: Rank Responses to Align Language Models with Human Feedback without tears, arxiv.2304.05302 [paper]
  • Direct Preference Optimization: Your Language Model is Secretly a Reward Model, NeurIPS 2023 [paper]
  • Iterative Reasoning Preference Optimization, NeurIPS 2024 [paper]
  • Enhancing LLM Reasoning with Reward-guided Tree Search, arxiv.2411.11694 [paper]
  • A Survey on LLM-as-a-Judge, arxiv.2411.15594 [paper]
  • SIaM: Self-Improving Code-Assisted Mathematical Reasoning of Large Language Models, arxiv.2408.15565 [paper]
  • Training language models to follow instructions with human feedback, NeurIPS 2022 [paper]
  • Self-Rewarding Language Models, ICML 2024 [paper]
  • Self-Evolutionary Large Language Models through Uncertainty-Enhanced Preference Optimization, arxiv.2409.11212 [paper]
  • Self-Explore: Enhancing Mathematical Reasoning in Language Models with Fine-grained Rewards, EMNLP 2024 [paper]
  • Step-DPO: Step-wise Preference Optimization for Long-chain Reasoning of LLMs, arxiv.2406.18629 [paper]
  • Step-Controlled DPO: Leveraging Stepwise Error for Enhanced Mathematical Reasoning, arxiv.2407.00782 [paper]
  • Chain of Preference Optimization: Improving Chain-of-Thought Reasoning in LLMs, NeurIPS 2024 [paper]
  • Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning, arxiv.2405.00451 [paper]
  • Step-level Value Preference Optimization for Mathematical Reasoning, EMNLP 2024 [paper]
  • From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function, arxiv.2404.12358 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Selective Preference Optimization via Token-Level Reward Function Estimation, arxiv.2408.13518 [paper]
  • Critical Tokens Matter: Token-Level Contrastive Estimation Enhances LLM's Reasoning Capability, arxiv.2411.19943 [paper]
  • Openai o1 system card, [blog]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]

Reinforcement Learning

  • Policy Gradient Methods for Reinforcement Learning with Function Approximation, NeurIPS 1999 [paper]
  • Proximal Policy Optimization Algorithms, arxiv.1707.06347 [paper]
  • DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models, arxiv.2402.03300 [paper]
  • ReMax: A Simple, Effective, and Efficient Reinforcement Learning Method for Aligning Large Language Models, ICML 2024 [paper]
  • Back to Basics: Revisiting REINFORCE-Style Optimization for Learning from Human Feedback in LLMs, ACL 2024 [paper]
  • Improving Language Model Reasoning with Self-motivated Learning, LREC 2024 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement, arxiv.2409.12122 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • A Survey on Offline Reinforcement Learning: Taxonomy, Review, and Open Problems, IEEE Trans. Neural Networks Learn. Syst. 2022 [paper]
  • Offline RL for Natural Language Generation with Implicit Language Q Learning, ICLR 2023 [paper]
  • Direct Preference Optimization: Your Language Model is Secretly a Reward Model, NeurIPS 2023 [paper]
  • Offline Reinforcement Learning for LLM Multi-Step Reasoning, arxiv.2412.16145 [paper]
  • Reinforcement Learning with Deep Energy-Based Policies, ICML 2017 [paper]
  • Bootstrapping Language Models with DPO Implicit Rewards, arxiv.2406.09760 [paper]
  • Planning Like Human: A Dual-process Framework for Dialogue Planning, ACL 2024 [paper]
  • Model-based Reinforcement Learning: A Survey, Found. Trends Mach. Learn. 2020 [paper]
  • Is Sora a World Simulator? A Comprehensive Survey on General World Models and Beyond, arxiv.2405.03520 [paper]
  • Mastering the game of Go without human knowledge, Nature 2017 [paper]
  • Reasoning with Language Model is Planning with World Model, EMNLP 2023 [paper]
  • SMART: Self-learning Meta-strategy Agent for Reasoning Tasks, arxiv.2410.16128 [paper]
  • Chain of Thought Prompting Elicits Reasoning in Large Language Models, NeurIPS 2022 [paper]
  • Least-to-Most Prompting Enables Complex Reasoning in Large Language Models, ICLR 2023 [paper]
  • Program of Thoughts Prompting: Disentangling Computation from Reasoning for Numerical Reasoning Tasks, Trans. Mach. Learn. Res. 2023 [paper]
  • Token-Supervised Value Models for Enhancing Mathematical Reasoning Capabilities of Large Language Models, ICLR 2025 [paper]
  • ReasonFlux: Hierarchical LLM Reasoning via Scaling Thought Templates, arxiv.2502.06772 [paper]
  • ArCHer: Training Language Model Agents via Hierarchical Multi-Turn RL, ICML 2024 [paper]
  • Offline Reinforcement Learning with Implicit Q-Learning, ICLR 2022 [paper]
  • Policy Gradient Methods for Reinforcement Learning with Function Approximation, NeurIPS 1999 [paper]

Optimizing Evaluator

Training Data Construction

  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback, ICML 2024 [paper]
  • Rule Based Rewards for Language Model Safety, NeurIPS 2024 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Let's Verify Step by Step, ICLR 2024 [paper]
  • Judging LLM-as-a-judge with MT-Bench and Chatbot Arena, NeurIPS 2023 [paper]
  • Uncertainty-Aware Step-wise Verification with Generative Reward Models, arxiv.2502.11250 [paper]
  • Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations, ACL 2024 [paper]
  • Multi-step Problem Solving Through a Verifier: An Empirical Analysis on Model-induced Process Supervision, EMNLP 2024 [paper]
  • Learning Planning-based Reasoning by Trajectories Collection and Process Reward Synthesizing, EMNLP 2024 [paper]
  • Improve Mathematical Reasoning in Language Models by Automated Process Supervision, arXiv.2406.06592 [paper]
  • Generative Verifiers: Reward Modeling as Next-Token Prediction, arxiv.2408.15240 [paper]
  • Evaluating Mathematical Reasoning Beyond Accuracy, arXiv.2404.05692 [paper]
  • LLM Critics Help Catch Bugs in Mathematics: Towards a Better Mathematical Verifier with Natural Language Feedback, arXiv.2406.14024 [paper]
  • The Lessons of Developing Process Reward Models in Mathematical Reasoning, arXiv.2501.07301 [paper]
  • AutoPRM: Automating Procedural Supervision for Multi-Step Reasoning via Controllable Question Decomposition NAACL 2024 [paper]
  • S3c-Math: Spontaneous Step-level Self-correction Makes Large Language Models Better Mathematical Reasoners, arXiv.2409.01524 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • AutoPSV: Automated Process-Supervised Verifier, NeurIPS 2024 [paper]
  • Improving Large Language Models via Fine-grained Reinforcement Learning with Minimum Editing Constraint, ACL 2024 [paper]
  • TLCR: Token-Level Continuous Reward for Fine-grained Reinforcement Learning from Human Feedback, ACL 2024 [paper]
  • From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function, arxiv.2404.12358 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Selective Preference Optimization via Token-Level Reward Function Estimation, arxiv.2408.13518 [paper]
  • Exploring the Limit of Outcome Reward for Learning Mathematical Reasoning, arxiv.2502.06781 [paper]

Training Format

  • Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations, ACL 2024 [paper]
  • Multi-step Problem Solving Through a Verifier: An Empirical Analysis on Model-induced Process Supervision, EMNLP 2024 [paper]
  • AutoPSV: Automated Process-Supervised Verifier, NeurIPS 2024 [paper]
  • Rank Analysis of Incomplete Block Designs: I. The Method of Paired Comparisons, Biometrika 1952 [paper]
  • Self-Generated Critiques Boost Reward Modeling for Language Models, arxiv.2411.16646 [paper]
  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • Improving LLM Reasoning through Scaling Inference Computation with Collaborative Verification, arXiv.2410.05318 [paper]
  • SimPO: Simple Preference Optimization with a Reference-Free Reward, NeurIPS 2024 [paper]
  • Advancing Process Verification for Large Language Models via Tree-Based Preference Learning EMNLP 2024 [paper]
  • RRHF: Rank Responses to Align Language Models with Human Feedback without tears, arxiv.2304.05302 [paper]
  • Generative Verifiers: Reward Modeling as Next-Token Prediction, arxiv.2408.15240 [paper]
  • Critique-out-Loud Reward Models, arXiv.2408.11791 [paper]
  • LLM Critics Help Catch Bugs in Mathematics: Towards a Better Mathematical Verifier with Natural Language Feedback, arXiv.2406.14024 [paper]
  • Generative Reward Models, arxiv.2410.12832 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • RL4F: Generating Natural Language Feedback with Reinforcement Learning for Repairing Model Outputs, ACL 2023 [paper]
  • Retroformer: Retrospective Large Language Agents with Policy Gradient Optimization, ICLR 2024 [paper]
  • Teaching Language Models to Critique via Reinforcement Learning, arxiv.2502.03492 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]

Optimizing Post-Processor

  • Learning to Check: Unleashing Potentials for Self-Correction in Large Language Models, arXiv.2402.13035 [paper]
  • Learning From Mistakes Makes LLM Better Reasoner, arXiv.2310.20689 [paper]
  • S3c-Math: Spontaneous Step-level Self-correction Makes Large Language Models Better Mathematical Reasoners, arXiv.2409.01524 [paper]
  • REFINER: Reasoning Feedback on Intermediate Representations, EACL 2024 [paper]
  • Embedding Self-Correction as an Inherent Ability in Large Language Models for Enhanced Mathematical Reasoning, arXiv.2410.10735 [paper]
  • Think Thrice Before You Act: Progressive Thought Refinement in Large Language Models, arXiv.2410.13413 [paper]
  • Generating Sequences by Learning to Self-Correct, ICLR 2023 [paper]
  • Small Language Models Need Strong Verifiers to Self-Correct Reasoning, ACL 2024 [paper]
  • Learning to Refine with Fine-Grained Natural Language Feedback, EMNLP 2024 [paper]
  • The ART of LLM Refinement: Ask, Refine, and Trust, NAACL 2024 [paper]
  • Meta-Reflection: A Feedback-Free Reflection Learning Framework, arXiv.2412.13781 [paper]
  • Training language models to follow instructions with human feedback, NeurIPS 2022 [paper]
  • RLEF: Grounding Code LLMs in Execution Feedback with Reinforcement Learning, arXiv.2410.02089 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]

🛸 Self-Evolution

self-evolution illustration

Theory

  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models, TMLR 2024 [paper]
  • The expectation-maximization algorithm, IEEE Signal Process. Mag. 1996 [paper]
  • Inference Scaling Laws: An Empirical Analysis of Compute-Optimal Inference for Problem-Solving with Language Models, arXiv.2408.00724 [paper]
  • Scaling laws for single-agent reinforcement learning, arxiv.2301.13442 [paper]
  • Scaling of Search and Learning: A Roadmap to Reproduce o1 from Reinforcement Learning Perspective, arxiv.2412.14135 [paper]
  • B-STaR: Monitoring and Balancing Exploration and Exploitation in Self-Taught Reasoners, arxiv.2412.17256 [paper]
  • Common 7B Language Models Already Possess Strong Math Capabilities, arxiv.2403.04706 [paper]

Self-Evolution Strategies

Independent Evolution

  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]
  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • Self-Refine: Iterative Refinement with Self-Feedback, NeurIPS 2023 [paper]
  • Enabling Language Models to Implicitly Learn Self-Improvement, arxiv.2310.00898 [paper]

Collaborative Evolution

  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]

Adversarial Evolution

  • Generative Adversarial Nets, NeurIPS 2014 [paper]
  • Evolving Alignment via Asymmetric Self-Play, arxiv.2411.00062 [paper]
  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]

Self-Evolution Patterns

Only Reasoner

  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]
  • Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems, arxiv.2412.09413 [paper]
  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • AlphaMath Almost Zero: process Supervision without process, NeurIPS 2024 [paper]
  • Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning, arxiv.2405.00451 [paper]
  • Self-Training with Direct Preference Optimization Improves Chain-of-Thought Reasoning, ACL 2024 [paper]
  • Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning, arxiv.2410.06508 [paper]
  • Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models, TMLR 2024 [paper]
  • Iterative Reasoning Preference Optimization, NeurIPS 2024 [paper]
  • ReGenesis: LLMs can Grow into Reasoning Generalists via Self-Improvement, arxiv.2410.02108 [paper]
  • Large Language Models Can Self-Improve, EMNLP 2023 [paper]
  • Large Language Models Can Self-Improve in Long-context Reasoning, arxiv.2411.08147 [paper]
  • ReST meets ReAct: Self-Improvement for Multi-Step Reasoning LLM Agent, arxiv.2312.10003 [paper]
  • RAFT: Reward rAnked FineTuning for Generative Foundation Model Alignment, Trans. Mach. Learn. Res. 2023 [paper]
  • Trial and Error: Exploration-Based Trajectory Optimization for LLM Agents, arxiv.2403.02502 [paper]

Reasoner + Evaluator

  • Self-Rewarding Language Models, ICML 2024 [paper]
  • Self-Evolutionary Large Language Models through Uncertainty-Enhanced Preference Optimization, arxiv.2409.11212 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking, arxiv.2501.04519 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • AlphaMath Almost Zero: process Supervision without process, NeurIPS 2024 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • Self-playing Adversarial Language Game Enhances LLM Reasoning, NeurIPS 2024 [paper]
  • Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models, ICML 2024 [paper]

Reasoner + Post-Processor

  • Re-ReST: Reflection-Reinforced Self-Training for Language Agents, EMNLP 2024 [paper]
  • Enabling Language Models to Implicitly Learn Self-Improvement, arxiv.2310.00898 [paper]

Reasoner + Task Creator

  • Evolving Alignment via Asymmetric Self-Play, arxiv.2411.00062 [paper]

Reasoner + Evaluator + Post-Processor

  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • RedStar: Does Scaling Long-CoT Data Unlock Better Slow-Reasoning Systems?, arxiv.2501.11284 [paper]

🚢 O1-like works

  • Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions arxiv.2411.14405 [paper]
  • O1 Replication Journey: A Strategic Progress Report - Part 1, arxiv.2410.18982 [paper]
  • O1 Replication Journey - Part 2: Surpassing O1-preview through Simple Distillation, Big Progress or Bitter Lesson?, arxiv.2411.16489 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • Qwq: Reflect deeply on the boundaries of the unknown, [blog]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems, arxiv.2412.09413 [paper]
  • rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking, arxiv.2501.04519 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • Learning to reason with llms, [blog]

📝 Citation

If you find our work helpful, you can cite this paper as:

@Misc{ReasoningSelfEvolution,
    title={A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution},
    author={Tao He and Hao Li and Jingchang Chen and Runxuan Liu and Yixin Cao and Lizi Liao and Zihao Zheng and Zheng Chu and Jiafeng Liang and Ming Liu and Bing Qin and Ting Liu},
    year={2025},
    url={http://dx.doi.org/10.13140/RG.2.2.23943.30886}
}
cs-holder/Reasoning-Self-Evolution-Survey

54

6 commits

updated Mar 6, 2025

See the code

README

A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution

Tao He1∗, Hao Li1∗, Jingchang Chen1, Runxuan Liu1, Yixin Cao2, Lizi Liao3, Zihao Zheng1, Zheng Chu1, Jiafeng Liang1, Ming Liu1†, Bing Qin1,
1Harbin Institute of Technology, Harbin, China
2Fudan University, Shanghai, China
2Singpore Management University, Singapore

This repository contains the resources for survey paper A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution

Self-Evolution Framework

taxonomy

For more details, please refer to the paper: A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution.

🎉 Updates

  • 2025/02/26 We updated the paper by replacing the terminology for the two search methods, adding a table to summarize the comparison between the two search approaches, and refining the content of theory in self-evolution.
  • 2025/02/24 We created this reading list repository.

We use the 💡 icon to identify articles that have been added since the last version of the paper.

This reading list will be updated periodically, and if you have any suggestions or find some we missed, feel free to contact us! You can submit an issue or send an email ([email protected] or [email protected]).

🎁 Resources

Surveys

  • Navigate through Enigmatic Labyrinth A Survey of Chain of Thought Reasoning: Advances, Frontiers and Future, ACL 2024 [paper]
  • A Survey on Self-Evolution of Large Language Models, arxiv.2404.14387 [paper]
  • A Survey on Data Synthesis and Augmentation for Large Language Models, arxiv.2410.12896 [paper]
  • Reinforcement learning enhanced LLMs: A survey, arxiv.2412.10400 [paper]
  • Automatically Correcting Large Language Models: Surveying the Landscape ofDiverse Automated Correction Strategies, TACL [paper]
  • When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs, TACL [paper]

Projects

  • HqWu-HITCS/Awesome-LLM-Survey, [project]
  • AGI-Edgerunners/LLM-Planning-Papers [project]
  • modelscope/awesome-deep-reasoning [project]
  • wasiahmad/Awesome-LLM-Synthetic-Data [project]
  • CSHaitao/Awesome-LLMs-as-Judges [project]

🚀 Data Evolution

data evolution

Task Evolution

  • Common 7B Language Models Already Possess Strong Math Capabilities, arXiv.2403.04706 [paper]
  • Language Models Can Teach Themselves to Program Better, ICLR 2023 [paper]
  • Learning Performance-Improving Code Edits, ICLR 2024 [paper]
  • MetaMath: Bootstrap Your Own Mathematical Questions for Large Language Models, ICLR 2024 [paper]
  • TinyGSM: achieving >80% on GSM8k with small language models, arxiv.2312.09241 [paper]
  • WizardLM: Empowering Large Language Models to Follow Complex Instructions, ICLR 2024 [paper]
  • Self-Instruct: Aligning Language Models with Self-Generated Instructions, ACL 2023 [paper]
  • Large Language Models Can Be Easily Distracted by Irrelevant Context, ICML 2023 [paper]
  • Orca-Math: Unlocking the potential of SLMs in Grade School Math, arxiv.2402.14830 [paper]
  • Self-Alignment with Instruction Backtranslation, ICLR 2024 [paper]
  • Augmenting Math Word Problems via Iterative Question Composing, arXiv.2401.09003 [paper]
  • Generating Symbolic Reasoning Problems with Transformer GANs,arxiv.2110.10054 [paper]
  • Magicoder: Empowering Code Generation with OSS-Instruct, ICML 2024 [paper]
  • MathGenie: Generating Synthetic Data with Question Back-translation for Enhancing Mathematical Reasoning of LLMs, ACL 2024 [paper]

CoT Evolution

Step-by-Step Reasoning

  • Chain-of-Thought Prompting Elicits Reasoning in Large Language Models, NeurIPS 2022 [paper]
  • Plan-and-Solve Prompting: Improving Zero-Shot Chain-of-Thought Reasoning by Large Language Models, ACL 2023 [paper]
  • Least-to-Most Prompting Enables Complex Reasoning in Large Language Models, ICLR 2023 [paper]
  • Successive Prompting for Decomposing Complex Questions, EMNLP 2022 [paper]
  • ReAct: Synergizing Reasoning and Acting in Language Models, ICLR 2023 [paper]

Evaluation

  • Training Verifiers to Solve Math Word Problems, arxiv.2110.14168 [paper]
  • Self-Consistency Improves Chain of Thought Reasoning in Language Models, ICLR 2023 [paper]
  • RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback, ICML 2024 [paper]
  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]
  • Self-Refine: Iterative Refinement with Self-Feedback, NeurIPS 2023 [paper]
  • SciInstruct: a Self-Reflective Instruction Annotated Dataset for Training Scientific Language Models, arxiv.2401.07950 [paper]
  • Check Your Facts and Try Again: Improving Large Language Models with External Knowledge and Automated Feedback, arXiv.2302.12813 [paper]
  • Reflexion: language agents with verbal reinforcement learning, NeurIPS 2023 [paper]
  • CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing, ICLR 2024 [paper]
  • Critique-out-Loud Reward Models, arXiv.2408.11791 [paper]
  • Self-Generated Critiques Boost Reward Modeling for Language Models, arxiv.2411.16646 [paper]
  • Forward-Backward Reasoning in Large Language Models for Mathematical Verification, ACL 2024 [paper]
  • Large Language Models are Better Reasoners with Self-Verification, EMNLP 2023 [paper]
  • Let's Verify Step by Step, ICLR 2024 [paper]
  • Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations, ACL 2024 [paper]
  • Multi-step Problem Solving Through a Verifier: An Empirical Analysis on Model-induced Process Supervision, EMNLP 2024 [paper]
  • LLM Critics Help Catch Bugs in Mathematics: Towards a Better Mathematical Verifier with Natural Language Feedback, arXiv.2406.14024 [paper]
  • AutoPSV: Automated Process-Supervised Verifier, NeurIPS 2024 [paper]
  • Making Language Models Better Reasoners with Step-Aware Verifier, ACL 2023 [paper]
  • Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing, NeurIPS 2024 [paper]
  • Self-Evaluation Guided Beam Search for Reasoning, NeurIPS 2023 [paper]
  • Critic-CoT: Boosting the reasoning abilities of large language model via Chain-of-thoughts Critic, arXiv.2408.16326 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • TLCR: Token-Level Continuous Reward for Fine-grained Reinforcement Learning from Human Feedback, ACL 2024 [paper]
  • Improving Large Language Models via Fine-grained Reinforcement Learning with Minimum Editing Constraint, ACL 2024 [paper]
  • Token-Supervised Value Models for Enhancing Mathematical Reasoning Capabilities of Large Language Models, ICLR 2025 [paper]
  • Selective Preference Optimization via Token-Level Reward Function Estimation, arxiv.2408.13518 [paper]
  • MCTS-Judge: Test-Time Scaling in LLM-as-a-Judge for Code Correctness Evaluation, arxiv.2502.12468 [paper]
  • Reward Hacking in Reinforcement Learning, [blog]
  • On Designing Effective RL Reward at Training Time for LLM Reasoning, arxiv.2410.15115 [paper]
  • Process Reinforcement through Implicit Rewards, arxiv.2502.01456 [paper]

Post-Processing (Correction/Filtering/Summarization/...)

  • Learn Beyond The Answer: Training Language Models with Reflection for Mathematical Reasoning, EMNLP 2024 [paper]
  • Meta-Reflection: A Feedback-Free Reflection Learning Framework, arXiv.2412.13781 [paper]
  • RoT: Enhancing Large Language Models with Reflection on Search Trees, arXiv.2404.05449 [paper]
  • PRACT: Optimizing Principled Reasoning and Acting of LLM Agent, arXiv.2410.18528 [paper]
  • CoT-based Synthesizer: Enhancing LLM Performance through Answer Synthesis, arXiv.2501.01668 [paper]
  • Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models, TMLR 2024 [paper]
  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]
  • Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems, arxiv.2412.09413 [paper]
  • Self-Consistency Improves Chain of Thought Reasoning in Language Models, ICLR 2023 [paper]
  • Universal Self-Consistency for Large Language Model Generation, arXiv.2311.17311 [paper]
  • Forward-Backward Reasoning in Large Language Models for Mathematical Verification, ACL 2024 [paper]
  • Large Language Models are Better Reasoners with Self-Verification, EMNLP 2023 [paper]
  • Perplexed by Perplexity: Perplexity-Based Data Pruning With Small Reference Models, arxiv.2405.20541 [paper]
  • Self-Training Meets Consistency: Improving LLMs' Reasoning With Consistency-Driven Rationale Evaluation, arXiv.2411.06387 [paper]
  • Training Verifiers to Solve Math Word Problems, arxiv.2110.14168 [paper]
  • OVM, Outcome-supervised Value Models for Planning in Mathematical Reasoning, NAACL 2024 [paper]
  • Learning to summarize with human feedback, NeurIPS 2020 [paper]
  • Self-Refine: Iterative Refinement with Self-Feedback, NeurIPS 2023 [paper]
  • Self-Contrast: Better Reflection Through Inconsistent Solving Perspectives, ACL 2024 [paper]
  • LLM Self-Correction with DeCRIM: Decompose, Critique, and Refine for Enhanced Following of Instructions with Multiple Constraints, EMNLP 2024 [paper]
  • Large Language Models Can Self-Correct with Key Condition Verification, EMNLP 2024 [paper]
  • CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing, ICLR 2024 [paper]
  • DotaMath: Decomposition of Thought with Code Assistance and Self-correction for Mathematical Reasoning, arXiv.2407.04078 [paper]
  • Embedding Self-Correction as an Inherent Ability in Large Language Models for Enhanced Mathematical Reasoning, arXiv.2410.10735 [paper]
  • Teaching Large Language Models to Self-Debug, ICLR 2024 [paper]
  • Advancing LLM Reasoning Generalists with Preference Trees, arXiv.2404.02078 [paper]
  • Self-Refinement of Language Models from External Proxy Metrics Feedback, arXiv.2403.00827 [paper]
  • Enhancing Mathematical Reasoning in LLMs by Stepwise Correction, arXiv.2410.12934 [paper]
  • The ART of LLM Refinement: Ask, Refine, and Trust, NAACL 2024 [paper]
  • Critic-CoT: Boosting the reasoning abilities of large language model via Chain-of-thoughts Critic, arXiv.2408.16326 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • S3c-Math: Spontaneous Step-level Self-correction Makes Large Language Models Better Mathematical Reasoners, arXiv.2409.01524 [paper]
  • Small Language Models Need Strong Verifiers to Self-Correct Reasoning, ACL 2024 [paper]
  • LLaMA-Berry: Pairwise Optimization for O1-like Olympiad-Level Mathematical Reasoning, arXiv.2410.02884 [paper]
  • Accessing GPT-4 level Mathematical Olympiad Solutions via Monte Carlo Tree Self-refine with LLaMa-3 8B, arXiv.2406.07394 [paper]
  • O1 Replication Journey: A Strategic Progress Report - Part 1, arxiv.2410.18982 [paper]
  • Step Back to Leap Forward: Self-Backtracking for Boosting Reasoning of Language Models, arxiv.2502.04404 [paper]

search difference

Explicit Tree Search For Short CoT

  • Tree of Thoughts: Deliberate Problem Solving with Large Language Models, NeurIPS 2023 [paper]
  • ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs, ICLR 2024 [paper]
  • Autonomous Tree-search Ability of Large Language Models, arxiv.2310.10686 [paper]
  • Algorithm of Thoughts: Enhancing Exploration of Ideas in Large Language Models, ICML 2024 [paper]
  • Token-Supervised Value Models for Enhancing Mathematical Reasoning Capabilities of Large Language Models, ICLR 2025 [paper]
  • Diverse Beam Search: Decoding Diverse Solutions from Neural Sequence Models, arxiv.1610.02424 [paper]
  • BPP-Search: Enhancing Tree of Thought Reasoning for Mathematical Modeling Problem Solving, arxiv.2411.17404 [paper]
  • AlphaMath Almost Zero: process Supervision without process, NeurIPS 2024 [paper]
  • OVM, Outcome-supervised Value Models for Planning in Mathematical Reasoning, NAACL 2024 [paper]
  • Rewarding Progress: Scaling Automated Process Verifiers for LLM Reasoning, arxiv.2410.08146 [paper]
  • Self-Evaluation Guided Beam Search for Reasoning, NeurIPS 2023 [paper]
  • Chain-of-Thought Reasoning Without Prompting, NeurIPS 2024 [paper]
  • ToolChain*: Efficient Action Space Navigation in Large Language Models with A* Search, ICLR 2024 [paper]
  • Q*: Improving Multi-step Reasoning for LLMs with Deliberative Planning, arxiv.2406.14283 [paper]
  • LLM-A*: Large Language Model Enhanced Incremental Heuristic Search on Path Planning, EMNLP 2024 [paper]
  • A Training Data Recipe to Accelerate A* Search with Language Models, EMNLP 2024 [paper]
  • Beyond A*: Better Planning with Transformers via Search Dynamics Bootstrapping, arxiv.2402.14083 [paper]
  • Dualformer: Controllable Fast and Slow Thinking by Learning with Randomized Reasoning Traces, arxiv.2410.09918 [paper]
  • Mastering the game of Go without human knowledge, Nature 2017 [paper]
  • Multi-armed bandits with episode context, Ann. Math. Artif. Intell. 2011 [paper]
  • Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning, arxiv.2405.00451 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions, arxiv.2411.14405 [paper]
  • Enhancing LLM Reasoning with Reward-guided Tree Search, arxiv.2411.11694 [paper]
  • Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing, NeurIPS 2024 [paper]
  • Reasoning with Language Model is Planning with World Model, EMNLP 2023 [paper]
  • Solving Math Word Problems via Cooperative Reasoning induced Language Models, ACL 2023 [paper]
  • Self-Consistency Improves Chain of Thought Reasoning in Language Models, ICLR 2023 [paper]
  • Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models, ICML 2024 [paper]
  • Alphazero-like Tree-Search can Guide Large Language Model Decoding and Training, ICML 2024 [paper]
  • Mutual Reasoning Makes Smaller LLMs Stronger Problem-Solvers, arxiv.2408.06195 [paper]
  • DeepSeek-Prover-V1.5: Harnessing Proof Assistant Feedback for Reinforcement Learning and Monte-Carlo Tree Search, arxiv.2408.08152 [paper]
  • Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning, arxiv.2410.06508 [paper]

Implicit Trial-and-Error Search For Long CoT

  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]
  • O1 Replication Journey - Part 2: Surpassing O1-preview through Simple Distillation, Big Progress or Bitter Lesson?, arxiv.2411.16489 [paper]
  • Back to Basics: Revisiting REINFORCE-Style Optimization for Learning from Human Feedback in LLMs, ACL 2024 [paper]
  • Do not think that much for 2+3=? on the overthinking of o1-like llms, arxiv.2412.21187 [paper] 💡
  • Thoughts are all over the place: On the underthinking of o1-like llms, arxiv.2501.18585 [paper] 💡
  • When more is less: Understanding chain-of-thought length in llms, arxiv.2502.07266 [paper] 💡
  • Logic-rl: Unleashing llm reasoning with rule-based reinforcement learning, arxiv.2502.14768 [paper] 💡
  • Demystifying long chain-of-thought reasoning in llms, arxiv.2502.03373 [paper] 💡
  • O1-pruner: Length-harmonizing fine-tuning for o1-like reasoning pruning, arxiv.2501.12570 [paper] 💡
  • Leveraging Constrained Monte Carlo Tree Search to Generate Reliable Long Chain-of-Thought for Mathematical Reasoning, arxiv.2502.11169 [paper] 💡

🔭 Model Evolution

  • Training language models to follow instructions with human feedback, NeurIPS 2022 [paper]
  • Learning to reason with llms, [blog]
  • Reinforcement Learning Enhanced LLMs: A Survey, arxiv.2412.10400 [paper]
  • Proximal Policy Optimization Algorithms, arxiv.1707.06347 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Hindsight Experience Replay, NeurIPS 2017 [paper]
  • DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models, arxiv.2402.03300 [paper]
  • Direct Preference Optimization: Your Language Model is Secretly a Reward Model, NeurIPS 2023 [paper]
  • Policy Gradient Methods for Reinforcement Learning with Function Approximation, NeurIPS 1999 [paper]
  • ReMax: A Simple, Effective, and Efficient Reinforcement Learning Method for Aligning Large Language Models, ICML 2024 [paper]
  • Back to Basics: Revisiting REINFORCE-Style Optimization for Learning from Human Feedback in LLMs, ACL 2024 [paper]
  • Approximating kl divergence, [blog]
  • Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement, arxiv.2409.12122 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • Bootstrapping Language Models with DPO Implicit Rewards, arxiv.2406.09760 [paper]
  • A General Theoretical Paradigm to Understand Learning from Human Preferences, AISTATS 2024 [paper]
  • iREPO: implicit Reward Pairwise Difference based Empirical Preference Optimization, arxiv.2405.15230 [paper]
  • Offline Reinforcement Learning for LLM Multi-Step Reasoning, arxiv.2412.16145 [paper]
  • Policy Optimization in RLHF: The Impact of Out-of-preference Data, arxiv.2312.10584 [paper]
  • Advancing LLM Reasoning Generalists with Preference Trees, arXiv.2404.02078 [paper]
  • Noise Contrastive Alignment of Language Models with Explicit Rewards, NeurIPS 2024 [paper]
  • Beyond Reverse KL: Generalizing Direct Preference Optimization with Diverse Divergence Constraints, ICLR 2024 [paper]
  • Provably Robust DPO: Aligning Language Models with Noisy Feedback, ICML 2024 [paper]
  • KTO: Model Alignment as Prospect Theoretic Optimization, arxiv.2402.01306 [paper]
  • Generalized Preference Optimization: A Unified Approach to Offline Alignment, ICML 2024 [paper]
  • ORPO: Monolithic Preference Optimization without Reference Model, EMNLP 2024 [paper]
  • From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function, arxiv.2404.12358 [paper]
  • Free Process Rewards without Process Labels, arxiv.2412.01981 [paper]
  • Process Reinforcement through Implicit Rewards, arxiv.2502.01456 [paper]

Optimizing Reasoner

Behavior Cloning

  • Scaling Relationship on Learning Mathematical Reasoning with Large Language Models, arxiv.2308.01825 [paper]
  • DART-Math: Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving, NeurIPS 2024 [paper]
  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • The Wisdom of Hindsight Makes Language Models Better Instruction Followers, ICML 2023 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning, arxiv.2410.06508 [paper]
  • Reverse Thinking Makes LLMs Stronger Reasoners, arxiv.2411.19865 [paper]

Preference Learning

  • RRHF: Rank Responses to Align Language Models with Human Feedback without tears, arxiv.2304.05302 [paper]
  • Direct Preference Optimization: Your Language Model is Secretly a Reward Model, NeurIPS 2023 [paper]
  • Iterative Reasoning Preference Optimization, NeurIPS 2024 [paper]
  • Enhancing LLM Reasoning with Reward-guided Tree Search, arxiv.2411.11694 [paper]
  • A Survey on LLM-as-a-Judge, arxiv.2411.15594 [paper]
  • SIaM: Self-Improving Code-Assisted Mathematical Reasoning of Large Language Models, arxiv.2408.15565 [paper]
  • Training language models to follow instructions with human feedback, NeurIPS 2022 [paper]
  • Self-Rewarding Language Models, ICML 2024 [paper]
  • Self-Evolutionary Large Language Models through Uncertainty-Enhanced Preference Optimization, arxiv.2409.11212 [paper]
  • Self-Explore: Enhancing Mathematical Reasoning in Language Models with Fine-grained Rewards, EMNLP 2024 [paper]
  • Step-DPO: Step-wise Preference Optimization for Long-chain Reasoning of LLMs, arxiv.2406.18629 [paper]
  • Step-Controlled DPO: Leveraging Stepwise Error for Enhanced Mathematical Reasoning, arxiv.2407.00782 [paper]
  • Chain of Preference Optimization: Improving Chain-of-Thought Reasoning in LLMs, NeurIPS 2024 [paper]
  • Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning, arxiv.2405.00451 [paper]
  • Step-level Value Preference Optimization for Mathematical Reasoning, EMNLP 2024 [paper]
  • From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function, arxiv.2404.12358 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Selective Preference Optimization via Token-Level Reward Function Estimation, arxiv.2408.13518 [paper]
  • Critical Tokens Matter: Token-Level Contrastive Estimation Enhances LLM's Reasoning Capability, arxiv.2411.19943 [paper]
  • Openai o1 system card, [blog]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]

Reinforcement Learning

  • Policy Gradient Methods for Reinforcement Learning with Function Approximation, NeurIPS 1999 [paper]
  • Proximal Policy Optimization Algorithms, arxiv.1707.06347 [paper]
  • DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models, arxiv.2402.03300 [paper]
  • ReMax: A Simple, Effective, and Efficient Reinforcement Learning Method for Aligning Large Language Models, ICML 2024 [paper]
  • Back to Basics: Revisiting REINFORCE-Style Optimization for Learning from Human Feedback in LLMs, ACL 2024 [paper]
  • Improving Language Model Reasoning with Self-motivated Learning, LREC 2024 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement, arxiv.2409.12122 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • A Survey on Offline Reinforcement Learning: Taxonomy, Review, and Open Problems, IEEE Trans. Neural Networks Learn. Syst. 2022 [paper]
  • Offline RL for Natural Language Generation with Implicit Language Q Learning, ICLR 2023 [paper]
  • Direct Preference Optimization: Your Language Model is Secretly a Reward Model, NeurIPS 2023 [paper]
  • Offline Reinforcement Learning for LLM Multi-Step Reasoning, arxiv.2412.16145 [paper]
  • Reinforcement Learning with Deep Energy-Based Policies, ICML 2017 [paper]
  • Bootstrapping Language Models with DPO Implicit Rewards, arxiv.2406.09760 [paper]
  • Planning Like Human: A Dual-process Framework for Dialogue Planning, ACL 2024 [paper]
  • Model-based Reinforcement Learning: A Survey, Found. Trends Mach. Learn. 2020 [paper]
  • Is Sora a World Simulator? A Comprehensive Survey on General World Models and Beyond, arxiv.2405.03520 [paper]
  • Mastering the game of Go without human knowledge, Nature 2017 [paper]
  • Reasoning with Language Model is Planning with World Model, EMNLP 2023 [paper]
  • SMART: Self-learning Meta-strategy Agent for Reasoning Tasks, arxiv.2410.16128 [paper]
  • Chain of Thought Prompting Elicits Reasoning in Large Language Models, NeurIPS 2022 [paper]
  • Least-to-Most Prompting Enables Complex Reasoning in Large Language Models, ICLR 2023 [paper]
  • Program of Thoughts Prompting: Disentangling Computation from Reasoning for Numerical Reasoning Tasks, Trans. Mach. Learn. Res. 2023 [paper]
  • Token-Supervised Value Models for Enhancing Mathematical Reasoning Capabilities of Large Language Models, ICLR 2025 [paper]
  • ReasonFlux: Hierarchical LLM Reasoning via Scaling Thought Templates, arxiv.2502.06772 [paper]
  • ArCHer: Training Language Model Agents via Hierarchical Multi-Turn RL, ICML 2024 [paper]
  • Offline Reinforcement Learning with Implicit Q-Learning, ICLR 2022 [paper]
  • Policy Gradient Methods for Reinforcement Learning with Function Approximation, NeurIPS 1999 [paper]

Optimizing Evaluator

Training Data Construction

  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback, ICML 2024 [paper]
  • Rule Based Rewards for Language Model Safety, NeurIPS 2024 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Let's Verify Step by Step, ICLR 2024 [paper]
  • Judging LLM-as-a-judge with MT-Bench and Chatbot Arena, NeurIPS 2023 [paper]
  • Uncertainty-Aware Step-wise Verification with Generative Reward Models, arxiv.2502.11250 [paper]
  • Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations, ACL 2024 [paper]
  • Multi-step Problem Solving Through a Verifier: An Empirical Analysis on Model-induced Process Supervision, EMNLP 2024 [paper]
  • Learning Planning-based Reasoning by Trajectories Collection and Process Reward Synthesizing, EMNLP 2024 [paper]
  • Improve Mathematical Reasoning in Language Models by Automated Process Supervision, arXiv.2406.06592 [paper]
  • Generative Verifiers: Reward Modeling as Next-Token Prediction, arxiv.2408.15240 [paper]
  • Evaluating Mathematical Reasoning Beyond Accuracy, arXiv.2404.05692 [paper]
  • LLM Critics Help Catch Bugs in Mathematics: Towards a Better Mathematical Verifier with Natural Language Feedback, arXiv.2406.14024 [paper]
  • The Lessons of Developing Process Reward Models in Mathematical Reasoning, arXiv.2501.07301 [paper]
  • AutoPRM: Automating Procedural Supervision for Multi-Step Reasoning via Controllable Question Decomposition NAACL 2024 [paper]
  • S3c-Math: Spontaneous Step-level Self-correction Makes Large Language Models Better Mathematical Reasoners, arXiv.2409.01524 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • AutoPSV: Automated Process-Supervised Verifier, NeurIPS 2024 [paper]
  • Improving Large Language Models via Fine-grained Reinforcement Learning with Minimum Editing Constraint, ACL 2024 [paper]
  • TLCR: Token-Level Continuous Reward for Fine-grained Reinforcement Learning from Human Feedback, ACL 2024 [paper]
  • From $r$ to $Q^*$: Your Language Model is Secretly a Q-Function, arxiv.2404.12358 [paper]
  • DPO Meets PPO: Reinforced Token Optimization for RLHF, arxiv.2404.18922 [paper]
  • Selective Preference Optimization via Token-Level Reward Function Estimation, arxiv.2408.13518 [paper]
  • Exploring the Limit of Outcome Reward for Learning Mathematical Reasoning, arxiv.2502.06781 [paper]

Training Format

  • Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations, ACL 2024 [paper]
  • Multi-step Problem Solving Through a Verifier: An Empirical Analysis on Model-induced Process Supervision, EMNLP 2024 [paper]
  • AutoPSV: Automated Process-Supervised Verifier, NeurIPS 2024 [paper]
  • Rank Analysis of Incomplete Block Designs: I. The Method of Paired Comparisons, Biometrika 1952 [paper]
  • Self-Generated Critiques Boost Reward Modeling for Language Models, arxiv.2411.16646 [paper]
  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • Improving LLM Reasoning through Scaling Inference Computation with Collaborative Verification, arXiv.2410.05318 [paper]
  • SimPO: Simple Preference Optimization with a Reference-Free Reward, NeurIPS 2024 [paper]
  • Advancing Process Verification for Large Language Models via Tree-Based Preference Learning EMNLP 2024 [paper]
  • RRHF: Rank Responses to Align Language Models with Human Feedback without tears, arxiv.2304.05302 [paper]
  • Generative Verifiers: Reward Modeling as Next-Token Prediction, arxiv.2408.15240 [paper]
  • Critique-out-Loud Reward Models, arXiv.2408.11791 [paper]
  • LLM Critics Help Catch Bugs in Mathematics: Towards a Better Mathematical Verifier with Natural Language Feedback, arXiv.2406.14024 [paper]
  • Generative Reward Models, arxiv.2410.12832 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • RL4F: Generating Natural Language Feedback with Reinforcement Learning for Repairing Model Outputs, ACL 2023 [paper]
  • Retroformer: Retrospective Large Language Agents with Policy Gradient Optimization, ICLR 2024 [paper]
  • Teaching Language Models to Critique via Reinforcement Learning, arxiv.2502.03492 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]

Optimizing Post-Processor

  • Learning to Check: Unleashing Potentials for Self-Correction in Large Language Models, arXiv.2402.13035 [paper]
  • Learning From Mistakes Makes LLM Better Reasoner, arXiv.2310.20689 [paper]
  • S3c-Math: Spontaneous Step-level Self-correction Makes Large Language Models Better Mathematical Reasoners, arXiv.2409.01524 [paper]
  • REFINER: Reasoning Feedback on Intermediate Representations, EACL 2024 [paper]
  • Embedding Self-Correction as an Inherent Ability in Large Language Models for Enhanced Mathematical Reasoning, arXiv.2410.10735 [paper]
  • Think Thrice Before You Act: Progressive Thought Refinement in Large Language Models, arXiv.2410.13413 [paper]
  • Generating Sequences by Learning to Self-Correct, ICLR 2023 [paper]
  • Small Language Models Need Strong Verifiers to Self-Correct Reasoning, ACL 2024 [paper]
  • Learning to Refine with Fine-Grained Natural Language Feedback, EMNLP 2024 [paper]
  • The ART of LLM Refinement: Ask, Refine, and Trust, NAACL 2024 [paper]
  • Meta-Reflection: A Feedback-Free Reflection Learning Framework, arXiv.2412.13781 [paper]
  • Training language models to follow instructions with human feedback, NeurIPS 2022 [paper]
  • RLEF: Grounding Code LLMs in Execution Feedback with Reinforcement Learning, arXiv.2410.02089 [paper]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]

🛸 Self-Evolution

self-evolution illustration

Theory

  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models, TMLR 2024 [paper]
  • The expectation-maximization algorithm, IEEE Signal Process. Mag. 1996 [paper]
  • Inference Scaling Laws: An Empirical Analysis of Compute-Optimal Inference for Problem-Solving with Language Models, arXiv.2408.00724 [paper]
  • Scaling laws for single-agent reinforcement learning, arxiv.2301.13442 [paper]
  • Scaling of Search and Learning: A Roadmap to Reproduce o1 from Reinforcement Learning Perspective, arxiv.2412.14135 [paper]
  • B-STaR: Monitoring and Balancing Exploration and Exploitation in Self-Taught Reasoners, arxiv.2412.17256 [paper]
  • Common 7B Language Models Already Possess Strong Math Capabilities, arxiv.2403.04706 [paper]

Self-Evolution Strategies

Independent Evolution

  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]
  • V-STaR: Training Verifiers for Self-Taught Reasoners, arxiv.2402.06457 [paper]
  • Self-Refine: Iterative Refinement with Self-Feedback, NeurIPS 2023 [paper]
  • Enabling Language Models to Implicitly Learn Self-Improvement, arxiv.2310.00898 [paper]

Collaborative Evolution

  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]

Adversarial Evolution

  • Generative Adversarial Nets, NeurIPS 2014 [paper]
  • Evolving Alignment via Asymmetric Self-Play, arxiv.2411.00062 [paper]
  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]

Self-Evolution Patterns

Only Reasoner

  • Reinforced Self-Training (ReST) for Language Modeling, arxiv.2308.08998 [paper]
  • Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems, arxiv.2412.09413 [paper]
  • STaR: Bootstrapping Reasoning With Reasoning, NeurIPS 2022 [paper]
  • AlphaMath Almost Zero: process Supervision without process, NeurIPS 2024 [paper]
  • Monte Carlo Tree Search Boosts Reasoning via Iterative Preference Learning, arxiv.2405.00451 [paper]
  • Self-Training with Direct Preference Optimization Improves Chain-of-Thought Reasoning, ACL 2024 [paper]
  • Towards Self-Improvement of LLMs via MCTS: Leveraging Stepwise Knowledge with Curriculum Preference Learning, arxiv.2410.06508 [paper]
  • Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models, TMLR 2024 [paper]
  • Iterative Reasoning Preference Optimization, NeurIPS 2024 [paper]
  • ReGenesis: LLMs can Grow into Reasoning Generalists via Self-Improvement, arxiv.2410.02108 [paper]
  • Large Language Models Can Self-Improve, EMNLP 2023 [paper]
  • Large Language Models Can Self-Improve in Long-context Reasoning, arxiv.2411.08147 [paper]
  • ReST meets ReAct: Self-Improvement for Multi-Step Reasoning LLM Agent, arxiv.2312.10003 [paper]
  • RAFT: Reward rAnked FineTuning for Generative Foundation Model Alignment, Trans. Mach. Learn. Res. 2023 [paper]
  • Trial and Error: Exploration-Based Trajectory Optimization for LLM Agents, arxiv.2403.02502 [paper]

Reasoner + Evaluator

  • Self-Rewarding Language Models, ICML 2024 [paper]
  • Self-Evolutionary Large Language Models through Uncertainty-Enhanced Preference Optimization, arxiv.2409.11212 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking, arxiv.2501.04519 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • AlphaMath Almost Zero: process Supervision without process, NeurIPS 2024 [paper]
  • ReST-MCTS*: LLM Self-Training via Process Reward Guided Tree Search, NeurIPS 2024 [paper]
  • Self-playing Adversarial Language Game Enhances LLM Reasoning, NeurIPS 2024 [paper]
  • Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models, ICML 2024 [paper]

Reasoner + Post-Processor

  • Re-ReST: Reflection-Reinforced Self-Training for Language Agents, EMNLP 2024 [paper]
  • Enabling Language Models to Implicitly Learn Self-Improvement, arxiv.2310.00898 [paper]

Reasoner + Task Creator

  • Evolving Alignment via Asymmetric Self-Play, arxiv.2411.00062 [paper]

Reasoner + Evaluator + Post-Processor

  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Advancing Language Model Reasoning through Reinforcement Learning and Inference Scaling, arxiv.2501.11651 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • RedStar: Does Scaling Long-CoT Data Unlock Better Slow-Reasoning Systems?, arxiv.2501.11284 [paper]

🚢 O1-like works

  • Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions arxiv.2411.14405 [paper]
  • O1 Replication Journey: A Strategic Progress Report - Part 1, arxiv.2410.18982 [paper]
  • O1 Replication Journey - Part 2: Surpassing O1-preview through Simple Distillation, Big Progress or Bitter Lesson?, arxiv.2411.16489 [paper]
  • Enhancing LLM Reasoning via Critique Models with Test-Time and Training-Time Supervision, arXiv.2411.16579 [paper]
  • Qwq: Reflect deeply on the boundaries of the unknown, [blog]
  • DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, arxiv.2501.12948 [paper]
  • Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems, arxiv.2412.09413 [paper]
  • rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep Thinking, arxiv.2501.04519 [paper]
  • o1-Coder: an o1 Replication for Coding, arxiv.2412.00154 [paper]
  • OpenR: An Open Source Framework for Advanced Reasoning with Large Language Models, arxiv.2410.09671 [paper]
  • Kimi k1.5: Scaling Reinforcement Learning with LLMs, arxiv.2501.12599 [paper]
  • Learning to reason with llms, [blog]

📝 Citation

If you find our work helpful, you can cite this paper as:

@Misc{ReasoningSelfEvolution,
    title={A Survey on Complex Reasoning of Large Language Models through the Lens of Self-Evolution},
    author={Tao He and Hao Li and Jingchang Chen and Runxuan Liu and Yixin Cao and Lizi Liao and Zihao Zheng and Zheng Chu and Jiafeng Liang and Ming Liu and Bing Qin and Ting Liu},
    year={2025},
    url={http://dx.doi.org/10.13140/RG.2.2.23943.30886}
}

Significant stargazers

Jiaxin Zhang

176 followers · starred Mar 2025