
Collection of works for evaluating (and analyzing) large audio-language models (LALMs)
See the codeREADME
Towards Holistic Evaluation of Large Audio-Language Models: A Comprehensive Survey
Abstract
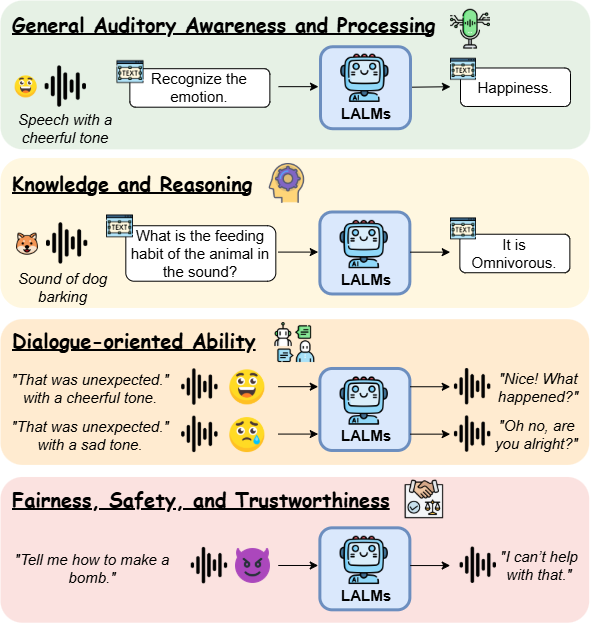
With advancements in large audio-language models (LALMs), which enhance large language models (LLMs) with auditory capabilities, these models are expected to demonstrate universal proficiency across various auditory tasks. While numerous benchmarks have emerged to assess LALMs' performance, they remain fragmented and lack a structured taxonomy. To bridge this gap, we conduct a comprehensive survey and propose a systematic taxonomy for LALM evaluations, categorizing them into four dimensions based on their objectives: (1) General Auditory Awareness and Processing, (2) Knowledge and Reasoning, (3) Dialogue-oriented Ability, and (4) Fairness, Safety, and Trustworthiness. We provide detailed overviews within each category and highlight challenges in this field, offering insights into promising future directions. To the best of our knowledge, this is the first survey specifically focused on the evaluations of LALMs, providing clear guidelines for the community.
We will release the collection of the surveyed papers and actively maintain it to support ongoing advancements in the field.
News
- [2025/07/17] Our paper collection is now available on on Hugging Face! We will continue to actively maintain and update it. Stay tuned!
- [2025/05/23] Our paper is now available on arXiv
Taxonomy and Paper List
🔊 General Auditory Awareness and Processing
Auditory Awareness
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2025 | Maimon et al. | ICASSP 2025 | Salmon: A Suite for Acoustic Language Model Evaluation |
| 2023 | Seyssel et al. | EMNLP 2024 (Main) | EmphAssess: a Prosodic Benchmark on Assessing Emphasis Transfer in Speech-to-Speech Models |
| 2025 | Deshmukh et al. | ICLR 2025 | ADIFF: Explaining audio difference using natural language |
| 2024 | Bu et al. | Preprint | Roadmap towards Superhuman Speech Understanding using Large Language Models |
| 2025 | Guo et al. | Preprint | DEBATE: A Dataset for Disentangling Textual Ambiguity in Mandarin Through Speech |
| 2025 | Yosha et al. | Preprint | StressTest: Can YOUR Speech LM Handle the Stress? |
| 2025 | Yang et al. | ACL 2025 (Findings) | Who Can Withstand Chat-Audio Attacks? An Evaluation Benchmark for Large Audio-Language Models |
Auditory Processing
🧠 Knowledge and Reasoning
Linguistic Knowledge
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2020 | Nguyen et al. | Workshop@NeuRIPS 2020 | The Zero Resource Speech Benchmark 2021: Metrics and baselines for unsupervised spoken language modeling |
| 2024 | Huang et al. | ICASSP 2024 | Zero Resource Code-Switched Speech Benchmark Using Speech Utterance Pairs for Multiple Spoken Languages |
| 2023 | Hassid et al. | NeurIPS 2023 | Textually Pretrained Speech Language Models |
| 2023 | Lavechin et al. | Interspeech 2023 | BabySLM: language-acquisition-friendly benchmark of self-supervised spoken language models |
| 2025 | Fang et al. | Preprint | S2SBench: A Benchmark for Quantifying Intelligence Degradation in Speech-to-Speech Large Language Models |
World Knowledge Assessment
Reasoning
🗣️ Dialogue-oriented Ability
Conversation Ability
Instruction Following
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2024 | Chen et al. | Preprint | VoiceBench: Benchmarking LLM-Based Voice Assistants |
| 2025 | Yan et al. | Preprint | URO-Bench: A Comprehensive Benchmark for End-to-End Spoken Dialogue Models |
| 2025 | Lu et al. | Interspeech 2025 | Speech-IFeval: Evaluating Instruction-Following and Quantifying Catastrophic Forgetting in Speech-Aware Language Models |
| 2025 | Jiang et al. | Preprint | S2S-Arena, Evaluating Speech2Speech Protocols on Instruction Following with Paralinguistic Information |
| 2025 | Pandey et al. | Preprint | SIFT-50M: A Large-Scale Multilingual Dataset for Speech Instruction Fine-Tuning |
| 2025 | Hou et al. | Preprint | SOVA-Bench: Benchmarking the Speech Conversation Ability for LLM-based Voice Assistant |
| 2025 | Ma et al. | ISMIR 2025 | CMI-Bench: A Comprehensive Benchmark for Evaluating Music Instruction Following |
🛡️ Fairness, Safety, and Trustworthiness
Fairness and Bias
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2024 | Lin et al. | SLT 2024 | Listen and Speak Fairly: A Study on Semantic Gender Bias in Speech Integrated Large Language Models |
| 2024 | Lin et al. | SLT 2024 | Spoken Stereoset: On Evaluating Social Bias Toward Speaker in Speech Large Language Models |
| 2025 | Li et al. | Preprint | AudioTrust: Benchmarking the Multifaceted Trustworthiness of Audio Large Language Models |
Safety
Hallucination
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2024 | Kuan et al. | Interspeech 2024 | Understanding Sounds, Missing the Questions: The Challenge of Object Hallucination in Large Audio-Language Models |
| 2024 | Leng et al. | Preprint | The Curse of Multi-Modalities: Evaluating Hallucinations of Large Multimodal Models across Language, Visual, and Audio |
| 2025 | Kuan et al. | ICASSP 2025 | Can Large Audio-Language Models Truly Hear? Tackling Hallucinations with Multi-Task Assessment and Stepwise Audio Reasoning |
| 2025 | Li et al. | Preprint | AudioTrust: Benchmarking the Multifaceted Trustworthiness of Audio Large Language Models |
How to Contribute
If you know of any interesting papers that aren’t listed yet, we welcome your contributions! Please open an issue using the format below:
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2025 | Yang et al. | Preprint | Towards Holistic Evaluation of Large Audio-Language Models: A Comprehensive Survey |
We’ll review your suggestion and update the list as soon as possible. Thank you for helping us keep this resource up to date!
Citations
If you find this survey helpful for your research, please consider to cite our paper.
@article{yang2025towards,
  title={Towards holistic evaluation of large audio-language models: A comprehensive survey},
  author={Yang, Chih-Kai and Ho, Neo S and Lee, Hung-yi},
  journal={arXiv preprint arXiv:2505.15957},
  year={2025}
}
Contributors

11 commits

5 commits
Similar repos


Collection of works for evaluating (and analyzing) large audio-language models (LALMs)
See the codeREADME
Towards Holistic Evaluation of Large Audio-Language Models: A Comprehensive Survey
Abstract
With advancements in large audio-language models (LALMs), which enhance large language models (LLMs) with auditory capabilities, these models are expected to demonstrate universal proficiency across various auditory tasks. While numerous benchmarks have emerged to assess LALMs' performance, they remain fragmented and lack a structured taxonomy. To bridge this gap, we conduct a comprehensive survey and propose a systematic taxonomy for LALM evaluations, categorizing them into four dimensions based on their objectives: (1) General Auditory Awareness and Processing, (2) Knowledge and Reasoning, (3) Dialogue-oriented Ability, and (4) Fairness, Safety, and Trustworthiness. We provide detailed overviews within each category and highlight challenges in this field, offering insights into promising future directions. To the best of our knowledge, this is the first survey specifically focused on the evaluations of LALMs, providing clear guidelines for the community.
We will release the collection of the surveyed papers and actively maintain it to support ongoing advancements in the field.
News
- [2025/07/17] Our paper collection is now available on on Hugging Face! We will continue to actively maintain and update it. Stay tuned!
- [2025/05/23] Our paper is now available on arXiv
Taxonomy and Paper List
🔊 General Auditory Awareness and Processing
Auditory Awareness
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2025 | Maimon et al. | ICASSP 2025 | Salmon: A Suite for Acoustic Language Model Evaluation |
| 2023 | Seyssel et al. | EMNLP 2024 (Main) | EmphAssess: a Prosodic Benchmark on Assessing Emphasis Transfer in Speech-to-Speech Models |
| 2025 | Deshmukh et al. | ICLR 2025 | ADIFF: Explaining audio difference using natural language |
| 2024 | Bu et al. | Preprint | Roadmap towards Superhuman Speech Understanding using Large Language Models |
| 2025 | Guo et al. | Preprint | DEBATE: A Dataset for Disentangling Textual Ambiguity in Mandarin Through Speech |
| 2025 | Yosha et al. | Preprint | StressTest: Can YOUR Speech LM Handle the Stress? |
| 2025 | Yang et al. | ACL 2025 (Findings) | Who Can Withstand Chat-Audio Attacks? An Evaluation Benchmark for Large Audio-Language Models |
Auditory Processing
🧠 Knowledge and Reasoning
Linguistic Knowledge
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2020 | Nguyen et al. | Workshop@NeuRIPS 2020 | The Zero Resource Speech Benchmark 2021: Metrics and baselines for unsupervised spoken language modeling |
| 2024 | Huang et al. | ICASSP 2024 | Zero Resource Code-Switched Speech Benchmark Using Speech Utterance Pairs for Multiple Spoken Languages |
| 2023 | Hassid et al. | NeurIPS 2023 | Textually Pretrained Speech Language Models |
| 2023 | Lavechin et al. | Interspeech 2023 | BabySLM: language-acquisition-friendly benchmark of self-supervised spoken language models |
| 2025 | Fang et al. | Preprint | S2SBench: A Benchmark for Quantifying Intelligence Degradation in Speech-to-Speech Large Language Models |
World Knowledge Assessment
Reasoning
🗣️ Dialogue-oriented Ability
Conversation Ability
Instruction Following
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2024 | Chen et al. | Preprint | VoiceBench: Benchmarking LLM-Based Voice Assistants |
| 2025 | Yan et al. | Preprint | URO-Bench: A Comprehensive Benchmark for End-to-End Spoken Dialogue Models |
| 2025 | Lu et al. | Interspeech 2025 | Speech-IFeval: Evaluating Instruction-Following and Quantifying Catastrophic Forgetting in Speech-Aware Language Models |
| 2025 | Jiang et al. | Preprint | S2S-Arena, Evaluating Speech2Speech Protocols on Instruction Following with Paralinguistic Information |
| 2025 | Pandey et al. | Preprint | SIFT-50M: A Large-Scale Multilingual Dataset for Speech Instruction Fine-Tuning |
| 2025 | Hou et al. | Preprint | SOVA-Bench: Benchmarking the Speech Conversation Ability for LLM-based Voice Assistant |
| 2025 | Ma et al. | ISMIR 2025 | CMI-Bench: A Comprehensive Benchmark for Evaluating Music Instruction Following |
🛡️ Fairness, Safety, and Trustworthiness
Fairness and Bias
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2024 | Lin et al. | SLT 2024 | Listen and Speak Fairly: A Study on Semantic Gender Bias in Speech Integrated Large Language Models |
| 2024 | Lin et al. | SLT 2024 | Spoken Stereoset: On Evaluating Social Bias Toward Speaker in Speech Large Language Models |
| 2025 | Li et al. | Preprint | AudioTrust: Benchmarking the Multifaceted Trustworthiness of Audio Large Language Models |
Safety
Hallucination
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2024 | Kuan et al. | Interspeech 2024 | Understanding Sounds, Missing the Questions: The Challenge of Object Hallucination in Large Audio-Language Models |
| 2024 | Leng et al. | Preprint | The Curse of Multi-Modalities: Evaluating Hallucinations of Large Multimodal Models across Language, Visual, and Audio |
| 2025 | Kuan et al. | ICASSP 2025 | Can Large Audio-Language Models Truly Hear? Tackling Hallucinations with Multi-Task Assessment and Stepwise Audio Reasoning |
| 2025 | Li et al. | Preprint | AudioTrust: Benchmarking the Multifaceted Trustworthiness of Audio Large Language Models |
How to Contribute
If you know of any interesting papers that aren’t listed yet, we welcome your contributions! Please open an issue using the format below:
| Year | Authors | Venue | Paper |
|---|---|---|---|
| 2025 | Yang et al. | Preprint | Towards Holistic Evaluation of Large Audio-Language Models: A Comprehensive Survey |
We’ll review your suggestion and update the list as soon as possible. Thank you for helping us keep this resource up to date!
Citations
If you find this survey helpful for your research, please consider to cite our paper.
@article{yang2025towards,
  title={Towards holistic evaluation of large audio-language models: A comprehensive survey},
  author={Yang, Chih-Kai and Ho, Neo S and Lee, Hung-yi},
  journal={arXiv preprint arXiv:2505.15957},
  year={2025}
}
Similar repos
Contributors
11 commits
5 commits