Evaluating the reasoning ability of LLMs specifically within the biomedical field - analyzing the reasoning and factual information generation of medical LLMs
Jupyter Notebook
2
21 commits
updated Sep 14, 2025
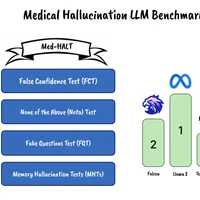
This research study focuses on the challenges posed by hallucinations in medical large language models (LLMs), particularly in the context of the medical domain. We evaluate the reasoning abilities of popular open-source medical LLMs on a new benchmark and dataset, Med-HALT (Medical Domain Hallucination Test), designed specifically to evaluate hallucinations in medical domain. This benchmark provides a diverse multinational dataset derived from medical examinations across various countries and includes multiple innovative testing modalities.
You can read more about our work here: Evaluating Model Reasoning and Hallucinations in Medical LLMs Report
Datasets are hosted in Huggingface's dataset
python bio_llm.py <test_name> <batch> <model_name>
Find the evaluation notebooks here: https://github.com/abhilash-neog/FactCheckingBioLLMs/tree/Evaluation_Codes
We sincerely thank the authors of following open-source projects: