
Official code for "Self-Distilled Agentic Reinforcement Learning"
See the codeREADME
Self-Distilled Agentic Reinforcement Learning
🔥 Overview
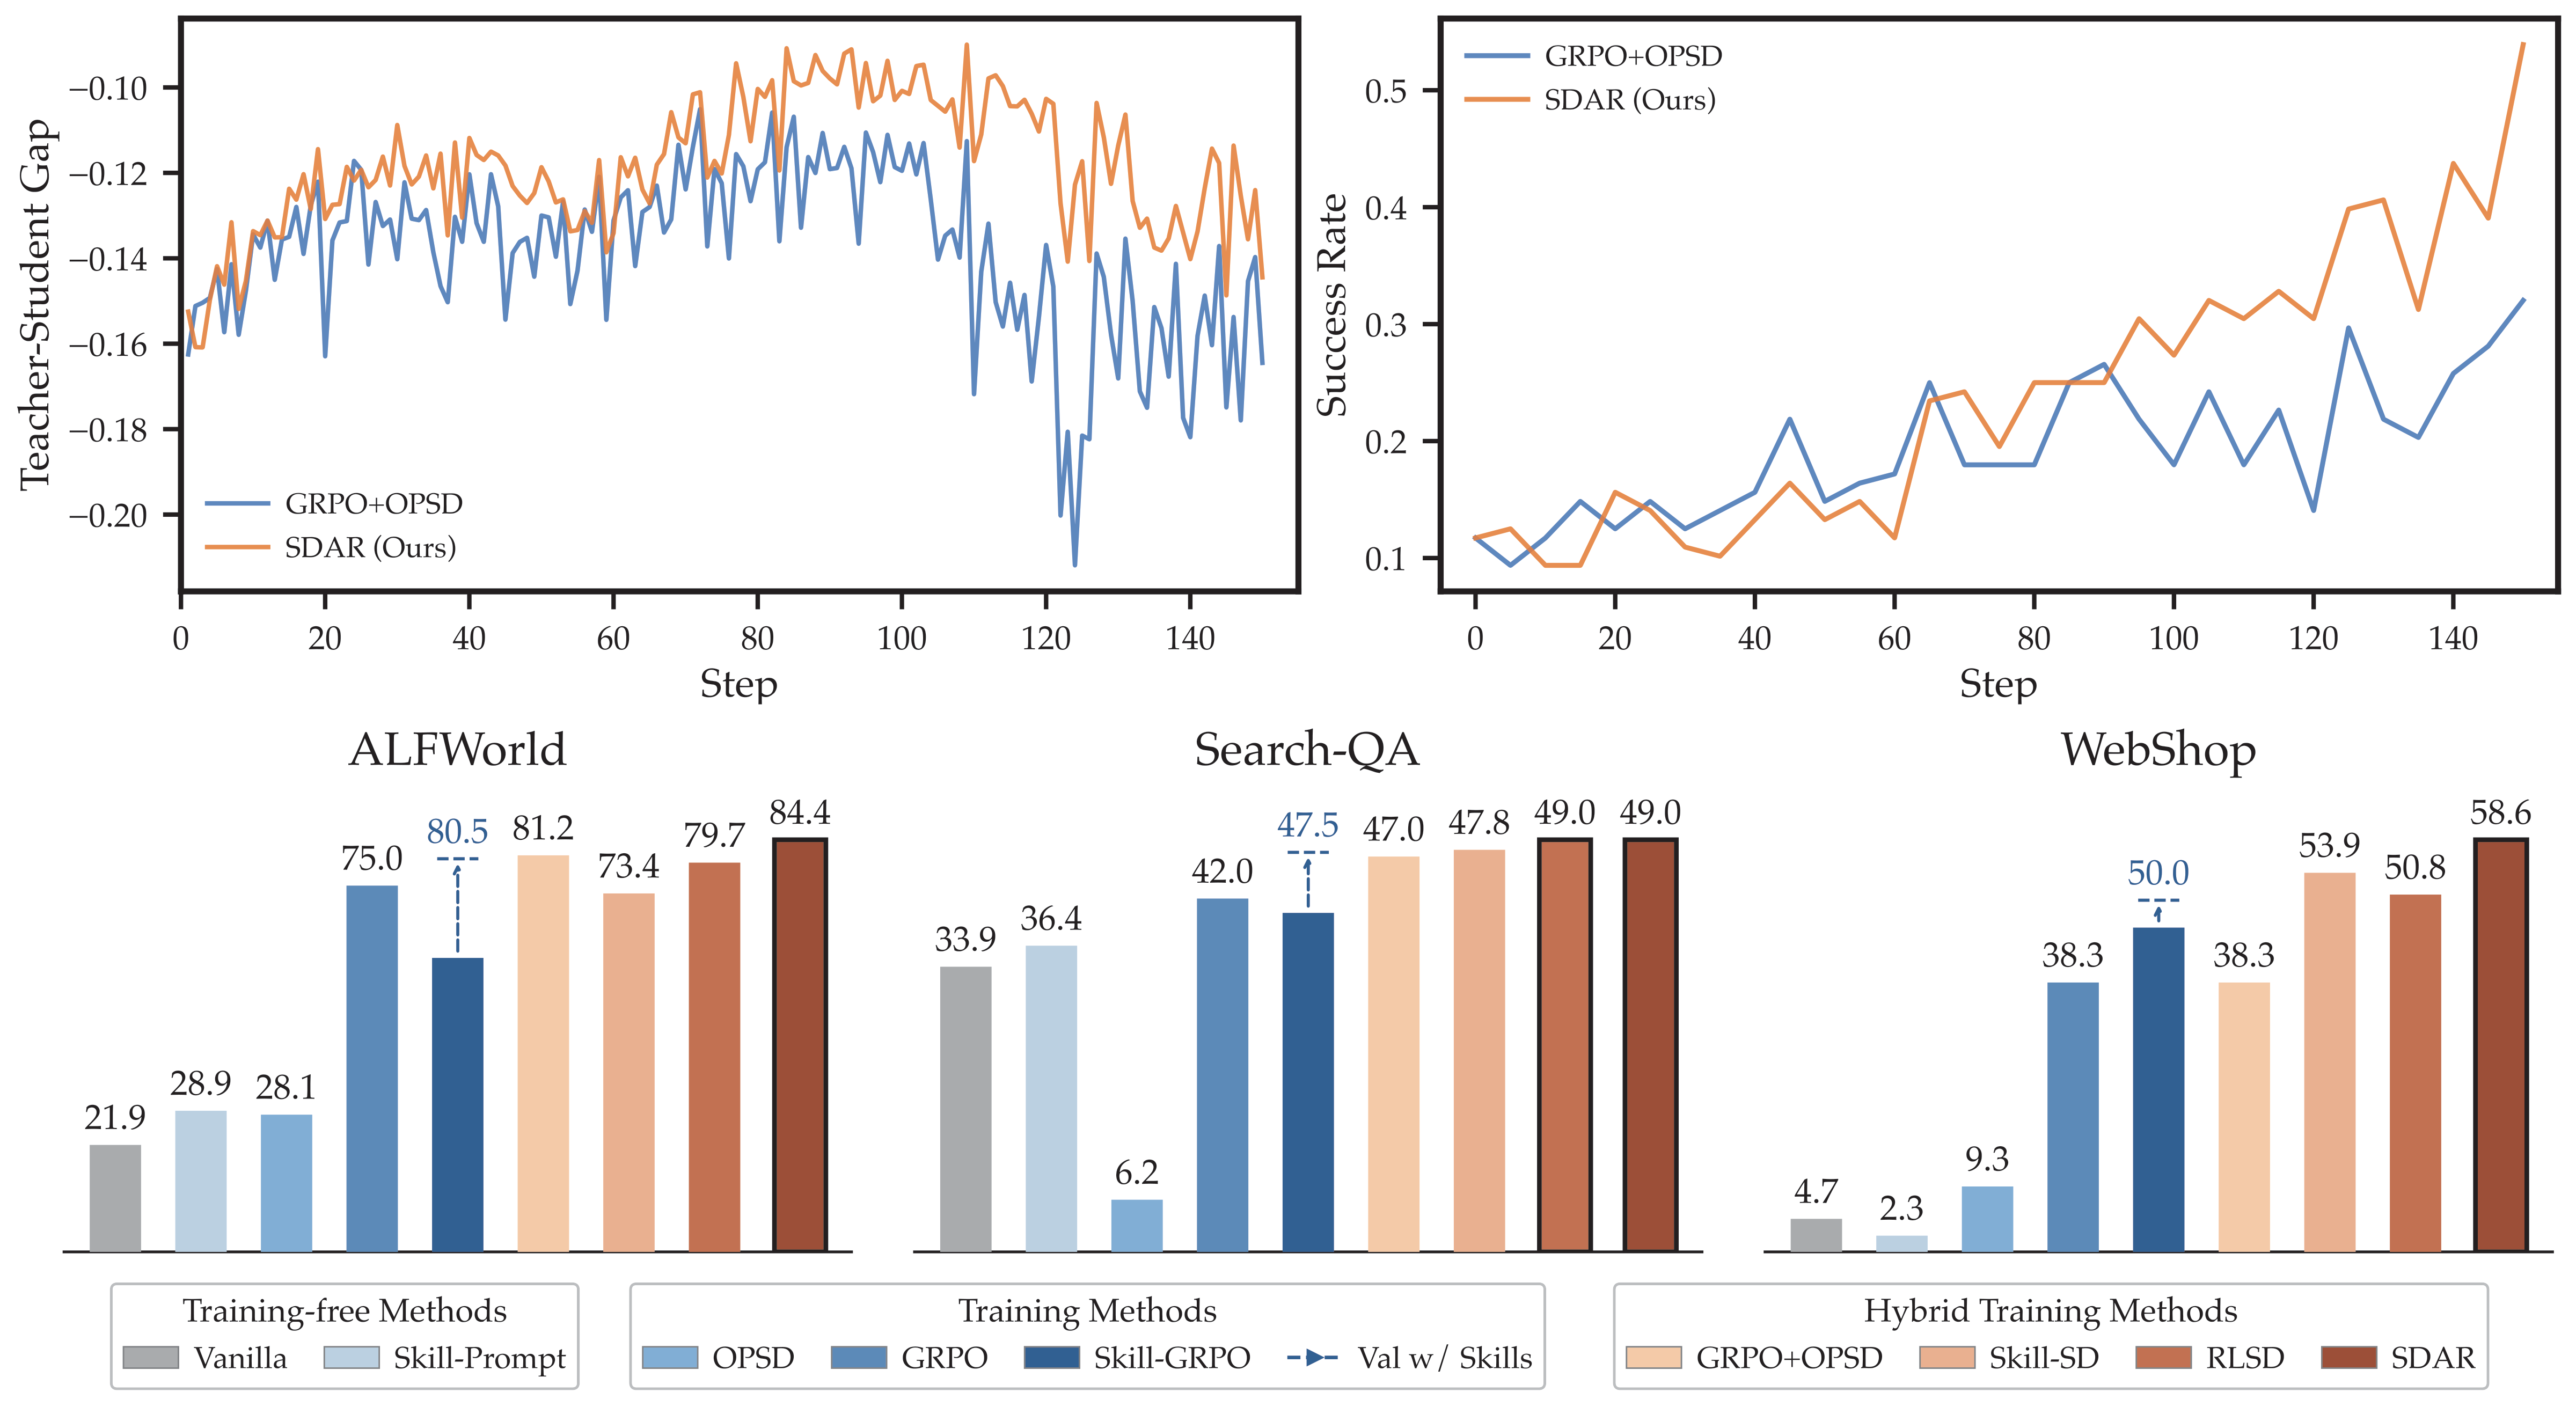
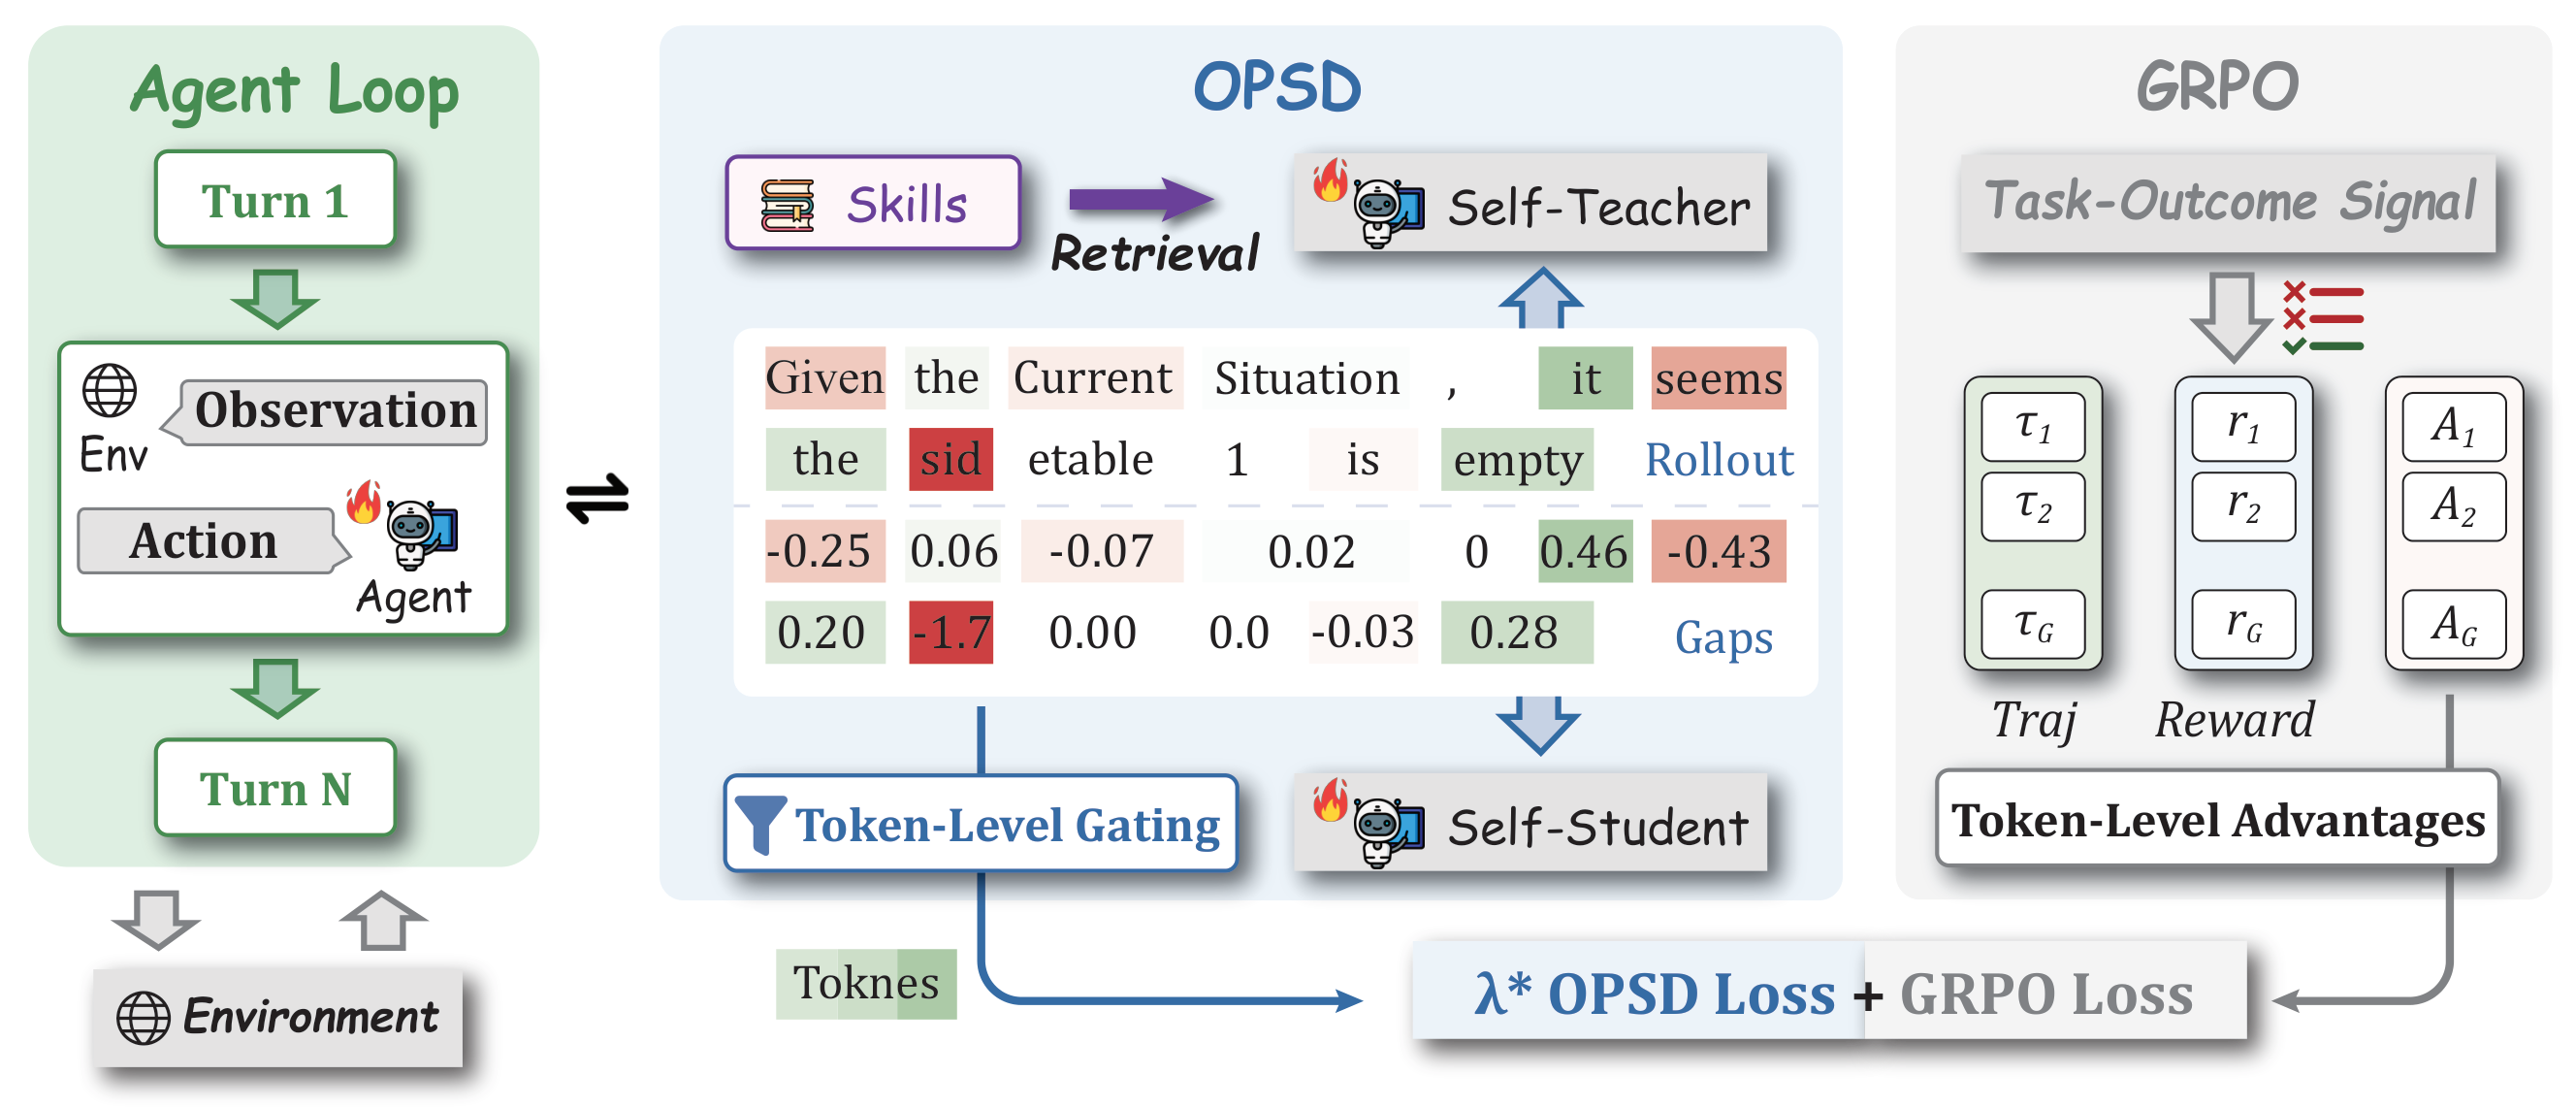
We introduce SDAR, a Self-Distilled Agentic Reinforcement learning method with gating mechanism.
🗞️ Awesome Work Powered by SDAR
SDAR is known as the first open-sourced framework that unifies Agentic RL with OP(S)D, providing a codebase that has supported the following works (listed in reverse time order and most recent first):
- RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning [Paper] [Code]
- TASPO: Reconciling Process Supervision with Outcome-Based Credit in Agentic Policy Optimization [Paper]
- AHEAD: Adaptive Hindsight with Environment-Augmented Distillation for Agentic RL [Paper] [Code]
- ICSD: Trust Is Not Enough: Influence Calibration for On-Policy Self-Distillation in Agentic RL [Paper] [Code]
- BCSD: Bidirectional Context Self-Distillation for Reinforcement Learning of Skill-Based LLM Agents [Paper]
- AgentOPSD: Recursive Self-Distillation for Agentic Reinforcement Learning [Paper] [Code]
- OCSD: Agentic Reinforcement Learning with Observation-Calibrated Self-Distillation [Paper] [Code]
- ADRS: Agentic Reinforcement Learning with Self-Distilled Reward Shaping [Paper] [Code]
- PCSD: Persistent Consistency for Self-Distillation in Agentic Reinforcement Learning [Paper]
- GRSD: Group-Reflective Self-Distillation for Agentic Reinforcement Learning [Paper] [Code]
- OVCSD: From Scoring to Acting: Outcome-Verified Comparative Self-Distillation for LLM Agents [Paper] [Code]
- MAPD: From Proprietary to Open-Source: Bridging the Distribution Gap via Multi-Agent Protocol Distillation in Agentic Search [Paper] [Code]
- SEED: Self-Evolving On-Policy Distillation for Agentic Reinforcement Learning [Paper] [Code]
- UCOB: Learning to Utilize and Evolve Agentic Skills via Credit-Aware On-Policy Bidirectional Self-Distillation [Paper] [Code]
- CRAFT: Counterfactual Credit Assignment from Free Sibling Rollouts for Self-Distilled Agentic Reinforcement Learning [Paper]
- ATOD: Annealed Turn-Aware On-Policy Distillation for Multi-Turn Agentic Tasks [Paper] [Code]
- OPID: On-Policy Skill Distillation for Agentic Reinforcement Learning [Paper] [Code]
- StepOPSD: Step-Aware Online Preference Distillation for Agent Reinforcement Learning [Paper]
📢 News
2026-9-18: We released RetireOPD, introducing Self-Retiring OPD for Agentic RL.2026-8-24: 🔥🔥 We released Agent-G2, introducing Gaussian hint guidance for Agentic RL.2026-8-6: 🔥 We released AgentOPSD, introducing recursive credit update for SDAR. Featured as 🤗 HF Daily Paper #1!2026-7-29: We released SkillRise, introducing cross-task skill evolution via agentic RL.2026-7-17: We released SEED, introducing self-evolving opd based on SDAR. Featured as 🤗 HF Daily Paper #3!2026-6-25: We released OPID, introducing skill evolving based on SDAR.2026-6-22: We fixed a bug (issue #35) about AlfWorld teacher skill retrieval problem. Please clone the repo again and have a try.2026-5-15: We released our paper and code for SDAR. Featured as 🤗 HF Daily Paper #2!2026-4: Previously, we released Skill0 and Skill1, about lifecycle of agent skills. They are both featured as 🤗 HF Daily Paper #2!
📖 Quick Feature Summary
| Feature Category | Supported Capabilities |
|---|---|
| Method | ✅ OP(S)D ✅ GRPO ✅ GRPO+OP(S)D ✅ RLSD ✅ Skill-SD ✅ SDAR (Ours) ✅ RetireOPD (Ours) |
| Environment | ✅ ALFWorld ✅ WebShop ✅ Search-QA |
| Model Support | ✅ Qwen3 ✅ Qwen2.5 |
📖 Results
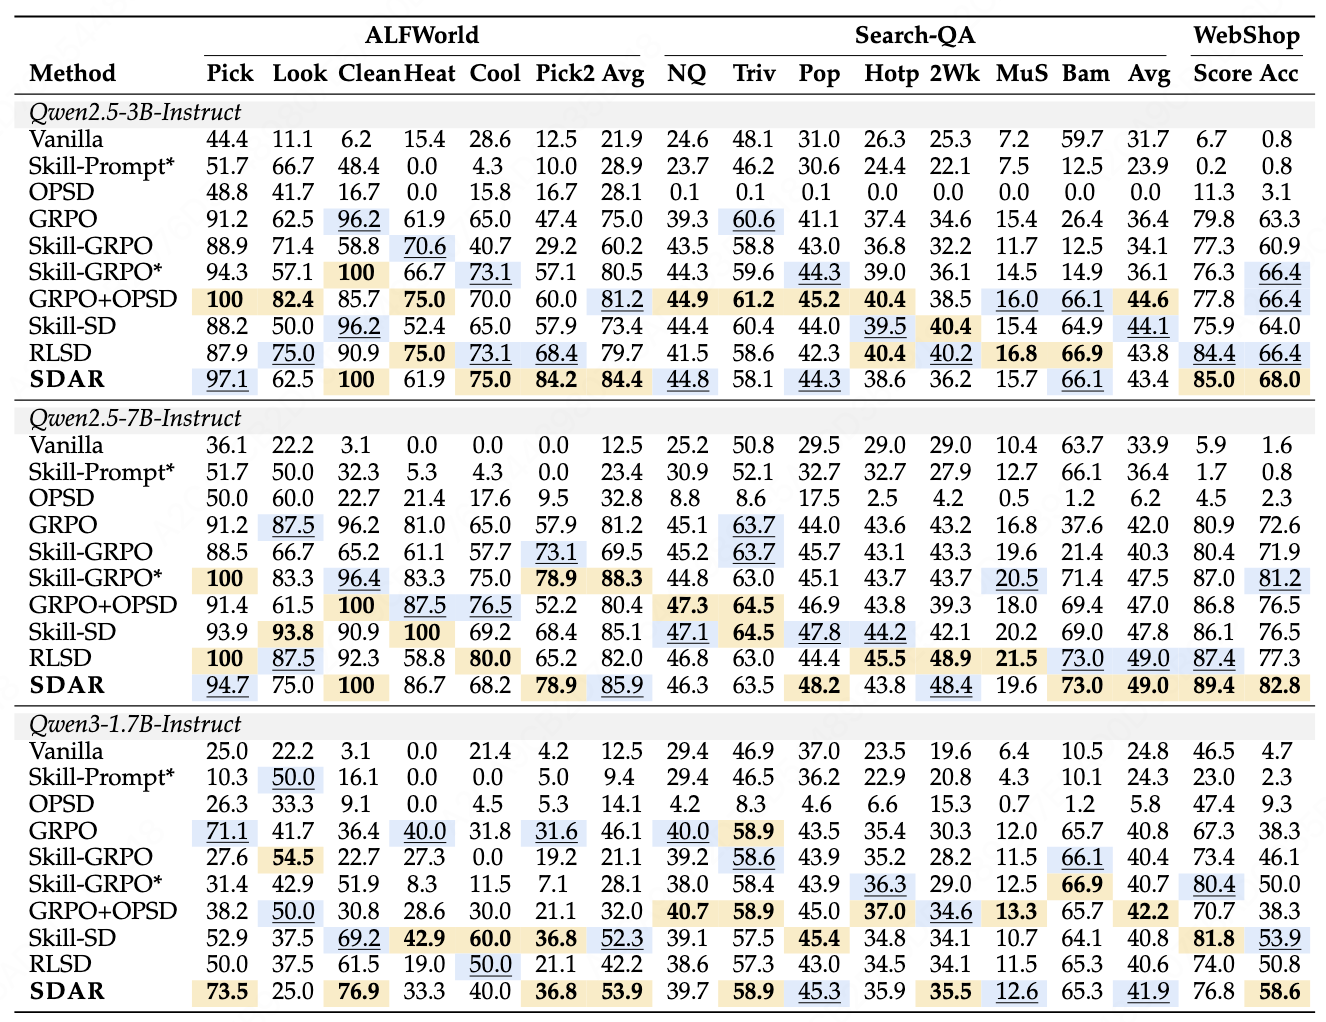
SDAR achieves substantial improvements over the standard RL baseline on ALFWorld, WebShop, and Search-QA.
| Algorithm | Task | Model | Success Rate |
|---|---|---|---|
| RetireOPD | ALFWorld | Qwen2.5-1.5B-Instruct | 89.8% |
| RetireOPD | ALFWorld | Qwen2.5-3B-Instruct | 93.8% |
| RetireOPD | ALFWorld | Qwen2.5-7B-Instruct | 95.3% |
| RetireOPD | WebShop | Qwen2.5-1.5B-Instruct | 75.8% |
| RetireOPD | WebShop | Qwen2.5-3B-Instruct | 77.3% |
| RetireOPD | WebShop | Qwen2.5-7B-Instruct | 84.4% |
🛠️ Installation
Python environment
conda create -n sdar python==3.12 -y
conda activate sdar

pip3 install vllm==0.11.0

pip3 install flash-attn==2.7.4.post1 --no-build-isolation --no-cache-dir
pip install -e .
Log in to Weights & Biases if you use WandB logging (scripts pass trainer.logger=['console','wandb'] in many cases):
export WANDB_API_KEY=your_key_here
Install Supported Environments
1. ALFWorld
Install with pip:
pip3 install gymnasium==0.29.1
pip3 install stable-baselines3==2.6.0
pip3 install alfworld
Download PDDL & Game files and pre-trained MaskRCNN detector (will be stored in ~/.cache/alfworld/):
alfworld-download -f
2. WebShop
WebShop requires Python <=3.10, so begin by creating a new environment:
conda create -n verl-webshop python==3.10 -y
conda activate verl-webshop
Install WebShop:
cd ./agent_system/environments/env_package/webshop/webshop
./setup.sh -d all
After WebShop is installed, return to the root directory and install the verl package:
cd repo_root/
pip3 install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
pip3 install flash-attn==2.7.4.post1 --no-build-isolation
pip3 install -e .
pip3 install vllm==0.8.2
# spacy 3.7.2 requires typer<0.10.0,>=0.3.0, but you have typer 0.15.2 which is incompatible.
# weasel 0.3.4 requires typer<0.10.0,>=0.3.0, but you have typer 0.15.2 which is incompatible.
The warnings can be safely ignored.
3. Search
cd ./agent_system/environments/env_package/search/third_party
pip install -e .
pip install gym==0.26.2
Prepare dataset (data will be saved at ~/data/searchR1_processed_direct):
cd repo_root/
python examples/data_preprocess/preprocess_search_r1_dataset.py
Since faiss-gpu is not available via pip, we setup a separate conda environment for the local retrieval server. Running this server will use around 6GB of GPU memory per GPU, so make sure to account for this in your training run configuration. Build Retriever environments:
# Create and activate the retriever environment with Python 3.10
conda create -n retriever python=3.10 -y
conda activate retriever

# Install PyTorch (with GPU support) and related libraries
conda install numpy==1.26.4 # needed to stop incompatible version of numpy from being installed via pip
pip install torch==2.6.0 torchvision==0.21.0 torchaudio==2.6.0 --index-url https://download.pytorch.org/whl/cu124

# Install other Python packages
pip install transformers datasets pyserini huggingface_hub

# Install the GPU version of faiss
conda install faiss-gpu==1.8.0 -c pytorch -c nvidia -y

# Install the API service framework
pip install uvicorn fastapi
Download the index:
conda activate retriever

local_dir=~/data/searchR1
python examples/search/searchr1_download.py --local_dir $local_dir
cat $local_dir/part_* > $local_dir/e5_Flat.index
gzip -d $local_dir/wiki-18.jsonl.gz
Start the local flat e5 retrieval server:
conda activate retriever

# redirect the output to a file to avoid cluttering the terminal
# we have observed outputting to the terminal causing spikes in server response times
bash examples/search/retriever/retrieval_launch.sh > retrieval_server.log
Training
1. SDAR
All scripts live under examples/ and assume the repo root as working directory. You can run e.g.:
bash examples/sdar_trainer/run_alfworld_3b.sh
bash examples/sdar_trainer/run_search_3b.sh
bash examples/sdar_trainer/run_webshop_3b.sh
2. RetireOPD
RetireOPD uses two-stage training (ALFWorld for example):
# Phase 1: Train the teacher

bash examples/skill_grpo_trainer/run_alfworld_3b.sh

# If Phase 1 produces a sharded FSDP checkpoint, merge the actor checkpoint into Hugging Face format before starting Phase 2.
# Record the teacher's validation score for the selected environment, which is the same metric as Phase 2 (`val/success_rate` by default).
# Phase 2: Train the RetireOPD

TEACHER_MODEL_PATH=/path/to/phase1_teacher_hf \
TEACHER_PERFORMANCE=0.50 \
bash examples/retireopd_trainer/run_alfworld_3b.sh

# Replace 0.50 with the teacher's validation success rate.
3. Other Baselines
Our reproduced codes for GRPO, Skill-GRPO, OP(S)D, GRPO+OP(S)D, Skill-SD, and RLSD are also provided in examples/.
Merge checkpoints
See scripts/model_merger.py for FSDP/Megatron merge examples using paths under ./checkpoints/....
⭐️ Citation
If you find this project useful, welcome to cite us.
@article{lu2026sdar,
  title={Self-distilled agentic reinforcement learning},
  author={Lu, Zhengxi and Yao, Zhiyuan and Han, Zhuowen and Wang, Zi-Han and Wu, Jinyang and Gu, Qi and Cai, Xunliang and Lu, Weiming and Xiao, Jun and Zhuang, Yueting and others},
  journal={arXiv preprint arXiv:2605.15155},
  year={2026}
}
@article{lu2026skill0,
  title={Skill0: In-context agentic reinforcement learning for skill internalization},
  author={Lu, Zhengxi and Yao, Zhiyuan and Wu, Jinyang and Han, Chengcheng and Gu, Qi and Cai, Xunliang and Lu, Weiming and Xiao, Jun and Zhuang, Yueting and Shen, Yongliang},
  journal={arXiv preprint arXiv:2604.02268},
  year={2026}
}
@article{wang2026agentopsd,
  title={AgentOPSD: Recursive Self-Distillation for Agentic Reinforcement Learning},
  author={Wang, Zi-Han and Lu, Zhengxi and Yao, Zhiyuan and Wu, Jinyang and Wu, Jie and Cai, Zhengzhou and Sun, Yueqing and Ye, Ziang and Hao, Linji and Gu, Qi and others},
  journal={arXiv preprint arXiv:2608.05987},
  year={2026}
}
@article{wu2026seed,
  title={SEED: Self-Evolving On-Policy Distillation for Agentic Reinforcement Learning},
  author={Wu, Jinyang and Yang, Shuo and Lu, Zhengxi and Zhang, Fan and Shen, Yuhao and Feng, Lang and Luo, Haoran and Lian, Zheng and Zhang, Shuai and Wen, Zhengqi and others},
  journal={arXiv preprint arXiv:2607.14777},
  year={2026}
}
@article{yang2026opid,
  title={Opid: On-policy skill distillation for agentic reinforcement learning},
  author={Yang, Shuo and Wu, Jinyang and Lu, Zhengxi and Shen, Yuhao and Zhang, Fan and Feng, Lang and Zhang, Shuai and Luo, Haoran and Lian, Zheng and Wen, Zhengqi and others},
  journal={arXiv preprint arXiv:2606.26790},
  year={2026}
}
@article{shi2026skill1,
  title={Skill1: Unified evolution of skill-augmented agents via reinforcement learning},
  author={Shi, Yaorui and Chen, Yuxin and Lu, Zhengxi and Miao, Yuchun and Liu, Shugui and Gu, Qi and Cai, Xunliang and Wang, Xiang and Zhang, An},
  journal={arXiv preprint arXiv:2605.06130},
  year={2026}
}
@article{yao2026skillrise,
  title={SkillRise: Agentic Reinforcement Learning for Cross-Task Skill Evolution},
  author={Yao, Zhiyuan and Chen, Yuxin and Lu, Zhengxi and Xu, Zishan and Sun, Yueqing and Guo, Yifu and Lu, Yuquan and Cai, Zhengzhou and Zhang, Kangning and Han, Zhuowen and others},
  journal={arXiv preprint arXiv:2607.26784},
  year={2026}
}
@misc{wang2026agentg2,
      title={Agent-G$^2$: Gaussian Guidance for Agentic Reinforcement Learning},
      author={Zixuan Wang and Yanrui Miao and Zhengxi Lu and Teng Pan and Yiwen Qiu and Hongxing Li and Peng Qiu and Ruiqing Zhang and Yongliang Shen},
      year={2026},
      eprint={2608.23318},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2608.23318},
}
@misc{yu2026retireopd,
      title={RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning},
      author={Yan Yu and Zhengxi Lu and Yizhou Liu and Yichen Pan and Aozhe Wang and Qipeng Chen and Hua Yang and Wenqi Zhang and Weiming Lu and Qianglong Chen and Yongliang Shen},
      year={2026},
      eprint={2609.20784},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2609.20784},
}
🤝 Acknowledgement
This project builds on verl-agent, veRL, ALFWorld, SkillRL, and Search-R1. We thank the authors of those projects.


Similar repos


Languages
Python
65.6%
Jupyter Notebook
20.2%
C
9.5%
Shell
2.3%
PDDL
1.3%
Official code for "Self-Distilled Agentic Reinforcement Learning"
See the codeREADME
Self-Distilled Agentic Reinforcement Learning
🔥 Overview
We introduce SDAR, a Self-Distilled Agentic Reinforcement learning method with gating mechanism.
🗞️ Awesome Work Powered by SDAR
SDAR is known as the first open-sourced framework that unifies Agentic RL with OP(S)D, providing a codebase that has supported the following works (listed in reverse time order and most recent first):
- RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning [Paper] [Code]
- TASPO: Reconciling Process Supervision with Outcome-Based Credit in Agentic Policy Optimization [Paper]
- AHEAD: Adaptive Hindsight with Environment-Augmented Distillation for Agentic RL [Paper] [Code]
- ICSD: Trust Is Not Enough: Influence Calibration for On-Policy Self-Distillation in Agentic RL [Paper] [Code]
- BCSD: Bidirectional Context Self-Distillation for Reinforcement Learning of Skill-Based LLM Agents [Paper]
- AgentOPSD: Recursive Self-Distillation for Agentic Reinforcement Learning [Paper] [Code]
- OCSD: Agentic Reinforcement Learning with Observation-Calibrated Self-Distillation [Paper] [Code]
- ADRS: Agentic Reinforcement Learning with Self-Distilled Reward Shaping [Paper] [Code]
- PCSD: Persistent Consistency for Self-Distillation in Agentic Reinforcement Learning [Paper]
- GRSD: Group-Reflective Self-Distillation for Agentic Reinforcement Learning [Paper] [Code]
- OVCSD: From Scoring to Acting: Outcome-Verified Comparative Self-Distillation for LLM Agents [Paper] [Code]
- MAPD: From Proprietary to Open-Source: Bridging the Distribution Gap via Multi-Agent Protocol Distillation in Agentic Search [Paper] [Code]
- SEED: Self-Evolving On-Policy Distillation for Agentic Reinforcement Learning [Paper] [Code]
- UCOB: Learning to Utilize and Evolve Agentic Skills via Credit-Aware On-Policy Bidirectional Self-Distillation [Paper] [Code]
- CRAFT: Counterfactual Credit Assignment from Free Sibling Rollouts for Self-Distilled Agentic Reinforcement Learning [Paper]
- ATOD: Annealed Turn-Aware On-Policy Distillation for Multi-Turn Agentic Tasks [Paper] [Code]
- OPID: On-Policy Skill Distillation for Agentic Reinforcement Learning [Paper] [Code]
- StepOPSD: Step-Aware Online Preference Distillation for Agent Reinforcement Learning [Paper]
📢 News
2026-9-18: We released RetireOPD, introducing Self-Retiring OPD for Agentic RL.2026-8-24: 🔥🔥 We released Agent-G2, introducing Gaussian hint guidance for Agentic RL.2026-8-6: 🔥 We released AgentOPSD, introducing recursive credit update for SDAR. Featured as 🤗 HF Daily Paper #1!2026-7-29: We released SkillRise, introducing cross-task skill evolution via agentic RL.2026-7-17: We released SEED, introducing self-evolving opd based on SDAR. Featured as 🤗 HF Daily Paper #3!2026-6-25: We released OPID, introducing skill evolving based on SDAR.2026-6-22: We fixed a bug (issue #35) about AlfWorld teacher skill retrieval problem. Please clone the repo again and have a try.2026-5-15: We released our paper and code for SDAR. Featured as 🤗 HF Daily Paper #2!2026-4: Previously, we released Skill0 and Skill1, about lifecycle of agent skills. They are both featured as 🤗 HF Daily Paper #2!
📖 Quick Feature Summary
| Feature Category | Supported Capabilities |
|---|---|
| Method | ✅ OP(S)D ✅ GRPO ✅ GRPO+OP(S)D ✅ RLSD ✅ Skill-SD ✅ SDAR (Ours) ✅ RetireOPD (Ours) |
| Environment | ✅ ALFWorld ✅ WebShop ✅ Search-QA |
| Model Support | ✅ Qwen3 ✅ Qwen2.5 |
📖 Results
SDAR achieves substantial improvements over the standard RL baseline on ALFWorld, WebShop, and Search-QA.
| Algorithm | Task | Model | Success Rate |
|---|---|---|---|
| RetireOPD | ALFWorld | Qwen2.5-1.5B-Instruct | 89.8% |
| RetireOPD | ALFWorld | Qwen2.5-3B-Instruct | 93.8% |
| RetireOPD | ALFWorld | Qwen2.5-7B-Instruct | 95.3% |
| RetireOPD | WebShop | Qwen2.5-1.5B-Instruct | 75.8% |
| RetireOPD | WebShop | Qwen2.5-3B-Instruct | 77.3% |
| RetireOPD | WebShop | Qwen2.5-7B-Instruct | 84.4% |
🛠️ Installation
Python environment
conda create -n sdar python==3.12 -y
conda activate sdar

pip3 install vllm==0.11.0

pip3 install flash-attn==2.7.4.post1 --no-build-isolation --no-cache-dir
pip install -e .
Log in to Weights & Biases if you use WandB logging (scripts pass trainer.logger=['console','wandb'] in many cases):
export WANDB_API_KEY=your_key_here
Install Supported Environments
1. ALFWorld
Install with pip:
pip3 install gymnasium==0.29.1
pip3 install stable-baselines3==2.6.0
pip3 install alfworld
Download PDDL & Game files and pre-trained MaskRCNN detector (will be stored in ~/.cache/alfworld/):
alfworld-download -f
2. WebShop
WebShop requires Python <=3.10, so begin by creating a new environment:
conda create -n verl-webshop python==3.10 -y
conda activate verl-webshop
Install WebShop:
cd ./agent_system/environments/env_package/webshop/webshop
./setup.sh -d all
After WebShop is installed, return to the root directory and install the verl package:
cd repo_root/
pip3 install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
pip3 install flash-attn==2.7.4.post1 --no-build-isolation
pip3 install -e .
pip3 install vllm==0.8.2
# spacy 3.7.2 requires typer<0.10.0,>=0.3.0, but you have typer 0.15.2 which is incompatible.
# weasel 0.3.4 requires typer<0.10.0,>=0.3.0, but you have typer 0.15.2 which is incompatible.
The warnings can be safely ignored.
3. Search
cd ./agent_system/environments/env_package/search/third_party
pip install -e .
pip install gym==0.26.2
Prepare dataset (data will be saved at ~/data/searchR1_processed_direct):
cd repo_root/
python examples/data_preprocess/preprocess_search_r1_dataset.py
Since faiss-gpu is not available via pip, we setup a separate conda environment for the local retrieval server. Running this server will use around 6GB of GPU memory per GPU, so make sure to account for this in your training run configuration. Build Retriever environments:
# Create and activate the retriever environment with Python 3.10
conda create -n retriever python=3.10 -y
conda activate retriever

# Install PyTorch (with GPU support) and related libraries
conda install numpy==1.26.4 # needed to stop incompatible version of numpy from being installed via pip
pip install torch==2.6.0 torchvision==0.21.0 torchaudio==2.6.0 --index-url https://download.pytorch.org/whl/cu124

# Install other Python packages
pip install transformers datasets pyserini huggingface_hub

# Install the GPU version of faiss
conda install faiss-gpu==1.8.0 -c pytorch -c nvidia -y

# Install the API service framework
pip install uvicorn fastapi
Download the index:
conda activate retriever

local_dir=~/data/searchR1
python examples/search/searchr1_download.py --local_dir $local_dir
cat $local_dir/part_* > $local_dir/e5_Flat.index
gzip -d $local_dir/wiki-18.jsonl.gz
Start the local flat e5 retrieval server:
conda activate retriever

# redirect the output to a file to avoid cluttering the terminal
# we have observed outputting to the terminal causing spikes in server response times
bash examples/search/retriever/retrieval_launch.sh > retrieval_server.log
Training
1. SDAR
All scripts live under examples/ and assume the repo root as working directory. You can run e.g.:
bash examples/sdar_trainer/run_alfworld_3b.sh
bash examples/sdar_trainer/run_search_3b.sh
bash examples/sdar_trainer/run_webshop_3b.sh
2. RetireOPD
RetireOPD uses two-stage training (ALFWorld for example):
# Phase 1: Train the teacher

bash examples/skill_grpo_trainer/run_alfworld_3b.sh

# If Phase 1 produces a sharded FSDP checkpoint, merge the actor checkpoint into Hugging Face format before starting Phase 2.
# Record the teacher's validation score for the selected environment, which is the same metric as Phase 2 (`val/success_rate` by default).
# Phase 2: Train the RetireOPD

TEACHER_MODEL_PATH=/path/to/phase1_teacher_hf \
TEACHER_PERFORMANCE=0.50 \
bash examples/retireopd_trainer/run_alfworld_3b.sh

# Replace 0.50 with the teacher's validation success rate.
3. Other Baselines
Our reproduced codes for GRPO, Skill-GRPO, OP(S)D, GRPO+OP(S)D, Skill-SD, and RLSD are also provided in examples/.
Merge checkpoints
See scripts/model_merger.py for FSDP/Megatron merge examples using paths under ./checkpoints/....
⭐️ Citation
If you find this project useful, welcome to cite us.
@article{lu2026sdar,
  title={Self-distilled agentic reinforcement learning},
  author={Lu, Zhengxi and Yao, Zhiyuan and Han, Zhuowen and Wang, Zi-Han and Wu, Jinyang and Gu, Qi and Cai, Xunliang and Lu, Weiming and Xiao, Jun and Zhuang, Yueting and others},
  journal={arXiv preprint arXiv:2605.15155},
  year={2026}
}
@article{lu2026skill0,
  title={Skill0: In-context agentic reinforcement learning for skill internalization},
  author={Lu, Zhengxi and Yao, Zhiyuan and Wu, Jinyang and Han, Chengcheng and Gu, Qi and Cai, Xunliang and Lu, Weiming and Xiao, Jun and Zhuang, Yueting and Shen, Yongliang},
  journal={arXiv preprint arXiv:2604.02268},
  year={2026}
}
@article{wang2026agentopsd,
  title={AgentOPSD: Recursive Self-Distillation for Agentic Reinforcement Learning},
  author={Wang, Zi-Han and Lu, Zhengxi and Yao, Zhiyuan and Wu, Jinyang and Wu, Jie and Cai, Zhengzhou and Sun, Yueqing and Ye, Ziang and Hao, Linji and Gu, Qi and others},
  journal={arXiv preprint arXiv:2608.05987},
  year={2026}
}
@article{wu2026seed,
  title={SEED: Self-Evolving On-Policy Distillation for Agentic Reinforcement Learning},
  author={Wu, Jinyang and Yang, Shuo and Lu, Zhengxi and Zhang, Fan and Shen, Yuhao and Feng, Lang and Luo, Haoran and Lian, Zheng and Zhang, Shuai and Wen, Zhengqi and others},
  journal={arXiv preprint arXiv:2607.14777},
  year={2026}
}
@article{yang2026opid,
  title={Opid: On-policy skill distillation for agentic reinforcement learning},
  author={Yang, Shuo and Wu, Jinyang and Lu, Zhengxi and Shen, Yuhao and Zhang, Fan and Feng, Lang and Zhang, Shuai and Luo, Haoran and Lian, Zheng and Wen, Zhengqi and others},
  journal={arXiv preprint arXiv:2606.26790},
  year={2026}
}
@article{shi2026skill1,
  title={Skill1: Unified evolution of skill-augmented agents via reinforcement learning},
  author={Shi, Yaorui and Chen, Yuxin and Lu, Zhengxi and Miao, Yuchun and Liu, Shugui and Gu, Qi and Cai, Xunliang and Wang, Xiang and Zhang, An},
  journal={arXiv preprint arXiv:2605.06130},
  year={2026}
}
@article{yao2026skillrise,
  title={SkillRise: Agentic Reinforcement Learning for Cross-Task Skill Evolution},
  author={Yao, Zhiyuan and Chen, Yuxin and Lu, Zhengxi and Xu, Zishan and Sun, Yueqing and Guo, Yifu and Lu, Yuquan and Cai, Zhengzhou and Zhang, Kangning and Han, Zhuowen and others},
  journal={arXiv preprint arXiv:2607.26784},
  year={2026}
}
@misc{wang2026agentg2,
      title={Agent-G$^2$: Gaussian Guidance for Agentic Reinforcement Learning},
      author={Zixuan Wang and Yanrui Miao and Zhengxi Lu and Teng Pan and Yiwen Qiu and Hongxing Li and Peng Qiu and Ruiqing Zhang and Yongliang Shen},
      year={2026},
      eprint={2608.23318},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2608.23318},
}
@misc{yu2026retireopd,
      title={RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning},
      author={Yan Yu and Zhengxi Lu and Yizhou Liu and Yichen Pan and Aozhe Wang and Qipeng Chen and Hua Yang and Wenqi Zhang and Weiming Lu and Qianglong Chen and Yongliang Shen},
      year={2026},
      eprint={2609.20784},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2609.20784},
}
🤝 Acknowledgement
This project builds on verl-agent, veRL, ALFWorld, SkillRL, and Search-R1. We thank the authors of those projects.
Similar repos
Languages
Python
65.6%
Jupyter Notebook
20.2%
C
9.5%
Shell
2.3%
PDDL
1.3%