Thinklab-SJTU/Awesome-LLM4AD

A curated list of awesome LLM/VLM/VLA/World Model for Autonomous Driving(LLM4AD) resources (continually updated)

1,896

175 commits

updated Sep 29, 2026

See the code

README

Awesome-LLM-for-Autonomous-Driving-Resources

AwesomeGitHub stars GitHub forks GitHub license

This is a collection of research papers about LLM-for-Autonomous-Driving(LLM4AD). The repository will be continuously updated to track the frontier of LLM4AD (Large Language Models for Autonomous Driving), which encompasses VLM4AD (Vision-Language Models for AD) and VLA4AD (Vision-Language-Action models for AD) as integral components of this unified paradigm. Maintained by SJTU-ReThinklab.

Welcome to follow and star! If you find any related materials could be helpful, feel free to contact us (yangzhenjie@sjtu.edu.cn or jiaxiaosong@sjtu.edu.cn) or make a PR.

Citation

Our survey paper is at https://arxiv.org/abs/2311.01043 which includes more detailed discussions and will be continuously updated.

If you find our repo is helpful, please consider cite it.

@misc{yang2023survey,
      title={LLM4Drive: A Survey of Large Language Models for Autonomous Driving}, 
      author={Zhenjie Yang and Xiaosong Jia and Hongyang Li and Junchi Yan},
      year={2023},
      eprint={2311.01043},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}

Table of Contents

Overview of LLM4AD

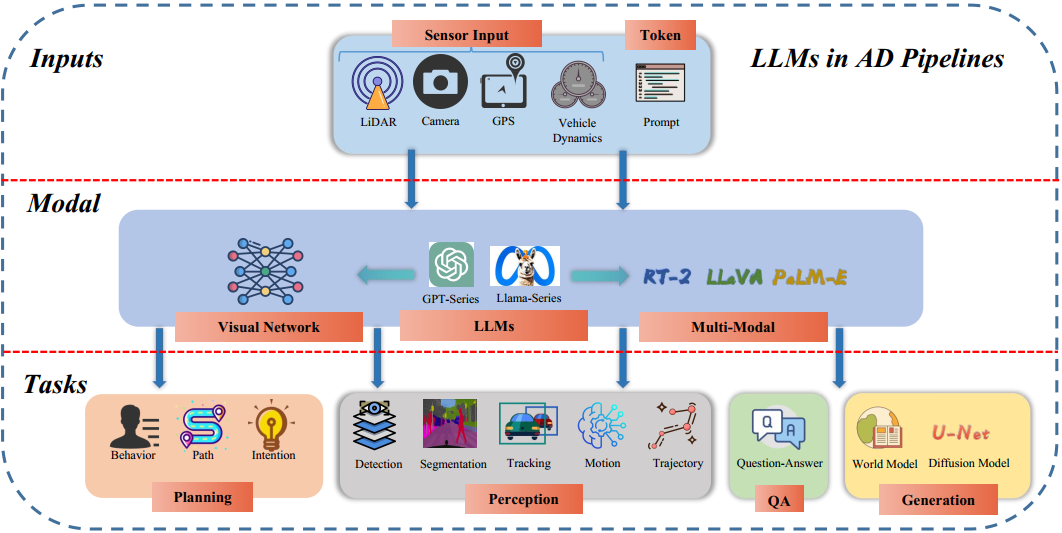
LLM-for-Autonomous-Driving (LLM4AD) refers to the application of Large Language Models(LLMs) in autonomous driving. We divide existing works based on the perspective of applying LLMs: planning, perception, question answering, and generation.

image info

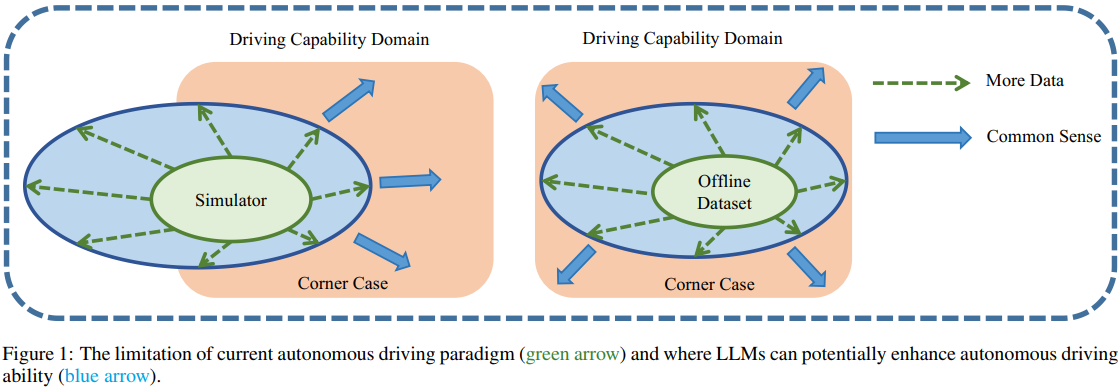
Motivation of LLM4AD

The orange circle represents the ideal level of driving competence, akin to that possessed by an experienced human driver. There are two main methods to acquire such proficiency: one, through learning-based techniques within simulated environments; and two, by learning from offline data through similar methodologies. It’s important to note that due to discrepancies between simulations and the real-world, these two domains are not fully the same, i.e. sim2real gap. Concurrently, offline data serves as a subset of real-world data since it’s collected directly from actual surroundings. However, it is difficult to fully cover the distribution as well due to the notorious long-tailed nature of autonomous driving tasks. The final goal of autonomous driving is to elevate driving abilities from a basic green stage to a more advanced blue level through extensive data collection and deep learning.

image info

Papers

Toggle
format:
- [title](paper link) [links]
  - author1, author2, and author3...
  - publisher
  - task
  - keyword
  - code or project page
  - datasets or environment or simulator
  - publish date
  - summary
  - metrics
  • RefineDrive: Reliable Failure-Guided Learning for Vision-Language-Action Driving

    • Zhe Sun, Ziyi Luo, Yehao Lu, Lei Zhou, Xi Li
    • Publish Date: 2026.09.28
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • RefineDrive is a failure-guided post-training framework for Vision-Language-Action autonomous driving that learns from self-generated failures through reliable diagnosis, minimum-correction target retrieval, and safety-aware reinforcement learning.
      • It derives structured, verifiable feedback on collisions and drivable-area violations from simulator states, retrieves hard-safety-constrained corrections from a clustered human trajectory bank, and uses correction SFT followed by GRPO with a Safety-Layered Reward.
      • On NAVSIM v1, RefineDrive improves a 4B base SFT policy from 87.7 to 91.7 PDMS and achieves 89.4 EPDMS on original NAVTEST scenes under NAVSIM v2 extended metrics without additional training.
  • CAR-VLA: Complexity-Aware and Risk-Adaptive Reasoning for Autonomous Driving

    • Xiaolei Chen, Zhuolin He, Yuxuan Liang, Xu Li, Haotian Chen, Shi Fan, Mengyang Zhao, Wenjuan Meng, Zisheng Chen, Zhihao Zhu, Zhounan Jin, Hengli Wang, Qingfan Wang, Jiamei Liang, Bin Li, Xiangyang Xue
    • Publish Date: 2026.09.28
    • Code: CAR-VLA
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • CAR-VLA is a unified driving VLA model that jointly considers scene complexity and dynamic risk to guide reasoning depth, urgency, and focus.
      • It maps four complexity-risk categories to three reasoning modes: Fast Intuition, Slow Thinking, and Reflex Response, with high-risk scenarios centered on the most critical hazard and immediate safe response.
      • Trained via progressive supervised learning linking scene assessment, reasoning-mode selection, and trajectory generation, followed by reasoning-augmented reinforcement learning, achieving competitive results on NAVSIM v1, NAVSIM v2, and Navhard.
  • AD-E2E-JEPA: A Joint-Embedding Predictive Architecture For End-to-End Autonomous Driving

    • Haoran Zhu, Wancong Zhang, Yann LeCun, Anna Choromanska
    • Publish Date: 2026.09.28
    • Code: AD-E2E-JEPA
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • Systematically evaluates existing action-conditioned JEPA world models (LeWM, DINO-WM, JEPA-WM) for end-to-end autonomous driving using a goal-conditioned zero-shot planning setting.
      • Proposes AD-E2E-JEPA with a SIGReg-regularized learnable projector that reduces planning patches by 16× and embedding dimension by 4×, achieving a 100× inference speedup while retaining planning performance.
      • Achieves 67.3/72.9 EPDMS on NAVSIMv2 in goal-conditioned zero-shot planning, and the self-supervised pretrained projector improves downstream imitation learning from 80.2 to 85.4 EPDMS.
  • MomWorld: Momentum-Aware Latent World Model for Long-Horizon Autonomous Driving

    • Ziying Song, Shengkai Zhang, Lei Yang, Haozhuang Chi, Yuchen Liu, Jiangtao Su, Lin Liu, Ziyang Liu, Chen Lv
    • Publish Date: 2026.09.27
    • Task: Planning
    • Datasets: NAVSIM, nuScenes, Bench2Drive
    • Summary:
      • MomWorld is a momentum-aware latent world model for long-horizon planning that extracts scene motion trends from historical-to-current observations and propagates latent momentum into future horizons.
      • It jointly predicts future configuration and momentum states with a learnable momentum persistence mechanism, scene-conditioned momentum updates, and a scene-adaptive reset gate to suppress stale momentum under abrupt changes.
      • It introduces MoFlow, a momentum-conditioned flow-matching module with horizon-aware residual fusion, improving long-horizon planning consistency and reducing the average collision rate by 12.2% relative to MomAD over a 6-second planning horizon on NAVSIM, nuScenes, and Bench2Drive.
  • VehDyn: A Driving World Model Benchmark for Vehicle Dynamics

    • Tianyi Wang, Wangsheng Du, Jiazhou Chen, Tianyi Zeng, Xiangyu Li, Jiseop Byeon, Yujin Wang, Yiming Xu, Yangyang Wang, Bingzhao Gao, Sikai Chen, Zhaomiao Guo, Junfeng Jiao, Christian Claudel, Alexandre Bayen
    • Publish Date: 2026.09.27
    • Task: Evaluation
    • Summary:
      • VehDyn is a driving world model benchmark for vehicle dynamics, built on a CARLA-CarSim co-simulation platform that couples photorealistic rendering with a validated multi-body dynamics model.
      • It contains 10,080 configurations from a full factorial design over vehicle types, tire-road friction coefficients, maneuvers, target speeds, scenes, and illuminations, each paired with synchronized position, velocity, and attitude sequences.
      • It introduces a hierarchical evaluation framework for trajectory alignment, kinematic consistency, and dynamic consistency, benchmarks 12 state-of-the-art video world models, and shows that trajectory metrics are nearly saturated while dynamic consistency remains challenging and visual quality weakly correlates with vehicle-dynamics fidelity.
  • RCVLA: 4D Radar-Grounded Semantic Reasoning and Trajectory Arbitration for Autonomous Driving

    • Lianqing Zheng, Xiaokai Bai, Yixuan Luo, Runwei Guan, Minghao Liu, Zhiqiang Wei, Hui-liang Shen, Xichan Zhu, Zhixiong Ma
    • Publish Date: 2026.09.26
    • Task: Planning
    • Summary:
      • RCVLA is a radar-camera vision-language-action framework with a radar-grounded semantic reasoning stage (RCVLA-Sem) and a trajectory arbitration stage (RCVLA-Phys).
      • It constructs Cap4DR with 86,016 radar-image-text samples for alignment pretraining and OmniHD-QA with 520,161 question-answer pairs for instruction tuning across scene description, key-object reasoning, occupancy understanding, and trajectory planning.
      • RCVLA-Sem improves CIDEr by 9.92 points and reduces key-object velocity error by 21.9% over OmniDrive; RCVLA-Phys reduces average L2 error from 0.348 to 0.259 m and average open-loop collision rate from 0.576% to 0.175%.
  • From Scene Graphs to Answers: Selective Neuro-Symbolic Reasoning for Autonomous Driving

    • Yiyao Wang, Pei Liu, Fangzhou Liu, Jun Ma
    • Publish Date: 2026.09.26
    • Task: VQA
    • Datasets: NuScenes-QA, nuScenes
    • Summary:
      • Introduces a query-adaptive neuro-symbolic reasoning framework for autonomous-driving question answering, with a hierarchical Spatiotemporal Scene Graph (STSG) that separates persistent object identities from frame-specific states and represents spatial relations and temporal transitions as explicit directed structures.
      • Uses a symbolic executor to resolve queries through exact graph operations and invokes an LLM only when symbolic execution abstains, with query-conditioned graph retrieval and evidence filtering preserving relation direction, temporal locality, and object semantics.
      • Achieves 80.63% overall accuracy on 5,916 NuScenes-QA questions under oracle perception, improving over the LLM-only configuration by 5.48 points with GPT-5.4-mini and 6.64 points with DeepSeek-V4-Flash, with largest gains on counting questions.
  • OneFixer: High-Quality and Consistent One-Step Autoregressive 3DGS Refinement for Driving Scenes

    • Boseong Jeon, Junhyeop Lee, Juhan Cha, Hayoung Kim
    • Publish Date: 2026.09.26
    • Project Page: OneFixer
    • Task: Perception
    • Datasets: Waymo
    • Summary:
      • OneFixer is a one-step autoregressive video-diffusion fixer for 3D Gaussian Splatting in driving scenes, trained in a single task-specific adaptation stage.
      • It uses a deployment-matched shared rollout where one-step predictions serve as causal context for flow matching while receiving direct pixel-space perceptual supervision, jointly learning fidelity and autoregressive robustness.
      • It exploits lane geometry and dynamic-agent states to improve geometric fidelity, achieving the lowest FVD, LPIPS, and DISTS at one step on Waymo and proprietary driving scenes, and reducing collision rate by one third in closed-loop simulation.
  • CausalDriveBench: Evaluating Causal Reasoning in Vision-Language-Action Models for Autonomous Driving

    • Narendiran Chembu, Navvrat Rao, Shreedhar Shreeshail Kodate, Gayatri Srujana Banda, Arko Sarkar, Abhinav Khanna, Rajarshee Das, Umesh Kanala, Siddarth Khandelwal, Kumar Aman, Aish Dubey, Kaustubh Beedkar, Arjun Jain
    • Publish Date: 2026.09.26
    • Task: Reasoning
    • Datasets: nuScenes
    • Summary:
      • CausalDriveBench is an evaluation framework grounded in Pearl's Causal Hierarchy that tests causal reasoning in driving-specific VLAs through structured visual question answering and alternative-trajectory prediction.
      • It constructs causal scene graphs over nuScenes to distinguish causally active, dormant, and distractor entities, covering all four rungs of PCH and containing 7,285 verified causal QA pairs and 1,000 counterfactual trajectories.
      • Evaluating 10 driving-specific VLAs and 3 general-purpose VLMs shows that causal QA accuracy remains limited, driving fine-tuning incurs variable costs on causal QA, and causal QA and trajectory accuracy are statistically uncorrelated across models.
  • DriveHierarchy: A Benchmark for Diagnosing VLM Driving Capabilities from Open-Loop Understanding to Closed-Loop Execution

    • Chengkai Xu, Jiaqi Liu, Yicheng Guo, Peng Hang, Jian Sun
    • Publish Date: 2026.09.25
    • Code: DriveHierarchy
    • Task: Evaluation
    • Summary:
      • DriveHierarchy is a hierarchical benchmark that organizes VLM-based autonomous driving into four ranks: perceptual grounding, contextual memory, mental reasoning, and closed-loop execution.
      • It integrates multiple open-source autonomous-driving datasets into a unified open-loop benchmark with 76,798 question-answer pairs over 84,279 frames, and develops a closed-loop simulation platform with 100 interactive scenarios.
      • Experiments on 15 VLMs show that DriveHierarchy captures structured non-redundant capability variation, relates open-loop understanding to closed-loop driving, and provides a practical basis for diagnosis and benchmark-guided optimization.
  • Evaluation Is All You Need for Multi-Modal Autonomous Driving

    • Zeyu He, Shiqi Liu, Ke Chen, Yun Yan, Jinzi Wu, Dianqiao Lei, Sirui Wang, ShuRui Peng, Tao Chen, Zhuo Huang, Yu Wu, Yadong Shao, Zhichao Li, Ke Sun, Yang Guan, Keqiang Li, Shengbo Eben Li
    • Publish Date: 2026.09.25
    • Task: Evaluation
    • Datasets: NAVSIM
    • Summary:
      • iDriveVLA is a multi-modal planning framework that improves the candidate trajectory space while enabling reliable and context-aware trajectory evaluation.
      • It introduces a unified trajectory evaluator with a Safety-aware Scorer for quality and risk estimation and a VLM-guided Modulator for scene-adaptive criterion weighting.
      • An oracle-aligned progressive training strategy combines candidate imitation pretraining, candidate space refinement, and semantic ranking alignment, achieving 94.95 PDMS on NAVSIM v1 and surpassing human-expert reference.
  • WALT: Learning World-Model-Aligned Latent Trajectories for Autonomous Driving

    • Mingkai Jia, Jiaxin Guo, Zhijian Shu, Jiawei Xu, Mingxiao Li, Jintao Cheng, Ping Tan, Wei Yin
    • Publish Date: 2026.09.24
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • WALT learns a compact generative trajectory latent space by transferring information from a frozen pretrained driving world model, aligning raw waypoints with action-relevant semantics without modifying the world model.
      • It uses a dual-branch trajectory autoencoder and systematically studies JEPA-based latent learning and REPA-style feature alignment for trajectory-only representation learning.
      • On NAVSIM, WALT improves PDMS from 89.4 to 89.8 on NAVSIMv1 and EPDMS from 87.3 to 87.9 on NAVSIMv2 while reducing trajectory planner FLOPs by 30.5%.
  • Sim-to-Real Aware End-to-End Learning Environment for Micromobility

    • Shouma Amano, Takuya Azumi
    • Publish Date: 2026.09.24
    • Task: End-to-End
    • Summary:
      • Proposes a sim-to-real-aware, vehicle-specific end-to-end learning environment for the WHILL Model CR on AWSIM and ROS 2.
      • Optimizes physical parameters via Bayesian optimization using real-world data to reduce the sim-to-real gap and trajectory errors across various driving scenarios.
      • Introduces a synchronized architecture for stable training of world model-based agents, with a DreamerV3 policy achieving obstacle avoidance and direct sim-to-real transfer to the physical vehicle without fine-tuning.
  • Less Language, More Latents: Annotation-Efficient VLAs for Driving

    • Alexey Zakharov, Kemal Oksuz, Puneet K. Dokania
    • Publish Date: 2026.09.23
    • Task: End-to-End
    • Datasets: Bench2Drive
    • Summary:
      • Introduces Latent Action Driving Annotations (LADA), a three-stage pipeline that transforms abundant unlabelled observation-trajectory pairs into training data for language-conditioned control.
      • Uses a latent action model with a vector-quantised bottleneck to build a compact codebook of high-level vehicle intents, and trains a vision-language translator on a small language-annotated subset.
      • Trains a driving VLA on observation-latent-action pairs over the full unlabelled corpus, achieving 87.98 Driving Score and 70.46% Success Rate on Bench2Drive with fewer than 5% language annotations.
  • ForeDrive: Foresight-Guided End-to-End Autonomous Driving with a Planning-Relevant Latent World Model

    • Sinuo Wang, Zichong Gu, Yuhan Huang, Wenxin Wen, Xun Yang, Yiqing Zhang, Xingyu Zhang, Ningyu Che, Jie Ling, Qiankun Yu, Wei Liu, Jing Xu, Xinggang Wang
    • Publish Date: 2026.09.22
    • Task: End-to-End
    • Datasets: NAVSIM
    • Summary:
      • ForeDrive learns a planning-relevant latent future representation with a JEPA-style world model and couples it asymmetrically to a Diffusion Transformer (DiT) planner, so that predicted futures act as direct conditioning signals for trajectory generation rather than mere pretraining or auxiliary supervision.
      • The framework uses gated visual fusion, future-status injection, and Trajectory-Adaptive Bias (TAB) to inject future latents as guidance without overriding the current observation, addressing varying future reliability across horizons and the misalignment between BEV trajectories and image tokens.
      • Trained with pure imitation learning and using only the current front-view image as visual input at inference, ForeDrive attains 89.9 PDMS on NAVSIM v1 and 90.0 one-stage EPDMS on NAVSIM v2, without reinforcement learning or an external trajectory scorer.
  • Sometimes You Gotta Run Before You Can Walk: Run-then-Walk Scheduling Strategy for VLM Autonomous Driving

    • Yuqi Ye, Shangkun Sun, Junhong Lin, Jiayi Zhao, Changhao Peng, Wei Zheng, Guoqing Liu, Tiesong Zhao, Wei Gao
    • Publish Date: 2026.09.22
    • Task: Planning
    • Datasets: NAVSIM, nuScenes
    • Summary:
      • Run-then-Walk is a simple yet effective two-stage reward scheduling strategy for GRPO that explicitly separates progress discovery from safety repair, achieving both better performance and faster convergence.
      • The Run phase focuses on progress to escape conservative bias and discover high-progress modes, while the subsequent Walk phase introduces endpoint and safety strategies to repair unsafe behaviors, overcoming the conservatism of Walk-first methods and the unsafe progress-seeking of joint optimization.
      • Validated on NAVSIMv1, NAVSIMv2, Navhard, and nuScenes with various VLM-based planners, demonstrating improved driving performance while requiring 40--50% fewer RL training epochs than baselines.
  • Relationally Grounded Latent World Models for Autonomous Driving

    • Fabian Schmidt, Markus Enzweiler, Abhinav Valada
    • Publish Date: 2026.09.21
    • Task: Prediction
    • Datasets: nuScenes
    • Summary:
      • Investigates whether traffic scene graphs can serve as privileged semantic supervision for latent world representations in autonomous driving.
      • Constructs actor-centric scene graphs from nuScenes 3D annotations, encodes their serialized relational structure with a frozen text embedding model, and aligns visual latent representations with this semantic target during training.
      • Removes the supervision branch at inference and, on nuScenes, reduces average trajectory L2 error from 0.661 to 0.622 and collision rate from 0.456 to 0.217, outperforming an unstructured caption-style semantic target.
  • PRIME: Perception Feedback with Situational Memory Embeddings in VLA Models

    • Erik Deinzer, Naya Baslan, Luca Paparusso, Narunas Vaskevicius, Peter Knott, Luigi Palmieri
    • Publish Date: 2026.09.18
    • Task: End-to-End
    • Datasets: Bench2Drive, Think2Drive
    • Summary:
      • PRIME introduces a learned feedback mechanism that conditions VLA perceptual queries on a novel Situational Memory, enabling intent-driven perceptual attention at minimal computational cost.
      • It aggregates latent representations of past perception, reasoning, navigation goals, and predicted behaviors across an L-step window via cross-attention, adding at most 29.7M parameters (0.41% of the 7.3B-parameter base model).
      • On Bench2Drive, PRIME achieves a state-of-the-art Driving Score of 82.47 (+4.73 over ORION) and a Success Rate of 60.00% (+5.38 pp), the highest reported among published VLAs trained on Think2Drive demonstrations.
  • ZYT-World: A Real-Time Controllable World Model for Closed-Loop Autonomous-Driving Simulation

    • Boni Hu, Xiong Wei, Haoming Huang, Yong Huang, Chenbo Wang, Yi Yang, Jiancheng Wang, Ruicheng Zhu, Zhimin Yang, Guanglai Liu, Qiaowan Jin, Dongzhuo Wang, Haiwei Kuang, Jiajun Fan, Yue Wu, Jiaxin Wei, Hao Sun, Feihong Yan, Yuyao Zhou, Wei Bi, Kaixuan Wang, Zichao Guo, Xiaozhi Chen
    • Publish Date: 2026.09.18
    • Task: Generation
    • Summary:
      • ZYT-World is a real-time controllable world model that natively generates four fisheye views with field of view > 180° and three pinhole views for closed-loop autonomous-driving simulation.
      • It combines projection-specific Plücker adapters, ego-motion adaptive layer normalization, and a lightweight pixel-aligned layout to control global motion and instance-level traffic participants and signals.
      • A distillation pipeline converts a 40-step bidirectional teacher into a one-step per-latent streaming generator, while TinyVAE, W8A8 quantization, and RigCritic enable over 90% PSNR/SSIM retention and 107.7× faster generation.
  • Astronex-World 1.0: Real-Time Interactive World Model Foundation

    • Xin Zhou, Cong Miao
    • Publish Date: 2026.09.17
    • Task: Prediction
    • Summary:
      • Astronex-World 1.0 is an open controllable video world-model foundation that predicts future visual states from text prompts or initial observations under frame-aligned camera trajectories, continuous actions, and an embodiment identifier, and accepts text events inserted at specified rollout positions.
      • The family includes a bidirectional full-context generation model and a causal model with block-causal attention and cross-block KV caching for persistent generation, both built on the Wan2.2-TI2V-5B prior; PRoPE injects camera intrinsics/extrinsics while a 64-dimensional action stream modulates every Transformer layer.
      • A five-stage training path develops bidirectional camera and action control, converts the backbone to block-causal generation, distills a few-step student, restores mixed-domain dynamics, and applies asymmetric DMD/DMD2 distribution matching; the causal model generates 832x480 video at 24 fps and streams in real time on one NVIDIA L20, scoring 73.5 on WBench Navi and 70.0 on WBench Full.
  • REARL: A Closed-loop Autonomous Driving Simulation Enhancement Framework with Real Traffic Data and Large Language Models

    • Xiaojun Bi, Jun Jiang, Yiwen Sun, Quanyi Ou, Yizhi Ma, Ke Cheng, Mingjie Bi, Yexin Li, Bowen Du
    • Publish Date: 2026.09.17
    • Task: Planning
    • Datasets: HighD
    • Summary:
      • REARL is a closed-loop simulation enhancement framework that integrates real traffic data with LLMs, using clustered real traffic data as representative scenarios and a timed sliding-window detector to monitor speed distribution and mean spacing discrepancies.
      • When a metric exceeds a threshold, the LLM adjusts vehicle decision-making; otherwise the existing controller is retained, and the LLM also selects matching real vehicle actions from a traffic snapshot to modulate simulated vehicles.
      • In a controlled HighD highway setting, REARL reduces the Hellinger distance for speed distributions to 0.3067 and the MAPE for mean spacing to 0.8371, while achieving a time headway of 22.8575 and a lane change rate of 0.0708.
  • FIVE-VLA: Fast and EffectIVE Autonomous Driving with Recurrent Action Memory

    • Kemal Oksuz, Alexandru Buburuzan, Yuhan Yao, Puneet K. Dokania
    • Publisher: Five AI, University of Oxford
    • Publish Date: 2026.09.16
    • Task: Planning
    • Datasets: Bench2Drive, NVIDIA Physical AI AV Dataset
    • Summary:
      • FIVE-VLA introduces an efficient vision encoder that processes 448×896 images with only 98 tokens (over 5× fewer than existing approaches) and bypasses text generation for single-pass trajectory prediction.
      • It proposes Recurrent Action Memory (RAM), a lightweight module that conditions action prediction on previous action tokens to provide temporal context for manoeuvres such as overtaking and emergency braking.
      • With 641M parameters, FIVE-VLA achieves ~10% more routes without traffic rule infractions than the previous state-of-the-art VLA on Bench2Drive, reduces collision-violation rates on the NVIDIA Physical AI AV dataset, and runs at ~30 fps on an A100 and ~4 fps on a T4 (8–30× speedup).
  • RAF-VLA: Representation Alignment with the Future for End-to-End Autonomous Driving

    • Dogun Kim, Yongjae Lee, Joonhee Lim, Yeina Lee, Junhyeok Park, Moogeun Park, Dongsuk Kum
    • Publish Date: 2026.09.15
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • RAF-VLA (Representation Alignment with the Future) is a VLA-based autonomous driving framework that aligns the policy's hidden states with future-frame representations from a pretrained world encoder, avoiding explicit future generation.
      • It employs Future-Aligned Supervised Fine-Tuning, a straightforward regularization that shapes planning-relevant internal representations while learning driving actions, eliminating the training burden and inference latency of world modeling.
      • Experiments on the NAVSIM benchmark show competitive planning performance against state-of-the-art VLA planners with substantially fewer training samples, while incurring only 3.8% training overhead and negligible 1 ms inference overhead.
  • EditWM: Event-Decomposed World Modeling with Incremental Correction for End-to-End Autonomous Driving

    • Junjie Yang, Qingwei Zeng, Youyou Li, Zicheng Ding, Ziyi Shi, Shuqi Shen, Hongliang Lu, Hai Yang
    • Publish Date: 2026.09.15
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • EditWM decomposes future prediction into normal evolution and event-driven incremental correction in compact visual feature space.
      • It freezes a trajectory-conditioned normal predictor and trains a correction decoder with a learned gate to produce bounded feature updates, using corrected future features for candidate-specific trajectory scoring.
      • Evaluated on all 12,146 NAVSIM navtest scenes, it reduces future-feature MSE by 5.35% over Normal with improvements in 83.54% of scenes and achieves 91.05 EPDMS.
  • GRAVA: Grounded Reasoning-to-Action Representation and Learning for Autonomous Driving

    • Xiao Liu, Haoyu Li, Jianghao Leng, Lin Wang, Chao Sun
    • Publish Date: 2026.09.14
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • GRAVA is a framework built around Grounded Reasoning-to-Action (GRA), unifying grounding, reasoning, and action generation in a single autoregressive stream.
      • It introduces an agentic GRA data construction pipeline that combines forward scene grounding with backward trajectory anchoring to build GR-NavSim with 2.2M grounded question-answer pairs and 70K GRA reasoning traces.
      • A progressive training strategy pre-trains grounded cognition, establishes the reasoning-to-action interface through imitation, and improves driving behavior via reinforcement learning; GRAVA-8B achieves state-of-the-art performance among purely autoregressive driving models on the full NAVSIM benchmark and improves long-tail key-object compliance and Closed-loop Driving Score by 19.3% and 20.5% over action-only prediction.
  • READ: Learning Risk-Informed Fields for End-to-End Autonomous Driving

    • Zhiyuan Liu, Yuanxin Tian, Zehong Ke, Jinhao Li, Hao Cheng, Zhenhua Xu, Wenhao Yu, Jianqiang Wang
    • Publish Date: 2026.09.11
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • READ learns an explicit, planning-aligned risk representation from complementary geometric and behavioral constraints for end-to-end autonomous driving.
      • It instantiates this representation as a continuous spatiotemporal field, enabling differentiable queries along candidate trajectories for trajectory evaluation and refinement.
      • READ integrates with both end-to-end planners and Vision-Language-Action models, showing consistent gains on NAVSIM and competitive results on NAVSIM v2.
  • PlannerForge: LLM Agents for Scenario-Based Testing of Motion Planners in Autonomous Driving

    • Yuan Gao, Sebastian Müller, Mattia Piccinini, Marc Kaufeld, Yuchen Zhang, Finn Rasmus Schäfer, Qunying Song, Johannes Betz
    • Publish Date: 2026.09.08
    • Task: Planning
    • Summary:
      • PlannerForge is a unified LLM-agent framework that extends all scenario-based testing stages for ADSs, from Scenario Generation to ADS Assessment, and adds ADS Enhancement and ADS Benchmarking.
      • It evaluates 10 off-the-shelf LLMs across Generation, Selection, Modification, Module Routing, Planner Testing, and Enhancement under 5 prompt conditions, with best-per-task scores ranging from 0.88 to 1.00; open-source 20-35B models match commercial APIs on most tasks.
      • End-to-end chaining retains 83% / 78% of seed queries (commercial / open), outperforms Scenario Factory 2.0 on natural-language generation and BM25/From-Words-to-Collisions on selection and physically valid edits, and at N=400 cost-tuning lifts planner success from 50.4% to 70.2% while cutting collisions from 19.0% to 8.4%.
  • Drive by Hindsight and Foresight: Tool-Grounded Synergistic Reasoning over Hierarchical Memory for Autonomous Driving

    • Baojie Chen, Zijun Jia, Jing Zhong
    • Publish Date: 2026.09.08
    • Task: Reasoning
    • Summary:
      • Introduces a synergistic framework that tightly couples hierarchical memory with proactive tool invocation in a closed reasoning loop for autonomous driving, addressing hallucination, weak spatio-temporal perception, and limited generalization in VLMs.
      • Proposes Hierarchical Driving Memory with scene-level short-term memory for dynamic scene state and evolving long-term memory for reusable experience and tool strategies, plus a Memory-Tool Synergistic Reasoning Framework for adaptive tool invocation and offline consolidation.
      • Uses verified memory-tool trajectories from multi-step teacher rollout for SFT and GRPO training; the 7B model achieves 80.03 overall reasoning score and 79.09% MCQ accuracy on DriveLMM-o1, surpassing the strongest baseline by 7.74 MCQ points, with ablations validating short-term memory (+24.2 STSBench accuracy) and long-term memory consolidation (+3.57 MCQ with frozen parameters).
  • CoLMIN: LLM-based Multi-Decision Path Negotiation for Cooperative Autonomous Driving

    • Zhe Huang, Zhaoxin Fan, Shuo Wang, Wenjun Wu, Xuan Zhao, Min Liu
    • Publish Date: 2026.09.04
    • Task: Planning
    • Datasets: CARLA
    • Summary:
      • CoLMIN is an LLM-based multi-decision path negotiation framework for cooperative autonomous driving, achieving stable decision consensus through multi-decision path negotiation and reflective reasoning.
      • It consists of three key components: an LLM-based Multi-Intent Negotiation module (LMin), an Evaluation-based Shallow Reflection Module (ESRM), and an LLM-based Deep Reflection Module (LDRM).
      • Experimental results in the CARLA simulation environment demonstrate that CoLMIN significantly outperforms existing methods in challenging interactive driving scenarios.
  • Continuous Actions from Discrete Minds: Latent-Aligned Planning for End-to-End Autonomous Driving

    • Ruoyu Yao, Yusen Xie, Qingzhao Liu, Pei Liu, Zewei Yang, Yipeng Zhu, Xiaolong Wang, Jun Ma
    • Publish Date: 2026.09.03
    • Task: Planning
    • Datasets: nuScenes
    • Summary:
      • LaPla is a unified Vision-Language-Action framework with latent-aligned planning that grounds semantic understanding in precise motion execution for end-to-end autonomous driving.
      • It uses a residual VQ-VAE action tokenizer and repurposes the representation as a physical prior, projecting hidden states into a pretrained VQ-VAE latent space to avoid quantization errors and bypass autoregressive generation.
      • LaPla reduces long-horizon L2 error by 15.52% on nuScenes and improves closed-loop success rate by 33.34 percentage points on NVIDIA AlpaSim with significantly reduced inference latency.
  • SV-WAM: An Efficient Surround-View World-Action Model for End-to-End Autonomous Driving

    • Jinyang Wang, Shiwei Li, Junjian Wang, Zhiqiang Deng, Jianbin Gao, Yihang Zhao, Liu Liu, Yongjia Zhao, Jinlong Chen, Huirui Xu, Yifeng Pan, Kangwei Liu, Fan Ren, Ji Tao, Minghao Yang
    • Publish Date: 2026.09.03
    • Task: Planning
    • Datasets: NAVSIMv2, nuScenes
    • Summary:
      • SV-WAM is an efficient surround-view world-action model that preserves full six-camera observations while using future-video prediction as dense training supervision rather than as an inference-time output.
      • It introduces an action-centered causal mask for joint action-video denoising, enabling the video branch to be discarded at deployment for efficient action-only planning.
      • A differentiable drivable-area compliance regularizer improves planning safety and boundary awareness, and experiments on NAVSIMv2 and nuScenes show state-of-the-art planning with low inference latency and competitive zero-shot transfer.
  • Drive-HWM: Hierarchical World Models for Dynamic-Latent Guided Autonomous Driving

    • Zhaoxin Fan, Tianbao Zhang, Wenjun Wu, Xiaofeng Wang, Yeying Jin, Jian Zhao, Zheng Zhu, Shuicheng Yan
    • Publish Date: 2026.09.03
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • Drive-HWM is a hierarchical slow–fast world modeling framework for autonomous driving that organizes future representation prediction and action generation at complementary temporal scales.
      • It introduces Dynamic-Aware Latents learned through optical-flow prediction to model driving motion dynamics; the slow world model predicts multi-step future representations, while the fast model jointly predicts the next frame and immediate action guided by these representations.
      • Extensive experiments on NAVSIM v1 and v2 demonstrate strong driving performance, and ablations validate the hierarchical slow–fast design, dynamics-aware future representations, and joint next-frame and action prediction.
  • Long-Horizon Consistent and Interaction-Aware World Models for Multi-Style End-to-End Driving

    • Yuxuan Han, Kunyuan Wu, Liyunong Yang, Zilu Wang, Cansen Jiang, Yi Xiao, Liang Hu
    • Publish Date: 2026.09.03
    • Task: End-to-End
    • Datasets: Bench2Drive
    • Summary:
      • StyleDrive, a world-model-based learning framework for end-to-end autonomous driving that jointly enforces long-horizon consistency, explicitly disentangles interactive traffic states, and supports multi-style policy optimization.
      • Introduces temporal consistency regularization with gated cross-attention, an explicit state disentanglement module separating ego-relevant from ego-irrelevant interactive states, and Group Relative Policy Optimization for multi-style driving without retraining.
      • Achieves 88.44 driving score (+17.08) and 66.82 success rate (+16.58) on Bench2Drive, and demonstrates promising sim-to-real transfer on a real automated guided vehicle platform.
  • From Proxy Learning to Driving Decisions: A Transfer-Based Framework for Evaluating Future-Aware Autonomous Driving Planners

    • Yikai Wu
    • Publish Date: 2026.09.02
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • Proposes the Proxy-to-Decision Transfer (PDT) Framework, an analysis framework for evaluating when learned future information supports a reliable driving-performance improvement claim.
      • Introduces a Decision-Transfer Decomposition Module for localizing value loss and a Reliability-Constrained Validation Module for requiring exact pairing, meaningful effect, scale-expanded confirmation, safety non-compensation, sequential comparability, and family-level robustness.
      • Evaluates a future-aware planner on NAVSIM-v1, showing proxy BCE improves while held selected PDM decreases, subset gains fail scale and support intervals, and none of 432 screened configurations passes the robustness gate.
  • Towards Zero-Shot Transfer Across Embodiments For Driving VLAs

    • Caio Azevedo, Stefano Sabatini, Sascha Hornauer, Fabien Moutarde
    • Publish Date: 2026.09.02
    • Task: End-to-End
    • Summary:
      • Studies multi-dataset training for driving VLAs and proposes BEV-Forcing, an auxiliary objective that transfers ground-plane object-layout information from a specialized Bird's-Eye-View model into the VLA backbone.
      • Shows that BEV-Forcing can improve both in-distribution and out-of-distribution performance when training on a small number of camera rigs.
      • Finds that benefits of the auxiliary task diminish as the number of training embodiments increases, motivating evaluation that accounts for data scaling.
  • CrashDiffuser: VLM-Guided Collision Intent Reasoning for Fine-Grained Safety-Critical Traffic Scenario Generation

    • Shucheng Zhang, Yuang Zhang, Bingzhang Wang, Muhammad Monjurul Karim, Kehua Chen, Yinhai Wang
    • Publish Date: 2026.09.02
    • Task: Generation
    • Datasets: WOMD
    • Summary:
      • CrashDiffuser is a closed-loop VLM-guided diffusion framework for fine-grained safety-critical traffic scenario generation, decoupling semantic collision reasoning from continuous trajectory synthesis.
      • It uses a hierarchical collision-intent interface from the requested target contact region, where the VLM extracts reusable scene-level context and predicts structured action tuples to condition a diffusion model for executable adversarial trajectories.
      • On WOMD-derived closed-loop scenarios, it achieves 50.33% single-attempt and 67.98% three-attempt target-collision rates, 40.05% contact-region control success, and competitive trajectory naturalness.
  • CoLT-Drive: Counterfactual Long-Tail Benchmarking and Knowledge-Preserving Adaptation for Driving Affordance Prediction

    • Zhengxu Tang, Guofeng Cui, Ziyu Gong, Xiaozhou Zhang, Ruifeng Deng, Chengzhi Qi, Ke Chen, Sachin Patil, Tianjun Xiao, Langechuan Liu, Pichao Wang
    • Publish Date: 2026.08.31
    • Code: CoLT-Drive
    • Task: Prediction
    • Datasets: CoLT-Drive
    • Summary:
      • CoLT-Drive, a 3,536-sample counterfactual long-tail benchmark for decision-level driving affordance prediction that inserts rare objects into otherwise fixed driving scenes and measures whether models predict acceptable longitudinal--lateral meta-action pairs.
      • KPA, a knowledge-preserving adaptation framework combining structured perception-to-decision prompting, SLERP-based expert merging, and RegMoE, a regime-aware LoRA mixture-of-experts module.
      • KPA achieves 60.8% pair accuracy on CoLT-Drive, outperforming the pretrained Qwen3-VL-2B baseline (50.3%) and LoRA SFT (32.4%) while maintaining competitive in-domain accuracy.
  • Qwen-Drive-1.0: An Initial Step towards a Vision-Language Foundation Model for Autonomous Driving

    • Xin Zhou, Zongchuang Zhao, Zhibo Yang, Mingsheng Li, Humen Zhong, Shuai Bai, Du Chu, Ruizhe Chen, Zhaohai Li, Jun Tang, Qiuyue Wang, Mingkun Yang, Jiazhao Zhang, Dayiheng Liu, Dingkang Liang, Xiang Bai
    • Publish Date: 2026.08.31
    • Task: Planning
    • Summary:
      • Qwen-Drive-1.0 is an initial vision-language foundation model for autonomous driving that unifies 3D perception, visual question answering, and motion planning within a single framework.
      • It integrates an external BEV perception head for 3D object detection, semantic occupancy prediction, and BEV map segmentation, providing an explicit and inspectable interface to 3D scene structure.
      • A Planning Expert generates future ego trajectories from shared VLM representations, while a staged training recipe combines driving supervision with general-purpose vision-language data to preserve broad visual understanding and instruction-following capabilities.
  • Rethinking Language's Role in Efficient VLA for Autonomous Vehicles: Toward Smarter, Trustworthy Driving

    • Tongfei Guo, Lili Su
    • Publish Date: 2026.08.31
    • Task: End-to-End
    • Datasets: nuScenes, NAVSIM, Bench2Drive
    • Summary:
      • Reframes language's role in efficient Vision-Language-Action (VLA) models for autonomous driving by introducing the Language Residue taxonomy (L1–L4) based on inference-time use of language.
      • Reviews representative methods across deployment axes (latency, parameters, memory, FLOPs, tokens) and analyzes them on open- and closed-loop driving benchmarks such as nuScenes, NAVSIM, and Bench2Drive.
      • Traces how efficient NLP/LLM methods are adapted to autonomous driving, identifying constraints and motivations, with a continuously updated repository to be available on GitHub.
  • Self-Aware Active Learning Enables Continual Improvement in Autonomous Driving

    • Dong Hu, Chao Huang, Carman K. M. Lee, Dimitrios Kanoulas
    • Publish Date: 2026.08.30
    • Task: Planning
    • Datasets: Waymo
    • Summary:
      • SAGE is an active learning framework for post-training adaptation in autonomous driving that uses a predictive world model to generate fear and curiosity signals.
      • Fear estimates short-horizon predictive risk and model uncertainty, while curiosity measures novelty through prediction error and adaptively calibrates the intervention threshold; when fear exceeds it, control transfers to an expert or fallback policy for focused imitation learning.
      • Evaluated in simulated route-transfer tasks, Waymo-based logged driving, CARLA occlusion hazards, and real-world mobile robot navigation, SAGE improves robustness, reduces safety violations, and maintains task performance.
  • GeoWAM: Visual Geometry World Action Models for Autonomous Driving

    • Yiren Lu, Xin Ye, Jiaming Liu, Philip Jacobson, Jin Yao, Yi-chung Chen, Liam Merino, Dhruva Dixith Kurra, Min Cai, Tom Lampo, Yu Yin, Danhua Guo, Burhan Yaman
    • Publish Date: 2026.08.24
    • Task: Planning
    • Summary:
      • GeoWAM introduces a visual geometry world action model for autonomous driving that uses point-cloud geometry as a more natural state space than pixels.
      • The model is pretrained to forecast future scene geometry, learning representations that jointly encode spatial structure and temporal evolution.
      • A geometry-conditioned action head leverages these learned geometric dynamics to predict future ego trajectories, yielding stronger driving policies than image-based alternatives in open-loop and closed-loop evaluations.
  • MomADv2: Reliable Temporal Memory for End-to-End Autonomous Driving

    • Ziying Song, Shengkai Zhang, Lin Liu, Peiliang Wu, Lei Yang, Dongyang Xu, Bin Sun, Li Wang, Shaoqing Xu, Caiyan Jia, Yadan Luo
    • Publish Date: 2026.08.24
    • Task: Planning
    • Datasets: NAVSIM, Bench2Drive, nuScenes
    • Summary:
      • Proposes MomADv2, a reliable state-space memory framework for long-horizon end-to-end autonomous driving that addresses command-inconsistent memory.
      • Introduces a Selective State-Space Planning Memory Query Module to filter historical planning queries and a Flow-Matching Trajectory Residual Refiner for fine-grained trajectory refinement.
      • Experiments on NAVSIM, Bench2Drive, and nuScenes show improved planning consistency and a 15.6% reduction in average collision rate over MomAD under 6-second planning.
  • Roadside-Cooperative Autonomous Driving: From Data Platform to Vision-Language End-to-End Reasoning

    • Yitao Xu, Tong Wu, Yiyan Wu, Guoji Xu, Yanbo Jiang, Jiahao Wang, Zehong Ke, Junkai Jiang, Fang Zhang, Jianqiang Wang
    • Publish Date: 2026.08.21
    • Task: End-to-End
    • Summary:
      • Introduces V2XBench, a V2X simulation platform with synchronized ego-roadside sensing and closed-loop evaluation, and Chat-V2XBench, a progressively structured VQA dataset for cooperative reasoning.
      • Proposes AURORA, an end-to-end cooperative driving framework with dual-view perception and a Query-level Cross-View Query Alignment and Fusion (CQAF) module to align ego and roadside viewpoints.
      • Achieves state-of-the-art closed-loop performance on V2XBench in heavily occluded scenarios, with 98.21% Route Completion and 76.02 Driving Score at low roadside communication bandwidth.
  • WA-JEPA: Rethinking the Video JEPA Paradigm for World-Action Modeling in Autonomous Driving

    • Xinlin Wang, Yujiao Xiang, Yuheng Zhou, Jingqi Wang, Minqing Huang, Jiajie Huang, Dongxu Wei, Tingguang Zhou, Xiyang Wang, Gong Chen, Zhi Xu, Feiyang Tan, Hangning Zhou, Mu Yang
    • Publish Date: 2026.08.21
    • Code: WA-JEPA
    • Task: Planning
    • Datasets: NAVSIM, nuPlan
    • Summary:
      • WA-JEPA is a V-JEPA-native world-action model designed for autonomous driving planning, rethinking the V-JEPA paradigm to overcome its limitations with random-mask completion and deterministic regression.
      • It employs hybrid future-masked pre-training and conditional flow matching over latent futures, and introduces a joint future-action predictor that denoises future scene tokens and ego trajectories together in a unified spatiotemporal latent space.
      • Pre-trained on nuPlan videos and fine-tuned on NAVSIM, WA-JEPA achieves 91.7 EPDMS on NAVSIM-v2 and attains the best HD-Score of 0.4462 on HUGSIM without HUGSIM-specific fine-tuning.
  • A Collaborative Multi-Modality Interaction for VLA-based End-to-End Autonomous Driving

    • Jingtao Sun, Xiaohai He, Yike Zhang, Dong Huang, Yaonan Wang, Ajmal Mian, Mike Zheng Shou
    • Publish Date: 2026.08.21
    • Task: Planning
    • Summary:
      • Proposes a robust VLA-based end-to-end autonomous driving system that combines multi-modality interaction with multi-trajectory planning and optimization for more reliable, interpretable, and safer driving decisions.
      • Introduces three core components: Affinity-Guided Optimal Transport for main-auxiliary modality two-way interaction; Distribution-Consistent Modality Transfer for heterogeneous modality distribution transfer and cross-modal interaction; and Multi-modal Multi-Trajectory Planning with Perception-Oriented Trajectory Refinement.
      • Experimental results on open-loop and closed-loop datasets demonstrate improvements in safety, long-horizon driving reasoning, and road scene perception over existing driving systems.
  • Multi-Agent Orchestration with the Common-Sense Reasoning Capabilities of LLMs for Autonomous Driving

    • Mehdi Azarafza, Faezeh Pasandideh, Ali Ehteshami Bejnordi, Stefan Henkler, Achim Rettberg
    • Publish Date: 2026.08.20
    • Task: Planning
    • Datasets: CARLA
    • Summary:
      • Proposes a hybrid multi-agent orchestration framework that uses LLM common-sense reasoning to coordinate PPO-trained reinforcement learning and PID control for autonomous driving.
      • Applies LLM reasoning iteratively to refine the RL reward function for dynamic driving environments, evaluated in highly randomized CARLA scenarios while retaining structured control and safety mechanisms.
  • Planning-Oriented End-to-End Autonomous Driving: Architectures, Evaluation, and Emerging Paradigms

    • Yanchen Guan, Xingcheng Liu, Bin Rao, Chengyue Wang, Guofa Li, Yunjian Li, Lishengsa Yue, Zhiyong Cui, Chengzhong Xu, Zhenning Li
    • Publish Date: 2026.08.20
    • Task: Planning
    • Summary:
      • Reviews the transition from camera-to-control regression to planning-oriented end-to-end autonomous driving, covering behavior cloning, conditional imitation learning, privileged distillation, BEV and vectorized planning, unified perception-prediction-planning architectures, world-model-based planners, and vision-language-action systems.
      • Organizes existing methods along four axes: input representation, planning output, supervision signal, and evaluation protocol, and examines the benchmark shift from open-loop trajectory matching to closed-loop simulation, non-reactive real-log evaluation, long-tail testing, and human-preference-aware metrics.
      • Argues that architectural progress requires benchmark-consistent evaluation and identifies open challenges in uncertainty-aware planning, learner-expert mismatch, runtime safety assurance, language-action grounding, world-model validation, and reproducible benchmarking.
  • DA-WAM: Decision-Aligned Future Latents for Driving World Models

    • Ruiguo Zhong, Benshan Ma, Xiaolong Chen, Lang Zhang, Mingyue Feng, Yaonong Wang, Pei Liu, Jun Ma
    • Publish Date: 2026.08.19
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • DA-WAM is a framework that unifies predictive representation learning, action-conditioned future modeling, and trajectory scoring under a single decision-making objective for autonomous driving.
      • It maintains predictive supervision throughout planner optimization via an online encoder and a stable momentum target, allowing future representations to co-evolve with the driving task.
      • An action-conditioned predictor generates a distinct future latent state per trajectory candidate, which is evaluated by a future-latent-conditioned factorized scorer with supervision from expert-matched trajectories and safety-critical hard negatives.
      • Extensive experiments on NAVSIM-v1 and NAVSIM-v2 demonstrate state-of-the-art performance.
  • GAPL: Grounded Action-effect Policy Learning for LLM-Based Trajectory Planning

    • Zhihong Cui, Hengyu Liu, Zhangkai Wu, Yushuai Li, Tianyi Li, Peiyuan Guan, Amir Taherkordi, Tor Skeie
    • Publish Date: 2026.08.18
    • Task: Planning
    • Datasets: Highway-env
    • Summary:
      • GAPL is a unified framework for LLM-based trajectory planning that integrates LLM-based effect estimation, simulation-based effect grounding, and policy optimization into a closed-loop system.
      • It consists of an LLM-based Effect Evaluator for structured multi-dimensional action-effect estimation, a Simulation-based Effect Grounder for dynamics-consistent effects, and an Effect-Aware Decision Maker that distills effect estimates to guide PPO-based policy learning.
      • Experiments on four Highway-env scenarios show consistent improvements over baselines, with average reductions in collision rate, ADE, and FDE of 0.76, 0.86, and 2.00, and an average reward gain of 1.44.
  • Plug-and-Play Traffic Element Awareness for End-to-End Autonomous Driving

    • Zongzheng Zhang, Jijun Wang, Saining Zhang, Shuo Wang, Yiru Wang, Hai Yang, Yang Chen, Yuwen Heng, Hao Sun, Anqing Jiang, Hao Zhao
    • Publish Date: 2026.08.18
    • Task: End-to-End
    • Datasets: nuScenes, NAVSIM-v1/NAVSIM-v2, Bench2Drive
    • Summary:
      • Presents the first systematic investigation of traffic element awareness for end-to-end autonomous driving.
      • Constructs a unified research infrastructure by augmenting multiple public driving datasets with comprehensive traffic-element annotations.
      • Introduces a minimal plug-and-play integration design that consistently improves driving performance across modern paradigms and datasets, establishing a new state of the art on NAVSIM-v2.
  • Geo-VLA: Geometry-Aware Vision-Language-Action Planning via Internalization of Map Semantics

    • Ran Chen, Jiaxing Ren, Zhikun Zhang, Yunhao Hou, Junbao Zhuo, Bochao Zou
    • Publish Date: 2026.08.18
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • Geo-VLA is a plug-and-play framework that enhances VLA models by learning geometry-aware visual representations, internalizing geometric map semantics during training while requiring no HD maps or additional lane information at inference.
      • Introduces Geo-QA, a geometry-focused question-answering dataset that injects road geometry into vision-language representations through contrastive learning and instruction tuning.
      • Achieves 92.1 PDMS on NAVSIM v1 and establishes a new state-of-the-art among single-camera VLA planners.
  • DriveCache: Action-Aware Caching for Driving World Model Inference

    • Jianchun Yang, Jian Liang, Xianda Guo, Pinhan Fu, Yanlun Peng, Conglang Zhang, Wenke Huang, Mang Ye
    • Publish Date: 2026.08.17
    • Task: Prediction
    • Summary:
      • DriveCache is a training-free, action-aware caching controller for driving world model inference that uses planned motion to allocate feature reuse across scenes.
      • It uses dynamic programming to place reuse across denoising steps under a calibrated response budget, with a causal drift check to refresh features and replan when generation departs from calibration.
      • Across three generator configurations, DriveCache improves the overall fidelity-efficiency trade-off over evaluated cache methods; code will be publicly available.
  • Risk-Adaptive Edge--Cloud Visual Reasoning for Communication-Efficient Autonomous Driving

    • Meng Ma, Shuyang Li, Naigang Wang, Ruimin Ke
    • Publish Date: 2026.08.15
    • Task: Planning
    • Summary:
      • Presents a risk-adaptive edge–cloud architecture where onboard traffic assessment triggers selective cloud VLM reasoning, reducing unnecessary visual uploads.
      • Uses an onboard VLM and lightweight detector for temporal traffic and path-relative hazard assessment, while keeping validation, vehicle control, and automatic emergency braking local.
      • In CARLA experiments, matches periodic cloud access success while reducing cloud requests by 54.1% and fewer AEB activations, and continues reducing cloud traffic across emulated network profiles.
  • SSP: An Event-Matched Syn2Sim2Phy Cross-Domain Evaluation Framework for Autonomous Driving VLA Models

    • Haojie Feng, Peizhi Zhang, Xinrui Zhang, Zhuoren Li, Junpeng Huang, Xiurong Wang, Dongxiao Yin, Yuxiang Zhang, Junfan Zhu, Lu Xiong
    • Publish Date: 2026.08.14
    • Task: End-to-End
    • Summary:
      • SSP (Synthetic-Simulation-Physical) is an event-matched Syn2Sim2Phy evaluation framework that anchors cross-domain comparison of autonomous driving VLA models to the same safety-critical interaction.
      • It starts from a synthetic long-tail video, builds a validated event specification preserving road topology, participant roles, relative motion, conflict evolution, passing order, response constraints, and event phases, and constructs platform-specific realizations in CARLA and on a closed proving ground with transfer audits.
      • SSP maps heterogeneous outputs from OpenEMMA, LLaViDA, and Alpamayo-R1 into common semantic slots and a 1 s trajectory window to assess output validity, semantic accuracy, critical-interaction recognition, trajectory quality, and risk response; across Cut-in and vulnerable-road-user crossing cases, macro-averaged Integrated VLA Capability Scores are 0.259, 0.291, and 0.325 in Synthetic, Simulation, and Physical domains, respectively.
  • LLM-Assisted Dynamic Threat Analysis for Attacker-Reachable Software Weaknesses in Autonomous Vehicles

    • Md Wasiul Haque, Sagar Dasgupta, Mizanur Rahman, Md Rayhanur Rahman
    • Publish Date: 2026.08.13
    • Task: Reasoning
    • Summary:
      • Investigates whether large language models (LLMs) can automate dynamic confirmation of attacker-reachable software weaknesses in Autoware, an open-source autonomous-driving stack.
      • Performs compiler-precise static analysis across 185 packages, identifying 1,375 decision rules, 2,274 validation checks, and 482 input-to-safety-output flows, then generates and compiles 3,700 artifact sets using two local open-weight LLMs.
      • Finds that build integration is the primary barrier: 80% of first-shot compilation failures stem from dependency wiring, the reasoning model compiled 64% of harnesses on the first attempt versus 6% for the code-specialized model, and no candidate weakness was dynamically confirmed within budget.
  • FIRE-VLA: Failure-Informed Self-Evolution for Vision-Language-Action Models in Autonomous Driving

    • Hao Dou
    • Publish Date: 2026.08.13
    • Task: Planning
    • Datasets: nuScenes
    • Summary:
      • FIRE-VLA introduces a failure-informed self-evolution framework for autonomous-driving VLA models, converting low-reward, low-diversity groups into privileged supervision via self-distillation from a frozen round-start copy of the same model, with only the teacher observing the hidden future trajectory.
      • It keeps GRPO active for every group while routing unresolved failures into answer-token supervision conditioned on the student's generated prefix; the updated policy then supplies the next round's teacher without requiring a larger external teacher.
      • Starting from the same Qwen2.5-VL-3B SFT checkpoint, FIRE-VLA retains comparable single-sample planning while reducing G=4 mean L2 from 1.848 to 1.500 m and lowering evaluation-persistent failure prevalence from 13.03% to 11.20% on 6,019 examples from 150 held-out nuScenes scenes.
  • FlashDrive: Flash Vision-Language-Action Inference for Autonomous Driving

    • Zekai Li, Yihao Liang, Hongfei Zhang, Jian Chen, Yesheng Liang, Zhijian Liu
    • Publish Date: 2026.08.13
    • Task: End-to-End
    • Summary:
      • FlashDrive is an algorithm-system co-design framework that accelerates Vision-Language-Action inference for autonomous driving by simultaneously targeting four bottlenecks: visual encoding, language-model prefill, reasoning token generation, and flow-matching denoising.
      • It exploits algorithmic shortcuts—streaming KV-cache reuse across frames, a non-autoregressive diffusion drafter for speculative decoding, and adaptive step caching guided by the velocity field's structure—layered on CUDA Graph compilation and kernel fusion.
      • Applied to Alpamayo 1.5-10B with W4A8 quantization, FlashDrive cuts end-to-end latency from 717ms to 151ms (4.7x) with essentially unchanged accuracy, raising throughput from 1.4 Hz to 6.6 Hz on a single GPU.
  • BrainWAM: Action-Space Coordination of Semantic Priors and Predictive Dynamics for Autonomous Driving

    • Bing Zhan, Shuyao Shang, Shuo Lu, Yuan Xu, Zhao Wang, Yida Wang, Xueyang Zhang, Kun Zhan, Jiahao Gu
    • Publish Date: 2026.08.13
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • BrainWAM is a structured action-space coordination framework for autonomous driving that unifies semantic priors from VLA models and predictive dynamics from WAMs by aligning two specialized action-oriented pathways at compact action representations.
      • It addresses the attention-allocation mismatch in naive token-level joint attention, where semantic shortcuts dominate the shared attention space and suppress predictive dynamics.
      • It introduces asynchronous rectified-flow inference with decoupled video and action denoising, achieving state-of-the-art performance on NAVSIM v1 (89.5 PDMS) and NAVSIM v2 (89.6 EPDMS).
  • Do Not Forget the Obvious - RISC: A Risk-Informed Slice-Coverage Protocol for Safe Autonomous Driving

    • Fabian Hüger
    • Publish Date: 2026.08.12
    • Task: Perception
    • Datasets: Zenseact Open Dataset
    • Summary:
      • RISC (Risk-Informed Slice Coverage) is a practical, model-agnostic protocol for risk-guided stress testing and coverage-qualified evaluation, translating safety concerns into machine-readable risk slices and selecting compact audit sets by risk.
      • The protocol uses lightweight signals to tag candidate data and can optionally leverage an LLM to surface relevant but overlooked conditions during test planning, helping engineers not to forget the obvious.
      • Instantiated for monocular pedestrian perception using 1,000 frames from the Zenseact Open Dataset, image statistics, and a YOLO-based detector proxy, risk-guided selection raises critical failure discovery from 34.0% under random sampling to 98.5%.
  • RiskWorld: Object-Centric Latent World Modeling for Autonomous Driving Risk Identification

    • Jingzheng Li, Yufei Ge, Qianren Mao, Zhijun Chen, Bing Li, Xingyu Peng, Baochang Zhang, Xianglong Liu
    • Publish Date: 2026.08.12
    • Task: Prediction
    • Summary:
      • RiskWorld is an object-centric latent world model that identifies risk by imagining the evolution of each candidate object relative to the ego vehicle.
      • It combines pretrained predictive video representations with structured ego-object histories, contextualizes observed interactions, and rolls relation-aware object states into the future using RSSM-style latent dynamics.
      • It decodes rollouts into object-level risk scores with auxiliary future-relation and temporal-risk predictions, achieving 63.0% F1 and 2.1% false-alarm rate on RiskBench.
  • XCoT-VLA: Executable Chain-of-Thought for Vision-Language-Action Driving

    • Foundation Model Team, XPeng Inc
    • Publisher: XPeng Inc
    • Publish Date: 2026.08.11
    • Task: Planning
    • Summary:
      • XCoT-VLA replaces verbose natural-language Chain-of-Thought with compact executable CoT tokens learned from automatically constructed Reason-Action supervision, connecting scene understanding, semantic reasoning, and trajectory generation.
      • The method conditions fixed trajectory queries via shared multimodal self-attention, with deterministic token-function routing applying the Reason FFN to XCoT tokens and the Control FFN to trajectory queries for flow-matching trajectory generation.
      • XCoT Policy Optimization (XCPO) is introduced as an optional refinement extension, and XCoT-VLA reduces longitudinal ADE from 1.645 to 1.323 and lateral FDE from 1.616 to 0.648 using only 2-6 executable XCoT tokens within the real-time planning budget.
  • Multi-View Relational Distillation for Spatial Reasoning with Vision-Language Models

    • Kiet T. Nguyen, Hanbo Shim, Jinwoo Kim, Seunghoon Hong
    • Publish Date: 2026.08.11
    • Task: Reasoning
    • Summary:
      • MVRD distills patch-wise cosine similarities across views instead of teacher features to improve visual-spatial reasoning while preserving language alignment.
      • It outperforms supervised fine-tuning and feature distillation, approaching feature fusion methods with considerably fewer added parameters and lower latency.
      • MVRD generalizes to 3D scene understanding tasks such as object grounding, dense captioning, and question answering.
  • DriveVLA-M0: Failure-Aware Memory Augmentation for Autonomous Driving

    • Zebin Xing, Yupeng Zheng, Qiang Chen, Linbo Wang, Yichen Zhang, Pengxuan Yang, Junli Wang, Deheng Qian, Xiaoqing Ye, Junyu Han, Yifeng Pan, Qichao Zhang, Dongbin Zhao
    • Publish Date: 2026.08.11
    • Code: DriveVLA-M0
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • DriveVLA-M0 is a retrieval-augmented Vision-Language-Action model with failure-aware latent memory for end-to-end autonomous driving.
      • It constructs a latent memory pool storing failure cases with structured scene representations and expert trajectory labels, and uses a Retrieve Model that decouples static road structure and dynamic agent interactions for structurally grounded retrieval.
      • Retrieved cases are injected at inference via lightweight decoupled LoRA-based test-time training (TTT) for targeted scenario-specific correction without modifying the backbone, achieving 94.1 PDMS on Navtest and 47.0 EPDMS on Navhard with only 26.44 ms TTT backward latency overhead.
  • Dreamer-SAC: Off-Policy Learning in Latent World Models for Sample-Efficient Autonomous Driving

    • Jiazhuo Li, Linjiang Cao, Qi Liu, Xi Xiong
    • Publish Date: 2026.08.11
    • Task: Planning
    • Summary:
      • Dreamer-SAC integrates a recurrent state-space world model with an off-policy soft actor-critic algorithm trained directly in latent space for sample-efficient autonomous driving.
      • The framework combines real interactions with short-horizon generated trajectories, n-step target estimation, and multi-objective supervision.
      • It outperforms DreamerV3, SAC, and PPO with substantially fewer real environment interactions, and reveals an inverted-U relationship between rollout horizon and policy performance.
  • Chain of Spatial Thoughts: Modality-Agnostic Spatial Grounding for Vision Language Models

    • Hunter Schofield, Mohammed Elmahgiubi, Mohammad Mahdavian, Richard Shi, Jinjun Shan, Amir Rasouli, Dongfeng Bai
    • Publish Date: 2026.08.10
    • Task: Reasoning
    • Summary:
      • Space Tokens is a lightweight, architecture-agnostic framework that equips VLMs with explicit continuous spatial representations without additional inference-time modules.
      • It distills scene-level 3D geometry and object-centric spatial attributes into continuous latent tokens, enabling their direct incorporation into chain-of-thought reasoning to improve spatial reasoning.
      • Experiments on VSI-Bench improve Qwen3-VL-8B by 4.3% and SenseNova-SI-1.3 by 1.3%, while achieving state-of-the-art performance on object size (79.2%) and room size estimation (75.7%).
  • 4D-WAM: 4D Consistent World Modeling for Autonomous Driving

    • Jiacheng Fu, Yibo Yuan, Meng Tian, Yue Li, Jiangtong Zhu, Jianhua Han, Yueyi Zhang, Jianwu Fang, Jianru Xue, Hang Xu, Zhiwei Xiong
    • Publish Date: 2026.08.10
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • 4D-WAM leverages geometric foundation models for training-time supervision, feeding WAM-predicted future frames into a geometric foundation model and using 4D-aware responses to define a 4D consistency loss, enabling physically consistent 4D scene understanding and prediction without additional inference cost.
      • It identifies an early-decision phenomenon in WAMs and proposes a decision-oriented timestep sampling strategy that emphasizes supervision at early, high-noise stages where driving decisions are primarily formed, further improving trajectory planning.
      • Extensive experiments show that 4D-WAM effectively models 4D consistent scene evolution and achieves state-of-the-art performance on the challenging NAVSIM-v1 and NAVSIM-v2 benchmarks.
  • FactorDrive: Adaptive Multi-Step Reasoning Driven by Planning-Critical Factors for End-to-End Autonomous Driving

    • Guolei Huang, Tengfei She, Yuxuan Lu, Yao Huang, Yuqi Ye, Yongjun Shen
    • Publish Date: 2026.08.10
    • Task: Planning
    • Datasets: nuScenes, NAVSIM
    • Summary:
      • FactorDrive, an end-to-end autonomous driving framework for adaptive multi-step reasoning driven by planning-critical factors (PCFs), grounding planning reasoning in trajectory-relevant spatial-physical evidence.
      • Introduces PCF-CoT, a chain-of-thought dataset organizing reasoning around scene-specific PCFs so that composition and depth of reasoning paths adapt to different planning demands.
      • Proposes Quality Search-Guided Group Relative Policy Optimization (QS-GRPO), which uses MCTS guided by trajectory-level planning rewards to discover higher-quality reasoning paths and optimizes the policy via GRPO, achieving state-of-the-art planning performance on nuScenes and NAVSIM.
  • DH-VLM: Dual-Horizon Cooperative Latent Reasoning for Autonomous Driving

    • Ziyi Song, Chen Xia, Hang Yu, Sheng Zhou, Zhisheng Niu
    • Publish Date: 2026.08.10
    • Task: Planning
    • Summary:
      • DH-VLM is a dual-horizon cooperative latent reasoning framework that enables asymmetric semantic cooperation between infrastructure and ego vehicle.
      • It integrates infrastructure-driven latent evolution to refine conditional latents, allowing the ego vehicle to leverage long-range contextual understanding while preserving autonomous local planning.
      • The framework includes a cooperation-oriented QA dataset and achieves state-of-the-art planning performance, reducing L2 error by 14.6%, collision rate by 26.9%, communication cost by 57.3%, and GPU memory usage by 25.5%.
  • CRUISE: Vision-Language Model-Guided Uncertainty-Aware Cross-Modal Sensor Fusion for Robust Autonomous Driving

    • Junyao Wang, Yulin Xu, Yu Li, Pramod Khargonekar, Mohammad Abdullah Al Faruque
    • Publisher: University of California, Irvine
    • Publish Date: 2026.08.10
    • Task: Perception
    • Summary:
      • CRUISE is a novel uncertainty-aware cross-modal sensor fusion framework for robust autonomous driving.
      • It integrates a vision-language model (VLM)-guided uncertainty quantification module that generates fine-grained, pixel-level uncertainty estimates.
      • A dynamic adaptive mechanism explicitly models cross-modal dependencies to exploit the complementary nature of multi-sensor inputs, improving generalization in out-of-distribution scenarios.
  • UnsDrive: Towards Robust End-to-End Autonomous Driving in Unstructured Scenes

    • Nanxin Zeng, Ruiqi Song, Xiangyu Guo, Baiyong Ding, Yunfeng Ai
    • Publish Date: 2026.08.10
    • Task: Planning
    • Summary:
      • UnsDrive is an end-to-end planner for unstructured mining scenes that builds an unknown-aware occupancy representation using multi-frame visibility cues and conditions a flow-matching planner to generate multimodal future trajectories.
      • It introduces an occupancy trajectory consistency loss and an uncertainty-aware trajectory scorer to penalize trajectories entering non-traversable or unobserved regions, improving safety under partial observability.
      • The paper also presents MineLoop, a mining-oriented closed-loop simulator, and shows UnsDrive outperforms strong baselines in trajectory accuracy, collision avoidance, and long-horizon driving robustness.
  • SimWAM: A Simple World Action Model for End-to-End Autonomous Driving

    • Zongchuang Zhao, Xin Zhou, Tianyang Xu, Zhengyang Sun, Kaixuan Zhou, Yu Wu, Honglin Li, Dingkang Liang, Xiang Bai
    • Publisher: Huazhong University of Science and Technology
    • Publish Date: 2026.08.07
    • Code: SimWAM
    • Task: Planning
    • Datasets: NAVSIM, nuScenes
    • Summary:
      • SimWAM is a simple yet effective World-Action Model that leverages future-video prediction as a training-time supervision signal, co-training a pretrained video expert and a lightweight action expert with joint flow matching.
      • An isolated attention mask keeps action prediction independent of future frames, enabling trajectory prediction without explicit future-frame generation at inference while allowing the video backbone to be replaced and the action expert scaled independently.
      • Reinforcement learning is further applied to optimize a compositional driving reward beyond trajectory imitation, achieving 91.5 PDMS on NAVSIM with substantially lower latency and zero-shot transfer to nuScenes.
  • CMU-Drive and V2V-VLA: Cooperative Multi-agent Unified Driving with Reasoning Benchmark and Vehicle-to-Vehicle Vision-Language-Action Models

    • Hsu-kuang Chiu, Stephen F. Smith
    • Publisher: Carnegie Mellon University
    • Publish Date: 2026.08.07
    • Task: End-to-End
    • Summary:
      • CMU-Drive is a closed-loop end-to-end benchmark for evaluating cooperative autonomous driving with multiple connected autonomous vehicles operating in safety-critical driving scenarios with background traffic participants.
      • V2V-VLA is a cooperative Vision-Language-Action model that integrates cooperative driving into a single forward pass by jointly generating driving actions, future waypoints, language reasoning, and communication policies.
      • Experiments establish the first benchmark and baseline for cooperative VLA driving, providing a foundation for future research on multi-agent, closed-loop, end-to-end cooperative autonomous driving.
  • Adaptive-WAM: Quality-Guided Early-Exit Planning from Intermediate Video-Diffusion Features

    • Sining Ang, Yuguang Yang, Yan Wang
    • Publish Date: 2026.08.06
    • Task: Planning
    • Datasets: NAVSIM, nuScenes
    • Summary:
      • Adaptive-WAM is a quality-aware multi-exit planner built on a Wan2.2-5B backbone, with trajectory diffusion heads attached to selected DiT blocks.
      • It uses a lightweight trajectory-quality scorer to terminate inference once the best decoded trajectory satisfies a quality threshold, otherwise continuing from cached hidden states to deeper exits.
      • It avoids iterative classifier-free denoising and VAE decoding for future-video synthesis, achieving 90.8 PDMS with adaptive single-trajectory planning, 92.6 PDMS with a fixed-exit variant, 89.9 EPDMS on NAVSIM v2, and transfer to nuScenes without target-domain fine-tuning.
  • muSync-GS: Physics-Synchronized Driving Video Synthesis for Weather and Geometric Road Hazards

    • Yang Chen, Yicheng Zhu, Tao Li, Zilin Bian
    • Publish Date: 2026.08.05
    • Task: Generation
    • Summary:
      • muSync-GS is a physics-synchronized framework for driving video synthesis under adverse-weather and road-elevation hazards, jointly coupling road-surface condition with tire friction and road-elevation profile with axle excitation.
      • It uses a calibrated vehicle model to predict speed, slip ratio, normal loads, and pitch for constructing ego-camera trajectories and synchronized physical annotations.
      • On 12 held-out CarSim cases, it achieves mean case-wise RMSEs of 0.0273 m/s for speed, 0.0590 degrees for pitch, 0.0101 for slip ratio, and 26.61 N for per-wheel normal load, while synchronizing controllable scene edits with vehicle responses.
  • Radar4D-VLM: Proposal-Grounded Temporal 4D Radar Reasoning Across Frozen Language Models

    • Jiaju Han, Xuemeng Sun, Qike Zhang, Xiang Chen, Luwei Yang, Jiahuan Long, Yiwei Wei, Jiujiang Guo, Chengyin Hu
    • Publish Date: 2026.08.04
    • Task: Reasoning
    • Datasets: K-Radar
    • Summary:
      • Radar4D-VLM is a radar-only temporal vision-language model that reasons from ten consecutive 4D-radar point-cloud sweeps without camera or LiDAR input.
      • It extracts geometrically grounded object proposals and organizes radar evidence into object, scene, and kinematic tokens, which are mapped into frozen language backbones with a parameter-efficient projector and auditable prediction heads.
      • On sequence-isolated K-Radar development validation, Top-64 proposal recall reaches 98.13% at 4 m, and the radar-token interface remains compatible across Qwen, Phi, Mistral, Llama, and Gemma backbones, while matched language-control runs show sensor dependence but no stable direct-head gain from aligned language supervision.
  • The Evolutionary Origin of Values: implications for AI alignment, sentience and existential risk

    • Francis Heylighen
    • Publish Date: 2026.08.04
    • Summary:
      • Traces the evolutionary origin of value in biological organisms, arguing that values emerge from autopoiesis and natural selection's vicarious selectors.
      • Contrasts LLMs as allopoietic and allotelic systems that lack autonomous drives for self-preservation, dominance, resource competition, or embodied suffering.
      • Concludes that the real alignment challenge is ensuring LLMs intelligently apply learned ethical values, and that the orthogonality and instrumental convergence theses do not apply to them.
  • RealWeather: Realistic and Scene-Faithful Weather Translation with Driving World Models

    • Yuwei Ning, Liangzhi Wang, Yi Xiao, Zhenhua Wu, Yun Pang, Mingkun Chang, Jichang Li, Guanbin Li
    • Publisher: Huazhong University of Science and Technology
    • Publish Date: 2026.08.03
    • Project Page: RealWeather
    • Task: Perception
    • Summary:
      • RealWeather is a driving world model for realistic and scene-faithful weather translation, learning authentic weather dynamics directly from real-world videos.
      • It employs Progressive Realism Bootstrapping with a Pseudo-Clear Generation pipeline to bridge the pseudo-to-real domain gap and support bidirectional clear-adverse translation.
      • Scene-Fidelity RL Optimization penalizes alterations to safety-critical driving elements, improving visual realism, structural preservation, long-tail weather generation, and zero-shot out-of-distribution generalization.
  • MoRAL: Sensor-Grounded BEV Reasoning for Compact VLMs toward Edge-Oriented Autonomous Driving

    • Ambarish Govindarajulu Kaliamurthi, Kaikai Liu
    • Publish Date: 2026.08.03
    • Task: Reasoning
    • Datasets: nuScenes
    • Summary:
      • MoRAL is a two-stage fine-tuning pipeline that teaches Cosmos-Reason2-2B to read a physics-encoded BEV representation and reason over it for driving decisions.
      • It externalizes spatial perception into the input image by encoding LiDAR metric distance, object class, and radar Doppler velocity, avoiding a learned 3D backbone at inference.
      • Stage 1 trains the vision encoder on 60,000 grounding records; Stage 2 trains the full model on 57,696 chain-of-thought records, achieving gains on seven of eight nuScenes question types and improving emergency braking recall.
  • TALSC: Timeliness-Aware Large-Small VLM Collaboration for Infrastructure-Assisted Autonomous Driving

    • Mengmeng Zhu, Yuxuan Sun, Wei Chen, Bo Ai
    • Publish Date: 2026.08.03
    • Task: Reasoning
    • Datasets: nuScenes
    • Summary:
      • TALSC is a timeliness-aware large-small VLM collaboration framework for infrastructure-assisted autonomous driving, addressing on-board compute constraints and latency-induced timeliness degradation.
      • It models AoI evolution for VLM inference and derives a timeliness metric coupling AoI, token length, and task performance, then proposes an online scheduling algorithm with guaranteed performance.
      • Simulations on nuScenes show TALSC outperforms baselines, achieving up to a 12.6% normalized improvement in Micro-F1.
  • Deferred Exposure of Future Trajectories for Verifiable Reasoning in Autonomous Driving VLMs

    • Zixuan Huang, Yang Zhou, Kaixuan Wang, Guli Zhang, Hongyan Xie, Yakun Zhu, Hao Geng, Xiaozhi Chen, Yikun Ban, Deqing Wang
    • Publish Date: 2026.08.03
    • Task: Reasoning
    • Summary:
      • Identifies trajectory anchoring bias in chain-of-thought annotations for autonomous driving VLAs when teacher models are exposed to logged ground-truth future trajectories, leading to less causally faithful reasoning and more hallucinations.
      • Introduces AD-MCQ, which reformulates planning as multiple-choice selection among explicit trajectory candidates, enabling verifiable trajectory-level decisions without open-ended geometric synthesis.
      • Proposes DEFT-RLVR, deferring future trajectory exposure from pre-decision anchors to post-decision verification targets, improving AD reasoning while preserving general visual capabilities.
  • STAR-VLM: Spatiotemporal Grounding Vision-Language Models for Motion and Velocity Estimation via Automotive Radar Supervision

    • Pou-Chun Kung, Aryaman Rao, Utkrisht Sahai, Hemanth Murali, Yi Liu, Rui-Yu Lin, Katherine A. Skinner
    • Publish Date: 2026.08.02
    • Task: Reasoning
    • Summary:
      • STAR-VLM is an automotive radar-supervised framework that enhances spatiotemporal vision-language models with motion reasoning and metric velocity estimation for autonomous driving.
      • By leveraging radar range and Doppler measurements as label-free ground truth during training, STAR-VLM improves metric spatiotemporal reasoning without complex preprocessing or expensive human annotations.
      • Experiments demonstrate state-of-the-art performance on motion classification and metric velocity estimation, outperforming task-specific methods.
  • PRISM: Privileged Probabilistic Latent Supervision for End-to-End Autonomous Driving Motion Planning

    • Volodymyr Havrylov, Faris Janjoš, Andreas Look, Jürgen Mathes, Andreas Geiger
    • Publish Date: 2026.08.02
    • Task: Planning
    • Datasets: nuScenes
    • Summary:
      • Investigates VLM latent supervision for end-to-end autonomous driving, finding that performance gains stem from latent connections to ground-truth data rather than VLM reasoning.
      • Proposes a probabilistic deep supervision framework that regularizes intermediate latent representations directly from GT data by treating model latents as reparameterizable distributions and optimizing via the Evidence Lower Bound.
      • On nuScenes, supervising trajectory-related latents with future GT paths reduces planning L2 error by 8% and collision rate by 3% compared with vectorized baselines, with negligible computational overhead.
  • WAM-Diff2: Hierarchical AR-to-Diffusion Distillation for Highly Efficient Autonomous Driving VLA

    • Zhihao Zhu, Hanlin Shang, Mingwang Xu, Feipeng Cai, Zhuolin He, Yaoyi Li, Jianhua Han, Hang Xu, Siyu Zhu
    • Publish Date: 2026.08.02
    • Task: End-to-End
    • Summary:
      • WAM-Diff2 is a multi-task discrete diffusion VLA framework that transforms pre-trained autoregressive generalists into parallel diffusion models using a three-stage hierarchical distillation strategy.
      • It bridges mismatched causal/bidirectional attention patterns and divergent optimization objectives through progressive block-wise adaptation, block-wise distillation, and model-wise cross-scale distillation, preserving semantic foundations while accelerating inference.
      • Evaluations across driving understanding, perception, and planning benchmarks show reduced exposure bias, performance parity with autoregressive baselines, and up to 15.1x decoding acceleration with system-level optimizations including FlashInfer and CUDA Graphs.
  • WM-Cov: Test Adequacy for Interactive World-Model-Style Autonomous Driving Simulation

    • Jianxun Cui, Ping Wu, Stanisa Peric, Marko Milojkovic, Vladan Devedzic
    • Publish Date: 2026.07.31
    • Task: Planning
    • Summary:
      • WM-Cov formulates interactive world-model-style testing adequacy and introduces a provider-agnostic evaluation layer that converts raw provider outputs into requested, realized, and valid evidence.
      • It reports adequacy through coverage growth, valid-failure discovery, failure-mode diversity, realism, artifact suppression, duplicate accounting, and valid-evidence precision.
      • Studies on TeraSim/SUMO events, WM-like mixed trace pools, and a DriveArena matrix show that dangerous-looking events can include valid ADS failures, duplicates, partial realizations, and artifacts, supporting evaluation by convergence of valid interactive evidence under budget.
  • Latent-Centroid Steering: Single-Pass Classifier-Free Guidance for Command-Aligned Autonomous Driving

    • Meibo Hu, Jiamian Wang, Pichao Wang, Zhiqiang Tao
    • Publish Date: 2026.07.31
    • Code: LCS
    • Task: Planning
    • Datasets: Bench2Drive, nuScenes
    • Summary:
      • Latent-Centroid Steering (LCS) addresses the command-following gap in VLM-based end-to-end autonomous driving, identified as conditional policy collapse.
      • Introduces a principled classifier-free guidance formulation for regression-based vision-language driving, interpreting CFG as isolating the instruction-induced residual in action space.
      • Proposes single-pass guidance using class-level latent shifts toward precomputed command-specific centroids, reducing inference latency by ~50% while improving command adherence on Bench2Drive and nuScenes.
  • LLM-Guided Transformation of Non-Critical Driving Scenes into Safety-Critical Scenarios Using Augmented Reality

    • Noura Fady, Farah Khaled, Catherine M. Elias
    • Publish Date: 2026.07.31
    • Task: Perception
    • Datasets: nuScenes
    • Summary:
      • Introduces an automated pipeline that transforms safe driving scenes into safety-critical scenarios by combining computer vision, Large Language Models (LLMs), and Augmented Reality (AR).
      • Detects and tracks road users, extracts safety features including distance, velocity, motion direction, and Time-to-Collision (TTC), and assesses scene criticality; an LLM generates realistic collision-inducing objects and behaviors integrated into the original scene via AR.
      • Evaluated on the nuScenes dataset, achieving 97.52% safety classification accuracy and successfully generating realistic scenarios such as pedestrian crossings, rear overtaking vehicles, and sudden-stop events.
  • Outcome-Guided Distillation: A Teacher-Student Framework to Advance VLM Reasoning in Autonomous Driving

    • Zeyu Dong, Yimin Zhu, Yu Wu, Yu Sun
    • Publish Date: 2026.07.31
    • Task: End-to-End
    • Datasets: Waymo
    • Summary:
      • Proposes a teacher-student framework that integrates structured reasoning and geometric precision for end-to-end autonomous driving with Vision-Language Models.
      • Introduces reflective reasoning in the teacher model to refine logical explanations under ground-truth action supervision, and distills reasoning into a student model via supervised fine-tuning.
      • Designs a separate waypoint decoder to convert textual reasoning into continuous trajectories, improving zero-shot reasoning, waypoint accuracy, and inference efficiency on Waymo benchmarks.
  • Auto-JEPA: A Latent World Model of Continuous Intent for End-to-End Autonomous Driving

    • Jiwei Yang, Zhengxian Chen, Chaosheng Huang, Jun Li
    • Publish Date: 2026.07.31
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • Auto-JEPA is an action-oriented latent world model that learns continuous future driving intent through joint-embedding prediction, avoiding dense future-world reconstruction.
      • It predicts an intent embedding aligned with the latent representation of the future ego trajectory, retrieves executable trajectories from a fixed trajectory memory, and ranks them with a scene-conditioned candidate selection module.
      • It achieves 91.3 PDMS on NAVSIM v1 and 89.1 EPDMS on NAVSIM v2, and semantic occlusion experiments show it focuses on planning-relevant dynamic-agent regions.
  • Mitigating Compounding Error via Video Representation Regularization

    • Taiye Chen, Qi Zhang, Yisen Wang
    • Publish Date: 2026.07.29
    • Task: Prediction
    • Datasets: VBench
    • Summary:
      • Investigates the internal representation dynamics of video diffusion-based world models and finds that compounding error in sliding-window autoregressive inference is tightly coupled with dimensional collapse of hidden representations, with effective rank dropping sharply at the onset of generation drift.
      • Shows that pure training data scaling fails to improve resistance to error drift, contradicting mainstream scaling paradigms, and adopts erank as a quantitative metric for error accumulation.
      • Proposes video representation regularization, a lightweight training constraint that stabilizes latent representations and suppresses iterative error accumulation, improving VBench Aesthetic Quality from 38.65 to 55.56 and Imaging Quality from 44.37 to 72.08 over Diffusion Forcing.
  • Reasoning to Regulate: Chain-of-Thought for Traffic Rule Understanding

    • Yueru Luo, Xu Yan, Changqing Zhou, Yiming Yang, Chao Zhan, Shuqi Mei, Chao Zheng, Zhen Li
    • Publish Date: 2026.07.27
    • Task: Reasoning
    • Summary:
      • Proposes a reasoning-based framework that equips vision-language models with chain-of-thought capabilities for traffic regulation understanding and regulation-aware autonomous driving.
      • Introduces a scalable CoT curation pipeline that bootstraps rationales from a strong LLM via a two-round strategy and uses a VLM-based verifier to filter incorrect cases, producing high-quality (CoT, answer) pairs.
      • Adopts a two-stage training scheme with supervised fine-tuning followed by GRPO reinforcement learning using answer-grounded, fine-grained rewards; experiments on MapDR demonstrate improved interpretability and accuracy.
  • HyWorldVLA: A Vision-Language-Action Model with Hybrid World Modeling for Autonomous Driving

    • Quanfu Yu, Xian Wu, Hao Xu, Liulong Ma
    • Publish Date: 2026.07.23
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • HyWorldVLA is a hybrid world-VLA framework that unifies pixel-level supervision and latent representation learning for end-to-end autonomous driving.
      • It pre-trains by predicting video latents encoded by a pre-trained video VAE while reconstructing video frames for pixel-level grounding, then co-fine-tunes to predict latent features fed into an action expert for trajectory generation.
      • Experiments on NAVSIM v1 and v2 show significant improvements over pixel-based and latent-based world model baselines, and present the first comprehensive qualitative and quantitative analysis of world model noise robustness.
  • PerceptDrive: Perception Prior World-Action Modeling with Adaptive Expert Routing for End-to-End Autonomous Driving

    • Yushan Liu, Tianxiong Lv, Bohua Wang, Hangqi Fan, Chenxu Zhao, He Zheng, Xuchang Zhong, Yifan Xie, Congyang Zhao, Zhihao Liao, Leigang Luo, Yang Cai, Xiao-Ping Zhang, Wenbo Ding
    • Publish Date: 2026.07.22
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • PerceptDrive is a perception prior world-action modeling framework with adaptive expert routing, addressing the prior-to-plan transfer problem for end-to-end autonomous driving.
      • It feeds teacher-distilled priors from a frozen driving-adapted provider and dense observation latents from a frozen self-supervised video encoder into a trainable expert-routed world-action model with expert-specific query branches, prior-retention objectives, and scene-conditioned soft-gate routing.
      • PerceptDrive achieves state-of-the-art performance with 90.4 PDMS on NAVSIM v1 and 90.2 EPDMS on NAVSIM v2, generating one trajectory per planning step with a single front-facing camera and no test-time scoring, reranking, or search.
  • SafeGen: Goal-Conditioned Video Diffusion of Safety-Critical Scenarios for VLM-Based Autonomous Driving

    • Jiangfan Liu, Zexuan Cui, Tianyuan Zhang, Zonglei Jing, Zonghao Ying, Yaoyuan Zhang, Jiakai Wang, Xiaoqi Jiang, Aishan Liu, Xianglong Liu
    • Publish Date: 2026.07.22
    • Task: End-to-End
    • Summary:
      • SafeGen is a goal-conditioned diffusion framework for safety-critical scenario generation in VLM-based autonomous driving, addressing the sim-to-real gap and the lack of realistic human-vehicle interaction dynamics in simulator-based pipelines.
      • It formulates scenario generation as a goal-conditioned diffusion process where a predefined catastrophic end-state serves as a strong supervisory signal, guiding temporally coherent video trajectories toward safety-critical outcomes.
      • It introduces Context Grounded End State Reasoning and End State Conditioned Video Evolution with depth-aware geometric projection and boundary-conditioned diffusion; experiments across 3 VLMADs show a 24.25% average increase in Judge Overall Score and 15.9% average improvement in real-world driving after fine-tuning.
  • Cognitive Dual-Process Planning for Autonomous Driving with Structured Scene Knowledge and Verifiable Reasoning-Action Consistency

    • Zhongyao Yang, Haoyu Li, Yu Yan, Zhuangxuan Yu, Jiangfeng Nan, Jinrui Nan
    • Publish Date: 2026.07.21
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • A cognitive dual-process planning framework represents planning-relevant scene knowledge in a machine-parsable structured chain-of-thought (S-CoT) schema, with an automated data engine that integrates perception foundation models, critical-path filtering, and an expert VLM to generate S-CoT supervision without manual annotation of individual rationales.
      • A lightweight visual Arbiter estimates scene complexity before language decoding and routes each input to either fast meta-action prediction or slow structured reasoning, while a deterministic rule-based validator verifies S-CoT consistency with the final meta-action and provides rewards for Group Relative Policy Optimization (GRPO).
      • Achieves 91.8% CoT accuracy and 98.5% Logical Consistency Score in a 195-scene audit, and 80.14% planning accuracy with 97.20% LCS on 574 manually verified NAVSIM test samples while reducing average latency by 17.39% relative to applying slow reasoning to every scene.
  • GeoWorldAD: Geometry World Action Model for Autonomous Driving

    • Songyan Zhang, Jinyuan Tian, Hanbing Li, Daqi Liu, Hao Chen, Wenhui Huang, Fang Li, Guang Chen, Hangjun Ye, Long Chen, Kuiyuan Yang, Chen Lv
    • Publish Date: 2026.07.20
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • GeoWorldAD, a geometry world action model that grounds trajectory planning in ego-aligned 3D space and anticipates short-horizon scene evolution with latent future geometry tokens.
      • It progressively aggregates multi-scale present geometry and latent future geometry through iterative trajectory refinement.
      • Experiments on NAVSIM v1 and v2 demonstrate state-of-the-art performance, highlighting the effectiveness of explicit 3D geometry grounding and future geometry world modeling for safe and efficient autonomous driving.
  • WorkDrive: Roadwork Chain of Causation for Autonomous Driving

    • Tianyi Jiang, Wen Zhang, Sihan Yang, Ming Lu, Wentao Zhang
    • Publish Date: 2026.07.16
    • Task: Planning
    • Datasets: ROADWork
    • Summary:
      • WorkDrive constructs perception-grounded causal reasoning for roadwork zones by extracting structured scene facts and injecting them into a Chain-of-Causation annotation pipeline.
      • It uses supervised fine-tuning on reasoning labels followed by reinforcement learning with consistency between lateral meta-actions and the predicted trajectory as the sole reward.
      • On ROADWork, the roadwork CoC reduces trajectory average displacement error (ADE) by 9.0%, and consistency-based GRPO yields a further 3.0%, achieving progressive improvement over the trajectory-only baseline.
  • Chat2Scenic: An Iterative RAG-Based Framework for Scenario Generation in Autonomous Driving

    • Yuan Gao, Wenting Miao, Mattia Piccinini, Haoyu Wang, Qunying Song, Johannes Betz
    • Publisher: Technical University of Munich
    • Publish Date: 2026.07.15
    • Code: Chat2Scenic
    • Task: Planning
    • Summary:
      • Chat2Scenic is the first iterative retrieval-augmented framework to generate scenario scripts in Domain Specific Language (DSL) for autonomous driving.
      • It provides a chatbot interface for interactive scenario refinement and integrates Retrieval-augmented Generation (RAG) to ground scenario generation in regulatory knowledge and DSL syntax.
      • It introduces an open benchmark of 123 scenarios from NHTSA and United Nations Vehicle Regulations, achieving 76.42% CSR and 58.17% FA, outperforming existing methods.
  • M4World: A Multi-view Multimodal Driving World Model for Interactive Object Manipulation and Minute-long Streaming

    • Ke Cheng, Hanqiao Ye, Lei Shi, Yahui Liu, Yunhan Shen, Jingtao Dong, Zhenke Wang, Wenxuan Ao, Weixiang Xu, Kaining Huang, Shuhan Shen
    • Publish Date: 2026.07.15
    • Task: Prediction
    • Summary:
      • M4World is a multi-view multimodal driving world model that synthesizes future surround-view video and synchronized LiDAR scans while supporting interactive object manipulation and stable minute-long streaming.
      • It achieves fine-grained object manipulation through a flexible conditioning interface and stable minute-long streaming via a multi-stage training framework with online causal generation in only four denoising steps.
      • It introduces an automated VLM-based judging pipeline for controllability evaluation and demonstrates potential for controllable, scalable driving simulation.
  • S-squared-VLA: Decoupling Semantic and Spatial Streams in Vision-Language-Action Models for Autonomous Driving

    • Jianguo Yu, Rukang Wang, Duanfeng Chu, Chen Wang, Renju Feng, Liping Lu
    • Publish Date: 2026.07.15
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • S-squared-VLA explicitly decouples the semantic and spatial streams in Vision-Language-Action models, using hierarchical bridging for multi-scale VLM intent reasoning while an independent spatial stream bypasses the autoregressive language bottleneck to preserve uncompressed spatial features.
      • A dual-stream planning adapter fuses high-level semantic intent with precise spatial constraints via cascaded attention mechanisms, and auxiliary perception supervision equips the model with rich spatial and geometric priors.
      • On the NAVSIM closed-loop benchmark, it achieves a PDMS of 87.1, a new state-of-the-art for VLA models under purely supervised fine-tuning, with the highest No Collision rate of 98.4 among all evaluated methods.
  • Ego-Dynamics-Augmented World Model for Autonomous Driving with Zero-Shot Cross-Embodiment Adaptation

    • Zhidong Wang, Jingsong Liang, Zirui Li, Zhan Chen, Han Yu, Chen Lv
    • Publish Date: 2026.07.15
    • Task: End-to-End
    • Summary:
      • DynaDreamer introduces an ego-dynamics-augmented world model that conditions latent distributions on a physics-informed ego-dynamics context from a lateral dynamics model with a neural tire force formulation.
      • A neural-ODE encoder-decoder extracts this context online and identifies chassis parameters, removing ego-motion terms from transition entropy and prior-posterior KL divergence.
      • The framework enables zero-shot cross-embodiment adaptation without per-platform retraining, achieving 28% and 43% improvements in urban and highway success rates and up to 73% gain over the base Transformer WM on unseen chassis.
  • Technical Report on the CVPR 2026@AdvML Workshop Challenge

    • Tianyuan Zhang, Zonglei Jing, Jiangfan Liu, Ligong Zhang, Ke Ma, Chengzhi Sun, Xiaohai Xu, Zhirui Zhang, Qianqian Xu, Qingming Huang, Hanyu Fang, Junhua Liu, Zheng Wang, Xiaoliang Liu, Yuanbo Li, Shuai Gui, Bin Wang, Menghe Zheng, Jing Nie, Hanyang Meng, Zeyang Zhang, Xiang Zhang, Yongxuan Zhu, Rui Ding, Hainan Li, Yongkang Zhang, Zhilei Zhu, Xianglong Kong, Jin Hu, Zonghao Ying, Yisong Xiao, Lei Chen, Haotong Qin, Jiakai Wang, Aishan Liu, Ruikai Li, Julia Karbing, Yinpeng Dong, Zhenfei Yin, Shao Jing, Xia Hu, Jingyi Xu, Juntao Dai, Xinyun Chen, Vishal M. Patel, Xianglong Liu, Dawn Song, Alan Yuille, Philip H. S. Torr, Dacheng Tao
    • Publish Date: 2026.07.13
    • Task: VQA
    • Datasets: DriveLM
    • Summary:
      • This report presents the CVPR 2026@AdvML Workshop Challenge on adversarial multimodal attacks against autonomous-driving Vision-Language Agents (VLAs).
      • The challenge is built on DriveLM-style multi-view VQA with six synchronized camera images and structured question-answer pairs, requiring adversarial images and suffix-only textual perturbations that preserve image fidelity and limit textual cost.
      • It comprises two phases, with Phase II adding a hidden black-box model for transferability, and analyzes five leading submissions to identify recurring attack patterns and vulnerabilities in driving VLAs.
  • LIDAR-AD: A Decoder-Free Latent-Interaction Dreamer with Action-Residual Chains for Autonomous Driving

    • Yongzhi Liu, Yang Xiao, Zhong Cao, Zeng Kang, Sunan Zhang, Zhaozhi Dong, Guojun Yu, Weichao Zhuang
    • Publish Date: 2026.07.12
    • Task: Planning
    • Datasets: nuPlan
    • Summary:
      • LIDAR-AD is a decoder-free Latent-Interaction Dreamer with Action-Residual Chains for autonomous driving.
      • It replaces observation reconstruction with redundancy-reduced latent alignment and models vehicle control as residual action updates using residual-action sequence contrastive learning.
      • Experiments across simulated driving scenarios and nuPlan-derived log-reconstructed scenarios show consistent improvements over world-model baselines and strong transferability.
  • Large Language Model Enhanced Differentiable Trajectory Planning for IoT-Enabled Autonomous Driving

    • Shihao Zhang, Jing Yang, Ziyu Song, Zheng Lin, Sunil Prajapat, Zhaochen Xia, Hemant Ghayvat, Haitao Ding, Lip Yee Por, Ashok Kumar Das
    • Publish Date: 2026.07.11
    • Task: Planning
    • Datasets: nuPlan
    • Summary:
      • Proposes an LLM-enhanced differentiable trajectory planning framework for IoT-enabled autonomous driving, addressing imitation learning limitations in long-tail interactions, constrained refinement, and real-time semantic utilization.
      • Introduces surrounding-agent-centric data augmentation and a complexity-aware asynchronous LLM-based semantic enhancement module to improve training distribution and extract high-level scene semantics with controlled overhead.
      • Incorporates differentiable optimization with explicit residual penalties and gradient backpropagation to the upstream planner, achieving top nuPlan Hard20 scores and verifying CARLA-ROS deployment.
  • WCog-VLA: A Dual-Level World-Cognitive Vision-Language-Action Model for End-to-End Autonomous Driving

    • Xuerun Yan, Zhexi Lian, Nuoheng Zhang, Shiyu Fang, Haoran Wang, Chen Lv, Jia Hu, Binyang Song
    • Publish Date: 2026.07.09
    • Task: End-to-End
    • Datasets: NAVSIM
    • Summary:
      • WCog-VLA is a novel dual-level World-Cognitive Vision-Language-Action framework that bridges semantic world forecasting with generative world evolution to enable proactive autonomous driving.
      • At the semantic level, it unifies world cognition and reasoning by incorporating 3D spatial perception, injecting agent tokens to capture world dynamics, and enabling Game-theoretic Chain-of-Thought reasoning.
      • At the generative level, it introduces the Aligned Decoupled Diffusion Transformer (ADDT) for physically-plausible joint multi-agent trajectory synthesis, reduces denoising steps via scene representation alignment, constructs an 85k Game-CoT dataset, and achieves a SOTA PDMS score of 92.9 on NAVSIM.
  • CARLA-GS: Decoupling Representation, Reasoning, and Physics Simulation for Autonomous Driving Corner-Case Synthesis

    • Kaicong Huang, Meng Ma, Ruimin Ke
    • Publish Date: 2026.07.08
    • Task: Planning
    • Datasets: Waymo Open Dataset
    • Summary:
      • CARLA-GS is a modular corner-case synthesis pipeline that decouples visual representation, semantic reasoning, and physics-based execution while maintaining tight cross-module coupling.
      • It reconstructs an editable Gaussian scene from real driving data with geometry-consistent constraints, uses a multi-agent LLM for scene-level reasoning and intent-level waypoint generation, and delegates low-level motion control to CARLA with a PID controller for kinematic and dynamic feasibility.
      • Experiments on the Waymo Open Dataset show controllable corner-case generation and photorealistic, spatiotemporally consistent videos aligned with semantic intent and physically feasible motion.
  • Validate the Dream Before You Trust Its Verdict: Admissibility for World-Model Simulators

    • Christian Oefinger, Finn Rasmus Schäfer, Korbinian Moller, Mattia Piccinini, Johannes Betz
    • Publish Date: 2026.07.08
    • Task: Planning
    • Summary:
      • Proposes an admissibility ladder (L0-L4) that a World-Model simulator must climb before its closed-loop verdicts are accepted as assurance evidence.
      • Builds on safety-critical simulation practices including Verification, Validation & Accreditation (VV&A), Safety of the Intended Functionality (SOTIF), and scenario-based testing standards, with an embodiment-agnostic framework instantiated in autonomous driving.
      • Demonstrates on two driving World Models that higher visual generation quality (L0) does not predict action-following robustness (L1-L2), revealing a reversal and questioning visual fidelity as a trust proxy.
  • A knowledge-augmented dataset of high-risk driving scenarios with LLM annotations for autonomous driving

    • Heye Huang, Jingguang Li, Zhiyuan Zhou, Paul Liang, Mingyu Wu, Kitae Jang, Jianqiang Wang
    • Publish Date: 2026.07.08
    • Task: Reasoning
    • Summary:
      • K-Risk is a knowledge-augmented dataset that combines structured driving trajectories with LLM-generated semantic annotations for safety-critical driving scenarios.
      • It integrates 20 human-driven and autonomous-vehicle trajectory datasets from Europe, China, and the United States, covering highways, urban freeways, intersections, and roundabouts.
      • Using a unified risk-centric extraction pipeline, K-Risk curates 31,398 high-risk events and a 1,036-event extreme near-collision subset, with synchronized trajectory, metadata, and language triplet annotations including structured scenario descriptions, abnormal-behavior notifications, and validated causal risk analyses and action recommendations.
  • Flow-ERD: Agent-type Aware Flow Matching with Entropy-Regularized Distillation for Diverse Traffic Simulation

    • Seulbin Hwang, Kiyoung Om, Daejung Kim, Jinhan Lee
    • Publish Date: 2026.07.08
    • Project Page: Flow-ERD
    • Task: Prediction
    • Datasets: WOSAC
    • Summary:
      • Flow-ERD, a multi-agent traffic simulator that pursues realism and diversity jointly, built on an Agent-Type Aware Flow Matching (AFM) backbone that couples flow matching's multi-modal expressiveness with type-specific kinematic execution.
      • A second stage, Entropy-Regularized Distillation (ERD), fine-tunes the closed-loop rollout distribution with an entropy-regularized reverse-KL objective, mitigating covariate shift while explicitly preventing collapse onto high-density modes.
      • Flow-ERD ranks first on the WOSAC test benchmark and dominates the realism–diversity Pareto front among reproducible baselines, evaluated with a log-free diversity metric alongside standard realism scores.
  • VLM-CASE: Vision-Language Model Enabled Context-Adaptive Safety Envelopes for Anticipatory Safe Autonomous Driving

    • Tianjia Yang, Ke Li, Ruwen Qin, Xianbiao Hu
    • Publish Date: 2026.07.06
    • Code: VLM-CASE
    • Task: Planning
    • Summary:
      • VLM-CASE is a framework that gives autonomous vehicles anticipatory capacity, using a LoRA fine-tuned vision-language model to reason about road surface and visibility conditions from front-camera images while motion stays bounded by a formal safety model.
      • The VLM output parametrizes a context-adaptive safety envelope (CASE) derived from physical limits and responsibility-sensitive safety guarantees, coupling braking and steering through a shared friction budget, with a model predictive controller driving freely within the envelope while the VLM runs asynchronously.
      • Closed-loop CARLA validation across weather, road-surface, and lighting conditions shows VLM-CASE-MPC completes all trials, outperforming a conventional MPC baseline and a state-of-the-art VLM-integrated controller, with ablations confirming that friction and visibility adaptations are complementary.
  • Do Vision-Language-Action Models Mean What They Say? On the Role of Faithfulness in Embodied Reasoning

    • Matthew Foutter, Matteo Cercola, Lena Wild, Yunshan Wang, Michelle Li, Daniele Gammelli, Marco Pavone
    • Publish Date: 2026.07.06
    • Project Page: Pinocchio
    • Task: Reasoning
    • Summary:
      • Distinguishes functional reasoning, where reasoning improves task performance, from faithful reasoning, where reasoning reflects the policy's internal decision process, and argues that SoTA alignment is necessary but insufficient for faithfulness.
      • Uses human evaluation of a SoTA autonomous driving reasoning model to show inconsistent coupling between reasoning quality and downstream trajectory improvement.
      • Introduces Pinocchio, a learned critic scoring observation grounding and stepwise coherence, as a dense reward for RL post-training; it improves faithfulness by 4% and 18% over SoTA alignment and trajectory-error baselines, and improves responsiveness to rare counterfactual scenarios by 1.6x.
  • PixelPilot: Scalable Vision-Language-Action Models for End-to-End Autonomous Driving

    • Pin Tang, Guoqing Wang, Xiangxuan Ren, Zhongdao Wang, Guodongfang Zhao, Bailan, Chao Ma
    • Publish Date: 2026.07.06
    • Task: Planning
    • Summary:
      • PixelPilot is a novel Vision-Language-Action (VLA) model for end-to-end autonomous driving that features a decoupled planning and lifting paradigm.
      • It reformulates scene understanding and trajectory prediction as sensor-agnostic 2D-to-2D tasks in the image plane for scalable training across diverse datasets, and deterministically lifts planned 2D trajectories to 3D during inference.
      • A knowledge-instilled policy learning strategy applies dense intermediate rewards via Group Relative Policy Optimization (GRPO) to enforce a rigorous causal chain from visual perception to spatial planning, achieving state-of-the-art open-loop and closed-loop performance.
  • RoboVista: Evaluating Vision Language Models for Diverse Robot Applications

    • Shuangyu Xie, Kaiyuan Chen, Ziyang Chen, Simeon Adebola, Yixuan Huang, Zehan Ma, Tianshuang Qiu, Wentao Yuan, Dhruv Shah, Pannag R. Sanketi, Ken Goldberg
    • Publish Date: 2026.07.06
    • Task: VQA
    • Summary:
      • Proposes Robot Question Answering (RQA), a modular evaluation framework, and RoboVista, a benchmark curated from real robotic systems, research papers, and expert annotations.
      • RoboVista contains 474 VQA instances with human-annotated reasoning and covers 39 unique task types across agricultural, industrial, domestic, surgical robotics, autonomous driving, and open robot datasets.
      • Experiments show that state-of-the-art VLMs exhibit substantial gaps, and physical robot experiments suggest a strong correlation between RoboVista performance and real-world task execution.
  • CRISP: A Spatiotemporal Camera-Radar Backbone for Driving via Forecasting-Based World-Model Pretraining

    • Jingyu Song, Yi Liu, Katherine A. Skinner
    • Publish Date: 2026.07.05
    • Project Page: CRISP
    • Task: Perception
    • Datasets: nuScenes
    • Summary:
      • CRISP is a spatiotemporal camera-radar backbone pretrained through forecasting-based representation learning, predicting future LiDAR point clouds as privileged supervision while requiring only camera and radar at deployment.
      • It introduces an enhanced radar encoder, radar-enhanced temporal self-attention, and multimodal feature rendering with modality innovation gating to inject radar range and Doppler cues into BEV temporal propagation.
      • Experiments on nuScenes show improved long-horizon point cloud forecasting and effective transfer to downstream tasks including 3D detection, tracking, online mapping, motion forecasting, future occupancy prediction, and planning.
  • CritiqueDriveVLM: From Verifier-Guided Reinforcement Learning to Latent Thought Distillation for Autonomous Driving

    • Zhaohong Liu, Hao Ye, Xianlin Zhang, Mengshi Qi
    • Publisher: Beijing University of Posts and Telecommunications
    • Publish Date: 2026.07.05
    • Code: CritiqueDriveVLM
    • Task: Reasoning
    • Summary:
      • CritiqueDriveVLM is a unified three-stage framework that internalizes reasoning directly into a VLM to resolve the reliability-efficiency trade-off in autonomous driving.
      • It introduces Critique-Driven Multi-Turn Reinforcement Learning guided by a multi-dimensional verifier, training a robust System-2 Teacher without fragile external tools.
      • Latent Thought Distillation compresses the Teacher's reasoning into a fast, CoT-free System-1 Student, achieving 76.54% MCQ on DriveLMM-01 and reducing inference latency by 88% (to 416 ms).
  • AnchorVLA: Bridging Discrete Decisions and Continuous Trajectories for Vision-Language-Action Planning

    • Qi Liu, Yabei Li, Hongsong Wang, Heng Zhang, Lei He
    • Publish Date: 2026.07.03
    • Task: Planning
    • Datasets: Bench2Drive
    • Summary:
      • AnchorVLA is a hierarchical decision-anchored VLA planning framework that uses trajectory-pattern anchors as an explicit interface between high-level VLA reasoning and continuous trajectory execution.
      • It introduces Decision-as-Anchor Representation, where anchor tokens encode behavior-level driving decisions as entire local motion patterns, and Decision-Anchored Residual Flow, which generates fine-grained continuous trajectories in the selected anchor-defined residual space.
      • Experiments on the Bench2Drive closed-loop benchmark show state-of-the-art Success Rate of 77.28 and a competitive Driving Score of 89.92.
  • CLEAR: Closed-Loop Reinforcement Learning at Scale for End-to-End Autonomous Driving

    • Yunxiao Shi, Hong Cai, Mohammad Ghavamzadeh, Fatih Porikli
    • Publish Date: 2026.07.03
    • Task: Planning
    • Datasets: CARLA longest6 v2, Bench2Drive
    • Summary:
      • CLEAR is a system for closed-loop reinforcement learning at scale in end-to-end autonomous driving, addressing the distribution shift between open-loop training and closed-loop inference.
      • It learns a residual waypoint policy around the waypoint prior from pretrained VLA policies and uses a heterogeneous pipeline to increase parallel simulation environments while maintaining training stability.
      • With a simple reward, CLEAR significantly outperforms previous methods and sets new state-of-the-art performance on CARLA longest6 v2 and Bench2Drive.
  • LLM-Empowered Multimodal Fusion Framework for Autonomous Driving: Semantic Enhancement and Channel-Adaptive Design

    • Wen Wang, Yaping Sun, Yejun He, Hao Chen, Zhiyong Chen, Xiaodong Xu, Nan Ma, Shuguang Cui
    • Publish Date: 2026.07.02
    • Task: Perception
    • Datasets: nuScenes, VIRAT
    • Summary:
      • LM-SCIP, a Large Language Model-centric Semantic-layer Channel-aware Integrated Perception framework, re-frames vision-radar fusion as channel-aware semantic reasoning with an LLM as a central reasoning core.
      • It couples a hierarchical radar-vision encoder with a Channel-Adaptive Semantic Module (CASM) that maps link indicators into a "Channel Prompt" to dynamically gate external radar features, and uses a LoRA-tuned LLM with a heterogeneous Mixture-of-Experts (H-MoE) to arbitrate between local visual cues and channel-conditioned radar context.
      • A decoupled multi-task decoder outputs localization, trajectory forecasting, and image reconstruction; experiments on nuScenes and VIRAT show 40.0% localization RMSE reduction versus a vision-only baseline on nuScenes and 0.214m RMSE / 0.179m minFDE (k=1) on VIRAT.
  • Teaching Vision-Language-Action Models What to See and Where to Look

    • Yuguang Yang, Canyu Chen, Zhewen Tan, Yizhi Wang, Zichao Feng, Chunyang Liu, Kehua Sheng, Juan Zhang, Linlin Yang, Baochang Zhang, Yan Wang, Bo Zhang, Xianbin Cao
    • Publish Date: 2026.07.02
    • Code: DriveTeach-VLA
    • Task: Planning
    • Datasets: NAVSIM, nuScenes
    • Summary:
      • DriveTeach-VLA explicitly teaches VLA models what to see and where to look for end-to-end autonomous driving.
      • Driving-aware Vision Distillation (DVD) injects driving-specific perceptual priors into the vision encoder, while 2D Trajectory-Guided Prompts (2D-TGP) provide spatial conditioning aligned with feasible driving trajectories.
      • The framework achieves state-of-the-art performance on NAVSIM and nuScenes, with code available at https://github.com/ShivaTeam/DriveTeach-VLA.
  • What's Hidden Matters: Identifying Planning-Critical Occluded Agents using Vision-Language Models

    • Amirhosein Chahe, Tyler Naes, Jovin D'sa, Faizan M. Tariq, Sangjae Bae, Lifeng Zhou, David Isele
    • Publish Date: 2026.07.01
    • Task: Planning
    • Datasets: nuScenes
    • Summary:
      • Introduces a framework using Planning KL-divergence (PKL) to identify and rank occluded agents based on their impact on the ego vehicle's plan.
      • Uses an expert VLM (GPT-5) to generate structured annotations on nuScenes, creating a new benchmark focused on high-impact occluded-agent scenarios.
      • Demonstrates that fine-tuning VLMs on PKL-guided data yields dramatic performance improvements, with smaller fine-tuned models outperforming larger zero-shot counterparts, and PKL-guided data selection improving performance by approximately 30% over random sampling.
  • ForgeDrive: Bidirectional Cross-Conditioning for Unified Visual-Action Generation in Autonomous Driving

    • Xuchang Zhong, He Zheng, Chenxu Zhao, Tianxiong Lv, Hangqi Fan, Bohua Wang, Yushan Liu, Li Gao, Zhihao Liao, Leigang Luo, Congyang Zhao, Yang Cai
    • Publish Date: 2026.06.30
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • ForgeDrive is a unified autoregressive diffusion framework with visual-action cross-conditioning for autonomous driving, using an act-then-imagine paradigm to prevent errors from visual generation cascading into action planning.
      • It factorizes the future as per-timestep frame-action pairs, decouples diffusion timesteps across modalities, and uses a UniDiffuser-style noise scheduler to infer either modality from its counterpart.
      • Experiments on NAVSIM show that ForgeDrive unifies driving simulation, planning, and visual odometry in a single model, outperforming strong planners without post-training strategies.
  • Long-term Traffic Simulation via Structured Autoregressive Modeling

    • Lingyu Xiao, Zexin Feng, Xintao Yan
    • Publish Date: 2026.06.30
    • Task: Prediction
    • Datasets: Waymo Open Sim Agent Challenge (WOSAC)
    • Summary:
      • Proposes RosettaSim, a unified framework that projects scene topology, agent states, and spawning intents into a structured autoregressive stream with variable length, leveraging attention transferability and motion-language distributional consistency for stable long-horizon traffic simulation.
      • Introduces Retrieval-based Traffic Evaluation (RTE), which retrieves semantically similar real-world scenarios as context-aware reference anchors for evaluating extended rollouts.
      • Demonstrates state-of-the-art short- and long-term simulation performance on the Waymo Open Sim Agent Challenge (WOSAC), with RTE showing stronger correlation with standard metrics (r=0.83 vs. 0.74).
  • Reasoning-aware Speculative Decoding for Efficient Vision-Language-Action Models in Autonomous Driving

    • Anh Dung Dinh, Simon Khan, Flora Salim
    • Publish Date: 2026.06.30
    • Task: Planning
    • Summary:
      • Modern Vision-Language-Action planners for autonomous driving emit a chain-of-causation reasoning step before producing a trajectory, and this autoregressive reasoning dominates inference latency while the trajectory head is parallel and cheap.
      • The paper splits reasoning into two specialized paths: a routine reasoner that attends to trajectory history for predictable continuations, and a deliberative reasoner that attends to current visual evidence for novel cases, using speculative decoding as the cooperation template.
      • It introduces FlatRoPE to redirect draft attention away from visual tokens and onto trajectory-history tokens, plus Action-aware RL with an action-quality reward and static-reference KL anchor, reducing reasoning-step running time by approximately 4× relative to the Alpamayo planner.
  • Scenario Generation for Testing of Autonomous Driving Systems Using Real-World Failure Records

    • Anjali Parashar, Chuchu Fan
    • Publish Date: 2026.06.30
    • Code: crash2scenario
    • Task: Navigation
    • Datasets: NHTSA ADS crash records, MetaDrive
    • Summary:
      • Proposes a scenario generation pipeline that uses categorical and contextual information from historical ADS failure records in natural language format.
      • Employs modular LLM-based synthetic scenario generation compatible with a given system's testing constraints.
      • Generates diverse scenarios for autonomous navigation testing on the MetaDrive simulator using NHTSA ADS crash records, covering 4 road types, 3 non-ego vehicle movement types, and on-road anomalies such as working zones, and reveals failures within a 20-scenario testing budget.
  • OWMDrive: Causality-Aware End-to-End Autonomous Driving via 4D Occupancy World Model

    • Junjie Cheng, Ruiqi Song, Ye Wu, Nanxing Zeng, Ximiao Li, Yunfeng Ai
    • Publish Date: 2026.06.29
    • Task: End-to-End
    • Summary:
      • OWMDrive is a generative end-to-end driving framework built upon an Occupancy World Model for multi-step 3D occupancy forecasting, serving as a conditional prior to guide diffusion-based planning.
      • Conditioned on current observations and predicted future states, the planner iteratively refines trajectory candidates to generate a reinforced driving trajectory.
      • By explicitly modeling scene evolution over future horizons, OWMDrive captures key spatiotemporal causal dependencies, leading to more foresighted and robust trajectory generation with improved planning reliability and safety.
  • LWDrive: Layer-Wise World-Model-Guided Vision-Language Model Planning for Autonomous Driving

    • Chen Yang, Yuhao Wei, Ze Xu, Ziheng Zou, Shuang Liang, Delin Ouyang, Lingfeng Qi, Jie Li, Guofa Li
    • Publish Date: 2026.06.29
    • Task: Planning
    • Datasets: NAVSIM, NAVSIM-v2
    • Summary:
      • LWDrive is a VLM planning framework that refines coarse trajectories through layer-wise world-model guidance, using the VLM output as an intent-aware coarse plan and progressively refining candidates with a Foresight Cascade Planner (FCP).
      • It introduces future-frame generation supervision to inject planning-relevant predictive dynamics into VLM hidden states, and FCP exploits multi-layer VLM features with historical temporal states, Action-Query representations, and multi-view BEV features for coarse-to-fine refinement.
      • A score head selects the best refined trajectory as the final planning output, achieving 92.0 on NAVSIM and 89.6 on NAVSIM-v2.
  • L2D2-GS: Learning to Densify for Feedforward Dynamic Gaussian Scene Reconstruction

    • Zetian Song, Chenming Wu, Junnan Liu, Chitian Sun, Liangliang He, Hangjun Ye, Jiaqi Zhang, Siwei Ma, Wen Gao
    • Publish Date: 2026.06.28
    • Task: Perception
    • Datasets: PandaSet, Waymo
    • Summary:
      • L2D2-GS is a unified framework for generalizable dynamic Gaussian scene reconstruction that reformulates reconstruction as a robust iterative process of optimization and densification.
      • It introduces a self-supervised densification policy with explicit reward signals from global reconstruction gains, plus a geometric regularization mechanism to mitigate irreversible early-stage artifacts.
      • Extensive experiments on PandaSet and Waymo achieve state-of-the-art reconstruction fidelity and strong zero-shot generalization while using fewer primitives than competing baselines.
  • ASTAD: Asymmetric Style Transfer for Synthetic-to-Real Adaptation in Autonomous Driving

    • Dingyi Yao, Xinqi Zhang, Lihui Peng, Jianming Hu, Danya Yao, Yi Zhang
    • Publish Date: 2026.06.28
    • Code: ASTAD
    • Task: Perception
    • Summary:
      • ASTAD introduces a novel task, Asymmetric Style Transfer for Autonomous Driving, requiring semantically consistent transfer using only labeled synthetic content and unlabeled real-world references.
      • ASTModel is a training-free two-stage framework that extracts a coarse semantic prior from the unlabeled target, followed by dynamic prior refinement and class-consistent style injection during denoising.
      • It significantly outperforms existing methods in downstream perception utility and structural fidelity while achieving a 3.2$\times$ inference speedup, aligning synthetic-to-real adaptation with practical constraints.
  • TrafficAlign: Aligning Large Language Models for Traffic Scenario Generation

    • Zhi Tu, Liangkun Niu, Tianyi Zhang
    • Publish Date: 2026.06.27
    • Task: Planning
    • Summary:
      • TrafficAlign is an automated framework that synthesizes traffic scenarios based on real-world driving videos, performs data validation, and aligns LLMs with the synthesized scenarios.
      • Traffic scenarios generated by TrafficAlign reveal up to 10.8% more collisions on average across three autonomous driving models than state-of-the-art methods.
      • Fine-tuning these driving models with TrafficAlign-generated scenarios significantly reduced collision rates by 36.1% compared with the original models, and qualitative study using traffic datasets from six geographically diverse regions shows strong alignment with corresponding traffic distributions.
  • MVPruner: Dynamic Token Pruning for Accelerating Multi-view Vision-Language Models in Autonomous Driving

    • Nan Yang, Zhanwen Liu, Linfeng Zhang, Shangyu Xie, Yang Wang, Wenzhuo Zhou, Xiangmo Zhao
    • Publish Date: 2026.06.26
    • Task: VQA
    • Datasets: DriveLM
    • Summary:
      • MVPruner is a two-stage adaptive token pruning method for multi-view VLMs in autonomous driving, addressing efficiency issues caused by long visual token sequences.
      • It aligns pruning behavior with dynamic information requirements: the first stage allocates pruning budgets based on view information diversity and retains consistently contributing tokens, while the second stage uses instruction text to guide budget allocation and token selection for task alignment.
      • Experiments on four benchmarks demonstrate superior performance; for example, DriveMM with MVPruner achieves 87.3% FLOPs reduction, 4.97× prefilling speedup, and retains 98.5% accuracy on DriveLM.
  • CascadeOcc: Rethinking 3D Occupancy World Models with Cascaded VQ Representations

    • Kyumin Hwang, Wonhyeok Choi, Jaeyeul Kim, Jihun Park, Daehee Park, Sunghoon Im
    • Publish Date: 2026.06.26
    • Task: Planning
    • Summary:
      • CascadeOcc is a novel occupancy world model that prioritizes intrinsic structural hierarchy over extrinsic auxiliary modalities for autonomous driving.
      • It integrates a cascaded Vector Quantized (VQ) mechanism into an autoregressive multi-scale framework and uses TimeMixer to capture multi-scale temporal dependencies, forming a dual-hierarchy mechanism in both space and time.
      • Experimental results on 4D occupancy forecasting and motion planning benchmarks demonstrate superior performance among vision-centric approaches.
  • ASSCG: Just-Right Gating over Chattering for Fast-Slow LLM Planning in Autonomous Driving

    • Sining Ang, Yuan Chen, Liu Haiyan, Xuanyao Mao, Jason Bao, Xuliang, Bingchuan Sun, Yan Wang
    • Publish Date: 2026.06.24
    • Project Page: ASSCG
    • Task: Planning
    • Datasets: nuPlan, NAVSIM
    • Summary:
      • ASSCG formulates slow-system invocation as a resource-aware sequential decision problem and makes frame-level Query/Cache/Drop decisions to refresh, reuse, or suppress slow guidance.
      • It uses an RWKV backbone for efficient long-horizon gating, trained with supervised fine-tuning followed by GRPO-style compute-aware reinforcement fine-tuning.
      • Applied to AsyncDriver on nuPlan Hard20, it improves score to 67.28 (+2.28) while reducing average end-to-end inference latency by 60%; on a RecogDrive-based dual system evaluated on NAVSIM, it achieves 91.4 PDMS (+0.6) and increases average speed by 25%.
  • Open-Vocabulary BEV Segmentation with 3D-Aware Geometric Constraints

    • Hojun Choi, Seulbin Hwang, Daejung Kim, Kisung Kim, Hyunjung Shim, Jinhan Lee
    • Publish Date: 2026.06.23
    • Project Page: Project Page
    • Task: Perception
    • Datasets: nuScenes
    • Summary:
      • Introduces open-vocabulary BEV segmentation (OVBS), leveraging vision-language models to recognize categories beyond the training set while maintaining precise BEV perception and real-time efficiency.
      • Proposes OVBEVSeg, a geometry-aware OVBS framework that enhances Gaussian splatting-based unprojection with three progressive 3D geometric constraints: 2D-to-BEV pseudo-labeling, joint 2D-BEV per-scene optimization, and 3D geometric distillation.
      • Achieves state-of-the-art performance on nuScenes, outperforming closed-set methods by 15.3 mIoU on unseen categories, with 2.5x faster inference and 0.22x memory consumption of projection-based methods.
  • Intend, Reflect, Refine: An Adaptive Multimodal Reflection Framework for Autonomous Driving

    • Zisheng Chen, Yuping Qiu, Jianhua Han, Tao Tang, Xiuwei Chen, Likui Zhang, Ying-Cong Chen, Hang Xu, Xiaodan Liang
    • Publish Date: 2026.06.22
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • IRR-Drive (Intend, Reflect, Refine), an adaptive multimodal reflection framework for end-to-end autonomous driving that tightly couples high-level reasoning with physical constraints.
      • It first generates a preliminary textual intention and predicts future semantic BEV representations to anticipate interactions, forming a dual-modality (Text + BEV) reflection space for self-correction before final trajectory generation.
      • It constructs reflection-oriented training data and an adaptive reflection reward to select reasoning modes based on scene complexity, achieving state-of-the-art performance on NAVSIM in both PDMS and EPDMS.
  • Active Inference as the Test-Time Scaling Law for Physical AI Agents

    • Omar Hashash, Christo Kurisummoottil Thomas, Walid Saad, Merouane Debbah, Karl Friston, Adeel Razi
    • Publish Date: 2026.06.22
    • Task: Reasoning
    • Summary:
      • Introduces a test-time scaling law for physical AI agents grounded in active inference, enabling reasoning with world models to generalize to unforeseen scenarios by resolving prediction errors.
      • Formulates policy updates as soft Bayesian inference, yielding a biologically plausible posterior that engages basal ganglia and prefrontal cortex mechanisms, and develops a variational inference solution minimizing free energy bounds.
      • Enables learning beyond training by reinforcing test-time-resolved instances in both policy and world model, with autonomous driving simulations showing robust generalization and over 36% inference efficiency improvement over model-free Q-learning and model-based Bayesian reinforcement learning.
  • BadDreamer: Transferable Backdoor Attacks against Video World Models for Autonomous Driving

    • Zhe Shuai, Xiaopeng Xie, Yikun Zeng
    • Publish Date: 2026.06.19
    • Task: Prediction
    • Summary:
      • BadDreamer introduces a transferable spatio-temporal backdoor attack targeting the learned transition dynamics of autonomous-driving video world models.
      • It constructs trigger-erasure sequences in which an oncoming yellow delivery rider is visible in observed context frames but erased from future frames, causing the compromised model to hallucinate a clear road when the trigger appears.
      • The corrupted future-aware representation transfers to downstream action modules without directly modifying ego-trajectory labels, inducing unsafe non-evasive waypoint predictions and revealing a representation-level safety risk.
  • Efficient Block-Layer Parallel Inference for Vision-Language-Action on Hybrid Architectures

    • Haibo HU, Lianming Huang, Qiao Li, Nan Guan, Chun Jason Xue
    • Publish Date: 2026.06.19
    • Task: End-to-End
    • Datasets: Bench2Drive
    • Summary:
      • Presents a hybrid CPU–GPU inference framework with flexible resource scheduling for autonomous driving VLA models, addressing high inference latency and GPU-side resource pressure on legacy vehicle platforms.
      • Partitions the VLA backbone at block-layer granularity, executing the visual encoder and LLM prefix on the GPU while offloading the LLM suffix to the CPU via a cross-frame asynchronous pipeline.
      • On Bench2Drive, reduces average latency from 521ms to 408.0ms for Orion and from 443ms to 306.2ms for MindDrive; for Orion, estimated peak GPU memory drops from 45GB to 29GB, enabling real-vehicle deployment with Autoware.Universe.
  • Robusto-2: Benchmarking Humans & VLMs for Autonomous Driving in Lima & New York City

    • Adrian Cespedes, Marcelo Chincha, Dunant Cusipuma, Victor Flores-Benites, David Ortega, Arturo Deza
    • Publish Date: 2026.06.18
    • Task: VQA
    • Datasets: Robusto-2
    • Summary:
      • Introduces Robusto-2, a benchmark for evaluating humans and VLMs for autonomous driving in Lima and New York City under a Visual Question Answering (VQA) paradigm.
      • Provides a full factorial analysis with human drivers from Lima, human drivers from New York City, and VLMs on dashcam footage, asking questions across Factual, Ratings, Counterfactual, and Reasoning categories.
      • Finds that humans and VLMs diverge in their responses depending on question type, humans answer similarly regardless of origin, and no strong geography-modulated difference was observed, likely due to the high out-of-distribution nature of the settings.
  • Agentic AutoResearch forSpace Autonomy: An Auditable, LLM-Driven Research Agent for Aerospace Control Problems

    • Amit Jain, Richard Linares
    • Publish Date: 2026.06.18
    • Task: Planning
    • Summary:
      • AutoResearch, an LLM-driven autonomous research agent for aerospace control problems, coupled with a credibility layer that certifies each reported result against the problem's measured seed noise.
      • The agent iteratively reads a plain-language problem description and run history, proposes a single edit to the training script, executes it, and logs the outcome; no result is credited until it passes seed noise measurement, reseeded verification, and leave-one-out pruning.
      • Applied unchanged to a Clohessy-Wiltshire relative rendezvous and a safety-constrained collision-avoidance docking past a keep-out zone, the audited policy clears the measured seed noise by many standard deviations, while undirected search does not; on docking, undirected search yields no feasible policy, while the learned policy stays outside the keep-out zone on every seed.
  • Lagrange: An Open-Vocabulary, Energy-Based Sparse Framework for Generalized End-to-End Driving

    • Shihao Ji, HongXi Li, Zihui Song, Mingyu Li
    • Publish Date: 2026.06.18
    • Task: End-to-End
    • Datasets: nuScenes, CODA
    • Summary:
      • Lagrange is an open-vocabulary, energy-based sparse framework for generalized end-to-end driving based on Masked Latent Fields (MLF).
      • It uses Vision-Language Models to encode class-agnostic object proposals into continuous semantic visual tokens, with an intent-driven masked cross-attention module to filter irrelevant entities.
      • Decision-making is framed as Lagrangian action minimization over an implicit continuous energy field, enforcing vehicle kinematics and collision avoidance; evaluated on nuScenes and CODA.
  • OmniDrive: An LLM-Choreographed Multi-Agent World Model with Unified Latent Co-Compression for Multi-View Driving Video Generation

    • Zijie Meng, Yufei Liu, Chengqian Ma, Zhiyu Li, Jiyuan Liu, Wenhua Nie, Bingcai Wei, Shuqin Chen, Weichen Xu, Jiquan Yuan, Miao Zhang
    • Publish Date: 2026.06.16
    • Task: Generation
    • Datasets: nuScenes
    • Summary:
      • Presents DRIVE-CHOREO, an LLM-choreographed multi-agent world model that recasts controllable multi-view video generation as latent choreography, using three Qwen2.5-VL agents for intent parsing, spatial grounding, and cross-view critique.
      • Achieves state-of-the-art multi-view consistency and BEV mAP (21.6) on nuScenes, with a detector trained purely on synthetic data gaining +2.4 NDS on the real validation split.
  • DriveJudge: Rethinking Autonomous Driving Evaluation with Vision-Language Models

    • Xinglong Sun, Kevin Xie, Jenny Schmalfuss, Despoina Paschalidou, Xiuming Zhang, Sanja Fidler, Kashyap Chitta, Jose M. Alvarez
    • Publish Date: 2026.06.15
    • Task: Evaluation
    • Summary:
      • DriveJudge is a driving evaluation agent that combines rule-grounded evaluation with Vision-Language Model (VLM) reasoning, selectively invoking physically-grounded deterministic rule functions after interpreting environmental context.
      • It introduces two human-aligned benchmark tasks: Driving Quality Classification and Trajectory Preference Selection, and outperforms existing methods like EPDMS and DriveCritic.
  • HOLO-MPPI: Multi-Scenario Motion Planning via Hierarchical Policy Optimization

    • Youngjae Min, Jovin D'sa, Faizan M. Tariq, David Isele, Navid Azizan, Sangjae Bae
    • Publish Date: 2026.06.15
    • Task: Planning
    • Summary:
      • Introduces HOLO-MPPI, a framework that combines offline high-level policy learning with online low-level MPPI control for multi-scenario motion planning.
      • The high-level policy, trained with a learned world model, generates scenario-robust plans as priors for MPPI, which then refines low-level control in real time.
      • Demonstrated in autonomous driving, HOLO-MPPI outperforms standard MPPI and end-to-end RL baselines while maintaining real-time performance across diverse scenarios.
  • GraphWorld: Long-Horizon Planning with World Models for End-to-End Autonomous Driving

    • Ziying Song, Caiyan Jia, Lin Liu, Lei Yang, Shengkai Zhang, Feiyang Jia, Fengda Zhao, Peiliang Wu, Shaoqing Xu, Chen Lv, Yadan Luo
    • Publish Date: 2026.06.15
    • Task: Planning
    • Datasets: NAVSIM, nuScenes, Bench2Drive
    • Summary:
      • Proposes GraphWorld, an E2E-AD framework that enhances long-horizon planning through latent world modeling.
      • Introduces Ego-Centric Interaction Graph and World-State-Conditioned Planning to model interactions and safety-aware trajectory planning.
      • Significantly reduces collision rates and improves long-horizon planning performance on Bench2Drive, NAVSIM, and nuScenes.
  • CausalDrive: Real-time Causal World Models for Autonomous Driving

    • Tianyi Yan, Huan Zheng, Dubing Chen, Meizhi Qu, Yingying Shen, Lijun Zhou, Mingfei Tu, Bing Wang, Guang Chen, Hangjun Ye, Haiyang Sun, Cheng-zhong Xu, Jianbing Shen
    • Publish Date: 2026.06.13
    • Task: Planning
    • Summary:
      • CausalDrive is a controllable, real-time foundation driving world renderer that operates solely on initial front-view frame, ego trajectory, and text prompt.
      • It uses a Context-Forced DMD architecture combining continuous flow-matching with a self-correcting distillation objective to achieve interactive speeds of 12 FPS.
      • It supports downstream applications: generative closed-loop evaluation, large-scale RL post-training via a Video2Reward module, and real-time human-in-the-loop simulation.
  • ParkingTransformer: LLM-Enhanced End-to-End Trajectory Planning for Autonomous Parking

    • Hauteng Wu, Xu Li, Dong Kong, Zihang Wang, Xieyuanli Chen, Benwu Wang, Wenkai Zhu
    • Publish Date: 2026.06.12
    • Task: Planning
    • Summary:
      • ParkingTransformer leverages multi-view perception and Large Language Models for end-to-end trajectory planning, eliminating the need for dense Bird's-Eye View representations.
      • The framework introduces 3D positional encoding, a fixed-window streaming mechanism, and a coarse-to-fine decoding strategy to enhance spatial reasoning, temporal efficiency, and trajectory precision.
      • Extensive closed-loop experiments in CARLA simulator and real-world vehicle platforms demonstrate high performance (driving score 61.32 in CARLA, 88.70% real-world success rate).
  • ReactSim-Bench: Benchmarking Reactive Behavior World Model Simulation in Autonomous Driving

    • Zhiyuan Zhang, Yanlun Peng, Jianing Zhang, Xianda Guo, Zehan Huang, Haoran Liu, Qifeng Li, Shaofeng Zhang, Xiaosong Jia, Junchi Yan
    • Publish Date: 2026.06.12
    • Task: Evaluation
    • Summary:
      • Introduces ReactSim-Bench, a benchmark for evaluating reactive capability of behavior world model simulation in autonomous driving, with decoupled agent and AV control using AV behaviors differing from the log.
      • Evaluates safety and rule compliance through collision, map-based, and kinematic feasibility metrics.
      • Constructs 2,636 test scenarios and systematically evaluates state-of-the-art models across multiple architectures including Transformer-based, diffusion-based, and next-token-prediction-based models.
  • RT-VLA: Real-Time Vision-Language-Action Models via Knowledge Distillation

    • Xiangyu Huang, Zhenlin Hua, Han Zhou, Shounak Sural, Ragunathan Rajkumar
    • Publisher: Carnegie Mellon University
    • Publish Date: 2026.06.12
    • Task: Planning
    • Summary:
      • Proposes RT-VLA, a lightweight distilled VLA model that transfers driving and reasoning capabilities from the state-of-the-art SimLingo teacher through multi-level supervised distillation.
      • Achieves competitive closed-loop driving performance while reducing inference time by 44.8× in vision-only mode and 7.9× in vision+language mode.
  • Multi-Agent Embodied Autonomous Driving: From V2X Information Exchange to Shared World Models

    • Senkang Hu, Zhengru Fang, Yihang Tao, Zihan Fang, Sam Tak Wu Kwong, Yuguang Fang
    • Publish Date: 2026.06.11
    • Task: Planning
    • Summary:
      • A comprehensive survey of multi-agent embodied autonomous driving through the lens of Shared World Models (SWMs), covering V2X communication, collaborative perception, inter-agent cognition, cooperative planning, end-to-end cooperative driving, and simulation.
      • Identifies key research priorities for multi-agent embodied autonomous driving, including verifiable shared-state maintenance, robust intent and plan alignment, and safe coordinated action under communication, latency, and deployment constraints.
  • VLADriveBench: Evaluating CoT-Action Relationship in VLA for Autonomous Driving

    • Thach Nguyen, Danhua Guo, Tom Lampo, Fei Wu, Burhan Yaman
    • Publish Date: 2026.06.10
    • Task: Evaluation
    • Summary:
      • VLADriveBench is a framework for evaluating the relationship between chain-of-thought (CoT) reasoning and driving actions in Vision-Language-Action models.
      • It introduces observational metrics (mentioning, hallucination, contradiction, action alignment) combined with a CoT intervention protocol to provide complementary views of the CoT-action relationship.
      • Findings show that high observational alignment does not guarantee causal CoT, and visual salience gates the extent of CoT influence.
  • VLGA: Vision-Language-Geometry-Action Models for Autonomous Driving

    • Jin Yao, Dhruva Dixith Kurra, Tom Lampo, Zezhou Cheng, Danhua Guo, Burhan Yaman
    • Publish Date: 2026.06.10
    • Task: Planning
    • Datasets: nuScenes, Bench2Drive
    • Summary:
      • Introduces geometry as a fourth modality (per-pixel pointmap) alongside vision, language, and action, supervised via a regression loss against LiDAR.
      • Achieves state-of-the-art open-loop results on nuScenes (0.50 m L2 error, 0.18% collision rate) and closed-loop driving score of 79.08 on Bench2Drive.
  • DrivingAgent: Design and Scheduling Agents for Autonomous Driving Systems

    • Zhongyu Xia, Wenhao Chen, Yongtao Wang, Ming-Hsuan Yang
    • Publish Date: 2026.06.10
    • Task: Planning
    • Datasets: nuScenes, Bench2Drive
    • Summary:
      • Proposes DrivingAgent, a novel agent framework with two phases: a design phase that automates module development by interpreting system architecture and generating code, and a scheduling phase that uses a lightweight LLM trained with reinforcement learning for dynamic real-time orchestration supported by structured memory.
      • Achieves a superior speed-accuracy trade-off on both the nuScenes and Bench2Drive benchmarks, demonstrating effective system design and scheduling for autonomous driving.
  • Task-Aligned Stability Analysis of Vision-Language Models for Autonomous Driving Hazard Detection

    • Everett Richards
    • Publish Date: 2026.06.10
    • Task: Perception
    • Summary:
      • Studies the relationship between corruption-induced embedding drift and task-aligned hazard score (margin drift) using CLIP-based VLMs for autonomous driving hazard detection.
      • Finds that the correlation is corruption-dependent, with some corruptions causing hazardous decision instability despite small embedding changes.
      • Highlights asymmetric failure modes: most corruptions lead to false negatives (missed hazards), while occlusion triggers false alarms, emphasizing the need for task-aligned robustness benchmarks.
  • Language-Driven Cost Optimization for Autonomous Driving

    • Diego Martinez-Baselga, Khaled Mustafa, Javier Alonso-Mora
    • Publish Date: 2026.06.09
    • Task: Planning
    • Summary:
      • A language-driven framework for adaptive cost design in autonomous driving, using an LLM to interpret scenario descriptions and user queries to generate parameters for a risk-aware MPPI controller.
      • Incorporates human-in-the-loop validation and iterative refinement based on user feedback to align vehicle behavior with intended requirements.
  • Where Does the Answer Come From? Benchmarking View-Level Visual Evidence Identification in Multi-View MLLMs for Autonomous Driving

    • Yimu Wang, Yee Man Choi, Barry Zhang, Mozhgan Nasr Azadani, Sean Sedwards, Krzysztof Czarnecki
    • Publish Date: 2026.06.08
    • Task: Generation
    • Datasets: nuScenes
    • Summary:
      • Introduces a benchmark for evaluating evidence-source identification in multi-view MLLMs for autonomous driving, requiring models to identify the supporting camera view and answer the question.
      • Contains 122 conflict-centric question-answer pairs from 73 scenes, spanning causality, counterfactual reasoning, and intent prediction.
      • Evaluates three settings (camera-view selection, oracle QA, and joint prediction) and exposes grounding failures that answer-only evaluation misses.
  • Zero-Shot Semantic Re-Identification for Autonomous Driving: A VLM Baseline Study

    • Eduardo Borges, Manuel Abreu, Luís Garrote, Urbano J. Nunes
    • Publish Date: 2026.06.08
    • Task: Perception
    • Summary:
      • Proposes a zero-shot pipeline using Vision-Language Models (VLMs) to generate structured semantic descriptions for re-identifying traffic participants in autonomous driving.
      • Provides an initial benchmark for language-based re-identification, showing retrieval performance comparable to supervised CNN baselines with greater interpretability.
      • Reveals challenges including attribute inconsistency across viewpoints and limited fine-grained discrimination between visually similar instances.
  • BLUE: Toward Better Language Use in Efficient Vision-Language-Action Models for Autonomous Driving

    • George Ling, Lijin Yang, Hao Yang, Zhongzhan Huang
    • Publish Date: 2026.06.07
    • Code: BLUE
    • Task: Planning
    • Datasets: Bench2Drive
    • Summary:
      • BLUE employs a lightweight gate that decides per frame whether to generate language or predict actions, reducing unnecessary computation.
      • It achieves state-of-the-art performance on Bench2Drive (76.2% success rate) and Longest6 v2 (36 driving score) with a 2.54x inference speedup.
      • The method requires no additional human annotation or backbone modification, making it a practical and efficient approach for language-augmented autonomous driving.
  • DriveReward: A Comprehensive Dataset and Generative Vision-Language Reward Model for Autonomous Driving

    • Qimao Chen, Fang Li, Yuechen Luo, Zehan Zhang, Haiyang Sun, Fangzhen Li, Bing Wang, Guang Chen, Yang Ji, Jiong Deng, Hongwei Xie, Hangjun Ye, Long Chen, Yi Zhang
    • Publish Date: 2026.06.07
    • Task: Evaluation
    • Summary:
      • Introduces DriveReward, a reasoning trajectory evaluation dataset with counterfactual driving behaviors for autonomous driving.
      • Proposes a specialized 1B Vision-Language Reward Model that outperforms larger VLMs on task-specific reward alignment.
      • Validates the reward model via RL finetuning and multi-modal trajectory scoring, achieving comparable performance to rule-based methods in open-loop and closed-loop evaluation.
  • LUNA-AD: Lightweight Uncertainty-Aware Language Model with Lifelong Learning for Autonomous Driving

    • Ruoyu Yao, Pei Liu, Ruiguo Zhong, Mingxing Peng, Rui Yang, Jun Ma
    • Publish Date: 2026.06.07
    • Task: Perception
    • Datasets: nuPlan
    • Summary:
      • Proposes LUNA-AD, a lightweight uncertainty-aware language model with lifelong learning for autonomous driving, featuring a tri-system architecture that reconciles complex multimodal behavioral reasoning, efficient deployment, and continual refinement.
      • Utilizes a multi-agent analytical system to generate uncertainty-aware decision-making demonstrations, a dual-head lightweight heuristic model for unified inference, and a reflection-driven lifelong learning mechanism to enhance driving robustness.
  • PLAN-S: Bridging Planning with Latent Style Dynamics for Autonomous Driving World Models

    • Xiaoyun Qiu, Jingtao He, Yijie Chen, Yusong Huang, Haotian Wang, Yixuan Wang, Xinhu Zheng
    • Publish Date: 2026.06.04
    • Task: Planning
    • Datasets: nuScenes, NAVSIM
    • Summary:
      • PLAN-S decodes a style-conditioned, four-channel semantic cost map from the latent representation to address the compactness-controllability dilemma in latent world model-based planning.
      • It introduces two host-side interfaces (attention-level fusion for regression planners and reward-level fusion for anchor-score planners) enabling explicit risk, drivability, and style modulation.
      • On nuScenes, PLAN-S reduces average L2 to 0.55 m and achieves a 42% relative reduction in 3 s collision rate; on NAVSIM, the rule-cost variant reaches 89.4 PDMS.
  • Discrete-WAM: Unified Discrete Vision-Action Token Editing for World-Policy Learning

    • Ziyang Yao, Haochen Liu, Yuncheng Jiang, Zeyu Zhu, Zibin Guo, Jingru Wang, Tianle Liu, Jianwei Cui, Kuiyuan Yang, Hongwei Xie, Jingwei Zhao, Guang Chen, Hangjun Ye
    • Publish Date: 2026.06.04
    • Task: Planning
    • Summary:
      • Introduces Discrete-WAM, a unified discrete vision-action world-policy framework that represents visual observations, future states, high-level decisions, and ego actions within a shared token space.
      • Jointly trains world modeling, world-policy modeling, and policy modeling through multi-task and multi-stage pretraining, enabling action-conditioned future prediction to support policy generation.
      • Decomposes policy generation into hierarchical decision prediction and parallel action-token editing, achieving strong planning performance with support for controllable future generation, counterfactual evaluation, and efficient parallel decoding.
  • EvoDrive: Pareto Evolution for Safety-Critical Autonomous Driving via Self-Improving LLM Agents

    • Tong Nie, Yuewen Mei, Yihong Tang, Junlin He, Jie Deng, Jian Sun, Wei Ma
    • Publish Date: 2026.06.02
    • Task: Planning
    • Summary:
      • EvoDrive is an automated LLM-based agentic evolution framework for multi-objective scenario generation in autonomous driving, using a simulator-grounded actor-critic architecture.
      • It maintains a Pareto archive to balance adversariality and realism, and demonstrates expanded Pareto frontiers and valuable scenario generation on MetaDrive and CARLA.
  • NVIDIA OmniDreams: Real-Time Generative World Model for Closed-Loop Autonomous Vehicle Simulation

    • NVIDIA, :, Aarti Basant, Amlan Kar, Despoina Paschalidou, Fangyin Wei, Francesco Ferroni, Guillermo Garcia Cobo, Haithem Turki, Huan Ling, Jaewoo Seo, James Lucas, Jay Zhangjie Wu, Jialiang Wang, Jonathan Lorraine, Jun Gao, Kai He, Katarina Tothova, Kevin Xie, Michał Tyszkiewicz, Qi Wu, Riccardo de Lutio, Ruilong Li, Sanja Fidler, Seung Wook Kim, Tianchang Shen, Tianshi Cao, Tobias Pfaff, William Lew, Xindi Wu, Xuanchi Ren, Yifan Lu, Yuxuan Zhang, Zan Gojcic, Zian Wang
    • Publisher: NVIDIA
    • Publish Date: 2026.06.02
    • Task: Generation
    • Summary:
      • OmniDreams is a foundation generative world model mid- and post-trained from the Cosmos diffusion model to autoregressively generate action-conditioned videos in real time for closed-loop autonomous vehicle simulation.
      • It synthesizes complex unobserved phenomena such as extreme weather and unpredictable dynamic agent behaviors, and acts as a responsive, reactive environment for training and evaluating driving policies.
  • GeoDrive-Bench: Benchmarking Region-Specific Multimodal Reasoning in Autonomous Driving

    • Yingzi Ma, Chaowei Xiao, Ming Jiang
    • Publish Date: 2026.06.01
    • Task: Evaluation
    • Summary:
      • Introduces GeoDrive-Bench, a benchmark with 5,053 human-validated QA pairs across six countries to evaluate VLMs' geo-culturally grounded driving reasoning.
      • Covers four driving tasks: perception, prediction, planning, and region reasoning, requiring models to infer correct behavior from visual evidence and local conventions.
      • Proposes a distillation algorithm to inject region-specific traffic-rule knowledge into VLMs, improving geo-cultural reasoning across regions.
  • Unified Driving Tokens: Representation- and Geometry-Guided Discrete Tokenizer for Driving World Models and Planning

    • Ziyang Yao, Zeyu Zhu, YunCheng Jiang, Zibin Guo, Huijing Zhao
    • Publish Date: 2026.06.01
    • Task: Perception, Planning
    • Datasets: NAVSIM
    • Summary:
      • Presents a representation-guided and geometry-enhanced discrete tokenizer for driving world models and planning, learning tokens under joint supervision.
      • Aligns discrete bottleneck with frozen DINO features for representation consistency while preserving appearance, and injects geometric cues via depth and pose supervision.
  • DriveAnchor: Progressive Anchor-based Flow Learning for Autonomous Driving Planning

    • Limin Yan, Haoyun Tang, Yutao Qiu, Hongqing Liu, Haoyu Xu
    • Publish Date: 2026.05.30
    • Task: Planning
    • Summary:
      • DriveAnchor is a three-stage framework for autonomous driving planning that achieves behavioral diversity, controllability, and safety.
      • It uses Demonstration Flow Pretraining with a vocabulary of 2,398 trajectory shapes, Guided Flow Post-training with an Energy Field for controllability, and Reward-Refined Flow Fine-tuning using zeroth-order reinforcement learning.
      • The method reduces near-range collision rates by 89% and improves mean reward by 32% without imitation accuracy degradation, validated through real-world vehicle testing.
  • StressDream: Steering Video World Models for Robust Policy Evaluation and Improvement

    • Junwon Seo, Sushant Veer, Ran Tian, Wenhao Ding, Apoorva Sharma, Karen Leung, Edward Schmerling, Marco Pavone, Andrea Bajcsy
    • Publish Date: 2026.05.29
    • Project Page: StressDream
    • Task: Evaluation
    • Summary:
      • StressDream steers video world model imaginations toward high-impact yet plausible outcomes by optimizing initial noise of diffusion-based world models.
      • It uses a semantic objective with a Vision-Language Model and a plausibility objective to avoid out-of-distribution noise.
      • Demonstrates on autonomous driving and robotic manipulation for robust policy evaluation and improvement.
  • nuReasoning: A Reasoning-Centric Dataset and Benchmark for Long-Tail Autonomous Driving

    • Zhiyu Huang, Johnson Liu, Rui Song, Zewei Zhou, Ruining Yang, Yun Zhang, Tianhui Cai, Hanyin Zhang, Mingxuan Gao, Valeria Xu, Jiali Chen, Yishan Shen, Yiluan Guo, Tony, Qi, Jiaqi Ma
    • Publish Date: 2026.05.29
    • Task: Reasoning
    • Summary:
      • nuReasoning is a large-scale real-world dataset and benchmark for reasoning-centric autonomous driving, containing 20,000 clips with human-verified reasoning annotations.
      • It supports both reasoning evaluation and planning evaluation, enabling direct study of how reasoning supervision affects driving performance.
      • Experiments show that fine-tuning VLMs on nuReasoning improves driving-specific question answering and incorporating reasoning supervision into VLA training improves planning performance.
  • IDOL: Inverse-Dynamics-Guided Future Prediction for End-to-End Autonomous Driving

    • Chenghao Zhang, Timin Li, Dongmei Li
    • Publish Date: 2026.05.29
    • Task: Prediction
    • Datasets: NAVSIM
    • Summary:
      • IDOL proposes an inverse-dynamics-guided future prediction framework for world-model-based end-to-end planning in latent BEV space.
      • It uses an inverse dynamics model to decode transition-aware trajectory features from predicted future latent states, turning future forecasting into actionable planning guidance.
      • Experiments on NAVSIM v1 and v2 benchmarks show state-of-the-art performance.
  • Before Parc Fermé: RL-Time Pruning for Efficient Embodied LLMs in Autonomous Driving

    • Luca Benfenati, Ali Azimi, Matteo Risso, Fabio Carapellese, Daniele Jahier Pagliari, Alessio Burrello
    • Publish Date: 2026.05.29
    • Task: Reasoning
    • Summary:
      • Proposes BPF, a pruning strategy performed during reinforcement learning to compress embodied LLM controllers, allowing pruning decisions to account for task-specific supervision and closed-loop feedback.
      • Introduces two variants: BPF-RL and BPF-SFT/RL, which iteratively prune at different training stages to achieve target compression ratios.
      • Evaluates on RobotxR1 autonomous-driving pipeline, demonstrating superior task-performance vs. memory/throughput trade-offs, with up to 27% decode throughput improvement on Jetson AGX Orin.
  • Does Visual Information Play a Decisive Role in Vision-Language-Action Model Driving Behavior?

    • Jingtao He, Hongliang Lu, Xiaoyun Qiu, Yixuan Wang, Xinhu Zheng
    • Publish Date: 2026.05.29
    • Task: Perception
    • Summary:
      • Introduces a structured multi-level visual perturbation framework to analyze visual-behavior dependency in VLA-based driving models.
      • Framework organizes controlled visual perturbations along three complementary dimensions: channel-level degradation, information-level disruption, and structure-level modification.
      • Evaluated on open-loop trajectory prediction and interactive closed-loop safety evaluation, revealing evaluation-dependent dependency patterns and uneven visual grounding.
  • World Models: A Comprehensive Survey of Architectures, Methodologies, Reasoning Paradigms, and Applications

    • Arif Hassan Zidan, Yi Pan, Hanqi Jiang, Ruiyu Yan, Wei Ruan, Zihao Wu, Lifeng Chen, Weihang You, Xinliang Li, Bowen Chen, Huawen Hu, Peilong Wang, Sizhuang Liu, Jing Zhang, Siyuan Li, Zhengliang Liu, Yu Bao, Lin Zhao, Lichao Sun, Dajiang Zhu, Xiang Li, Jinglei Lv, Quanzheng Li, Wei Liu, Tianming Liu, Wei Zhang
    • Publish Date: 2026.05.28
    • Summary:
      • Presents a comprehensive multi-axis taxonomy for world models across architecture, methodology, reasoning, and application domains.
      • Traces the evolution from early cognitive-science foundations to milestone systems and highlights recent convergence of chain-of-thought reasoning with world-model imagination.
  • SARAD: LLM-Based Safety-Aware Hybrid Reinforcement Learning with Collision Prediction for Autonomous Driving

    • Kangyu Wu, Peng Cui, Guoxi Chen, Ya Zhang
    • Publish Date: 2026.05.27
    • Task: Prediction, Planning
    • Summary:
      • SARAD substitutes the random exploration of DRL with RAG-enhanced, LLM-guided decisions sourced from a dynamic expert knowledge repository.
      • An attention discriminator is proposed to integrate the prior knowledge of LLMs into DRL policy optimization.
      • A collision predictor module, fine-tuned with historical collision data, is further designed to improve vehicle safety.
  • DriveWAM: Video Generative Priors Enable Scalable World-Action Modeling for Autonomous Driving

    • Chen Shi, Jinrui Xu, Shaoshuai Shi, Kehua Sheng, Bo Zhang, Li Jiang
    • Publish Date: 2026.05.27
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • DriveWAM adapts a pretrained video diffusion transformer into an autoregressive video-action policy, preserving video-generation architecture for action generation.
      • Introduces scene-evolving driving guidance with a frozen VLM for chunk-specific semantic intent, and selective KV memory for bounded long-horizon rollout.
      • Achieves strong planning performance on NAVSIM and PhysicalAI-Autonomous-Vehicles benchmark, with data-scaling study confirming scaling potential.
  • TPS-Drive: Task-Guided Representation Purification for VLM-based Autonomous Driving

    • Jiaxiang Li, Yumao Liu, Ke Ma
    • Publish Date: 2026.05.26
    • Task: Perception, Planning
    • Datasets: nuScenes, NAVSIM
    • Summary:
      • Proposes TPS-Drive, a framework centered on Task-Guided Representation Purification to mitigate spatial hallucinations and representation interference in VLM-based autonomous driving.
      • Introduces an Agent-Centric Tokenizer with task-guided vector quantization, supervised by a frozen 3D detection head, to reallocate codebook capacity from static backgrounds to dynamic agents.
      • Optimized via a progressive three-stage training paradigm with reward-driven refinement, achieving state-of-the-art safety on NAVSIM benchmarks and reduced collision rates in nuScenes.
  • Decision-Making with Lightweight Confidence-Aware Language Model for Autonomous Driving

    • Ruoyu Yao, Ruiguo Zhong, Pei Liu, Mingxing Peng, Rui Yang, Jun Ma
    • Publish Date: 2026.05.25
    • Task: Planning
    • Datasets: nuPlan
    • Summary:
      • Proposes a lightweight confidence-aware language model for autonomous driving decision-making, leveraging a multi-agent collaborative workflow for demonstration generation.
      • Employs confidence-aware fine-tuning with Retrieval Augmented Generation (RAG) to distill knowledge into a dual-head lightweight model.
      • Achieves state-of-the-art success rates on the nuPlan benchmark while maintaining low inference latency.
  • PEDESTRIANQA: A Benchmark for Vision-Language Models on Pedestrian Intention and Trajectory Prediction

    • Naman Mishra, Shankar Gangisetty, C. V. Jawahar
    • Publish Date: 2026.05.23
    • Task: Evaluation
    • Summary:
      • Introduces PedestrianQA, a large-scale video-based dataset that formulates pedestrian intention and trajectory prediction as question-answering tasks with structured rationales.
      • Demonstrates that finetuning state-of-the-art VLMs on PedestrianQA significantly improves intention classification, trajectory forecasting accuracy, and the quality of explanatory rationales.
  • SparseWorld: Enhancing End-to-End Autonomous Driving via World Models with Sparse Scene Representation

    • Ruoyu Wang, Jingke Wang, Yukai Ma, Yuehao Huang, Shuangming Lei, Guanglin Xu, Aixue Ye, Yong Liu
    • Publish Date: 2026.05.23
    • Project Page: SparseWorld
    • Task: Planning
    • Datasets: nuScenes, Bench2Drive
    • Summary:
      • Proposes SparseWorld, a lightweight world model that predicts only critical scene layout via autoregressive rollout of future map elements and agents, reducing computational cost.
      • Uses a Sparse Dreamer with joint temporal-spatial attention to anticipate future instances, refining motion prediction and trajectory planning.
      • Achieves state-of-the-art open-loop planning on nuScenes (0.05% collision rate) and significantly outperforms baselines in closed-loop on Bench2Drive.
  • D2-V2X: Depth-Driven Cooperative V2X Reasoning for Autonomous Driving

    • Kevin Richard, Alphin Varghese, Colin Pham, David Oh, Srijan Das
    • Publish Date: 2026.05.22
    • Code: D2-V2X
    • Task: Evaluation
    • Summary:
      • Introduces D2-V2X, a spatially-aware Question-Rationale-Answer (QRA) benchmark with 8,500 triplets from multimodal vehicle and infrastructure sensors.
      • Establishes a baseline that aligns 3D LiDAR features with VLM latent space, using Chain-of-Thought rationales to explicitly articulate spatial relations, achieving 24.4% recall in identifying occluded hazards and reducing spatial estimation error by 77%.
  • ChainFlow-VLA: Causal Flow Planning with Vision-Language Models

    • Xiyang Wang, Xinlin Wang, Tingguang Zhou, Gong Chen, Xingtai Gui, Zhi Xu, Xiaolei Wu, Feiyang Tan, Hangning Zhou, Mu Yang
    • Publish Date: 2026.05.22
    • Code: ChainFlow-VLA
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • ChainFlow-VLA unifies causal generation and global refinement within a unified probabilistic framework for end-to-end autonomous driving.
      • It formulates planning as a mixture over AR-induced modes and learns VLM-conditioned residual distributions, achieving robust planning in ambiguous and long-tail scenarios.
      • The approach achieves a state-of-the-art score of 94.85 on the NAVSIM v1 leaderboard, matching human-level performance.
  • DRIVESPATIAL: A Benchmark for Spatiotemporal Intelligence in VLMs for Autonomous Driving

    • Hao Vo, Khoa Vo, Phu Loc Nguyen, Sieu Tran, Duc Minh Nguyen, Ngo Xuan Cuong, Gladys Gawugah, Sreevenkata Anjani Tishita Godavarthi, Chase Rainwater, Nghi D. Q. Bui, Anh Nguyen, Duy Minh Ho Nguyen, Ngan Le
    • Publish Date: 2026.05.22
    • Task: Evaluation
    • Summary:
      • DriveSpatial is a benchmark of 15.6K human-verified QA pairs across 20 tasks from five large-scale AD datasets, evaluating four abilities: Cognitive Scene Construction, Multi-view Relational Understanding, Temporal Reasoning, and Generalization.
      • It reveals a substantial human-model gap, with the strongest model trailing humans by 28.4 points, and shows that explicit BEV grounding consistently improves performance, indicating current VLMs lack the scene-construction ability needed for reliable spatiotemporal driving intelligence.
  • LVDrive: Latent Visual Representation Enhanced Vision-Language-Action Autonomous Driving Model

    • Xiaodong Mei, Diankun Zhang, Hongwei Xie, Guang Chen, Hangjun Ye, Dan Xu
    • Publish Date: 2026.05.21
    • Task: Planning
    • Datasets: Bench2Drive
    • Summary:
      • Introduces a future scene prediction task entirely in high-level latent space under auxiliary supervision from a pretrained vision backbone, avoiding inefficient pixel-level reconstruction.
      • Jointly models future scene and motion prediction within a unified embedding space, processed in a single forward pass for future-aware reasoning.
      • Designs a two-stage trajectory decoding strategy that leverages learned latent future representations to refine trajectory generation, achieving significant improvements on the Bench2Drive benchmark.
  • Lost in Fog: Sensor Perturbations Expose Reasoning Fragility in Driving VLAs

    • Abhinaw Priyadershi, Jelena Frtunikj
    • Publish Date: 2026.05.20
    • Task: Perception
    • Summary:
      • Conducted a controlled perturbation study of Vision-Language-Action robustness in autonomous driving, evaluating across 1,996 scenarios under eight sensor perturbations.
      • Found that reasoning consistency (Chain-of-Causation) is a high-fidelity indicator of trajectory reliability, with trajectory deviation spiking 5.3× when explanations change.
      • Established CoC consistency as a quantitative proxy for planning safety, motivating reasoning-based runtime monitoring for safer VLA deployment.
  • Distill to Think, Foresee to Act: Cognitive-Physical Reinforcement Learning for Autonomous Driving

    • Yang Wu, Qiang Meng, Zhaojiang Liu, Youquan Liu, Jian Yang, Jin Xie
    • Publish Date: 2026.05.20
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • CoPhy, a Cognitive-Physical reinforcement learning framework for autonomous driving, distilling VLM knowledge into BEV encoder and building an auto-regressive world model.
      • It uses GRPO with a dual-reward mechanism: physical reward from BEV rollouts and cognitive reward from language-aligned scorer.
      • Achieves state-of-the-art on NAVSIM v1 and v2 benchmarks and enables safer driving via cognitively informed scene compliance.
  • Bridging Structure and Language: Graph-Based Visual Reasoning for Autonomous Road Understanding

    • Lena Wild, Katie Z Luo, Marco Pavone
    • Publish Date: 2026.05.20
    • Task: Perception
    • Summary:
      • Introduces Combined Road Substrate (CRS), a graph-grounded framework that integrates geometric road structure and open-vocabulary semantics for structured road reasoning.
      • Demonstrates that training small vision-language models with as few as 20-80 CRS-enriched scenes yields stable gains in compositional reasoning, revealing that structured supervision is key rather than model scale.
  • VL-DPO: Vision-Language-Guided Finetuning for Preference-Aligned Autonomous Driving

    • Zhefan Xu, Ghassen Jerfel, Marina Haliem, Qi Zhao, Jeonhyung Kang, Khaled S. Refaat
    • Publish Date: 2026.05.19
    • Task: Planning
    • Datasets: Waymo Open End-to-End Driving Dataset
    • Summary:
      • VL-DPO leverages a Vision-Language Model as a zero-shot reasoner to automatically generate preference pairs from a pretrained model's rollouts, then finetunes the model via Direct Preference Optimization.
      • The framework aligns ego-vehicle motion forecasting models with human preferences, achieving an 11.94% increase in rater feedback score and a 10.01% reduction in average displacement error.
  • Beyond Imitation: Learning Safe End-to-End Autonomous Driving from Hard Negatives

    • Junli Wang, Zhihua Hua, Xueyi Liu, Zebin Xing, Haochen Tian, Kun Ma, Hangjun Ye, Guang Chen, Long Chen, Qichao Zhang
    • Publish Date: 2026.05.19
    • Task: Perception, Planning
    • Datasets: NAVSIM
    • Summary:
      • BeyondDrive, a failure-aware imitation learning framework for end-to-end autonomous driving that jointly learns from successful and failed driving behaviors.
      • Introduces flow matching-based negative trajectory generator to synthesize safety-critical trajectories, diversity-aware sampling to cover diverse failure modes, and Repulsive Distance Loss to establish discriminative safety boundaries.
      • Achieves 89.7 PDMS on NAVSIMv1 closed-loop benchmark, outperforming prior state-of-the-art, and demonstrates strong zero-shot transferability on HUGSIM.
  • HEAT: Heterogeneous End-to-End Autonomous Driving via Trajectory-Guided World Models

    • Hoonhee Cho, Giwon Lee, Jae-Young Kang, Hyemin Yang, Heejun Park, Kuk-Jin Yoon
    • Publish Date: 2026.05.19
    • Task: Planning
    • Datasets: nuScenes, NAVSIM, Waymo
    • Summary:
      • Proposes a trajectory-driven learning paradigm that organizes training around planning trajectories to capture domain-invariant representations of driving intent.
      • Incorporates a world model that predicts future latent features conditioned on ego actions, improving feature consistency and mitigating domain-induced biases.
      • Demonstrates that a single unified model can be trained on heterogeneous datasets (nuScenes, NAVSIM, Waymo) while maintaining strong performance within each domain.
  • SafeAlign-VLA: A Negative-Enhanced Safe Alignment Framework for Risk-Aware Autonomous Driving

    • Kefei Tian, Yuansheng Lian, Kai Yang, Xiangdong Chen, Shen Li
    • Publish Date: 2026.05.19
    • Task: Perception
    • Datasets: NAVSIM
    • Summary:
      • SafeAlign-VLA introduces a negative-enhanced safe alignment framework for Vision-Language-Action (VLA) models, incorporating negative data into both supervised fine-tuning and reinforcement learning.
      • A counterfactual safety pairing paradigm generates structured safety labels and counterfactual positive trajectories from risky scenarios, enabling the model to understand risky behaviors and safety boundaries.
      • Two-stage training is employed: negative-enhanced supervised fine-tuning for failure feedback and trajectory correction, followed by anchor-based group relative policy optimization (AGRO) that uses positive and negative trajectories as contrastive anchors to penalize high-risk behaviors.
  • Xiaomi EV World Model: A Joint World Model Integrating Reconstruction and Generation for Autonomous Driving

    • Lijun Zhou, Hongcheng Luo, Zhenxin Zhu, Cheng Chi, Mingfei Tu, Kaixin Xiong, Lei Gong, Zhanqian Wu, Zehan Zhang, Fangzhen Li, Hao Li, Yingying Shen, Jiale He, Haohui Zhu, Shan Zhao, Kai Wang, Zhiwei Zhan, Yuechuan Pu, Kaiyuan Tan, Ruiling Yang, Xianqi Wang, Tianyi Yan, Jiawei Zhou, Lei Zhang, Jingyang Zhao, Xi Zhou, Chitian Sun, Chenming Wu, Jiong Deng, Hongwei Xie, Ming Lu, Kun Ma, Long Chen, Guang Chen, Hangjun Ye, Bing Wang, Haiyang Sun
    • Publisher: Xiaomi EV
    • Publish Date: 2026.05.18
    • Task: Generation
    • Summary:
      • Proposes a unified technical system for world models in autonomous driving, comprising world representation (WorldRec) and world generation (WorldGen).
      • WorldRec uses feed-forward reconstruction with sparse scene queries to produce compact 3D Gaussian scene representations, while WorldGen enables high-quality causal video generation with few denoising steps.
      • The Joint World Model (JWM) integrates both modules to enhance generation stability, cross-frame consistency, and visual fidelity for closed-loop simulation and end-to-end training.
  • GEM: Gaussian Evolution Model for Occupancy Forecasting and Motion Planning

    • Cheng Chen, Hao Huang, Saurabh Bagchi
    • Publish Date: 2026.05.17
    • Task: Prediction, Planning
    • Summary:
      • Proposes GEM, a Gaussian Evolution Model for non-autoregressive occupancy world modeling, representing driving scenes as explicit continuous 4D Gaussian primitives with learned dynamics.
      • Enables direct querying of Gaussian world representation at arbitrary timestamps for efficient full-horizon forecasting and supports motion planning by predicting future ego trajectories.
      • Achieves state-of-the-art future semantic occupancy forecasting and strong motion planning performance with flexible temporal querying.
  • CLAP: Contrastive Latent-space Prompt Optimization for End-to-end Autonomous Driving

    • Ruiyang Zhu, Yuehan He, Boyuan Zheng, Zesen Zhao, Ahmad Chalhoub, Qingzhao Zhang, Z. Morley Mao
    • Publish Date: 2026.05.17
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • CLAP introduces a contrastive latent-space prompt optimization framework for end-to-end autonomous driving, enhancing performance in long-tail scenarios.
      • The method uses per-roadblock soft prompts optimized via contrastive learning and directionally regularized optimization, improving planning error on challenging frames without regressing normal frames.
      • Validated on NAVSIM benchmark with various VLA backbones, achieving 24% reduction in challenging scenario planning error.
  • PCASim: Promptable Closed-loop Adversarial Simulation for Urban Traffic Environment

    • Chuancheng Zhang, Zhenhao Wang, Kaizheng Li, Yaran Lin, Qiang Guo, Bin Jiang
    • Publish Date: 2026.05.15
    • Project Page: PCASim
    • Task: Generation
    • Summary:
      • PCASim introduces a promptable closed-loop adversarial simulation framework for urban traffic, integrating rule-based filtering, knowledge retrieval, and large language models to generate safety-critical scenarios.
      • The framework employs reinforcement learning to train diverse vehicle behaviors, enriching scenario diversity and realism, achieving improvements in domain-specific language accuracy, scenario transformation success rate, and obstacle-avoidance capability.
  • Learning Direct Control Policies with Flow Matching for Autonomous Driving

    • Marcello Ceresini, Federico Pirazzoli, Andrea Bertogalli, Lorenzo Cipelli, Filippo D'Addeo, Anthony Dell'Eva, Alessandro Paolo Capasso, Alberto Broggi
    • Publish Date: 2026.05.14
    • Project Page: DirectControlFlowMatching
    • Task: Planning
    • Summary:
      • Presents a flow-matching planner that directly outputs control trajectories (acceleration and curvature) conditioned on a BEV raster, enabling low-latency inference via ODE integration.
      • Trained on urban simulator data and tested in closed-loop on in-distribution and out-of-distribution scenarios (highways, unseen cities), demonstrating reliable generalization attributed to the BEV representation and flow-matching formulation.
  • EponaV2: Driving World Model with Comprehensive Future Reasoning

    • Jiawei Xu, Zhizhou Zhong, Zhijian Shu, Mingkai Jia, Mingxiao Li, Jia-Wang Bian, Qian Zhang, Kaicheng Zhang, Jin Xie, Jian Yang, Wei Yin
    • Publish Date: 2026.05.14
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • Proposes EponaV2, a driving world model that forecasts comprehensive future representations (geometry & semantics) to enhance planning without relying on expensive manual annotation.
      • Introduces a flow matching group relative policy optimization mechanism, inspired by LLM training, to further improve planning accuracy.
      • Achieves state-of-the-art performance on three NAVSIM benchmarks among perception-free models.
  • MAPLE: Latent Multi-Agent Play for End-to-End Autonomous Driving

    • Rajeev Yasarla, Deepti Hegde, Hsin-Pai Cheng, Shizhong Han, Yunxiao Shi, Meysam Sadeghigooghari, Hanno Ackermann, Litian Liu, Pranav Desai, Fatih Porikli, Mohammad Ghavamzadeh, Hong Cai
    • Publish Date: 2026.05.13
    • Task: Planning
    • Datasets: Bench2Drive
    • Summary:
      • MAPLE introduces a latent-space multi-agent rollout framework for reactive, closed-loop training of VLA-based end-to-end motion planners, enabling independent control of ego and traffic agents over multi-step horizons.
      • The two-stage training pipeline combines supervised fine-tuning on latent rollouts with reinforcement learning using global/agent-specific rewards and diversity rewards, achieving state-of-the-art performance on Bench2Drive without external simulators.
  • MindVLA-U1: VLA Beats VA with Unified Streaming Architecture for Autonomous Driving

    • Yuzhou Huang, Benjin Zhu, Hengtong Lu, Victor Shea-Jay Huang, Haiming Zhang, Wei Chen, Jifeng Dai, Yan Xie, Hongsheng Li
    • Publish Date: 2026.05.12
    • Task: Planning
    • Datasets: WOD-E2E
    • Summary:
      • First unified streaming VLA architecture for autonomous driving, producing autoregressive language tokens and flow-matching continuous action trajectories in a single forward pass over a shared representation.
      • Streaming design processes driving video framewise with a learned memory channel for temporal context, enabling smooth trajectory evolution without redundant multi-frame VLM modeling.
      • Surpasses experienced human drivers on the long-tail WOD-E2E benchmark for the first time (8.20 RFS vs. 8.13 GT RFS) and achieves state-of-the-art planning ADEs over prior VA/VLA methods with throughput matching VA-class models.
  • Action Emergence from Streaming Intent

    • Pengfei Jing, Victor Shea-Jay Huang, Hengtong Lu, Jifeng Dai, Xie Yan, Benjin Zhu
    • Publish Date: 2026.05.12
    • Task: Planning
    • Datasets: Waymo
    • Summary:
      • Formalizes action emergence as generating physically feasible, semantically appropriate, safety-compliant actions via scene-conditioned reasoning, rather than retrieval or interpolation.
      • Introduces Streaming Intent, a mechanism with continuous chain-of-thought and temporal streaming across clips, realized in the SI model using autoregressive intent decoding and flow-matching action head.
      • Achieves competitive performance on the Waymo End-to-End benchmark (RFS 7.96 val, 7.74 test) and demonstrates intent-faithful controllability without pre-built trajectory banks.
  • C-CoT: Counterfactual Chain-of-Thought with Vision-Language Models for Safe Autonomous Driving

    • Kefei Tian, Yuansheng Lian, Kai Yang, Xiangdong Chen, Shen Li
    • Publish Date: 2026.05.11
    • Task: Planning
    • Datasets: DeepAccident-CCoT
    • Summary:
      • Proposes a counterfactual chain-of-thought (C-CoT) framework that decomposes driving decisions into five stages, including counterfactual risk reasoning with a meta-action evaluation tree.
      • Achieves risk prediction recall of 81.9%, reduces collision rate to 3.52%, and lowers L2 error to 1.98 m on the DeepAccident-CCoT dataset.
  • DeepSight: Long-Horizon World Modeling via Latent States Prediction for End-to-End Autonomous Driving

    • Lingjun Zhang, Changjie Wu, Linzhe Shi, Jiangyang Li, Jiaxin Liu, Lei Yang, Hang Zhang, Mu Xu, Hong Wang
    • Publish Date: 2026.05.11
    • Code: DeepSight
    • Task: Planning
    • Datasets: Bench2Drive
    • Summary:
      • DeepSight proposes a driving world model that performs parallel prediction of latent semantic features in BEV space for consecutive future frames, enabling long-horizon world modeling.
      • It introduces an efficient and adaptive text reasoning mechanism that leverages social knowledge and reasoning to improve driving performance in challenging long-tail scenarios.
      • The approach achieves state-of-the-art results on the closed-loop Bench2drive benchmark.
  • CoWorld-VLA: Thinking in a Multi-Expert World Model for Autonomous Driving

    • Minqing Huang, Yujiao Xiang, Zihan Liang, Jiajie Huang, Jingqi Wang, Zhi Xu, Feiyang Tan, Hangning Zhou, Mu Yang, Gong Che
    • Publish Date: 2026.05.11
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • CoWorld-VLA proposes a multi-expert world reasoning framework for autonomous driving, where world representations serve as explicit conditions to guide action planning.
      • It extracts complementary world information through multi-source supervision and encodes it into four types of expert tokens: semantic interaction, geometric structure, dynamic evolution, and ego trajectory tokens.
      • A diffusion-based hierarchical multi-expert fusion planner is employed to generate continuous ego trajectories, achieving competitive results on the NAVSIM benchmark.
  • Temporal Sampling Frequency Matters: A Capacity-Aware Study of End-to-End Driving Trajectory Prediction

    • Yumao Liu, Tao Liu, Xiangyu Li, Jiaxiang Li, Ke Ma
    • Publish Date: 2026.05.11
    • Task: Prediction
    • Datasets: Waymo, nuScenes
    • Summary:
      • Investigates temporal sampling frequency as an explicit training design variable for end-to-end driving trajectory prediction, challenging the default use of highest available frequency.
      • Demonstrates model-dependent frequency responses: smaller models benefit from lower or intermediate frequencies, while a larger VLA-style model achieves best performance at the highest frequency across three datasets.
      • Provides capacity-aware analysis showing that sparse sampling may miss cues while dense sampling adds redundant visual content, and that iteration-matched controls rule out unequal training updates as the sole explanation.
  • DriveFuture: Future-Aware Latent World Models for Autonomous Driving

    • Yufeng Hong, Xiaotian Zhou, Yingyan Li, Xiangpo Zhou, Lin Liu, Yadan Luo, Shaoqing Xu, Lei Yang, Ziying Song
    • Publish Date: 2026.05.10
    • Task: Planning
    • Datasets: NAVSIM
    • Summary:
      • DriveFuture explicitly conditions current latent state modeling on future world states to learn planning-oriented foresight.
      • It uses cross-attention to refine predicted future latent states and a diffusion-based trajectory planner, achieving state-of-the-art performance on NAVSIM benchmarks.
  • VECTOR-Drive: Tightly Coupled Vision-Language and Trajectory Expert Routing for End-to-End Autonomous Driving

    • Rui Zhao, Jianlin Yu, Zhenhai Gao, Jiaqiao Liu, Fei Gao
    • Publish Date: 2026.05.09
    • Task: Planning
    • Datasets: Bench2Drive
    • Summary:
      • Proposes VECTOR-DRIVE, a tightly coupled vision-language-action (VLA) framework that keeps all tokens coupled via shared self-attention and routes feed-forward computation by token semantics, coupling vision-language reasoning and trajectory prediction.
      • Achieves 88.91 Driving Score on Bench2Drive, outperforming representative end-to-end and VLA-based baselines, and validates the benefits of shared attention, semantic-aware expert routing, progressive training, and flow-based action decoding.
  • GEM: Generating LiDAR World Model via Deformable Mamba

    • Yang Wu, Zhaojiang Liu, Qiang Meng, Youquan Liu, Renliang Weng, Jianjun Qian, Jian Yang, Jin Xie
    • Publish Date: 2026.05.08
    • Code: GitHub
    • Task: Generation
    • Summary:
      • Proposes GEM, a generative LiDAR world model using deformable Mamba architecture for improved fidelity and imagination.
      • Introduces a LiDAR scene tokenizer and dynamic-static separator for unsupervised disentanglement of features.
      • Achieves state-of-the-art performance on diverse benchmarks, with optional integration for autonomous rollout and what-if scenarios.
  • See Tomorrow, Act Today: Foresight-Driven Autonomous Driving

    • Bozhou Zhang, Nan Song, Yuang Wang, Jiankang Deng, Xiatian Zhu, Li Zhang
    • Publish Date: 2026.05.08
    • Task: Planning
    • Datasets: NAVSIM, nuScenes
    • Summary:
      • ForeSight introduces a foresight-driven planning framework for autonomous driving, using a world model to generate future scenes before planning actions.
      • The framework shifts from reactive to anticipatory decision-making by conditioning actions on imagined future observations.
      • Experiments on NAVSIM and nuScenes demonstrate state-of-the-art performance compared to previous reactive methods.
  • Information Coordination as a Bridge: A Neuro-Symbolic Architecture for Reliable Autonomous Driving Scene Understanding

    • Shuo Liu, Lei Shi, Haowen Liu, Jing Xu, Yufei Gao, Yucheng Shi
    • Publish Date: 2026.05.06
    • Task: Perception
    • Datasets: nuScenes, Waymo
    • Summary:
      • Proposes InfoCoordiBridge, a BEV-centric neuro-symbolic architecture that inserts an explicit coordination bridge between perception and language reasoning for reliable autonomous driving scene understanding.
      • Comprises three modules: a unified multi-agent perception layer, an ICA module for aligning and fusing multi-source outputs into a single SceneSummary, and an SSRE module for SceneSummary-grounded reasoning with verification.
      • Experiments on nuScenes and Waymo show that ICA improves fusion consistency and reduces redundancy, while SSRE reduces hallucinated entity mentions compared to VLM and agentic baselines.
  • HERMES++: Toward a Unified Driving World Model for 3D Scene Understanding and Generation

    • Xin Zhou, Dingkang Liang, Xiwu Chen, Feiyang Tan, Dingyuan Zhang, Hengshuang Zhao, Xiang Bai
    • Publish Date: 2026.04.30
    • Code: HERMESV2
    • Task: Generation
    • Summary:
      • HERMES++ is a unified driving world model that integrates 3D scene understanding and future geometry prediction within a single framework.
      • It utilizes BEV representation, LLM-enhanced world queries, a Current-to-Future Link, and Joint Geometric Optimization to achieve strong performance.
      • The model outperforms specialist approaches in both future point cloud prediction and 3D scene understanding tasks.
  • GSDrive: Reinforcing Driving Policies by Multi-mode Trajectory Probing with 3D Gaussian Splatting Environment

    • Ziang Gu

Truncated — view the full README on GitHub.

large-language-models
vision-language-action-model
vision-language-model
world-model

Significant stargazers

Tianxing Chen (陈天行)

1,757 followers · starred Jan 2024

Bo Zhang

135 followers · starred Nov 2023

Hao Shao

148 followers · starred Dec 2023

Lingdong Kong

483 followers · starred May 2024