
Collects papers on autonomous driving E2E learning, VLM/VLA and Hybrid systems, with organized research branches and trends in these fields.
HTML
211
27 commits
updated May 27, 2026
README
Awesome-GE2EAD



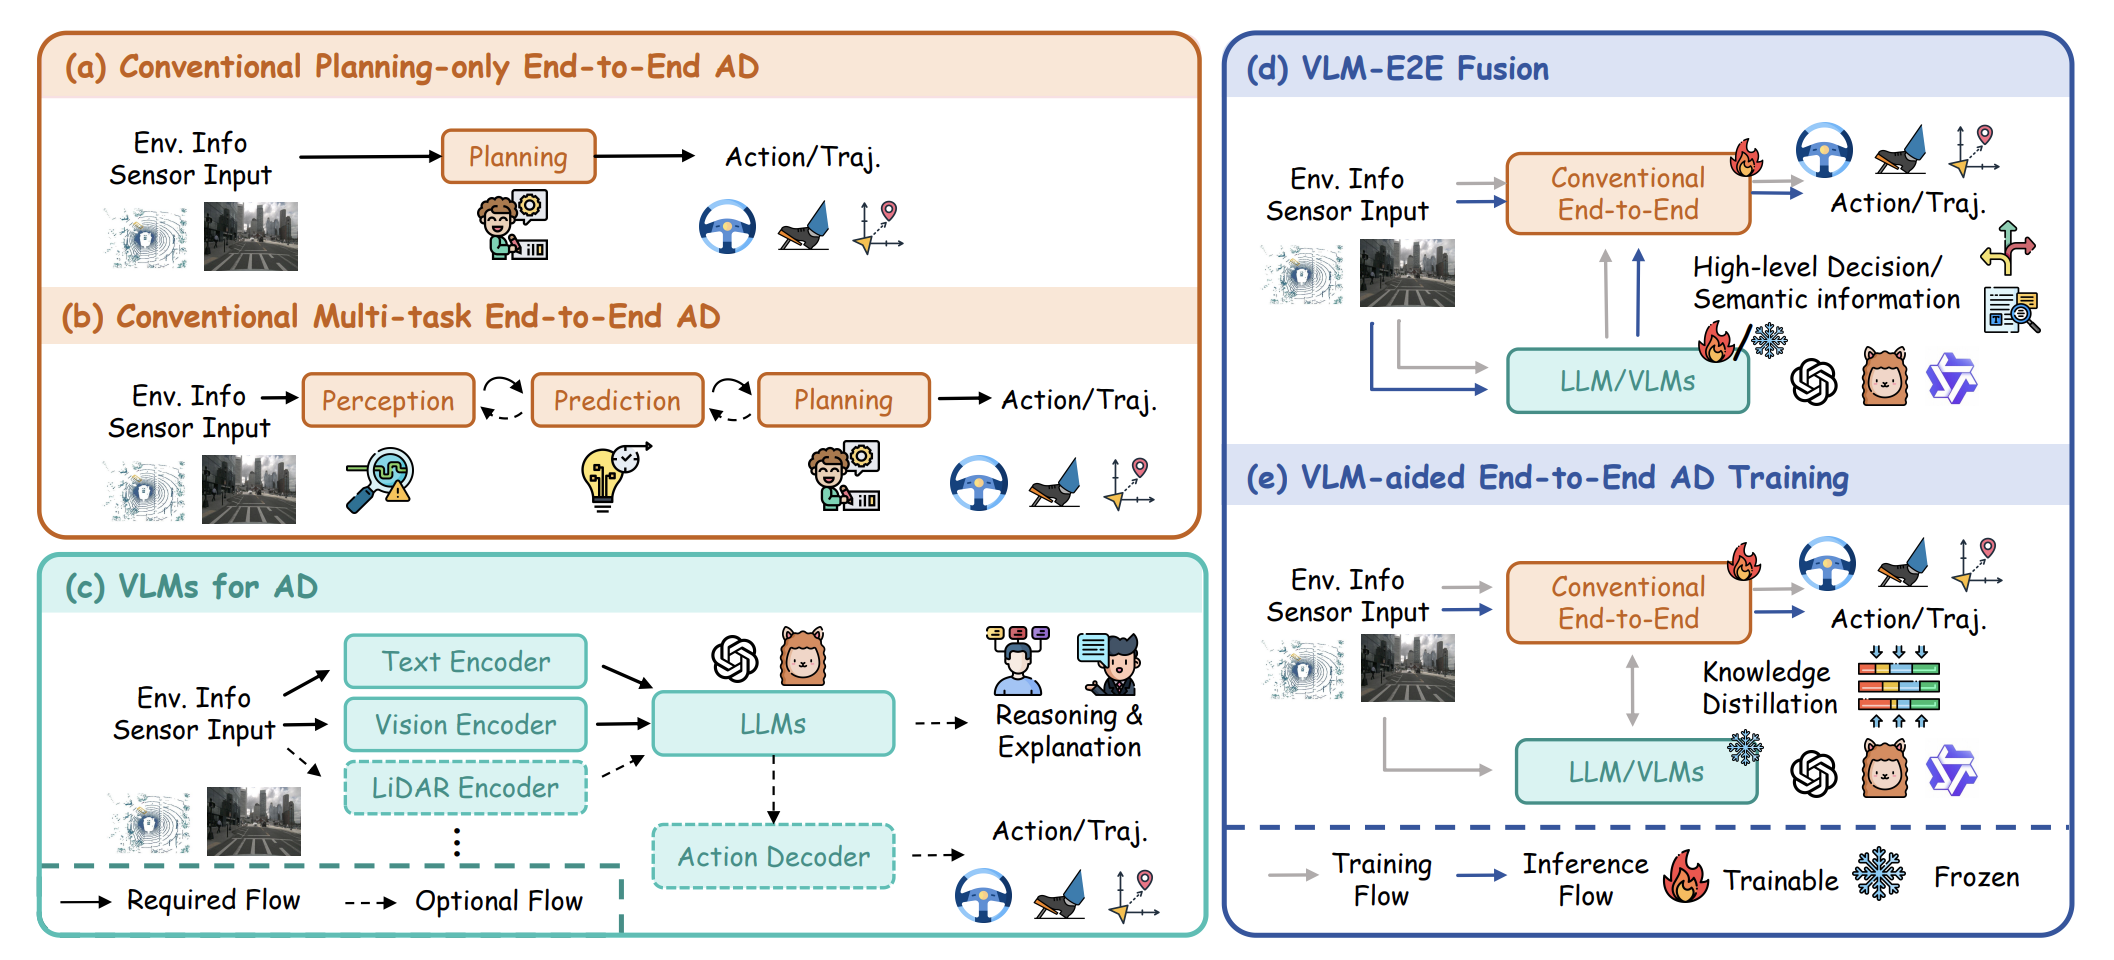
This is the official repository for "Survey of General End-to-End Autonomous Driving: A Unified Perspective".
This project aims to provide a unified roadmap for the field by:
-
🗂️ Literature Taxonomy: Classifying methods into Conventional (e.g., UniAD), VLM-centric (e.g., DriveLM), and Hybrid (e.g., Senna) approaches.
-
💾 Dataset Curation: Collecting both Standard and Vision-Language datasets relevant to end-to-end AD.
-
📈 Trend Analysis: Outlining main research branches and emerging trends based on our survey.
Citation
If you find this project useful in your research, please consider citing:
@article{yang2025survey,
  title={Survey of General End-to-End Autonomous Driving: A Unified Perspective},
  author={Yang, Yixiang and Han, Chuanrong and Mao, Runhao and others},
  journal={TechRxiv},
  year={2025},
  month={December},
  doi={10.36227/techrxiv.176523315.56439138/v1},
  url={https://doi.org/10.36227/techrxiv.176523315.56439138/v1}
}
📌 Milestones
-
🚀 2025-12-24: We organize the list of papers in a completely new tabular format.
-
🚀 2025-12-10: The paper “Survey of General End-to-End Autonomous Driving: A Unified Perspective” was released, and this repository was made publicly available.
Table of Contents
Mindmap, Top Methods
GE2EAD Mindmap
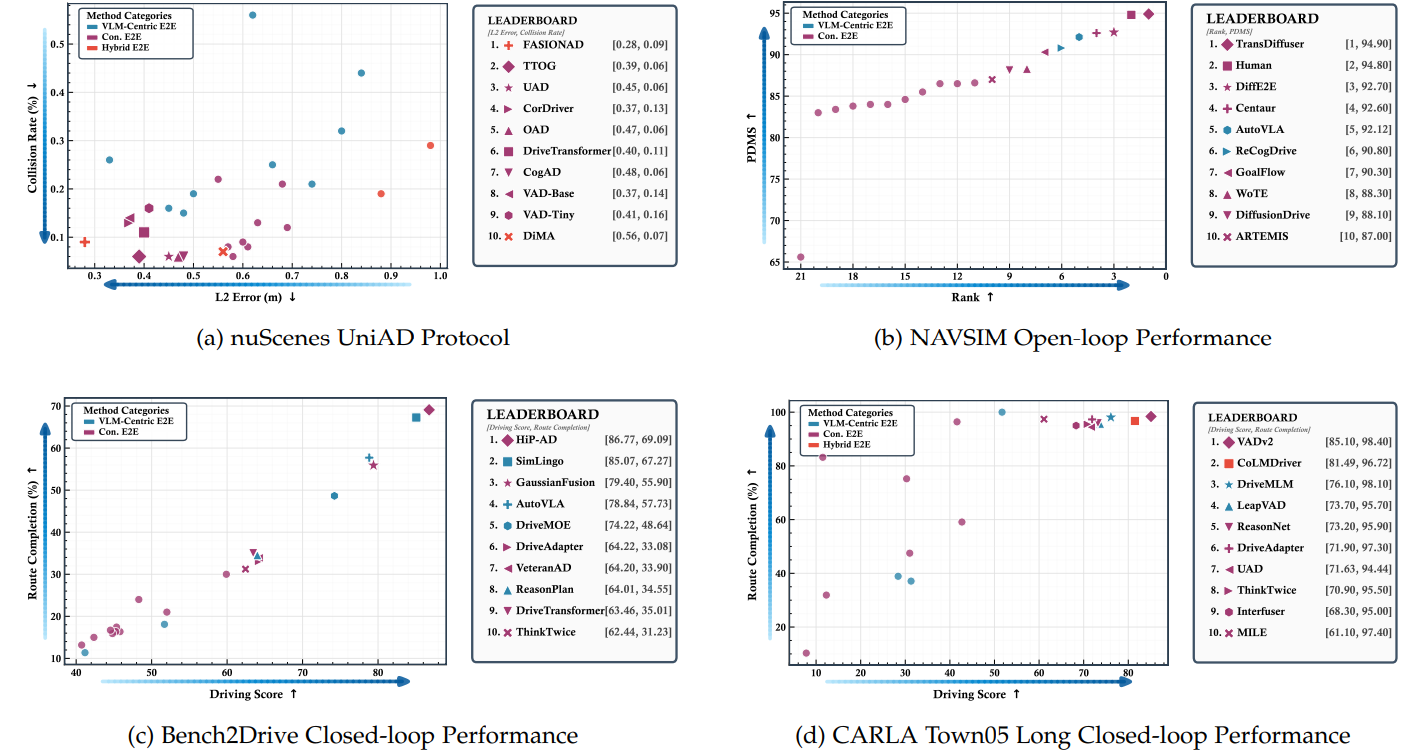
Top Methods
Papers
Conventional End-to-End Methods (VA)
Conventional End-to-End Methods (VA)
2026
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| CLOVER Closed-Loop Value Estimation & Ranking for End-to-End Autonomous Driving Planning | 2026 | Self-Distillation · Scoring |  |  | — |
| RAD-2 Scaling Reinforcement Learning in a Generator-Discriminator Framework | 2026 | RL · Generator-Discriminator |  | — | — |
| SparseDriveV2 Scoring is All You Need for End-to-End Autonomous Driving | 2026 | Scoring · Factorized Vocab |  |  | — |
| Latent-WAM Latent World Action Modeling for End-to-End Autonomous Driving | 2026 | World Model · Latent Compression |  | — | — |
| FlowAD Ego-Scene Interactive Modeling for Autonomous Driving | ICLR 2026 | Flow Matching · Ego-Scene |  |  | — |
| HDP Hyper Diffusion Planner: Unleashing the Potential of Diffusion Models for End-to-End Autonomous Driving | 2026 | Diffusion · Real-Vehicle |  |  | Project |
| MeanFuser Fast One-Step Multi-Modal Trajectory Generation via MeanFlow for End-to-End Autonomous Driving | CVPR 2026 | MeanFlow · One-Step |  |  | — |
| ResWorld Temporal Residual World Model for End-to-End Autonomous Driving | ICLR 2026 | World Model · Temporal Residual |  |  | — |
| Drive-JEPA Video JEPA Meets Multimodal Trajectory Distillation for End-to-End Driving | 2026 | V-JEPA · Distillation |  |  | — |
| PlannerRFT Reinforcing Diffusion Planners through Closed-Loop and Sample-Efficient Fine-Tuning | 2026 | Diffusion Planner · Reinforcement Fine-Tuning |  | — | Project |
| DrivoR Driving on Registers | CVPR 2026 | Register Tokens · ViT · Scoring |  |  | Project |
| AlignDrive Aligned Lateral-Longitudinal Planning for End-to-End Autonomous Driving | 2026 | Lateral-Longitudinal · Path-Conditioned |  |  | Project |
2025
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| DriveLaW Unifying Planning and Video Generation in a Latent Driving World | 2025 | World Model · Video Generation |  |  | Project |
| SimScale Learning to Drive via Real-World Simulation at Scale | 2025 | Scalable Simulation · Neural Rendering |  |  | Project |
| FutureX FutureX: Enhance End-to-End Autonomous Driving via Latent Chain-of-Thought World Model | 2025 | World Model · Latent CoT |  | — | — |
| Spatial Retrieval AD Spatial Retrieval Augmented Autonomous Driving | 2025 | Retrieval · Geo Images |  |  | Project |
| UniMM-V2X UniMM-V2X: MoE-Enhanced Multi-Level Fusion for End-to-End Cooperative Autonomous Driving | 2025 | MoE · Multi-Agent |  |  | — |
| UniLION UniLION: Towards Unified Autonomous Driving Model with Linear Group RNNs | 2025 | Linear RNN |  |  | — |
| DiffusionDriveV2 DiffusionDriveV2: Reinforcement Learning-Constrained Truncated Diffusion Modeling in End-to-End Autonomous Driving | 2025 | Diffusion · RL |  |  | — |
| LAP LAP: Fast Latent Diffusion Planner with Fine-Grained Feature Distillation for Autonomous Driving | 2025 | Latent Diffusion · Planning |  |  | — |
| GuideFlow GuideFlow: Constraint-Guided Flow Matching for Planning in End-to-End Autonomous Driving | 2025 | Generative · Flow Matching |  |  | — |
| DiffRefiner DiffRefiner: Coarse to Fine Trajectory Planning via Diffusion Refinement with Semantic Interaction for End to End Autonomous Driving | 2025 | Diffusion · Refinement |  |  | — |
| ResAD ResAD: Normalized Residual Trajectory Modeling for End-to-End Autonomous Driving | 2025 | Trajectory Modeling |  |  | — |
| SeerDrive Future-Aware End-to-End Driving: Bidirectional Modeling of Trajectory Planning and Scene Evolution | NeurIPS 2025 | World Model · Planning |  |  | — |
| BridgeDrive Diffusion Bridge Policy for Closed-Loop Trajectory Planning in Autonomous Driving | ICLR 2026 | Diffusion Bridge · Anchor-to-Refined |  |  | — |
| DriveDPO DriveDPO: Policy Learning via Safety DPO For End-to-End Autonomous Driving | 2025 | DPO · Safety |  | — | — |
| AnchDrive AnchDrive: Bootstrapping Diffusion Policies with Hybrid Trajectory Anchors for End-to-End Driving | 2025 | Diffusion · Anchors |  | — | — |
| AdaThinkDrive AdaThinkDrive: Adaptive Thinking via Reinforcement Learning for Autonomous Driving | 2025 | RL · CoT |  | — | — |
| VeteranAD Perception in Plan: Coupled Perception and Planning for End-to-End Autonomous Driving | 2025 | Perception-Planning |  |  | — |
| EvaDrive Evolutionary Adversarial Policy Optimization for End-to-End Autonomous Driving | 2025 | RL · Adversarial |  | — | — |
| ReconDreamer-RL Enhancing Reinforcement Learning via Diffusion-based Scene Reconstruction | 2025 | RL · World Model |  |  | — |
| GMF-Drive Gated Mamba Fusion with Spatial-Aware BEV Representation for End-to-End Autonomous Driving | 2025 | Mamba · Fusion |  | — | — |
| DistillDrive End-to-End Multi-Mode Autonomous Driving Distillation by Isomorphic Hetero-Source Planning Model | 2025 | Distillation |  |  | — |
| GEMINUS Dual-aware Global and Scene-Adaptive Mixture-of-Experts for End-to-End Autonomous Driving | 2025 | MoE · Adaptive |  |  | — |
| DiVER Breaking Imitation Bottlenecks: Reinforced Diffusion Powers Diverse Trajectory Generation | 2025 | RL · Diffusion |  | — | — |
| World4Drive End-to-End Autonomous Driving via Intention-aware Physical Latent World Model | ICCV 2025 | World Model |  |  | — |
| FocalAD Local Motion Planning for End-to-End Autonomous Driving | 2025 | Motion Planning |  | — | — |
| GaussianFusion Gaussian-Based Multi-Sensor Fusion for End-to-End Autonomous Driving | 2025 | Gaussian Splatting · Fusion |  |  | — |
| CogAD Cognitive-Hierarchy Guided End-to-End Autonomous Driving | 2025 | Cognitive · Hierarchy |  | — | — |
| DiffE2E Rethinking End-to-End Driving with a Hybrid Action Diffusion and Supervised Policy | 2025 | Diffusion · Hybrid |  | — | Project |
| TransDiffuser End-to-end Trajectory Generation with Decorrelated Multi-modal Representation for Autonomous Driving | 2025 | Diffusion · Multimodal |  | — | — |
| MomAD Don’t Shake the Wheel: Momentum-Aware Planning in End-to-End Autonomous Driving | CVPR 2025 | Planning · Momentum |  |  | — |
| Consistency Predictive Planner for Autonomous Driving with Consistency Models | 2025 | Consistency · Planning |  | — | — |
| ARTEMIS Autoregressive End-to-End Trajectory Planning with Mixture of Experts for Autonomous Driving | 2025 | MoE · Autoregressive |  | — | — |
| TTOG Two Tasks, One Goal: Uniting Motion and Planning for Excellent End To End Autonomous Driving Performance | 2025 | Multi-task |  | — | — |
| DiffusionDrive Truncated Diffusion Model for End-to-End Autonomous Driving | CVPR 2025 | Diffusion |  |  | — |
| WoTE End-to-End Driving with Online Trajectory Evaluation via BEV World Model | 2025 | World Model · BEV |  |  | — |
| DMAD Divide and Merge: Motion and Semantic Learning in End-to-End Autonomous Driving | 2025 | Multi-task |  |  | — |
| Centaur Robust End-to-End Autonomous Driving with Test-Time Training | 2025 | Test-Time Training |  | — | — |
| Drive in Corridors Enhancing the Safety of End-to-end Autonomous Driving via Corridor Learning and Planning | 2025 | Safety · Planning |  | — | — |
| BridgeAD Bridging Past and Future: End-to-End Autonomous Driving with Historical Prediction and Planning | CVPR 2025 | Prediction · Planning |  |  | — |
| Hydra-MDP++ Advancing End-to-End Driving via Expert-Guided Hydra-Distillation | 2025 | Distillation · Multi-head |  |  | — |
| DiffAD A Unified Diffusion Modeling Approach for Autonomous Driving | 2025 | Diffusion |  | — | — |
| GoalFlow Goal-Driven Flow Matching for Multimodal Trajectories Generation in End-to-End Autonomous Driving | CVPR 2025 | Flow Matching |  |  | — |
| HiP-AD Hierarchical and Multi-Granularity Planning with Deformable Attention for Autonomous Driving in a Single Decoder | ICCV 2025 | Attention · Planning |  |  | — |
| LAW Enhancing End-to-End Autonomous Driving with Latent World Model | ICLR 2025 | World Model |  |  | — |
| DriveTransformer Unified Transformer for Scalable End-to-End Autonomous Driving | ICLR 2025 | Transformer |  |  | — |
| UncAD Towards Safe End-to-end Autonomous Driving via Online Map Uncertainty | ICRA 2025 | Uncertainty · Map |  |  | — |
| RAD Training an End-to-End Driving Policy via Large-Scale 3DGS-based Reinforcement Learning | 2025 | RL · 3DGS |  | — | Project |
| OAD Trajectory Offset Learning: A Framework for Enhanced End-to-End Autonomous Driving | 2025 | Trajectory · Offset |  |  | — |
2024
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| GaussianAD Gaussian-Centric End-to-End Autonomous Driving | 2024 | Gaussian Splatting · Perception |  |  | — |
| MA2T Module-wise Adaptive Adversarial Training for End-to-end Autonomous Driving | 2024 | Adversarial · Robustness |  | — | — |
| Hint-AD Holistically Aligned Interpretability in End-to-End Autonomous Driving | 2024 | Interpretability · Alignment |  |  | Project |
| DRAMA An Efficient End-to-end Motion Planner for Autonomous Driving with Mamba | CVPR 2025 | Mamba · Motion Planning |  |  | Project |
| PPAD Iterative Interactions of Prediction and Planning for End-to-end Autonomous Driving | ECCV 2024 | Prediction · Planning |  |  | — |
| BEV-Planner Is Ego Status All You Need for Open-Loop End-to-End Autonomous Driving? | CVPR 2024 | BEV · Evaluation |  |  | — |
| EfficientFuser Efficient Fusion and Task Guided Embedding for End-to-end Autonomous Driving | 2024 | Efficient · Fusion |  | — | — |
| UAD End-to-End Autonomous Driving without Costly Modularization and 3D Manual Annotation | 2024 | Unsupervised |  | — | — |
| Hydra-MDP End-to-end Multimodal Planning with Multi-target Hydra-Distillation | 2024 | Distillation · Multimodal |  | | — |
| DualAD Disentangling the Dynamic and Static World for End-to-End Driving | CVPR 2025 | Dual-Stream · Dynamic |  |  | — |
| SparseDrive End-to-End Autonomous Driving via Sparse Scene Representation | 2024 | Sparse · Scene Rep |  |  | — |
| GAD GAD-Generative Learning for HD Map-Free Autonomous Driving | 2024 | Generative · Map-Free |  |  | — |
| SparseAD Sparse Query-Centric Paradigm for Efficient End-to-End Autonomous Driving | 2024 | Sparse · Query |  | — | — |
| GenAD Generative End-to-End Autonomous Driving | ECCV 2024 | Generative · Prediction |  |  | — |
| GraphAD Interaction Scene Graph for End-to-end Autonomous Driving | 2024 | Graph · Interaction |  |  | — |
| ActiveAD Planning-Oriented Active Learning for End-to-End Autonomous Driving | 2024 | Active Learning |  | — | — |
| VADv2 End-to-End Vectorized Autonomous Driving via Probabilistic Planning | 2024 | Vectorized · Probabilistic |  |  | — |
2023
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| DriveAdapter Breaking the Coupling Barrier of Perception and Planning in End-to-End Autonomous Driving | ICCV 2023 | Adapter · Decoupling |  |  | — |
| VAD Vectorized Scene Representation for Efficient Autonomous Driving | ICCV 2023 | Vectorized · Efficient |  |  | — |
| ThinkTwice Think Twice before Driving: Towards Scalable Decoders for End-to-End Autonomous Driving | CVPR 2023 | Decoder · Refinement |  |  | — |
| ReasonNet End-to-End Driving with Temporal and Global Reasoning | CVPR 2023 | Reasoning · Temporal |  |  | — |
| SuperDriverAI Towards Design and Implementation for End-to-End Learning-based Autonomous Driving | 2023 | Attention · DNN |  | — | — |
| UniAD Planning-oriented Autonomous Driving | CVPR 2023 | Multi-task · Unified |  |  | — |
| E2E Dense End-to-End Learning of Behavioural Inputs for Autonomous Driving in Dense Traffic | IROS 2023 | Optimization · Dense Traffic |  | — | — |
| CRCHFL Communication Resources Constrained Hierarchical Federated Learning for End-to-End Autonomous Driving | IROS 2023 | Federated Learning |  | — | — |
| PPGeo Policy pre-training for autonomous driving via self-supervised geometric modeling | ICLR 2023 | Self-Supervised · Geometric |  |  | — |
Before 2023
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| MMFN Multi-Modal-Fusion-Net for End-to-End Driving | IROS 2022 | Fusion · Multi-Modal |  |  | — |
| KEMP Keyframe-Based Hierarchical End-to-End Deep Model for Long-Term Trajectory Prediction | ICRA 2022 | Keyframe · Hierarchical |  | — | — |
| TCP Trajectory-guided Control Prediction for End-to-end Autonomous Driving: A Simple yet Strong Baseline | NeurIPS 2022 | Trajectory · Control |  |  | — |
| ST-P3 End-to-end Vision-based Autonomous Driving via Spatial-Temporal Feature Learning | ECCV 2022 | Spatial-Temporal · Interpretable |  |  | — |
| MP3 A Unified Model to Map, Perceive, Predict and Plan | CVPR 2021 | Mapless · Prediction | Paper | — | — |
| Multitask Multi-task Learning with Attention for End-to-end Autonomous Driving | CVPR 2021 | Multi-task · Attention |  |  | — |
| Transfuser Multi-Modal Fusion Transformer for End-to-End Autonomous Driving | CVPR 2021 | Transformer · Fusion | Paper |  | — |
| NEAT Neural Attention Fields for End-to-End Autonomous Driving | ICCV 2021 | Attention Fields · BEV | Paper |  | — |
| Fast-LiDARNet Efficient and Robust LiDAR-Based End-to-End Navigation | ICRA 2021 | LiDAR · Efficient |  | — | — |
| IVMP Learning Interpretable End-to-End Vision-Based Motion Planning for Autonomous Driving with Optical Flow Distillation | ICRA 2021 | Interpretable · Optical Flow |  | — | Project |
| P3 Perceive, Predict, and Plan: Safe Motion Planning Through Interpretable Semantic Representations | ECCV 2020 | Semantic · Interpretability |  | — | — |
| DARB Exploring data aggregation in policy learning for vision-based urban autonomous driving | CVPR 2020 | Data Aggregation · Policy | Paper |  | — |
| Roach End-to-End Urban Driving by Imitating a Reinforcement Learning Coach | ICCV 2021 | RL · Imitation |  |  | — |
| LBC Learning by cheating | CoRL 2019 | Knowledge Distillation |  |  | — |
| CIL End-to-End driving via conditional imitation learning | CoRL 2018 | Imitation Learning |  |  | — |
| Drive in A Day Learning to drive in a day | 2018 | RL |  |  | — |
| CNN E2E End to End Learning for Self-Driving Cars | 2016 | CNN · Imitation |  |  | — |
| ALVINN An autonomous land vehicle in a neural network | NeurIPS 1988 | Neural Network | Paper | — | — |
VLM-Centric End-to-End Methods
VLM-Centric End-to-End Methods
2026
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| ReflectDrive-2 Reinforcement-Learning-Aligned Self-Editing for Discrete Diffusion Driving | 2026 | Discrete Diffusion · Self-Edit · RL |  | — | — |
| OneDrive Unified Multi-Paradigm Driving with Vision-Language-Action Models | 2026 | Single Decoder · Multi-Paradigm |  |  | — |
| UniDriveVLA Unifying Understanding, Perception, and Action Planning for Autonomous Driving | 2026 | MoT · Expert Decoupling |  |  | Project |
| AutoDrive-P³ Unified Chain of Perception–Prediction–Planning Thought via Reinforcement Fine-Tuning | ICLR 2026 | P³ CoT · GRPO |  |  | — |
| DynVLA Learning World Dynamics for Action Reasoning in Autonomous Driving | 2026 | Dynamics CoT · RFT |  |  | — |
| LaST-VLA Thinking in Latent Spatio-Temporal Space for Vision-Language-Action in Autonomous Driving | 2026 | Latent CoT · GRPO |  |  | — |
| ELF-VLA Unleashing VLA Potentials in Autonomous Driving via Explicit Learning from Failures | 2026 | Failure Diagnostics · RL |  | — | — |
| VGGDrive Empowering Vision-Language Models with Cross-View Geometric Grounding for Autonomous Driving | CVPR 2026 | VLM · 3D Geometry |  |  | — |
| HiST-VLA A Hierarchical Spatio-Temporal Vision-Language-Action Model for End-to-End Autonomous Driving | 2026 | VLA · Spatio-Temporal · Token Sparse |  | — | — |
| SparseOccVLA Bridging Occupancy and Vision-Language Models via Sparse Queries | 2026 | Sparse Occupancy · Unified 4D Understanding |  |  | Project |
| SGDrive Scene-to-Goal Hierarchical World Cognition for Autonomous Driving | 2026 | Hierarchical Cognition · Scene-Agent-Goal |  |  | — |
2025
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| Counterfactual VLA Self-Reflective Vision-Language-Action Model with Adaptive Reasoning | 2025 | Self-Reflective · Counterfactual Reasoning |  | — | — |
| ColaVLA Leveraging Cognitive Latent Reasoning for Hierarchical Parallel Trajectory Planning | 2025 | Cognitive Latent Reasoning · Parallel Planning |  |  | Project |
| DrivePI DrivePI: Spatial-aware 4D MLLM for Unified Autonomous Driving Understanding, Perception, Prediction and Planning | 2025 | 4D Spatial · Occupancy |  |  | — |
| WAM-Diff WAM-Diff: A Masked Diffusion VLA Framework with MoE and Online Reinforcement Learning for Autonomous Driving | 2025 | Masked Diffusion · MoE · Online RL |  |  | — |
| SpaceDrive SpaceDrive: Infusing Spatial Awareness into VLM-based Autonomous Driving | 2025 | Spatial Encoding |  |  | Project |
| OpenREAD OpenREAD: Reinforced Open-Ended Reasoning for End-to-End Autonomous Driving with LLM-as-Critic | 2025 | RFT/RL · LLM-as-Critic |  |  | |
| CoT4AD CoT4AD: A Vision-Language-Action Model with Explicit Chain-of-Thought Reasoning | 2025 | VLA · CoT |  | — | — |
| MPA Model-Based Policy Adaptation for Closed-Loop End-to-End Autonomous Driving | NeurIPS 2025 | Model-Based · Sim |  | — | Project |
| AD-R1 AD-R1: Closed-Loop Reinforcement Learning with Impartial World Models | 2025 | RL · World Model |  | — | — |
| Alpamayo-R1 Alpamayo-R1: Bridging Reasoning and Action Prediction for Generalizable Autonomous Driving | 2025 | VLA · Reasoning |  |  | — |
| DriveVLA-W0 DRIVEVLA-W0: World Models Amplify Data Scaling Law in Autonomous Driving | 2025 | VLA · World Model |  |  | — |
| MTRDrive MTRDrive: Memory-Tool Synergistic Reasoning for Robust Autonomous Driving | 2025 | VLM · Memory |  | — | — |
| ReflectDrive Discrete Diffusion for Reflective Vision-Language-Action Models in Autonomous Driving | 2025 | Diffusion · VLA |  | — | — |
| IRL-VLA IRL-VLA: Training an Vision-Language-Action Policy via Reward World Model | 2025 | IRL · VLA |  |  | — |
| Prune2Drive Prune2Drive: A Plug-and-Play Framework for Accelerating Vision-Language Models | 2025 | VLM · Pruning |  | — | — |
| FastDriveVLA FastDriveVLA: Efficient End-to-End Driving via Plug-and-Play Reconstruction-based Token Pruning | 2025 | VLA · Pruning |  | — | — |
| MCAM Multimodal Causal Analysis Model for Ego-Vehicle-Level Driving Video Understanding | 2025 | Causal · Multimodal |  |  | — |
| AutoDrive-R² Incentivizing Reasoning and Self-Reflection Capacity for VLA Model in Autonomous Driving | 2025 | VLA · Reflection |  | — | — |
| DriveAgent-R1 Advancing VLM-based Autonomous Driving with Hybrid Thinking and Active Perception | 2025 | VLM · Active |  | — | — |
| NavigScene Bridging Local Perception and Global Navigation for Beyond-Visual-Range Autonomous Driving | 2025 | Navigation · Perception |  | — | — |
| ADRD LLM-DRIVEN AUTONOMOUS DRIVING BASED ON RULE-BASED DECISION SYSTEMS | 2025 | LLM · Rule-Based |  | — | — |
| AutoVLA A Vision-Language-Action Model for End-to-End Autonomous Driving with Adaptive Reasoning | 2025 | VLA · RL |  |  | Project |
| Poutine Vision-Language-Trajectory Pre-Training and Reinforcement Learning Post-Training | 2025 | VLT · RL |  | — | — |
| ReCogDrive A Reinforced Cognitive Framework for End-to-End Autonomous Driving | 2025 | VLM · Diffusion |  |  | Project |
| AD-EE Early Exiting for Fast and Reliable Vision-Language Models in Autonomous Driving | 2025 | VLM · Efficient |  | — | — |
| FastDrive Structured Labeling Enables Faster Vision-Language Models for End-to-End Autonomous Driving | 2025 | VLM · Structured |  | — | — |
| HMVLM Multistage Reasoning-Enhanced Vision-Language Model for Long-Tailed Driving Scenarios | 2025 | VLM · Long-Tail |  | — | — |
| S4-Driver Scalable Self-Supervised Driving Multimodal Large Language Model | CVPR 2025 | Self-Supervised · MLLM |  | — | — |
| DiffVLA Vision-Language Guided Diffusion Planning for Autonomous Driving | 2025 | Diffusion · VLM |  | — | — |
| X-Driver Explainable Autonomous Driving with Vision-Language Models | 2025 | MLLM · CoT |  | — | — |
| DriveGPT4-V2 Harnessing Large Language Model Capabilities for Enhanced Closed-Loop Autonomous Driving | CVPR 2025 | LLM · Closed-Loop | | — | — |
| DriveMind A Dual-VLM based Reinforcement Learning Framework for Autonomous Driving | 2025 | Dual-VLM · RL |  | — | — |
| ReasonPlan Unified Scene Prediction and Decision Reasoning for Closed-loop Autonomous Driving | 2025 | MLLM · Reasoning |  |  | — |
| FutureSightDrive Thinking Visually with Spatio-Temporal CoT for Autonomous Driving | 2025 | CoT · Spatio-Temporal |  |  | — |
| PADriver Towards Personalized Autonomous Driving | 2025 | MLLM · Personalized |  | — | — |
| LDM Unlock the Power of Unlabeled Data in Language Driving Model | ICRA 2025 | Self-Supervised · Distillation |  | — | — |
| DriveMoE Mixture-of-Experts for Vision-Language-Action Model in End-to-End Autonomous Driving | 2025 | MoE · VLA |  |  | Project |
| DriveMonkey Extending Large Vision-Language Model for Diverse Interactive Tasks in Autonomous Driving | 2025 | LVLM · Interactive |  |  | — |
| AgentThink A Unified Framework for Tool-Augmented Chain-of-Thought Reasoning in Vision-Language Models | 2025 | CoT · Tools |  | — | — |
| DSDrive Distilling Large Language Model for Lightweight End-to-End Autonomous Driving | 2025 | Distillation · Lightweight |  | — | — |
| LightEMMA Lightweight End-to-end Multimodal Autonomous Driving | 2025 | Lightweight · Multimodal |  |  | — |
| THCAD Towards Human-Centric Autonomous Driving: A Fast-Slow Architecture Integrating LLM Guidance with RL | 2025 | LLM · RL · Fast-Slow |  | — | — |
| DriveSOTIF Advancing Perception SOTIF Through Multimodal Large Language Models | 2025 | SOTIF · MLLM |  | — | — |
| Actor-Reasoner Interact, Instruct to Improve: A LLM-Driven Parallel Actor-Reasoner Framework | 2025 | LLM · Interaction |  |  | — |
| MPDrive Improving Spatial Understanding with Marker-Based Prompt Learning for Autonomous Driving | CVPR 2025 | Prompt · Spatial |  | — | — |
| V3LMA Visual 3D-enhanced Language Model for Autonomous Driving | 2025 | 3D · LVLM |  | — | — |
| OpenDriveVLA Towards End-to-end Autonomous Driving with Large Vision Language Action Model | 2025 | VLA · Open-Source |  |  | Project |
| SimLingo Vision-Only Closed-Loop Autonomous Driving with Language-Action Alignment | CVPR 2025 | VLA · Closed-Loop | |  | Project |
| SAFEAUTO KNOWLEDGE-ENHANCED SAFE AUTONOMOUS DRIVING WITH MULTIMODAL FOUNDATION MODELS | ICLR 2025 | Safety · Multimodal |  |  | — |
| NuGrounding A Multi-View 3D Visual Grounding Framework in Autonomous Driving | 2025 | Grounding · 3D |  | — | — |
| CoT-Drive Efficient Motion Forecasting for Autonomous Driving with LLMs and Chain-of-Thought Prompting | 2025 | CoT · Forecasting |  | — | — |
| CoLMDriver LLM-based Negotiation Benefits Cooperative Autonomous Driving | 2025 | Cooperative · LLM |  |  | — |
| AlphaDrive Unleashing the Power of VLMs in Autonomous Driving via Reinforcement Learning and Reasoning | 2025 | RL · Reasoning |  |  | — |
| TrackingMeetsLMM Tracking Meets Large Multimodal Models for Driving Scenario Understanding | 2025 | Tracking · LMM |  |  | — |
| BEVDriver Leveraging BEV Maps in LLMs for Robust Closed-Loop Driving | 2025 | BEV · LLM |  | — | — |
| DynRsl-VLM Enhancing Autonomous Driving Perception with Dynamic Resolution Vision-Language Models | 2025 | Dynamic Res · VLM |  | — | — |
| Sce2DriveX A Generalized MLLM Framework for Scene-to-Drive Learning | 2025 | MLLM · Scene |  | — | — |
| VLM-Assisted-CL VLM-Assisted Continual learning for Visual Question Answering in Self-Driving | 2025 | Continual Learning |  | — | — |
| LeapVAD A Leap in Autonomous Driving via Cognitive Perception and Dual-Process Thinking | 2025 | Cognitive · Dual-Process |  |  | Project |
2024
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| VLM-RL A Unified Vision Language Model and Reinforcement Learning Framework for Safe Autonomous Driving | 2024 | RL · VLM |  |  | Project |
| GPVL Generative Planning with 3D-vision Language Pre-training for End-to-End Autonomous Driving | AAAI 2025 | Generative · 3D-VL |  |  | — |
| CALMM-Drive Confidence-Aware Autonomous Driving with Large Multimodal Model | 2024 | CoT · Confidence |  | — | — |
| WiseAD Knowledge Augmented End-to-End Autonomous Driving with Vision-Language Model | 2024 | VLM · Reasoning |  |  | — |
| OpenEMMA Open-Source Multimodal Model for End-to-End Autonomous Driving | WACV 2025 | Open-Source · Multimodal |  |  | — |
| FeD Feedback-Guided Autonomous Driving | CVPR 2024 | Feedback · LLM | Paper | — | Project |
| LeapAD Continuously learning, adapting, and improving: A dual-process approach to autonomous driving | NeurIPS 2024 | Dual-Process · Continual |  |  | Project |
| DriveMM All-in-One Large Multimodal Model for Autonomous Driving | 2024 | Multimodal · Generalization |  |  | Project |
| Exp-Planning Explanation for Trajectory Planning using Multi-modal Large Language Model for Autonomous Driving | ECCV 2024 | Explainability · Planning |  | — | — |
| LaVida Drive Vision-Text Interaction VLM for Autonomous Driving with Token Selection, Recovery and Enhancement | 2024 | VQA · Interaction |  | — | — |
| EMMA End-to-End Multimodal Model for Autonomous Driving | 2024 | End-to-End · Multimodal |  | — | — |
| DriVLMe Enhancing LLM-based Autonomous Driving Agents with Embodied and Social Experiences | IROS 2024 | Embodied · Social |  |  | Project |
| OccLLaMA An Occupancy-Language-Action Generative World Model for Autonomous Driving | 2024 | World Model · Occupancy |  | — | — |
| MiniDrive More Efficient Vision-Language Models with Multi-Level 2D Features as Text Tokens | 2024 | Efficient · MoE |  | — | — |
| RDA-Driver Making Large Language Models Better Planners with Reasoning-Decision Alignment | ECCV 2024 | Reasoning · Alignment |  | — | — |
| EC-Drive Edge-Cloud Collaborative Motion Planning for Autonomous Driving with Large Language Models | ICCT 2024 | Edge-Cloud · Collaborative |  | — | Project |
| V2X-VLM End-to-End V2X Cooperative Autonomous Driving Through Large Vision-Language Models | 2024 | V2X · Cooperative |  |  | Project |
| Cube-LLM Language-Image Models with 3D Understanding | 2024 | 3D · Language-Image |  | — | Project |
| VLM-MPC Vision Language Foundation Model (VLM)-Guided Model Predictive Controller (MPC) | 2024 | MPC · Control |  | — | — |
| SimpleLLM4AD An End-to-End Vision-Language Model with Graph Visual Question Answering | IEIT Systems | Graph VQA · Pipeline |  | — | — |
| AsyncDriver Asynchronous Large Language Model Enhanced Planner for Autonomous Driving | ECCV 2024 | Asynchronous · Closed-Loop |  |  | — |
| AD-H AUTONOMOUS DRIVING WITH HIERARCHICAL AGENTS | ICLR 2025 | Hierarchical · Agents | Paper | — | — |
| CarLLaVA Vision language models for camera-only closed-loop driving | 2024 | Camera-only · Closed-Loop |  | — | Project |
| PlanAgent A Multi-modal Large Language Agent for Closed-loop Vehicle Motion Planning | 2024 | Agent · Closed-Loop |  | — | — |
| Atlas Is a 3D-Tokenized LLM the Key to Reliable Autonomous Driving? | 2024 | 3D-Tokenized · LLM |  | — | — |
| TRR Agent Interpretable Decision-Making for Autonomous Vehicles with Retrieval-Augmented Reasoning via LLM | 2024 | RAG · Rule-Based |  | — | — |
| OmniDrive A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning | CVPR 2025 | Counterfactual · 3D |  |  | — |
| Co-driver VLM-based Autonomous Driving Assistant with Human-like Behavior and Understanding | 2024 | Assistant · Human-like |  | — | — |
| AgentsCoDriver Large Language Model Empowered Collaborative Driving with Lifelong Learning | 2024 | Collaborative · Lifelong |  | — | — |
| EM-VLM4AD Multi-Frame, Lightweight & Efficient Vision-Language Models for Question Answering | CVPR 2024 | Efficient · VQA |  |  | — |
| LeGo-Drive Language-enhanced Goal-oriented Closed-Loop End-to-End Autonomous Driving | IROS 2024 | Goal-oriented · Closed-Loop |  |  | Project |
| Hybrid Reasoning Hybrid Reasoning Based on Large Language Models for Autonomous Car Driving | ICCMA 2024 | Reasoning · Math |  | — | — |
| VLAAD Vision and Language Assistant for Autonomous Driving | WACV 2024 | Assistant · Explainability | Paper | — | — |
| ELM Embodied Understanding of Driving Scenarios | ECCV 2024 | Embodied · Scene Understanding |  | — | — |
| RAG-Driver Generalisable Driving Explanations with Retrieval-Augmented In-Context Learning | RSS 2024 | RAG · In-Context |  |  | Project |
| BEV-TSR Text-Scene Retrieval in BEV Space for Autonomous Driving | AAAI 2025 | Retrieval · BEV |  | — | — |
| LLaDA Driving Everywhere with Large Language Model Policy Adaptation | CVPR 2024 | Adaptation · Traffic Rules |  |  | Project |
2023
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| LingoQA Visual Question Answering for Autonomous Driving | ECCV 2024 | VQA · LLM |  |  | — |
| LaMPilot An Open Benchmark Dataset for Autonomous Driving with Language Model Programs | CVPR 2024 | Benchmark · LLM |  |  | — |
| LLM-ASSIST Enhancing Closed-Loop Planning with Language-Based Reasoning | 2023 | Planning · Reasoning |  | — | Project |
| DriveLM Driving with Graph Visual Question Answering | ECCV 2024 | Graph VQA · Reasoning |  |  | — |
| DriveMLM Aligning Multi-Modal Large Language Models with Behavioral Planning States | 2023 | MLLM · Planning |  |  | — |
| LiDAR-LLM Exploring the Potential of Large Language Models for 3D LiDAR Understanding | 2023 | LiDAR · LLM |  | — | Project |
| Talk2BEV Language-enhanced Bird's-eye View Maps for Autonomous Driving | 2023 | BEV · LVLM |  |  | Project |
| Talk2Drive Personalized Autonomous Driving with Large Language Models: Field Experiments | 2023 | Personalized · LLM |  | — | Project |
| LMDrive Closed-Loop End-to-End Driving with Large Language Models | CVPR 2024 | Closed-Loop · LLM |  |  | — |
| Reason2Drive Towards Interpretable and Chain-based Reasoning for Autonomous Driving | ECCV 2024 | Reasoning · Interpretability |  |  | — |
| CAVG GPT-4 Enhanced Multimodal Grounding for Autonomous Driving | 2023 | Grounding · GPT-4 |  |  | — |
| Dolphins Multimodal Language Model for Driving | ECCV 2024 | Multimodal · VLM |  |  | Project |
| Agent-Driver A Language Agent for Autonomous Driving | COLM 2024 | Agent · Memory |  |  | Project |
| LLM-Safety Empowering Autonomous Driving with Large Language Models: A Safety Perspective | ICLR 2024 | Safety · MPC |  |  | — |
| Co-Pilot ChatGPT as Your Vehicle Co-Pilot: An Initial Attempt | 2023 | Co-Pilot · LLM | Paper | — | — |
| RRR Receive, Reason, and React: Drive as You Say with Large Language Models | ITSM 2024 | Tools · LLM |  | — | — |
| LanguageMPC Large Language Models as Decision Makers for Autonomous Driving | 2023 | MPC · CoT |  | — | — |
| Driving with LLMs Fusing Object-Level Vector Modality for Explainable Autonomous Driving | 2023 | Object-Level · Explainable |  |  | — |
| DriveGPT4 Interpretable End-to-end Autonomous Driving via Large Language Model | RAL | Interpretable · LLM | Paper | — | Project |
| GPT-Driver Learning to Drive with GPT | NeurIPS 2023 | Planner · GPT |  |  | Project |
| DiLu A Knowledge-Driven Approach to Autonomous Driving with Large Language Models | ICLR 2024 | Knowledge-Driven · Reflection |  |  | Project |
| Drive as You Speak Enabling Human-Like Interaction with Large Language Models in Autonomous Vehicles | 2023 | Interaction · LLM |  | — | — |
| HiLM-D Enhancing MLLMs with Multi-Scale High-Resolution Details for Autonomous Driving | IJCV | High-Res · MLLM |  | — | — |
| SurrealDriver Designing LLM-powered Generative Driver Agent Framework based on Human Data | 2023 | Generative · Agent |  | — | — |
| Drive Like a Human Rethinking Autonomous Driving with Large Language Models | 2023 | Reasoning · Reflection |  |  | — |
| ADAPT Action-aware Driving Caption Transformer | ICRA 2023 | Captioning · Transformer |  |  | — |
Hybrid End-to-End Methods
Hybrid End-to-End Methods
2026
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| DriveDreamer-Policy A Geometry-Grounded World–Action Model for Unified Generation and Planning | 2026 | WAM · Geometry-Grounded |  | — | Project |
| Uni-World VLA Interleaved World Modeling and Planning for Autonomous Driving | 2026 | Interleaved · World Model |  |  | — |
| HybridDriveVLA From Representational Complementarity to Dual Systems: Synergizing VLM and Vision-Only Backbones for End-to-End Driving | 2026 | Dual System · Fast-Slow |  | — | — |
| DriveWorld-VLA Unified Latent-Space World Modeling with Vision–Language–Action for Autonomous Driving | 2026 | World Model · VLA · Latent |  |  | — |
| LatentVLA Efficient Vision-Language Models for Autonomous Driving via Latent Action Prediction | 2026 | Latent Action · Knowledge Distillation |  | — | — |
2025
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| MindDrive MindDrive: An All-in-One Framework Bridging World Models and Vision-Language Model for End-to-End Autonomous Driving | 2025 | World Model · VLM Evaluator |  |  | Project |
| AdaDrive AdaDrive: Self-Adaptive Slow-Fast System for Language-Grounded Autonomous Driving | ICCV 2025 | Slow-Fast · LLM |  |  | — |
| ReAL-AD Towards Human-Like Reasoning in End-to-End Autonomous Driving | 2025 | Reasoning · VLM |  | — | Project |
| VLAD A VLM-Augmented Autonomous Driving Framework with Hierarchical Planning and Interpretable Decision Process | ITSC 2025 | VLM · Hierarchical |  | — | — |
| LeAD The LLM Enhanced Planning System Converged with End-to-end Autonomous Driving | 2025 | LLM · E2E |  | — | — |
| NetRoller Interfacing General and Specialized Models for End-to-End Autonomous Driving | 2025 | Adapter · VLM |  |  | — |
| SOLVE Synergy of Language-Vision and End-to-End Networks for Autonomous Driving | CVPR 2025 | VLM · Fusion |  | — | — |
| VERDI VLM-Embedded Reasoning for Autonomous Driving | 2025 | VLM · Reasoning |  | — | — |
| ALN-P3 Unified Language Alignment for Perception, Prediction, and Planning in Autonomous Driving | 2025 | Alignment · Language |  | — | — |
| VLM-E2E Enhancing End-to-End Autonomous Driving with Multimodal Driver Attention Fusion | 2025 | VLM · Attention |  | — | — |
| DIMA Distilling Multi-modal Large Language Models for Autonomous Driving | CVPR 2025 | Distillation · MLLM |  | — | — |
2024
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| VLM-AD End-to-End Autonomous Driving through Vision-Language Model Supervision | 2024 | Supervision · VLM |  | — | — |
| FASIONAD FAst and Slow FusION Thinking Systems for Human-Like Autonomous Driving | 2024 | Fast-Slow · Fusion |  | — | — |
| Senna Bridging Large Vision-Language Models and End-to-End Autonomous Driving | 2024 | VLM · Robustness |  |  | — |
| Hint-AD Holistically Aligned Interpretability in End-to-End Autonomous Driving | CoRL 2024 | Interpretability · Alignment | | | Project |
| DriveVLM The Convergence of Autonomous Driving and Large Vision-Language Models | CoRL 2024 | Hybrid · VLM |  | — | Project |
| DME-Driver Integrating Human Decision Logic and 3D Scene Perception in Autonomous Driving | AAAI 2025 | Logic · Perception |  | — | — |
| VLP Vision Language Planning for Autonomous Driving | CVPR 2024 | Planning · Reasoning |  | — | — |
Dataset
Normal Dataset
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code |
|---|---|---|---|---|
| NAVSIM Data-Driven Non-Reactive Autonomous Vehicle Simulation and Benchmarking | NeurIPS 2024 | Closed-Loop · Planning Benchmark |  |  |
| Bench2Drive Towards Multi-Ability Benchmarking of Closed-Loop End-to-End Autonomous Driving | NeurIPS 2024 | CARLA · Closed-Loop · Multi-Ability |  |  |
| nuScenes A Multimodal Dataset for Autonomous Driving | CVPR 2020 | Multimodal · LiDAR · Radar |  | Dataset |
| Waymo Waymo Open Dataset: Scalability in Perception | CVPR 2020 | Perception · LiDAR | Paper | Dataset |
| HUGSIM A Real-Time, Photo-Realistic and Closed-Loop Simulator for Autonomous Driving | 2024 | Gaussian Splatting · Closed-Loop Sim |  |  |
| ONCE One Million Scenes for Autonomous Driving | NeurIPS 2021 | Unsupervised · 3D Detection |  | Dataset |
| Lyft One Thousand and One Hours: Self-driving Motion Prediction Dataset | 2020 | Motion Prediction |  | Dataset |
| BDD100K A Diverse Driving Dataset for Heterogeneous Multitask Learning | CVPR 2020 | Multitask · Video |  |  |
| Argoverse 3D Tracking and Forecasting with Rich Maps | CVPR 2019 | Tracking · Forecasting · Maps |  | Dataset |
| ApolloScape The ApolloScape Open Dataset for Autonomous Driving | CVPR 2018 | Segmentation · LiDAR |  |  |
| CARLA An Open Urban Driving Simulator | CoRL 2017 | Simulator · Urban Driving |  | Dataset |
| Mapillary Vistas Semantic Understanding of Street Scenes | ICCV 2017 | Semantic Segmentation | Paper | Dataset |
| KITTI The KITTI Vision Benchmark Suite | CVPR 2012 | 3D Detection · Tracking |  | Dataset |
Vision Language Dataset
Vision Language Dataset
2025
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| nuScenesR²-6K Incentivizing Reasoning and Self-Reflection Capacity for VLA Model | 2025 | CoT · Reasoning | | — | — |
| Bench2ADVLM A Closed-Loop Benchmark for Vision-language Models | 2025 | Benchmark · Closed-Loop |  | — | — |
| Drive-R1 Bridging Reasoning and Planning in VLMs with RL | 2025 | RL · Reasoning |  | — | — |
| STSBench A Spatio-temporal Scenario Benchmark for MLLMs | 2025 | Spatio-Temporal · 3D |  | Dataset | Project |
| DriveAction A Benchmark for Exploring Human-like Driving Decisions in VLA Models | 2025 | Action-Driven · VLA |  | Dataset | Project |
| S4-Driver WOMD-Planning-ADE Benchmark: Scalable Self-Supervised Driving MLLM | CVPR 2025 | Self-Supervised · Planning |  | — | — |
| ImpromptuVLA Open Weights and Open Data for Driving Vision-Language-Action Models | 2025 | Open Data · VLA |  | Dataset | Project |
| NuInteract Extending Large Vision-Language Model for Diverse Interactive Tasks | 2025 | Interaction · VLM | | | Project |
| VLADBench Fine-Grained Evaluation of Large Vision-Language Models | 2025 | Evaluation · Reasoning |  | Dataset | Project |
| DriveLMM-o1 A Step-by-Step Reasoning Dataset and Large Multimodal Model | 2025 | Reasoning · MLLM |  | Dataset | Project |
| SimLingo Vision-Only Closed-Loop Autonomous Driving with Language-Action Alignment | CVPR 2025 | Alignment · Closed-Loop |  | Dataset | Project |
| Robusto-1 Comparing Humans and VLMs on real out-of-distribution AD VQA | 2025 | OOD · VQA |  | Dataset | — |
| DrivingVQA RIV-CoT: Retrieval-Based Interleaved Visual Chain-of-Thought | 2025 | VQA · CoT |  | Dataset | Project |
| DriveBench Are VLMs Ready for Autonomous Driving? An Empirical Study | ICCV 2025 | Reliability · Evaluation |  | Dataset | Project |
| CoVLA Comprehensive Vision-Language-Action Dataset | WACV 2025 | VLA · Video |  | Dataset | Project |
| WOMD-Reasoning A Large-Scale Dataset for Interaction Reasoning in Driving | ICML 2025 | Interaction · Reasoning |  | Dataset | Project |
| OmniDrive LLM-Agent for Autonomous Driving with 3D Perception | CVPR 2025 | 3D Perception · Agent | | | Project |
| CODA-LM Automated Evaluation of Large Vision-Language Models on Self-driving Corner Cases | WACV 2025 | Corner Cases · Evaluation |  | Dataset | Project |
| HiLM-D (DRAMA-ROLISP) Enhancing MLLMs with Multi-Scale High-Resolution Details | IJCV 2025 | Risk · High-Res | |  | Project |
| nuPrompt Language Prompt for Autonomous Driving | AAAI 2025 | Prompt · 3D |  |  | Project |
2024
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| SURDS Benchmarking Spatial Understanding and Reasoning in Driving Scenarios | 2024 | Spatial · Reasoning |  | Dataset | Project |
| ContextVLM Zero-Shot and Few-Shot Context Understanding | ITSC 2024 | Context · Few-Shot |  | Dataset | Project |
| DriveCoT Integrating Chain-of-Thought Reasoning with End-to-End Driving | 2024 | CoT · Reasoning |  | Dataset | Project |
| DriveVLM SUP-AD Dataset: The Convergence of Autonomous Driving and VLMs | CoRL 2024 | Scene Understanding · Planning | | — | Project |
| NuInstruct Holistic Autonomous Driving Understanding by BEV Injected Multi-Modal Large Models | CVPR 2024 | Instruction · BEV |  | Dataset | Project |
| DriveLM Driving with Graph Visual Question Answering | ECCV 2024 | Graph VQA · Graph | | Dataset | Project |
| LingoQA Visual Question Answering for Autonomous Driving | ECCV 2024 | VQA · Freeform | | | Project |
| LMDrive Closed-Loop End-to-End Driving with Large Language Models | 2024 | Closed-Loop · Language | | Dataset | Project |
| NuScenes-MQA Integrated Evaluation of Captions and QA using Markup Annotations | WACV 2024 | Captioning · QA |  | Dataset | Project |
| Talk2BEV Language-enhanced Bird’s-eye View Maps | ICRA 2024 | BEV · Maps | | Dataset | Project |
| DriveGPT4 Interpretable End-to-end Autonomous Driving via LLM | RA-L 2024 | Interpretable · Instruction |  | Dataset | Project |
| Rank2Tell A Multimodal Driving Dataset for Joint Importance Ranking and Reasoning | WACV 2024 | Ranking · Reasoning |  | Dataset | — |
| NuScenes-QA A Multi-Modal Visual Question Answering Benchmark | AAAI 2024 | VQA · Benchmark |  | Dataset | Project |
| MAPLM A Real-World Large-Scale Vision-Language Dataset for Map and Traffic Scene | CVPR 2024 | Map · Traffic | Paper | Dataset | Project |
2023
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| DriveMLM Aligning Multi-Modal Large Language Models with Behavioral Planning States | 2023 | Planning · Explanation | | | — |
| Reason2Drive Towards Interpretable and Chain-based Reasoning for Autonomous Driving | 2023 | Reasoning · Chain-based | | Dataset | Project |
| Refer-KITTI Referring Multi-Object Tracking | CVPR 2023 | Tracking · Referring |  |  | Project |
| DRAMA Joint Risk Localization and Captioning in Driving | WACV 2023 | Risk · Captioning |  | Dataset | Project |
Before 2023
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| SUTD-TrafficQA A Question Answering Benchmark and an Efficient Network for Video Reasoning | CVPR 2021 | Video QA · Reasoning |  | Dataset | Project |
| BDD-OIA Explainable Object-induced Action Decision for Autonomous Vehicles | CVPR 2020 | Explainable · Decision |  | Dataset | Project |
| HAD Grounding Human-to-Vehicle Advice for Self-driving Vehicles | CVPR 2019 | Advice · Grounding |  | Dataset | — |
| Talk2Car Taking Control of Your Self-Driving Car | EMNLP 2019 | Commands · Referral |  |  | Project |
| BDD-X Textual Explanations for Self-Driving Vehicles | ECCV 2018 | Explanation · Captioning |  |  | Project |
License
The GE2EAD resources is released under the Apache 2.0 license.
Significant stargazers

67 followers · starred Dec 2025
Similar repos


Languages
HTML
51.9%
CSS
44.8%
JavaScript
3.2%
Collects papers on autonomous driving E2E learning, VLM/VLA and Hybrid systems, with organized research branches and trends in these fields.
HTML
211
27 commits
updated May 27, 2026
README
Awesome-GE2EAD
This is the official repository for "Survey of General End-to-End Autonomous Driving: A Unified Perspective".
This project aims to provide a unified roadmap for the field by:
-
🗂️ Literature Taxonomy: Classifying methods into Conventional (e.g., UniAD), VLM-centric (e.g., DriveLM), and Hybrid (e.g., Senna) approaches.
-
💾 Dataset Curation: Collecting both Standard and Vision-Language datasets relevant to end-to-end AD.
-
📈 Trend Analysis: Outlining main research branches and emerging trends based on our survey.
Citation
If you find this project useful in your research, please consider citing:
@article{yang2025survey,
  title={Survey of General End-to-End Autonomous Driving: A Unified Perspective},
  author={Yang, Yixiang and Han, Chuanrong and Mao, Runhao and others},
  journal={TechRxiv},
  year={2025},
  month={December},
  doi={10.36227/techrxiv.176523315.56439138/v1},
  url={https://doi.org/10.36227/techrxiv.176523315.56439138/v1}
}
📌 Milestones
-
🚀 2025-12-24: We organize the list of papers in a completely new tabular format.
-
🚀 2025-12-10: The paper “Survey of General End-to-End Autonomous Driving: A Unified Perspective” was released, and this repository was made publicly available.
Table of Contents
Mindmap, Top Methods
GE2EAD Mindmap
Top Methods
Papers
Conventional End-to-End Methods (VA)
Conventional End-to-End Methods (VA)
2026
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| CLOVER Closed-Loop Value Estimation & Ranking for End-to-End Autonomous Driving Planning | 2026 | Self-Distillation · Scoring | | | — |
| RAD-2 Scaling Reinforcement Learning in a Generator-Discriminator Framework | 2026 | RL · Generator-Discriminator | | — | — |
| SparseDriveV2 Scoring is All You Need for End-to-End Autonomous Driving | 2026 | Scoring · Factorized Vocab | | | — |
| Latent-WAM Latent World Action Modeling for End-to-End Autonomous Driving | 2026 | World Model · Latent Compression | | — | — |
| FlowAD Ego-Scene Interactive Modeling for Autonomous Driving | ICLR 2026 | Flow Matching · Ego-Scene | | | — |
| HDP Hyper Diffusion Planner: Unleashing the Potential of Diffusion Models for End-to-End Autonomous Driving | 2026 | Diffusion · Real-Vehicle | | | Project |
| MeanFuser Fast One-Step Multi-Modal Trajectory Generation via MeanFlow for End-to-End Autonomous Driving | CVPR 2026 | MeanFlow · One-Step | | | — |
| ResWorld Temporal Residual World Model for End-to-End Autonomous Driving | ICLR 2026 | World Model · Temporal Residual | | | — |
| Drive-JEPA Video JEPA Meets Multimodal Trajectory Distillation for End-to-End Driving | 2026 | V-JEPA · Distillation | | | — |
| PlannerRFT Reinforcing Diffusion Planners through Closed-Loop and Sample-Efficient Fine-Tuning | 2026 | Diffusion Planner · Reinforcement Fine-Tuning | | — | Project |
| DrivoR Driving on Registers | CVPR 2026 | Register Tokens · ViT · Scoring | | | Project |
| AlignDrive Aligned Lateral-Longitudinal Planning for End-to-End Autonomous Driving | 2026 | Lateral-Longitudinal · Path-Conditioned | | | Project |
2025
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| DriveLaW Unifying Planning and Video Generation in a Latent Driving World | 2025 | World Model · Video Generation | | | Project |
| SimScale Learning to Drive via Real-World Simulation at Scale | 2025 | Scalable Simulation · Neural Rendering | | | Project |
| FutureX FutureX: Enhance End-to-End Autonomous Driving via Latent Chain-of-Thought World Model | 2025 | World Model · Latent CoT | | — | — |
| Spatial Retrieval AD Spatial Retrieval Augmented Autonomous Driving | 2025 | Retrieval · Geo Images | | | Project |
| UniMM-V2X UniMM-V2X: MoE-Enhanced Multi-Level Fusion for End-to-End Cooperative Autonomous Driving | 2025 | MoE · Multi-Agent | | | — |
| UniLION UniLION: Towards Unified Autonomous Driving Model with Linear Group RNNs | 2025 | Linear RNN | | | — |
| DiffusionDriveV2 DiffusionDriveV2: Reinforcement Learning-Constrained Truncated Diffusion Modeling in End-to-End Autonomous Driving | 2025 | Diffusion · RL | | | — |
| LAP LAP: Fast Latent Diffusion Planner with Fine-Grained Feature Distillation for Autonomous Driving | 2025 | Latent Diffusion · Planning | | | — |
| GuideFlow GuideFlow: Constraint-Guided Flow Matching for Planning in End-to-End Autonomous Driving | 2025 | Generative · Flow Matching | | | — |
| DiffRefiner DiffRefiner: Coarse to Fine Trajectory Planning via Diffusion Refinement with Semantic Interaction for End to End Autonomous Driving | 2025 | Diffusion · Refinement | | | — |
| ResAD ResAD: Normalized Residual Trajectory Modeling for End-to-End Autonomous Driving | 2025 | Trajectory Modeling | | | — |
| SeerDrive Future-Aware End-to-End Driving: Bidirectional Modeling of Trajectory Planning and Scene Evolution | NeurIPS 2025 | World Model · Planning | | | — |
| BridgeDrive Diffusion Bridge Policy for Closed-Loop Trajectory Planning in Autonomous Driving | ICLR 2026 | Diffusion Bridge · Anchor-to-Refined | | | — |
| DriveDPO DriveDPO: Policy Learning via Safety DPO For End-to-End Autonomous Driving | 2025 | DPO · Safety | | — | — |
| AnchDrive AnchDrive: Bootstrapping Diffusion Policies with Hybrid Trajectory Anchors for End-to-End Driving | 2025 | Diffusion · Anchors | | — | — |
| AdaThinkDrive AdaThinkDrive: Adaptive Thinking via Reinforcement Learning for Autonomous Driving | 2025 | RL · CoT | | — | — |
| VeteranAD Perception in Plan: Coupled Perception and Planning for End-to-End Autonomous Driving | 2025 | Perception-Planning | | | — |
| EvaDrive Evolutionary Adversarial Policy Optimization for End-to-End Autonomous Driving | 2025 | RL · Adversarial | | — | — |
| ReconDreamer-RL Enhancing Reinforcement Learning via Diffusion-based Scene Reconstruction | 2025 | RL · World Model | | | — |
| GMF-Drive Gated Mamba Fusion with Spatial-Aware BEV Representation for End-to-End Autonomous Driving | 2025 | Mamba · Fusion | | — | — |
| DistillDrive End-to-End Multi-Mode Autonomous Driving Distillation by Isomorphic Hetero-Source Planning Model | 2025 | Distillation | | | — |
| GEMINUS Dual-aware Global and Scene-Adaptive Mixture-of-Experts for End-to-End Autonomous Driving | 2025 | MoE · Adaptive | | | — |
| DiVER Breaking Imitation Bottlenecks: Reinforced Diffusion Powers Diverse Trajectory Generation | 2025 | RL · Diffusion | | — | — |
| World4Drive End-to-End Autonomous Driving via Intention-aware Physical Latent World Model | ICCV 2025 | World Model | | | — |
| FocalAD Local Motion Planning for End-to-End Autonomous Driving | 2025 | Motion Planning | | — | — |
| GaussianFusion Gaussian-Based Multi-Sensor Fusion for End-to-End Autonomous Driving | 2025 | Gaussian Splatting · Fusion | | | — |
| CogAD Cognitive-Hierarchy Guided End-to-End Autonomous Driving | 2025 | Cognitive · Hierarchy | | — | — |
| DiffE2E Rethinking End-to-End Driving with a Hybrid Action Diffusion and Supervised Policy | 2025 | Diffusion · Hybrid | | — | Project |
| TransDiffuser End-to-end Trajectory Generation with Decorrelated Multi-modal Representation for Autonomous Driving | 2025 | Diffusion · Multimodal | | — | — |
| MomAD Don’t Shake the Wheel: Momentum-Aware Planning in End-to-End Autonomous Driving | CVPR 2025 | Planning · Momentum | | | — |
| Consistency Predictive Planner for Autonomous Driving with Consistency Models | 2025 | Consistency · Planning | | — | — |
| ARTEMIS Autoregressive End-to-End Trajectory Planning with Mixture of Experts for Autonomous Driving | 2025 | MoE · Autoregressive | | — | — |
| TTOG Two Tasks, One Goal: Uniting Motion and Planning for Excellent End To End Autonomous Driving Performance | 2025 | Multi-task | | — | — |
| DiffusionDrive Truncated Diffusion Model for End-to-End Autonomous Driving | CVPR 2025 | Diffusion | | | — |
| WoTE End-to-End Driving with Online Trajectory Evaluation via BEV World Model | 2025 | World Model · BEV | | | — |
| DMAD Divide and Merge: Motion and Semantic Learning in End-to-End Autonomous Driving | 2025 | Multi-task | | | — |
| Centaur Robust End-to-End Autonomous Driving with Test-Time Training | 2025 | Test-Time Training | | — | — |
| Drive in Corridors Enhancing the Safety of End-to-end Autonomous Driving via Corridor Learning and Planning | 2025 | Safety · Planning | | — | — |
| BridgeAD Bridging Past and Future: End-to-End Autonomous Driving with Historical Prediction and Planning | CVPR 2025 | Prediction · Planning | | | — |
| Hydra-MDP++ Advancing End-to-End Driving via Expert-Guided Hydra-Distillation | 2025 | Distillation · Multi-head | | | — |
| DiffAD A Unified Diffusion Modeling Approach for Autonomous Driving | 2025 | Diffusion | | — | — |
| GoalFlow Goal-Driven Flow Matching for Multimodal Trajectories Generation in End-to-End Autonomous Driving | CVPR 2025 | Flow Matching | | | — |
| HiP-AD Hierarchical and Multi-Granularity Planning with Deformable Attention for Autonomous Driving in a Single Decoder | ICCV 2025 | Attention · Planning | | | — |
| LAW Enhancing End-to-End Autonomous Driving with Latent World Model | ICLR 2025 | World Model | | | — |
| DriveTransformer Unified Transformer for Scalable End-to-End Autonomous Driving | ICLR 2025 | Transformer | | | — |
| UncAD Towards Safe End-to-end Autonomous Driving via Online Map Uncertainty | ICRA 2025 | Uncertainty · Map | | | — |
| RAD Training an End-to-End Driving Policy via Large-Scale 3DGS-based Reinforcement Learning | 2025 | RL · 3DGS | | — | Project |
| OAD Trajectory Offset Learning: A Framework for Enhanced End-to-End Autonomous Driving | 2025 | Trajectory · Offset | | | — |
2024
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| GaussianAD Gaussian-Centric End-to-End Autonomous Driving | 2024 | Gaussian Splatting · Perception | | | — |
| MA2T Module-wise Adaptive Adversarial Training for End-to-end Autonomous Driving | 2024 | Adversarial · Robustness | | — | — |
| Hint-AD Holistically Aligned Interpretability in End-to-End Autonomous Driving | 2024 | Interpretability · Alignment | | | Project |
| DRAMA An Efficient End-to-end Motion Planner for Autonomous Driving with Mamba | CVPR 2025 | Mamba · Motion Planning | | | Project |
| PPAD Iterative Interactions of Prediction and Planning for End-to-end Autonomous Driving | ECCV 2024 | Prediction · Planning | | | — |
| BEV-Planner Is Ego Status All You Need for Open-Loop End-to-End Autonomous Driving? | CVPR 2024 | BEV · Evaluation | | | — |
| EfficientFuser Efficient Fusion and Task Guided Embedding for End-to-end Autonomous Driving | 2024 | Efficient · Fusion | | — | — |
| UAD End-to-End Autonomous Driving without Costly Modularization and 3D Manual Annotation | 2024 | Unsupervised | | — | — |
| Hydra-MDP End-to-end Multimodal Planning with Multi-target Hydra-Distillation | 2024 | Distillation · Multimodal | | | — |
| DualAD Disentangling the Dynamic and Static World for End-to-End Driving | CVPR 2025 | Dual-Stream · Dynamic | | | — |
| SparseDrive End-to-End Autonomous Driving via Sparse Scene Representation | 2024 | Sparse · Scene Rep | | | — |
| GAD GAD-Generative Learning for HD Map-Free Autonomous Driving | 2024 | Generative · Map-Free | | | — |
| SparseAD Sparse Query-Centric Paradigm for Efficient End-to-End Autonomous Driving | 2024 | Sparse · Query | | — | — |
| GenAD Generative End-to-End Autonomous Driving | ECCV 2024 | Generative · Prediction | | | — |
| GraphAD Interaction Scene Graph for End-to-end Autonomous Driving | 2024 | Graph · Interaction | | | — |
| ActiveAD Planning-Oriented Active Learning for End-to-End Autonomous Driving | 2024 | Active Learning | | — | — |
| VADv2 End-to-End Vectorized Autonomous Driving via Probabilistic Planning | 2024 | Vectorized · Probabilistic | | | — |
2023
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| DriveAdapter Breaking the Coupling Barrier of Perception and Planning in End-to-End Autonomous Driving | ICCV 2023 | Adapter · Decoupling | | | — |
| VAD Vectorized Scene Representation for Efficient Autonomous Driving | ICCV 2023 | Vectorized · Efficient | | | — |
| ThinkTwice Think Twice before Driving: Towards Scalable Decoders for End-to-End Autonomous Driving | CVPR 2023 | Decoder · Refinement | | | — |
| ReasonNet End-to-End Driving with Temporal and Global Reasoning | CVPR 2023 | Reasoning · Temporal | | | — |
| SuperDriverAI Towards Design and Implementation for End-to-End Learning-based Autonomous Driving | 2023 | Attention · DNN | | — | — |
| UniAD Planning-oriented Autonomous Driving | CVPR 2023 | Multi-task · Unified | | | — |
| E2E Dense End-to-End Learning of Behavioural Inputs for Autonomous Driving in Dense Traffic | IROS 2023 | Optimization · Dense Traffic | | — | — |
| CRCHFL Communication Resources Constrained Hierarchical Federated Learning for End-to-End Autonomous Driving | IROS 2023 | Federated Learning | | — | — |
| PPGeo Policy pre-training for autonomous driving via self-supervised geometric modeling | ICLR 2023 | Self-Supervised · Geometric | | | — |
Before 2023
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| MMFN Multi-Modal-Fusion-Net for End-to-End Driving | IROS 2022 | Fusion · Multi-Modal | | | — |
| KEMP Keyframe-Based Hierarchical End-to-End Deep Model for Long-Term Trajectory Prediction | ICRA 2022 | Keyframe · Hierarchical | | — | — |
| TCP Trajectory-guided Control Prediction for End-to-end Autonomous Driving: A Simple yet Strong Baseline | NeurIPS 2022 | Trajectory · Control | | | — |
| ST-P3 End-to-end Vision-based Autonomous Driving via Spatial-Temporal Feature Learning | ECCV 2022 | Spatial-Temporal · Interpretable | | | — |
| MP3 A Unified Model to Map, Perceive, Predict and Plan | CVPR 2021 | Mapless · Prediction | Paper | — | — |
| Multitask Multi-task Learning with Attention for End-to-end Autonomous Driving | CVPR 2021 | Multi-task · Attention | | | — |
| Transfuser Multi-Modal Fusion Transformer for End-to-End Autonomous Driving | CVPR 2021 | Transformer · Fusion | Paper | | — |
| NEAT Neural Attention Fields for End-to-End Autonomous Driving | ICCV 2021 | Attention Fields · BEV | Paper | | — |
| Fast-LiDARNet Efficient and Robust LiDAR-Based End-to-End Navigation | ICRA 2021 | LiDAR · Efficient | | — | — |
| IVMP Learning Interpretable End-to-End Vision-Based Motion Planning for Autonomous Driving with Optical Flow Distillation | ICRA 2021 | Interpretable · Optical Flow | | — | Project |
| P3 Perceive, Predict, and Plan: Safe Motion Planning Through Interpretable Semantic Representations | ECCV 2020 | Semantic · Interpretability | | — | — |
| DARB Exploring data aggregation in policy learning for vision-based urban autonomous driving | CVPR 2020 | Data Aggregation · Policy | Paper | | — |
| Roach End-to-End Urban Driving by Imitating a Reinforcement Learning Coach | ICCV 2021 | RL · Imitation | | | — |
| LBC Learning by cheating | CoRL 2019 | Knowledge Distillation | | | — |
| CIL End-to-End driving via conditional imitation learning | CoRL 2018 | Imitation Learning | | | — |
| Drive in A Day Learning to drive in a day | 2018 | RL | | | — |
| CNN E2E End to End Learning for Self-Driving Cars | 2016 | CNN · Imitation | | | — |
| ALVINN An autonomous land vehicle in a neural network | NeurIPS 1988 | Neural Network | Paper | — | — |
VLM-Centric End-to-End Methods
VLM-Centric End-to-End Methods
2026
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| ReflectDrive-2 Reinforcement-Learning-Aligned Self-Editing for Discrete Diffusion Driving | 2026 | Discrete Diffusion · Self-Edit · RL | | — | — |
| OneDrive Unified Multi-Paradigm Driving with Vision-Language-Action Models | 2026 | Single Decoder · Multi-Paradigm | | | — |
| UniDriveVLA Unifying Understanding, Perception, and Action Planning for Autonomous Driving | 2026 | MoT · Expert Decoupling | | | Project |
| AutoDrive-P³ Unified Chain of Perception–Prediction–Planning Thought via Reinforcement Fine-Tuning | ICLR 2026 | P³ CoT · GRPO | | | — |
| DynVLA Learning World Dynamics for Action Reasoning in Autonomous Driving | 2026 | Dynamics CoT · RFT | | | — |
| LaST-VLA Thinking in Latent Spatio-Temporal Space for Vision-Language-Action in Autonomous Driving | 2026 | Latent CoT · GRPO | | | — |
| ELF-VLA Unleashing VLA Potentials in Autonomous Driving via Explicit Learning from Failures | 2026 | Failure Diagnostics · RL | | — | — |
| VGGDrive Empowering Vision-Language Models with Cross-View Geometric Grounding for Autonomous Driving | CVPR 2026 | VLM · 3D Geometry | | | — |
| HiST-VLA A Hierarchical Spatio-Temporal Vision-Language-Action Model for End-to-End Autonomous Driving | 2026 | VLA · Spatio-Temporal · Token Sparse | | — | — |
| SparseOccVLA Bridging Occupancy and Vision-Language Models via Sparse Queries | 2026 | Sparse Occupancy · Unified 4D Understanding | | | Project |
| SGDrive Scene-to-Goal Hierarchical World Cognition for Autonomous Driving | 2026 | Hierarchical Cognition · Scene-Agent-Goal | | | — |
2025
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| Counterfactual VLA Self-Reflective Vision-Language-Action Model with Adaptive Reasoning | 2025 | Self-Reflective · Counterfactual Reasoning | | — | — |
| ColaVLA Leveraging Cognitive Latent Reasoning for Hierarchical Parallel Trajectory Planning | 2025 | Cognitive Latent Reasoning · Parallel Planning | | | Project |
| DrivePI DrivePI: Spatial-aware 4D MLLM for Unified Autonomous Driving Understanding, Perception, Prediction and Planning | 2025 | 4D Spatial · Occupancy | | | — |
| WAM-Diff WAM-Diff: A Masked Diffusion VLA Framework with MoE and Online Reinforcement Learning for Autonomous Driving | 2025 | Masked Diffusion · MoE · Online RL | | | — |
| SpaceDrive SpaceDrive: Infusing Spatial Awareness into VLM-based Autonomous Driving | 2025 | Spatial Encoding | | | Project |
| OpenREAD OpenREAD: Reinforced Open-Ended Reasoning for End-to-End Autonomous Driving with LLM-as-Critic | 2025 | RFT/RL · LLM-as-Critic | | | |
| CoT4AD CoT4AD: A Vision-Language-Action Model with Explicit Chain-of-Thought Reasoning | 2025 | VLA · CoT | | — | — |
| MPA Model-Based Policy Adaptation for Closed-Loop End-to-End Autonomous Driving | NeurIPS 2025 | Model-Based · Sim | | — | Project |
| AD-R1 AD-R1: Closed-Loop Reinforcement Learning with Impartial World Models | 2025 | RL · World Model | | — | — |
| Alpamayo-R1 Alpamayo-R1: Bridging Reasoning and Action Prediction for Generalizable Autonomous Driving | 2025 | VLA · Reasoning | | | — |
| DriveVLA-W0 DRIVEVLA-W0: World Models Amplify Data Scaling Law in Autonomous Driving | 2025 | VLA · World Model | | | — |
| MTRDrive MTRDrive: Memory-Tool Synergistic Reasoning for Robust Autonomous Driving | 2025 | VLM · Memory | | — | — |
| ReflectDrive Discrete Diffusion for Reflective Vision-Language-Action Models in Autonomous Driving | 2025 | Diffusion · VLA | | — | — |
| IRL-VLA IRL-VLA: Training an Vision-Language-Action Policy via Reward World Model | 2025 | IRL · VLA | | | — |
| Prune2Drive Prune2Drive: A Plug-and-Play Framework for Accelerating Vision-Language Models | 2025 | VLM · Pruning | | — | — |
| FastDriveVLA FastDriveVLA: Efficient End-to-End Driving via Plug-and-Play Reconstruction-based Token Pruning | 2025 | VLA · Pruning | | — | — |
| MCAM Multimodal Causal Analysis Model for Ego-Vehicle-Level Driving Video Understanding | 2025 | Causal · Multimodal | | | — |
| AutoDrive-R² Incentivizing Reasoning and Self-Reflection Capacity for VLA Model in Autonomous Driving | 2025 | VLA · Reflection | | — | — |
| DriveAgent-R1 Advancing VLM-based Autonomous Driving with Hybrid Thinking and Active Perception | 2025 | VLM · Active | | — | — |
| NavigScene Bridging Local Perception and Global Navigation for Beyond-Visual-Range Autonomous Driving | 2025 | Navigation · Perception | | — | — |
| ADRD LLM-DRIVEN AUTONOMOUS DRIVING BASED ON RULE-BASED DECISION SYSTEMS | 2025 | LLM · Rule-Based | | — | — |
| AutoVLA A Vision-Language-Action Model for End-to-End Autonomous Driving with Adaptive Reasoning | 2025 | VLA · RL | | | Project |
| Poutine Vision-Language-Trajectory Pre-Training and Reinforcement Learning Post-Training | 2025 | VLT · RL | | — | — |
| ReCogDrive A Reinforced Cognitive Framework for End-to-End Autonomous Driving | 2025 | VLM · Diffusion | | | Project |
| AD-EE Early Exiting for Fast and Reliable Vision-Language Models in Autonomous Driving | 2025 | VLM · Efficient | | — | — |
| FastDrive Structured Labeling Enables Faster Vision-Language Models for End-to-End Autonomous Driving | 2025 | VLM · Structured | | — | — |
| HMVLM Multistage Reasoning-Enhanced Vision-Language Model for Long-Tailed Driving Scenarios | 2025 | VLM · Long-Tail | | — | — |
| S4-Driver Scalable Self-Supervised Driving Multimodal Large Language Model | CVPR 2025 | Self-Supervised · MLLM | | — | — |
| DiffVLA Vision-Language Guided Diffusion Planning for Autonomous Driving | 2025 | Diffusion · VLM | | — | — |
| X-Driver Explainable Autonomous Driving with Vision-Language Models | 2025 | MLLM · CoT | | — | — |
| DriveGPT4-V2 Harnessing Large Language Model Capabilities for Enhanced Closed-Loop Autonomous Driving | CVPR 2025 | LLM · Closed-Loop | | — | — |
| DriveMind A Dual-VLM based Reinforcement Learning Framework for Autonomous Driving | 2025 | Dual-VLM · RL | | — | — |
| ReasonPlan Unified Scene Prediction and Decision Reasoning for Closed-loop Autonomous Driving | 2025 | MLLM · Reasoning | | | — |
| FutureSightDrive Thinking Visually with Spatio-Temporal CoT for Autonomous Driving | 2025 | CoT · Spatio-Temporal | | | — |
| PADriver Towards Personalized Autonomous Driving | 2025 | MLLM · Personalized | | — | — |
| LDM Unlock the Power of Unlabeled Data in Language Driving Model | ICRA 2025 | Self-Supervised · Distillation | | — | — |
| DriveMoE Mixture-of-Experts for Vision-Language-Action Model in End-to-End Autonomous Driving | 2025 | MoE · VLA | | | Project |
| DriveMonkey Extending Large Vision-Language Model for Diverse Interactive Tasks in Autonomous Driving | 2025 | LVLM · Interactive | | | — |
| AgentThink A Unified Framework for Tool-Augmented Chain-of-Thought Reasoning in Vision-Language Models | 2025 | CoT · Tools | | — | — |
| DSDrive Distilling Large Language Model for Lightweight End-to-End Autonomous Driving | 2025 | Distillation · Lightweight | | — | — |
| LightEMMA Lightweight End-to-end Multimodal Autonomous Driving | 2025 | Lightweight · Multimodal | | | — |
| THCAD Towards Human-Centric Autonomous Driving: A Fast-Slow Architecture Integrating LLM Guidance with RL | 2025 | LLM · RL · Fast-Slow | | — | — |
| DriveSOTIF Advancing Perception SOTIF Through Multimodal Large Language Models | 2025 | SOTIF · MLLM | | — | — |
| Actor-Reasoner Interact, Instruct to Improve: A LLM-Driven Parallel Actor-Reasoner Framework | 2025 | LLM · Interaction | | | — |
| MPDrive Improving Spatial Understanding with Marker-Based Prompt Learning for Autonomous Driving | CVPR 2025 | Prompt · Spatial | | — | — |
| V3LMA Visual 3D-enhanced Language Model for Autonomous Driving | 2025 | 3D · LVLM | | — | — |
| OpenDriveVLA Towards End-to-end Autonomous Driving with Large Vision Language Action Model | 2025 | VLA · Open-Source | | | Project |
| SimLingo Vision-Only Closed-Loop Autonomous Driving with Language-Action Alignment | CVPR 2025 | VLA · Closed-Loop | | | Project |
| SAFEAUTO KNOWLEDGE-ENHANCED SAFE AUTONOMOUS DRIVING WITH MULTIMODAL FOUNDATION MODELS | ICLR 2025 | Safety · Multimodal | | | — |
| NuGrounding A Multi-View 3D Visual Grounding Framework in Autonomous Driving | 2025 | Grounding · 3D | | — | — |
| CoT-Drive Efficient Motion Forecasting for Autonomous Driving with LLMs and Chain-of-Thought Prompting | 2025 | CoT · Forecasting | | — | — |
| CoLMDriver LLM-based Negotiation Benefits Cooperative Autonomous Driving | 2025 | Cooperative · LLM | | | — |
| AlphaDrive Unleashing the Power of VLMs in Autonomous Driving via Reinforcement Learning and Reasoning | 2025 | RL · Reasoning | | | — |
| TrackingMeetsLMM Tracking Meets Large Multimodal Models for Driving Scenario Understanding | 2025 | Tracking · LMM | | | — |
| BEVDriver Leveraging BEV Maps in LLMs for Robust Closed-Loop Driving | 2025 | BEV · LLM | | — | — |
| DynRsl-VLM Enhancing Autonomous Driving Perception with Dynamic Resolution Vision-Language Models | 2025 | Dynamic Res · VLM | | — | — |
| Sce2DriveX A Generalized MLLM Framework for Scene-to-Drive Learning | 2025 | MLLM · Scene | | — | — |
| VLM-Assisted-CL VLM-Assisted Continual learning for Visual Question Answering in Self-Driving | 2025 | Continual Learning | | — | — |
| LeapVAD A Leap in Autonomous Driving via Cognitive Perception and Dual-Process Thinking | 2025 | Cognitive · Dual-Process | | | Project |
2024
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| VLM-RL A Unified Vision Language Model and Reinforcement Learning Framework for Safe Autonomous Driving | 2024 | RL · VLM | | | Project |
| GPVL Generative Planning with 3D-vision Language Pre-training for End-to-End Autonomous Driving | AAAI 2025 | Generative · 3D-VL | | | — |
| CALMM-Drive Confidence-Aware Autonomous Driving with Large Multimodal Model | 2024 | CoT · Confidence | | — | — |
| WiseAD Knowledge Augmented End-to-End Autonomous Driving with Vision-Language Model | 2024 | VLM · Reasoning | | | — |
| OpenEMMA Open-Source Multimodal Model for End-to-End Autonomous Driving | WACV 2025 | Open-Source · Multimodal | | | — |
| FeD Feedback-Guided Autonomous Driving | CVPR 2024 | Feedback · LLM | Paper | — | Project |
| LeapAD Continuously learning, adapting, and improving: A dual-process approach to autonomous driving | NeurIPS 2024 | Dual-Process · Continual | | | Project |
| DriveMM All-in-One Large Multimodal Model for Autonomous Driving | 2024 | Multimodal · Generalization | | | Project |
| Exp-Planning Explanation for Trajectory Planning using Multi-modal Large Language Model for Autonomous Driving | ECCV 2024 | Explainability · Planning | | — | — |
| LaVida Drive Vision-Text Interaction VLM for Autonomous Driving with Token Selection, Recovery and Enhancement | 2024 | VQA · Interaction | | — | — |
| EMMA End-to-End Multimodal Model for Autonomous Driving | 2024 | End-to-End · Multimodal | | — | — |
| DriVLMe Enhancing LLM-based Autonomous Driving Agents with Embodied and Social Experiences | IROS 2024 | Embodied · Social | | | Project |
| OccLLaMA An Occupancy-Language-Action Generative World Model for Autonomous Driving | 2024 | World Model · Occupancy | | — | — |
| MiniDrive More Efficient Vision-Language Models with Multi-Level 2D Features as Text Tokens | 2024 | Efficient · MoE | | — | — |
| RDA-Driver Making Large Language Models Better Planners with Reasoning-Decision Alignment | ECCV 2024 | Reasoning · Alignment | | — | — |
| EC-Drive Edge-Cloud Collaborative Motion Planning for Autonomous Driving with Large Language Models | ICCT 2024 | Edge-Cloud · Collaborative | | — | Project |
| V2X-VLM End-to-End V2X Cooperative Autonomous Driving Through Large Vision-Language Models | 2024 | V2X · Cooperative | | | Project |
| Cube-LLM Language-Image Models with 3D Understanding | 2024 | 3D · Language-Image | | — | Project |
| VLM-MPC Vision Language Foundation Model (VLM)-Guided Model Predictive Controller (MPC) | 2024 | MPC · Control | | — | — |
| SimpleLLM4AD An End-to-End Vision-Language Model with Graph Visual Question Answering | IEIT Systems | Graph VQA · Pipeline | | — | — |
| AsyncDriver Asynchronous Large Language Model Enhanced Planner for Autonomous Driving | ECCV 2024 | Asynchronous · Closed-Loop | | | — |
| AD-H AUTONOMOUS DRIVING WITH HIERARCHICAL AGENTS | ICLR 2025 | Hierarchical · Agents | Paper | — | — |
| CarLLaVA Vision language models for camera-only closed-loop driving | 2024 | Camera-only · Closed-Loop | | — | Project |
| PlanAgent A Multi-modal Large Language Agent for Closed-loop Vehicle Motion Planning | 2024 | Agent · Closed-Loop | | — | — |
| Atlas Is a 3D-Tokenized LLM the Key to Reliable Autonomous Driving? | 2024 | 3D-Tokenized · LLM | | — | — |
| TRR Agent Interpretable Decision-Making for Autonomous Vehicles with Retrieval-Augmented Reasoning via LLM | 2024 | RAG · Rule-Based | | — | — |
| OmniDrive A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning | CVPR 2025 | Counterfactual · 3D | | | — |
| Co-driver VLM-based Autonomous Driving Assistant with Human-like Behavior and Understanding | 2024 | Assistant · Human-like | | — | — |
| AgentsCoDriver Large Language Model Empowered Collaborative Driving with Lifelong Learning | 2024 | Collaborative · Lifelong | | — | — |
| EM-VLM4AD Multi-Frame, Lightweight & Efficient Vision-Language Models for Question Answering | CVPR 2024 | Efficient · VQA | | | — |
| LeGo-Drive Language-enhanced Goal-oriented Closed-Loop End-to-End Autonomous Driving | IROS 2024 | Goal-oriented · Closed-Loop | | | Project |
| Hybrid Reasoning Hybrid Reasoning Based on Large Language Models for Autonomous Car Driving | ICCMA 2024 | Reasoning · Math | | — | — |
| VLAAD Vision and Language Assistant for Autonomous Driving | WACV 2024 | Assistant · Explainability | Paper | — | — |
| ELM Embodied Understanding of Driving Scenarios | ECCV 2024 | Embodied · Scene Understanding | | — | — |
| RAG-Driver Generalisable Driving Explanations with Retrieval-Augmented In-Context Learning | RSS 2024 | RAG · In-Context | | | Project |
| BEV-TSR Text-Scene Retrieval in BEV Space for Autonomous Driving | AAAI 2025 | Retrieval · BEV | | — | — |
| LLaDA Driving Everywhere with Large Language Model Policy Adaptation | CVPR 2024 | Adaptation · Traffic Rules | | | Project |
2023
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| LingoQA Visual Question Answering for Autonomous Driving | ECCV 2024 | VQA · LLM | | | — |
| LaMPilot An Open Benchmark Dataset for Autonomous Driving with Language Model Programs | CVPR 2024 | Benchmark · LLM | | | — |
| LLM-ASSIST Enhancing Closed-Loop Planning with Language-Based Reasoning | 2023 | Planning · Reasoning | | — | Project |
| DriveLM Driving with Graph Visual Question Answering | ECCV 2024 | Graph VQA · Reasoning | | | — |
| DriveMLM Aligning Multi-Modal Large Language Models with Behavioral Planning States | 2023 | MLLM · Planning | | | — |
| LiDAR-LLM Exploring the Potential of Large Language Models for 3D LiDAR Understanding | 2023 | LiDAR · LLM | | — | Project |
| Talk2BEV Language-enhanced Bird's-eye View Maps for Autonomous Driving | 2023 | BEV · LVLM | | | Project |
| Talk2Drive Personalized Autonomous Driving with Large Language Models: Field Experiments | 2023 | Personalized · LLM | | — | Project |
| LMDrive Closed-Loop End-to-End Driving with Large Language Models | CVPR 2024 | Closed-Loop · LLM | | | — |
| Reason2Drive Towards Interpretable and Chain-based Reasoning for Autonomous Driving | ECCV 2024 | Reasoning · Interpretability | | | — |
| CAVG GPT-4 Enhanced Multimodal Grounding for Autonomous Driving | 2023 | Grounding · GPT-4 | | | — |
| Dolphins Multimodal Language Model for Driving | ECCV 2024 | Multimodal · VLM | | | Project |
| Agent-Driver A Language Agent for Autonomous Driving | COLM 2024 | Agent · Memory | | | Project |
| LLM-Safety Empowering Autonomous Driving with Large Language Models: A Safety Perspective | ICLR 2024 | Safety · MPC | | | — |
| Co-Pilot ChatGPT as Your Vehicle Co-Pilot: An Initial Attempt | 2023 | Co-Pilot · LLM | Paper | — | — |
| RRR Receive, Reason, and React: Drive as You Say with Large Language Models | ITSM 2024 | Tools · LLM | | — | — |
| LanguageMPC Large Language Models as Decision Makers for Autonomous Driving | 2023 | MPC · CoT | | — | — |
| Driving with LLMs Fusing Object-Level Vector Modality for Explainable Autonomous Driving | 2023 | Object-Level · Explainable | | | — |
| DriveGPT4 Interpretable End-to-end Autonomous Driving via Large Language Model | RAL | Interpretable · LLM | Paper | — | Project |
| GPT-Driver Learning to Drive with GPT | NeurIPS 2023 | Planner · GPT | | | Project |
| DiLu A Knowledge-Driven Approach to Autonomous Driving with Large Language Models | ICLR 2024 | Knowledge-Driven · Reflection | | | Project |
| Drive as You Speak Enabling Human-Like Interaction with Large Language Models in Autonomous Vehicles | 2023 | Interaction · LLM | | — | — |
| HiLM-D Enhancing MLLMs with Multi-Scale High-Resolution Details for Autonomous Driving | IJCV | High-Res · MLLM | | — | — |
| SurrealDriver Designing LLM-powered Generative Driver Agent Framework based on Human Data | 2023 | Generative · Agent | | — | — |
| Drive Like a Human Rethinking Autonomous Driving with Large Language Models | 2023 | Reasoning · Reflection | | | — |
| ADAPT Action-aware Driving Caption Transformer | ICRA 2023 | Captioning · Transformer | | | — |
Hybrid End-to-End Methods
Hybrid End-to-End Methods
2026
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| DriveDreamer-Policy A Geometry-Grounded World–Action Model for Unified Generation and Planning | 2026 | WAM · Geometry-Grounded | | — | Project |
| Uni-World VLA Interleaved World Modeling and Planning for Autonomous Driving | 2026 | Interleaved · World Model | | | — |
| HybridDriveVLA From Representational Complementarity to Dual Systems: Synergizing VLM and Vision-Only Backbones for End-to-End Driving | 2026 | Dual System · Fast-Slow | | — | — |
| DriveWorld-VLA Unified Latent-Space World Modeling with Vision–Language–Action for Autonomous Driving | 2026 | World Model · VLA · Latent | | | — |
| LatentVLA Efficient Vision-Language Models for Autonomous Driving via Latent Action Prediction | 2026 | Latent Action · Knowledge Distillation | | — | — |
2025
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| MindDrive MindDrive: An All-in-One Framework Bridging World Models and Vision-Language Model for End-to-End Autonomous Driving | 2025 | World Model · VLM Evaluator | | | Project |
| AdaDrive AdaDrive: Self-Adaptive Slow-Fast System for Language-Grounded Autonomous Driving | ICCV 2025 | Slow-Fast · LLM | | | — |
| ReAL-AD Towards Human-Like Reasoning in End-to-End Autonomous Driving | 2025 | Reasoning · VLM | | — | Project |
| VLAD A VLM-Augmented Autonomous Driving Framework with Hierarchical Planning and Interpretable Decision Process | ITSC 2025 | VLM · Hierarchical | | — | — |
| LeAD The LLM Enhanced Planning System Converged with End-to-end Autonomous Driving | 2025 | LLM · E2E | | — | — |
| NetRoller Interfacing General and Specialized Models for End-to-End Autonomous Driving | 2025 | Adapter · VLM | | | — |
| SOLVE Synergy of Language-Vision and End-to-End Networks for Autonomous Driving | CVPR 2025 | VLM · Fusion | | — | — |
| VERDI VLM-Embedded Reasoning for Autonomous Driving | 2025 | VLM · Reasoning | | — | — |
| ALN-P3 Unified Language Alignment for Perception, Prediction, and Planning in Autonomous Driving | 2025 | Alignment · Language | | — | — |
| VLM-E2E Enhancing End-to-End Autonomous Driving with Multimodal Driver Attention Fusion | 2025 | VLM · Attention | | — | — |
| DIMA Distilling Multi-modal Large Language Models for Autonomous Driving | CVPR 2025 | Distillation · MLLM | | — | — |
2024
| 🧠 Method | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💻 GitHub | 🌐 Project |
|---|---|---|---|---|---|
| VLM-AD End-to-End Autonomous Driving through Vision-Language Model Supervision | 2024 | Supervision · VLM | | — | — |
| FASIONAD FAst and Slow FusION Thinking Systems for Human-Like Autonomous Driving | 2024 | Fast-Slow · Fusion | | — | — |
| Senna Bridging Large Vision-Language Models and End-to-End Autonomous Driving | 2024 | VLM · Robustness | | | — |
| Hint-AD Holistically Aligned Interpretability in End-to-End Autonomous Driving | CoRL 2024 | Interpretability · Alignment | | | Project |
| DriveVLM The Convergence of Autonomous Driving and Large Vision-Language Models | CoRL 2024 | Hybrid · VLM | | — | Project |
| DME-Driver Integrating Human Decision Logic and 3D Scene Perception in Autonomous Driving | AAAI 2025 | Logic · Perception | | — | — |
| VLP Vision Language Planning for Autonomous Driving | CVPR 2024 | Planning · Reasoning | | — | — |
Dataset
Normal Dataset
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code |
|---|---|---|---|---|
| NAVSIM Data-Driven Non-Reactive Autonomous Vehicle Simulation and Benchmarking | NeurIPS 2024 | Closed-Loop · Planning Benchmark | | |
| Bench2Drive Towards Multi-Ability Benchmarking of Closed-Loop End-to-End Autonomous Driving | NeurIPS 2024 | CARLA · Closed-Loop · Multi-Ability | | |
| nuScenes A Multimodal Dataset for Autonomous Driving | CVPR 2020 | Multimodal · LiDAR · Radar | | Dataset |
| Waymo Waymo Open Dataset: Scalability in Perception | CVPR 2020 | Perception · LiDAR | Paper | Dataset |
| HUGSIM A Real-Time, Photo-Realistic and Closed-Loop Simulator for Autonomous Driving | 2024 | Gaussian Splatting · Closed-Loop Sim | | |
| ONCE One Million Scenes for Autonomous Driving | NeurIPS 2021 | Unsupervised · 3D Detection | | Dataset |
| Lyft One Thousand and One Hours: Self-driving Motion Prediction Dataset | 2020 | Motion Prediction | | Dataset |
| BDD100K A Diverse Driving Dataset for Heterogeneous Multitask Learning | CVPR 2020 | Multitask · Video | | |
| Argoverse 3D Tracking and Forecasting with Rich Maps | CVPR 2019 | Tracking · Forecasting · Maps | | Dataset |
| ApolloScape The ApolloScape Open Dataset for Autonomous Driving | CVPR 2018 | Segmentation · LiDAR | | |
| CARLA An Open Urban Driving Simulator | CoRL 2017 | Simulator · Urban Driving | | Dataset |
| Mapillary Vistas Semantic Understanding of Street Scenes | ICCV 2017 | Semantic Segmentation | Paper | Dataset |
| KITTI The KITTI Vision Benchmark Suite | CVPR 2012 | 3D Detection · Tracking | | Dataset |
Vision Language Dataset
Vision Language Dataset
2025
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| nuScenesR²-6K Incentivizing Reasoning and Self-Reflection Capacity for VLA Model | 2025 | CoT · Reasoning | | — | — |
| Bench2ADVLM A Closed-Loop Benchmark for Vision-language Models | 2025 | Benchmark · Closed-Loop | | — | — |
| Drive-R1 Bridging Reasoning and Planning in VLMs with RL | 2025 | RL · Reasoning | | — | — |
| STSBench A Spatio-temporal Scenario Benchmark for MLLMs | 2025 | Spatio-Temporal · 3D | | Dataset | Project |
| DriveAction A Benchmark for Exploring Human-like Driving Decisions in VLA Models | 2025 | Action-Driven · VLA | | Dataset | Project |
| S4-Driver WOMD-Planning-ADE Benchmark: Scalable Self-Supervised Driving MLLM | CVPR 2025 | Self-Supervised · Planning | | — | — |
| ImpromptuVLA Open Weights and Open Data for Driving Vision-Language-Action Models | 2025 | Open Data · VLA | | Dataset | Project |
| NuInteract Extending Large Vision-Language Model for Diverse Interactive Tasks | 2025 | Interaction · VLM | | | Project |
| VLADBench Fine-Grained Evaluation of Large Vision-Language Models | 2025 | Evaluation · Reasoning | | Dataset | Project |
| DriveLMM-o1 A Step-by-Step Reasoning Dataset and Large Multimodal Model | 2025 | Reasoning · MLLM | | Dataset | Project |
| SimLingo Vision-Only Closed-Loop Autonomous Driving with Language-Action Alignment | CVPR 2025 | Alignment · Closed-Loop | | Dataset | Project |
| Robusto-1 Comparing Humans and VLMs on real out-of-distribution AD VQA | 2025 | OOD · VQA | | Dataset | — |
| DrivingVQA RIV-CoT: Retrieval-Based Interleaved Visual Chain-of-Thought | 2025 | VQA · CoT | | Dataset | Project |
| DriveBench Are VLMs Ready for Autonomous Driving? An Empirical Study | ICCV 2025 | Reliability · Evaluation | | Dataset | Project |
| CoVLA Comprehensive Vision-Language-Action Dataset | WACV 2025 | VLA · Video | | Dataset | Project |
| WOMD-Reasoning A Large-Scale Dataset for Interaction Reasoning in Driving | ICML 2025 | Interaction · Reasoning | | Dataset | Project |
| OmniDrive LLM-Agent for Autonomous Driving with 3D Perception | CVPR 2025 | 3D Perception · Agent | | | Project |
| CODA-LM Automated Evaluation of Large Vision-Language Models on Self-driving Corner Cases | WACV 2025 | Corner Cases · Evaluation | | Dataset | Project |
| HiLM-D (DRAMA-ROLISP) Enhancing MLLMs with Multi-Scale High-Resolution Details | IJCV 2025 | Risk · High-Res | | | Project |
| nuPrompt Language Prompt for Autonomous Driving | AAAI 2025 | Prompt · 3D | | | Project |
2024
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| SURDS Benchmarking Spatial Understanding and Reasoning in Driving Scenarios | 2024 | Spatial · Reasoning | | Dataset | Project |
| ContextVLM Zero-Shot and Few-Shot Context Understanding | ITSC 2024 | Context · Few-Shot | | Dataset | Project |
| DriveCoT Integrating Chain-of-Thought Reasoning with End-to-End Driving | 2024 | CoT · Reasoning | | Dataset | Project |
| DriveVLM SUP-AD Dataset: The Convergence of Autonomous Driving and VLMs | CoRL 2024 | Scene Understanding · Planning | | — | Project |
| NuInstruct Holistic Autonomous Driving Understanding by BEV Injected Multi-Modal Large Models | CVPR 2024 | Instruction · BEV | | Dataset | Project |
| DriveLM Driving with Graph Visual Question Answering | ECCV 2024 | Graph VQA · Graph | | Dataset | Project |
| LingoQA Visual Question Answering for Autonomous Driving | ECCV 2024 | VQA · Freeform | | | Project |
| LMDrive Closed-Loop End-to-End Driving with Large Language Models | 2024 | Closed-Loop · Language | | Dataset | Project |
| NuScenes-MQA Integrated Evaluation of Captions and QA using Markup Annotations | WACV 2024 | Captioning · QA | | Dataset | Project |
| Talk2BEV Language-enhanced Bird’s-eye View Maps | ICRA 2024 | BEV · Maps | | Dataset | Project |
| DriveGPT4 Interpretable End-to-end Autonomous Driving via LLM | RA-L 2024 | Interpretable · Instruction | | Dataset | Project |
| Rank2Tell A Multimodal Driving Dataset for Joint Importance Ranking and Reasoning | WACV 2024 | Ranking · Reasoning | | Dataset | — |
| NuScenes-QA A Multi-Modal Visual Question Answering Benchmark | AAAI 2024 | VQA · Benchmark | | Dataset | Project |
| MAPLM A Real-World Large-Scale Vision-Language Dataset for Map and Traffic Scene | CVPR 2024 | Map · Traffic | Paper | Dataset | Project |
2023
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| DriveMLM Aligning Multi-Modal Large Language Models with Behavioral Planning States | 2023 | Planning · Explanation | | | — |
| Reason2Drive Towards Interpretable and Chain-based Reasoning for Autonomous Driving | 2023 | Reasoning · Chain-based | | Dataset | Project |
| Refer-KITTI Referring Multi-Object Tracking | CVPR 2023 | Tracking · Referring | | | Project |
| DRAMA Joint Risk Localization and Captioning in Driving | WACV 2023 | Risk · Captioning | | Dataset | Project |
Before 2023
| 📦 Dataset | 🗓️ Year / Venue | 🏷️ Tags | 📄 Paper | 💾 Dataset / Code | 🌐 Project |
|---|---|---|---|---|---|
| SUTD-TrafficQA A Question Answering Benchmark and an Efficient Network for Video Reasoning | CVPR 2021 | Video QA · Reasoning | | Dataset | Project |
| BDD-OIA Explainable Object-induced Action Decision for Autonomous Vehicles | CVPR 2020 | Explainable · Decision | | Dataset | Project |
| HAD Grounding Human-to-Vehicle Advice for Self-driving Vehicles | CVPR 2019 | Advice · Grounding | | Dataset | — |
| Talk2Car Taking Control of Your Self-Driving Car | EMNLP 2019 | Commands · Referral | | | Project |
| BDD-X Textual Explanations for Self-Driving Vehicles | ECCV 2018 | Explanation · Captioning | | | Project |
License
The GE2EAD resources is released under the Apache 2.0 license.
Similar repos
Significant stargazers
67 followers · starred Dec 2025
Languages
HTML
51.9%
CSS
44.8%
JavaScript
3.2%