TUM-AVS/FM-AD-Survey

[Survey Paper] This repository collects research papers of large Foundation Models for Scenario Generation and Analysis in Autonomous Driving. The repository will be continuously updated to track the latest update.

Python

238

107 commits

updated Sep 20, 2026

See the code

README

Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis :car:

Paper Badge Stars Badge Forks Badge Pull Requests Badge Issues Badge License Badge

This repository will collect research, implementations, and resources related to Foundation Models for Scenario Generation and Analysis in autonomous driving. The repository will be maintained by TUM-AVS (Professorship of Autonomous Vehicle Systems at Technical University of Munich) and will be continuously updated to track the latest work in the community.

:fire: Updates

  • Aug. 2026 – Added 9 new papers on scenario generation* and 11 new papers on scenario analysis*.
  • Jul. 2026 – Added 4 new papers on scenario generation* and 14 new papers on scenario analysis*.
  • Jun. 2026 – Added 33 new papers on scenario analysis* (monthly backlog catch-up spanning Dec 2023 – Jun 2026).
  • May 2026 – Added 7 new papers on scenario generation* and 19 new papers on scenario analysis*.
  • Apr. 2026 – Added 5 new papers on scenario generation* and 13 new papers on scenario analysis*.
  • Mar. 2026 – Added 10 new papers on scenario generation* and 11 new papers on scenario analysis*.
  • Feb. 2026 – Added 4 new papers on scenario generation* and 19 new papers on scenario analysis*.
  • Jan. 2026 – 🎉 Our survey paper is accepted by IEEE Open Journal of Intelligent Transportation Systems (OJ-ITS) and uploaded a new version to arXiv.
  • Dec. 2025 – Added 3 new papers on scenario generation* and 14 new papers on scenario analysis*. Added new columns: Hardware and Citation.
  • Nov. 2025 – Added 2 new papers on scenario analysis*. Added new section: Useful Resources and Links.
  • Uploaded new version to arXiv. Repository now categorizes 348 papers:
    • 93 on scenario generation
    • 56 on scenario analysis
    • 58 on datasets
    • 21 on simulators
    • 25 on benchmark challenges
    • 95 on other related topics (e.g., FMs' implementation)
  • Oct. 2025 – Added 17 new papers on scenario generation* and 2 new papers on scenario analysis*.
  • Sep. 2025 – Added 3 new papers on scenario generation* and 14 new papers on scenario analysis*.
  • Aug. 2025 – Added 4 new papers on scenario generation* and 4 new papers on scenario analysis*.
  • Jul. 2025 – Added 9 new papers on scenario generation* and 8 new papers on scenario analysis*.
  • Jun. 2025 – Released our paper on arXiv. Repository now categorizes 342 papers:
    • 93 on scenario generation
    • 54 on scenario analysis
    • 55 on datasets
    • 21 on simulators
    • 25 on benchmark challenges
    • 94 on other related topics
  • May 2025 – Repository initialized.

🤝   Citation

Please visit Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis for more details and comprehensive information. If you find our paper and repo helpful, please consider citing it as follows:

@ARTICLE{11370877,
  author={Gao, Yuan and Piccinini, Mattia and Zhang, Yuchen and Wang, Dingrui and Moller, Korbinian and Brusnicki, Roberto and Zarrouki, Baha and Gambi, Alessio and Totz, Jan Frederik and Storms, Kai and Peters, Steven and Stocco, Andrea and Alrifaee, Bassam and Pavone, Marco and Betz, Johannes},
  journal={IEEE Open Journal of Intelligent Transportation Systems}, 
  title={Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis}, 
  year={2026},
  volume={},
  number={},
  pages={1-1},
  keywords={Autonomous vehicles;Surveys;Foundation models;Scenario generation;Frequency modulation;Visualization;Reviews;Diffusion models;Adaptation models;Cognition;Autonomous vehicles;foundation model;scenario generation;scenario analysis;scenario based testing},
  doi={10.1109/OJITS.2026.3660686}}

:page_with_curl: Introduction

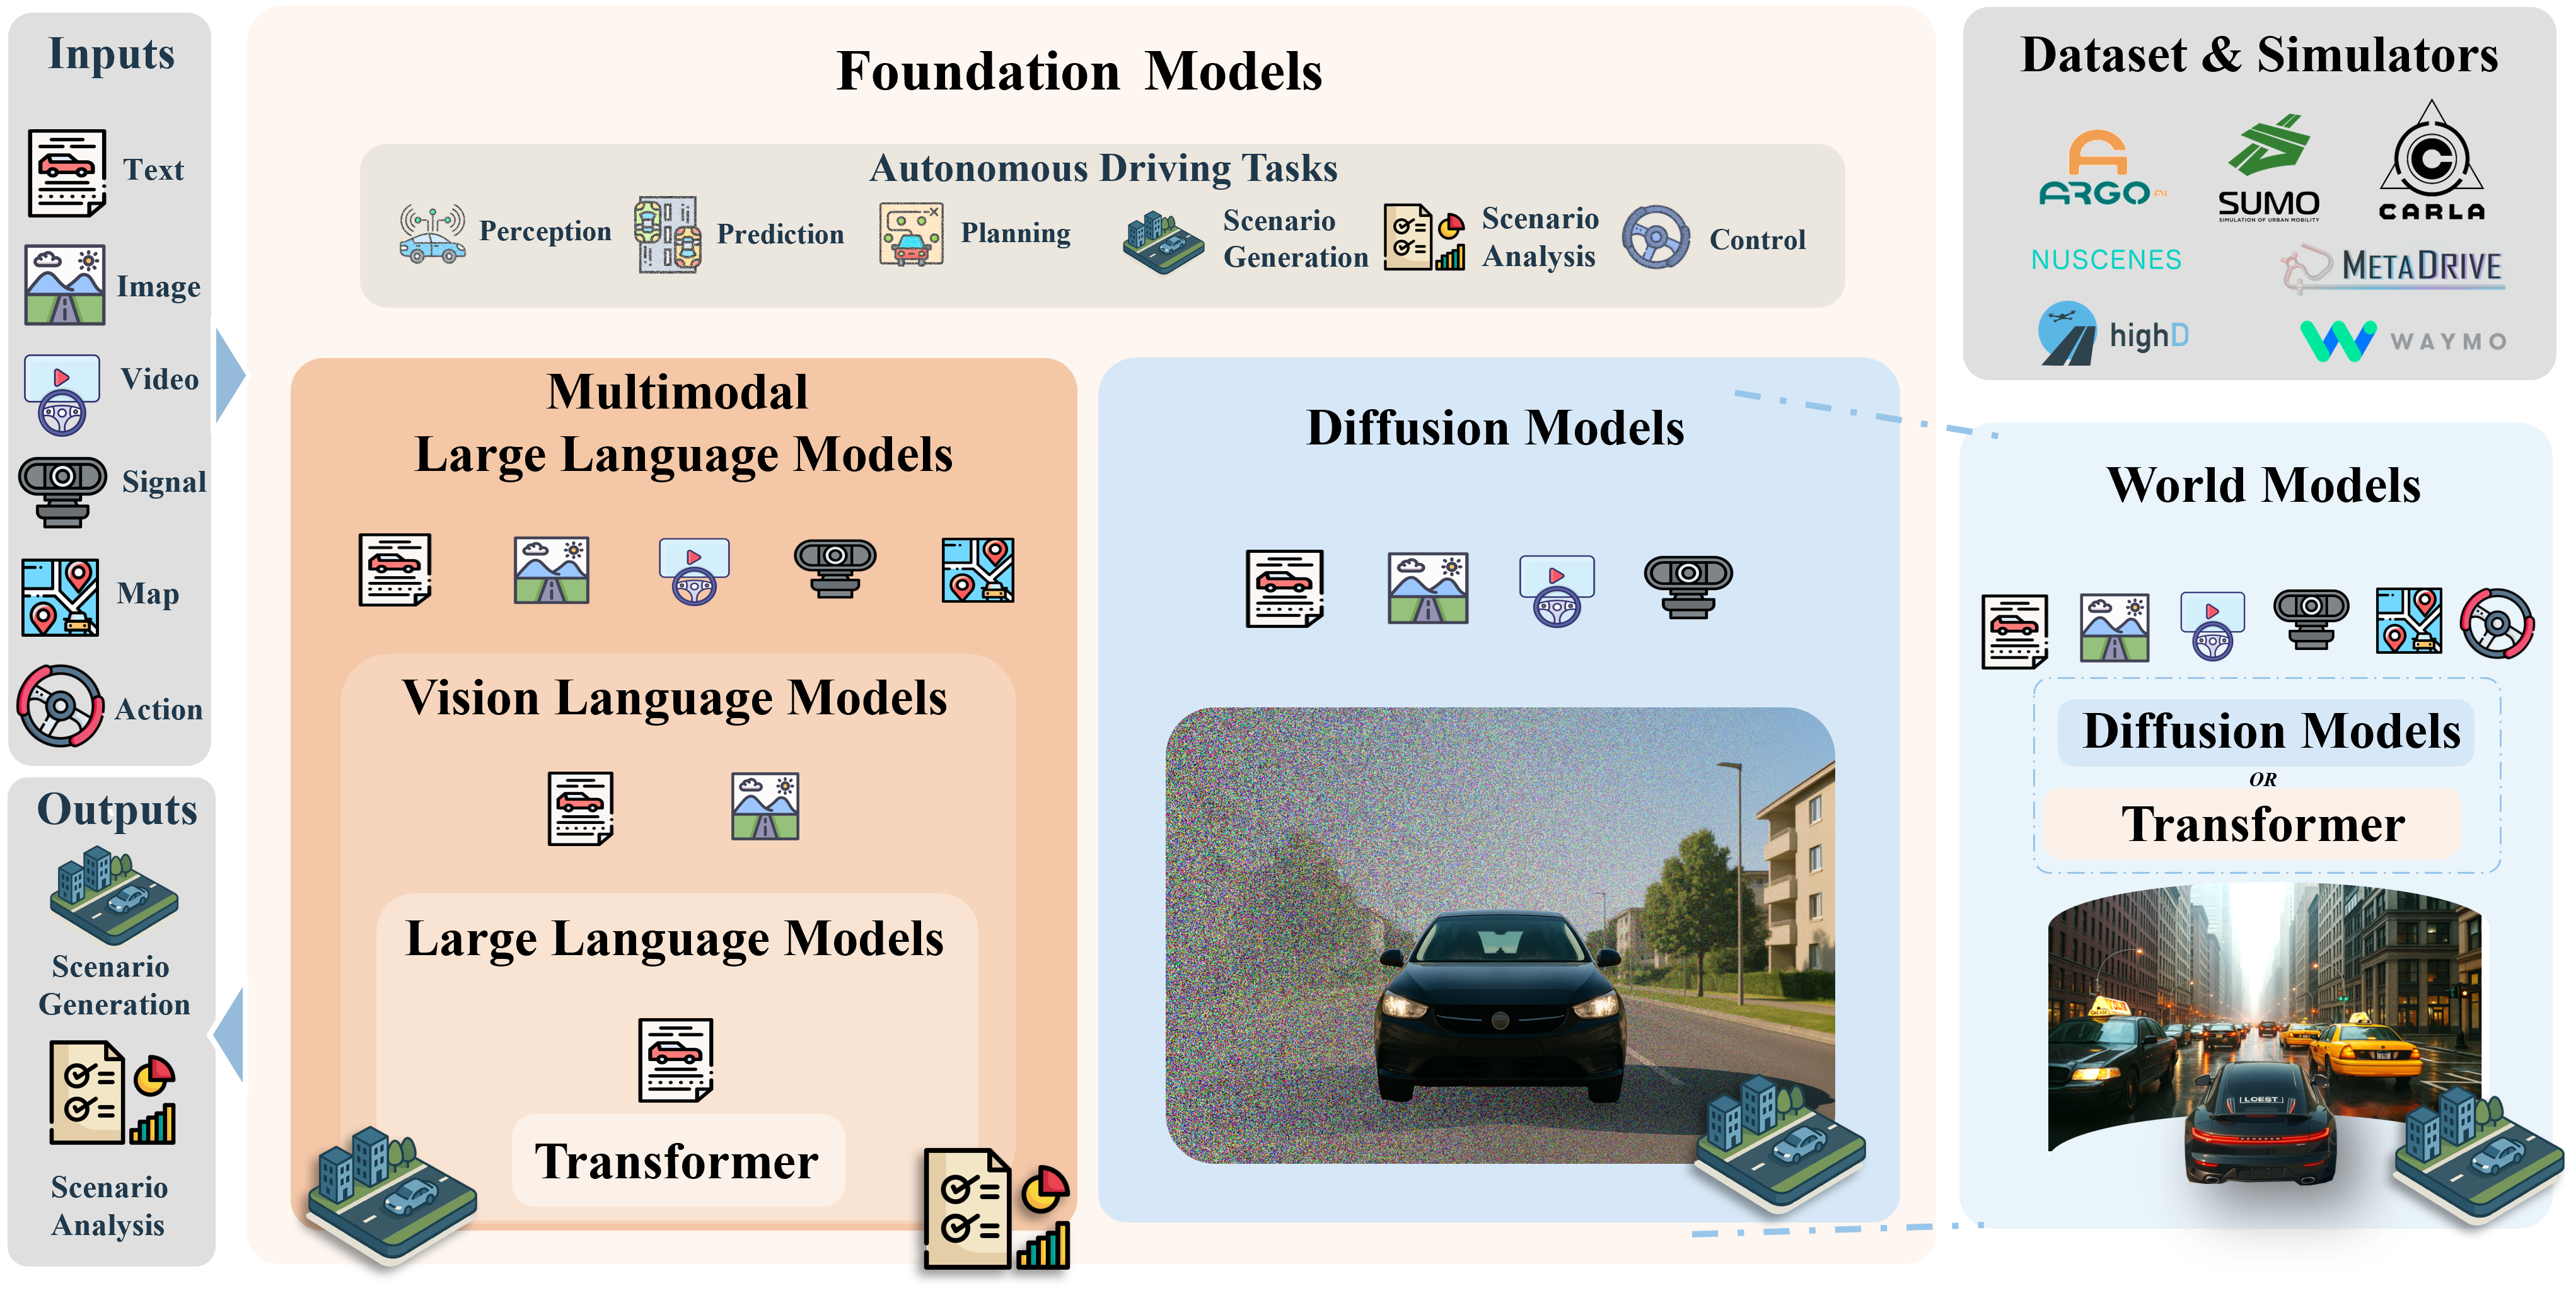
Foundation models are large-scale, pre-trained models that can be adapted to a wide range of downstream tasks. In the context of autonomous driving, foundation models offer a powerful approach to scenario generation and analysis, enabling more comprehensive and realistic testing, validation, and verification of autonomous driving systems. This repository aims to collect and organize research, tools, and resources in this important field.

:chart_with_upwards_trend: Publication Timeline

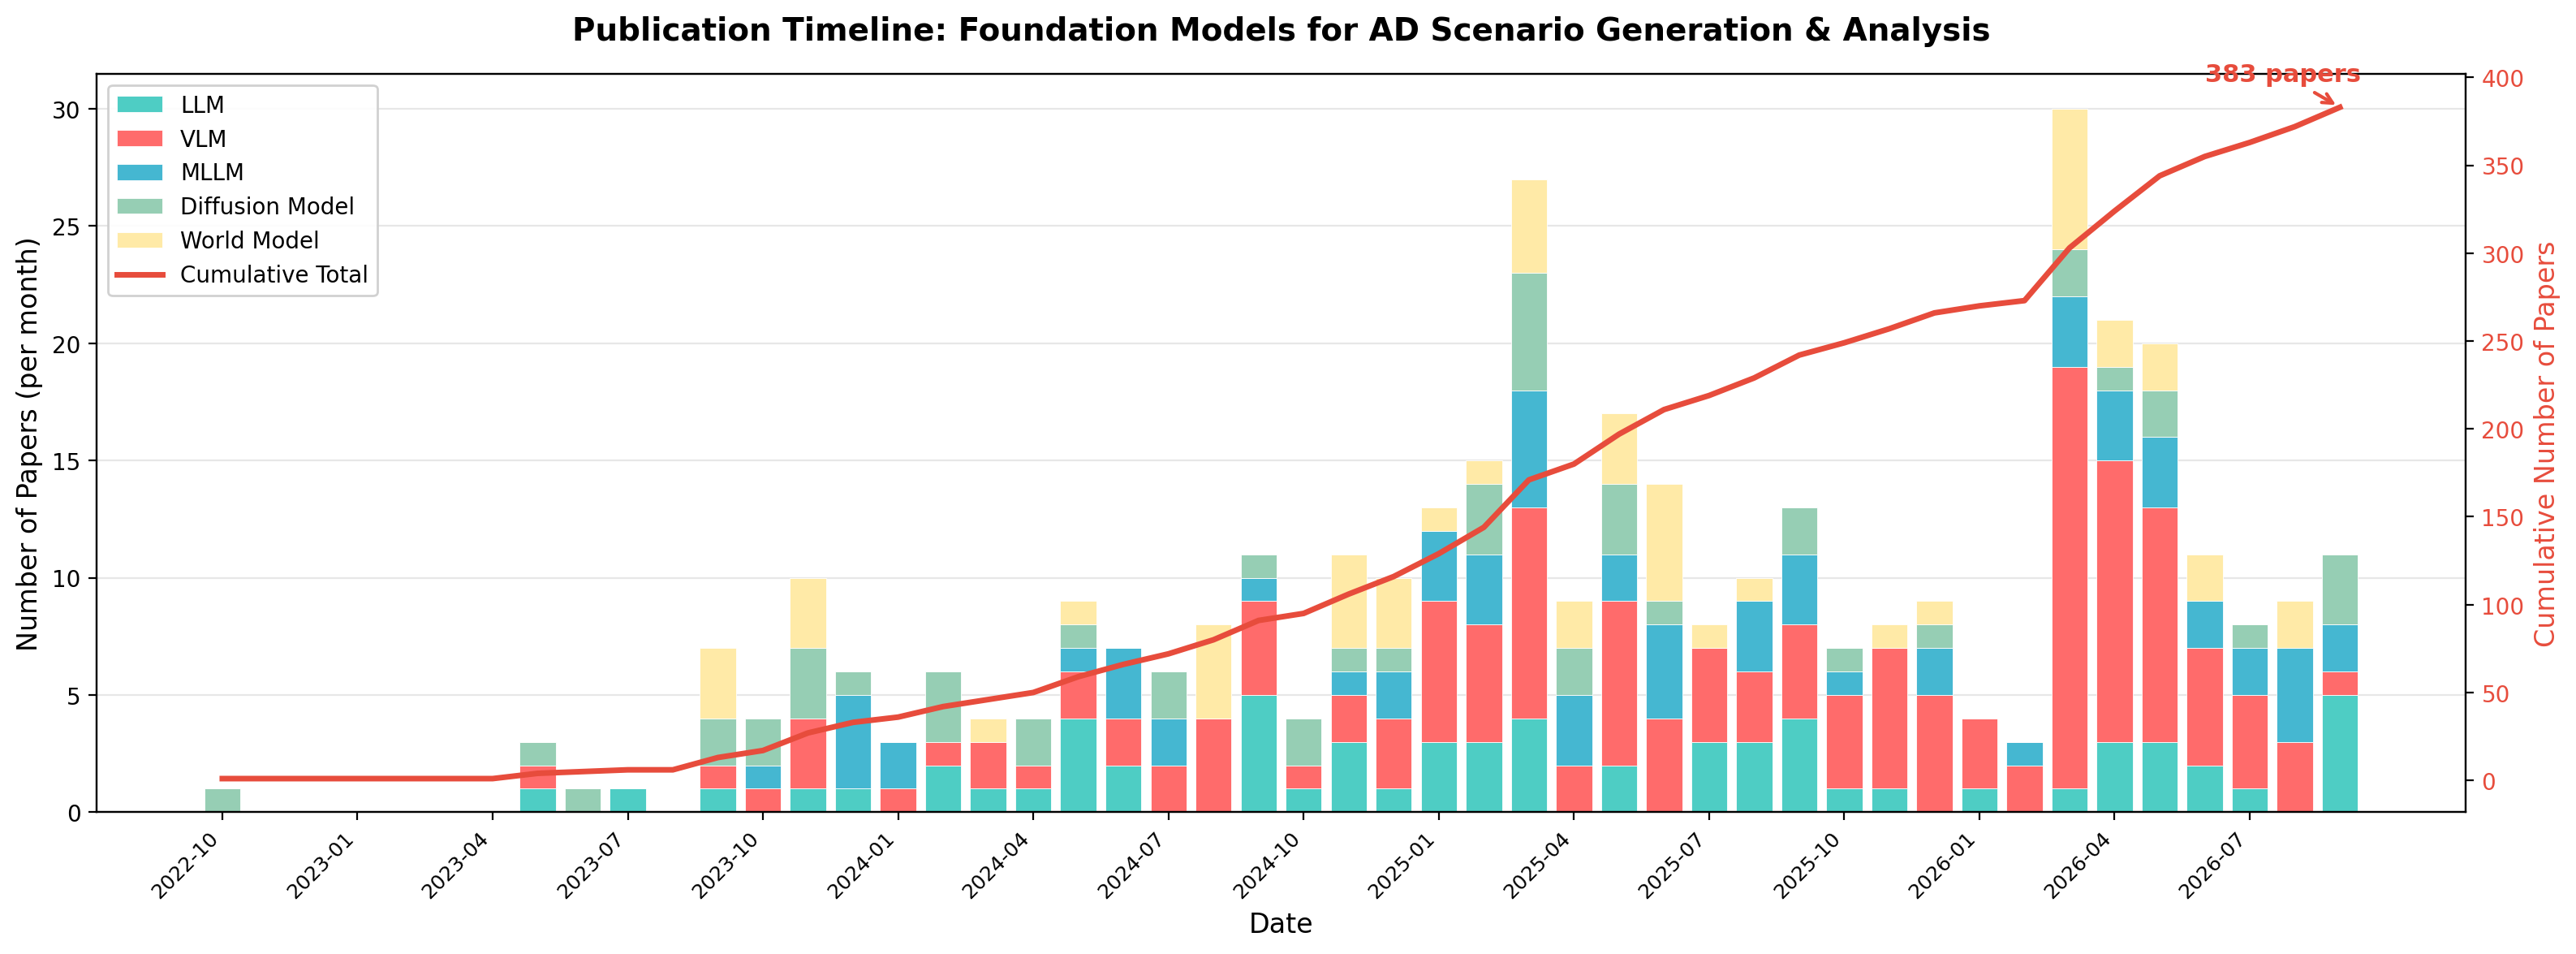
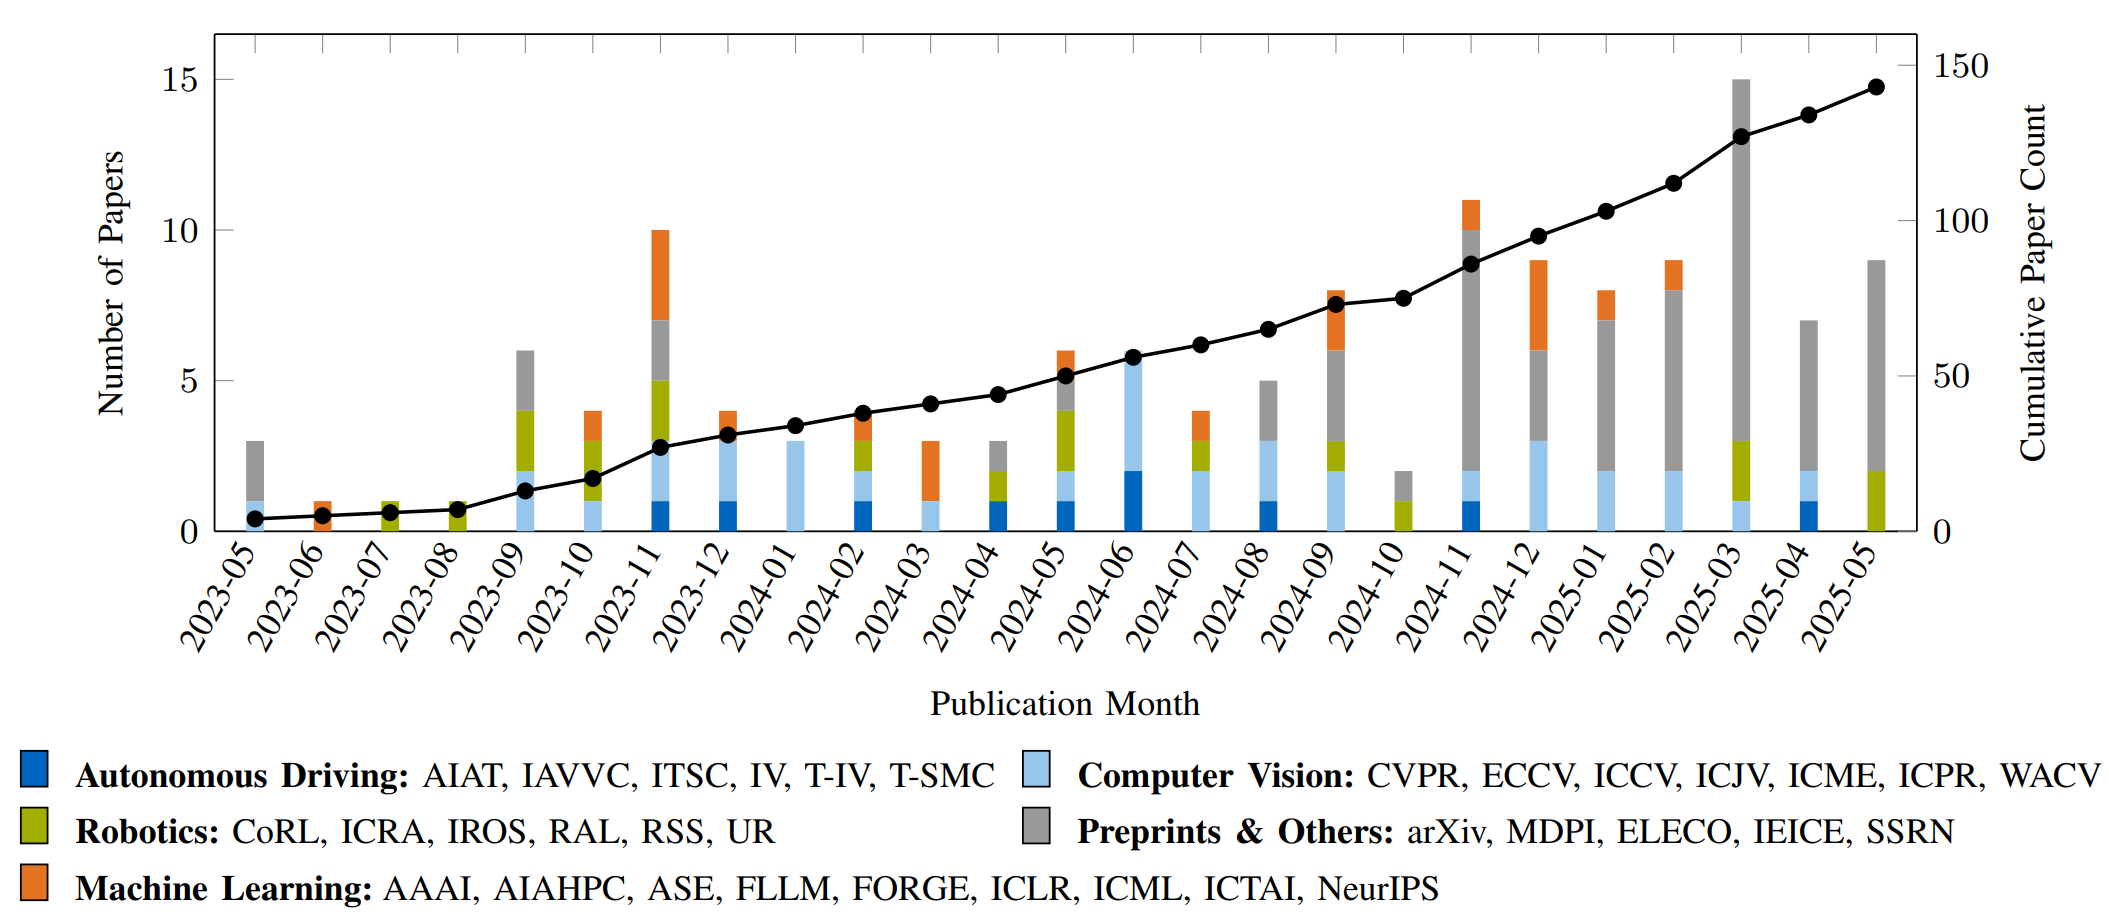
The following figure shows the evolution of foundation model research in autonomous driving scenario generation and analysis over time:

:mag: Search Methodology

The following list of keywords was used to search this survey's papers in the Google Scholar database. The keywords were entered either individually or in combination with other keywords in the list. The search was conducted until May 2025.

Keywords:

  • Foundation Model Types: Foundation Models, Large Language Models (LLMs), Vision-Language Models (VLMs), Multimodal Large Language Models (MLLMs), Diffusion Models (DMs), World Models (WMs), Generative Models (GMs)
  • Scenario Generation & Analysis: Scenario Generation, Scenario Simulation, Traffic Simulation, Scenario Testing, Scenario Understanding, Driving Scene Generation, Scene Reasoning, Risk Assessment, Safety-Critical Scenarios, Accident Prediction
  • Application Context: Autonomous Driving, Self-Driving Vehicles, AV Simulation, Driving Video Generation, Traffic Datasets, Closed-Loop Simulation, Safety Assurance

🕒 Timeline of the Development of Foundation Models

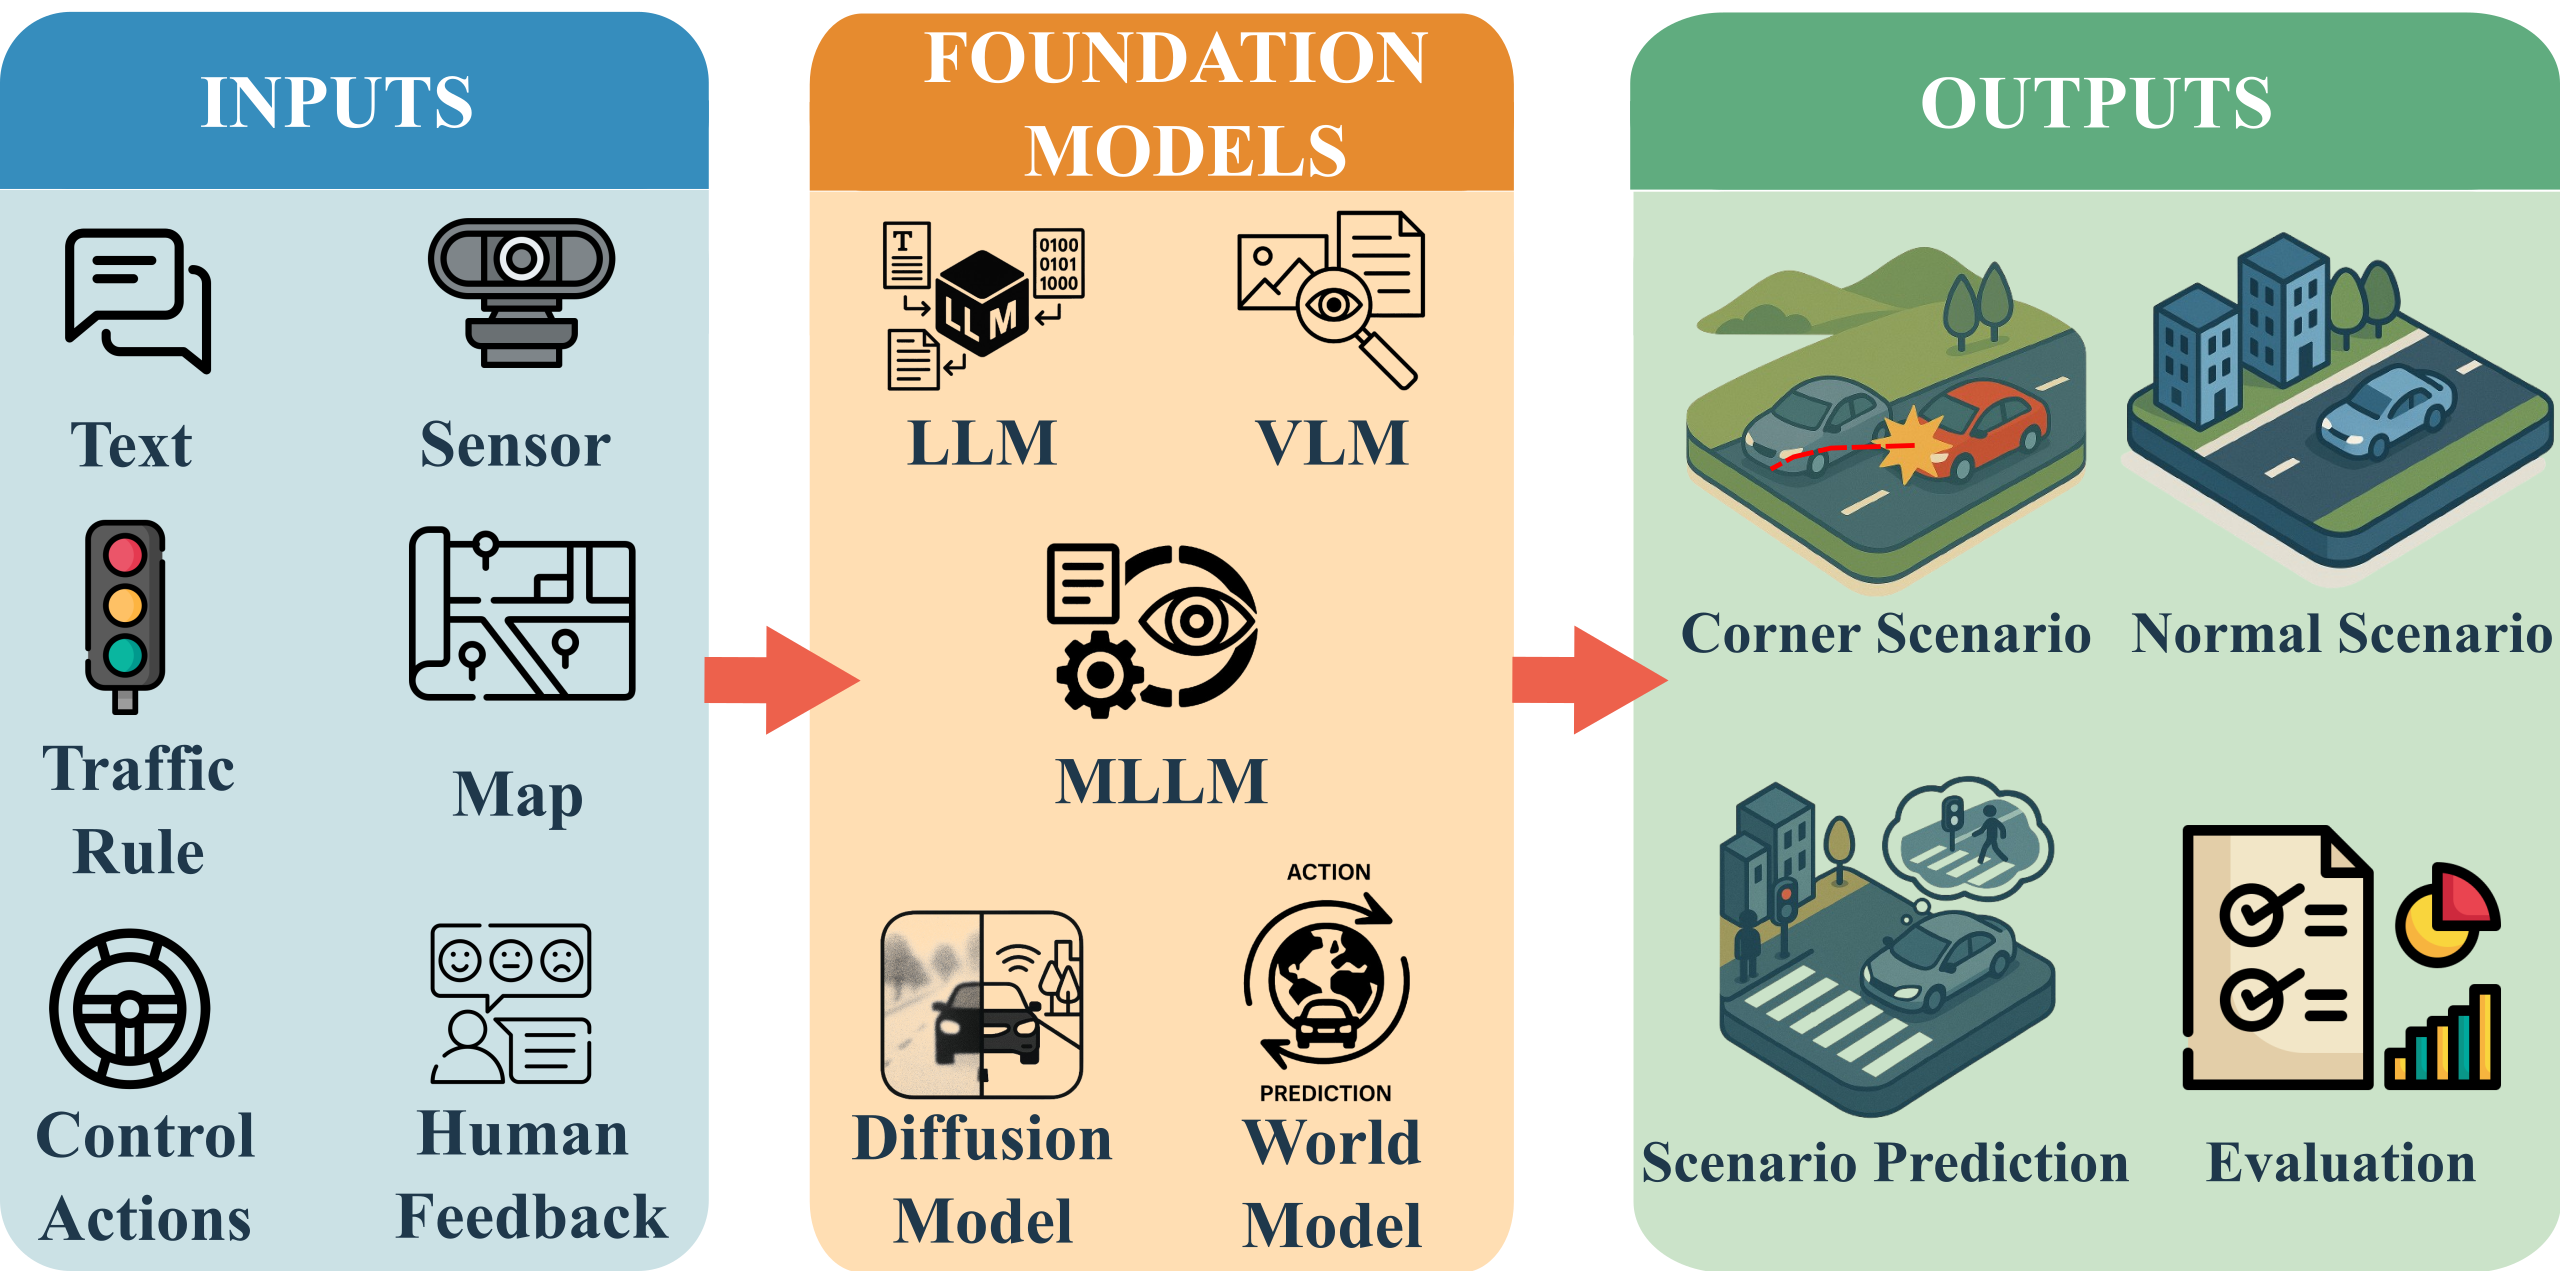
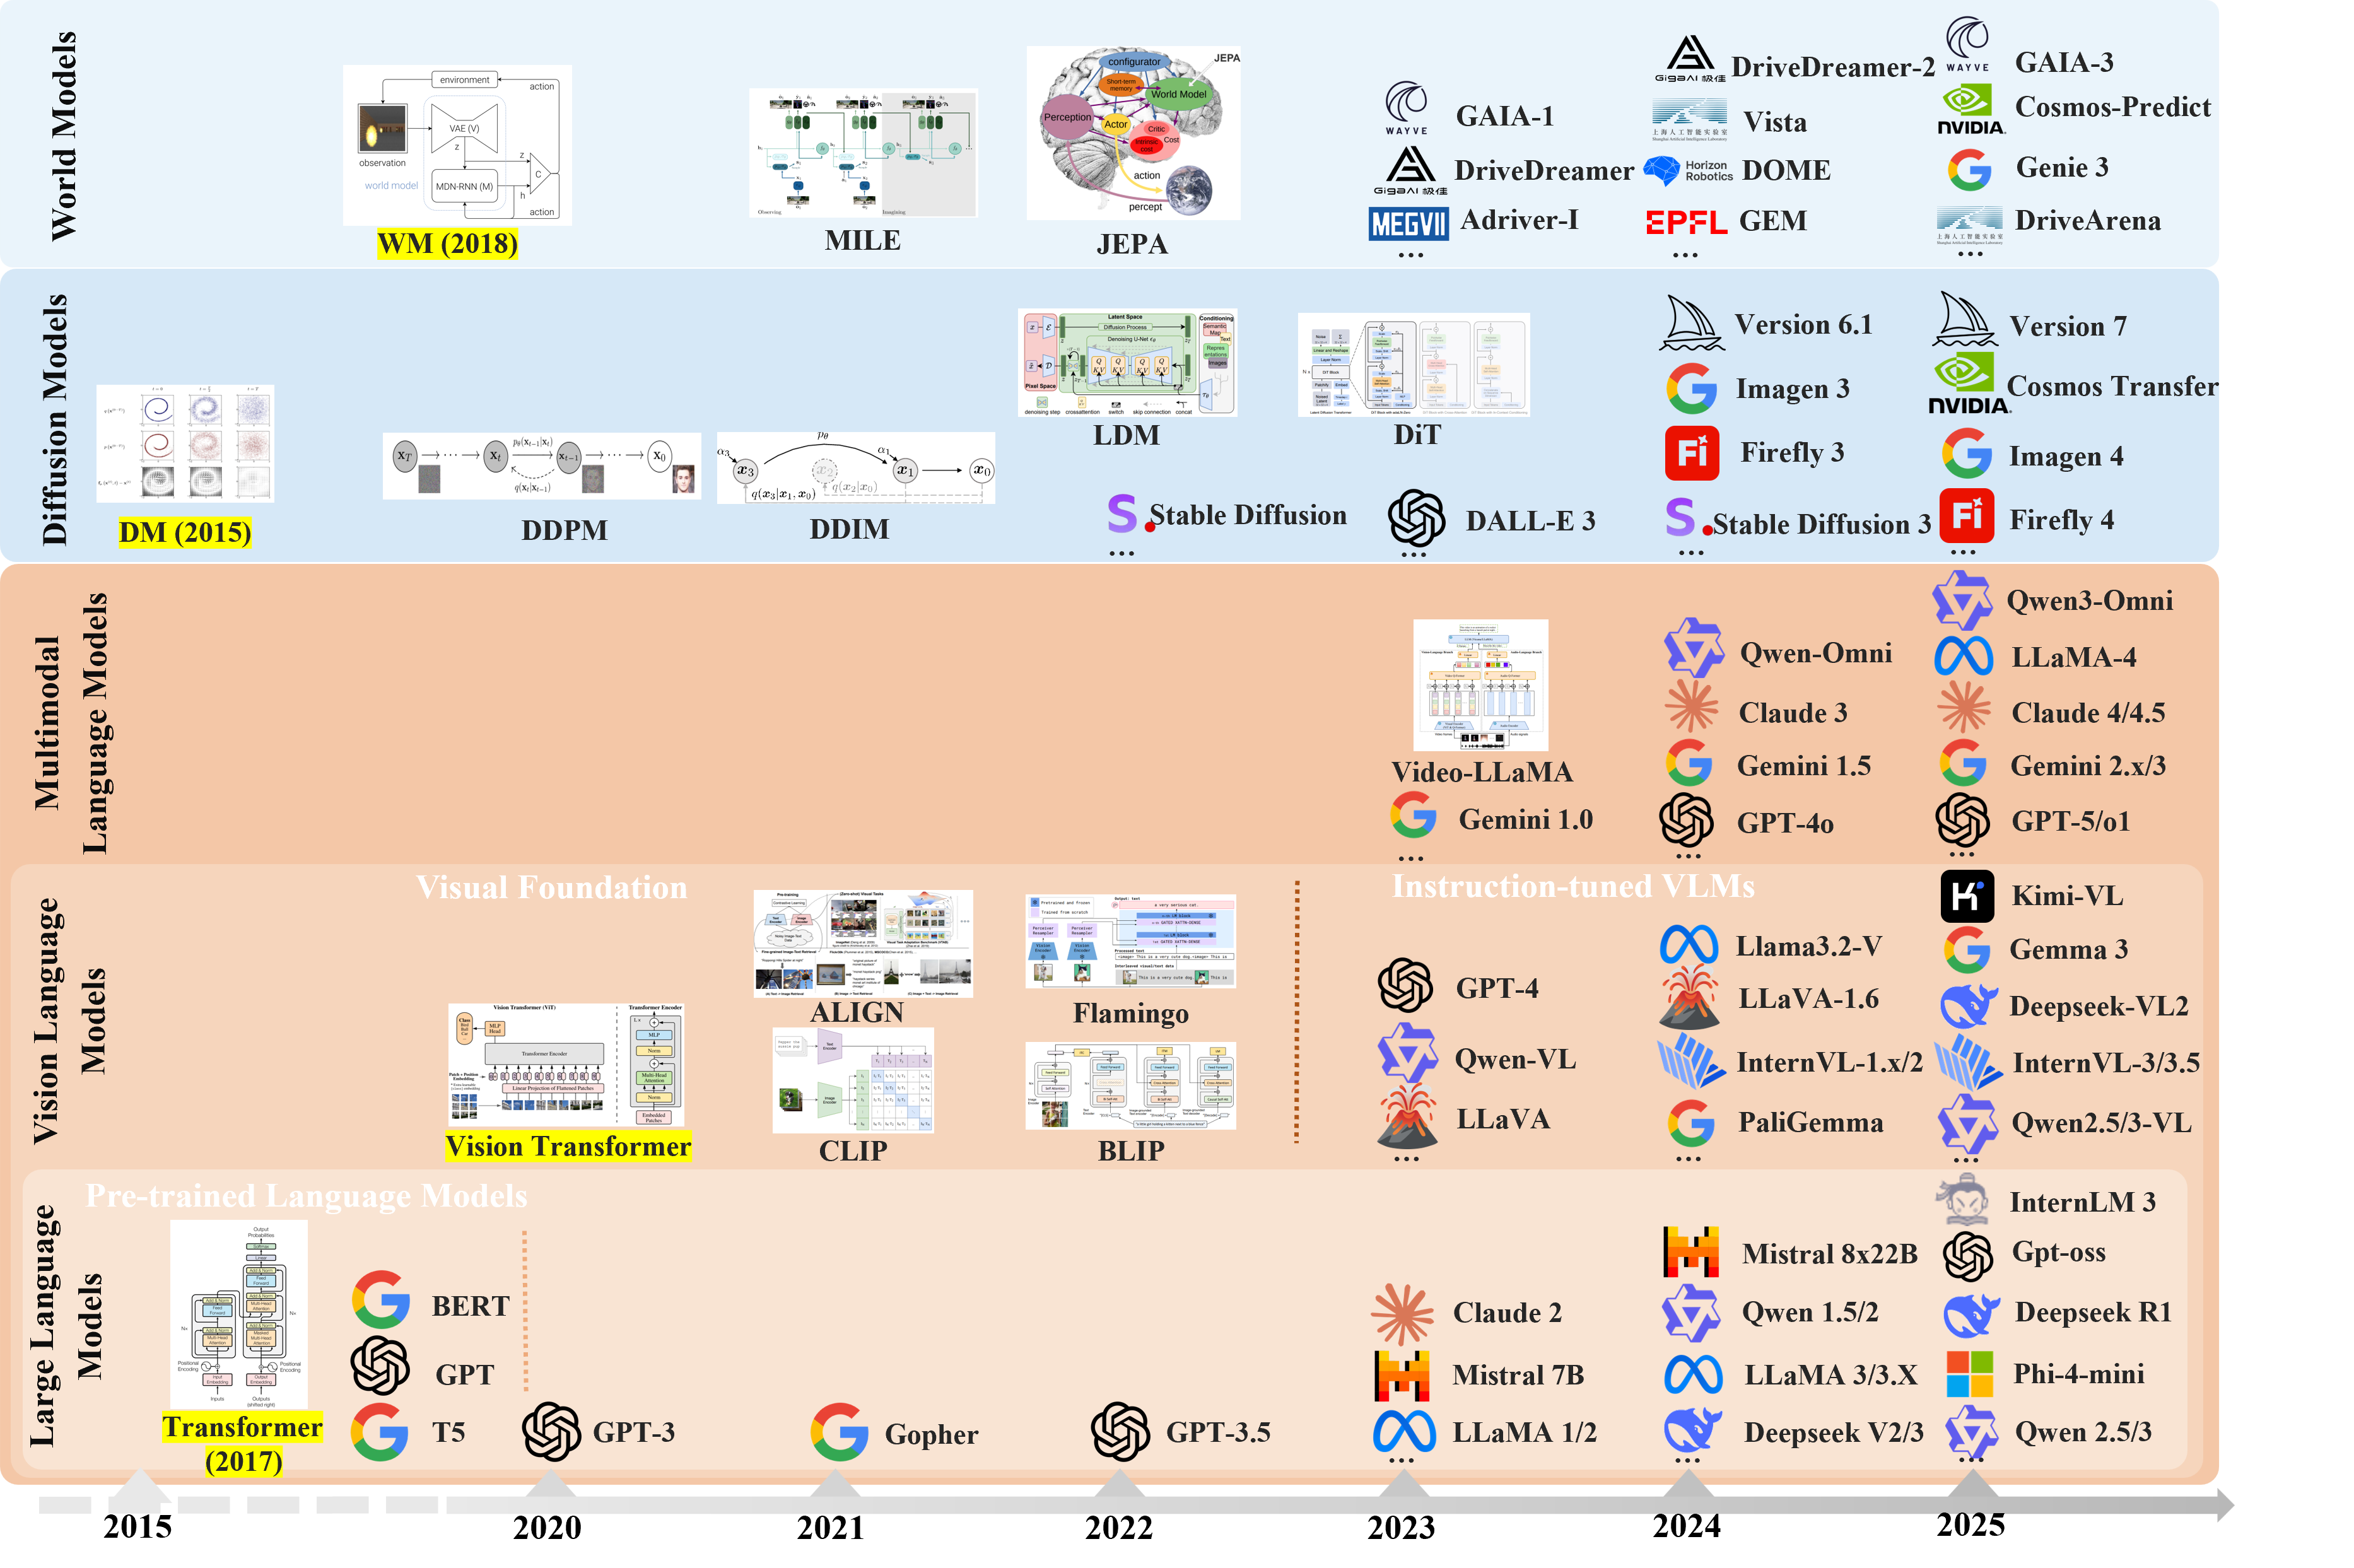
The figure illustrates the evolution of foundation models. LLMs (e.g., BERT, GPT) appear at the bottom, followed by VLMs built on visual FMs (e.g., ViT, CLIP) and instruction-tuned VLMs for interactive vision–language reasoning. MLLMs are shown at the top. In parallel, the progression of visual FMs is traced through Diffusion Models (DMs) and World Models (WMs). Highlighted entries mark key conceptual milestones.

🌟 Large Language Models for Autonomous Driving

Scenario Generation (LLM)
PaperDateVenueCodeHardwareCitation
TARGET: Automated Scenario Generation from Traffic Rules for Testing Autonomous Vehicles2023-05IEEE Transactions on Software Engineering-API&RTX409024
Language Conditioned Traffic Generation2023-07CoRL 2023GitHubAPI98
A Generative AI-driven Application: Use of Large Language Models for Traffic Scenario Generation2023-11ELECO 2023-API15
ChatGPT-Based Scenario Engineer: A New Framework on Scenario Generation for Trajectory Prediction2024-02IEEE Transactions on Intelligent Vehicles--48
Enhancing Autonomous Vehicle Training with Language Model Integration and Critical Scenario Generation2024-04arXivGitHubA600024
LLMScenario: Large Language Model Driven Scenario Generation2024-05IEEE Transactions on Systems, Man, and Cybernetics: Systems-API69
Automatic Generation Method for Autonomous Driving Simulation Scenarios Based on Large Language Model2024-05AIAT 2024-API2
ChatScene: Knowledge-Enabled Safety-Critical Scenario Generation for Autonomous Vehicles2024-05CVPR 2024GitHubAPI113
Editable scene simulation for autonomous driving via collaborative llm-agents2024-06CVPR 2024GitHubAPI130
Chat2Scenario: Scenario Extraction From Dataset Through Utilization of Large Language Model2024-06IV 2024GitHub-15
SoVAR: Building Generalizable Scenarios from Accident Reports for Autonomous Driving Testing2024-09ASE 2024-RTX407029
LeGEND: A Top-Down Approach to Scenario Generation of Autonomous Driving Systems Assisted by Large Language Models2024-09ASE 2024GitHubRTX309032
Traffic Scene Generation from Natural Language Description for Autonomous Vehicles with Large Language Model2024-09arXivGitHubAPI18
Promptable Closed-loop Traffic Simulation2024-09CoRL 2024GitHubA10016
Multimodal Large Language Model Driven Scenario Testing for Autonomous Vehicles2024-09Automotive Innovation--26
LLM-Driven Testing for Autonomous Driving Scenarios2024-11FLLM 2024-API& T415
ChatSUMO: Large Language Model for Automating Traffic Scenario Generation in Simulation of Urban MObility2024-11IEEE Transactions on Intelligent Vehicles-RTX409054
Generating Out-Of-Distribution Scenarios Using Language Models2024-11arXiv-API13
Generating Traffic Scenarios via In-Context Learning to Learn Better Motion Planner2024-12AAAI 2025 OralGitHubRTX 30903
LLM-attacker: Enhancing Closed-loop Adversarial Scenario Generation for Autonomous Driving with Large Language Models2025-01TITS 2025-RTX 400025
ML-SceGen: A Multi-level Scenario Generation Framework2025-01arXiv-RTX 40900
From Words to Collisions: LLM-Guided Evaluation and Adversarial Generation of Safety-Critical Driving Scenarios2025-02ITSC 2025GitHubAPI3
CurricuVLM: Towards Safe Autonomous Driving via Personalized Safety-Critical Curriculum Learning with Vision-Language Models2025-02arXivGitHub-10
Text2Scenario: Text-Driven Scenario Generation for Autonomous Driving Test2025-03arXivGitHub-14
Enhancing Autonomous Driving Safety with Collision Scenario Integration2025-03arXiv-8xV1006
Seeking to Collide: Online Safety-Critical Scenario Generation for Autonomous Driving with Retrieval Augmented Large Language Models2025-05ITSC 2025-API5
From Failures to Fixes: LLM-Driven Scenario Repair for Self-Evolving Autonomous Driving2025-05arXiv-RTX40900
AGENTS-LLM: Augmentative GENeration of Challenging Traffic Scenarios with an Agentic LLM Framework2025-07arXiv-API1
LLM-based Realistic Safety-Critical Driving Video Generation2025-07arXiv-RTX40901
Adversarial Generation and Collaborative Evolution of Safety-Critical Scenarios for Autonomous Vehicles2025-08arXivGitHub2xRTX40900
LLM-based Human-like Traffic Simulation for Self-driving Tests2025-08arXiv-API& A8000
Conversational Code Generation: a Case Study of Designing a Dialogue System for Generating Driving Scenarios for Testing Autonomous Vehicles2025-09GeCoIn 2025-A60003
Txt2Sce: Scenario Generation for Autonomous Driving System Testing Based on Textual Reports2025-09arXiv-RTX3070Ti1
LLM‑Based Semantic Modeling & Cooperative Evolutionary Fuzzing2025-09APSEC 2025--0
LinguaSim: Interactive Multi-Vehicle Testing Scenario Generation via Natural Language Instruction Based on Large Language Models2025-10IEEE ITSC 2025--0
Learning from Risk: LLM-Guided Generation of Safety-Critical Scenarios with Prior Knowledge2025-11arXivGitHub-0
AnchorDrive: LLM Scenario Rollout with Anchor-Guided Diffusion Regeneration for Safety-Critical Scenario Generation2026-03arXiv--0
TRACE: Topology-aware Reconstruction of Accidents in CARLA for AV Evaluation2026-04FSE 2026GitHubAPI0
Traffic Scenario Orchestration from Language via Constraint Satisfaction2026-05arXiv--0
PCASim: Promptable Closed-loop Adversarial Simulation for Urban Traffic Environment2026-05arXivProject-0
TrafficAlign: Aligning Large Language Models for Traffic Scenario Generation2026-06CVPR 2026GitHub-0
REARL: A Closed-loop Autonomous Driving Simulation Enhancement Framework with Real Traffic Data and Large Language Models2026-09arXiv--0
LLM-Guided Transformation of Non-Critical Driving Scenes into Safety-Critical Scenarios Using Augmented Reality2026-09arXiv--0
SimSkill: A Self-Evolving LLM Agent for Skill and Knowledge Accumulation in Traffic Simulation2026-09arXivGitHubM1 Max & API0
PlannerForge: LLM Agents for Scenario-Based Testing of Motion Planners in Autonomous Driving2026-09EMNLP 2026GitHubRTX5090 & API0
Scenario Analysis (LLM)
PaperDateVenueCodeHardwareCitation
Semantic Anomaly Detection with Large Language Models2023-09Autonomous Robots--131
LaMPilot: An Open Benchmark Dataset for Autonomous Driving with Language Model Programs2023-12CVPR 2024GitHub-0
Hybrid Reasoning Based on Large Language Models for Autonomous Car Driving2024-02arXivGitHub-0
Reality Bites: Assessing the Realism of Driving Scenarios with Large Language Models2024-03IEEE/ACM First International Conference on AI Foundation Models and Software Engineering (Forge)GitHubAPI22
Driving with LLMs: Fusing Object-Level Vector Modality for Explainable Autonomous Driving2024-05ICRA 2024GitHubAPI340
Bench4Merge: A Comprehensive Benchmark for Merging in Realistic Dense Traffic with Micro-Interactive Vehicles2024-10arXivGitHub-0
SenseRAG: Constructing Environmental Knowledge Bases with Proactive Querying for LLM-Based Autonomous Driving2025-012025 WACVW-API9
From Words to Collisions: LLM-Guided Evaluation and Adversarial Generation of Safety-Critical Driving Scenarios2025-02ITSC 2025GitHubAPI3
A Comprehensive LLM-powered Framework for Driving Intelligence Evaluation2025-03ICRA 2025GitHubAPI7
Understanding Driving Risks using Large Language Models: Toward Elderly Driver Assessment2025-07arXiv--0
Collision risk prediction and takeover requirements assessment based on radar-video integrated sensors data: A system framework based on LLM2025-08Accident Analysis & Prevention-API&RTX40907
Evaluation of Large Language Models for Anomaly Detection in Autonomous Vehicles2025-09arXiv--0
AgentDrive: An open benchmark suite for agentic AI reasoning in autonomous systems2026-01arXivGitHub-0
LLM-MLFFN: Multi-Level Autonomous Driving Behavior Feature Fusion via Large Language Model2025-03arXiv--0
Towards Lawful Autonomous Driving: Deriving Scenario-Aware Driving Requirements from Traffic Laws and Regulations2026-04arXiv--0
SwarmDrive: Semantic V2V Coordination for Latency-Constrained Cooperative Autonomous Driving2026-04arXiv--0
Pedestrian-Aware LLM-Driven Behavioral Planning for Autonomous Vehicles2026-05IEEE ITSC 2026--0
AutoMine Solution for AV2 2026 Scenario Mining Challenge2026-06arXiv--0
A knowledge-augmented dataset of high-risk driving scenarios with LLM annotations for autonomous driving2026-07arXivGitHub-0
SAFARI: An Industrial Benchmark for LLM-Assisted Hazard Analysis and Risk Assessment2026-09arXivGitHubAPI0

🌟 Vision-Language Models for Autonomous Driving

Scenario Generation (VLM)
Scenario Analysis (VLM)
PaperDateVenueCodeHardwareCitation
Unsupervised 3D Perception with 2D Vision-Language Distillation for Autonomous Driving2023-09ICCV 2023--49
OpenAnnotate3D: Open-Vocabulary Auto-Labeling System for Multi-modal 3D Data2023-10ICRA 2024GitHubAPI&RTX409019
On the Road with GPT-4V(ision): Early Explorations of Visual-Language Model on Autonomous Driving2023-11ICIL 2024 Workshop on Large Language Models for AgentsGitHub-105
Talk2BEV: Language-enhanced Bird's-eye View Maps for Autonomous Driving2023-11ICRA 2024GitHubA100114
LLM Multimodal Traffic Accident Forecasting2023-11Sensors 2023 MDPI--98
NuScenes-MQA: Integrated Evaluation of Captions and QA for Autonomous Driving Datasets using Markup Annotations2024-01WACVW LLVM-AD 2024GitHub8xA10035
Is it safe to cross? Interpretable Risk Assessment with GPT-4V for Safety-Aware Street Crossing2024-02UR 2024--22
Multi-Frame, Lightweight & Efficient Vision-Language Models for Question Answering in Autonomous Driving2024-03VLADR 2024GitHubRTX 3090Ti&V10055
Embodied Understanding of Driving Scenarios (ELM)2024-03ECCV 2024GitHub-0
LATTE: A Real-time Lightweight Attention-based Traffic Accident Anticipation Engine2024-04Information Fusion (Elsevier)-RTX40803
OmniDrive: A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning2024-05CVPR 2025GitHub-47
Hard Cases Detection in Motion Prediction by Vision-Language Foundation Models2024-05arXivGitHub-0
Reason2Drive: Towards Interpretable and Chain-based Reasoning for Autonomous Driving2024-06ECCV 2024GitHub8xV100118
ConnectGPT: Connect Large Language Models with Connected and Automated Vehicles2024-06IV 2024--21
SimpleLLM4AD: An End-to-End Vision-Language Model with Graph Visual Question Answering for Autonomous Driving2024-07arXiv--14
Large Language Models Powered Context-aware Motion Prediction in Autonomous Driving2024-07IROS 2024GitHubAPI13
DriveGenVLM: Real-world Video Generation for Vision Language Model based Autonomous Driving2024-08IAVVC 2024-L413
V2X-VLM: End-to-End V2X Cooperative Autonomous Driving Through Large Vision-Language Models2024-08arXiv-RTX409046
Multi-Frame Vision-Language Model for Long-form Reasoning in Driver Behavior Analysis2024-08arXiv--0
Think-Driver: From Driving-Scene Understanding to Decision-Making with Vision Language Models2024-09ECCV 2024 Workshop-4xRTX40904
Can LVLMs Obtain a Driver's License? A Benchmark Towards Reliable AGI for Autonomous Driving2024-09AAAI 2025Project-0
ContextVLM: Zero-Shot and Few-Shot Context Understanding for Autonomous Driving using Vision Language Models2024-09arXivGitHub-0
Efficient Driving Behavior Narration and Reasoning on Edge Device Using Large Language Models2024-09arXiv--0
VLM-Auto: VLM-based Autonomous Driving Assistant with Human-like Behavior and Understanding for Complex Road Scenes2024-10FLLM 2024GitHubRTX409041
Visual Adversarial Attack on Vision-Language Models for Autonomous Driving2024-11arXiv-A80019
Automated Evaluation of Large Vision-Language Models on Self-driving Corner Cases2024-12WACV 2025GitHub8xA80033
SFF Rendering-Based Uncertainty Prediction using VisionLLM2024-12AAAI 2025 Workshop LM4Plan-A1003
AutoTrust: Benchmarking Trustworthiness in Large Vision Language Models for Autonomous Driving2024-12arXivGitHub-0
Are VLMs Ready for Autonomous Driving? An Empirical Study from the Reliability, Data, and Metric Perspectives2025-01ICCV 2025GitHub8xA80028
Enhancing Large Vision Model in Street Scene Semantic Understanding through Leveraging Posterior Optimization Trajectory2025-01arXiv-2xRTX40907
Enhancing Vision-Language Models with Scene Graphs for Traffic Accident Understanding2025-01IAVVC 2024--15
DriveLM: Driving with Graph Visual Question Answering2025-01ECCV 2024GitHub8xV100473
Scenario Understanding of Traffic Scenes Through Large Visual Language Models2025-01WACV 2025-A1007
Application of Vision-Language Model to Pedestrian Behavior and Scene Understanding in Autonomous Driving2025-01arXiv--0
INSIGHT: Enhancing Autonomous Driving Safety through Vision-Language Models on Context-Aware Hazard Detection and Edge Case Evaluation2025-02arXiv-A60008
Evaluating Multimodal Vision-Language Model Prompting Strategies for Visual Question Answering in Road Scene Understanding2025-02WACV workshop 2025-RTX409014
Vision-Integrated LLMs for Autonomous Driving Assistance: Human Performance Comparison and Trust Evaluation2025-02arXiv--0
NuGrounding: A Multi-View 3D Visual Grounding Framework in Autonomous Driving2025-03arXiv--4
Fine-Grained Evaluation of Large Vision-Language Models in Autonomous Driving2025-03ICCV 2025GitHub8xV10010
AutoDrive-QA- Automated Generation of Multiple-Choice Questions for Autonomous Driving Datasets Using Large Vision-Language Models2025-03arXivGitHub3xA60004
DriveLMM-o1: A Step-by-Step Reasoning Dataset and Large Multimodal Model for Driving Scenario Understanding2025-03arXivGitHub4xA600020
ORION: A Holistic End-to-End Autonomous Driving Framework by Vision-Language Instructed Action Generation2025-03arXivGitHub32xA80050
ChatBEV: A Visual Language Model that Understands BEV Maps2025-03arXiv--2
Robusto-1 Dataset: Comparing Humans and VLMs on real out-of-distribution Autonomous Driving VQA from Peru2025-03arXivGitHubA100&API2
Evaluation of Safety Cognition Capability in Vision-Language Models for Autonomous Driving2025-03arXiv--0
ST-VLM: Kinematic Instruction Tuning for Spatio-Temporal Reasoning in Vision-Language Models2025-03arXivProject-0
Retrieval-Based Interleaved Visual Chain-of-Thought in Real-World Driving Scenarios2025-04arXivGitHub4xA1006
ReasonDrive: Efficient Visual Question Answering for Autonomous Vehicles with Reasoning-Enhanced Small Vision-Language Models2025-04arXivGitHub-0
Vision Foundation Model Embedding-Based Semantic Anomaly Detection2025-05ICRA 2025 Workshop--3
OpenLKA: An Open Dataset of Lane Keeping Assist from Recent Car Models under Real-world Driving Conditions2025-05arXivGitHub-3
SURDS: Benchmarking Spatial Understanding and Reasoning in Driving Scenarios with Vision Language Models2025-05NeurIPS 2025GitHub8xA8006
Extending Large Vision-Language Model for Diverse Interactive Tasks in Autonomous Driving2025-05arXivGitHub8xA8005
Bridging Human Oversight and Black-box Driver Assistance: Vision-Language Models for Predictive Alerting in Lane Keeping Assist systems2025-05arXiv--3
AgentThink: A Unified Framework for Tool-Augmented Chain-of-Thought Reasoning in Vision-Language Models for Autonomous Driving2025-05EMNLP Findings 2025GitHub-0
FutureSightDrive: Thinking Visually with Spatio-Temporal CoT for Autonomous Driving2025-06NeurIPS 2025-8xA600065
Case-based Reasoning Augmented Large Language Model Framework for Decision Making in Realistic Safety-Critical Driving Scenarios2025-06arXiv-API1
Structured Labeling Enables Faster Vision-Language Models for End-to-End Autonomous Driving2025-06arXiv-8xRTX40902
DriveAction: A Benchmark for Exploring Human-like Driving Decisions in VLA Models2025-06arXivDataset-0
Box-QAymo: Box-Referring VQA Dataset for Autonomous Driving2025-07arXivGitHub-0
DriveMRP: Enhancing Vision-Language Models with Synthetic Motion Data for Motion Risk Prediction2025-07arXivGitHub8xH1000
SafeDriveRAG: Towards Safe Autonomous Driving with Knowledge Graph-based Retrieval-Augmented Generation2025-07ACMMM 2025GitHub-3
DRAMA-X: A Fine-grained Intent Prediction and Risk Reasoning Benchmark For Driving2025-08arXivGitHub-2
NuRisk: A Visual Question Answering Dataset for Agent-Level Risk Assessment in Autonomous Driving2025-09ICRA-API&RTX50901
DriveAgent-R1: Advancing VLM-based Autonomous Driving with Active Perception and Hybrid Thinking2025-09arXiv-API&8xH201
Enhancing Vision-Language Models for Autonomous Driving through Task-Specific Prompting and Spatial Reasoning2025-09IROS 2025 RoboSenseGitHubAPI0
Are VLMs Ready for Lane Topology Awareness in Autonomous Driving?2025-09arXiv--0
More Than Meets the Eye? Uncovering the Reasoning-Planning Disconnect in Training Vision-Language Driving Models2025-10arXiv--0
STRIDE-QA: Visual Question Answering Dataset for Spatiotemporal Reasoning in Urban Driving Scenes2025-10AAAI 2026GitHub16xH1003
VLR-Driver: Large Vision-Language-Reasoning Models for Embodied Autonomous Driving2025-10ICCV 2025--0
Hierarchical Reasoning with Vision-Language Models for Incident Reports from Dashcam Videos2025-10arXivGitHub-0
WaymoQA: A Multi-View Visual Question Answering Dataset for Safety-Critical Reasoning in Autonomous Driving2025-11arXiv-8xA60000
A TOOL FOR BENCHMARKING LARGE LANGUAGE MODELS’ ROBUSTNESS IN ASSESSING THE REALISM OF DRIVING SCENARIOS2025-11arXiv-API0
V2X-VLM: End-to-End V2X Cooperative Autonomous Driving Through Large Vision-Language Models2025-11arXiv-RTX 409049
RoadBench: Benchmarking MLLMs on Fine-Grained Spatial Understanding and Reasoning under Urban Road Scenarios2025-11arXivGitHub-0
Is Your VLM for Autonomous Driving Safety-Ready? A Comprehensive Benchmark for Evaluating External and In-Cabin Risks2025-11arXiv--0
Toward Automatic Safe Driving Instruction: A Large-Scale Vision Language Model Approach2025-11arXiv--0
RoadSceneVQA: Benchmarking Visual Question Answering in Roadside Perception Systems for Intelligent Transportation System2025-12arXivGitHub4xA1000
OmniDrive-R1: Reinforcement-driven Interleaved Multi-modal Chain-of-Thought for Trustworthy Vision-Language Autonomous Driving2025-12arXiv-16xA8000
Counterfactual VLA: Self-Reflective Vision-Language-Action Model with Adaptive Reasoning2025-12CVPR 2026--0
Semantic-Drive: Democratizing Long-Tail Data Curation via Open-Vocabulary Grounding and Neuro-Symbolic VLM Consensus2025-12arXivGitHub-0
Vision-Based Natural Language Scene Understanding for Autonomous Driving: An Extended Dataset and a New Model for Traffic Scene Description Generation2026-01arXiv-A1000
AutoDriDM: An Explainable Benchmark for Decision-Making of Vision-Language Models in Autonomous Driving2026-01arXiv-A1000
ScenePilot-Bench: A Large-Scale Dataset and Benchmark for Evaluation of Vision-Language Models in Autonomous Driving 2026-01arXivGitHub4xA8000
Vision and Language: Novel Representations and Artificial intelligence for Driving Scene Safety Assessment and Autonomous Vehicle Planning2026-02arXiv--0
DRIV-EX: Counterfactual Explanations for Driving LLMs2026-02arXiv-20xA1000
DriveCombo: Benchmarking Compositional Traffic Rule Reasoning in Autonomous Driving2026-03arXiv--0
DriveCode: Domain Specific Numerical Encoding for LLM-Based Autonomous Driving2026-03arXiv-8xH1000
Probing Visual Concepts in Lightweight Vision-Language Models for Automated Driving2026-03arXivGitHub-0
BEVLM: Distilling Semantic Knowledge from LLMs into Bird’s-Eye View Representations2026-03arXiv-8xH1000
Perception-Aware Multimodal Spatial Reasoning from Monocular Images2026-03arXiv-8xH1000
Comparative Analysis of Patch Attack on VLM-Based Autonomous Driving Architectures2026-03arXivIV 2025-0
More than the Sum: Panorama-Language Models for Adverse Omni-Scenes2026-03CVPR2026-https://github.com/InSAI-Lab/PanoVQA0
Probing the Reliability of Driving VLMs: From Inconsistent Responses to Grounded Temporal Reasoning2026-03arXiv-4xA1000
Are Video Reasoning Models Ready to Go Outside?2026-03arXivGitHub4xA1000
WorldVLM: Combining World Model Forecasting and Vision-Language Reasoning2026-03arXiv-4xA400
VLM-AutoDrive: Post-Training Vision-Language Models for Safety-Critical Autonomous Driving Events2026-03arXiv-32xH1000
KLDrive: Fine-Grained 3D Scene Reasoning for Autonomous Driving based on Knowledge Graph2026-03arXiv-A60000
DRIVINGVQA: A Dataset for Interleaved Visual Chain-of-Thought in Real-World Driving Scenarios2026-03ECAL 2026GitHub4xA1000
3DCity-LLM: Empowering Multi-modality Large Language Models for 3D City-scale Perception and Understanding2026-03arXivGitHubA1000
Collision-Aware Vision-Language Learning for End-to-End Driving with Multimodal Infraction Datasets2026-03arXiv--0
Dual-Stage LLM Framework for Scenario-Centric Semantic Interpretation in Driving Assistance2026-03arXiv--0
A Semantic Observer Layer for Autonomous Vehicles: Pre-Deployment Feasibility Study of VLMs for Low-Latency Anomaly Detection2026-03arXiv-50900
How Well Do Vision-Language Models Understand Sequential Driving Scenes? A Sensitivity Study (VENUSS)2026-04arXiv-API0
BATON: A Multimodal Benchmark for Bidirectional Automation Transition Observation in Naturalistic Driving2026-04arXiv-API0
CrashSight: A Phase-Aware, Infrastructure-Centric Video Benchmark for Traffic Crash Scene Understanding and Reasoning2026-04arXiv-8xA1000
VAGNet: Vision-based Accident Anticipation with Global Features2026-04arXiv-RTX40900
SignReasoner: Compositional Reasoning for Complex Traffic Sign Understanding via Functional Structure Units2026-04arXiv-4xH1000
CCTVBench: Contrastive Consistency Traffic VideoQA Benchmark for Multimodal LLMs2026-04arXiv-API0
Towards Safe Mobility: A Unified Transportation Foundation Model enabled by Open-Ended Vision-Language Dataset (UniVLT / LTD)2026-04arXiv-8xH1000
EgoDyn-Bench: Evaluating Ego-Motion Understanding in Vision-Centric Foundation Models for Autonomous Driving2026-04arXiv-API0
Zoom In, Reason Out: Efficient Far-field Anomaly Detection in Expressway Surveillance Videos via Focused VLM Reasoning Guided by Bayesian Inference (VIBES)2026-04arXiv-RTX40900
VLM-VPI: A Vision-Language Reasoning Framework for Improving Automated Vehicle-Pedestrian Interactions2026-04arXiv-API0
HiDrive: A Closed-Loop Benchmark for High-Level Autonomous Driving2026-05arXivGitHub-0
Bench2Drive-VL: Benchmarks for Closed-Loop Autonomous Driving with Vision-Language Models2026-04arXivGitHub-0
Bridging Structure and Language: Graph-Based Visual Reasoning for Autonomous Road Understanding2026-05arXiv--0
C-CoT: Counterfactual Chain-of-Thought with Vision-Language Models for Safe Autonomous Driving2026-05arXiv--0
D2-V2X: Depth-Driven Cooperative V2X Reasoning for Autonomous Driving2026-05arXivGitHub-0
DRIVESPATIAL: A Benchmark for Spatiotemporal Intelligence in VLMs for Autonomous Driving2026-05NeurIPS 2026Project-0
PEDESTRIANQA: A Benchmark for Vision-Language Models on Pedestrian Intention and Trajectory Prediction2026-05arXivGitHub-0
ReasonBreak: Probing Vulnerabilities in Reasoning-Enabled Vision-Language-Action Models for Autonomous Driving2026-05arXiv--0
Two-Pass Zero-Shot Temporal-Spatial Grounding of Rare Traffic Events in Surveillance Video2026-05arXiv--0
nuReasoning: A Reasoning-Centric Dataset and Benchmark for Long-Tail Autonomous Driving2026-05arXivProject-0
Vision-Language Work Zone Intelligence for Safety-Critical Speed Regulation of Mixed-Autonomy Vehicles in Dynamic Environments2026-06arXivGitHub-0
Multi-Stage VLM Pipeline for Zero-Shot Traffic Accident Understanding2026-05arXivGitHub-0
DriveJudge: Rethinking Autonomous Driving Evaluation with Vision-Language Models2026-06arXiv--0
GeoDrive-Bench: Benchmarking Region-Specific Multimodal Reasoning in Autonomous Driving2026-06arXivGitHub-0
Metadata-Aware Multi-Prompt Reasoning for Zero-Shot Accident Understanding2026-06arXiv--0
Robusto-2: Benchmarking Humans & VLMs for Autonomous Driving in Lima & New York City2026-06arXiv--0
AUTOPILOT VQA: Benchmarking Vision-Language Models for Incident-Centric Dashcam Understanding2026-07arXiv--0
DispatchRAG: Grounding Emergency Dispatch Decisions in Real-World Protocols from Traffic Accident Video2026-07arXiv--0
Reasoning to Regulate: Chain-of-Thought for Traffic Rule Understanding2026-07arXiv--0
CAViAR: A Causal Video Dataset for Fine-Grained Accident Reasoning in Real-World Scenarios2026-08arXivGitHub-0
Observe Before You Alert: Adaptive Driver Alerting with Vision-Language Models2026-09arXiv-RTX50900
CrossView: Can Vision-Language Models Reason Across Cameras?2026-08arXivGitHubAPI0
SIREN-Bench: Behavior-Driven Generation and Evaluation of Emergency-Vehicle Interactions2026-08arXiv-V100S0

🌟 Multimodal Large Language Models for Autonomous Driving

Scenario Generation (MLLM)

| OmniTraffic: A Controllable Generation Pipeline and Benchmark for Spatio-Temporal Traffic Reasoning | 2026-06 | arXiv | - | - | 0 |

Scenario Analysis (MLLM)
PaperDateVenueCodeHardwareCitation
DriveGPT4: Interpretable End-to-end Autonomous Driving via Large Language Model2023-10IEEE Robotics and Automation Letters 2024GitHub-615
Dolphins: Multimodal Language Model for Driving2023-12ECCV 2024GitHub4xA100139
AccidentGPT: Accident analysis and prevention from V2X Environmental Perception with Multi-modal Large Model2023-12IV 2024GitHub-45
Lidar-llm: Exploring the potential of large language models for 3d lidar understanding2023-12AAAI 2025GitHubA100125
LingoQA: Visual Question Answering for Autonomous Driving2023-12ECCV 2024GitHub8xA100143
Holistic Autonomous Driving Understanding by Bird's-Eye-View Injected Multi-Modal Large Models2024-01CVPR 2024GitHub-106
MAPLM: A Real-World Large-Scale Vision-Language Benchmark for Map and Traffic Scene Understanding2024-01CVPR 2024GitHub8xV100&2xA10065
Probing Multimodal LLMs as World Models for Driving2024-05arXiv--0
WTS: A Pedestrian-Centric Traffic Video Dataset for Fine-Grained Spatial-Temporal Understanding2024-06ECCV 2024GitHub-19
Semantic Understanding of Traffic Scenes with Large Vision Language Models2024-06IV 2024GitHubAPI27
VLAAD: Vision and Language Assistant for Autonomous Driving2024-06WACVW 2024GitHub-52
InternDrive: A Multimodal Large Language Model for Autonomous Driving Scenario Understanding2024-07AIAHPC 2024-API4
WOMD-Reasoning: A Large-Scale Dataset for Interaction Reasoning in Driving2024-07ICML 2025GitHub-0
Using Multimodal Large Language Models for Automated Detection of Traffic Safety Critical Events2024-09Vehicles 2024 MDPI-API10
MLLM-SUL: Multimodal Large Language Model for Semantic Scene Understanding and Localization in Traffic Scenarios2024-12arXivGitHubA8007
Application of Multimodal Large Language Models in Autonomous Driving2024-12arXiv--0
Distilling Multi-modal Large Language Models for Autonomous Driving2025-01CVPR 2025--23
TB-Bench: Training and Testing Multi-Modal AI for Understanding Spatio-Temporal Traffic Behaviors from Dashcam Images/Videos2025-01arXivGitHub-0
TUMTraffic-VideoQA: A Benchmark for Unified Spatio-Temporal Video Understanding in Traffic Scenes2025-02ICML 2025GitHub4xA10013
ScVLM: Enhancing Vision-Language Model for Safety-Critical Event Understanding2025-02WACV Workshop 2025GitHub2xA1008
Sce2DriveX: A Generalized MLLM Framework for Scene-to-Drive Learning2025-02IEEE RAL-8xL2018
A Framework for a Capability-driven Evaluation of Scenario Understanding for Multimodal Large Language Models in Autonomous Driving2025-03arXiv--1
HiLM-D: Enhancing MLLMs with Multi-Scale High-Resolution Details for Autonomous Driving2025-03International Journal of Computer Vision-8xV10068
NuPlanQA: A Large-Scale Dataset and Benchmark for Multi-View Driving Scene Understanding in Multi-Modal Large Language Models2025-03ICCV 2025GitHub-8
Tracking Meets Large Multimodal Models for Driving Scenario Understanding2025-03arXivGitHub2xA60004
SimLingo: Vision-Only Closed-Loop Autonomous Driving with Language-Action Alignment2025-03CVPR 2025GitHub8xA10034
V3LMA: Visual 3D-enhanced Language Model for Autonomous Driving2025-04CVPR DriveX 2025GitHubH1003
Are Vision LLMs Road-Ready? A Comprehensive Benchmark for Safety-Critical Driving Video Understanding2025-04arXivGitHub-7
V2V-LLM: Vehicle-to-Vehicle Cooperative Autonomous Driving with Multi-Modal Large Language Models2025-04arXivGitHub8xA10022
ALN-P3: Unified Language Alignment for Perception, Prediction, and Planning in Autonomous Driving2025-05arXiv-2xH2003
DriveSOTIF: Advancing SOTIF Through Multimodal Large Language Models2025-05arXivGitHub-0
X-Driver: Explainable Autonomous Driving with Vision-Language Models2025-06arXiv--5
STSBench: A Spatio-temporal Scenario Benchmark for Multi-modal Large Language Models in Autonomous Driving2025-06NeurIPS 2025GitHub-2
SafePLUG: Empowering Multimodal LLMs with Pixel-Level Insight and Temporal Grounding for Traffic Accident Understanding2025-08arXiv-8xA1002
RoboTron-Drive: All-in-One Large Multimodal Model for Autonomous Driving2025-08ICCV2025GitHub32xA1009
Passing the Driving Knowledge Test (DriveQA)2025-08ICCV 2025--0
EMMA: End-to-End Multimodal Model for Autonomous Driving2025-09TMLR--161
Investigating Traffic Accident Detection Using Multimodal Large Language Models2025-09IAVVC 2025--1
AccidentBench: Benchmarking Multimodal Understanding and Reasoning in Vehicle Accidents and Beyond2025-09arXivGitHub-0
Addressing Corner Cases in Autonomous Driving: A World Model-based Approach with Mixture of Experts and LLMs2025-10Transportation Research Part C: Emerging Technologies-40900
BeLLA: End-to-End Birds Eye View Large Language Assistant for Autonomous Driving2025-12arXiv-4xH1000
MMDrive: Interactive Scene Understanding Beyond Vision with Multi-representational Fusion2025-12arXiv--0
Wild-Drive: Off-Road Scene Captioning and Path Planning via Robust Multi-modal Routing and Efficient Large Language Model2026-02arXiv-40900
DriveXQA: Cross-modal Visual Question Answering for Adverse Driving Scene Understanding2026-03arXivGitHub4xA1000
Interpretable Traffic Responsibility from Dashcam Video via Legal Multi-Agent Reasoning2026-03arXiv--0
ExpressMind: A Multimodal Pretrained Large Language Model for Expressway Operation2026-03arXivGitHub8xH200
AITP: Traffic Accident Responsibility Allocation via Multimodal Large Language Models2026-04CVPR 2026 Findings-8xA1000
XEmbodied: A Foundation Model with Enhanced Geometric and Physical Cues for Large-Scale Embodied Environments2026-04arXiv--0
V2X-QA: A Comprehensive Reasoning Dataset and Benchmark for MLLMs in Autonomous Driving Across Ego, Infrastructure, and Cooperative Views2026-04arXivGitHub-0
DriveSafe: A Framework for Risk Detection and Safety Suggestions in Driving Scenarios2026-05arXiv--0
Enhancing Multimodal Large Language Models for Safety-Critical Driving Video Analysis2026-05arXiv--0
GuardAD: Safeguarding Autonomous Driving MLLMs via Markovian Safety Logic2026-05arXiv--0
Where Does the Answer Come From? Benchmarking View-Level Visual Evidence Identification in Multi-View MLLMs for Autonomous Driving2026-06arXiv--0
OmniSpace: Efficient Geometry Awareness for Autonomous Vehicles MLLMs2026-06arXiv--0
Beyond Scene Priors: Fine-Grained Traffic Scene Reasoning with Benchmarking and Query-Guided Small-Object Focus2026-07arXiv--0
D3VL: Understanding Driving Scenes from 3D Time Series Data and Video with Language Models2026-07arXivProject-0
Sim-to-Real Traffic Scene Understanding by Decoupling Semantics from Caption Generation with V-JEPA2026-09arXivGitHubRTX60000
Inter-3D VQA: A Roadside Multimodal Benchmark for 3D Spatiotemporally Grounded Visual Question Answering2026-08arXivGitHub4×RTX Pro 60000
UniTraffic-Agent: Unified Traffic Video Reasoning for AI City Challenge 2026 Track 3 with Two Out-of-Domain Evaluations2026-08arXivGitHubAPI0
CASCADE: A Spatio-Temporal-Causal Reasoning Representation and Dataset for Driving2026-09arXiv--0
From Detection to Understanding: TAR and TAR-Bench for Multi-Task Traffic Anomaly Reasoning2026-08arXiv-8×A1000
Drive the Thoughts: Runtime Monitoring of VLA Reasoning-Trajectory Consistency2026-08arXivGitHubA100 & API0

🌟 Diffusion Models for Autonomous Driving

Scenario Generation (Diffusion Models)
PaperDateVenueCodeHardwareCitation
Guided Conditional Diffusion for Controllable Traffic Simulation2022-10ICRA 2023GitHub-223
Generating Driving Scenes with Diffusion2023-05ICRA Workshop--25
DiffScene: Guided Diffusion Models for Safety-Critical Scenario Generation2023-06AdvML-Frontiers 2023-RTX309076
BEVControl: Accurately Controlling Street-view Elements with Multi-perspective Consistency via BEV Sketch Layout2023-09arXiv--45
DriveSceneGen: Generating Diverse and Realistic Driving Scenarios From Scratch2023-09IEEE Robotics and Automation Letters 2024GitHub4xV10022
MagicDrive: Street View Generation with Diverse 3D Geometry Control2023-10ICLR 2024GitHubV100219
DrivingDiffusion: Layout-Guided multi-view driving scene video generation with latent diffusion model2023-10ECCV 2024GitHub8xA10080
Language-guided traffic simulation via scene-level diffusion2023-11CoRL 2023-RTX 3090121
Scenario Diffusion: Controllable Driving Scenario Generation With Diffusion2023-11NeurIPS 2023-2xA600064
Panacea: Panoramic and Controllable Video Generation for Autonomous Driving2023-11CVPR 2024GitHub-127
SAFE-SIM: Safety-Critical Closed-Loop Traffic Simulation with Diffusion-Controllable Adversaries2023-12ECCV 2024GitHub4xA600028
Text2Street: Controllable Text-to-image Generation for Street Views2024-02ICPR 2024--12
ChatTraffic: Text-to-Traffic Generation via Diffusion Model2024-02IEEE Transactions on Intelligent Transportation SystemsGitHubRTX409019
GEODIFFUSION: Text-Prompted Geometric Control for Object Detection Data Generation2024-02LCLR 2024GitHub-56
GenDDS: Generating Diverse Driving Video Scenarios with Prompt-to-Video Generative Model2024-04ITSC 2024-RTX3090Ti6
Versatile Behavior Diffusion for Generalized Traffic Agent Simulation2024-04RSS 2024GitHub8xL4013
SceneControl: Diffusion for Controllable Traffic Scene Generation2024-05ICRA 2024--33
SLEDGE: Synthesizing Driving Environments with Generative Models and Rule-Based Traffic2024-07ECCV 2024GitHub-24
DrivingGen: Efficient Safety-Critical Driving Video Generation with Latent Diffusion Models2024-07ICME 2024--9
Controllable Traffic Simulation through LLM-Guided Hierarchical Chain-of-Thought Reasoning2024-09IROS 2025--7
AdvDiffuser: Generating Adversarial Safety-Critical Driving Scenarios via Guided Diffusion2024-10IROS 2024-4xRTX309021
Data-driven Diffusion Models for Enhancing Safety in Autonomous Vehicle Traffic Simulations2024-10arXiv--4
DiffRoad: Realistic and Diverse Road Scenario Generation for Autonomous Vehicle Testing2024-11arXiv--7
SceneDiffuser: Efficient and Controllable Driving Simulation Initialization and Rollout2024-12NeurIPS 2024--48
Direct Preference Optimization-Enhanced Multi-Guided Diffusion Model for Traffic Scenario Generation2025-02arXiv--2
Causal Composition Diffusion Model for Closed-loop Traffic Generation2025-02CVPR 2025GitHub4xV10011
Rolling Ahead Diffusion for Traffic Scene Simulation2025-02AAAI 2025 Workshop-V1002
AVD2: Accident Video Diffusion for Accident Video Description2025-03ICRA 2025GitHub-16
DualDiff+: Dual-Branch Diffusion for High-Fidelity Video Generation with Reward Guidance2025-03arXivGitHub8xA8004
Scenario Dreamer: Vectorized Latent Diffusion for Generating Driving Simulation Environments2025-03CVPR 2025GitHub8xA10016
DriveGen: Towards Infinite Diverse Traffic Scenarios with Large Models2025-03arXiv--4
DiVE: Efficient Multi-View Driving Scenes Generation Based on Video Diffusion Transformer2025-04arXiv-8xA8004
Decoupled Diffusion Sparks Adaptive Scene Generation2025-04ICCV 2025GitHubA10010
DualDiff: Dual-branch Diffusion Model for Autonomous Driving with Semantic Fusion2025-05ICRA 2025GitHub-3
LD-Scene: LLM-Guided Diffusion for Controllable Generation of Adversarial Safety-Critical Driving Scenarios2025-05arXiv-RTX40907
Dual-Conditioned Temporal Diffusion Modeling for Driving Scene Generation2025-05ICAR 2025GitHubV1001
Diffusion Models for Safety Validation of Autonomous Driving Systems2025-06arXiv-GTX1080Ti1
Diffusion-Based Generation and Imputation of Driving Scenarios from Limited Vehicle CAN Data2025-09ITSC 2025-A1000
Path Diffuser: Diffusion Model for Data-Driven Traffic Simulator2025-09-GitHub-0
3D: Boosting Feed-Forward Driving Scene Generation with Efficient Video Diffusion2025-10NeurIPS 2025 Workshop-H203
VLM as Strategist: Adaptive Generation of Safety-critical Testing Scenarios via Guided Diffusion2025-12arXiv-8x40900
FAR-Drive: Frame-AutoRegressive Video Generation in Closed-Loop Autonomous Driving2026-03arXiv--0
Controllable Latent Diffusion for Traffic Simulation2026-03arXivGitHub-0
ScenarioControl: Vision-Language Controllable Vectorized Latent Scenario Generation2026-04arXivProject-0
DriveCtrl: Conditioned Sim-to-Real Driving Video Generation2026-05arXiv-L400
AnyScene: Towards Highly Controllable Driving Scene Generation at Anywhere and Beyond2026-05arXivProject8xA1000
SafeGen: Goal-Conditioned Video Diffusion of Safety-Critical Scenarios for VLM-Based Autonomous Driving2026-07arXivGitHub-0
One Diffusion Model, Two Roles: Guided Trajectory Planning and Safety-Critical Scenario Generation in Closed-Loop Simulation2026-09arXiv--0
CrashDiffuser: VLM-Guided Collision Intent Reasoning for Fine-Grained Safety-Critical Traffic Scenario Generation2026-09arXiv-H2000
Safety-Critical Scenanrio Emerges from Initial Scene2026-09arXiv--0
Scenario Analysis (Diffusion Models)
PaperDateVenueCodeHardwareCitation
AVD2: Accident Video Diffusion for Accident Video Description2025-03ICRA 2025GitHub-16

🌟 World Models for Autonomous Driving

World Models for Autonomous Driving
PaperDateVenueCodeHardwareCitation
DriveDreamer: Towards Real-world-driven World Models for Autonomous Driving2023-09ECCV 2024GitHubA800376
GAIA-1: A Generative World Model for Autonomous Driving2023-09arXiv Wayve-32xA100428
TrafficBots: Towards World Models for Autonomous Driving Simulation and Motion Prediction2023-09ICRA 2023GitHub6xRTX2080Ti70
Copilot4D: Learning Unsupervised World Models for Autonomous Driving via Discrete Diffusion2023-11ICLR 2024--102
MUVO: A Multimodal Generative World Model for Autonomous Driving with Geometric Representations2023-11IV 2025--4
Driving into the Future: Multiview Visual Forecasting and Planning with World Model for Autonomous Driving2023-11CVPR 2024GitHubA40280
Vista: A Generalizable Driving World Model with High Fidelity and Versatile Controllability2024-03NeurIPS 2024GitHub8xA100181
DriveDreamer-2: LLM-Enhanced World Models for Diverse Driving Video Generation2024-05AAAI 2025GitHubA800162
UniScene: Multi-Camera Unified Pre-training via 3D Scene Reconstruction for Autonomous Driving2024-08RAL 2024GitHub8xA403
WoVoGen: World Volume-aware Diffusion for Controllable Multi-camera Driving Scene Generation2024-08ECCV 2024GitHub8xA600084
Panacea+: Panoramic and Controllable Video Generation for Autonomous Driving2024-08CVPR 2024GitHub-127
DriveArena: A Closed-loop Generative Simulation Platform for Autonomous Driving2024-08arXivGitHub8xA10058
DriveDreamer4D: World Models Are Effective Data Machines for 4D Driving Scene Representation2024-11CVPR 2025GitHubH2066
ReconDreamer: Crafting World Models for Driving Scene Reconstruction via Online Restoration2024-11CVPR 2025GitHub-55
MagicDrive3D: Controllable 3D Generation for Any-View Rendering in Street Scenes2024-11arXivGitHub-56
MagicDrive-V2: High-Resolution Long Video Generation for Autonomous Driving with Adaptive Control2024-11ICCV 2025GitHub8xA80018
ACT-Bench: Towards Action Controllable World Models for Autonomous Driving2024-12arXiv-8xH1007
GEM: A Generalizable Ego-Vision Multimodal World Model for Fine-Grained Ego-Motion, Object Dynamics, and Scene Composition Control2024-12CVPR 2025GitHubH10037
DrivingWorld: Constructing World Model for Autonomous Driving via Video GPT2024-12arXivGitHub32xRTX4090&64xA10041
Driving in the Occupancy World: Vision-Centric 4D Occupancy Forecasting and Planning via World Models for Autonomous Driving2025-01AAAI 2025GitHub8xA10025
MaskGWM: A Generalizable Driving World Model with Video Mask Reconstruction2025-02arXivGitHub32xA80020
Cosmos-Reason1: From Physical Common Sense To Embodied Reasoning2025-03arXivGitHub-57
GAIA-2: A Controllable Multi-View Generative World Model for Autonomous Driving2025-03arXiv-256xH10066
Other Vehicle Trajectories Are Also Needed: A Driving World Model Unifies Ego-Other Vehicle Trajectories in Video Latent Space2025-03arXiv-64xA8005
Seeing the Future, Perceiving the Future: A Unified Driving World Model for Future Generation and Perception2025-03arXivGitHub-5
Cosmos-Transfer1: Conditional World Generation with Adaptive Multimodal Control2025-04arXivGitHub1024xH10033
DriVerse: Navigation World Model for Driving Simulation via Multimodal Trajectory Prompting and Motion Alignment2025-04ACMMM 2025GitHub-6
OccSora: 4D Occupancy Generation Models as World Simulators for Autonomous Driving2025-05arXivGitHub8xA10064
PosePilot: Steering Camera Pose for Generative World Models with Self-supervised Depth2025-05IROS 2025-8xA1002
ProphetDWM: A Driving World Model for Rolling Out Future Actions and Videos2025-05arXiv-4xA1004
ReSim: Reliable World Simulation for Autonomous Driving2025-06arXivGitHub40xA10010
SceneDiffuser++: City-Scale Traffic Simulation via a Generative World Model2025-06CVPR 2025--6
Epona: Autoregressive Diffusion World Model for Autonomous Driving2025-06ICCV 2025GitHub48xA10022
STAGE: A Stream-Centric Generative World Model for Long-Horizon Driving-Scene Simulation2025-06IROS 2025--3
DeepVerse: 4D Autoregressive Video Generation as a World Model2025-06arXivGitHubA10011
World Model-Based End-to-End Scene Generation for Accident Anticipation in Autonomous Driving2025-07Commun EngGitHubRTX40902
HERMES: A Unified Self-Driving World Model for Simultaneous 3D Scene Understanding and Generation2025-08ICCV 2025GitHub32xH2027
Driving scenario generation and evaluation using a structured layer representation and foundational models2025-11arXivGitHubAPI0
GaussianDWM: 3D Gaussian Driving World Model for Unified Scene Understanding and Multi-Modal Generation2025-12CVPR 2026GitHub16xA1000
VistaGEN: Consistent Driving Video Generation with Fine-Grained Control Using Multiview Visual-Language Reasoning2026-03arXiv0
X-World: Controllable Ego-Centric Multi-Camera World Models for Scalable End-to-End Driving2026-03arXivGitHub0
Toward Physically Consistent Driving Video World Models under Challenging Trajectories2026-03arXivGitHub48xH200
DrivingGen: A Comprehensive Benchmark for Generative Video World Models in Autonomous Driving2026-03ICLR2026GitHub0
Composing Driving Worlds through Disentangled Control for Adversarial Scenario Generation2026-03arXivGitHub16xH1000
Bridging Scene Generation and Planning: Driving with World Model via Unifying Vision and Motion Representation2026-03arXivGitHub16xA1000
LMGenDrive: Bridging Multimodal Understanding and Generative World Modeling for End-to-End Driving2026-04arXiv--0
HERMES++: Toward a Unified Driving World Model for 3D Scene Understanding and Generation2026-04arXivGitHub-0
Is Your Driving World Model an All-Around Player? (WorldLens)2026-05arXiv--0
Xiaomi Auto World Model: A Joint World Model Integrating Reconstruction and Generation for Autonomous Driving2026-05arXivProject-0
Diffusion Transformer World-Action Model for AV Scene Prediction2026-06arXivGitHub-0
ReactSim-Bench: Benchmarking Reactive Behavior World Model Simulation in Autonomous Driving2026-06arXivGitHub-0
GaussianDWM++: Language-Grounded 3D Gaussian Driving World Model for Unified Scene Understanding, Editing, and Multi-Modal Generation2026-08arXivGitHub16×A1000
4D-WAM: 4D Consistent World Modeling for Autonomous Driving2026-08arXiv-16×H2000

📊 Datasets Comparison

The following figure shows the usage distribution of different foundation model types across autonomous driving datasets:

Datasets Comparison
DatasetYearImgViewRealLidarRadarTraj3D2DLaneWeatherTimeRegionCompany
CamVid2009RGBFPV✔✖️✖️✖️✖️✔✔✔DU-
KITTI2013RGB/SFPV✔✔✖️✔✔✔✔✔DU/R/H-
Cyclists2016RGBFPV✔✖️✖️✖️✖️✖️✖️✖️DU-
Cityscapes2016RGB/SFPV✔✖️✖️✖️✔✔✔✖️DU-
SYNTHIA2016RGBFPV✖️✖️✖️✖️✔✔✔✔D/NU-
Campus2016RGBBEV✖️✖️✖️✖️✖️✖️✖️✖️DC-
RobotCar2016RGBFPV✔✖️✖️✖️✖️✖️✖️✖️D/NU-
Mapillary2017RGBFPV✔✖️✖️✖️✖️✔✔✔D/NU-
P.F.B.2017RGBFPV✔✖️✖️✖️✖️✔✔✔D/NU-
BDD100K2018RGBFPV✔✖️✖️✖️✔✔✔✔DU/H-
HighD2018RGBBEV✔✖️✖️✖️✖️✔✔✖️DH-
Udacity2018RGBFPV✔✖️✖️✖️✖️✖️✖️✖️DU-
KAIST2018RGB/SFPV✔✔✖️✖️✖️✔✔✔D/NU-
Argoverse2019RGB/SFPV✔✔✖️✖️✖️✔✔✔D/NU-
TRAF2019RGBFPV✔✖️✖️✖️✖️✔✔✔DU-
ApolloScape2019RGB/SFPV✔✖️✖️✖️✔✔✔✔DU-
ACFR2019RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DRA-
H3D2019RGBFPV✔✖️✖️✖️✖️✔✔✔DU-
INTERACTION2019RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DI/RA-
Comma2k192019RGBFPV✔✖️✖️✔✔✖️✖️✖️D/NU/S/R/H-
InD2020RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DI-
RounD2020RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DRA-
nuScenes2020RGBFPV✔✔✔✖️✔✔✔✔D/NU-
Lyft Level 52020RGBFPV✔✔✔✖️✔✔✔✔D/NU/S-
Waymo Open2020RGBFPV✔✔✔✔✔✔✔✔D/NU-
A*3D2020RGBFPV✔✔✔✔✔✔✔✔D/NU-
RobotCar Radar2020RGBFPV✔✔✔✔✔✔✔✔D/NU-
Toronto3D2020RGBBEV✔✔✖️✔✔✖️✔✖️D/NUUniversity of Waterloo
A2D22020RGBFPV✔✔✔✔✔✔✖️✔✔DU/H/S/R
WADS2020RGBFPV✔✔✔✔✔✖️✖️✔D/NU/S/RMichigan Technological University
Argoverse 22021RGB/SFPV✔✔✖️✖️✔✔✔✔D/NU-
PandaSet2021RGBFPV✔✔✔✔✔✔✔✔D/NU-
ONCE2021RGBFPV✔✔✔✔✔✔✔✔D/NU-
Leddar PixSet2021RGBFPV✔✔✖️✔✔✔✖️✔D/NU/S/RLeddar
ZOD2022RGBFPV✔✔✔✔✔✔✔✔D/NU/R/S/HZenseact
IDD-3D2022RGBFPV✔✔✖️✖️✔✔✖️✖️-RINAI
CODA2022RGBFPV✔✔✔✔✔✔✔✔D/NU/S/RHuawei
SHIFT2022RGBFPV✔✔✔✔✔✔✔✔D/NU/S/R/HETH Zürich
DeepAccident2023RGB/SFPV/BEV✖️✔✖️✖️✔✔✔✔D/NU/S/R/HHKU, Huawei, CARLA
Dual_Radar2023RGBFPV✔✔✔✔✔✖️✔✔D/NUTsinghua University
V2V4Real2023RGBFPV✔✔✖️✔✔✖️✔✖️-U/H/SUCLA Mobility Lab
SCaRL2024RGB/SFPV/BEV✖️✔✔✔✔✔✔✔D/NU/S/R/HFraunhofer CARLA
MARS2024RGBFPV✔✔✔✔✔✔✔✔D/NU/S/HNYU, MAY Mobility
Scenes1012024RGBFPV✔✖️✖️✔✖️✖️✔✔D/NU/S/R/HWayve
TruckScenes2025RGBFPV✔✔✔✔✔✖️✔✔D/NH/UMAN

Notes: View: FPV=First-Person, BEV=Bird's-Eye; Time: D=Day, N=Night; Region: U=Urban, R=Rural, H=Highway, S=Suburban, C=Campus, I=Intersection, RA=Road Area; Img: RGB/S=RGB+Stereo

🎮 Simulators

The following figure shows the usage distribution of different foundation model types across autonomous driving simulators:

Simulators
SimulatorYearBack-endOpen SourceRealistic PerceptionCustom ScenarioReal World MapHuman Design MapPython APIC++ APIROS APICompany
TORCS2000None✔✔✔✖️✖️✖️✖️✖️-
Webots2004ODE✔✔✔✔✖️✔✔✖️-
CarRacing2017None✔✖️✖️✖️✔✔✖️✖️-
CARLA2017UE4✔✔✔✖️✔✔✔✔-
SimMobilityST2017None✔✖️✖️✖️✖️✖️✖️✖️-
GTA-V2017RAGE✖️✔✖️✖️✖️✖️✖️✖️-
highway-env2018None✔✖️✔✖️✔✔✖️✖️-
Deepdrive2018UE4✔✔✔✖️✔✔✔✖️-
esmini2018Unity✔✖️✖️✖️✖️✔✖️✖️-
AutonoViSim2018PhysX✖️✔✔✖️✖️✔✖️✖️-
AirSim2018UE4✔✔✔✖️✔✔✔✖️-
SUMO2018None✔✖️✔✔✔✖️✔✖️-
Apollo2018Unity✔✔✔✔✔✔✔✖️-
Sim4CV2018UE4✔✔✔✖️✔✔✖️✖️-
MATLAB2018MATLAB✖️✔✔✔✔✔✔✔Mathworks
Scenic2019None✔✔✔✔✔✔✖️✖️Toyota Research Institute, UC Berkeley
SUMMIT2020UE4✔✔✔✖️✔✔✔✖️-
MultiCarRacing2020None✔✖️✔✖️✔✔✖️✖️-
SMARTS2020None✔✔✔✔✔✔✖️✖️-
LGSVL2020Unity✔✔✔✔✔✔✔✔-
CausalCity2020UE4✔✔✔✔✔✔✖️✖️-
Vista2020None✔✔✔✔✖️✔✖️✖️MIT
MetaDrive2021Panda3D✔✔✔✔✔✔✔✖️-
L2R2021UE4✔✔✔✔✔✔✔✖️-
AutoDRIVE2021Unity✔✔✔✔✔✔✔✔-
Nuplan2021None✔✔✔✔✔✔✖️✖️Motional
AWSIM2021Unity✔✔✔✔✔✖️✖️✔Autoware
InterSim2022None✔✔✔✔✖️✔✖️✖️Tsinghua
Nocturne2022None✔✔✔✔✔✔✔✖️Facebook
BeamNG.tech2022Soft-body physics✖️✔✔✖️✔✔✖️✔BeamNG GmbH
Waymax2023JAX✔✔✔✖️✔✔✖️✖️Waymo
UNISim2023None✖️✔✔✔✖️✖️✔✖️Waabi
TBSim2023None✔✔✔✔✔✔✖️✖️NVIDIA
Nvidia DriveWorks2024Nvidia GPU✖️✔✔✔✖️✔✔✖️NVIDIA

🏆 Foundation Model Benchmark Challenges (2022–2025)

Benchmark Challenges

Autonomous Driving

NameHost
CARLA AD ChallengeCARLA
DRL4RealICCV
Waymo Open Dataset ChallengeWaymo / CVPR WAD
Argoverse 2: Scenario MiningArgoAI
Roboflow-20VLRoboflow-VL / CVPR
AVA ChallengeAVA Challenge Team
NameHost
IGLU ChallengeNeurIPS / IGLU Team
LLM Efficiency ChallengeNeurIPS
Trojan DetectionNeurIPS / CAIS
SMART-101CVPR
NICE ChallengeCVPR / LG Research
SyntaGenCVPR
Habitat ChallengeCVPR / FAIR
BIG-benchGoogle Research
BIG-bench Hard (BBH)Google Research
HELMStanford CRFM
MMBenchOpenCompass
MMMUCVPR / U-Waterloo / OSU
Open LLM LeaderboardVILA-Lab
Text-to-Image LeaderboardArtificial Analysis
Ego4DFAIR
VizWiz Grand ChallengeCVPR VizWiz Workshop
MedFMNeurIPS / Shanghai AI Laboratory
3D Scene UnderstandingCVPR
Common Tools and Frameworks

This section provides links to commonly used tools, frameworks, and resources for working with foundation models in autonomous driving.

Model Repositories and Leaderboards

Model Inference Frameworks

  • vLLM - High-throughput and memory-efficient inference engine for LLMs
  • LMDeploy - Toolkit for compressing, deploying, and serving LLMs
  • Ollama - Run large language models locally
  • Text Generation Inference - Production-ready inference container by Hugging Face
  • TensorRT-LLM - High-performance inference library by NVIDIA

Training and Fine-tuning

Contributing

We welcome contributions from the community! If you have research papers, tools, or resources to add, please create a pull request or open an issue.

License

This repository is released under the Apache 2.0 license.

autonomous-driving
diffusion-models
foundation-models
large-language-models
llms
mllms
multimodal-large-language-models
scenario-analysis
scenario-generation
survey
vision-language-model
vlms
world-models

Contributors

rbrusnicki

64 commits

yuangao-tum

43 commits

TUM-AVS/FM-AD-Survey

[Survey Paper] This repository collects research papers of large Foundation Models for Scenario Generation and Analysis in Autonomous Driving. The repository will be continuously updated to track the latest update.

Python

238

107 commits

updated Sep 20, 2026

See the code

README

Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis :car:

Paper Badge Stars Badge Forks Badge Pull Requests Badge Issues Badge License Badge

This repository will collect research, implementations, and resources related to Foundation Models for Scenario Generation and Analysis in autonomous driving. The repository will be maintained by TUM-AVS (Professorship of Autonomous Vehicle Systems at Technical University of Munich) and will be continuously updated to track the latest work in the community.
:fire: Updates
  • Aug. 2026 – Added 9 new papers on scenario generation* and 11 new papers on scenario analysis*.
  • Jul. 2026 – Added 4 new papers on scenario generation* and 14 new papers on scenario analysis*.
  • Jun. 2026 – Added 33 new papers on scenario analysis* (monthly backlog catch-up spanning Dec 2023 – Jun 2026).
  • May 2026 – Added 7 new papers on scenario generation* and 19 new papers on scenario analysis*.
  • Apr. 2026 – Added 5 new papers on scenario generation* and 13 new papers on scenario analysis*.
  • Mar. 2026 – Added 10 new papers on scenario generation* and 11 new papers on scenario analysis*.
  • Feb. 2026 – Added 4 new papers on scenario generation* and 19 new papers on scenario analysis*.
  • Jan. 2026 – 🎉 Our survey paper is accepted by IEEE Open Journal of Intelligent Transportation Systems (OJ-ITS) and uploaded a new version to arXiv.
  • Dec. 2025 – Added 3 new papers on scenario generation* and 14 new papers on scenario analysis*. Added new columns: Hardware and Citation.
  • Nov. 2025 – Added 2 new papers on scenario analysis*. Added new section: Useful Resources and Links.
  • Uploaded new version to arXiv. Repository now categorizes 348 papers:
    • 93 on scenario generation
    • 56 on scenario analysis
    • 58 on datasets
    • 21 on simulators
    • 25 on benchmark challenges
    • 95 on other related topics (e.g., FMs' implementation)
  • Oct. 2025 – Added 17 new papers on scenario generation* and 2 new papers on scenario analysis*.
  • Sep. 2025 – Added 3 new papers on scenario generation* and 14 new papers on scenario analysis*.
  • Aug. 2025 – Added 4 new papers on scenario generation* and 4 new papers on scenario analysis*.
  • Jul. 2025 – Added 9 new papers on scenario generation* and 8 new papers on scenario analysis*.
  • Jun. 2025 – Released our paper on arXiv. Repository now categorizes 342 papers:
    • 93 on scenario generation
    • 54 on scenario analysis
    • 55 on datasets
    • 21 on simulators
    • 25 on benchmark challenges
    • 94 on other related topics
  • May 2025 – Repository initialized.

🤝   Citation

Please visit Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis for more details and comprehensive information. If you find our paper and repo helpful, please consider citing it as follows:

@ARTICLE{11370877,
  author={Gao, Yuan and Piccinini, Mattia and Zhang, Yuchen and Wang, Dingrui and Moller, Korbinian and Brusnicki, Roberto and Zarrouki, Baha and Gambi, Alessio and Totz, Jan Frederik and Storms, Kai and Peters, Steven and Stocco, Andrea and Alrifaee, Bassam and Pavone, Marco and Betz, Johannes},
  journal={IEEE Open Journal of Intelligent Transportation Systems}, 
  title={Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis}, 
  year={2026},
  volume={},
  number={},
  pages={1-1},
  keywords={Autonomous vehicles;Surveys;Foundation models;Scenario generation;Frequency modulation;Visualization;Reviews;Diffusion models;Adaptation models;Cognition;Autonomous vehicles;foundation model;scenario generation;scenario analysis;scenario based testing},
  doi={10.1109/OJITS.2026.3660686}}

:page_with_curl: Introduction

Foundation models are large-scale, pre-trained models that can be adapted to a wide range of downstream tasks. In the context of autonomous driving, foundation models offer a powerful approach to scenario generation and analysis, enabling more comprehensive and realistic testing, validation, and verification of autonomous driving systems. This repository aims to collect and organize research, tools, and resources in this important field.
:chart_with_upwards_trend: Publication Timeline

The following figure shows the evolution of foundation model research in autonomous driving scenario generation and analysis over time:
:mag: Search Methodology

The following list of keywords was used to search this survey's papers in the Google Scholar database. The keywords were entered either individually or in combination with other keywords in the list. The search was conducted until May 2025.

Keywords:

  • Foundation Model Types: Foundation Models, Large Language Models (LLMs), Vision-Language Models (VLMs), Multimodal Large Language Models (MLLMs), Diffusion Models (DMs), World Models (WMs), Generative Models (GMs)
  • Scenario Generation & Analysis: Scenario Generation, Scenario Simulation, Traffic Simulation, Scenario Testing, Scenario Understanding, Driving Scene Generation, Scene Reasoning, Risk Assessment, Safety-Critical Scenarios, Accident Prediction
  • Application Context: Autonomous Driving, Self-Driving Vehicles, AV Simulation, Driving Video Generation, Traffic Datasets, Closed-Loop Simulation, Safety Assurance

🕒 Timeline of the Development of Foundation Models

The figure illustrates the evolution of foundation models. LLMs (e.g., BERT, GPT) appear at the bottom, followed by VLMs built on visual FMs (e.g., ViT, CLIP) and instruction-tuned VLMs for interactive vision–language reasoning. MLLMs are shown at the top. In parallel, the progression of visual FMs is traced through Diffusion Models (DMs) and World Models (WMs). Highlighted entries mark key conceptual milestones.
🌟 Large Language Models for Autonomous Driving

Scenario Generation (LLM)
PaperDateVenueCodeHardwareCitation
TARGET: Automated Scenario Generation from Traffic Rules for Testing Autonomous Vehicles2023-05IEEE Transactions on Software Engineering-API&RTX409024
Language Conditioned Traffic Generation2023-07CoRL 2023GitHubAPI98
A Generative AI-driven Application: Use of Large Language Models for Traffic Scenario Generation2023-11ELECO 2023-API15
ChatGPT-Based Scenario Engineer: A New Framework on Scenario Generation for Trajectory Prediction2024-02IEEE Transactions on Intelligent Vehicles--48
Enhancing Autonomous Vehicle Training with Language Model Integration and Critical Scenario Generation2024-04arXivGitHubA600024
LLMScenario: Large Language Model Driven Scenario Generation2024-05IEEE Transactions on Systems, Man, and Cybernetics: Systems-API69
Automatic Generation Method for Autonomous Driving Simulation Scenarios Based on Large Language Model2024-05AIAT 2024-API2
ChatScene: Knowledge-Enabled Safety-Critical Scenario Generation for Autonomous Vehicles2024-05CVPR 2024GitHubAPI113
Editable scene simulation for autonomous driving via collaborative llm-agents2024-06CVPR 2024GitHubAPI130
Chat2Scenario: Scenario Extraction From Dataset Through Utilization of Large Language Model2024-06IV 2024GitHub-15
SoVAR: Building Generalizable Scenarios from Accident Reports for Autonomous Driving Testing2024-09ASE 2024-RTX407029
LeGEND: A Top-Down Approach to Scenario Generation of Autonomous Driving Systems Assisted by Large Language Models2024-09ASE 2024GitHubRTX309032
Traffic Scene Generation from Natural Language Description for Autonomous Vehicles with Large Language Model2024-09arXivGitHubAPI18
Promptable Closed-loop Traffic Simulation2024-09CoRL 2024GitHubA10016
Multimodal Large Language Model Driven Scenario Testing for Autonomous Vehicles2024-09Automotive Innovation--26
LLM-Driven Testing for Autonomous Driving Scenarios2024-11FLLM 2024-API& T415
ChatSUMO: Large Language Model for Automating Traffic Scenario Generation in Simulation of Urban MObility2024-11IEEE Transactions on Intelligent Vehicles-RTX409054
Generating Out-Of-Distribution Scenarios Using Language Models2024-11arXiv-API13
Generating Traffic Scenarios via In-Context Learning to Learn Better Motion Planner2024-12AAAI 2025 OralGitHubRTX 30903
LLM-attacker: Enhancing Closed-loop Adversarial Scenario Generation for Autonomous Driving with Large Language Models2025-01TITS 2025-RTX 400025
ML-SceGen: A Multi-level Scenario Generation Framework2025-01arXiv-RTX 40900
From Words to Collisions: LLM-Guided Evaluation and Adversarial Generation of Safety-Critical Driving Scenarios2025-02ITSC 2025GitHubAPI3
CurricuVLM: Towards Safe Autonomous Driving via Personalized Safety-Critical Curriculum Learning with Vision-Language Models2025-02arXivGitHub-10
Text2Scenario: Text-Driven Scenario Generation for Autonomous Driving Test2025-03arXivGitHub-14
Enhancing Autonomous Driving Safety with Collision Scenario Integration2025-03arXiv-8xV1006
Seeking to Collide: Online Safety-Critical Scenario Generation for Autonomous Driving with Retrieval Augmented Large Language Models2025-05ITSC 2025-API5
From Failures to Fixes: LLM-Driven Scenario Repair for Self-Evolving Autonomous Driving2025-05arXiv-RTX40900
AGENTS-LLM: Augmentative GENeration of Challenging Traffic Scenarios with an Agentic LLM Framework2025-07arXiv-API1
LLM-based Realistic Safety-Critical Driving Video Generation2025-07arXiv-RTX40901
Adversarial Generation and Collaborative Evolution of Safety-Critical Scenarios for Autonomous Vehicles2025-08arXivGitHub2xRTX40900
LLM-based Human-like Traffic Simulation for Self-driving Tests2025-08arXiv-API& A8000
Conversational Code Generation: a Case Study of Designing a Dialogue System for Generating Driving Scenarios for Testing Autonomous Vehicles2025-09GeCoIn 2025-A60003
Txt2Sce: Scenario Generation for Autonomous Driving System Testing Based on Textual Reports2025-09arXiv-RTX3070Ti1
LLM‑Based Semantic Modeling & Cooperative Evolutionary Fuzzing2025-09APSEC 2025--0
LinguaSim: Interactive Multi-Vehicle Testing Scenario Generation via Natural Language Instruction Based on Large Language Models2025-10IEEE ITSC 2025--0
Learning from Risk: LLM-Guided Generation of Safety-Critical Scenarios with Prior Knowledge2025-11arXivGitHub-0
AnchorDrive: LLM Scenario Rollout with Anchor-Guided Diffusion Regeneration for Safety-Critical Scenario Generation2026-03arXiv--0
TRACE: Topology-aware Reconstruction of Accidents in CARLA for AV Evaluation2026-04FSE 2026GitHubAPI0
Traffic Scenario Orchestration from Language via Constraint Satisfaction2026-05arXiv--0
PCASim: Promptable Closed-loop Adversarial Simulation for Urban Traffic Environment2026-05arXivProject-0
TrafficAlign: Aligning Large Language Models for Traffic Scenario Generation2026-06CVPR 2026GitHub-0
REARL: A Closed-loop Autonomous Driving Simulation Enhancement Framework with Real Traffic Data and Large Language Models2026-09arXiv--0
LLM-Guided Transformation of Non-Critical Driving Scenes into Safety-Critical Scenarios Using Augmented Reality2026-09arXiv--0
SimSkill: A Self-Evolving LLM Agent for Skill and Knowledge Accumulation in Traffic Simulation2026-09arXivGitHubM1 Max & API0
PlannerForge: LLM Agents for Scenario-Based Testing of Motion Planners in Autonomous Driving2026-09EMNLP 2026GitHubRTX5090 & API0
Scenario Analysis (LLM)
PaperDateVenueCodeHardwareCitation
Semantic Anomaly Detection with Large Language Models2023-09Autonomous Robots--131
LaMPilot: An Open Benchmark Dataset for Autonomous Driving with Language Model Programs2023-12CVPR 2024GitHub-0
Hybrid Reasoning Based on Large Language Models for Autonomous Car Driving2024-02arXivGitHub-0
Reality Bites: Assessing the Realism of Driving Scenarios with Large Language Models2024-03IEEE/ACM First International Conference on AI Foundation Models and Software Engineering (Forge)GitHubAPI22
Driving with LLMs: Fusing Object-Level Vector Modality for Explainable Autonomous Driving2024-05ICRA 2024GitHubAPI340
Bench4Merge: A Comprehensive Benchmark for Merging in Realistic Dense Traffic with Micro-Interactive Vehicles2024-10arXivGitHub-0
SenseRAG: Constructing Environmental Knowledge Bases with Proactive Querying for LLM-Based Autonomous Driving2025-012025 WACVW-API9
From Words to Collisions: LLM-Guided Evaluation and Adversarial Generation of Safety-Critical Driving Scenarios2025-02ITSC 2025GitHubAPI3
A Comprehensive LLM-powered Framework for Driving Intelligence Evaluation2025-03ICRA 2025GitHubAPI7
Understanding Driving Risks using Large Language Models: Toward Elderly Driver Assessment2025-07arXiv--0
Collision risk prediction and takeover requirements assessment based on radar-video integrated sensors data: A system framework based on LLM2025-08Accident Analysis & Prevention-API&RTX40907
Evaluation of Large Language Models for Anomaly Detection in Autonomous Vehicles2025-09arXiv--0
AgentDrive: An open benchmark suite for agentic AI reasoning in autonomous systems2026-01arXivGitHub-0
LLM-MLFFN: Multi-Level Autonomous Driving Behavior Feature Fusion via Large Language Model2025-03arXiv--0
Towards Lawful Autonomous Driving: Deriving Scenario-Aware Driving Requirements from Traffic Laws and Regulations2026-04arXiv--0
SwarmDrive: Semantic V2V Coordination for Latency-Constrained Cooperative Autonomous Driving2026-04arXiv--0
Pedestrian-Aware LLM-Driven Behavioral Planning for Autonomous Vehicles2026-05IEEE ITSC 2026--0
AutoMine Solution for AV2 2026 Scenario Mining Challenge2026-06arXiv--0
A knowledge-augmented dataset of high-risk driving scenarios with LLM annotations for autonomous driving2026-07arXivGitHub-0
SAFARI: An Industrial Benchmark for LLM-Assisted Hazard Analysis and Risk Assessment2026-09arXivGitHubAPI0

🌟 Vision-Language Models for Autonomous Driving

Scenario Generation (VLM)
Scenario Analysis (VLM)
PaperDateVenueCodeHardwareCitation
Unsupervised 3D Perception with 2D Vision-Language Distillation for Autonomous Driving2023-09ICCV 2023--49
OpenAnnotate3D: Open-Vocabulary Auto-Labeling System for Multi-modal 3D Data2023-10ICRA 2024GitHubAPI&RTX409019
On the Road with GPT-4V(ision): Early Explorations of Visual-Language Model on Autonomous Driving2023-11ICIL 2024 Workshop on Large Language Models for AgentsGitHub-105
Talk2BEV: Language-enhanced Bird's-eye View Maps for Autonomous Driving2023-11ICRA 2024GitHubA100114
LLM Multimodal Traffic Accident Forecasting2023-11Sensors 2023 MDPI--98
NuScenes-MQA: Integrated Evaluation of Captions and QA for Autonomous Driving Datasets using Markup Annotations2024-01WACVW LLVM-AD 2024GitHub8xA10035
Is it safe to cross? Interpretable Risk Assessment with GPT-4V for Safety-Aware Street Crossing2024-02UR 2024--22
Multi-Frame, Lightweight & Efficient Vision-Language Models for Question Answering in Autonomous Driving2024-03VLADR 2024GitHubRTX 3090Ti&V10055
Embodied Understanding of Driving Scenarios (ELM)2024-03ECCV 2024GitHub-0
LATTE: A Real-time Lightweight Attention-based Traffic Accident Anticipation Engine2024-04Information Fusion (Elsevier)-RTX40803
OmniDrive: A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning2024-05CVPR 2025GitHub-47
Hard Cases Detection in Motion Prediction by Vision-Language Foundation Models2024-05arXivGitHub-0
Reason2Drive: Towards Interpretable and Chain-based Reasoning for Autonomous Driving2024-06ECCV 2024GitHub8xV100118
ConnectGPT: Connect Large Language Models with Connected and Automated Vehicles2024-06IV 2024--21
SimpleLLM4AD: An End-to-End Vision-Language Model with Graph Visual Question Answering for Autonomous Driving2024-07arXiv--14
Large Language Models Powered Context-aware Motion Prediction in Autonomous Driving2024-07IROS 2024GitHubAPI13
DriveGenVLM: Real-world Video Generation for Vision Language Model based Autonomous Driving2024-08IAVVC 2024-L413
V2X-VLM: End-to-End V2X Cooperative Autonomous Driving Through Large Vision-Language Models2024-08arXiv-RTX409046
Multi-Frame Vision-Language Model for Long-form Reasoning in Driver Behavior Analysis2024-08arXiv--0
Think-Driver: From Driving-Scene Understanding to Decision-Making with Vision Language Models2024-09ECCV 2024 Workshop-4xRTX40904
Can LVLMs Obtain a Driver's License? A Benchmark Towards Reliable AGI for Autonomous Driving2024-09AAAI 2025Project-0
ContextVLM: Zero-Shot and Few-Shot Context Understanding for Autonomous Driving using Vision Language Models2024-09arXivGitHub-0
Efficient Driving Behavior Narration and Reasoning on Edge Device Using Large Language Models2024-09arXiv--0
VLM-Auto: VLM-based Autonomous Driving Assistant with Human-like Behavior and Understanding for Complex Road Scenes2024-10FLLM 2024GitHubRTX409041
Visual Adversarial Attack on Vision-Language Models for Autonomous Driving2024-11arXiv-A80019
Automated Evaluation of Large Vision-Language Models on Self-driving Corner Cases2024-12WACV 2025GitHub8xA80033
SFF Rendering-Based Uncertainty Prediction using VisionLLM2024-12AAAI 2025 Workshop LM4Plan-A1003
AutoTrust: Benchmarking Trustworthiness in Large Vision Language Models for Autonomous Driving2024-12arXivGitHub-0
Are VLMs Ready for Autonomous Driving? An Empirical Study from the Reliability, Data, and Metric Perspectives2025-01ICCV 2025GitHub8xA80028
Enhancing Large Vision Model in Street Scene Semantic Understanding through Leveraging Posterior Optimization Trajectory2025-01arXiv-2xRTX40907
Enhancing Vision-Language Models with Scene Graphs for Traffic Accident Understanding2025-01IAVVC 2024--15
DriveLM: Driving with Graph Visual Question Answering2025-01ECCV 2024GitHub8xV100473
Scenario Understanding of Traffic Scenes Through Large Visual Language Models2025-01WACV 2025-A1007
Application of Vision-Language Model to Pedestrian Behavior and Scene Understanding in Autonomous Driving2025-01arXiv--0
INSIGHT: Enhancing Autonomous Driving Safety through Vision-Language Models on Context-Aware Hazard Detection and Edge Case Evaluation2025-02arXiv-A60008
Evaluating Multimodal Vision-Language Model Prompting Strategies for Visual Question Answering in Road Scene Understanding2025-02WACV workshop 2025-RTX409014
Vision-Integrated LLMs for Autonomous Driving Assistance: Human Performance Comparison and Trust Evaluation2025-02arXiv--0
NuGrounding: A Multi-View 3D Visual Grounding Framework in Autonomous Driving2025-03arXiv--4
Fine-Grained Evaluation of Large Vision-Language Models in Autonomous Driving2025-03ICCV 2025GitHub8xV10010
AutoDrive-QA- Automated Generation of Multiple-Choice Questions for Autonomous Driving Datasets Using Large Vision-Language Models2025-03arXivGitHub3xA60004
DriveLMM-o1: A Step-by-Step Reasoning Dataset and Large Multimodal Model for Driving Scenario Understanding2025-03arXivGitHub4xA600020
ORION: A Holistic End-to-End Autonomous Driving Framework by Vision-Language Instructed Action Generation2025-03arXivGitHub32xA80050
ChatBEV: A Visual Language Model that Understands BEV Maps2025-03arXiv--2
Robusto-1 Dataset: Comparing Humans and VLMs on real out-of-distribution Autonomous Driving VQA from Peru2025-03arXivGitHubA100&API2
Evaluation of Safety Cognition Capability in Vision-Language Models for Autonomous Driving2025-03arXiv--0
ST-VLM: Kinematic Instruction Tuning for Spatio-Temporal Reasoning in Vision-Language Models2025-03arXivProject-0
Retrieval-Based Interleaved Visual Chain-of-Thought in Real-World Driving Scenarios2025-04arXivGitHub4xA1006
ReasonDrive: Efficient Visual Question Answering for Autonomous Vehicles with Reasoning-Enhanced Small Vision-Language Models2025-04arXivGitHub-0
Vision Foundation Model Embedding-Based Semantic Anomaly Detection2025-05ICRA 2025 Workshop--3
OpenLKA: An Open Dataset of Lane Keeping Assist from Recent Car Models under Real-world Driving Conditions2025-05arXivGitHub-3
SURDS: Benchmarking Spatial Understanding and Reasoning in Driving Scenarios with Vision Language Models2025-05NeurIPS 2025GitHub8xA8006
Extending Large Vision-Language Model for Diverse Interactive Tasks in Autonomous Driving2025-05arXivGitHub8xA8005
Bridging Human Oversight and Black-box Driver Assistance: Vision-Language Models for Predictive Alerting in Lane Keeping Assist systems2025-05arXiv--3
AgentThink: A Unified Framework for Tool-Augmented Chain-of-Thought Reasoning in Vision-Language Models for Autonomous Driving2025-05EMNLP Findings 2025GitHub-0
FutureSightDrive: Thinking Visually with Spatio-Temporal CoT for Autonomous Driving2025-06NeurIPS 2025-8xA600065
Case-based Reasoning Augmented Large Language Model Framework for Decision Making in Realistic Safety-Critical Driving Scenarios2025-06arXiv-API1
Structured Labeling Enables Faster Vision-Language Models for End-to-End Autonomous Driving2025-06arXiv-8xRTX40902
DriveAction: A Benchmark for Exploring Human-like Driving Decisions in VLA Models2025-06arXivDataset-0
Box-QAymo: Box-Referring VQA Dataset for Autonomous Driving2025-07arXivGitHub-0
DriveMRP: Enhancing Vision-Language Models with Synthetic Motion Data for Motion Risk Prediction2025-07arXivGitHub8xH1000
SafeDriveRAG: Towards Safe Autonomous Driving with Knowledge Graph-based Retrieval-Augmented Generation2025-07ACMMM 2025GitHub-3
DRAMA-X: A Fine-grained Intent Prediction and Risk Reasoning Benchmark For Driving2025-08arXivGitHub-2
NuRisk: A Visual Question Answering Dataset for Agent-Level Risk Assessment in Autonomous Driving2025-09ICRA-API&RTX50901
DriveAgent-R1: Advancing VLM-based Autonomous Driving with Active Perception and Hybrid Thinking2025-09arXiv-API&8xH201
Enhancing Vision-Language Models for Autonomous Driving through Task-Specific Prompting and Spatial Reasoning2025-09IROS 2025 RoboSenseGitHubAPI0
Are VLMs Ready for Lane Topology Awareness in Autonomous Driving?2025-09arXiv--0
More Than Meets the Eye? Uncovering the Reasoning-Planning Disconnect in Training Vision-Language Driving Models2025-10arXiv--0
STRIDE-QA: Visual Question Answering Dataset for Spatiotemporal Reasoning in Urban Driving Scenes2025-10AAAI 2026GitHub16xH1003
VLR-Driver: Large Vision-Language-Reasoning Models for Embodied Autonomous Driving2025-10ICCV 2025--0
Hierarchical Reasoning with Vision-Language Models for Incident Reports from Dashcam Videos2025-10arXivGitHub-0
WaymoQA: A Multi-View Visual Question Answering Dataset for Safety-Critical Reasoning in Autonomous Driving2025-11arXiv-8xA60000
A TOOL FOR BENCHMARKING LARGE LANGUAGE MODELS’ ROBUSTNESS IN ASSESSING THE REALISM OF DRIVING SCENARIOS2025-11arXiv-API0
V2X-VLM: End-to-End V2X Cooperative Autonomous Driving Through Large Vision-Language Models2025-11arXiv-RTX 409049
RoadBench: Benchmarking MLLMs on Fine-Grained Spatial Understanding and Reasoning under Urban Road Scenarios2025-11arXivGitHub-0
Is Your VLM for Autonomous Driving Safety-Ready? A Comprehensive Benchmark for Evaluating External and In-Cabin Risks2025-11arXiv--0
Toward Automatic Safe Driving Instruction: A Large-Scale Vision Language Model Approach2025-11arXiv--0
RoadSceneVQA: Benchmarking Visual Question Answering in Roadside Perception Systems for Intelligent Transportation System2025-12arXivGitHub4xA1000
OmniDrive-R1: Reinforcement-driven Interleaved Multi-modal Chain-of-Thought for Trustworthy Vision-Language Autonomous Driving2025-12arXiv-16xA8000
Counterfactual VLA: Self-Reflective Vision-Language-Action Model with Adaptive Reasoning2025-12CVPR 2026--0
Semantic-Drive: Democratizing Long-Tail Data Curation via Open-Vocabulary Grounding and Neuro-Symbolic VLM Consensus2025-12arXivGitHub-0
Vision-Based Natural Language Scene Understanding for Autonomous Driving: An Extended Dataset and a New Model for Traffic Scene Description Generation2026-01arXiv-A1000
AutoDriDM: An Explainable Benchmark for Decision-Making of Vision-Language Models in Autonomous Driving2026-01arXiv-A1000
ScenePilot-Bench: A Large-Scale Dataset and Benchmark for Evaluation of Vision-Language Models in Autonomous Driving 2026-01arXivGitHub4xA8000
Vision and Language: Novel Representations and Artificial intelligence for Driving Scene Safety Assessment and Autonomous Vehicle Planning2026-02arXiv--0
DRIV-EX: Counterfactual Explanations for Driving LLMs2026-02arXiv-20xA1000
DriveCombo: Benchmarking Compositional Traffic Rule Reasoning in Autonomous Driving2026-03arXiv--0
DriveCode: Domain Specific Numerical Encoding for LLM-Based Autonomous Driving2026-03arXiv-8xH1000
Probing Visual Concepts in Lightweight Vision-Language Models for Automated Driving2026-03arXivGitHub-0
BEVLM: Distilling Semantic Knowledge from LLMs into Bird’s-Eye View Representations2026-03arXiv-8xH1000
Perception-Aware Multimodal Spatial Reasoning from Monocular Images2026-03arXiv-8xH1000
Comparative Analysis of Patch Attack on VLM-Based Autonomous Driving Architectures2026-03arXivIV 2025-0
More than the Sum: Panorama-Language Models for Adverse Omni-Scenes2026-03CVPR2026-https://github.com/InSAI-Lab/PanoVQA0
Probing the Reliability of Driving VLMs: From Inconsistent Responses to Grounded Temporal Reasoning2026-03arXiv-4xA1000
Are Video Reasoning Models Ready to Go Outside?2026-03arXivGitHub4xA1000
WorldVLM: Combining World Model Forecasting and Vision-Language Reasoning2026-03arXiv-4xA400
VLM-AutoDrive: Post-Training Vision-Language Models for Safety-Critical Autonomous Driving Events2026-03arXiv-32xH1000
KLDrive: Fine-Grained 3D Scene Reasoning for Autonomous Driving based on Knowledge Graph2026-03arXiv-A60000
DRIVINGVQA: A Dataset for Interleaved Visual Chain-of-Thought in Real-World Driving Scenarios2026-03ECAL 2026GitHub4xA1000
3DCity-LLM: Empowering Multi-modality Large Language Models for 3D City-scale Perception and Understanding2026-03arXivGitHubA1000
Collision-Aware Vision-Language Learning for End-to-End Driving with Multimodal Infraction Datasets2026-03arXiv--0
Dual-Stage LLM Framework for Scenario-Centric Semantic Interpretation in Driving Assistance2026-03arXiv--0
A Semantic Observer Layer for Autonomous Vehicles: Pre-Deployment Feasibility Study of VLMs for Low-Latency Anomaly Detection2026-03arXiv-50900
How Well Do Vision-Language Models Understand Sequential Driving Scenes? A Sensitivity Study (VENUSS)2026-04arXiv-API0
BATON: A Multimodal Benchmark for Bidirectional Automation Transition Observation in Naturalistic Driving2026-04arXiv-API0
CrashSight: A Phase-Aware, Infrastructure-Centric Video Benchmark for Traffic Crash Scene Understanding and Reasoning2026-04arXiv-8xA1000
VAGNet: Vision-based Accident Anticipation with Global Features2026-04arXiv-RTX40900
SignReasoner: Compositional Reasoning for Complex Traffic Sign Understanding via Functional Structure Units2026-04arXiv-4xH1000
CCTVBench: Contrastive Consistency Traffic VideoQA Benchmark for Multimodal LLMs2026-04arXiv-API0
Towards Safe Mobility: A Unified Transportation Foundation Model enabled by Open-Ended Vision-Language Dataset (UniVLT / LTD)2026-04arXiv-8xH1000
EgoDyn-Bench: Evaluating Ego-Motion Understanding in Vision-Centric Foundation Models for Autonomous Driving2026-04arXiv-API0
Zoom In, Reason Out: Efficient Far-field Anomaly Detection in Expressway Surveillance Videos via Focused VLM Reasoning Guided by Bayesian Inference (VIBES)2026-04arXiv-RTX40900
VLM-VPI: A Vision-Language Reasoning Framework for Improving Automated Vehicle-Pedestrian Interactions2026-04arXiv-API0
HiDrive: A Closed-Loop Benchmark for High-Level Autonomous Driving2026-05arXivGitHub-0
Bench2Drive-VL: Benchmarks for Closed-Loop Autonomous Driving with Vision-Language Models2026-04arXivGitHub-0
Bridging Structure and Language: Graph-Based Visual Reasoning for Autonomous Road Understanding2026-05arXiv--0
C-CoT: Counterfactual Chain-of-Thought with Vision-Language Models for Safe Autonomous Driving2026-05arXiv--0
D2-V2X: Depth-Driven Cooperative V2X Reasoning for Autonomous Driving2026-05arXivGitHub-0
DRIVESPATIAL: A Benchmark for Spatiotemporal Intelligence in VLMs for Autonomous Driving2026-05NeurIPS 2026Project-0
PEDESTRIANQA: A Benchmark for Vision-Language Models on Pedestrian Intention and Trajectory Prediction2026-05arXivGitHub-0
ReasonBreak: Probing Vulnerabilities in Reasoning-Enabled Vision-Language-Action Models for Autonomous Driving2026-05arXiv--0
Two-Pass Zero-Shot Temporal-Spatial Grounding of Rare Traffic Events in Surveillance Video2026-05arXiv--0
nuReasoning: A Reasoning-Centric Dataset and Benchmark for Long-Tail Autonomous Driving2026-05arXivProject-0
Vision-Language Work Zone Intelligence for Safety-Critical Speed Regulation of Mixed-Autonomy Vehicles in Dynamic Environments2026-06arXivGitHub-0
Multi-Stage VLM Pipeline for Zero-Shot Traffic Accident Understanding2026-05arXivGitHub-0
DriveJudge: Rethinking Autonomous Driving Evaluation with Vision-Language Models2026-06arXiv--0
GeoDrive-Bench: Benchmarking Region-Specific Multimodal Reasoning in Autonomous Driving2026-06arXivGitHub-0
Metadata-Aware Multi-Prompt Reasoning for Zero-Shot Accident Understanding2026-06arXiv--0
Robusto-2: Benchmarking Humans & VLMs for Autonomous Driving in Lima & New York City2026-06arXiv--0
AUTOPILOT VQA: Benchmarking Vision-Language Models for Incident-Centric Dashcam Understanding2026-07arXiv--0
DispatchRAG: Grounding Emergency Dispatch Decisions in Real-World Protocols from Traffic Accident Video2026-07arXiv--0
Reasoning to Regulate: Chain-of-Thought for Traffic Rule Understanding2026-07arXiv--0
CAViAR: A Causal Video Dataset for Fine-Grained Accident Reasoning in Real-World Scenarios2026-08arXivGitHub-0
Observe Before You Alert: Adaptive Driver Alerting with Vision-Language Models2026-09arXiv-RTX50900
CrossView: Can Vision-Language Models Reason Across Cameras?2026-08arXivGitHubAPI0
SIREN-Bench: Behavior-Driven Generation and Evaluation of Emergency-Vehicle Interactions2026-08arXiv-V100S0

🌟 Multimodal Large Language Models for Autonomous Driving

Scenario Generation (MLLM)

| OmniTraffic: A Controllable Generation Pipeline and Benchmark for Spatio-Temporal Traffic Reasoning | 2026-06 | arXiv | - | - | 0 |

Scenario Analysis (MLLM)
PaperDateVenueCodeHardwareCitation
DriveGPT4: Interpretable End-to-end Autonomous Driving via Large Language Model2023-10IEEE Robotics and Automation Letters 2024GitHub-615
Dolphins: Multimodal Language Model for Driving2023-12ECCV 2024GitHub4xA100139
AccidentGPT: Accident analysis and prevention from V2X Environmental Perception with Multi-modal Large Model2023-12IV 2024GitHub-45
Lidar-llm: Exploring the potential of large language models for 3d lidar understanding2023-12AAAI 2025GitHubA100125
LingoQA: Visual Question Answering for Autonomous Driving2023-12ECCV 2024GitHub8xA100143
Holistic Autonomous Driving Understanding by Bird's-Eye-View Injected Multi-Modal Large Models2024-01CVPR 2024GitHub-106
MAPLM: A Real-World Large-Scale Vision-Language Benchmark for Map and Traffic Scene Understanding2024-01CVPR 2024GitHub8xV100&2xA10065
Probing Multimodal LLMs as World Models for Driving2024-05arXiv--0
WTS: A Pedestrian-Centric Traffic Video Dataset for Fine-Grained Spatial-Temporal Understanding2024-06ECCV 2024GitHub-19
Semantic Understanding of Traffic Scenes with Large Vision Language Models2024-06IV 2024GitHubAPI27
VLAAD: Vision and Language Assistant for Autonomous Driving2024-06WACVW 2024GitHub-52
InternDrive: A Multimodal Large Language Model for Autonomous Driving Scenario Understanding2024-07AIAHPC 2024-API4
WOMD-Reasoning: A Large-Scale Dataset for Interaction Reasoning in Driving2024-07ICML 2025GitHub-0
Using Multimodal Large Language Models for Automated Detection of Traffic Safety Critical Events2024-09Vehicles 2024 MDPI-API10
MLLM-SUL: Multimodal Large Language Model for Semantic Scene Understanding and Localization in Traffic Scenarios2024-12arXivGitHubA8007
Application of Multimodal Large Language Models in Autonomous Driving2024-12arXiv--0
Distilling Multi-modal Large Language Models for Autonomous Driving2025-01CVPR 2025--23
TB-Bench: Training and Testing Multi-Modal AI for Understanding Spatio-Temporal Traffic Behaviors from Dashcam Images/Videos2025-01arXivGitHub-0
TUMTraffic-VideoQA: A Benchmark for Unified Spatio-Temporal Video Understanding in Traffic Scenes2025-02ICML 2025GitHub4xA10013
ScVLM: Enhancing Vision-Language Model for Safety-Critical Event Understanding2025-02WACV Workshop 2025GitHub2xA1008
Sce2DriveX: A Generalized MLLM Framework for Scene-to-Drive Learning2025-02IEEE RAL-8xL2018
A Framework for a Capability-driven Evaluation of Scenario Understanding for Multimodal Large Language Models in Autonomous Driving2025-03arXiv--1
HiLM-D: Enhancing MLLMs with Multi-Scale High-Resolution Details for Autonomous Driving2025-03International Journal of Computer Vision-8xV10068
NuPlanQA: A Large-Scale Dataset and Benchmark for Multi-View Driving Scene Understanding in Multi-Modal Large Language Models2025-03ICCV 2025GitHub-8
Tracking Meets Large Multimodal Models for Driving Scenario Understanding2025-03arXivGitHub2xA60004
SimLingo: Vision-Only Closed-Loop Autonomous Driving with Language-Action Alignment2025-03CVPR 2025GitHub8xA10034
V3LMA: Visual 3D-enhanced Language Model for Autonomous Driving2025-04CVPR DriveX 2025GitHubH1003
Are Vision LLMs Road-Ready? A Comprehensive Benchmark for Safety-Critical Driving Video Understanding2025-04arXivGitHub-7
V2V-LLM: Vehicle-to-Vehicle Cooperative Autonomous Driving with Multi-Modal Large Language Models2025-04arXivGitHub8xA10022
ALN-P3: Unified Language Alignment for Perception, Prediction, and Planning in Autonomous Driving2025-05arXiv-2xH2003
DriveSOTIF: Advancing SOTIF Through Multimodal Large Language Models2025-05arXivGitHub-0
X-Driver: Explainable Autonomous Driving with Vision-Language Models2025-06arXiv--5
STSBench: A Spatio-temporal Scenario Benchmark for Multi-modal Large Language Models in Autonomous Driving2025-06NeurIPS 2025GitHub-2
SafePLUG: Empowering Multimodal LLMs with Pixel-Level Insight and Temporal Grounding for Traffic Accident Understanding2025-08arXiv-8xA1002
RoboTron-Drive: All-in-One Large Multimodal Model for Autonomous Driving2025-08ICCV2025GitHub32xA1009
Passing the Driving Knowledge Test (DriveQA)2025-08ICCV 2025--0
EMMA: End-to-End Multimodal Model for Autonomous Driving2025-09TMLR--161
Investigating Traffic Accident Detection Using Multimodal Large Language Models2025-09IAVVC 2025--1
AccidentBench: Benchmarking Multimodal Understanding and Reasoning in Vehicle Accidents and Beyond2025-09arXivGitHub-0
Addressing Corner Cases in Autonomous Driving: A World Model-based Approach with Mixture of Experts and LLMs2025-10Transportation Research Part C: Emerging Technologies-40900
BeLLA: End-to-End Birds Eye View Large Language Assistant for Autonomous Driving2025-12arXiv-4xH1000
MMDrive: Interactive Scene Understanding Beyond Vision with Multi-representational Fusion2025-12arXiv--0
Wild-Drive: Off-Road Scene Captioning and Path Planning via Robust Multi-modal Routing and Efficient Large Language Model2026-02arXiv-40900
DriveXQA: Cross-modal Visual Question Answering for Adverse Driving Scene Understanding2026-03arXivGitHub4xA1000
Interpretable Traffic Responsibility from Dashcam Video via Legal Multi-Agent Reasoning2026-03arXiv--0
ExpressMind: A Multimodal Pretrained Large Language Model for Expressway Operation2026-03arXivGitHub8xH200
AITP: Traffic Accident Responsibility Allocation via Multimodal Large Language Models2026-04CVPR 2026 Findings-8xA1000
XEmbodied: A Foundation Model with Enhanced Geometric and Physical Cues for Large-Scale Embodied Environments2026-04arXiv--0
V2X-QA: A Comprehensive Reasoning Dataset and Benchmark for MLLMs in Autonomous Driving Across Ego, Infrastructure, and Cooperative Views2026-04arXivGitHub-0
DriveSafe: A Framework for Risk Detection and Safety Suggestions in Driving Scenarios2026-05arXiv--0
Enhancing Multimodal Large Language Models for Safety-Critical Driving Video Analysis2026-05arXiv--0
GuardAD: Safeguarding Autonomous Driving MLLMs via Markovian Safety Logic2026-05arXiv--0
Where Does the Answer Come From? Benchmarking View-Level Visual Evidence Identification in Multi-View MLLMs for Autonomous Driving2026-06arXiv--0
OmniSpace: Efficient Geometry Awareness for Autonomous Vehicles MLLMs2026-06arXiv--0
Beyond Scene Priors: Fine-Grained Traffic Scene Reasoning with Benchmarking and Query-Guided Small-Object Focus2026-07arXiv--0
D3VL: Understanding Driving Scenes from 3D Time Series Data and Video with Language Models2026-07arXivProject-0
Sim-to-Real Traffic Scene Understanding by Decoupling Semantics from Caption Generation with V-JEPA2026-09arXivGitHubRTX60000
Inter-3D VQA: A Roadside Multimodal Benchmark for 3D Spatiotemporally Grounded Visual Question Answering2026-08arXivGitHub4×RTX Pro 60000
UniTraffic-Agent: Unified Traffic Video Reasoning for AI City Challenge 2026 Track 3 with Two Out-of-Domain Evaluations2026-08arXivGitHubAPI0
CASCADE: A Spatio-Temporal-Causal Reasoning Representation and Dataset for Driving2026-09arXiv--0
From Detection to Understanding: TAR and TAR-Bench for Multi-Task Traffic Anomaly Reasoning2026-08arXiv-8×A1000
Drive the Thoughts: Runtime Monitoring of VLA Reasoning-Trajectory Consistency2026-08arXivGitHubA100 & API0

🌟 Diffusion Models for Autonomous Driving

Scenario Generation (Diffusion Models)
PaperDateVenueCodeHardwareCitation
Guided Conditional Diffusion for Controllable Traffic Simulation2022-10ICRA 2023GitHub-223
Generating Driving Scenes with Diffusion2023-05ICRA Workshop--25
DiffScene: Guided Diffusion Models for Safety-Critical Scenario Generation2023-06AdvML-Frontiers 2023-RTX309076
BEVControl: Accurately Controlling Street-view Elements with Multi-perspective Consistency via BEV Sketch Layout2023-09arXiv--45
DriveSceneGen: Generating Diverse and Realistic Driving Scenarios From Scratch2023-09IEEE Robotics and Automation Letters 2024GitHub4xV10022
MagicDrive: Street View Generation with Diverse 3D Geometry Control2023-10ICLR 2024GitHubV100219
DrivingDiffusion: Layout-Guided multi-view driving scene video generation with latent diffusion model2023-10ECCV 2024GitHub8xA10080
Language-guided traffic simulation via scene-level diffusion2023-11CoRL 2023-RTX 3090121
Scenario Diffusion: Controllable Driving Scenario Generation With Diffusion2023-11NeurIPS 2023-2xA600064
Panacea: Panoramic and Controllable Video Generation for Autonomous Driving2023-11CVPR 2024GitHub-127
SAFE-SIM: Safety-Critical Closed-Loop Traffic Simulation with Diffusion-Controllable Adversaries2023-12ECCV 2024GitHub4xA600028
Text2Street: Controllable Text-to-image Generation for Street Views2024-02ICPR 2024--12
ChatTraffic: Text-to-Traffic Generation via Diffusion Model2024-02IEEE Transactions on Intelligent Transportation SystemsGitHubRTX409019
GEODIFFUSION: Text-Prompted Geometric Control for Object Detection Data Generation2024-02LCLR 2024GitHub-56
GenDDS: Generating Diverse Driving Video Scenarios with Prompt-to-Video Generative Model2024-04ITSC 2024-RTX3090Ti6
Versatile Behavior Diffusion for Generalized Traffic Agent Simulation2024-04RSS 2024GitHub8xL4013
SceneControl: Diffusion for Controllable Traffic Scene Generation2024-05ICRA 2024--33
SLEDGE: Synthesizing Driving Environments with Generative Models and Rule-Based Traffic2024-07ECCV 2024GitHub-24
DrivingGen: Efficient Safety-Critical Driving Video Generation with Latent Diffusion Models2024-07ICME 2024--9
Controllable Traffic Simulation through LLM-Guided Hierarchical Chain-of-Thought Reasoning2024-09IROS 2025--7
AdvDiffuser: Generating Adversarial Safety-Critical Driving Scenarios via Guided Diffusion2024-10IROS 2024-4xRTX309021
Data-driven Diffusion Models for Enhancing Safety in Autonomous Vehicle Traffic Simulations2024-10arXiv--4
DiffRoad: Realistic and Diverse Road Scenario Generation for Autonomous Vehicle Testing2024-11arXiv--7
SceneDiffuser: Efficient and Controllable Driving Simulation Initialization and Rollout2024-12NeurIPS 2024--48
Direct Preference Optimization-Enhanced Multi-Guided Diffusion Model for Traffic Scenario Generation2025-02arXiv--2
Causal Composition Diffusion Model for Closed-loop Traffic Generation2025-02CVPR 2025GitHub4xV10011
Rolling Ahead Diffusion for Traffic Scene Simulation2025-02AAAI 2025 Workshop-V1002
AVD2: Accident Video Diffusion for Accident Video Description2025-03ICRA 2025GitHub-16
DualDiff+: Dual-Branch Diffusion for High-Fidelity Video Generation with Reward Guidance2025-03arXivGitHub8xA8004
Scenario Dreamer: Vectorized Latent Diffusion for Generating Driving Simulation Environments2025-03CVPR 2025GitHub8xA10016
DriveGen: Towards Infinite Diverse Traffic Scenarios with Large Models2025-03arXiv--4
DiVE: Efficient Multi-View Driving Scenes Generation Based on Video Diffusion Transformer2025-04arXiv-8xA8004
Decoupled Diffusion Sparks Adaptive Scene Generation2025-04ICCV 2025GitHubA10010
DualDiff: Dual-branch Diffusion Model for Autonomous Driving with Semantic Fusion2025-05ICRA 2025GitHub-3
LD-Scene: LLM-Guided Diffusion for Controllable Generation of Adversarial Safety-Critical Driving Scenarios2025-05arXiv-RTX40907
Dual-Conditioned Temporal Diffusion Modeling for Driving Scene Generation2025-05ICAR 2025GitHubV1001
Diffusion Models for Safety Validation of Autonomous Driving Systems2025-06arXiv-GTX1080Ti1
Diffusion-Based Generation and Imputation of Driving Scenarios from Limited Vehicle CAN Data2025-09ITSC 2025-A1000
Path Diffuser: Diffusion Model for Data-Driven Traffic Simulator2025-09-GitHub-0
3D: Boosting Feed-Forward Driving Scene Generation with Efficient Video Diffusion2025-10NeurIPS 2025 Workshop-H203
VLM as Strategist: Adaptive Generation of Safety-critical Testing Scenarios via Guided Diffusion2025-12arXiv-8x40900
FAR-Drive: Frame-AutoRegressive Video Generation in Closed-Loop Autonomous Driving2026-03arXiv--0
Controllable Latent Diffusion for Traffic Simulation2026-03arXivGitHub-0
ScenarioControl: Vision-Language Controllable Vectorized Latent Scenario Generation2026-04arXivProject-0
DriveCtrl: Conditioned Sim-to-Real Driving Video Generation2026-05arXiv-L400
AnyScene: Towards Highly Controllable Driving Scene Generation at Anywhere and Beyond2026-05arXivProject8xA1000
SafeGen: Goal-Conditioned Video Diffusion of Safety-Critical Scenarios for VLM-Based Autonomous Driving2026-07arXivGitHub-0
One Diffusion Model, Two Roles: Guided Trajectory Planning and Safety-Critical Scenario Generation in Closed-Loop Simulation2026-09arXiv--0
CrashDiffuser: VLM-Guided Collision Intent Reasoning for Fine-Grained Safety-Critical Traffic Scenario Generation2026-09arXiv-H2000
Safety-Critical Scenanrio Emerges from Initial Scene2026-09arXiv--0
Scenario Analysis (Diffusion Models)
PaperDateVenueCodeHardwareCitation
AVD2: Accident Video Diffusion for Accident Video Description2025-03ICRA 2025GitHub-16

🌟 World Models for Autonomous Driving

World Models for Autonomous Driving
PaperDateVenueCodeHardwareCitation
DriveDreamer: Towards Real-world-driven World Models for Autonomous Driving2023-09ECCV 2024GitHubA800376
GAIA-1: A Generative World Model for Autonomous Driving2023-09arXiv Wayve-32xA100428
TrafficBots: Towards World Models for Autonomous Driving Simulation and Motion Prediction2023-09ICRA 2023GitHub6xRTX2080Ti70
Copilot4D: Learning Unsupervised World Models for Autonomous Driving via Discrete Diffusion2023-11ICLR 2024--102
MUVO: A Multimodal Generative World Model for Autonomous Driving with Geometric Representations2023-11IV 2025--4
Driving into the Future: Multiview Visual Forecasting and Planning with World Model for Autonomous Driving2023-11CVPR 2024GitHubA40280
Vista: A Generalizable Driving World Model with High Fidelity and Versatile Controllability2024-03NeurIPS 2024GitHub8xA100181
DriveDreamer-2: LLM-Enhanced World Models for Diverse Driving Video Generation2024-05AAAI 2025GitHubA800162
UniScene: Multi-Camera Unified Pre-training via 3D Scene Reconstruction for Autonomous Driving2024-08RAL 2024GitHub8xA403
WoVoGen: World Volume-aware Diffusion for Controllable Multi-camera Driving Scene Generation2024-08ECCV 2024GitHub8xA600084
Panacea+: Panoramic and Controllable Video Generation for Autonomous Driving2024-08CVPR 2024GitHub-127
DriveArena: A Closed-loop Generative Simulation Platform for Autonomous Driving2024-08arXivGitHub8xA10058
DriveDreamer4D: World Models Are Effective Data Machines for 4D Driving Scene Representation2024-11CVPR 2025GitHubH2066
ReconDreamer: Crafting World Models for Driving Scene Reconstruction via Online Restoration2024-11CVPR 2025GitHub-55
MagicDrive3D: Controllable 3D Generation for Any-View Rendering in Street Scenes2024-11arXivGitHub-56
MagicDrive-V2: High-Resolution Long Video Generation for Autonomous Driving with Adaptive Control2024-11ICCV 2025GitHub8xA80018
ACT-Bench: Towards Action Controllable World Models for Autonomous Driving2024-12arXiv-8xH1007
GEM: A Generalizable Ego-Vision Multimodal World Model for Fine-Grained Ego-Motion, Object Dynamics, and Scene Composition Control2024-12CVPR 2025GitHubH10037
DrivingWorld: Constructing World Model for Autonomous Driving via Video GPT2024-12arXivGitHub32xRTX4090&64xA10041
Driving in the Occupancy World: Vision-Centric 4D Occupancy Forecasting and Planning via World Models for Autonomous Driving2025-01AAAI 2025GitHub8xA10025
MaskGWM: A Generalizable Driving World Model with Video Mask Reconstruction2025-02arXivGitHub32xA80020
Cosmos-Reason1: From Physical Common Sense To Embodied Reasoning2025-03arXivGitHub-57
GAIA-2: A Controllable Multi-View Generative World Model for Autonomous Driving2025-03arXiv-256xH10066
Other Vehicle Trajectories Are Also Needed: A Driving World Model Unifies Ego-Other Vehicle Trajectories in Video Latent Space2025-03arXiv-64xA8005
Seeing the Future, Perceiving the Future: A Unified Driving World Model for Future Generation and Perception2025-03arXivGitHub-5
Cosmos-Transfer1: Conditional World Generation with Adaptive Multimodal Control2025-04arXivGitHub1024xH10033
DriVerse: Navigation World Model for Driving Simulation via Multimodal Trajectory Prompting and Motion Alignment2025-04ACMMM 2025GitHub-6
OccSora: 4D Occupancy Generation Models as World Simulators for Autonomous Driving2025-05arXivGitHub8xA10064
PosePilot: Steering Camera Pose for Generative World Models with Self-supervised Depth2025-05IROS 2025-8xA1002
ProphetDWM: A Driving World Model for Rolling Out Future Actions and Videos2025-05arXiv-4xA1004
ReSim: Reliable World Simulation for Autonomous Driving2025-06arXivGitHub40xA10010
SceneDiffuser++: City-Scale Traffic Simulation via a Generative World Model2025-06CVPR 2025--6
Epona: Autoregressive Diffusion World Model for Autonomous Driving2025-06ICCV 2025GitHub48xA10022
STAGE: A Stream-Centric Generative World Model for Long-Horizon Driving-Scene Simulation2025-06IROS 2025--3
DeepVerse: 4D Autoregressive Video Generation as a World Model2025-06arXivGitHubA10011
World Model-Based End-to-End Scene Generation for Accident Anticipation in Autonomous Driving2025-07Commun EngGitHubRTX40902
HERMES: A Unified Self-Driving World Model for Simultaneous 3D Scene Understanding and Generation2025-08ICCV 2025GitHub32xH2027
Driving scenario generation and evaluation using a structured layer representation and foundational models2025-11arXivGitHubAPI0
GaussianDWM: 3D Gaussian Driving World Model for Unified Scene Understanding and Multi-Modal Generation2025-12CVPR 2026GitHub16xA1000
VistaGEN: Consistent Driving Video Generation with Fine-Grained Control Using Multiview Visual-Language Reasoning2026-03arXiv0
X-World: Controllable Ego-Centric Multi-Camera World Models for Scalable End-to-End Driving2026-03arXivGitHub0
Toward Physically Consistent Driving Video World Models under Challenging Trajectories2026-03arXivGitHub48xH200
DrivingGen: A Comprehensive Benchmark for Generative Video World Models in Autonomous Driving2026-03ICLR2026GitHub0
Composing Driving Worlds through Disentangled Control for Adversarial Scenario Generation2026-03arXivGitHub16xH1000
Bridging Scene Generation and Planning: Driving with World Model via Unifying Vision and Motion Representation2026-03arXivGitHub16xA1000
LMGenDrive: Bridging Multimodal Understanding and Generative World Modeling for End-to-End Driving2026-04arXiv--0
HERMES++: Toward a Unified Driving World Model for 3D Scene Understanding and Generation2026-04arXivGitHub-0
Is Your Driving World Model an All-Around Player? (WorldLens)2026-05arXiv--0
Xiaomi Auto World Model: A Joint World Model Integrating Reconstruction and Generation for Autonomous Driving2026-05arXivProject-0
Diffusion Transformer World-Action Model for AV Scene Prediction2026-06arXivGitHub-0
ReactSim-Bench: Benchmarking Reactive Behavior World Model Simulation in Autonomous Driving2026-06arXivGitHub-0
GaussianDWM++: Language-Grounded 3D Gaussian Driving World Model for Unified Scene Understanding, Editing, and Multi-Modal Generation2026-08arXivGitHub16×A1000
4D-WAM: 4D Consistent World Modeling for Autonomous Driving2026-08arXiv-16×H2000

📊 Datasets Comparison

The following figure shows the usage distribution of different foundation model types across autonomous driving datasets:
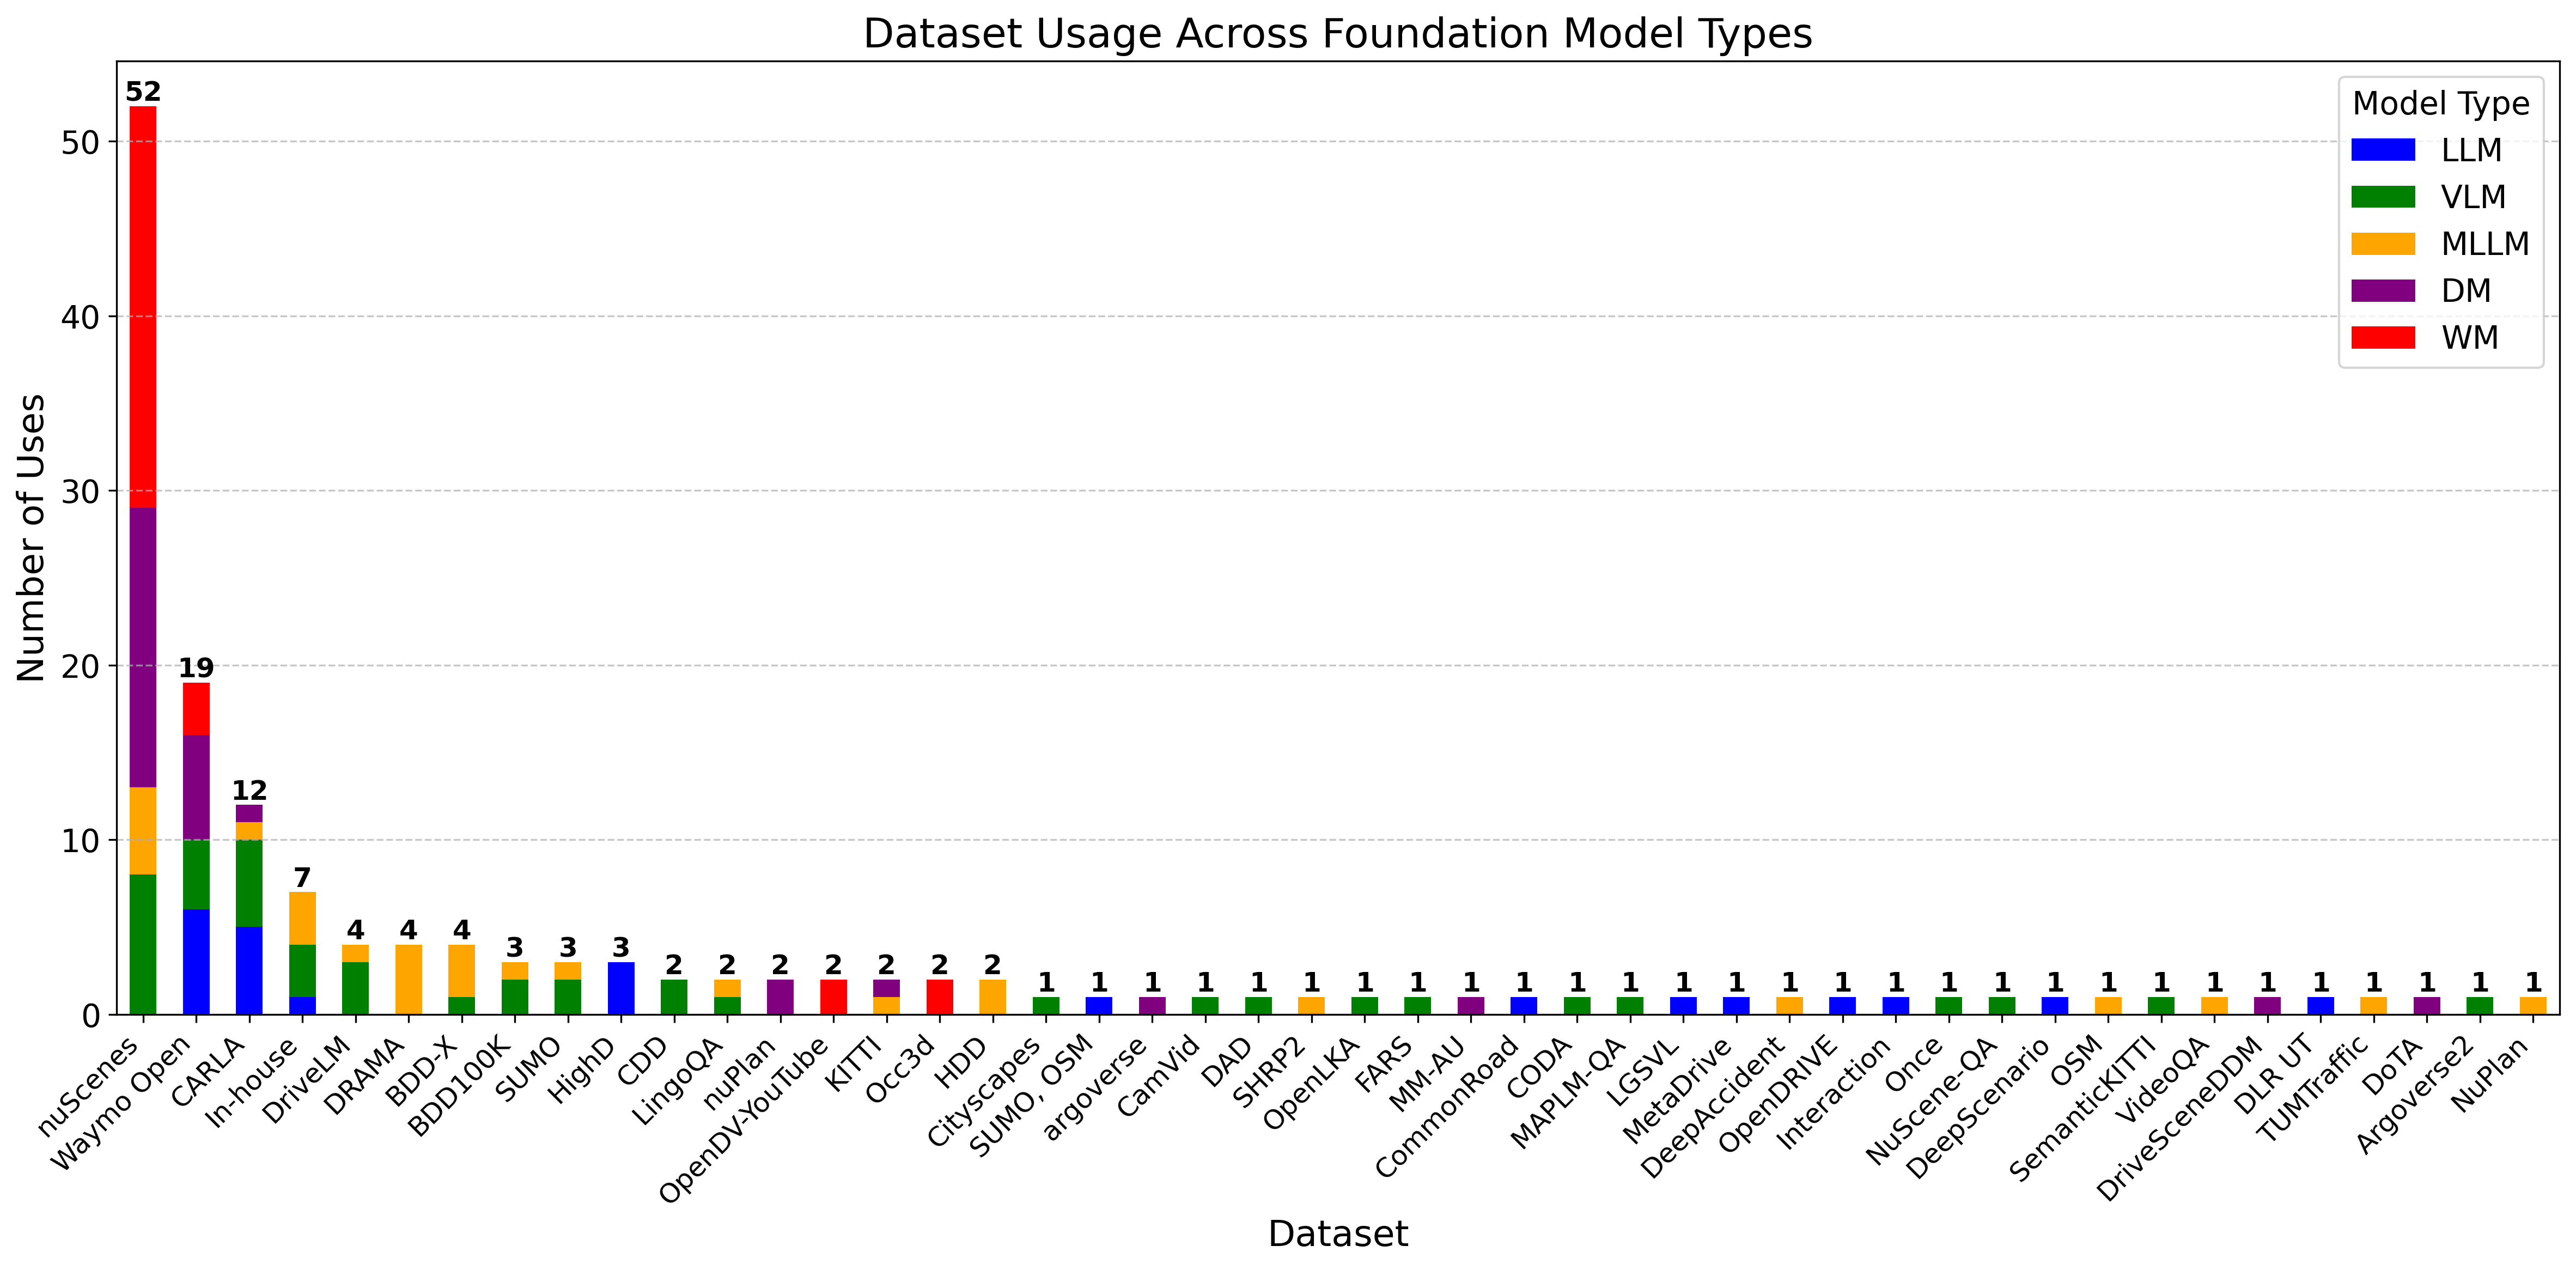
Datasets Comparison
DatasetYearImgViewRealLidarRadarTraj3D2DLaneWeatherTimeRegionCompany
CamVid2009RGBFPV✔✖️✖️✖️✖️✔✔✔DU-
KITTI2013RGB/SFPV✔✔✖️✔✔✔✔✔DU/R/H-
Cyclists2016RGBFPV✔✖️✖️✖️✖️✖️✖️✖️DU-
Cityscapes2016RGB/SFPV✔✖️✖️✖️✔✔✔✖️DU-
SYNTHIA2016RGBFPV✖️✖️✖️✖️✔✔✔✔D/NU-
Campus2016RGBBEV✖️✖️✖️✖️✖️✖️✖️✖️DC-
RobotCar2016RGBFPV✔✖️✖️✖️✖️✖️✖️✖️D/NU-
Mapillary2017RGBFPV✔✖️✖️✖️✖️✔✔✔D/NU-
P.F.B.2017RGBFPV✔✖️✖️✖️✖️✔✔✔D/NU-
BDD100K2018RGBFPV✔✖️✖️✖️✔✔✔✔DU/H-
HighD2018RGBBEV✔✖️✖️✖️✖️✔✔✖️DH-
Udacity2018RGBFPV✔✖️✖️✖️✖️✖️✖️✖️DU-
KAIST2018RGB/SFPV✔✔✖️✖️✖️✔✔✔D/NU-
Argoverse2019RGB/SFPV✔✔✖️✖️✖️✔✔✔D/NU-
TRAF2019RGBFPV✔✖️✖️✖️✖️✔✔✔DU-
ApolloScape2019RGB/SFPV✔✖️✖️✖️✔✔✔✔DU-
ACFR2019RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DRA-
H3D2019RGBFPV✔✖️✖️✖️✖️✔✔✔DU-
INTERACTION2019RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DI/RA-
Comma2k192019RGBFPV✔✖️✖️✔✔✖️✖️✖️D/NU/S/R/H-
InD2020RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DI-
RounD2020RGBBEV✔✖️✖️✖️✖️✖️✖️✖️DRA-
nuScenes2020RGBFPV✔✔✔✖️✔✔✔✔D/NU-
Lyft Level 52020RGBFPV✔✔✔✖️✔✔✔✔D/NU/S-
Waymo Open2020RGBFPV✔✔✔✔✔✔✔✔D/NU-
A*3D2020RGBFPV✔✔✔✔✔✔✔✔D/NU-
RobotCar Radar2020RGBFPV✔✔✔✔✔✔✔✔D/NU-
Toronto3D2020RGBBEV✔✔✖️✔✔✖️✔✖️D/NUUniversity of Waterloo
A2D22020RGBFPV✔✔✔✔✔✔✖️✔✔DU/H/S/R
WADS2020RGBFPV✔✔✔✔✔✖️✖️✔D/NU/S/RMichigan Technological University
Argoverse 22021RGB/SFPV✔✔✖️✖️✔✔✔✔D/NU-
PandaSet2021RGBFPV✔✔✔✔✔✔✔✔D/NU-
ONCE2021RGBFPV✔✔✔✔✔✔✔✔D/NU-
Leddar PixSet2021RGBFPV✔✔✖️✔✔✔✖️✔D/NU/S/RLeddar
ZOD2022RGBFPV✔✔✔✔✔✔✔✔D/NU/R/S/HZenseact
IDD-3D2022RGBFPV✔✔✖️✖️✔✔✖️✖️-RINAI
CODA2022RGBFPV✔✔✔✔✔✔✔✔D/NU/S/RHuawei
SHIFT2022RGBFPV✔✔✔✔✔✔✔✔D/NU/S/R/HETH Zürich
DeepAccident2023RGB/SFPV/BEV✖️✔✖️✖️✔✔✔✔D/NU/S/R/HHKU, Huawei, CARLA
Dual_Radar2023RGBFPV✔✔✔✔✔✖️✔✔D/NUTsinghua University
V2V4Real2023RGBFPV✔✔✖️✔✔✖️✔✖️-U/H/SUCLA Mobility Lab
SCaRL2024RGB/SFPV/BEV✖️✔✔✔✔✔✔✔D/NU/S/R/HFraunhofer CARLA
MARS2024RGBFPV✔✔✔✔✔✔✔✔D/NU/S/HNYU, MAY Mobility
Scenes1012024RGBFPV✔✖️✖️✔✖️✖️✔✔D/NU/S/R/HWayve
TruckScenes2025RGBFPV✔✔✔✔✔✖️✔✔D/NH/UMAN

Notes: View: FPV=First-Person, BEV=Bird's-Eye; Time: D=Day, N=Night; Region: U=Urban, R=Rural, H=Highway, S=Suburban, C=Campus, I=Intersection, RA=Road Area; Img: RGB/S=RGB+Stereo

🎮 Simulators

The following figure shows the usage distribution of different foundation model types across autonomous driving simulators:
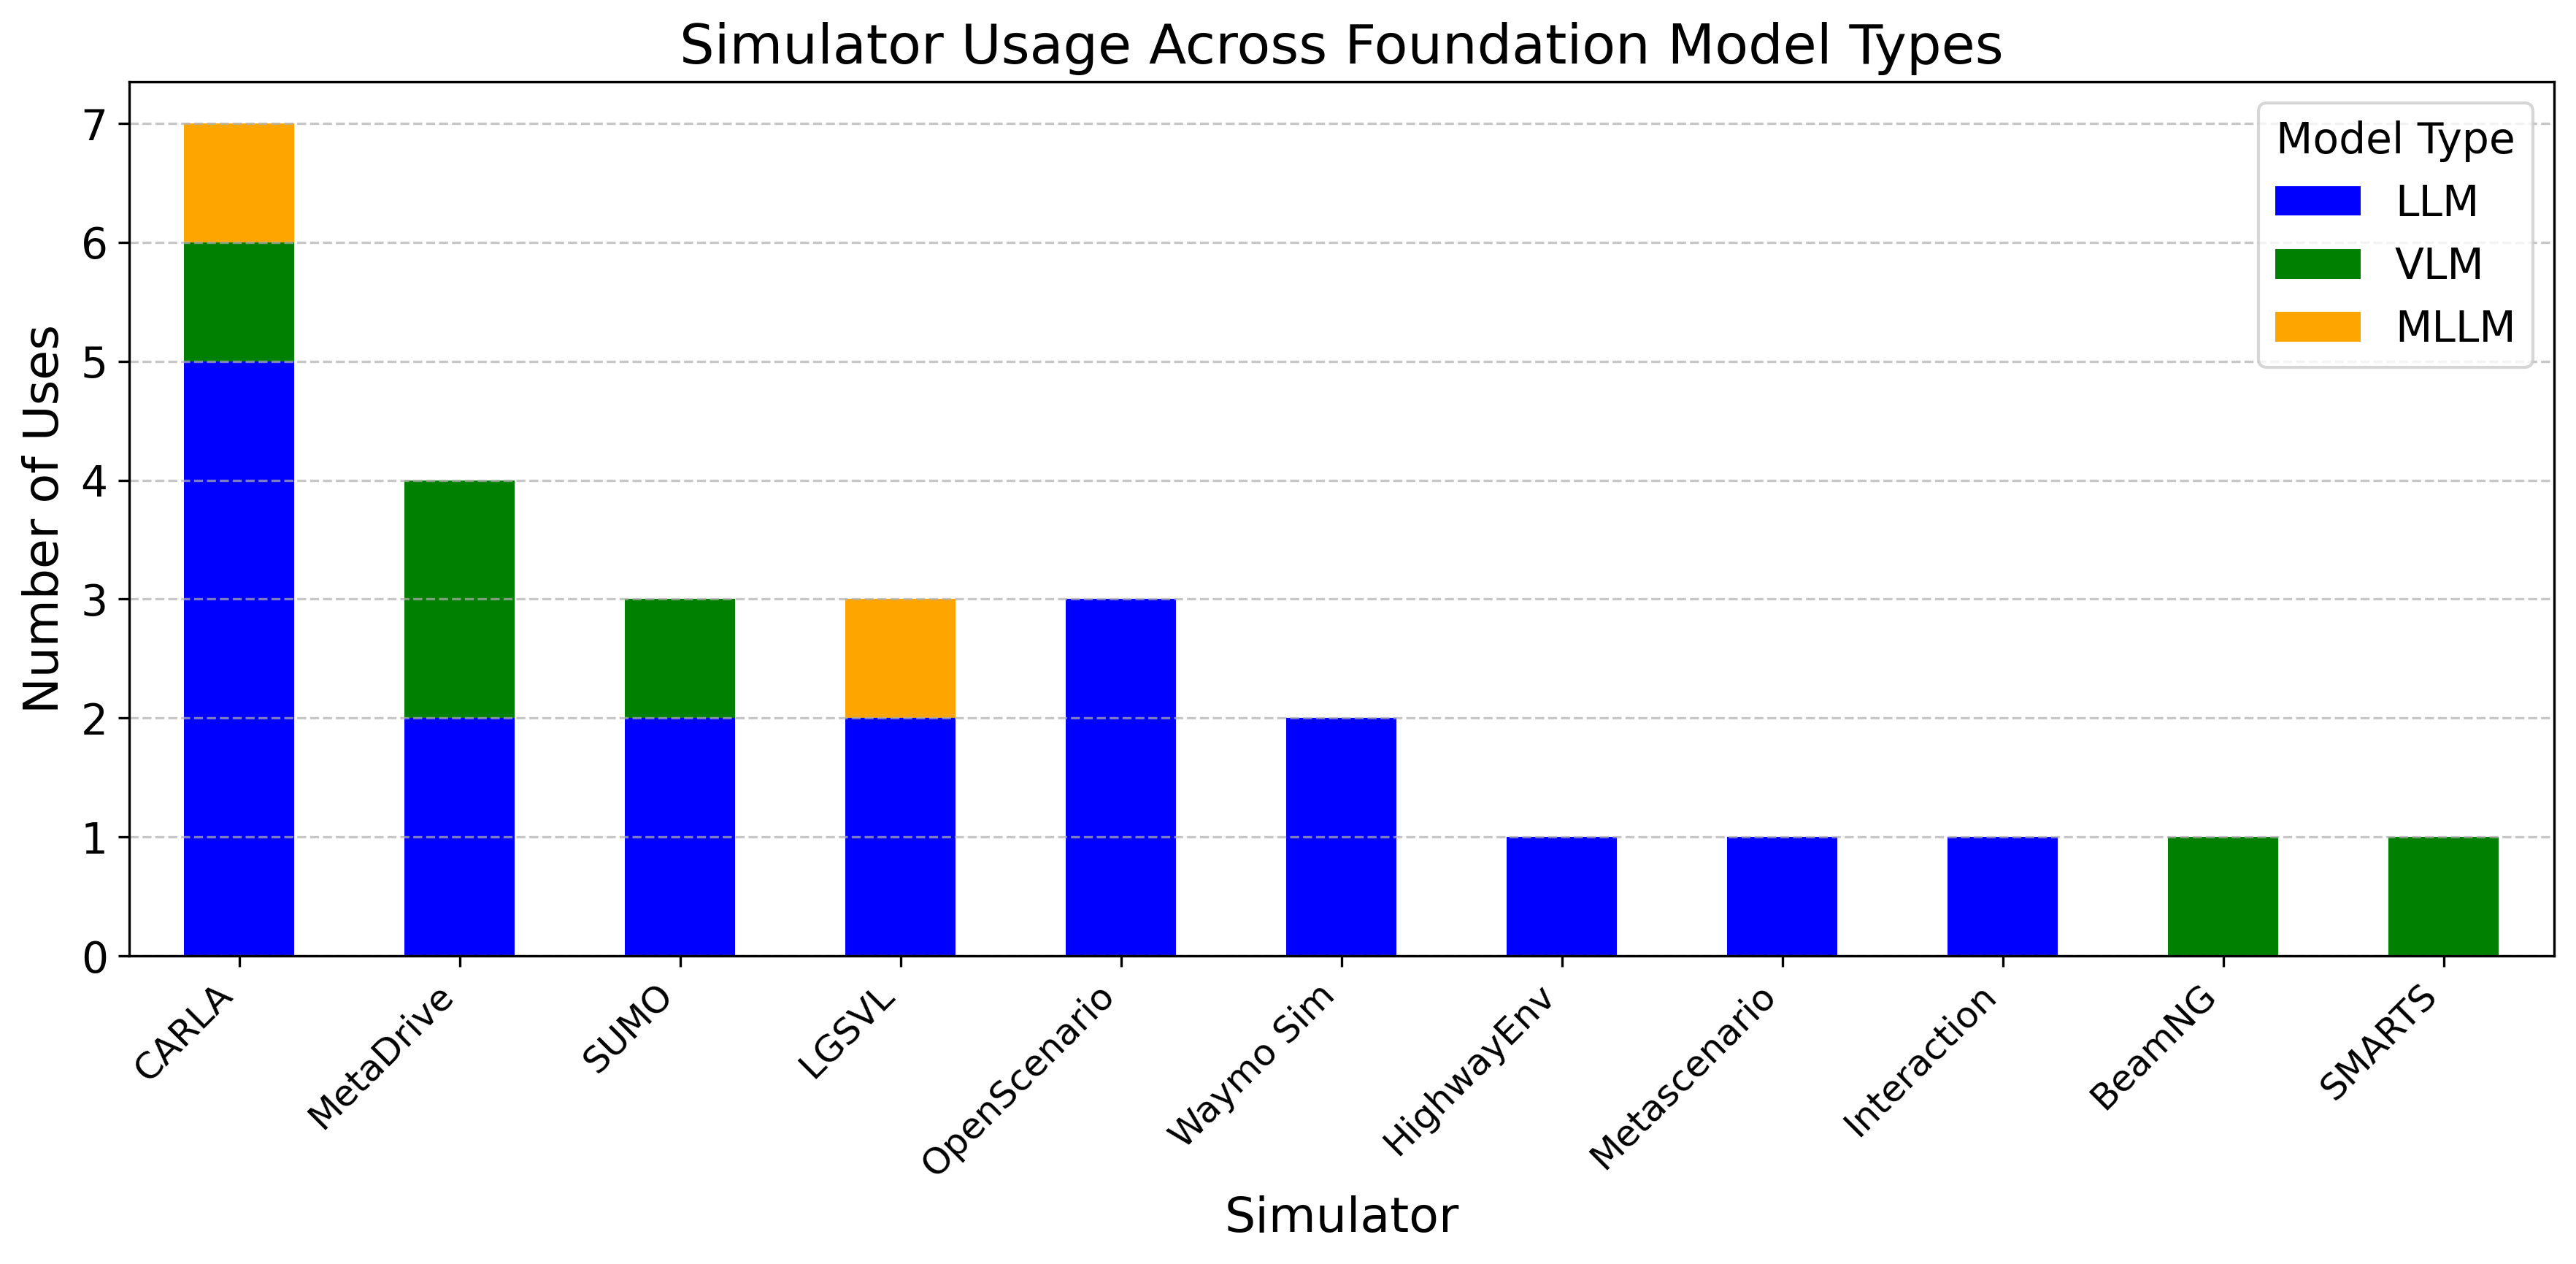
Simulators
SimulatorYearBack-endOpen SourceRealistic PerceptionCustom ScenarioReal World MapHuman Design MapPython APIC++ APIROS APICompany
TORCS2000None✔✔✔✖️✖️✖️✖️✖️-
Webots2004ODE✔✔✔✔✖️✔✔✖️-
CarRacing2017None✔✖️✖️✖️✔✔✖️✖️-
CARLA2017UE4✔✔✔✖️✔✔✔✔-
SimMobilityST2017None✔✖️✖️✖️✖️✖️✖️✖️-
GTA-V2017RAGE✖️✔✖️✖️✖️✖️✖️✖️-
highway-env2018None✔✖️✔✖️✔✔✖️✖️-
Deepdrive2018UE4✔✔✔✖️✔✔✔✖️-
esmini2018Unity✔✖️✖️✖️✖️✔✖️✖️-
AutonoViSim2018PhysX✖️✔✔✖️✖️✔✖️✖️-
AirSim2018UE4✔✔✔✖️✔✔✔✖️-
SUMO2018None✔✖️✔✔✔✖️✔✖️-
Apollo2018Unity✔✔✔✔✔✔✔✖️-
Sim4CV2018UE4✔✔✔✖️✔✔✖️✖️-
MATLAB2018MATLAB✖️✔✔✔✔✔✔✔Mathworks
Scenic2019None✔✔✔✔✔✔✖️✖️Toyota Research Institute, UC Berkeley
SUMMIT2020UE4✔✔✔✖️✔✔✔✖️-
MultiCarRacing2020None✔✖️✔✖️✔✔✖️✖️-
SMARTS2020None✔✔✔✔✔✔✖️✖️-
LGSVL2020Unity✔✔✔✔✔✔✔✔-
CausalCity2020UE4✔✔✔✔✔✔✖️✖️-
Vista2020None✔✔✔✔✖️✔✖️✖️MIT
MetaDrive2021Panda3D✔✔✔✔✔✔✔✖️-
L2R2021UE4✔✔✔✔✔✔✔✖️-
AutoDRIVE2021Unity✔✔✔✔✔✔✔✔-
Nuplan2021None✔✔✔✔✔✔✖️✖️Motional
AWSIM2021Unity✔✔✔✔✔✖️✖️✔Autoware
InterSim2022None✔✔✔✔✖️✔✖️✖️Tsinghua
Nocturne2022None✔✔✔✔✔✔✔✖️Facebook
BeamNG.tech2022Soft-body physics✖️✔✔✖️✔✔✖️✔BeamNG GmbH
Waymax2023JAX✔✔✔✖️✔✔✖️✖️Waymo
UNISim2023None✖️✔✔✔✖️✖️✔✖️Waabi
TBSim2023None✔✔✔✔✔✔✖️✖️NVIDIA
Nvidia DriveWorks2024Nvidia GPU✖️✔✔✔✖️✔✔✖️NVIDIA

🏆 Foundation Model Benchmark Challenges (2022–2025)

Benchmark Challenges

Autonomous Driving

NameHost
CARLA AD ChallengeCARLA
DRL4RealICCV
Waymo Open Dataset ChallengeWaymo / CVPR WAD
Argoverse 2: Scenario MiningArgoAI
Roboflow-20VLRoboflow-VL / CVPR
AVA ChallengeAVA Challenge Team
NameHost
IGLU ChallengeNeurIPS / IGLU Team
LLM Efficiency ChallengeNeurIPS
Trojan DetectionNeurIPS / CAIS
SMART-101CVPR
NICE ChallengeCVPR / LG Research
SyntaGenCVPR
Habitat ChallengeCVPR / FAIR
BIG-benchGoogle Research
BIG-bench Hard (BBH)Google Research
HELMStanford CRFM
MMBenchOpenCompass
MMMUCVPR / U-Waterloo / OSU
Open LLM LeaderboardVILA-Lab
Text-to-Image LeaderboardArtificial Analysis
Ego4DFAIR
VizWiz Grand ChallengeCVPR VizWiz Workshop
MedFMNeurIPS / Shanghai AI Laboratory
3D Scene UnderstandingCVPR
Common Tools and Frameworks

This section provides links to commonly used tools, frameworks, and resources for working with foundation models in autonomous driving.

Model Repositories and Leaderboards

Model Inference Frameworks

  • vLLM - High-throughput and memory-efficient inference engine for LLMs
  • LMDeploy - Toolkit for compressing, deploying, and serving LLMs
  • Ollama - Run large language models locally
  • Text Generation Inference - Production-ready inference container by Hugging Face
  • TensorRT-LLM - High-performance inference library by NVIDIA

Training and Fine-tuning

Contributing

We welcome contributions from the community! If you have research papers, tools, or resources to add, please create a pull request or open an issue.

License

This repository is released under the Apache 2.0 license.

autonomous-driving
diffusion-models
foundation-models
large-language-models
llms
mllms
multimodal-large-language-models
scenario-analysis
scenario-generation
survey
vision-language-model
vlms
world-models

Contributors

rbrusnicki

64 commits

yuangao-tum

43 commits

Languages

Python

100.0%