Heterogeneous inference framework for Mixture-of-Experts (MoE) models.
Python
0
1,208 commits
updated Sep 30, 2026
KTransformers is a research project focused on efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing. The project has evolved into two core modules: kt-kernel and kt-sft.
CPU-optimized kernel operations for heterogeneous LLM inference.
Key Features:
Quick Start:
cd kt-kernel
pip install .
Use Cases:
Performance Examples:
| Model | Hardware Configuration | Total Throughput | Output Throughput |
|---|---|---|---|
| DeepSeek-R1-0528 (FP8) | 8×L20 GPU + Xeon Gold 6454S | 227.85 tokens/s | 87.58 tokens/s (8-way concurrency) |
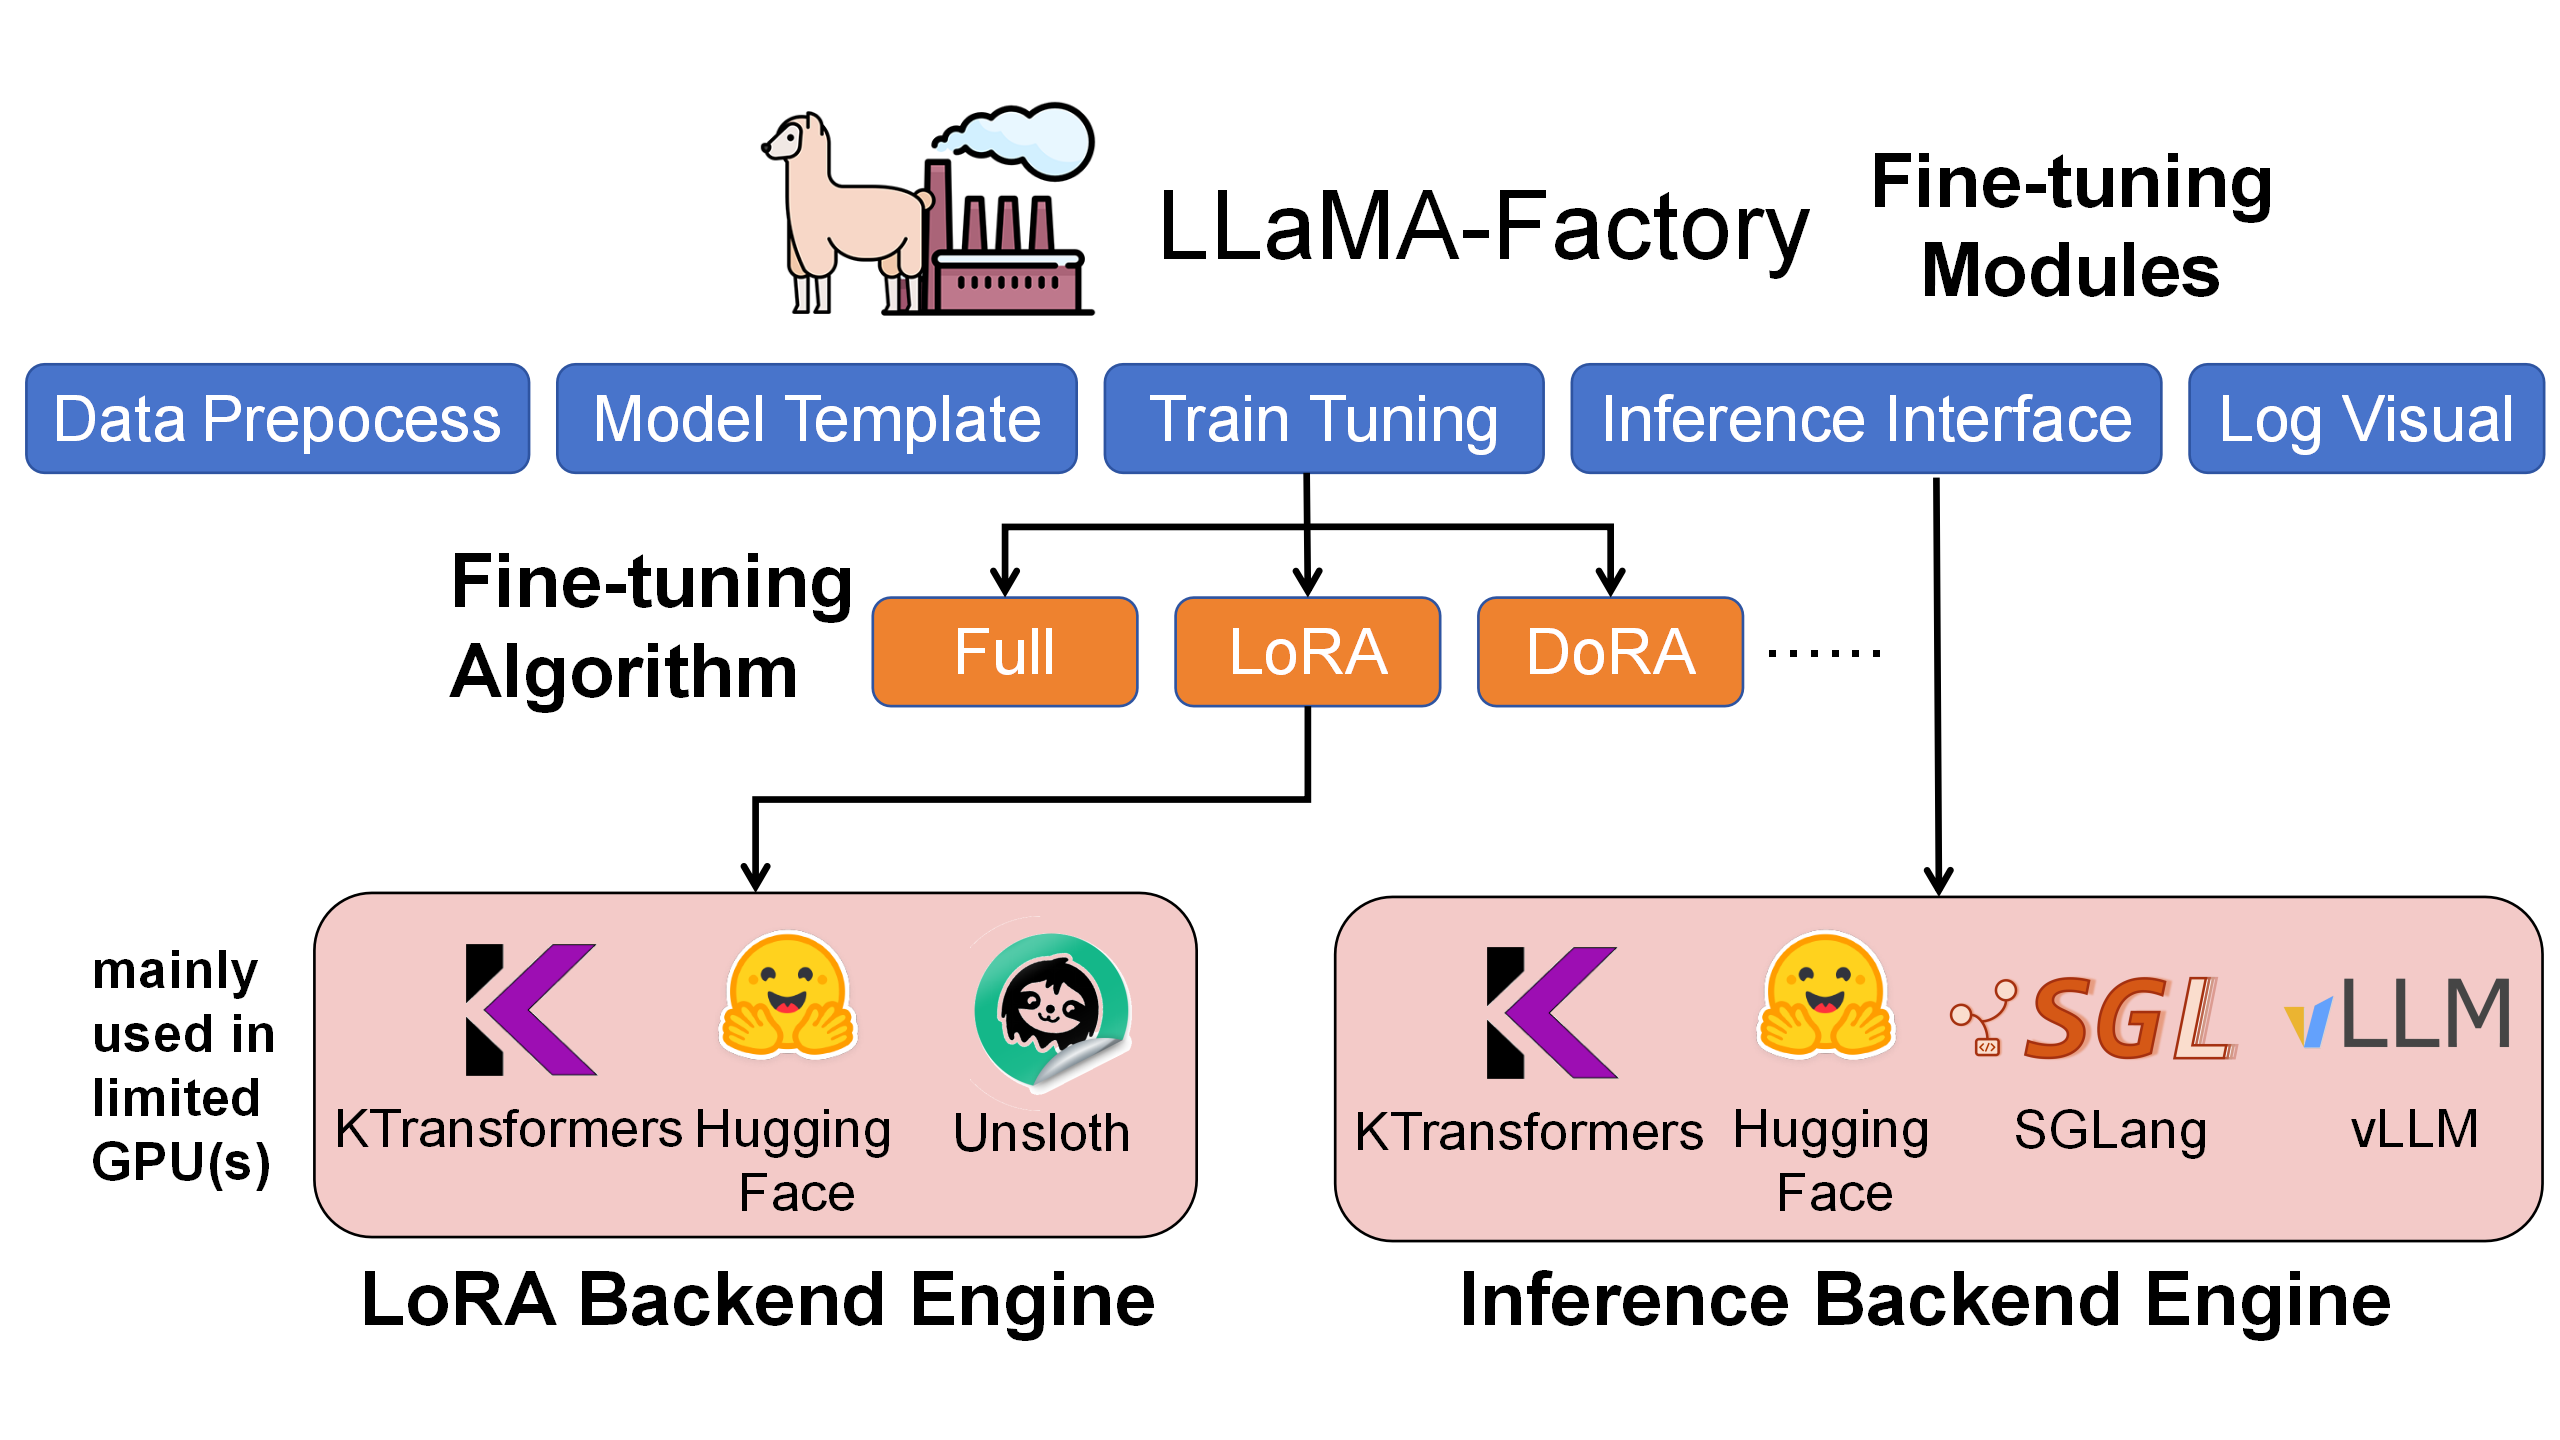
KTransformers × LLaMA-Factory integration for ultra-large MoE model fine-tuning.
Key Features:
Performance Examples:
| Model | Configuration | Throughput | GPU Memory |
|---|---|---|---|
| DeepSeek-V3 (671B) | LoRA + AMX | ~40 tokens/s | 70GB (multi-GPU) |
| DeepSeek-V2-Lite (14B) | LoRA + AMX | ~530 tokens/s | 6GB |
Quick Start:
cd kt-sft
# Install environment following kt-sft/README.md
USE_KT=1 llamafactory-cli train examples/train_lora/deepseek3_lora_sft_kt.yaml
If you use KTransformers in your research, please cite our paper:
@inproceedings{10.1145/3731569.3764843,
  title = {KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models},
  author = {Chen, Hongtao and Xie, Weiyu and Zhang, Boxin and Tang, Jingqi and Wang, Jiahao and Dong, Jianwei and Chen, Shaoyuan and Yuan, Ziwei and Lin, Chen and Qiu, Chengyu and Zhu, Yuening and Ou, Qingliang and Liao, Jiaqi and Chen, Xianglin and Ai, Zhiyuan and Wu, Yongwei and Zhang, Mingxing},
  booktitle = {Proceedings of the ACM SIGOPS 31st Symposium on Operating Systems Principles},
  year = {2025}
}
Developed and maintained by:
We welcome contributions! Please feel free to submit issues and pull requests.
The original integrated KTransformers framework has been archived to the archive/ directory for reference. The project now focuses on the two core modules above for better modularity and maintainability.
For the original documentation with full quick-start guides and examples, see:
Heterogeneous inference framework for Mixture-of-Experts (MoE) models.
Python
0
1,208 commits
updated Sep 30, 2026
KTransformers is a research project focused on efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing. The project has evolved into two core modules: kt-kernel and kt-sft.
CPU-optimized kernel operations for heterogeneous LLM inference.
Key Features:
Quick Start:
cd kt-kernel
pip install .
Use Cases:
Performance Examples:
| Model | Hardware Configuration | Total Throughput | Output Throughput |
|---|---|---|---|
| DeepSeek-R1-0528 (FP8) | 8×L20 GPU + Xeon Gold 6454S | 227.85 tokens/s | 87.58 tokens/s (8-way concurrency) |
KTransformers × LLaMA-Factory integration for ultra-large MoE model fine-tuning.
Key Features:
Performance Examples:
| Model | Configuration | Throughput | GPU Memory |
|---|---|---|---|
| DeepSeek-V3 (671B) | LoRA + AMX | ~40 tokens/s | 70GB (multi-GPU) |
| DeepSeek-V2-Lite (14B) | LoRA + AMX | ~530 tokens/s | 6GB |
Quick Start:
cd kt-sft
# Install environment following kt-sft/README.md
USE_KT=1 llamafactory-cli train examples/train_lora/deepseek3_lora_sft_kt.yaml
If you use KTransformers in your research, please cite our paper:
@inproceedings{10.1145/3731569.3764843,
  title = {KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models},
  author = {Chen, Hongtao and Xie, Weiyu and Zhang, Boxin and Tang, Jingqi and Wang, Jiahao and Dong, Jianwei and Chen, Shaoyuan and Yuan, Ziwei and Lin, Chen and Qiu, Chengyu and Zhu, Yuening and Ou, Qingliang and Liao, Jiaqi and Chen, Xianglin and Ai, Zhiyuan and Wu, Yongwei and Zhang, Mingxing},
  booktitle = {Proceedings of the ACM SIGOPS 31st Symposium on Operating Systems Principles},
  year = {2025}
}
Developed and maintained by:
We welcome contributions! Please feel free to submit issues and pull requests.
The original integrated KTransformers framework has been archived to the archive/ directory for reference. The project now focuses on the two core modules above for better modularity and maintainability.
For the original documentation with full quick-start guides and examples, see:



