
A high-performance framework for training LLMs, VLMs, diffusion, and embodied models on NVIDIA GPUs and Kunlun XPUs.
567
stars
390
commits
Python
primary language
Sep 15, 2026
updated
README
English | 简体中文

Train LLMs, VLMs, diffusion and embodied models, faster.


🌐 Website · 📖 Docs · ✍️ Blog · ⚡ Quick Start · 📊 Performance · 🏛️ Supported Models · 💬 Contact Us
Example: embodied-model training on LoongForge — DreamZero at 4.38× baseline throughput, loss curves aligned

💡 Why LoongForge?
LoongForge is an open-source training framework developed by the Baidu AI Cloud Baige team, built to deliver faster training for mainstream LLMs, VLMs, diffusion, and embodied models, thereby significantly reducing costs.
- Easy to Use — Ready-to-run configs and launch examples for supported models, covering pre-training, continued pre-training, SFT, and LoRA.
- High Performance — Built on multiple training backends (Megatron-LM and torch-native), with deep optimizations for each model family across parallelism strategy, memory footprint, communication overlap, and kernel efficiency, while keeping training loss curves aligned with the baseline.
- Proven at Scale — Open-sourced from AIAK-Training-LLM, a training acceleration suite serving enterprise customers in Education, Computer Vision, and Embodied AI, with the largest production runs reaching 5,000+ XPUs.
🐉 LoongForge is named after the traditional Chinese loong boat (龙舟), a symbol of coordinated power and forward momentum.
🏗️ Architecture
Since optimal training strategies differ across model families and scales, LoongForge adopts a multi-backend architecture.

- Megatron Stack — For LLMs, VLMs, and diffusion models. Powered by a patched Megatron-LM and extended with MoE parallelism, per-component heterogeneous parallelism, long-sequence optimizations, etc.
- Torch-Native Stack — For embodied models (VLA and WAM). A standalone torch-native subsystem featuring DDP / ZeRO-1 / FSDP / HSDP, with deep optimizations for representative models across I/O, communication strategy, kernel efficiency, etc.
🔥 Latest News
- [2026/09] ✨ Added Kimi-K3 BF16 training support for both LLMs and VLMs.
- [2026/09] ⚡ Added an optimized DreamZero Wan2.2-5B FSDP recipe with cache-aware data loading, compiled attention blocks, frozen-module handling, and Delta-FP8 AllGather.
- [2026/08] 🤖 Added VLA training support for Wall-OSS-0.5, with custom fused operators for higher training throughput.
- [2026/08] 📄 Released the TAOT paper — topology-aware dynamic expert replica placement that tackles expert-parallel (EP) load imbalance in MoE training, cutting overhead by up to 74% over industry solutions, with 1.43× speedup measured on a real training case. [blog]
- [2026/08] ✨ Added training support for GLM-5.2, along with a GLM-5.2 + MoonViT custom-composition example for extending GLM with multimodal capabilities.
- [2026/08] ✨ Added training support for MiniCPM-V-4.6 and Qwen3.8-27B.
- [2026/08] 🧪 Introduced a unified evaluation module for the embodied stack, currently covering Pi0.5 / xVLA / GR00T, with more models on the way.
- [2026/07] 🐳 Unified the prebuilt Docker images — all model families (LLM / VLM / VLA / Diffusion) now share a single image.
- [2026/07] 🤖 Released LoongForge-Embodied, a torch-native DDP/FSDP training subsystem for embodied models (Pi0.5, GR00T-N1.6/N1.7, xVLA, LingBot-VA, FastWAM, DreamZero, and Cosmos3), with up to 4.38× speedup. [blog]
- [2026/07] ✨ Added training support for Qwen-Image-Edit-2511.
- [2026/07] ✨ Added training support for DeepSeek-V4-Flash / DeepSeek-V4-Pro.
📅 More
- [2026/06] 🤖 Expanded VLA coverage with GR00T N1.6; 2.3× speedup on GR00T training. [blog]
- [2026/05] ⚡ Accelerated Wan 2.2 training by 116%, and added CP and data packing support.
- [2026/05] ✨ Added training support for Kimi K2.5 / K2.6, and introduced INT4 / NVFP4 PTQ.
- [2026/05] 🎉 v0.1.0 — first official tagged release of LoongForge.
- [2026/05] 🌟 Powered the training and public release of LLaVA-OneVision-2.0.
- [2026/04] 🧩 Added training support for MiniMax-M2.7 on both NVIDIA GPU and Kunlun XPU.
- [2026/04] 🚀 LoongForge source code publicly available on GitHub. [blog]
- [2025/10] 🌟 Powered the training and public release of LLaVA-OneVision-1.5 under AIAK-Training-LLM, the predecessor of LoongForge. [blog]
✨ Key Features
🚀 Foundation Models
- MoE EP Communication Optimization — Overlapped All2All / activation offload / compute, with further memory reduction beyond upstream Megatron-LM on DeepSeek-V3, Qwen3-MoE, etc.
- MoE Expert Load Balancing — Topology-aware dynamic replication of hot experts to balance EP workloads, with up to 74% lower overhead than industry solutions. [TAOT Paper]
- Adaptive FP8 Training — End-to-end FP8 for LLMs and VLMs with standard blockwise FP8; optional adaptive mode picks per-operator precision by GEMM shape and efficiency.
- Custom Fused Operators — Fused kernels like FusedDSA for DSA-style models — TileLang version open-sourced, high-performance CUDA version available on Baidu Baige platform.
- Long-Sequence Training — Context Parallel (CP) with chunked-pipeline scheduling scales LLM training to long sequence lengths.
🧩 Multi-Modal Models
- Flexible Multi-Modal Composition — Assemble VLMs from interchangeable ViT and LLM components (e.g. GLM-5.2 + MoonViT) straight from config — no custom model code.
- Heterogeneous Parallelism — Independent TP / DP / recompute / freeze per model component (e.g., ViT vs. LLM) for optimal throughput and memory. [blog]
- Decoupled Encoder-Decoder Training — Separates ViT and LLM into independent tasks, eliminating encoder-induced pipeline bubbles.
- DP Load Balancing — Load-aware data redistribution mitigates sequence-packing imbalance, improving multi-node scaling efficiency. [blog]
🤖 Embodied Models
- VLA & WAM Training — A dedicated torch-native DDP/FSDP subsystem for VLA and world-action (WAM) models, decoupled from the Megatron core, with flexible DDP / ZeRO-1 / FSDP / HSDP strategies. [README]
- Delta-FP8 FSDP Communication — Optionally compresses BF16 FSDP2 AllGather deltas into blockwise FP8 on supported NVIDIA GPUs while keeping model computation in BF16. [Usage]
- Per-Model Deep Optimization — Training code deeply customized for each supported model across I/O, communication strategy, and kernel efficiency — 1.79×–4.38× over official baselines in our benchmarks.
- Unified Evaluation — Evaluate trained policies on LIBERO / CALVIN / SimplerEnv / RoboTwin, with coverage expanding continuously.
🧰 Workflow & Compatibility
- Versatile Pipelines & Data Tools — Out-of-the-box Pretrain / MidTrain / SFT / LoRA, with built-in dataset format conversion and sequence packing.
- Flexible Checkpointing — Offline bidirectional Megatron ↔ HuggingFace conversion plus native online HF load/save — no format barriers across your workflow.
- Heterogeneous Hardware — Native support for NVIDIA GPUs and Kunlun XPUs via a minimally-intrusive plugin design.
📖 Deep-dive: LLM · VLM · Embodied Model
📊 Performance
Training throughput speedups over mainstream open-source baselines — each model and its baseline were benchmarked on the same machine type with the same training hyperparameters:
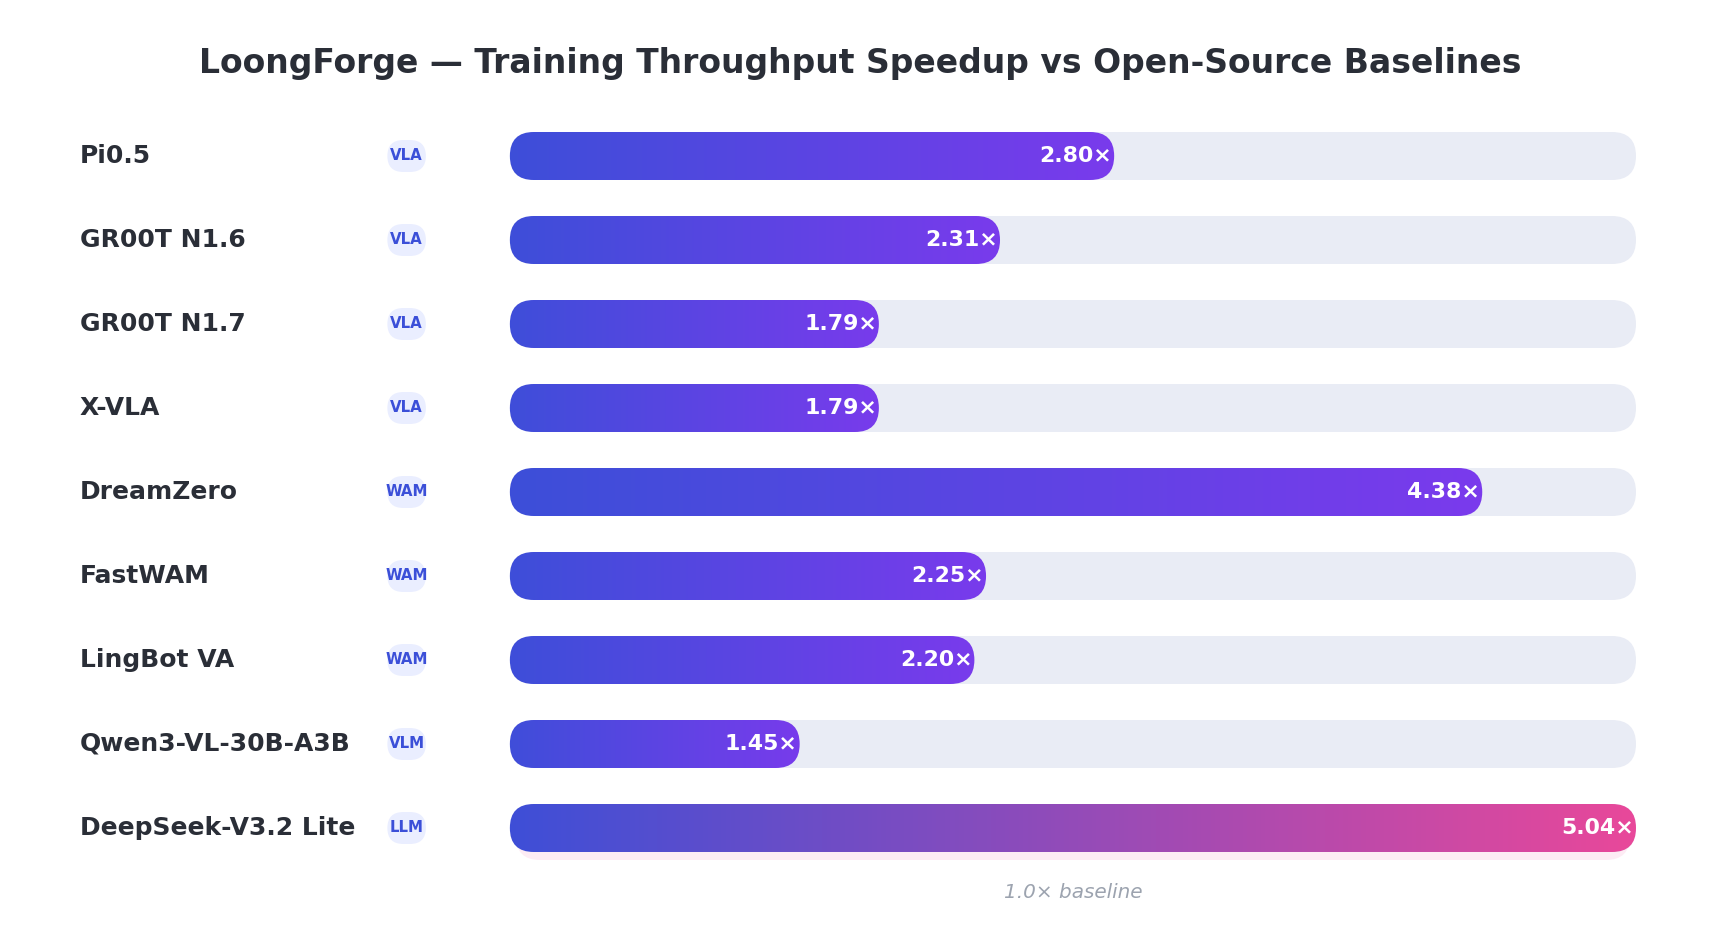
DeepSeek-V3.2 Lite reflects DSA operator-level optimizations and was validated on a reduced-layer configuration due to test-bed scale limits.
Numbers were measured at a point in time and may evolve as implementations change on both sides.
⚡ Quick Start
1. Install — use the unified prebuilt Docker image (one image for all model families) or build from source:
- NVIDIA GPU: Installation Guide
- Kunlun XPU: Installation Guide
2. Pick a tutorial — by hardware and modality:
- NVIDIA GPU: LLM · VLM · VLA & WAM · Diffusion
- Kunlun XPU: Kunlun XPU Tutorials
3. Find your model's scripts — ready-to-run launch scripts are available under examples/ / examples_xpu/, with configs in configs/models/.
🏛️ Supported Models
LoongForge supports a broad range of model families across LLM, VLM, diffusion, and embodied. Select a model below to open its training examples. For complete usage instructions, see the User Guide and the full model support matrix.
| LLM | VLM | Diffusion | Embodied |
|---|---|---|---|
|
|
|
🌟 Powered by LoongForge
Open-source models trained with LoongForge or its predecessor AIAK-Training-LLM:
| Model | Highlights |
|---|---|
| LLaVA-OneVision-2.0 | Next-generation multimodal model, with new VideoCaption and Spatial datasets |
| Innovator-VL | Scientific multimodal LLM for advanced reasoning |
| LLaVA-OneVision-1.5 | Fully open framework for democratized multimodal training |
| Qianfan-VL | Domain-enhanced vision-language models for enterprise, 3B–70B parameters |
📂 Repository Layout
📁 Directory tree
LoongForge/
├── loongforge/                   # Core training framework
│   ├── train/                    # Training entry points & trainers
│   │   ├── pretrain/             #   Pretrain (LLM, VLM)
│   │   ├── sft/                  #   SFT (LLM, VLM, InternVL, ERNIE)
│   │   └── diffusion/            #   Diffusion (WAN, Qwen-Image)
│   ├── models/                   # Unified model abstractions
│   │   ├── foundation/           #   LLM backbones (LLaMA, Qwen, DeepSeek, ...)
│   │   ├── encoder/              #   Vision encoders (ViT, Qwen-VL, InternVL, ...)
│   │   ├── omni_models/          #   Multi-modal composition
│   │   ├── diffusion/            #   Diffusion models (WAN, Qwen-Image)
│   │   └── common/               #   Shared layers and utilities
│   ├── embodied/                 # LoongForge-Embodied: standalone torch-native (DDP/FSDP)
│   │                             #   embodied (VLA + world-action) subsystem — see loongforge/embodied/README.md
│   ├── data/                     # Data pipelines (multi-modal, video, DP balance)
│   ├── tokenizer/                # Tokenizers
│   └── utils/                    # Config map, constants, etc.
├── third_party/Loong-Megatron/   # Patched Megatron-LM (git submodule)
├── configs/                      # Hydra YAML configs (models, data)
├── examples/                     # GPU launch scripts
├── examples_xpu/                 # Kunlun XPU launch scripts
├── tools/                        # Checkpoint conversion, data preprocessing
├── ops/                          # Custom fused operators (incl. open-sourced TileLang)
├── patches/                      # TransformerEngine patches
├── docker/                       # Dockerfiles (GPU & XPU)
├── tests/                        # E2E test suite (YAML-driven)
└── docs/                         # Documentation
📝 Citation
If you find LoongForge helpful, please cite this project:
@software{LoongForge2026,
  title  = {LoongForge: A high-performance framework for training LLMs, VLMs, diffusion, and embodied models},
  author = {{The LoongForge Authors}},
  year   = {2026},
  url    = {https://github.com/baidu-baige/LoongForge}
}
If you use TAOT for MoE training in LoongForge, you can cite our paper:
@article{zhang2026taot,
  title   = {{TAOT}: Topology-Aware Optimal Transport for Dynamic Expert Replica Placement in {MoE} Training},
  author  = {Zhang, Lingyun and Zhang, Henghua and Gu, Shilei and Mo, Kai and Han, Shuai and Li, Shiyong and Wang, Yanpeng and Shen, Dou},
  journal = {arXiv preprint arXiv:2608.03676},
  year    = {2026},
  url     = {https://arxiv.org/abs/2608.03676}
}
🤝 Contributing
We warmly welcome community contributions — bug reports, feature proposals, and PRs alike. Please read our Contributing Guidelines before submitting.
Thanks to all our contributors:
🙏 Acknowledgments
LoongForge builds on NVIDIA's Megatron-LM and draws inspiration from many excellent open-source projects, including HuggingFace Transformers, LLaMA-Factory, Megatron-Bridge, and LeRobot, as well as the official implementations of the models it supports (e.g. OpenPI, NVIDIA Isaac GR00T). We sincerely thank these communities for their outstanding contributions, and would also like to extend our gratitude to the LINUX DO community for its welcoming space for technical discussion and support for open-source sharing.
💬 Contact Us
- GitHub Issues — Bug reports, usage questions, and feature requests. Open an issue.
- Developer Communities — WeChat group, Xiaohongshu, and more. Join here.
- Email — Enterprise adoption, large-scale deployment, partnership, or any other topic. loongforge@baidu.com.
📄 License
LoongForge is released under the Apache License 2.0. Some files are derived from third-party open-source projects; please refer to the specific file headers for their respective copyright and attribution.
Contributors


See what people are saying
Similar repos


Languages
Python
93.4%
Shell
3.1%
Cuda
2.2%
A high-performance framework for training LLMs, VLMs, diffusion, and embodied models on NVIDIA GPUs and Kunlun XPUs.
567
stars
390
commits
Python
primary language
Sep 15, 2026
updated
README
English | 简体中文
Train LLMs, VLMs, diffusion and embodied models, faster.
🌐 Website · 📖 Docs · ✍️ Blog · ⚡ Quick Start · 📊 Performance · 🏛️ Supported Models · 💬 Contact Us
Example: embodied-model training on LoongForge — DreamZero at 4.38× baseline throughput, loss curves aligned
💡 Why LoongForge?
LoongForge is an open-source training framework developed by the Baidu AI Cloud Baige team, built to deliver faster training for mainstream LLMs, VLMs, diffusion, and embodied models, thereby significantly reducing costs.
- Easy to Use — Ready-to-run configs and launch examples for supported models, covering pre-training, continued pre-training, SFT, and LoRA.
- High Performance — Built on multiple training backends (Megatron-LM and torch-native), with deep optimizations for each model family across parallelism strategy, memory footprint, communication overlap, and kernel efficiency, while keeping training loss curves aligned with the baseline.
- Proven at Scale — Open-sourced from AIAK-Training-LLM, a training acceleration suite serving enterprise customers in Education, Computer Vision, and Embodied AI, with the largest production runs reaching 5,000+ XPUs.
🐉 LoongForge is named after the traditional Chinese loong boat (龙舟), a symbol of coordinated power and forward momentum.
🏗️ Architecture
Since optimal training strategies differ across model families and scales, LoongForge adopts a multi-backend architecture.
- Megatron Stack — For LLMs, VLMs, and diffusion models. Powered by a patched Megatron-LM and extended with MoE parallelism, per-component heterogeneous parallelism, long-sequence optimizations, etc.
- Torch-Native Stack — For embodied models (VLA and WAM). A standalone torch-native subsystem featuring DDP / ZeRO-1 / FSDP / HSDP, with deep optimizations for representative models across I/O, communication strategy, kernel efficiency, etc.
🔥 Latest News
- [2026/09] ✨ Added Kimi-K3 BF16 training support for both LLMs and VLMs.
- [2026/09] ⚡ Added an optimized DreamZero Wan2.2-5B FSDP recipe with cache-aware data loading, compiled attention blocks, frozen-module handling, and Delta-FP8 AllGather.
- [2026/08] 🤖 Added VLA training support for Wall-OSS-0.5, with custom fused operators for higher training throughput.
- [2026/08] 📄 Released the TAOT paper — topology-aware dynamic expert replica placement that tackles expert-parallel (EP) load imbalance in MoE training, cutting overhead by up to 74% over industry solutions, with 1.43× speedup measured on a real training case. [blog]
- [2026/08] ✨ Added training support for GLM-5.2, along with a GLM-5.2 + MoonViT custom-composition example for extending GLM with multimodal capabilities.
- [2026/08] ✨ Added training support for MiniCPM-V-4.6 and Qwen3.8-27B.
- [2026/08] 🧪 Introduced a unified evaluation module for the embodied stack, currently covering Pi0.5 / xVLA / GR00T, with more models on the way.
- [2026/07] 🐳 Unified the prebuilt Docker images — all model families (LLM / VLM / VLA / Diffusion) now share a single image.
- [2026/07] 🤖 Released LoongForge-Embodied, a torch-native DDP/FSDP training subsystem for embodied models (Pi0.5, GR00T-N1.6/N1.7, xVLA, LingBot-VA, FastWAM, DreamZero, and Cosmos3), with up to 4.38× speedup. [blog]
- [2026/07] ✨ Added training support for Qwen-Image-Edit-2511.
- [2026/07] ✨ Added training support for DeepSeek-V4-Flash / DeepSeek-V4-Pro.
📅 More
- [2026/06] 🤖 Expanded VLA coverage with GR00T N1.6; 2.3× speedup on GR00T training. [blog]
- [2026/05] ⚡ Accelerated Wan 2.2 training by 116%, and added CP and data packing support.
- [2026/05] ✨ Added training support for Kimi K2.5 / K2.6, and introduced INT4 / NVFP4 PTQ.
- [2026/05] 🎉 v0.1.0 — first official tagged release of LoongForge.
- [2026/05] 🌟 Powered the training and public release of LLaVA-OneVision-2.0.
- [2026/04] 🧩 Added training support for MiniMax-M2.7 on both NVIDIA GPU and Kunlun XPU.
- [2026/04] 🚀 LoongForge source code publicly available on GitHub. [blog]
- [2025/10] 🌟 Powered the training and public release of LLaVA-OneVision-1.5 under AIAK-Training-LLM, the predecessor of LoongForge. [blog]
✨ Key Features
🚀 Foundation Models
- MoE EP Communication Optimization — Overlapped All2All / activation offload / compute, with further memory reduction beyond upstream Megatron-LM on DeepSeek-V3, Qwen3-MoE, etc.
- MoE Expert Load Balancing — Topology-aware dynamic replication of hot experts to balance EP workloads, with up to 74% lower overhead than industry solutions. [TAOT Paper]
- Adaptive FP8 Training — End-to-end FP8 for LLMs and VLMs with standard blockwise FP8; optional adaptive mode picks per-operator precision by GEMM shape and efficiency.
- Custom Fused Operators — Fused kernels like FusedDSA for DSA-style models — TileLang version open-sourced, high-performance CUDA version available on Baidu Baige platform.
- Long-Sequence Training — Context Parallel (CP) with chunked-pipeline scheduling scales LLM training to long sequence lengths.
🧩 Multi-Modal Models
- Flexible Multi-Modal Composition — Assemble VLMs from interchangeable ViT and LLM components (e.g. GLM-5.2 + MoonViT) straight from config — no custom model code.
- Heterogeneous Parallelism — Independent TP / DP / recompute / freeze per model component (e.g., ViT vs. LLM) for optimal throughput and memory. [blog]
- Decoupled Encoder-Decoder Training — Separates ViT and LLM into independent tasks, eliminating encoder-induced pipeline bubbles.
- DP Load Balancing — Load-aware data redistribution mitigates sequence-packing imbalance, improving multi-node scaling efficiency. [blog]
🤖 Embodied Models
- VLA & WAM Training — A dedicated torch-native DDP/FSDP subsystem for VLA and world-action (WAM) models, decoupled from the Megatron core, with flexible DDP / ZeRO-1 / FSDP / HSDP strategies. [README]
- Delta-FP8 FSDP Communication — Optionally compresses BF16 FSDP2 AllGather deltas into blockwise FP8 on supported NVIDIA GPUs while keeping model computation in BF16. [Usage]
- Per-Model Deep Optimization — Training code deeply customized for each supported model across I/O, communication strategy, and kernel efficiency — 1.79×–4.38× over official baselines in our benchmarks.
- Unified Evaluation — Evaluate trained policies on LIBERO / CALVIN / SimplerEnv / RoboTwin, with coverage expanding continuously.
🧰 Workflow & Compatibility
- Versatile Pipelines & Data Tools — Out-of-the-box Pretrain / MidTrain / SFT / LoRA, with built-in dataset format conversion and sequence packing.
- Flexible Checkpointing — Offline bidirectional Megatron ↔ HuggingFace conversion plus native online HF load/save — no format barriers across your workflow.
- Heterogeneous Hardware — Native support for NVIDIA GPUs and Kunlun XPUs via a minimally-intrusive plugin design.
📖 Deep-dive: LLM · VLM · Embodied Model
📊 Performance
Training throughput speedups over mainstream open-source baselines — each model and its baseline were benchmarked on the same machine type with the same training hyperparameters:
DeepSeek-V3.2 Lite reflects DSA operator-level optimizations and was validated on a reduced-layer configuration due to test-bed scale limits.
Numbers were measured at a point in time and may evolve as implementations change on both sides.
⚡ Quick Start
1. Install — use the unified prebuilt Docker image (one image for all model families) or build from source:
- NVIDIA GPU: Installation Guide
- Kunlun XPU: Installation Guide
2. Pick a tutorial — by hardware and modality:
- NVIDIA GPU: LLM · VLM · VLA & WAM · Diffusion
- Kunlun XPU: Kunlun XPU Tutorials
3. Find your model's scripts — ready-to-run launch scripts are available under examples/ / examples_xpu/, with configs in configs/models/.
🏛️ Supported Models
LoongForge supports a broad range of model families across LLM, VLM, diffusion, and embodied. Select a model below to open its training examples. For complete usage instructions, see the User Guide and the full model support matrix.
| LLM | VLM | Diffusion | Embodied |
|---|---|---|---|
|
|
|
🌟 Powered by LoongForge
Open-source models trained with LoongForge or its predecessor AIAK-Training-LLM:
| Model | Highlights |
|---|---|
| LLaVA-OneVision-2.0 | Next-generation multimodal model, with new VideoCaption and Spatial datasets |
| Innovator-VL | Scientific multimodal LLM for advanced reasoning |
| LLaVA-OneVision-1.5 | Fully open framework for democratized multimodal training |
| Qianfan-VL | Domain-enhanced vision-language models for enterprise, 3B–70B parameters |
📂 Repository Layout
📁 Directory tree
LoongForge/
├── loongforge/                   # Core training framework
│   ├── train/                    # Training entry points & trainers
│   │   ├── pretrain/             #   Pretrain (LLM, VLM)
│   │   ├── sft/                  #   SFT (LLM, VLM, InternVL, ERNIE)
│   │   └── diffusion/            #   Diffusion (WAN, Qwen-Image)
│   ├── models/                   # Unified model abstractions
│   │   ├── foundation/           #   LLM backbones (LLaMA, Qwen, DeepSeek, ...)
│   │   ├── encoder/              #   Vision encoders (ViT, Qwen-VL, InternVL, ...)
│   │   ├── omni_models/          #   Multi-modal composition
│   │   ├── diffusion/            #   Diffusion models (WAN, Qwen-Image)
│   │   └── common/               #   Shared layers and utilities
│   ├── embodied/                 # LoongForge-Embodied: standalone torch-native (DDP/FSDP)
│   │                             #   embodied (VLA + world-action) subsystem — see loongforge/embodied/README.md
│   ├── data/                     # Data pipelines (multi-modal, video, DP balance)
│   ├── tokenizer/                # Tokenizers
│   └── utils/                    # Config map, constants, etc.
├── third_party/Loong-Megatron/   # Patched Megatron-LM (git submodule)
├── configs/                      # Hydra YAML configs (models, data)
├── examples/                     # GPU launch scripts
├── examples_xpu/                 # Kunlun XPU launch scripts
├── tools/                        # Checkpoint conversion, data preprocessing
├── ops/                          # Custom fused operators (incl. open-sourced TileLang)
├── patches/                      # TransformerEngine patches
├── docker/                       # Dockerfiles (GPU & XPU)
├── tests/                        # E2E test suite (YAML-driven)
└── docs/                         # Documentation
📝 Citation
If you find LoongForge helpful, please cite this project:
@software{LoongForge2026,
  title  = {LoongForge: A high-performance framework for training LLMs, VLMs, diffusion, and embodied models},
  author = {{The LoongForge Authors}},
  year   = {2026},
  url    = {https://github.com/baidu-baige/LoongForge}
}
If you use TAOT for MoE training in LoongForge, you can cite our paper:
@article{zhang2026taot,
  title   = {{TAOT}: Topology-Aware Optimal Transport for Dynamic Expert Replica Placement in {MoE} Training},
  author  = {Zhang, Lingyun and Zhang, Henghua and Gu, Shilei and Mo, Kai and Han, Shuai and Li, Shiyong and Wang, Yanpeng and Shen, Dou},
  journal = {arXiv preprint arXiv:2608.03676},
  year    = {2026},
  url     = {https://arxiv.org/abs/2608.03676}
}
🤝 Contributing
We warmly welcome community contributions — bug reports, feature proposals, and PRs alike. Please read our Contributing Guidelines before submitting.
Thanks to all our contributors:
🙏 Acknowledgments
LoongForge builds on NVIDIA's Megatron-LM and draws inspiration from many excellent open-source projects, including HuggingFace Transformers, LLaMA-Factory, Megatron-Bridge, and LeRobot, as well as the official implementations of the models it supports (e.g. OpenPI, NVIDIA Isaac GR00T). We sincerely thank these communities for their outstanding contributions, and would also like to extend our gratitude to the LINUX DO community for its welcoming space for technical discussion and support for open-source sharing.
💬 Contact Us
- GitHub Issues — Bug reports, usage questions, and feature requests. Open an issue.
- Developer Communities — WeChat group, Xiaohongshu, and more. Join here.
- Email — Enterprise adoption, large-scale deployment, partnership, or any other topic. loongforge@baidu.com.
📄 License
LoongForge is released under the Apache License 2.0. Some files are derived from third-party open-source projects; please refer to the specific file headers for their respective copyright and attribution.
See what people are saying
Similar repos
Contributors
Languages
Python
93.4%
Shell
3.1%
Cuda
2.2%