
A series of technical report on Slow Thinking with LLM
Python
769
133 commits
updated Aug 13, 2025
README
STILL: Slow Thinking with LLMs


We are STILL exploring the uncharted territory of o1-like reasoning systems.
Content List
- LLM Exploration Mechanism
- Code-Integrated Reasoning
- ICPC-Eval
- SimpleDeepSearcher
- OlymMATH
- R1-Searcher
- STILL-3
- Virgo
- STILL-Hallucination Mitigation
- STILL-2
- STILL-1
News
- [12 August 2025] LLM Exploration Mechanism: We systematically analyze LLM exploration mechanisms in RLVR, quantifying differences between SFT and RL, revealing entropy-performance dynamics, and proposing strategies to enhance exploration and training efficiency. We open-source our code in project page
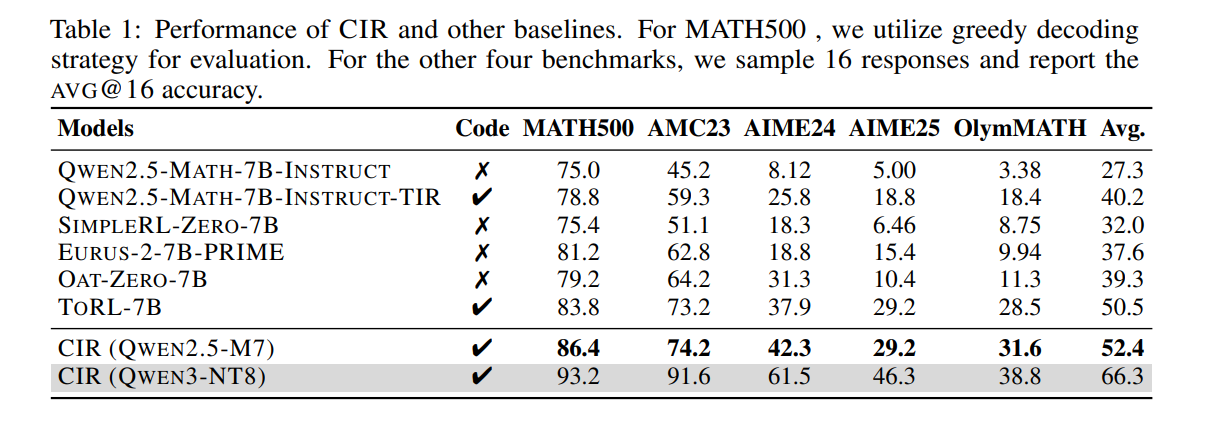
- [2 June 2025] Code-Integrated Reasoning: We propose an improved tool-augmented reinforcement learning approach for code-integrated reasoning that balances exploration and stability, achieving strong performance on five mathematical benchmarks. We further provide an in-depth analysis of the mechanisms behind code-integrated reasoning, explaining why and how it is effective. For More details, please refer to our Project Page and Model.
- [29 May 2025] ICPC-Eval: We introduce ICPC-Eval, a new benchmark of 118 ICPC problems for evaluating LLM reasoning in competitive coding, featuring realistic ICPC competition scenario, robust local evaluation, and a iterative repair metrics Refine@K. We open-source our dataset, evaluation code, and paper. For more details, please refer to our project page and huggingface 🤗.
- [11 April 2025] SimpleDeepSearcher: We propose the SimpleDeepSearcher framework, which aims to stimulate autonomous web search capabilities in large language models through knowledge distillation and self-distillation. By leveraging powerful reasoning models and a real-world web search environment, we carefully curated and filtered 871 high-quality training examples, significantly enhancing model performance on complex information retrieval tasks and outperforming existing reinforcement learning approaches. All models and efficient fine-tuning datasets (0.5k and 0.8k) have been open-sourced.For more details, please refer to our project page and huggingface 🤗.
- [8 April 2025] ⚡️⚡️We open source our code and training data of STILL-3!
- [28 Mar 2025] OlymMATH: We introduce OlymMATH, a challenging benchmark of 200 Olympiad-level math problems across algebra, geometry, number theory, and combinatorics in both English and Chinese. Even the most advanced models achieve only moderate accuracy on OlymMATH-EN-HARD, highlighting significant room for improvement in mathematical reasoning. We open-source our dataset, evaluation code, and paper. For more details, please refer to our project page and huggingface 🤗.
- [9 Mar 2025] R1-Searcher: We propose R1-Searcher, a novel two-stage outcome-based RL approach designed to enhance the search capabilities of LLMs.
- This method allows LLMs to autonomously invoke external search systems to access additional knowledge during the reasoning process.
- Our framework relies exclusively on RL, without requiring process rewards or distillation for a cold start.
- We conduct training on both base models (zero-shot) and fine-tuned models, analyzing key research questions arising during the training process.
- **We open-source our models: Qwen-2.5-7B-Base-RL and Llama-3.1-8B-Instruct-RL, code and data.
- [7 Mar 2025] STILL-3: We propose STILL-3, An Empirical Study on Eliciting and Improving R1-like Reasoning Models.
- We systematically experiment with and document the effects of various factors influencing RL training, conducting experiments on both base models (zero) and fine-tuned models.
- Beyond RL training, we also explore the use of tool manipulation, finding that it significantly boosts the reasoning performance of large reasoning models.
- We open source our code and training data!
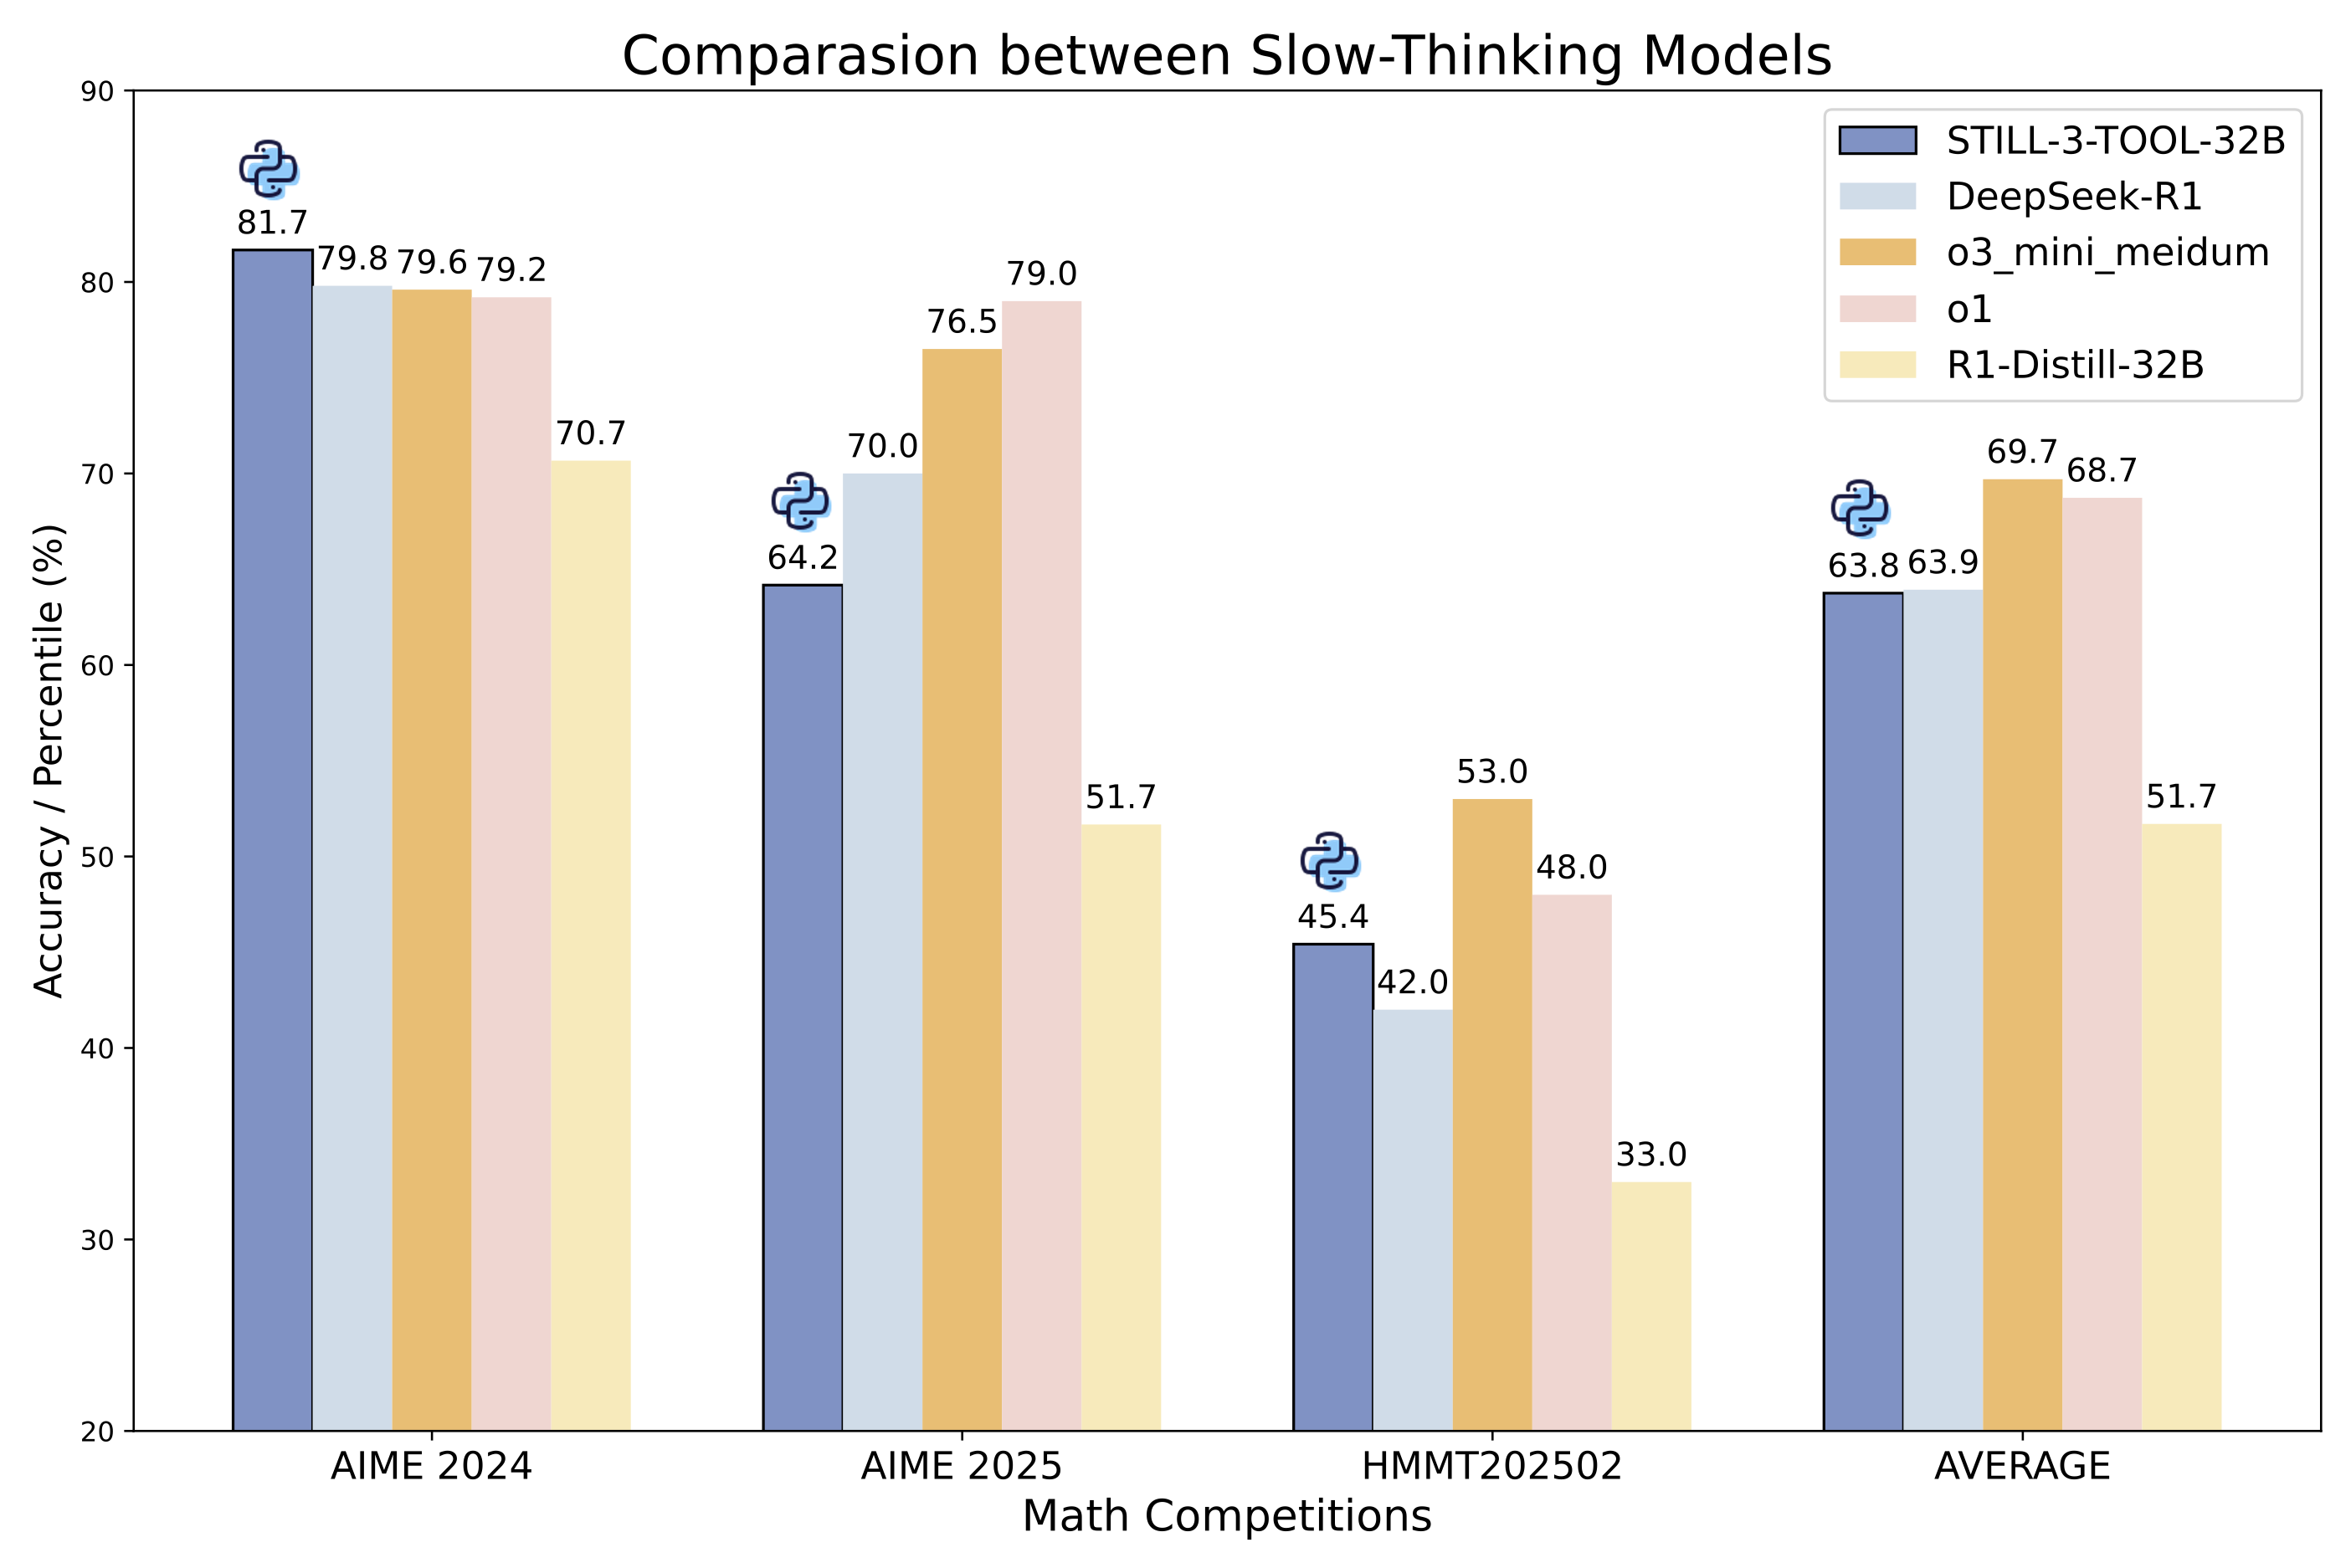
- [1 Mar 2025] STILL-3-Tool-32B: We propose STILL-3-Tool-32B, leveraging python code to help the reasoning process. During evaluation, STILL-3-Tool-32B achieves 81.70% accuracy on AIME 2024, matching the performance of o3-mini, outperforming o1 and DeepSeek-R1. We open-source our code, model, and data. For more details, please refer to our Notion page.
- [26 Jan 2025] STILL-3-1.5B-preview: We release STILL-3-1.5B-preview, a 1.5B slow-thinking reasoning model achieves 39.33% accuracy on AIME benchmark! We utilize 30k queries to adapt reinforcement learning on 1.5B model (DeepSeek-R1-Distill-Qwen-1.5B) and observe the continuous performance improvement as the number of training steps increased. For better reproducing our work and advancing research progress, we open-source our code, model, and data.
- [6 Jan 2025] Virgo: We develop Virgo, a multi-modal slow-thinking reasoning model, based on Qwen2-VL-72B-Instruct, which achieves leading performance on four challenging multi-modal benchmarks. We demonstrate that the slow-thinking reasoning ability can be transferred from text to vision. We open-source the model and training data.
- [3 Jan 2025] STILL-Hallucination Mitigation: We propose HaluSearch, a framework that integrates tree search algorithms and a dynamic system switch mechanism, inspired by dual process theory, to reduce LLM hallucinations during inference.
- [22 Dec 2024] We open-source part of the training data in Github or HuggingFace and the model for community researchers to use for research purposes.
- [12 Dec 2024] STILL-2: We preliminarily reproduce a slow-thinking reasoning system, achieving competitive performance compared to industry-level reasoning systems on these benchmarks! And we also release the technical report, which presents the details about our reproduction.
- [18 Nov 2024] STILL-1: We release our first technical report, where we leverage reward-guided tree search algorithm to assist LLM reasoning process and largely enhance the performance of LLM on complex reasoning tasks.
Detailed Contents
From Trial-and-Error to Improvement: A Systematic Analysis of LLM Exploration Mechanisms in RLVR [Report]
We conduct a comprehensive study on LLM exploration mechanisms in RLVR, aiming to quantify, characterize, and optimize how large language models explore solution spaces during complex problem-solving.
-
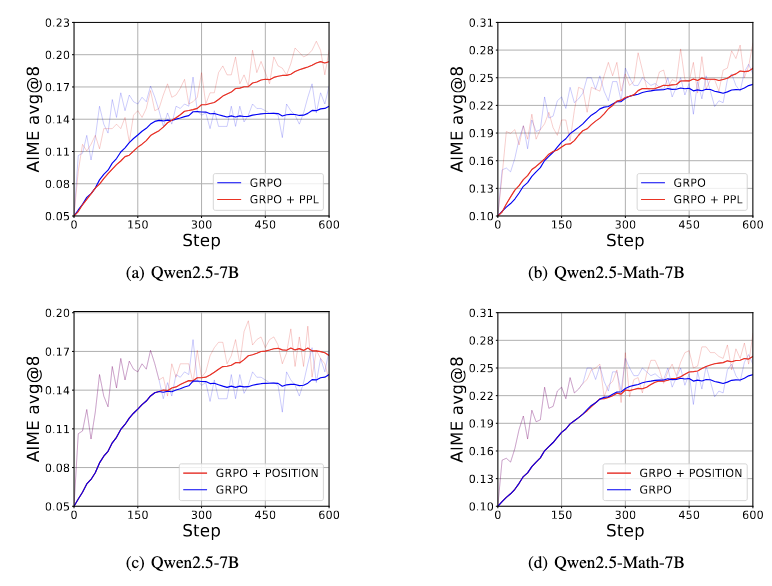
🔍 Core Focus & Analysis: We conduct a systematic analysis of the exploration capabilities of large language models (LLMs), examining key aspects such as the quantification of exploration boundaries, the interplay between entropy and performance, and strategies for enhancing data efficiency in reinforcement learning. Additionally, we compare the exploration behaviors of supervised fine-tuning (SFT) models, reinforcement learning (RL) models, and tool-integrated configurations, shedding light on their respective impacts on the breadth and efficiency of exploration.
-
🧠 Key Findings:
- SFT expands exploration boundaries, while RL sharpens single-attempt accuracy but constricts exploration scope.
- entropy-performance during RL dynamics shift with training stages (rising stage curbs errors to form reasoning patterns, plateau stage refines high-entropy key tokens), instance quality (low-PPL samples enable more robust learning), and token positions (later tokens exert greater influence on outcomes).
- RFT maintains exploration capacity through controlled noisy data injection and prioritization of high-entropy, high-branching-factor samples.
-
🚀 Strategies: We introduce PPL- and position-aware advantage shaping techniques to boost the training efficiency of rollout data in the RL process.
Towards Effective Code-Integrated Reasoning [Report]
We investigate Code-Integrated Reasoning, an approach where models generate and execute code during reasoning to enhance performance, particularly in complex mathematical tasks.
-
🔍 Challenges & Strategies: We identify key challenges in tool-augmented RL and develop strategies to balance exploration and stability during training, significantly improving training effectiveness.
-
📈 Performance: Our method demonstrates substantial performance gains, achieving state-of-the-art results across multiple benchmarks with an average accuracy of 52.4%, surpassing several competitive baselines.
-
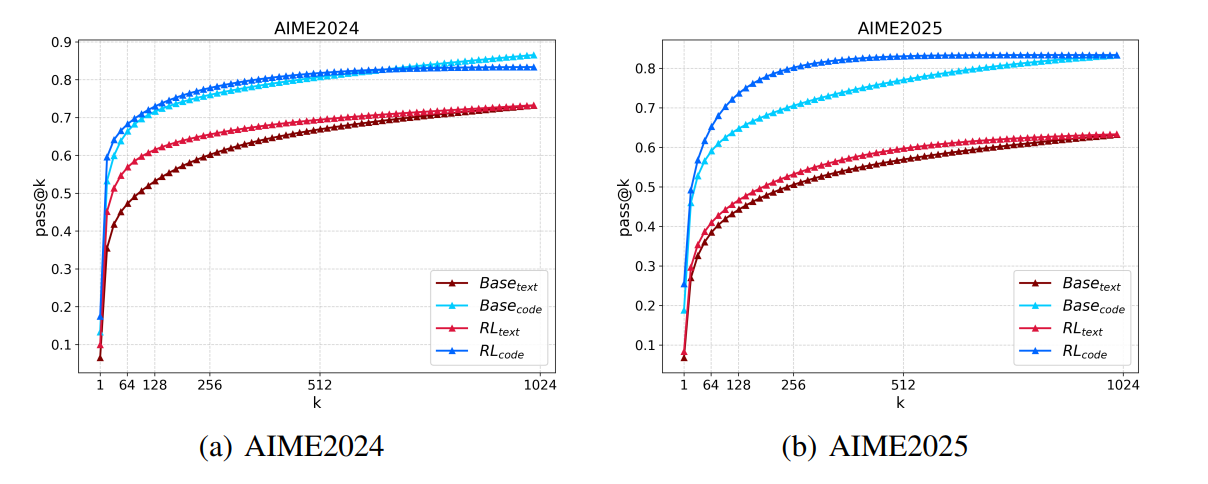
💡 Mechanistic Insights: We further provide an in-depth analysis of the mechanisms behind code-integrated reasoning, explaining why and how it is effective in expanding model capabilities, improving reasoning efficiency, and providing valuable error feedback, with notable performance gains in specific problem types.
ICPC-Eval: Probing the Frontiers of LLM Reasoning with Competitive Programming Contests [Report]
-
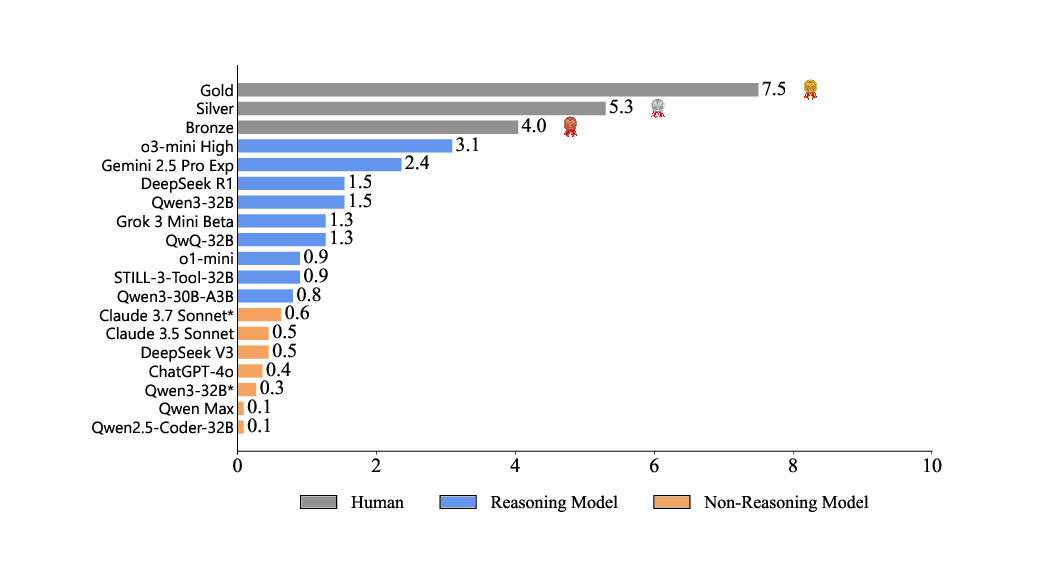
🧠 We introduce a new benchmark ICPC-Eval designed to evaluate the reasoning ability of LLMs under realistic competitive programming environments, based on 118 curated problems from 11 recent ICPC regional contests worldwide.
-
🏆 It captures the true distribution of problem types and difficulty found in real ICPC contests—far more representative than synthetic benchmarks or filtered OJ tasks.
-
🔍 To overcome the limitations of metrics like Pass@K, we propose Refine@K, an execution-feedback-driven metric that measures iterative code refinement and simulates how models improve solutions over multiple attempts—more aligned with human competitive coding behavior.
-
🧰 We provide a robust local evaluation toolkit, along with high-quality test cases, enabling fast and accurate validation without relying on external online judges.
-
📉 Experimental results show that even state-of-the-art reasoning models like DeepSeek-R1 struggle to match top human teams and often require multi-turn code refinement to fully unlock their potential—highlighting the gap between LLMs and real-world competitive coders.
SimpleDeepSearcher: Deep Information Seeking via Web-Powered Reasoning Trajectory Synthesis [Notion]
-
🚀 To address the inefficiency and redundant reasoning of large models in complex information retrieval tasks, we curate and filter 871 high-quality samples from a real web search environment. By leveraging knowledge distillation and self-distillation on strong reasoning models, we achieve significant performance gains, surpassing existing reinforcement learning methods.
-
🌐 We construct a large-scale data synthesis pipeline based on real and open web environments, substantially enhancing the model's capability in handling complex and noisy search scenarios.
-
🎯 We fine-tune Qwen-2.5-7B-Instruct, Qwen-2.5-32B-Instruct, Dpsk-Distilled-Qwen-32B, and QwQ-32B. Our model outperforms existing baselines on five benchmarks (2WikiMultiHopQA, Bamboogle, Musique, FRAMES, GAIA), and demonstrates especially strong performance on the more challenging Frames and GAIA datasets.
-
💡 We also explore reinforcement learning on distilled models to continuously stimulate their capabilities, and observe several intriguing phenomena.
OlymMATH: Challenging the Boundaries of Reasoning: An Olympiad-Level Math Benchmark for Large Language Models [Report]
-
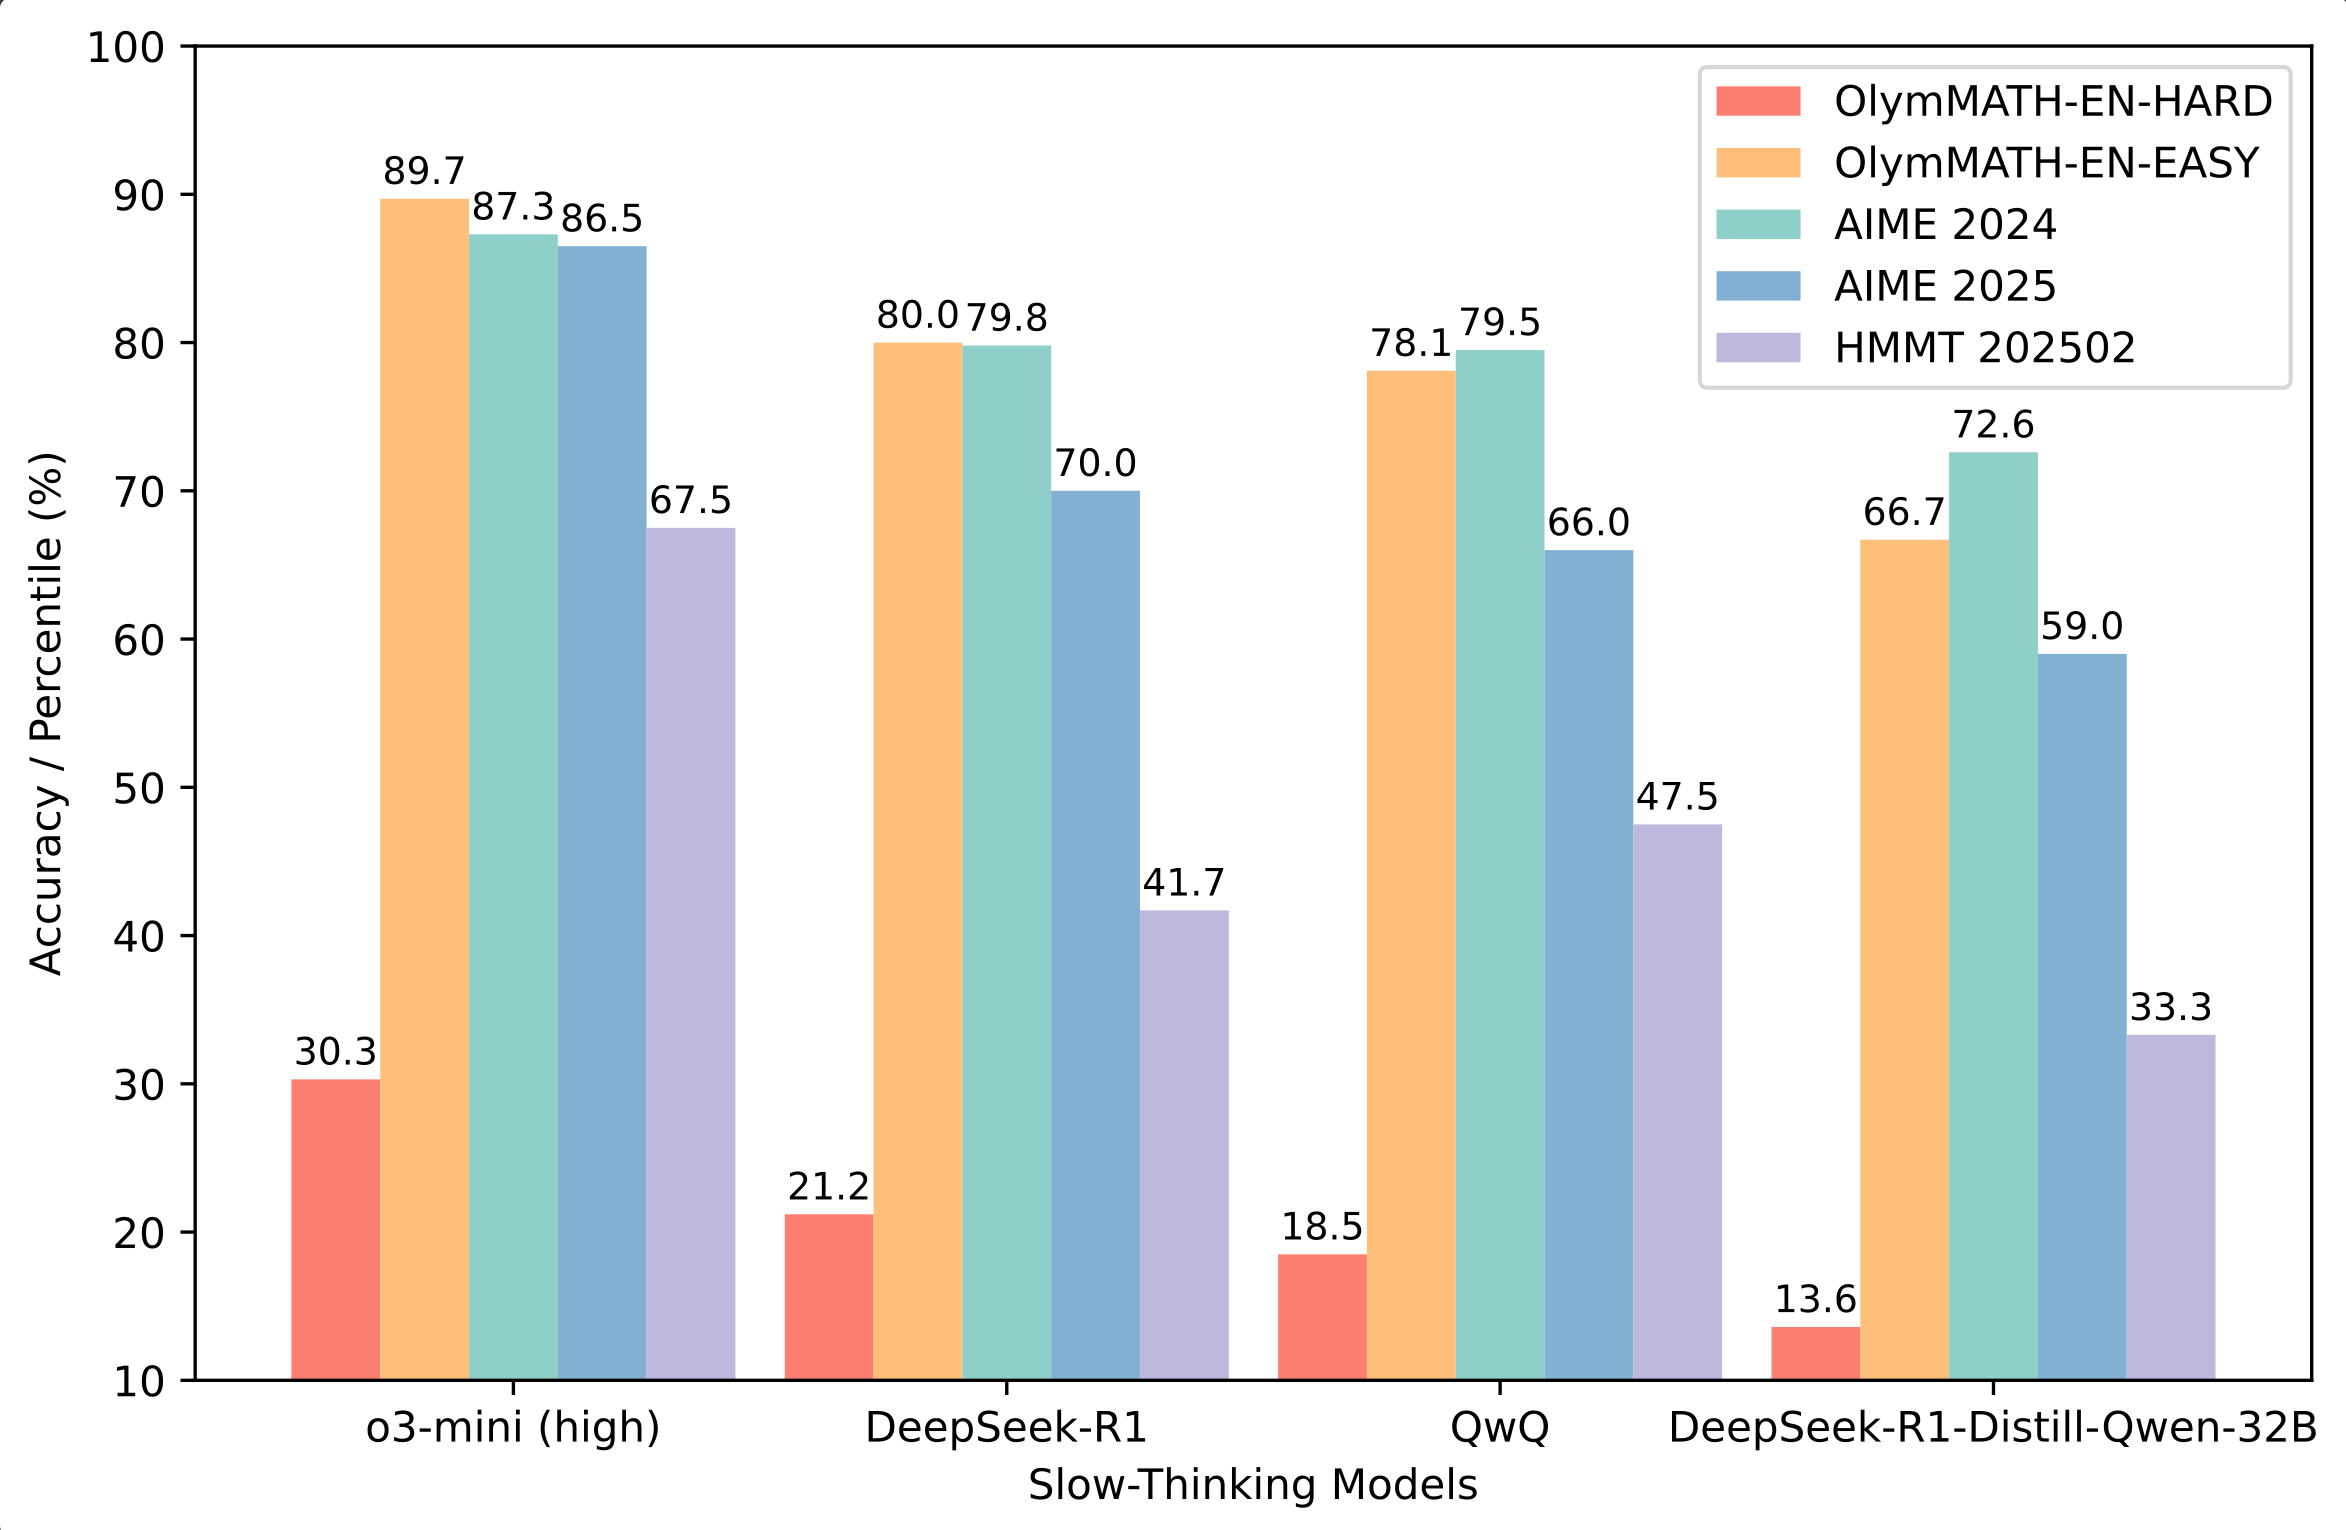
🧮 We introduce OlymMATH, a meticulously curated benchmark of 200 high-quality Olympiad-level math problems spanning algebra, geometry, number theory, and combinatorics.
-
🌐 Our benchmark features fully parallel English and Chinese problem sets (OlymMATH-EN and OlymMATH-ZH), enabling comprehensive multilingual evaluation of mathematical reasoning capabilities.
-
📊 OlymMATH is strategically divided into two difficulty levels: The EASY subset closely aligns with AIME-level difficulty, providing an effective evaluation for standard reasoning approaches The HARD subset is specifically designed to challenge state-of-the-art reasoning models, pushing the boundaries of their capabilities.
-
🔍 Our experiments reveal that even the most advanced models struggle with OlymMATH-HARD, highlighting significant room for improvement in mathematical reasoning.
-
🧠 We observe that LLMs often resort to empirical guessing rather than rigorous reasoning, using pattern matching, heuristic methods, or proposition simplification to arrive at answers without systematic derivation. OlymMATH-HARD effectively challenges these "shortcut" approaches, as its complex problems require deeper mathematical understanding.
R1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning [Report]
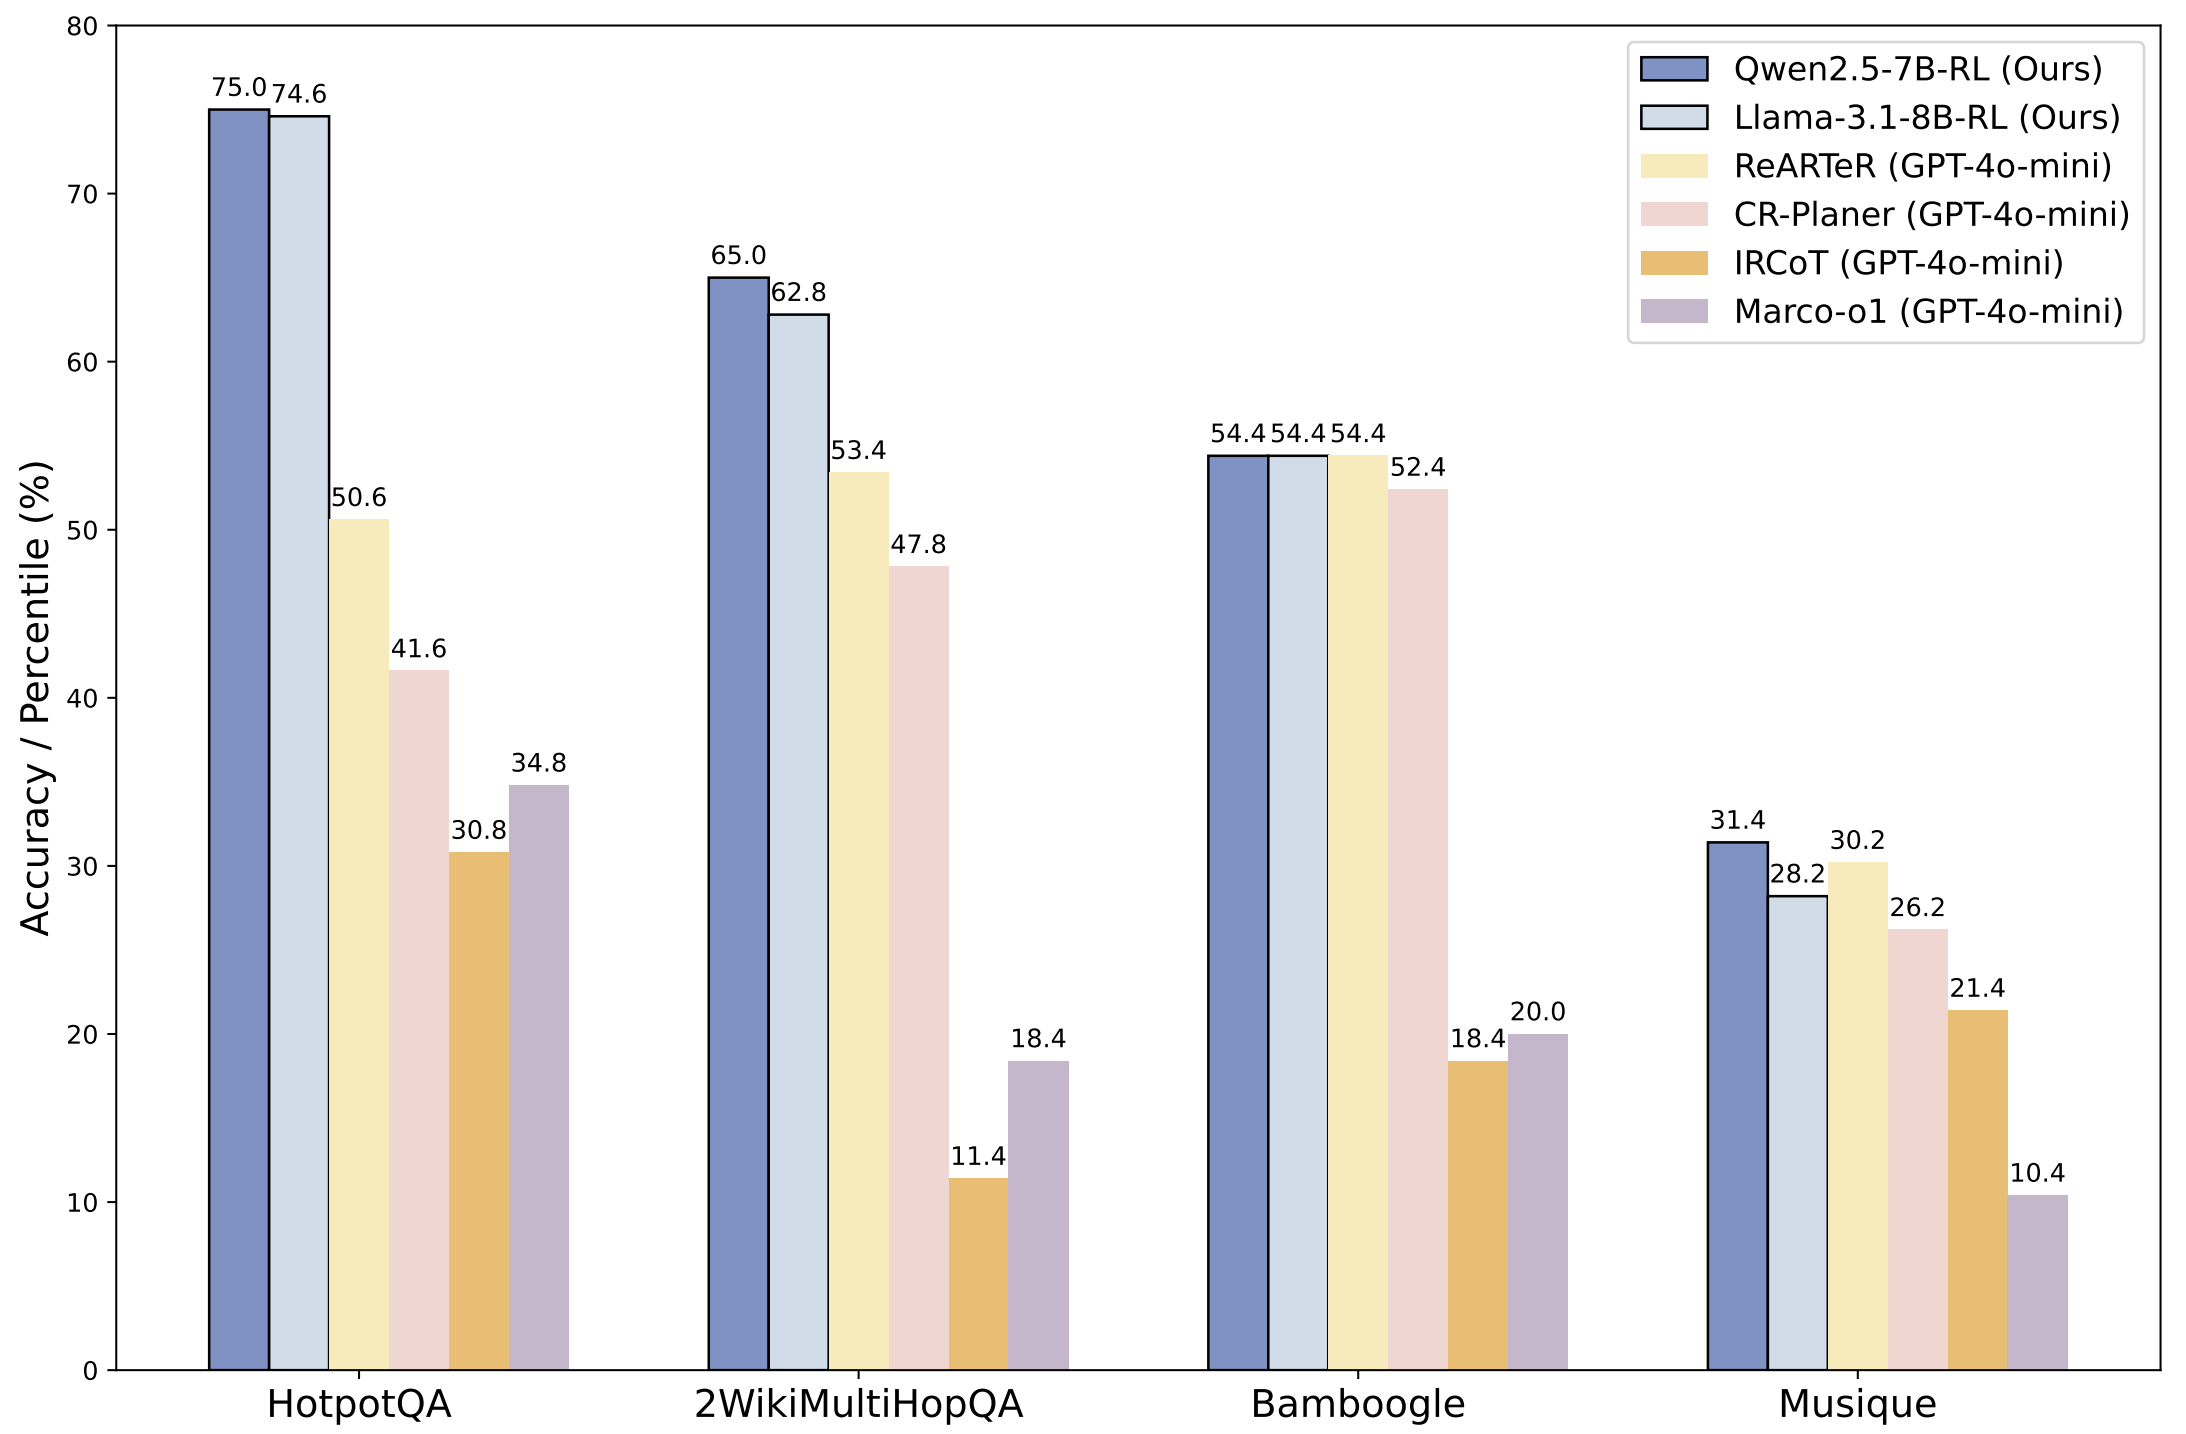
- The core motivation lies in incentivizing the search capabilities of large language models (LLMs) by enabling exploration within an external retrieval environment. A two-stage outcome-based reinforcement learning (RL) framework is designed to guide the model in freely exploring how to invoke an external retrieval system for acquiring relevant information.
- The proposed methodology relies solely on outcome-based reinforcement learning, eliminating the need for distillation techniques or cold-start strategies based on supervised fine-tuning (SFT). Moreover, it is effective for both base models (zero-shot) and fine-tuned models.
- A modified RL training method is introduced, building on Reinforce++ with RAG-based rollout and retrieval mask-based loss calculation. The RAG-based rollout strategy enhances the model's ability to utilize retrieved information effectively during the reasoning process. Additionally, retrieval mask-based loss calculation ensures precise capture of the relevance of retrieved information during training while minimizing interference from irrelevant data.
- 🔥 Here are our model: Qwen-2.5-7B-Base-RL and Llama-3.1-8B-Instruct-RL, code and data.
STILL-3: An Empirical Study on Eliciting and Improving R1-like Reasoning Models [Report]
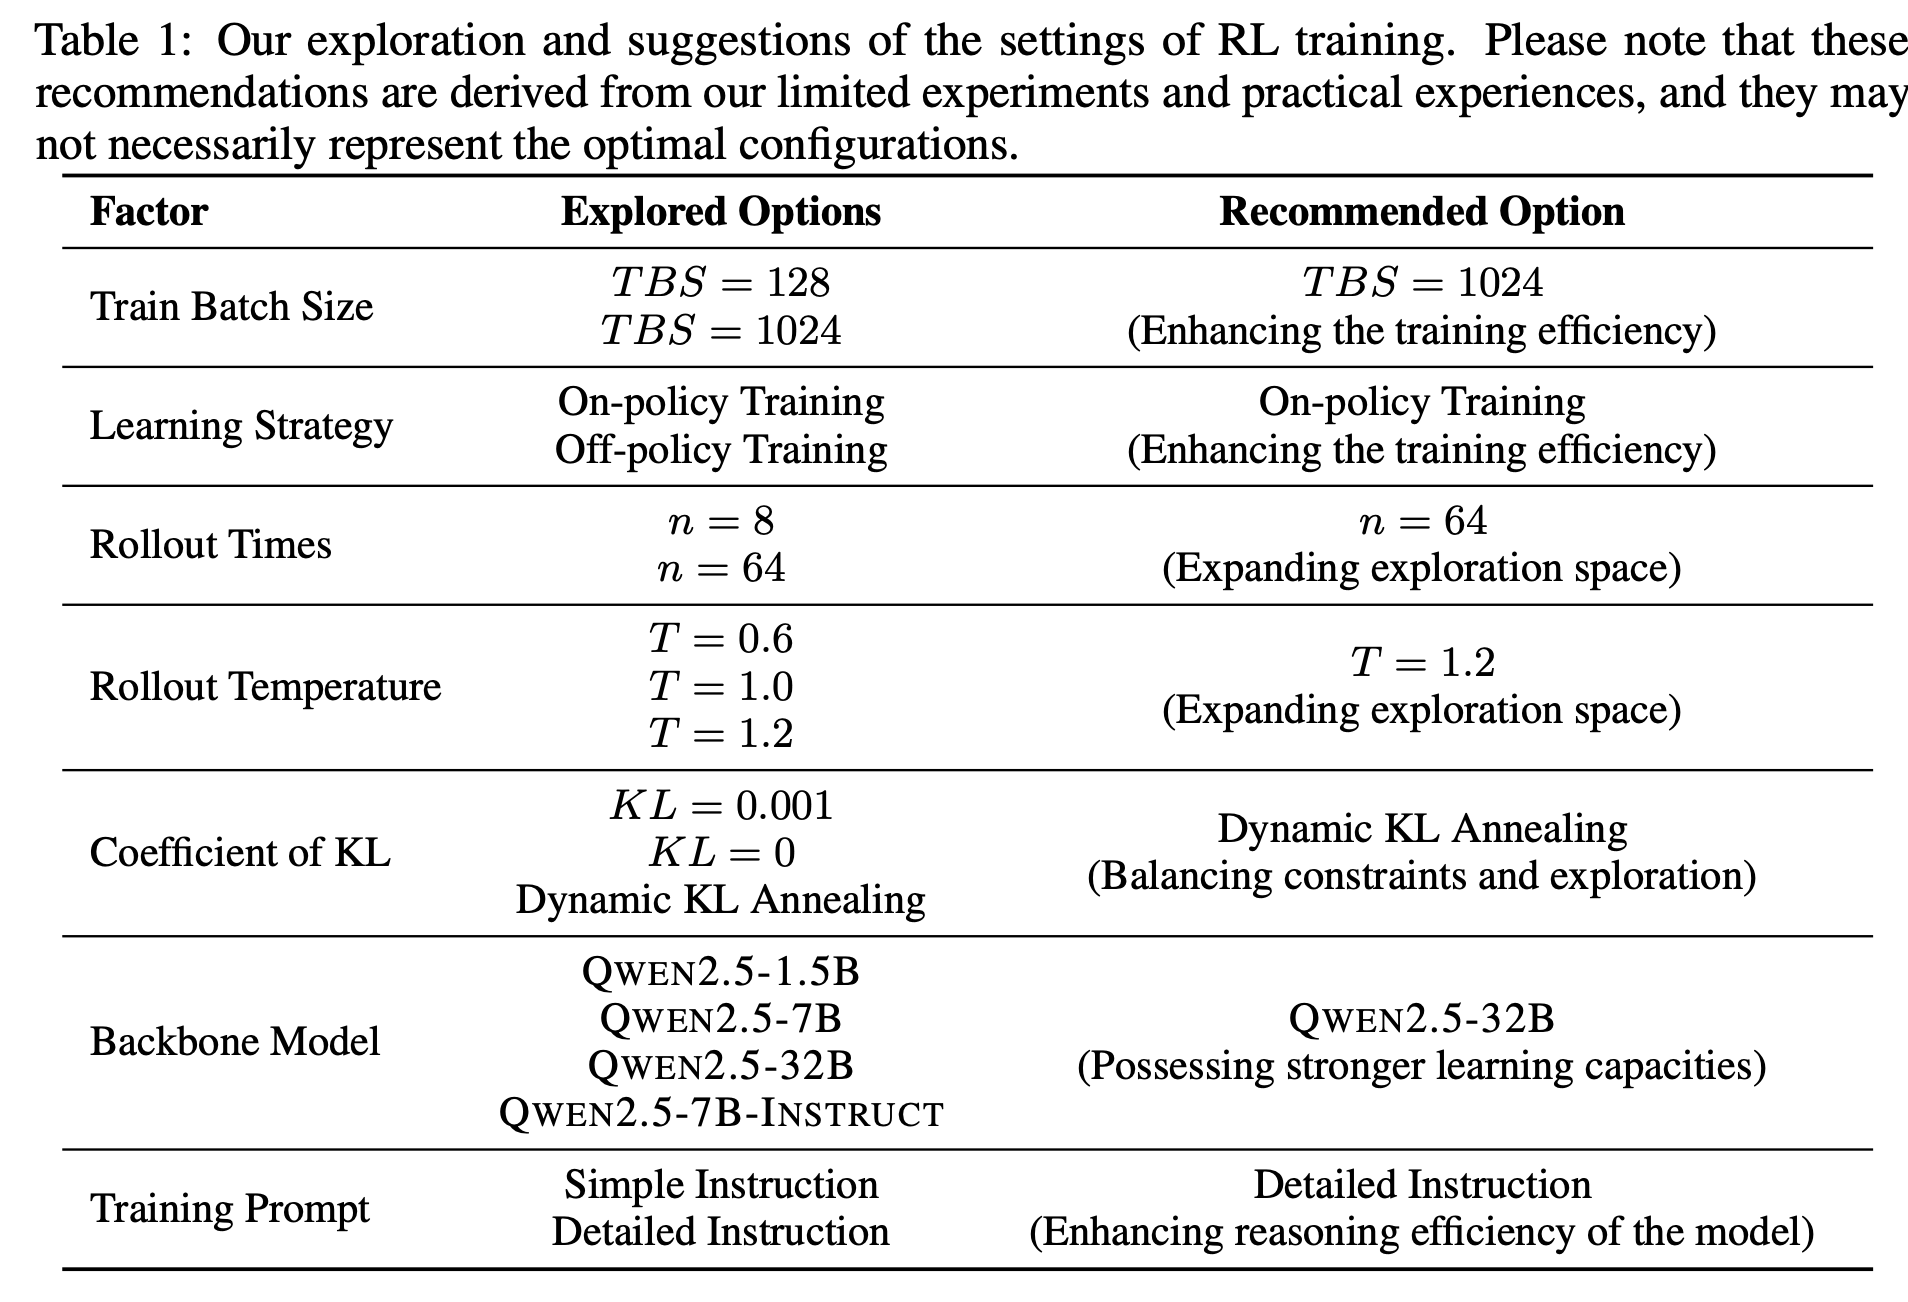
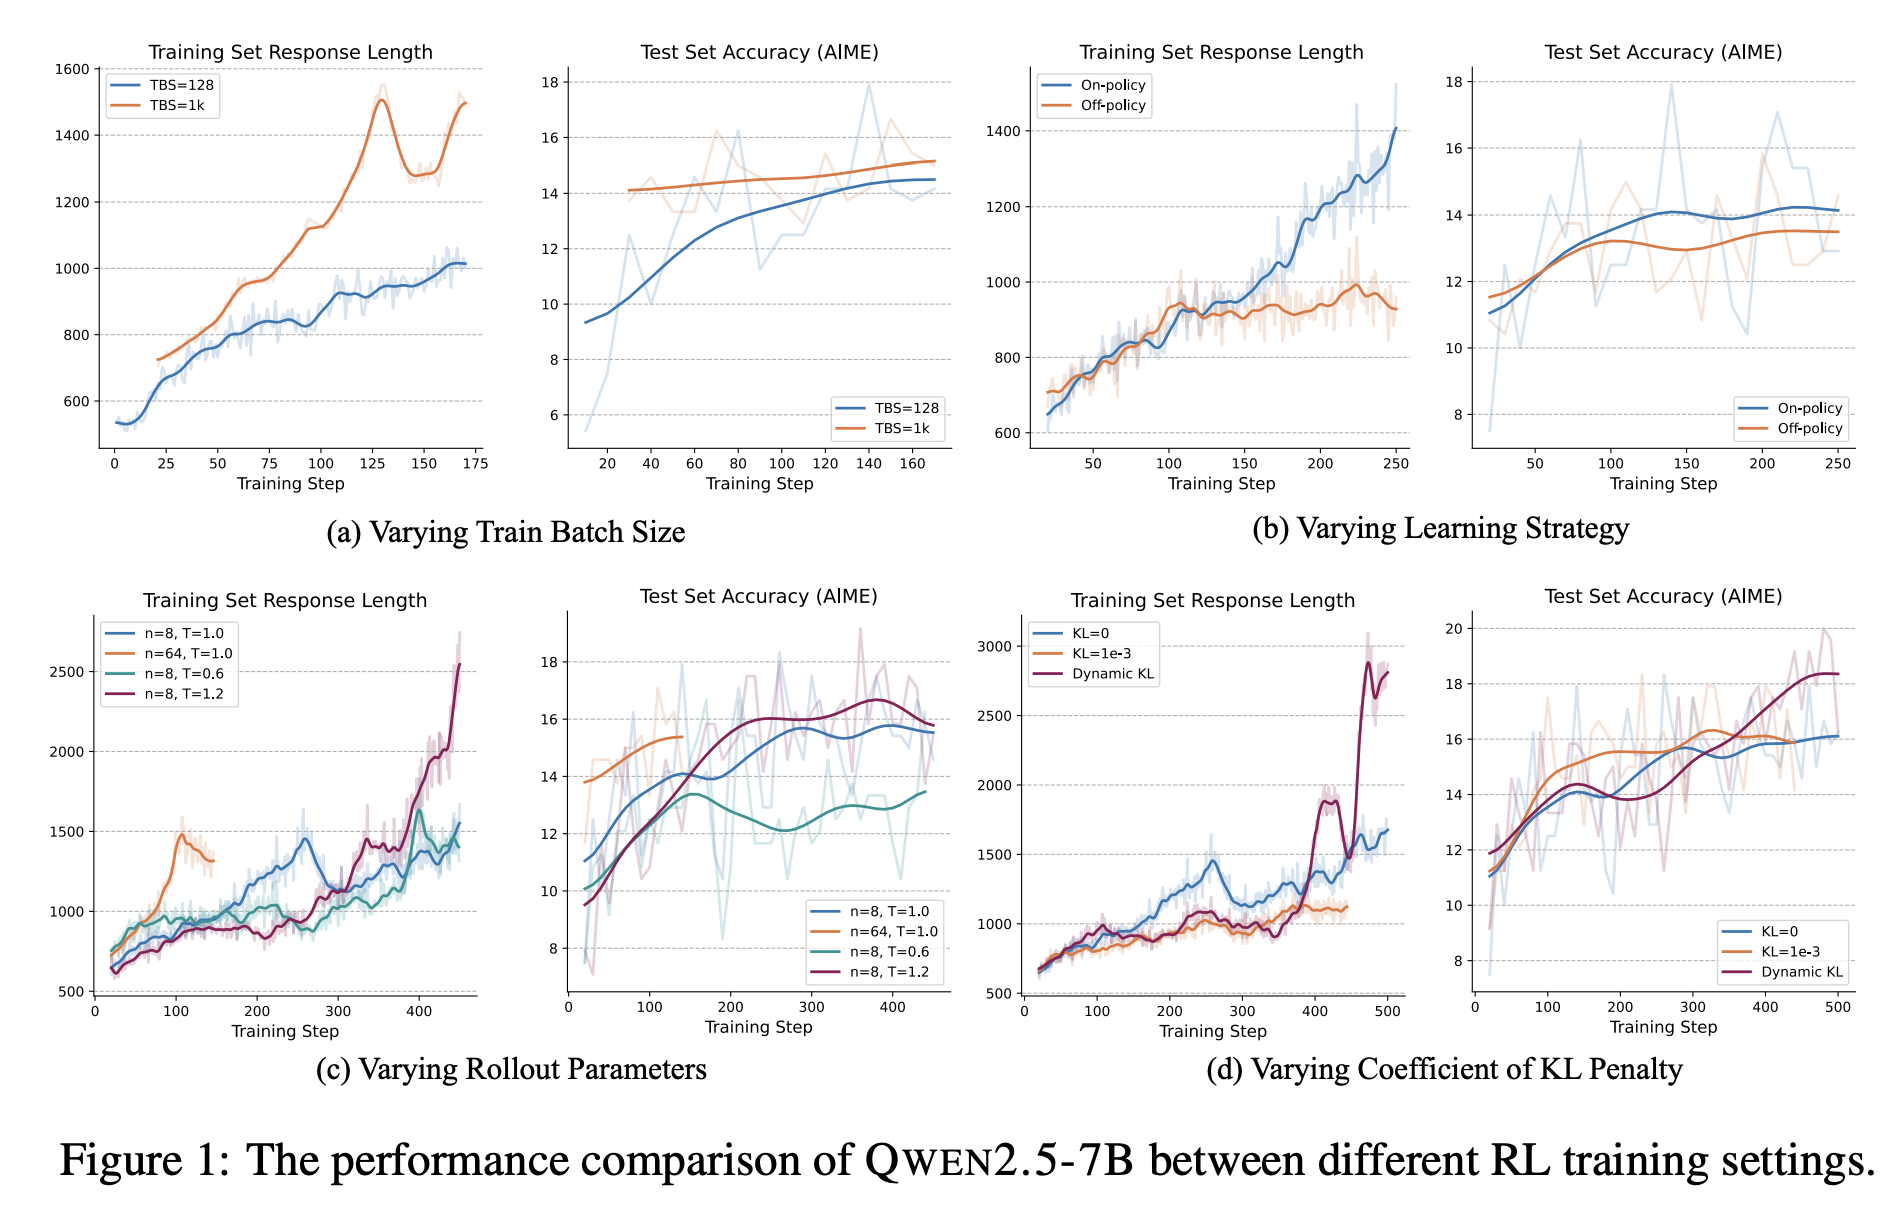
- The performance of large reasoning models is heavily influenced by the settings of RL.
- We thoroughly investigate and document these effects by testing a range of parameter configurations. Following this, we provide a recommendation for RL training.
- After pre-training, the base models already exhibit the potential to perform individual complex reasoning actions. The RL process effectively activates this capability, enabling the model to integrate these actions into a coherent and deliberate thinking process.
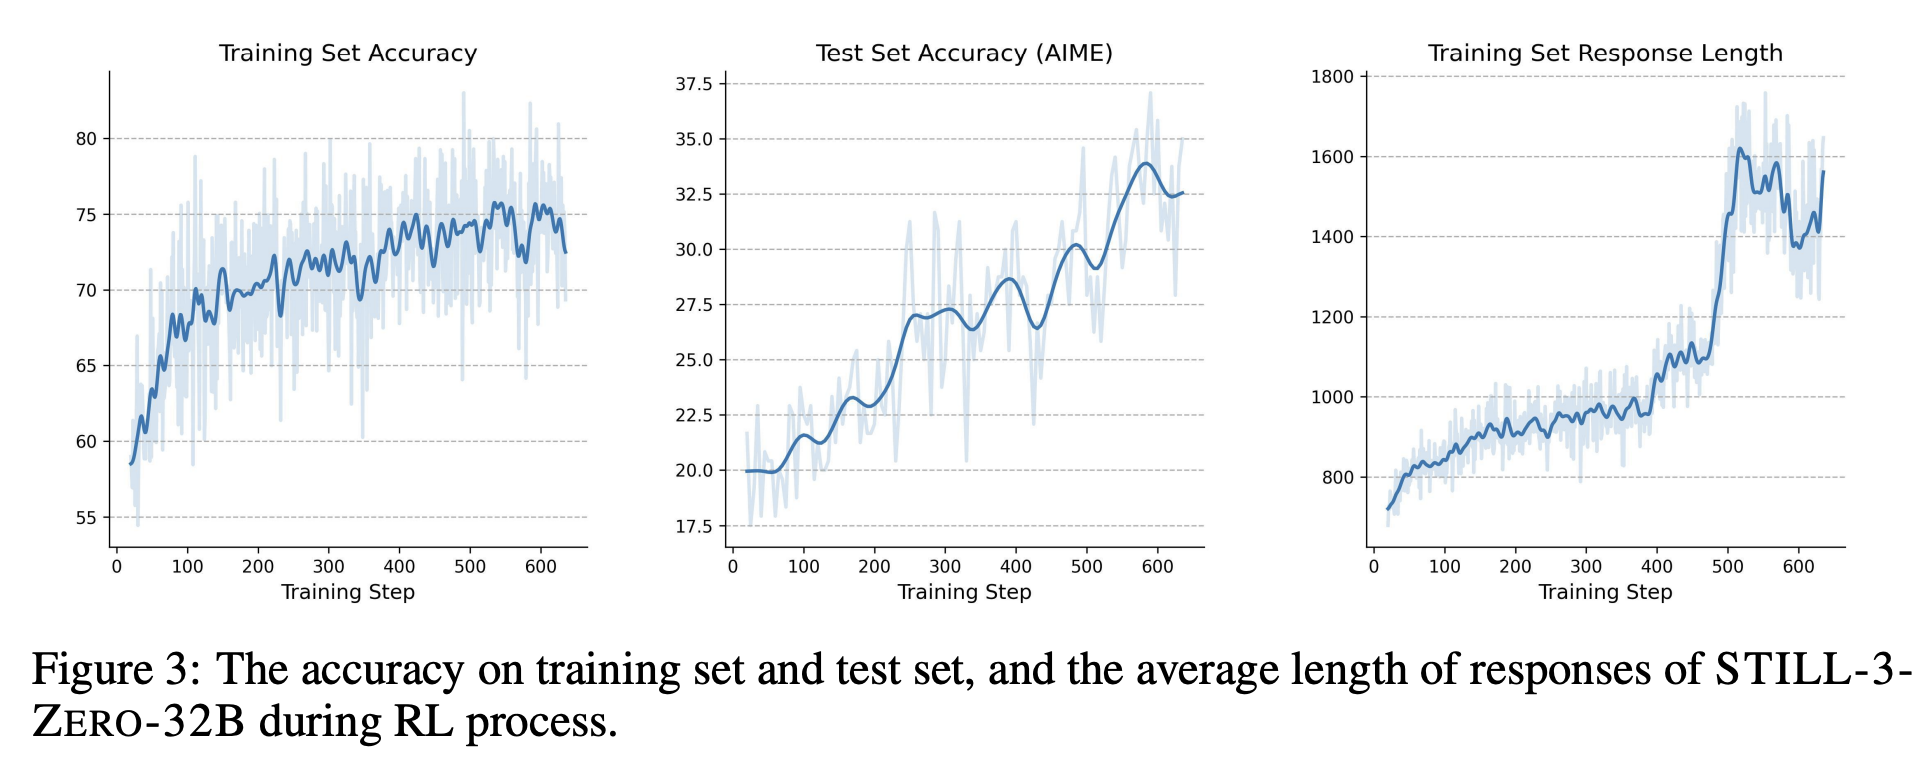
- Our RL training approach consistently improves the QWEN2.5-32B base model, enhancing both response length and test accuracy.
- Response length serves as an important indicator of the success of RL training; however, it is a consequence, not a cause, of performance improvement. Designing specialized reward functions to explicitly encourage the model to produce longer responses may lead to issues such as reward hacking, which can’t inherently enhance the model’s reasoning capabilities.
- RL training consistently improves the performance of fine-tuned models, encompassing both short and long CoT reasoning models.
- Even after Qwen2.5-1.5B attains a high level of performance through training with distilled data, RL training further elevates its capabilities, achieving a remarkable accuracy of 39.33 on AIME 2024 (STILL-3-1.5B-Preview).
- Through supervised fine-tuning, LRMs can acquire the capability to manipulate external tools, leading to a significant enhancement in the model’s performance.
- By effectively utilizing tool manipulation, STILL-3-TOOL-32B achieves an impressive accuracy of 86.67 (greedy search) on AIME 2024.
- Remarkably, this ability can be activated with only a small number of high-quality training instances.
- We will soon open-source our model, code, and data.
✨ STILL-3-Tool-32B: Empowering Reasoning Models with Wings: Tool Manipulation Significantly Enhances the Reasoning Ability of O1- and R1-like LLMs
- 🧑💻 We attempt to activate the tool manipulation capability of the long CoT thinking model, enabling it to spontaneously generate code and call upon tools to assist in the problem-solving process.
- 📈 To our surprise, we find that our approach outperform the comparative baseline models (such as DeepSeek-R1, o1, o3-mini-medium) on AIME 24, and its average performance across three math competitions was on par with DeepSeek-R1!
- 📝 We have detailed the training process, data construction, and case studies of STILL-3-Tool-32B in our Notion page.
- 🔥 Here are our model, code and data.
🚀 STILL-3-1.5B-Preview: A 1.5B slow-thinking reasoning model continuously evolving through RL.
- To delve deeper into the potential of reinforcement learning, we applied this training method to the publicly released SFT model by DeepSeek, known as DeepSeek-R1-Distill-Qwen-1.5B, which has enhanced by complex reasoning capacities.
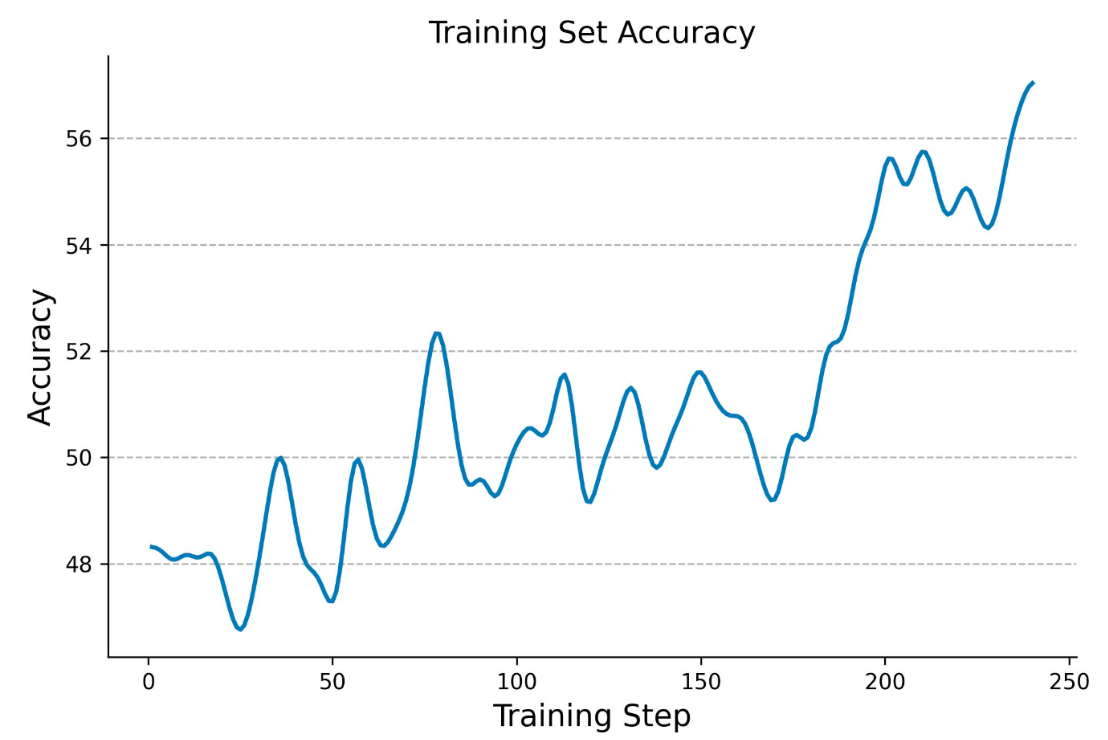
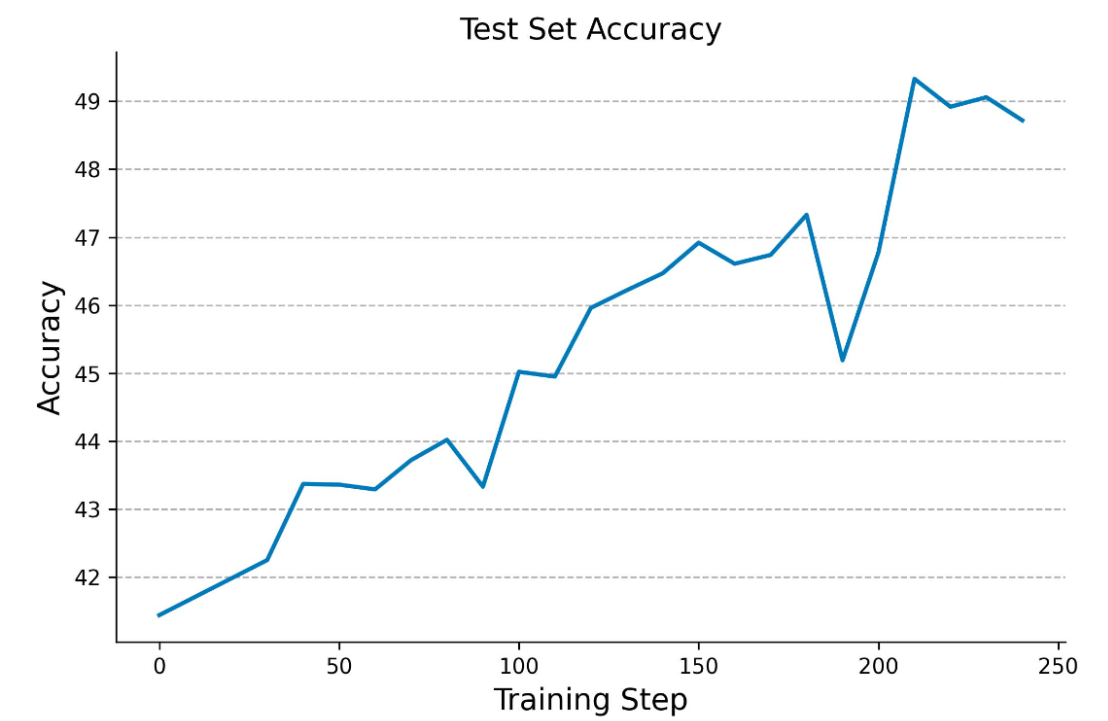
- Throughout the RL process, we noticed a progressive expansion in both the training and test sets. This led to a substantial enhancement in the model's reasoning skills, culminating in a 39.33% accuracy score on the American Invitational Mathematics Examination (AIME) leaderboard.
- We are open-sourcing all of the relevant code (based on OpenRLHF), model, and training data (30k from MATH,NuminaMathCoT, and AIME 1983-2023) to foster further research and development in the field of reinforcement learning algorithms.
We evaluated the model on four benchmarks: MATH, AIME, OMNI, and LiveAOPS. For MATH and AIME, we employed a sampling decoding setup with a sampling temperature of 0.6 and a top-p sampling probability of 0.95. Each question was sampled 64 times, and the average score was calculated. For OMNI and LiveAOPS (August-November 2024), we randomly sampled a subset of answers as integers to facilitate automated evaluation, and used greedy search decoding for the evaluation. The trained model, STILL-3-1.5B-preview, achieved significant improvement. The accuracy on the AIME task increased from 28.67% to 39.33%, resulting in a relative improvement of 37.18%.
| MATH | AIME | OMNI | LiveAOPS | Avg. | |
|---|---|---|---|---|---|
| Qwen-2.5-Math-7B-Instruct | 83.60 | 16.67 | - | - | - |
| Qwen-2.5-Math-72B-Instruct | 85.90 | 30.00 | - | - | - |
| O1-preview | 85.50 | 44.60 | - | - | - |
| STILL-2 | 90.20 | 46.67 | - | - | - |
| QwQ-32B | 90.60 | 50.00 | - | - | - |
| DeepSeek-R1-Distill-Qwen-1.5B | 84.04 | 28.67 | 25.60 | 33.33 | 42.91 |
| STILL-3-1.5B-preview | 85.48 | 39.33 | 33.00 | 39.50 | 49.33 |
🚀 Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems [Report]
-
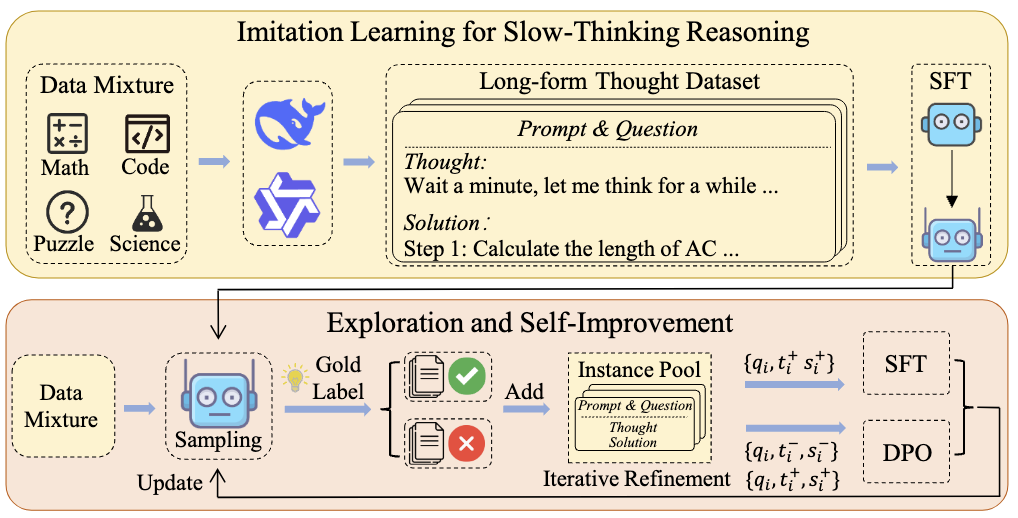
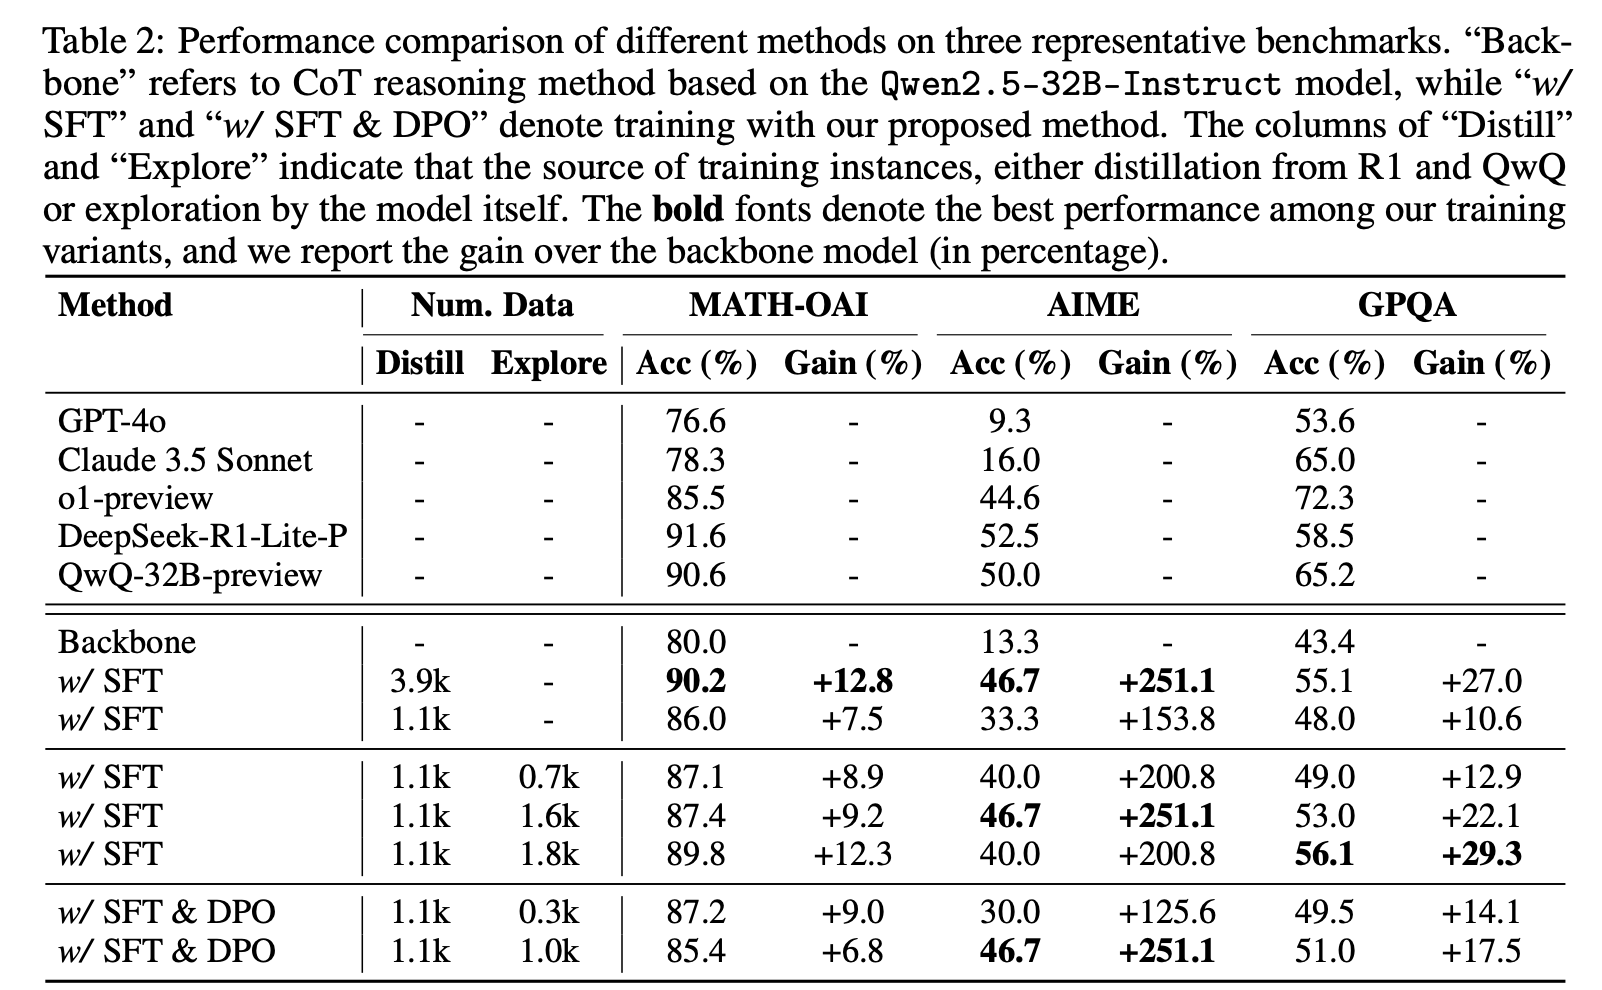
Slow-thinking reasoning systems, such as o1, have demonstrated remarkable capabilities in solving complex reasoning tasks, and are primarily developed and maintained by industry, with their core techniques not publicly disclosed. This paper presents a reproduction report on implementing o1-like reasoning systems. We introduce an imitate, explore, and self-improve framework as our primary technical approach to train the reasoning model. In the initial phase, we use distilled long-form thought data to fine-tune the reasoning model, enabling it to invoke a slow-thinking mode. The model is then encouraged to explore challenging problems by generating multiple rollouts, which can result in increasingly more high-quality trajectories that lead to correct answers. Furthermore, the model undergoes self-improvement by iteratively refining its training dataset.
Quick Start
from transformers import AutoTokenizer, AutoModelForCausalLM
from vllm import LLM, SamplingParams

# Load model and tokenizer
model_path = "RUC-AIBOX/STILL-2"
tokenizer = AutoTokenizer.from_pretrained(model_path)

# PROMPT
PROMPT = 'Your role as an assistant involves thoroughly exploring questions through a systematic long thinking process before providing the final precise and accurate solutions. This requires engaging in a comprehensive cycle of analysis, summarizing, exploration, reassessment, reflection, backtracing, and iteration to develop well-considered thinking process.\n\nPlease structure your response into two main sections: Thought and Solution.\n\nIn the Thought section, detail your reasoning process using the specified format:\n\n```\n<|begin_of_thought|>\n{thought with steps seperated with "\n\n"}\n<|end_of_thought|>\n```\n\nEach step should include detailed considerations such as analisying questions, summarizing relevant findings, brainstorming new ideas, verifying the accuracy of the current steps, refining any errors, and revisiting previous steps. Try to use casual, genuine phrases like: "Hmm...", "This is interesting because...", "Wait, let me think about...", "Actually...", "Now that I look at it...", "This reminds me of...", "I wonder if...", "But then again...", "Let\'s see if...", "Alternatively...", "Let\'s summaize existing information...", "This might mean that...", "why/how/when/where...", etc, to make your thought process be coherent, clear, and logically sound, effectively simulating human cognitive processes.\n\nIn the Solution section, based on various attempts, explorations, and reflections from the Thought section, systematically present the final solution that you deem correct. The solution should remain a logical, accurate, concise expression style and detail necessary step needed to reach the conclusion, formatted as follows:\n\n```\n<|begin_of_solution|>\n{final formatted, precise, and clear solution}\n<|end_of_solution|>\n```\n\nNow, try to solve the following question through the above guidlines:\n'

# Input text
question = "Convert the point $(0,3)$ in rectangular coordinates to polar coordinates.  Enter your answer in the form $(r,\\theta),$ where $r > 0$ and $0 \\le \\theta < 2 \\pi.$"

input_prompts = tokenizer.apply_chat_template(
    [{"role": "user", "content": PROMPT + question}],
    tokenize=False,
    add_generation_prompt=True,
)

# Params
stop_words = ["<|im_end|>", "<|endoftext|>"]

llm = LLM(
    model=model_path,
    tensor_parallel_size=8,
    max_model_len=int(1.5 * 20000),
    gpu_memory_utilization=0.95,
    dtype="bfloat16",
)

sampling_params = SamplingParams(
    temperature=0,
    top_p=1.0,
    max_tokens=20000,
    stop=stop_words,
    seed=42,
    skip_special_tokens=False,
)

# Completion
responses = llm.generate(input_prompts, sampling_params)
print(responses[0].outputs[0].text)
🚀 Enhancing LLM Reasoning with Reward-guided Tree Search [Report]
-
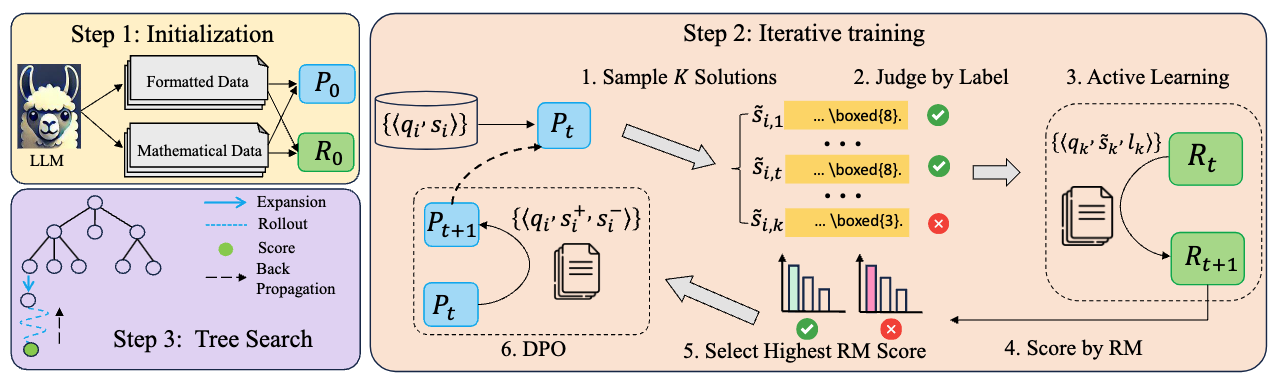
Recently, test-time scaling has garnered significant attention from the research community, largely due to the substantial advancements of the o1 model released by OpenAI. However, develop an o1-like reasoning approach is challenging, and researchers have been making various attempts to advance this open area of research. In this paper, we present a preliminary exploration into enhancing the reasoning abilities of LLMs through reward-guided tree search algorithms. This framework is implemented by integrating the policy model, reward model, and search algorithm. It is primarily constructed around a tree search algorithm, where the policy model navigates a dynamically expanding tree guided by a specially trained reward model.
🚀 Think More, Hallucinate Less: Mitigating Hallucinations via Dual Process of Fast and Slow Thinking [Report]
-
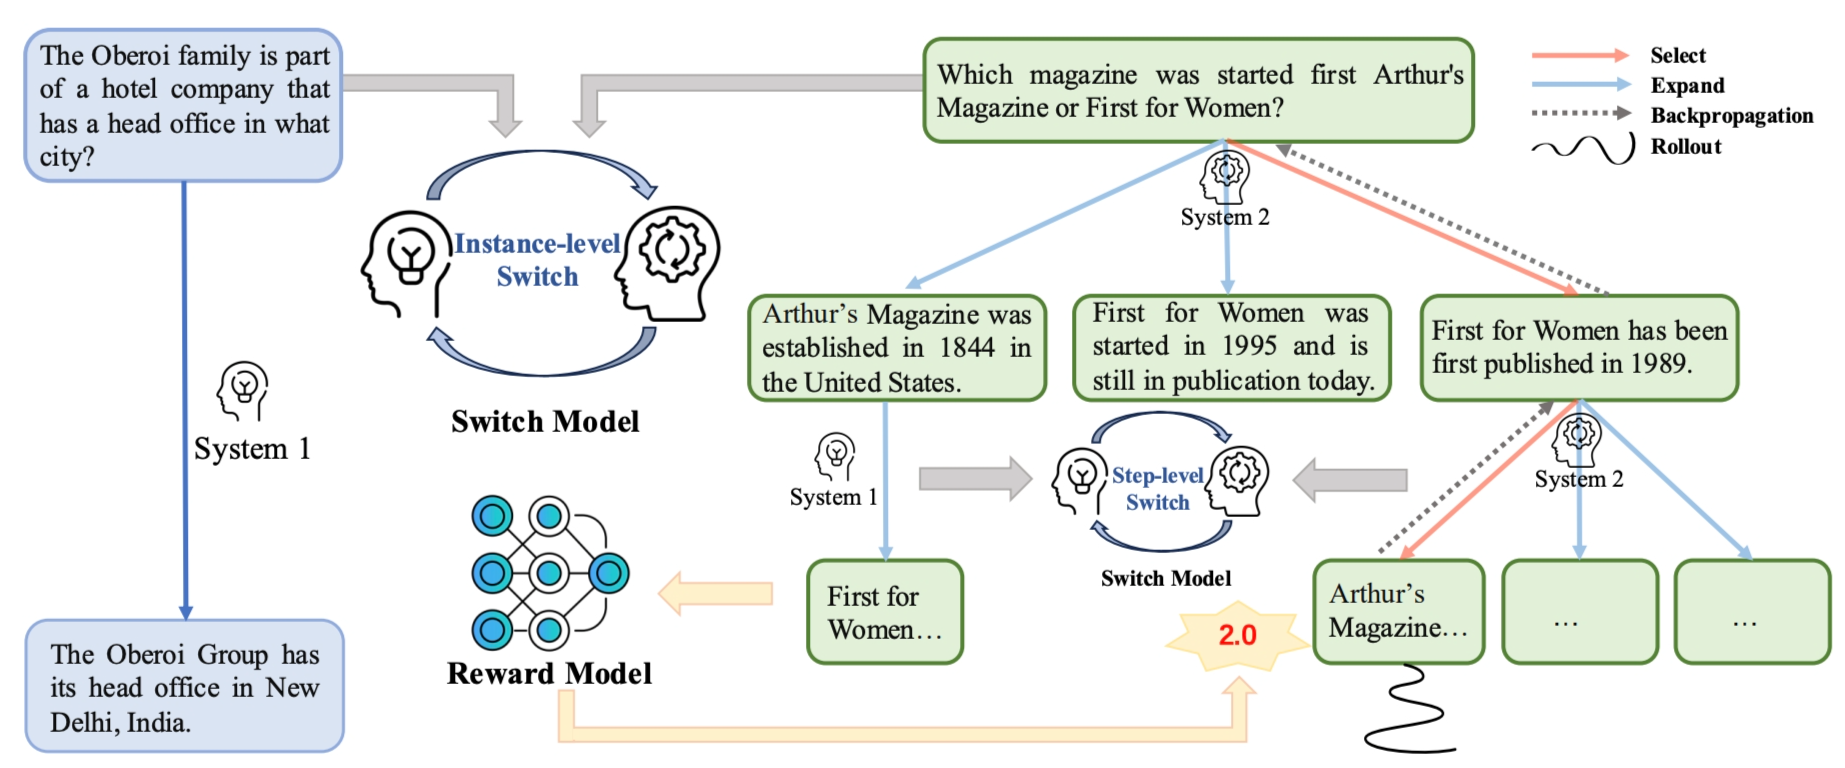
Large language models demonstrate exceptional capabilities, yet still face the hallucination issue. We propose HaluSearch, a novel framework that incorporates tree search-based algorithms to enable an explicit slow thinking generation process for mitigating hallucinations of LLMs during inference. HaluSearch frames text generation as a step-by-step reasoning process, using a self-evaluation reward model to score each generation step and guide the tree search towards the most reliable generation pathway. To balance efficiency and quality, we introduce a hierarchical thinking system switch mechanism inspired by the dual process theory in cognitive science, which dynamically alternates between fast and slow thinking modes at both the instance and step levels.
🚀 Virgo: A Preliminary Exploration on Reproducing o1-like MLLM [Report]
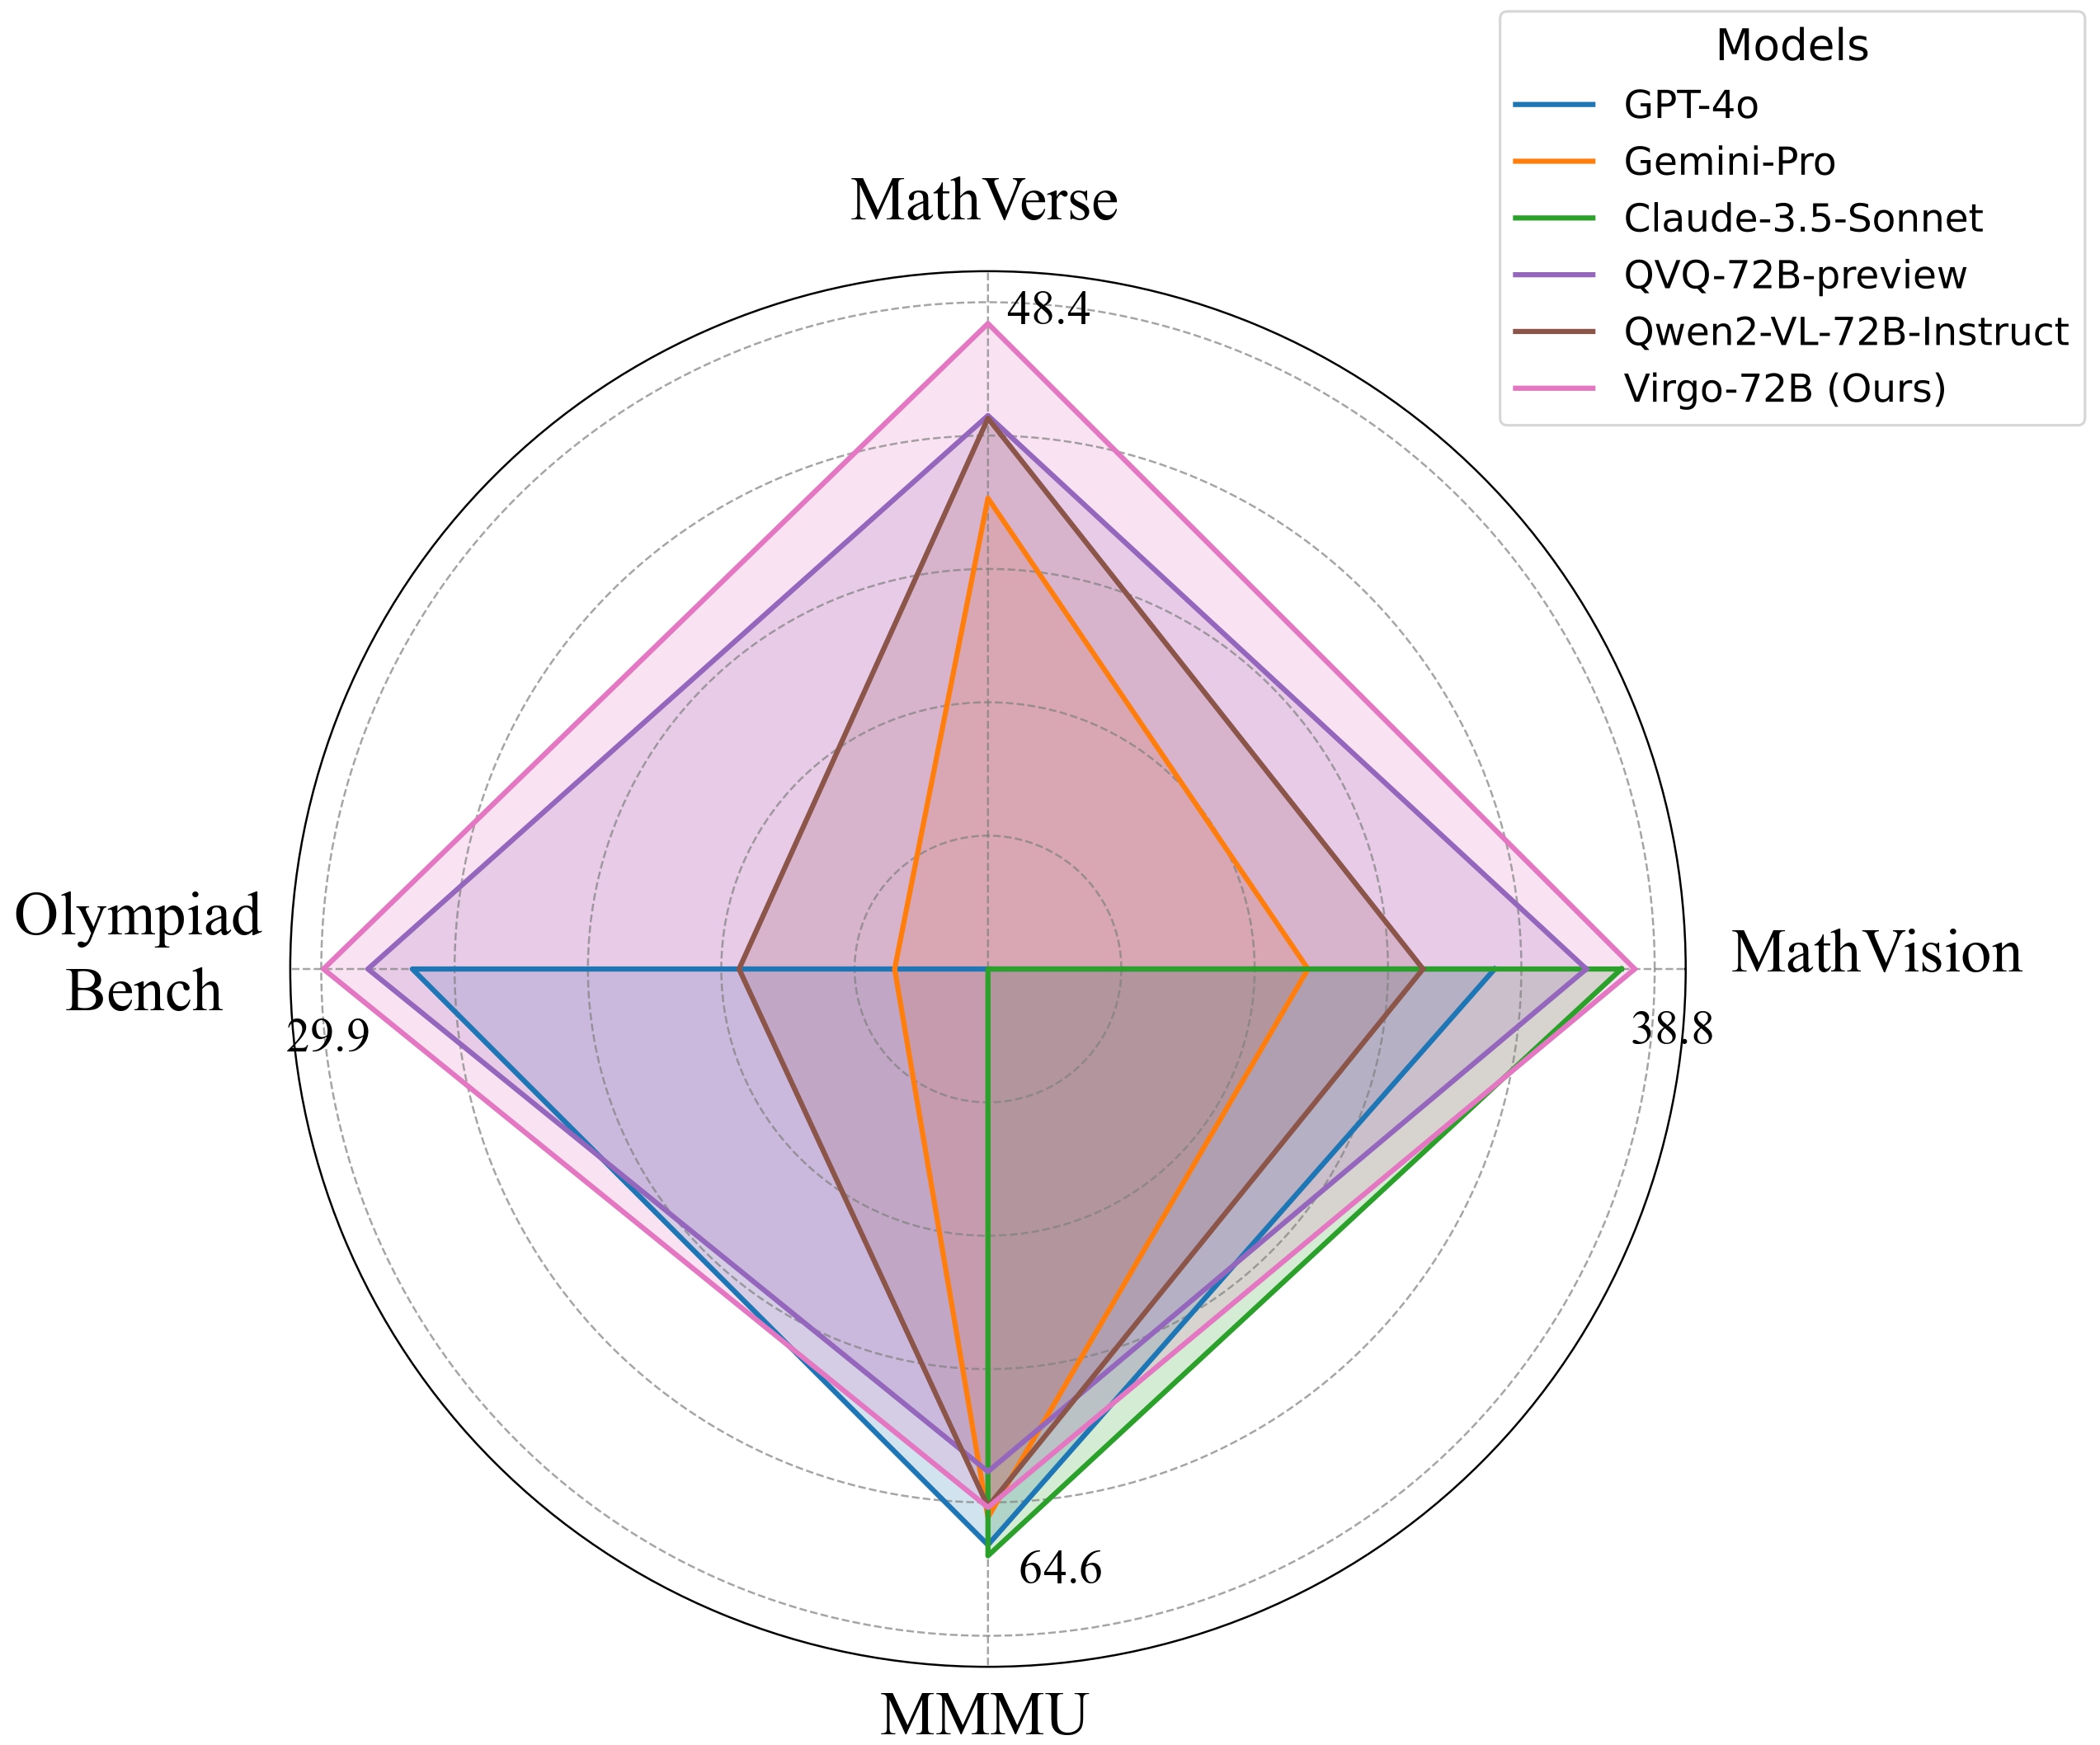
- There is a growing interest in reproducing o1-like MLLM in the research community. We explore a straightforward approach by fine-tuning a capable MLLM with a small amount of textual long-form thought data, resulting in a multimodal slow-thinking model, Virgo (Visual reasoning with long thought). We find that these long-form reasoning processes, expressed in natural language, can be effectively transferred to MLLMs. Moreover, it seems that such textual reasoning data can be even more effective than visual reasoning data in eliciting the slow-thinking capacities of MLLMs.
Future Work
Despite the promising results, our exploration remains preliminary, and there is still a substantial capacity gap compared to industry-level systems. As future work, we plan to investigate how to scale our training approach and extend its capacity to more complex tasks.
As always, we are committed to keeping our technical approach open, and we will release the data, model, and other resources. We welcome collaboration and support in computational resources.
Acknowledgements
We would like to express our sincere gratitude to DataCanvas Alaya NeW and BAAI for their generous computational resources and support.
Additionally, we are deeply thankful for the OpenRLHF open-source training framework, which has provided an invaluable foundation for our work.
Reference
Please kindly cite our reports if they are helpful for your research.
@article{Slow_Thinking_with_LLMs_1,
  title={Enhancing LLM Reasoning with Reward-guided Tree Search},
  author={Jiang, Jinhao and Chen, Zhipeng and Min, Yingqian and Chen, Jie and Cheng, Xiaoxue and Wang, Jiapeng and Tang, Yiru and Sun, Haoxiang and Deng, Jia and Zhao, Wayne Xin and Liu, Zheng and Yan, Dong and Xie, Jian and Wang, Zhongyuan and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2411.11694},
  year={2024}
}
@article{Slow_Thinking_with_LLMs_2,
  title={Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems},
  author={Min, Yingqian and Chen, Zhipeng and Jiang, Jinhao and Chen, Jie and Deng, Jia and Hu, Yiwen and Tang, Yiru and Wang, Jiapeng and Cheng, Xiaoxue and Song, Huatong and Zhao, Wayne Xin and Liu, Zheng and Wang, Zhongyuan and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2412.09413},
  year={2024}
}
@article{Slow_Thinking_with_LLMs_3,
      title={An Empirical Study on Eliciting and Improving R1-like Reasoning Models},
      author={Chen, Zhipeng and Min, Yingqian and Zhang, Beichen  and Chen, Jie and Jiang, Jinhao and Cheng, Daixuan and Zhao, Wayne Xin and Liu, Zheng and Miao, Xu and Lu, Yang and Fang, Lei and Wang, Zhongyuan and Wen, Ji-Rong},
      journal={arXiv preprint arXiv:2503.04548},
      year={2025}
}
@article{cheng2025think,
  title={Think More, Hallucinate Less: Mitigating Hallucinations via Dual Process of Fast and Slow Thinking},
  author={Cheng, Xiaoxue and Li, Junyi and Zhao, Wayne Xin and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2501.01306},
  year={2025}
}
@article{du2025virgo,
      title={Virgo: A Preliminary Exploration on Reproducing o1-like MLLM},
      author={Yifan Du and Zikang Liu and Yifan Li and Wayne Xin Zhao and Yuqi Huo and Bingning Wang and Weipeng Chen and Zheng Liu and Zhongyuan Wang and Ji-Rong Wen},
      journal={arXiv preprint arXiv:2501.01904},
      year={2025}
}
@article{R1-searcher,
  title={R1-searcher:  Stimulating the Search Capability of LLM from Zero via Reinforcement Learning},
  author={Huatong Song, Jinhao Jiang, Yingqian Min, Jie Chen, Zhipeng Chen, Wayne Xin Zhao, Ji-Rong Wen, Yang Lu, Xu Miu},
  url={https://github.com/SsmallSong/R1-searcher},
  year={2025}
}
Star History
Contributors


Similar repos


Languages
Python
85.4%
Jupyter Notebook
10.1%
Shell
4.5%
A series of technical report on Slow Thinking with LLM
Python
769
133 commits
updated Aug 13, 2025
README
STILL: Slow Thinking with LLMs
We are STILL exploring the uncharted territory of o1-like reasoning systems.
Content List
- LLM Exploration Mechanism
- Code-Integrated Reasoning
- ICPC-Eval
- SimpleDeepSearcher
- OlymMATH
- R1-Searcher
- STILL-3
- Virgo
- STILL-Hallucination Mitigation
- STILL-2
- STILL-1
News
- [12 August 2025] LLM Exploration Mechanism: We systematically analyze LLM exploration mechanisms in RLVR, quantifying differences between SFT and RL, revealing entropy-performance dynamics, and proposing strategies to enhance exploration and training efficiency. We open-source our code in project page
- [2 June 2025] Code-Integrated Reasoning: We propose an improved tool-augmented reinforcement learning approach for code-integrated reasoning that balances exploration and stability, achieving strong performance on five mathematical benchmarks. We further provide an in-depth analysis of the mechanisms behind code-integrated reasoning, explaining why and how it is effective. For More details, please refer to our Project Page and Model.
- [29 May 2025] ICPC-Eval: We introduce ICPC-Eval, a new benchmark of 118 ICPC problems for evaluating LLM reasoning in competitive coding, featuring realistic ICPC competition scenario, robust local evaluation, and a iterative repair metrics Refine@K. We open-source our dataset, evaluation code, and paper. For more details, please refer to our project page and huggingface 🤗.
- [11 April 2025] SimpleDeepSearcher: We propose the SimpleDeepSearcher framework, which aims to stimulate autonomous web search capabilities in large language models through knowledge distillation and self-distillation. By leveraging powerful reasoning models and a real-world web search environment, we carefully curated and filtered 871 high-quality training examples, significantly enhancing model performance on complex information retrieval tasks and outperforming existing reinforcement learning approaches. All models and efficient fine-tuning datasets (0.5k and 0.8k) have been open-sourced.For more details, please refer to our project page and huggingface 🤗.
- [8 April 2025] ⚡️⚡️We open source our code and training data of STILL-3!
- [28 Mar 2025] OlymMATH: We introduce OlymMATH, a challenging benchmark of 200 Olympiad-level math problems across algebra, geometry, number theory, and combinatorics in both English and Chinese. Even the most advanced models achieve only moderate accuracy on OlymMATH-EN-HARD, highlighting significant room for improvement in mathematical reasoning. We open-source our dataset, evaluation code, and paper. For more details, please refer to our project page and huggingface 🤗.
- [9 Mar 2025] R1-Searcher: We propose R1-Searcher, a novel two-stage outcome-based RL approach designed to enhance the search capabilities of LLMs.
- This method allows LLMs to autonomously invoke external search systems to access additional knowledge during the reasoning process.
- Our framework relies exclusively on RL, without requiring process rewards or distillation for a cold start.
- We conduct training on both base models (zero-shot) and fine-tuned models, analyzing key research questions arising during the training process.
- **We open-source our models: Qwen-2.5-7B-Base-RL and Llama-3.1-8B-Instruct-RL, code and data.
- [7 Mar 2025] STILL-3: We propose STILL-3, An Empirical Study on Eliciting and Improving R1-like Reasoning Models.
- We systematically experiment with and document the effects of various factors influencing RL training, conducting experiments on both base models (zero) and fine-tuned models.
- Beyond RL training, we also explore the use of tool manipulation, finding that it significantly boosts the reasoning performance of large reasoning models.
- We open source our code and training data!
- [1 Mar 2025] STILL-3-Tool-32B: We propose STILL-3-Tool-32B, leveraging python code to help the reasoning process. During evaluation, STILL-3-Tool-32B achieves 81.70% accuracy on AIME 2024, matching the performance of o3-mini, outperforming o1 and DeepSeek-R1. We open-source our code, model, and data. For more details, please refer to our Notion page.
- [26 Jan 2025] STILL-3-1.5B-preview: We release STILL-3-1.5B-preview, a 1.5B slow-thinking reasoning model achieves 39.33% accuracy on AIME benchmark! We utilize 30k queries to adapt reinforcement learning on 1.5B model (DeepSeek-R1-Distill-Qwen-1.5B) and observe the continuous performance improvement as the number of training steps increased. For better reproducing our work and advancing research progress, we open-source our code, model, and data.
- [6 Jan 2025] Virgo: We develop Virgo, a multi-modal slow-thinking reasoning model, based on Qwen2-VL-72B-Instruct, which achieves leading performance on four challenging multi-modal benchmarks. We demonstrate that the slow-thinking reasoning ability can be transferred from text to vision. We open-source the model and training data.
- [3 Jan 2025] STILL-Hallucination Mitigation: We propose HaluSearch, a framework that integrates tree search algorithms and a dynamic system switch mechanism, inspired by dual process theory, to reduce LLM hallucinations during inference.
- [22 Dec 2024] We open-source part of the training data in Github or HuggingFace and the model for community researchers to use for research purposes.
- [12 Dec 2024] STILL-2: We preliminarily reproduce a slow-thinking reasoning system, achieving competitive performance compared to industry-level reasoning systems on these benchmarks! And we also release the technical report, which presents the details about our reproduction.
- [18 Nov 2024] STILL-1: We release our first technical report, where we leverage reward-guided tree search algorithm to assist LLM reasoning process and largely enhance the performance of LLM on complex reasoning tasks.
Detailed Contents
From Trial-and-Error to Improvement: A Systematic Analysis of LLM Exploration Mechanisms in RLVR [Report]
We conduct a comprehensive study on LLM exploration mechanisms in RLVR, aiming to quantify, characterize, and optimize how large language models explore solution spaces during complex problem-solving.
-
🔍 Core Focus & Analysis: We conduct a systematic analysis of the exploration capabilities of large language models (LLMs), examining key aspects such as the quantification of exploration boundaries, the interplay between entropy and performance, and strategies for enhancing data efficiency in reinforcement learning. Additionally, we compare the exploration behaviors of supervised fine-tuning (SFT) models, reinforcement learning (RL) models, and tool-integrated configurations, shedding light on their respective impacts on the breadth and efficiency of exploration.
-
🧠 Key Findings:
- SFT expands exploration boundaries, while RL sharpens single-attempt accuracy but constricts exploration scope.
- entropy-performance during RL dynamics shift with training stages (rising stage curbs errors to form reasoning patterns, plateau stage refines high-entropy key tokens), instance quality (low-PPL samples enable more robust learning), and token positions (later tokens exert greater influence on outcomes).
- RFT maintains exploration capacity through controlled noisy data injection and prioritization of high-entropy, high-branching-factor samples.
-
🚀 Strategies: We introduce PPL- and position-aware advantage shaping techniques to boost the training efficiency of rollout data in the RL process.
Towards Effective Code-Integrated Reasoning [Report]
We investigate Code-Integrated Reasoning, an approach where models generate and execute code during reasoning to enhance performance, particularly in complex mathematical tasks.
-
🔍 Challenges & Strategies: We identify key challenges in tool-augmented RL and develop strategies to balance exploration and stability during training, significantly improving training effectiveness.
-
📈 Performance: Our method demonstrates substantial performance gains, achieving state-of-the-art results across multiple benchmarks with an average accuracy of 52.4%, surpassing several competitive baselines.
-
💡 Mechanistic Insights: We further provide an in-depth analysis of the mechanisms behind code-integrated reasoning, explaining why and how it is effective in expanding model capabilities, improving reasoning efficiency, and providing valuable error feedback, with notable performance gains in specific problem types.
ICPC-Eval: Probing the Frontiers of LLM Reasoning with Competitive Programming Contests [Report]
-
🧠 We introduce a new benchmark ICPC-Eval designed to evaluate the reasoning ability of LLMs under realistic competitive programming environments, based on 118 curated problems from 11 recent ICPC regional contests worldwide.
-
🏆 It captures the true distribution of problem types and difficulty found in real ICPC contests—far more representative than synthetic benchmarks or filtered OJ tasks.
-
🔍 To overcome the limitations of metrics like Pass@K, we propose Refine@K, an execution-feedback-driven metric that measures iterative code refinement and simulates how models improve solutions over multiple attempts—more aligned with human competitive coding behavior.
-
🧰 We provide a robust local evaluation toolkit, along with high-quality test cases, enabling fast and accurate validation without relying on external online judges.
-
📉 Experimental results show that even state-of-the-art reasoning models like DeepSeek-R1 struggle to match top human teams and often require multi-turn code refinement to fully unlock their potential—highlighting the gap between LLMs and real-world competitive coders.
SimpleDeepSearcher: Deep Information Seeking via Web-Powered Reasoning Trajectory Synthesis [Notion]
-
🚀 To address the inefficiency and redundant reasoning of large models in complex information retrieval tasks, we curate and filter 871 high-quality samples from a real web search environment. By leveraging knowledge distillation and self-distillation on strong reasoning models, we achieve significant performance gains, surpassing existing reinforcement learning methods.
-
🌐 We construct a large-scale data synthesis pipeline based on real and open web environments, substantially enhancing the model's capability in handling complex and noisy search scenarios.
-
🎯 We fine-tune Qwen-2.5-7B-Instruct, Qwen-2.5-32B-Instruct, Dpsk-Distilled-Qwen-32B, and QwQ-32B. Our model outperforms existing baselines on five benchmarks (2WikiMultiHopQA, Bamboogle, Musique, FRAMES, GAIA), and demonstrates especially strong performance on the more challenging Frames and GAIA datasets.
-
💡 We also explore reinforcement learning on distilled models to continuously stimulate their capabilities, and observe several intriguing phenomena.
OlymMATH: Challenging the Boundaries of Reasoning: An Olympiad-Level Math Benchmark for Large Language Models [Report]
-
🧮 We introduce OlymMATH, a meticulously curated benchmark of 200 high-quality Olympiad-level math problems spanning algebra, geometry, number theory, and combinatorics.
-
🌐 Our benchmark features fully parallel English and Chinese problem sets (OlymMATH-EN and OlymMATH-ZH), enabling comprehensive multilingual evaluation of mathematical reasoning capabilities.
-
📊 OlymMATH is strategically divided into two difficulty levels: The EASY subset closely aligns with AIME-level difficulty, providing an effective evaluation for standard reasoning approaches The HARD subset is specifically designed to challenge state-of-the-art reasoning models, pushing the boundaries of their capabilities.
-
🔍 Our experiments reveal that even the most advanced models struggle with OlymMATH-HARD, highlighting significant room for improvement in mathematical reasoning.
-
🧠 We observe that LLMs often resort to empirical guessing rather than rigorous reasoning, using pattern matching, heuristic methods, or proposition simplification to arrive at answers without systematic derivation. OlymMATH-HARD effectively challenges these "shortcut" approaches, as its complex problems require deeper mathematical understanding.
R1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning [Report]
- The core motivation lies in incentivizing the search capabilities of large language models (LLMs) by enabling exploration within an external retrieval environment. A two-stage outcome-based reinforcement learning (RL) framework is designed to guide the model in freely exploring how to invoke an external retrieval system for acquiring relevant information.
- The proposed methodology relies solely on outcome-based reinforcement learning, eliminating the need for distillation techniques or cold-start strategies based on supervised fine-tuning (SFT). Moreover, it is effective for both base models (zero-shot) and fine-tuned models.
- A modified RL training method is introduced, building on Reinforce++ with RAG-based rollout and retrieval mask-based loss calculation. The RAG-based rollout strategy enhances the model's ability to utilize retrieved information effectively during the reasoning process. Additionally, retrieval mask-based loss calculation ensures precise capture of the relevance of retrieved information during training while minimizing interference from irrelevant data.
- 🔥 Here are our model: Qwen-2.5-7B-Base-RL and Llama-3.1-8B-Instruct-RL, code and data.
STILL-3: An Empirical Study on Eliciting and Improving R1-like Reasoning Models [Report]
- The performance of large reasoning models is heavily influenced by the settings of RL.
- We thoroughly investigate and document these effects by testing a range of parameter configurations. Following this, we provide a recommendation for RL training.
- After pre-training, the base models already exhibit the potential to perform individual complex reasoning actions. The RL process effectively activates this capability, enabling the model to integrate these actions into a coherent and deliberate thinking process.
- Our RL training approach consistently improves the QWEN2.5-32B base model, enhancing both response length and test accuracy.
- Response length serves as an important indicator of the success of RL training; however, it is a consequence, not a cause, of performance improvement. Designing specialized reward functions to explicitly encourage the model to produce longer responses may lead to issues such as reward hacking, which can’t inherently enhance the model’s reasoning capabilities.
- RL training consistently improves the performance of fine-tuned models, encompassing both short and long CoT reasoning models.
- Even after Qwen2.5-1.5B attains a high level of performance through training with distilled data, RL training further elevates its capabilities, achieving a remarkable accuracy of 39.33 on AIME 2024 (STILL-3-1.5B-Preview).
- Through supervised fine-tuning, LRMs can acquire the capability to manipulate external tools, leading to a significant enhancement in the model’s performance.
- By effectively utilizing tool manipulation, STILL-3-TOOL-32B achieves an impressive accuracy of 86.67 (greedy search) on AIME 2024.
- Remarkably, this ability can be activated with only a small number of high-quality training instances.
- We will soon open-source our model, code, and data.
✨ STILL-3-Tool-32B: Empowering Reasoning Models with Wings: Tool Manipulation Significantly Enhances the Reasoning Ability of O1- and R1-like LLMs
- 🧑💻 We attempt to activate the tool manipulation capability of the long CoT thinking model, enabling it to spontaneously generate code and call upon tools to assist in the problem-solving process.
- 📈 To our surprise, we find that our approach outperform the comparative baseline models (such as DeepSeek-R1, o1, o3-mini-medium) on AIME 24, and its average performance across three math competitions was on par with DeepSeek-R1!
- 📝 We have detailed the training process, data construction, and case studies of STILL-3-Tool-32B in our Notion page.
- 🔥 Here are our model, code and data.
🚀 STILL-3-1.5B-Preview: A 1.5B slow-thinking reasoning model continuously evolving through RL.
- To delve deeper into the potential of reinforcement learning, we applied this training method to the publicly released SFT model by DeepSeek, known as DeepSeek-R1-Distill-Qwen-1.5B, which has enhanced by complex reasoning capacities.
- Throughout the RL process, we noticed a progressive expansion in both the training and test sets. This led to a substantial enhancement in the model's reasoning skills, culminating in a 39.33% accuracy score on the American Invitational Mathematics Examination (AIME) leaderboard.
- We are open-sourcing all of the relevant code (based on OpenRLHF), model, and training data (30k from MATH,NuminaMathCoT, and AIME 1983-2023) to foster further research and development in the field of reinforcement learning algorithms.
We evaluated the model on four benchmarks: MATH, AIME, OMNI, and LiveAOPS. For MATH and AIME, we employed a sampling decoding setup with a sampling temperature of 0.6 and a top-p sampling probability of 0.95. Each question was sampled 64 times, and the average score was calculated. For OMNI and LiveAOPS (August-November 2024), we randomly sampled a subset of answers as integers to facilitate automated evaluation, and used greedy search decoding for the evaluation. The trained model, STILL-3-1.5B-preview, achieved significant improvement. The accuracy on the AIME task increased from 28.67% to 39.33%, resulting in a relative improvement of 37.18%.
| MATH | AIME | OMNI | LiveAOPS | Avg. | |
|---|---|---|---|---|---|
| Qwen-2.5-Math-7B-Instruct | 83.60 | 16.67 | - | - | - |
| Qwen-2.5-Math-72B-Instruct | 85.90 | 30.00 | - | - | - |
| O1-preview | 85.50 | 44.60 | - | - | - |
| STILL-2 | 90.20 | 46.67 | - | - | - |
| QwQ-32B | 90.60 | 50.00 | - | - | - |
| DeepSeek-R1-Distill-Qwen-1.5B | 84.04 | 28.67 | 25.60 | 33.33 | 42.91 |
| STILL-3-1.5B-preview | 85.48 | 39.33 | 33.00 | 39.50 | 49.33 |
🚀 Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems [Report]
-
Slow-thinking reasoning systems, such as o1, have demonstrated remarkable capabilities in solving complex reasoning tasks, and are primarily developed and maintained by industry, with their core techniques not publicly disclosed. This paper presents a reproduction report on implementing o1-like reasoning systems. We introduce an imitate, explore, and self-improve framework as our primary technical approach to train the reasoning model. In the initial phase, we use distilled long-form thought data to fine-tune the reasoning model, enabling it to invoke a slow-thinking mode. The model is then encouraged to explore challenging problems by generating multiple rollouts, which can result in increasingly more high-quality trajectories that lead to correct answers. Furthermore, the model undergoes self-improvement by iteratively refining its training dataset.
Quick Start
from transformers import AutoTokenizer, AutoModelForCausalLM
from vllm import LLM, SamplingParams

# Load model and tokenizer
model_path = "RUC-AIBOX/STILL-2"
tokenizer = AutoTokenizer.from_pretrained(model_path)

# PROMPT
PROMPT = 'Your role as an assistant involves thoroughly exploring questions through a systematic long thinking process before providing the final precise and accurate solutions. This requires engaging in a comprehensive cycle of analysis, summarizing, exploration, reassessment, reflection, backtracing, and iteration to develop well-considered thinking process.\n\nPlease structure your response into two main sections: Thought and Solution.\n\nIn the Thought section, detail your reasoning process using the specified format:\n\n```\n<|begin_of_thought|>\n{thought with steps seperated with "\n\n"}\n<|end_of_thought|>\n```\n\nEach step should include detailed considerations such as analisying questions, summarizing relevant findings, brainstorming new ideas, verifying the accuracy of the current steps, refining any errors, and revisiting previous steps. Try to use casual, genuine phrases like: "Hmm...", "This is interesting because...", "Wait, let me think about...", "Actually...", "Now that I look at it...", "This reminds me of...", "I wonder if...", "But then again...", "Let\'s see if...", "Alternatively...", "Let\'s summaize existing information...", "This might mean that...", "why/how/when/where...", etc, to make your thought process be coherent, clear, and logically sound, effectively simulating human cognitive processes.\n\nIn the Solution section, based on various attempts, explorations, and reflections from the Thought section, systematically present the final solution that you deem correct. The solution should remain a logical, accurate, concise expression style and detail necessary step needed to reach the conclusion, formatted as follows:\n\n```\n<|begin_of_solution|>\n{final formatted, precise, and clear solution}\n<|end_of_solution|>\n```\n\nNow, try to solve the following question through the above guidlines:\n'

# Input text
question = "Convert the point $(0,3)$ in rectangular coordinates to polar coordinates.  Enter your answer in the form $(r,\\theta),$ where $r > 0$ and $0 \\le \\theta < 2 \\pi.$"

input_prompts = tokenizer.apply_chat_template(
    [{"role": "user", "content": PROMPT + question}],
    tokenize=False,
    add_generation_prompt=True,
)

# Params
stop_words = ["<|im_end|>", "<|endoftext|>"]

llm = LLM(
    model=model_path,
    tensor_parallel_size=8,
    max_model_len=int(1.5 * 20000),
    gpu_memory_utilization=0.95,
    dtype="bfloat16",
)

sampling_params = SamplingParams(
    temperature=0,
    top_p=1.0,
    max_tokens=20000,
    stop=stop_words,
    seed=42,
    skip_special_tokens=False,
)

# Completion
responses = llm.generate(input_prompts, sampling_params)
print(responses[0].outputs[0].text)
🚀 Enhancing LLM Reasoning with Reward-guided Tree Search [Report]
-
Recently, test-time scaling has garnered significant attention from the research community, largely due to the substantial advancements of the o1 model released by OpenAI. However, develop an o1-like reasoning approach is challenging, and researchers have been making various attempts to advance this open area of research. In this paper, we present a preliminary exploration into enhancing the reasoning abilities of LLMs through reward-guided tree search algorithms. This framework is implemented by integrating the policy model, reward model, and search algorithm. It is primarily constructed around a tree search algorithm, where the policy model navigates a dynamically expanding tree guided by a specially trained reward model.
🚀 Think More, Hallucinate Less: Mitigating Hallucinations via Dual Process of Fast and Slow Thinking [Report]
-
Large language models demonstrate exceptional capabilities, yet still face the hallucination issue. We propose HaluSearch, a novel framework that incorporates tree search-based algorithms to enable an explicit slow thinking generation process for mitigating hallucinations of LLMs during inference. HaluSearch frames text generation as a step-by-step reasoning process, using a self-evaluation reward model to score each generation step and guide the tree search towards the most reliable generation pathway. To balance efficiency and quality, we introduce a hierarchical thinking system switch mechanism inspired by the dual process theory in cognitive science, which dynamically alternates between fast and slow thinking modes at both the instance and step levels.
🚀 Virgo: A Preliminary Exploration on Reproducing o1-like MLLM [Report]
- There is a growing interest in reproducing o1-like MLLM in the research community. We explore a straightforward approach by fine-tuning a capable MLLM with a small amount of textual long-form thought data, resulting in a multimodal slow-thinking model, Virgo (Visual reasoning with long thought). We find that these long-form reasoning processes, expressed in natural language, can be effectively transferred to MLLMs. Moreover, it seems that such textual reasoning data can be even more effective than visual reasoning data in eliciting the slow-thinking capacities of MLLMs.
Future Work
Despite the promising results, our exploration remains preliminary, and there is still a substantial capacity gap compared to industry-level systems. As future work, we plan to investigate how to scale our training approach and extend its capacity to more complex tasks.
As always, we are committed to keeping our technical approach open, and we will release the data, model, and other resources. We welcome collaboration and support in computational resources.
Acknowledgements
We would like to express our sincere gratitude to DataCanvas Alaya NeW and BAAI for their generous computational resources and support.
Additionally, we are deeply thankful for the OpenRLHF open-source training framework, which has provided an invaluable foundation for our work.
Reference
Please kindly cite our reports if they are helpful for your research.
@article{Slow_Thinking_with_LLMs_1,
  title={Enhancing LLM Reasoning with Reward-guided Tree Search},
  author={Jiang, Jinhao and Chen, Zhipeng and Min, Yingqian and Chen, Jie and Cheng, Xiaoxue and Wang, Jiapeng and Tang, Yiru and Sun, Haoxiang and Deng, Jia and Zhao, Wayne Xin and Liu, Zheng and Yan, Dong and Xie, Jian and Wang, Zhongyuan and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2411.11694},
  year={2024}
}
@article{Slow_Thinking_with_LLMs_2,
  title={Imitate, Explore, and Self-Improve: A Reproduction Report on Slow-thinking Reasoning Systems},
  author={Min, Yingqian and Chen, Zhipeng and Jiang, Jinhao and Chen, Jie and Deng, Jia and Hu, Yiwen and Tang, Yiru and Wang, Jiapeng and Cheng, Xiaoxue and Song, Huatong and Zhao, Wayne Xin and Liu, Zheng and Wang, Zhongyuan and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2412.09413},
  year={2024}
}
@article{Slow_Thinking_with_LLMs_3,
      title={An Empirical Study on Eliciting and Improving R1-like Reasoning Models},
      author={Chen, Zhipeng and Min, Yingqian and Zhang, Beichen  and Chen, Jie and Jiang, Jinhao and Cheng, Daixuan and Zhao, Wayne Xin and Liu, Zheng and Miao, Xu and Lu, Yang and Fang, Lei and Wang, Zhongyuan and Wen, Ji-Rong},
      journal={arXiv preprint arXiv:2503.04548},
      year={2025}
}
@article{cheng2025think,
  title={Think More, Hallucinate Less: Mitigating Hallucinations via Dual Process of Fast and Slow Thinking},
  author={Cheng, Xiaoxue and Li, Junyi and Zhao, Wayne Xin and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2501.01306},
  year={2025}
}
@article{du2025virgo,
      title={Virgo: A Preliminary Exploration on Reproducing o1-like MLLM},
      author={Yifan Du and Zikang Liu and Yifan Li and Wayne Xin Zhao and Yuqi Huo and Bingning Wang and Weipeng Chen and Zheng Liu and Zhongyuan Wang and Ji-Rong Wen},
      journal={arXiv preprint arXiv:2501.01904},
      year={2025}
}
@article{R1-searcher,
  title={R1-searcher:  Stimulating the Search Capability of LLM from Zero via Reinforcement Learning},
  author={Huatong Song, Jinhao Jiang, Yingqian Min, Jie Chen, Zhipeng Chen, Wayne Xin Zhao, Ji-Rong Wen, Yang Lu, Xu Miu},
  url={https://github.com/SsmallSong/R1-searcher},
  year={2025}
}
Star History
Similar repos
Contributors
Languages
Python
85.4%
Jupyter Notebook
10.1%
Shell
4.5%