[RSS 2025] Learning to Act Anywhere with Task-centric Latent Actions
See the code[!IMPORTANT] 🌟 Stay up to date at opendrivelab.com!
📄 Paper | 🚀 Demo Page (Coming Soon)
✒️ Qingwen Bu, Y. Yang, J. Cai, S. Gao, G. Ren, M. Yao, P. Luo, H. Li
📧 Primary Contact: Qingwen Bu (buqingwen@opendrivelab.com)
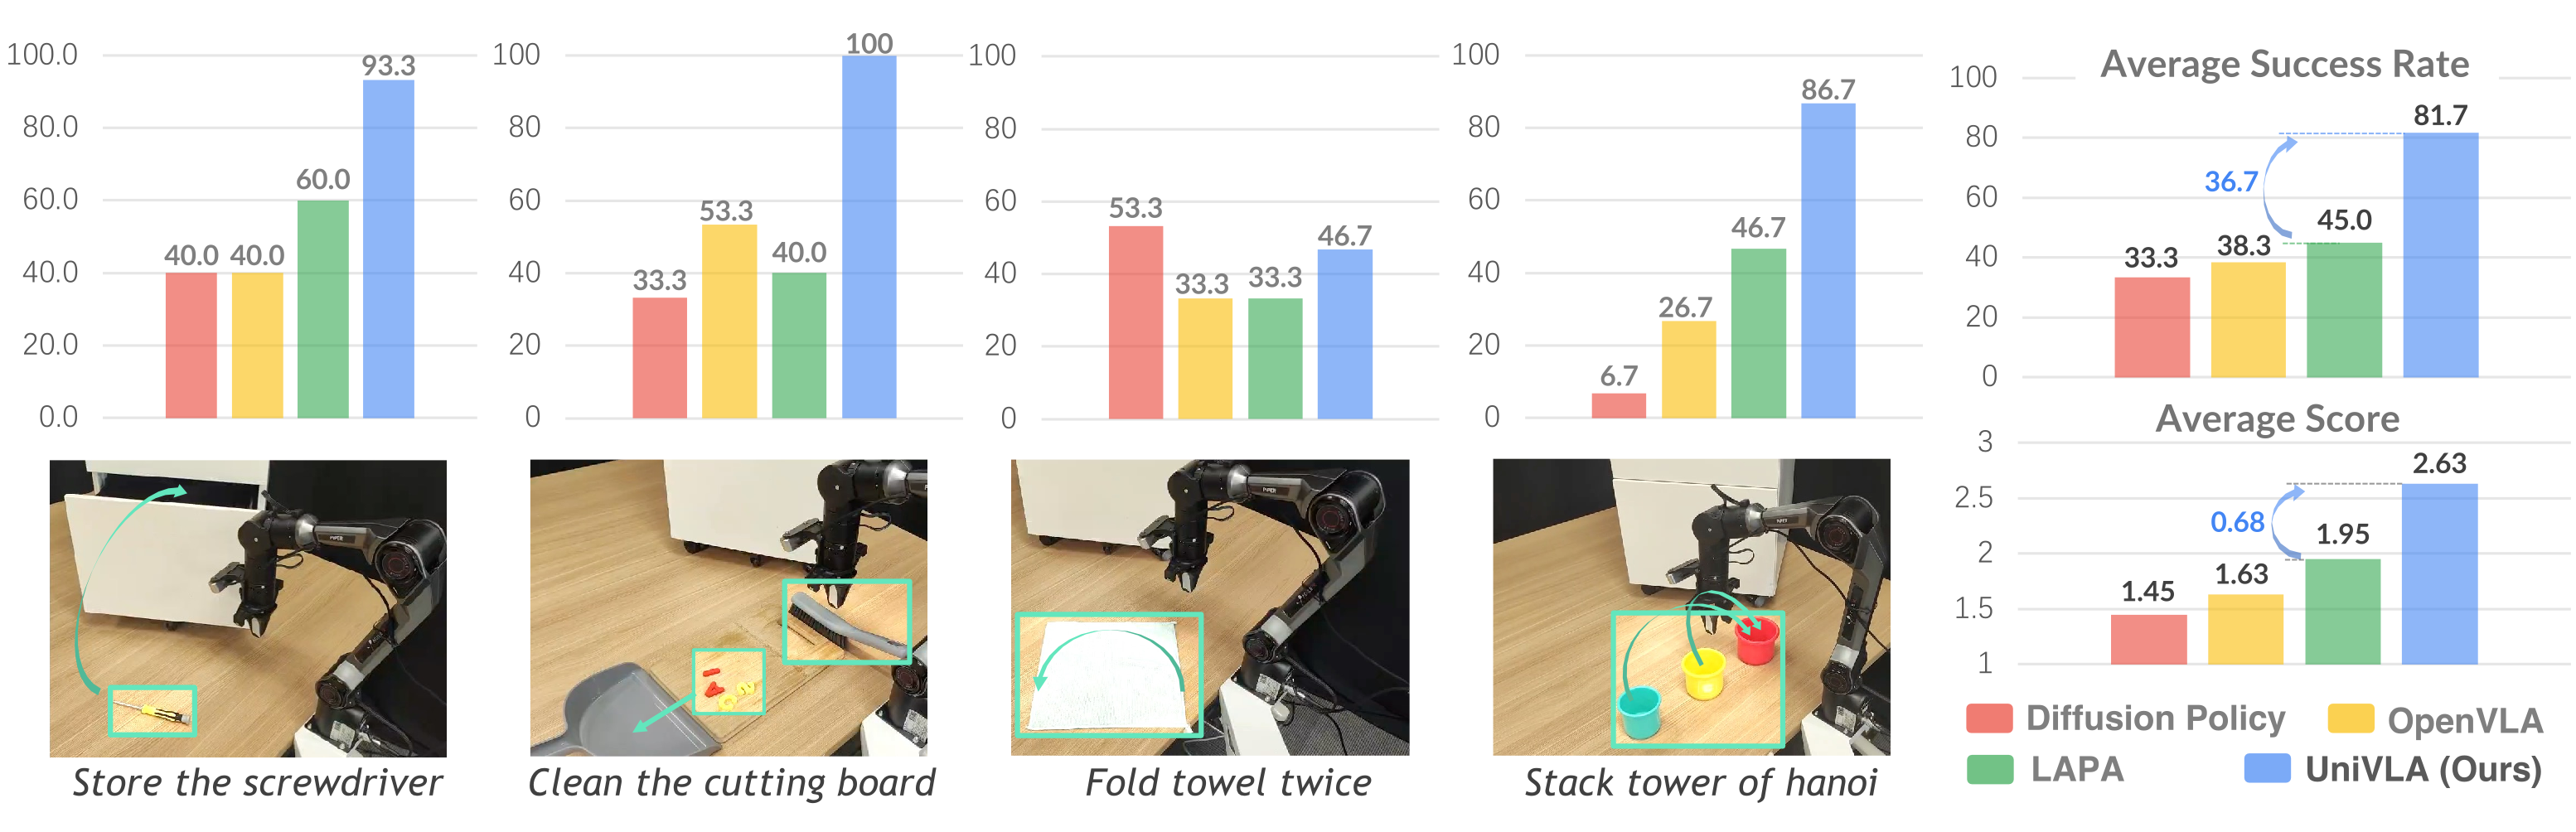
Real-world robot experiments.
| Store the screwdriver (1x speed) | Clean the cutting board (1x speed) | Fold towel twice (1x speed) |
| Stack the tower of hanoi (1x speed) | ||
| Model Name | Backbone | HF Path | Note |
|---|---|---|---|
| lam-stage-1 | - | univla-latent-action-model | The stage-1 latent action model trained on OpenX and Ego4D. |
| lam-stage-2 | - | univla-latent-action-model | The stage-2 latent action model trained on OpenX and Ego4D. (Generate task-centric latent actions.) |
| univla-7b | TRI-ML/prismatic-vlms/prism-dinosiglip-224px+7b | univla-7b | UniVLA pretrained on our full data collection (Manip. + Navi. + Human). |
| univla-7b-bridge-pt | TRI-ML/prismatic-vlms/prism-dinosiglip-224px+7b | univla-7b-bridge-pt | UniVLA pretrained only on BridgeV2 data. |
| univla-7b-human-pt | TRI-ML/prismatic-vlms/prism-dinosiglip-224px+7b | univla-7b-human-pt | UniVLA pretrained only on Ego4D human videos. |
| univla-libero | univla-7b | univla-7b-224-sft-libero | Finetuned on the LIBERO dataset |
| univla-calvin | univla-7b | univla-7b-224-sft-calvin | Finetuned on the CALVIN dataset |
| univla-r2r | univla-7b | univla-7b-224-sft-r2r | Finetuned on the R2R dataset |
| univla-bridge | univla-7b | univla-7b-224-sft-simpler-bridge | Finetuned on the BridgeV2 (OXE ver.) dataset |
conda create -n univla python=3.10 -y
conda activate univla
# Install pytorch
# Look up https://pytorch.org/get-started/previous-versions/ with your cuda version for a correct command
# Our experiments are conducted with 'torch 2.2.0 + cuda 12.1'
pip install torch torchvision

# Clone our repo and pip install to download dependencies
git clone git@github.com:OpenDriveLab/UniVLA.git
cd univla
pip install -e .

# Install Flash Attention 2 for training (https://github.com/Dao-AILab/flash-attention)
pip install packaging ninja
ninja --version; echo $?  # Verify Ninja --> should return exit code "0"
pip install "flash-attn==2.5.5" --no-build-isolation
[optional] Please follow this instruction if you'd like to convert Ego4D data into RLDS format for training UniVLA.
We hightly recommond directly using our pre-trained latent action model ckeckpoints to save your time and compute.
[!NOTE] Our latent action model is trained on a comprehensive data collection, encompassing multiple robotic manipulation and navigation datasets from Open X-Embodiment, along with a curated subset of the Ego4D dataset (detailed data construction procedures are provided in the appendix of our paper).
To adapt the model to additional datasets or custom data sources, users may refer to
./prismatic/vla/datasets/rlds/oxe/mixtures.pyto either utilize predefined data mixtures or define new ones. Subsequently, thedata_mixparameter in the configuration file should be updated accordingly.
The latent action model is implemented based on VQ-VAE. We train the latent action model on the collection of dataset comprising robot manipulation, navigation and human videos. In stage-1 training, we use an overall batch size of 512 and 100k optimization steps to construct the task-irrelevant latent actions:
torchrun --standalone --nnodes 1 --nproc-per-node 8 main.py fit \
    --config config/lam-stage-1.yaml \
    2>&1 | tee lam-stage-1.log
The following stage-2 then focuses on learning task-centric latent actions on the basis of stage-1 results. Please modify the stage_one_ckpt in latent_action_model/config/lam-stage-2.yaml to your local path of stage-1 checkpoint, then run training with:
torchrun --standalone --nnodes 1 --nproc-per-node 8 main.py fit \
    --config config/lam-stage-2.yaml \
    2>&1 | tee lam-stage-2.log
Latent Action Pseudo-Labeling for Policy Optimization: The trained latent action model is employed to generate pseudo-labels for policy optimization via a next-token prediction objective. Specifically, the indices of inferred latent actions in the VQ-VAE codebook are mapped to dedicated tokens in the LLaMA tokenizer, denoted as {ACT_0, ACT_1, ..., ACT_C}.
Cost-effective Pre-Training: The full-scale pre-training procedure, incorporating both OpenX and Ego4D datasets, was performed using a 32-GPU A100 cluster over 20,000 optimization steps. This training regimen required approximately 960 A100 GPU-hours, representing just 5% of the computational resources utilized by OpenVLA. Furthermore, experiments conducted on the 'Bridge' and 'Human' subsets demanded only 200 GPU-hours, demonstrating substantially reduced computational requirements compared to previous vision-language-action models.
To initiate pre-training, please refer to the following scipt or simply run bash ./vla-scripts/train.sh:
[!NOTE] For pretraining UniVLA only on BridgeV2 or Human (Ego4D) data, please modify
vla.typetoprism-dinosiglip-224px+mx-bridge(human)correspondingly. Detailed setups can be found in./prismatic/conf/vla.py.
### Experiment on a 32-GPU cluster
GPUS_PER_NODE=8
NNODES=4
MASTER_PORT=${MASTER_PORT:-28596}
MASTER_ADDR=${MASTER_ADDR:-"127.0.0.1"}
RANK=${RANK:-0}

# Run your training script with torchrun
torchrun --nproc_per_node ${GPUS_PER_NODE} --nnodes ${NNODES} --node_rank ${RANK} --master_addr ${MASTER_ADDR} --master_port ${MASTER_PORT} train.py \
                                 --vla.type prism-dinosiglip-224px+mx-oxe-magic-soup-plus \
                                 --run_root_dir "vla_log" \
Once pretraining is complete, convert the UniVLA weights (default 'Prismatic' format) to HuggingFace AutoClasses with:
python vla-scripts/extern/convert_openvla_weights_to_hf.py \
    --openvla_model_path_or_id /path/to/your/pretrained_ckpt_path \
    --ckpt_name /path/to/your/specific_ckpt_name.pt \
    --output_hf_model_local_path /path/to/your/output_model_path
The converted model is then compatible with HF AutoClasses 'AutoModelForVision2Seq'.
Our guidelines are based on real-device testing conducted on the AgiLex platform. If you have code deployed on other platforms or in different data formats, we welcome pull requests!
We provide a simple guideline to deploy UniVLA on your customized setups.
Please first download the LIBERO datasets that we used in experiments
Start training with torchrun:
vla_path and lam_path of the training config.data_root_dir.dataset_name from libero_spatial_no_noops, libero_object_no_noops, libero_goal_no_noops, and libero_10_no_noopsWe trained on 'Spatial', 'Object' and 'Goal' for 30k steps and 'Long' for 40k steps. Please first modify the
max_stepsin training config accordingly for reproduction.
# Start training on LIBERO-10(long) with 8 GPUs
torchrun --standalone --nnodes 1 --nproc-per-node 8 finetune_libero.py \
                                 --dataset_name "libero_10_no_noops" \
                                 --run_root_dir "libero_log" \
Once you finished training and get the action decoder and UniVLA backbone, you can start evaluation with:
# Start evaluation on LIBERO-10
# [Optional] Install LIBERO dependencies
pip install -r experiments/robot/libero/libero_requirements.txt

# By default, we test for 50 rollouts every task, totalling 500 independent trials.
python experiments/robot/libero/run_libero_eval.py \
    --task_suite_name libero_10 \   # Choose from [libero_spatial, libero_object, libero_goal, libero_10]
    --action_decoder_path /path/to/your/action_decoder_path.pt \
    --pretrained_checkpoint /path/to/your/libero_10_finetuned_univla \
    --save_video False    # Whether to save rollout videos \
    --num_trials_per_task 50 \
    --seed 7
Please first follow CALVIN to install relavent dependencies and prepare your dataset
vla_path and lam_path of the training config.calvin_root.torchrun:torchrun --standalone --nnodes 1 --nproc-per-node 8 finetune_calvin.py \
--vla_path /path/to/your/univla-7b \
--lam_path /path/to/your/lam-stage-2.ckpt \
--calvin_root /path/to/yout/calvin_root_path \
--max_steps 100000 \
--batch_size 8 \
--grad_accumulation_steps 2 \
--window_size 12 \
--run_root_dir "calvin_log"
Start evaluation on CALVIN:
# Mutli-GPU evaluation is supported
torchrun --standalone --nnodes 1 --nproc-per-node 8 experiments/robot/calvin/run_calvin_eval_ddp.py \
    --calvin_root /path/to/yout/calvin_root_path \
    --action_decoder_path /path/to/your/action_decoder_path.pt \
    --pretrained_checkpoint /path/to/your/calvin_finetuned_univla \
    --seed 7
[!NOTE] Please refer to this documentation for detailed guidelines.
Our SimplerEnv evlauation is based on the official repo.
# We used the Maniskill3 version
git clone -b maniskill3 https://github.com/simpler-env/SimplerEnv.git

cd SimplerEnv
pip install --upgrade git+https://github.com/haosulab/ManiSkill.git
pip install -e .
Add experiments/robot/simpler-bridge/policies/univla to simpler_env/policies, and replace simpler_env/real2sim_eval_maniskill3.py with experiments/robot/simpler-bridge/real2sim_eval_maniskill3.py.
Run evaluation on SimplerEnv-Bridge "Put Spoon on Table Cloth" task:
Please refer to
experiments/robot/simpler-bridge/eval_simpler_bridge_4task.shfor the evaluation on all tasks.
ckpt_path="/path/to/your/univla-7b-224-sft-simpler-bridge"
action_decoder_path="/path/to/your/univla-7b-224-sft-simpler-bridge/action_decoder.pt"

CUDA_VISIBLE_DEVICES=0 XLA_PYTHON_CLIENT_PREALLOCATE=false python real2sim_eval_maniskill3.py \
    --model="univla" -e "PutSpoonOnTableClothInScene-v1" -s 0 --num-episodes 24 --num-envs 1 \
    --action_decoder_path ${action_decoder_path} \
    --ckpt_path ${ckpt_path} \
[!NOTE] LIBERO Simulation Benchmark Results.
| Model | LIBERO-Spatial | LIBERO-Object | LIBERO-Goal | LIBERO-Long | Average | |||||
|---|---|---|---|---|---|---|---|---|---|---|
| SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | |
| Diffusion Policy | 78.3 ± 1.1% | 5 | 92.5 ± 0.7% | 2 | 68.3 ± 1.2% | 5 | 50.5 ± 1.3% | 5 | 72.4 ± 0.7% | 5 |
| Octo | 78.9 ± 1.0% | 4 | 85.7 ± 0.9% | 4 | 84.6 ± 0.9% | 2 | 51.1 ± 1.3% | 4 | 75.1 ± 0.6% | 3 |
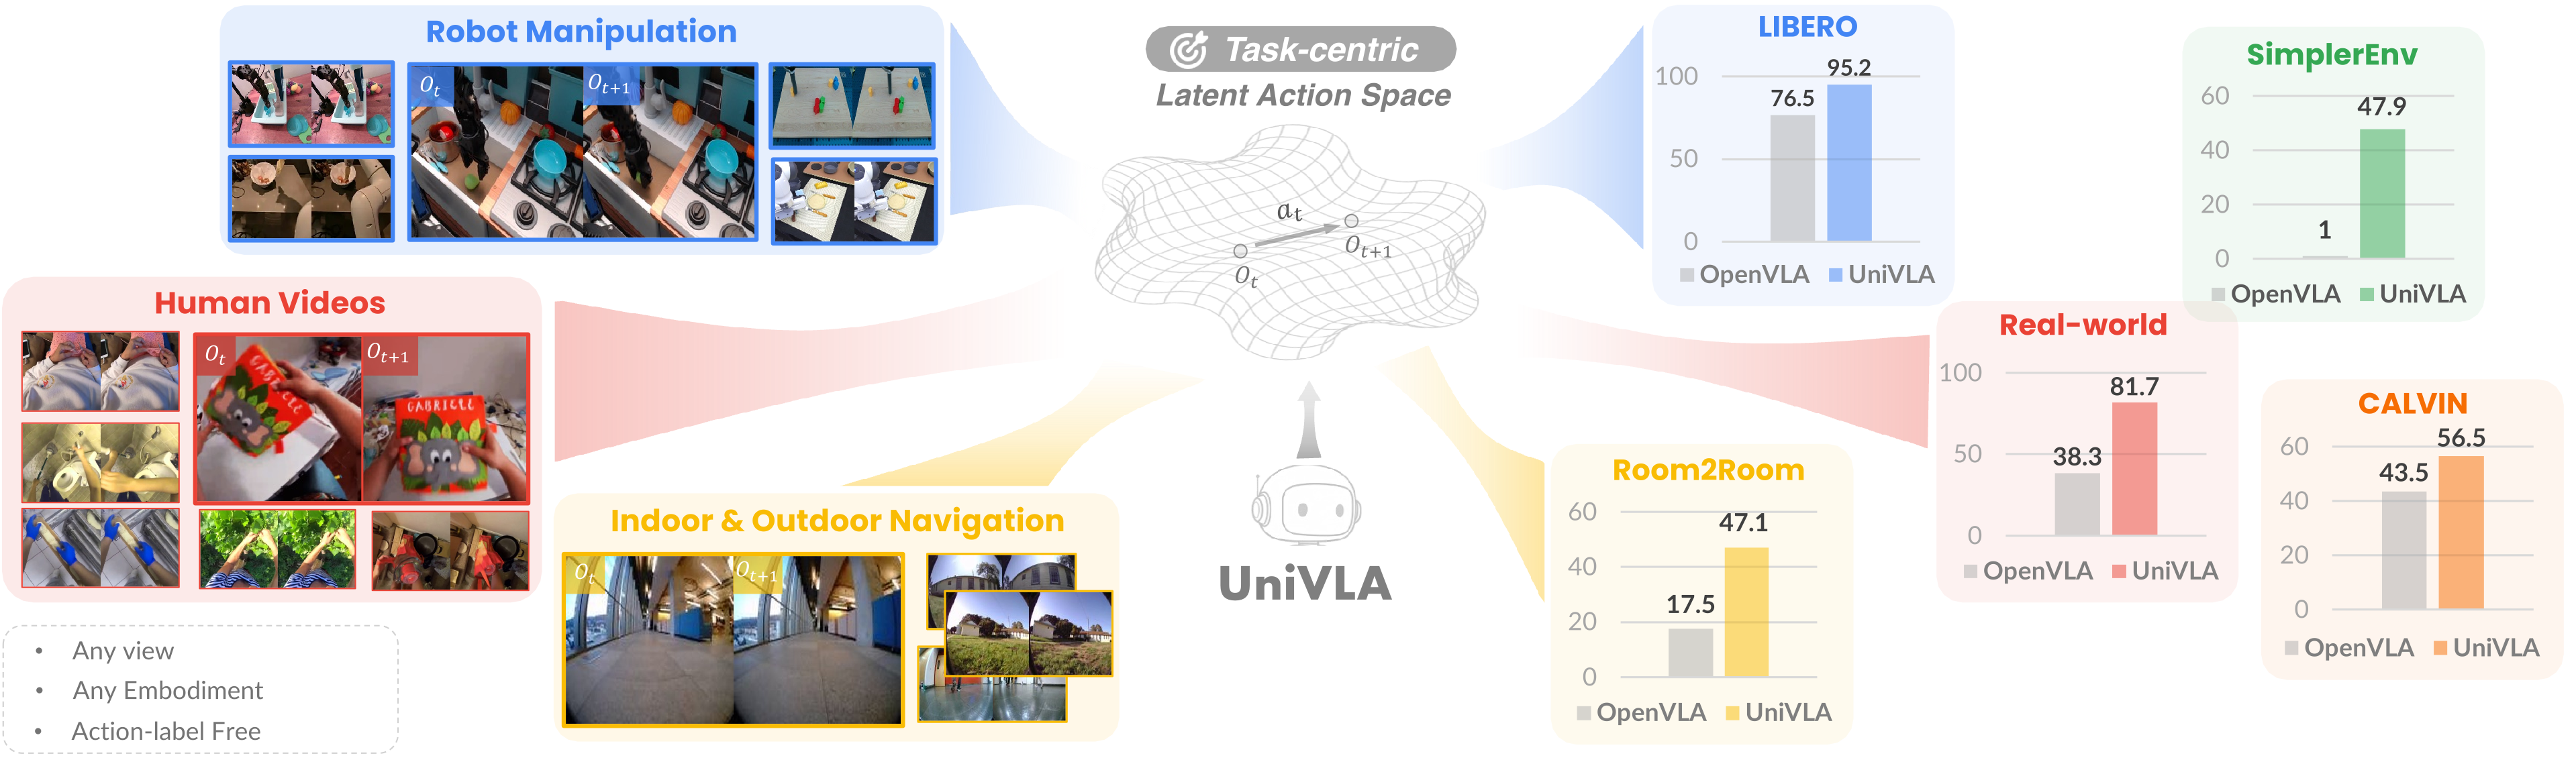
| OpenVLA | 84.7 ± 0.9% | 2 | 88.4 ± 0.8% | 3 | 79.2 ± 1.0% | 3 | 53.7 ± 1.3% | 3 | 76.5 ± 0.6% | 2 |
| TraceVLA | 84.6 ± 0.2% | 3 | 85.2 ± 0.4% | 5 | 75.1 ± 0.3% | 4 | 54.1 ± 1.0% | 2 | 74.8 ± 0.5% | 4 |
| UniVLA (Ours) | 96.5 ± 0.5% | 1 | 96.8 ± 0.5% | 1 | 95.6 ± 0.4% | 1 | 92.0 ± 1.0% | 1 | 95.2 ± 0.3% | 1 |
[!NOTE] LIBERO Results with Limited Data. (Models are trained with 10%, 20%, 50%, and the full dataset)
| Model | LIBERO-Goal | LIBERO-Long | ||||||
|---|---|---|---|---|---|---|---|---|
| 10% | 20% | 50% | 100% | 10% | 20% | 50% | 100% | |
| ATM | 64.3% | 77.1% | - | - | 36.5% | 39.1% | - | - |
| OpenVLA | 61.4% | 66.0% | 77.0% | 79.2% | 11.6% | 22.4% | 36.6% | 53.7% |
| OpenVLA-OFT | 76.8% | 88.2% | 91.1% | 96.2% | 43.0% | 62.2% | 77.8% | 90.7% |
| UniVLA (Ours) | 86.3% | 90.4% | 93.1% | 95.6% | 62.4% | 71.4% | 87.0% | 92.0% |
[!NOTE] SimplerEnv evaluation on WidowX Robot tasks. (Averaged across 3 seeds)
We fix a minor bug about input processing, so the UniVLA's results are higher than the numbers reported in our original paper.
| Model | Put Spoon on Towel | Put Carrot on Plate | Stack Green Block on Yellow Block | Put Eggplant in Yellow Basket | #Overall Average | ||||
|---|---|---|---|---|---|---|---|---|---|
| Grasp Spoon | Success | Grasp Carrot | Success | Grasp Green Block | Success | Grasp Eggplant | Success | ||
| RT-1-X | 16.7% | 0.0% | 20.8% | 4.2% | 8.3% | 0.0% | 0.0% | 0.0% | 1.1% |
| Octo-Base | 34.7% | 12.5% | 52.8% | 8.3% | 31.9% | 0.0% | 66.7% | 43.1% | 16.0% |
| Octo-Small | 77.8% | 47.2% | 27.8% | 9.7% | 40.3% | 4.2% | 87.5% | 56.9% | 30.0% |
| OpenVLA | 4.1% | 0.0% | 33.3% | 0.0% | 12.5% | 0.0% | 8.3% | 4.1% | 1.0% |
| RoboVLM | 54.2% | 29.2% | 25.0% | 25.0% | 45.8% | 12.5% | 58.3% | 58.3% | 31.3% |
| UniVLA | 76.4% ± 4.8% | 52.8% ± 6.4% | 79.2% ± 0.0% | 55.6% ± 2.4% | 66.7% ± 4.1% | 2.8% ± 2.4% | 93.0% ± 4.8% | 80.6% ± 6.4% | 47.9% ± 1.0% |
[!NOTE] Real-world Experiments.
If you find our code or models useful in your work, please cite our paper:
@article{bu2025univla,
  title={Univla: Learning to act anywhere with task-centric latent actions},
  author={Bu, Qingwen and Yang, Yanting and Cai, Jisong and Gao, Shenyuan and Ren, Guanghui and Yao, Maoqing and Luo, Ping and Li, Hongyang},
  journal={arXiv preprint arXiv:2505.06111},
  year={2025}
}
We thank OpenVLA for their open-sourced work!
464 followers · starred May 2025
171 followers · starred Jun 2026
[RSS 2025] Learning to Act Anywhere with Task-centric Latent Actions
See the code[!IMPORTANT] 🌟 Stay up to date at opendrivelab.com!
📄 Paper | 🚀 Demo Page (Coming Soon)
✒️ Qingwen Bu, Y. Yang, J. Cai, S. Gao, G. Ren, M. Yao, P. Luo, H. Li
📧 Primary Contact: Qingwen Bu (buqingwen@opendrivelab.com)
Real-world robot experiments.
| Store the screwdriver (1x speed) | Clean the cutting board (1x speed) | Fold towel twice (1x speed) |
| Stack the tower of hanoi (1x speed) | ||
| Model Name | Backbone | HF Path | Note |
|---|---|---|---|
| lam-stage-1 | - | univla-latent-action-model | The stage-1 latent action model trained on OpenX and Ego4D. |
| lam-stage-2 | - | univla-latent-action-model | The stage-2 latent action model trained on OpenX and Ego4D. (Generate task-centric latent actions.) |
| univla-7b | TRI-ML/prismatic-vlms/prism-dinosiglip-224px+7b | univla-7b | UniVLA pretrained on our full data collection (Manip. + Navi. + Human). |
| univla-7b-bridge-pt | TRI-ML/prismatic-vlms/prism-dinosiglip-224px+7b | univla-7b-bridge-pt | UniVLA pretrained only on BridgeV2 data. |
| univla-7b-human-pt | TRI-ML/prismatic-vlms/prism-dinosiglip-224px+7b | univla-7b-human-pt | UniVLA pretrained only on Ego4D human videos. |
| univla-libero | univla-7b | univla-7b-224-sft-libero | Finetuned on the LIBERO dataset |
| univla-calvin | univla-7b | univla-7b-224-sft-calvin | Finetuned on the CALVIN dataset |
| univla-r2r | univla-7b | univla-7b-224-sft-r2r | Finetuned on the R2R dataset |
| univla-bridge | univla-7b | univla-7b-224-sft-simpler-bridge | Finetuned on the BridgeV2 (OXE ver.) dataset |
conda create -n univla python=3.10 -y
conda activate univla
# Install pytorch
# Look up https://pytorch.org/get-started/previous-versions/ with your cuda version for a correct command
# Our experiments are conducted with 'torch 2.2.0 + cuda 12.1'
pip install torch torchvision

# Clone our repo and pip install to download dependencies
git clone git@github.com:OpenDriveLab/UniVLA.git
cd univla
pip install -e .

# Install Flash Attention 2 for training (https://github.com/Dao-AILab/flash-attention)
pip install packaging ninja
ninja --version; echo $?  # Verify Ninja --> should return exit code "0"
pip install "flash-attn==2.5.5" --no-build-isolation
[optional] Please follow this instruction if you'd like to convert Ego4D data into RLDS format for training UniVLA.
We hightly recommond directly using our pre-trained latent action model ckeckpoints to save your time and compute.
[!NOTE] Our latent action model is trained on a comprehensive data collection, encompassing multiple robotic manipulation and navigation datasets from Open X-Embodiment, along with a curated subset of the Ego4D dataset (detailed data construction procedures are provided in the appendix of our paper).
To adapt the model to additional datasets or custom data sources, users may refer to
./prismatic/vla/datasets/rlds/oxe/mixtures.pyto either utilize predefined data mixtures or define new ones. Subsequently, thedata_mixparameter in the configuration file should be updated accordingly.
The latent action model is implemented based on VQ-VAE. We train the latent action model on the collection of dataset comprising robot manipulation, navigation and human videos. In stage-1 training, we use an overall batch size of 512 and 100k optimization steps to construct the task-irrelevant latent actions:
torchrun --standalone --nnodes 1 --nproc-per-node 8 main.py fit \
    --config config/lam-stage-1.yaml \
    2>&1 | tee lam-stage-1.log
The following stage-2 then focuses on learning task-centric latent actions on the basis of stage-1 results. Please modify the stage_one_ckpt in latent_action_model/config/lam-stage-2.yaml to your local path of stage-1 checkpoint, then run training with:
torchrun --standalone --nnodes 1 --nproc-per-node 8 main.py fit \
    --config config/lam-stage-2.yaml \
    2>&1 | tee lam-stage-2.log
Latent Action Pseudo-Labeling for Policy Optimization: The trained latent action model is employed to generate pseudo-labels for policy optimization via a next-token prediction objective. Specifically, the indices of inferred latent actions in the VQ-VAE codebook are mapped to dedicated tokens in the LLaMA tokenizer, denoted as {ACT_0, ACT_1, ..., ACT_C}.
Cost-effective Pre-Training: The full-scale pre-training procedure, incorporating both OpenX and Ego4D datasets, was performed using a 32-GPU A100 cluster over 20,000 optimization steps. This training regimen required approximately 960 A100 GPU-hours, representing just 5% of the computational resources utilized by OpenVLA. Furthermore, experiments conducted on the 'Bridge' and 'Human' subsets demanded only 200 GPU-hours, demonstrating substantially reduced computational requirements compared to previous vision-language-action models.
To initiate pre-training, please refer to the following scipt or simply run bash ./vla-scripts/train.sh:
[!NOTE] For pretraining UniVLA only on BridgeV2 or Human (Ego4D) data, please modify
vla.typetoprism-dinosiglip-224px+mx-bridge(human)correspondingly. Detailed setups can be found in./prismatic/conf/vla.py.
### Experiment on a 32-GPU cluster
GPUS_PER_NODE=8
NNODES=4
MASTER_PORT=${MASTER_PORT:-28596}
MASTER_ADDR=${MASTER_ADDR:-"127.0.0.1"}
RANK=${RANK:-0}

# Run your training script with torchrun
torchrun --nproc_per_node ${GPUS_PER_NODE} --nnodes ${NNODES} --node_rank ${RANK} --master_addr ${MASTER_ADDR} --master_port ${MASTER_PORT} train.py \
                                 --vla.type prism-dinosiglip-224px+mx-oxe-magic-soup-plus \
                                 --run_root_dir "vla_log" \
Once pretraining is complete, convert the UniVLA weights (default 'Prismatic' format) to HuggingFace AutoClasses with:
python vla-scripts/extern/convert_openvla_weights_to_hf.py \
    --openvla_model_path_or_id /path/to/your/pretrained_ckpt_path \
    --ckpt_name /path/to/your/specific_ckpt_name.pt \
    --output_hf_model_local_path /path/to/your/output_model_path
The converted model is then compatible with HF AutoClasses 'AutoModelForVision2Seq'.
Our guidelines are based on real-device testing conducted on the AgiLex platform. If you have code deployed on other platforms or in different data formats, we welcome pull requests!
We provide a simple guideline to deploy UniVLA on your customized setups.
Please first download the LIBERO datasets that we used in experiments
Start training with torchrun:
vla_path and lam_path of the training config.data_root_dir.dataset_name from libero_spatial_no_noops, libero_object_no_noops, libero_goal_no_noops, and libero_10_no_noopsWe trained on 'Spatial', 'Object' and 'Goal' for 30k steps and 'Long' for 40k steps. Please first modify the
max_stepsin training config accordingly for reproduction.
# Start training on LIBERO-10(long) with 8 GPUs
torchrun --standalone --nnodes 1 --nproc-per-node 8 finetune_libero.py \
                                 --dataset_name "libero_10_no_noops" \
                                 --run_root_dir "libero_log" \
Once you finished training and get the action decoder and UniVLA backbone, you can start evaluation with:
# Start evaluation on LIBERO-10
# [Optional] Install LIBERO dependencies
pip install -r experiments/robot/libero/libero_requirements.txt

# By default, we test for 50 rollouts every task, totalling 500 independent trials.
python experiments/robot/libero/run_libero_eval.py \
    --task_suite_name libero_10 \   # Choose from [libero_spatial, libero_object, libero_goal, libero_10]
    --action_decoder_path /path/to/your/action_decoder_path.pt \
    --pretrained_checkpoint /path/to/your/libero_10_finetuned_univla \
    --save_video False    # Whether to save rollout videos \
    --num_trials_per_task 50 \
    --seed 7
Please first follow CALVIN to install relavent dependencies and prepare your dataset
vla_path and lam_path of the training config.calvin_root.torchrun:torchrun --standalone --nnodes 1 --nproc-per-node 8 finetune_calvin.py \
--vla_path /path/to/your/univla-7b \
--lam_path /path/to/your/lam-stage-2.ckpt \
--calvin_root /path/to/yout/calvin_root_path \
--max_steps 100000 \
--batch_size 8 \
--grad_accumulation_steps 2 \
--window_size 12 \
--run_root_dir "calvin_log"
Start evaluation on CALVIN:
# Mutli-GPU evaluation is supported
torchrun --standalone --nnodes 1 --nproc-per-node 8 experiments/robot/calvin/run_calvin_eval_ddp.py \
    --calvin_root /path/to/yout/calvin_root_path \
    --action_decoder_path /path/to/your/action_decoder_path.pt \
    --pretrained_checkpoint /path/to/your/calvin_finetuned_univla \
    --seed 7
[!NOTE] Please refer to this documentation for detailed guidelines.
Our SimplerEnv evlauation is based on the official repo.
# We used the Maniskill3 version
git clone -b maniskill3 https://github.com/simpler-env/SimplerEnv.git

cd SimplerEnv
pip install --upgrade git+https://github.com/haosulab/ManiSkill.git
pip install -e .
Add experiments/robot/simpler-bridge/policies/univla to simpler_env/policies, and replace simpler_env/real2sim_eval_maniskill3.py with experiments/robot/simpler-bridge/real2sim_eval_maniskill3.py.
Run evaluation on SimplerEnv-Bridge "Put Spoon on Table Cloth" task:
Please refer to
experiments/robot/simpler-bridge/eval_simpler_bridge_4task.shfor the evaluation on all tasks.
ckpt_path="/path/to/your/univla-7b-224-sft-simpler-bridge"
action_decoder_path="/path/to/your/univla-7b-224-sft-simpler-bridge/action_decoder.pt"

CUDA_VISIBLE_DEVICES=0 XLA_PYTHON_CLIENT_PREALLOCATE=false python real2sim_eval_maniskill3.py \
    --model="univla" -e "PutSpoonOnTableClothInScene-v1" -s 0 --num-episodes 24 --num-envs 1 \
    --action_decoder_path ${action_decoder_path} \
    --ckpt_path ${ckpt_path} \
[!NOTE] LIBERO Simulation Benchmark Results.
| Model | LIBERO-Spatial | LIBERO-Object | LIBERO-Goal | LIBERO-Long | Average | |||||
|---|---|---|---|---|---|---|---|---|---|---|
| SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | SR (↑) | Rank (↓) | |
| Diffusion Policy | 78.3 ± 1.1% | 5 | 92.5 ± 0.7% | 2 | 68.3 ± 1.2% | 5 | 50.5 ± 1.3% | 5 | 72.4 ± 0.7% | 5 |
| Octo | 78.9 ± 1.0% | 4 | 85.7 ± 0.9% | 4 | 84.6 ± 0.9% | 2 | 51.1 ± 1.3% | 4 | 75.1 ± 0.6% | 3 |
| OpenVLA | 84.7 ± 0.9% | 2 | 88.4 ± 0.8% | 3 | 79.2 ± 1.0% | 3 | 53.7 ± 1.3% | 3 | 76.5 ± 0.6% | 2 |
| TraceVLA | 84.6 ± 0.2% | 3 | 85.2 ± 0.4% | 5 | 75.1 ± 0.3% | 4 | 54.1 ± 1.0% | 2 | 74.8 ± 0.5% | 4 |
| UniVLA (Ours) | 96.5 ± 0.5% | 1 | 96.8 ± 0.5% | 1 | 95.6 ± 0.4% | 1 | 92.0 ± 1.0% | 1 | 95.2 ± 0.3% | 1 |
[!NOTE] LIBERO Results with Limited Data. (Models are trained with 10%, 20%, 50%, and the full dataset)
| Model | LIBERO-Goal | LIBERO-Long | ||||||
|---|---|---|---|---|---|---|---|---|
| 10% | 20% | 50% | 100% | 10% | 20% | 50% | 100% | |
| ATM | 64.3% | 77.1% | - | - | 36.5% | 39.1% | - | - |
| OpenVLA | 61.4% | 66.0% | 77.0% | 79.2% | 11.6% | 22.4% | 36.6% | 53.7% |
| OpenVLA-OFT | 76.8% | 88.2% | 91.1% | 96.2% | 43.0% | 62.2% | 77.8% | 90.7% |
| UniVLA (Ours) | 86.3% | 90.4% | 93.1% | 95.6% | 62.4% | 71.4% | 87.0% | 92.0% |
[!NOTE] SimplerEnv evaluation on WidowX Robot tasks. (Averaged across 3 seeds)
We fix a minor bug about input processing, so the UniVLA's results are higher than the numbers reported in our original paper.
| Model | Put Spoon on Towel | Put Carrot on Plate | Stack Green Block on Yellow Block | Put Eggplant in Yellow Basket | #Overall Average | ||||
|---|---|---|---|---|---|---|---|---|---|
| Grasp Spoon | Success | Grasp Carrot | Success | Grasp Green Block | Success | Grasp Eggplant | Success | ||
| RT-1-X | 16.7% | 0.0% | 20.8% | 4.2% | 8.3% | 0.0% | 0.0% | 0.0% | 1.1% |
| Octo-Base | 34.7% | 12.5% | 52.8% | 8.3% | 31.9% | 0.0% | 66.7% | 43.1% | 16.0% |
| Octo-Small | 77.8% | 47.2% | 27.8% | 9.7% | 40.3% | 4.2% | 87.5% | 56.9% | 30.0% |
| OpenVLA | 4.1% | 0.0% | 33.3% | 0.0% | 12.5% | 0.0% | 8.3% | 4.1% | 1.0% |
| RoboVLM | 54.2% | 29.2% | 25.0% | 25.0% | 45.8% | 12.5% | 58.3% | 58.3% | 31.3% |
| UniVLA | 76.4% ± 4.8% | 52.8% ± 6.4% | 79.2% ± 0.0% | 55.6% ± 2.4% | 66.7% ± 4.1% | 2.8% ± 2.4% | 93.0% ± 4.8% | 80.6% ± 6.4% | 47.9% ± 1.0% |
[!NOTE] Real-world Experiments.
If you find our code or models useful in your work, please cite our paper:
@article{bu2025univla,
  title={Univla: Learning to act anywhere with task-centric latent actions},
  author={Bu, Qingwen and Yang, Yanting and Cai, Jisong and Gao, Shenyuan and Ren, Guanghui and Yao, Maoqing and Luo, Ping and Li, Hongyang},
  journal={arXiv preprint arXiv:2505.06111},
  year={2025}
}
We thank OpenVLA for their open-sourced work!
464 followers · starred May 2025
171 followers · starred Jun 2026



