README
🌐 UniVLA: Unified Vision-Language-Action Model
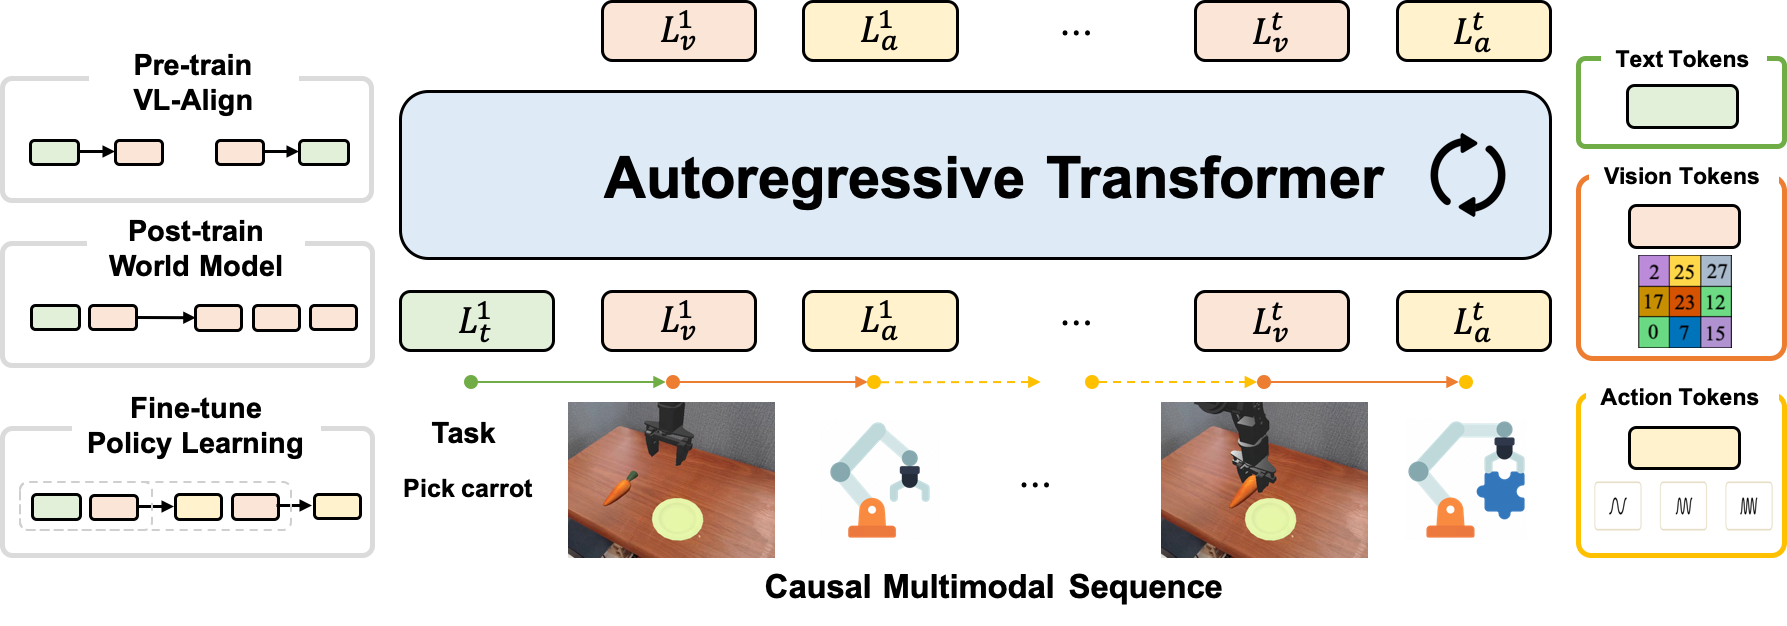
A general-purpose VLA Model designed to unify vision, language, and action for robotics and autonomous driving.
📜 [technical report] 🤗 [model weights] 🤖 [project page]
🚀 News
- 2025.10.15: DriveVLA-W0, extended the UniVLA framework to autonomous driving, code released.
- 2025.6.27: code released for robotic simulations.
- 2025.6.25: paper released on the arXiv.
🧪 Highlights
- Unified Vision-Language-Action Model: supports image grounding, video generation, and action prediction.
- Strong Performance on Several Robotics Benchmarks: support CALVIN, LIBERO, SimplerEnv.
- Interleaved Video Training: support interleaved vision-action training in Markov Decision Process.
- Broader Applications: Real-robot ALOHA & Autonomous Driving.
🔧 REPO TODO List
- Policy learning for CALVIN, LIBERO, and SimplerEnv.
- Support for evaluation.
- World model pretraining for video generation.
- Example for real-robot ALOHA.
- Support for autonomous driving.
- Support for general grounding.
📚 Experiments
Emu3 Pretraining Models
You can download the pretraining models from HuggingFace, here we provide the links.
World Model Training
More details can be found in the World Model Training document.
# train the world model
bash scripts/pretrain/train_video_1node.sh
This model is used to serve as the prerained model for the downstream policy learning tasks, such as CALVIN, LIBERO, and SimplerEnv.
1. CALVIN Benchmark
| Method | Mode | Setting | AVG | CKPT |
|---|---|---|---|---|
| UniVLA | video sft | ABCD->D | 4.63 (5x:4.71) | huggingface |
Note: 5× means 5× inference steps, i.e., 180 steps total.
Training
- Here provide single node training script, recommend multi-node training.
# video sft
bash scripts/simulator/calvin/train_calvin_abcd_video.sh
2. LIBERO Benchmark
| Method | Mode | SPATIAL | OBJECTS | GOAL | 10 | AVG | CKPT |
|---|---|---|---|---|---|---|---|
| UniVLA | img sft | 97.0 | 99.0 | 92.6 | 90.8 | 94.8 | huggingface |
| UniVLA | video sft | 95.4 | 98.8 | 93.6 | 94.0 | 95.5 | huggingface |
Training
bash scripts/simulator/libero/train_libero_video.sh
3. SimplerEnv Benchmark
| Method | Robot | Mode | Put Spoon | Put Carrot | Stack Block | Put Eggplant | AVG | CKPT |
|---|---|---|---|---|---|---|---|---|
| UniVLA | Bridge(WidowX) | video sft | 83.3 | 66.7 | 33.3 | 95.8 | 69.8 | huggingface |
Training
bash scripts/simulator/simplerenv/train_simplerenv_bridge_video.sh
Setup
Here we provide a conda environment setup for the project.
conda create -n emu_vla python=3.10
pip install -r requirements.txt
Benchmark setup, training and evaluation
📁 Code Structure
OmniSim/
├── configs/       # Model configuration files
├── models/        # Tokenizer and diffusion test
├── train/         # Training dataset and pipeline
├── reference/     # Reference code
│   ├── Emu3/      # Base code
│   └── RoboVLMs/  # Evaluation code
├── scripts/       # Shell scripts for training & evaluation
├── tools/         # Data preprocessing tools
└── README.md      # Project description and user guide
❤️ Acknowledgement
Our work is built upon the following projects, Thanks for their great open-source work!
🌟Citation
If you find this project useful, please consider citing our work:
@article{wang2025unified,
  title={Unified Vision-Language-Action Model},
  author={Wang, Yuqi and Li, Xinghang and Wang, Wenxuan and Zhang, Junbo and Li, Yingyan and Chen, Yuntao and Wang, Xinlong and Zhang, Zhaoxiang},
  journal={arXiv preprint arXiv:2506.19850},
  year={2025}
}
Contributors

8 commits

2 commits
Similar repos


Languages
Python
53.9%
Jupyter Notebook
42.1%
Shell
4.0%
README
🌐 UniVLA: Unified Vision-Language-Action Model
A general-purpose VLA Model designed to unify vision, language, and action for robotics and autonomous driving.
📜 [technical report] 🤗 [model weights] 🤖 [project page]
🚀 News
- 2025.10.15: DriveVLA-W0, extended the UniVLA framework to autonomous driving, code released.
- 2025.6.27: code released for robotic simulations.
- 2025.6.25: paper released on the arXiv.
🧪 Highlights
- Unified Vision-Language-Action Model: supports image grounding, video generation, and action prediction.
- Strong Performance on Several Robotics Benchmarks: support CALVIN, LIBERO, SimplerEnv.
- Interleaved Video Training: support interleaved vision-action training in Markov Decision Process.
- Broader Applications: Real-robot ALOHA & Autonomous Driving.
🔧 REPO TODO List
- Policy learning for CALVIN, LIBERO, and SimplerEnv.
- Support for evaluation.
- World model pretraining for video generation.
- Example for real-robot ALOHA.
- Support for autonomous driving.
- Support for general grounding.
📚 Experiments
Emu3 Pretraining Models
You can download the pretraining models from HuggingFace, here we provide the links.
World Model Training
More details can be found in the World Model Training document.
# train the world model
bash scripts/pretrain/train_video_1node.sh
This model is used to serve as the prerained model for the downstream policy learning tasks, such as CALVIN, LIBERO, and SimplerEnv.
1. CALVIN Benchmark
| Method | Mode | Setting | AVG | CKPT |
|---|---|---|---|---|
| UniVLA | video sft | ABCD->D | 4.63 (5x:4.71) | huggingface |
Note: 5× means 5× inference steps, i.e., 180 steps total.
Training
- Here provide single node training script, recommend multi-node training.
# video sft
bash scripts/simulator/calvin/train_calvin_abcd_video.sh
2. LIBERO Benchmark
| Method | Mode | SPATIAL | OBJECTS | GOAL | 10 | AVG | CKPT |
|---|---|---|---|---|---|---|---|
| UniVLA | img sft | 97.0 | 99.0 | 92.6 | 90.8 | 94.8 | huggingface |
| UniVLA | video sft | 95.4 | 98.8 | 93.6 | 94.0 | 95.5 | huggingface |
Training
bash scripts/simulator/libero/train_libero_video.sh
3. SimplerEnv Benchmark
| Method | Robot | Mode | Put Spoon | Put Carrot | Stack Block | Put Eggplant | AVG | CKPT |
|---|---|---|---|---|---|---|---|---|
| UniVLA | Bridge(WidowX) | video sft | 83.3 | 66.7 | 33.3 | 95.8 | 69.8 | huggingface |
Training
bash scripts/simulator/simplerenv/train_simplerenv_bridge_video.sh
Setup
Here we provide a conda environment setup for the project.
conda create -n emu_vla python=3.10
pip install -r requirements.txt
Benchmark setup, training and evaluation
📁 Code Structure
OmniSim/
├── configs/       # Model configuration files
├── models/        # Tokenizer and diffusion test
├── train/         # Training dataset and pipeline
├── reference/     # Reference code
│   ├── Emu3/      # Base code
│   └── RoboVLMs/  # Evaluation code
├── scripts/       # Shell scripts for training & evaluation
├── tools/         # Data preprocessing tools
└── README.md      # Project description and user guide
❤️ Acknowledgement
Our work is built upon the following projects, Thanks for their great open-source work!
🌟Citation
If you find this project useful, please consider citing our work:
@article{wang2025unified,
  title={Unified Vision-Language-Action Model},
  author={Wang, Yuqi and Li, Xinghang and Wang, Wenxuan and Zhang, Junbo and Li, Yingyan and Chen, Yuntao and Wang, Xinlong and Zhang, Zhaoxiang},
  journal={arXiv preprint arXiv:2506.19850},
  year={2025}
}
Similar repos
Contributors
8 commits
2 commits
Languages
Python
53.9%
Jupyter Notebook
42.1%
Shell
4.0%