
"A Survey on Agent-as-a-Judge"
See the codeREADME



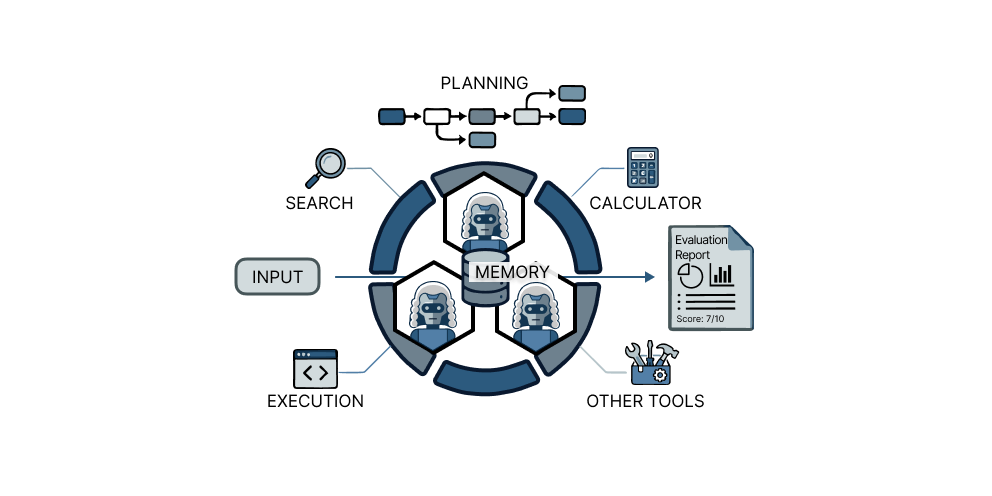
Welcome to Awesome Agent-as-a-Judge! 👋 This repository provides a collection of papers for A Survey on Agent-as-a-Judge, where LLM-based agents are used as judges to evaluate different types of outputs, including natural language generation, code generation, mathematical reasoning, and more.
📑 Table of Contents
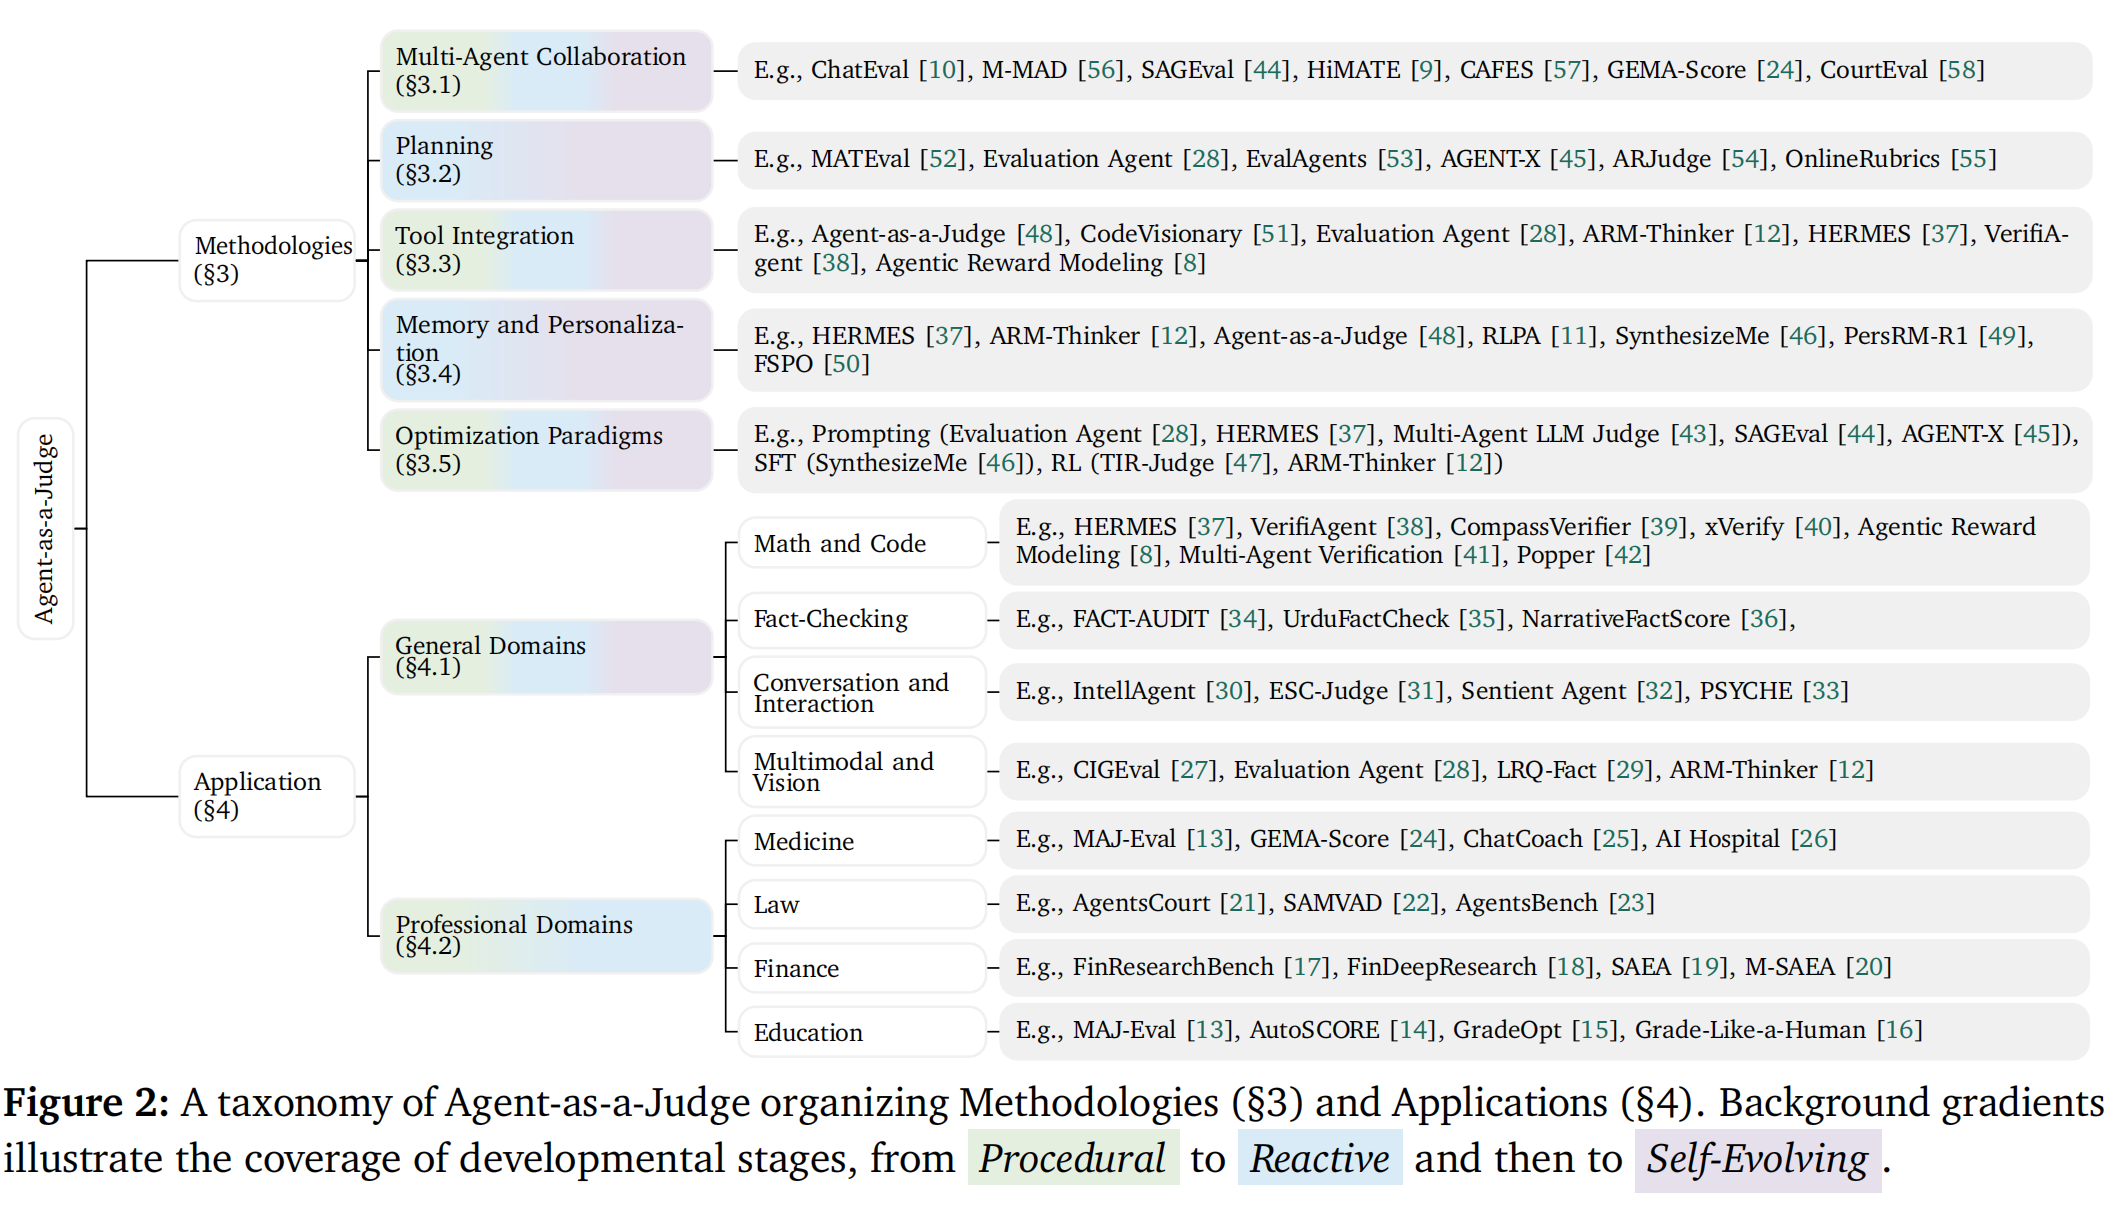
📊 Taxonomy
📚 Papers
Methodologies
Multi-Agent Collaboration
- [2026/03] CollabEval: Enhancing LLM-as-a-Judge via Multi-Agent Collaboration | paper | Venue: AAAI 2025 Workshop
- [2025/11] HiMATE: A Hierarchical Multi-Agent Framework for Machine Translation Evaluation | paper | Venue: EMNLP 2025
- [2025/11] Efficient LLM Safety Evaluation through Multi-Agent Debate | paper
- [2025/11] No-Human in the Loop: Agentic Evaluation at Scale for Recommendation | paper | Venue: NeurIPS 2025 Workshop
- [2025/10] Multi-Agent Debate for LLM Judges with Adaptive Stability Detection | paper | Venue: NeurIPS 2025
- [2025/07] CourtEval: A courtroom-based multi-agent evaluation framework. | paper | Venue: ACL 2025
- [2025/05] CAFES: A Collaborative Multi-Agent Framework for Multi-Granular Multimodal Essay Scoring | paper
- [2025/05] Judging with Many Minds: Do More Perspectives Mean Less Prejudice? On Bias Amplification and Resistance in Multi-Agent Based LLM-as-Judge | paper | Venue: EMNLP Findings 2025
- [2025/04] Leveraging LLMs as Meta-Judges: A Multi-Agent Framework for Evaluating LLM Judgments | paper
- [2025/03] GEMA-Score: Granular Explainable Multi-Agent Score for Radiology Report Evaluation | paper
- [2025/02] Table-Critic: A Multi-Agent Framework for Collaborative Criticism and Refinement in Table Reasoning | paper | Venue: ACL 2025
- [2025/02] Faithful, Unfaithful or Ambiguous? Multi-Agent Debate with Initial Stance for Summary Evaluation | paper | Venue: NAACL 2025
- [2024/12] M-MAD: Multidimensional Multi-Agent Debate for Advanced Machine Translation Evaluation | paper | Venue: ACL 2025
- [2024/11] SAGEval: The frontiers of Satisfactory Agent based NLG Evaluation | paper
- [2024/01] ChatEval: Towards Better LLM-based Evaluators through Multi-Agent Debate | paper | Venue: ICLR 2024
- [2023/03] Large language models are diverse role-players for summarization evaluation | paper | Venue: NLPCC 2023
Planning
- [2026/03] APRES: An Agentic Paper Revision and Evaluation System | paper
- [2026/01] Agentic Rubrics as Contextual Verifiers for SWE Agents | paper
- [2025/11] Large Language Models as User-Agents for Evaluating Task-Oriented-Dialogue Systems . | paper
- [2025/10] Online Rubrics Elicitation from Pairwise Comparisons | paper
- [2025/05] AGENT-X: Adaptive Guideline-based Expert Network for Threshold-free AI-generated teXt detection | paper
- [2025/04] EvalAgent: Discovering Implicit Evaluation Criteria from the Web | paper | Venue: COLM 2025
- [2025/01] Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge | paper | Venue: ICML 2025
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/05] MATEval: A Multi-Agent Discussion Framework for Advancing Open-Ended Text Evaluation | paper | Venue: DASFAA 2024
Tool Integration
- [2026/04] AgentV-RL: Scaling Reward Modeling with Agentic Verifier | paper
- [2026/02] DREAM: Deep Research Evaluation with Agentic Metrics | paper
- [2026/02] Scaling Agentic Verifier for Competitive Coding | paper
- [2026/01] Agentic Reward Modeling: Verifying GUI Agent via Online Proactive Interaction | paper
- [2026/01] Scaling Medical Reasoning Verification via Tool-Integrated Reinforcement Learning | paper
- [2025/12] Multimodal Reinforcement Learning with Adaptive Verifier for AI Agents | paper
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/12] CoSineVerifier: Tool-Augmented Answer Verification for Computation-Oriented Scientific Questions | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/11] TIM-PRM: Verifying multimodal reasoning with Tool-Integrated PRM | paper
- [2025/11] Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning | paper | Venue: ICLR 2026 Workshop
- [2025/10] OpenReward: Learning to Reward Long-form Agentic Tasks via Reinforcement Learning | paper
- [2025/10] TaTToo: Tool-Grounded Thinking PRM for Test-Time Scaling in Tabular Reasoning | paper | Venue: ICLR 2026
- [2025/08] Auto-Eval Judge: Towards a General Agentic Framework for Task Completion Evaluation | paper
- [2025/07] Can External Validation Tools Improve Annotation Quality for LLM-as-a-Judge? | paper | Venue: ACL 2025
- [2025/06] Mind2Web 2: Evaluating Agentic Search with Agent-as-a-Judge | paper | Venue: NeurIPS 2025
- [2025/04] CodeVisionary: An Agent-based Framework for Evaluating Large Language Models in Code Generation | paper | Venue: ASE 2025
- [2025/04] TALE: A Tool-Augmented Framework for Reference-Free Evaluation of Large Language Models | paper
- [2025/04] T1: Tool-integrated Self-verification for Test-time Compute Scaling in Small Language Models | paper
- [2025/04] VerifiAgent: a Unified Verification Agent in Language Model Reasoning | paper | Venue: EMNLP 2025
- [2025/02] Learning to Align Multi-Faceted Evaluation: A Unified and Robust Framework | paper | Venue: ACL Findings 2025
- [2025/02] Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals. | paper | Venue: ACL 2025
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/10] Agent-as-a-Judge: Evaluate Agents with Agent | paper | Venue: ICML 2025
- [2023/10] Tool-Augmented Reward Modeling | paper | Venue: ICLR 2024 Spotlight
Memory and Personalization
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/09] GUI-PRA: Process Reward Agent for GUI Tasks | paper
- [2025/08] PersRM-R1: Enhance Personalized Reward Modeling with Reinforcement Learning | paper
- [2025/06] SynthesizeMe! Inducing Persona-Guided Prompts for Personalized Reward Models in LLMs | paper | Venue: ACL 2025
- [2025/05] Teaching Language Models to Evolve with Users: Dynamic Profile Modeling for Personalized Alignment | paper | Venue: NeurIPS 2025
- [2025/02] FSPO: Few-Shot Preference Optimization of Synthetic Preference Data in LLMs Elicits Effective Personalization to Real Users | paper
- [2024/10] Agent-as-a-Judge: Evaluate Agents with Agent | paper | Venue: ICML 2025
Optimization Paradigms
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/10] Incentivizing Agentic Reasoning in LLM Judges via Tool-Integrated Reinforcement Learning | paper
- [2025/06] SynthesizeMe! Inducing Persona-Guided Prompts for Personalized Reward Models in LLMs | paper | Venue: ACL 2025
- [2025/05] AGENT-X: Adaptive Guideline-based Expert Network for Threshold-free AI-generated teXt detection | paper
- [2025/04] Multi-Agent LLM Judge: automatic personalized LLM judge design for evaluating natural language generation applications | paper
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/11] SAGEval: The frontiers of Satisfactory Agent based NLG Evaluation | paper
Applications
Professional Domains
Education
- [2025/09] AutoSCORE: Enhancing Automated Scoring with Multi-Agent Large Language Models via Structured Component Recognition | paper
- [2025/07] Multi-agent-as-judge: Aligning llm-agent-based automated evaluation with multi-dimensional human evaluation. | paper
- [2025/03] Rubric Is All You Need: Enhancing LLM-based Code Evaluation With Question-Specific Rubrics | paper | Venue: ICER 2025
- [2024/10] A LLM-Powered Automatic Grading Framework with Human-Level Guidelines Optimization | paper
- [2024/05] Grade Like a Human: Rethinking Automated Assessment with Multi-Agent LLMs | paper
Finance
- [2025/07] FinResearchBench: A Logic Tree based Agent-as-a-Judge Evaluation Framework for Financial Research Agents | paper | Venue: ICAIF 2025
- [2025/07] From Tasks to Teams: A Risk-First Evaluation Framework for Multi-Agent LLM Systems in Finance | paper | Venue: ICML Workshop 2025
- [2025/02] FinDeepResearch: Evaluating Deep Research Agents in Rigorous Financial Analysis | paper
- [2025/02] Standard Benchmarks Fail -- Auditing LLM Agents in Finance Must Prioritize Risk | paper
Law
- [2025/09] SAMVAD: A Multi-Agent System for Simulating Judicial Deliberation Dynamics in India | paper
- [2024/12] AgentsBench: A Multi-Agent LLM Simulation Framework for Legal Judgment Prediction | paper
- [2024/03] AgentsCourt: Building judicial decision-making agents with court debate simulation and legal knowledge augmentation. | paper | Venue: EMNLP 2024
Medicine
- [2026/01] Scaling Medical Reasoning Verification via Tool-Integrated Reinforcement Learning | paper
- [2025/07] Multi-agent-as-judge: Aligning llm-agent-based automated evaluation with multi-dimensional human evaluation. | paper
- [2025/03] GEMA-Score: Granular Explainable Multi-Agent Score for Radiology Report Evaluation | paper
- [2024/02] Benchmarking Large Language Models on Communicative Medical Coaching: A Dataset and a Novel System | paper | Venue: ACL 2024
- [2024/02] Ai hospital: Benchmarking large language models in a multi-agent medical interaction simulator | paper | Venue: COLING 2025
General Domains
Multimodal and Vision
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/04] CIGEval: A Unified Agentic Framework for Evaluating Conditional Image Generation | paper | Venue: ACL 2025
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/10] LRQ-Fact: LLM-Generated Relevant Questions for Multimodal Fact-Checking . | paper
Conversation and Interaction
- [2025/11] Large Language Models as User-Agents for Evaluating Task-Oriented-Dialogue Systems . | paper
- [2025/05] ESC-Judge: A Framework for Comparing Emotional Support Conversational Agents | paper | Venue: EMNLP 2025
- [2025/05] Sentient Agent as a Judge: Evaluating Higher-Order Social Cognition | paper
- [2025/01] IntellAgent: A Multi-Agent Framework for Evaluating Conversational AI Systems | paper
- [2025/01] PSYCHE: A Multi-faceted Patient Simulation Framework for Evaluation of Psychiatric Assessment Conversational Agent | paper
Fact-Checking
- [2025/05] UrduFactCheck: An Agentic Fact-Checking Framework for Urdu | paper | Venue: EMNLP 2025
- [2025/02] FACT-AUDIT: An Adaptive Multi-Agent Framework for Dynamic Fact-Checking Evaluation | paper | Venue: ACL 2025
- [2025/01] NarrativeFactScore: Agent-as-Judge for Factual Summarization of Long Narratives | paper | Venue: EMNLP 2025
Math and Code
- [2026/02] Scaling Agentic Verifier for Competitive Coding | paper
- [2025/12] CoSineVerifier: Tool-Augmented Answer Verification for Computation-Oriented Scientific Questions | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/08] CompassVerifier: A Unified and Robust Verifier for LLMs Evaluation and Outcome Reward | paper | Venue: EMNLP 2025
- [2025/05] Step-Wise Formal Verification for LLM-Based Mathematical Problem Solving | paper
- [2025/04] VerifiAgent: a Unified Verification Agent in Language Model Reasoning | paper | Venue: EMNLP 2025
- [2025/04] xVerify: Efficient Answer Verifier for Reasoning Model Evaluations | paper
- [2025/04] CodeVisionary: An Agent-based Framework for Evaluating Large Language Models in Code Generation | paper | Venue: ASE 2025
- [2025/02] Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals. | paper | Venue: ACL 2025
- [2025/02] Multi-Agent Verification: Scaling Test-Time Compute with Multiple Verifiers | paper | Venue: COLM 2025
- [2025/02] Popper: Automated Hypothesis Validation with Agentic Sequential Falsifications | paper | Venue: ICML 2025
🪴 Acknowledge
We would like to thank the contributors, open-source projects, and research communities whose work made this collection possible. This repository builds upon the excellent research in agent-based evaluation methods.
📖 Citation
@misc{you2026agentasajudge,
      title={Agent-as-a-Judge},
      author={Runyang You and Hongru Cai and Caiqi Zhang and Qiancheng Xu and Meng Liu and Tiezheng Yu and Yongqi Li and Wenjie Li},
      year={2026},
      eprint={2601.05111},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.05111},
}


⭐ Thank you for visiting Awesome Agent-as-a-Judge! ⭐
Similar repos


"A Survey on Agent-as-a-Judge"
See the codeREADME
Welcome to Awesome Agent-as-a-Judge! 👋 This repository provides a collection of papers for A Survey on Agent-as-a-Judge, where LLM-based agents are used as judges to evaluate different types of outputs, including natural language generation, code generation, mathematical reasoning, and more.
📑 Table of Contents
📊 Taxonomy
📚 Papers
Methodologies
Multi-Agent Collaboration
- [2026/03] CollabEval: Enhancing LLM-as-a-Judge via Multi-Agent Collaboration | paper | Venue: AAAI 2025 Workshop
- [2025/11] HiMATE: A Hierarchical Multi-Agent Framework for Machine Translation Evaluation | paper | Venue: EMNLP 2025
- [2025/11] Efficient LLM Safety Evaluation through Multi-Agent Debate | paper
- [2025/11] No-Human in the Loop: Agentic Evaluation at Scale for Recommendation | paper | Venue: NeurIPS 2025 Workshop
- [2025/10] Multi-Agent Debate for LLM Judges with Adaptive Stability Detection | paper | Venue: NeurIPS 2025
- [2025/07] CourtEval: A courtroom-based multi-agent evaluation framework. | paper | Venue: ACL 2025
- [2025/05] CAFES: A Collaborative Multi-Agent Framework for Multi-Granular Multimodal Essay Scoring | paper
- [2025/05] Judging with Many Minds: Do More Perspectives Mean Less Prejudice? On Bias Amplification and Resistance in Multi-Agent Based LLM-as-Judge | paper | Venue: EMNLP Findings 2025
- [2025/04] Leveraging LLMs as Meta-Judges: A Multi-Agent Framework for Evaluating LLM Judgments | paper
- [2025/03] GEMA-Score: Granular Explainable Multi-Agent Score for Radiology Report Evaluation | paper
- [2025/02] Table-Critic: A Multi-Agent Framework for Collaborative Criticism and Refinement in Table Reasoning | paper | Venue: ACL 2025
- [2025/02] Faithful, Unfaithful or Ambiguous? Multi-Agent Debate with Initial Stance for Summary Evaluation | paper | Venue: NAACL 2025
- [2024/12] M-MAD: Multidimensional Multi-Agent Debate for Advanced Machine Translation Evaluation | paper | Venue: ACL 2025
- [2024/11] SAGEval: The frontiers of Satisfactory Agent based NLG Evaluation | paper
- [2024/01] ChatEval: Towards Better LLM-based Evaluators through Multi-Agent Debate | paper | Venue: ICLR 2024
- [2023/03] Large language models are diverse role-players for summarization evaluation | paper | Venue: NLPCC 2023
Planning
- [2026/03] APRES: An Agentic Paper Revision and Evaluation System | paper
- [2026/01] Agentic Rubrics as Contextual Verifiers for SWE Agents | paper
- [2025/11] Large Language Models as User-Agents for Evaluating Task-Oriented-Dialogue Systems . | paper
- [2025/10] Online Rubrics Elicitation from Pairwise Comparisons | paper
- [2025/05] AGENT-X: Adaptive Guideline-based Expert Network for Threshold-free AI-generated teXt detection | paper
- [2025/04] EvalAgent: Discovering Implicit Evaluation Criteria from the Web | paper | Venue: COLM 2025
- [2025/01] Learning to Plan & Reason for Evaluation with Thinking-LLM-as-a-Judge | paper | Venue: ICML 2025
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/05] MATEval: A Multi-Agent Discussion Framework for Advancing Open-Ended Text Evaluation | paper | Venue: DASFAA 2024
Tool Integration
- [2026/04] AgentV-RL: Scaling Reward Modeling with Agentic Verifier | paper
- [2026/02] DREAM: Deep Research Evaluation with Agentic Metrics | paper
- [2026/02] Scaling Agentic Verifier for Competitive Coding | paper
- [2026/01] Agentic Reward Modeling: Verifying GUI Agent via Online Proactive Interaction | paper
- [2026/01] Scaling Medical Reasoning Verification via Tool-Integrated Reinforcement Learning | paper
- [2025/12] Multimodal Reinforcement Learning with Adaptive Verifier for AI Agents | paper
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/12] CoSineVerifier: Tool-Augmented Answer Verification for Computation-Oriented Scientific Questions | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/11] TIM-PRM: Verifying multimodal reasoning with Tool-Integrated PRM | paper
- [2025/11] Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning | paper | Venue: ICLR 2026 Workshop
- [2025/10] OpenReward: Learning to Reward Long-form Agentic Tasks via Reinforcement Learning | paper
- [2025/10] TaTToo: Tool-Grounded Thinking PRM for Test-Time Scaling in Tabular Reasoning | paper | Venue: ICLR 2026
- [2025/08] Auto-Eval Judge: Towards a General Agentic Framework for Task Completion Evaluation | paper
- [2025/07] Can External Validation Tools Improve Annotation Quality for LLM-as-a-Judge? | paper | Venue: ACL 2025
- [2025/06] Mind2Web 2: Evaluating Agentic Search with Agent-as-a-Judge | paper | Venue: NeurIPS 2025
- [2025/04] CodeVisionary: An Agent-based Framework for Evaluating Large Language Models in Code Generation | paper | Venue: ASE 2025
- [2025/04] TALE: A Tool-Augmented Framework for Reference-Free Evaluation of Large Language Models | paper
- [2025/04] T1: Tool-integrated Self-verification for Test-time Compute Scaling in Small Language Models | paper
- [2025/04] VerifiAgent: a Unified Verification Agent in Language Model Reasoning | paper | Venue: EMNLP 2025
- [2025/02] Learning to Align Multi-Faceted Evaluation: A Unified and Robust Framework | paper | Venue: ACL Findings 2025
- [2025/02] Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals. | paper | Venue: ACL 2025
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/10] Agent-as-a-Judge: Evaluate Agents with Agent | paper | Venue: ICML 2025
- [2023/10] Tool-Augmented Reward Modeling | paper | Venue: ICLR 2024 Spotlight
Memory and Personalization
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/09] GUI-PRA: Process Reward Agent for GUI Tasks | paper
- [2025/08] PersRM-R1: Enhance Personalized Reward Modeling with Reinforcement Learning | paper
- [2025/06] SynthesizeMe! Inducing Persona-Guided Prompts for Personalized Reward Models in LLMs | paper | Venue: ACL 2025
- [2025/05] Teaching Language Models to Evolve with Users: Dynamic Profile Modeling for Personalized Alignment | paper | Venue: NeurIPS 2025
- [2025/02] FSPO: Few-Shot Preference Optimization of Synthetic Preference Data in LLMs Elicits Effective Personalization to Real Users | paper
- [2024/10] Agent-as-a-Judge: Evaluate Agents with Agent | paper | Venue: ICML 2025
Optimization Paradigms
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/10] Incentivizing Agentic Reasoning in LLM Judges via Tool-Integrated Reinforcement Learning | paper
- [2025/06] SynthesizeMe! Inducing Persona-Guided Prompts for Personalized Reward Models in LLMs | paper | Venue: ACL 2025
- [2025/05] AGENT-X: Adaptive Guideline-based Expert Network for Threshold-free AI-generated teXt detection | paper
- [2025/04] Multi-Agent LLM Judge: automatic personalized LLM judge design for evaluating natural language generation applications | paper
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/11] SAGEval: The frontiers of Satisfactory Agent based NLG Evaluation | paper
Applications
Professional Domains
Education
- [2025/09] AutoSCORE: Enhancing Automated Scoring with Multi-Agent Large Language Models via Structured Component Recognition | paper
- [2025/07] Multi-agent-as-judge: Aligning llm-agent-based automated evaluation with multi-dimensional human evaluation. | paper
- [2025/03] Rubric Is All You Need: Enhancing LLM-based Code Evaluation With Question-Specific Rubrics | paper | Venue: ICER 2025
- [2024/10] A LLM-Powered Automatic Grading Framework with Human-Level Guidelines Optimization | paper
- [2024/05] Grade Like a Human: Rethinking Automated Assessment with Multi-Agent LLMs | paper
Finance
- [2025/07] FinResearchBench: A Logic Tree based Agent-as-a-Judge Evaluation Framework for Financial Research Agents | paper | Venue: ICAIF 2025
- [2025/07] From Tasks to Teams: A Risk-First Evaluation Framework for Multi-Agent LLM Systems in Finance | paper | Venue: ICML Workshop 2025
- [2025/02] FinDeepResearch: Evaluating Deep Research Agents in Rigorous Financial Analysis | paper
- [2025/02] Standard Benchmarks Fail -- Auditing LLM Agents in Finance Must Prioritize Risk | paper
Law
- [2025/09] SAMVAD: A Multi-Agent System for Simulating Judicial Deliberation Dynamics in India | paper
- [2024/12] AgentsBench: A Multi-Agent LLM Simulation Framework for Legal Judgment Prediction | paper
- [2024/03] AgentsCourt: Building judicial decision-making agents with court debate simulation and legal knowledge augmentation. | paper | Venue: EMNLP 2024
Medicine
- [2026/01] Scaling Medical Reasoning Verification via Tool-Integrated Reinforcement Learning | paper
- [2025/07] Multi-agent-as-judge: Aligning llm-agent-based automated evaluation with multi-dimensional human evaluation. | paper
- [2025/03] GEMA-Score: Granular Explainable Multi-Agent Score for Radiology Report Evaluation | paper
- [2024/02] Benchmarking Large Language Models on Communicative Medical Coaching: A Dataset and a Novel System | paper | Venue: ACL 2024
- [2024/02] Ai hospital: Benchmarking large language models in a multi-agent medical interaction simulator | paper | Venue: COLING 2025
General Domains
Multimodal and Vision
- [2025/12] ARM-Thinker: Reinforcing Multimodal Generative Reward Models with Agentic Tool Use and Visual Reasoning | paper
- [2025/04] CIGEval: A Unified Agentic Framework for Evaluating Conditional Image Generation | paper | Venue: ACL 2025
- [2024/12] Evaluation Agent: Efficient and Promptable Evaluation Framework for Visual Generative Models | paper | Venue: ACL 2025
- [2024/10] LRQ-Fact: LLM-Generated Relevant Questions for Multimodal Fact-Checking . | paper
Conversation and Interaction
- [2025/11] Large Language Models as User-Agents for Evaluating Task-Oriented-Dialogue Systems . | paper
- [2025/05] ESC-Judge: A Framework for Comparing Emotional Support Conversational Agents | paper | Venue: EMNLP 2025
- [2025/05] Sentient Agent as a Judge: Evaluating Higher-Order Social Cognition | paper
- [2025/01] IntellAgent: A Multi-Agent Framework for Evaluating Conversational AI Systems | paper
- [2025/01] PSYCHE: A Multi-faceted Patient Simulation Framework for Evaluation of Psychiatric Assessment Conversational Agent | paper
Fact-Checking
- [2025/05] UrduFactCheck: An Agentic Fact-Checking Framework for Urdu | paper | Venue: EMNLP 2025
- [2025/02] FACT-AUDIT: An Adaptive Multi-Agent Framework for Dynamic Fact-Checking Evaluation | paper | Venue: ACL 2025
- [2025/01] NarrativeFactScore: Agent-as-Judge for Factual Summarization of Long Narratives | paper | Venue: EMNLP 2025
Math and Code
- [2026/02] Scaling Agentic Verifier for Competitive Coding | paper
- [2025/12] CoSineVerifier: Tool-Augmented Answer Verification for Computation-Oriented Scientific Questions | paper
- [2025/11] HERMES: Towards Efficient and Verifiable Mathematical Reasoning in LLMs. | paper
- [2025/08] CompassVerifier: A Unified and Robust Verifier for LLMs Evaluation and Outcome Reward | paper | Venue: EMNLP 2025
- [2025/05] Step-Wise Formal Verification for LLM-Based Mathematical Problem Solving | paper
- [2025/04] VerifiAgent: a Unified Verification Agent in Language Model Reasoning | paper | Venue: EMNLP 2025
- [2025/04] xVerify: Efficient Answer Verifier for Reasoning Model Evaluations | paper
- [2025/04] CodeVisionary: An Agent-based Framework for Evaluating Large Language Models in Code Generation | paper | Venue: ASE 2025
- [2025/02] Agentic Reward Modeling: Integrating Human Preferences with Verifiable Correctness Signals. | paper | Venue: ACL 2025
- [2025/02] Multi-Agent Verification: Scaling Test-Time Compute with Multiple Verifiers | paper | Venue: COLM 2025
- [2025/02] Popper: Automated Hypothesis Validation with Agentic Sequential Falsifications | paper | Venue: ICML 2025
🪴 Acknowledge
We would like to thank the contributors, open-source projects, and research communities whose work made this collection possible. This repository builds upon the excellent research in agent-based evaluation methods.
📖 Citation
@misc{you2026agentasajudge,
      title={Agent-as-a-Judge},
      author={Runyang You and Hongru Cai and Caiqi Zhang and Qiancheng Xu and Meng Liu and Tiezheng Yu and Yongqi Li and Wenjie Li},
      year={2026},
      eprint={2601.05111},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.05111},
}
⭐ Thank you for visiting Awesome Agent-as-a-Judge! ⭐